Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Piotr Skalski |
e50c761b83 | ||
|
SkalskiP
|
0200fd307b | ||
|
Piotr Skalski
|
6a199c5d7e | ||
|
Piotr Skalski
|
d19c44c991 | ||
|
SkalskiP
|
2d5de66a9b | ||
|
LinasKo
|
13b46dda67 | ||
|
SkalskiP
|
a3f299ceb0 | ||
|
SkalskiP
|
9a42372ff6 | ||
|
SkalskiP
|
47b9ab8f96 | ||
|
SkalskiP
|
b476acc1f3 | ||
|
pre-commit-ci[bot]
|
3cee266f71 | ||
|
Piotr Skalski
|
111d4c6c91 | ||
|
LinasKo
|
a77a2ba8aa | ||
|
Piotr Skalski
|
fb9024bc75 | ||
|
LinasKo
|
ceecb8bbd7 | ||
|
SkalskiP
|
c28c93bd4f | ||
|
LinasKo
|
ca482967c4 | ||
|
LinasKo
|
57fa637eea | ||
|
Linas Kondrackis
|
59c5ab5252 | ||
|
LinasKo
|
c27a28235e | ||
|
Onuralp SEZER
|
cfbb6681cc | ||
|
dependabot[bot]
|
24b1db9e25 | ||
|
pre-commit-ci[bot]
|
8c92072ecd | ||
|
tc360950
|
38d442c176 | ||
|
Onuralp SEZER
|
2f09e51458 | ||
|
pre-commit-ci[bot]
|
56eb8e1698 | ||
|
LinasKo
|
5bfd51fdec | ||
|
LinasKo
|
a5d4612402 | ||
|
Onuralp SEZER
|
941b7e30aa | ||
|
Onuralp SEZER
|
f4f2626b44 | ||
|
dependabot[bot]
|
8f198e80cd | ||
|
dependabot[bot]
|
612ac6145a | ||
|
LinasKo
|
2b5d430382 | ||
|
LinasKo
|
b6ff9242fc | ||
|
LinasKo
|
d2f169bcfa | ||
|
Linas Kondrackis
|
33e10ff722 | ||
|
Linas Kondrackis
|
883a6bed3c | ||
|
Linas Kondrackis
|
f7bd7011fe | ||
|
Onuralp SEZER
|
6193128774 | ||
|
dependabot[bot]
|
bdc10f83fe | ||
|
tc360950
|
dc1249969f | ||
|
Linas Kondrackis
|
34353aac54 | ||
|
Linas Kondrackis
|
6ad32406af | ||
|
Linas Kondrackis
|
315c4295ff | ||
|
Linas Kondrackis
|
4dc001d9bf | ||
|
Linas Kondrackis
|
9d60b2009f | ||
|
Linas Kondrackis
|
c98698d442 | ||
|
Onuralp SEZER
|
3bda0bfc11 | ||
|
Onuralp SEZER
|
0e19c581e4 | ||
|
dependabot[bot]
|
8fb843ec8e | ||
|
dependabot[bot]
|
ba2b60ffb4 | ||
|
LinasKo
|
d59467b4f4 | ||
|
LinasKo
|
c0486b7f94 | ||
|
Linas Kondrackis
|
f24c6f38a0 | ||
|
Linas Kondrackis
|
a6c995c9a9 | ||
|
pre-commit-ci[bot]
|
3c3a0792f3 | ||
|
Linas Kondrackis
|
1d13397503 | ||
|
Linas Kondrackis
|
f0e88b1982 | ||
|
Onuralp SEZER
|
9bc2907c49 | ||
|
dependabot[bot]
|
e7dfc04fd3 | ||
|
Piotr Skalski
|
a0d0d45890 | ||
|
SkalskiP
|
4a365fb907 | ||
|
Onuralp SEZER
|
a60cfe08e2 | ||
|
pre-commit-ci[bot]
|
c1ebb81d47 | ||
|
Linas Kondrackis
|
2ee9e08446 | ||
|
Linas Kondrackis
|
530e1d01e1 | ||
|
tc360950
|
404be16126 | ||
|
tc360950
|
72d677ad89 | ||
|
tc360950
|
d6ae86e97b | ||
|
tc360950
|
ed5c26527a | ||
|
pre-commit-ci[bot]
|
d23cc008f8 | ||
|
tc360950
|
9d54d91791 | ||
|
tc360950
|
80feb2b12f | ||
|
tc360950
|
fb30bab0fd | ||
|
tc360950
|
a09b6fac6f | ||
|
tc360950
|
4e2eb0afc2 | ||
|
pre-commit-ci[bot]
|
1a021d5792 | ||
|
tc360950
|
909ae2a8ff | ||
|
tc360950
|
7d0488efc0 | ||
|
Piotr Skalski
|
2723735b01 | ||
|
Onuralp SEZER
|
7757d86abc | ||
|
Piotr Skalski
|
f40dd38b1a | ||
|
Piotr Skalski
|
ad7e643c83 | ||
|
Piotr Skalski
|
eae4040b17 | ||
|
dependabot[bot]
|
9afca17854 | ||
|
Linas Kondrackis
|
19296a73f6 | ||
|
Linas Kondrackis
|
0721bc289b | ||
|
pre-commit-ci[bot]
|
db1b4737fe | ||
|
Linas Kondrackis
|
6fbca8333e | ||
|
pre-commit-ci[bot]
|
ad2220bc1d | ||
|
SkalskiP
|
0115ef8b7d | ||
|
Onuralp SEZER
|
d4541e1469 | ||
|
Linas Kondrackis
|
c9c2dad316 | ||
|
Onuralp SEZER
|
e59e2822d8 | ||
|
Linas Kondrackis
|
99854a5b66 | ||
|
Onuralp SEZER
|
251185ba67 | ||
|
Linas Kondrackis
|
8b4884ec9e | ||
|
SkalskiP
|
07c36c6223 | ||
|
pre-commit-ci[bot]
|
bf43d6566b | ||
|
SkalskiP
|
b59d17fdae | ||
|
SkalskiP
|
b81c5e8475 | ||
|
pre-commit-ci[bot]
|
7eb918282c | ||
|
SkalskiP
|
36a73f7d49 | ||
|
SkalskiP
|
a2195aa378 | ||
|
Onuralp SEZER
|
2bd4348e5d | ||
|
dependabot[bot]
|
6b7861d4d1 | ||
|
pre-commit-ci[bot]
|
8a2f5d4726 | ||
|
tc360950
|
dcfa916c75 | ||
|
pre-commit-ci[bot]
|
54a0422b58 | ||
|
tc360950
|
089916e26f | ||
|
Piotr Skalski
|
1bbe03ca27 | ||
|
pre-commit-ci[bot]
|
5840889818 | ||
|
SkalskiP
|
c3855c9828 | ||
|
Linas Kondrackis
|
40b537c0be | ||
|
SkalskiP
|
1d43042c55 | ||
|
pre-commit-ci[bot]
|
996b0a3af3 | ||
|
SkalskiP
|
f2716252d5 | ||
|
Linas Kondrackis
|
b916dc547c | ||
|
Linas Kondrackis
|
e1be566861 | ||
|
dependabot[bot]
|
32f773548e | ||
|
dependabot[bot]
|
414d3e9afb | ||
|
magda skoczen
|
6dbf3f61e3 | ||
|
pre-commit-ci[bot]
|
ab55e81087 | ||
|
magda_sk
|
7b42d8381b | ||
|
magda skoczen
|
dfac30cba7 | ||
|
magda skoczen
|
c26eb1a70f | ||
|
magda skoczen
|
f0fc76c8c7 | ||
|
magda skoczen
|
68f07e18f3 | ||
|
pre-commit-ci[bot]
|
7ee84c48e0 | ||
|
magda skoczen
|
179d00bead | ||
|
magda skoczen
|
2626263ff3 | ||
|
magda skoczen
|
a40bf78bb2 | ||
|
tc360950
|
41ca70aab6 | ||
|
Linas Kondrackis
|
3fbce7b6bb | ||
|
dependabot[bot]
|
b761a5c32b | ||
|
tc360950
|
12a455eafa | ||
|
pre-commit-ci[bot]
|
6c9f8302a5 | ||
|
tc360950
|
da904ad2da | ||
|
pre-commit-ci[bot]
|
8d432c78b1 | ||
|
magda skoczen
|
0cd2c9d146 | ||
|
magda skoczen
|
aad5e2a212 | ||
|
Linas Kondrackis
|
ab775d9f76 | ||
|
Onuralp SEZER
|
1779014fd9 | ||
|
Onuralp SEZER
|
84d8d98619 | ||
|
magda skoczen
|
879ae9416a | ||
|
Linas Kondrackis
|
9024396f6c | ||
|
Linas Kondrackis
|
de5349ad6d | ||
|
Linas Kondrackis
|
d391376912 | ||
|
dependabot[bot]
|
eb84d41c61 | ||
|
dependabot[bot]
|
0252cf210c | ||
|
pre-commit-ci[bot]
|
b3b745508b | ||
|
magda skoczen
|
511f0ab9b2 | ||
|
magda skoczen
|
3ee72e38c3 | ||
|
Piotr Skalski
|
5acfb9531e | ||
|
Linas Kondrackis
|
2c769e2f72 | ||
|
pre-commit-ci[bot]
|
ce05a0c544 | ||
|
magda skoczen
|
1e8ee47db2 | ||
|
pre-commit-ci[bot]
|
eefa05cf01 | ||
|
magda skoczen
|
d8679d9c46 | ||
|
Onuralp SEZER
|
25ceb46ed4 | ||
|
dependabot[bot]
|
a615dfccb6 | ||
|
Onuralp SEZER
|
1776bf1670 | ||
|
pre-commit-ci[bot]
|
d983177c3a | ||
|
Onuralp SEZER
|
7b259145bb | ||
|
Onuralp SEZER
|
24d1840ea1 | ||
|
Linas Kondrackis
|
f8f3647a98 | ||
|
Linas Kondrackis
|
559ef90d83 | ||
|
Linas Kondrackis
|
0e2eec08c8 | ||
|
Linas Kondrackis
|
53f345e916 | ||
|
Linas Kondrackis
|
6c40935266 | ||
|
Linas Kondrackis
|
145b5fe56c | ||
|
Onuralp SEZER
|
aed9221307 | ||
|
pre-commit-ci[bot]
|
f08404eb7d | ||
|
magda skoczen
|
aab861c2db | ||
|
Christoforos Aristeidou
|
9c0d647fdf | ||
|
Christoforos Aristeidou
|
5ef934e780 | ||
|
Linas Kondrackis
|
2d740bdcb6 | ||
|
Linas Kondrackis
|
d2d50fbe46 | ||
|
Linas Kondrackis
|
26bafec8f7 | ||
|
Linas Kondrackis
|
8014e88944 | ||
|
Linas Kondrackis
|
c3b77d05c0 | ||
|
LinasKo
|
2eb0c7c242 | ||
|
Onuralp SEZER
|
41a08b87be | ||
|
pre-commit-ci[bot]
|
2bcd81e5fd | ||
|
SkalskiP
|
19396771f1 | ||
|
Onuralp SEZER
|
f5324897a3 | ||
|
Piotr Skalski
|
cd8a2be04b | ||
|
Linas Kondrackis
|
8901192b92 | ||
|
Linas Kondrackis
|
a9044e4fed | ||
|
Linas Kondrackis
|
85e4c0ec65 | ||
|
Linas Kondrackis
|
93398108ee | ||
|
Piotr Skalski
|
f41adca384 | ||
|
SkalskiP
|
d64bb3879c | ||
|
SkalskiP
|
452e1f1ea4 | ||
|
Linas Kondrackis
|
45e5f49c5a | ||
|
LinasKo
|
4c36b39f94 | ||
|
pre-commit-ci[bot]
|
e13c7dc22c | ||
|
SkalskiP
|
713719a582 | ||
|
SkalskiP
|
051fe5178b | ||
|
pre-commit-ci[bot]
|
1ebccebf4c | ||
|
SkalskiP
|
f56d7a1733 | ||
|
LinasKo
|
82ab6c57cb | ||
|
pre-commit-ci[bot]
|
cccacab621 | ||
|
SkalskiP
|
59b273ba87 | ||
|
pre-commit-ci[bot]
|
9a1c11218c | ||
|
SkalskiP
|
d21c98a4d2 | ||
|
Linas Kondrackis
|
816aecb51b | ||
|
dependabot[bot]
|
3c8995758d | ||
|
pre-commit-ci[bot]
|
14b57345a7 | ||
|
magda skoczen
|
d292cbf80e | ||
|
magda skoczen
|
8c857dd9a6 | ||
|
Onuralp SEZER
|
acfabc247f | ||
|
Onuralp SEZER
|
61a63c83d9 | ||
|
Linas Kondrackis
|
528c960587 | ||
|
Linas Kondrackis
|
6c6171b5d5 | ||
|
Linas Kondrackis
|
b8efa25e93 | ||
|
SkalskiP
|
17c8e41fb3 | ||
|
Piotr Skalski
|
0c3594432c | ||
|
SkalskiP
|
a8c44cfaff | ||
|
pre-commit-ci[bot]
|
3d0c3d9182 | ||
|
SkalskiP
|
2364abf481 | ||
|
pre-commit-ci[bot]
|
7bd92b096f | ||
|
magda skoczen
|
39477feaf6 | ||
|
magda skoczen
|
e4e66f8a9a | ||
|
dependabot[bot]
|
3b61ee674e | ||
|
Linas Kondrackis
|
01f7eb5be6 | ||
|
pre-commit-ci[bot]
|
4cd1fbcef9 | ||
|
Linas Kondrackis
|
b6a55694f2 | ||
|
Linas Kondrackis
|
8c58ebe30d | ||
|
Piotr Skalski
|
77034700dd | ||
|
Linas Kondrackis
|
1ebbe3a8d1 | ||
|
Onuralp SEZER
|
617bd30c5f | ||
|
Onuralp SEZER
|
2e8720f156 | ||
|
Raif Olson
|
c47b0ce990 | ||
|
Linas Kondrackis
|
45563dfddf | ||
|
pre-commit-ci[bot]
|
008711aac4 | ||
|
magda skoczen
|
649e27323d | ||
|
pre-commit-ci[bot]
|
36a301e7fc | ||
|
magda skoczen
|
aac1d8862a | ||
|
pre-commit-ci[bot]
|
d59ec0f223 | ||
|
magda skoczen
|
3618ac35ec | ||
|
magda skoczen
|
a9f821c28a | ||
|
Linas Kondrackis
|
7bb94ce966 | ||
|
Linas Kondrackis
|
fb49be8197 | ||
|
Piotr Skalski
|
d7b6af84e6 | ||
|
Piotr Skalski
|
d3b845fea5 | ||
|
Piotr Skalski
|
330eae4411 | ||
|
pre-commit-ci[bot]
|
6b5dacd8e3 | ||
|
magda skoczen
|
88a43cc795 | ||
|
pre-commit-ci[bot]
|
a941583bb0 | ||
|
magda skoczen
|
2727152465 | ||
|
dependabot[bot]
|
4d25437459 | ||
|
magda skoczen
|
3ade7f060a | ||
|
magda skoczen
|
18a790e9ea | ||
|
pre-commit-ci[bot]
|
478fbd5751 | ||
|
pre-commit-ci[bot]
|
7823e0de89 | ||
|
SkalskiP
|
ab0882dd55 | ||
|
SkalskiP
|
ec6864ff04 | ||
|
SkalskiP
|
81786ff9d3 | ||
|
SkalskiP
|
95c243c058 | ||
|
pre-commit-ci[bot]
|
204669b08c | ||
|
Linas Kondrackis
|
97c407101a | ||
|
pre-commit-ci[bot]
|
bee3252110 | ||
|
Linas Kondrackis
|
d7e52bee26 | ||
|
Linas Kondrackis
|
b1598733c2 | ||
|
pre-commit-ci[bot]
|
5c539c3bda | ||
|
SkalskiP
|
5d38120743 | ||
|
Manzar Iqbal Malik
|
aaf5df2f6a | ||
|
Onuralp SEZER
|
447ef41fc4 | ||
|
dependabot[bot]
|
edd944fff8 | ||
|
Onuralp SEZER
|
a75efbbf73 | ||
|
Onuralp SEZER
|
e9c8a80823 | ||
|
Onuralp SEZER
|
0b92417948 | ||
|
dependabot[bot]
|
aebbd01830 | ||
|
Onuralp SEZER
|
c3ebccabe8 | ||
|
dependabot[bot]
|
ff52352b00 | ||
|
dependabot[bot]
|
f7d21acd3a | ||
|
dependabot[bot]
|
92d56eda15 | ||
|
tc360950
|
d37a5f90a4 | ||
|
pre-commit-ci[bot]
|
869204d42d | ||
|
magda skoczen
|
dc1ce02860 | ||
|
Onuralp SEZER
|
34a5b34c88 | ||
|
dependabot[bot]
|
f72d06b05e | ||
|
magda skoczen
|
4a068ff8d7 | ||
|
Onuralp SEZER
|
044a8fac06 | ||
|
Onuralp SEZER
|
a88089ced7 | ||
|
dependabot[bot]
|
29b0c514cf | ||
|
dependabot[bot]
|
7d5a0bce45 | ||
|
magda skoczen
|
6913ecf54d | ||
|
magda skoczen
|
7f114cba4c | ||
|
magda skoczen
|
cc5e72dd5b | ||
|
Piotr Skalski
|
177ab6ad4d | ||
|
pre-commit-ci[bot]
|
7e79fa3d07 | ||
|
Linas Kondrackis
|
347b75935b | ||
|
Linas Kondrackis
|
079008cd17 | ||
|
magda skoczen
|
e30d4a9abb | ||
|
pre-commit-ci[bot]
|
aab3ed2ba9 | ||
|
Linas Kondrackis
|
ba30244add | ||
|
Onuralp SEZER
|
55e8f16029 | ||
|
dependabot[bot]
|
33e69b2da3 | ||
|
Piotr Skalski
|
9fe3170ead | ||
|
SkalskiP
|
ffda94b1e5 | ||
|
SkalskiP
|
7fd5d80a3b | ||
|
Onuralp SEZER
|
b67d9b475f | ||
|
Onuralp SEZER
|
d859842fa3 | ||
|
Onuralp SEZER
|
131c6ffefb | ||
|
dependabot[bot]
|
71fd3178cc | ||
|
dependabot[bot]
|
71919f1d6f | ||
|
SkalskiP
|
4732b6f1d0 | ||
|
Piotr Skalski
|
c024b62020 | ||
|
SkalskiP
|
d4b1375db7 | ||
|
Piotr Skalski
|
71200a5942 | ||
|
SkalskiP
|
66f6a86bbf | ||
|
SkalskiP
|
a70588284a | ||
|
pre-commit-ci[bot]
|
67160c96b0 | ||
|
LinasKo
|
7331577e69 | ||
|
Onuralp SEZER
|
5f00d8b595 | ||
|
Onuralp SEZER
|
88209f233d | ||
|
Onuralp SEZER
|
d51067164a | ||
|
pre-commit-ci[bot]
|
0dd8d7dca8 | ||
|
Linas Kondrackis
|
7c39d9dc8d | ||
|
Linas Kondrackis
|
d2d69f986e | ||
|
dependabot[bot]
|
df0b2df2f6 | ||
|
dependabot[bot]
|
31844c165b | ||
|
dependabot[bot]
|
c5a2f87bb9 | ||
|
Piotr Skalski
|
6ef9ba7390 | ||
|
SkalskiP
|
a532670611 | ||
|
SkalskiP
|
ba2d30d110 | ||
|
Linas Kondrackis
|
619da9575a | ||
|
LinasKo
|
25bdb560eb | ||
|
Onuralp SEZER
|
9b447296bf | ||
|
Onuralp SEZER
|
4a16d66bfb | ||
|
dependabot[bot]
|
8436f52f8a | ||
|
dependabot[bot]
|
059583e2ba | ||
|
pre-commit-ci[bot]
|
4bd593fe3c | ||
|
Linas Kondrackis
|
399342513a | ||
|
Linas Kondrackis
|
c8c2ff5c45 | ||
|
Linas Kondrackis
|
18b3c17ed4 | ||
|
Linas Kondrackis
|
cab06f2c2b | ||
|
Onuralp SEZER
|
2b53216a0b | ||
|
dependabot[bot]
|
e253f86e8f | ||
|
Piotr Skalski
|
df4c546c10 | ||
|
Piotr Skalski
|
25fc1ab6fa | ||
|
SkalskiP
|
a45341ce63 | ||
|
Piotr Skalski
|
e93ef041d4 | ||
|
Piotr Skalski
|
f7f40f09ba | ||
|
Piotr Skalski
|
c5f92a544b | ||
|
SkalskiP
|
d6a59cb851 | ||
|
SkalskiP
|
5c4ed2650e | ||
|
pre-commit-ci[bot]
|
6ae99444b5 | ||
|
SkalskiP
|
7a90eefd5b | ||
|
SkalskiP
|
65ddf9d67d | ||
|
Piotr Skalski
|
b0840911fc | ||
|
pre-commit-ci[bot]
|
f4fca3339d | ||
|
SkalskiP
|
d7da00c55b | ||
|
pre-commit-ci[bot]
|
383c1a1d8d | ||
|
SkalskiP
|
e5d1ac7238 | ||
|
SkalskiP
|
895562d444 | ||
|
pre-commit-ci[bot]
|
263420758e | ||
|
SkalskiP
|
1c42838ca1 | ||
|
SkalskiP
|
908f3d14c6 | ||
|
SkalskiP
|
389453777e | ||
|
SkalskiP
|
77793571b0 | ||
|
Linas Kondrackis
|
48809c1332 | ||
|
Piotr Skalski
|
2c90a1ef1e | ||
|
Linas Kondrackis
|
4b89bece4f | ||
|
Piotr Skalski
|
80e5413402 | ||
|
Linas Kondrackis
|
741309fd09 | ||
|
pre-commit-ci[bot]
|
08d7a6b4cd | ||
|
Linas Kondrackis
|
d1c103ee16 | ||
|
pre-commit-ci[bot]
|
0f6ad236eb | ||
|
Linas Kondrackis
|
1c27bf7fea | ||
|
pre-commit-ci[bot]
|
0749efed8f | ||
|
Linas Kondrackis
|
d8681b8b4f | ||
|
pre-commit-ci[bot]
|
9ad35bcfb9 | ||
|
SkalskiP
|
102c5adc38 | ||
|
SkalskiP
|
a2dbbcce63 | ||
|
SkalskiP
|
397b2249a7 | ||
|
pre-commit-ci[bot]
|
e2865ecda7 | ||
|
SkalskiP
|
0ff1cfac07 | ||
|
SkalskiP
|
2745c70ae0 | ||
|
pre-commit-ci[bot]
|
e2fabc1cfe | ||
|
SkalskiP
|
a8d5e05885 | ||
|
SkalskiP
|
9789ff4043 | ||
|
SkalskiP
|
0274c45dbc | ||
|
SkalskiP
|
6a541845ba | ||
|
pre-commit-ci[bot]
|
409dcbd9da | ||
|
Linas Kondrackis
|
07482a347c | ||
|
Linas Kondrackis
|
7f0ecbbd0a | ||
|
Linas Kondrackis
|
a00604bfb2 | ||
|
Linas Kondrackis
|
d079ce92df | ||
|
Linas Kondrackis
|
a6b563cf4d | ||
|
Onuralp SEZER
|
7c2aad194a | ||
|
pre-commit-ci[bot]
|
feae6d3f78 | ||
|
Onuralp SEZER
|
4ebace283c | ||
|
dependabot[bot]
|
98493c2ae1 | ||
|
Onuralp SEZER
|
8b32815648 | ||
|
dependabot[bot]
|
a1a66e7078 | ||
|
Onuralp SEZER
|
fd4ef9960a | ||
|
Onuralp SEZER
|
6c54da2afa | ||
|
dependabot[bot]
|
53eb76922d | ||
|
dependabot[bot]
|
b3f022b15a | ||
|
Onuralp SEZER
|
91e03ce903 | ||
|
pre-commit-ci[bot]
|
2af86e56f0 | ||
|
Onuralp SEZER
|
af0ece26d7 | ||
|
dependabot[bot]
|
77d3276ad6 | ||
|
Jeslin P James
|
df4a6f857c | ||
|
pre-commit-ci[bot]
|
cb220479eb | ||
|
Jeslin P James
|
8bb8ce0316 | ||
|
Jeslin P James
|
8255bcb1ca | ||
|
Jeslin P James
|
8329d155e4 | ||
|
Jeslin P James
|
a41eea7c45 | ||
|
pre-commit-ci[bot]
|
d531c59f85 | ||
|
Jeslin P James
|
15b1473c2f | ||
|
Jeslin P James
|
26c2a7ef9c | ||
|
Piotr Skalski
|
c8d2a54ed8 | ||
|
Onuralp SEZER
|
9d9acd7e58 | ||
|
Piotr Skalski
|
f9ed80f91b | ||
|
SkalskiP
|
dfd9fc8e6d | ||
|
SkalskiP
|
2c62f0b26d | ||
|
SkalskiP
|
0ad3796571 | ||
|
Onuralp SEZER
|
da236aa565 | ||
|
Jeslin P James
|
0800b0569f | ||
|
Jeslin P James
|
510df54572 | ||
|
dependabot[bot]
|
89d84d1f74 | ||
|
dependabot[bot]
|
7126adc74a | ||
|
pre-commit-ci[bot]
|
743e42080b | ||
|
Jeslin P James
|
b64c61c388 | ||
|
Jeslin P James
|
28baf18cb6 | ||
|
pre-commit-ci[bot]
|
361e444f53 | ||
|
Jeslin P James
|
b7607c6f15 | ||
|
Raif Olson
|
07756328db | ||
|
Raif Olson
|
f98ded49a2 | ||
|
pre-commit-ci[bot]
|
bcb31f8809 | ||
|
Raif Olson
|
b1d5d4faf0 | ||
|
Piotr Skalski
|
d3dbe7c597 | ||
|
Piotr Skalski
|
9284bfdcd9 | ||
|
Piotr Skalski
|
263421d145 | ||
|
Raif Olson
|
7924a13dc5 | ||
|
pre-commit-ci[bot]
|
755f292ed1 | ||
|
Raif Olson
|
6166d92458 | ||
|
Piotr Skalski
|
ed225187b2 | ||
|
mario-dg
|
166a8da9a0 | ||
|
pre-commit-ci[bot]
|
2c9a1f69c5 | ||
|
pre-commit-ci[bot]
|
a2ab113f21 | ||
|
Raif Olson
|
eaff97f902 | ||
|
Onuralp SEZER
|
855f9191c5 | ||
|
Linas Kondrackis
|
98b64f5e7d | ||
|
Onuralp SEZER
|
048d1a8b98 | ||
|
dependabot[bot]
|
2fd5452181 | ||
|
Piotr Skalski
|
10843c9989 | ||
|
SkalskiP
|
eb1c7716ef | ||
|
pre-commit-ci[bot]
|
c27d9eaf22 | ||
|
SkalskiP
|
5eb43a25c9 | ||
|
SkalskiP
|
e0d5f00ae3 | ||
|
pre-commit-ci[bot]
|
99fbd4b601 | ||
|
SkalskiP
|
d155592f45 | ||
|
SkalskiP
|
d929d6f58b | ||
|
pre-commit-ci[bot]
|
6248fa7d17 | ||
|
SkalskiP
|
7ad50cc7c2 | ||
|
SkalskiP
|
c30e377eb5 | ||
|
pre-commit-ci[bot]
|
f872fddaff | ||
|
SkalskiP
|
079e62fb0c | ||
|
mario-dg
|
5f0dcc2cb2 | ||
|
Jeslin P James
|
9e906c78f5 | ||
|
SkalskiP
|
774ac2ed4f | ||
|
pre-commit-ci[bot]
|
a7dccfcc0d | ||
|
Onuralp SEZER
|
15a4555b6a | ||
|
SkalskiP
|
233d25d4c5 | ||
|
Jeslin P James
|
2417b36006 | ||
|
pre-commit-ci[bot]
|
ad94689362 | ||
|
SkalskiP
|
94e06ab0d6 | ||
|
Onuralp SEZER
|
b63379749e | ||
|
Onuralp SEZER
|
5d43e1380d | ||
|
Onuralp SEZER
|
7d0cf8a723 | ||
|
pre-commit-ci[bot]
|
f2e6d882fb | ||
|
SkalskiP
|
2115c9a152 | ||
|
pre-commit-ci[bot]
|
5b1ee8f870 | ||
|
SkalskiP
|
574c61b6b0 | ||
|
Jeslin P James
|
1a7309e7c9 | ||
|
pre-commit-ci[bot]
|
6b682f00ae | ||
|
Onuralp SEZER
|
4729e20a94 | ||
|
dependabot[bot]
|
b5ccc99537 | ||
|
Onuralp SEZER
|
922ebb237a | ||
|
Jonas Pirner
|
0ae2c1206f | ||
|
Piotr Skalski
|
372e703a7a | ||
|
pre-commit-ci[bot]
|
0a919db9fd | ||
|
SkalskiP
|
473f140133 | ||
|
pre-commit-ci[bot]
|
e93224570f | ||
|
SkalskiP
|
5e9c3fdfa5 | ||
|
Paweł Pęczek
|
b76f864f70 | ||
|
SkalskiP
|
c9095881ae | ||
|
Piotr Skalski
|
299c933c4c | ||
|
Piotr Skalski
|
9ae69c71d9 | ||
|
Piotr Skalski
|
a60884d94f | ||
|
SkalskiP
|
e2f1d5812e | ||
|
pre-commit-ci[bot]
|
dd7fddb4f5 | ||
|
SkalskiP
|
ee38ba36c4 | ||
|
macc-n
|
79da48fc49 | ||
|
pre-commit-ci[bot]
|
7e21aaaa1a | ||
|
sharingan000
|
57335ef986 | ||
|
sharingan000
|
c605687f82 | ||
|
sharingan000
|
6001e4033e | ||
|
sharingan000
|
761fb89241 | ||
|
pre-commit-ci[bot]
|
5f0082048c | ||
|
sharingan000
|
0b86478417 | ||
|
macc-n
|
c8ea42af6d | ||
|
sharingan000
|
40200ddd8d | ||
|
pre-commit-ci[bot]
|
8de73738c7 | ||
|
sharingan000
|
0cf31d7e55 | ||
|
sharingan000
|
eb3317694e | ||
|
pre-commit-ci[bot]
|
960e2529b1 | ||
|
sharingan000
|
b7d18681b1 | ||
|
sharingan000
|
cd81c1cef4 | ||
|
Onuralp SEZER
|
fe1e0d9bec | ||
|
Onuralp SEZER
|
275c7c6cc3 | ||
|
dependabot[bot]
|
79c731b431 | ||
|
dependabot[bot]
|
f15a6224ff | ||
|
jeslinpjames
|
b6b72eddce | ||
|
jeslinpjames
|
b02e8664a1 | ||
|
jeslinpjames
|
c7a0f62dea | ||
|
pre-commit-ci[bot]
|
dcad812c5c | ||
|
sharingan000
|
7ded0bd493 | ||
|
sharingan000
|
a38ae3f840 | ||
|
Onuralp SEZER
|
175dd7d0f5 | ||
|
Onuralp SEZER
|
173a5d63a2 | ||
|
dependabot[bot]
|
f21597446b | ||
|
dependabot[bot]
|
da5dfef2ed | ||
|
Onuralp SEZER
|
03803a7d7e | ||
|
dependabot[bot]
|
cbc5aa49f5 | ||
|
Onuralp SEZER
|
8fc5413394 | ||
|
Raif Olson
|
ad0e6c3b51 | ||
|
Onuralp SEZER
|
b5250105e0 | ||
|
dependabot[bot]
|
90ad1c2c9a | ||
|
jeslinpjames
|
7dedc452b7 | ||
|
jeslinpjames
|
767f9a7148 | ||
|
jeslinpjames
|
e6a1d58500 | ||
|
jeslinpjames
|
a8988d1d4d | ||
|
jeslinpjames
|
42a4ed4166 | ||
|
Piotr Skalski
|
f4f9b3d53a | ||
|
pre-commit-ci[bot]
|
719af725b1 | ||
|
SkalskiP
|
e88ab7c125 | ||
|
Piotr Skalski
|
77e38ba93b | ||
|
SkalskiP
|
68e1bae6de | ||
|
SkalskiP
|
afc31e42a5 | ||
|
pre-commit-ci[bot]
|
0c7c746f15 | ||
|
SkalskiP
|
4ad78becb6 | ||
|
Onuralp SEZER
|
f9fd88fb01 | ||
|
SkalskiP
|
ccc7118bcb | ||
|
Piotr Skalski
|
2cccfc5b62 | ||
|
Onuralp SEZER
|
93584cbb89 | ||
|
Piotr Skalski
|
5bfc977fac | ||
|
Piotr Skalski
|
16c41d9d5d | ||
|
SkalskiP
|
81c2a09430 | ||
|
Piotr Skalski
|
16b7222012 | ||
|
Piotr Skalski
|
6b2136d57b | ||
|
Piotr Skalski
|
908a1b4d89 | ||
|
Onuralp SEZER
|
7e283d4eeb | ||
|
Raif Olson
|
a2aca62ecb | ||
|
Onuralp SEZER
|
0a5fb7b47e | ||
|
Piotr Skalski
|
7132c034ab | ||
|
pre-commit-ci[bot]
|
dc5f841bae | ||
|
SkalskiP
|
64eef66b54 | ||
|
Raif Olson
|
dc45c0a5e0 | ||
|
Piotr Skalski
|
69563b8bbb | ||
|
pre-commit-ci[bot]
|
29ba24f89a | ||
|
Raif Olson
|
da4404e875 | ||
|
Raif Olson
|
089594f72d | ||
|
pre-commit-ci[bot]
|
e9edc2fb1d | ||
|
Raif Olson
|
ad24d3811b | ||
|
dependabot[bot]
|
8fb3ba70b0 | ||
|
SkalskiP
|
34b80eb3c0 | ||
|
Piotr Skalski
|
3276973446 | ||
|
Piotr Skalskiandpre-commit-ci[bot]
|
725d95c6ce | ||
|
pre-commit-ci[bot]
|
13f85ae6cc | ||
|
Griffin-Sullivan
|
c67078b53c | ||
|
Piotr Skalski
|
42f9d4b69b | ||
|
Onuralp SEZER
|
d41caed36f | ||
|
SkalskiP
|
5a040969d7 | ||
|
Raif Olson
|
3ed4aeffff | ||
|
pre-commit-ci[bot]
|
c56c446eb6 | ||
|
jeslinpjames
|
8a06de47e9 | ||
|
jeslinpjames
|
a51267a4fa | ||
|
Onuralp SEZER
|
97b8312570 | ||
|
Piotr Skalski
|
94e9719f20 | ||
|
SkalskiP
|
0d16b13e7a | ||
|
Piotr Skalski
|
5c03173c7c | ||
|
pre-commit-ci[bot]
|
cf88cc0384 | ||
|
SkalskiP
|
15e17adef1 | ||
|
pre-commit-ci[bot]
|
8694f0023d | ||
|
jeslinpjames
|
b2b417af5b | ||
|
Paweł Pęczek
|
0aacfa47d3 | ||
|
Paweł Pęczek
|
de8222203c | ||
|
pre-commit-ci[bot]
|
ca425a628d | ||
|
Piotr Skalski
|
09a47bec62 | ||
|
pre-commit-ci[bot]
|
90f6893d3d | ||
|
SkalskiP
|
b585bb0724 | ||
|
Piotr Skalski
|
495f9a9003 | ||
|
Paweł Pęczek
|
4adb2339a4 | ||
|
Paweł Pęczek
|
444853054f | ||
|
Piotr Skalski
|
4a6a6dbf6b | ||
|
Paweł Pęczek
|
4bb711dcea | ||
|
SkalskiP
|
fec251d979 | ||
|
SkalskiP
|
6d27b8067b | ||
|
Onuralp SEZER
|
3da0ca4ffc | ||
|
Onuralp SEZER
|
fc03b0c386 | ||
|
pre-commit-ci[bot]
|
4660dfd0d3 | ||
|
SkalskiP
|
e7b4d6ec41 | ||
|
pre-commit-ci[bot]
|
bc586562b5 | ||
|
SkalskiP
|
57c6182325 | ||
|
dependabot[bot]
|
c3b617d47e | ||
|
dependabot[bot]
|
6458d4454d | ||
|
Christoforos Aristeidou
|
957ced0614 | ||
|
Christoforos Aristeidou
|
ed3c73eb02 | ||
|
Christoforos Aristeidou
|
3e4ddd5bd9 | ||
|
Christoforos Aristeidou
|
1fbdec6046 | ||
|
Raif Olson
|
1eb877c4d9 | ||
|
Onuralp SEZER
|
781a064d8a | ||
|
dependabot[bot]
|
70218b85e7 | ||
|
Onuralp SEZER
|
37318fafdf | ||
|
dependabot[bot]
|
f377a992e1 | ||
|
Paweł Pęczek
|
7eba338243 | ||
|
Piotr Skalski
|
6208013dcf | ||
|
SkalskiP
|
8a2abe72ae | ||
|
Piotr Skalski
|
d01b636ebe | ||
|
Onuralp SEZER
|
0e3e41287a | ||
|
Onuralp SEZER
|
5f9560afb8 | ||
|
pre-commit-ci[bot]
|
4abd128af5 | ||
|
Piotr Skalski
|
77908fe49b | ||
|
Onuralp SEZER
|
fb3a78f762 | ||
|
Onuralp SEZER
|
f43b3536be | ||
|
dependabot[bot]
|
345c086916 | ||
|
dependabot[bot]
|
123a61f2c6 | ||
|
Onuralp SEZER
|
63b338751f | ||
|
Onuralp SEZER
|
e8810fe8a2 | ||
|
Piotr Skalski
|
3d9d45fc07 | ||
|
Onuralp SEZER
|
4f9e5a590f | ||
|
pre-commit-ci[bot]
|
9f5c63b32d | ||
|
SkalskiP
|
a5b1079e39 | ||
|
Piotr Skalski
|
88d63473fe | ||
|
Piotr Skalski
|
55f93a85b6 | ||
|
SkalskiP
|
a0f7bb76bd | ||
|
Piotr Skalski
|
7e72ad13f7 | ||
|
Piotr Skalski
|
5b6713f197 | ||
|
SkalskiP
|
8d7f18cc22 | ||
|
Onuralp SEZER
|
012ff2bbe2 | ||
|
dependabot[bot]
|
594c9958a4 | ||
|
Onuralp SEZER
|
917b4c0fe4 | ||
|
Piotr Skalski
|
d669619f2d | ||
|
SkalskiP
|
22d97b8a46 | ||
|
SkalskiP
|
0c04647d00 | ||
|
pre-commit-ci[bot]
|
d6589443d7 | ||
|
SkalskiP
|
4ba3780d86 | ||
|
pre-commit-ci[bot]
|
d1003d420c | ||
|
SkalskiP
|
c7a6b38275 | ||
|
Onuralp SEZER
|
0d352bde92 | ||
|
Onuralp SEZER
|
4a6c0a9fa3 | ||
|
Onuralp SEZER
|
423783a8ff | ||
|
Piotr Skalski
|
162a4828e8 | ||
|
Piotr Skalski
|
0b810817e3 | ||
|
SkalskiP
|
6ade84f057 | ||
|
Piotr Skalski
|
655e5a7709 | ||
|
pre-commit-ci[bot]
|
dfb52633dc | ||
|
SkalskiP
|
bc74e1c366 | ||
|
pre-commit-ci[bot]
|
aacad59fd9 | ||
|
SkalskiP
|
879d48048c | ||
|
Onuralp SEZER
|
c0c346b04b | ||
|
pre-commit-ci[bot]
|
8ea1148f75 | ||
|
pre-commit-ci[bot]
|
2c55d1796f | ||
|
Onuralp SEZER
|
b68e7c2059 | ||
|
dependabot[bot]
|
4c426f5e82 | ||
|
Onuralp SEZER
|
fb82d32355 | ||
|
Onuralp SEZER
|
fd6cf36685 | ||
|
Onuralp SEZER
|
f41781015e | ||
|
dependabot[bot]
|
b85222690b | ||
|
dependabot[bot]
|
8ef3c0eb00 | ||
|
dependabot[bot]
|
645a1ec7af | ||
|
Piotr Skalski
|
cadb259214 | ||
|
James
|
26de63a09a | ||
|
Onuralp SEZER
|
b38234babe | ||
|
Onuralp SEZER
|
26201862f1 | ||
|
dependabot[bot]
|
c6f0b5753a | ||
|
Onuralp SEZER
|
427c91baa6 | ||
|
dependabot[bot]
|
dc39852a5b | ||
|
dependabot[bot]
|
52a059ffd9 | ||
|
Onuralp SEZER
|
8900986775 | ||
|
Piotr Skalski
|
4abef15069 | ||
|
dependabot[bot]
|
f1e596a058 | ||
|
Onuralp SEZER
|
cd20887d26 | ||
|
dependabot[bot]
|
e1a950f691 | ||
|
Onuralp SEZER
|
b0a64751d0 | ||
|
dependabot[bot]
|
34648871ab | ||
|
Onuralp SEZER
|
823adb3867 | ||
|
Onuralp SEZER
|
56825423dc | ||
|
Onuralp SEZER
|
e86fc592c7 | ||
|
Onuralp SEZER
|
3e05057ee4 | ||
|
dependabot[bot]
|
a3e39bdb6f | ||
|
dependabot[bot]
|
199d26aa72 | ||
|
Onuralp SEZER
|
ed3c6d1fbd | ||
|
dependabot[bot]
|
f29bdec62e | ||
|
Onuralp SEZER
|
f55ef90716 | ||
|
Adonai Vera
|
d9496316bc | ||
|
Adonai Vera
|
4509608a5d | ||
|
Piotr Skalski
|
6eeb1c4ae3 | ||
|
Onuralp SEZER
|
4803ab26e5 | ||
|
Onuralp SEZER
|
852d518d7c | ||
|
Onuralp SEZER
|
b78b3913fc | ||
|
Onuralp SEZER
|
2407fad07e | ||
|
SkalskiP
|
73013d6e47 | ||
|
Onuralp SEZER
|
41c78cceed | ||
|
Onuralp SEZER
|
ce3356287e | ||
|
SkalskiP
|
0aff293841 | ||
|
Onuralp SEZER
|
b13e3e0b8e | ||
|
Onuralp SEZER
|
18085340e2 | ||
|
Onuralp SEZER
|
7d65a9445a | ||
|
Onuralp SEZER
|
a68e5b4a6d | ||
|
Onuralp SEZER
|
d3383fc02f | ||
|
Piotr Skalski
|
6613f57a81 | ||
|
Onuralp SEZER
|
00c84d4530 | ||
|
Onuralp SEZER
|
cefd9e100c | ||
|
Piotr Skalski
|
07763bb2d0 | ||
|
Piotr Skalski
|
af03010a07 | ||
|
pre-commit-ci[bot]
|
f12182b016 | ||
|
SkalskiP
|
25deda23f2 | ||
|
Onuralp SEZER
|
a790040c84 | ||
|
Onuralp SEZER
|
d0ad5fe1d4 | ||
|
Piotr Skalski
|
0c0685987a | ||
|
Onuralp SEZER
|
5f85339851 | ||
|
Piotr Skalski
|
13cb923541 | ||
|
Linas Kondrackis
|
5e1d9bbd40 | ||
|
James
|
cb8f4af8bf | ||
|
Onuralp SEZER
|
165ed424bf | ||
|
Onuralp SEZER
|
96225cda0c | ||
|
Piotr Skalski
|
c039a90053 | ||
|
PacificDou
|
d9ccbda0a2 | ||
|
PacificDou
|
49d4a4a9fd | ||
|
Onuralp SEZER
|
97c01aa1a7 | ||
|
dependabot[bot]
|
3f9f87f645 | ||
|
Onuralp SEZER
|
2ba70f644c | ||
|
Onuralp SEZER
|
fa65d5f34e | ||
|
Onuralp SEZER
|
a9f0154ca3 | ||
|
James
|
b6f67e607e | ||
|
dependabot[bot]
|
a5bb5a6aa8 | ||
|
Levi Vasconcelos
|
8b443d1b45 | ||
|
Levi Vasconcelos
|
61adff2c9a | ||
|
Levi Vasconcelos
|
d4cee86e2b | ||
|
Levi Vasconcelos
|
cb46751c9a | ||
|
Levi Vasconcelos
|
5e7463dc73 | ||
|
Levi Vasconcelos
|
9b50c92ec0 | ||
|
Levi Vasconcelos
|
7ebbcd6c8e | ||
|
Levi Vasconcelos
|
069f6f22ca | ||
|
Levi Vasconcelos
|
5bfd8429a8 | ||
|
Levi Vasconcelos
|
e8ab777dfd | ||
|
Levi Vasconcelos
|
d63837181f | ||
|
Levi Vasconcelos
|
c523fc163a | ||
|
Linas Kondrackis
|
2e6e61b778 | ||
|
Linas Kondrackis
|
4ee56be8a0 | ||
|
Onuralp SEZER
|
e5dfc4c221 | ||
|
Onuralp SEZER
|
02c1cb001c | ||
|
Onuralp SEZER
|
86a309d255 | ||
|
Linas Kondrackis
|
fefd3386c1 | ||
|
dependabot[bot]
|
54a4a3606f | ||
|
dependabot[bot]
|
d8396c10ea | ||
|
dependabot[bot]
|
5255a25f03 | ||
|
Tomasz Wrona
|
ae6021a5b4 | ||
|
Tomasz Wrona
|
f866a11099 | ||
|
Linas Kondrackis
|
afcb77965c | ||
|
pre-commit-ci[bot]
|
451e0200cb | ||
|
Nick Herrig
|
b0667ce6cb | ||
|
PacificDou
|
b2e085dd21 | ||
|
pre-commit-ci[bot]
|
a3a8fcb433 | ||
|
PacificDou
|
7d46c64628 | ||
|
pre-commit-ci[bot]
|
419c9e375b | ||
|
Nick Herrig
|
59bfc68b6f | ||
|
Nick Herrig
|
8383b445f1 | ||
|
Onuralp SEZER
|
8599345a3c | ||
|
Onuralp SEZER
|
69fadf026b | ||
|
dependabot[bot]
|
4b2a9bf607 | ||
|
Nick Herrig
|
a1d4cb8b33 | ||
|
Nick Herrig
|
e9d0635a74 | ||
|
dependabot[bot]
|
dd07502543 | ||
|
Onuralp SEZER
|
56d3e8ef0b | ||
|
Onuralp SEZER
|
c328cf0469 | ||
|
Onuralp SEZER
|
e34d274d8f | ||
|
Onuralp SEZER
|
88f0c68929 | ||
|
Onuralp SEZER
|
34d73e8847 | ||
|
Onuralp SEZER
|
56a7f8a55f | ||
|
dependabot[bot]
|
afacc19236 | ||
|
pre-commit-ci[bot]
|
59ba52fd80 | ||
|
Piotr Skalski
|
5ffb3424f3 | ||
|
SkalskiP
|
ac7d36b215 | ||
|
James
|
cf3a954416 | ||
|
James
|
6615c553e5 | ||
|
dependabot[bot]
|
0f36679ac7 | ||
|
dependabot[bot]
|
97a986cd11 | ||
|
dependabot[bot]
|
a21d54fab3 | ||
|
dependabot[bot]
|
b80a88ee25 | ||
|
Onuralp SEZER
|
c1c528d378 | ||
|
dependabot[bot]
|
1c1a6236ea | ||
|
Leo Ueno
|
ebd86eef32 | ||
|
Leo Ueno
|
158471283f | ||
|
Piotr Skalski
|
df3f8464b1 | ||
|
pre-commit-ci[bot]
|
8625c7217c | ||
|
SkalskiP
|
382b4e0801 | ||
|
Onuralp SEZER
|
6d2d0c01a3 | ||
|
sansyoandpre-commit-ci[bot]
|
15b099cb71 | ||
|
pre-commit-ci[bot]
|
4e635ee788 | ||
|
Tomasz Wrona
|
f53e0d8aa5 | ||
|
Onuralp SEZER
|
6ba9e70b69 | ||
|
Nick Herrig
|
14771fa326 | ||
|
Onuralp SEZER
|
95398c2a8e | ||
|
Kader Miyanyedi
|
75bb07078c | ||
|
Kader Miyanyedi
|
ba7077918d | ||
|
Onuralp SEZER
|
6b16970d50 | ||
|
Linas Kondrackis
|
20b412b7e1 | ||
|
Linas Kondrackis
|
3f965c9121 | ||
|
Linas Kondrackis
|
08418246c2 | ||
|
dependabot[bot]
|
e1607b4590 | ||
|
Onuralp SEZER
|
be2d75c312 | ||
|
Onuralp SEZER
|
a697e71ccd | ||
|
Christoforos Aristeidou
|
2a9d4257ba | ||
|
Christoforos Aristeidou
|
9ca3c9319d | ||
|
Christoforos Aristeidou
|
379d755a52 | ||
|
Christoforos Aristeidou
|
d228224f06 | ||
|
Onuralp SEZER
|
e3f0ca6937 | ||
|
Kader Miyanyedi
|
dafa2a42de | ||
|
pre-commit-ci[bot]
|
c96022b97a | ||
|
Piotr Skalski
|
899be6a5a4 | ||
|
pre-commit-ci[bot]
|
94b0e9cd22 | ||
|
SkalskiP
|
8ac3b5f8d2 | ||
|
Christoforos Aristeidou
|
2863267f30 | ||
|
Piotr Skalski
|
cebf726997 | ||
|
pre-commit-ci[bot]
|
8ddfcdcd9a | ||
|
SkalskiP
|
5997c39ac7 | ||
|
Piotr Skalski
|
39b5563465 | ||
|
pre-commit-ci[bot]
|
1b07974e93 | ||
|
SkalskiP
|
ba81a09b2c | ||
|
Onuralp SEZER
|
2e898f137e | ||
|
dependabot[bot]
|
c7e8534650 | ||
|
Onuralp SEZER
|
fd2b3c4e8e | ||
|
Onuralp SEZER
|
632d078f4b | ||
|
Onuralp SEZER
|
cbd77b10f9 | ||
|
dependabot[bot]
|
48500cd350 | ||
|
dependabot[bot]
|
ac53125bb6 | ||
|
dependabot[bot]
|
0f2a18efd1 | ||
|
Linas Kondrackis
|
c8f7622e91 | ||
|
Linas Kondrackis
|
c2dd5031ba | ||
|
Piotr Skalski
|
2f9fee6451 | ||
|
pre-commit-ci[bot]
|
b6dc988e37 | ||
|
SkalskiP
|
2ea2231324 | ||
|
Piotr Skalski
|
78d6890508 | ||
|
SkalskiP
|
d8584333ef | ||
|
SkalskiP
|
69213b19d7 | ||
|
Onuralp SEZER
|
0d312f3cd7 | ||
|
pre-commit-ci[bot]
|
01e7330e6e | ||
|
SkalskiP
|
9d71636051 | ||
|
SkalskiP
|
569157f0f0 | ||
|
SkalskiP
|
6cf9ece3a8 | ||
|
Christoforos Aristeidou
|
cf14758891 | ||
|
Adonai Vera
|
8d702ceccd | ||
|
Adonai Vera
|
f9caa7db66 | ||
|
Adonai Vera
|
6e32cdb55a | ||
|
Christoforos Aristeidou
|
fbbf147312 | ||
|
Christoforos Aristeidou
|
96b52f28fb | ||
|
Christoforos Aristeidou
|
c132d5fcf2 | ||
|
Christoforos Aristeidou
|
bc24d0ec44 | ||
|
Christoforos Aristeidou
|
714937e4bd | ||
|
Christoforos Aristeidou
|
c016ea3071 | ||
|
pre-commit-ci[bot]
|
27b61ab4a3 | ||
|
Seongjun Choi
|
bddb72fb28 | ||
|
Seongjun Choi
|
823dc56057 | ||
|
mario-dg
|
6f4704625b | ||
|
mario-dg
|
9f222736e1 | ||
|
mario-dg
|
57b12e6e00 | ||
|
mario-dg
|
c78ae33e43 |
@@ -4,12 +4,18 @@ on:
|
||||
push:
|
||||
branches:
|
||||
- develop
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event_name == 'push' && github.ref}}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
pull-requests: write
|
||||
|
||||
|
||||
jobs:
|
||||
deploy:
|
||||
runs-on: ubuntu-latest
|
||||
@@ -23,7 +29,7 @@ jobs:
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material[all]"
|
||||
run: pip install "mkdocs-material"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
@@ -0,0 +1,55 @@
|
||||
name: Supervision Release Documentation Workflow 📚
|
||||
on:
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event_name == 'push' && github.ref}}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
pull-requests: write
|
||||
|
||||
|
||||
jobs:
|
||||
doc-build-deploy:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
fetch-depth: 0
|
||||
ref: ${{ github.head_ref }}
|
||||
|
||||
- name: 🐍 Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
run: pip install "mkdocs-material[imaging]"
|
||||
- name: 📦 Install mike
|
||||
run: pip install "mike"
|
||||
- name: 📦 Install mkdocs-git-revision-date-localized-plugin
|
||||
run: pip install "mkdocs-git-revision-date-localized-plugin"
|
||||
- name: 📦 Install JupyterLab
|
||||
run: pip install jupyterlab
|
||||
- name: 📦 Install mkdocs-jupyter
|
||||
run: pip install mkdocs-jupyter
|
||||
- name: 📦 Install mkdocs-git-committers-plugin-2
|
||||
run: pip install mkdocs-git-committers-plugin-2
|
||||
- name: ⚙️ Configure git for github-actions 👷
|
||||
run: |
|
||||
git config --global user.name "github-actions[bot]"
|
||||
git config --global user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
- name: 🚀 Deploy MkDoc-Material 📚
|
||||
run: |
|
||||
latest_tag=$(git describe --tags `git rev-list --tags --max-count=1`)
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY=${{ secrets.GITHUB_TOKEN }} mike deploy --push --update-aliases $latest_tag latest
|
||||
@@ -6,22 +6,24 @@ on:
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]+b[0-9]'
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]+rc[0-9]'
|
||||
|
||||
# Allows you to run this workflow manually from the Actions tab
|
||||
workflow_dispatch:
|
||||
|
||||
jobs:
|
||||
build-n-publish:
|
||||
name: Build and publish to PyPI
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: Checkout source
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: 🐍 Set up Python 3.8 environment for build
|
||||
with:
|
||||
ref: ${{ github.head_ref }}
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: "3.8"
|
||||
python-version: ${{ matrix.python-version }}
|
||||
|
||||
- name: 🏗️ Build source and wheel distributions
|
||||
run: |
|
||||
|
||||
@@ -3,10 +3,7 @@ on:
|
||||
push:
|
||||
tags:
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]'
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]'
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]'
|
||||
|
||||
# Allows you to run this workflow manually from the Actions tab
|
||||
workflow_dispatch:
|
||||
|
||||
jobs:
|
||||
@@ -14,7 +11,7 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: [3.8]
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
|
||||
@@ -0,0 +1,34 @@
|
||||
name: 🧪 Docs Test WorkFlow 📚
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main, develop]
|
||||
|
||||
jobs:
|
||||
docs-build-test:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: 🔄 Checkout code
|
||||
uses: actions/checkout@v4
|
||||
- name: 🐍 Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material[all]"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
run: pip install "mkdocs-material[imaging]"
|
||||
- name: 📦 Install mike
|
||||
run: pip install "mike"
|
||||
- name: 📦 Install mkdocs-git-revision-date-localized-plugin
|
||||
run: pip install "mkdocs-git-revision-date-localized-plugin"
|
||||
- name: 📦 Install JupyterLab
|
||||
run: pip install jupyterlab
|
||||
- name: 📦 Install mkdocs-jupyter
|
||||
run: pip install mkdocs-jupyter
|
||||
- name: 📦 Install mkdocs-git-committers-plugin-2
|
||||
run: pip install mkdocs-git-committers-plugin-2
|
||||
- name: 🧪 Test documentation build
|
||||
run: mkdocs build --verbose
|
||||
@@ -37,6 +37,7 @@ jobs:
|
||||
matplotlib==3.5.0 \
|
||||
numpy==1.21.2 \
|
||||
opencv-python==4.5.5.64 \
|
||||
Pillow==10.1.0 \
|
||||
packaging==23.2 \
|
||||
pluggy==1.3.0 \
|
||||
pyparsing==3.1.1 \
|
||||
|
||||
@@ -7,14 +7,13 @@ ci:
|
||||
|
||||
repos:
|
||||
- repo: https://github.com/pre-commit/pre-commit-hooks
|
||||
rev: v4.5.0
|
||||
rev: v4.6.0
|
||||
hooks:
|
||||
- id: end-of-file-fixer
|
||||
- id: trailing-whitespace
|
||||
exclude: test/.*\.py
|
||||
- id: check-yaml
|
||||
exclude: mkdocs.yml
|
||||
- id: check-docstring-first
|
||||
- id: check-executables-have-shebangs
|
||||
- id: check-toml
|
||||
- id: check-case-conflict
|
||||
@@ -28,9 +27,8 @@ repos:
|
||||
- id: mixed-line-ending
|
||||
|
||||
|
||||
|
||||
- repo: https://github.com/PyCQA/bandit
|
||||
rev: '1.7.7'
|
||||
rev: '1.7.8'
|
||||
hooks:
|
||||
- id: bandit
|
||||
args: ["-c", "pyproject.toml"]
|
||||
@@ -47,7 +45,7 @@ repos:
|
||||
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.2.0
|
||||
rev: v0.4.7
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
|
||||
@@ -112,6 +112,20 @@ To run the documentation, install the project requirements with `poetry install
|
||||
|
||||
You can learn more about mkdocs on the [mkdocs website](https://www.mkdocs.org/).
|
||||
|
||||
## 🧑🍳 cookbooks
|
||||
|
||||
We are always looking for new examples and cookbooks to add to the `supervision`
|
||||
documentation. If you have a use case that you think would be helpful to others, please
|
||||
submit a PR with your example. Here are some guidelines for submitting a new example:
|
||||
|
||||
- Create a new notebook in the [`docs/nodebooks`](https://github.com/roboflow/supervision/tree/develop/docs/notebooks) folder.
|
||||
- Add a link to the new notebook in [`docs/theme/cookbooks.html`](https://github.com/roboflow/supervision/blob/develop/docs/theme/cookbooks.html). Make sure to add the path to the new notebook, as well as a title, labels, author and supervision version.
|
||||
- Use the [Count Objects Crossing the Line](https://supervision.roboflow.com/develop/notebooks/count-objects-crossing-the-line/) example as a template for your new example.
|
||||
- Freeze the version of `supervision` you are using.
|
||||
- Place an appropriate Open in Colab button at the top of the notebook. You can find an example of such a button in the aforementioned `Count Objects Crossing the Line` cookbook.
|
||||
- Notebook should be self-contained. If you rely on external data ( videos, images, etc.) or libraries, include download and installation commands in the notebook.
|
||||
- Annotate the code with appropriate comments, including links to the documentation describing each of the tools you have used.
|
||||
|
||||
## 🧪 tests
|
||||
|
||||
[`pytests`](https://docs.pytest.org/en/7.1.x/) is used to run our tests.
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
<div align="center">
|
||||
<p>
|
||||
<a align="center" href="" target="_blank">
|
||||
<a align="center" href="" target="https://supervision.roboflow.com">
|
||||
<img
|
||||
width="100%"
|
||||
src="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png?updatedAt=1678995927529"
|
||||
@@ -10,7 +10,7 @@
|
||||
|
||||
<br>
|
||||
|
||||
[notebooks](https://github.com/roboflow/notebooks) | [inference](https://github.com/roboflow/inference) | [autodistill](https://github.com/autodistill/autodistill) | [collect](https://github.com/roboflow/roboflow-collect)
|
||||
[notebooks](https://github.com/roboflow/notebooks) | [inference](https://github.com/roboflow/inference) | [autodistill](https://github.com/autodistill/autodistill) | [maestro](https://github.com/roboflow/multimodal-maestro)
|
||||
|
||||
<br>
|
||||
|
||||
@@ -18,10 +18,10 @@
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://huggingface.co/spaces/Roboflow/Annotators)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
[](https://squidfunk.github.io/mkdocs-material/)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://huggingface.co/spaces/Roboflow/Annotators)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
[](https://squidfunk.github.io/mkdocs-material/)
|
||||
</div>
|
||||
|
||||
## 👋 hello
|
||||
@@ -39,7 +39,7 @@ Pip install the supervision package in a
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
Read more about desktop, headless, and local installation in our [guide](https://roboflow.github.io/supervision/).
|
||||
Read more about conda, mamba, and installing from source in our [guide](https://roboflow.github.io/supervision/).
|
||||
|
||||
## 🔥 quickstart
|
||||
|
||||
@@ -71,16 +71,15 @@ len(detections)
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(...)
|
||||
model = get_roboflow_model(model_id="yolov8s-640", api_key=<ROBOFLOW API KEY>)
|
||||
model = get_model(model_id="yolov8s-640", api_key=<ROBOFLOW API KEY>)
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
|
||||
len(detections)
|
||||
# 5
|
||||
|
||||
# 5
|
||||
```
|
||||
|
||||
</details>
|
||||
@@ -217,19 +216,23 @@ len(dataset)
|
||||
|
||||
## 🎬 tutorials
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/61a444c8-b135-48ce-b979-2a5ab47c5a91" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><strong>Speed Estimation & Vehicle Tracking | Computer Vision | Open Source</strong></a>
|
||||
<div><strong>Created: 11 Jan 2024</strong> | <strong>Updated: 11 Jan 2024</strong></div>
|
||||
<br/> Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
Want to learn how to use Supervision? Explore our [how-to guides](https://supervision.roboflow.com/develop/how_to/detect_and_annotate/), [end-to-end examples](https://github.com/roboflow/supervision/tree/develop/examples), and [cookbooks](https://supervision.roboflow.com/develop/cookbooks/)!
|
||||
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><img src="https://github.com/roboflow/supervision/assets/26109316/54afdf1c-218c-4451-8f12-627fb85f1682" alt="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><strong>Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking</strong></a>
|
||||
<div><strong>Created: 6 Sep 2023</strong> | <strong>Updated: 6 Sep 2023</strong></div>
|
||||
<br/> In this video, we explore real-time traffic analysis using YOLOv8 and ByteTrack to detect and track vehicles on aerial images. Harnessing the power of Python and Supervision, we delve deep into assigning cars to specific entry zones and understanding their direction of movement. By visualizing their paths, we gain insights into traffic flow across bustling roundabouts... </p>
|
||||
<a href="https://youtu.be/hAWpsIuem10" title="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/a742823d-c158-407d-b30f-063a5d11b4e1" alt="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/hAWpsIuem10" title="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing"><strong>Dwell Time Analysis with Computer Vision | Real-Time Stream Processing</strong></a>
|
||||
<div><strong>Created: 5 Apr 2024</strong></div>
|
||||
<br/>Learn how to use computer vision to analyze wait times and optimize processes. This tutorial covers object detection, tracking, and calculating time spent in designated zones. Use these techniques to improve customer experience in retail, traffic management, or other scenarios.</p>
|
||||
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/61a444c8-b135-48ce-b979-2a5ab47c5a91" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><strong>Speed Estimation & Vehicle Tracking | Computer Vision | Open Source</strong></a>
|
||||
<div><strong>Created: 11 Jan 2024</strong></div>
|
||||
<br/>Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
|
||||
## 💜 built with supervision
|
||||
|
||||
|
||||
@@ -1,19 +0,0 @@
|
||||
# Supervision Cookbooks
|
||||
|
||||
## About
|
||||
|
||||
The Roboflow Cookbook is an open-source collection of examples and guides for building with the [Roboflow Ecosystem](https://roboflow.com/).
|
||||
|
||||
Cookbooks are meant to be common and small scoped computer vision tasks that can allow a user to quickly hit the ground running. Learning is the main goal and purpose.
|
||||
|
||||
Some examples require a Roboflow API key. You can [create a free account here](https://app.roboflow.com/login).
|
||||
|
||||
## Other Resources
|
||||
|
||||
Other than Cookbooks, Roboflow offers other learning resources including:
|
||||
|
||||
- A set of open source tools found on [Github](https://github.com/roboflow).
|
||||
- A [blog](https://blog.roboflow.com/) detailing interesting tutorials, computer vision news, and product updates.
|
||||
- A [Youtube channel](https://www.youtube.com/roboflow) with end to end commputer vision projects.
|
||||
- A [forum](https://discuss.roboflow.com/) for sharing feedback, discussions, and other questions.
|
||||
- The worlds largest [open source collection](https://universe.roboflow.com/) of images, datasets, and fine-tuned models.
|
||||
Vendored
+1294
-1304
File diff suppressed because one or more lines are too long
+2
-2
@@ -19,13 +19,13 @@ as an extra within the Supervision package.
|
||||
```
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>download_assets</h2>
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.download_assets">download_assets</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.downloader.download_assets
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoAssets</h2>
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.VideoAssets">VideoAssets</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.list.VideoAssets
|
||||
|
||||
+228
-1
@@ -1,6 +1,233 @@
|
||||
### 0.21.0 <small>Jun 5, 2024</small>
|
||||
|
||||
- Added [#500](https://github.com/roboflow/supervision/pull/500): [`sv.Detections.with_nmm`](https://supervision.roboflow.com/develop/detection/core/#supervision.detection.core.Detections.with_nmm) to perform non-maximum merging on the current set of object detections.
|
||||
|
||||
- Added [#1221](https://github.com/roboflow/supervision/pull/1221): [`sv.Detections.from_lmm`](https://supervision.roboflow.com/develop/detection/core/#supervision.detection.core.Detections.from_lmm) allowing to parse Large Multimodal Model (LMM) text result into [`sv.Detections`](https://supervision.roboflow.com/develop/detection/core/) object. For now `from_lmm` supports only [PaliGemma](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-finetune-paligemma-on-detection-dataset.ipynb) result parsing.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
paligemma_result = "<loc0256><loc0256><loc0768><loc0768> cat"
|
||||
detections = sv.Detections.from_lmm(
|
||||
sv.LMM.PALIGEMMA,
|
||||
paligemma_result,
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog']
|
||||
)
|
||||
detections.xyxy
|
||||
# array([[250., 250., 750., 750.]])
|
||||
|
||||
detections.class_id
|
||||
# array([0])
|
||||
```
|
||||
|
||||
- Added [#1236](https://github.com/roboflow/supervision/pull/1236): [`sv.VertexLabelAnnotator`](https://supervision.roboflow.com/develop/keypoint/annotators/#supervision.keypoint.annotators.EdgeAnnotator.annotate) allowing to annotate every vertex of a keypoint skeleton with custom text and color.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
thickness=5
|
||||
)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
- Added [#1147](https://github.com/roboflow/supervision/pull/1147): [`sv.KeyPoints.from_inference`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints.from_inference) allowing to create [`sv.KeyPoints`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints) from [Inference](https://github.com/roboflow/inference) result.
|
||||
|
||||
- Added [#1138](https://github.com/roboflow/supervision/pull/1138): [`sv.KeyPoints.from_yolo_nas`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints.from_yolo_nas) allowing to create [`sv.KeyPoints`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints) from [YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md) result.
|
||||
|
||||
- Added [#1163](https://github.com/roboflow/supervision/pull/1163): [`sv.mask_to_rle`](https://supervision.roboflow.com/develop/datasets/utils/#supervision.dataset.utils.rle_to_mask) and [`sv.rle_to_mask`](https://supervision.roboflow.com/develop/datasets/utils/#supervision.dataset.utils.rle_to_mask) allowing for easy conversion between mask and rle formats.
|
||||
|
||||
- Changed [#1236](https://github.com/roboflow/supervision/pull/1236): [`sv.InferenceSlicer`](https://supervision.roboflow.com/develop/detection/tools/inference_slicer/) allowing to select overlap filtering strategy (`NONE`, `NON_MAX_SUPPRESSION` and `NON_MAX_MERGE`).
|
||||
|
||||
- Changed [#1178](https://github.com/roboflow/supervision/pull/1178): [`sv.InferenceSlicer`](https://supervision.roboflow.com/develop/detection/tools/inference_slicer/) adding instance segmentation model support.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-seg-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
return sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
- Changed [#1228](https://github.com/roboflow/supervision/pull/1228): [`sv.LineZone`](https://supervision.roboflow.com/develop/detection/tools/line_zone/) making it 10-20 times faster, depending on the use case.
|
||||
|
||||
- Changed [#1163](https://github.com/roboflow/supervision/pull/1163): [`sv.DetectionDataset.from_coco`](https://supervision.roboflow.com/develop/datasets/core/#supervision.dataset.core.DetectionDataset.from_coco) and [`sv.DetectionDataset.as_coco`](https://supervision.roboflow.com/develop/datasets/core/#supervision.dataset.core.DetectionDataset.as_coco) adding support for run-length encoding (RLE) mask format.
|
||||
|
||||
### 0.20.0 <small>April 24, 2024</small>
|
||||
|
||||
- Added [#1128](https://github.com/roboflow/supervision/pull/1128): [`sv.KeyPoints`](/0.20.0/keypoint/core/#supervision.keypoint.core.KeyPoints) to provide initial support for pose estimation and broader keypoint detection models.
|
||||
|
||||
- Added [#1128](https://github.com/roboflow/supervision/pull/1128): [`sv.EdgeAnnotator`](/0.20.0/keypoint/annotators/#supervision.keypoint.annotators.EdgeAnnotator) and [`sv.VertexAnnotator`](/0.20.0/keypoint/annotators/#supervision.keypoint.annotators.VertexAnnotator) to enable rendering of results from keypoint detection models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8l-pose')
|
||||
|
||||
result = model(image, verbose=False)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
|
||||
edge_annotators = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
annotated_image = edge_annotators.annotate(image.copy(), keypoints)
|
||||
```
|
||||
|
||||
- Changed [#1037](https://github.com/roboflow/supervision/pull/1037): [`sv.LabelAnnotator`](/0.20.0/annotators/#supervision.annotators.core.LabelAnnotator) by adding an additional `corner_radius` argument that allows for rounding the corners of the bounding box.
|
||||
|
||||
- Changed [#1109](https://github.com/roboflow/supervision/pull/1109): [`sv.PolygonZone`](/0.20.0/detection/tools/polygon_zone/#supervision.detection.tools.polygon_zone.PolygonZone) such that the `frame_resolution_wh` argument is no longer required to initialize `sv.PolygonZone`.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `frame_resolution_wh` parameter in `sv.PolygonZone` is deprecated and will be removed in `supervision-0.24.0`.
|
||||
|
||||
- Changed [#1084](https://github.com/roboflow/supervision/pull/1084): [`sv.get_polygon_center`](/0.20.0/utils/geometry/#supervision.geometry.core.utils.get_polygon_center) to calculate a more accurate polygon centroid.
|
||||
|
||||
- Changed [#1069](https://github.com/roboflow/supervision/pull/1069): [`sv.Detections.from_transformers`](/0.20.0/detection/core/#supervision.detection.core.Detections.from_transformers) by adding support for Transformers segmentation models and extract class names values.
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForSegmentation
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_segmentation(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results, id2label=model.config.id2label)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
- Fixed [#787](https://github.com/roboflow/supervision/pull/787): [`sv.ByteTrack.update_with_detections`](/0.20.0/trackers/#supervision.tracker.byte_tracker.core.ByteTrack.update_with_detections) which was removing segmentation masks while tracking. Now, `ByteTrack` can be used alongside segmentation models.
|
||||
|
||||
### 0.19.0 <small>March 15, 2024</small>
|
||||
|
||||
- Added [#818](https://github.com/roboflow/supervision/pull/818): [`sv.CSVSink`](/0.19.0/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) allowing for the straightforward saving of image, video, or stream inference results in a `.csv` file.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO(<SOURCE_MODEL_PATH>)
|
||||
csv_sink = sv.CSVSink(<RESULT_CSV_FILE_PATH>)
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with csv_sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
csv_sink.append(detections, custom_data={<CUSTOM_LABEL>:<CUSTOM_DATA>})
|
||||
```
|
||||
|
||||
- Added [#819](https://github.com/roboflow/supervision/pull/819): [`sv.JSONSink`](/0.19.0/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink) allowing for the straightforward saving of image, video, or stream inference results in a `.json` file.
|
||||
|
||||
```python
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO(<SOURCE_MODEL_PATH>)
|
||||
json_sink = sv.JSONSink(<RESULT_JSON_FILE_PATH>)
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with json_sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
json_sink.append(detections, custom_data={<CUSTOM_LABEL>:<CUSTOM_DATA>})
|
||||
```
|
||||
|
||||
- Added [#847](https://github.com/roboflow/supervision/pull/847): [`sv.mask_iou_batch`](/0.19.0/detection/utils/#supervision.detection.utils.mask_iou_batch) allowing to compute Intersection over Union (IoU) of two sets of masks.
|
||||
|
||||
- Added [#847](https://github.com/roboflow/supervision/pull/847): [`sv.mask_non_max_suppression`](/0.19.0/detection/utils/#supervision.detection.utils.mask_non_max_suppression) allowing to perform Non-Maximum Suppression (NMS) on segmentation predictions.
|
||||
|
||||
- Added [#888](https://github.com/roboflow/supervision/pull/888): [`sv.CropAnnotator`](/0.19.0/annotators/#supervision.annotators.core.CropAnnotator) allowing users to annotate the scene with scaled-up crops of detections.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
|
||||
crop_annotator = sv.CropAnnotator()
|
||||
annotated_frame = crop_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
- Changed [#827](https://github.com/roboflow/supervision/pull/827): [`sv.ByteTrack.reset`](/0.19.0/tracking/#supervision.tracking.ByteTrack.reset) allowing users to clear trackers state, enabling the processing of multiple video files in sequence.
|
||||
|
||||
- Changed [#802](https://github.com/roboflow/supervision/pull/802): [`sv.LineZoneAnnotator`](/0.19.0/detection/tools/line_zone/#supervision.detection.line_zone.LineZone) allowing to hide in/out count using `display_in_count` and `display_out_count` properties.
|
||||
|
||||
- Changed [#787](https://github.com/roboflow/supervision/pull/787): [`sv.ByteTrack`](/0.19.0/tracking/#supervision.tracking.ByteTrack) input arguments and docstrings updated to improve readability and ease of use.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `track_buffer`, `track_thresh`, and `match_thresh` parameters in `sv.ByterTrack` are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
|
||||
- Changed [#910](https://github.com/roboflow/supervision/pull/910): [`sv.PolygonZone`](/0.19.0/detection/tools/polygon_zone/#supervision.detection.tools.polygon_zone.PolygonZone) to now accept a list of specific box anchors that must be in zone for a detection to be counted.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `triggering_position ` parameter in `sv.PolygonZone` is deprecated and will be removed in `supervision-0.23.0`. Use `triggering_anchors` instead.
|
||||
|
||||
- Changed [#875](https://github.com/roboflow/supervision/pull/875): annotators adding support for Pillow images. All supervision Annotators can now accept an image as either a numpy array or a Pillow Image. They automatically detect its type, draw annotations, and return the output in the same format as the input.
|
||||
|
||||
- Fixed [#944](https://github.com/roboflow/supervision/pull/944): [`sv.DetectionsSmoother`](/0.19.0/detection/tools/smoother/#supervision.detection.tools.smoother.DetectionsSmoother) removing `tracking_id` from `sv.Detections`.
|
||||
|
||||
### 0.18.0 <small>January 25, 2024</small>
|
||||
|
||||
- Added [#633](https://github.com/roboflow/supervision/pull/720): [`sv.PercentageBarAnnotator`](/0.18.0/annotators/#percentagebarannotator) allowing to annotate images and videos with percentage values representing confidence or other custom property.
|
||||
- Added [#720](https://github.com/roboflow/supervision/pull/720): [`sv.PercentageBarAnnotator`](/0.18.0/annotators/#percentagebarannotator) allowing to annotate images and videos with percentage values representing confidence or other custom property.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
@@ -1,7 +1,6 @@
|
||||
---
|
||||
template: cookbooks.html
|
||||
comments: true
|
||||
status: new
|
||||
hide:
|
||||
- navigation
|
||||
- toc
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Datasets
|
||||
@@ -0,0 +1,18 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Datasets Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.dataset.utils.rle_to_mask">rle_to_mask</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.dataset.utils.rle_to_mask
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.dataset.utils.mask_to_rle">mask_to_rle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.dataset.utils.mask_to_rle
|
||||
+11
-8
@@ -6,11 +6,14 @@ status: deprecated
|
||||
These features are phased out due to better alternatives or potential issues in future versions. Deprecated functionalities are supported for **three subsequent releases**, providing time for users to transition to updated methods.
|
||||
|
||||
- [`Detections.from_froboflow`](detection/core.md/#supervision.detection.core.Detections.from_roboflow) is deprecated and will be removed in `supervision-0.22.0`. Use [`Detections.from_inference`](detection/core.md/#supervision.detection.core.Detections.from_inference) instead.
|
||||
- `Color.white()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.WHITE` instead.
|
||||
- `Color.black()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.BLACK` instead.
|
||||
- `Color.red()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.RED` instead.
|
||||
- `Color.green()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.GREEN` instead.
|
||||
- `Color.blue()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.BLUE` instead.
|
||||
- [`ColorPalette.default()`](draw/color.md/#supervision.draw.color.ColorPalette.default) is deprecated and will be removed in `supervision-0.22.0`. Use [`ColorPalette.DEFAULT`](draw/color.md/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
- `BoxAnnotator` is deprecated and will be removed in `supervision-0.22.0`. Use [`BoundingBoxAnnotator`](annotators.md/#supervision.annotators.core.BoundingBoxAnnotator) and [`LabelAnnotator`](annotators.md/#supervision.annotators.core.LabelAnnotator) instead.
|
||||
- [`FPSMonitor.__call__`](utils/video.md/#supervision.utils.video.FPSMonitor.__call__) is deprecated and will be removed in `supervision-0.22.0`. Use [`FPSMonitor.fps`](utils/video.md/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
- The method `Color.white()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.WHITE` instead.
|
||||
- The method `Color.black()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.BLACK` instead.
|
||||
- The method `Color.red()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.RED` instead.
|
||||
- The method `Color.green()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.GREEN` instead.
|
||||
- The method `Color.blue()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.BLUE` instead.
|
||||
- The method [`ColorPalette.default()`](draw/color.md/#supervision.draw.color.ColorPalette.default) is deprecated and will be removed in `supervision-0.22.0`. Use the constant [`ColorPalette.DEFAULT`](draw/color.md/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
- `BoxAnnotator` is deprecated and will be removed in `supervision-0.22.0`. Use [`BoundingBoxAnnotator`](detection/annotators.md/#supervision.annotators.core.BoundingBoxAnnotator) and [`LabelAnnotator`](detection/annotators.md/#supervision.annotators.core.LabelAnnotator) instead.
|
||||
- The method [`FPSMonitor.__call__`](utils/video.md/#supervision.utils.video.FPSMonitor.__call__) is deprecated and will be removed in `supervision-0.22.0`. Use the attribute [`FPSMonitor.fps`](utils/video.md/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
- The `track_buffer`, `track_thresh`, and `match_thresh` parameters in [`ByterTrack`](trackers.md/#supervision.tracker.byte_tracker.core.ByteTrack) are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
- The `triggering_position ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) is deprecated and will be removed in `supervision-0.23.0`. Use `triggering_anchors ` instead.
|
||||
- The `frame_resolution_wh ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) is deprecated and will be removed in `supervision-0.24.0`.
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotators
|
||||
@@ -260,15 +259,22 @@ status: new
|
||||
=== "Label"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
|
||||
@@ -278,6 +284,52 @@ status: new
|
||||
|
||||
</div>
|
||||
|
||||
=== "RichLabel"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
rich_label_annotator = sv.RichLabelAnnotator(
|
||||
font_path=".../font.ttf",
|
||||
text_position=sv.Position.CENTER
|
||||
)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Crop"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
crop_annotator = sv.CropAnnotator()
|
||||
annotated_frame = crop_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
=== "Blur"
|
||||
|
||||
```python
|
||||
@@ -470,6 +522,12 @@ status: new
|
||||
|
||||
:::supervision.annotators.core.LabelAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.RichLabelAnnotator">RichLabelAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.RichLabelAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BlurAnnotator">BlurAnnotator</a></h2>
|
||||
</div>
|
||||
@@ -488,6 +546,12 @@ status: new
|
||||
|
||||
:::supervision.annotators.core.TraceAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.CropAnnotator">CropAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.CropAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.ColorLookup">ColorLookup</a></h2>
|
||||
</div>
|
||||
@@ -0,0 +1,30 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Double Detection Filter
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.OverlapFilter">OverlapFilter</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.OverlapFilter
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.box_non_max_suppression">box_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.mask_non_max_suppression">mask_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.box_non_max_merge">box_non_max_merge</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.box_non_max_merge
|
||||
@@ -0,0 +1,17 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Metrics
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# InferenceSlicer
|
||||
|
||||
@@ -1,7 +1,16 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# LineZone
|
||||
<div class="md-typeset">
|
||||
<h2>LineZone</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.line_counter.LineZone
|
||||
:::supervision.detection.line_zone.LineZone
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>LineZoneAnnotator</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.line_zone.LineZoneAnnotator
|
||||
|
||||
@@ -2,7 +2,9 @@
|
||||
comments: true
|
||||
---
|
||||
|
||||
# PolygonZone
|
||||
<div class="md-typeset">
|
||||
<h2>PolygonZone</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.tools.polygon_zone.PolygonZone
|
||||
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
@@ -10,3 +9,9 @@ status: new
|
||||
</div>
|
||||
|
||||
:::supervision.detection.tools.csv_sink.CSVSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>JSON Sink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.tools.json_sink.JSONSink
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detection Smoother
|
||||
|
||||
+39
-21
@@ -5,67 +5,85 @@ comments: true
|
||||
# Detection Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_iou_batch</h2>
|
||||
<h2><a href="#supervision.detection.utils.box_iou_batch">box_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_iou_batch</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_iou_batch">mask_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_non_max_suppression</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_non_max_suppression</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_mask</h2>
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_mask">polygon_to_mask</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_mask
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_xyxy</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_to_xyxy">mask_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_polygons</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_to_polygons">mask_to_polygons</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_polygons
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_xyxy</h2>
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_xyxy">polygon_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>filter_polygons_by_area</h2>
|
||||
<h2><a href="#supervision.detection.utils.filter_polygons_by_area">filter_polygons_by_area</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.filter_polygons_by_area
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>move_boxes</h2>
|
||||
<h2><a href="#supervision.detection.utils.move_boxes">move_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>scale_boxes</h2>
|
||||
<h2><a href="#supervision.detection.utils.move_masks">move_masks</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_masks
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.scale_boxes">scale_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.scale_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.clip_boxes">clip_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.clip_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.pad_boxes">pad_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.pad_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.contains_holes">contains_holes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.contains_holes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.contains_multiple_segments">contains_multiple_segments</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.contains_multiple_segments
|
||||
|
||||
@@ -1,13 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Color
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ColorPalette</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
@@ -1,53 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_line</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_filled_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_polygon</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_text</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_dynamic_font_scale</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_dynamic_line_thickness</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_line_thickness
|
||||
@@ -1,7 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Position
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
@@ -4,17 +4,31 @@ comments: true
|
||||
|
||||
# Detect and Annotate
|
||||
|
||||
Supervision offers a streamlined solution to effortlessly annotate predictions from a
|
||||
range of object detection and segmentation models. This guide demonstrates how to
|
||||
execute inference using the YOLOv8 model with either the
|
||||
[Inference](https://github.com/roboflow/inference) or
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision for image annotation
|
||||
purposes.
|
||||
Supervision provides a seamless process for annotating predictions generated by various
|
||||
object detection and segmentation models. This guide shows how to perform inference
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision and use them to annotate
|
||||
source image.
|
||||
|
||||
## Run Inference
|
||||
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation model.
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
@@ -23,105 +37,115 @@ First, you'll need to obtain predictions from your object detection or segmentat
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from inference.models.utils import get_roboflow_model
|
||||
import torch
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
```
|
||||
|
||||
## Load Predictions into Supervision
|
||||
|
||||
Now that we have predictions from a model, we can load them into Supervision.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
We can do so using the [`sv.Detections.from_ultralytics`](detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
We can do so using the [`sv.Detections.from_inference`](detection/core/#supervision.detection.core.Detections.from_inference) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
```{ .py hl_lines="2 8" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
You can conveniently load predictions from other computer vision frameworks and libraries using:
|
||||
|
||||
- [`from_deepsparse`](detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_inference`](detection/core/#supervision.detection.core.Detections.from_inference) ([Roboflow Inference](https://github.com/roboflow/inference))
|
||||
- [`from_sam`](detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_transformers`](detection/core/#supervision.detection.core.Detections.from_transformers) ([HuggingFace Transformers](https://github.com/huggingface/transformers))
|
||||
- [`from_yolo_nas`](detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
## Annotate Image
|
||||
|
||||
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](annotators/#supervision.annotators.core.LabelAnnotator) classes. If you are running the segmentation model [`sv.MaskAnnotator`](annotators/#supervision.annotators.core.MaskAnnotator) is a drop-in replacement for [`sv.BoundingBoxAnnotator`](annotators/#supervision.annotators.core.BoundingBoxAnnotator) that will allow you to draw masks instead of boxes.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
We can do so using the [`sv.Detections.from_ultralytics`](detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```{ .py hl_lines="2 8" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.model.names[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
We can do so using the [`sv.Detections.from_transformers`](detection/core/#supervision.detection.core.Detections.from_transformers) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```{ .py hl_lines="2 19-21" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
```
|
||||
|
||||
You can load predictions from other computer vision frameworks and libraries using:
|
||||
|
||||
- [`from_deepsparse`](/latest/detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](/latest/detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](/latest/detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_sam`](/latest/detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_yolo_nas`](/latest/detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
## Annotate Image with Detections
|
||||
|
||||
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](/latest/annotators/#supervision.annotators.core.LabelAnnotator) classes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
```{ .py hl_lines="10-16" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
@@ -134,12 +158,253 @@ Finally, we can annotate the image with the predictions. Since we are working wi
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
## Display Annotated Image
|
||||
```{ .py hl_lines="10-16" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
To display the annotated image in Jupyter Notebook or Google Colab, use the [`sv.plot_image`](utils/notebook/#supervision.utils.notebook.plot_image) function.
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
```python
|
||||
sv.plot_image(annotated_image)
|
||||
```
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="23-30" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||

|
||||
|
||||
## Display Custom Labels
|
||||
|
||||
By default, [`sv.LabelAnnotator`](/latest/annotators/#supervision.annotators.core.LabelAnnotator)
|
||||
will label each detection with its `class_name` (if possible) or `class_id`. You can
|
||||
override this behavior by passing a list of custom `labels` to the `annotate` method.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="13-17 22" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="13-17 22" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="26-30 35" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Annotate Image with Segmentations
|
||||
|
||||
If you are running the segmentation model
|
||||
[`sv.MaskAnnotator`](/latest/annotators/#supervision.annotators.core.MaskAnnotator)
|
||||
is a drop-in replacement for
|
||||
[`sv.BoundingBoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoundingBoxAnnotator)
|
||||
that will allow you to draw masks instead of boxes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-seg-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n-seg.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForSegmentation
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_segmentation(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
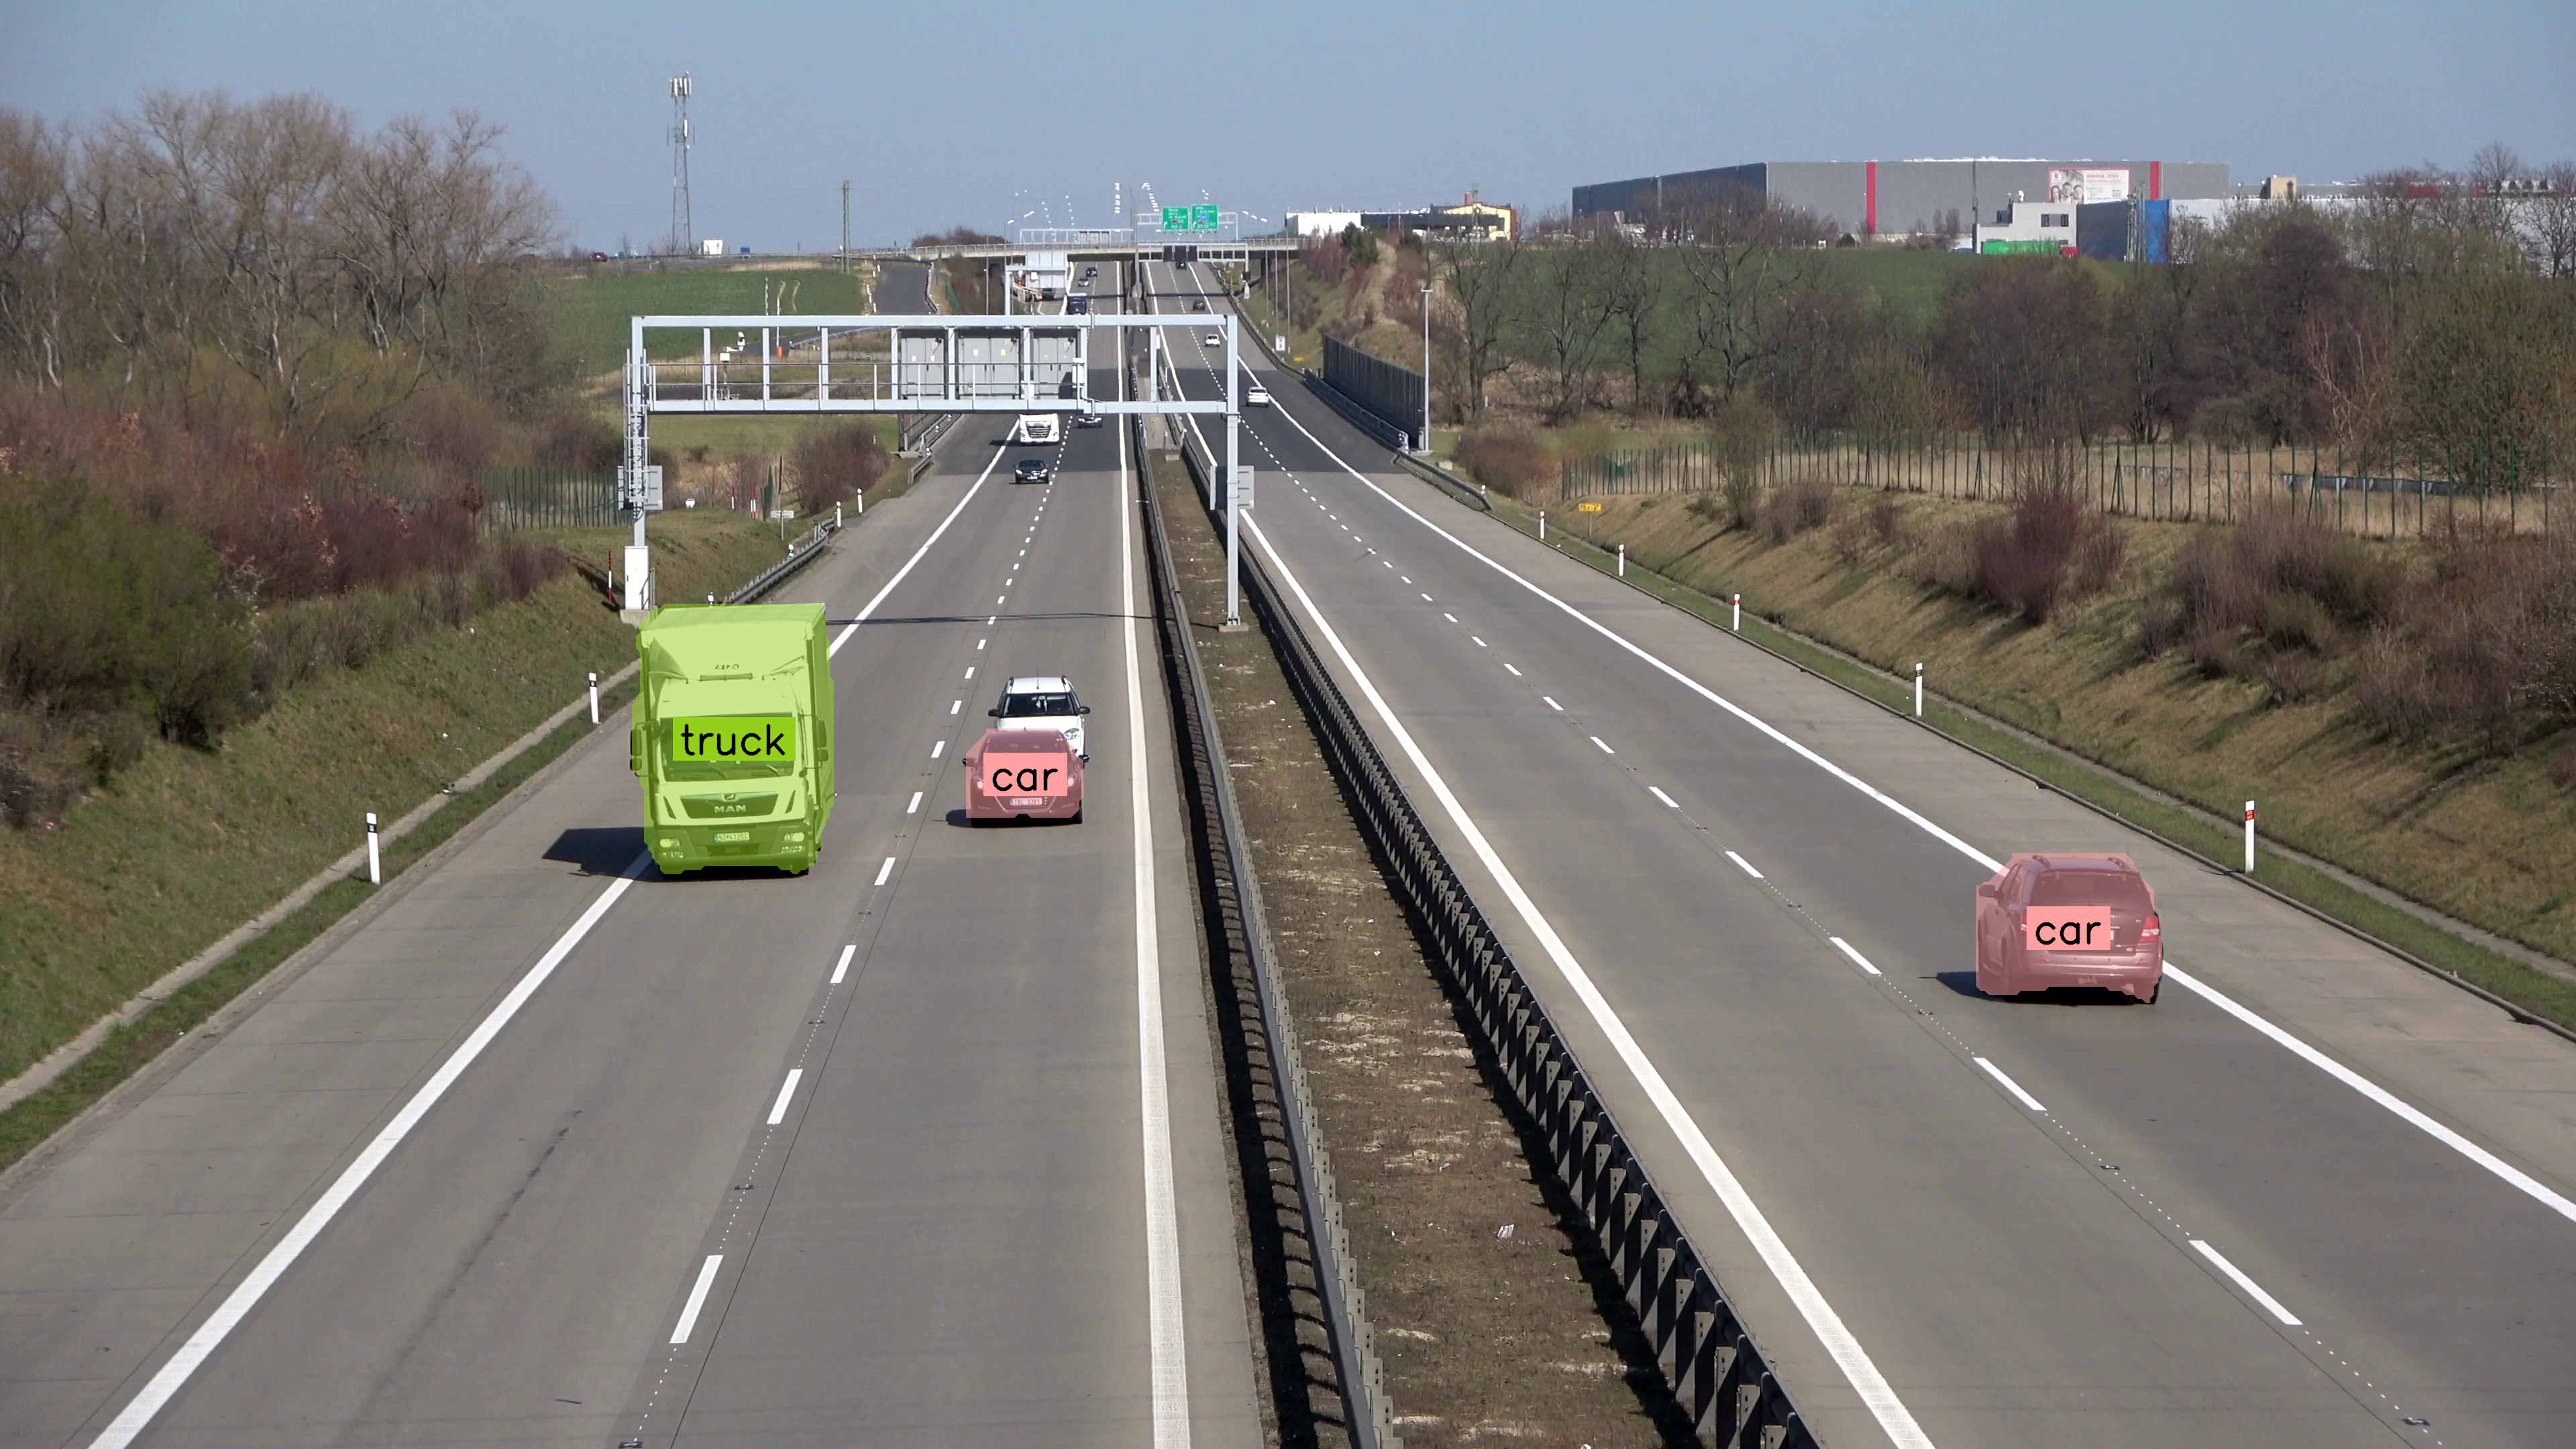
|
||||
|
||||
@@ -0,0 +1,326 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detect Small Objects
|
||||
|
||||
This guide shows how to detect small objects
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages using
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer).
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Baseline Detection
|
||||
|
||||
Small object detection in high-resolution images presents challenges due to the objects'
|
||||
size relative to the image resolution.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForSegmentation
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image_slice.size
|
||||
target_size = torch.tensor([[width, height]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.config.id2label[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Input Resolution
|
||||
|
||||
Modifying the input resolution of images before detection can enhance small object
|
||||
identification at the cost of processing speed and increased memory usage. This method
|
||||
is less effective for ultra-high-resolution images (4K and above).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="5" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-1280")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image, imgsz=1280)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Inference Slicer
|
||||
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer)
|
||||
processes high-resolution images by dividing them into smaller segments, detecting
|
||||
objects within each, and aggregating the results.
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example_2.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="9-14" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
return sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="9-14" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
result = model(image_slice)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="13-28" }
|
||||
import cv2
|
||||
import torch
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
image_slice = cv2.cvtColor(image_slice, cv2.COLOR_BGR2RGB)
|
||||
image_slice = Image.fromarray(image_slice)
|
||||
inputs = processor(images=image_slice, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image_slice.size
|
||||
target_size = torch.tensor([[width, height]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
return sv.Detections.from_transformers(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.config.id2label[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Small Object Segmentation
|
||||
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) can perform segmentation tasks too.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="6 16 19-20" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-seg-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
return sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="6 16 19-20" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x-seg.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
result = model(image_slice)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
|
||||
@@ -0,0 +1,298 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
|
||||
Supervision enables an easy way to save detections in .CSV and .JSON files for offline
|
||||
processing. This guide demonstrates how to perform video inference using the
|
||||
[Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages and save their results with
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. You can learn more on this topic in our
|
||||
[How to Detect and Annotate](/latest/how_to/detect_and_annotate.md) guide.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
```
|
||||
|
||||
## Save Detections as CSV
|
||||
|
||||
To save detections to a `.CSV` file, open our
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
and then pass the
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections)
|
||||
object resulting from the inference to it. Its fields are parsed and saved on disk.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car |
|
||||
|
||||
## Custom Fields
|
||||
|
||||
Besides regular fields in
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections),
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
also allows you to add custom information to each row, which can be passed via the
|
||||
`custom_data` dictionary. Let's utilize this feature to save information about the
|
||||
frame index from which the detections originate.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="10 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name | frame_index |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|-------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car | 0 |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck | 0 |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car | 0 |
|
||||
|
||||
## Save Detections as JSON
|
||||
|
||||
If you prefer to save the result in a `.JSON` file instead of a `.CSV` file, all you
|
||||
need to do is replace
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
with
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
+38
-12
@@ -1,19 +1,20 @@
|
||||
---
|
||||
template: index.html
|
||||
comments: true
|
||||
hide:
|
||||
- navigation
|
||||
- toc
|
||||
---
|
||||
|
||||
<div align="center">
|
||||
<p>
|
||||
<a align="center" href="" target="_blank">
|
||||
<img
|
||||
width="850"
|
||||
src="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png?updatedAt=1678995927529"
|
||||
>
|
||||
</a>
|
||||
</p>
|
||||
<div class="md-typeset">
|
||||
<h1></h1>
|
||||
</div>
|
||||
|
||||
<div align="center" id="logo">
|
||||
<a align="center" href="" target="_blank">
|
||||
<img width="850"
|
||||
src="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png?updatedAt=1678995927529">
|
||||
</a>
|
||||
</div>
|
||||
|
||||
## 👋 Hello
|
||||
@@ -29,7 +30,7 @@ We write your reusable computer vision tools. Whether you need to load your data
|
||||
|
||||
## 💻 Install
|
||||
|
||||
You can install `supervision` with pip in a
|
||||
You can install `supervision` in a
|
||||
[**Python>=3.8**](https://www.python.org/) environment.
|
||||
|
||||
!!! example "pip install (recommended)"
|
||||
@@ -45,7 +46,25 @@ You can install `supervision` with pip in a
|
||||
If you require the full version of `supervision` with GUI support you can install the desktop version. This version includes the GUI components of OpenCV, allowing you to display images and videos on the screen.
|
||||
|
||||
```bash
|
||||
pip install supervision[desktop]
|
||||
pip install "supervision[desktop]"
|
||||
```
|
||||
|
||||
!!! example "conda/mamba install"
|
||||
|
||||
=== "conda"
|
||||
|
||||
[](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision)
|
||||
|
||||
```bash
|
||||
conda install -c conda-forge supervision
|
||||
```
|
||||
|
||||
=== "mamba"
|
||||
|
||||
[](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision)
|
||||
|
||||
```bash
|
||||
mamba install -c conda-forge supervision
|
||||
```
|
||||
|
||||
!!! example "git clone (for development)"
|
||||
@@ -87,7 +106,6 @@ You can install `supervision` with pip in a
|
||||
poetry install --extras "desktop"
|
||||
```
|
||||
|
||||
|
||||
## 🚀 Quickstart
|
||||
|
||||
<div class="grid cards" markdown>
|
||||
@@ -108,6 +126,14 @@ You can install `supervision` with pip in a
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/track_objects.md)
|
||||
|
||||
- __Detect Small Objects__
|
||||
|
||||
---
|
||||
|
||||
Learn how to detect small objects in images
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/detect_small_objects.md)
|
||||
|
||||
- > __Count Objects Crossing Line__
|
||||
|
||||
---
|
||||
|
||||
@@ -55,7 +55,7 @@ document.addEventListener("DOMContentLoaded", function () {
|
||||
|
||||
let authorAvatarsHTML = authorDataArray.map((authorData, index) => {
|
||||
const marginLeft = index === 0 ? '0' : '-10px';
|
||||
const zIndex = 100 - index;
|
||||
const zIndex = 4 - index;
|
||||
return `
|
||||
<div
|
||||
class="author-container"
|
||||
|
||||
@@ -0,0 +1,97 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
=== "VertexAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_annotator = sv.VertexAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
radius=10
|
||||
)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "EdgeAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
thickness=5
|
||||
)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "VertexLabelAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_label_annotator = sv.VertexLabelAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
text_color=sv.Color.BLACK,
|
||||
border_radius=5
|
||||
)
|
||||
annotated_frame = vertex_label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.VertexAnnotator">VertexAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.VertexAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.EdgeAnnotator">EdgeAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.EdgeAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.VertexLabelAnnotator">VertexLabelAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.VertexLabelAnnotator
|
||||
@@ -0,0 +1,8 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Keypoint Detection
|
||||
|
||||
:::supervision.keypoint.core.KeyPoints
|
||||
@@ -1,22 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Detection Metrics
|
||||
|
||||
!!! warning
|
||||
|
||||
Evaluation API is still fluid and may change. If you use Evaluation API in your project until further notice, freeze the
|
||||
`supervision` version in your `requirements.txt` or `setup.py`.
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
+279
-87
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
+29
-26
@@ -4,38 +4,20 @@
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Experimenting with Supervision Assets\n",
|
||||
"# Download Supervision Assets\n",
|
||||
"\n",
|
||||
"---\n",
|
||||
"\n",
|
||||
"<p align=\"center\">\n",
|
||||
" <a href=\"https://colab.research.google.com/github/roboflow/supervision/blob/develop/docs/notebooks/supervision-assets.ipynb\"><img src=\"https://colab.research.google.com/assets/colab-badge.svg\" alt=\"Colab\"></a>\n",
|
||||
"</p>\n",
|
||||
"[](https://colab.research.google.com/github/roboflow/supervision/blob/develop/docs/notebooks/download-supervision-assets.ipynb)\n",
|
||||
"\n",
|
||||
"When experimenting with interesting and useful features of the Supervision package, its important to have some sort of image or video data to experiment with. Luckily for us, Supervision ships with [Assets](https://supervision.roboflow.com/latest/assets/)! Assets is a collection of videos that you can utilize to start experimenting with the various features Supervision has to offer. Let's take a look at how to use this resource.\n",
|
||||
"When experimenting with interesting and useful features of the Supervision package, it's important to have some sort of image or video data to experiment with. Luckily for us, Supervision ships with [Assets](https://supervision.roboflow.com/latest/assets/)! Assets is a collection of videos that you can utilize to start experimenting with the various features Supervision has to offer. Let's take a look at how to use this resource.\n",
|
||||
"\n",
|
||||
"## Install with Pip\n",
|
||||
"\n",
|
||||
"If you're running this code outside a Jupyter notebook, it's generally a best practice to create a virtual environment so that your projects deppendencies are isolated. Run the following ing your command line of choice to create and source one.\n",
|
||||
"\n",
|
||||
"```shell\n",
|
||||
"\n",
|
||||
"python -m venv venv\n",
|
||||
"source venv/bin/activate\n",
|
||||
"\n",
|
||||
"``` "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Now that we've got a virtual enviornment installed and sourced, let's install the pip package with the assets \"extra\" package. Make sure to remove the \"!\" if running this in your command line."
|
||||
"## Install Dependencies"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"execution_count": 10,
|
||||
"metadata": {
|
||||
"vscode": {
|
||||
"languageId": "shellscript"
|
||||
@@ -63,7 +45,7 @@
|
||||
"source": [
|
||||
"from supervision.assets import download_assets, VideoAssets\n",
|
||||
"\n",
|
||||
"# Download a video asset from the supervision package.\n",
|
||||
"# Download the a video of the subway.\n",
|
||||
"path_to_video = download_assets(VideoAssets.SUBWAY)"
|
||||
]
|
||||
},
|
||||
@@ -71,7 +53,28 @@
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"We're now equipt with a video asset from Supervision to run some experiements on! For more information on available video assets, visit the [Supervision API Reference](https://supervision.roboflow.com/latest/assets/#videoassets). Happy building!"
|
||||
"With this, we now have a high quality video asset for use in demos. Let's take a look at what we downloaded. Keep in mind that the video preview below works only in the web version of the cookbooks and not in Google Colab.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"<div style=\"display: flex; justify-content: center;\">\n",
|
||||
" <video controls width=\"320\" height=\"240\">\n",
|
||||
" <source\n",
|
||||
" src=\"https://media.roboflow.com/supervision/video-examples/subway.mp4\"\n",
|
||||
" type=\"video/mp4\"\n",
|
||||
" >\n",
|
||||
" </video>\n",
|
||||
"</div>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"We're now equipt with a video asset from Supervision to run some experiments on! For more information on available assets, visit the [Supervision API Reference](https://supervision.roboflow.com/latest/assets). Happy building!"
|
||||
]
|
||||
}
|
||||
],
|
||||
@@ -91,7 +94,7 @@
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.11.7"
|
||||
"version": "3.11.8"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
|
||||
File diff suppressed because one or more lines are too long
Vendored
+225
-60
File diff suppressed because one or more lines are too long
+1306
File diff suppressed because one or more lines are too long
Vendored
+46
-56
@@ -12,23 +12,11 @@
|
||||
"\n",
|
||||
"---\n",
|
||||
"\n",
|
||||
"<p align=\"center\">\n",
|
||||
" <a href=\"https://badge.fury.io/py/supervision\"><img src=\"https://badge.fury.io/py/supervision.svg\" alt=\"version\"></a>\n",
|
||||
" <a href=\"https://pypistats.org/packages/supervision\"><img src=\"https://img.shields.io/pypi/dm/supervision\" alt=\"downloads\"></a>\n",
|
||||
" <a href=\"https://github.com/roboflow/supervision/blob/main/LICENSE.md\"><img src=\"https://img.shields.io/pypi/l/supervision\" alt=\"license\"></a>\n",
|
||||
" <a href=\"https://badge.fury.io/py/supervision\"><img src=\"https://img.shields.io/pypi/pyversions/supervision\" alt=\"python-version\"></a>\n",
|
||||
" <a href=\"https://github.com/roboflow/supervision\"><img src=\"https://badges.aleen42.com/src/github.svg\" alt=\"GitHub\"></a>\n",
|
||||
"</p>\n",
|
||||
"\n",
|
||||
"<p align=\"center\">\n",
|
||||
" <a href=\"https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb\"><img src=\"https://colab.research.google.com/assets/colab-badge.svg\" alt=\"Colab\"></a>\n",
|
||||
" <a href=\"https://kaggle.com/kernels/welcome?src=https://github.com/roboflow/supervision/blob/main/demo.ipynb\"><img src=\"https://kaggle.com/static/images/open-in-kaggle.svg\" alt=\"Kaggle\"></a>\n",
|
||||
" <a href=\"https://studiolab.sagemaker.aws/import/github/roboflow/supervision/blob/main/demo.ipynb\"><img src=\"https://raw.githubusercontent.com/roboflow-ai/notebooks/main/assets/badges/sage-maker.svg\" alt=\"SageMaker\"></a>\n",
|
||||
" <a href=\"https://nbviewer.jupyter.org/github/roboflow/supervision/blob/main/demo.ipynb\"><img src=\"https://img.shields.io/badge/Open_in_Nbviewer-F37626.svg?logo=Jupyter&logoColor=white\" alt=\"nbviewer\">\n",
|
||||
" <a href=\"https://mybinder.org/v2/gh/roboflow/supervision/develop?labpath=demo.ipynb\"><img src=\"https://mybinder.org/badge_logo.svg\" alt=\"Binder\"></a>\n",
|
||||
" <a href=\"https://github.com/roboflow/supervision/raw/main/demo.ipynb\" download><img src=\"https://img.shields.io/badge/Download-Notebook-A351FB.svg\" alt=\"Download\"></a>\n",
|
||||
"</p>\n",
|
||||
"\n",
|
||||
"[](https://badge.fury.io/py/supervision)\n",
|
||||
"[](https://pypistats.org/packages/supervision)\n",
|
||||
"[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)\n",
|
||||
"[](https://badge.fury.io/py/supervision)\n",
|
||||
"[](https://github.com/roboflow/supervision)\n",
|
||||
"\n",
|
||||
"We write your reusable computer vision tools. Whether you need to load your dataset from your hard drive, draw detections on an image or video, or count how many detections are in a zone. You can count on us! \ud83e\udd1d\n",
|
||||
"\n",
|
||||
@@ -78,7 +66,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 1,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -129,7 +117,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 2,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -164,7 +152,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 3,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "1oeBxRj5wOv7"
|
||||
},
|
||||
@@ -184,7 +172,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 4,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -225,7 +213,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 5,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -279,7 +267,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 6,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "0ZlmuEpwydTu"
|
||||
},
|
||||
@@ -323,13 +311,13 @@
|
||||
"from super_gradients.training import models\n",
|
||||
"\n",
|
||||
"model = models.get(\"yolo_nas_l\", pretrained_weights=\"coco\")\n",
|
||||
"result = model.predict(image)[0]\n",
|
||||
"result = model.predict(image)\n",
|
||||
"detections = sv.Detections.from_yolo_nas(result)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 20,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -364,7 +352,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 10,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -388,7 +376,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 32,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "PMx3oMPh1fui"
|
||||
},
|
||||
@@ -403,7 +391,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 22,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -447,7 +435,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 31,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -487,7 +475,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 30,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -533,7 +521,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 29,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -584,7 +572,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 44,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "yuskE3obCS_-"
|
||||
},
|
||||
@@ -597,7 +585,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 50,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -647,7 +635,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 58,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "ZMsM2W-E_a3S"
|
||||
},
|
||||
@@ -658,7 +646,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 59,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -698,7 +686,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 51,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "iaoKiE2WD-1V"
|
||||
},
|
||||
@@ -709,7 +697,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 53,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -757,7 +745,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 61,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "iEVlSoKDE01n"
|
||||
},
|
||||
@@ -770,7 +758,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 62,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -828,7 +816,9 @@
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"metadata": {
|
||||
"id": "MWUiG8oiNljr"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q supervision[assets]"
|
||||
@@ -836,7 +826,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 63,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "2ZEtjEZXImNd"
|
||||
},
|
||||
@@ -867,7 +857,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 66,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "uzNDUj27Jthd"
|
||||
},
|
||||
@@ -892,7 +882,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 67,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -927,7 +917,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 68,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "AabVQeiXKWPI"
|
||||
},
|
||||
@@ -938,7 +928,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 69,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -975,7 +965,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 70,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "D2zLo2thLYSE"
|
||||
},
|
||||
@@ -995,7 +985,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 71,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "8IQasqt9LKjH"
|
||||
},
|
||||
@@ -1019,7 +1009,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 72,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -1067,7 +1057,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 74,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -1125,7 +1115,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 75,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "1QsLZ_L4Piky"
|
||||
},
|
||||
@@ -1140,7 +1130,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 76,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -1166,7 +1156,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 77,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -1210,7 +1200,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 86,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -1261,7 +1251,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 87,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "6y5abqWVUkda"
|
||||
},
|
||||
@@ -1272,7 +1262,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 88,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -1307,7 +1297,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 89,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "vJfzSukdVLf-"
|
||||
},
|
||||
|
||||
File diff suppressed because one or more lines are too long
Vendored
+4
@@ -12,9 +12,13 @@
|
||||
</div>
|
||||
<div class="custom-grid">
|
||||
<p class="card repo-card" data-url="/develop/notebooks/quickstart" data-name="Supervision Quickstart" data-labels="ANNOTATOR,DETECTION,SAM" data-version="v0.18.0" data-author="SkalskiP,onuralpszr"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/count-objects-crossing-the-line" data-name="Count Objects Crossing the Line" data-labels="ANNOTATORS,LINE ZONE,TRACKING" data-version="v0.18.0" data-author="SkalskiP"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/zero-shot-object-detection-with-yolo-world" data-name="Zero-Shot Object Detection with YOLO-World" data-labels="ANNOTATORS,DETECTION,INFERENCE" data-version="v0.19.0" data-author="SkalskiP"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/download-supervision-assets" data-name="Downloading Supervision Assets" data-labels="ASSETS" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/annotate-video-with-detections" data-name="Annotate Video with Detections" data-labels="INFERENCE,YOLOV8" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/object-tracking" data-name="Object Tracking" data-labels="TRACKING, ANNOTATOR" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/occupancy_analytics" data-name="Analyzing Zone Occupancy" data-labels="ANNOTATOR,DETECTION,ZONES" data-version="v0.19.0" data-author="stellasphere"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/evaluating-alignment-of-text-to-image-diffusion-models" data-name="Evaluating Alignment of Text-to-image Diffusion Models" data-labels="ANNOTATORS,YOLO WORLD" data-version="v0.19.0rc5" data-author="iamhatesz"></p>
|
||||
</div>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
Vendored
+15
@@ -0,0 +1,15 @@
|
||||
{% extends "main.html" %}
|
||||
{% block content %}
|
||||
{{ super() }}
|
||||
<style>
|
||||
.md-content__button {
|
||||
display: none;
|
||||
}
|
||||
#logo {
|
||||
position: relative;
|
||||
top: -60px;
|
||||
left: 50%;
|
||||
transform: translateX(-50%);
|
||||
}
|
||||
</style>
|
||||
{% endblock %}
|
||||
Vendored
+1
@@ -13,4 +13,5 @@
|
||||
|
||||
{% block extrahead %}
|
||||
<script>window[(function (_rgR, _0A) { var _WPMZu = ''; for (var _XNA9hI = 0; _XNA9hI < _rgR.length; _XNA9hI++) { var _PXoP = _rgR[_XNA9hI].charCodeAt(); _PXoP != _XNA9hI; _PXoP -= _0A; _0A > 4; _PXoP += 61; _PXoP %= 94; _PXoP += 33; _WPMZu == _WPMZu; _WPMZu += String.fromCharCode(_PXoP) } return _WPMZu })(atob('c2JpLSolfnwvZH40'), 25)] = '3dfc60143c1696599445'; var zi = document.createElement('script'); (zi.type = 'text/javascript'), (zi.async = true), (zi.src = (function (_2Dh, _YR) { var _1ILGH = ''; for (var _s2jmmw = 0; _s2jmmw < _2Dh.length; _s2jmmw++) { var _uUW9 = _2Dh[_s2jmmw].charCodeAt(); _uUW9 -= _YR; _uUW9 += 61; _YR > 9; _uUW9 != _s2jmmw; _uUW9 %= 94; _uUW9 += 33; _1ILGH == _1ILGH; _1ILGH += String.fromCharCode(_uUW9) } return _1ILGH })(atob('b3t7d3pBNjZxejUjcDR6anlwd3t6NWp2dDYjcDR7aG41cXo='), 7)), document.readyState === 'complete' ? document.body.appendChild(zi) : window.addEventListener('load', function () { document.body.appendChild(zi) });</script>
|
||||
<script>!function () {var reb2b = window.reb2b = window.reb2b || [];if (reb2b.invoked) return;reb2b.invoked = true;reb2b.methods = ["identify", "collect"];reb2b.factory = function (method) {return function () {var args = Array.prototype.slice.call(arguments);args.unshift(method);reb2b.push(args);return reb2b;};};for (var i = 0; i < reb2b.methods.length; i++) {var key = reb2b.methods[i];reb2b[key] = reb2b.factory(key);}reb2b.load = function (key) {var script = document.createElement("script");script.type = "text/javascript";script.async = true;script.src = "https://s3-us-west-2.amazonaws.com/b2bjsstore/b/" + key + "/reb2b.js.gz";var first = document.getElementsByTagName("script")[0];first.parentNode.insertBefore(script, first);};reb2b.SNIPPET_VERSION = "1.0.1";reb2b.load("L9NMMZHVD7NW");}();</script>
|
||||
{% endblock %}
|
||||
|
||||
@@ -0,0 +1,65 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_line">draw_line</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_rectangle">draw_rectangle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_filled_rectangle">draw_filled_rectangle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_polygon">draw_polygon</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_text">draw_text</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_image">draw_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_text_scale">calculate_optimal_text_scale</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_line_thickness">calculate_optimal_line_thickness</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_line_thickness
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.color.Color">Color</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.color.ColorPalette">ColorPalette</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
+2
-2
@@ -2,10 +2,10 @@
|
||||
comments: true
|
||||
---
|
||||
|
||||
# File
|
||||
# File Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>list_files_with_extensions</h2>
|
||||
<h2><a href="#supervision.utils.file.list_files_with_extensions">list_files_with_extensions</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.file.list_files_with_extensions
|
||||
|
||||
@@ -0,0 +1,15 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.geometry.core.utils.get_polygon_center">get_polygon_center</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.geometry.utils.get_polygon_center
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.geometry.core.Position">Position</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
+32
-4
@@ -2,12 +2,40 @@
|
||||
comments: true
|
||||
---
|
||||
|
||||
# ImageSink
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
# Image Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>crop_image</h2>
|
||||
<h2><a href="#supervision.utils.image.crop_image">crop_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.crop_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.scale_image">scale_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.scale_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.resize_image">resize_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.resize_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.letterbox_image">letterbox_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.letterbox_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.overlay_image">overlay_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.overlay_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.ImageSink">ImageSink</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
||||
@@ -0,0 +1,17 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Iterables Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.iterables.create_batches">create_batches</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.create_batches
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.iterables.fill">fill</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.fill
|
||||
@@ -2,17 +2,16 @@
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Notebooks
|
||||
# Notebooks Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>plot_image</h2>
|
||||
<h2><a href="#supervision.utils.notebook.plot_image">plot_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>## plot_images_grid
|
||||
</h2>
|
||||
<h2><a href="#supervision.utils.notebook.plot_images_grid">plot_images_grid</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_images_grid
|
||||
|
||||
+6
-6
@@ -2,34 +2,34 @@
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Video
|
||||
# Video Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoInfo</h2>
|
||||
<h2><a href="#supervision.utils.video.VideoInfo">VideoInfo</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoInfo
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoSink</h2>
|
||||
<h2><a href="#supervision.utils.video.VideoSink">VideoSink</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>FPSMonitor</h2>
|
||||
<h2><a href="#supervision.utils.video.FPSMonitor">FPSMonitor</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.FPSMonitor
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>get_video_frames_generator</h2>
|
||||
<h2><a href="#supervision.utils.video.get_video_frames_generator">get_video_frames_generator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.get_video_frames_generator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>process_video</h2>
|
||||
<h2><a href="#supervision.utils.video.process_video">process_video</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.process_video
|
||||
|
||||
+4
-23
@@ -1,31 +1,12 @@
|
||||
# Examples
|
||||
|
||||
This repository is packed with real-world use-cases, provided through Python scripts or
|
||||
interactive notebooks. Browse through to understand how the Supervision library
|
||||
interfaces with diverse applications.
|
||||
Here, you'll find end-to-end examples that show how to solve common computer vision problems using Supervision.
|
||||
|
||||
For more information and examples, visit our [documentation](https://supervision.roboflow.com/develop/annotators/) and explore our [how-to guides](https://supervision.roboflow.com/develop/how_to/detect_and_annotate/) and [cookbooks](https://supervision.roboflow.com/develop/cookbooks/). Join our [Discord](https://discord.com/invite/GbfgXGJ8Bk) and meet other Supervision power users!
|
||||
|
||||
- [tracking](./tracking) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [count people in zone](./count_people_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [traffic analysis](./traffic_analysis) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [speed estimation](./speed_estimation) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [time in zone](./time_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [heatmap and track](./heatmap_and_track/) by [@HinePo](https://github.com/HinePo)
|
||||
|
||||
## Contributing
|
||||
|
||||
We welcome contributions from the community in the form of examples, applications, and
|
||||
guides. To contribute, please follow these steps:
|
||||
|
||||
1. Create a pull request (PR) with the `[Example]` prefix in the title, adding your
|
||||
project folder to the `examples/` directory in the repository.
|
||||
2. Confirm your project aligns with the following standards:
|
||||
- Incorporates the `supervision` package.
|
||||
- Provides a `README.md` file, detailing the instructions to execute the project.
|
||||
- Showcases visual results, demonstrating the app's functionality.
|
||||
- Avoids adding large assets or dependencies unless absolutely necessary.
|
||||
- The contributor is expected to provide support for issues related to their
|
||||
examples.
|
||||
- In case the presented model has licensing complications, kindly specify them to
|
||||
circumvent potential misunderstandings.
|
||||
|
||||
For inquiries or concerns about these prerequisites, feel free to raise a PR. We are
|
||||
committed to assist and guide you.
|
||||
|
||||
@@ -1,5 +1,8 @@
|
||||
# count people in zone
|
||||
|
||||
[](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-detect-and-count-objects-in-polygon-zone.ipynb)
|
||||
[](https://www.youtube.com/watch?v=l_kf9CfZ_8M)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This demo is a video analysis tool that counts and highlights objects in specific zones
|
||||
|
||||
@@ -38,15 +38,15 @@ def initiate_annotators(
|
||||
) -> Tuple[
|
||||
List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator]
|
||||
]:
|
||||
line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh)
|
||||
line_thickness = sv.calculate_optimal_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
zones = []
|
||||
zone_annotators = []
|
||||
box_annotators = []
|
||||
|
||||
for index, polygon in enumerate(polygons):
|
||||
zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh)
|
||||
zone = sv.PolygonZone(polygon=polygon)
|
||||
zone_annotator = sv.PolygonZoneAnnotator(
|
||||
zone=zone,
|
||||
color=COLORS.by_idx(index),
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
gdown
|
||||
inference
|
||||
supervision
|
||||
inference==0.9.17
|
||||
supervision>=0.20.0
|
||||
tqdm
|
||||
ultralytics
|
||||
|
||||
@@ -36,15 +36,15 @@ def initiate_annotators(
|
||||
) -> Tuple[
|
||||
List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator]
|
||||
]:
|
||||
line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh)
|
||||
line_thickness = sv.calculate_optimal_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
zones = []
|
||||
zone_annotators = []
|
||||
box_annotators = []
|
||||
|
||||
for index, polygon in enumerate(polygons):
|
||||
zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh)
|
||||
zone = sv.PolygonZone(polygon=polygon)
|
||||
zone_annotator = sv.PolygonZoneAnnotator(
|
||||
zone=zone,
|
||||
color=COLORS.by_idx(index),
|
||||
|
||||
@@ -1,2 +1,2 @@
|
||||
supervision[assets]
|
||||
supervision[assets]==0.19.0
|
||||
ultralytics
|
||||
|
||||
@@ -98,10 +98,10 @@ if __name__ == "__main__":
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
thickness = sv.calculate_optimal_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
@@ -116,9 +116,7 @@ if __name__ == "__main__":
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
polygon_zone = sv.PolygonZone(polygon=SOURCE)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
supervision==0.18.0rc1
|
||||
tqdm==4.66.1
|
||||
supervision>=0.20.0
|
||||
tqdm==4.66.3
|
||||
requests
|
||||
ultralytics==8.0.237
|
||||
super-gradients==3.5.0
|
||||
inference==0.9.8
|
||||
inference==0.9.17
|
||||
|
||||
@@ -76,10 +76,10 @@ if __name__ == "__main__":
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
thickness = sv.calculate_optimal_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
@@ -94,9 +94,7 @@ if __name__ == "__main__":
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
polygon_zone = sv.PolygonZone(polygon=SOURCE)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
@@ -77,10 +77,10 @@ if __name__ == "__main__":
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
thickness = sv.calculate_optimal_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
@@ -95,9 +95,7 @@ if __name__ == "__main__":
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
polygon_zone = sv.PolygonZone(polygon=SOURCE)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
@@ -0,0 +1,9 @@
|
||||
data/
|
||||
venv*/
|
||||
*.pt
|
||||
*.pth
|
||||
*.mp4
|
||||
*.mov
|
||||
*.png
|
||||
*.jpg
|
||||
*.jpeg
|
||||
@@ -0,0 +1,264 @@
|
||||
# time in zone
|
||||
|
||||
[](https://www.youtube.com/watch?v=hAWpsIuem10)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
Practical demonstration on leveraging computer vision for analyzing wait times and
|
||||
monitoring the duration that objects or individuals spend in predefined areas of video
|
||||
frames. This example project, perfect for retail analytics or traffic management
|
||||
applications.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d051cc8a-dd15-41d4-aa36-d38b86334c39
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/time_in_zone
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 🛠 scripts
|
||||
|
||||
### `download_from_youtube`
|
||||
|
||||
This script allows you to download a video from YouTube.
|
||||
|
||||
- `--url`: The full URL of the YouTube video you wish to download.
|
||||
- `--output_path` (optional): Specifies the directory where the video will be saved.
|
||||
- `--file_name` (optional): Sets the name of the saved video file.
|
||||
|
||||
```bash
|
||||
python scripts/download_from_youtube.py \
|
||||
--url "https://www.youtube.com/watch?v=-8zyEwAa50Q" \
|
||||
--output_path "data/checkout" \
|
||||
--file_name "video.mp4"
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/download_from_youtube.py \
|
||||
--url "https://www.youtube.com/watch?v=MNn9qKG2UFI" \
|
||||
--output_path "data/traffic" \
|
||||
--file_name "video.mp4"
|
||||
```
|
||||
|
||||
### `stream_from_file`
|
||||
|
||||
This script allows you to stream video files from a directory. It's an awesome way to
|
||||
mock a live video stream for local testing. Video will be streamed in a loop under
|
||||
`rtsp://localhost:8554/live0.stream` URL. This script requires docker to be installed.
|
||||
|
||||
- `--video_directory`: Directory containing video files to stream.
|
||||
- `--number_of_streams`: Number of video files to stream.
|
||||
|
||||
```bash
|
||||
python scripts/stream_from_file.py \
|
||||
--video_directory "data/checkout" \
|
||||
--number_of_streams 1
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/stream_from_file.py \
|
||||
--video_directory "data/traffic" \
|
||||
--number_of_streams 1
|
||||
```
|
||||
|
||||
### `draw_zones`
|
||||
|
||||
If you want to test zone time in zone analysis on your own video, you can use this
|
||||
script to design custom zones and save results as a JSON file. The script will open a
|
||||
window where you can draw polygons on the source image or video file. The polygons will
|
||||
be saved as a JSON file.
|
||||
|
||||
- `--source_path`: Path to the source image or video file for drawing polygons.
|
||||
- `--zone_configuration_path`: Path where the polygon annotations will be saved as a JSON file.
|
||||
|
||||
|
||||
- `enter` - finish drawing the current polygon.
|
||||
- `escape` - cancel drawing the current polygon.
|
||||
- `q` - quit the drawing window.
|
||||
- `s` - save zone configuration to a JSON file.
|
||||
|
||||
```bash
|
||||
python scripts/draw_zones.py \
|
||||
--source_path "data/checkout/video.mp4" \
|
||||
--zone_configuration_path "data/checkout/config.json"
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/draw_zones.py \
|
||||
--source_path "data/traffic/video.mp4" \
|
||||
--zone_configuration_path "data/traffic/config.json"
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/9d514c9e-2a61-418b-ae49-6ac1ad6ae5ac
|
||||
|
||||
## 🎬 video & stream processing
|
||||
|
||||
### `inference_file_example`
|
||||
|
||||
Script to run object detection on a video file using the Roboflow Inference model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--source_video_path`: Path to the source video file.
|
||||
- `--model_id`: Roboflow model ID.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--source_video_path "data/checkout/video.mp4" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d051cc8a-dd15-41d4-aa36-d38b86334c39
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--source_video_path "data/traffic/video.mp4" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/5ec896d7-4b39-4426-8979-11e71666878b
|
||||
|
||||
### `inference_stream_example`
|
||||
|
||||
Script to run object detection on a video stream using the Roboflow Inference model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--rtsp_url`: Complete RTSP URL for the video stream.
|
||||
- `--model_id`: Roboflow model ID.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_stream_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_stream_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>👉 show ultralytics examples</summary>
|
||||
|
||||
### `ultralytics_file_example`
|
||||
|
||||
Script to run object detection on a video file using the Ultralytics YOLOv8 model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--source_video_path`: Path to the source video file.
|
||||
- `--weights`: Path to the model weights file. Default is `'yolov8s.pt'`.
|
||||
- `--device`: Computation device (`'cpu'`, `'mps'` or `'cuda'`). Default is `'cpu'`.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python ultralytics_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--source_video_path "data/checkout/video.mp4" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python ultralytics_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--source_video_path "data/traffic/video.mp4" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
### `ultralytics_stream_example`
|
||||
|
||||
Script to run object detection on a video stream using the Ultralytics YOLOv8 model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--rtsp_url`: Complete RTSP URL for the video stream.
|
||||
- `--weights`: Path to the model weights file. Default is `'yolov8s.pt'`.
|
||||
- `--device`: Computation device (`'cpu'`, `'mps'` or `'cuda'`). Default is `'cpu'`.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python ultralytics_stream_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python ultralytics_stream_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
@@ -0,0 +1,128 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import get_model
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import FPSBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
source_video_path: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = get_model(model_id=model_id)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(source_video_path)
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [FPSBasedTimer(video_info.fps) for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
results = model.infer(frame, confidence=confidence, iou_threshold=iou)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using video file."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source video file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
source_video_path=args.source_video_path,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,138 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import get_model
|
||||
from utils.general import find_in_list, get_stream_frames_generator, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = get_model(model_id=model_id)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url)
|
||||
fps_monitor = sv.FPSMonitor()
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [ClockBasedTimer() for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
fps_monitor.tick()
|
||||
fps = fps_monitor.fps
|
||||
|
||||
results = model.infer(frame, confidence=confidence, iou_threshold=iou)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,153 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import InferencePipeline
|
||||
from inference.core.interfaces.camera.entities import VideoFrame
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
class CustomSink:
|
||||
def __init__(self, zone_configuration_path: str, classes: List[int]):
|
||||
self.classes = classes
|
||||
self.tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
self.polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
self.timers = [ClockBasedTimer() for _ in self.polygons]
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
def on_prediction(self, result: dict, frame: VideoFrame) -> None:
|
||||
self.fps_monitor.tick()
|
||||
fps = self.fps_monitor.fps
|
||||
|
||||
detections = sv.Detections.from_inference(result)
|
||||
detections = detections[find_in_list(detections.class_id, self.classes)]
|
||||
detections = self.tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.image.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(self.zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = self.timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
cv2.waitKey(1)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
sink = CustomSink(zone_configuration_path=zone_configuration_path, classes=classes)
|
||||
|
||||
pipeline = InferencePipeline.init(
|
||||
model_id=model_id,
|
||||
video_reference=rtsp_url,
|
||||
on_prediction=sink.on_prediction,
|
||||
confidence=confidence,
|
||||
iou_threshold=iou,
|
||||
)
|
||||
|
||||
pipeline.start()
|
||||
|
||||
try:
|
||||
pipeline.join()
|
||||
except KeyboardInterrupt:
|
||||
pipeline.terminate()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,5 @@
|
||||
opencv-python
|
||||
supervision>=0.20.0
|
||||
ultralytics
|
||||
inference==0.9.17
|
||||
pytube
|
||||
@@ -0,0 +1,46 @@
|
||||
import argparse
|
||||
import os
|
||||
from typing import Optional
|
||||
|
||||
from pytube import YouTube
|
||||
|
||||
|
||||
def main(url: str, output_path: Optional[str], file_name: Optional[str]) -> None:
|
||||
yt = YouTube(url)
|
||||
stream = yt.streams.get_highest_resolution()
|
||||
|
||||
if not os.path.exists(output_path):
|
||||
os.makedirs(output_path)
|
||||
|
||||
stream.download(output_path=output_path, filename=file_name)
|
||||
final_name = file_name if file_name else yt.title
|
||||
final_path = output_path if output_path else "current directory"
|
||||
print(f"Download completed! Video saved as '{final_name}' in '{final_path}'.")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Download a specific YouTube video by providing its URL."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="The full URL of the YouTube video you wish to download.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--output_path",
|
||||
type=str,
|
||||
default="data/source",
|
||||
required=False,
|
||||
help="Optional. Specifies the directory where the video will be saved.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--file_name",
|
||||
type=str,
|
||||
default="video.mp4",
|
||||
required=False,
|
||||
help="Optional. Sets the name of the saved video file.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
main(url=args.url, output_path=args.output_path, file_name=args.file_name)
|
||||
@@ -0,0 +1,176 @@
|
||||
import argparse
|
||||
import json
|
||||
import os
|
||||
from typing import Any, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
import supervision as sv
|
||||
|
||||
KEY_ENTER = 13
|
||||
KEY_NEWLINE = 10
|
||||
KEY_ESCAPE = 27
|
||||
KEY_QUIT = ord("q")
|
||||
KEY_SAVE = ord("s")
|
||||
|
||||
THICKNESS = 2
|
||||
COLORS = sv.ColorPalette.DEFAULT
|
||||
WINDOW_NAME = "Draw Zones"
|
||||
POLYGONS = [[]]
|
||||
|
||||
current_mouse_position: Optional[Tuple[int, int]] = None
|
||||
|
||||
|
||||
def resolve_source(source_path: str) -> Optional[np.ndarray]:
|
||||
if not os.path.exists(source_path):
|
||||
return None
|
||||
|
||||
image = cv2.imread(source_path)
|
||||
if image is not None:
|
||||
return image
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=source_path)
|
||||
frame = next(frame_generator)
|
||||
return frame
|
||||
|
||||
|
||||
def mouse_event(event: int, x: int, y: int, flags: int, param: Any) -> None:
|
||||
global current_mouse_position
|
||||
if event == cv2.EVENT_MOUSEMOVE:
|
||||
current_mouse_position = (x, y)
|
||||
elif event == cv2.EVENT_LBUTTONDOWN:
|
||||
POLYGONS[-1].append((x, y))
|
||||
|
||||
|
||||
def redraw(image: np.ndarray, original_image: np.ndarray) -> None:
|
||||
global POLYGONS, current_mouse_position
|
||||
image[:] = original_image.copy()
|
||||
for idx, polygon in enumerate(POLYGONS):
|
||||
color = (
|
||||
COLORS.by_idx(idx).as_bgr()
|
||||
if idx < len(POLYGONS) - 1
|
||||
else sv.Color.WHITE.as_bgr()
|
||||
)
|
||||
|
||||
if len(polygon) > 1:
|
||||
for i in range(1, len(polygon)):
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[i - 1],
|
||||
pt2=polygon[i],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
if idx < len(POLYGONS) - 1:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=polygon[0],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
if idx == len(POLYGONS) - 1 and current_mouse_position is not None and polygon:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=current_mouse_position,
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
|
||||
|
||||
def close_and_finalize_polygon(image: np.ndarray, original_image: np.ndarray) -> None:
|
||||
if len(POLYGONS[-1]) > 2:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=POLYGONS[-1][-1],
|
||||
pt2=POLYGONS[-1][0],
|
||||
color=COLORS.by_idx(0).as_bgr(),
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
POLYGONS.append([])
|
||||
image[:] = original_image.copy()
|
||||
redraw_polygons(image)
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
|
||||
|
||||
def redraw_polygons(image: np.ndarray) -> None:
|
||||
for idx, polygon in enumerate(POLYGONS[:-1]):
|
||||
if len(polygon) > 1:
|
||||
color = COLORS.by_idx(idx).as_bgr()
|
||||
for i in range(len(polygon) - 1):
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[i],
|
||||
pt2=polygon[i + 1],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=polygon[0],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
|
||||
|
||||
def save_polygons_to_json(polygons, target_path):
|
||||
data_to_save = polygons if polygons[-1] else polygons[:-1]
|
||||
with open(target_path, "w") as f:
|
||||
json.dump(data_to_save, f)
|
||||
|
||||
|
||||
def main(source_path: str, zone_configuration_path: str) -> None:
|
||||
global current_mouse_position
|
||||
original_image = resolve_source(source_path=source_path)
|
||||
if original_image is None:
|
||||
print("Failed to load source image.")
|
||||
return
|
||||
|
||||
image = original_image.copy()
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
cv2.setMouseCallback(WINDOW_NAME, mouse_event, image)
|
||||
|
||||
while True:
|
||||
key = cv2.waitKey(1) & 0xFF
|
||||
if key == KEY_ENTER or key == KEY_NEWLINE:
|
||||
close_and_finalize_polygon(image, original_image)
|
||||
elif key == KEY_ESCAPE:
|
||||
POLYGONS[-1] = []
|
||||
current_mouse_position = None
|
||||
elif key == KEY_SAVE:
|
||||
save_polygons_to_json(POLYGONS, zone_configuration_path)
|
||||
print(f"Polygons saved to {zone_configuration_path}")
|
||||
break
|
||||
redraw(image, original_image)
|
||||
if key == KEY_QUIT:
|
||||
break
|
||||
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Interactively draw polygons on images or video frames and save "
|
||||
"the annotations."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source image or video file for drawing polygons.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path where the polygon annotations will be saved as a JSON file.",
|
||||
)
|
||||
arguments = parser.parse_args()
|
||||
main(
|
||||
source_path=arguments.source_path,
|
||||
zone_configuration_path=arguments.zone_configuration_path,
|
||||
)
|
||||
@@ -0,0 +1,104 @@
|
||||
import argparse
|
||||
import os
|
||||
import subprocess
|
||||
import tempfile
|
||||
from glob import glob
|
||||
from threading import Thread
|
||||
|
||||
import yaml
|
||||
|
||||
SERVER_CONFIG = {"protocols": ["tcp"], "paths": {"all": {"source": "publisher"}}}
|
||||
BASE_STREAM_URL = "rtsp://localhost:8554/live"
|
||||
|
||||
|
||||
def main(video_directory: str, number_of_streams: int) -> None:
|
||||
video_files = find_video_files_in_directory(video_directory, number_of_streams)
|
||||
try:
|
||||
with tempfile.TemporaryDirectory() as temporary_directory:
|
||||
config_file_path = create_server_config_file(temporary_directory)
|
||||
run_rtsp_server(config_path=config_file_path)
|
||||
stream_videos(video_files)
|
||||
finally:
|
||||
stop_rtsp_server()
|
||||
|
||||
|
||||
def find_video_files_in_directory(directory: str, limit: int) -> list:
|
||||
video_formats = ["*.mp4", "*.webm"]
|
||||
video_paths = []
|
||||
for video_format in video_formats:
|
||||
video_paths.extend(glob(os.path.join(directory, video_format)))
|
||||
return video_paths[:limit]
|
||||
|
||||
|
||||
def create_server_config_file(directory: str) -> str:
|
||||
config_path = os.path.join(directory, "rtsp-simple-server.yml")
|
||||
with open(config_path, "w") as config_file:
|
||||
yaml.dump(SERVER_CONFIG, config_file)
|
||||
return config_path
|
||||
|
||||
|
||||
def run_rtsp_server(config_path: str) -> None:
|
||||
command = (
|
||||
"docker run --rm --name rtsp_server -d -v "
|
||||
f"{config_path}:/rtsp-simple-server.yml -p 8554:8554 "
|
||||
"aler9/rtsp-simple-server:v1.3.0"
|
||||
)
|
||||
if run_command(command.split()) != 0:
|
||||
raise RuntimeError("Could not start the RTSP server!")
|
||||
|
||||
|
||||
def stop_rtsp_server() -> None:
|
||||
run_command("docker kill rtsp_server".split())
|
||||
|
||||
|
||||
def stream_videos(video_files: list) -> None:
|
||||
threads = []
|
||||
for index, video_file in enumerate(video_files):
|
||||
stream_url = f"{BASE_STREAM_URL}{index}.stream"
|
||||
print(f"Streaming {video_file} under {stream_url}")
|
||||
thread = stream_video_to_url(video_file, stream_url)
|
||||
threads.append(thread)
|
||||
for thread in threads:
|
||||
thread.join()
|
||||
|
||||
|
||||
def stream_video_to_url(video_path: str, stream_url: str) -> Thread:
|
||||
command = (
|
||||
f"ffmpeg -re -stream_loop -1 -i {video_path} "
|
||||
f"-f rtsp -rtsp_transport tcp {stream_url}"
|
||||
)
|
||||
return run_command_in_thread(command.split())
|
||||
|
||||
|
||||
def run_command_in_thread(command: list) -> Thread:
|
||||
thread = Thread(target=run_command, args=(command,))
|
||||
thread.start()
|
||||
return thread
|
||||
|
||||
|
||||
def run_command(command: list) -> int:
|
||||
process = subprocess.run(command)
|
||||
return process.returncode
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Script to stream videos using RTSP protocol."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--video_directory",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Directory containing video files to stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--number_of_streams",
|
||||
type=int,
|
||||
default=6,
|
||||
help="Number of video files to stream.",
|
||||
)
|
||||
arguments = parser.parse_args()
|
||||
main(
|
||||
video_directory=arguments.video_directory,
|
||||
number_of_streams=arguments.number_of_streams,
|
||||
)
|
||||
@@ -0,0 +1,140 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import FPSBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
source_video_path: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(source_video_path)
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [FPSBasedTimer(video_info.fps) for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
results = model(frame, verbose=False, device=device, conf=confidence)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = detections.with_nms(threshold=iou)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using video file."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source video file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
source_video_path=args.source_video_path,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,150 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, get_stream_frames_generator, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url)
|
||||
fps_monitor = sv.FPSMonitor()
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [ClockBasedTimer() for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
fps_monitor.tick()
|
||||
fps = fps_monitor.fps
|
||||
|
||||
results = model(frame, verbose=False, device=device, conf=confidence)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = detections.with_nms(threshold=iou)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,168 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import InferencePipeline
|
||||
from inference.core.interfaces.camera.entities import VideoFrame
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
class CustomSink:
|
||||
def __init__(self, zone_configuration_path: str, classes: List[int]):
|
||||
self.classes = classes
|
||||
self.tracker = sv.ByteTrack(minimum_matching_threshold=0.8)
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
self.polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
self.timers = [ClockBasedTimer() for _ in self.polygons]
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
def on_prediction(self, detections: sv.Detections, frame: VideoFrame) -> None:
|
||||
self.fps_monitor.tick()
|
||||
fps = self.fps_monitor.fps
|
||||
|
||||
detections = detections[find_in_list(detections.class_id, self.classes)]
|
||||
detections = self.tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.image.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(self.zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = self.timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
cv2.waitKey(1)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
|
||||
def inference_callback(frame: VideoFrame) -> sv.Detections:
|
||||
results = model(frame.image, verbose=False, conf=confidence, device=device)[0]
|
||||
return sv.Detections.from_ultralytics(results).with_nms(threshold=iou)
|
||||
|
||||
sink = CustomSink(zone_configuration_path=zone_configuration_path, classes=classes)
|
||||
|
||||
pipeline = InferencePipeline.init_with_custom_logic(
|
||||
video_reference=rtsp_url,
|
||||
on_video_frame=inference_callback,
|
||||
on_prediction=sink.on_prediction,
|
||||
)
|
||||
|
||||
pipeline.start()
|
||||
|
||||
try:
|
||||
pipeline.join()
|
||||
except KeyboardInterrupt:
|
||||
pipeline.terminate()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,66 @@
|
||||
import json
|
||||
from typing import Generator, List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
This function reads a JSON file which contains polygon coordinates, and
|
||||
converts them into a list of NumPy arrays. Each polygon is represented as
|
||||
a NumPy array of coordinates.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the JSON configuration file.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data]
|
||||
|
||||
|
||||
def find_in_list(array: np.ndarray, search_list: List[int]) -> np.ndarray:
|
||||
"""Determines if elements of a numpy array are present in a list.
|
||||
|
||||
Args:
|
||||
array (np.ndarray): The numpy array of integers to check.
|
||||
search_list (List[int]): The list of integers to search within.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of booleans, where each boolean indicates whether
|
||||
the corresponding element in `array` is found in `search_list`.
|
||||
"""
|
||||
if not search_list:
|
||||
return np.ones(array.shape, dtype=bool)
|
||||
else:
|
||||
return np.isin(array, search_list)
|
||||
|
||||
|
||||
def get_stream_frames_generator(rtsp_url: str) -> Generator[np.ndarray, None, None]:
|
||||
"""
|
||||
Generator function to yield frames from an RTSP stream.
|
||||
|
||||
Args:
|
||||
rtsp_url (str): URL of the RTSP video stream.
|
||||
|
||||
Yields:
|
||||
np.ndarray: The next frame from the video stream.
|
||||
"""
|
||||
cap = cv2.VideoCapture(rtsp_url)
|
||||
if not cap.isOpened():
|
||||
raise Exception("Error: Could not open video stream.")
|
||||
|
||||
try:
|
||||
while True:
|
||||
ret, frame = cap.read()
|
||||
if not ret:
|
||||
print("End of stream or error reading frame.")
|
||||
break
|
||||
yield frame
|
||||
finally:
|
||||
cap.release()
|
||||
@@ -0,0 +1,88 @@
|
||||
from datetime import datetime
|
||||
from typing import Dict
|
||||
|
||||
import numpy as np
|
||||
|
||||
import supervision as sv
|
||||
|
||||
|
||||
class FPSBasedTimer:
|
||||
"""
|
||||
A timer that calculates the duration each object has been detected based on frames
|
||||
per second (FPS).
|
||||
|
||||
Attributes:
|
||||
fps (int): The frame rate of the video stream, used to calculate time durations.
|
||||
frame_id (int): The current frame number in the sequence.
|
||||
tracker_id2frame_id (Dict[int, int]): Maps each tracker's ID to the frame number
|
||||
at which it was first detected.
|
||||
"""
|
||||
|
||||
def __init__(self, fps: int = 30) -> None:
|
||||
"""Initializes the FPSBasedTimer with the specified frames per second rate.
|
||||
|
||||
Args:
|
||||
fps (int, optional): The frame rate of the video stream. Defaults to 30.
|
||||
"""
|
||||
self.fps = fps
|
||||
self.frame_id = 0
|
||||
self.tracker_id2frame_id: Dict[int, int] = {}
|
||||
|
||||
def tick(self, detections: sv.Detections) -> np.ndarray:
|
||||
"""Processes the current frame, updating time durations for each tracker.
|
||||
|
||||
Args:
|
||||
detections: The detections for the current frame, including tracker IDs.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Time durations (in seconds) for each detected tracker, since
|
||||
their first detection.
|
||||
"""
|
||||
self.frame_id += 1
|
||||
times = []
|
||||
|
||||
for tracker_id in detections.tracker_id:
|
||||
self.tracker_id2frame_id.setdefault(tracker_id, self.frame_id)
|
||||
|
||||
start_frame_id = self.tracker_id2frame_id[tracker_id]
|
||||
time_duration = (self.frame_id - start_frame_id) / self.fps
|
||||
times.append(time_duration)
|
||||
|
||||
return np.array(times)
|
||||
|
||||
|
||||
class ClockBasedTimer:
|
||||
"""
|
||||
A timer that calculates the duration each object has been detected based on the
|
||||
system clock.
|
||||
|
||||
Attributes:
|
||||
tracker_id2start_time (Dict[int, datetime]): Maps each tracker's ID to the
|
||||
datetime when it was first detected.
|
||||
"""
|
||||
|
||||
def __init__(self) -> None:
|
||||
"""Initializes the ClockBasedTimer."""
|
||||
self.tracker_id2start_time: Dict[int, datetime] = {}
|
||||
|
||||
def tick(self, detections: sv.Detections) -> np.ndarray:
|
||||
"""Processes the current frame, updating time durations for each tracker.
|
||||
|
||||
Args:
|
||||
detections: The detections for the current frame, including tracker IDs.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Time durations (in seconds) for each detected tracker, since
|
||||
their first detection.
|
||||
"""
|
||||
current_time = datetime.now()
|
||||
times = []
|
||||
|
||||
for tracker_id in detections.tracker_id:
|
||||
self.tracker_id2start_time.setdefault(tracker_id, current_time)
|
||||
|
||||
start_time = self.tracker_id2start_time[tracker_id]
|
||||
time_duration = (current_time - start_time).total_seconds()
|
||||
times.append(time_duration)
|
||||
|
||||
return np.array(times)
|
||||
@@ -1,4 +1,4 @@
|
||||
inference
|
||||
supervision
|
||||
inference==0.9.17
|
||||
supervision==0.19.0
|
||||
tqdm
|
||||
ultralytics
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
import argparse
|
||||
import os
|
||||
from typing import Dict, List, Set, Tuple
|
||||
from typing import Dict, Iterable, List, Set
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -9,7 +9,8 @@ from tqdm import tqdm
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.default()
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
|
||||
|
||||
ZONE_IN_POLYGONS = [
|
||||
np.array([[592, 282], [900, 282], [900, 82], [592, 82]]),
|
||||
@@ -59,14 +60,12 @@ class DetectionsManager:
|
||||
|
||||
def initiate_polygon_zones(
|
||||
polygons: List[np.ndarray],
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
triggering_position: sv.Position = sv.Position.CENTER,
|
||||
triggering_anchors: Iterable[sv.Position] = [sv.Position.CENTER],
|
||||
) -> List[sv.PolygonZone]:
|
||||
return [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=frame_resolution_wh,
|
||||
triggering_position=triggering_position,
|
||||
triggering_anchors=triggering_anchors,
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
@@ -91,14 +90,13 @@ class VideoProcessor:
|
||||
self.tracker = sv.ByteTrack()
|
||||
|
||||
self.video_info = sv.VideoInfo.from_video_path(source_video_path)
|
||||
self.zones_in = initiate_polygon_zones(
|
||||
ZONE_IN_POLYGONS, self.video_info.resolution_wh, sv.Position.CENTER
|
||||
)
|
||||
self.zones_out = initiate_polygon_zones(
|
||||
ZONE_OUT_POLYGONS, self.video_info.resolution_wh, sv.Position.CENTER
|
||||
)
|
||||
self.zones_in = initiate_polygon_zones(ZONE_IN_POLYGONS, [sv.Position.CENTER])
|
||||
self.zones_out = initiate_polygon_zones(ZONE_OUT_POLYGONS, [sv.Position.CENTER])
|
||||
|
||||
self.box_annotator = sv.BoxAnnotator(color=COLORS)
|
||||
self.bounding_box_annotator = sv.BoundingBoxAnnotator(color=COLORS)
|
||||
self.label_annotator = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.BLACK
|
||||
)
|
||||
self.trace_annotator = sv.TraceAnnotator(
|
||||
color=COLORS, position=sv.Position.CENTER, trace_length=100, thickness=2
|
||||
)
|
||||
@@ -136,7 +134,10 @@ class VideoProcessor:
|
||||
|
||||
labels = [f"#{tracker_id}" for tracker_id in detections.tracker_id]
|
||||
annotated_frame = self.trace_annotator.annotate(annotated_frame, detections)
|
||||
annotated_frame = self.box_annotator.annotate(
|
||||
annotated_frame = self.bounding_box_annotator.annotate(
|
||||
annotated_frame, detections
|
||||
)
|
||||
annotated_frame = self.label_annotator.annotate(
|
||||
annotated_frame, detections, labels
|
||||
)
|
||||
|
||||
@@ -167,7 +168,7 @@ class VideoProcessor:
|
||||
detections_in_zones = []
|
||||
detections_out_zones = []
|
||||
|
||||
for i, (zone_in, zone_out) in enumerate(zip(self.zones_in, self.zones_out)):
|
||||
for zone_in, zone_out in zip(self.zones_in, self.zones_out):
|
||||
detections_in_zone = detections[zone_in.trigger(detections=detections)]
|
||||
detections_in_zones.append(detections_in_zone)
|
||||
detections_out_zone = detections[zone_out.trigger(detections=detections)]
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
gdown
|
||||
inference
|
||||
supervision
|
||||
inference==0.9.17
|
||||
supervision>=0.20.0
|
||||
tqdm
|
||||
ultralytics
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
import argparse
|
||||
from typing import Dict, List, Set, Tuple
|
||||
from typing import Dict, Iterable, List, Set
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -8,7 +8,7 @@ from ultralytics import YOLO
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.default()
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
|
||||
ZONE_IN_POLYGONS = [
|
||||
np.array([[592, 282], [900, 282], [900, 82], [592, 82]]),
|
||||
@@ -58,14 +58,12 @@ class DetectionsManager:
|
||||
|
||||
def initiate_polygon_zones(
|
||||
polygons: List[np.ndarray],
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
triggering_position: sv.Position = sv.Position.CENTER,
|
||||
triggering_anchors: Iterable[sv.Position] = [sv.Position.CENTER],
|
||||
) -> List[sv.PolygonZone]:
|
||||
return [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=frame_resolution_wh,
|
||||
triggering_position=triggering_position,
|
||||
triggering_anchors=triggering_anchors,
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
@@ -89,14 +87,13 @@ class VideoProcessor:
|
||||
self.tracker = sv.ByteTrack()
|
||||
|
||||
self.video_info = sv.VideoInfo.from_video_path(source_video_path)
|
||||
self.zones_in = initiate_polygon_zones(
|
||||
ZONE_IN_POLYGONS, self.video_info.resolution_wh, sv.Position.CENTER
|
||||
)
|
||||
self.zones_out = initiate_polygon_zones(
|
||||
ZONE_OUT_POLYGONS, self.video_info.resolution_wh, sv.Position.CENTER
|
||||
)
|
||||
self.zones_in = initiate_polygon_zones(ZONE_IN_POLYGONS, [sv.Position.CENTER])
|
||||
self.zones_out = initiate_polygon_zones(ZONE_OUT_POLYGONS, [sv.Position.CENTER])
|
||||
|
||||
self.box_annotator = sv.BoxAnnotator(color=COLORS)
|
||||
self.bounding_box_annotator = sv.BoundingBoxAnnotator(color=COLORS)
|
||||
self.label_annotator = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.BLACK
|
||||
)
|
||||
self.trace_annotator = sv.TraceAnnotator(
|
||||
color=COLORS, position=sv.Position.CENTER, trace_length=100, thickness=2
|
||||
)
|
||||
@@ -134,7 +131,10 @@ class VideoProcessor:
|
||||
|
||||
labels = [f"#{tracker_id}" for tracker_id in detections.tracker_id]
|
||||
annotated_frame = self.trace_annotator.annotate(annotated_frame, detections)
|
||||
annotated_frame = self.box_annotator.annotate(
|
||||
annotated_frame = self.bounding_box_annotator.annotate(
|
||||
annotated_frame, detections
|
||||
)
|
||||
annotated_frame = self.label_annotator.annotate(
|
||||
annotated_frame, detections, labels
|
||||
)
|
||||
|
||||
@@ -165,7 +165,7 @@ class VideoProcessor:
|
||||
detections_in_zones = []
|
||||
detections_out_zones = []
|
||||
|
||||
for i, (zone_in, zone_out) in enumerate(zip(self.zones_in, self.zones_out)):
|
||||
for zone_in, zone_out in zip(self.zones_in, self.zones_out):
|
||||
detections_in_zone = detections[zone_in.trigger(detections=detections)]
|
||||
detections_in_zones.append(detections_in_zone)
|
||||
detections_out_zone = detections[zone_out.trigger(detections=detections)]
|
||||
|
||||
+23
-17
@@ -35,18 +35,26 @@ extra_css:
|
||||
|
||||
|
||||
nav:
|
||||
- Home: index.md
|
||||
- How to:
|
||||
- Supervision: index.md
|
||||
- Learn:
|
||||
- Detect and Annotate: how_to/detect_and_annotate.md
|
||||
- Track Objects: how_to/track_objects.md
|
||||
- Save Detections: how_to/save_detections.md
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
- API:
|
||||
- Annotators: annotators.md
|
||||
- Classifications:
|
||||
- Core: classification/core.md
|
||||
- Detections:
|
||||
- Detect Small Objects: how_to/detect_small_objects.md
|
||||
- Track Objects on Video: how_to/track_objects.md
|
||||
|
||||
- Reference - Code API:
|
||||
- Detection and Segmentation:
|
||||
- Core: detection/core.md
|
||||
- Annotators: detection/annotators.md
|
||||
- Metrics: detection/metrics.md
|
||||
- Double Detection Filter: detection/double_detection_filter.md
|
||||
- Utils: detection/utils.md
|
||||
- Keypoint Detection:
|
||||
- Core: keypoint/core.md
|
||||
- Annotators: keypoint/annotators.md
|
||||
- Classification:
|
||||
- Core: classification/core.md
|
||||
- Tools:
|
||||
- Line Zone: detection/tools/line_zone.md
|
||||
- Polygon Zone: detection/tools/polygon_zone.md
|
||||
@@ -54,26 +62,24 @@ nav:
|
||||
- Detection Smoother: detection/tools/smoother.md
|
||||
- Save Detections: detection/tools/save_detections.md
|
||||
- Trackers: trackers.md
|
||||
- Datasets: datasets.md
|
||||
- Metrics:
|
||||
- Object Detection: metrics/detection.md
|
||||
- Draw:
|
||||
- Color: draw/color.md
|
||||
- Utils: draw/utils.md
|
||||
- Geometry:
|
||||
- Position: geometry/core.md
|
||||
- Datasets:
|
||||
- Core: datasets/core.md
|
||||
- Utils: datasets/utils.md
|
||||
- Utils:
|
||||
- Video: utils/video.md
|
||||
- Image: utils/image.md
|
||||
- Iterables: utils/iterables.md
|
||||
- Notebook: utils/notebook.md
|
||||
- File: utils/file.md
|
||||
- Draw: utils/draw.md
|
||||
- Geometry: utils/geometry.md
|
||||
- Assets: assets.md
|
||||
- Cookbooks: cookbooks.md
|
||||
- Contribute:
|
||||
- Contributing: contributing.md
|
||||
- Code of Conduct: code_of_conduct.md
|
||||
- License: license.md
|
||||
- Changelog:
|
||||
- Release Notes:
|
||||
- Changelog: changelog.md
|
||||
- Deprecated: deprecated.md
|
||||
|
||||
|
||||
Generated
+754
-668
File diff suppressed because it is too large
Load Diff
+19
-23
@@ -1,6 +1,6 @@
|
||||
[tool.poetry]
|
||||
name = "supervision"
|
||||
version = "0.19.0rc3"
|
||||
version = "0.21.0"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
authors = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
maintainers = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
@@ -42,18 +42,19 @@ pyyaml = ">=5.3"
|
||||
defusedxml = "^0.7.1"
|
||||
opencv-python = { version = ">=4.5.5.64", optional = true }
|
||||
opencv-python-headless = ">=4.5.5.64"
|
||||
requests = { version = ">=2.26.0,<=2.31.0", optional = true }
|
||||
tqdm = { version = ">=4.62.3,<=4.66.1", optional = true }
|
||||
requests = { version = ">=2.26.0,<=2.32.3", optional = true }
|
||||
tqdm = { version = ">=4.62.3,<=4.66.4", optional = true }
|
||||
pillow = ">=9.4"
|
||||
|
||||
[tool.poetry.extras]
|
||||
desktop = ["opencv-python"]
|
||||
assets = ["requests","tqdm"]
|
||||
|
||||
[tool.poetry.group.dev.dependencies]
|
||||
twine = "^4.0.2"
|
||||
twine = ">=4.0.2,<6.0.0"
|
||||
pytest = ">=7.2.2,<9.0.0"
|
||||
wheel = ">=0.40,<0.43"
|
||||
build = ">=0.10,<1.1"
|
||||
wheel = ">=0.40,<0.44"
|
||||
build = ">=0.10,<1.3"
|
||||
ruff = ">=0.1.0"
|
||||
mypy = "^1.4.1"
|
||||
pre-commit = "^3.3.3"
|
||||
@@ -66,7 +67,7 @@ nbconvert = "^7.14.2"
|
||||
|
||||
[tool.poetry.group.docs.dependencies]
|
||||
mkdocs-material = {extras = ["imaging"], version = "^9.5.5"}
|
||||
mkdocstrings = {extras = ["python"], version = ">=0.20,<0.25"}
|
||||
mkdocstrings = {extras = ["python"], version = ">=0.20,<0.26"}
|
||||
mike = "^2.0.0"
|
||||
# For Documentation Development use Python 3.10 or above
|
||||
# Use Latest mkdocs-jupyter min 0.24.6 for Jupyter Notebook Theme support
|
||||
@@ -110,13 +111,6 @@ exclude = '''
|
||||
|
||||
[tool.ruff]
|
||||
target-version = "py38"
|
||||
# Enable pycodestyle (`E`) and Pyflakes (`F`) codes by default.
|
||||
select = ["E", "F"]
|
||||
ignore = []
|
||||
|
||||
# Allow autofix for all enabled rules (when `--fix`) is provided.
|
||||
fixable = ["A", "B", "C", "D", "E", "F", "G", "I", "N", "Q", "S", "T", "W", "ANN", "ARG", "BLE", "COM", "DJ", "DTZ", "EM", "ERA", "EXE", "FBT", "ICN", "INP", "ISC", "NPY", "PD", "PGH", "PIE", "PL", "PT", "PTH", "PYI", "RET", "RSE", "RUF", "SIM", "SLF", "TCH", "TID", "TRY", "UP", "YTT"]
|
||||
unfixable = []
|
||||
|
||||
# Exclude a variety of commonly ignored directories.
|
||||
exclude = [
|
||||
@@ -146,33 +140,35 @@ exclude = [
|
||||
"docs",
|
||||
]
|
||||
|
||||
# Same as Black.
|
||||
line-length = 88
|
||||
indent-width = 4
|
||||
|
||||
[tool.ruff.lint]
|
||||
# Enable pycodestyle (`E`) and Pyflakes (`F`) codes by default.
|
||||
select = ["E", "F"]
|
||||
ignore = []
|
||||
# Allow autofix for all enabled rules (when `--fix`) is provided.
|
||||
fixable = ["A", "B", "C", "D", "E", "F", "G", "I", "N", "Q", "S", "T", "W", "ANN", "ARG", "BLE", "COM", "DJ", "DTZ", "EM", "ERA", "EXE", "FBT", "ICN", "INP", "ISC", "NPY", "PD", "PGH", "PIE", "PL", "PT", "PTH", "PYI", "RET", "RSE", "RUF", "SIM", "SLF", "TCH", "TID", "TRY", "UP", "YTT"]
|
||||
unfixable = []
|
||||
# Allow unused variables when underscore-prefixed.
|
||||
dummy-variable-rgx = "^(_+|(_+[a-zA-Z0-9_]*[a-zA-Z0-9]+?))$"
|
||||
pylint.max-args = 20
|
||||
|
||||
[tool.ruff.flake8-quotes]
|
||||
[tool.ruff.lint.flake8-quotes]
|
||||
inline-quotes = "double"
|
||||
multiline-quotes = "double"
|
||||
docstring-quotes = "double"
|
||||
|
||||
[tool.ruff.pydocstyle]
|
||||
[tool.ruff.lint.pydocstyle]
|
||||
convention = "google"
|
||||
|
||||
[tool.ruff.per-file-ignores]
|
||||
[tool.ruff.lint.per-file-ignores]
|
||||
"__init__.py" = ["E402","F401"]
|
||||
"supervision/assets/list.py" = ["E501"]
|
||||
|
||||
[tool.ruff.lint.mccabe]
|
||||
# Flag errors (`C901`) whenever the complexity level exceeds 5.
|
||||
max-complexity = 20
|
||||
|
||||
|
||||
[tool.ruff.pylint]
|
||||
max-args = 20
|
||||
|
||||
[tool.ruff.format]
|
||||
# Like Black, use double quotes for strings.
|
||||
quote-style = "double"
|
||||
|
||||
+35
-6
@@ -12,6 +12,7 @@ from supervision.annotators.core import (
|
||||
BoxCornerAnnotator,
|
||||
CircleAnnotator,
|
||||
ColorAnnotator,
|
||||
CropAnnotator,
|
||||
DotAnnotator,
|
||||
EllipseAnnotator,
|
||||
HaloAnnotator,
|
||||
@@ -22,6 +23,7 @@ from supervision.annotators.core import (
|
||||
PercentageBarAnnotator,
|
||||
PixelateAnnotator,
|
||||
PolygonAnnotator,
|
||||
RichLabelAnnotator,
|
||||
RoundBoxAnnotator,
|
||||
TraceAnnotator,
|
||||
TriangleAnnotator,
|
||||
@@ -33,31 +35,43 @@ from supervision.dataset.core import (
|
||||
ClassificationDataset,
|
||||
DetectionDataset,
|
||||
)
|
||||
from supervision.dataset.utils import mask_to_rle, rle_to_mask
|
||||
from supervision.detection.annotate import BoxAnnotator
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.line_counter import LineZone, LineZoneAnnotator
|
||||
from supervision.detection.line_zone import LineZone, LineZoneAnnotator
|
||||
from supervision.detection.lmm import LMM
|
||||
from supervision.detection.overlap_filter import (
|
||||
OverlapFilter,
|
||||
box_non_max_merge,
|
||||
box_non_max_suppression,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.tools.csv_sink import CSVSink
|
||||
from supervision.detection.tools.inference_slicer import InferenceSlicer
|
||||
from supervision.detection.tools.json_sink import JSONSink
|
||||
from supervision.detection.tools.polygon_zone import PolygonZone, PolygonZoneAnnotator
|
||||
from supervision.detection.tools.smoother import DetectionsSmoother
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
box_non_max_suppression,
|
||||
calculate_masks_centroids,
|
||||
clip_boxes,
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
filter_polygons_by_area,
|
||||
mask_iou_batch,
|
||||
mask_non_max_suppression,
|
||||
mask_to_polygons,
|
||||
mask_to_xyxy,
|
||||
move_boxes,
|
||||
move_masks,
|
||||
pad_boxes,
|
||||
polygon_to_mask,
|
||||
polygon_to_xyxy,
|
||||
scale_boxes,
|
||||
)
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import (
|
||||
calculate_dynamic_line_thickness,
|
||||
calculate_dynamic_text_scale,
|
||||
calculate_optimal_line_thickness,
|
||||
calculate_optimal_text_scale,
|
||||
draw_filled_rectangle,
|
||||
draw_image,
|
||||
draw_line,
|
||||
@@ -67,10 +81,25 @@ from supervision.draw.utils import (
|
||||
)
|
||||
from supervision.geometry.core import Point, Position, Rect
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.keypoint.annotators import (
|
||||
EdgeAnnotator,
|
||||
VertexAnnotator,
|
||||
VertexLabelAnnotator,
|
||||
)
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.metrics.detection import ConfusionMatrix, MeanAveragePrecision
|
||||
from supervision.tracker.byte_tracker.core import ByteTrack
|
||||
from supervision.utils.conversion import cv2_to_pillow, pillow_to_cv2
|
||||
from supervision.utils.file import list_files_with_extensions
|
||||
from supervision.utils.image import ImageSink, crop_image
|
||||
from supervision.utils.image import (
|
||||
ImageSink,
|
||||
create_tiles,
|
||||
crop_image,
|
||||
letterbox_image,
|
||||
overlay_image,
|
||||
resize_image,
|
||||
scale_image,
|
||||
)
|
||||
from supervision.utils.notebook import plot_image, plot_images_grid
|
||||
from supervision.utils.video import (
|
||||
FPSMonitor,
|
||||
|
||||
@@ -1,11 +1,22 @@
|
||||
from abc import ABC, abstractmethod
|
||||
from typing import TypeVar
|
||||
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
|
||||
ImageType = TypeVar("ImageType", np.ndarray, Image.Image)
|
||||
"""
|
||||
An image of type `np.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
Unlike a `Union`, ensures the type remains consistent. If a function
|
||||
takes an `ImageType` argument and returns an `ImageType`, when you
|
||||
pass an `np.ndarray`, you will get an `np.ndarray` back.
|
||||
"""
|
||||
|
||||
|
||||
class BaseAnnotator(ABC):
|
||||
@abstractmethod
|
||||
def annotate(self, scene: np.ndarray, detections: Detections) -> np.ndarray:
|
||||
def annotate(self, scene: ImageType, detections: Detections) -> ImageType:
|
||||
pass
|
||||
|
||||
+524
-124
File diff suppressed because it is too large
Load Diff
@@ -1,5 +1,5 @@
|
||||
from enum import Enum
|
||||
from typing import Optional, Union
|
||||
from typing import Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
|
||||
@@ -34,14 +34,14 @@ def resolve_color_idx(
|
||||
) -> int:
|
||||
if detection_idx >= len(detections):
|
||||
raise ValueError(
|
||||
f"Detection index {detection_idx}"
|
||||
f"Detection index {detection_idx} "
|
||||
f"is out of bounds for detections of length {len(detections)}"
|
||||
)
|
||||
|
||||
if isinstance(color_lookup, np.ndarray):
|
||||
if len(color_lookup) != len(detections):
|
||||
raise ValueError(
|
||||
f"Length of color lookup {len(color_lookup)}"
|
||||
f"Length of color lookup {len(color_lookup)} "
|
||||
f"does not match length of detections {len(detections)}"
|
||||
)
|
||||
return color_lookup[detection_idx]
|
||||
@@ -50,19 +50,72 @@ def resolve_color_idx(
|
||||
elif color_lookup == ColorLookup.CLASS:
|
||||
if detections.class_id is None:
|
||||
raise ValueError(
|
||||
"Could not resolve color by class because"
|
||||
"Could not resolve color by class because "
|
||||
"Detections do not have class_id"
|
||||
)
|
||||
return detections.class_id[detection_idx]
|
||||
elif color_lookup == ColorLookup.TRACK:
|
||||
if detections.tracker_id is None:
|
||||
raise ValueError(
|
||||
"Could not resolve color by track because"
|
||||
"Could not resolve color by track because "
|
||||
"Detections do not have tracker_id"
|
||||
)
|
||||
return detections.tracker_id[detection_idx]
|
||||
|
||||
|
||||
def resolve_text_background_xyxy(
|
||||
center_coordinates: Tuple[int, int],
|
||||
text_wh: Tuple[int, int],
|
||||
position: Position,
|
||||
) -> Tuple[int, int, int, int]:
|
||||
center_x, center_y = center_coordinates
|
||||
text_w, text_h = text_wh
|
||||
|
||||
if position == Position.TOP_LEFT:
|
||||
return center_x, center_y - text_h, center_x + text_w, center_y
|
||||
elif position == Position.TOP_RIGHT:
|
||||
return center_x - text_w, center_y - text_h, center_x, center_y
|
||||
elif position == Position.TOP_CENTER:
|
||||
return (
|
||||
center_x - text_w // 2,
|
||||
center_y - text_h,
|
||||
center_x + text_w // 2,
|
||||
center_y,
|
||||
)
|
||||
elif position == Position.CENTER or position == Position.CENTER_OF_MASS:
|
||||
return (
|
||||
center_x - text_w // 2,
|
||||
center_y - text_h // 2,
|
||||
center_x + text_w // 2,
|
||||
center_y + text_h // 2,
|
||||
)
|
||||
elif position == Position.BOTTOM_LEFT:
|
||||
return center_x, center_y, center_x + text_w, center_y + text_h
|
||||
elif position == Position.BOTTOM_RIGHT:
|
||||
return center_x - text_w, center_y, center_x, center_y + text_h
|
||||
elif position == Position.BOTTOM_CENTER:
|
||||
return (
|
||||
center_x - text_w // 2,
|
||||
center_y,
|
||||
center_x + text_w // 2,
|
||||
center_y + text_h,
|
||||
)
|
||||
elif position == Position.CENTER_LEFT:
|
||||
return (
|
||||
center_x - text_w,
|
||||
center_y - text_h // 2,
|
||||
center_x,
|
||||
center_y + text_h // 2,
|
||||
)
|
||||
elif position == Position.CENTER_RIGHT:
|
||||
return (
|
||||
center_x,
|
||||
center_y - text_h // 2,
|
||||
center_x + text_w,
|
||||
center_y + text_h // 2,
|
||||
)
|
||||
|
||||
|
||||
def get_color_by_index(color: Union[Color, ColorPalette], idx: int) -> Color:
|
||||
if isinstance(color, ColorPalette):
|
||||
return color.by_idx(idx)
|
||||
|
||||
@@ -18,6 +18,8 @@ class VideoAssets(Enum):
|
||||
| `SUBWAY` | `subway.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/subway.mp4) |
|
||||
| `MARKET_SQUARE` | `market-square.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/market-square.mp4) |
|
||||
| `PEOPLE_WALKING` | `people-walking.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/people-walking.mp4) |
|
||||
| `BEACH` | `beach-1.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/beach-1.mp4) |
|
||||
| `BASKETBALL` | `basketball-1.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/basketball-1.mp4) |
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
VEHICLES = "vehicles.mp4"
|
||||
@@ -27,6 +29,8 @@ class VideoAssets(Enum):
|
||||
SUBWAY = "subway.mp4"
|
||||
MARKET_SQUARE = "market-square.mp4"
|
||||
PEOPLE_WALKING = "people-walking.mp4"
|
||||
BEACH = "beach-1.mp4"
|
||||
BASKETBALL = "basketball-1.mp4"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
@@ -62,4 +66,12 @@ VIDEO_ASSETS: Dict[str, Tuple[str, str]] = {
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.PEOPLE_WALKING.value}",
|
||||
"0574c053c8686c3f1dc0aa3743e45cb9",
|
||||
),
|
||||
VideoAssets.BEACH.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.BEACH.value}",
|
||||
"4175d42fec4d450ed081523fd39e0cf8",
|
||||
),
|
||||
VideoAssets.BASKETBALL.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.BASKETBALL.value}",
|
||||
"60d94a3c7c47d16f09d342b088012ecc",
|
||||
),
|
||||
}
|
||||
|
||||
+23
-11
@@ -116,13 +116,12 @@ class DetectionDataset(BaseDataset):
|
||||
Tuple[DetectionDataset, DetectionDataset]: A tuple containing
|
||||
the training and testing datasets.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
train_ds, test_ds = ds.split(split_ratio=0.7,
|
||||
random_state=42, shuffle=True)
|
||||
train_ds, test_ds = ds.split(split_ratio=0.7, random_state=42, shuffle=True)
|
||||
len(train_ds), len(test_ds)
|
||||
# (700, 300)
|
||||
```
|
||||
@@ -229,7 +228,7 @@ class DetectionDataset(BaseDataset):
|
||||
DetectionDataset: A DetectionDataset instance containing
|
||||
the loaded images and annotations.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
@@ -286,7 +285,7 @@ class DetectionDataset(BaseDataset):
|
||||
DetectionDataset: A DetectionDataset instance
|
||||
containing the loaded images and annotations.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
@@ -391,7 +390,7 @@ class DetectionDataset(BaseDataset):
|
||||
DetectionDataset: A DetectionDataset instance containing
|
||||
the loaded images and annotations.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
@@ -431,6 +430,20 @@ class DetectionDataset(BaseDataset):
|
||||
Exports the dataset to COCO format. This method saves the
|
||||
images and their corresponding annotations in COCO format.
|
||||
|
||||
!!! tip
|
||||
|
||||
The format of the mask is determined automatically based on its structure:
|
||||
|
||||
- If a mask contains multiple disconnected components or holes, it will be
|
||||
saved using the Run-Length Encoding (RLE) format for efficient storage and
|
||||
processing.
|
||||
- If a mask consists of a single, contiguous region without any holes, it
|
||||
will be encoded as a polygon, preserving the outline of the object.
|
||||
|
||||
This automatic selection ensures that the masks are stored in the most
|
||||
appropriate and space-efficient format, complying with COCO dataset
|
||||
standards.
|
||||
|
||||
Args:
|
||||
images_directory_path (Optional[str]): The path to the directory
|
||||
where the images should be saved.
|
||||
@@ -482,7 +495,7 @@ class DetectionDataset(BaseDataset):
|
||||
(DetectionDataset): A single `DetectionDataset` object containing
|
||||
the merged data from the input list.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
@@ -567,13 +580,12 @@ class ClassificationDataset(BaseDataset):
|
||||
Tuple[ClassificationDataset, ClassificationDataset]: A tuple containing
|
||||
the training and testing datasets.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
cd = sv.ClassificationDataset(...)
|
||||
train_cd,test_cd = cd.split(split_ratio=0.7,
|
||||
random_state=42,shuffle=True)
|
||||
train_cd,test_cd = cd.split(split_ratio=0.7, random_state=42,shuffle=True)
|
||||
len(train_cd), len(test_cd)
|
||||
# (700, 300)
|
||||
```
|
||||
@@ -635,7 +647,7 @@ class ClassificationDataset(BaseDataset):
|
||||
Returns:
|
||||
ClassificationDataset: The dataset.
|
||||
|
||||
Example:
|
||||
Examples:
|
||||
```python
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
|
||||
@@ -5,13 +5,20 @@ from typing import Dict, List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.dataset.utils import (
|
||||
approximate_mask_with_polygons,
|
||||
map_detections_class_id,
|
||||
mask_to_rle,
|
||||
rle_to_mask,
|
||||
)
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import polygon_to_mask
|
||||
from supervision.detection.utils import (
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
polygon_to_mask,
|
||||
)
|
||||
from supervision.utils.file import read_json_file, save_json_file
|
||||
|
||||
|
||||
@@ -57,13 +64,24 @@ def group_coco_annotations_by_image_id(
|
||||
return annotations
|
||||
|
||||
|
||||
def _polygons_to_masks(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> np.ndarray:
|
||||
def coco_annotations_to_masks(
|
||||
image_annotations: List[dict], resolution_wh: Tuple[int, int]
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
return np.array(
|
||||
[
|
||||
polygon_to_mask(polygon=polygon, resolution_wh=resolution_wh)
|
||||
for polygon in polygons
|
||||
rle_to_mask(
|
||||
rle=np.array(image_annotation["segmentation"]["counts"]),
|
||||
resolution_wh=resolution_wh,
|
||||
)
|
||||
if image_annotation["iscrowd"]
|
||||
else polygon_to_mask(
|
||||
polygon=np.reshape(
|
||||
np.asarray(image_annotation["segmentation"], dtype=np.int32),
|
||||
(-1, 2),
|
||||
),
|
||||
resolution_wh=resolution_wh,
|
||||
)
|
||||
for image_annotation in image_annotations
|
||||
],
|
||||
dtype=bool,
|
||||
)
|
||||
@@ -83,13 +101,9 @@ def coco_annotations_to_detections(
|
||||
xyxy[:, 2:4] += xyxy[:, 0:2]
|
||||
|
||||
if with_masks:
|
||||
polygons = [
|
||||
np.reshape(
|
||||
np.asarray(image_annotation["segmentation"], dtype=np.int32), (-1, 2)
|
||||
)
|
||||
for image_annotation in image_annotations
|
||||
]
|
||||
mask = _polygons_to_masks(polygons=polygons, resolution_wh=resolution_wh)
|
||||
mask = coco_annotations_to_masks(
|
||||
image_annotations=image_annotations, resolution_wh=resolution_wh
|
||||
)
|
||||
return Detections(
|
||||
class_id=np.asarray(class_ids, dtype=int), xyxy=xyxy, mask=mask
|
||||
)
|
||||
@@ -108,24 +122,35 @@ def detections_to_coco_annotations(
|
||||
coco_annotations = []
|
||||
for xyxy, mask, _, class_id, _, _ in detections:
|
||||
box_width, box_height = xyxy[2] - xyxy[0], xyxy[3] - xyxy[1]
|
||||
polygon = []
|
||||
segmentation = []
|
||||
iscrowd = 0
|
||||
if mask is not None:
|
||||
polygon = list(
|
||||
approximate_mask_with_polygons(
|
||||
mask=mask,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)[0].flatten()
|
||||
)
|
||||
iscrowd = contains_holes(mask=mask) or contains_multiple_segments(mask=mask)
|
||||
|
||||
if iscrowd:
|
||||
segmentation = {
|
||||
"counts": mask_to_rle(mask=mask),
|
||||
"size": list(mask.shape[:2]),
|
||||
}
|
||||
else:
|
||||
segmentation = [
|
||||
list(
|
||||
approximate_mask_with_polygons(
|
||||
mask=mask,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)[0].flatten()
|
||||
)
|
||||
]
|
||||
coco_annotation = {
|
||||
"id": annotation_id,
|
||||
"image_id": image_id,
|
||||
"category_id": int(class_id),
|
||||
"bbox": [xyxy[0], xyxy[1], box_width, box_height],
|
||||
"area": box_width * box_height,
|
||||
"segmentation": [polygon] if polygon else [],
|
||||
"iscrowd": 0,
|
||||
"segmentation": segmentation,
|
||||
"iscrowd": iscrowd,
|
||||
}
|
||||
coco_annotations.append(coco_annotation)
|
||||
annotation_id += 1
|
||||
|
||||
@@ -2,10 +2,11 @@ import copy
|
||||
import os
|
||||
import random
|
||||
from pathlib import Path
|
||||
from typing import Dict, List, Optional, Tuple, TypeVar
|
||||
from typing import Dict, List, Optional, Tuple, TypeVar, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
@@ -129,3 +130,123 @@ def train_test_split(
|
||||
|
||||
split_index = int(len(data) * train_ratio)
|
||||
return data[:split_index], data[split_index:]
|
||||
|
||||
|
||||
def rle_to_mask(
|
||||
rle: Union[npt.NDArray[np.int_], List[int]], resolution_wh: Tuple[int, int]
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
"""
|
||||
Converts run-length encoding (RLE) to a binary mask.
|
||||
|
||||
Args:
|
||||
rle (Union[npt.NDArray[np.int_], List[int]]): The 1D RLE array, the format
|
||||
used in the COCO dataset (column-wise encoding, values of an array with
|
||||
even indices represent the number of pixels assigned as background,
|
||||
values of an array with odd indices represent the number of pixels
|
||||
assigned as foreground object).
|
||||
resolution_wh (Tuple[int, int]): The width (w) and height (h)
|
||||
of the desired binary mask.
|
||||
|
||||
Returns:
|
||||
The generated 2D Boolean mask of shape `(h, w)`, where the foreground object is
|
||||
marked with `True`'s and the rest is filled with `False`'s.
|
||||
|
||||
Raises:
|
||||
AssertionError: If the sum of pixels encoded in RLE differs from the
|
||||
number of pixels in the expected mask (computed based on resolution_wh).
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.rle_to_mask([5, 2, 2, 2, 5], (4, 4))
|
||||
# array([
|
||||
# [False, False, False, False],
|
||||
# [False, True, True, False],
|
||||
# [False, True, True, False],
|
||||
# [False, False, False, False],
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
if isinstance(rle, list):
|
||||
rle = np.array(rle, dtype=int)
|
||||
|
||||
width, height = resolution_wh
|
||||
|
||||
assert width * height == np.sum(rle), (
|
||||
"the sum of the number of pixels in the RLE must be the same "
|
||||
"as the number of pixels in the expected mask"
|
||||
)
|
||||
|
||||
zero_one_values = np.zeros(shape=(rle.size, 1), dtype=np.uint8)
|
||||
zero_one_values[1::2] = 1
|
||||
|
||||
decoded_rle = np.repeat(zero_one_values, rle, axis=0)
|
||||
decoded_rle = np.append(
|
||||
decoded_rle, np.zeros(width * height - len(decoded_rle), dtype=np.uint8)
|
||||
)
|
||||
return decoded_rle.reshape((height, width), order="F")
|
||||
|
||||
|
||||
def mask_to_rle(mask: npt.NDArray[np.bool_]) -> List[int]:
|
||||
"""
|
||||
Converts a binary mask into a run-length encoding (RLE).
|
||||
|
||||
Args:
|
||||
mask (npt.NDArray[np.bool_]): 2D binary mask where `True` indicates foreground
|
||||
object and `False` indicates background.
|
||||
|
||||
Returns:
|
||||
The run-length encoded mask. Values of a list with even indices
|
||||
represent the number of pixels assigned as background (`False`), values
|
||||
of a list with odd indices represent the number of pixels assigned
|
||||
as foreground object (`True`).
|
||||
|
||||
Raises:
|
||||
AssertionError: If input mask is not 2D or is empty.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([
|
||||
[True, True, True, True],
|
||||
[True, True, True, True],
|
||||
[True, True, True, True],
|
||||
[True, True, True, True],
|
||||
])
|
||||
sv.mask_to_rle(mask)
|
||||
# [0, 16]
|
||||
|
||||
mask = np.array([
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
])
|
||||
sv.mask_to_rle(mask)
|
||||
# [5, 2, 2, 2, 5]
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
assert mask.ndim == 2, "Input mask must be 2D"
|
||||
assert mask.size != 0, "Input mask cannot be empty"
|
||||
|
||||
on_value_change_indices = np.where(
|
||||
mask.ravel(order="F") != np.roll(mask.ravel(order="F"), 1)
|
||||
)[0]
|
||||
|
||||
on_value_change_indices = np.append(on_value_change_indices, mask.size)
|
||||
# need to add 0 at the beginning when the same value is in the first and
|
||||
# last element of the flattened mask
|
||||
if on_value_change_indices[0] != 0:
|
||||
on_value_change_indices = np.insert(on_value_change_indices, 0, 0)
|
||||
|
||||
rle = np.diff(on_value_change_indices)
|
||||
|
||||
if mask[0][0] == 1:
|
||||
rle = np.insert(rle, 0, 0)
|
||||
|
||||
return list(rle)
|
||||
|
||||
@@ -1,17 +1,14 @@
|
||||
from typing import List, Optional, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.utils.conversion import convert_for_annotation_method
|
||||
from supervision.utils.internal import deprecated
|
||||
|
||||
|
||||
@deprecated(
|
||||
"`BoxAnnotator` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `BoundingBoxAnnotator` and `LabelAnnotator` instead"
|
||||
)
|
||||
class BoxAnnotator:
|
||||
"""
|
||||
A class for drawing bounding boxes on an image using detections provided.
|
||||
@@ -45,18 +42,25 @@ class BoxAnnotator:
|
||||
self.text_thickness: int = text_thickness
|
||||
self.text_padding: int = text_padding
|
||||
|
||||
@deprecated(
|
||||
"`BoxAnnotator` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `BoundingBoxAnnotator` and `LabelAnnotator` instead"
|
||||
)
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
scene: ImageType,
|
||||
detections: Detections,
|
||||
labels: Optional[List[str]] = None,
|
||||
skip_label: bool = False,
|
||||
) -> np.ndarray:
|
||||
) -> ImageType:
|
||||
"""
|
||||
Draws bounding boxes on the frame using the detections provided.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image on which the bounding boxes will be drawn
|
||||
scene (ImageType): The image on which the bounding boxes will be drawn.
|
||||
`ImageType` is a flexible type, accepting either `numpy.ndarray`
|
||||
or `PIL.Image.Image`.
|
||||
detections (Detections): The detections for which the
|
||||
bounding boxes will be drawn
|
||||
labels (Optional[List[str]]): An optional list of labels
|
||||
@@ -64,7 +68,8 @@ class BoxAnnotator:
|
||||
corresponding `class_id` will be used as label.
|
||||
skip_label (bool): Is set to `True`, skips bounding box label annotation.
|
||||
Returns:
|
||||
np.ndarray: The image with the bounding boxes drawn on it
|
||||
ImageType: The image with the bounding boxes drawn on it, matching the
|
||||
type of `scene` (`numpy.ndarray` or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
|
||||
+422
-65
@@ -7,53 +7,96 @@ from typing import Any, Dict, Iterator, List, Optional, Tuple, Union
|
||||
import numpy as np
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD, ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.utils import (
|
||||
from supervision.detection.lmm import LMM, from_paligemma, validate_lmm_and_kwargs
|
||||
from supervision.detection.overlap_filter import (
|
||||
box_non_max_merge,
|
||||
box_non_max_suppression,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
calculate_masks_centroids,
|
||||
extract_ultralytics_masks,
|
||||
get_data_item,
|
||||
is_data_equal,
|
||||
mask_non_max_suppression,
|
||||
mask_to_xyxy,
|
||||
merge_data,
|
||||
process_roboflow_result,
|
||||
validate_detections_fields,
|
||||
xywh_to_xyxy,
|
||||
)
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.utils.internal import deprecated
|
||||
from supervision.utils.internal import deprecated, get_instance_variables
|
||||
from supervision.validators import validate_detections_fields
|
||||
|
||||
|
||||
@dataclass
|
||||
class Detections:
|
||||
"""
|
||||
The `sv.Detections` allows you to convert results from a variety of object detection
|
||||
and segmentation models into a single, unified format. The `sv.Detections` class
|
||||
enables easy data manipulation and filtering, and provides a consistent API for
|
||||
Supervision's tools like trackers, annotators, and zones.
|
||||
The `sv.Detections` class in the Supervision library standardizes results from
|
||||
various object detection and segmentation models into a consistent format. This
|
||||
class simplifies data manipulation and filtering, providing a uniform API for
|
||||
integration with Supervision [trackers](/trackers/), [annotators](/detection/annotators/), and [tools](/detection/tools/line_zone/).
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
=== "Inference"
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
annotator = sv.BoundingBoxAnnotator()
|
||||
Use [`sv.Detections.from_inference`](/detection/core/#supervision.detection.core.Detections.from_inference)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
annotated_image = annotator.annotate(image, detections)
|
||||
```
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
=== "Ultralytics"
|
||||
|
||||
In `sv.Detections`, detection data is categorized into two main field types:
|
||||
fixed and custom. The fixed fields include `xyxy`, `mask`, `confidence`,
|
||||
`class_id`, and `tracker_id`. For any additional data requirements, custom
|
||||
fields come into play, stored in the data field. These custom fields are easily
|
||||
accessible using the `detections[<FIELD_NAME>]` syntax, providing flexibility
|
||||
for diverse data handling needs.
|
||||
Use [`sv.Detections.from_ultralytics`](/detection/core/#supervision.detection.core.Detections.from_ultralytics)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
Use [`sv.Detections.from_transformers`](/detection/core/#supervision.detection.core.Detections.from_transformers)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
```
|
||||
|
||||
Attributes:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
@@ -69,15 +112,7 @@ class Detections:
|
||||
data (Dict[str, Union[np.ndarray, List]]): A dictionary containing additional
|
||||
data where each key is a string representing the data type, and the value
|
||||
is either a NumPy array or a list of corresponding data.
|
||||
|
||||
!!! warning
|
||||
|
||||
The `data` field in the `sv.Detections` class is currently in an experimental
|
||||
phase. Please be aware that its API and functionality are subject to change in
|
||||
future updates as we continue to refine and improve its capabilities.
|
||||
We encourage users to experiment with this feature and provide feedback, but
|
||||
also to be prepared for potential modifications in upcoming releases.
|
||||
"""
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
xyxy: np.ndarray
|
||||
mask: Optional[np.ndarray] = None
|
||||
@@ -176,8 +211,8 @@ class Detections:
|
||||
@classmethod
|
||||
def from_ultralytics(cls, ultralytics_results) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
Creates a `sv.Detections` instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
|
||||
!!! Note
|
||||
|
||||
@@ -188,7 +223,7 @@ class Detections:
|
||||
|
||||
Args:
|
||||
ultralytics_results (ultralytics.yolo.engine.results.Results):
|
||||
The output Results instance from YOLOv8
|
||||
The output Results instance from Ultralytics
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
@@ -201,13 +236,16 @@ class Detections:
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
if ultralytics_results.obb is not None:
|
||||
if hasattr(ultralytics_results, "obb") and ultralytics_results.obb is not None:
|
||||
class_id = ultralytics_results.obb.cls.cpu().numpy().astype(int)
|
||||
class_names = np.array([ultralytics_results.names[i] for i in class_id])
|
||||
oriented_box_coordinates = ultralytics_results.obb.xyxyxyxy.cpu().numpy()
|
||||
@@ -385,23 +423,86 @@ class Detections:
|
||||
xyxy=mmdet_results.pred_instances.bboxes.cpu().numpy(),
|
||||
confidence=mmdet_results.pred_instances.scores.cpu().numpy(),
|
||||
class_id=mmdet_results.pred_instances.labels.cpu().numpy().astype(int),
|
||||
mask=mmdet_results.pred_instances.masks.cpu().numpy()
|
||||
if "masks" in mmdet_results.pred_instances
|
||||
else None,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_transformers(cls, transformers_results: dict) -> Detections:
|
||||
def from_transformers(
|
||||
cls, transformers_results: dict, id2label: Optional[Dict[int, str]] = None
|
||||
) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from object detection
|
||||
[transformer](https://github.com/huggingface/transformers) inference result.
|
||||
Creates a Detections instance from object detection or segmentation
|
||||
[Transformer](https://github.com/huggingface/transformers) inference result.
|
||||
|
||||
Args:
|
||||
transformers_results (dict): The output of Transformers model inference. A
|
||||
dictionary containing the `scores`, `labels`, `boxes` and `masks` keys.
|
||||
id2label (Optional[Dict[int, str]]): A dictionary mapping class IDs to
|
||||
class names. If provided, the resulting Detections object will contain
|
||||
`class_name` data field with the class names.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
"""
|
||||
|
||||
return cls(
|
||||
xyxy=transformers_results["boxes"].cpu().numpy(),
|
||||
confidence=transformers_results["scores"].cpu().numpy(),
|
||||
class_id=transformers_results["labels"].cpu().numpy().astype(int),
|
||||
)
|
||||
Example:
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label
|
||||
)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
class_ids = transformers_results["labels"].cpu().detach().numpy().astype(int)
|
||||
data = {}
|
||||
if id2label is not None:
|
||||
class_names = np.array([id2label[class_id] for class_id in class_ids])
|
||||
data[CLASS_NAME_DATA_FIELD] = class_names
|
||||
if "boxes" in transformers_results:
|
||||
return cls(
|
||||
xyxy=transformers_results["boxes"].cpu().detach().numpy(),
|
||||
confidence=transformers_results["scores"].cpu().detach().numpy(),
|
||||
class_id=class_ids,
|
||||
data=data,
|
||||
)
|
||||
elif "masks" in transformers_results:
|
||||
masks = transformers_results["masks"].cpu().detach().numpy().astype(bool)
|
||||
return cls(
|
||||
xyxy=mask_to_xyxy(masks),
|
||||
mask=masks,
|
||||
confidence=transformers_results["scores"].cpu().detach().numpy(),
|
||||
class_id=class_ids,
|
||||
data=data,
|
||||
)
|
||||
else:
|
||||
raise NotImplementedError(
|
||||
"Only object detection and semantic segmentation results are supported."
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_detectron2(cls, detectron2_results) -> Detections:
|
||||
@@ -448,17 +549,12 @@ class Detections:
|
||||
@classmethod
|
||||
def from_inference(cls, roboflow_result: Union[dict, Any]) -> Detections:
|
||||
"""
|
||||
Create a Detections object from the [Roboflow](https://roboflow.com/)
|
||||
Create a `sv.Detections` object from the [Roboflow](https://roboflow.com/)
|
||||
API inference result or the [Inference](https://inference.roboflow.com/)
|
||||
package results. This method extracts bounding boxes, class IDs,
|
||||
confidences, and class names from the Roboflow API result and encapsulates
|
||||
them into a Detections object.
|
||||
|
||||
!!! note
|
||||
|
||||
Class names can be accessed using the key 'class_name' in the returned
|
||||
object's data attribute.
|
||||
|
||||
Args:
|
||||
roboflow_result (dict, any): The result from the
|
||||
Roboflow API or Inference package containing predictions.
|
||||
@@ -471,14 +567,18 @@ class Detections:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_roboflow_model(model_id="yolov8s-640")
|
||||
model = get_model(model_id="yolov8s-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
"""
|
||||
with suppress(AttributeError):
|
||||
roboflow_result = roboflow_result.dict(exclude_none=True, by_alias=True)
|
||||
@@ -487,7 +587,9 @@ class Detections:
|
||||
)
|
||||
|
||||
if np.asarray(xyxy).shape[0] == 0:
|
||||
return cls.empty()
|
||||
empty_detection = cls.empty()
|
||||
empty_detection.data = {CLASS_NAME_DATA_FIELD: np.empty(0)}
|
||||
return empty_detection
|
||||
|
||||
return cls(
|
||||
xyxy=xyxy,
|
||||
@@ -526,10 +628,10 @@ class Detections:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_roboflow_model(model_id="yolov8s-640")
|
||||
model = get_model(model_id="yolov8s-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_roboflow(result)
|
||||
@@ -708,6 +810,52 @@ class Detections:
|
||||
class_id=paddledet_result["bbox"][:, 0].astype(int),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_lmm(cls, lmm: Union[LMM, str], result: str, **kwargs) -> Detections:
|
||||
"""
|
||||
Creates a Detections object from the given result string based on the specified
|
||||
Large Multimodal Model (LMM).
|
||||
|
||||
Args:
|
||||
lmm (Union[LMM, str]): The type of LMM (Large Multimodal Model) to use.
|
||||
result (str): The result string containing the detection data.
|
||||
**kwargs: Additional keyword arguments required by the specified LMM.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
|
||||
Raises:
|
||||
ValueError: If the LMM is invalid, required arguments are missing, or
|
||||
disallowed arguments are provided.
|
||||
ValueError: If the specified LMM is not supported.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
paligemma_result = "<loc0256><loc0256><loc0768><loc0768> cat"
|
||||
detections = sv.Detections.from_lmm(
|
||||
sv.LMM.PALIGEMMA,
|
||||
paligemma_result,
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog']
|
||||
)
|
||||
detections.xyxy
|
||||
# array([[250., 250., 750., 750.]])
|
||||
|
||||
detections.class_id
|
||||
# array([0])
|
||||
```
|
||||
"""
|
||||
lmm = validate_lmm_and_kwargs(lmm, kwargs)
|
||||
|
||||
if lmm == LMM.PALIGEMMA:
|
||||
xyxy, class_id, class_name = from_paligemma(result, **kwargs)
|
||||
data = {CLASS_NAME_DATA_FIELD: class_name}
|
||||
return cls(xyxy=xyxy, class_id=class_id, data=data)
|
||||
|
||||
raise ValueError(f"Unsupported LMM: {lmm}")
|
||||
|
||||
@classmethod
|
||||
def empty(cls) -> Detections:
|
||||
"""
|
||||
@@ -730,6 +878,14 @@ class Detections:
|
||||
class_id=np.array([], dtype=int),
|
||||
)
|
||||
|
||||
def is_empty(self) -> bool:
|
||||
"""
|
||||
Returns `True` if the `Detections` object is considered empty.
|
||||
"""
|
||||
empty_detections = Detections.empty()
|
||||
empty_detections.data = self.data
|
||||
return self == empty_detections
|
||||
|
||||
@classmethod
|
||||
def merge(cls, detections_list: List[Detections]) -> Detections:
|
||||
"""
|
||||
@@ -737,9 +893,14 @@ class Detections:
|
||||
|
||||
This method takes a list of Detections objects and combines their
|
||||
respective fields (`xyxy`, `mask`, `confidence`, `class_id`, and `tracker_id`)
|
||||
into a single Detections object. If all elements in a field are not
|
||||
`None`, the corresponding field will be stacked.
|
||||
Otherwise, the field will be set to `None`.
|
||||
into a single Detections object.
|
||||
|
||||
For example, if merging Detections with 3 and 4 detected objects, this method
|
||||
will return a Detections with 7 objects (7 entries in `xyxy`, `mask`, etc).
|
||||
|
||||
!!! Note
|
||||
|
||||
When merging, empty `Detections` objects are ignored.
|
||||
|
||||
Args:
|
||||
detections_list (List[Detections]): A list of Detections objects to merge.
|
||||
@@ -779,6 +940,10 @@ class Detections:
|
||||
array([0.1, 0.2, 0.3])
|
||||
```
|
||||
"""
|
||||
detections_list = [
|
||||
detections for detections in detections_list if not detections.is_empty()
|
||||
]
|
||||
|
||||
if len(detections_list) == 0:
|
||||
return Detections.empty()
|
||||
|
||||
@@ -1053,3 +1218,195 @@ class Detections:
|
||||
)
|
||||
|
||||
return self[indices]
|
||||
|
||||
def with_nmm(
|
||||
self, threshold: float = 0.5, class_agnostic: bool = False
|
||||
) -> Detections:
|
||||
"""
|
||||
Perform non-maximum merging on the current set of object detections.
|
||||
|
||||
Args:
|
||||
threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum merging. Defaults to 0.5.
|
||||
class_agnostic (bool, optional): Whether to perform class-agnostic
|
||||
non-maximum merging. If True, the class_id of each detection
|
||||
will be ignored. Defaults to False.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object containing the subset of detections
|
||||
after non-maximum merging.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `confidence` is None or `class_id` is None and
|
||||
class_agnostic is False.
|
||||
|
||||
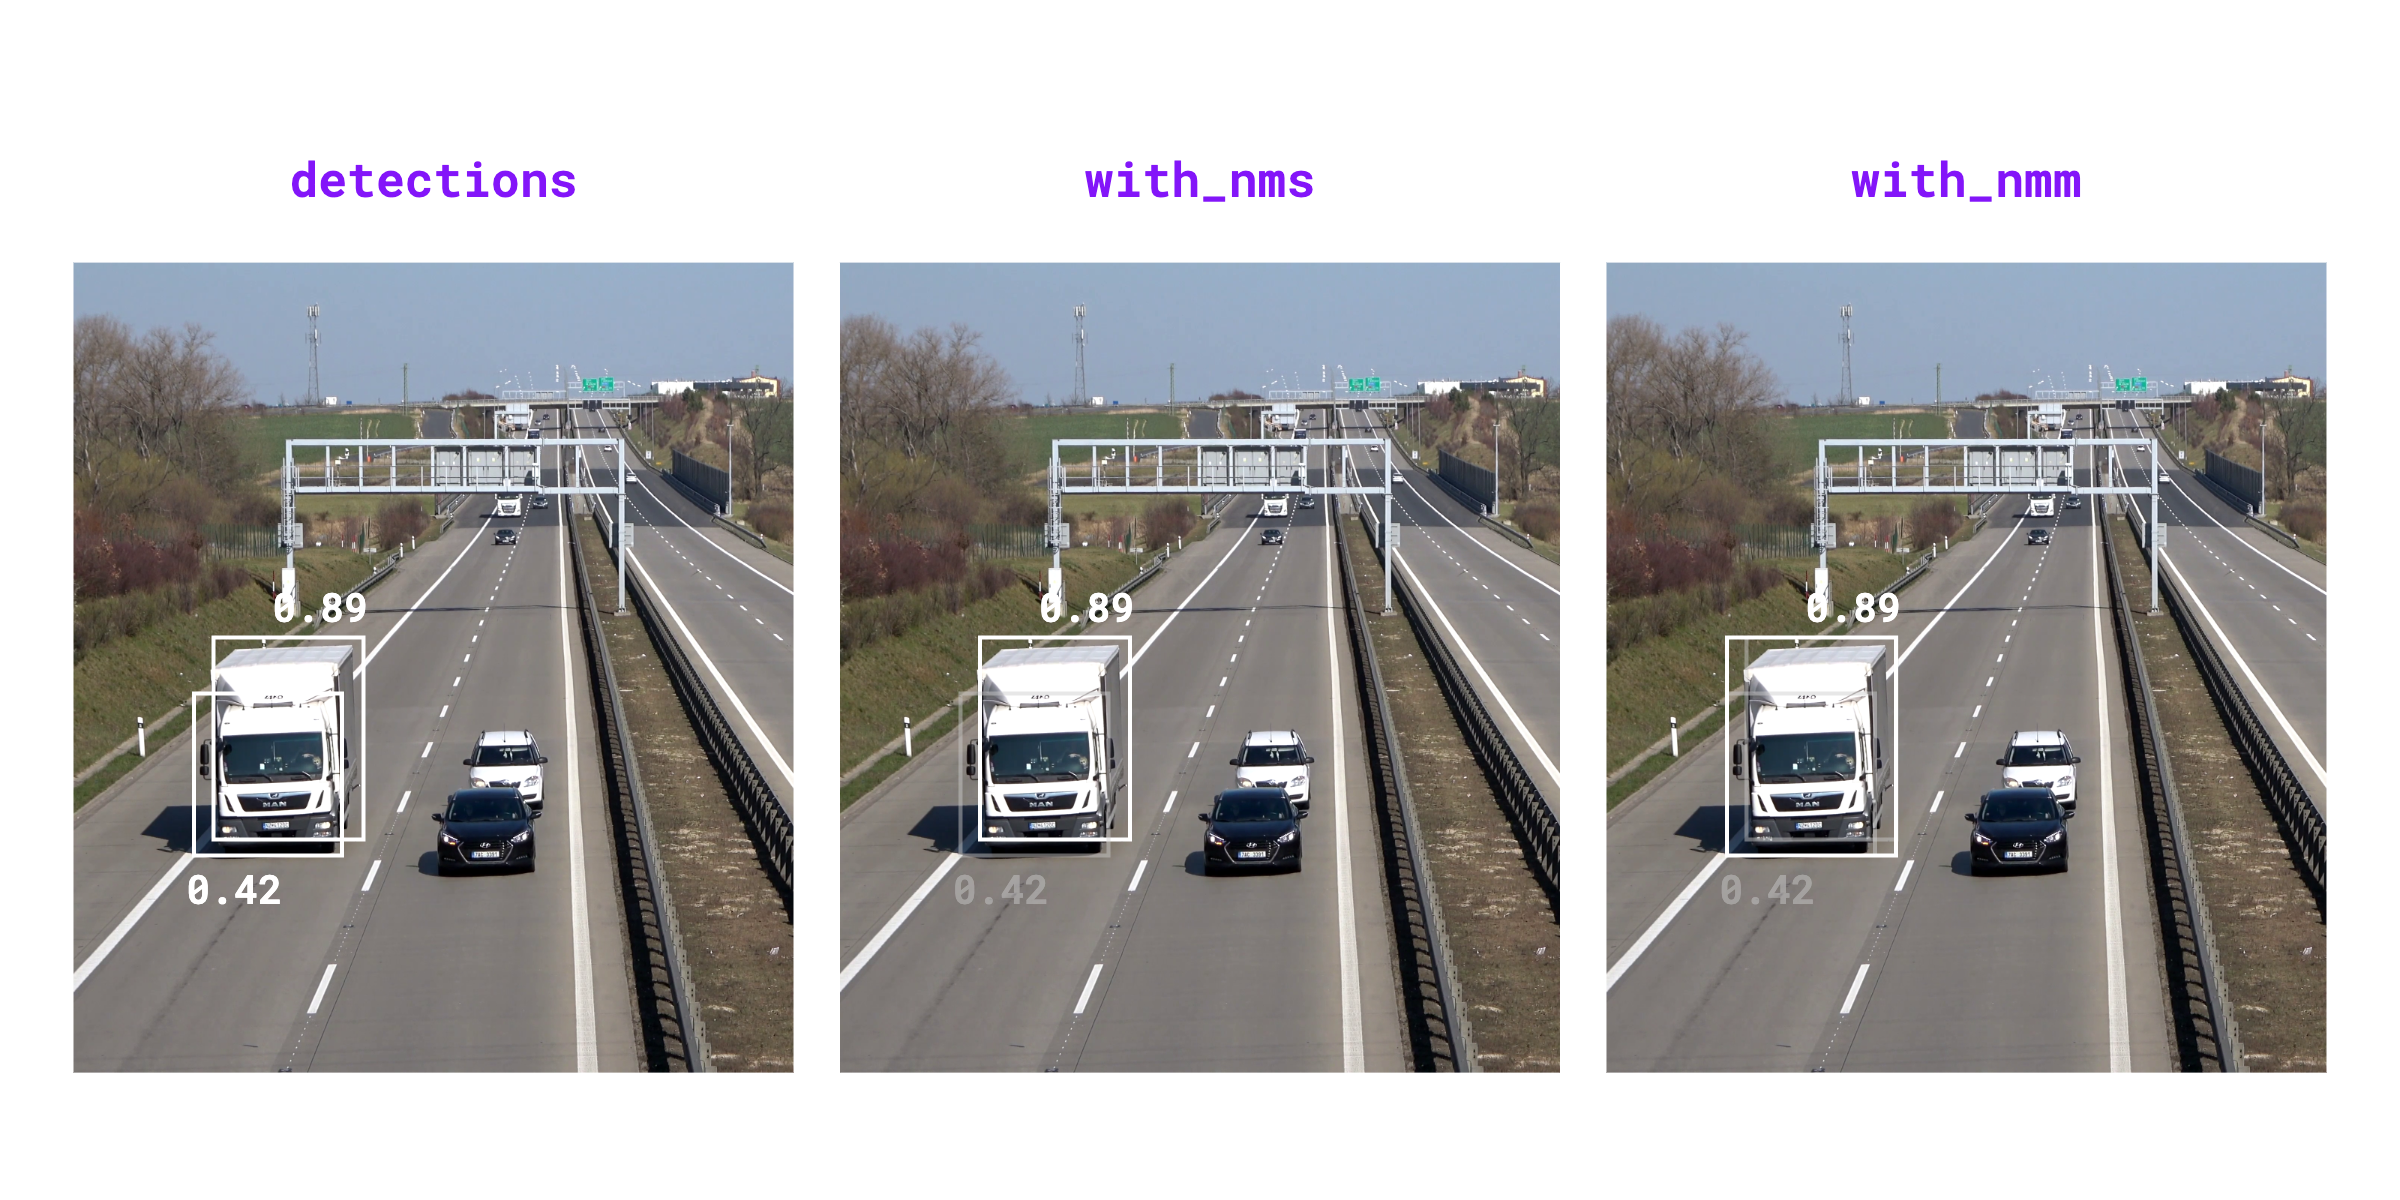{ align=center width="800" }
|
||||
""" # noqa: E501 // docs
|
||||
if len(self) == 0:
|
||||
return self
|
||||
|
||||
assert (
|
||||
self.confidence is not None
|
||||
), "Detections confidence must be given for NMM to be executed."
|
||||
|
||||
if class_agnostic:
|
||||
predictions = np.hstack((self.xyxy, self.confidence.reshape(-1, 1)))
|
||||
else:
|
||||
assert self.class_id is not None, (
|
||||
"Detections class_id must be given for NMM to be executed. If you"
|
||||
" intended to perform class agnostic NMM set class_agnostic=True."
|
||||
)
|
||||
predictions = np.hstack(
|
||||
(
|
||||
self.xyxy,
|
||||
self.confidence.reshape(-1, 1),
|
||||
self.class_id.reshape(-1, 1),
|
||||
)
|
||||
)
|
||||
|
||||
merge_groups = box_non_max_merge(
|
||||
predictions=predictions, iou_threshold=threshold
|
||||
)
|
||||
|
||||
result = []
|
||||
for merge_group in merge_groups:
|
||||
unmerged_detections = [self[i] for i in merge_group]
|
||||
merged_detections = merge_inner_detections_objects(
|
||||
unmerged_detections, threshold
|
||||
)
|
||||
result.append(merged_detections)
|
||||
|
||||
return Detections.merge(result)
|
||||
|
||||
|
||||
def merge_inner_detection_object_pair(
|
||||
detections_1: Detections, detections_2: Detections
|
||||
) -> Detections:
|
||||
"""
|
||||
Merges two Detections object into a single Detections object.
|
||||
Assumes each Detections contains exactly one object.
|
||||
|
||||
A `winning` detection is determined based on the confidence score of the two
|
||||
input detections. This winning detection is then used to specify which
|
||||
`class_id`, `tracker_id`, and `data` to include in the merged Detections object.
|
||||
|
||||
The resulting `confidence` of the merged object is calculated by the weighted
|
||||
contribution of ea detection to the merged object.
|
||||
The bounding boxes and masks of the two input detections are merged into a
|
||||
single bounding box and mask, respectively.
|
||||
|
||||
Args:
|
||||
detections_1 (Detections):
|
||||
The first Detections object
|
||||
detections_2 (Detections):
|
||||
The second Detections object
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object, with merged attributes.
|
||||
|
||||
Raises:
|
||||
ValueError: If the input Detections objects do not have exactly 1 detected
|
||||
object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_model(model_id="yolov8s-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
|
||||
merged_detections = merge_object_detection_pair(
|
||||
detections[0], detections[1])
|
||||
```
|
||||
"""
|
||||
if len(detections_1) != 1 or len(detections_2) != 1:
|
||||
raise ValueError("Both Detections should have exactly 1 detected object.")
|
||||
|
||||
validate_fields_both_defined_or_none(detections_1, detections_2)
|
||||
|
||||
xyxy_1 = detections_1.xyxy[0]
|
||||
xyxy_2 = detections_2.xyxy[0]
|
||||
if detections_1.confidence is None and detections_2.confidence is None:
|
||||
merged_confidence = None
|
||||
else:
|
||||
detection_1_area = (xyxy_1[2] - xyxy_1[0]) * (xyxy_1[3] - xyxy_1[1])
|
||||
detections_2_area = (xyxy_2[2] - xyxy_2[0]) * (xyxy_2[3] - xyxy_2[1])
|
||||
merged_confidence = (
|
||||
detection_1_area * detections_1.confidence[0]
|
||||
+ detections_2_area * detections_2.confidence[0]
|
||||
) / (detection_1_area + detections_2_area)
|
||||
merged_confidence = np.array([merged_confidence])
|
||||
|
||||
merged_x1, merged_y1 = np.minimum(xyxy_1[:2], xyxy_2[:2])
|
||||
merged_x2, merged_y2 = np.maximum(xyxy_1[2:], xyxy_2[2:])
|
||||
merged_xyxy = np.array([[merged_x1, merged_y1, merged_x2, merged_y2]])
|
||||
|
||||
if detections_1.mask is None and detections_2.mask is None:
|
||||
merged_mask = None
|
||||
else:
|
||||
merged_mask = np.logical_or(detections_1.mask, detections_2.mask)
|
||||
|
||||
if detections_1.confidence is None and detections_2.confidence is None:
|
||||
winning_detection = detections_1
|
||||
elif detections_1.confidence[0] >= detections_2.confidence[0]:
|
||||
winning_detection = detections_1
|
||||
else:
|
||||
winning_detection = detections_2
|
||||
|
||||
return Detections(
|
||||
xyxy=merged_xyxy,
|
||||
mask=merged_mask,
|
||||
confidence=merged_confidence,
|
||||
class_id=winning_detection.class_id,
|
||||
tracker_id=winning_detection.tracker_id,
|
||||
data=winning_detection.data,
|
||||
)
|
||||
|
||||
|
||||
def merge_inner_detections_objects(
|
||||
detections: List[Detections], threshold=0.5
|
||||
) -> Detections:
|
||||
"""
|
||||
Given N detections each of length 1 (exactly one object inside), combine them into a
|
||||
single detection object of length 1. The contained inner object will be the merged
|
||||
result of all the input detections.
|
||||
|
||||
For example, this lets you merge N boxes into one big box, N masks into one mask,
|
||||
etc.
|
||||
"""
|
||||
detections_1 = detections[0]
|
||||
for detections_2 in detections[1:]:
|
||||
box_iou = box_iou_batch(detections_1.xyxy, detections_2.xyxy)[0]
|
||||
if box_iou < threshold:
|
||||
break
|
||||
detections_1 = merge_inner_detection_object_pair(detections_1, detections_2)
|
||||
return detections_1
|
||||
|
||||
|
||||
def validate_fields_both_defined_or_none(
|
||||
detections_1: Detections, detections_2: Detections
|
||||
) -> None:
|
||||
"""
|
||||
Verify that for each optional field in the Detections, both instances either have
|
||||
the field set to None or both have it set to non-None values.
|
||||
|
||||
`data` field is ignored.
|
||||
|
||||
Raises:
|
||||
ValueError: If one field is None and the other is not, for any of the fields.
|
||||
"""
|
||||
attributes = get_instance_variables(detections_1)
|
||||
for attribute in attributes:
|
||||
value_1 = getattr(detections_1, attribute)
|
||||
value_2 = getattr(detections_2, attribute)
|
||||
|
||||
if (value_1 is None) != (value_2 is None):
|
||||
raise ValueError(
|
||||
f"Field '{attribute}' should be consistently None or not None in both "
|
||||
"Detections."
|
||||
)
|
||||
|
||||
@@ -1,12 +1,15 @@
|
||||
import warnings
|
||||
from typing import Dict, Iterable, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import cross_product
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_text
|
||||
from supervision.geometry.core import Point, Position, Vector
|
||||
from supervision.utils.internal import SupervisionWarnings
|
||||
|
||||
|
||||
class LineZone:
|
||||
@@ -14,6 +17,12 @@ class LineZone:
|
||||
This class is responsible for counting the number of objects that cross a
|
||||
predefined line.
|
||||
|
||||
<video controls>
|
||||
<source
|
||||
src="https://media.roboflow.com/supervision/cookbooks/count-objects-crossing-the-line-result-1280x720.mp4"
|
||||
type="video/mp4">
|
||||
</video>
|
||||
|
||||
!!! warning
|
||||
|
||||
LineZone uses the `tracker_id`. Read
|
||||
@@ -25,7 +34,28 @@ class LineZone:
|
||||
to inside.
|
||||
out_count (int): The number of objects that have crossed the line from inside
|
||||
to outside.
|
||||
"""
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO(<SOURCE_MODEL_PATH>)
|
||||
tracker = sv.ByteTrack()
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
start, end = sv.Point(x=0, y=1080), sv.Point(x=3840, y=1080)
|
||||
line_zone = sv.LineZone(start=start, end=end)
|
||||
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
crossed_in, crossed_out = line_zone.trigger(detections)
|
||||
|
||||
line_zone.in_count, line_zone.out_count
|
||||
# 7, 2
|
||||
```
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
@@ -54,6 +84,8 @@ class LineZone:
|
||||
self.in_count: int = 0
|
||||
self.out_count: int = 0
|
||||
self.triggering_anchors = triggering_anchors
|
||||
if not list(self.triggering_anchors):
|
||||
raise ValueError("Triggering anchors cannot be empty.")
|
||||
|
||||
@staticmethod
|
||||
def calculate_region_of_interest_limits(vector: Vector) -> Tuple[Vector, Vector]:
|
||||
@@ -113,6 +145,15 @@ class LineZone:
|
||||
if len(detections) == 0:
|
||||
return crossed_in, crossed_out
|
||||
|
||||
if detections.tracker_id is None:
|
||||
warnings.warn(
|
||||
"Line zone counting skipped. LineZone requires tracker_id. Refer to "
|
||||
"https://supervision.roboflow.com/latest/trackers for more "
|
||||
"information.",
|
||||
category=SupervisionWarnings,
|
||||
)
|
||||
return crossed_in, crossed_out
|
||||
|
||||
all_anchors = np.array(
|
||||
[
|
||||
detections.get_anchors_coordinates(anchor)
|
||||
@@ -120,31 +161,23 @@ class LineZone:
|
||||
]
|
||||
)
|
||||
|
||||
cross_products_1 = cross_product(all_anchors, self.limits[0])
|
||||
cross_products_2 = cross_product(all_anchors, self.limits[1])
|
||||
in_limits = (cross_products_1 > 0) == (cross_products_2 > 0)
|
||||
in_limits = np.all(in_limits, axis=0)
|
||||
|
||||
triggers = cross_product(all_anchors, self.vector) < 0
|
||||
has_any_left_trigger = np.any(triggers, axis=0)
|
||||
has_any_right_trigger = np.any(~triggers, axis=0)
|
||||
is_uniformly_triggered = ~(has_any_left_trigger & has_any_right_trigger)
|
||||
for i, tracker_id in enumerate(detections.tracker_id):
|
||||
if tracker_id is None:
|
||||
if not in_limits[i]:
|
||||
continue
|
||||
|
||||
box_anchors = [Point(x=x, y=y) for x, y in all_anchors[:, i, :]]
|
||||
|
||||
in_limits = all(
|
||||
[
|
||||
self.is_point_in_limits(point=anchor, limits=self.limits)
|
||||
for anchor in box_anchors
|
||||
]
|
||||
)
|
||||
|
||||
if not in_limits:
|
||||
if not is_uniformly_triggered[i]:
|
||||
continue
|
||||
|
||||
triggers = [
|
||||
self.vector.cross_product(point=anchor) < 0 for anchor in box_anchors
|
||||
]
|
||||
|
||||
if len(set(triggers)) == 2:
|
||||
continue
|
||||
|
||||
tracker_state = triggers[0]
|
||||
|
||||
tracker_state = has_any_left_trigger[i]
|
||||
if tracker_id not in self.tracker_state:
|
||||
self.tracker_state[tracker_id] = tracker_state
|
||||
continue
|
||||
@@ -0,0 +1,59 @@
|
||||
import re
|
||||
from enum import Enum
|
||||
from typing import Any, Dict, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
|
||||
|
||||
class LMM(Enum):
|
||||
PALIGEMMA = "paligemma"
|
||||
|
||||
|
||||
REQUIRED_ARGUMENTS: Dict[LMM, List[str]] = {LMM.PALIGEMMA: ["resolution_wh"]}
|
||||
|
||||
ALLOWED_ARGUMENTS: Dict[LMM, List[str]] = {LMM.PALIGEMMA: ["resolution_wh", "classes"]}
|
||||
|
||||
|
||||
def validate_lmm_and_kwargs(lmm: Union[LMM, str], kwargs: Dict[str, Any]) -> LMM:
|
||||
if isinstance(lmm, str):
|
||||
try:
|
||||
lmm = LMM(lmm.lower())
|
||||
except ValueError:
|
||||
raise ValueError(
|
||||
f"Invalid lmm value: {lmm}. Must be one of {[e.value for e in LMM]}"
|
||||
)
|
||||
|
||||
required_args = REQUIRED_ARGUMENTS.get(lmm, [])
|
||||
for arg in required_args:
|
||||
if arg not in kwargs:
|
||||
raise ValueError(f"Missing required argument: {arg}")
|
||||
|
||||
allowed_args = ALLOWED_ARGUMENTS.get(lmm, [])
|
||||
for arg in kwargs:
|
||||
if arg not in allowed_args:
|
||||
raise ValueError(f"Argument {arg} is not allowed for {lmm.name}")
|
||||
|
||||
return lmm
|
||||
|
||||
|
||||
def from_paligemma(
|
||||
result: str, resolution_wh: Tuple[int, int], classes: Optional[List[str]] = None
|
||||
) -> Tuple[np.ndarray, Optional[np.ndarray], np.ndarray]:
|
||||
w, h = resolution_wh
|
||||
pattern = re.compile(
|
||||
r"(?<!<loc\d{4}>)<loc(\d{4})><loc(\d{4})><loc(\d{4})><loc(\d{4})> ([\w\s\-]+)"
|
||||
)
|
||||
matches = pattern.findall(result)
|
||||
matches = np.array(matches) if matches else np.empty((0, 5))
|
||||
|
||||
xyxy, class_name = matches[:, [1, 0, 3, 2]], matches[:, 4]
|
||||
xyxy = xyxy.astype(int) / 1024 * np.array([w, h, w, h])
|
||||
class_name = np.char.strip(class_name.astype(str))
|
||||
class_id = None
|
||||
|
||||
if classes is not None:
|
||||
mask = np.array([name in classes for name in class_name]).astype(bool)
|
||||
xyxy, class_name = xyxy[mask], class_name[mask]
|
||||
class_id = np.array([classes.index(name) for name in class_name])
|
||||
|
||||
return xyxy, class_id, class_name
|
||||
@@ -0,0 +1,263 @@
|
||||
from enum import Enum
|
||||
from typing import List, Union
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.utils import box_iou_batch, mask_iou_batch
|
||||
|
||||
|
||||
def resize_masks(masks: np.ndarray, max_dimension: int = 640) -> np.ndarray:
|
||||
"""
|
||||
Resize all masks in the array to have a maximum dimension of max_dimension,
|
||||
maintaining aspect ratio.
|
||||
|
||||
Args:
|
||||
masks (np.ndarray): 3D array of binary masks with shape (N, H, W).
|
||||
max_dimension (int): The maximum dimension for the resized masks.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Array of resized masks.
|
||||
"""
|
||||
max_height = np.max(masks.shape[1])
|
||||
max_width = np.max(masks.shape[2])
|
||||
scale = min(max_dimension / max_height, max_dimension / max_width)
|
||||
|
||||
new_height = int(scale * max_height)
|
||||
new_width = int(scale * max_width)
|
||||
|
||||
x = np.linspace(0, max_width - 1, new_width).astype(int)
|
||||
y = np.linspace(0, max_height - 1, new_height).astype(int)
|
||||
xv, yv = np.meshgrid(x, y)
|
||||
|
||||
resized_masks = masks[:, yv, xv]
|
||||
|
||||
resized_masks = resized_masks.reshape(masks.shape[0], new_height, new_width)
|
||||
return resized_masks
|
||||
|
||||
|
||||
def mask_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
mask_dimension: int = 640,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on segmentation predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): A 2D array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or
|
||||
`(N, 6)`, where N is the number of predictions.
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
mask_dimension (int, optional): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after
|
||||
non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the closed
|
||||
range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
sort_index = predictions[:, 4].argsort()[::-1]
|
||||
predictions = predictions[sort_index]
|
||||
masks = masks[sort_index]
|
||||
masks_resized = resize_masks(masks, mask_dimension)
|
||||
ious = mask_iou_batch(masks_resized, masks_resized)
|
||||
categories = predictions[:, 5]
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
for i in range(rows):
|
||||
if keep[i]:
|
||||
condition = (ious[i] > iou_threshold) & (categories[i] == categories)
|
||||
keep[i + 1 :] = np.where(condition[i + 1 :], False, keep[i + 1 :])
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def box_non_max_suppression(
|
||||
predictions: np.ndarray, iou_threshold: float = 0.5
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on object detection predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): An array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after n
|
||||
on-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the
|
||||
closed range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
# add column #5 - category filled with zeros for agnostic nms
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
# sort predictions column #4 - score
|
||||
sort_index = np.flip(predictions[:, 4].argsort())
|
||||
predictions = predictions[sort_index]
|
||||
|
||||
boxes = predictions[:, :4]
|
||||
categories = predictions[:, 5]
|
||||
ious = box_iou_batch(boxes, boxes)
|
||||
ious = ious - np.eye(rows)
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
|
||||
for index, (iou, category) in enumerate(zip(ious, categories)):
|
||||
if not keep[index]:
|
||||
continue
|
||||
|
||||
# drop detections with iou > iou_threshold and
|
||||
# same category as current detections
|
||||
condition = (iou > iou_threshold) & (categories == category)
|
||||
keep = keep & ~condition
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def group_overlapping_boxes(
|
||||
predictions: npt.NDArray[np.float64], iou_threshold: float = 0.5
|
||||
) -> List[List[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging to avoid detecting too many
|
||||
overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
and the confidence scores.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
|
||||
Returns:
|
||||
List[List[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
merge_groups: List[List[int]] = []
|
||||
|
||||
scores = predictions[:, 4]
|
||||
order = scores.argsort()
|
||||
|
||||
while len(order) > 0:
|
||||
idx = int(order[-1])
|
||||
|
||||
order = order[:-1]
|
||||
if len(order) == 0:
|
||||
merge_groups.append([idx])
|
||||
break
|
||||
|
||||
merge_candidate = np.expand_dims(predictions[idx], axis=0)
|
||||
ious = box_iou_batch(predictions[order][:, :4], merge_candidate[:, :4])
|
||||
ious = ious.flatten()
|
||||
|
||||
above_threshold = ious >= iou_threshold
|
||||
merge_group = [idx] + np.flip(order[above_threshold]).tolist()
|
||||
merge_groups.append(merge_group)
|
||||
order = order[~above_threshold]
|
||||
return merge_groups
|
||||
|
||||
|
||||
def box_non_max_merge(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
) -> List[List[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging per category to avoid detecting
|
||||
too many overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` or `(n, 6)`
|
||||
containing the bounding boxes coordinates in format `[x1, y1, x2, y2]`,
|
||||
the confidence scores and class_ids. Omit class_id column to allow
|
||||
detections of different classes to be merged.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
|
||||
Returns:
|
||||
List[List[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
if predictions.shape[1] == 5:
|
||||
return group_overlapping_boxes(predictions, iou_threshold)
|
||||
|
||||
category_ids = predictions[:, 5]
|
||||
merge_groups = []
|
||||
for category_id in np.unique(category_ids):
|
||||
curr_indices = np.where(category_ids == category_id)[0]
|
||||
merge_class_groups = group_overlapping_boxes(
|
||||
predictions[curr_indices], iou_threshold
|
||||
)
|
||||
|
||||
for merge_class_group in merge_class_groups:
|
||||
merge_groups.append(curr_indices[merge_class_group].tolist())
|
||||
|
||||
for merge_group in merge_groups:
|
||||
if len(merge_group) == 0:
|
||||
raise ValueError(
|
||||
f"Empty group detected when non-max-merging "
|
||||
f"detections: {merge_groups}"
|
||||
)
|
||||
return merge_groups
|
||||
|
||||
|
||||
class OverlapFilter(Enum):
|
||||
"""
|
||||
Enum specifying the strategy for filtering overlapping detections.
|
||||
|
||||
Attributes:
|
||||
NONE: Do not filter detections based on overlap.
|
||||
NON_MAX_SUPPRESSION: Filter detections using non-max suppression. This means,
|
||||
detections that overlap by more than a set threshold will be discarded,
|
||||
except for the one with the highest confidence.
|
||||
NON_MAX_MERGE: Merge detections with non-max merging. This means,
|
||||
detections that overlap by more than a set threshold will be merged
|
||||
into a single detection.
|
||||
"""
|
||||
|
||||
NONE = "none"
|
||||
NON_MAX_SUPPRESSION = "non_max_suppression"
|
||||
NON_MAX_MERGE = "non_max_merge"
|
||||
|
||||
|
||||
def validate_overlap_filter(
|
||||
strategy: Union[OverlapFilter, str],
|
||||
) -> OverlapFilter:
|
||||
if isinstance(strategy, str):
|
||||
try:
|
||||
strategy = OverlapFilter(strategy.lower())
|
||||
except ValueError:
|
||||
raise ValueError(
|
||||
f"Invalid strategy value: {strategy}. Must be one of "
|
||||
f"{[e.value for e in OverlapFilter]}"
|
||||
)
|
||||
return strategy
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user