Merge branch 'develop' into add_nmm_to_detections to resolve conflicts
This commit is contained in:
 mario-dg
@@ -0,0 +1,16 @@
|
||||
version: 2
|
||||
updates:
|
||||
# GitHub Actions
|
||||
- package-ecosystem: "github-actions"
|
||||
directory: "/"
|
||||
schedule:
|
||||
interval: "daily"
|
||||
commit-message:
|
||||
prefix: ⬆️
|
||||
# Python
|
||||
- package-ecosystem: "pip"
|
||||
directory: "/"
|
||||
schedule:
|
||||
interval: "daily"
|
||||
commit-message:
|
||||
prefix: ⬆️
|
||||
@@ -0,0 +1,33 @@
|
||||
|
||||
name: Clear cache
|
||||
|
||||
on:
|
||||
schedule:
|
||||
- cron: '0 0 1 * *'
|
||||
workflow_dispatch:
|
||||
|
||||
permissions:
|
||||
actions: write
|
||||
|
||||
jobs:
|
||||
clear-cache:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Clear cache
|
||||
uses: actions/github-script@v7
|
||||
with:
|
||||
script: |
|
||||
console.log("About to clear")
|
||||
const caches = await github.rest.actions.getActionsCacheList({
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
})
|
||||
for (const cache of caches.data.actions_caches) {
|
||||
console.log(cache)
|
||||
github.rest.actions.deleteActionsCacheById({
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
cache_id: cache.id,
|
||||
})
|
||||
}
|
||||
console.log("Clear completed")
|
||||
@@ -1,19 +1,53 @@
|
||||
name: Docs WorkFlow
|
||||
name: Docs WorkFlow - Develop Tag 📚
|
||||
|
||||
on:
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
- main
|
||||
- develop
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event_name == 'push' && github.ref}}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
pull-requests: write
|
||||
|
||||
|
||||
jobs:
|
||||
deploy:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/setup-python@v4
|
||||
- name: 🔄 Checkout code
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
python-version: 3.x
|
||||
- run: pip install mkdocs-material
|
||||
- run: pip install "mkdocstrings[python]"
|
||||
- run: mkdocs gh-deploy --force
|
||||
fetch-depth: 0
|
||||
- name: 🐍 Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
run: pip install "mkdocs-material[imaging]"
|
||||
- name: 📦 Install mike
|
||||
run: pip install "mike"
|
||||
- name: 📦 Install mkdocs-git-revision-date-localized-plugin
|
||||
run: pip install "mkdocs-git-revision-date-localized-plugin"
|
||||
- name: 📦 Install JupyterLab
|
||||
run: pip install jupyterlab
|
||||
- name: 📦 Install mkdocs-jupyter
|
||||
run: pip install mkdocs-jupyter
|
||||
- name: 📦 Install mkdocs-git-committers-plugin-2
|
||||
run: pip install mkdocs-git-committers-plugin-2
|
||||
- name: ⚙️ Configure git for github-actions
|
||||
run: |
|
||||
git config --global user.name "github-actions[bot]"
|
||||
git config --global user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
- name: 🚀 Deploy MkDoc-Material with mike
|
||||
run: |
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY=${{ secrets.GITHUB_TOKEN }} mike deploy --push develop
|
||||
|
||||
@@ -6,22 +6,24 @@ on:
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]+b[0-9]'
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]+rc[0-9]'
|
||||
|
||||
# Allows you to run this workflow manually from the Actions tab
|
||||
workflow_dispatch:
|
||||
|
||||
jobs:
|
||||
build-n-publish:
|
||||
name: Build and publish to PyPI
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: Checkout source
|
||||
uses: actions/checkout@v3
|
||||
|
||||
- name: 🐍 Set up Python 3.8 environment for build
|
||||
uses: actions/setup-python@v4
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
python-version: "3.8"
|
||||
ref: ${{ github.head_ref }}
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
|
||||
- name: 🏗️ Build source and wheel distributions
|
||||
run: |
|
||||
|
||||
@@ -3,10 +3,7 @@ on:
|
||||
push:
|
||||
tags:
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]'
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]'
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]'
|
||||
|
||||
# Allows you to run this workflow manually from the Actions tab
|
||||
workflow_dispatch:
|
||||
|
||||
jobs:
|
||||
@@ -14,14 +11,14 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: [3.8]
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v3
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
ref: ${{ github.head_ref }}
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v4
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
|
||||
|
||||
@@ -0,0 +1,34 @@
|
||||
name: 🧪 Docs Test WorkFlow 📚
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main, develop]
|
||||
|
||||
jobs:
|
||||
docs-build-test:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: 🔄 Checkout code
|
||||
uses: actions/checkout@v4
|
||||
- name: 🐍 Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material[all]"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
run: pip install "mkdocs-material[imaging]"
|
||||
- name: 📦 Install mike
|
||||
run: pip install "mike"
|
||||
- name: 📦 Install mkdocs-git-revision-date-localized-plugin
|
||||
run: pip install "mkdocs-git-revision-date-localized-plugin"
|
||||
- name: 📦 Install JupyterLab
|
||||
run: pip install jupyterlab
|
||||
- name: 📦 Install mkdocs-jupyter
|
||||
run: pip install mkdocs-jupyter
|
||||
- name: 📦 Install mkdocs-git-committers-plugin-2
|
||||
run: pip install mkdocs-git-committers-plugin-2
|
||||
- name: 🧪 Test documentation build
|
||||
run: mkdocs build --verbose
|
||||
@@ -0,0 +1,58 @@
|
||||
name: Python 3.8 - Min Dep Test WorkFlow
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main, develop]
|
||||
|
||||
jobs:
|
||||
build-min-dep-test:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.8"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v5
|
||||
# id based on python version
|
||||
id: python-setup
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
check-latest: true
|
||||
|
||||
- name: 📦 Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install \
|
||||
attrs==23.1.0 \
|
||||
certifi==2023.7.22 \
|
||||
charset-normalizer==2.0.12 \
|
||||
cycler==0.12.1 \
|
||||
exceptiongroup==1.1.3 \
|
||||
fonttools==4.43.1 \
|
||||
idna==3.4 \
|
||||
iniconfig==2.0.0 \
|
||||
kiwisolver==1.4.5 \
|
||||
matplotlib==3.5.0 \
|
||||
numpy==1.21.2 \
|
||||
opencv-python==4.5.5.64 \
|
||||
Pillow==10.1.0 \
|
||||
packaging==23.2 \
|
||||
pluggy==1.3.0 \
|
||||
pyparsing==3.1.1 \
|
||||
pytest==7.2.0 \
|
||||
python-dateutil==2.8.2 \
|
||||
PyYAML==5.3 \
|
||||
requests==2.26.0 \
|
||||
scipy==1.10.0 \
|
||||
setuptools-scm==8.0.4 \
|
||||
six==1.16.0 \
|
||||
tomli==2.0.1 \
|
||||
tqdm==4.62.3 \
|
||||
typing_extensions==4.8.0 \
|
||||
urllib3==1.26.18 \
|
||||
defusedxml==0.7.1
|
||||
|
||||
- name: 🧪 Test
|
||||
run: "python -m pytest ./test"
|
||||
@@ -5,22 +5,25 @@ on:
|
||||
branches: [main, develop]
|
||||
|
||||
jobs:
|
||||
build:
|
||||
build-dev-test:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.8", "3.9", "3.10","3.11"]
|
||||
python-version: ["3.8", "3.9", "3.10", "3.11", "3.12"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v3
|
||||
uses: actions/checkout@v4
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v4
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
- name: 🦾 Install dependencies
|
||||
check-latest: true
|
||||
|
||||
- name: 📦 Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install -e .
|
||||
pip install .
|
||||
pip install pytest
|
||||
|
||||
- name: 🧪 Test
|
||||
run: "python -m pytest ./test"
|
||||
|
||||
@@ -11,7 +11,7 @@ jobs:
|
||||
name: 👋 Welcome
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/first-interaction@v1.1.1
|
||||
- uses: actions/first-interaction@v1.3.0
|
||||
with:
|
||||
repo-token: ${{ secrets.GITHUB_TOKEN }}
|
||||
issue-message: "Hello there, thank you for opening an Issue ! 🙏🏻 The team was notified and they will get back to you asap."
|
||||
|
||||
+20
-2
@@ -133,5 +133,23 @@ dmypy.json
|
||||
# Pyre type checker
|
||||
.pyre/
|
||||
|
||||
# Notebooks
|
||||
notebooks/
|
||||
# OSX folder attributes
|
||||
.DS_Store
|
||||
.AppleDouble
|
||||
.LSOverride
|
||||
|
||||
# Thumbnails
|
||||
._*
|
||||
|
||||
# Files that might appear on external disk
|
||||
.Spotlight-V100
|
||||
.Trashes
|
||||
|
||||
# Windows
|
||||
Thumbs.db
|
||||
Desktop.ini
|
||||
|
||||
# Linux
|
||||
*~
|
||||
.directory
|
||||
.Trash-*
|
||||
|
||||
+8
-31
@@ -7,18 +7,17 @@ ci:
|
||||
|
||||
repos:
|
||||
- repo: https://github.com/pre-commit/pre-commit-hooks
|
||||
rev: v4.5.0
|
||||
rev: v4.6.0
|
||||
hooks:
|
||||
- id: end-of-file-fixer
|
||||
- id: trailing-whitespace
|
||||
exclude: test/.*\.py
|
||||
- id: check-yaml
|
||||
- id: check-docstring-first
|
||||
exclude: mkdocs.yml
|
||||
- id: check-executables-have-shebangs
|
||||
- id: check-toml
|
||||
- id: check-case-conflict
|
||||
- id: check-added-large-files
|
||||
args: ['--maxkb=2048']
|
||||
exclude: ^logo/
|
||||
- id: detect-private-key
|
||||
- id: forbid-new-submodules
|
||||
- id: pretty-format-json
|
||||
@@ -27,50 +26,28 @@ repos:
|
||||
- id: end-of-file-fixer
|
||||
- id: mixed-line-ending
|
||||
|
||||
# - repo: https://github.com/asottile/pyupgrade
|
||||
# rev: v3.9.0
|
||||
# hooks:
|
||||
# - id: pyupgrade
|
||||
# name: Upgrade code
|
||||
# args: [--py38-plus]
|
||||
|
||||
|
||||
- repo: https://github.com/PyCQA/flake8
|
||||
rev: 6.1.0
|
||||
hooks:
|
||||
- id: flake8
|
||||
name: Flake8 Checks
|
||||
entry: flake8
|
||||
additional_dependencies: [Flake8-pyproject]
|
||||
|
||||
|
||||
- repo: https://github.com/PyCQA/bandit
|
||||
rev: '1.7.5'
|
||||
rev: '1.7.8'
|
||||
hooks:
|
||||
- id: bandit
|
||||
args: ["-c", "pyproject.toml"]
|
||||
additional_dependencies: ["bandit[toml]"]
|
||||
|
||||
- repo: https://github.com/pycqa/isort
|
||||
rev: 5.12.0
|
||||
rev: 5.13.2
|
||||
hooks:
|
||||
- id: isort
|
||||
name: isort (python)
|
||||
- id: isort
|
||||
name: isort (cython)
|
||||
types: [cython]
|
||||
- id: isort
|
||||
name: isort (pyi)
|
||||
types: [pyi]
|
||||
|
||||
|
||||
- repo: https://github.com/psf/black
|
||||
rev: 23.9.1
|
||||
hooks:
|
||||
- id: black
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.0.292
|
||||
rev: v0.3.5
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
- id: ruff-format
|
||||
types_or: [ python, pyi, jupyter ]
|
||||
|
||||
+1
-1
@@ -15,7 +15,7 @@ url: 'https://roboflow.github.io/supervision/'
|
||||
abstract: >-
|
||||
supervision features a range of utilities for use in
|
||||
computer vision projects, from detections processing and
|
||||
filtering to confusion matrix calcuation.
|
||||
filtering to confusion matrix calculation.
|
||||
keywords:
|
||||
- computer vision
|
||||
- image processing
|
||||
|
||||
+16
-3
@@ -52,7 +52,7 @@ git push -u origin main
|
||||
|
||||
### Pre-commit tool
|
||||
|
||||
This project utilizes the [pre-commit](https://pre-commit.com/) tool to maintain code quality and consistency. Before submitting a pull request or making any commits, it is important to run the pre-commit tool to ensure that your changes meet the project's guidelines.
|
||||
This project uses the [pre-commit](https://pre-commit.com/) tool to maintain code quality and consistency. Before submitting a pull request or making any commits, it is important to run the pre-commit tool to ensure that your changes meet the project's guidelines.
|
||||
|
||||
Furthermore, we have integrated a pre-commit GitHub Action into our workflow. This means that with every pull request opened, the pre-commit checks will be automatically enforced, streamlining the code review process and ensuring that all contributions adhere to our quality standards.
|
||||
|
||||
@@ -76,7 +76,6 @@ All new functions and classes in `supervision` should include docstrings. This i
|
||||
|
||||
So far, **there is no type checking with mypy**. See [issue](https://github.com/roboflow-ai/template-python/issues/4).
|
||||
|
||||
|
||||
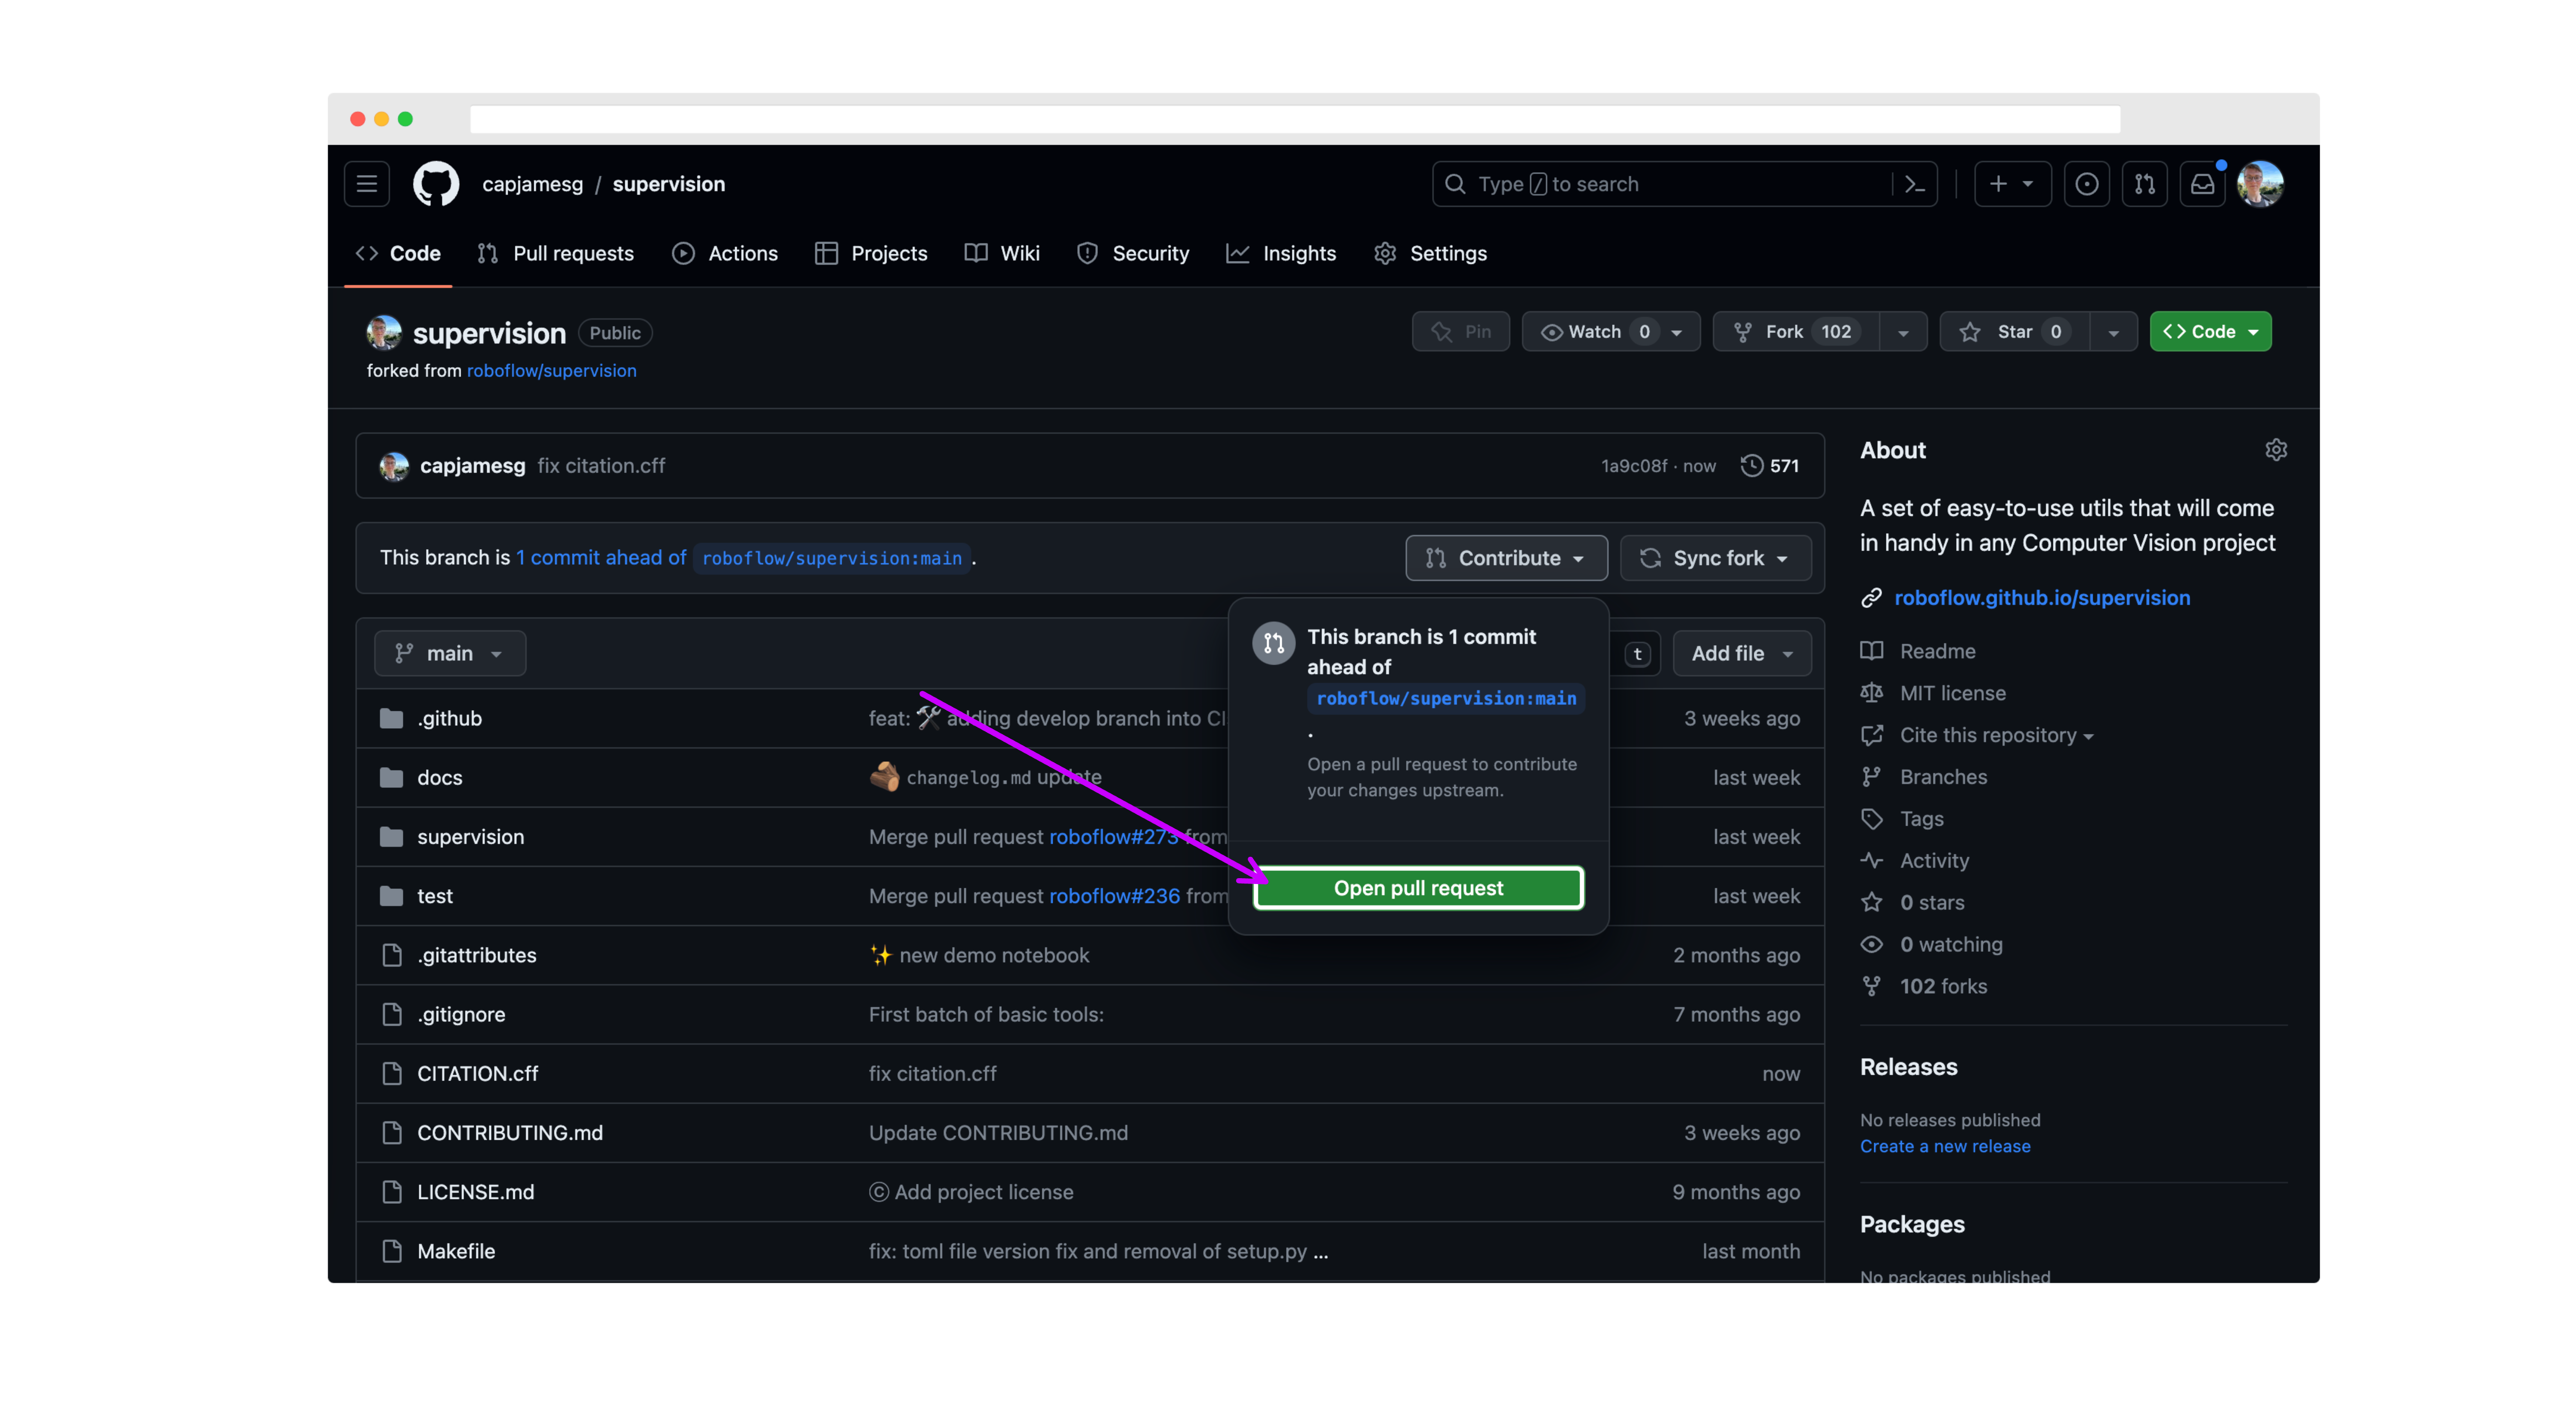
Then, go back to your fork of the `supervision` repository, click "Pull Requests", and click "New Pull Request".
|
||||
|
||||
|
||||
@@ -109,10 +108,24 @@ PRs must pass all tests and linting requirements before they can be merged.
|
||||
|
||||
The `supervision` documentation is stored in a folder called `docs`. The project documentation is built using `mkdocs`.
|
||||
|
||||
To run the documentation, install the project requirements with `poetry install dev`. Then, run `mkdocs serve` to start the documentation server.
|
||||
To run the documentation, install the project requirements with `poetry install --with dev`. Then, run `mkdocs serve` to start the documentation server.
|
||||
|
||||
You can learn more about mkdocs on the [mkdocs website](https://www.mkdocs.org/).
|
||||
|
||||
## 🧑🍳 cookbooks
|
||||
|
||||
We are always looking for new examples and cookbooks to add to the `supervision`
|
||||
documentation. If you have a use case that you think would be helpful to others, please
|
||||
submit a PR with your example. Here are some guidelines for submitting a new example:
|
||||
|
||||
- Create a new notebook in the [`docs/nodebooks`](https://github.com/roboflow/supervision/tree/develop/docs/notebooks) folder.
|
||||
- Add a link to the new notebook in [`docs/theme/cookbooks.html`](https://github.com/roboflow/supervision/blob/develop/docs/theme/cookbooks.html). Make sure to add the path to the new notebook, as well as a title, labels, author and supervision version.
|
||||
- Use the [Count Objects Crossing the Line](https://supervision.roboflow.com/develop/notebooks/count-objects-crossing-the-line/) example as a template for your new example.
|
||||
- Freeze the version of `supervision` you are using.
|
||||
- Place an appropriate Open in Colab button at the top of the notebook. You can find an example of such a button in the aforementioned `Count Objects Crossing the Line` cookbook.
|
||||
- Notebook should be self-contained. If you rely on external data ( videos, images, etc.) or libraries, include download and installation commands in the notebook.
|
||||
- Annotate the code with appropriate comments, including links to the documentation describing each of the tools you have used.
|
||||
|
||||
## 🧪 tests
|
||||
|
||||
[`pytests`](https://docs.pytest.org/en/7.1.x/) is used to run our tests.
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
<div align="center">
|
||||
<p>
|
||||
<a align="center" href="" target="_blank">
|
||||
<a align="center" href="" target="https://supervision.roboflow.com">
|
||||
<img
|
||||
width="100%"
|
||||
src="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png?updatedAt=1678995927529"
|
||||
@@ -10,289 +10,226 @@
|
||||
|
||||
<br>
|
||||
|
||||
[notebooks](https://github.com/roboflow/notebooks) | [inference](https://github.com/roboflow/inference) | [autodistill](https://github.com/autodistill/autodistill) | [collect](https://github.com/roboflow/roboflow-collect)
|
||||
[notebooks](https://github.com/roboflow/notebooks) | [inference](https://github.com/roboflow/inference) | [autodistill](https://github.com/autodistill/autodistill) | [maestro](https://github.com/roboflow/multimodal-maestro)
|
||||
|
||||
<br>
|
||||
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://huggingface.co/spaces/Roboflow/Annotators)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
[](https://squidfunk.github.io/mkdocs-material/)
|
||||
</div>
|
||||
|
||||
<a href="https://github.com/roboflow/supervision/issues?q=is%3Aissue+label%3Ahacktoberfest+">
|
||||
<img width="100%" src="https://media.roboflow.com/open-source/supervision/hacktoberfest-banner-3.png">
|
||||
</a>
|
||||
|
||||
## 👋 hello
|
||||
|
||||
**We write your reusable computer vision tools.** Whether you need to load your dataset from your hard drive, draw detections on an image or video, or count how many detections are in a zone. You can count on us! 🤝
|
||||
|
||||
[](https://github.com/orgs/roboflow/projects/10)
|
||||
|
||||
## 💻 install
|
||||
|
||||
Pip install the supervision package in a
|
||||
[**3.11>=Python>=3.8**](https://www.python.org/) environment.
|
||||
[**Python>=3.8**](https://www.python.org/) environment.
|
||||
|
||||
```bash
|
||||
pip install supervision[desktop]
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
Read more about desktop, headless, and local installation in our [guide](https://roboflow.github.io/supervision/).
|
||||
Read more about conda, mamba, and installing from source in our [guide](https://roboflow.github.io/supervision/).
|
||||
|
||||
## 🔥 quickstart
|
||||
|
||||
### [detections processing](https://roboflow.github.io/supervision/detection/core/)
|
||||
### models
|
||||
|
||||
Supervision was designed to be model agnostic. Just plug in any classification, detection, or segmentation model. For your convenience, we have created [connectors](https://supervision.roboflow.com/latest/detection/core/#detections) for the most popular libraries like Ultralytics, Transformers, or MMDetection.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> from ultralytics import YOLO
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
>>> model = YOLO('yolov8s.pt')
|
||||
>>> result = model(IMAGE)[0]
|
||||
>>> detections = sv.Detections.from_ultralytics(result)
|
||||
image = cv2.imread(...)
|
||||
model = YOLO('yolov8s.pt')
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
|
||||
>>> len(detections)
|
||||
5
|
||||
len(detections)
|
||||
# 5
|
||||
```
|
||||
|
||||
<details close>
|
||||
<summary>👉 more detections utils</summary>
|
||||
<details>
|
||||
<summary>👉 more model connectors</summary>
|
||||
|
||||
- Easily switch inference pipeline between supported object detection/instance segmentation models
|
||||
- inference
|
||||
|
||||
Running with [Inference](https://github.com/roboflow/inference) requires a [Roboflow API KEY](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key).
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> from segment_anything import sam_model_registry, SamAutomaticMaskGenerator
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
>>> sam = sam_model_registry[MODEL_TYPE](checkpoint=CHECKPOINT_PATH).to(device=DEVICE)
|
||||
>>> mask_generator = SamAutomaticMaskGenerator(sam)
|
||||
>>> sam_result = mask_generator.generate(IMAGE)
|
||||
>>> detections = sv.Detections.from_sam(sam_result=sam_result)
|
||||
```
|
||||
image = cv2.imread(...)
|
||||
model = get_roboflow_model(model_id="yolov8s-640", api_key=<ROBOFLOW API KEY>)
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
|
||||
- [Advanced filtering](https://roboflow.github.io/supervision/quickstart/detections/)
|
||||
len(detections)
|
||||
# 5
|
||||
|
||||
```python
|
||||
>>> detections = detections[detections.class_id == 0]
|
||||
>>> detections = detections[detections.confidence > 0.5]
|
||||
>>> detections = detections[detections.area > 1000]
|
||||
```
|
||||
|
||||
- Image annotation
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> box_annotator = sv.BoxAnnotator()
|
||||
>>> annotated_frame = box_annotator.annotate(
|
||||
... scene=IMAGE,
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
### [datasets processing](https://roboflow.github.io/supervision/dataset/core/)
|
||||
### annotators
|
||||
|
||||
Supervision offers a wide range of highly customizable [annotators](https://supervision.roboflow.com/latest/annotators/), allowing you to compose the perfect visualization for your use case.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... )
|
||||
image = cv2.imread(...)
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> dataset.classes
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/691e219c-0565-4403-9218-ab5644f39bce
|
||||
|
||||
### datasets
|
||||
|
||||
Supervision provides a set of [utils](https://supervision.roboflow.com/latest/datasets/) that allow you to load, split, merge, and save datasets in one of the supported formats.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
dataset = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
)
|
||||
|
||||
dataset.classes
|
||||
['dog', 'person']
|
||||
|
||||
>>> len(dataset)
|
||||
1000
|
||||
len(dataset)
|
||||
# 1000
|
||||
```
|
||||
|
||||
<details close>
|
||||
<summary>👉 more dataset utils</summary>
|
||||
|
||||
- Load object detection/instance segmentation datasets in one of the supported formats
|
||||
- load
|
||||
|
||||
```python
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... )
|
||||
```python
|
||||
dataset = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
)
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_pascal_voc(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...'
|
||||
... )
|
||||
dataset = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_coco(
|
||||
... images_directory_path='...',
|
||||
... annotations_path='...'
|
||||
... )
|
||||
```
|
||||
dataset = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=...,
|
||||
annotations_path=...
|
||||
)
|
||||
```
|
||||
|
||||
- Loop over dataset entries
|
||||
- split
|
||||
|
||||
```python
|
||||
>>> for name, image, labels in dataset:
|
||||
... print(labels.xyxy)
|
||||
```python
|
||||
train_dataset, test_dataset = dataset.split(split_ratio=0.7)
|
||||
test_dataset, valid_dataset = test_dataset.split(split_ratio=0.5)
|
||||
|
||||
array([[404. , 719. , 538. , 884.5 ],
|
||||
[155. , 497. , 404. , 833.5 ],
|
||||
[ 20.154999, 347.825 , 416.125 , 915.895 ]], dtype=float32)
|
||||
```
|
||||
len(train_dataset), len(test_dataset), len(valid_dataset)
|
||||
# (700, 150, 150)
|
||||
```
|
||||
|
||||
- Split dataset for training, testing, and validation
|
||||
- merge
|
||||
|
||||
```python
|
||||
>>> train_dataset, test_dataset = dataset.split(split_ratio=0.7)
|
||||
>>> test_dataset, valid_dataset = test_dataset.split(split_ratio=0.5)
|
||||
```python
|
||||
ds_1 = sv.DetectionDataset(...)
|
||||
len(ds_1)
|
||||
# 100
|
||||
ds_1.classes
|
||||
# ['dog', 'person']
|
||||
|
||||
>>> len(train_dataset), len(test_dataset), len(valid_dataset)
|
||||
(700, 150, 150)
|
||||
```
|
||||
ds_2 = sv.DetectionDataset(...)
|
||||
len(ds_2)
|
||||
# 200
|
||||
ds_2.classes
|
||||
# ['cat']
|
||||
|
||||
- Merge multiple datasets
|
||||
ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
len(ds_merged)
|
||||
# 300
|
||||
ds_merged.classes
|
||||
# ['cat', 'dog', 'person']
|
||||
```
|
||||
|
||||
```python
|
||||
>>> ds_1 = sv.DetectionDataset(...)
|
||||
>>> len(ds_1)
|
||||
100
|
||||
>>> ds_1.classes
|
||||
['dog', 'person']
|
||||
- save
|
||||
|
||||
>>> ds_2 = sv.DetectionDataset(...)
|
||||
>>> len(ds_2)
|
||||
200
|
||||
>>> ds_2.classes
|
||||
['cat']
|
||||
```python
|
||||
dataset.as_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
)
|
||||
|
||||
>>> ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
>>> len(ds_merged)
|
||||
300
|
||||
>>> ds_merged.classes
|
||||
['cat', 'dog', 'person']
|
||||
```
|
||||
dataset.as_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
|
||||
- Save object detection/instance segmentation datasets in one of the supported formats
|
||||
dataset.as_coco(
|
||||
images_directory_path=...,
|
||||
annotations_path=...
|
||||
)
|
||||
```
|
||||
|
||||
```python
|
||||
>>> dataset.as_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... )
|
||||
- convert
|
||||
|
||||
>>> dataset.as_pascal_voc(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...'
|
||||
... )
|
||||
|
||||
>>> dataset.as_coco(
|
||||
... images_directory_path='...',
|
||||
... annotations_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Convert labels between supported formats
|
||||
|
||||
```python
|
||||
>>> sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... ).as_pascal_voc(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Load classification datasets in one of the supported formats
|
||||
|
||||
```python
|
||||
>>> cs = sv.ClassificationDataset.from_folder_structure(
|
||||
... root_directory_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Save classification datasets in one of the supported formats
|
||||
|
||||
```python
|
||||
>>> cs.as_folder_structure(
|
||||
... root_directory_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
### [model evaluation](https://roboflow.github.io/supervision/metrics/detection/)
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(...)
|
||||
|
||||
>>> def callback(image: np.ndarray) -> sv.Detections:
|
||||
... ...
|
||||
|
||||
>>> confusion_matrix = sv.ConfusionMatrix.benchmark(
|
||||
... dataset = dataset,
|
||||
... callback = callback
|
||||
... )
|
||||
|
||||
>>> confusion_matrix.matrix
|
||||
array([
|
||||
[0., 0., 0., 0.],
|
||||
[0., 1., 0., 1.],
|
||||
[0., 1., 1., 0.],
|
||||
[1., 1., 0., 0.]
|
||||
])
|
||||
```
|
||||
|
||||
<details close>
|
||||
<summary>👉 more metrics</summary>
|
||||
|
||||
- Mean average precision (mAP) for object detection tasks.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(...)
|
||||
|
||||
>>> def callback(image: np.ndarray) -> sv.Detections:
|
||||
... ...
|
||||
|
||||
>>> mean_average_precision = sv.MeanAveragePrecision.benchmark(
|
||||
... dataset = dataset,
|
||||
... callback = callback
|
||||
... )
|
||||
|
||||
>>> mean_average_precision.map50_95
|
||||
0.433
|
||||
```
|
||||
```python
|
||||
sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
).as_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## 🎬 tutorials
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><img src="https://github.com/roboflow/supervision/assets/26109316/54afdf1c-218c-4451-8f12-627fb85f1682" alt="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><strong>Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking</strong></a>
|
||||
<div><strong>Created: 6 Sep 2023</strong> | <strong>Updated: 6 Sep 2023</strong></div>
|
||||
<br/> In this video, we explore real-time traffic analysis using YOLOv8 and ByteTrack to detect and track vehicles on aerial images. Harnessing the power of Python and Supervision, we delve deep into assigning cars to specific entry zones and understanding their direction of movement. By visualizing their paths, we gain insights into traffic flow across bustling roundabouts... </p>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/61a444c8-b135-48ce-b979-2a5ab47c5a91" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><strong>Speed Estimation & Vehicle Tracking | Computer Vision | Open Source</strong></a>
|
||||
<div><strong>Created: 11 Jan 2024</strong> | <strong>Updated: 11 Jan 2024</strong></div>
|
||||
<br/> Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/D-D6ZmadzPE" title="SAM - Segment Anything Model by Meta AI: Complete Guide"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/6913ff11-53c6-4341-8d90-eaff3023c3fd" alt="SAM - Segment Anything Model by Meta AI: Complete Guide" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/D-D6ZmadzPE" title="SAM - Segment Anything Model by Meta AI: Complete Guide"><strong>SAM - Segment Anything Model by Meta AI: Complete Guide</strong></a>
|
||||
<div><strong>Created: 11 Apr 2023</strong> | <strong>Updated: 11 Apr 2023</strong></div>
|
||||
<br/> Discover the incredible potential of Meta AI's Segment Anything Model (SAM)! We dive into SAM, an efficient and promptable model for image segmentation, which has revolutionized computer vision tasks. With over 1 billion masks on 11M licensed and privacy-respecting images, SAM's zero-shot performance is often competitive with or even superior to prior fully supervised results... </p>
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><img src="https://github.com/roboflow/supervision/assets/26109316/54afdf1c-218c-4451-8f12-627fb85f1682" alt="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><strong>Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking</strong></a>
|
||||
<div><strong>Created: 6 Sep 2023</strong> | <strong>Updated: 6 Sep 2023</strong></div>
|
||||
<br/> In this video, we explore real-time traffic analysis using YOLOv8 and ByteTrack to detect and track vehicles on aerial images. Harnessing the power of Python and Supervision, we delve deep into assigning cars to specific entry zones and understanding their direction of movement. By visualizing their paths, we gain insights into traffic flow across bustling roundabouts... </p>
|
||||
|
||||
## 💜 built with supervision
|
||||
|
||||
@@ -302,6 +239,8 @@ https://user-images.githubusercontent.com/26109316/207858600-ee862b22-0353-440b-
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-60e9c81b3900
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/3ac6982f-4943-4108-9b7f-51787ef1a69f
|
||||
|
||||
## 📚 documentation
|
||||
|
||||
Visit our [documentation](https://roboflow.github.io/supervision) page to learn how supervision can help you build computer vision applications faster and more reliably.
|
||||
@@ -363,5 +302,4 @@ We love your input! Please see our [contributing guide](https://github.com/robof
|
||||
</a>
|
||||
</a>
|
||||
</div>
|
||||
|
||||
</div>
|
||||
|
||||
Vendored
+1342
-1322
File diff suppressed because one or more lines are too long
+367
-93
@@ -1,16 +1,23 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
=== "BoundingBox"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
>>> annotated_frame = bounding_box_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -19,19 +26,40 @@
|
||||
|
||||
</div>
|
||||
|
||||
=== "RoundBox"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
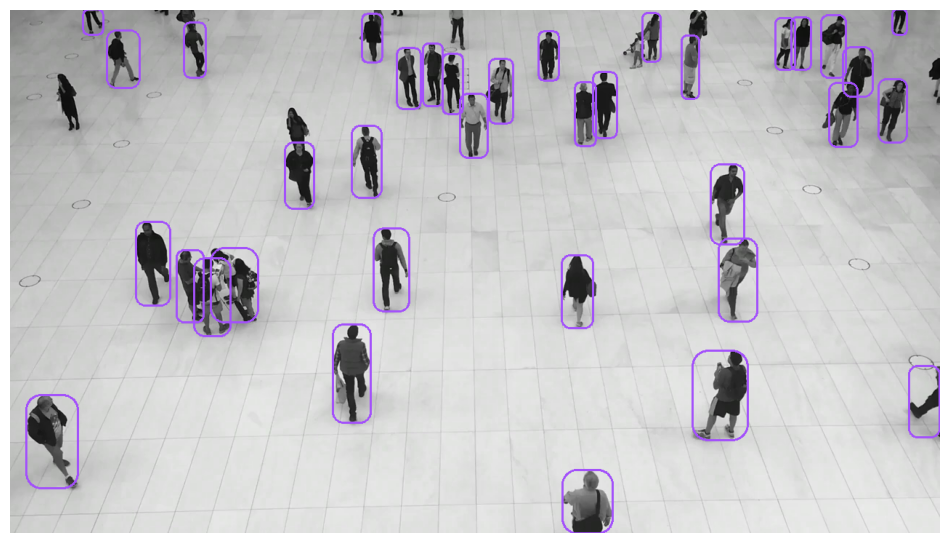
round_box_annotator = sv.RoundBoxAnnotator()
|
||||
annotated_frame = round_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "BoxCorner"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> corner_annotator = sv.BoxCornerAnnotator()
|
||||
>>> annotated_frame = corner_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
corner_annotator = sv.BoxCornerAnnotator()
|
||||
annotated_frame = corner_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -40,19 +68,19 @@
|
||||
|
||||
</div>
|
||||
|
||||
=== "BoxMask"
|
||||
=== "Color"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> box_mask_annotator = sv.BoxMaskAnnotator()
|
||||
>>> annotated_frame = box_mask_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
color_annotator = sv.ColorAnnotator()
|
||||
annotated_frame = color_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -64,16 +92,16 @@
|
||||
=== "Circle"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> circle_annotator = sv.CircleAnnotator()
|
||||
>>> annotated_frame = circle_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
circle_annotator = sv.CircleAnnotator()
|
||||
annotated_frame = circle_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -82,19 +110,61 @@
|
||||
|
||||
</div>
|
||||
|
||||
=== "Dot"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
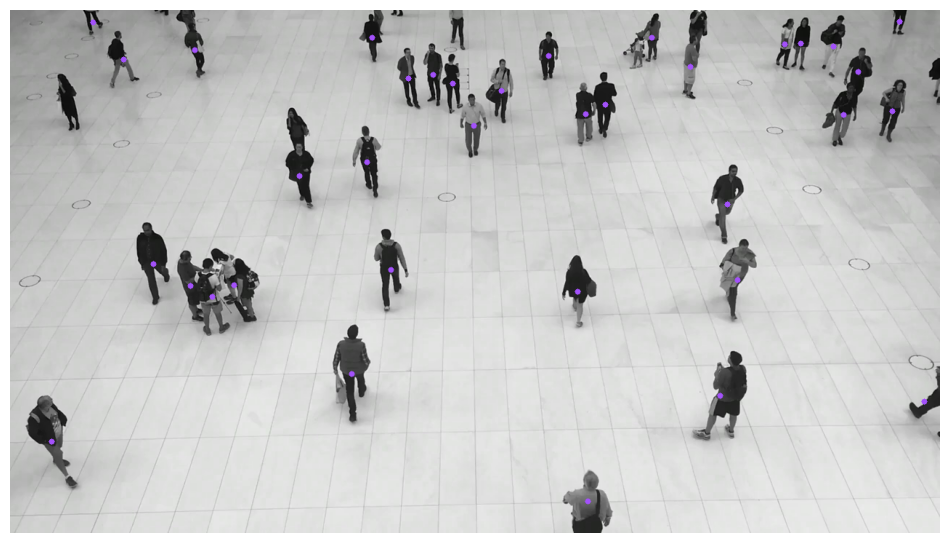
dot_annotator = sv.DotAnnotator()
|
||||
annotated_frame = dot_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Triangle"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
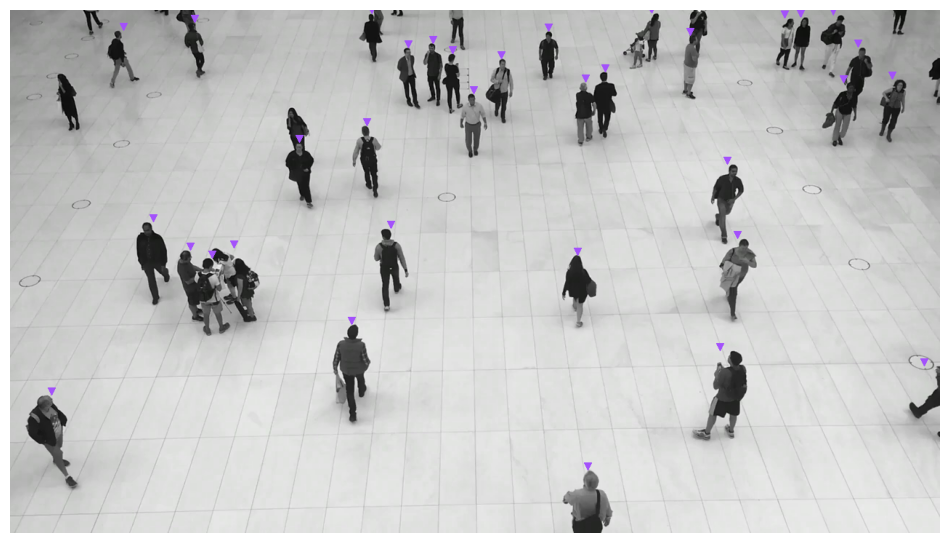
triangle_annotator = sv.TriangleAnnotator()
|
||||
annotated_frame = triangle_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Ellipse"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> ellipse_annotator = sv.EllipseAnnotator()
|
||||
>>> annotated_frame = ellipse_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
ellipse_annotator = sv.EllipseAnnotator()
|
||||
annotated_frame = ellipse_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -106,37 +176,58 @@
|
||||
=== "Halo"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> halo_annotator = sv.HaloAnnotator()
|
||||
>>> annotated_frame = halo_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
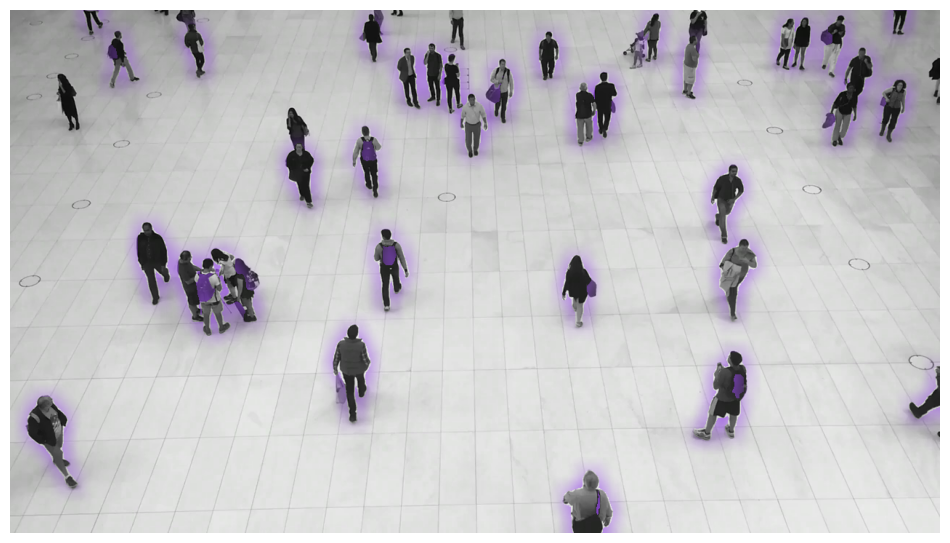
halo_annotator = sv.HaloAnnotator()
|
||||
annotated_frame = halo_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "PercentageBar"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
percentage_bar_annotator = sv.PercentageBarAnnotator()
|
||||
annotated_frame = percentage_bar_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
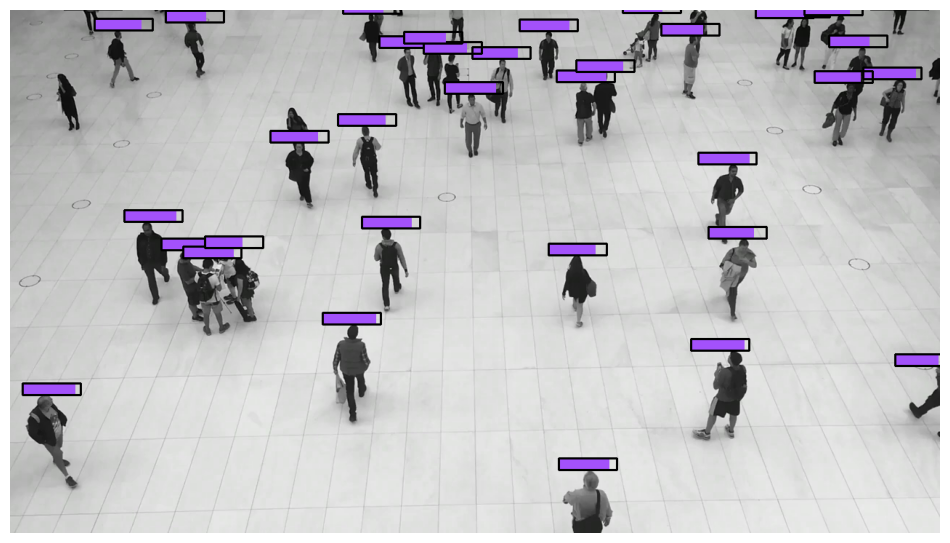{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Mask"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> mask_annotator = sv.MaskAnnotator()
|
||||
>>> annotated_frame = mask_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
annotated_frame = mask_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -145,19 +236,47 @@
|
||||
|
||||
</div>
|
||||
|
||||
=== "Polygon"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
polygon_annotator = sv.PolygonAnnotator()
|
||||
annotated_frame = polygon_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
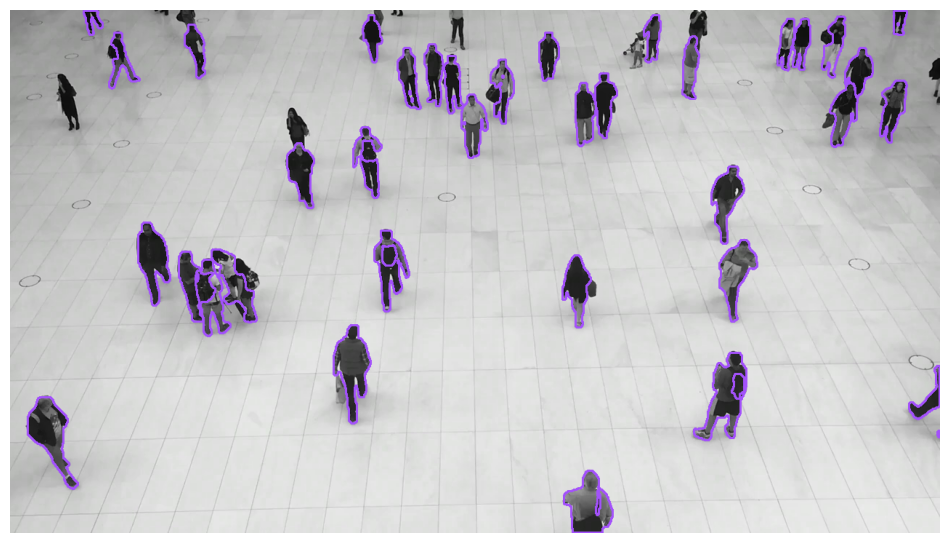{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Label"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
>>> annotated_frame = label_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -166,19 +285,34 @@
|
||||
|
||||
</div>
|
||||
|
||||
=== "Crop"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
crop_annotator = sv.CropAnnotator()
|
||||
annotated_frame = crop_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
=== "Blur"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> blur_annotator = sv.BlurAnnotator()
|
||||
>>> annotated_frame = blur_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
blur_annotator = sv.BlurAnnotator()
|
||||
annotated_frame = blur_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -187,19 +321,50 @@
|
||||
|
||||
</div>
|
||||
|
||||
=== "Pixelate"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
pixelate_annotator = sv.PixelateAnnotator()
|
||||
annotated_frame = pixelate_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
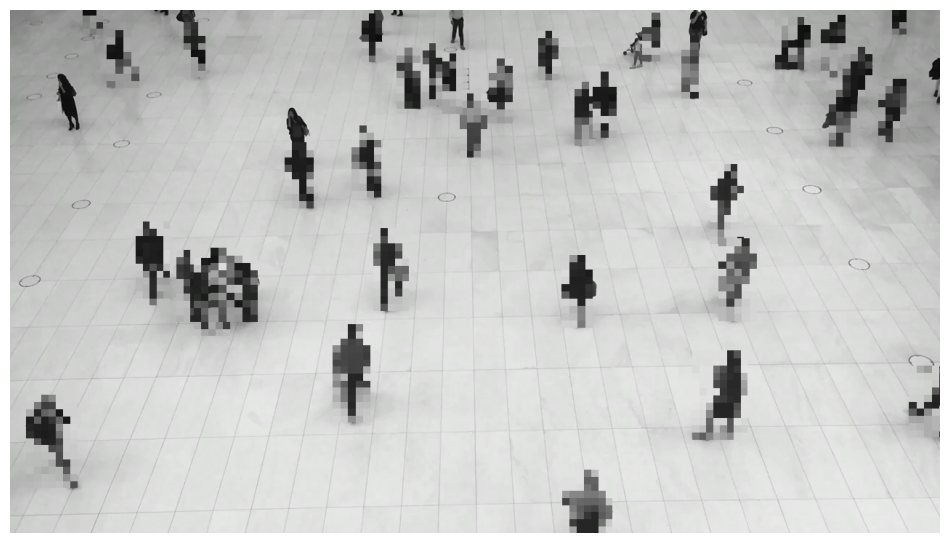{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Trace"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
model = YOLO('yolov8x.pt')
|
||||
|
||||
>>> trace_annotator = sv.TraceAnnotator()
|
||||
>>> annotated_frame = trace_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
frames_generator = get_video_frames_generator(source_path='...')
|
||||
tracker = sv.ByteTrack()
|
||||
|
||||
with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
annotated_frame = trace_annotator.annotate(
|
||||
scene=frame.copy(),
|
||||
detections=detections)
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -208,42 +373,151 @@
|
||||
|
||||
</div>
|
||||
|
||||
## BoundingBoxAnnotator
|
||||
=== "HeatMap"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO('yolov8x.pt')
|
||||
|
||||
heat_map_annotator = sv.HeatMapAnnotator()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
frames_generator = get_video_frames_generator(source_path='...')
|
||||
|
||||
with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
annotated_frame = heat_map_annotator.annotate(
|
||||
scene=frame.copy(),
|
||||
detections=detections)
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
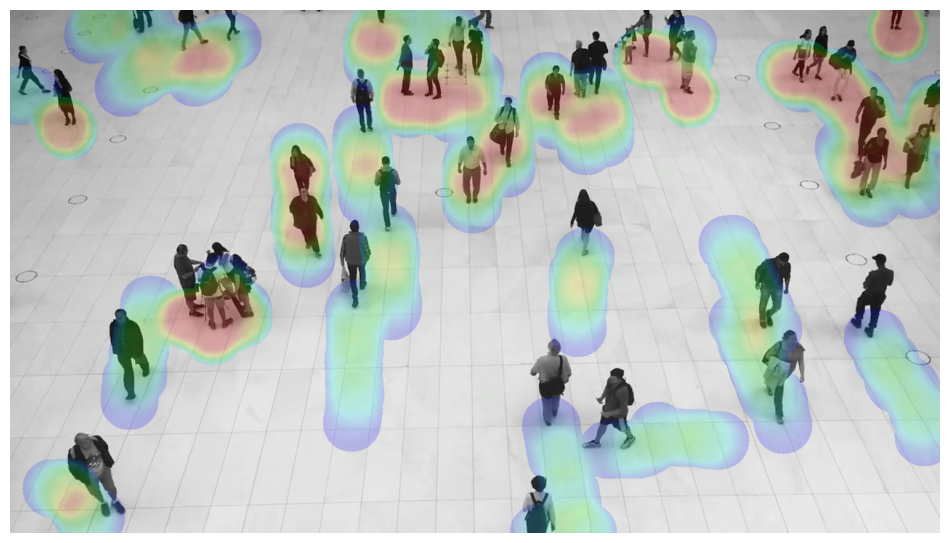{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BoundingBoxAnnotator">BoundingBoxAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.BoundingBoxAnnotator
|
||||
|
||||
## BoxCornerAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.RoundBoxAnnotator">RoundBoxAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.RoundBoxAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BoxCornerAnnotator">BoxCornerAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.BoxCornerAnnotator
|
||||
|
||||
## BoxMaskAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.OrientedBoxAnnotator">OrientedBoxAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.BoxMaskAnnotator
|
||||
:::supervision.annotators.core.OrientedBoxAnnotator
|
||||
|
||||
## CircleAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.ColorAnnotator">ColorAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.ColorAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.CircleAnnotator">CircleAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.CircleAnnotator
|
||||
|
||||
## EllipseAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.DotAnnotator">DotAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.DotAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.TriangleAnnotator">TriangleAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.TriangleAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.EllipseAnnotator">EllipseAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.EllipseAnnotator
|
||||
|
||||
## HaloAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.HaloAnnotator">HaloAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.HaloAnnotator
|
||||
|
||||
## MaskAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.PercentageBarAnnotator">PercentageBarAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.PercentageBarAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.HeatMapAnnotator">HeatMapAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.HeatMapAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.MaskAnnotator">MaskAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.MaskAnnotator
|
||||
|
||||
## LabelAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.PolygonAnnotator">PolygonAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.PolygonAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.LabelAnnotator">LabelAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.LabelAnnotator
|
||||
|
||||
## BlurAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BlurAnnotator">BlurAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.BlurAnnotator
|
||||
|
||||
## TraceAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.PixelateAnnotator">PixelateAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.PixelateAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.TraceAnnotator">TraceAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.TraceAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.CropAnnotator">CropAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.CropAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.ColorLookup">ColorLookup</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.utils.ColorLookup
|
||||
|
||||
@@ -0,0 +1,31 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Assets
|
||||
|
||||
Supervision offers an assets download utility that allows you to download video files
|
||||
that you can use in your demos.
|
||||
|
||||
## Install extra
|
||||
|
||||
To install the Supervision assets utility, you can use `pip`. This utility is available
|
||||
as an extra within the Supervision package.
|
||||
|
||||
!!! example "pip install"
|
||||
|
||||
```bash
|
||||
pip install "supervision[assets]"
|
||||
```
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>download_assets</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.downloader.download_assets
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoAssets</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.list.VideoAssets
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 19 KiB |
+297
-46
@@ -1,18 +1,269 @@
|
||||
### 0.19.0 <small>March 15, 2024</small>
|
||||
|
||||
- Added [#818](https://github.com/roboflow/supervision/pull/818): [`sv.CSVSink`](/0.19.0/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) allowing for the straightforward saving of image, video, or stream inference results in a `.csv` file.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO(<SOURCE_MODEL_PATH>)
|
||||
csv_sink = sv.CSVSink(<RESULT_CSV_FILE_PATH>)
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with csv_sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
csv_sink.append(detections, custom_data={<CUSTOM_LABEL>:<CUSTOM_DATA>})
|
||||
```
|
||||
|
||||
- Added [#819](https://github.com/roboflow/supervision/pull/819): [`sv.JSONSink`](/0.19.0/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink) allowing for the straightforward saving of image, video, or stream inference results in a `.json` file.
|
||||
|
||||
```python
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO(<SOURCE_MODEL_PATH>)
|
||||
json_sink = sv.JSONSink(<RESULT_JSON_FILE_PATH>)
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with json_sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
json_sink.append(detections, custom_data={<CUSTOM_LABEL>:<CUSTOM_DATA>})
|
||||
```
|
||||
|
||||
- Added [#847](https://github.com/roboflow/supervision/pull/847): [`sv.mask_iou_batch`](/0.19.0/detection/utils/#supervision.detection.utils.mask_iou_batch) allowing to compute Intersection over Union (IoU) of two sets of masks.
|
||||
|
||||
- Added [#847](https://github.com/roboflow/supervision/pull/847): [`sv.mask_non_max_suppression`](/0.19.0/detection/utils/#supervision.detection.utils.mask_non_max_suppression) allowing to perform Non-Maximum Suppression (NMS) on segmentation predictions.
|
||||
|
||||
- Added [#888](https://github.com/roboflow/supervision/pull/888): [`sv.CropAnnotator`](/0.19.0/annotators/#supervision.annotators.core.CropAnnotator) allowing users to annotate the scene with scaled-up crops of detections.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
|
||||
crop_annotator = sv.CropAnnotator()
|
||||
annotated_frame = crop_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
- Changed [#827](https://github.com/roboflow/supervision/pull/827): [`sv.ByteTrack.reset`](/0.19.0/tracking/#supervision.tracking.ByteTrack.reset) allowing users to clear trackers state, enabling the processing of multiple video files in sequence.
|
||||
|
||||
- Changed [#802](https://github.com/roboflow/supervision/pull/802): [`sv.LineZoneAnnotator`](/0.19.0/detection/tools/line_zone/#supervision.detection.line_zone.LineZone) allowing to hide in/out count using `display_in_count` and `display_out_count` properties.
|
||||
|
||||
- Changed [#787](https://github.com/roboflow/supervision/pull/787): [`sv.ByteTrack`](/0.19.0/tracking/#supervision.tracking.ByteTrack) input arguments and docstrings updated to improve readability and ease of use.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `track_buffer`, `track_thresh`, and `match_thresh` parameters in `sv.ByterTrack` are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
|
||||
- Changed [#910](https://github.com/roboflow/supervision/pull/910): [`sv.PolygonZone`](/0.19.0/detection/tools/polygon_zone/#supervision.detection.tools.polygon_zone.PolygonZone) to now accept a list of specific box anchors that must be in zone for a detection to be counted.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `triggering_position ` parameter in `sv.PolygonZone` is deprecated and will be removed in `supervision-0.23.0`. Use `triggering_anchors` instead.
|
||||
|
||||
- Changed [#875](https://github.com/roboflow/supervision/pull/875): annotators adding support for Pillow images. All supervision Annotators can now accept an image as either a numpy array or a Pillow Image. They automatically detect its type, draw annotations, and return the output in the same format as the input.
|
||||
|
||||
- Fixed [#944](https://github.com/roboflow/supervision/pull/944): [`sv.DetectionsSmoother`](/0.19.0/detection/tools/smoother/#supervision.detection.tools.smoother.DetectionsSmoother) removing `tracking_id` from `sv.Detections`.
|
||||
|
||||
### 0.18.0 <small>January 25, 2024</small>
|
||||
|
||||
- Added [#720](https://github.com/roboflow/supervision/pull/720): [`sv.PercentageBarAnnotator`](/0.18.0/annotators/#percentagebarannotator) allowing to annotate images and videos with percentage values representing confidence or other custom property.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> percentage_bar_annotator = sv.PercentageBarAnnotator()
|
||||
>>> annotated_frame = percentage_bar_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [#702](https://github.com/roboflow/supervision/pull/702): [`sv.RoundBoxAnnotator`](/0.18.0/annotators/#roundboxannotator) allowing to annotate images and videos with rounded corners bounding boxes.
|
||||
|
||||
- Added [#770](https://github.com/roboflow/supervision/pull/770): [`sv.OrientedBoxAnnotator`](/0.18.0/annotators/#orientedboxannotator) allowing to annotate images and videos with OBB (Oriented Bounding Boxes).
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO("yolov8n-obb.pt")
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
|
||||
oriented_box_annotator = sv.OrientedBoxAnnotator()
|
||||
annotated_frame = oriented_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
- Added [#696](https://github.com/roboflow/supervision/pull/696): [`sv.DetectionsSmoother`](/0.18.0/detection/tools/smoother/#detection-smoother) allowing for smoothing detections over multiple frames in video tracking.
|
||||
|
||||
- Added [#769](https://github.com/roboflow/supervision/pull/769): [`sv.ColorPalette.from_matplotlib`](/0.18.0/draw/color/#supervision.draw.color.ColorPalette.from_matplotlib) allowing users to create a `sv.ColorPalette` instance from a Matplotlib color palette.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> sv.ColorPalette.from_matplotlib('viridis', 5)
|
||||
ColorPalette(colors=[Color(r=68, g=1, b=84), Color(r=59, g=82, b=139), ...])
|
||||
```
|
||||
|
||||
- Changed [#770](https://github.com/roboflow/supervision/pull/770): [`sv.Detections.from_ultralytics`](/0.18.0/detection/core/#supervision.detection.core.Detections.from_ultralytics) adding support for OBB (Oriented Bounding Boxes).
|
||||
|
||||
- Changed [#735](https://github.com/roboflow/supervision/pull/735): [`sv.LineZone`](/0.18.0/detection/tools/line_zone/#linezone) to now accept a list of specific box anchors that must cross the line for a detection to be counted. This update marks a significant improvement from the previous requirement, where all four box corners were necessary. Users can now specify a single anchor, such as `sv.Position.BOTTOM_CENTER`, or any other combination of anchors defined as `List[sv.Position]`.
|
||||
|
||||
- Changed [#756](https://github.com/roboflow/supervision/pull/756): [`sv.Color`](/0.18.0/draw/color/#color)'s and [`sv.ColorPalette`](/0.18.0/draw/color/#colorpalette)'s method of accessing predefined colors, transitioning from a function-based approach (`sv.Color.red()`) to a more intuitive and conventional property-based method (`sv.Color.RED`).
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
`sv.ColorPalette.default()` is deprecated and will be removed in `supervision-0.22.0`. Use `sv.ColorPalette.DEFAULT` instead.
|
||||
|
||||
|
||||
- Changed [#769](https://github.com/roboflow/supervision/pull/769): [`sv.ColorPalette.DEFAULT`](/0.18.0/draw/color/#colorpalette) value, giving users a more extensive set of annotation colors.
|
||||
|
||||
- Changed [#677](https://github.com/roboflow/supervision/pull/677): `sv.Detections.from_roboflow` to [`sv.Detections.from_inference`](/0.18.0/detection/core/#supervision.detection.core.Detections.from_inference) streamlining its functionality to be compatible with both the both [inference](https://github.com/roboflow/inference) pip package and the Robloflow [hosted API](https://docs.roboflow.com/deploy/hosted-api).
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
`Detections.from_roboflow()` is deprecated and will be removed in `supervision-0.22.0`. Use `Detections.from_inference` instead.
|
||||
|
||||
|
||||
- Fixed [#735](https://github.com/roboflow/supervision/pull/735): [`sv.LineZone`](/0.18.0/detection/tools/line_zone/#linezone) functionality to accurately update the counter when an object crosses a line from any direction, including from the side. This enhancement enables more precise tracking and analytics, such as calculating individual in/out counts for each lane on the road.
|
||||
|
||||
### 0.17.0 <small>December 06, 2023</small>
|
||||
|
||||
- Added [#633](https://github.com/roboflow/supervision/pull/633): [`sv.PixelateAnnotator`](/0.17.0/annotators/#supervision.annotators.core.PixelateAnnotator) allowing to pixelate objects on images and videos.
|
||||
|
||||
- Added [#652](https://github.com/roboflow/supervision/pull/652): [`sv.TriangleAnnotator`](/0.17.0/annotators/#supervision.annotators.core.TriangleAnnotator) allowing to annotate images and videos with triangle markers.
|
||||
|
||||
- Added [#602](https://github.com/roboflow/supervision/pull/602): [`sv.PolygonAnnotator`](/0.17.0/annotators/#supervision.annotators.core.PolygonAnnotator) allowing to annotate images and videos with segmentation mask outline.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> polygon_annotator = sv.PolygonAnnotator()
|
||||
>>> annotated_frame = polygon_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [#476](https://github.com/roboflow/supervision/pull/476): [`sv.assets`](/0.18.0/assets/) allowing download of video files that you can use in your demos.
|
||||
|
||||
```python
|
||||
>>> from supervision.assets import download_assets, VideoAssets
|
||||
>>> download_assets(VideoAssets.VEHICLES)
|
||||
"vehicles.mp4"
|
||||
```
|
||||
|
||||
- Added [#605](https://github.com/roboflow/supervision/pull/605): [`Position.CENTER_OF_MASS`](/0.17.0/geometry/core/#position) allowing to place labels in center of mass of segmentation masks.
|
||||
|
||||
- Added [#651](https://github.com/roboflow/supervision/pull/651): [`sv.scale_boxes`](/0.17.0/detection/utils/#supervision.detection.utils.scale_boxes) allowing to scale [`sv.Detections.xyxy`](/0.17.0/detection/core/#supervision.detection.core.Detections) values.
|
||||
|
||||
- Added [#637](https://github.com/roboflow/supervision/pull/637): [`sv.calculate_dynamic_text_scale`](/0.17.0/draw/utils/#supervision.draw.utils.calculate_dynamic_text_scale) and [`sv.calculate_dynamic_line_thickness`](/0.17.0/draw/utils/#supervision.draw.utils.calculate_dynamic_line_thickness) allowing text scale and line thickness to match image resolution.
|
||||
|
||||
- Added [#620](https://github.com/roboflow/supervision/pull/620): [`sv.Color.as_hex`](/0.17.0/draw/color/#supervision.draw.color.Color.as_hex) allowing to extract color value in HEX format.
|
||||
|
||||
- Added [#572](https://github.com/roboflow/supervision/pull/572): [`sv.Classifications.from_timm`](/0.17.0/classification/core/#supervision.classification.core.Classifications.from_timm) allowing to load classification result from [timm](https://huggingface.co/docs/hub/timm) models.
|
||||
|
||||
- Added [#478](https://github.com/roboflow/supervision/pull/478): [`sv.Classifications.from_clip`](/0.17.0/classification/core/#supervision.classification.core.Classifications.from_clip) allowing to load classification result from [clip](https://github.com/openai/clip) model.
|
||||
|
||||
- Added [#571](https://github.com/roboflow/supervision/pull/571): [`sv.Detections.from_azure_analyze_image`](/0.17.0/detection/core/#supervision.detection.core.Detections.from_azure_analyze_image) allowing to load detection results from [Azure Image Analysis](https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/concept-object-detection-40).
|
||||
|
||||
- Changed [#646](https://github.com/roboflow/supervision/pull/646): `sv.BoxMaskAnnotator` renaming it to [`sv.ColorAnnotator`](/0.17.0/annotators/#supervision.annotators.core.ColorAnnotator).
|
||||
|
||||
- Changed [#606](https://github.com/roboflow/supervision/pull/606): [`sv.MaskAnnotator`](/0.17.0/annotators/#supervision.annotators.core.MaskAnnotator) to make it **5x faster**.
|
||||
|
||||
- Fixed [#584](https://github.com/roboflow/supervision/pull/584): [`sv.DetectionDataset.from_yolo`](/0.17.0/datasets/#supervision.dataset.core.DetectionDataset.from_yolo) to ignore empty lines in annotation files.
|
||||
|
||||
- Fixed [#555](https://github.com/roboflow/supervision/pull/555): [`sv.BlurAnnotator`](/0.17.0/annotators/#supervision.annotators.core.BlurAnnotator) to trim negative coordinates before bluring detections.
|
||||
|
||||
- Fixed [#511](https://github.com/roboflow/supervision/pull/511): [`sv.TraceAnnotator`](/0.17.0/annotators/#supervision.annotators.core.TraceAnnotator) to respect trace position.
|
||||
|
||||
### 0.16.0 <small>October 19, 2023</small>
|
||||
|
||||
- Added [#422](https://github.com/roboflow/supervision/pull/422): [`sv.BoxMaskAnnotator`](/0.16.0/annotators/#supervision.annotators.core.BoxMaskAnnotator) allowing to annotate images and videos with mox masks.
|
||||
|
||||
- Added [#433](https://github.com/roboflow/supervision/pull/433): [`sv.HaloAnnotator`](/0.16.0/annotators/#supervision.annotators.core.HaloAnnotator) allowing to annotate images and videos with halo effect.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> halo_annotator = sv.HaloAnnotator()
|
||||
>>> annotated_frame = halo_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [#466](https://github.com/roboflow/supervision/pull/466): [`sv.HeatMapAnnotator`](/0.16.0/annotators/#supervision.annotators.core.HeatMapAnnotator) allowing to annotate videos with heat maps.
|
||||
|
||||
- Added [#492](https://github.com/roboflow/supervision/pull/492): [`sv.DotAnnotator`](/0.16.0/annotators/#supervision.annotators.core.DotAnnotator) allowing to annotate images and videos with dots.
|
||||
|
||||
- Added [#449](https://github.com/roboflow/supervision/pull/449): [`sv.draw_image`](/0.16.0/draw/utils/#supervision.draw.utils.draw_image) allowing to draw an image onto a given scene with specified opacity and dimensions.
|
||||
|
||||
- Added [#280](https://github.com/roboflow/supervision/pull/280): [`sv.FPSMonitor`](/0.16.0/utils/video/#supervision.utils.video.FPSMonitor) for monitoring frames per second (FPS) to benchmark latency.
|
||||
|
||||
- Added [#454](https://github.com/roboflow/supervision/pull/454): 🤗 Hugging Face Annotators [space](https://huggingface.co/spaces/Roboflow/Annotators).
|
||||
|
||||
- Changed [#482](https://github.com/roboflow/supervision/pull/482): [`sv.LineZone.trigger`](/0.16.0/detection/tools/line_zone/#supervision.detection.line_counter.LineZone.trigger) now return `Tuple[np.ndarray, np.ndarray]`. The first array indicates which detections have crossed the line from outside to inside. The second array indicates which detections have crossed the line from inside to outside.
|
||||
|
||||
- Changed [#465](https://github.com/roboflow/supervision/pull/465): Annotator argument name from `color_map: str` to `color_lookup: ColorLookup` enum to increase type safety.
|
||||
|
||||
- Changed [#426](https://github.com/roboflow/supervision/pull/426): [`sv.MaskAnnotator`](/0.16.0/annotators/#supervision.annotators.core.MaskAnnotator) allowing 2x faster annotation.
|
||||
|
||||
- Fixed [#477](https://github.com/roboflow/supervision/pull/477): Poetry env definition allowing proper local installation.
|
||||
|
||||
- Fixed [#430](https://github.com/roboflow/supervision/pull/430): [`sv.ByteTrack`](/0.16.0/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) to return `np.array([], dtype=int)` when `svDetections` is empty.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
`sv.Detections.from_yolov8` and `sv.Classifications.from_yolov8` as those are now replaced by [`sv.Detections.from_ultralytics`](/0.16.0/detection/core/#supervision.detection.core.Detections.from_ultralytics) and [`sv.Classifications.from_ultralytics`](/0.16.0/classification/core/#supervision.classification.core.Classifications.from_ultralytics).
|
||||
|
||||
|
||||
### 0.15.0 <small>October 5, 2023</small>
|
||||
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.BoundingBoxAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BoundingBoxAnnotator) allowing to annotate images and videos with bounding boxes.
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.BoundingBoxAnnotator`](/0.15.0/annotators/#supervision.annotators.core.BoundingBoxAnnotator) allowing to annotate images and videos with bounding boxes.
|
||||
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.BoxCornerAnnotator `](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BoxCornerAnnotator) allowing to annotate images and videos with just bounding box corners.
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.BoxCornerAnnotator `](/0.15.0/annotators/#supervision.annotators.core.BoxCornerAnnotator) allowing to annotate images and videos with just bounding box corners.
|
||||
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.MaskAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.MaskAnnotator) allowing to annotate images and videos with segmentation masks.
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.MaskAnnotator`](/0.15.0/annotators/#supervision.annotators.core.MaskAnnotator) allowing to annotate images and videos with segmentation masks.
|
||||
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.EllipseAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.EllipseAnnotator) allowing to annotate images and videos with ellipses (sports game style).
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.EllipseAnnotator`](/0.15.0/annotators/#supervision.annotators.core.EllipseAnnotator) allowing to annotate images and videos with ellipses (sports game style).
|
||||
|
||||
- Added [#386](https://github.com/roboflow/supervision/pull/386): [`sv.CircleAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.CircleAnnotator) allowing to annotate images and videos with circles.
|
||||
- Added [#386](https://github.com/roboflow/supervision/pull/386): [`sv.CircleAnnotator`](/0.15.0/annotators/#supervision.annotators.core.CircleAnnotator) allowing to annotate images and videos with circles.
|
||||
|
||||
- Added [#354](https://github.com/roboflow/supervision/pull/354): [`sv.TraceAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.TraceAnnotator) allowing to draw path of moving objects on videos.
|
||||
- Added [#354](https://github.com/roboflow/supervision/pull/354): [`sv.TraceAnnotator`](/0.15.0/annotators/#supervision.annotators.core.TraceAnnotator) allowing to draw path of moving objects on videos.
|
||||
|
||||
- Added [#405](https://github.com/roboflow/supervision/pull/405): [`sv.BlurAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BlurAnnotator) allowing to blur objects on images and videos.
|
||||
- Added [#405](https://github.com/roboflow/supervision/pull/405): [`sv.BlurAnnotator`](/0.15.0/annotators/#supervision.annotators.core.BlurAnnotator) allowing to blur objects on images and videos.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -29,17 +280,17 @@
|
||||
|
||||
- Added [#354](https://github.com/roboflow/supervision/pull/354): Supervision usage [example](https://github.com/roboflow/supervision/tree/develop/examples/traffic_analysis). You can now learn how to perform traffic flow analysis with Supervision.
|
||||
|
||||
- Changed [#399](https://github.com/roboflow/supervision/pull/399): [`sv.Detections.from_roboflow`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_roboflow) now does not require `class_list` to be specified. The `class_id` value can be extracted directly from the [inference](https://github.com/roboflow/inference) response.
|
||||
- Changed [#399](https://github.com/roboflow/supervision/pull/399): [`sv.Detections.from_roboflow`](/0.15.0/detection/core/#supervision.detection.core.Detections.from_roboflow) now does not require `class_list` to be specified. The `class_id` value can be extracted directly from the [inference](https://github.com/roboflow/inference) response.
|
||||
|
||||
- Changed [#381](https://github.com/roboflow/supervision/pull/381): [`sv.VideoSink`](https://supervision.roboflow.com/utils/video/#videosink) now allows to customize the output codec.
|
||||
- Changed [#381](https://github.com/roboflow/supervision/pull/381): [`sv.VideoSink`](/0.15.0/utils/video/#videosink) now allows to customize the output codec.
|
||||
|
||||
- Changed [#361](https://github.com/roboflow/supervision/pull/361): [`sv.InferenceSlicer`](https://supervision.roboflow.com/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) can now operate in multithreading mode.
|
||||
- Changed [#361](https://github.com/roboflow/supervision/pull/361): [`sv.InferenceSlicer`](/0.15.0/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) can now operate in multithreading mode.
|
||||
|
||||
- Fixed [#348](https://github.com/roboflow/supervision/pull/348): [`sv.Detections.from_deepsparse`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_deepsparse) to allow processing empty [deepsparse](https://github.com/neuralmagic/deepsparse) result object.
|
||||
- Fixed [#348](https://github.com/roboflow/supervision/pull/348): [`sv.Detections.from_deepsparse`](/0.15.0/detection/core/#supervision.detection.core.Detections.from_deepsparse) to allow processing empty [deepsparse](https://github.com/neuralmagic/deepsparse) result object.
|
||||
|
||||
### 0.14.0 <small>August 31, 2023</small>
|
||||
|
||||
- Added [#282](https://github.com/roboflow/supervision/pull/282): support for SAHI inference technique with [`sv.InferenceSlicer`](https://supervision.roboflow.com/detection/tools/inference_slicer).
|
||||
- Added [#282](https://github.com/roboflow/supervision/pull/282): support for SAHI inference technique with [`sv.InferenceSlicer`](/0.14.0/detection/tools/inference_slicer).
|
||||
|
||||
```python
|
||||
>>> import cv2
|
||||
@@ -58,23 +309,23 @@
|
||||
>>> detections = slicer(image)
|
||||
```
|
||||
|
||||
- Added [#297](https://github.com/roboflow/supervision/pull/297): [`Detections.from_deepsparse`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_deepsparse) to enable seamless integration with [DeepSparse](https://github.com/neuralmagic/deepsparse) framework.
|
||||
- Added [#297](https://github.com/roboflow/supervision/pull/297): [`Detections.from_deepsparse`](/0.14.0/detection/core/#supervision.detection.core.Detections.from_deepsparse) to enable seamless integration with [DeepSparse](https://github.com/neuralmagic/deepsparse) framework.
|
||||
|
||||
- Added [#281](https://github.com/roboflow/supervision/pull/281): [`sv.Classifications.from_ultralytics`](https://supervision.roboflow.com/classification/core/#supervision.classification.core.Classifications.from_ultralytics) to enable seamless integration with [Ultralytics](https://github.com/ultralytics/ultralytics) framework. This will enable you to use supervision with all [models](https://docs.ultralytics.com/models/) that Ultralytics supports.
|
||||
- Added [#281](https://github.com/roboflow/supervision/pull/281): [`sv.Classifications.from_ultralytics`](/0.14.0/classification/core/#supervision.classification.core.Classifications.from_ultralytics) to enable seamless integration with [Ultralytics](https://github.com/ultralytics/ultralytics) framework. This will enable you to use supervision with all [models](https://docs.ultralytics.com/models/) that Ultralytics supports.
|
||||
|
||||
!!! warning
|
||||
!!! failure "Deprecated"
|
||||
|
||||
[sv.Detections.from_yolov8](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_yolov8) and [sv.Classifications.from_yolov8](https://supervision.roboflow.com/classification/core/#supervision.classification.core.Classifications.from_yolov8) are now deprecated and will be removed with supervision-0.16.0 release.
|
||||
[sv.Detections.from_yolov8](/0.14.0/detection/core/#supervision.detection.core.Detections.from_yolov8) and [sv.Classifications.from_yolov8](/0.14.0/classification/core/#supervision.classification.core.Classifications.from_yolov8) are now deprecated and will be removed with `supervision-0.16.0` release.
|
||||
|
||||
- Added [#341](https://github.com/roboflow/supervision/pull/341): First supervision usage example script showing how to detect and track objects on video using YOLOv8 + Supervision.
|
||||
|
||||
- Changed [#296](https://github.com/roboflow/supervision/pull/296): [`sv.ClassificationDataset`](https://supervision.roboflow.com/dataset/core/#supervision.dataset.core.ClassificationDataset) and [`sv.DetectionDataset`](https://supervision.roboflow.com/dataset/core/#supervision.dataset.core.DetectionDataset) now use image path (not image name) as dataset keys.
|
||||
- Changed [#296](https://github.com/roboflow/supervision/pull/296): [`sv.ClassificationDataset`](/0.14.0/dataset/core/#supervision.dataset.core.ClassificationDataset) and [`sv.DetectionDataset`](/0.14.0/dataset/core/#supervision.dataset.core.DetectionDataset) now use image path (not image name) as dataset keys.
|
||||
|
||||
- Fixed [#300](https://github.com/roboflow/supervision/pull/300): [`Detections.from_roboflow`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_roboflow) to filter out polygons with less than 3 points.
|
||||
- Fixed [#300](https://github.com/roboflow/supervision/pull/300): [`Detections.from_roboflow`](/0.14.0/detection/core/#supervision.detection.core.Detections.from_roboflow) to filter out polygons with less than 3 points.
|
||||
|
||||
### 0.13.0 <small>August 8, 2023</small>
|
||||
|
||||
- Added [#236](https://github.com/roboflow/supervision/pull/236): support for mean average precision (mAP) for object detection models with [`sv.MeanAveragePrecision`](https://roboflow.github.io/supervision/metrics/detection/#meanaverageprecision).
|
||||
- Added [#236](https://github.com/roboflow/supervision/pull/236): support for mean average precision (mAP) for object detection models with [`sv.MeanAveragePrecision`](/0.13.0/metrics/detection/#meanaverageprecision).
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -96,25 +347,25 @@
|
||||
0.433
|
||||
```
|
||||
|
||||
- Added [#256](https://github.com/roboflow/supervision/pull/256): support for ByteTrack for object tracking with [`sv.ByteTrack`](https://roboflow.github.io/supervision/tracker/core/#bytetrack).
|
||||
- Added [#256](https://github.com/roboflow/supervision/pull/256): support for ByteTrack for object tracking with [`sv.ByteTrack`](/0.13.0/tracker/core/#bytetrack).
|
||||
|
||||
- Added [#222](https://github.com/roboflow/supervision/pull/222): [`sv.Detections.from_ultralytics`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_ultralytics) to enable seamless integration with [Ultralytics](https://github.com/ultralytics/ultralytics) framework. This will enable you to use `supervision` with all [models](https://docs.ultralytics.com/models/) that Ultralytics supports.
|
||||
- Added [#222](https://github.com/roboflow/supervision/pull/222): [`sv.Detections.from_ultralytics`](/0.13.0/detection/core/#supervision.detection.core.Detections.from_ultralytics) to enable seamless integration with [Ultralytics](https://github.com/ultralytics/ultralytics) framework. This will enable you to use `supervision` with all [models](https://docs.ultralytics.com/models/) that Ultralytics supports.
|
||||
|
||||
!!! warning
|
||||
!!! failure "Deprecated"
|
||||
|
||||
[`sv.Detections.from_yolov8`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_yolov8) is now deprecated and will be removed with `supervision-0.15.0` release.
|
||||
[`sv.Detections.from_yolov8`](/0.13.0/detection/core/#supervision.detection.core.Detections.from_yolov8) is now deprecated and will be removed with `supervision-0.15.0` release.
|
||||
|
||||
- Added [#191](https://github.com/roboflow/supervision/pull/191): [`sv.Detections.from_paddledet`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_paddledet) to enable seamless integration with [PaddleDetection](https://github.com/PaddlePaddle/PaddleDetection) framework.
|
||||
- Added [#191](https://github.com/roboflow/supervision/pull/191): [`sv.Detections.from_paddledet`](/0.13.0/detection/core/#supervision.detection.core.Detections.from_paddledet) to enable seamless integration with [PaddleDetection](https://github.com/PaddlePaddle/PaddleDetection) framework.
|
||||
|
||||
- Added [#245](https://github.com/roboflow/supervision/pull/245): support for loading PASCAL VOC segmentation datasets with [`sv.DetectionDataset.`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.from_pascal_voc).
|
||||
- Added [#245](https://github.com/roboflow/supervision/pull/245): support for loading PASCAL VOC segmentation datasets with [`sv.DetectionDataset.`](/0.13.0/dataset/core/#supervision.dataset.core.DetectionDataset.from_pascal_voc).
|
||||
|
||||
### 0.12.0 <small>July 24, 2023</small>
|
||||
|
||||
!!! warning
|
||||
!!! failure "Python 3.7. Support Terminated"
|
||||
|
||||
With the `supervision-0.12.0` release, we are terminating official support for Python 3.7.
|
||||
|
||||
- Added [#177](https://github.com/roboflow/supervision/pull/177): initial support for object detection model benchmarking with [`sv.ConfusionMatrix`](https://roboflow.github.io/supervision/metrics/detection/#confusionmatrix).
|
||||
- Added [#177](https://github.com/roboflow/supervision/pull/177): initial support for object detection model benchmarking with [`sv.ConfusionMatrix`](/0.12.0/metrics/detection/#confusionmatrix).
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -141,23 +392,23 @@ array([
|
||||
])
|
||||
```
|
||||
|
||||
- Added [#173](https://github.com/roboflow/supervision/pull/173): [`Detections.from_mmdetection`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_mmdetection) to enable seamless integration with [MMDetection](https://github.com/open-mmlab/mmdetection) framework.
|
||||
- Added [#173](https://github.com/roboflow/supervision/pull/173): [`Detections.from_mmdetection`](/0.12.0/detection/core/#supervision.detection.core.Detections.from_mmdetection) to enable seamless integration with [MMDetection](https://github.com/open-mmlab/mmdetection) framework.
|
||||
|
||||
- Added [#130](https://github.com/roboflow/supervision/issues/130): ability to [install](https://roboflow.github.io/supervision/) package in `headless` or `desktop` mode.
|
||||
- Added [#130](https://github.com/roboflow/supervision/issues/130): ability to [install](https://supervision.roboflow.com/) package in `headless` or `desktop` mode.
|
||||
|
||||
- Changed [#180](https://github.com/roboflow/supervision/pull/180): packing method from `setup.py` to `pyproject.toml`.
|
||||
|
||||
- Fixed [#188](https://github.com/roboflow/supervision/issues/188): [`sv.DetectionDataset.from_cooc`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.from_coco) can't be loaded when there are images without annotations.
|
||||
- Fixed [#188](https://github.com/roboflow/supervision/issues/188): [`sv.DetectionDataset.from_cooc`](/0.12.0/dataset/core/#supervision.dataset.core.DetectionDataset.from_coco) can't be loaded when there are images without annotations.
|
||||
|
||||
- Fixed [#226](https://github.com/roboflow/supervision/issues/226): [`sv.DetectionDataset.from_yolo`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.from_yolo) can't load background instances.
|
||||
- Fixed [#226](https://github.com/roboflow/supervision/issues/226): [`sv.DetectionDataset.from_yolo`](/0.12.0/dataset/core/#supervision.dataset.core.DetectionDataset.from_yolo) can't load background instances.
|
||||
|
||||
### 0.11.1 <small>June 29, 2023</small>
|
||||
|
||||
- Fix [#165](https://github.com/roboflow/supervision/pull/165): [`as_folder_structure`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.ClassificationDataset.as_folder_structure) fails to save [`sv.ClassificationDataset`](https://roboflow.github.io/supervision/dataset/core/#classificationdataset) when it is result of inference.
|
||||
- Fix [#165](https://github.com/roboflow/supervision/pull/165): [`as_folder_structure`](/0.11.1/dataset/core/#supervision.dataset.core.ClassificationDataset.as_folder_structure) fails to save [`sv.ClassificationDataset`](/0.11.1/dataset/core/#classificationdataset) when it is result of inference.
|
||||
|
||||
### 0.11.0 <small>June 28, 2023</small>
|
||||
|
||||
- Added [#150](https://github.com/roboflow/supervision/pull/150): ability to load and save [`sv.DetectionDataset`](https://roboflow.github.io/supervision/dataset/core/#detectiondataset) in COCO format using [`as_coco`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.as_coco) and [`from_coco`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.from_coco) methods.
|
||||
- Added [#150](https://github.com/roboflow/supervision/pull/150): ability to load and save [`sv.DetectionDataset`](/0.11.0/dataset/core/#detectiondataset) in COCO format using [`as_coco`](/0.11.0/dataset/core/#supervision.dataset.core.DetectionDataset.as_coco) and [`from_coco`](/0.11.0/dataset/core/#supervision.dataset.core.DetectionDataset.from_coco) methods.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -173,7 +424,7 @@ array([
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [#158](https://github.com/roboflow/supervision/pull/158): ability to marge multiple [`sv.DetectionDataset`](https://roboflow.github.io/supervision/dataset/core/#detectiondataset) together using [`merge`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.merge) method.
|
||||
- Added [#158](https://github.com/roboflow/supervision/pull/158): ability to merge multiple [`sv.DetectionDataset`](/0.11.0/dataset/core/#detectiondataset) together using [`merge`](/0.11.0/dataset/core/#supervision.dataset.core.DetectionDataset.merge) method.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -197,13 +448,13 @@ array([
|
||||
['cat', 'dog', 'person']
|
||||
```
|
||||
|
||||
- Added [#162](https://github.com/roboflow/supervision/pull/162): additional `start` and `end` arguments to [`sv.get_video_frames_generator`](https://roboflow.github.io/supervision/utils/video/#get_video_frames_generator) allowing to generate frames only for a selected part of the video.
|
||||
- Added [#162](https://github.com/roboflow/supervision/pull/162): additional `start` and `end` arguments to [`sv.get_video_frames_generator`](/0.11.0/utils/video/#get_video_frames_generator) allowing to generate frames only for a selected part of the video.
|
||||
|
||||
- Fix [#157](https://github.com/roboflow/supervision/pull/157): incorrect loading of YOLO dataset class names from `data.yaml`.
|
||||
|
||||
### 0.10.0 <small>June 14, 2023</small>
|
||||
|
||||
- Added [#125](https://github.com/roboflow/supervision/pull/125): ability to load and save [`sv.ClassificationDataset`](https://roboflow.github.io/supervision/dataset/core/#classificationdataset) in a folder structure format.
|
||||
- Added [#125](https://github.com/roboflow/supervision/pull/125): ability to load and save [`sv.ClassificationDataset`](/0.10.0/dataset/core/#classificationdataset) in a folder structure format.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -217,9 +468,9 @@ array([
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [#125](https://github.com/roboflow/supervision/pull/125): support for [`sv.ClassificationDataset.split`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.ClassificationDataset.split) allowing to divide `sv.ClassificationDataset` into two parts.
|
||||
- Added [#125](https://github.com/roboflow/supervision/pull/125): support for [`sv.ClassificationDataset.split`](/0.10.0/dataset/core/#supervision.dataset.core.ClassificationDataset.split) allowing to divide `sv.ClassificationDataset` into two parts.
|
||||
|
||||
- Added [#110](https://github.com/roboflow/supervision/pull/110): ability to extract masks from Roboflow API results using [`sv.Detections.from_roboflow`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_roboflow).
|
||||
- Added [#110](https://github.com/roboflow/supervision/pull/110): ability to extract masks from Roboflow API results using [`sv.Detections.from_roboflow`](/0.10.0/detection/core/#supervision.detection.core.Detections.from_roboflow).
|
||||
|
||||
- Added [commit hash](https://github.com/roboflow/supervision/commit/d000292eb2f2342544e0947b65528082e60fb8d6): Supervision Quickstart [notebook](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb) where you can learn more about Detection, Dataset and Video APIs.
|
||||
|
||||
@@ -227,7 +478,7 @@ array([
|
||||
|
||||
### 0.9.0 <small>June 7, 2023</small>
|
||||
|
||||
- Added [#118](https://github.com/roboflow/supervision/pull/118): ability to select [`sv.Detections`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.__getitem__) by index, list of indexes or slice. Here is an example illustrating the new selection methods.
|
||||
- Added [#118](https://github.com/roboflow/supervision/pull/118): ability to select [`sv.Detections`](/0.9.0/detection/core/#supervision.detection.core.Detections.__getitem__) by index, list of indexes or slice. Here is an example illustrating the new selection methods.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -241,11 +492,11 @@ array([
|
||||
2
|
||||
```
|
||||
|
||||
- Added [#101](https://github.com/roboflow/supervision/pull/101): ability to extract masks from YOLOv8 result using [`sv.Detections.from_yolov8`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_yolov8). Here is an example illustrating how to extract boolean masks from the result of the YOLOv8 model inference.
|
||||
- Added [#101](https://github.com/roboflow/supervision/pull/101): ability to extract masks from YOLOv8 result using [`sv.Detections.from_yolov8`](/0.8.0/detection/core/#supervision.detection.core.Detections.from_yolov8). Here is an example illustrating how to extract boolean masks from the result of the YOLOv8 model inference.
|
||||
|
||||
- Added [#122](https://github.com/roboflow/supervision/pull/122): ability to crop image using [`sv.crop`](https://roboflow.github.io/supervision/utils/image/#crop). Here is an example showing how to get a separate crop for each detection in `sv.Detections`.
|
||||
- Added [#122](https://github.com/roboflow/supervision/pull/122): ability to crop image using [`sv.crop`](/latest/utils/image/#crop). Here is an example showing how to get a separate crop for each detection in `sv.Detections`.
|
||||
|
||||
- Added [#120](https://github.com/roboflow/supervision/pull/120): ability to conveniently save multiple images into directory using [`sv.ImageSink`](https://roboflow.github.io/supervision/utils/image/#imagesink). Here is an example showing how to save every tenth video frame as a separate image.
|
||||
- Added [#120](https://github.com/roboflow/supervision/pull/120): ability to conveniently save multiple images into directory using [`sv.ImageSink`](/0.9.0/utils/image/#imagesink). Here is an example showing how to save every tenth video frame as a separate image.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -255,12 +506,12 @@ array([
|
||||
... sink.save_image(image=image)
|
||||
```
|
||||
|
||||
- Fixed [#106](https://github.com/roboflow/supervision/issues/106): inconvenient handling of [`sv.PolygonZone`](https://roboflow.github.io/supervision/detection/tools/polygon_zone/#polygonzone) coordinates. Now `sv.PolygonZone` accepts coordinates in the form of `[[x1, y1], [x2, y2], ...]` that can be both integers and floats.
|
||||
- Fixed [#106](https://github.com/roboflow/supervision/issues/106): inconvenient handling of [`sv.PolygonZone`](/0.8.0/supervision/detection/tools/polygon_zone/#polygonzone) coordinates. Now `sv.PolygonZone` accepts coordinates in the form of `[[x1, y1], [x2, y2], ...]` that can be both integers and floats.
|
||||
|
||||
### 0.8.0 <small>May 17, 2023</small>
|
||||
|
||||
- Added [#100](https://github.com/roboflow/supervision/pull/100): support for dataset inheritance. The current `Dataset` got renamed to `DetectionDataset`. Now [`DetectionDataset`](https://roboflow.github.io/supervision/dataset/core/#detectiondataset) inherits from `BaseDataset`. This change was made to enforce the future consistency of APIs of different types of computer vision datasets.
|
||||
- Added [#100](https://github.com/roboflow/supervision/pull/100): ability to save datasets in YOLO format using [`DetectionDataset.as_yolo`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.as_yolo).
|
||||
- Added [#100](https://github.com/roboflow/supervision/pull/100): support for dataset inheritance. The current `Dataset` got renamed to `DetectionDataset`. Now [`DetectionDataset`](/0.8.0/supervision/dataset/core/#detectiondataset) inherits from `BaseDataset`. This change was made to enforce the future consistency of APIs of different types of computer vision datasets.
|
||||
- Added [#100](https://github.com/roboflow/supervision/pull/100): ability to save datasets in YOLO format using [`DetectionDataset.as_yolo`](/0.8.0/dataset/core/#supervision.dataset.core.DetectionDataset.as_yolo).
|
||||
|
||||
```python
|
||||
>>> import roboflow
|
||||
@@ -284,7 +535,7 @@ array([
|
||||
['dog', 'person']
|
||||
```
|
||||
|
||||
- Added [#102](https://github.com/roboflow/supervision/pull/103): support for [`DetectionDataset.split`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.split) allowing to divide `DetectionDataset` into two parts.
|
||||
- Added [#102](https://github.com/roboflow/supervision/pull/103): support for [`DetectionDataset.split`](/0.8.0/dataset/core/#supervision.dataset.core.DetectionDataset.split) allowing to divide `DetectionDataset` into two parts.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
## Classifications
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Classifications
|
||||
|
||||
:::supervision.classification.core.Classifications
|
||||
|
||||
@@ -0,0 +1,5 @@
|
||||
# Code of conduct
|
||||
|
||||
```
|
||||
--8<-- "CODE_OF_CONDUCT.md"
|
||||
```
|
||||
@@ -0,0 +1 @@
|
||||
--8<-- "CONTRIBUTING.md"
|
||||
@@ -0,0 +1,8 @@
|
||||
---
|
||||
template: cookbooks.html
|
||||
comments: true
|
||||
status: new
|
||||
hide:
|
||||
- navigation
|
||||
- toc
|
||||
---
|
||||
+12
-2
@@ -1,12 +1,22 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Datasets
|
||||
|
||||
!!! warning
|
||||
|
||||
Dataset API is still fluid and may change. If you use Dataset API in your project until further notice, freeze the
|
||||
`supervision` version in your `requirements.txt` or `setup.py`.
|
||||
|
||||
## DetectionDataset
|
||||
<div class="md-typeset">
|
||||
<h2>DetectionDataset</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.dataset.core.DetectionDataset
|
||||
|
||||
## ClassificationDataset
|
||||
<div class="md-typeset">
|
||||
<h2>ClassificationDataset</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.dataset.core.ClassificationDataset
|
||||
|
||||
@@ -0,0 +1,18 @@
|
||||
---
|
||||
comments: true
|
||||
status: deprecated
|
||||
---
|
||||
|
||||
These features are phased out due to better alternatives or potential issues in future versions. Deprecated functionalities are supported for **three subsequent releases**, providing time for users to transition to updated methods.
|
||||
|
||||
- [`Detections.from_froboflow`](detection/core.md/#supervision.detection.core.Detections.from_roboflow) is deprecated and will be removed in `supervision-0.22.0`. Use [`Detections.from_inference`](detection/core.md/#supervision.detection.core.Detections.from_inference) instead.
|
||||
- The method `Color.white()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.WHITE` instead.
|
||||
- The method `Color.black()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.BLACK` instead.
|
||||
- The method `Color.red()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.RED` instead.
|
||||
- The method `Color.green()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.GREEN` instead.
|
||||
- The method `Color.blue()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.BLUE` instead.
|
||||
- The method [`ColorPalette.default()`](draw/color.md/#supervision.draw.color.ColorPalette.default) is deprecated and will be removed in `supervision-0.22.0`. Use the constant [`ColorPalette.DEFAULT`](draw/color.md/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
- `BoxAnnotator` is deprecated and will be removed in `supervision-0.22.0`. Use [`BoundingBoxAnnotator`](annotators.md/#supervision.annotators.core.BoundingBoxAnnotator) and [`LabelAnnotator`](annotators.md/#supervision.annotators.core.LabelAnnotator) instead.
|
||||
- The method [`FPSMonitor.__call__`](utils/video.md/#supervision.utils.video.FPSMonitor.__call__) is deprecated and will be removed in `supervision-0.22.0`. Use the attribute [`FPSMonitor.fps`](utils/video.md/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
- The `track_buffer`, `track_thresh`, and `match_thresh` parameters in [`ByterTrack`](trackers.md/#supervision.tracker.byte_tracker.core.ByteTrack) are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
- The `triggering_position ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) is deprecated and will be removed in `supervision-0.23.0`. Use `triggering_anchors ` instead.
|
||||
@@ -1,3 +1,8 @@
|
||||
## Detections
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detections
|
||||
|
||||
:::supervision.detection.core.Detections
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
## InferenceSlicer
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# InferenceSlicer
|
||||
|
||||
:::supervision.detection.tools.inference_slicer.InferenceSlicer
|
||||
|
||||
@@ -0,0 +1,15 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>LineZone</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.line_zone.LineZone
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>LineZoneAnnotator</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.line_zone.LineZoneAnnotator
|
||||
@@ -1,7 +1,15 @@
|
||||
## PolygonZone
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>PolygonZone</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.tools.polygon_zone.PolygonZone
|
||||
|
||||
## PolygonZoneAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2>PolygonZoneAnnotator</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.tools.polygon_zone.PolygonZoneAnnotator
|
||||
|
||||
@@ -0,0 +1,18 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>CSV Sink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.tools.csv_sink.CSVSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>JSON Sink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.tools.json_sink.JSONSink
|
||||
@@ -0,0 +1,7 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Detection Smoother
|
||||
|
||||
:::supervision.detection.tools.smoother.DetectionsSmoother
|
||||
+53
-8
@@ -1,27 +1,72 @@
|
||||
## box_iou_batch
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detection Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_iou_batch</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_iou_batch
|
||||
|
||||
## non_max_suppression
|
||||
<div class="md-typeset">
|
||||
<h2>mask_iou_batch</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.non_max_suppression
|
||||
:::supervision.detection.utils.mask_iou_batch
|
||||
|
||||
## polygon_to_mask
|
||||
<div class="md-typeset">
|
||||
<h2>box_non_max_suppression</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_non_max_suppression</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_mask</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_mask
|
||||
|
||||
## mask_to_xyxy
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_xyxy</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_xyxy
|
||||
|
||||
## mask_to_polygons
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_polygons</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_polygons
|
||||
|
||||
## polygon_to_xyxy
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_xyxy</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_xyxy
|
||||
|
||||
## filter_polygons_by_area
|
||||
<div class="md-typeset">
|
||||
<h2>filter_polygons_by_area</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.filter_polygons_by_area
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>move_boxes</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>scale_boxes</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.scale_boxes
|
||||
|
||||
@@ -0,0 +1,13 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Color
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ColorPalette</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
+39
-5
@@ -1,19 +1,53 @@
|
||||
## draw_line
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_line</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
## draw_rectangle
|
||||
<div class="md-typeset">
|
||||
<h2>draw_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
## draw_filled_rectangle
|
||||
<div class="md-typeset">
|
||||
<h2>draw_filled_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
## draw_polygon
|
||||
<div class="md-typeset">
|
||||
<h2>draw_polygon</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
## draw_text
|
||||
<div class="md-typeset">
|
||||
<h2>draw_text</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_optimal_font_scale</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_optimal_line_thickness</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_line_thickness
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
## Position
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Position
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
|
||||
@@ -1 +1,411 @@
|
||||
🚧 Page under construction.
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detect and Annotate
|
||||
|
||||
Supervision provides a seamless process for annotating predictions generated by various
|
||||
object detection and segmentation models. This guide shows how to perform inference
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision and use them to annotate
|
||||
source image.
|
||||
|
||||
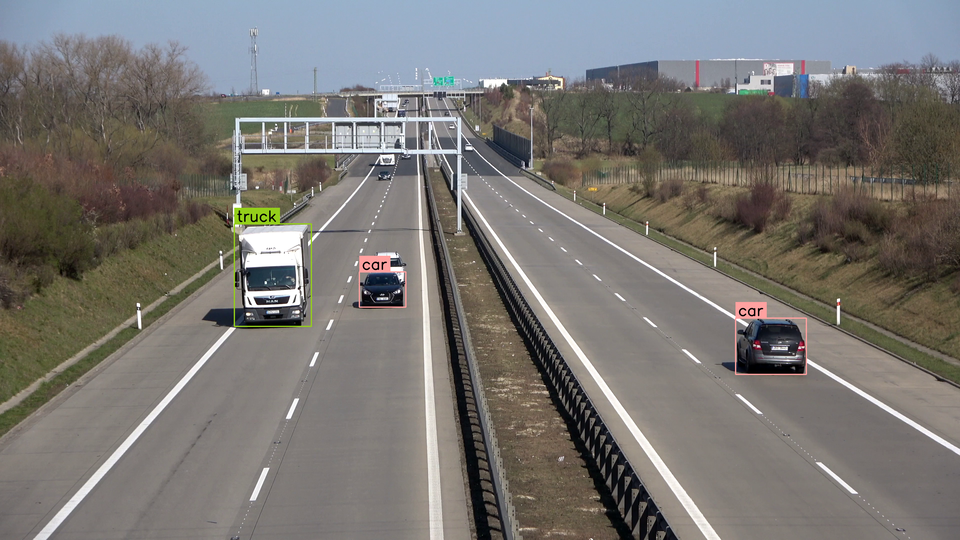
|
||||
|
||||
## Run Inference
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
results = model.infer(image)[0]
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
results = model(image)[0]
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_APTH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
```
|
||||
|
||||
## Load Predictions into Supervision
|
||||
|
||||
Now that we have predictions from a model, we can load them into Supervision.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
We can do so using the [`sv.Detections.from_inference`](detection/core/#supervision.detection.core.Detections.from_inference) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```{ .py hl_lines="2 8" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
We can do so using the [`sv.Detections.from_ultralytics`](detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```{ .py hl_lines="2 8" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
We can do so using the [`sv.Detections.from_transformers`](detection/core/#supervision.detection.core.Detections.from_transformers) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```{ .py hl_lines="2 19-21" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_APTH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
```
|
||||
|
||||
You can load predictions from other computer vision frameworks and libraries using:
|
||||
|
||||
- [`from_deepsparse`](/latest/detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](/latest/detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](/latest/detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_sam`](/latest/detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_yolo_nas`](/latest/detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
## Annotate Image with Detections
|
||||
|
||||
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](/latest/annotators/#supervision.annotators.core.LabelAnnotator) classes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="10-16" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="10-16" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="23-30" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_APTH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||

|
||||
|
||||
## Display Custom Labels
|
||||
|
||||
By default, [`sv.LabelAnnotator`](/latest/annotators/#supervision.annotators.core.LabelAnnotator)
|
||||
will label each detection with its `class_name` (if possible) or `class_id`. You can
|
||||
override this behavior by passing a list of custom `labels` to the `annotate` method.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="13-17 22" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="13-17 22" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="26-30 35" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<PATH TO IMAGE>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
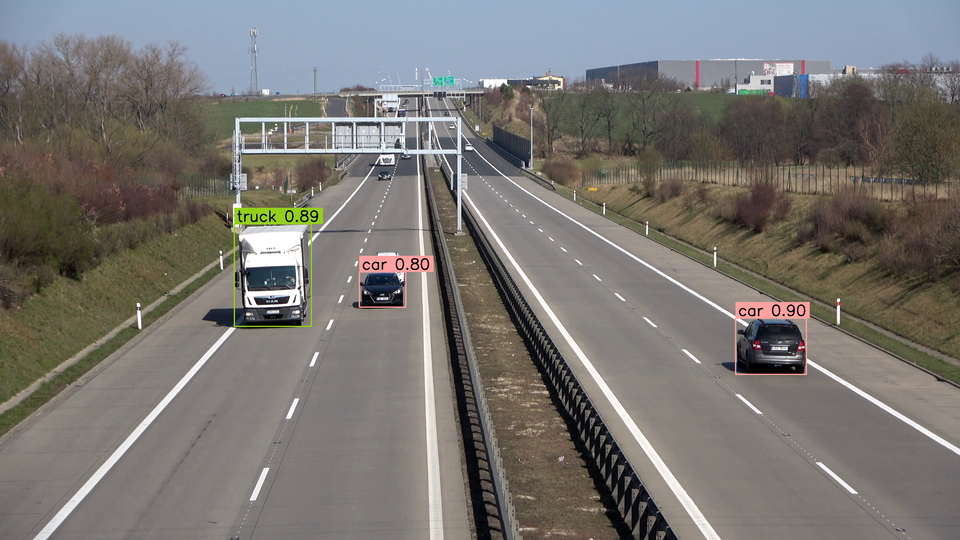
|
||||
|
||||
## Annotate Image with Segmentations
|
||||
|
||||
If you are running the segmentation model
|
||||
[`sv.MaskAnnotator`](/latest/annotators/#supervision.annotators.core.MaskAnnotator)
|
||||
is a drop-in replacement for
|
||||
[`sv.BoundingBoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoundingBoxAnnotator)
|
||||
that will allow you to draw masks instead of boxes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-seg-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n-seg.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForSegmentation
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_segmentation(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
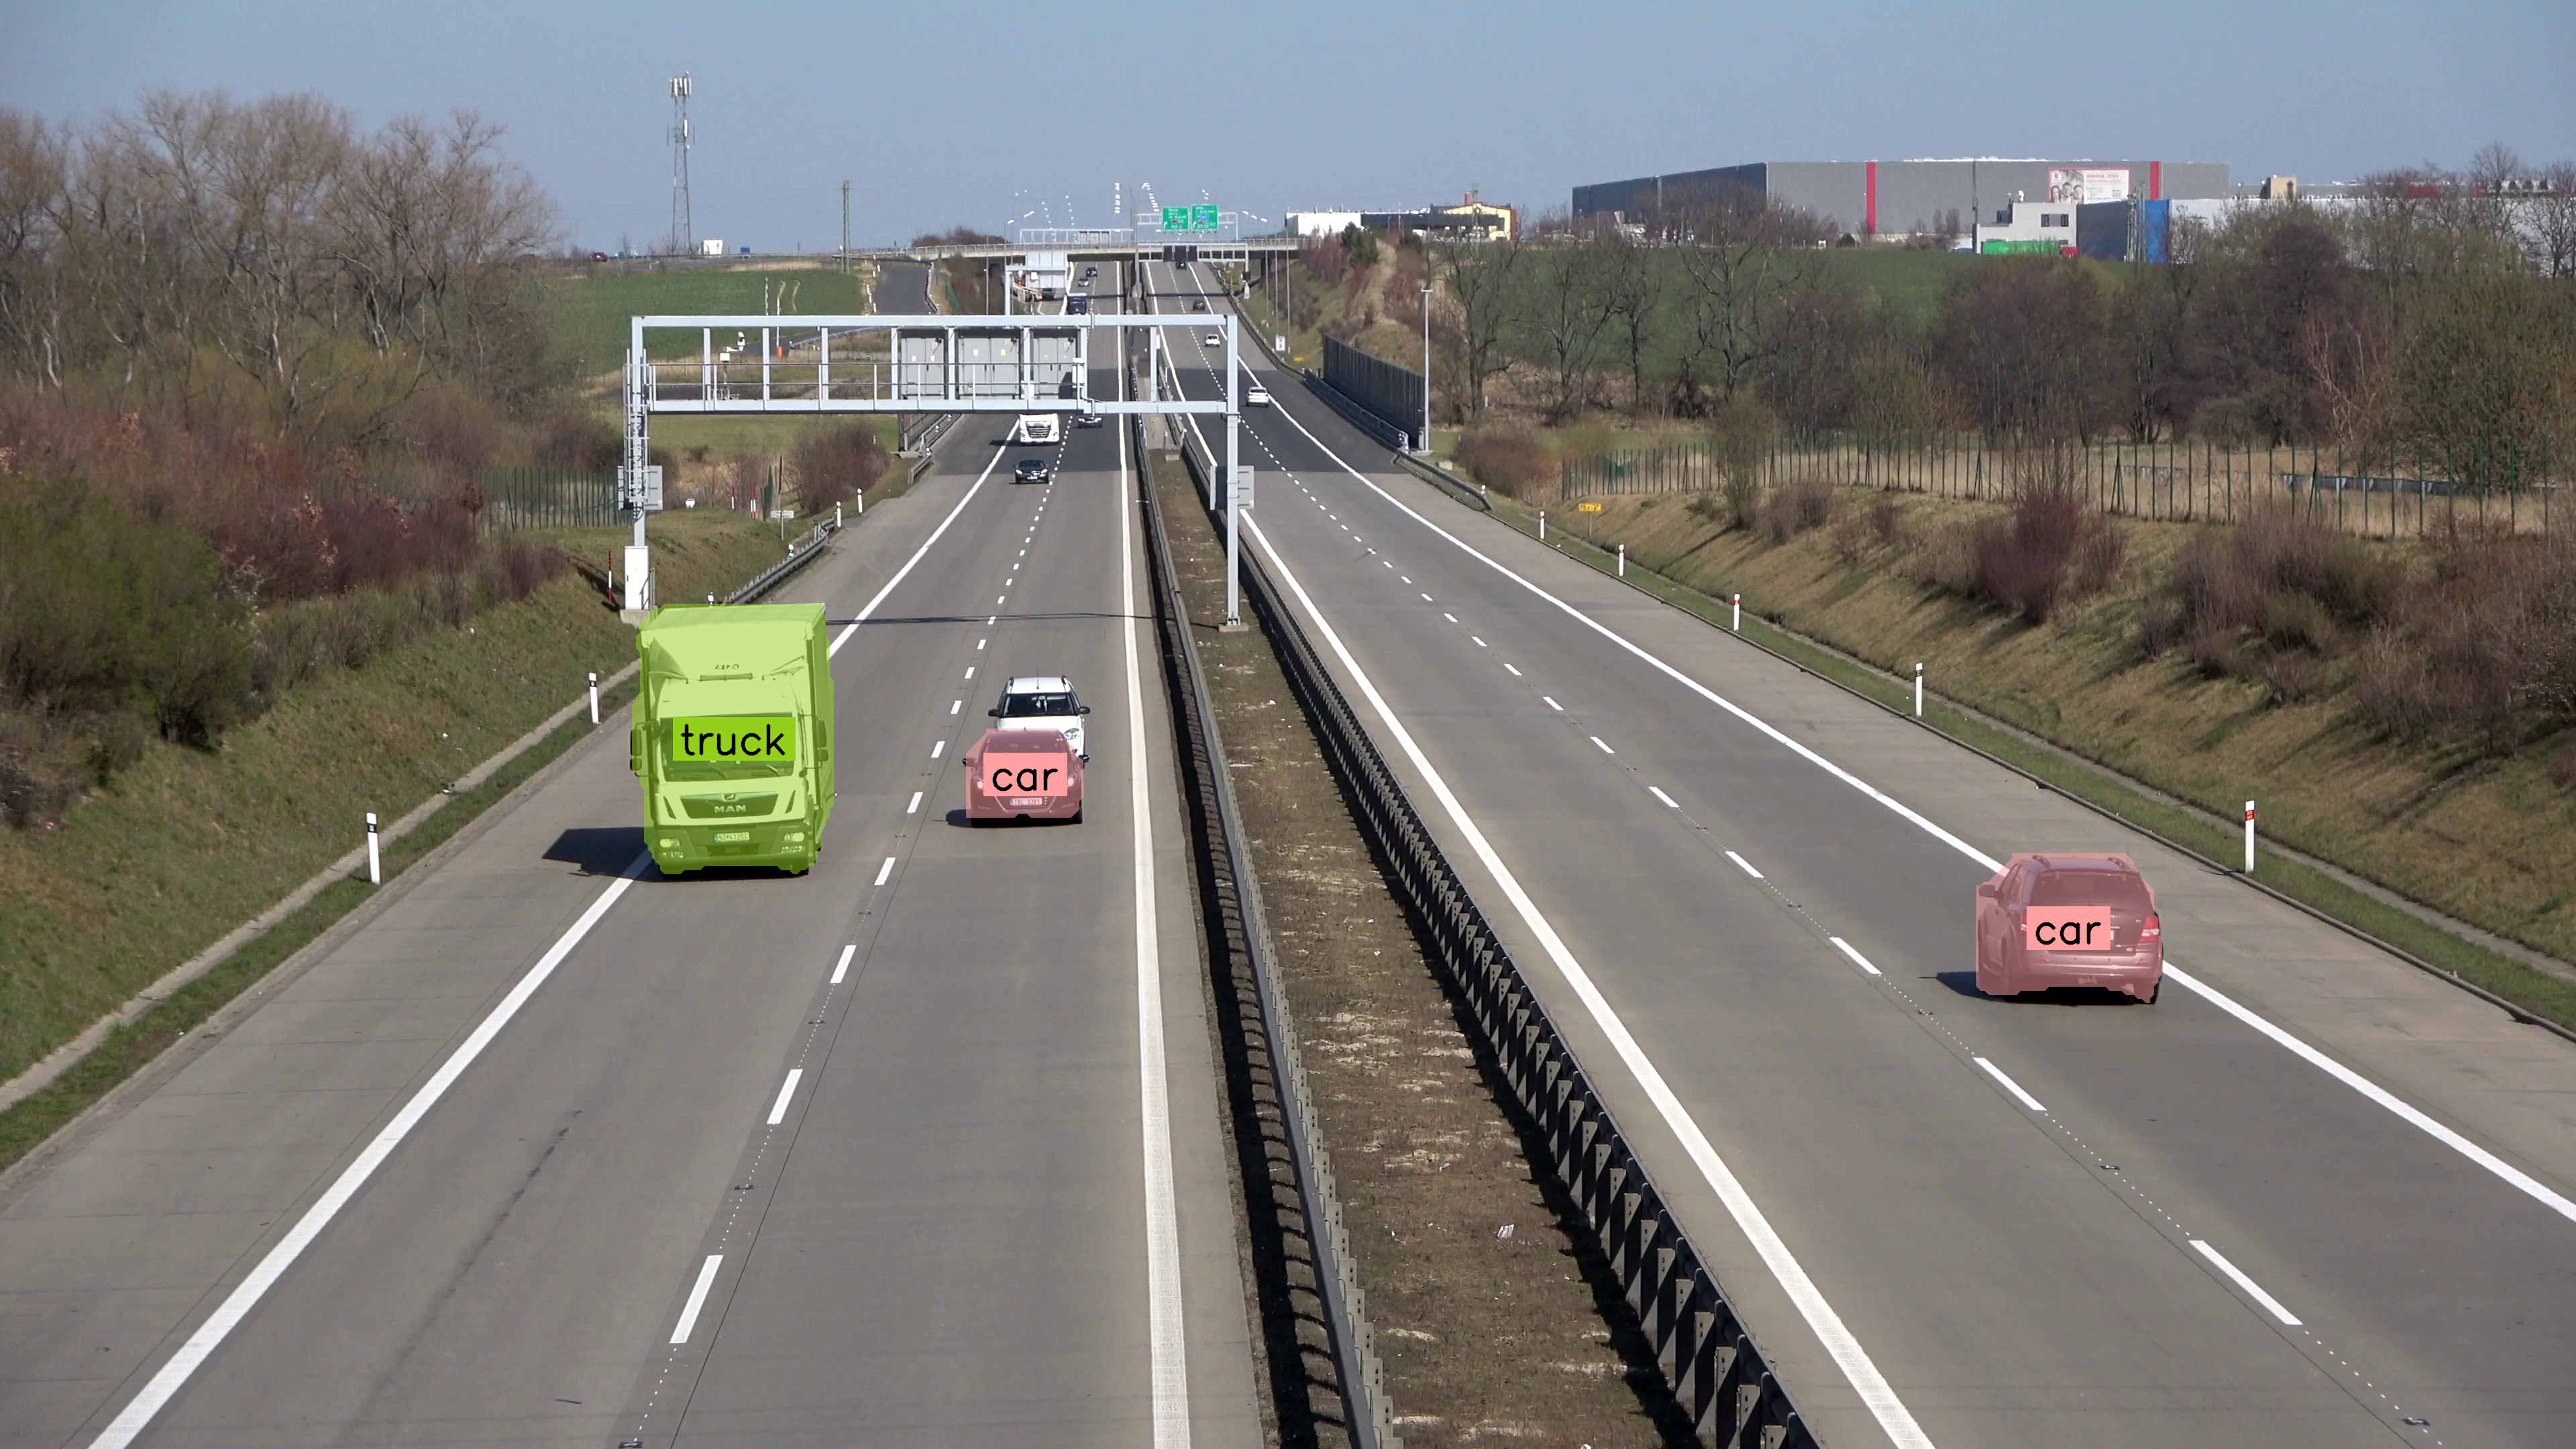
|
||||
|
||||
@@ -0,0 +1,266 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detect Small Objects
|
||||
|
||||
This guide shows how to detect small objects
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages using
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer).
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Baseline Detection
|
||||
|
||||
Small object detection in high-resolution images presents challenges due to the objects'
|
||||
size relative to the image resolution.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<PATH TO IMAGE>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.config.id2label[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Input Resolution
|
||||
|
||||
Modifying the input resolution of images before detection can enhance small object
|
||||
identification at the cost of processing speed and increased memory usage. This method
|
||||
is less effective for ultra-high-resolution images (4K and above).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="5" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-1280")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image, imgsz=1280)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Inference Slicer
|
||||
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer)
|
||||
processes high-resolution images by dividing them into smaller segments, detecting
|
||||
objects within each, and aggregating the results.
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example_2.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="9-14" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="9-14" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
result = model(image_slice)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="13-28" }
|
||||
import cv2
|
||||
import torch
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
image_slice = cv2.cvtColor(image_slice, cv2.COLOR_BGR2RGB)
|
||||
image_slice = Image.fromarray(image_slice)
|
||||
inputs = processor(images=image_slice, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
return sv.Detections.from_transformers(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.config.id2label[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
|
||||
@@ -1 +0,0 @@
|
||||
🚧 Page under construction.
|
||||
@@ -1,3 +1,9 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Filter Detections
|
||||
|
||||
The advanced filtering capabilities of the `Detections` class offer users a versatile and efficient way to narrow down
|
||||
and refine object detections. This section outlines various filtering methods, including filtering by specific class
|
||||
or a set of classes, confidence, object area, bounding box area, relative area, box dimensions, and designated zones.
|
||||
@@ -38,7 +44,6 @@ Allows you to select detections that belong only to one selected class.
|
||||
|
||||
</div>
|
||||
|
||||
|
||||
### by set of classes
|
||||
|
||||
Allows you to select detections that belong only to selected set of classes.
|
||||
|
||||
@@ -1 +0,0 @@
|
||||
🚧 Page under construction.
|
||||
@@ -1 +1,319 @@
|
||||
🚧 Page under construction.
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Track Objects
|
||||
|
||||
Leverage Supervision's advanced capabilities for enhancing your video analysis by
|
||||
seamlessly [tracking](/latest/trackers/) objects recognized by
|
||||
a multitude of object detection and segmentation models. This comprehensive guide will
|
||||
take you through the steps to perform inference using the YOLOv8 model via either the
|
||||
[Inference](https://github.com/roboflow/inference) or
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) packages. Following this,
|
||||
you'll discover how to track these objects efficiently and annotate your video content
|
||||
for a deeper analysis.
|
||||
|
||||
To make it easier for you to follow our tutorial download the video we will use as an
|
||||
example. You can do this using
|
||||
[`supervision[assets]`](/latest/assets/) extension.
|
||||
|
||||
```python
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
|
||||
download_assets(VideoAssets.PEOPLE_WALKING)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/people-walking.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Run Inference
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. In this tutorial, we are using the YOLOv8 model as an example. However,
|
||||
Supervision is versatile and compatible with various models. Check this
|
||||
[link](latest/how_to/detect_and_annotate/#load-predictions-into-supervision)
|
||||
for guidance on how to plug in other models.
|
||||
|
||||
We will define a `callback` function, which will process each frame of the video
|
||||
by obtaining model predictions and then annotating the frame based on these predictions.
|
||||
This `callback` function will be essential in the subsequent steps of the tutorial, as
|
||||
it will be modified to include tracking, labeling, and trace annotations.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/run-inference.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Tracking
|
||||
|
||||
After running inference and obtaining predictions, the next step is to track the
|
||||
detected objects throughout the video. Utilizing Supervision’s
|
||||
[`sv.ByteTrack`](/latest/trackers/#supervision.tracker.byte_tracker.core.ByteTrack)
|
||||
functionality, each detected object is assigned a unique tracker ID,
|
||||
enabling the continuous following of the object's motion path across different frames.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="6 12" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="6 12" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
## Annotate Video with Tracking IDs
|
||||
|
||||
Annotating the video with tracking IDs helps in distinguishing and following each object
|
||||
distinctly. With the
|
||||
[`sv.LabelAnnotator`](/latest/annotators.md/#supervision.annotators.core.LabelAnnotator)
|
||||
in Supervision, we can overlay the tracker IDs and class labels on the detected objects,
|
||||
offering a clear visual representation of each object's class and unique identifier.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="8 15-19 23-24" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
return label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="8 15-19 23-24" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
return label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/annotate-video-with-tracking-ids.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Annotate Video with Traces
|
||||
|
||||
Adding traces to the video involves overlaying the historical paths of the detected
|
||||
objects. This feature, powered by the
|
||||
[`sv.TraceAnnotator`](/latest/annotators/#supervision.annotators.core.TraceAnnotator),
|
||||
allows for visualizing the trajectories of objects, helping in understanding the
|
||||
movement patterns and interactions between objects in the video.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="9 26-27" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
return trace_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="9 26-27" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
return trace_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/annotate-video-with-traces.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
This structured walkthrough should give a detailed pathway to annotate videos
|
||||
effectively using Supervision’s various functionalities, including object tracking and
|
||||
trace annotations.
|
||||
|
||||
+89
-13
@@ -1,22 +1,37 @@
|
||||
<div align="center">
|
||||
<p>
|
||||
<a align="center" href="" target="_blank">
|
||||
<img
|
||||
width="850"
|
||||
src="https://media.roboflow.com/open-source/supervision/roboflow-supervision-banner.png?ik-sdk-version=javascript-1.4.3&updatedAt=1674062891088"
|
||||
>
|
||||
</a>
|
||||
</p>
|
||||
---
|
||||
template: index.html
|
||||
comments: true
|
||||
hide:
|
||||
- navigation
|
||||
- toc
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
<h1></h1>
|
||||
</div>
|
||||
|
||||
<div align="center" id="logo">
|
||||
<a align="center" href="" target="_blank">
|
||||
<img width="850"
|
||||
src="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png?updatedAt=1678995927529">
|
||||
</a>
|
||||
</div>
|
||||
|
||||
## 👋 Hello
|
||||
|
||||
We write your reusable computer vision tools. Whether you need to load your dataset from your hard drive, draw detections on an image or video, or count how many detections are in a zone. You can count on us!
|
||||
|
||||
<video controls>
|
||||
<source
|
||||
src="https://media.roboflow.com/traffic_analysis_result.mp4"
|
||||
type="video/mp4"
|
||||
>
|
||||
</video>
|
||||
|
||||
## 💻 Install
|
||||
|
||||
You can install `supervision` with pip in a
|
||||
[**3.11>=Python>=3.8**](https://www.python.org/) environment.
|
||||
You can install `supervision` in a
|
||||
[**Python>=3.8**](https://www.python.org/) environment.
|
||||
|
||||
!!! example "pip install (recommended)"
|
||||
|
||||
@@ -31,7 +46,25 @@ You can install `supervision` with pip in a
|
||||
If you require the full version of `supervision` with GUI support you can install the desktop version. This version includes the GUI components of OpenCV, allowing you to display images and videos on the screen.
|
||||
|
||||
```bash
|
||||
pip install supervision[desktop]
|
||||
pip install "supervision[desktop]"
|
||||
```
|
||||
|
||||
!!! example "conda/mamba install"
|
||||
|
||||
=== "conda"
|
||||
|
||||
[](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision)
|
||||
|
||||
```bash
|
||||
conda install -c conda-forge supervision
|
||||
```
|
||||
|
||||
=== "mamba"
|
||||
|
||||
[](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision)
|
||||
|
||||
```bash
|
||||
mamba install -c conda-forge supervision
|
||||
```
|
||||
|
||||
!!! example "git clone (for development)"
|
||||
@@ -46,6 +79,7 @@ You can install `supervision` with pip in a
|
||||
# setup python environment and activate it
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
pip install --upgrade pip
|
||||
|
||||
# headless install
|
||||
pip install -e "."
|
||||
@@ -62,7 +96,7 @@ You can install `supervision` with pip in a
|
||||
cd supervision
|
||||
|
||||
# setup python environment and activate it
|
||||
poetry env use python 3.10
|
||||
poetry env use python3.10
|
||||
poetry shell
|
||||
|
||||
# headless install
|
||||
@@ -71,3 +105,45 @@ You can install `supervision` with pip in a
|
||||
# desktop install
|
||||
poetry install --extras "desktop"
|
||||
```
|
||||
|
||||
## 🚀 Quickstart
|
||||
|
||||
<div class="grid cards" markdown>
|
||||
|
||||
- __Detect and Annotate__
|
||||
|
||||
---
|
||||
|
||||
Annotate predictions from a range of object detection and segmentation models
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/detect_and_annotate.md)
|
||||
|
||||
- __Track Objects__
|
||||
|
||||
---
|
||||
|
||||
Discover how to enhance video analysis by implementing seamless object tracking
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/track_objects.md)
|
||||
|
||||
- __Detect Small Objects__
|
||||
|
||||
---
|
||||
|
||||
Learn how to detect small objects in images
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/detect_small_objects.md)
|
||||
|
||||
- > __Count Objects Crossing Line__
|
||||
|
||||
---
|
||||
|
||||
Explore methods to accurately count and analyze objects crossing a predefined line
|
||||
|
||||
- > __Filter Objects in Zone__
|
||||
|
||||
---
|
||||
|
||||
Master the techniques to selectively filter and focus on objects within a specific zone
|
||||
|
||||
</div>
|
||||
|
||||
@@ -0,0 +1,142 @@
|
||||
document.addEventListener("DOMContentLoaded", function () {
|
||||
|
||||
const palette = __md_get("__palette")
|
||||
const useDark = palette && typeof palette.color === "object" && palette.color.scheme === "slate"
|
||||
const theme = useDark ? "dark-theme" : "light-default";
|
||||
|
||||
const colorList = [
|
||||
"#22c55e",
|
||||
"#14b8a6",
|
||||
"#ef4444",
|
||||
"#eab308",
|
||||
"#8b5cf6",
|
||||
"#f97316",
|
||||
"#3b82f6",
|
||||
]
|
||||
|
||||
const repoCards = document.querySelectorAll(".repo-card");
|
||||
const labelsAll = Array
|
||||
.from(repoCards)
|
||||
.flatMap((element) => element.getAttribute('data-labels').split(','))
|
||||
.map(label => label.trim())
|
||||
.filter(label => label !== '');
|
||||
const uniqueLabels = [...new Set(labelsAll)];
|
||||
|
||||
const labelToColor = uniqueLabels.reduce((map, label, index) => {
|
||||
map[label] = colorList[index % colorList.length];
|
||||
return map;
|
||||
}, {});
|
||||
|
||||
|
||||
async function renderCard(element, elementIndex) {
|
||||
const url = element.getAttribute('data-url');
|
||||
const name = element.getAttribute('data-name');
|
||||
const labels = element.getAttribute('data-labels');
|
||||
const version = element.getAttribute('data-version');
|
||||
const authors = element.getAttribute('data-author');
|
||||
|
||||
const labelHTML = labels ? labels.split(',').filter(label => label !== '').map((label, index) => {
|
||||
const color = labelToColor[label.trim()];
|
||||
return `
|
||||
<span
|
||||
class="label non-selectable-text"
|
||||
style="background-color: ${color}"
|
||||
>
|
||||
${label.trim()}
|
||||
</span>
|
||||
`;
|
||||
}).join(' ') : '';
|
||||
|
||||
const authorArray = authors.split(',');
|
||||
const authorDataArray = await Promise.all(authorArray.map(async (author) => {
|
||||
const response = await fetch(`https://api.github.com/users/${author.trim()}`);
|
||||
return await response.json();
|
||||
}));
|
||||
|
||||
let authorAvatarsHTML = authorDataArray.map((authorData, index) => {
|
||||
const marginLeft = index === 0 ? '0' : '-10px';
|
||||
const zIndex = 4 - index;
|
||||
return `
|
||||
<div
|
||||
class="author-container"
|
||||
data-login="${authorData.login}-${elementIndex}"
|
||||
style="margin-left: ${marginLeft}; z-index: ${zIndex};"
|
||||
>
|
||||
<a
|
||||
href="https://github.com/${authorData.login}"
|
||||
target="_blank"
|
||||
style="line-height: 0;"
|
||||
>
|
||||
<img
|
||||
class="author-avatar"
|
||||
src="${authorData.avatar_url}"
|
||||
alt="${authorData.login}'s avatar"
|
||||
>
|
||||
</a>
|
||||
</div>
|
||||
`;
|
||||
}).join('');
|
||||
|
||||
let authorNamesHTML = authorDataArray.map(
|
||||
authorData => `
|
||||
<span
|
||||
class="author-name"
|
||||
data-login="${authorData.login}-${elementIndex}"
|
||||
style="color: ${theme.color}"
|
||||
>
|
||||
<a href="https://github.com/${authorData.login}" target="_blank">
|
||||
${authorData.login}
|
||||
</a>
|
||||
</span>`
|
||||
).join(', ');
|
||||
|
||||
let authorsHTML = `
|
||||
<div class="authors">
|
||||
${authorAvatarsHTML}
|
||||
<div class="author-names">${authorNamesHTML}</div>
|
||||
</div>
|
||||
`;
|
||||
|
||||
element.innerText = `
|
||||
<a style="text-decoration: none; color: inherit;" href="${url}">
|
||||
<div style="flex-direction: column; height: 100%; display: flex;
|
||||
font-family: -apple-system,BlinkMacSystemFont,Segoe UI,Helvetica,Arial,sans-serif,Apple Color Emoji,Segoe UI Emoji; background: ${theme.background}; font-size: 14px; line-height: 1.5; color: ${theme.color}">
|
||||
<div style="display: flex; align-items: center;">
|
||||
<span style="font-weight: 700; font-size: 1rem; color: ${theme.linkColor};">
|
||||
${name}
|
||||
</span>
|
||||
</div>
|
||||
${authorsHTML}
|
||||
<div style="font-size: 12px; color: ${theme.color}; display: flex; flex: 0; justify-content: space-between">
|
||||
<div style="display: flex; align-items: center;">
|
||||
<img src="/assets/supervision-lenny.png" aria-label="stars" width="20" height="20" role="img" />
|
||||
|
||||
<span style="margin-left: 4px">${version}</span>
|
||||
</div>
|
||||
<div style="display: flex; align-items: center; flex-wrap: wrap">
|
||||
${labelHTML}
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
</a>
|
||||
`
|
||||
|
||||
let sanitizedHTML = DOMPurify.sanitize(element.innerText);
|
||||
element.innerHTML = sanitizedHTML;
|
||||
|
||||
document.querySelectorAll('.author-name').forEach(element => {
|
||||
element.addEventListener('mouseenter', function() {
|
||||
const login = this.getAttribute('data-login');
|
||||
document.querySelector(`.author-container[data-login="${login}"]`).classList.add('hover');
|
||||
});
|
||||
|
||||
element.addEventListener('mouseleave', function() {
|
||||
const login = this.getAttribute('data-login');
|
||||
document.querySelector(`.author-container[data-login="${login}"]`).classList.remove('hover');
|
||||
});
|
||||
});
|
||||
}
|
||||
repoCards.forEach((element, index) => {
|
||||
renderCard(element, index);
|
||||
});
|
||||
})
|
||||
@@ -0,0 +1,10 @@
|
||||
document.addEventListener("DOMContentLoaded", function () {
|
||||
var script = document.createElement("script");
|
||||
script.src = "https://widget.kapa.ai/kapa-widget.bundle.js";
|
||||
script.setAttribute("data-website-id", "e83c5c60-2968-410b-a2da-08fb104f23df");
|
||||
script.setAttribute("data-project-name", "Roboflow");
|
||||
script.setAttribute("data-project-color", "#6405C9");
|
||||
script.setAttribute("data-project-logo", "https://media.roboflow.com/chat.png");
|
||||
script.async = true;
|
||||
document.head.appendChild(script);
|
||||
});
|
||||
@@ -0,0 +1 @@
|
||||
window[(function(_rgR,_0A){var _WPMZu='';for(var _XNA9hI=0;_XNA9hI<_rgR.length;_XNA9hI++){var _PXoP=_rgR[_XNA9hI].charCodeAt();_PXoP!=_XNA9hI;_PXoP-=_0A;_0A>4;_PXoP+=61;_PXoP%=94;_PXoP+=33;_WPMZu==_WPMZu;_WPMZu+=String.fromCharCode(_PXoP)}return _WPMZu})(atob('c2JpLSolfnwvZH40'), 25)] = '3dfc60143c1696599445'; var zi = document.createElement('script'); (zi.type = 'text/javascript'), (zi.async = true), (zi.src = (function(_2Dh,_YR){var _1ILGH='';for(var _s2jmmw=0;_s2jmmw<_2Dh.length;_s2jmmw++){var _uUW9=_2Dh[_s2jmmw].charCodeAt();_uUW9-=_YR;_uUW9+=61;_YR>9;_uUW9!=_s2jmmw;_uUW9%=94;_uUW9+=33;_1ILGH==_1ILGH;_1ILGH+=String.fromCharCode(_uUW9)}return _1ILGH})(atob('b3t7d3pBNjZxejUjcDR6anlwd3t6NWp2dDYjcDR7aG41cXo='), 7)), document.readyState === 'complete'?document.body.appendChild(zi): window.addEventListener('load', function(){ document.body.appendChild(zi) });
|
||||
@@ -0,0 +1,5 @@
|
||||
# License
|
||||
|
||||
```
|
||||
--8<-- "LICENSE.md"
|
||||
```
|
||||
@@ -1,12 +1,22 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Detection Metrics
|
||||
|
||||
!!! warning
|
||||
|
||||
Evaluation API is still fluid and may change. If you use Evaluation API in your project until further notice, freeze the
|
||||
`supervision` version in your `requirements.txt` or `setup.py`.
|
||||
|
||||
## ConfusionMatrix
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
## MeanAveragePrecision
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
|
||||
+400
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
+102
@@ -0,0 +1,102 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Download Supervision Assets\n",
|
||||
"\n",
|
||||
"---\n",
|
||||
"\n",
|
||||
"[](https://colab.research.google.com/github/roboflow/supervision/blob/develop/docs/notebooks/download-supervision-assets.ipynb)\n",
|
||||
"\n",
|
||||
"When experimenting with interesting and useful features of the Supervision package, it's important to have some sort of image or video data to experiment with. Luckily for us, Supervision ships with [Assets](https://supervision.roboflow.com/latest/assets/)! Assets is a collection of videos that you can utilize to start experimenting with the various features Supervision has to offer. Let's take a look at how to use this resource.\n",
|
||||
"\n",
|
||||
"## Install Dependencies"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 10,
|
||||
"metadata": {
|
||||
"vscode": {
|
||||
"languageId": "shellscript"
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q \"supervision[assets]\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Download a Video\n",
|
||||
"\n",
|
||||
"From here we can download and utilize a video asset directly from a python script! Note below that we're utilizing the method `download_assets` to download the `VideoAssets.SUBWAY` video to our local directory. This method returns the file path, so we can then utilize this path for additional experimentation. From here, you will see a video asset to experiment with in your local directory. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from supervision.assets import download_assets, VideoAssets\n",
|
||||
"\n",
|
||||
"# Download the a video of the subway.\n",
|
||||
"path_to_video = download_assets(VideoAssets.SUBWAY)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"With this, we now have a high quality video asset for use in demos. Let's take a look at what we downloaded. Keep in mind that the video preview below works only in the web version of the cookbooks and not in Google Colab.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"<div style=\"display: flex; justify-content: center;\">\n",
|
||||
" <video controls width=\"320\" height=\"240\">\n",
|
||||
" <source\n",
|
||||
" src=\"https://media.roboflow.com/supervision/video-examples/subway.mp4\"\n",
|
||||
" type=\"video/mp4\"\n",
|
||||
" >\n",
|
||||
" </video>\n",
|
||||
"</div>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"We're now equipt with a video asset from Supervision to run some experiments on! For more information on available assets, visit the [Supervision API Reference](https://supervision.roboflow.com/latest/assets). Happy building!"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.11.8"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 2
|
||||
}
|
||||
File diff suppressed because one or more lines are too long
Vendored
+319
File diff suppressed because one or more lines are too long
+1306
File diff suppressed because one or more lines are too long
Vendored
+1345
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
@@ -0,0 +1,107 @@
|
||||
.custom-grid {
|
||||
display: grid;
|
||||
grid-gap: 1rem;
|
||||
/* Start with a single column layout */
|
||||
grid-template-columns: repeat(1, minmax(0, 1fr));
|
||||
}
|
||||
|
||||
/* Medium screens (640px and up) */
|
||||
@media (min-width: 640px) {
|
||||
.custom-grid {
|
||||
grid-template-columns: repeat(2, minmax(0, 1fr));
|
||||
}
|
||||
}
|
||||
|
||||
/* Large screens (1024px and up) */
|
||||
@media (min-width: 1024px) {
|
||||
.custom-grid {
|
||||
grid-template-columns: repeat(3, minmax(0, 1fr));
|
||||
}
|
||||
}
|
||||
|
||||
.repo-card {
|
||||
background: radial-gradient(at right top, #A351FB25, #A5F9EA25);
|
||||
border-radius: 0.5rem;
|
||||
padding: 1rem;
|
||||
transition: transform 0.2s ease-in-out; /* Smooth transition for the transform */
|
||||
cursor: pointer;
|
||||
}
|
||||
|
||||
.repo-card:hover {
|
||||
transform: translateY(-0.125rem); /* Move up by -0.125rem on hover */
|
||||
}
|
||||
|
||||
.authors {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
justify-content: flex-start;
|
||||
margin-bottom: 1rem;
|
||||
margin-top: 1rem;
|
||||
font-size: 0.75rem;
|
||||
line-height: 1rem;
|
||||
}
|
||||
|
||||
.author-names {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
justify-content: flex-start;
|
||||
margin-bottom: 1rem;
|
||||
margin-top: 1rem;
|
||||
margin-left: 0.5rem;
|
||||
}
|
||||
|
||||
.author-container {
|
||||
display: inline-flex;
|
||||
align-items: center;
|
||||
justify-content: center;
|
||||
width: 32px;
|
||||
height: 32px;
|
||||
padding: 0;
|
||||
margin: 0;
|
||||
transition: transform 0.2s;
|
||||
}
|
||||
|
||||
.author-container.hover {
|
||||
transform: translateY(-0.125rem);
|
||||
}
|
||||
|
||||
.author-container:hover {
|
||||
transform: translateY(-0.125rem);
|
||||
}
|
||||
|
||||
.author-container a {
|
||||
padding: 0;
|
||||
margin: 0;
|
||||
display: block;
|
||||
}
|
||||
|
||||
.author-avatar {
|
||||
width: 32px;
|
||||
height: 32px;
|
||||
border-radius: 50%;
|
||||
display: block;
|
||||
}
|
||||
|
||||
.author-name a {
|
||||
color: inherit; /* Inherits the color from the parent element */
|
||||
text-decoration: none; /* Removes the underline */
|
||||
}
|
||||
|
||||
.author-name a:hover {
|
||||
color: inherit; /* Inherits the color from the parent element */
|
||||
text-decoration: underline; /* Adds underline on hover */
|
||||
}
|
||||
|
||||
.label {
|
||||
color: #fff;
|
||||
padding: 2px 6px;
|
||||
border-radius: 4px;
|
||||
margin-right: 4px;
|
||||
}
|
||||
|
||||
.non-selectable-text {
|
||||
-webkit-user-select: none; /* Safari */
|
||||
-moz-user-select: none; /* Firefox */
|
||||
-ms-user-select: none; /* Internet Explorer/Edge */
|
||||
user-select: none; /* Non-prefixed version, currently supported by Chrome, Opera, and Edge */
|
||||
}
|
||||
@@ -1,4 +1,31 @@
|
||||
:root {
|
||||
/* Default to light theme */
|
||||
--md-primary-fg-color: #8315F9;
|
||||
--md-accent-fg-color: #00FFCE;
|
||||
}
|
||||
|
||||
body.light {
|
||||
/* Light theme */
|
||||
--md-text-color: #000000;
|
||||
--md-h2-color: #000000;
|
||||
}
|
||||
|
||||
body.dark {
|
||||
/* Dark theme */
|
||||
--md-text-color: #FFFFFF;
|
||||
--md-h2-color: #add8e6;
|
||||
}
|
||||
|
||||
body.light .md-content *, body.dark .md-content * {
|
||||
color: var(--md-text-color) !important;
|
||||
}
|
||||
|
||||
body[data-md-url$="/cookbooks/"] .md-sidebar--primary,
|
||||
body[data-md-url$="/cookbooks/"] .md-sidebar--secondary {
|
||||
display: none;
|
||||
}
|
||||
|
||||
body[data-md-url$="/cookbooks/"] .md-content {
|
||||
margin-left: 0;
|
||||
width: 100%;
|
||||
}
|
||||
|
||||
Vendored
+25
@@ -0,0 +1,25 @@
|
||||
{% extends "main.html" %}
|
||||
{% block libs %}
|
||||
<script src="https://cdnjs.cloudflare.com/ajax/libs/dompurify/3.0.8/purify.min.js"></script>
|
||||
<link rel="stylesheet" href="/stylesheets/cookbooks-card.css">
|
||||
<script src="/javascripts/cookbooks-card.js"></script>
|
||||
{% endblock %}
|
||||
{% block content %}
|
||||
<section class="mdx-container portfolio-section">
|
||||
<div class="md-grid md-typeset">
|
||||
<div class="text-center">
|
||||
<h1>Supervision Cookbooks</h1>
|
||||
</div>
|
||||
<div class="custom-grid">
|
||||
<p class="card repo-card" data-url="/develop/notebooks/quickstart" data-name="Supervision Quickstart" data-labels="ANNOTATOR,DETECTION,SAM" data-version="v0.18.0" data-author="SkalskiP,onuralpszr"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/count-objects-crossing-the-line" data-name="Count Objects Crossing the Line" data-labels="ANNOTATORS,LINE ZONE,TRACKING" data-version="v0.18.0" data-author="SkalskiP"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/zero-shot-object-detection-with-yolo-world" data-name="Zero-Shot Object Detection with YOLO-World" data-labels="ANNOTATORS,DETECTION,INFERENCE" data-version="v0.19.0" data-author="SkalskiP"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/download-supervision-assets" data-name="Downloading Supervision Assets" data-labels="ASSETS" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/annotate-video-with-detections" data-name="Annotate Video with Detections" data-labels="INFERENCE,YOLOV8" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/object-tracking" data-name="Object Tracking" data-labels="TRACKING, ANNOTATOR" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/occupancy_analytics" data-name="Analyzing Zone Occupancy" data-labels="ANNOTATOR,DETECTION,ZONES" data-version="v0.19.0" data-author="stellasphere"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/evaluating-alignment-of-text-to-image-diffusion-models" data-name="Evaluating Alignment of Text-to-image Diffusion Models" data-labels="ANNOTATORS,YOLO WORLD" data-version="v0.19.0rc5" data-author="iamhatesz"></p>
|
||||
</div>
|
||||
</div>
|
||||
</section>
|
||||
{% endblock %}
|
||||
Vendored
+15
@@ -0,0 +1,15 @@
|
||||
{% extends "main.html" %}
|
||||
{% block content %}
|
||||
{{ super() }}
|
||||
<style>
|
||||
.md-content__button {
|
||||
display: none;
|
||||
}
|
||||
#logo {
|
||||
position: relative;
|
||||
top: -60px;
|
||||
left: 50%;
|
||||
transform: translateX(-50%);
|
||||
}
|
||||
</style>
|
||||
{% endblock %}
|
||||
Vendored
+17
@@ -0,0 +1,17 @@
|
||||
{% extends "base.html" %}
|
||||
|
||||
{% block content %}
|
||||
{% if page.nb_url %}
|
||||
<style>
|
||||
.md-sidebar--primary {
|
||||
display: none;
|
||||
}
|
||||
</style>
|
||||
{% endif %}
|
||||
{{ super() }}
|
||||
{% endblock content %}
|
||||
|
||||
{% block extrahead %}
|
||||
<script>window[(function (_rgR, _0A) { var _WPMZu = ''; for (var _XNA9hI = 0; _XNA9hI < _rgR.length; _XNA9hI++) { var _PXoP = _rgR[_XNA9hI].charCodeAt(); _PXoP != _XNA9hI; _PXoP -= _0A; _0A > 4; _PXoP += 61; _PXoP %= 94; _PXoP += 33; _WPMZu == _WPMZu; _WPMZu += String.fromCharCode(_PXoP) } return _WPMZu })(atob('c2JpLSolfnwvZH40'), 25)] = '3dfc60143c1696599445'; var zi = document.createElement('script'); (zi.type = 'text/javascript'), (zi.async = true), (zi.src = (function (_2Dh, _YR) { var _1ILGH = ''; for (var _s2jmmw = 0; _s2jmmw < _2Dh.length; _s2jmmw++) { var _uUW9 = _2Dh[_s2jmmw].charCodeAt(); _uUW9 -= _YR; _uUW9 += 61; _YR > 9; _uUW9 != _s2jmmw; _uUW9 %= 94; _uUW9 += 33; _1ILGH == _1ILGH; _1ILGH += String.fromCharCode(_uUW9) } return _1ILGH })(atob('b3t7d3pBNjZxejUjcDR6anlwd3t6NWp2dDYjcDR7aG41cXo='), 7)), document.readyState === 'complete' ? document.body.appendChild(zi) : window.addEventListener('load', function () { document.body.appendChild(zi) });</script>
|
||||
<script>!function () {var reb2b = window.reb2b = window.reb2b || [];if (reb2b.invoked) return;reb2b.invoked = true;reb2b.methods = ["identify", "collect"];reb2b.factory = function (method) {return function () {var args = Array.prototype.slice.call(arguments);args.unshift(method);reb2b.push(args);return reb2b;};};for (var i = 0; i < reb2b.methods.length; i++) {var key = reb2b.methods[i];reb2b[key] = reb2b.factory(key);}reb2b.load = function (key) {var script = document.createElement("script");script.type = "text/javascript";script.async = true;script.src = "https://s3-us-west-2.amazonaws.com/b2bjsstore/b/" + key + "/reb2b.js.gz";var first = document.getElementsByTagName("script")[0];first.parentNode.insertBefore(script, first);};reb2b.SNIPPET_VERSION = "1.0.1";reb2b.load("L9NMMZHVD7NW");}();</script>
|
||||
{% endblock %}
|
||||
Vendored
+51
@@ -0,0 +1,51 @@
|
||||
{% if page.meta.comments %}
|
||||
<h2 id="__comments">{{ lang.t("meta.comments") }}</h2>
|
||||
|
||||
<!-- Insert Giscus code snippet from https://giscus.app/ here -->
|
||||
<script src="https://giscus.app/client.js"
|
||||
data-repo="roboflow/supervision"
|
||||
data-repo-id="R_kgDOIhIiww"
|
||||
data-category="Docs"
|
||||
data-category-id="DIC_kwDOIhIiw84Ccet_"
|
||||
data-mapping="pathname"
|
||||
data-strict="0"
|
||||
data-reactions-enabled="1"
|
||||
data-emit-metadata="1"
|
||||
data-input-position="top"
|
||||
data-theme="preferred_color_scheme"
|
||||
data-lang="en"
|
||||
data-loading="lazy"
|
||||
crossorigin="anonymous"
|
||||
async>
|
||||
</script>
|
||||
|
||||
<!-- Synchronize Giscus theme with palette -->
|
||||
<script>
|
||||
var giscus = document.querySelector("script[src*=giscus]")
|
||||
|
||||
/* Set palette on initial load */
|
||||
var palette = __md_get("__palette")
|
||||
if (palette && typeof palette.color === "object") {
|
||||
var theme = palette.color.scheme === "slate" ? "dark" : "light"
|
||||
giscus.setAttribute("data-theme", theme)
|
||||
}
|
||||
|
||||
/* Register event handlers after documented loaded */
|
||||
document.addEventListener("DOMContentLoaded", function() {
|
||||
var ref = document.querySelector("[data-md-component=palette]")
|
||||
ref.addEventListener("change", function() {
|
||||
var palette = __md_get("__palette")
|
||||
if (palette && typeof palette.color === "object") {
|
||||
var theme = palette.color.scheme === "slate" ? "dark" : "light"
|
||||
|
||||
/* Instruct Giscus to change theme */
|
||||
var frame = document.querySelector(".giscus-frame")
|
||||
frame.contentWindow.postMessage(
|
||||
{ giscus: { setConfig: { theme } } },
|
||||
"https://giscus.app"
|
||||
)
|
||||
}
|
||||
})
|
||||
})
|
||||
</script>
|
||||
{% endif %}
|
||||
+6
-1
@@ -1,3 +1,8 @@
|
||||
## ByteTrack
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# ByteTrack
|
||||
|
||||
:::supervision.tracker.byte_tracker.core.ByteTrack
|
||||
|
||||
+9
-1
@@ -1,3 +1,11 @@
|
||||
## list_files_with_extensions
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# File Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>list_files_with_extensions</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.file.list_files_with_extensions
|
||||
|
||||
+31
-2
@@ -1,7 +1,36 @@
|
||||
## ImageSink
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Image Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ImageSink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
||||
## crop
|
||||
<div class="md-typeset">
|
||||
<h2>crop_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.crop_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>letterbox_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.letterbox_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>resize_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.resize_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>place_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.place_image
|
||||
|
||||
@@ -0,0 +1,18 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Iterables Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>create_batches</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.create_batches
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>fill</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.fill
|
||||
+13
-2
@@ -1,7 +1,18 @@
|
||||
## plot_image
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Notebooks Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>plot_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_image
|
||||
|
||||
## plot_images_grid
|
||||
<div class="md-typeset">
|
||||
<h2>plot_images_grid
|
||||
</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_images_grid
|
||||
|
||||
+21
-5
@@ -1,19 +1,35 @@
|
||||
## VideoInfo
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Video Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoInfo</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoInfo
|
||||
|
||||
## VideoSink
|
||||
<div class="md-typeset">
|
||||
<h2>VideoSink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoSink
|
||||
|
||||
## FPSMonitor
|
||||
<div class="md-typeset">
|
||||
<h2>FPSMonitor</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.FPSMonitor
|
||||
|
||||
## get_video_frames_generator
|
||||
<div class="md-typeset">
|
||||
<h2>get_video_frames_generator</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.get_video_frames_generator
|
||||
|
||||
## process_video
|
||||
<div class="md-typeset">
|
||||
<h2>process_video</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.process_video
|
||||
|
||||
@@ -0,0 +1,32 @@
|
||||
# Examples
|
||||
|
||||
This repository is packed with real-world use-cases, provided through Python scripts or
|
||||
interactive notebooks. Browse through to understand how the Supervision library
|
||||
interfaces with diverse applications.
|
||||
|
||||
- [tracking](./tracking) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [count people in zone](./count_people_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [traffic analysis](./traffic_analysis) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [speed estimation](./speed_estimation) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [time in zone](./time_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [heatmap and track](./heatmap_and_track/) by [@HinePo](https://github.com/HinePo)
|
||||
|
||||
## Contributing
|
||||
|
||||
We welcome contributions from the community in the form of examples, applications, and
|
||||
guides. To contribute, please follow these steps:
|
||||
|
||||
1. Create a pull request (PR) with the `[Example]` prefix in the title, adding your
|
||||
project folder to the `examples/` directory in the repository.
|
||||
2. Confirm your project aligns with the following standards:
|
||||
- Incorporates the `supervision` package.
|
||||
- Provides a `README.md` file, detailing the instructions to execute the project.
|
||||
- Showcases visual results, demonstrating the app's functionality.
|
||||
- Avoids adding large assets or dependencies unless absolutely necessary.
|
||||
- The contributor is expected to provide support for issues related to their
|
||||
examples.
|
||||
- In case the presented model has licensing complications, kindly specify them to
|
||||
circumvent potential misunderstandings.
|
||||
|
||||
For inquiries or concerns about these prerequisites, feel free to raise a PR. We are
|
||||
committed to assist and guide you.
|
||||
@@ -0,0 +1,13 @@
|
||||
# Ignore everything in the data directory
|
||||
data/*
|
||||
|
||||
# But re-include all .json files
|
||||
!data/*.json
|
||||
|
||||
*.pt
|
||||
*.pth
|
||||
*.mp4
|
||||
*.mov
|
||||
*.png
|
||||
*.jpg
|
||||
*.jpeg
|
||||
@@ -0,0 +1,120 @@
|
||||
# count people in zone
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This demo is a video analysis tool that counts and highlights objects in specific zones
|
||||
of a video. Each zone and the objects within it are marked in different colors, making
|
||||
it easy to see and count the objects in each area. The tool can save this enhanced
|
||||
video or display it live on the screen.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/f84db7b5-79e2-4142-a1da-64daa43ce667
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/count_people_in_zone
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
- download `traffic_analysis.pt` and `traffic_analysis.mov` files
|
||||
|
||||
```bash
|
||||
./setup.sh
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- ultralytics
|
||||
|
||||
- `--source_weights_path` (optional): The path to the YOLO model's weights file.
|
||||
Defaults to `"yolov8x.pt"` if not specified.
|
||||
|
||||
- `--zone_configuration_path`: Specifies the path to the JSON file containing zone
|
||||
configurations. This file defines the polygonal areas in the video where objects will
|
||||
be counted.
|
||||
- `--source_video_path`: The path to the source video file that will be analyzed.
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations.
|
||||
If not provided, the processed video will be displayed in real-time.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is `0.7`.
|
||||
|
||||
- inference
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"yolov8x-1280"`.
|
||||
|
||||
- `--zone_configuration_path`: Specifies the path to the JSON file containing zone
|
||||
configurations. This file defines the polygonal areas in the video where objects will
|
||||
be counted.
|
||||
- `--source_video_path`: The path to the source video file that will be analyzed.
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations.
|
||||
If not provided, the processed video will be displayed in real-time.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is `0.7`.
|
||||
|
||||
## 📌 zone configuration
|
||||
|
||||
- `horizontal-zone-config.json`: Defines zones divided horizontally across the frame.
|
||||
- `multi-zone-config.json`: Configures multiple zones with custom shapes and positions.
|
||||
- `quarters-zone-config.json`: Splits the frame into four equal quarters.
|
||||
- `vertical-zone-config.json`: Divides the frame into vertical zones of equal width.
|
||||
|
||||
## ⚙️ run example
|
||||
|
||||
- ultralytics
|
||||
|
||||
```bash
|
||||
python ultralytics_example.py \
|
||||
--zone_configuration_path data/multi-zone-config.json \
|
||||
--source_video_path data/market-square.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
- inference
|
||||
|
||||
```bash
|
||||
python inference_example.py \
|
||||
--roboflow_api_key <ROBOFLOW API KEY> \
|
||||
--zone_configuration_path data/multi-zone-config.json \
|
||||
--source_video_path data/market-square.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
@@ -0,0 +1,76 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
960
|
||||
],
|
||||
[
|
||||
0,
|
||||
960
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
960
|
||||
],
|
||||
[
|
||||
2160,
|
||||
960
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
0,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
2880
|
||||
],
|
||||
[
|
||||
0,
|
||||
2880
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
2880
|
||||
],
|
||||
[
|
||||
2160,
|
||||
2880
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,122 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
540,
|
||||
985
|
||||
],
|
||||
[
|
||||
1620,
|
||||
985
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1620,
|
||||
2855
|
||||
],
|
||||
[
|
||||
540,
|
||||
2855
|
||||
],
|
||||
[
|
||||
0,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
540,
|
||||
985
|
||||
],
|
||||
[
|
||||
0,
|
||||
0
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1620,
|
||||
985
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
540,
|
||||
985
|
||||
],
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
1620,
|
||||
985
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
],
|
||||
[
|
||||
540,
|
||||
2855
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1620,
|
||||
2855
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1620,
|
||||
2855
|
||||
],
|
||||
[
|
||||
540,
|
||||
2855
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,76 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
],
|
||||
[
|
||||
0,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,76 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
540,
|
||||
0
|
||||
],
|
||||
[
|
||||
540,
|
||||
3840
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
540,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
],
|
||||
[
|
||||
540,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
1620,
|
||||
0
|
||||
],
|
||||
[
|
||||
1620,
|
||||
3840
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1620,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
],
|
||||
[
|
||||
1620,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,224 @@
|
||||
import argparse
|
||||
import json
|
||||
import os
|
||||
from typing import List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference.core.models.roboflow import RoboflowInferenceModel
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from tqdm import tqdm
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.default()
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
This function reads a JSON file which contains polygon coordinates, and
|
||||
converts them into a list of NumPy arrays. Each polygon is represented as
|
||||
a NumPy array of coordinates.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the JSON configuration file.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data["polygons"]]
|
||||
|
||||
|
||||
def initiate_annotators(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> Tuple[
|
||||
List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator]
|
||||
]:
|
||||
line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
zones = []
|
||||
zone_annotators = []
|
||||
box_annotators = []
|
||||
|
||||
for index, polygon in enumerate(polygons):
|
||||
zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh)
|
||||
zone_annotator = sv.PolygonZoneAnnotator(
|
||||
zone=zone,
|
||||
color=COLORS.by_idx(index),
|
||||
thickness=line_thickness,
|
||||
text_thickness=line_thickness * 2,
|
||||
text_scale=text_scale * 2,
|
||||
)
|
||||
box_annotator = sv.BoundingBoxAnnotator(
|
||||
color=COLORS.by_idx(index), thickness=line_thickness
|
||||
)
|
||||
zones.append(zone)
|
||||
zone_annotators.append(zone_annotator)
|
||||
box_annotators.append(box_annotator)
|
||||
|
||||
return zones, zone_annotators, box_annotators
|
||||
|
||||
|
||||
def detect(
|
||||
frame: np.ndarray, model: RoboflowInferenceModel, confidence_threshold: float = 0.5
|
||||
) -> sv.Detections:
|
||||
"""
|
||||
Detect objects in a frame using Inference model, filtering detections by class ID
|
||||
and confidence threshold.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The frame to process, expected to be a NumPy array.
|
||||
model (RoboflowInferenceModel): The Inference model used for processing the
|
||||
frame.
|
||||
confidence_threshold (float, optional): The confidence threshold for filtering
|
||||
detections. Default is 0.5.
|
||||
|
||||
Returns:
|
||||
sv.Detections: Filtered detections after processing the frame with the Inference
|
||||
model.
|
||||
|
||||
Note:
|
||||
This function is specifically tailored for an Inference model and assumes class
|
||||
ID 0 for filtering.
|
||||
"""
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
filter_by_class = detections.class_id == 0
|
||||
filter_by_confidence = detections.confidence > confidence_threshold
|
||||
return detections[filter_by_class & filter_by_confidence]
|
||||
|
||||
|
||||
def annotate(
|
||||
frame: np.ndarray,
|
||||
zones: List[sv.PolygonZone],
|
||||
zone_annotators: List[sv.PolygonZoneAnnotator],
|
||||
box_annotators: List[sv.BoundingBoxAnnotator],
|
||||
detections: sv.Detections,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotate a frame with zone and box annotations based on given detections.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The original frame to be annotated.
|
||||
zones (List[sv.PolygonZone]): A list of polygon zones used for detection.
|
||||
zone_annotators (List[sv.PolygonZoneAnnotator]): A list of annotators for
|
||||
drawing zone annotations.
|
||||
box_annotators (List[sv.BoundingBoxAnnotator]): A list of annotators for
|
||||
drawing box annotations.
|
||||
detections (sv.Detections): Detections to be used for annotation.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated frame.
|
||||
"""
|
||||
annotated_frame = frame.copy()
|
||||
for zone, zone_annotator, box_annotator in zip(
|
||||
zones, zone_annotators, box_annotators
|
||||
):
|
||||
detections_in_zone = detections[zone.trigger(detections=detections)]
|
||||
annotated_frame = zone_annotator.annotate(scene=annotated_frame)
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections_in_zone
|
||||
)
|
||||
return annotated_frame
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Counting people in zones with Inference and Supervision"
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id",
|
||||
default="yolov8x-1280",
|
||||
help="Roboflow model ID",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--roboflow_api_key",
|
||||
default=None,
|
||||
help="Roboflow API KEY",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
default=None,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
help="IOU threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
api_key = args.roboflow_api_key
|
||||
api_key = os.environ.get("ROBOFLOW_API_KEY", api_key)
|
||||
if api_key is None:
|
||||
raise ValueError(
|
||||
"Roboflow API key is missing. Please provide it as an argument or set the "
|
||||
"ROBOFLOW_API_KEY environment variable."
|
||||
)
|
||||
args.roboflow_api_key = api_key
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(args.source_video_path)
|
||||
polygons = load_zones_config(args.zone_configuration_path)
|
||||
zones, zone_annotators, box_annotators = initiate_annotators(
|
||||
polygons=polygons, resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
|
||||
model = get_roboflow_model(model_id=args.model_id, api_key=args.roboflow_api_key)
|
||||
|
||||
frames_generator = sv.get_video_frames_generator(args.source_video_path)
|
||||
if args.target_video_path is not None:
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
sink.write_frame(annotated_frame)
|
||||
else:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
|
||||
cv2.destroyAllWindows()
|
||||
@@ -0,0 +1,5 @@
|
||||
gdown
|
||||
inference
|
||||
supervision==0.19.0
|
||||
tqdm
|
||||
ultralytics
|
||||
Executable
+14
@@ -0,0 +1,14 @@
|
||||
#!/bin/bash
|
||||
|
||||
# Get the directory where the script is located
|
||||
DIR="$( cd "$( dirname "${BASH_SOURCE[0]}" )" && pwd )"
|
||||
|
||||
# Check if 'data' directory does not exist and then create it
|
||||
if [[ ! -e $DIR/data ]]; then
|
||||
mkdir "$DIR/data"
|
||||
else
|
||||
echo "'data' directory already exists."
|
||||
fi
|
||||
|
||||
# Download the market-square.mp4 file from Google Drive
|
||||
gdown -O "$DIR/data/market-square.mp4" "https://drive.google.com/uc?id=1vVrEVMxucHgqGd7vAa501ASojbeGPhIr"
|
||||
@@ -0,0 +1,206 @@
|
||||
import argparse
|
||||
import json
|
||||
from typing import List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from tqdm import tqdm
|
||||
from ultralytics import YOLO
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.default()
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
This function reads a JSON file which contains polygon coordinates, and
|
||||
converts them into a list of NumPy arrays. Each polygon is represented as
|
||||
a NumPy array of coordinates.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the JSON configuration file.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data["polygons"]]
|
||||
|
||||
|
||||
def initiate_annotators(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> Tuple[
|
||||
List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator]
|
||||
]:
|
||||
line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
zones = []
|
||||
zone_annotators = []
|
||||
box_annotators = []
|
||||
|
||||
for index, polygon in enumerate(polygons):
|
||||
zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh)
|
||||
zone_annotator = sv.PolygonZoneAnnotator(
|
||||
zone=zone,
|
||||
color=COLORS.by_idx(index),
|
||||
thickness=line_thickness,
|
||||
text_thickness=line_thickness * 2,
|
||||
text_scale=text_scale * 2,
|
||||
)
|
||||
box_annotator = sv.BoundingBoxAnnotator(
|
||||
color=COLORS.by_idx(index), thickness=line_thickness
|
||||
)
|
||||
zones.append(zone)
|
||||
zone_annotators.append(zone_annotator)
|
||||
box_annotators.append(box_annotator)
|
||||
|
||||
return zones, zone_annotators, box_annotators
|
||||
|
||||
|
||||
def detect(
|
||||
frame: np.ndarray, model: YOLO, confidence_threshold: float = 0.5
|
||||
) -> sv.Detections:
|
||||
"""
|
||||
Detect objects in a frame using a YOLO model, filtering detections by class ID and
|
||||
confidence threshold.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The frame to process, expected to be a NumPy array.
|
||||
model (YOLO): The YOLO model used for processing the frame.
|
||||
confidence_threshold (float, optional): The confidence threshold for filtering
|
||||
detections. Default is 0.5.
|
||||
|
||||
Returns:
|
||||
sv.Detections: Filtered detections after processing the frame with the YOLO
|
||||
model.
|
||||
|
||||
Note:
|
||||
This function is specifically tailored for a YOLO model and assumes class ID 0
|
||||
for filtering.
|
||||
"""
|
||||
results = model(frame, imgsz=1280, verbose=False)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
filter_by_class = detections.class_id == 0
|
||||
filter_by_confidence = detections.confidence > confidence_threshold
|
||||
return detections[filter_by_class & filter_by_confidence]
|
||||
|
||||
|
||||
def annotate(
|
||||
frame: np.ndarray,
|
||||
zones: List[sv.PolygonZone],
|
||||
zone_annotators: List[sv.PolygonZoneAnnotator],
|
||||
box_annotators: List[sv.BoundingBoxAnnotator],
|
||||
detections: sv.Detections,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotate a frame with zone and box annotations based on given detections.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The original frame to be annotated.
|
||||
zones (List[sv.PolygonZone]): A list of polygon zones used for detection.
|
||||
zone_annotators (List[sv.PolygonZoneAnnotator]): A list of annotators for
|
||||
drawing zone annotations.
|
||||
box_annotators (List[sv.BoundingBoxAnnotator]): A list of annotators for
|
||||
drawing box annotations.
|
||||
detections (sv.Detections): Detections to be used for annotation.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated frame.
|
||||
"""
|
||||
annotated_frame = frame.copy()
|
||||
for zone, zone_annotator, box_annotator in zip(
|
||||
zones, zone_annotators, box_annotators
|
||||
):
|
||||
detections_in_zone = detections[zone.trigger(detections=detections)]
|
||||
annotated_frame = zone_annotator.annotate(scene=annotated_frame)
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections_in_zone
|
||||
)
|
||||
return annotated_frame
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Counting people in zones with YOLO and Supervision"
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_weights_path",
|
||||
default="yolov8x.pt",
|
||||
help="Path to the source weights file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
default=None,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
help="IOU threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(args.source_video_path)
|
||||
polygons = load_zones_config(args.zone_configuration_path)
|
||||
zones, zone_annotators, box_annotators = initiate_annotators(
|
||||
polygons=polygons, resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
|
||||
model = YOLO(args.source_weights_path)
|
||||
|
||||
frames_generator = sv.get_video_frames_generator(args.source_video_path)
|
||||
if args.target_video_path is not None:
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
sink.write_frame(annotated_frame)
|
||||
else:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
|
||||
cv2.destroyAllWindows()
|
||||
@@ -0,0 +1,75 @@
|
||||
# heatmap and tracking
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This script performs heatmap and tracking analysis using YOLOv8, an object-detection method and
|
||||
ByteTrack, a simple yet effective online multi-object tracking method. It uses the
|
||||
supervision package for multiple tasks such as drawing heatmap annotations, tracking objects, etc.
|
||||
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/heatmap_and_track
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the weights file for the
|
||||
YOLO model. This file contains the trained model data necessary for object detection.
|
||||
- `--source_video_path` (optional): The path to the source video file that will be
|
||||
analyzed. This is the input video on which crowd analysis will be performed.
|
||||
If not specified default is `people-walking.mp4` from supervision assets
|
||||
- `--target_video_path` (optional): The path to save the output.mp4 video with annotations.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`. This determines how confident the model should
|
||||
be to recognize an object in the video.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection accuracy,
|
||||
particularly in distinguishing between different objects.
|
||||
- `--heatmap_alpha` (optional): Opacity of the overlay mask, between 0 and 1.
|
||||
- `--radius` (optional): Radius of the heat circle.
|
||||
- `--track_threshold` (optional): Detection confidence threshold for track activation.
|
||||
- `--track_seconds` (optional): Number of seconds to buffer when a track is lost.
|
||||
- `--match_threshold` (optional): Threshold for matching tracks with detections.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
```bash
|
||||
python script.py \
|
||||
--source_weights_path weight.pt \
|
||||
--source_video_path input_video.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5 \
|
||||
--target_video_path output_video.mp4
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
@@ -0,0 +1,2 @@
|
||||
supervision[assets]==0.19.0
|
||||
ultralytics
|
||||
@@ -0,0 +1,181 @@
|
||||
import argparse
|
||||
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
|
||||
import supervision as sv
|
||||
from supervision.assets import VideoAssets, download_assets
|
||||
|
||||
|
||||
def download_video() -> str:
|
||||
download_assets(VideoAssets.PEOPLE_WALKING)
|
||||
return VideoAssets.PEOPLE_WALKING.value
|
||||
|
||||
|
||||
def heatmap_and_track(
|
||||
source_weights_path: str,
|
||||
source_video_path: str,
|
||||
target_video_path: str,
|
||||
confidence_threshold: float = 0.35,
|
||||
iou_threshold: float = 0.5,
|
||||
heatmap_alpha: float = 0.5,
|
||||
radius: int = 25,
|
||||
track_threshold: float = 0.35,
|
||||
track_seconds: int = 5,
|
||||
match_threshold: float = 0.99,
|
||||
) -> None:
|
||||
### instantiate model
|
||||
model = YOLO(source_weights_path)
|
||||
|
||||
### heatmap config
|
||||
heat_map_annotator = sv.HeatMapAnnotator(
|
||||
position=sv.Position.BOTTOM_CENTER,
|
||||
opacity=heatmap_alpha,
|
||||
radius=radius,
|
||||
kernel_size=25,
|
||||
top_hue=0,
|
||||
low_hue=125,
|
||||
)
|
||||
|
||||
### annotation config
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
|
||||
### get the video fps
|
||||
cap = cv2.VideoCapture(source_video_path)
|
||||
fps = int(cap.get(cv2.CAP_PROP_FPS))
|
||||
cap.release()
|
||||
|
||||
### tracker config
|
||||
byte_tracker = sv.ByteTrack(
|
||||
track_thresh=track_threshold,
|
||||
track_buffer=track_seconds * fps,
|
||||
match_thresh=match_threshold,
|
||||
frame_rate=fps,
|
||||
)
|
||||
|
||||
### video config
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(
|
||||
source_path=source_video_path, stride=1
|
||||
)
|
||||
|
||||
### Detect, track, annotate, save
|
||||
with sv.VideoSink(target_path=target_video_path, video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(
|
||||
source=frame,
|
||||
classes=[0], # only person class
|
||||
conf=confidence_threshold,
|
||||
iou=iou_threshold,
|
||||
# show_conf = True,
|
||||
# save_txt = True,
|
||||
# save_conf = True,
|
||||
# save = True,
|
||||
device=None, # use None = CPU, 0 = single GPU, or [0,1] = dual GPU
|
||||
)[0]
|
||||
|
||||
detections = sv.Detections.from_ultralytics(result) # get detections
|
||||
|
||||
detections = byte_tracker.update_with_detections(
|
||||
detections
|
||||
) # update tracker
|
||||
|
||||
### draw heatmap
|
||||
annotated_frame = heat_map_annotator.annotate(
|
||||
scene=frame.copy(), detections=detections
|
||||
)
|
||||
|
||||
### draw other attributes from `detections` object
|
||||
labels = [
|
||||
f"#{tracker_id}"
|
||||
for class_id, tracker_id in zip(
|
||||
detections.class_id, detections.tracker_id
|
||||
)
|
||||
]
|
||||
|
||||
label_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections, labels=labels
|
||||
)
|
||||
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Heatmap and Tracking with Supervision"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_weights_path",
|
||||
required=True,
|
||||
help="Path to the source weights file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
default=download_video(),
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
default="output.mp4",
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.35,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.5,
|
||||
help="IOU threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--heatmap_alpha",
|
||||
default=0.5,
|
||||
help="Opacity of the overlay mask, between 0 and 1",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--radius",
|
||||
default=25,
|
||||
help="Radius of the heat circle",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--track_threshold",
|
||||
default=0.35,
|
||||
help="Detection confidence threshold for track activation",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--track_seconds",
|
||||
default=5,
|
||||
help="Number of seconds to buffer when a track is lost",
|
||||
type=int,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--match_threshold",
|
||||
default=0.99,
|
||||
help="Threshold for matching tracks with detections",
|
||||
type=float,
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
heatmap_and_track(
|
||||
source_weights_path=args.source_weights_path,
|
||||
source_video_path=args.source_video_path,
|
||||
target_video_path=args.target_video_path,
|
||||
confidence_threshold=args.confidence_threshold,
|
||||
iou_threshold=args.iou_threshold,
|
||||
heatmap_alpha=args.heatmap_alpha,
|
||||
radius=args.radius,
|
||||
track_threshold=args.track_threshold,
|
||||
track_seconds=args.track_seconds,
|
||||
match_threshold=args.match_threshold,
|
||||
)
|
||||
@@ -0,0 +1,9 @@
|
||||
data/
|
||||
venv*/
|
||||
*.pt
|
||||
*.pth
|
||||
*.mp4
|
||||
*.mov
|
||||
*.png
|
||||
*.jpg
|
||||
*.jpeg
|
||||
@@ -0,0 +1,117 @@
|
||||
# speed estimation
|
||||
|
||||
[](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-estimate-vehicle-speed-with-computer-vision.ipynb)
|
||||
[](https://youtu.be/uWP6UjDeZvY)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This example performs speed estimation analysis using various object-detection models
|
||||
and ByteTrack - a simple yet effective online multi-object tracking method. It uses the
|
||||
supervision package for multiple tasks such as tracking, annotations, etc.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d50118c1-2ae4-458d-915a-5d860fd36f71
|
||||
|
||||
> [!IMPORTANT]
|
||||
> Adjust the [`SOURCE`](https://github.com/roboflow/supervision/blob/e32b05a636dab2ea1f39299e529c4b22b8baa8da/examples/speed_estimation/ultralytics_example.py#L10)
|
||||
> and [`TARGET`](https://github.com/roboflow/supervision/blob/e32b05a636dab2ea1f39299e529c4b22b8baa8da/examples/speed_estimation/ultralytics_example.py#L15)
|
||||
> configuration if you plan to run a speed estimation script on your video file. Those must be adjusted separately for each camera view. You can learn more
|
||||
> from our YouTube [tutorial](https://youtu.be/uWP6UjDeZvY).
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/speed_estimation
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3.10 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
- download `vehicles.mp4` file
|
||||
|
||||
```bash
|
||||
python3.10 video_downloader.py
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"yolov8x-1280"`.
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights
|
||||
file, which is essential for the object detection process. This file contains the
|
||||
data that the model uses to identify objects in the video.
|
||||
- `--source_video_path`: Required. The path to the source video file that will be
|
||||
analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
- `--target_video_path`: The path to save the output video with
|
||||
annotations. If not specified, the processed video will be displayed in real-time
|
||||
without being saved.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO
|
||||
model to filter detections. Default is `0.3`. This determines how confident the
|
||||
model should be to recognize an object in the video.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection
|
||||
accuracy, particularly in distinguishing between different objects.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
- yolo-nas
|
||||
|
||||
```bash
|
||||
python yolo_nas_example.py \
|
||||
--source_video_path data/vehicles.mp4 \
|
||||
--target_video_path data/vehicles-result.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
- inference
|
||||
|
||||
```bash
|
||||
python inference_example.py \
|
||||
--roboflow_api_key <ROBOFLOW API KEY> \
|
||||
--source_video_path data/vehicles.mp4 \
|
||||
--target_video_path data/vehicles-result.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
- ultralytics
|
||||
|
||||
```bash
|
||||
python ultralytics_example.py \
|
||||
--source_video_path data/vehicles.mp4 \
|
||||
--target_video_path data/vehicles-result.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
@@ -0,0 +1,170 @@
|
||||
import argparse
|
||||
import os
|
||||
from collections import defaultdict, deque
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
import supervision as sv
|
||||
|
||||
SOURCE = np.array([[1252, 787], [2298, 803], [5039, 2159], [-550, 2159]])
|
||||
|
||||
TARGET_WIDTH = 25
|
||||
TARGET_HEIGHT = 250
|
||||
|
||||
TARGET = np.array(
|
||||
[
|
||||
[0, 0],
|
||||
[TARGET_WIDTH - 1, 0],
|
||||
[TARGET_WIDTH - 1, TARGET_HEIGHT - 1],
|
||||
[0, TARGET_HEIGHT - 1],
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
class ViewTransformer:
|
||||
def __init__(self, source: np.ndarray, target: np.ndarray) -> None:
|
||||
source = source.astype(np.float32)
|
||||
target = target.astype(np.float32)
|
||||
self.m = cv2.getPerspectiveTransform(source, target)
|
||||
|
||||
def transform_points(self, points: np.ndarray) -> np.ndarray:
|
||||
if points.size == 0:
|
||||
return points
|
||||
|
||||
reshaped_points = points.reshape(-1, 1, 2).astype(np.float32)
|
||||
transformed_points = cv2.perspectiveTransform(reshaped_points, self.m)
|
||||
return transformed_points.reshape(-1, 2)
|
||||
|
||||
|
||||
def parse_arguments() -> argparse.Namespace:
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Vehicle Speed Estimation using Inference and Supervision"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id",
|
||||
default="yolov8x-640",
|
||||
help="Roboflow model ID",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--roboflow_api_key",
|
||||
default=None,
|
||||
help="Roboflow API KEY",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
required=True,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold", default=0.7, help="IOU threshold for the model", type=float
|
||||
)
|
||||
|
||||
return parser.parse_args()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parse_arguments()
|
||||
|
||||
api_key = args.roboflow_api_key
|
||||
api_key = os.environ.get("ROBOFLOW_API_KEY", api_key)
|
||||
if api_key is None:
|
||||
raise ValueError(
|
||||
"Roboflow API key is missing. Please provide it as an argument or set the "
|
||||
"ROBOFLOW_API_KEY environment variable."
|
||||
)
|
||||
args.roboflow_api_key = api_key
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=args.source_video_path)
|
||||
model = get_roboflow_model(model_id=args.model_id, api_key=args.roboflow_api_key)
|
||||
|
||||
byte_track = sv.ByteTrack(
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
text_thickness=thickness,
|
||||
text_position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
trace_annotator = sv.TraceAnnotator(
|
||||
thickness=thickness,
|
||||
trace_length=video_info.fps * 2,
|
||||
position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in frame_generator:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = detections[detections.confidence > args.confidence_threshold]
|
||||
detections = detections[polygon_zone.trigger(detections)]
|
||||
detections = detections.with_nms(threshold=args.iou_threshold)
|
||||
detections = byte_track.update_with_detections(detections=detections)
|
||||
|
||||
points = detections.get_anchors_coordinates(
|
||||
anchor=sv.Position.BOTTOM_CENTER
|
||||
)
|
||||
points = view_transformer.transform_points(points=points).astype(int)
|
||||
|
||||
for tracker_id, [_, y] in zip(detections.tracker_id, points):
|
||||
coordinates[tracker_id].append(y)
|
||||
|
||||
labels = []
|
||||
for tracker_id in detections.tracker_id:
|
||||
if len(coordinates[tracker_id]) < video_info.fps / 2:
|
||||
labels.append(f"#{tracker_id}")
|
||||
else:
|
||||
coordinate_start = coordinates[tracker_id][-1]
|
||||
coordinate_end = coordinates[tracker_id][0]
|
||||
distance = abs(coordinate_start - coordinate_end)
|
||||
time = len(coordinates[tracker_id]) / video_info.fps
|
||||
speed = distance / time * 3.6
|
||||
labels.append(f"#{tracker_id} {int(speed)} km/h")
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = trace_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections, labels=labels
|
||||
)
|
||||
|
||||
sink.write_frame(annotated_frame)
|
||||
cv2.imshow("frame", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
@@ -0,0 +1,6 @@
|
||||
supervision==0.19.0
|
||||
tqdm==4.66.1
|
||||
requests
|
||||
ultralytics==8.0.237
|
||||
super-gradients==3.5.0
|
||||
inference==0.9.8
|
||||
@@ -0,0 +1,148 @@
|
||||
import argparse
|
||||
from collections import defaultdict, deque
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from ultralytics import YOLO
|
||||
|
||||
import supervision as sv
|
||||
|
||||
SOURCE = np.array([[1252, 787], [2298, 803], [5039, 2159], [-550, 2159]])
|
||||
|
||||
TARGET_WIDTH = 25
|
||||
TARGET_HEIGHT = 250
|
||||
|
||||
TARGET = np.array(
|
||||
[
|
||||
[0, 0],
|
||||
[TARGET_WIDTH - 1, 0],
|
||||
[TARGET_WIDTH - 1, TARGET_HEIGHT - 1],
|
||||
[0, TARGET_HEIGHT - 1],
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
class ViewTransformer:
|
||||
def __init__(self, source: np.ndarray, target: np.ndarray) -> None:
|
||||
source = source.astype(np.float32)
|
||||
target = target.astype(np.float32)
|
||||
self.m = cv2.getPerspectiveTransform(source, target)
|
||||
|
||||
def transform_points(self, points: np.ndarray) -> np.ndarray:
|
||||
if points.size == 0:
|
||||
return points
|
||||
|
||||
reshaped_points = points.reshape(-1, 1, 2).astype(np.float32)
|
||||
transformed_points = cv2.perspectiveTransform(reshaped_points, self.m)
|
||||
return transformed_points.reshape(-1, 2)
|
||||
|
||||
|
||||
def parse_arguments() -> argparse.Namespace:
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Vehicle Speed Estimation using Ultralytics and Supervision"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
required=True,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold", default=0.7, help="IOU threshold for the model", type=float
|
||||
)
|
||||
|
||||
return parser.parse_args()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parse_arguments()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=args.source_video_path)
|
||||
model = YOLO("yolov8x.pt")
|
||||
|
||||
byte_track = sv.ByteTrack(
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
text_thickness=thickness,
|
||||
text_position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
trace_annotator = sv.TraceAnnotator(
|
||||
thickness=thickness,
|
||||
trace_length=video_info.fps * 2,
|
||||
position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in frame_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
detections = detections[detections.confidence > args.confidence_threshold]
|
||||
detections = detections[polygon_zone.trigger(detections)]
|
||||
detections = detections.with_nms(threshold=args.iou_threshold)
|
||||
detections = byte_track.update_with_detections(detections=detections)
|
||||
|
||||
points = detections.get_anchors_coordinates(
|
||||
anchor=sv.Position.BOTTOM_CENTER
|
||||
)
|
||||
points = view_transformer.transform_points(points=points).astype(int)
|
||||
|
||||
for tracker_id, [_, y] in zip(detections.tracker_id, points):
|
||||
coordinates[tracker_id].append(y)
|
||||
|
||||
labels = []
|
||||
for tracker_id in detections.tracker_id:
|
||||
if len(coordinates[tracker_id]) < video_info.fps / 2:
|
||||
labels.append(f"#{tracker_id}")
|
||||
else:
|
||||
coordinate_start = coordinates[tracker_id][-1]
|
||||
coordinate_end = coordinates[tracker_id][0]
|
||||
distance = abs(coordinate_start - coordinate_end)
|
||||
time = len(coordinates[tracker_id]) / video_info.fps
|
||||
speed = distance / time * 3.6
|
||||
labels.append(f"#{tracker_id} {int(speed)} km/h")
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = trace_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections, labels=labels
|
||||
)
|
||||
|
||||
sink.write_frame(annotated_frame)
|
||||
cv2.imshow("frame", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
@@ -0,0 +1,8 @@
|
||||
import os
|
||||
|
||||
from supervision.assets import VideoAssets, download_assets
|
||||
|
||||
if not os.path.exists("data"):
|
||||
os.makedirs("data")
|
||||
os.chdir("data")
|
||||
download_assets(VideoAssets.VEHICLES)
|
||||
@@ -0,0 +1,148 @@
|
||||
import argparse
|
||||
from collections import defaultdict, deque
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from super_gradients.common.object_names import Models
|
||||
from super_gradients.training import models
|
||||
|
||||
import supervision as sv
|
||||
|
||||
SOURCE = np.array([[1252, 787], [2298, 803], [5039, 2159], [-550, 2159]])
|
||||
|
||||
TARGET_WIDTH = 25
|
||||
TARGET_HEIGHT = 250
|
||||
|
||||
TARGET = np.array(
|
||||
[
|
||||
[0, 0],
|
||||
[TARGET_WIDTH - 1, 0],
|
||||
[TARGET_WIDTH - 1, TARGET_HEIGHT - 1],
|
||||
[0, TARGET_HEIGHT - 1],
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
class ViewTransformer:
|
||||
def __init__(self, source: np.ndarray, target: np.ndarray) -> None:
|
||||
source = source.astype(np.float32)
|
||||
target = target.astype(np.float32)
|
||||
self.m = cv2.getPerspectiveTransform(source, target)
|
||||
|
||||
def transform_points(self, points: np.ndarray) -> np.ndarray:
|
||||
if points.size == 0:
|
||||
return points
|
||||
|
||||
reshaped_points = points.reshape(-1, 1, 2).astype(np.float32)
|
||||
transformed_points = cv2.perspectiveTransform(reshaped_points, self.m)
|
||||
return transformed_points.reshape(-1, 2)
|
||||
|
||||
|
||||
def parse_arguments() -> argparse.Namespace:
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Vehicle Speed Estimation using YOLO-NAS and Supervision"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
required=True,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold", default=0.7, help="IOU threshold for the model", type=float
|
||||
)
|
||||
|
||||
return parser.parse_args()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parse_arguments()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=args.source_video_path)
|
||||
model = models.get(Models.YOLO_NAS_L, pretrained_weights="coco")
|
||||
|
||||
byte_track = sv.ByteTrack(
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
text_thickness=thickness,
|
||||
text_position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
trace_annotator = sv.TraceAnnotator(
|
||||
thickness=thickness,
|
||||
trace_length=video_info.fps * 2,
|
||||
position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in frame_generator:
|
||||
result = model.predict(frame)[0]
|
||||
detections = sv.Detections.from_yolo_nas(result)
|
||||
detections = detections[polygon_zone.trigger(detections)]
|
||||
detections = detections.with_nms(threshold=args.iou_threshold)
|
||||
detections = byte_track.update_with_detections(detections=detections)
|
||||
|
||||
points = detections.get_anchors_coordinates(
|
||||
anchor=sv.Position.BOTTOM_CENTER
|
||||
)
|
||||
points = view_transformer.transform_points(points=points).astype(int)
|
||||
|
||||
for tracker_id, [_, y] in zip(detections.tracker_id, points):
|
||||
coordinates[tracker_id].append(y)
|
||||
|
||||
labels = []
|
||||
for tracker_id in detections.tracker_id:
|
||||
if len(coordinates[tracker_id]) < video_info.fps / 2:
|
||||
labels.append(f"#{tracker_id}")
|
||||
else:
|
||||
coordinate_start = coordinates[tracker_id][-1]
|
||||
coordinate_end = coordinates[tracker_id][0]
|
||||
distance = abs(coordinate_start - coordinate_end)
|
||||
time = len(coordinates[tracker_id]) / video_info.fps
|
||||
speed = distance / time * 3.6
|
||||
labels.append(f"#{tracker_id} {int(speed)} km/h")
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = trace_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections, labels=labels
|
||||
)
|
||||
|
||||
sink.write_frame(annotated_frame)
|
||||
cv2.imshow("frame", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
@@ -0,0 +1,9 @@
|
||||
data/
|
||||
venv*/
|
||||
*.pt
|
||||
*.pth
|
||||
*.mp4
|
||||
*.mov
|
||||
*.png
|
||||
*.jpg
|
||||
*.jpeg
|
||||
@@ -0,0 +1,262 @@
|
||||
# time in zone
|
||||
|
||||
## 👋 hello
|
||||
|
||||
Practical demonstration on leveraging computer vision for analyzing wait times and
|
||||
monitoring the duration that objects or individuals spend in predefined areas of video
|
||||
frames. This example project, perfect for retail analytics or traffic management
|
||||
applications.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d051cc8a-dd15-41d4-aa36-d38b86334c39
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/time_in_zone
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 🛠 scripts
|
||||
|
||||
### `download_from_youtube`
|
||||
|
||||
This script allows you to download a video from YouTube.
|
||||
|
||||
- `--url`: The full URL of the YouTube video you wish to download.
|
||||
- `--output_path` (optional): Specifies the directory where the video will be saved.
|
||||
- `--file_name` (optional): Sets the name of the saved video file.
|
||||
|
||||
```bash
|
||||
python scripts/download_from_youtube.py \
|
||||
--url "https://www.youtube.com/watch?v=-8zyEwAa50Q" \
|
||||
--output_path "data/checkout" \
|
||||
--file_name "video.mp4"
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/download_from_youtube.py \
|
||||
--url "https://www.youtube.com/watch?v=MNn9qKG2UFI" \
|
||||
--output_path "data/traffic" \
|
||||
--file_name "video.mp4"
|
||||
```
|
||||
|
||||
### `stream_from_file`
|
||||
|
||||
This script allows you to stream video files from a directory. It's an awesome way to
|
||||
mock a live video stream for local testing. Video will be streamed in a loop under
|
||||
`rtsp://localhost:8554/live0.stream` URL. This script requires docker to be installed.
|
||||
|
||||
- `--video_directory`: Directory containing video files to stream.
|
||||
- `--number_of_streams`: Number of video files to stream.
|
||||
|
||||
```bash
|
||||
python scripts/stream_from_file.py \
|
||||
--video_directory "data/checkout" \
|
||||
--number_of_streams 1
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/stream_from_file.py \
|
||||
--video_directory "data/traffic" \
|
||||
--number_of_streams 1
|
||||
```
|
||||
|
||||
### `draw_zones`
|
||||
|
||||
If you want to test zone time in zone analysis on your own video, you can use this
|
||||
script to design custom zones and save results as a JSON file. The script will open a
|
||||
window where you can draw polygons on the source image or video file. The polygons will
|
||||
be saved as a JSON file.
|
||||
|
||||
- `--source_path`: Path to the source image or video file for drawing polygons.
|
||||
- `--zone_configuration_path`: Path where the polygon annotations will be saved as a JSON file.
|
||||
|
||||
|
||||
- `enter` - finish drawing the current polygon.
|
||||
- `escape` - cancel drawing the current polygon.
|
||||
- `q` - quit the drawing window.
|
||||
- `s` - save zone configuration to a JSON file.
|
||||
|
||||
```bash
|
||||
python scripts/draw_zones.py \
|
||||
--source_path "data/checkout/video.mp4" \
|
||||
--zone_configuration_path "data/checkout/config.json"
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/draw_zones.py \
|
||||
--source_path "data/traffic/video.mp4" \
|
||||
--zone_configuration_path "data/traffic/custom_config.json"
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/9d514c9e-2a61-418b-ae49-6ac1ad6ae5ac
|
||||
|
||||
## 🎬 video & stream processing
|
||||
|
||||
### `inference_file_example`
|
||||
|
||||
Script to run object detection on a video file using the Roboflow Inference model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--source_video_path`: Path to the source video file.
|
||||
- `--model_id`: Roboflow model ID.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--source_video_path "data/checkout/video.mp4" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d051cc8a-dd15-41d4-aa36-d38b86334c39
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--source_video_path "data/traffic/video.mp4" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/5ec896d7-4b39-4426-8979-11e71666878b
|
||||
|
||||
### `inference_stream_example`
|
||||
|
||||
Script to run object detection on a video stream using the Roboflow Inference model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--rtsp_url`: Complete RTSP URL for the video stream.
|
||||
- `--model_id`: Roboflow model ID.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>👉 show ultralytics examples</summary>
|
||||
|
||||
### `ultralytics_file_example`
|
||||
|
||||
Script to run object detection on a video file using the Ultralytics YOLOv8 model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--source_video_path`: Path to the source video file.
|
||||
- `--weights`: Path to the model weights file. Default is `'yolov8s.pt'`.
|
||||
- `--device`: Computation device (`'cpu'`, `'mps'` or `'cuda'`). Default is `'cpu'`.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--source_video_path "data/checkout/video.mp4" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--source_video_path "data/traffic/video.mp4" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
### `ultralytics_stream_example`
|
||||
|
||||
Script to run object detection on a video stream using the Ultralytics YOLOv8 model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--rtsp_url`: Complete RTSP URL for the video stream.
|
||||
- `--weights`: Path to the model weights file. Default is `'yolov8s.pt'`.
|
||||
- `--device`: Computation device (`'cpu'`, `'mps'` or `'cuda'`). Default is `'cpu'`.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
@@ -0,0 +1,132 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import get_model
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import FPSBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
source_video_path: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = get_model(model_id=model_id)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(source_video_path)
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [FPSBasedTimer(video_info.fps) for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
results = model.infer(frame, confidence=confidence, iou_threshold=iou)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using video file."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source video file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
source_video_path=args.source_video_path,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,142 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import get_model
|
||||
from utils.general import find_in_list, get_stream_frames_generator, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = get_model(model_id=model_id)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url)
|
||||
fps_monitor = sv.FPSMonitor()
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [ClockBasedTimer() for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
fps_monitor.tick()
|
||||
fps = fps_monitor.fps
|
||||
|
||||
results = model.infer(frame, confidence=confidence, iou_threshold=iou)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,158 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import InferencePipeline
|
||||
from inference.core.interfaces.camera.entities import VideoFrame
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
class CustomSink:
|
||||
def __init__(self, zone_configuration_path: str, classes: List[int]):
|
||||
self.classes = classes
|
||||
self.tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
self.polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
self.timers = [ClockBasedTimer() for _ in self.polygons]
|
||||
self.zones = None
|
||||
|
||||
def on_prediction(self, result: dict, frame: VideoFrame) -> None:
|
||||
if self.zones is None:
|
||||
resolution_wh = frame.image.shape[1], frame.image.shape[0]
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
self.fps_monitor.tick()
|
||||
fps = self.fps_monitor.fps
|
||||
|
||||
detections = sv.Detections.from_inference(result)
|
||||
detections = detections[find_in_list(detections.class_id, self.classes)]
|
||||
detections = self.tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.image.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(self.zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = self.timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
cv2.waitKey(1)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
sink = CustomSink(zone_configuration_path=zone_configuration_path, classes=classes)
|
||||
|
||||
pipeline = InferencePipeline.init(
|
||||
model_id=model_id,
|
||||
video_reference=rtsp_url,
|
||||
on_prediction=sink.on_prediction,
|
||||
confidence=confidence,
|
||||
iou_threshold=iou,
|
||||
)
|
||||
|
||||
pipeline.start()
|
||||
|
||||
try:
|
||||
pipeline.join()
|
||||
except KeyboardInterrupt:
|
||||
pipeline.terminate()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,5 @@
|
||||
opencv-python
|
||||
supervision
|
||||
ultralytics
|
||||
inference
|
||||
pytube
|
||||
@@ -0,0 +1,46 @@
|
||||
import argparse
|
||||
import os
|
||||
from typing import Optional
|
||||
|
||||
from pytube import YouTube
|
||||
|
||||
|
||||
def main(url: str, output_path: Optional[str], file_name: Optional[str]) -> None:
|
||||
yt = YouTube(url)
|
||||
stream = yt.streams.get_highest_resolution()
|
||||
|
||||
if not os.path.exists(output_path):
|
||||
os.makedirs(output_path)
|
||||
|
||||
stream.download(output_path=output_path, filename=file_name)
|
||||
final_name = file_name if file_name else yt.title
|
||||
final_path = output_path if output_path else "current directory"
|
||||
print(f"Download completed! Video saved as '{final_name}' in '{final_path}'.")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Download a specific YouTube video by providing its URL."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="The full URL of the YouTube video you wish to download.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--output_path",
|
||||
type=str,
|
||||
default="data/source",
|
||||
required=False,
|
||||
help="Optional. Specifies the directory where the video will be saved.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--file_name",
|
||||
type=str,
|
||||
default="video.mp4",
|
||||
required=False,
|
||||
help="Optional. Sets the name of the saved video file.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
main(url=args.url, output_path=args.output_path, file_name=args.file_name)
|
||||
@@ -0,0 +1,176 @@
|
||||
import argparse
|
||||
import json
|
||||
import os
|
||||
from typing import Any, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
import supervision as sv
|
||||
|
||||
KEY_ENTER = 13
|
||||
KEY_NEWLINE = 10
|
||||
KEY_ESCAPE = 27
|
||||
KEY_QUIT = ord("q")
|
||||
KEY_SAVE = ord("s")
|
||||
|
||||
THICKNESS = 2
|
||||
COLORS = sv.ColorPalette.DEFAULT
|
||||
WINDOW_NAME = "Draw Zones"
|
||||
POLYGONS = [[]]
|
||||
|
||||
current_mouse_position: Optional[Tuple[int, int]] = None
|
||||
|
||||
|
||||
def resolve_source(source_path: str) -> Optional[np.ndarray]:
|
||||
if not os.path.exists(source_path):
|
||||
return None
|
||||
|
||||
image = cv2.imread(source_path)
|
||||
if image is not None:
|
||||
return image
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=source_path)
|
||||
frame = next(frame_generator)
|
||||
return frame
|
||||
|
||||
|
||||
def mouse_event(event: int, x: int, y: int, flags: int, param: Any) -> None:
|
||||
global current_mouse_position
|
||||
if event == cv2.EVENT_MOUSEMOVE:
|
||||
current_mouse_position = (x, y)
|
||||
elif event == cv2.EVENT_LBUTTONDOWN:
|
||||
POLYGONS[-1].append((x, y))
|
||||
|
||||
|
||||
def redraw(image: np.ndarray, original_image: np.ndarray) -> None:
|
||||
global POLYGONS, current_mouse_position
|
||||
image[:] = original_image.copy()
|
||||
for idx, polygon in enumerate(POLYGONS):
|
||||
color = (
|
||||
COLORS.by_idx(idx).as_bgr()
|
||||
if idx < len(POLYGONS) - 1
|
||||
else sv.Color.WHITE.as_bgr()
|
||||
)
|
||||
|
||||
if len(polygon) > 1:
|
||||
for i in range(1, len(polygon)):
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[i - 1],
|
||||
pt2=polygon[i],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
if idx < len(POLYGONS) - 1:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=polygon[0],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
if idx == len(POLYGONS) - 1 and current_mouse_position is not None and polygon:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=current_mouse_position,
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
|
||||
|
||||
def close_and_finalize_polygon(image: np.ndarray, original_image: np.ndarray) -> None:
|
||||
if len(POLYGONS[-1]) > 2:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=POLYGONS[-1][-1],
|
||||
pt2=POLYGONS[-1][0],
|
||||
color=COLORS.by_idx(0).as_bgr(),
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
POLYGONS.append([])
|
||||
image[:] = original_image.copy()
|
||||
redraw_polygons(image)
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
|
||||
|
||||
def redraw_polygons(image: np.ndarray) -> None:
|
||||
for idx, polygon in enumerate(POLYGONS[:-1]):
|
||||
if len(polygon) > 1:
|
||||
color = COLORS.by_idx(idx).as_bgr()
|
||||
for i in range(len(polygon) - 1):
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[i],
|
||||
pt2=polygon[i + 1],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=polygon[0],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
|
||||
|
||||
def save_polygons_to_json(polygons, target_path):
|
||||
data_to_save = polygons if polygons[-1] else polygons[:-1]
|
||||
with open(target_path, "w") as f:
|
||||
json.dump(data_to_save, f)
|
||||
|
||||
|
||||
def main(source_path: str, zone_configuration_path: str) -> None:
|
||||
global current_mouse_position
|
||||
original_image = resolve_source(source_path=source_path)
|
||||
if original_image is None:
|
||||
print("Failed to load source image.")
|
||||
return
|
||||
|
||||
image = original_image.copy()
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
cv2.setMouseCallback(WINDOW_NAME, mouse_event, image)
|
||||
|
||||
while True:
|
||||
key = cv2.waitKey(1) & 0xFF
|
||||
if key == KEY_ENTER or key == KEY_NEWLINE:
|
||||
close_and_finalize_polygon(image, original_image)
|
||||
elif key == KEY_ESCAPE:
|
||||
POLYGONS[-1] = []
|
||||
current_mouse_position = None
|
||||
elif key == KEY_SAVE:
|
||||
save_polygons_to_json(POLYGONS, zone_configuration_path)
|
||||
print(f"Polygons saved to {zone_configuration_path}")
|
||||
break
|
||||
redraw(image, original_image)
|
||||
if key == KEY_QUIT:
|
||||
break
|
||||
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Interactively draw polygons on images or video frames and save "
|
||||
"the annotations."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source image or video file for drawing polygons.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path where the polygon annotations will be saved as a JSON file.",
|
||||
)
|
||||
arguments = parser.parse_args()
|
||||
main(
|
||||
source_path=arguments.source_path,
|
||||
zone_configuration_path=arguments.zone_configuration_path,
|
||||
)
|
||||
@@ -0,0 +1,104 @@
|
||||
import argparse
|
||||
import os
|
||||
import subprocess
|
||||
import tempfile
|
||||
from glob import glob
|
||||
from threading import Thread
|
||||
|
||||
import yaml
|
||||
|
||||
SERVER_CONFIG = {"protocols": ["tcp"], "paths": {"all": {"source": "publisher"}}}
|
||||
BASE_STREAM_URL = "rtsp://localhost:8554/live"
|
||||
|
||||
|
||||
def main(video_directory: str, number_of_streams: int) -> None:
|
||||
video_files = find_video_files_in_directory(video_directory, number_of_streams)
|
||||
try:
|
||||
with tempfile.TemporaryDirectory() as temporary_directory:
|
||||
config_file_path = create_server_config_file(temporary_directory)
|
||||
run_rtsp_server(config_path=config_file_path)
|
||||
stream_videos(video_files)
|
||||
finally:
|
||||
stop_rtsp_server()
|
||||
|
||||
|
||||
def find_video_files_in_directory(directory: str, limit: int) -> list:
|
||||
video_formats = ["*.mp4", "*.webm"]
|
||||
video_paths = []
|
||||
for video_format in video_formats:
|
||||
video_paths.extend(glob(os.path.join(directory, video_format)))
|
||||
return video_paths[:limit]
|
||||
|
||||
|
||||
def create_server_config_file(directory: str) -> str:
|
||||
config_path = os.path.join(directory, "rtsp-simple-server.yml")
|
||||
with open(config_path, "w") as config_file:
|
||||
yaml.dump(SERVER_CONFIG, config_file)
|
||||
return config_path
|
||||
|
||||
|
||||
def run_rtsp_server(config_path: str) -> None:
|
||||
command = (
|
||||
"docker run --rm --name rtsp_server -d -v "
|
||||
f"{config_path}:/rtsp-simple-server.yml -p 8554:8554 "
|
||||
"aler9/rtsp-simple-server:v1.3.0"
|
||||
)
|
||||
if run_command(command.split()) != 0:
|
||||
raise RuntimeError("Could not start the RTSP server!")
|
||||
|
||||
|
||||
def stop_rtsp_server() -> None:
|
||||
run_command("docker kill rtsp_server".split())
|
||||
|
||||
|
||||
def stream_videos(video_files: list) -> None:
|
||||
threads = []
|
||||
for index, video_file in enumerate(video_files):
|
||||
stream_url = f"{BASE_STREAM_URL}{index}.stream"
|
||||
print(f"Streaming {video_file} under {stream_url}")
|
||||
thread = stream_video_to_url(video_file, stream_url)
|
||||
threads.append(thread)
|
||||
for thread in threads:
|
||||
thread.join()
|
||||
|
||||
|
||||
def stream_video_to_url(video_path: str, stream_url: str) -> Thread:
|
||||
command = (
|
||||
f"ffmpeg -re -stream_loop -1 -i {video_path} "
|
||||
f"-f rtsp -rtsp_transport tcp {stream_url}"
|
||||
)
|
||||
return run_command_in_thread(command.split())
|
||||
|
||||
|
||||
def run_command_in_thread(command: list) -> Thread:
|
||||
thread = Thread(target=run_command, args=(command,))
|
||||
thread.start()
|
||||
return thread
|
||||
|
||||
|
||||
def run_command(command: list) -> int:
|
||||
process = subprocess.run(command)
|
||||
return process.returncode
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Script to stream videos using RTSP protocol."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--video_directory",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Directory containing video files to stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--number_of_streams",
|
||||
type=int,
|
||||
default=6,
|
||||
help="Number of video files to stream.",
|
||||
)
|
||||
arguments = parser.parse_args()
|
||||
main(
|
||||
video_directory=arguments.video_directory,
|
||||
number_of_streams=arguments.number_of_streams,
|
||||
)
|
||||
@@ -0,0 +1,144 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import FPSBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
source_video_path: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(source_video_path)
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [FPSBasedTimer(video_info.fps) for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
results = model(frame, verbose=False, device=device, conf=confidence)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = detections.with_nms(threshold=iou)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using video file."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source video file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
source_video_path=args.source_video_path,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,154 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, get_stream_frames_generator, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url)
|
||||
fps_monitor = sv.FPSMonitor()
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [ClockBasedTimer() for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
fps_monitor.tick()
|
||||
fps = fps_monitor.fps
|
||||
|
||||
results = model(frame, verbose=False, device=device, conf=confidence)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = detections.with_nms(threshold=iou)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,173 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import InferencePipeline
|
||||
from inference.core.interfaces.camera.entities import VideoFrame
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
class CustomSink:
|
||||
def __init__(self, zone_configuration_path: str, classes: List[int]):
|
||||
self.classes = classes
|
||||
self.tracker = sv.ByteTrack(minimum_matching_threshold=0.8)
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
self.polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
self.timers = [ClockBasedTimer() for _ in self.polygons]
|
||||
self.zones = None
|
||||
|
||||
def on_prediction(self, detections: sv.Detections, frame: VideoFrame) -> None:
|
||||
if self.zones is None:
|
||||
resolution_wh = frame.image.shape[1], frame.image.shape[0]
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
self.fps_monitor.tick()
|
||||
fps = self.fps_monitor.fps
|
||||
|
||||
detections = detections[find_in_list(detections.class_id, self.classes)]
|
||||
detections = self.tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.image.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(self.zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = self.timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
cv2.waitKey(1)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
|
||||
def inference_callback(frame: VideoFrame) -> sv.Detections:
|
||||
results = model(frame.image, verbose=False, conf=confidence, device=device)[0]
|
||||
return sv.Detections.from_ultralytics(results).with_nms(threshold=iou)
|
||||
|
||||
sink = CustomSink(zone_configuration_path=zone_configuration_path, classes=classes)
|
||||
|
||||
pipeline = InferencePipeline.init_with_custom_logic(
|
||||
video_reference=rtsp_url,
|
||||
on_video_frame=inference_callback,
|
||||
on_prediction=sink.on_prediction,
|
||||
)
|
||||
|
||||
pipeline.start()
|
||||
|
||||
try:
|
||||
pipeline.join()
|
||||
except KeyboardInterrupt:
|
||||
pipeline.terminate()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user