Merge remote-tracking branch 'origin/develop' into develop
This commit is contained in:
 SkalskiP
commit
65ddf9d67d
|
|
@ -71,16 +71,15 @@ len(detections)
|
|||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(...)
|
||||
model = get_roboflow_model(model_id="yolov8s-640", api_key=<ROBOFLOW API KEY>)
|
||||
model = get_model(model_id="yolov8s-640", api_key=<ROBOFLOW API KEY>)
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
|
||||
len(detections)
|
||||
# 5
|
||||
|
||||
# 5
|
||||
```
|
||||
|
||||
</details>
|
||||
|
|
|
|||
|
|
@ -19,13 +19,13 @@ as an extra within the Supervision package.
|
|||
```
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>download_assets</h2>
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.download_assets">download_assets</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.downloader.download_assets
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoAssets</h2>
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.VideoAssets">VideoAssets</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.list.VideoAssets
|
||||
|
|
|
|||
|
|
@ -12,7 +12,7 @@ These features are phased out due to better alternatives or potential issues in
|
|||
- The method `Color.green()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.GREEN` instead.
|
||||
- The method `Color.blue()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.BLUE` instead.
|
||||
- The method [`ColorPalette.default()`](draw/color.md/#supervision.draw.color.ColorPalette.default) is deprecated and will be removed in `supervision-0.22.0`. Use the constant [`ColorPalette.DEFAULT`](draw/color.md/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
- `BoxAnnotator` is deprecated and will be removed in `supervision-0.22.0`. Use [`BoundingBoxAnnotator`](annotators.md/#supervision.annotators.core.BoundingBoxAnnotator) and [`LabelAnnotator`](annotators.md/#supervision.annotators.core.LabelAnnotator) instead.
|
||||
- `BoxAnnotator` is deprecated and will be removed in `supervision-0.22.0`. Use [`BoundingBoxAnnotator`](detection/annotators.md/#supervision.annotators.core.BoundingBoxAnnotator) and [`LabelAnnotator`](detection/annotators.md/#supervision.annotators.core.LabelAnnotator) instead.
|
||||
- The method [`FPSMonitor.__call__`](utils/video.md/#supervision.utils.video.FPSMonitor.__call__) is deprecated and will be removed in `supervision-0.22.0`. Use the attribute [`FPSMonitor.fps`](utils/video.md/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
- The `track_buffer`, `track_thresh`, and `match_thresh` parameters in [`ByterTrack`](trackers.md/#supervision.tracker.byte_tracker.core.ByteTrack) are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
- The `triggering_position ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) is deprecated and will be removed in `supervision-0.23.0`. Use `triggering_anchors ` instead.
|
||||
|
|
|
|||
|
|
@ -0,0 +1,17 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Metrics
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
|
|
@ -6,67 +6,67 @@ status: new
|
|||
# Detection Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_iou_batch</h2>
|
||||
<h2><a href="#supervision.detection.utils.box_iou_batch">box_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_iou_batch</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_iou_batch">mask_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_non_max_suppression</h2>
|
||||
<h2><a href="#supervision.detection.utils.box_non_max_suppression">box_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_non_max_suppression</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_non_max_suppression">mask_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_mask</h2>
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_mask">polygon_to_mask</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_mask
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_xyxy</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_to_xyxy">mask_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_polygons</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_to_polygons">mask_to_polygons</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_polygons
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_xyxy</h2>
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_xyxy">polygon_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>filter_polygons_by_area</h2>
|
||||
<h2><a href="#supervision.detection.utils.filter_polygons_by_area">filter_polygons_by_area</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.filter_polygons_by_area
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>move_boxes</h2>
|
||||
<h2><a href="#supervision.detection.utils.move_boxes">move_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>scale_boxes</h2>
|
||||
<h2><a href="#supervision.detection.utils.scale_boxes">scale_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.scale_boxes
|
||||
|
|
|
|||
|
|
@ -1,13 +0,0 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Color
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ColorPalette</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
|
|
@ -1,53 +0,0 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_line</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_filled_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_polygon</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_text</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_optimal_font_scale</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_optimal_line_thickness</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_line_thickness
|
||||
|
|
@ -1,7 +0,0 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Position
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
|
|
@ -27,7 +27,7 @@ model.
|
|||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
```
|
||||
|
||||
|
|
@ -38,7 +38,7 @@ model.
|
|||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
```
|
||||
|
||||
|
|
@ -52,7 +52,7 @@ model.
|
|||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_APTH>)
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
|
|
@ -78,7 +78,7 @@ Now that we have predictions from a model, we can load them into Supervision.
|
|||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
|
@ -93,7 +93,7 @@ Now that we have predictions from a model, we can load them into Supervision.
|
|||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
|
@ -111,7 +111,7 @@ Now that we have predictions from a model, we can load them into Supervision.
|
|||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_APTH>)
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
|
|
@ -146,7 +146,7 @@ Finally, we can annotate the image with the predictions. Since we are working wi
|
|||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
|
|
@ -167,7 +167,7 @@ Finally, we can annotate the image with the predictions. Since we are working wi
|
|||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_APTH>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
|
|
@ -191,7 +191,7 @@ Finally, we can annotate the image with the predictions. Since we are working wi
|
|||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_APTH>)
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
|
|
@ -230,7 +230,7 @@ override this behavior by passing a list of custom `labels` to the `annotate` me
|
|||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
|
|
@ -257,7 +257,7 @@ override this behavior by passing a list of custom `labels` to the `annotate` me
|
|||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
|
|
@ -287,7 +287,7 @@ override this behavior by passing a list of custom `labels` to the `annotate` me
|
|||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<PATH TO IMAGE>)
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
|
|
@ -334,7 +334,7 @@ that will allow you to draw masks instead of boxes.
|
|||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-seg-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
|
|
@ -355,7 +355,7 @@ that will allow you to draw masks instead of boxes.
|
|||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n-seg.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
|
|
|
|||
|
|
@ -28,7 +28,7 @@ size relative to the image resolution.
|
|||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
|
|
@ -49,7 +49,7 @@ size relative to the image resolution.
|
|||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
|
|
@ -73,7 +73,7 @@ size relative to the image resolution.
|
|||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<PATH TO IMAGE>)
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
|
|
@ -116,7 +116,7 @@ is less effective for ultra-high-resolution images (4K and above).
|
|||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-1280")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
|
|
@ -137,7 +137,7 @@ is less effective for ultra-high-resolution images (4K and above).
|
|||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image, imgsz=1280)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
|
|
@ -171,7 +171,7 @@ objects within each, and aggregating the results.
|
|||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
|
|
@ -198,7 +198,7 @@ objects within each, and aggregating the results.
|
|||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
result = model(image_slice)[0]
|
||||
|
|
@ -229,7 +229,7 @@ objects within each, and aggregating the results.
|
|||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
image_slice = cv2.cvtColor(image_slice, cv2.COLOR_BGR2RGB)
|
||||
|
|
|
|||
|
|
@ -1,10 +0,0 @@
|
|||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotate
|
||||
|
||||
:::supervision.keypoint.annotate.VertexAnnotator
|
||||
|
||||
:::supervision.keypoint.annotate.EdgeAnnotator
|
||||
|
|
@ -0,0 +1,60 @@
|
|||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
=== "VertexAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_annotator = sv.VertexAnnotator(color=sv.Color.GREEN, radius=10)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
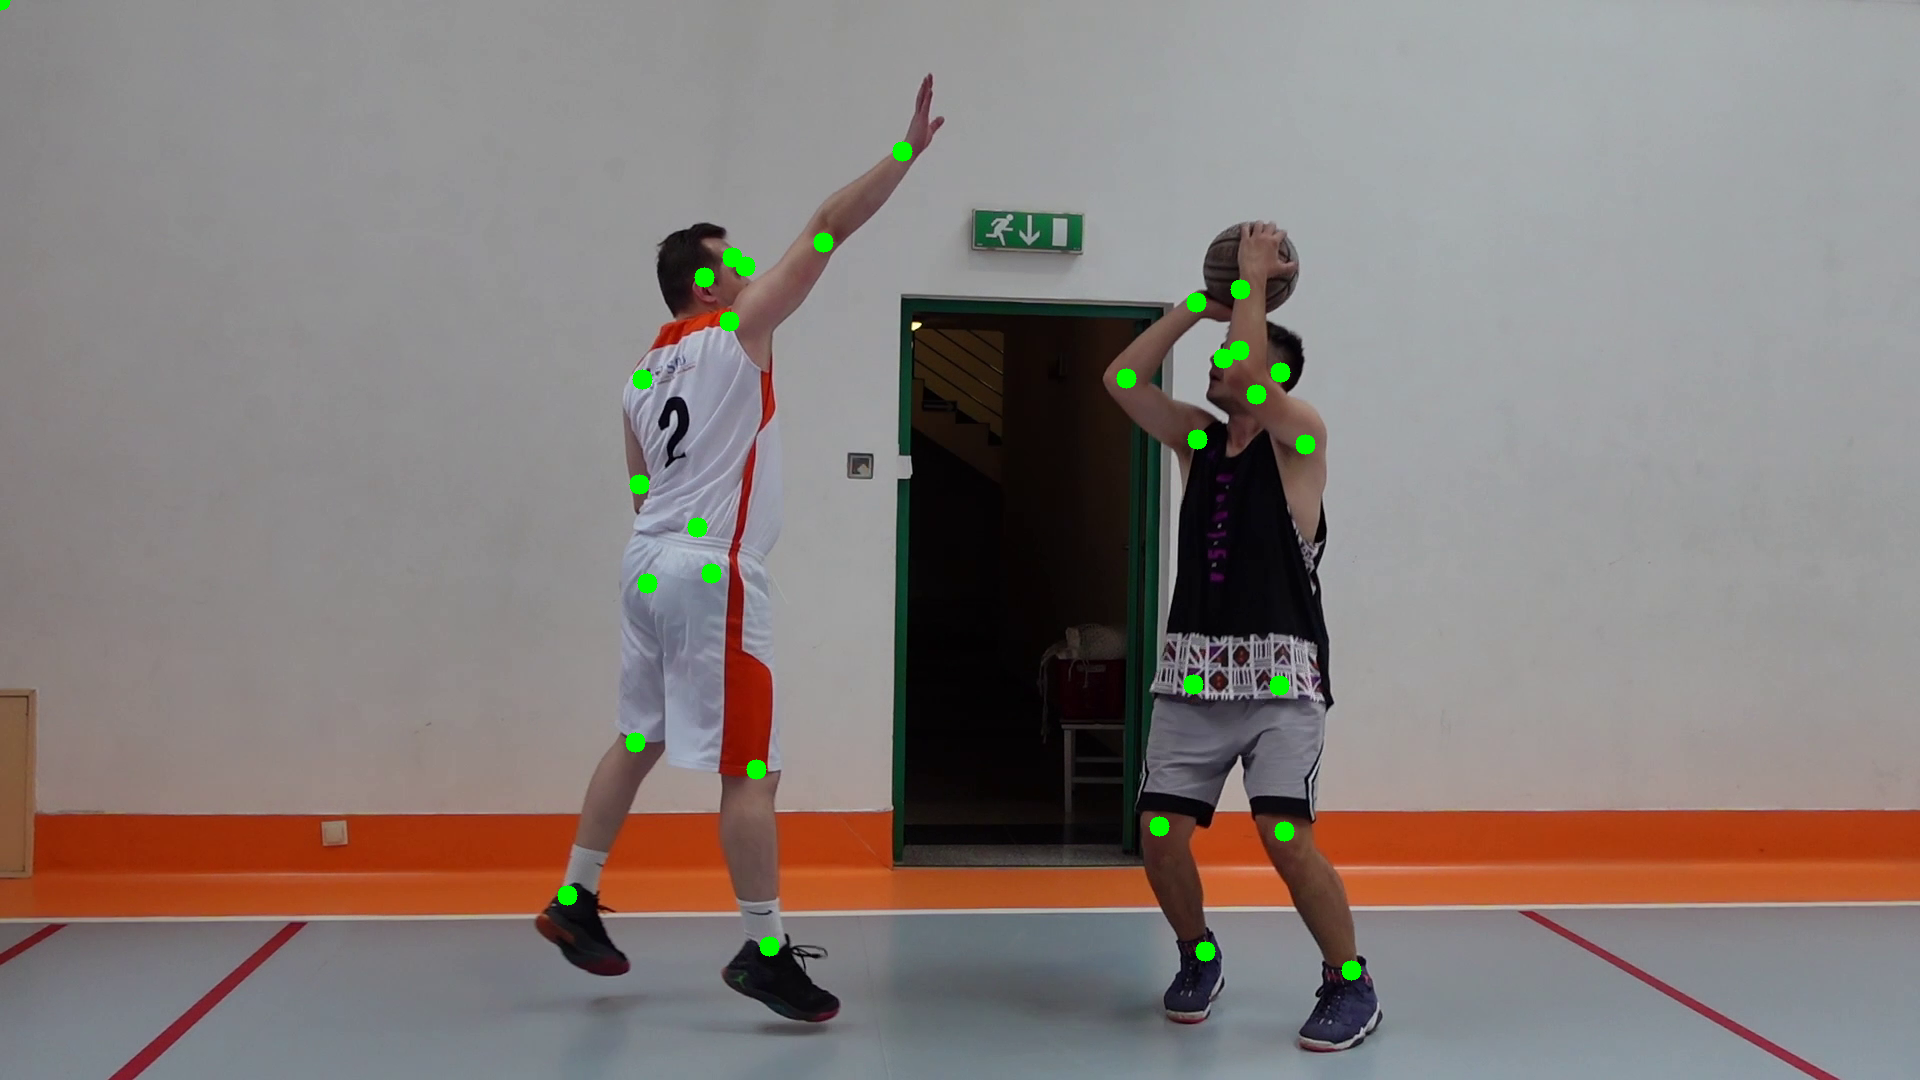{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "EdgeAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
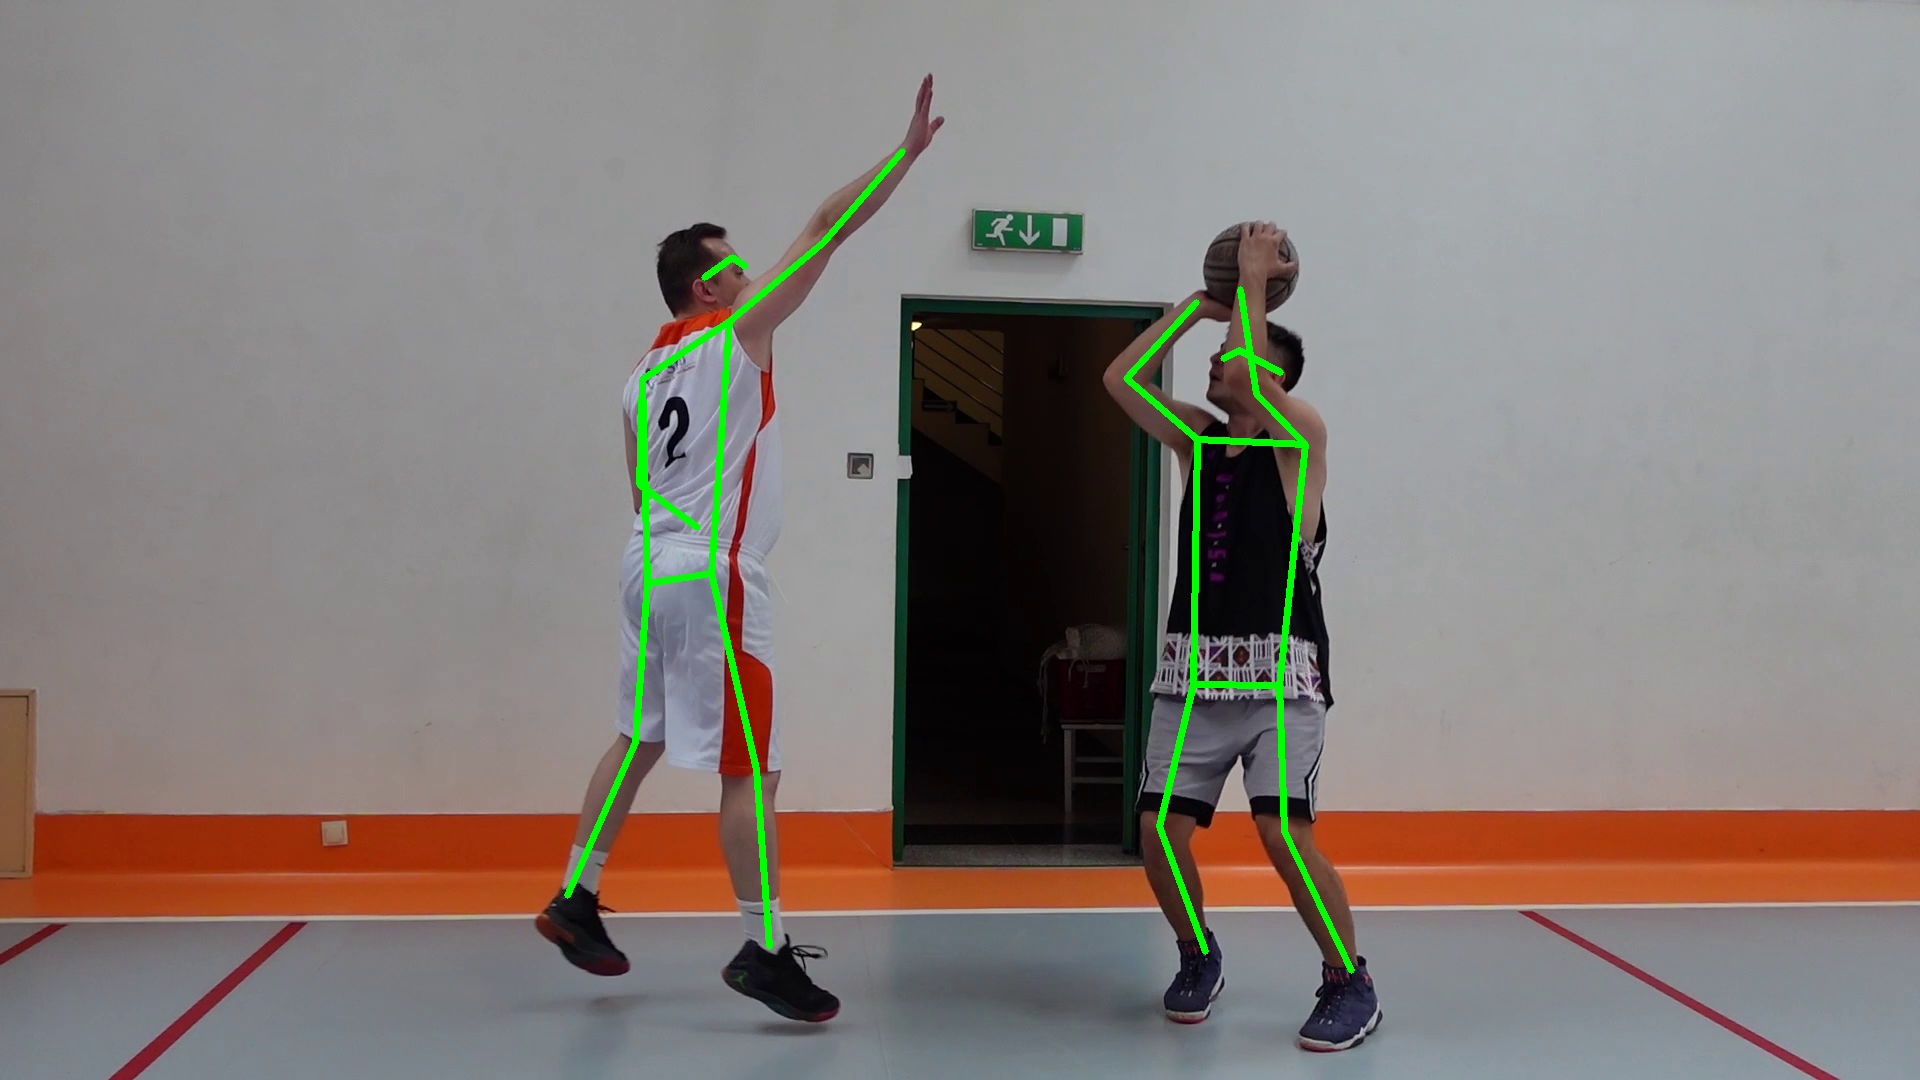{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.VertexAnnotator">VertexAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.VertexAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.EdgeAnnotator">EdgeAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.EdgeAnnotator
|
||||
|
|
@ -1,22 +0,0 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Detection Metrics
|
||||
|
||||
!!! warning
|
||||
|
||||
Evaluation API is still fluid and may change. If you use Evaluation API in your project until further notice, freeze the
|
||||
`supervision` version in your `requirements.txt` or `setup.py`.
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
|
|
@ -0,0 +1,65 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_line">draw_line</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_rectangle">draw_rectangle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_filled_rectangle">draw_filled_rectangle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_polygon">draw_polygon</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_text">draw_text</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_image">draw_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_font_scale">calculate_optimal_font_scale</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_line_thickness">calculate_optimal_line_thickness</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_line_thickness
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.color.Color">Color</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.color.ColorPalette">ColorPalette</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
|
|
@ -5,7 +5,7 @@ comments: true
|
|||
# File Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>list_files_with_extensions</h2>
|
||||
<h2><a href="#supervision.utils.file.list_files_with_extensions">list_files_with_extensions</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.file.list_files_with_extensions
|
||||
|
|
|
|||
|
|
@ -0,0 +1,9 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.geometry.core.Position">Position</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
|
|
@ -6,37 +6,37 @@ status: new
|
|||
# Image Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>crop_image</h2>
|
||||
<h2><a href="#supervision.utils.image.crop_image">crop_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.crop_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>scale_image</h2>
|
||||
<h2><a href="#supervision.utils.image.scale_image">crop_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.scale_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>resize_image</h2>
|
||||
<h2><a href="#supervision.utils.image.resize_image">resize_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.resize_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>letterbox_image</h2>
|
||||
<h2><a href="#supervision.utils.image.letterbox_image">letterbox_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.letterbox_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>overlay_image</h2>
|
||||
<h2><a href="#supervision.utils.image.overlay_image">overlay_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.overlay_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ImageSink</h2>
|
||||
<h2><a href="#supervision.utils.image.ImageSink">ImageSink</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
|
|
|||
|
|
@ -6,13 +6,13 @@ status: new
|
|||
# Iterables Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>create_batches</h2>
|
||||
<h2><a href="#supervision.utils.iterables.create_batches">create_batches</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.create_batches
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>fill</h2>
|
||||
<h2><a href="#supervision.utils.iterables.fill">fill</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.fill
|
||||
|
|
|
|||
|
|
@ -5,14 +5,13 @@ comments: true
|
|||
# Notebooks Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>plot_image</h2>
|
||||
<h2><a href="#supervision.utils.notebook.plot_image">plot_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>plot_images_grid
|
||||
</h2>
|
||||
<h2><a href="#supervision.utils.notebook.plot_images_grid">plot_images_grid</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_images_grid
|
||||
|
|
|
|||
|
|
@ -5,31 +5,31 @@ comments: true
|
|||
# Video Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoInfo</h2>
|
||||
<h2><a href="#supervision.utils.video.VideoInfo">VideoInfo</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoInfo
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoSink</h2>
|
||||
<h2><a href="#supervision.utils.video.VideoSink">VideoSink</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>FPSMonitor</h2>
|
||||
<h2><a href="#supervision.utils.video.FPSMonitor">FPSMonitor</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.FPSMonitor
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>get_video_frames_generator</h2>
|
||||
<h2><a href="#supervision.utils.video.get_video_frames_generator">get_video_frames_generator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.get_video_frames_generator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>process_video</h2>
|
||||
<h2><a href="#supervision.utils.video.process_video">process_video</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.process_video
|
||||
|
|
|
|||
22
mkdocs.yml
22
mkdocs.yml
|
|
@ -44,15 +44,16 @@ nav:
|
|||
- Track Objects: how_to/track_objects.md
|
||||
|
||||
- API:
|
||||
- Annotators: annotators.md
|
||||
- Classifications:
|
||||
- Core: classification/core.md
|
||||
- Detections:
|
||||
- Detection and Segmentation:
|
||||
- Core: detection/core.md
|
||||
- Annotators: detection/annotators.md
|
||||
- Metrics: detection/metrics.md
|
||||
- Utils: detection/utils.md
|
||||
- KeyPoints:
|
||||
- Keypoint Detection:
|
||||
- Core: keypoint/core.md
|
||||
- Annotators: keypoint/annotate.md
|
||||
- Annotators: keypoint/annotators.md
|
||||
- Classification:
|
||||
- Core: classification/core.md
|
||||
- Tools:
|
||||
- Line Zone: detection/tools/line_zone.md
|
||||
- Polygon Zone: detection/tools/polygon_zone.md
|
||||
|
|
@ -61,19 +62,14 @@ nav:
|
|||
- Save Detections: detection/tools/save_detections.md
|
||||
- Trackers: trackers.md
|
||||
- Datasets: datasets.md
|
||||
- Metrics:
|
||||
- Object Detection: metrics/detection.md
|
||||
- Draw:
|
||||
- Color: draw/color.md
|
||||
- Utils: draw/utils.md
|
||||
- Geometry:
|
||||
- Position: geometry/core.md
|
||||
- Utils:
|
||||
- Video: utils/video.md
|
||||
- Image: utils/image.md
|
||||
- Iterables: utils/iterables.md
|
||||
- Notebook: utils/notebook.md
|
||||
- File: utils/file.md
|
||||
- Draw: utils/draw.md
|
||||
- Geometry: utils/geometry.md
|
||||
- Assets: assets.md
|
||||
- Cookbooks: cookbooks.md
|
||||
- Contribute:
|
||||
|
|
|
|||
|
|
@ -69,7 +69,7 @@ from supervision.draw.utils import (
|
|||
)
|
||||
from supervision.geometry.core import Point, Position, Rect
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.keypoint.annotate import EdgeAnnotator, VertexAnnotator
|
||||
from supervision.keypoint.annotators import EdgeAnnotator, VertexAnnotator
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.metrics.detection import ConfusionMatrix, MeanAveragePrecision
|
||||
from supervision.tracker.byte_tracker.core import ByteTrack
|
||||
|
|
|
|||
|
|
@ -19,6 +19,7 @@ class VideoAssets(Enum):
|
|||
| `MARKET_SQUARE` | `market-square.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/market-square.mp4) |
|
||||
| `PEOPLE_WALKING` | `people-walking.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/people-walking.mp4) |
|
||||
| `BEACH` | `beach-1.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/beach-1.mp4) |
|
||||
| `BASKETBALL` | `basketball-1.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/basketball-1.mp4) |
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
VEHICLES = "vehicles.mp4"
|
||||
|
|
@ -29,6 +30,7 @@ class VideoAssets(Enum):
|
|||
MARKET_SQUARE = "market-square.mp4"
|
||||
PEOPLE_WALKING = "people-walking.mp4"
|
||||
BEACH = "beach-1.mp4"
|
||||
BASKETBALL = "basketball-1.mp4"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
|
|
@ -68,4 +70,8 @@ VIDEO_ASSETS: Dict[str, Tuple[str, str]] = {
|
|||
f"{BASE_VIDEO_URL}{VideoAssets.BEACH.value}",
|
||||
"4175d42fec4d450ed081523fd39e0cf8",
|
||||
),
|
||||
VideoAssets.BASKETBALL.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.BASKETBALL.value}",
|
||||
"60d94a3c7c47d16f09d342b088012ecc",
|
||||
),
|
||||
}
|
||||
|
|
|
|||
|
|
@ -27,34 +27,71 @@ from supervision.validators import validate_detections_fields
|
|||
@dataclass
|
||||
class Detections:
|
||||
"""
|
||||
The `sv.Detections` allows you to convert results from a variety of object detection
|
||||
and segmentation models into a single, unified format. The `sv.Detections` class
|
||||
enables easy data manipulation and filtering, and provides a consistent API for
|
||||
Supervision's tools like trackers, annotators, and zones.
|
||||
The `sv.Detections` class in the Supervision library standardizes results from
|
||||
various object detection and segmentation models into a consistent format. This
|
||||
class simplifies data manipulation and filtering, providing a uniform API for
|
||||
integration with Supervision [trackers](/trackers/), [annotators](/detection/annotators/), and [tools](/detection/tools/line_zone/).
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
=== "Inference"
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
annotator = sv.BoundingBoxAnnotator()
|
||||
Use [`sv.Detections.from_inference`](/detection/core/#supervision.detection.core.Detections.from_inference)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
annotated_image = annotator.annotate(image, detections)
|
||||
```
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
=== "Ultralytics"
|
||||
|
||||
In `sv.Detections`, detection data is categorized into two main field types:
|
||||
fixed and custom. The fixed fields include `xyxy`, `mask`, `confidence`,
|
||||
`class_id`, and `tracker_id`. For any additional data requirements, custom
|
||||
fields come into play, stored in the data field. These custom fields are easily
|
||||
accessible using the `detections[<FIELD_NAME>]` syntax, providing flexibility
|
||||
for diverse data handling needs.
|
||||
Use [`sv.Detections.from_ultralytics`](/detection/core/#supervision.detection.core.Detections.from_ultralytics)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
Use [`sv.Detections.from_transformers`](/detection/core/#supervision.detection.core.Detections.from_transformers)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
```
|
||||
|
||||
Attributes:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
|
|
@ -70,15 +107,7 @@ class Detections:
|
|||
data (Dict[str, Union[np.ndarray, List]]): A dictionary containing additional
|
||||
data where each key is a string representing the data type, and the value
|
||||
is either a NumPy array or a list of corresponding data.
|
||||
|
||||
!!! warning
|
||||
|
||||
The `data` field in the `sv.Detections` class is currently in an experimental
|
||||
phase. Please be aware that its API and functionality are subject to change in
|
||||
future updates as we continue to refine and improve its capabilities.
|
||||
We encourage users to experiment with this feature and provide feedback, but
|
||||
also to be prepared for potential modifications in upcoming releases.
|
||||
"""
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
xyxy: np.ndarray
|
||||
mask: Optional[np.ndarray] = None
|
||||
|
|
@ -177,8 +206,8 @@ class Detections:
|
|||
@classmethod
|
||||
def from_ultralytics(cls, ultralytics_results) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
Creates a `sv.Detections` instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
|
||||
!!! Note
|
||||
|
||||
|
|
@ -202,10 +231,13 @@ class Detections:
|
|||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
if "obb" in ultralytics_results and ultralytics_results.obb is not None:
|
||||
|
|
@ -396,11 +428,6 @@ class Detections:
|
|||
Creates a Detections instance from object detection or segmentation
|
||||
[Transformer](https://github.com/huggingface/transformers) inference result.
|
||||
|
||||
!!! note
|
||||
|
||||
Class names can be accessed using the key `class_name` in the returned
|
||||
object's data attribute.
|
||||
|
||||
Args:
|
||||
transformers_results (dict): The output of Transformers model inference. A
|
||||
dictionary containing the `scores`, `labels`, `boxes` and `masks` keys.
|
||||
|
|
@ -437,6 +464,10 @@ class Detections:
|
|||
id2label=model.config.id2label
|
||||
)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
class_ids = transformers_results["labels"].cpu().detach().numpy().astype(int)
|
||||
|
|
@ -510,17 +541,12 @@ class Detections:
|
|||
@classmethod
|
||||
def from_inference(cls, roboflow_result: Union[dict, Any]) -> Detections:
|
||||
"""
|
||||
Create a Detections object from the [Roboflow](https://roboflow.com/)
|
||||
Create a `sv.Detections` object from the [Roboflow](https://roboflow.com/)
|
||||
API inference result or the [Inference](https://inference.roboflow.com/)
|
||||
package results. This method extracts bounding boxes, class IDs,
|
||||
confidences, and class names from the Roboflow API result and encapsulates
|
||||
them into a Detections object.
|
||||
|
||||
!!! note
|
||||
|
||||
Class names can be accessed using the key `class_name` in the returned
|
||||
object's data attribute.
|
||||
|
||||
Args:
|
||||
roboflow_result (dict, any): The result from the
|
||||
Roboflow API or Inference package containing predictions.
|
||||
|
|
@ -533,14 +559,18 @@ class Detections:
|
|||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_roboflow_model(model_id="yolov8s-640")
|
||||
model = get_model(model_id="yolov8s-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
"""
|
||||
with suppress(AttributeError):
|
||||
roboflow_result = roboflow_result.dict(exclude_none=True, by_alias=True)
|
||||
|
|
@ -590,10 +620,10 @@ class Detections:
|
|||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_roboflow_model(model_id="yolov8s-640")
|
||||
model = get_model(model_id="yolov8s-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_roboflow(result)
|
||||
|
|
|
|||
|
|
@ -1,104 +0,0 @@
|
|||
from abc import ABC, abstractmethod
|
||||
from logging import warn
|
||||
from typing import List, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.color import Color
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.keypoint.skeletons import SKELETONS_BY_VERTEX_COUNT
|
||||
from supervision.utils.conversion import convert_for_annotation_method
|
||||
|
||||
|
||||
class BaseKeyPointAnnotator(ABC):
|
||||
@abstractmethod
|
||||
def annotate(self, scene: ImageType, detections: KeyPoints) -> ImageType:
|
||||
pass
|
||||
|
||||
|
||||
class VertexAnnotator(BaseKeyPointAnnotator):
|
||||
def __init__(
|
||||
self,
|
||||
color: Color = Color.ROBOFLOW,
|
||||
radius: int = 4,
|
||||
) -> None:
|
||||
"""
|
||||
Most basic keypoint annotator.
|
||||
|
||||
Args:
|
||||
color (Color, optional): The color of the keypoint.
|
||||
radius (int, optional): The radius of the keypoint.
|
||||
"""
|
||||
self.color = color
|
||||
self.radius = radius
|
||||
|
||||
@convert_for_annotation_method
|
||||
def annotate(self, scene: ImageType, keypoints: KeyPoints) -> ImageType:
|
||||
if len(keypoints) == 0:
|
||||
return scene
|
||||
|
||||
for xy in keypoints.xy:
|
||||
for x, y in xy:
|
||||
cv2.circle(
|
||||
img=scene,
|
||||
center=(int(x), int(y)),
|
||||
radius=self.radius,
|
||||
color=self.color.as_bgr(),
|
||||
thickness=-1,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
def __init__(
|
||||
self,
|
||||
color: Color = Color.ROBOFLOW,
|
||||
thickness: int = 2,
|
||||
edges: Optional[List[Tuple[int, int]]] = None,
|
||||
) -> None:
|
||||
"""
|
||||
Draw the lines between points of the image.
|
||||
|
||||
Args:
|
||||
color (Color, optional): The color of the lines.
|
||||
thickness (int, optional): The thickness of the lines.
|
||||
edge (Optional[List[Tuple[int, int]]]): The edges to draw.
|
||||
If set to `None`, will attempt to select automatically.
|
||||
"""
|
||||
self.color = color
|
||||
self.thickness = thickness
|
||||
self.edges = edges
|
||||
|
||||
@convert_for_annotation_method
|
||||
def annotate(self, scene: ImageType, keypoints: KeyPoints) -> ImageType:
|
||||
if len(keypoints) == 0:
|
||||
return scene
|
||||
|
||||
for xy in keypoints.xy:
|
||||
edges = self.edges
|
||||
if not edges:
|
||||
edges = SKELETONS_BY_VERTEX_COUNT.get(len(xy))
|
||||
if not edges:
|
||||
warn(f"No skeleton found with {len(xy)} vertices")
|
||||
return scene
|
||||
|
||||
for class_a, class_b in edges:
|
||||
xy_a = xy[class_a - 1]
|
||||
xy_b = xy[class_b - 1]
|
||||
missing_a = np.allclose(xy_a, 0)
|
||||
missing_b = np.allclose(xy_b, 0)
|
||||
if missing_a or missing_b:
|
||||
continue
|
||||
|
||||
cv2.line(
|
||||
img=scene,
|
||||
pt1=(int(xy_a[0]), int(xy_a[1])),
|
||||
pt2=(int(xy_b[0]), int(xy_b[1])),
|
||||
color=self.color.as_bgr(),
|
||||
thickness=self.thickness,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
|
@ -0,0 +1,177 @@
|
|||
from abc import ABC, abstractmethod
|
||||
from logging import warn
|
||||
from typing import List, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.color import Color
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.keypoint.skeletons import SKELETONS_BY_VERTEX_COUNT
|
||||
from supervision.utils.conversion import convert_for_annotation_method
|
||||
|
||||
|
||||
class BaseKeyPointAnnotator(ABC):
|
||||
@abstractmethod
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
pass
|
||||
|
||||
|
||||
class VertexAnnotator(BaseKeyPointAnnotator):
|
||||
"""
|
||||
A class that specializes in drawing skeleton vertices on images. It uses
|
||||
specified key points to determine the locations where the vertices should be
|
||||
drawn.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Color = Color.ROBOFLOW,
|
||||
radius: int = 4,
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
color (Color, optional): The color to use for annotating key points.
|
||||
radius (int, optional): The radius of the circles used to represent the key
|
||||
points.
|
||||
"""
|
||||
self.color = color
|
||||
self.radius = radius
|
||||
|
||||
@convert_for_annotation_method
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene with skeleton vertices based on the provided key
|
||||
points. It draws circles at each key point location.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where bounding boxes will be drawn. `ImageType`
|
||||
is a flexible type, accepting either `numpy.ndarray` or
|
||||
`PIL.Image.Image`.
|
||||
key_points (KeyPoints): A collection of key points where each key point
|
||||
consists of x and y coordinates.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_annotator = sv.VertexAnnotator(color=sv.Color.GREEN, radius=10)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
for xy in key_points.xy:
|
||||
for x, y in xy:
|
||||
cv2.circle(
|
||||
img=scene,
|
||||
center=(int(x), int(y)),
|
||||
radius=self.radius,
|
||||
color=self.color.as_bgr(),
|
||||
thickness=-1,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
"""
|
||||
A class that specializes in drawing skeleton edges on images using specified key
|
||||
points. It connects key points with lines to form the skeleton structure.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Color = Color.ROBOFLOW,
|
||||
thickness: int = 2,
|
||||
edges: Optional[List[Tuple[int, int]]] = None,
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
color (Color, optional): The color to use for the edges.
|
||||
thickness (int, optional): The thickness of the edges.
|
||||
edges (Optional[List[Tuple[int, int]]]): The edges to draw.
|
||||
If set to `None`, will attempt to select automatically.
|
||||
"""
|
||||
self.color = color
|
||||
self.thickness = thickness
|
||||
self.edges = edges
|
||||
|
||||
@convert_for_annotation_method
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene by drawing lines between specified key points to form
|
||||
edges.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where bounding boxes will be drawn. `ImageType`
|
||||
is a flexible type, accepting either `numpy.ndarray` or
|
||||
`PIL.Image.Image`.
|
||||
key_points (KeyPoints): A collection of key points where each key point
|
||||
consists of x and y coordinates.
|
||||
|
||||
Returns:
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
for xy in key_points.xy:
|
||||
edges = self.edges
|
||||
if not edges:
|
||||
edges = SKELETONS_BY_VERTEX_COUNT.get(len(xy))
|
||||
if not edges:
|
||||
warn(f"No skeleton found with {len(xy)} vertices")
|
||||
return scene
|
||||
|
||||
for class_a, class_b in edges:
|
||||
xy_a = xy[class_a - 1]
|
||||
xy_b = xy[class_b - 1]
|
||||
missing_a = np.allclose(xy_a, 0)
|
||||
missing_b = np.allclose(xy_b, 0)
|
||||
if missing_a or missing_b:
|
||||
continue
|
||||
|
||||
cv2.line(
|
||||
img=scene,
|
||||
pt1=(int(xy_a[0]), int(xy_a[1])),
|
||||
pt2=(int(xy_b[0]), int(xy_b[1])),
|
||||
color=self.color.as_bgr(),
|
||||
thickness=self.thickness,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
|
@ -14,28 +14,26 @@ from supervision.validators import validate_keypoints_fields
|
|||
@dataclass
|
||||
class KeyPoints:
|
||||
"""
|
||||
The `sv.KeyPoints` allows you to convert results from a variety of keypoint
|
||||
keypoints models into a single, unified format.
|
||||
The `sv.KeyPoints` class in the Supervision library standardizes results from
|
||||
various keypoint detection and pose estimation models into a consistent format. This
|
||||
class simplifies data manipulation and filtering, providing a uniform API for
|
||||
integration with Supervision annotators.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
=== "Ultralytics"
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s-pose.pt')
|
||||
result = model(image)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
```
|
||||
Use [`sv.KeyPoints.from_ultralytics`](/keypoint/core/#supervision.keypoint.core.KeyPoints.from_ultralytics)
|
||||
method, which accepts model results.
|
||||
|
||||
!!! tip
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
In `sv.KeyPoints`, detection data is categorized into two main field types:
|
||||
fixed and custom. The fixed fields include `xy`, `confidence`,
|
||||
`class_id`. For any additional data requirements, custom
|
||||
fields come into play, stored in the data field. These custom fields are easily
|
||||
accessible using the `keypoints[<FIELD_NAME>]` syntax, providing flexibility
|
||||
for diverse data handling needs.
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s-pose.pt')
|
||||
result = model(image)[0]
|
||||
key_points = sv.KeyPoints.from_ultralytics(result)
|
||||
```
|
||||
|
||||
Attributes:
|
||||
xy (np.ndarray): An array of shape `(n, 2)` containing
|
||||
|
|
@ -47,15 +45,7 @@ class KeyPoints:
|
|||
data (Dict[str, Union[np.ndarray, List]]): A dictionary containing additional
|
||||
data where each key is a string representing the data type, and the value
|
||||
is either a NumPy array or a list of corresponding data.
|
||||
|
||||
!!! warning
|
||||
|
||||
The `data` field in the `sv.KeyPoints` class is currently in an experimental
|
||||
phase. Please be aware that its API and functionality are subject to change in
|
||||
future updates as we continue to refine and improve its capabilities.
|
||||
We encourage users to experiment with this feature and provide feedback, but
|
||||
also to be prepared for potential modifications in upcoming releases.
|
||||
"""
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
xy: npt.NDArray[np.float32]
|
||||
class_id: Optional[npt.NDArray[np.int_]] = None
|
||||
|
|
@ -263,7 +253,7 @@ class KeyPoints:
|
|||
Create an empty Keypoints object with no keypoints.
|
||||
|
||||
Returns:
|
||||
(Keypoints): An empty Keypoints object.
|
||||
(KeyPoints): An empty Keypoints object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
|
|
|
|||
Loading…
Reference in New Issue