Merge pull request #1127 from roboflow/develop
`supervision-0.20.0` release
 Piotr Skalski
 GitHub
|
|
@ -4,12 +4,18 @@ on:
|
|||
push:
|
||||
branches:
|
||||
- develop
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event_name == 'push' && github.ref}}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
pull-requests: write
|
||||
|
||||
|
||||
jobs:
|
||||
deploy:
|
||||
runs-on: ubuntu-latest
|
||||
|
|
@ -23,7 +29,7 @@ jobs:
|
|||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material[all]"
|
||||
run: pip install "mkdocs-material"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
|
|
@ -0,0 +1,55 @@
|
|||
name: Supervision Release Documentation Workflow 📚
|
||||
on:
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event_name == 'push' && github.ref}}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
pull-requests: write
|
||||
|
||||
|
||||
jobs:
|
||||
doc-build-deploy:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
fetch-depth: 0
|
||||
ref: ${{ github.head_ref }}
|
||||
|
||||
- name: 🐍 Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
run: pip install "mkdocs-material[imaging]"
|
||||
- name: 📦 Install mike
|
||||
run: pip install "mike"
|
||||
- name: 📦 Install mkdocs-git-revision-date-localized-plugin
|
||||
run: pip install "mkdocs-git-revision-date-localized-plugin"
|
||||
- name: 📦 Install JupyterLab
|
||||
run: pip install jupyterlab
|
||||
- name: 📦 Install mkdocs-jupyter
|
||||
run: pip install mkdocs-jupyter
|
||||
- name: 📦 Install mkdocs-git-committers-plugin-2
|
||||
run: pip install mkdocs-git-committers-plugin-2
|
||||
- name: ⚙️ Configure git for github-actions 👷
|
||||
run: |
|
||||
git config --global user.name "github-actions[bot]"
|
||||
git config --global user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
- name: 🚀 Deploy MkDoc-Material 📚
|
||||
run: |
|
||||
latest_tag=$(git describe --tags `git rev-list --tags --max-count=1`)
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY=${{ secrets.GITHUB_TOKEN }} mike deploy --push --update-aliases $latest_tag latest
|
||||
|
|
@ -6,22 +6,24 @@ on:
|
|||
- '[0-9]+.[0-9]+[0-9]+.[0-9]+b[0-9]'
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]+rc[0-9]'
|
||||
|
||||
# Allows you to run this workflow manually from the Actions tab
|
||||
workflow_dispatch:
|
||||
|
||||
jobs:
|
||||
build-n-publish:
|
||||
name: Build and publish to PyPI
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: Checkout source
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: 🐍 Set up Python 3.8 environment for build
|
||||
with:
|
||||
ref: ${{ github.head_ref }}
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: "3.8"
|
||||
python-version: ${{ matrix.python-version }}
|
||||
|
||||
- name: 🏗️ Build source and wheel distributions
|
||||
run: |
|
||||
|
|
|
|||
|
|
@ -4,7 +4,6 @@ on:
|
|||
tags:
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]'
|
||||
|
||||
# Allows you to run this workflow manually from the Actions tab
|
||||
workflow_dispatch:
|
||||
|
||||
jobs:
|
||||
|
|
@ -12,7 +11,7 @@ jobs:
|
|||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: [3.8]
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
|
|
|
|||
|
|
@ -7,7 +7,7 @@ ci:
|
|||
|
||||
repos:
|
||||
- repo: https://github.com/pre-commit/pre-commit-hooks
|
||||
rev: v4.5.0
|
||||
rev: v4.6.0
|
||||
hooks:
|
||||
- id: end-of-file-fixer
|
||||
- id: trailing-whitespace
|
||||
|
|
@ -27,7 +27,6 @@ repos:
|
|||
- id: mixed-line-ending
|
||||
|
||||
|
||||
|
||||
- repo: https://github.com/PyCQA/bandit
|
||||
rev: '1.7.8'
|
||||
hooks:
|
||||
|
|
@ -46,7 +45,7 @@ repos:
|
|||
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.3.2
|
||||
rev: v0.4.1
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
|
|
|
|||
39
README.md
|
|
@ -18,10 +18,10 @@
|
|||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://huggingface.co/spaces/Roboflow/Annotators)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
[](https://squidfunk.github.io/mkdocs-material/)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://huggingface.co/spaces/Roboflow/Annotators)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
[](https://squidfunk.github.io/mkdocs-material/)
|
||||
</div>
|
||||
|
||||
## 👋 hello
|
||||
|
|
@ -39,7 +39,7 @@ Pip install the supervision package in a
|
|||
pip install supervision
|
||||
```
|
||||
|
||||
Read more about desktop, headless, and local installation in our [guide](https://roboflow.github.io/supervision/).
|
||||
Read more about conda, mamba, and installing from source in our [guide](https://roboflow.github.io/supervision/).
|
||||
|
||||
## 🔥 quickstart
|
||||
|
||||
|
|
@ -71,16 +71,15 @@ len(detections)
|
|||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(...)
|
||||
model = get_roboflow_model(model_id="yolov8s-640", api_key=<ROBOFLOW API KEY>)
|
||||
model = get_model(model_id="yolov8s-640", api_key=<ROBOFLOW API KEY>)
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
|
||||
len(detections)
|
||||
# 5
|
||||
|
||||
# 5
|
||||
```
|
||||
|
||||
</details>
|
||||
|
|
@ -217,19 +216,23 @@ len(dataset)
|
|||
|
||||
## 🎬 tutorials
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/61a444c8-b135-48ce-b979-2a5ab47c5a91" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><strong>Speed Estimation & Vehicle Tracking | Computer Vision | Open Source</strong></a>
|
||||
<div><strong>Created: 11 Jan 2024</strong> | <strong>Updated: 11 Jan 2024</strong></div>
|
||||
<br/> Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
Want to learn how to use Supervision? Explore our [how-to guides](https://supervision.roboflow.com/develop/how_to/detect_and_annotate/), [end-to-end examples](https://github.com/roboflow/supervision/tree/develop/examples), and [cookbooks](https://supervision.roboflow.com/develop/cookbooks/)!
|
||||
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><img src="https://github.com/roboflow/supervision/assets/26109316/54afdf1c-218c-4451-8f12-627fb85f1682" alt="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><strong>Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking</strong></a>
|
||||
<div><strong>Created: 6 Sep 2023</strong> | <strong>Updated: 6 Sep 2023</strong></div>
|
||||
<br/> In this video, we explore real-time traffic analysis using YOLOv8 and ByteTrack to detect and track vehicles on aerial images. Harnessing the power of Python and Supervision, we delve deep into assigning cars to specific entry zones and understanding their direction of movement. By visualizing their paths, we gain insights into traffic flow across bustling roundabouts... </p>
|
||||
<a href="https://youtu.be/hAWpsIuem10" title="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/a742823d-c158-407d-b30f-063a5d11b4e1" alt="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/hAWpsIuem10" title="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing"><strong>Dwell Time Analysis with Computer Vision | Real-Time Stream Processing</strong></a>
|
||||
<div><strong>Created: 5 Apr 2024</strong></div>
|
||||
<br/>Learn how to use computer vision to analyze wait times and optimize processes. This tutorial covers object detection, tracking, and calculating time spent in designated zones. Use these techniques to improve customer experience in retail, traffic management, or other scenarios.</p>
|
||||
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/61a444c8-b135-48ce-b979-2a5ab47c5a91" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><strong>Speed Estimation & Vehicle Tracking | Computer Vision | Open Source</strong></a>
|
||||
<div><strong>Created: 11 Jan 2024</strong></div>
|
||||
<br/>Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
|
||||
## 💜 built with supervision
|
||||
|
||||
|
|
|
|||
|
|
@ -19,13 +19,13 @@ as an extra within the Supervision package.
|
|||
```
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>download_assets</h2>
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.download_assets">download_assets</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.downloader.download_assets
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoAssets</h2>
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.VideoAssets">VideoAssets</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.list.VideoAssets
|
||||
|
|
|
|||
|
|
@ -1,3 +1,68 @@
|
|||
### 0.20.0 <small>April 24, 2024</small>
|
||||
|
||||
- Added [#1128](https://github.com/roboflow/supervision/pull/1128): [`sv.KeyPoints`](/0.20.0/keypoint/core/#supervision.keypoint.core.KeyPoints) to provide initial support for pose estimation and broader keypoint detection models.
|
||||
|
||||
- Added [#1128](https://github.com/roboflow/supervision/pull/1128): [`sv.EdgeAnnotator`](/0.20.0/keypoint/annotators/#supervision.keypoint.annotators.EdgeAnnotator) and [`sv.VertexAnnotator`](/0.20.0/keypoint/annotators/#supervision.keypoint.annotators.VertexAnnotator) to enable rendering of results from keypoint detection models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8l-pose')
|
||||
|
||||
result = model(image, verbose=False)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
|
||||
edge_annotators = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
annotated_image = edge_annotators.annotate(image.copy(), keypoints)
|
||||
```
|
||||
|
||||
- Changed [#1037](https://github.com/roboflow/supervision/pull/1037): [`sv.LabelAnnotator`](/0.20.0/annotators/#supervision.annotators.core.LabelAnnotator) by adding an additional `corner_radius` argument that allows for rounding the corners of the bounding box.
|
||||
|
||||
- Changed [#1109](https://github.com/roboflow/supervision/pull/1109): [`sv.PolygonZone`](/0.20.0/detection/tools/polygon_zone/#supervision.detection.tools.polygon_zone.PolygonZone) such that the `frame_resolution_wh` argument is no longer required to initialize `sv.PolygonZone`.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `frame_resolution_wh` parameter in `sv.PolygonZone` is deprecated and will be removed in `supervision-0.24.0`.
|
||||
|
||||
- Changed [#1084](https://github.com/roboflow/supervision/pull/1084): [`sv.get_polygon_center`](/0.20.0/utils/geometry/#supervision.geometry.core.utils.get_polygon_center) to calculate a more accurate polygon centroid.
|
||||
|
||||
- Changed [#1069](https://github.com/roboflow/supervision/pull/1069): [`sv.Detections.from_transformers`](/0.20.0/detection/core/#supervision.detection.core.Detections.from_transformers) by adding support for Transformers segmentation models and extract class names values.
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForSegmentation
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_segmentation(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results, id2label=model.config.id2label)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
- Fixed [#787](https://github.com/roboflow/supervision/pull/787): [`sv.ByteTrack.update_with_detections`](/0.20.0/trackers/#supervision.tracker.byte_tracker.core.ByteTrack.update_with_detections) which was removing segmentation masks while tracking. Now, `ByteTrack` can be used alongside segmentation models.
|
||||
|
||||
### 0.19.0 <small>March 15, 2024</small>
|
||||
|
||||
- Added [#818](https://github.com/roboflow/supervision/pull/818): [`sv.CSVSink`](/0.19.0/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) allowing for the straightforward saving of image, video, or stream inference results in a `.csv` file.
|
||||
|
|
|
|||
|
|
@ -12,7 +12,8 @@ These features are phased out due to better alternatives or potential issues in
|
|||
- The method `Color.green()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.GREEN` instead.
|
||||
- The method `Color.blue()` is deprecated and will be removed in `supervision-0.22.0`. Use the constant `Color.BLUE` instead.
|
||||
- The method [`ColorPalette.default()`](draw/color.md/#supervision.draw.color.ColorPalette.default) is deprecated and will be removed in `supervision-0.22.0`. Use the constant [`ColorPalette.DEFAULT`](draw/color.md/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
- `BoxAnnotator` is deprecated and will be removed in `supervision-0.22.0`. Use [`BoundingBoxAnnotator`](annotators.md/#supervision.annotators.core.BoundingBoxAnnotator) and [`LabelAnnotator`](annotators.md/#supervision.annotators.core.LabelAnnotator) instead.
|
||||
- `BoxAnnotator` is deprecated and will be removed in `supervision-0.22.0`. Use [`BoundingBoxAnnotator`](detection/annotators.md/#supervision.annotators.core.BoundingBoxAnnotator) and [`LabelAnnotator`](detection/annotators.md/#supervision.annotators.core.LabelAnnotator) instead.
|
||||
- The method [`FPSMonitor.__call__`](utils/video.md/#supervision.utils.video.FPSMonitor.__call__) is deprecated and will be removed in `supervision-0.22.0`. Use the attribute [`FPSMonitor.fps`](utils/video.md/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
- The `track_buffer`, `track_thresh`, and `match_thresh` parameters in [`ByterTrack`](trackers.md/#supervision.tracker.byte_tracker.core.ByteTrack) are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
- The `triggering_position ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) is deprecated and will be removed in `supervision-0.23.0`. Use `triggering_anchors ` instead.
|
||||
- The `frame_resolution_wh ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) is deprecated and will be removed in `supervision-0.24.0`.
|
||||
|
|
|
|||
|
|
@ -260,15 +260,22 @@ status: new
|
|||
=== "Label"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
|
||||
|
|
@ -281,7 +288,7 @@ status: new
|
|||
=== "Crop"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
|
@ -0,0 +1,17 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Metrics
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
|
|
@ -6,67 +6,67 @@ status: new
|
|||
# Detection Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_iou_batch</h2>
|
||||
<h2><a href="#supervision.detection.utils.box_iou_batch">box_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_iou_batch</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_iou_batch">mask_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_non_max_suppression</h2>
|
||||
<h2><a href="#supervision.detection.utils.box_non_max_suppression">box_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_non_max_suppression</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_non_max_suppression">mask_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_mask</h2>
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_mask">polygon_to_mask</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_mask
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_xyxy</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_to_xyxy">mask_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_polygons</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_to_polygons">mask_to_polygons</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_polygons
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_xyxy</h2>
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_xyxy">polygon_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>filter_polygons_by_area</h2>
|
||||
<h2><a href="#supervision.detection.utils.filter_polygons_by_area">filter_polygons_by_area</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.filter_polygons_by_area
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>move_boxes</h2>
|
||||
<h2><a href="#supervision.detection.utils.move_boxes">move_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>scale_boxes</h2>
|
||||
<h2><a href="#supervision.detection.utils.scale_boxes">scale_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.scale_boxes
|
||||
|
|
|
|||
|
|
@ -1,13 +0,0 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Color
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ColorPalette</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
|
|
@ -1,53 +0,0 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_line</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_filled_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_polygon</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_text</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_dynamic_font_scale</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_dynamic_line_thickness</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_line_thickness
|
||||
|
|
@ -1,7 +0,0 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Position
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
|
|
@ -1,20 +1,35 @@
|
|||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detect and Annotate
|
||||
|
||||
Supervision offers a streamlined solution to effortlessly annotate predictions from a
|
||||
range of object detection and segmentation models. This guide demonstrates how to
|
||||
execute inference using the YOLOv8 model with either the
|
||||
[Inference](https://github.com/roboflow/inference) or
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision for image annotation
|
||||
purposes.
|
||||
Supervision provides a seamless process for annotating predictions generated by various
|
||||
object detection and segmentation models. This guide shows how to perform inference
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision and use them to annotate
|
||||
source image.
|
||||
|
||||
## Run Inference
|
||||
|
||||
|
||||
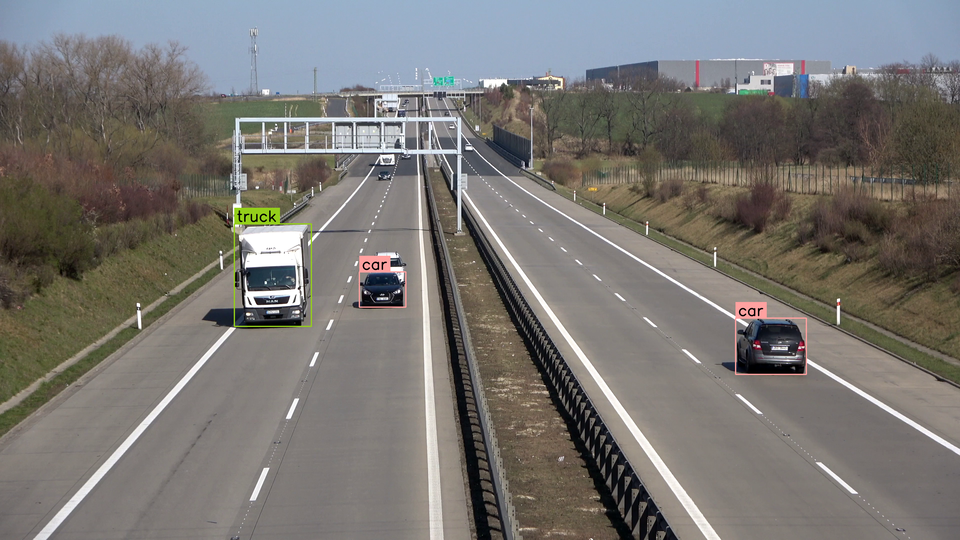
First, you'll need to obtain predictions from your object detection or segmentation model.
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
|
|
@ -23,105 +38,115 @@ First, you'll need to obtain predictions from your object detection or segmentat
|
|||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from inference.models.utils import get_roboflow_model
|
||||
import torch
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
```
|
||||
|
||||
## Load Predictions into Supervision
|
||||
|
||||
Now that we have predictions from a model, we can load them into Supervision.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
We can do so using the [`sv.Detections.from_ultralytics`](detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
We can do so using the [`sv.Detections.from_inference`](detection/core/#supervision.detection.core.Detections.from_inference) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
```{ .py hl_lines="2 8" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
You can conveniently load predictions from other computer vision frameworks and libraries using:
|
||||
|
||||
- [`from_deepsparse`](detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_inference`](detection/core/#supervision.detection.core.Detections.from_inference) ([Roboflow Inference](https://github.com/roboflow/inference))
|
||||
- [`from_sam`](detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_transformers`](detection/core/#supervision.detection.core.Detections.from_transformers) ([HuggingFace Transformers](https://github.com/huggingface/transformers))
|
||||
- [`from_yolo_nas`](detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
## Annotate Image
|
||||
|
||||
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](annotators/#supervision.annotators.core.LabelAnnotator) classes. If you are running the segmentation model [`sv.MaskAnnotator`](annotators/#supervision.annotators.core.MaskAnnotator) is a drop-in replacement for [`sv.BoundingBoxAnnotator`](annotators/#supervision.annotators.core.BoundingBoxAnnotator) that will allow you to draw masks instead of boxes.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
We can do so using the [`sv.Detections.from_ultralytics`](detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```{ .py hl_lines="2 8" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.model.names[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
We can do so using the [`sv.Detections.from_transformers`](detection/core/#supervision.detection.core.Detections.from_transformers) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```{ .py hl_lines="2 19-21" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
```
|
||||
|
||||
You can load predictions from other computer vision frameworks and libraries using:
|
||||
|
||||
- [`from_deepsparse`](/latest/detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](/latest/detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](/latest/detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_sam`](/latest/detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_yolo_nas`](/latest/detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
## Annotate Image with Detections
|
||||
|
||||
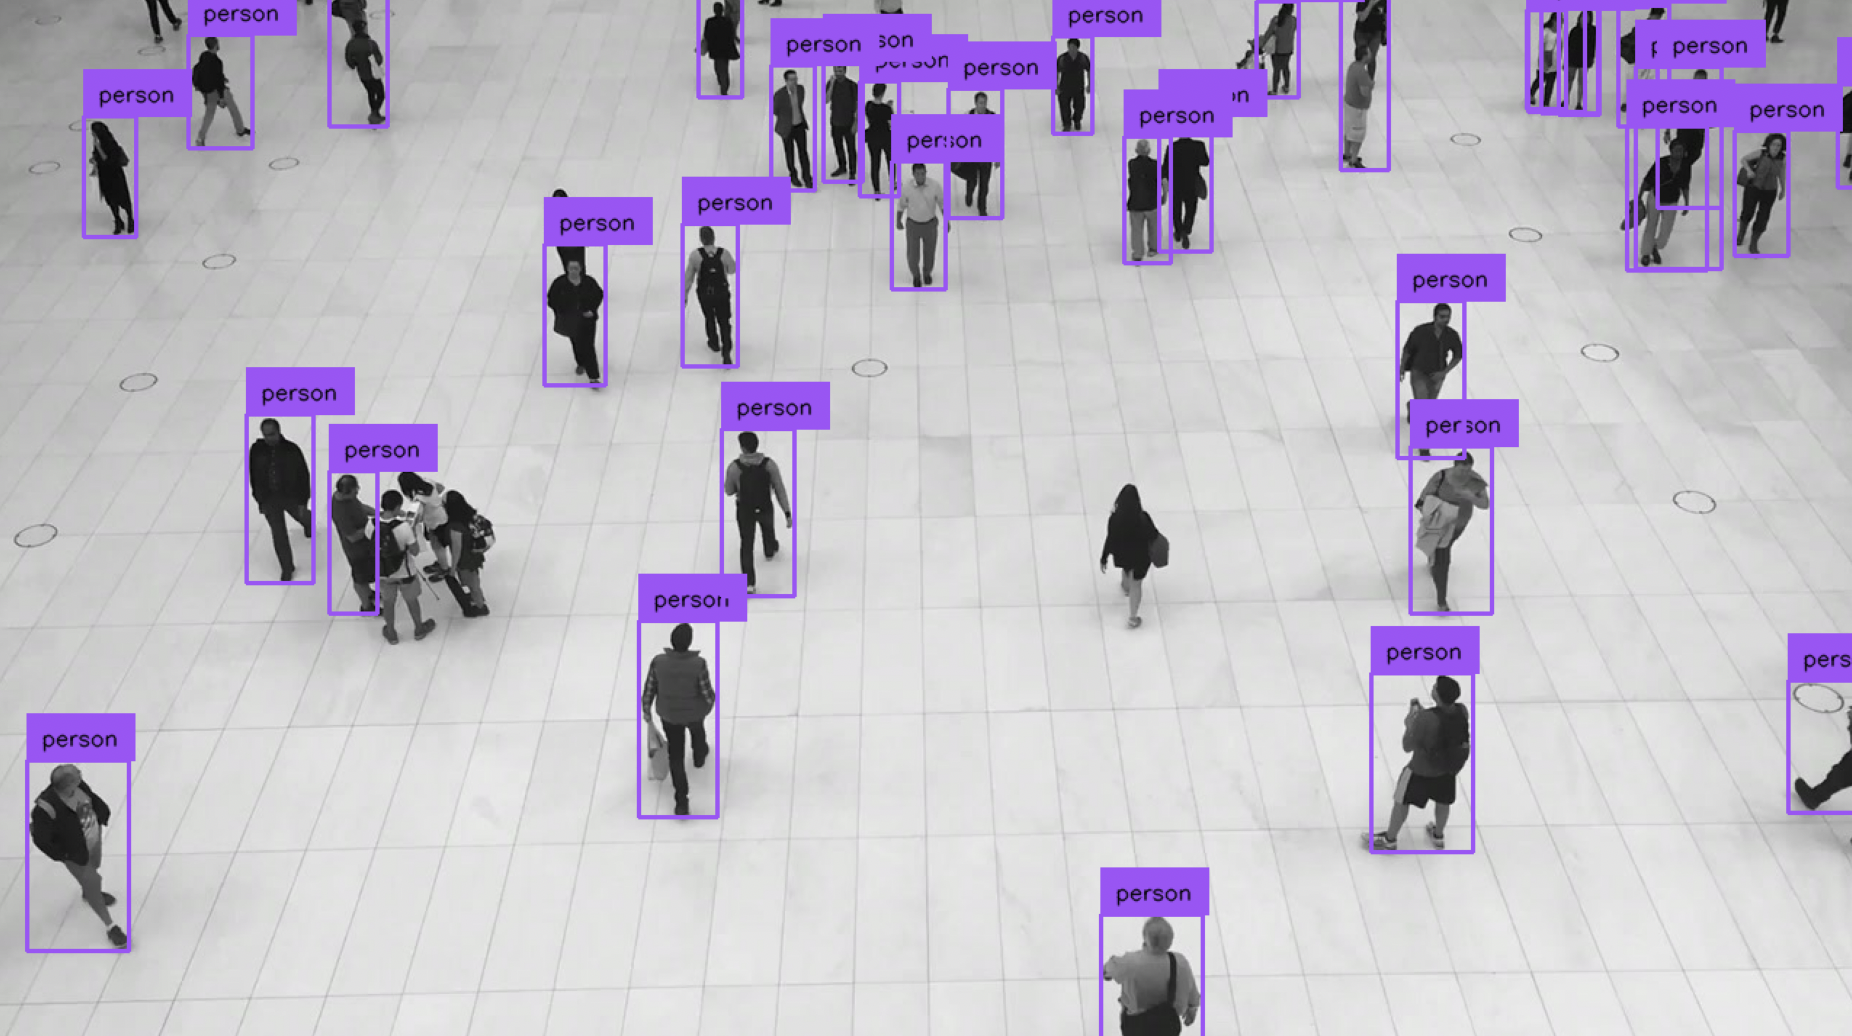
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](/latest/annotators/#supervision.annotators.core.LabelAnnotator) classes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
```{ .py hl_lines="10-16" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
|
|
@ -134,12 +159,253 @@ Finally, we can annotate the image with the predictions. Since we are working wi
|
|||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
## Display Annotated Image
|
||||
```{ .py hl_lines="10-16" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
To display the annotated image in Jupyter Notebook or Google Colab, use the [`sv.plot_image`](utils/notebook/#supervision.utils.notebook.plot_image) function.
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
```python
|
||||
sv.plot_image(annotated_image)
|
||||
```
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="23-30" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||

|
||||
|
||||
## Display Custom Labels
|
||||
|
||||
By default, [`sv.LabelAnnotator`](/latest/annotators/#supervision.annotators.core.LabelAnnotator)
|
||||
will label each detection with its `class_name` (if possible) or `class_id`. You can
|
||||
override this behavior by passing a list of custom `labels` to the `annotate` method.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="13-17 22" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="13-17 22" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="26-30 35" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
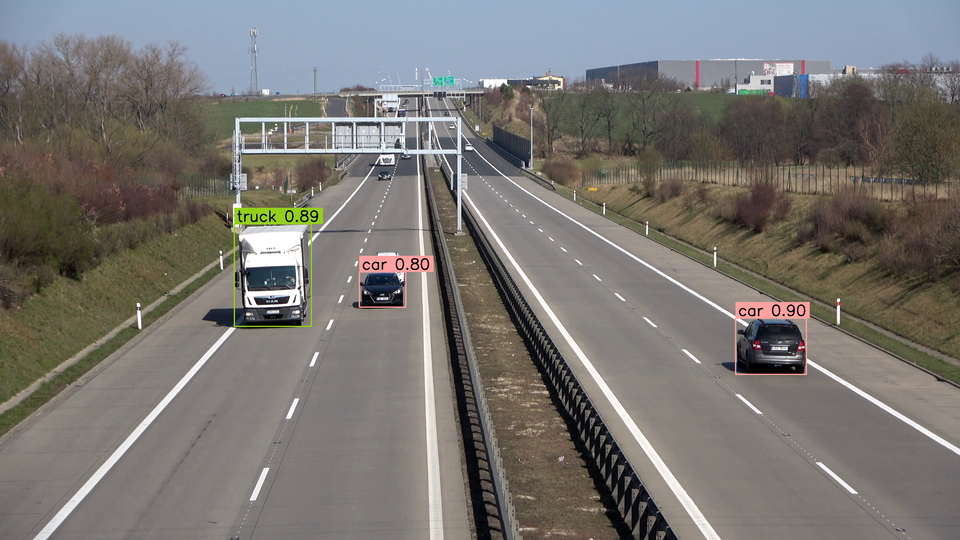
|
||||
|
||||
## Annotate Image with Segmentations
|
||||
|
||||
If you are running the segmentation model
|
||||
[`sv.MaskAnnotator`](/latest/annotators/#supervision.annotators.core.MaskAnnotator)
|
||||
is a drop-in replacement for
|
||||
[`sv.BoundingBoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoundingBoxAnnotator)
|
||||
that will allow you to draw masks instead of boxes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-seg-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n-seg.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForSegmentation
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_segmentation(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
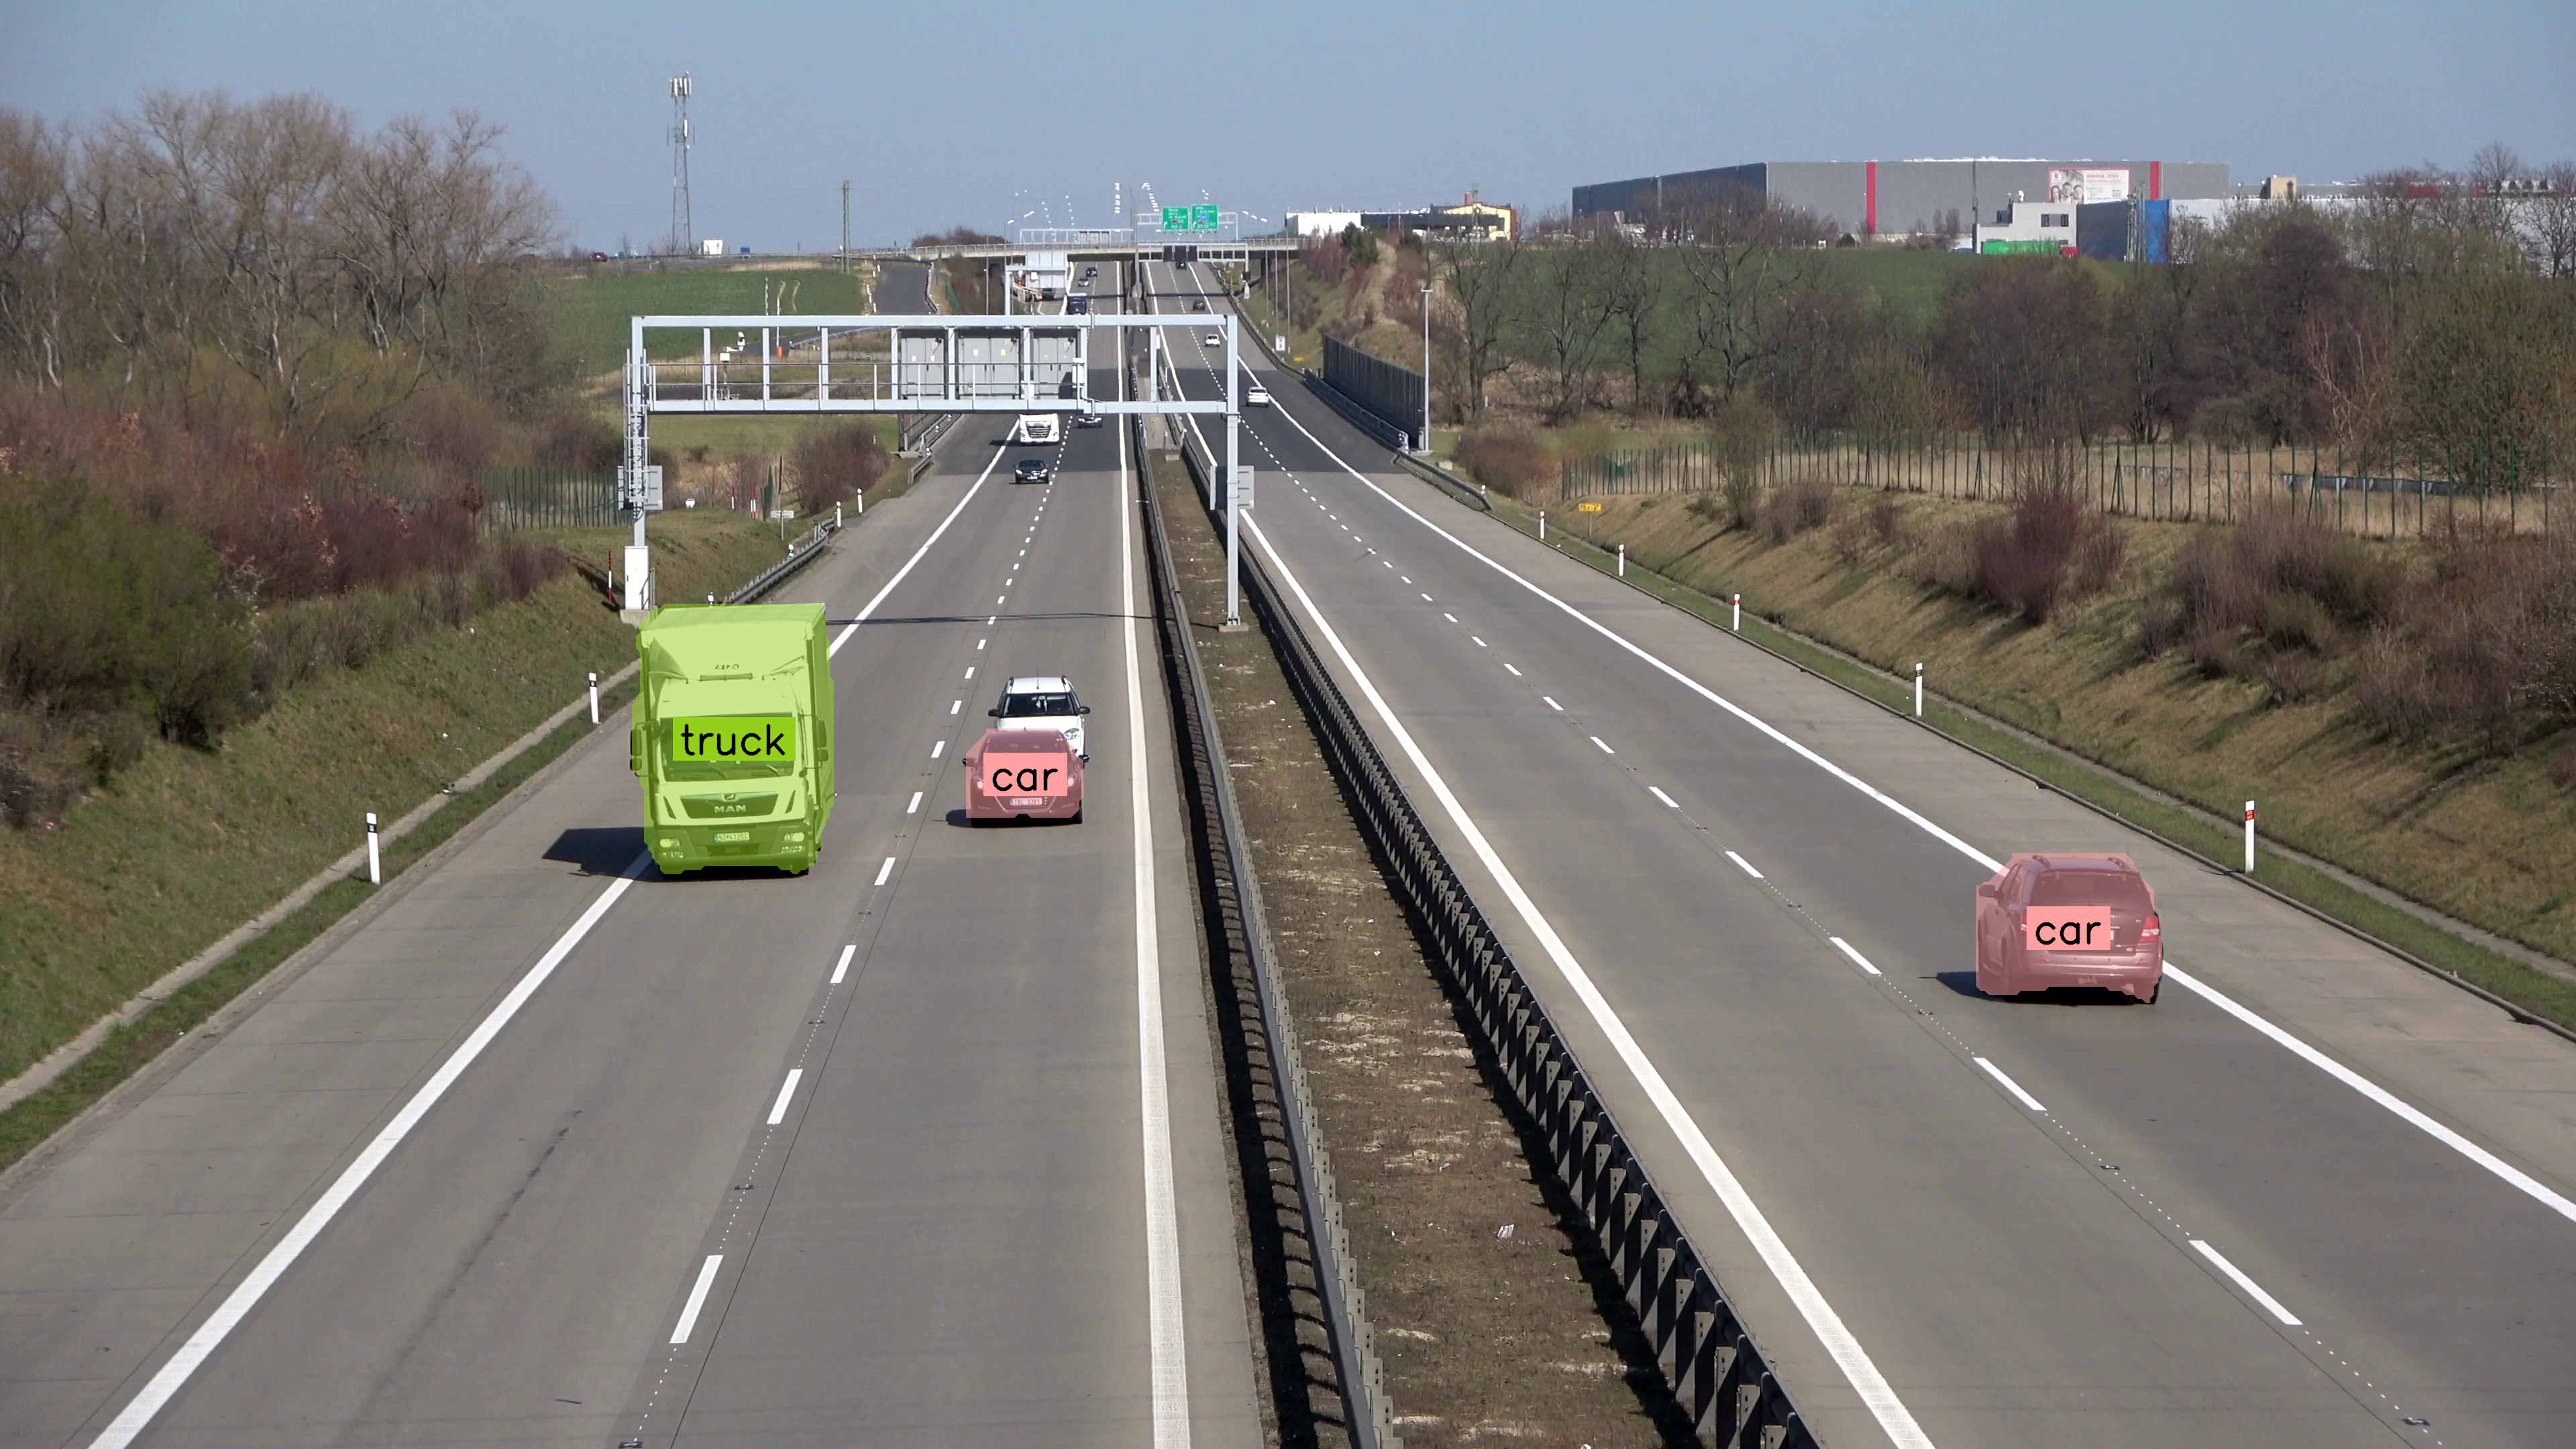
|
||||
|
|
|
|||
|
|
@ -0,0 +1,266 @@
|
|||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detect Small Objects
|
||||
|
||||
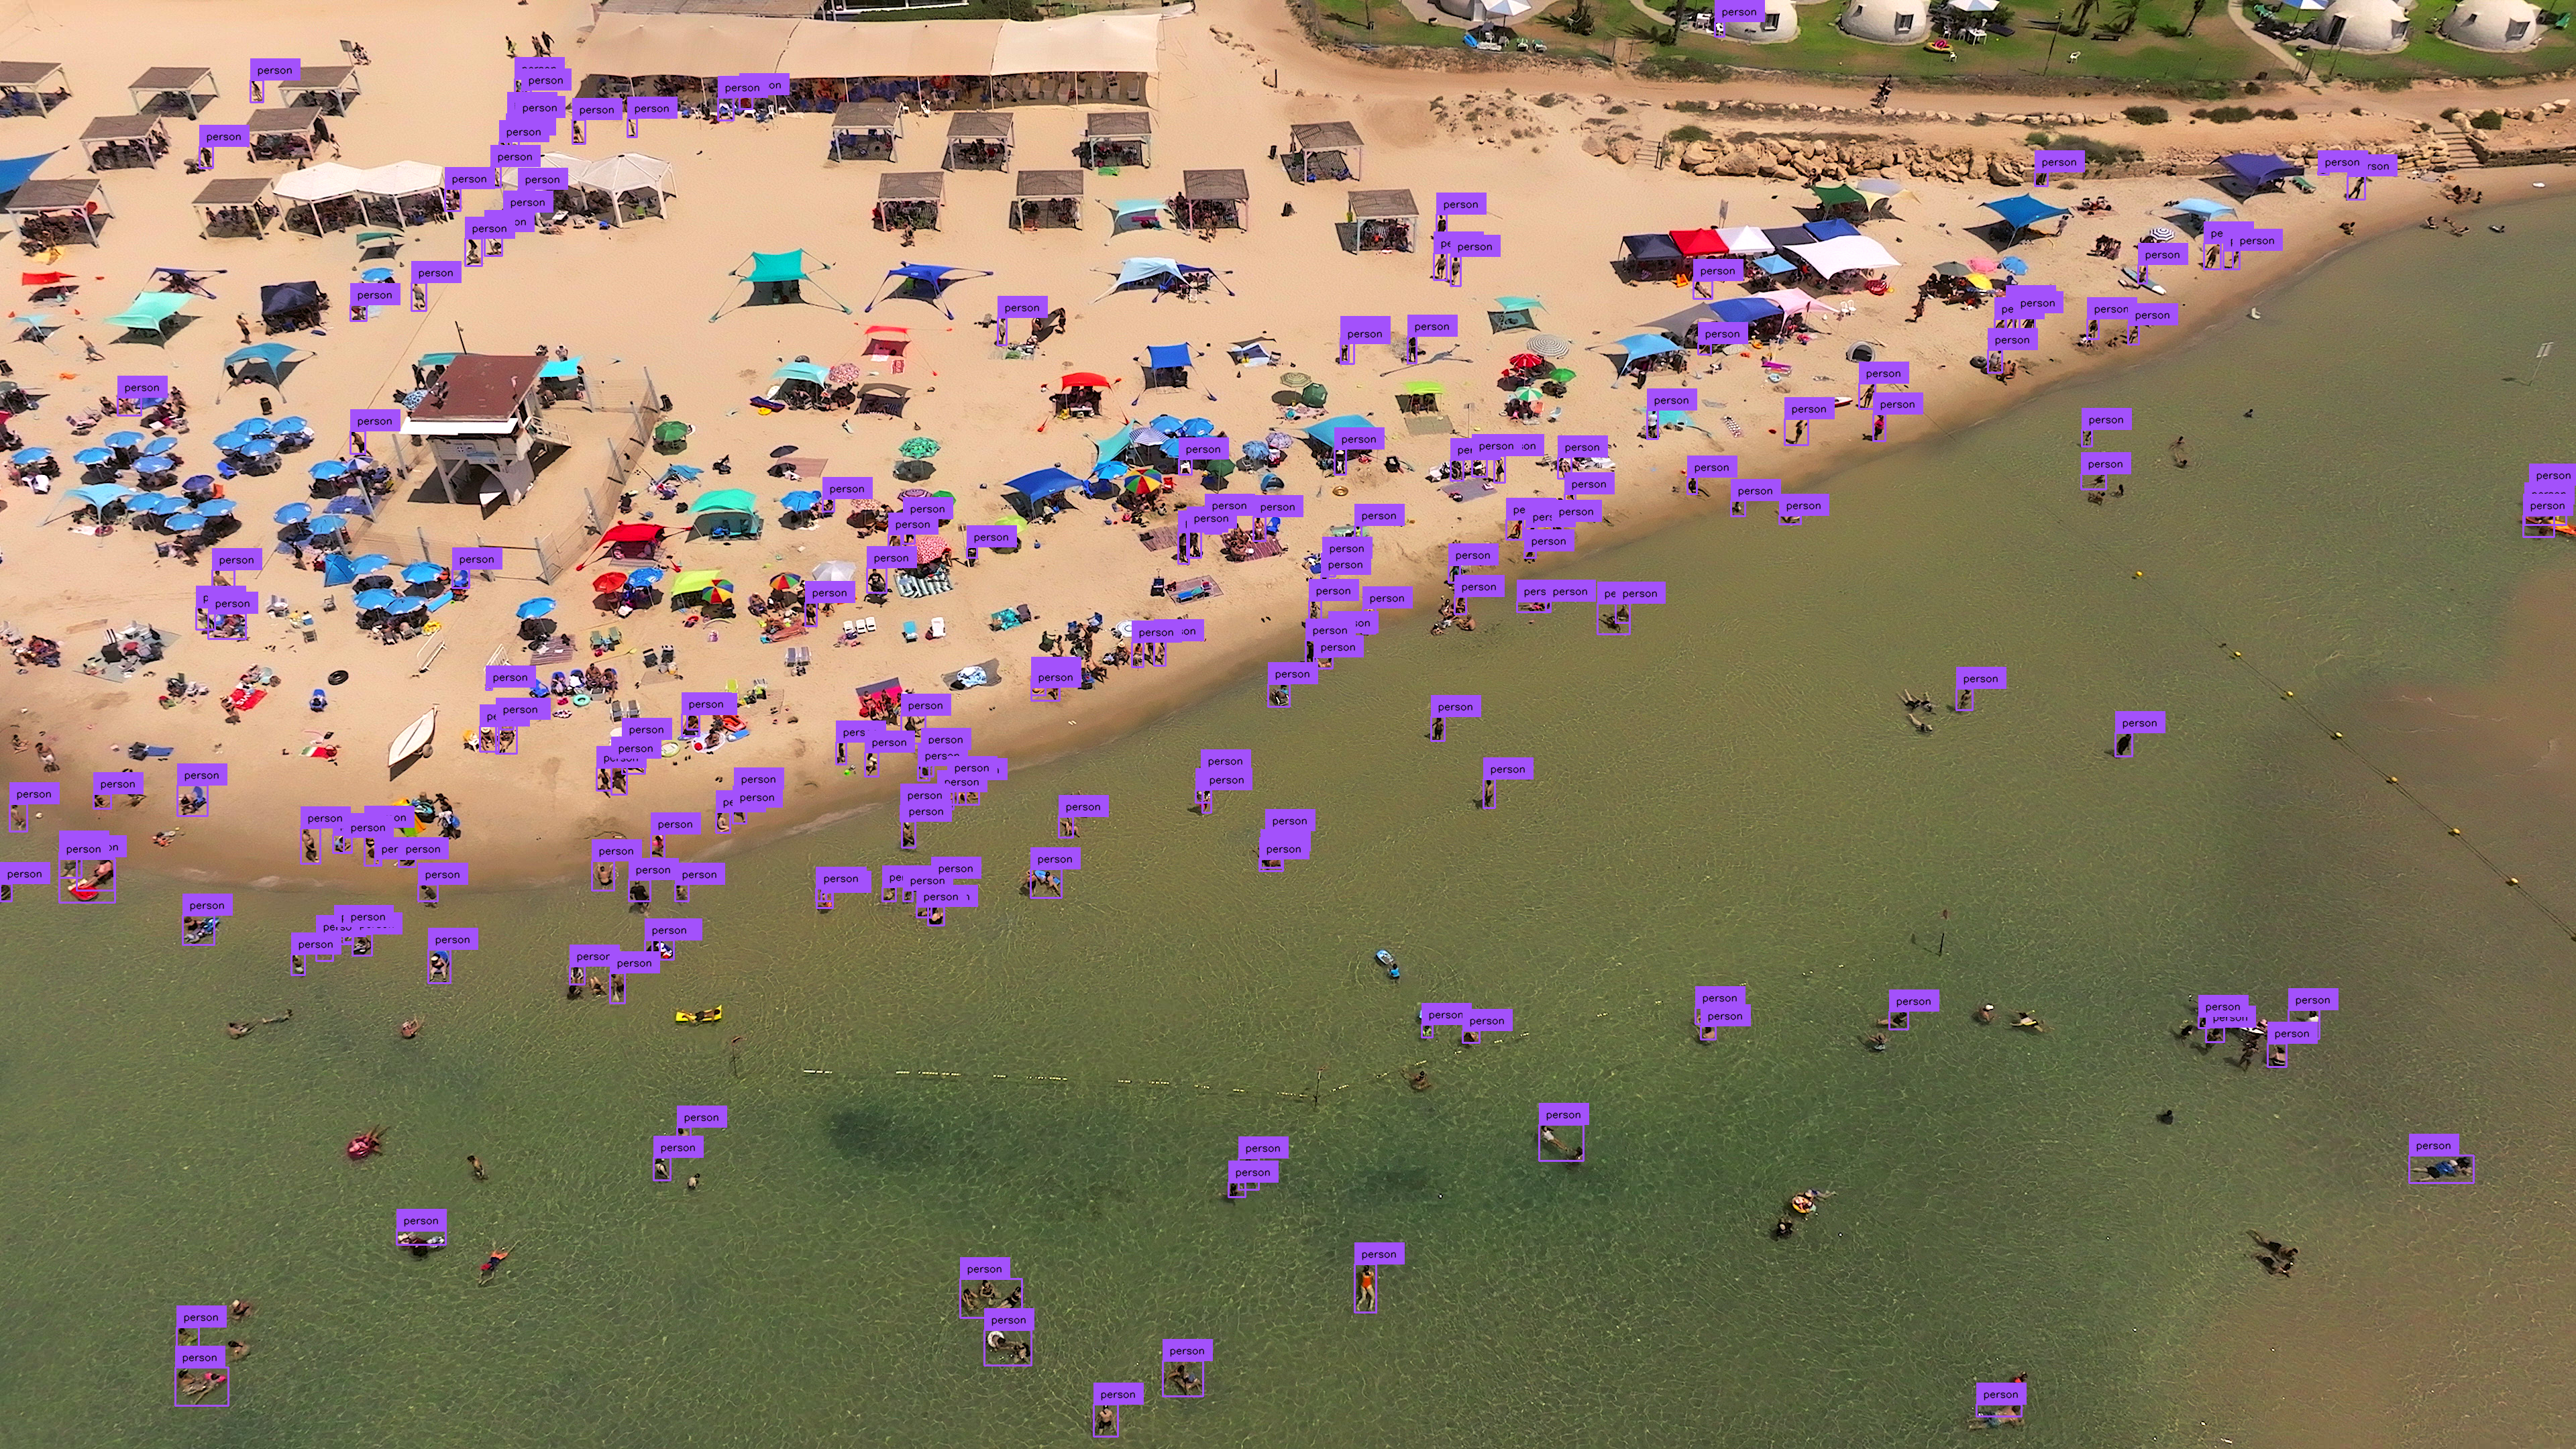
This guide shows how to detect small objects
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages using
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer).
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Baseline Detection
|
||||
|
||||
Small object detection in high-resolution images presents challenges due to the objects'
|
||||
size relative to the image resolution.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.config.id2label[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
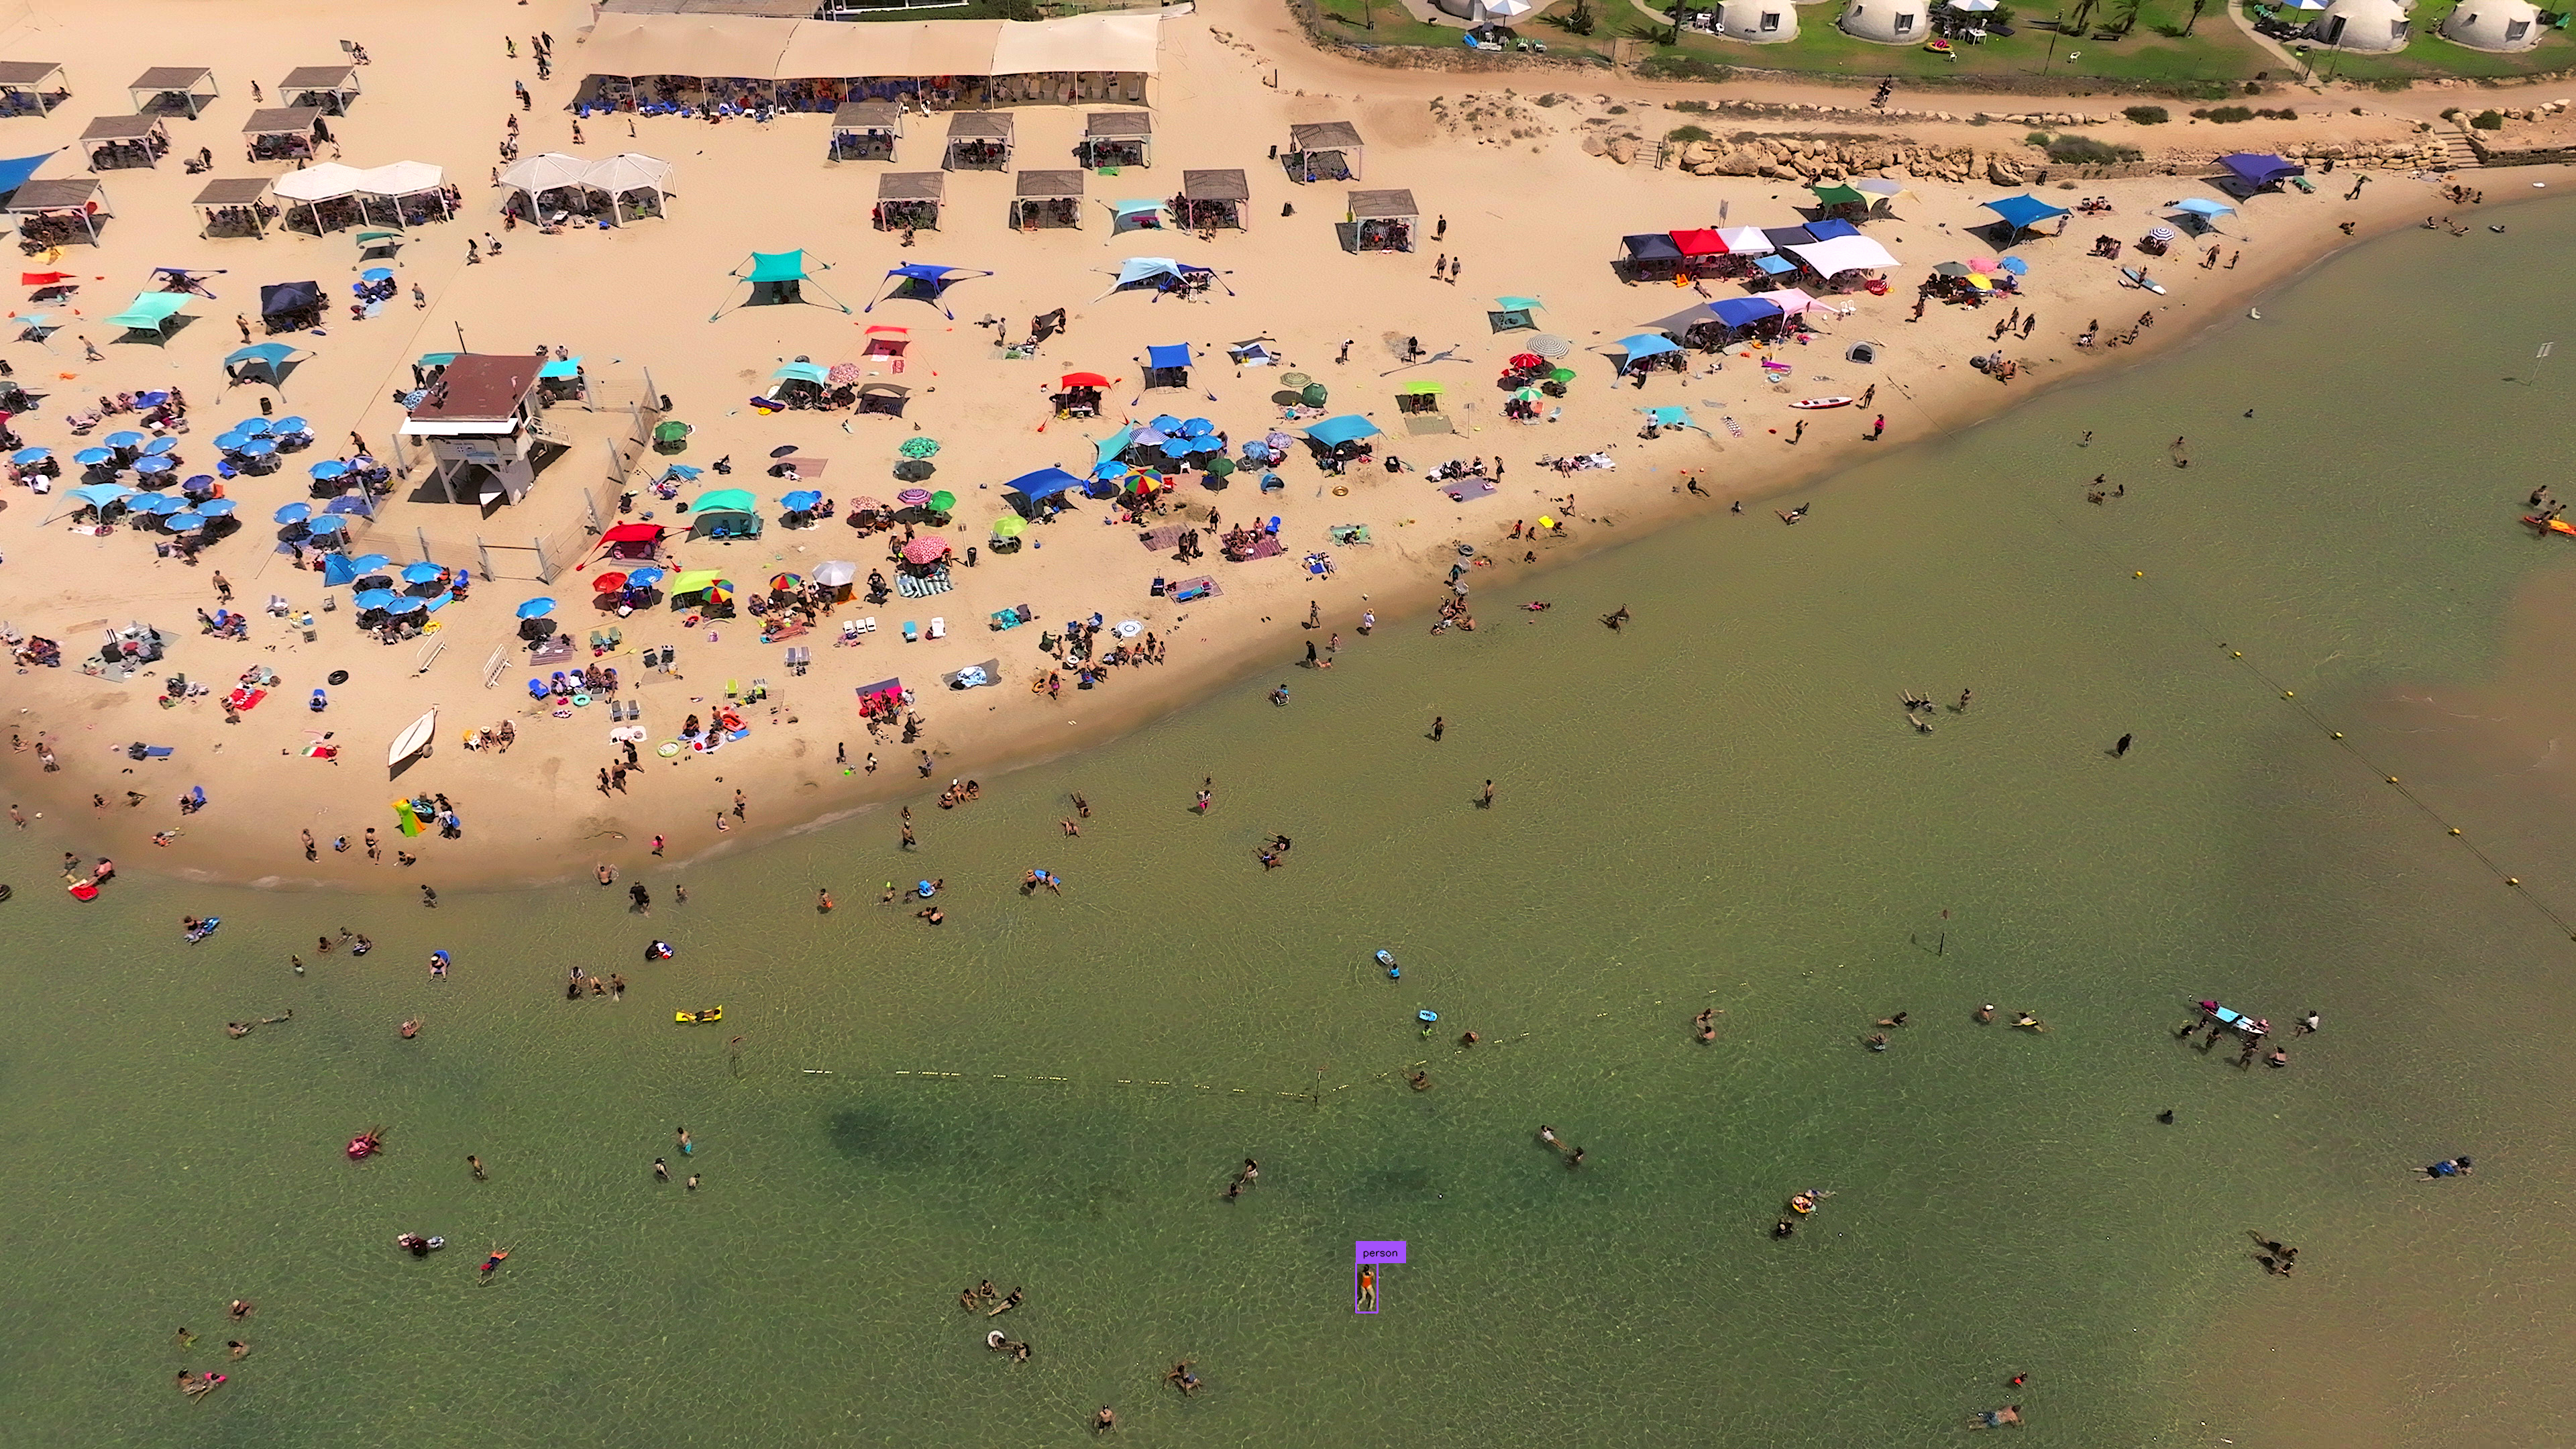
|
||||
|
||||
## Input Resolution
|
||||
|
||||
Modifying the input resolution of images before detection can enhance small object
|
||||
identification at the cost of processing speed and increased memory usage. This method
|
||||
is less effective for ultra-high-resolution images (4K and above).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="5" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-1280")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image, imgsz=1280)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
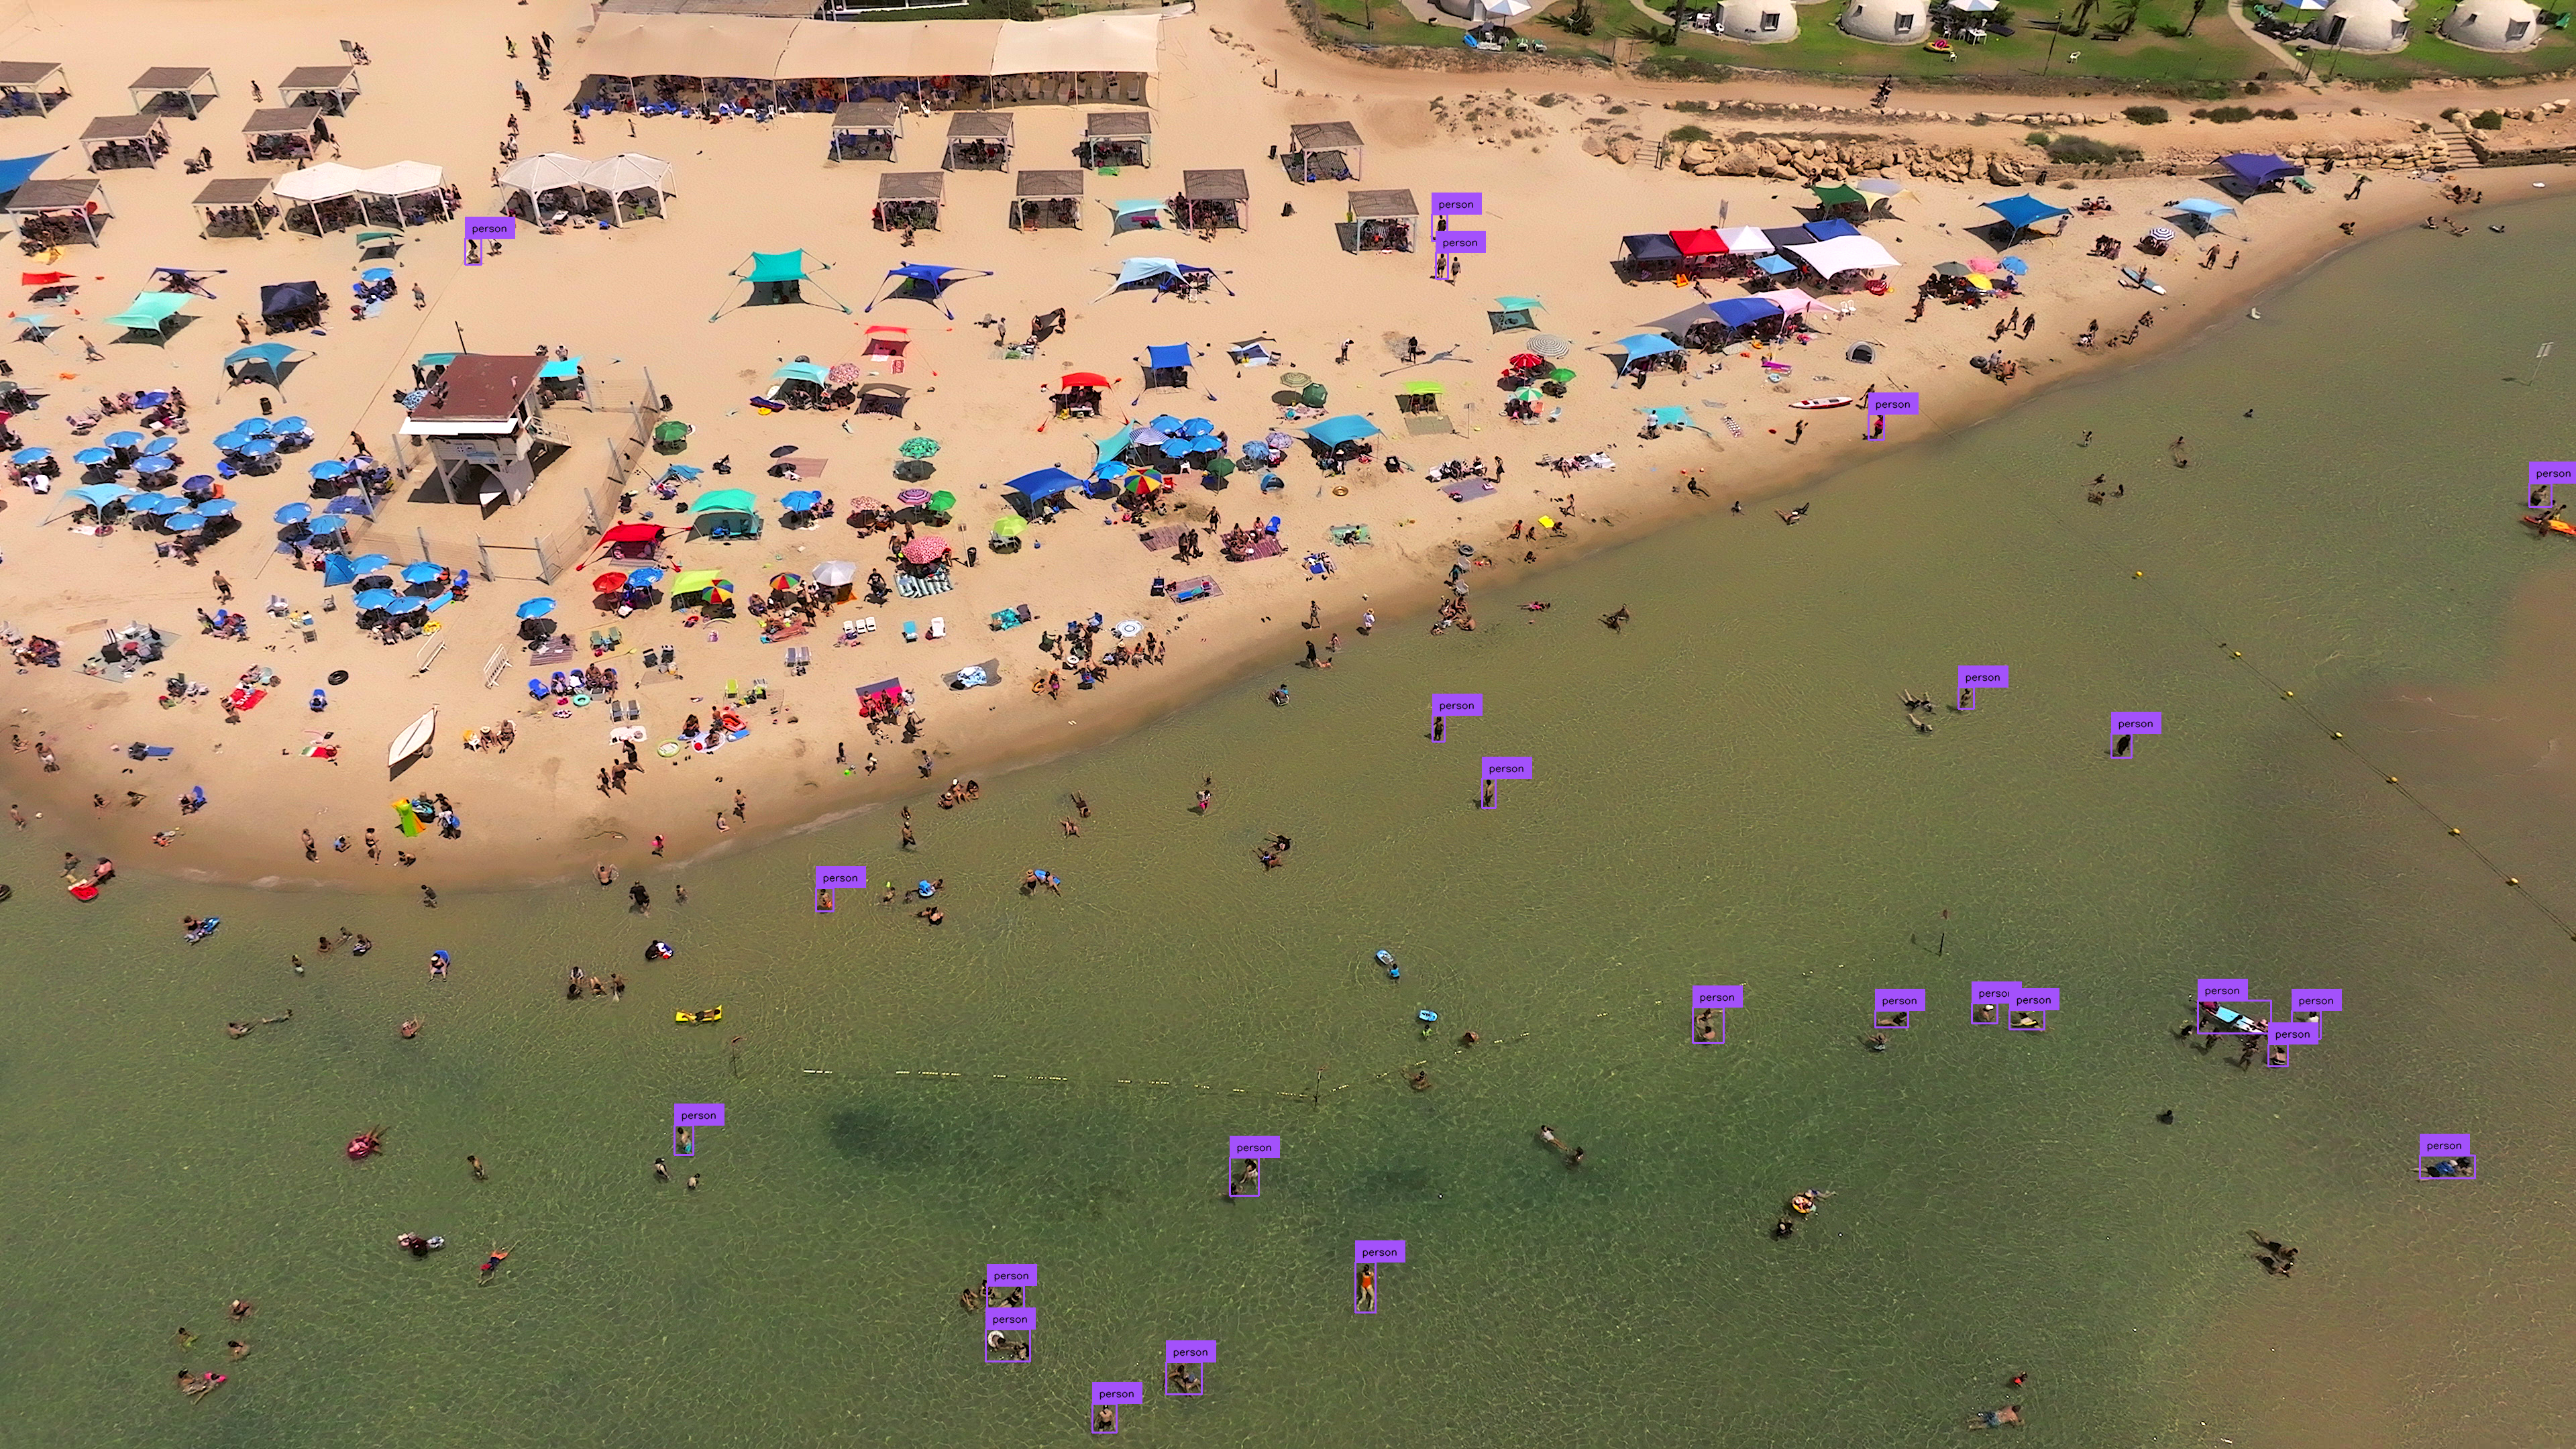
|
||||
|
||||
## Inference Slicer
|
||||
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer)
|
||||
processes high-resolution images by dividing them into smaller segments, detecting
|
||||
objects within each, and aggregating the results.
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example_2.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="9-14" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="9-14" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
result = model(image_slice)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="13-28" }
|
||||
import cv2
|
||||
import torch
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
image_slice = cv2.cvtColor(image_slice, cv2.COLOR_BGR2RGB)
|
||||
image_slice = Image.fromarray(image_slice)
|
||||
inputs = processor(images=image_slice, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
return sv.Detections.from_transformers(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.config.id2label[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
|
||||
|
|
@ -0,0 +1,299 @@
|
|||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
|
||||
Supervision enables an easy way to save detections in .CSV and .JSON files for offline
|
||||
processing. This guide demonstrates how to perform video inference using the
|
||||
[Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages and save their results with
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. You can learn more on this topic in our
|
||||
[How to Detect and Annotate](/latest/how_to/detect_and_annotate.md) guide.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
```
|
||||
|
||||
## Save Detections as CSV
|
||||
|
||||
To save detections to a `.CSV` file, open our
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
and then pass the
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections)
|
||||
object resulting from the inference to it. Its fields are parsed and saved on disk.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car |
|
||||
|
||||
## Custom Fields
|
||||
|
||||
Besides regular fields in
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections),
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
also allows you to add custom information to each row, which can be passed via the
|
||||
`custom_data` dictionary. Let's utilize this feature to save information about the
|
||||
frame index from which the detections originate.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="10 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name | frame_index |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|-------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car | 0 |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck | 0 |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car | 0 |
|
||||
|
||||
## Save Detections as JSON
|
||||
|
||||
If you prefer to save the result in a `.JSON` file instead of a `.CSV` file, all you
|
||||
need to do is replace
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
with
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
|
@ -30,7 +30,7 @@ We write your reusable computer vision tools. Whether you need to load your data
|
|||
|
||||
## 💻 Install
|
||||
|
||||
You can install `supervision` with pip in a
|
||||
You can install `supervision` in a
|
||||
[**Python>=3.8**](https://www.python.org/) environment.
|
||||
|
||||
!!! example "pip install (recommended)"
|
||||
|
|
@ -49,6 +49,24 @@ You can install `supervision` with pip in a
|
|||
pip install "supervision[desktop]"
|
||||
```
|
||||
|
||||
!!! example "conda/mamba install"
|
||||
|
||||
=== "conda"
|
||||
|
||||
[](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision)
|
||||
|
||||
```bash
|
||||
conda install -c conda-forge supervision
|
||||
```
|
||||
|
||||
=== "mamba"
|
||||
|
||||
[](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision)
|
||||
|
||||
```bash
|
||||
mamba install -c conda-forge supervision
|
||||
```
|
||||
|
||||
!!! example "git clone (for development)"
|
||||
|
||||
=== "virtualenv"
|
||||
|
|
@ -88,7 +106,6 @@ You can install `supervision` with pip in a
|
|||
poetry install --extras "desktop"
|
||||
```
|
||||
|
||||
|
||||
## 🚀 Quickstart
|
||||
|
||||
<div class="grid cards" markdown>
|
||||
|
|
@ -109,6 +126,14 @@ You can install `supervision` with pip in a
|
|||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/track_objects.md)
|
||||
|
||||
- __Detect Small Objects__
|
||||
|
||||
---
|
||||
|
||||
Learn how to detect small objects in images
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/detect_small_objects.md)
|
||||
|
||||
- > __Count Objects Crossing Line__
|
||||
|
||||
---
|
||||
|
|
|
|||
|
|
@ -0,0 +1,60 @@
|
|||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
=== "VertexAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_annotator = sv.VertexAnnotator(color=sv.Color.GREEN, radius=10)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
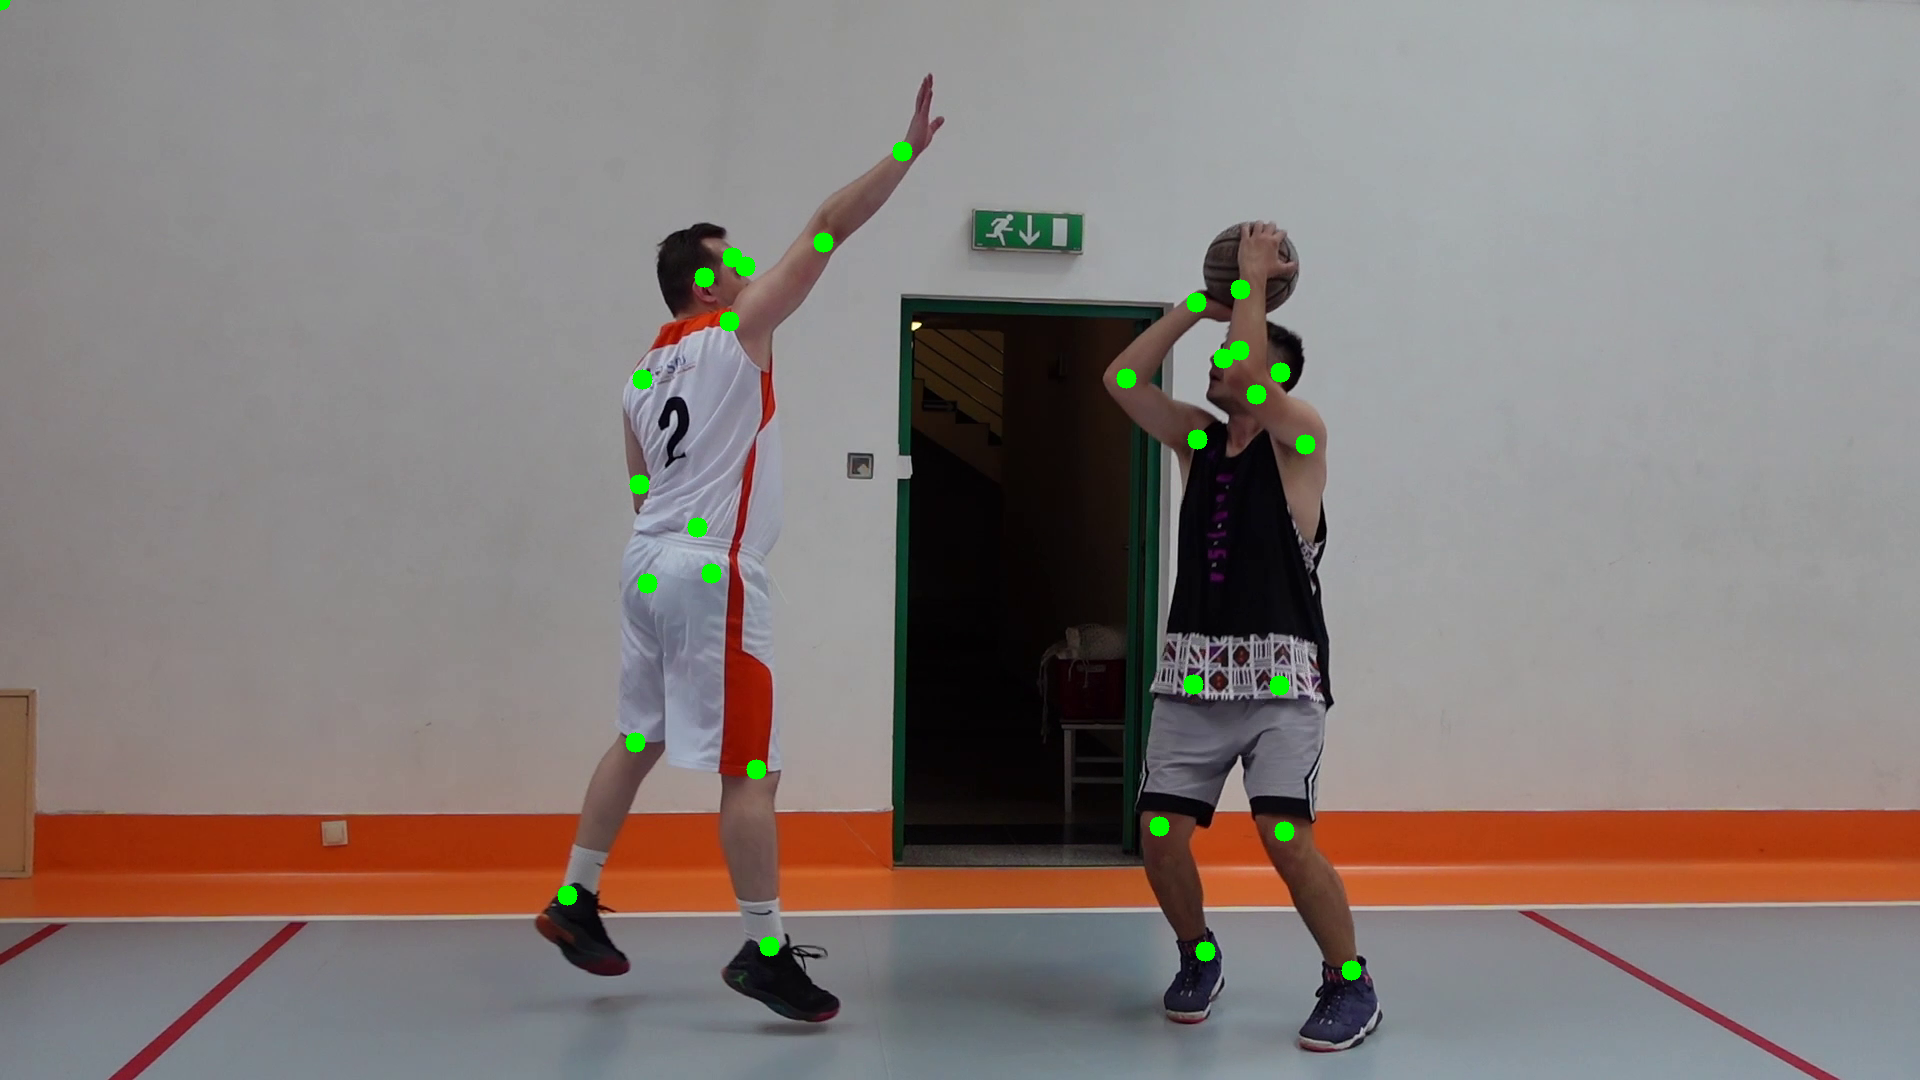{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "EdgeAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
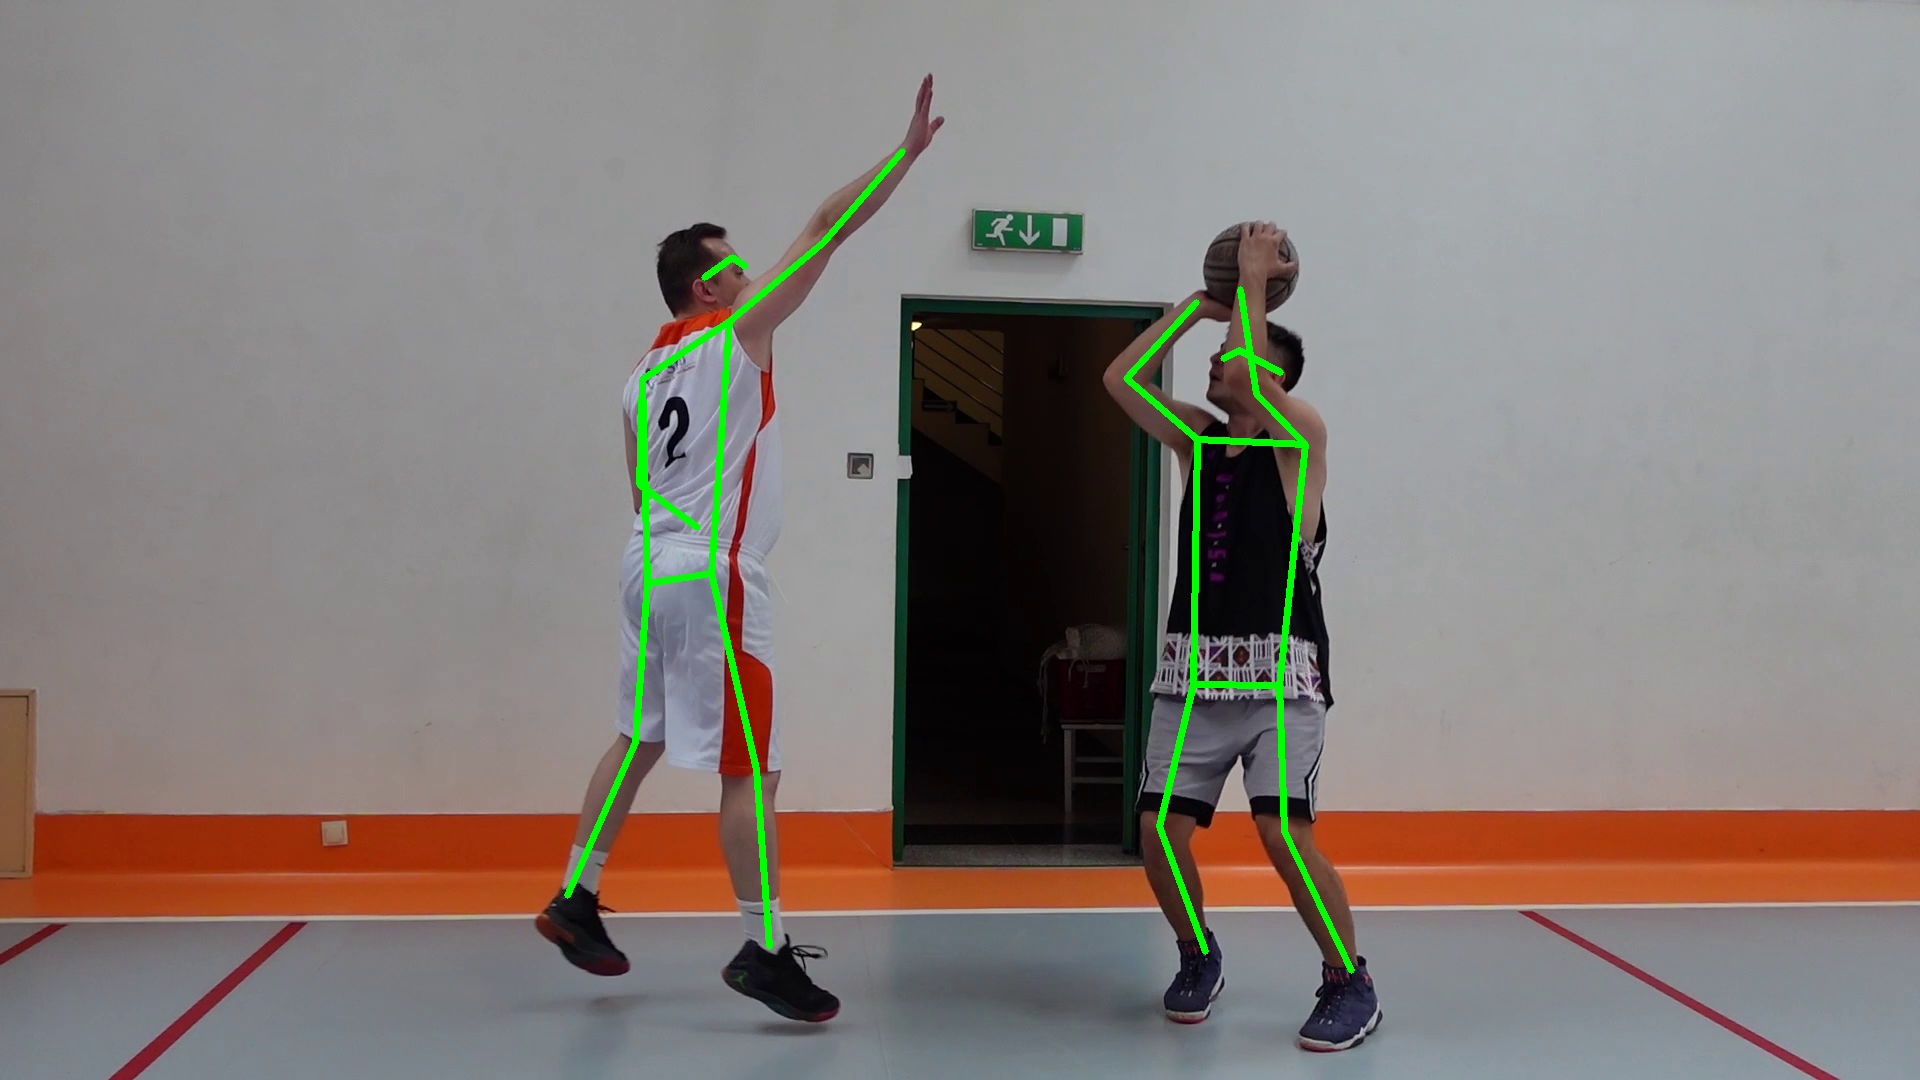{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.VertexAnnotator">VertexAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.VertexAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.EdgeAnnotator">EdgeAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.EdgeAnnotator
|
||||
|
|
@ -0,0 +1,8 @@
|
|||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Keypoint Detection
|
||||
|
||||
:::supervision.keypoint.core.KeyPoints
|
||||
|
|
@ -1,22 +0,0 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Detection Metrics
|
||||
|
||||
!!! warning
|
||||
|
||||
Evaluation API is still fluid and may change. If you use Evaluation API in your project until further notice, freeze the
|
||||
`supervision` version in your `requirements.txt` or `setup.py`.
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
|
|
@ -0,0 +1,65 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_line">draw_line</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_rectangle">draw_rectangle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_filled_rectangle">draw_filled_rectangle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_polygon">draw_polygon</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_text">draw_text</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_image">draw_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_font_scale">calculate_optimal_font_scale</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_line_thickness">calculate_optimal_line_thickness</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_line_thickness
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.color.Color">Color</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.color.ColorPalette">ColorPalette</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
|
|
@ -5,7 +5,7 @@ comments: true
|
|||
# File Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>list_files_with_extensions</h2>
|
||||
<h2><a href="#supervision.utils.file.list_files_with_extensions">list_files_with_extensions</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.file.list_files_with_extensions
|
||||
|
|
|
|||
|
|
@ -0,0 +1,15 @@
|
|||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.geometry.core.utils.get_polygon_center">get_polygon_center</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.geometry.utils.get_polygon_center
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.geometry.core.Position">Position</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
|
|
@ -6,25 +6,37 @@ status: new
|
|||
# Image Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ImageSink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>crop_image</h2>
|
||||
<h2><a href="#supervision.utils.image.crop_image">crop_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.crop_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>resize_image</h2>
|
||||
<h2><a href="#supervision.utils.image.scale_image">crop_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.scale_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.resize_image">resize_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.resize_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>place_image</h2>
|
||||
<h2><a href="#supervision.utils.image.letterbox_image">letterbox_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.place_image
|
||||
:::supervision.utils.image.letterbox_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.overlay_image">overlay_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.overlay_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.ImageSink">ImageSink</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
|
|
|||
|
|
@ -0,0 +1,18 @@
|
|||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Iterables Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.iterables.create_batches">create_batches</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.create_batches
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.iterables.fill">fill</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.fill
|
||||
|
|
@ -5,14 +5,13 @@ comments: true
|
|||
# Notebooks Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>plot_image</h2>
|
||||
<h2><a href="#supervision.utils.notebook.plot_image">plot_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>## plot_images_grid
|
||||
</h2>
|
||||
<h2><a href="#supervision.utils.notebook.plot_images_grid">plot_images_grid</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_images_grid
|
||||
|
|
|
|||
|
|
@ -5,31 +5,31 @@ comments: true
|
|||
# Video Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoInfo</h2>
|
||||
<h2><a href="#supervision.utils.video.VideoInfo">VideoInfo</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoInfo
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoSink</h2>
|
||||
<h2><a href="#supervision.utils.video.VideoSink">VideoSink</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>FPSMonitor</h2>
|
||||
<h2><a href="#supervision.utils.video.FPSMonitor">FPSMonitor</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.FPSMonitor
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>get_video_frames_generator</h2>
|
||||
<h2><a href="#supervision.utils.video.get_video_frames_generator">get_video_frames_generator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.get_video_frames_generator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>process_video</h2>
|
||||
<h2><a href="#supervision.utils.video.process_video">process_video</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.process_video
|
||||
|
|
|
|||
|
|
@ -1,31 +1,12 @@
|
|||
# Examples
|
||||
|
||||
This repository is packed with real-world use-cases, provided through Python scripts or
|
||||
interactive notebooks. Browse through to understand how the Supervision library
|
||||
interfaces with diverse applications.
|
||||
Here, you'll find end-to-end examples that show how to solve common computer vision problems using Supervision.
|
||||
|
||||
For more information and examples, visit our [documentation](https://supervision.roboflow.com/develop/annotators/) and explore our [how-to guides](https://supervision.roboflow.com/develop/how_to/detect_and_annotate/) and [cookbooks](https://supervision.roboflow.com/develop/cookbooks/). Join our [Discord](https://discord.com/invite/GbfgXGJ8Bk) and meet other Supervision power users!
|
||||
|
||||
- [tracking](./tracking) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [count people in zone](./count_people_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [traffic analysis](./traffic_analysis) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [speed estimation](./speed_estimation) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [time in zone](./time_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [heatmap and track](./heatmap_and_track/) by [@HinePo](https://github.com/HinePo)
|
||||
|
||||
## Contributing
|
||||
|
||||
We welcome contributions from the community in the form of examples, applications, and
|
||||
guides. To contribute, please follow these steps:
|
||||
|
||||
1. Create a pull request (PR) with the `[Example]` prefix in the title, adding your
|
||||
project folder to the `examples/` directory in the repository.
|
||||
2. Confirm your project aligns with the following standards:
|
||||
- Incorporates the `supervision` package.
|
||||
- Provides a `README.md` file, detailing the instructions to execute the project.
|
||||
- Showcases visual results, demonstrating the app's functionality.
|
||||
- Avoids adding large assets or dependencies unless absolutely necessary.
|
||||
- The contributor is expected to provide support for issues related to their
|
||||
examples.
|
||||
- In case the presented model has licensing complications, kindly specify them to
|
||||
circumvent potential misunderstandings.
|
||||
|
||||
For inquiries or concerns about these prerequisites, feel free to raise a PR. We are
|
||||
committed to assist and guide you.
|
||||
|
|
|
|||
|
|
@ -1,5 +1,8 @@
|
|||
# count people in zone
|
||||
|
||||
[](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-detect-and-count-objects-in-polygon-zone.ipynb)
|
||||
[](https://www.youtube.com/watch?v=l_kf9CfZ_8M)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This demo is a video analysis tool that counts and highlights objects in specific zones
|
||||
|
|
|
|||
|
|
@ -1,5 +1,5 @@
|
|||
gdown
|
||||
inference
|
||||
supervision
|
||||
supervision==0.19.0
|
||||
tqdm
|
||||
ultralytics
|
||||
|
|
|
|||
|
|
@ -1,2 +1,2 @@
|
|||
supervision[assets]
|
||||
supervision[assets]==0.19.0
|
||||
ultralytics
|
||||
|
|
|
|||
|
|
@ -1,4 +1,4 @@
|
|||
supervision==0.18.0rc1
|
||||
supervision==0.19.0
|
||||
tqdm==4.66.1
|
||||
requests
|
||||
ultralytics==8.0.237
|
||||
|
|
|
|||
|
|
@ -0,0 +1,9 @@
|
|||
data/
|
||||
venv*/
|
||||
*.pt
|
||||
*.pth
|
||||
*.mp4
|
||||
*.mov
|
||||
*.png
|
||||
*.jpg
|
||||
*.jpeg
|
||||
|
|
@ -0,0 +1,264 @@
|
|||
# time in zone
|
||||
|
||||
[](https://www.youtube.com/watch?v=hAWpsIuem10)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
Practical demonstration on leveraging computer vision for analyzing wait times and
|
||||
monitoring the duration that objects or individuals spend in predefined areas of video
|
||||
frames. This example project, perfect for retail analytics or traffic management
|
||||
applications.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d051cc8a-dd15-41d4-aa36-d38b86334c39
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/time_in_zone
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 🛠 scripts
|
||||
|
||||
### `download_from_youtube`
|
||||
|
||||
This script allows you to download a video from YouTube.
|
||||
|
||||
- `--url`: The full URL of the YouTube video you wish to download.
|
||||
- `--output_path` (optional): Specifies the directory where the video will be saved.
|
||||
- `--file_name` (optional): Sets the name of the saved video file.
|
||||
|
||||
```bash
|
||||
python scripts/download_from_youtube.py \
|
||||
--url "https://www.youtube.com/watch?v=-8zyEwAa50Q" \
|
||||
--output_path "data/checkout" \
|
||||
--file_name "video.mp4"
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/download_from_youtube.py \
|
||||
--url "https://www.youtube.com/watch?v=MNn9qKG2UFI" \
|
||||
--output_path "data/traffic" \
|
||||
--file_name "video.mp4"
|
||||
```
|
||||
|
||||
### `stream_from_file`
|
||||
|
||||
This script allows you to stream video files from a directory. It's an awesome way to
|
||||
mock a live video stream for local testing. Video will be streamed in a loop under
|
||||
`rtsp://localhost:8554/live0.stream` URL. This script requires docker to be installed.
|
||||
|
||||
- `--video_directory`: Directory containing video files to stream.
|
||||
- `--number_of_streams`: Number of video files to stream.
|
||||
|
||||
```bash
|
||||
python scripts/stream_from_file.py \
|
||||
--video_directory "data/checkout" \
|
||||
--number_of_streams 1
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/stream_from_file.py \
|
||||
--video_directory "data/traffic" \
|
||||
--number_of_streams 1
|
||||
```
|
||||
|
||||
### `draw_zones`
|
||||
|
||||
If you want to test zone time in zone analysis on your own video, you can use this
|
||||
script to design custom zones and save results as a JSON file. The script will open a
|
||||
window where you can draw polygons on the source image or video file. The polygons will
|
||||
be saved as a JSON file.
|
||||
|
||||
- `--source_path`: Path to the source image or video file for drawing polygons.
|
||||
- `--zone_configuration_path`: Path where the polygon annotations will be saved as a JSON file.
|
||||
|
||||
|
||||
- `enter` - finish drawing the current polygon.
|
||||
- `escape` - cancel drawing the current polygon.
|
||||
- `q` - quit the drawing window.
|
||||
- `s` - save zone configuration to a JSON file.
|
||||
|
||||
```bash
|
||||
python scripts/draw_zones.py \
|
||||
--source_path "data/checkout/video.mp4" \
|
||||
--zone_configuration_path "data/checkout/config.json"
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/draw_zones.py \
|
||||
--source_path "data/traffic/video.mp4" \
|
||||
--zone_configuration_path "data/traffic/custom_config.json"
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/9d514c9e-2a61-418b-ae49-6ac1ad6ae5ac
|
||||
|
||||
## 🎬 video & stream processing
|
||||
|
||||
### `inference_file_example`
|
||||
|
||||
Script to run object detection on a video file using the Roboflow Inference model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--source_video_path`: Path to the source video file.
|
||||
- `--model_id`: Roboflow model ID.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--source_video_path "data/checkout/video.mp4" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d051cc8a-dd15-41d4-aa36-d38b86334c39
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--source_video_path "data/traffic/video.mp4" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/5ec896d7-4b39-4426-8979-11e71666878b
|
||||
|
||||
### `inference_stream_example`
|
||||
|
||||
Script to run object detection on a video stream using the Roboflow Inference model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--rtsp_url`: Complete RTSP URL for the video stream.
|
||||
- `--model_id`: Roboflow model ID.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>👉 show ultralytics examples</summary>
|
||||
|
||||
### `ultralytics_file_example`
|
||||
|
||||
Script to run object detection on a video file using the Ultralytics YOLOv8 model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--source_video_path`: Path to the source video file.
|
||||
- `--weights`: Path to the model weights file. Default is `'yolov8s.pt'`.
|
||||
- `--device`: Computation device (`'cpu'`, `'mps'` or `'cuda'`). Default is `'cpu'`.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--source_video_path "data/checkout/video.mp4" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--source_video_path "data/traffic/video.mp4" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
### `ultralytics_stream_example`
|
||||
|
||||
Script to run object detection on a video stream using the Ultralytics YOLOv8 model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--rtsp_url`: Complete RTSP URL for the video stream.
|
||||
- `--weights`: Path to the model weights file. Default is `'yolov8s.pt'`.
|
||||
- `--device`: Computation device (`'cpu'`, `'mps'` or `'cuda'`). Default is `'cpu'`.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
|
|
@ -0,0 +1,132 @@
|
|||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import get_model
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import FPSBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
source_video_path: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = get_model(model_id=model_id)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(source_video_path)
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [FPSBasedTimer(video_info.fps) for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
results = model.infer(frame, confidence=confidence, iou_threshold=iou)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using video file."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source video file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
source_video_path=args.source_video_path,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
|
|
@ -0,0 +1,142 @@
|
|||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import get_model
|
||||
from utils.general import find_in_list, get_stream_frames_generator, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = get_model(model_id=model_id)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url)
|
||||
fps_monitor = sv.FPSMonitor()
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [ClockBasedTimer() for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
fps_monitor.tick()
|
||||
fps = fps_monitor.fps
|
||||
|
||||
results = model.infer(frame, confidence=confidence, iou_threshold=iou)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
|
|
@ -0,0 +1,158 @@
|
|||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import InferencePipeline
|
||||
from inference.core.interfaces.camera.entities import VideoFrame
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
class CustomSink:
|
||||
def __init__(self, zone_configuration_path: str, classes: List[int]):
|
||||
self.classes = classes
|
||||
self.tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
self.polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
self.timers = [ClockBasedTimer() for _ in self.polygons]
|
||||
self.zones = None
|
||||
|
||||
def on_prediction(self, result: dict, frame: VideoFrame) -> None:
|
||||
if self.zones is None:
|
||||
resolution_wh = frame.image.shape[1], frame.image.shape[0]
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
self.fps_monitor.tick()
|
||||
fps = self.fps_monitor.fps
|
||||
|
||||
detections = sv.Detections.from_inference(result)
|
||||
detections = detections[find_in_list(detections.class_id, self.classes)]
|
||||
detections = self.tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.image.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(self.zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = self.timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
cv2.waitKey(1)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
sink = CustomSink(zone_configuration_path=zone_configuration_path, classes=classes)
|
||||
|
||||
pipeline = InferencePipeline.init(
|
||||
model_id=model_id,
|
||||
video_reference=rtsp_url,
|
||||
on_prediction=sink.on_prediction,
|
||||
confidence=confidence,
|
||||
iou_threshold=iou,
|
||||
)
|
||||
|
||||
pipeline.start()
|
||||
|
||||
try:
|
||||
pipeline.join()
|
||||
except KeyboardInterrupt:
|
||||
pipeline.terminate()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
|
|
@ -0,0 +1,5 @@
|
|||
opencv-python
|
||||
supervision
|
||||
ultralytics
|
||||
inference
|
||||
pytube
|
||||
|
|
@ -0,0 +1,46 @@
|
|||
import argparse
|
||||
import os
|
||||
from typing import Optional
|
||||
|
||||
from pytube import YouTube
|
||||
|
||||
|
||||
def main(url: str, output_path: Optional[str], file_name: Optional[str]) -> None:
|
||||
yt = YouTube(url)
|
||||
stream = yt.streams.get_highest_resolution()
|
||||
|
||||
if not os.path.exists(output_path):
|
||||
os.makedirs(output_path)
|
||||
|
||||
stream.download(output_path=output_path, filename=file_name)
|
||||
final_name = file_name if file_name else yt.title
|
||||
final_path = output_path if output_path else "current directory"
|
||||
print(f"Download completed! Video saved as '{final_name}' in '{final_path}'.")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Download a specific YouTube video by providing its URL."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="The full URL of the YouTube video you wish to download.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--output_path",
|
||||
type=str,
|
||||
default="data/source",
|
||||
required=False,
|
||||
help="Optional. Specifies the directory where the video will be saved.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--file_name",
|
||||
type=str,
|
||||
default="video.mp4",
|
||||
required=False,
|
||||
help="Optional. Sets the name of the saved video file.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
main(url=args.url, output_path=args.output_path, file_name=args.file_name)
|
||||
|
|
@ -0,0 +1,176 @@
|
|||
import argparse
|
||||
import json
|
||||
import os
|
||||
from typing import Any, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
import supervision as sv
|
||||
|
||||
KEY_ENTER = 13
|
||||
KEY_NEWLINE = 10
|
||||
KEY_ESCAPE = 27
|
||||
KEY_QUIT = ord("q")
|
||||
KEY_SAVE = ord("s")
|
||||
|
||||
THICKNESS = 2
|
||||
COLORS = sv.ColorPalette.DEFAULT
|
||||
WINDOW_NAME = "Draw Zones"
|
||||
POLYGONS = [[]]
|
||||
|
||||
current_mouse_position: Optional[Tuple[int, int]] = None
|
||||
|
||||
|
||||
def resolve_source(source_path: str) -> Optional[np.ndarray]:
|
||||
if not os.path.exists(source_path):
|
||||
return None
|
||||
|
||||
image = cv2.imread(source_path)
|
||||
if image is not None:
|
||||
return image
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=source_path)
|
||||
frame = next(frame_generator)
|
||||
return frame
|
||||
|
||||
|
||||
def mouse_event(event: int, x: int, y: int, flags: int, param: Any) -> None:
|
||||
global current_mouse_position
|
||||
if event == cv2.EVENT_MOUSEMOVE:
|
||||
current_mouse_position = (x, y)
|
||||
elif event == cv2.EVENT_LBUTTONDOWN:
|
||||
POLYGONS[-1].append((x, y))
|
||||
|
||||
|
||||
def redraw(image: np.ndarray, original_image: np.ndarray) -> None:
|
||||
global POLYGONS, current_mouse_position
|
||||
image[:] = original_image.copy()
|
||||
for idx, polygon in enumerate(POLYGONS):
|
||||
color = (
|
||||
COLORS.by_idx(idx).as_bgr()
|
||||
if idx < len(POLYGONS) - 1
|
||||
else sv.Color.WHITE.as_bgr()
|
||||
)
|
||||
|
||||
if len(polygon) > 1:
|
||||
for i in range(1, len(polygon)):
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[i - 1],
|
||||
pt2=polygon[i],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
if idx < len(POLYGONS) - 1:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=polygon[0],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
if idx == len(POLYGONS) - 1 and current_mouse_position is not None and polygon:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=current_mouse_position,
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
|
||||
|
||||
def close_and_finalize_polygon(image: np.ndarray, original_image: np.ndarray) -> None:
|
||||
if len(POLYGONS[-1]) > 2:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=POLYGONS[-1][-1],
|
||||
pt2=POLYGONS[-1][0],
|
||||
color=COLORS.by_idx(0).as_bgr(),
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
POLYGONS.append([])
|
||||
image[:] = original_image.copy()
|
||||
redraw_polygons(image)
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
|
||||
|
||||
def redraw_polygons(image: np.ndarray) -> None:
|
||||
for idx, polygon in enumerate(POLYGONS[:-1]):
|
||||
if len(polygon) > 1:
|
||||
color = COLORS.by_idx(idx).as_bgr()
|
||||
for i in range(len(polygon) - 1):
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[i],
|
||||
pt2=polygon[i + 1],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=polygon[0],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
|
||||
|
||||
def save_polygons_to_json(polygons, target_path):
|
||||
data_to_save = polygons if polygons[-1] else polygons[:-1]
|
||||
with open(target_path, "w") as f:
|
||||
json.dump(data_to_save, f)
|
||||
|
||||
|
||||
def main(source_path: str, zone_configuration_path: str) -> None:
|
||||
global current_mouse_position
|
||||
original_image = resolve_source(source_path=source_path)
|
||||
if original_image is None:
|
||||
print("Failed to load source image.")
|
||||
return
|
||||
|
||||
image = original_image.copy()
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
cv2.setMouseCallback(WINDOW_NAME, mouse_event, image)
|
||||
|
||||
while True:
|
||||
key = cv2.waitKey(1) & 0xFF
|
||||
if key == KEY_ENTER or key == KEY_NEWLINE:
|
||||
close_and_finalize_polygon(image, original_image)
|
||||
elif key == KEY_ESCAPE:
|
||||
POLYGONS[-1] = []
|
||||
current_mouse_position = None
|
||||
elif key == KEY_SAVE:
|
||||
save_polygons_to_json(POLYGONS, zone_configuration_path)
|
||||
print(f"Polygons saved to {zone_configuration_path}")
|
||||
break
|
||||
redraw(image, original_image)
|
||||
if key == KEY_QUIT:
|
||||
break
|
||||
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Interactively draw polygons on images or video frames and save "
|
||||
"the annotations."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source image or video file for drawing polygons.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path where the polygon annotations will be saved as a JSON file.",
|
||||
)
|
||||
arguments = parser.parse_args()
|
||||
main(
|
||||
source_path=arguments.source_path,
|
||||
zone_configuration_path=arguments.zone_configuration_path,
|
||||
)
|
||||
|
|
@ -0,0 +1,104 @@
|
|||
import argparse
|
||||
import os
|
||||
import subprocess
|
||||
import tempfile
|
||||
from glob import glob
|
||||
from threading import Thread
|
||||
|
||||
import yaml
|
||||
|
||||
SERVER_CONFIG = {"protocols": ["tcp"], "paths": {"all": {"source": "publisher"}}}
|
||||
BASE_STREAM_URL = "rtsp://localhost:8554/live"
|
||||
|
||||
|
||||
def main(video_directory: str, number_of_streams: int) -> None:
|
||||
video_files = find_video_files_in_directory(video_directory, number_of_streams)
|
||||
try:
|
||||
with tempfile.TemporaryDirectory() as temporary_directory:
|
||||
config_file_path = create_server_config_file(temporary_directory)
|
||||
run_rtsp_server(config_path=config_file_path)
|
||||
stream_videos(video_files)
|
||||
finally:
|
||||
stop_rtsp_server()
|
||||
|
||||
|
||||
def find_video_files_in_directory(directory: str, limit: int) -> list:
|
||||
video_formats = ["*.mp4", "*.webm"]
|
||||
video_paths = []
|
||||
for video_format in video_formats:
|
||||
video_paths.extend(glob(os.path.join(directory, video_format)))
|
||||
return video_paths[:limit]
|
||||
|
||||
|
||||
def create_server_config_file(directory: str) -> str:
|
||||
config_path = os.path.join(directory, "rtsp-simple-server.yml")
|
||||
with open(config_path, "w") as config_file:
|
||||
yaml.dump(SERVER_CONFIG, config_file)
|
||||
return config_path
|
||||
|
||||
|
||||
def run_rtsp_server(config_path: str) -> None:
|
||||
command = (
|
||||
"docker run --rm --name rtsp_server -d -v "
|
||||
f"{config_path}:/rtsp-simple-server.yml -p 8554:8554 "
|
||||
"aler9/rtsp-simple-server:v1.3.0"
|
||||
)
|
||||
if run_command(command.split()) != 0:
|
||||
raise RuntimeError("Could not start the RTSP server!")
|
||||
|
||||
|
||||
def stop_rtsp_server() -> None:
|
||||
run_command("docker kill rtsp_server".split())
|
||||
|
||||
|
||||
def stream_videos(video_files: list) -> None:
|
||||
threads = []
|
||||
for index, video_file in enumerate(video_files):
|
||||
stream_url = f"{BASE_STREAM_URL}{index}.stream"
|
||||
print(f"Streaming {video_file} under {stream_url}")
|
||||
thread = stream_video_to_url(video_file, stream_url)
|
||||
threads.append(thread)
|
||||
for thread in threads:
|
||||
thread.join()
|
||||
|
||||
|
||||
def stream_video_to_url(video_path: str, stream_url: str) -> Thread:
|
||||
command = (
|
||||
f"ffmpeg -re -stream_loop -1 -i {video_path} "
|
||||
f"-f rtsp -rtsp_transport tcp {stream_url}"
|
||||
)
|
||||
return run_command_in_thread(command.split())
|
||||
|
||||
|
||||
def run_command_in_thread(command: list) -> Thread:
|
||||
thread = Thread(target=run_command, args=(command,))
|
||||
thread.start()
|
||||
return thread
|
||||
|
||||
|
||||
def run_command(command: list) -> int:
|
||||
process = subprocess.run(command)
|
||||
return process.returncode
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Script to stream videos using RTSP protocol."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--video_directory",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Directory containing video files to stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--number_of_streams",
|
||||
type=int,
|
||||
default=6,
|
||||
help="Number of video files to stream.",
|
||||
)
|
||||
arguments = parser.parse_args()
|
||||
main(
|
||||
video_directory=arguments.video_directory,
|
||||
number_of_streams=arguments.number_of_streams,
|
||||
)
|
||||
|
|
@ -0,0 +1,144 @@
|
|||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import FPSBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
source_video_path: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(source_video_path)
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [FPSBasedTimer(video_info.fps) for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
results = model(frame, verbose=False, device=device, conf=confidence)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = detections.with_nms(threshold=iou)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using video file."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source video file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
source_video_path=args.source_video_path,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
|
|
@ -0,0 +1,154 @@
|
|||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, get_stream_frames_generator, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url)
|
||||
fps_monitor = sv.FPSMonitor()
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [ClockBasedTimer() for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
fps_monitor.tick()
|
||||
fps = fps_monitor.fps
|
||||
|
||||
results = model(frame, verbose=False, device=device, conf=confidence)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = detections.with_nms(threshold=iou)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
|
|
@ -0,0 +1,173 @@
|
|||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import InferencePipeline
|
||||
from inference.core.interfaces.camera.entities import VideoFrame
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
class CustomSink:
|
||||
def __init__(self, zone_configuration_path: str, classes: List[int]):
|
||||
self.classes = classes
|
||||
self.tracker = sv.ByteTrack(minimum_matching_threshold=0.8)
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
self.polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
self.timers = [ClockBasedTimer() for _ in self.polygons]
|
||||
self.zones = None
|
||||
|
||||
def on_prediction(self, detections: sv.Detections, frame: VideoFrame) -> None:
|
||||
if self.zones is None:
|
||||
resolution_wh = frame.image.shape[1], frame.image.shape[0]
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
self.fps_monitor.tick()
|
||||
fps = self.fps_monitor.fps
|
||||
|
||||
detections = detections[find_in_list(detections.class_id, self.classes)]
|
||||
detections = self.tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.image.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(self.zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = self.timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
cv2.waitKey(1)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
|
||||
def inference_callback(frame: VideoFrame) -> sv.Detections:
|
||||
results = model(frame.image, verbose=False, conf=confidence, device=device)[0]
|
||||
return sv.Detections.from_ultralytics(results).with_nms(threshold=iou)
|
||||
|
||||
sink = CustomSink(zone_configuration_path=zone_configuration_path, classes=classes)
|
||||
|
||||
pipeline = InferencePipeline.init_with_custom_logic(
|
||||
video_reference=rtsp_url,
|
||||
on_video_frame=inference_callback,
|
||||
on_prediction=sink.on_prediction,
|
||||
)
|
||||
|
||||
pipeline.start()
|
||||
|
||||
try:
|
||||
pipeline.join()
|
||||
except KeyboardInterrupt:
|
||||
pipeline.terminate()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
|
|
@ -0,0 +1,66 @@
|
|||
import json
|
||||
from typing import Generator, List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
This function reads a JSON file which contains polygon coordinates, and
|
||||
converts them into a list of NumPy arrays. Each polygon is represented as
|
||||
a NumPy array of coordinates.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the JSON configuration file.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data]
|
||||
|
||||
|
||||
def find_in_list(array: np.ndarray, search_list: List[int]) -> np.ndarray:
|
||||
"""Determines if elements of a numpy array are present in a list.
|
||||
|
||||
Args:
|
||||
array (np.ndarray): The numpy array of integers to check.
|
||||
search_list (List[int]): The list of integers to search within.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of booleans, where each boolean indicates whether
|
||||
the corresponding element in `array` is found in `search_list`.
|
||||
"""
|
||||
if not search_list:
|
||||
return np.ones(array.shape, dtype=bool)
|
||||
else:
|
||||
return np.isin(array, search_list)
|
||||
|
||||
|
||||
def get_stream_frames_generator(rtsp_url: str) -> Generator[np.ndarray, None, None]:
|
||||
"""
|
||||
Generator function to yield frames from an RTSP stream.
|
||||
|
||||
Args:
|
||||
rtsp_url (str): URL of the RTSP video stream.
|
||||
|
||||
Yields:
|
||||
np.ndarray: The next frame from the video stream.
|
||||
"""
|
||||
cap = cv2.VideoCapture(rtsp_url)
|
||||
if not cap.isOpened():
|
||||
raise Exception("Error: Could not open video stream.")
|
||||
|
||||
try:
|
||||
while True:
|
||||
ret, frame = cap.read()
|
||||
if not ret:
|
||||
print("End of stream or error reading frame.")
|
||||
break
|
||||
yield frame
|
||||
finally:
|
||||
cap.release()
|
||||
|
|
@ -0,0 +1,88 @@
|
|||
from datetime import datetime
|
||||
from typing import Dict
|
||||
|
||||
import numpy as np
|
||||
|
||||
import supervision as sv
|
||||
|
||||
|
||||
class FPSBasedTimer:
|
||||
"""
|
||||
A timer that calculates the duration each object has been detected based on frames
|
||||
per second (FPS).
|
||||
|
||||
Attributes:
|
||||
fps (int): The frame rate of the video stream, used to calculate time durations.
|
||||
frame_id (int): The current frame number in the sequence.
|
||||
tracker_id2frame_id (Dict[int, int]): Maps each tracker's ID to the frame number
|
||||
at which it was first detected.
|
||||
"""
|
||||
|
||||
def __init__(self, fps: int = 30) -> None:
|
||||
"""Initializes the FPSBasedTimer with the specified frames per second rate.
|
||||
|
||||
Args:
|
||||
fps (int, optional): The frame rate of the video stream. Defaults to 30.
|
||||
"""
|
||||
self.fps = fps
|
||||
self.frame_id = 0
|
||||
self.tracker_id2frame_id: Dict[int, int] = {}
|
||||
|
||||
def tick(self, detections: sv.Detections) -> np.ndarray:
|
||||
"""Processes the current frame, updating time durations for each tracker.
|
||||
|
||||
Args:
|
||||
detections: The detections for the current frame, including tracker IDs.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Time durations (in seconds) for each detected tracker, since
|
||||
their first detection.
|
||||
"""
|
||||
self.frame_id += 1
|
||||
times = []
|
||||
|
||||
for tracker_id in detections.tracker_id:
|
||||
self.tracker_id2frame_id.setdefault(tracker_id, self.frame_id)
|
||||
|
||||
start_frame_id = self.tracker_id2frame_id[tracker_id]
|
||||
time_duration = (self.frame_id - start_frame_id) / self.fps
|
||||
times.append(time_duration)
|
||||
|
||||
return np.array(times)
|
||||
|
||||
|
||||
class ClockBasedTimer:
|
||||
"""
|
||||
A timer that calculates the duration each object has been detected based on the
|
||||
system clock.
|
||||
|
||||
Attributes:
|
||||
tracker_id2start_time (Dict[int, datetime]): Maps each tracker's ID to the
|
||||
datetime when it was first detected.
|
||||
"""
|
||||
|
||||
def __init__(self) -> None:
|
||||
"""Initializes the ClockBasedTimer."""
|
||||
self.tracker_id2start_time: Dict[int, datetime] = {}
|
||||
|
||||
def tick(self, detections: sv.Detections) -> np.ndarray:
|
||||
"""Processes the current frame, updating time durations for each tracker.
|
||||
|
||||
Args:
|
||||
detections: The detections for the current frame, including tracker IDs.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Time durations (in seconds) for each detected tracker, since
|
||||
their first detection.
|
||||
"""
|
||||
current_time = datetime.now()
|
||||
times = []
|
||||
|
||||
for tracker_id in detections.tracker_id:
|
||||
self.tracker_id2start_time.setdefault(tracker_id, current_time)
|
||||
|
||||
start_time = self.tracker_id2start_time[tracker_id]
|
||||
time_duration = (current_time - start_time).total_seconds()
|
||||
times.append(time_duration)
|
||||
|
||||
return np.array(times)
|
||||
|
|
@ -1,4 +1,4 @@
|
|||
inference
|
||||
supervision
|
||||
supervision==0.19.0
|
||||
tqdm
|
||||
ultralytics
|
||||
|
|
|
|||
|
|
@ -1,5 +1,5 @@
|
|||
gdown
|
||||
inference
|
||||
supervision>=0.19.0rc5
|
||||
supervision>=0.19.0
|
||||
tqdm
|
||||
ultralytics
|
||||
|
|
|
|||
27
mkdocs.yml
|
|
@ -38,15 +38,22 @@ nav:
|
|||
- Home: index.md
|
||||
- How to:
|
||||
- Detect and Annotate: how_to/detect_and_annotate.md
|
||||
- Track Objects: how_to/track_objects.md
|
||||
- Save Detections: how_to/save_detections.md
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
- Detect Small Objects: how_to/detect_small_objects.md
|
||||
- Track Objects: how_to/track_objects.md
|
||||
|
||||
- API:
|
||||
- Annotators: annotators.md
|
||||
- Classifications:
|
||||
- Core: classification/core.md
|
||||
- Detections:
|
||||
- Detection and Segmentation:
|
||||
- Core: detection/core.md
|
||||
- Annotators: detection/annotators.md
|
||||
- Metrics: detection/metrics.md
|
||||
- Utils: detection/utils.md
|
||||
- Keypoint Detection:
|
||||
- Core: keypoint/core.md
|
||||
- Annotators: keypoint/annotators.md
|
||||
- Classification:
|
||||
- Core: classification/core.md
|
||||
- Tools:
|
||||
- Line Zone: detection/tools/line_zone.md
|
||||
- Polygon Zone: detection/tools/polygon_zone.md
|
||||
|
|
@ -55,18 +62,14 @@ nav:
|
|||
- Save Detections: detection/tools/save_detections.md
|
||||
- Trackers: trackers.md
|
||||
- Datasets: datasets.md
|
||||
- Metrics:
|
||||
- Object Detection: metrics/detection.md
|
||||
- Draw:
|
||||
- Color: draw/color.md
|
||||
- Utils: draw/utils.md
|
||||
- Geometry:
|
||||
- Position: geometry/core.md
|
||||
- Utils:
|
||||
- Video: utils/video.md
|
||||
- Image: utils/image.md
|
||||
- Iterables: utils/iterables.md
|
||||
- Notebook: utils/notebook.md
|
||||
- File: utils/file.md
|
||||
- Draw: utils/draw.md
|
||||
- Geometry: utils/geometry.md
|
||||
- Assets: assets.md
|
||||
- Cookbooks: cookbooks.md
|
||||
- Contribute:
|
||||
|
|
|
|||
|
|
@ -1,4 +1,4 @@
|
|||
# This file is automatically @generated by Poetry 1.7.1 and should not be changed by hand.
|
||||
# This file is automatically @generated by Poetry 1.8.2 and should not be changed by hand.
|
||||
|
||||
[[package]]
|
||||
name = "anyio"
|
||||
|
|
@ -244,26 +244,27 @@ css = ["tinycss2 (>=1.1.0,<1.3)"]
|
|||
|
||||
[[package]]
|
||||
name = "build"
|
||||
version = "1.1.1"
|
||||
version = "1.2.1"
|
||||
description = "A simple, correct Python build frontend"
|
||||
optional = false
|
||||
python-versions = ">= 3.7"
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "build-1.1.1-py3-none-any.whl", hash = "sha256:8ed0851ee76e6e38adce47e4bee3b51c771d86c64cf578d0c2245567ee200e73"},
|
||||
{file = "build-1.1.1.tar.gz", hash = "sha256:8eea65bb45b1aac2e734ba2cc8dad3a6d97d97901a395bd0ed3e7b46953d2a31"},
|
||||
{file = "build-1.2.1-py3-none-any.whl", hash = "sha256:75e10f767a433d9a86e50d83f418e83efc18ede923ee5ff7df93b6cb0306c5d4"},
|
||||
{file = "build-1.2.1.tar.gz", hash = "sha256:526263f4870c26f26c433545579475377b2b7588b6f1eac76a001e873ae3e19d"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
colorama = {version = "*", markers = "os_name == \"nt\""}
|
||||
importlib-metadata = {version = ">=4.6", markers = "python_full_version < \"3.10.2\""}
|
||||
packaging = ">=19.0"
|
||||
packaging = ">=19.1"
|
||||
pyproject_hooks = "*"
|
||||
tomli = {version = ">=1.1.0", markers = "python_version < \"3.11\""}
|
||||
|
||||
[package.extras]
|
||||
docs = ["furo (>=2023.08.17)", "sphinx (>=7.0,<8.0)", "sphinx-argparse-cli (>=1.5)", "sphinx-autodoc-typehints (>=1.10)", "sphinx-issues (>=3.0.0)"]
|
||||
test = ["filelock (>=3)", "pytest (>=6.2.4)", "pytest-cov (>=2.12)", "pytest-mock (>=2)", "pytest-rerunfailures (>=9.1)", "pytest-xdist (>=1.34)", "setuptools (>=42.0.0)", "setuptools (>=56.0.0)", "setuptools (>=56.0.0)", "setuptools (>=67.8.0)", "wheel (>=0.36.0)"]
|
||||
typing = ["importlib-metadata (>=5.1)", "mypy (>=1.5.0,<1.6.0)", "tomli", "typing-extensions (>=3.7.4.3)"]
|
||||
test = ["build[uv,virtualenv]", "filelock (>=3)", "pytest (>=6.2.4)", "pytest-cov (>=2.12)", "pytest-mock (>=2)", "pytest-rerunfailures (>=9.1)", "pytest-xdist (>=1.34)", "setuptools (>=42.0.0)", "setuptools (>=56.0.0)", "setuptools (>=56.0.0)", "setuptools (>=67.8.0)", "wheel (>=0.36.0)"]
|
||||
typing = ["build[uv]", "importlib-metadata (>=5.1)", "mypy (>=1.9.0,<1.10.0)", "tomli", "typing-extensions (>=3.7.4.3)"]
|
||||
uv = ["uv (>=0.1.18)"]
|
||||
virtualenv = ["virtualenv (>=20.0.35)"]
|
||||
|
||||
[[package]]
|
||||
|
|
@ -1121,13 +1122,13 @@ license = ["ukkonen"]
|
|||
|
||||
[[package]]
|
||||
name = "idna"
|
||||
version = "3.6"
|
||||
version = "3.7"
|
||||
description = "Internationalized Domain Names in Applications (IDNA)"
|
||||
optional = false
|
||||
python-versions = ">=3.5"
|
||||
files = [
|
||||
{file = "idna-3.6-py3-none-any.whl", hash = "sha256:c05567e9c24a6b9faaa835c4821bad0590fbb9d5779e7caa6e1cc4978e7eb24f"},
|
||||
{file = "idna-3.6.tar.gz", hash = "sha256:9ecdbbd083b06798ae1e86adcbfe8ab1479cf864e4ee30fe4e46a003d12491ca"},
|
||||
{file = "idna-3.7-py3-none-any.whl", hash = "sha256:82fee1fc78add43492d3a1898bfa6d8a904cc97d8427f683ed8e798d07761aa0"},
|
||||
{file = "idna-3.7.tar.gz", hash = "sha256:028ff3aadf0609c1fd278d8ea3089299412a7a8b9bd005dd08b9f8285bcb5cfc"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
|
|
@ -2161,13 +2162,12 @@ pytz = "*"
|
|||
|
||||
[[package]]
|
||||
name = "mkdocs-jupyter"
|
||||
version = "0.24.3"
|
||||
version = "0.24.7"
|
||||
description = "Use Jupyter in mkdocs websites"
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs_jupyter-0.24.3-py3-none-any.whl", hash = "sha256:904262a8678a5e5920b7c3c03b5010b36301a69d0a38f2fcbf430493adf6879e"},
|
||||
{file = "mkdocs_jupyter-0.24.3.tar.gz", hash = "sha256:3d81da9aea27480e93bab22438910c4f0b9630613e74f85b576590d78e0e8b14"},
|
||||
{file = "mkdocs_jupyter-0.24.7-py3-none-any.whl", hash = "sha256:893d04bea1e007479a46e4e72852cd4d280c4d358ce4a0445250f3f80c639723"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
|
|
@ -2178,18 +2178,15 @@ mkdocs-material = ">9.0.0"
|
|||
nbconvert = ">=7.2.9,<8"
|
||||
pygments = ">2.12.0"
|
||||
|
||||
[package.extras]
|
||||
test = ["coverage[toml]", "pymdown-extensions", "pytest", "pytest-cov"]
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-material"
|
||||
version = "9.5.13"
|
||||
version = "9.5.18"
|
||||
description = "Documentation that simply works"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs_material-9.5.13-py3-none-any.whl", hash = "sha256:5cbe17fee4e3b4980c8420a04cc762d8dc052ef1e10532abd4fce88e5ea9ce6a"},
|
||||
{file = "mkdocs_material-9.5.13.tar.gz", hash = "sha256:d8e4caae576312a88fd2609b81cf43d233cdbe36860d67a68702b018b425bd87"},
|
||||
{file = "mkdocs_material-9.5.18-py3-none-any.whl", hash = "sha256:1e0e27fc9fe239f9064318acf548771a4629d5fd5dfd45444fd80a953fe21eb4"},
|
||||
{file = "mkdocs_material-9.5.18.tar.gz", hash = "sha256:a43f470947053fa2405c33995f282d24992c752a50114f23f30da9d8d0c57e62"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
|
|
@ -2225,13 +2222,13 @@ files = [
|
|||
|
||||
[[package]]
|
||||
name = "mkdocstrings"
|
||||
version = "0.24.1"
|
||||
version = "0.24.3"
|
||||
description = "Automatic documentation from sources, for MkDocs."
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocstrings-0.24.1-py3-none-any.whl", hash = "sha256:b4206f9a2ca8a648e222d5a0ca1d36ba7dee53c88732818de183b536f9042b5d"},
|
||||
{file = "mkdocstrings-0.24.1.tar.gz", hash = "sha256:cc83f9a1c8724fc1be3c2fa071dd73d91ce902ef6a79710249ec8d0ee1064401"},
|
||||
{file = "mkdocstrings-0.24.3-py3-none-any.whl", hash = "sha256:5c9cf2a32958cd161d5428699b79c8b0988856b0d4a8c5baf8395fc1bf4087c3"},
|
||||
{file = "mkdocstrings-0.24.3.tar.gz", hash = "sha256:f327b234eb8d2551a306735436e157d0a22d45f79963c60a8b585d5f7a94c1d2"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
|
|
@ -2360,13 +2357,13 @@ test = ["flaky", "ipykernel (>=6.19.3)", "ipython", "ipywidgets", "nbconvert (>=
|
|||
|
||||
[[package]]
|
||||
name = "nbconvert"
|
||||
version = "7.16.2"
|
||||
version = "7.16.3"
|
||||
description = "Converting Jupyter Notebooks (.ipynb files) to other formats. Output formats include asciidoc, html, latex, markdown, pdf, py, rst, script. nbconvert can be used both as a Python library (`import nbconvert`) or as a command line tool (invoked as `jupyter nbconvert ...`)."
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "nbconvert-7.16.2-py3-none-any.whl", hash = "sha256:0c01c23981a8de0220255706822c40b751438e32467d6a686e26be08ba784382"},
|
||||
{file = "nbconvert-7.16.2.tar.gz", hash = "sha256:8310edd41e1c43947e4ecf16614c61469ebc024898eb808cce0999860fc9fb16"},
|
||||
{file = "nbconvert-7.16.3-py3-none-any.whl", hash = "sha256:ddeff14beeeedf3dd0bc506623e41e4507e551736de59df69a91f86700292b3b"},
|
||||
{file = "nbconvert-7.16.3.tar.gz", hash = "sha256:a6733b78ce3d47c3f85e504998495b07e6ea9cf9bf6ec1c98dda63ec6ad19142"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
|
|
@ -2393,7 +2390,7 @@ docs = ["ipykernel", "ipython", "myst-parser", "nbsphinx (>=0.2.12)", "pydata-sp
|
|||
qtpdf = ["nbconvert[qtpng]"]
|
||||
qtpng = ["pyqtwebengine (>=5.15)"]
|
||||
serve = ["tornado (>=6.1)"]
|
||||
test = ["flaky", "ipykernel", "ipywidgets (>=7.5)", "pytest"]
|
||||
test = ["flaky", "ipykernel", "ipywidgets (>=7.5)", "pytest (>=7)"]
|
||||
webpdf = ["playwright"]
|
||||
|
||||
[[package]]
|
||||
|
|
@ -2469,13 +2466,13 @@ setuptools = "*"
|
|||
|
||||
[[package]]
|
||||
name = "notebook"
|
||||
version = "7.1.2"
|
||||
version = "7.1.3"
|
||||
description = "Jupyter Notebook - A web-based notebook environment for interactive computing"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "notebook-7.1.2-py3-none-any.whl", hash = "sha256:fc6c24b9aef18d0cd57157c9c47e95833b9b0bdc599652639acf0bdb61dc7d5f"},
|
||||
{file = "notebook-7.1.2.tar.gz", hash = "sha256:efc2c80043909e0faa17fce9e9b37c059c03af0ec99a4d4db84cb21d9d2e936a"},
|
||||
{file = "notebook-7.1.3-py3-none-any.whl", hash = "sha256:919b911e59f41f6e3857ce93c9d93535ba66bb090059712770e5968c07e1004d"},
|
||||
{file = "notebook-7.1.3.tar.gz", hash = "sha256:41fcebff44cf7bb9377180808bcbae066629b55d8c7722f1ebbe75ca44f9cfc1"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
|
|
@ -2692,79 +2689,80 @@ files = [
|
|||
|
||||
[[package]]
|
||||
name = "pillow"
|
||||
version = "10.2.0"
|
||||
version = "10.3.0"
|
||||
description = "Python Imaging Library (Fork)"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "pillow-10.2.0-cp310-cp310-macosx_10_10_x86_64.whl", hash = "sha256:7823bdd049099efa16e4246bdf15e5a13dbb18a51b68fa06d6c1d4d8b99a796e"},
|
||||
{file = "pillow-10.2.0-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:83b2021f2ade7d1ed556bc50a399127d7fb245e725aa0113ebd05cfe88aaf588"},
|
||||
{file = "pillow-10.2.0-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:6fad5ff2f13d69b7e74ce5b4ecd12cc0ec530fcee76356cac6742785ff71c452"},
|
||||
{file = "pillow-10.2.0-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:da2b52b37dad6d9ec64e653637a096905b258d2fc2b984c41ae7d08b938a67e4"},
|
||||
{file = "pillow-10.2.0-cp310-cp310-manylinux_2_28_aarch64.whl", hash = "sha256:47c0995fc4e7f79b5cfcab1fc437ff2890b770440f7696a3ba065ee0fd496563"},
|
||||
{file = "pillow-10.2.0-cp310-cp310-manylinux_2_28_x86_64.whl", hash = "sha256:322bdf3c9b556e9ffb18f93462e5f749d3444ce081290352c6070d014c93feb2"},
|
||||
{file = "pillow-10.2.0-cp310-cp310-musllinux_1_1_aarch64.whl", hash = "sha256:51f1a1bffc50e2e9492e87d8e09a17c5eea8409cda8d3f277eb6edc82813c17c"},
|
||||
{file = "pillow-10.2.0-cp310-cp310-musllinux_1_1_x86_64.whl", hash = "sha256:69ffdd6120a4737710a9eee73e1d2e37db89b620f702754b8f6e62594471dee0"},
|
||||
{file = "pillow-10.2.0-cp310-cp310-win32.whl", hash = "sha256:c6dafac9e0f2b3c78df97e79af707cdc5ef8e88208d686a4847bab8266870023"},
|
||||
{file = "pillow-10.2.0-cp310-cp310-win_amd64.whl", hash = "sha256:aebb6044806f2e16ecc07b2a2637ee1ef67a11840a66752751714a0d924adf72"},
|
||||
{file = "pillow-10.2.0-cp310-cp310-win_arm64.whl", hash = "sha256:7049e301399273a0136ff39b84c3678e314f2158f50f517bc50285fb5ec847ad"},
|
||||
{file = "pillow-10.2.0-cp311-cp311-macosx_10_10_x86_64.whl", hash = "sha256:35bb52c37f256f662abdfa49d2dfa6ce5d93281d323a9af377a120e89a9eafb5"},
|
||||
{file = "pillow-10.2.0-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:9c23f307202661071d94b5e384e1e1dc7dfb972a28a2310e4ee16103e66ddb67"},
|
||||
{file = "pillow-10.2.0-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:773efe0603db30c281521a7c0214cad7836c03b8ccff897beae9b47c0b657d61"},
|
||||
{file = "pillow-10.2.0-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:11fa2e5984b949b0dd6d7a94d967743d87c577ff0b83392f17cb3990d0d2fd6e"},
|
||||
{file = "pillow-10.2.0-cp311-cp311-manylinux_2_28_aarch64.whl", hash = "sha256:716d30ed977be8b37d3ef185fecb9e5a1d62d110dfbdcd1e2a122ab46fddb03f"},
|
||||
{file = "pillow-10.2.0-cp311-cp311-manylinux_2_28_x86_64.whl", hash = "sha256:a086c2af425c5f62a65e12fbf385f7c9fcb8f107d0849dba5839461a129cf311"},
|
||||
{file = "pillow-10.2.0-cp311-cp311-musllinux_1_1_aarch64.whl", hash = "sha256:c8de2789052ed501dd829e9cae8d3dcce7acb4777ea4a479c14521c942d395b1"},
|
||||
{file = "pillow-10.2.0-cp311-cp311-musllinux_1_1_x86_64.whl", hash = "sha256:609448742444d9290fd687940ac0b57fb35e6fd92bdb65386e08e99af60bf757"},
|
||||
{file = "pillow-10.2.0-cp311-cp311-win32.whl", hash = "sha256:823ef7a27cf86df6597fa0671066c1b596f69eba53efa3d1e1cb8b30f3533068"},
|
||||
{file = "pillow-10.2.0-cp311-cp311-win_amd64.whl", hash = "sha256:1da3b2703afd040cf65ec97efea81cfba59cdbed9c11d8efc5ab09df9509fc56"},
|
||||
{file = "pillow-10.2.0-cp311-cp311-win_arm64.whl", hash = "sha256:edca80cbfb2b68d7b56930b84a0e45ae1694aeba0541f798e908a49d66b837f1"},
|
||||
{file = "pillow-10.2.0-cp312-cp312-macosx_10_10_x86_64.whl", hash = "sha256:1b5e1b74d1bd1b78bc3477528919414874748dd363e6272efd5abf7654e68bef"},
|
||||
{file = "pillow-10.2.0-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:0eae2073305f451d8ecacb5474997c08569fb4eb4ac231ffa4ad7d342fdc25ac"},
|
||||
{file = "pillow-10.2.0-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:b7c2286c23cd350b80d2fc9d424fc797575fb16f854b831d16fd47ceec078f2c"},
|
||||
{file = "pillow-10.2.0-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:1e23412b5c41e58cec602f1135c57dfcf15482013ce6e5f093a86db69646a5aa"},
|
||||
{file = "pillow-10.2.0-cp312-cp312-manylinux_2_28_aarch64.whl", hash = "sha256:52a50aa3fb3acb9cf7213573ef55d31d6eca37f5709c69e6858fe3bc04a5c2a2"},
|
||||
{file = "pillow-10.2.0-cp312-cp312-manylinux_2_28_x86_64.whl", hash = "sha256:127cee571038f252a552760076407f9cff79761c3d436a12af6000cd182a9d04"},
|
||||
{file = "pillow-10.2.0-cp312-cp312-musllinux_1_1_aarch64.whl", hash = "sha256:8d12251f02d69d8310b046e82572ed486685c38f02176bd08baf216746eb947f"},
|
||||
{file = "pillow-10.2.0-cp312-cp312-musllinux_1_1_x86_64.whl", hash = "sha256:54f1852cd531aa981bc0965b7d609f5f6cc8ce8c41b1139f6ed6b3c54ab82bfb"},
|
||||
{file = "pillow-10.2.0-cp312-cp312-win32.whl", hash = "sha256:257d8788df5ca62c980314053197f4d46eefedf4e6175bc9412f14412ec4ea2f"},
|
||||
{file = "pillow-10.2.0-cp312-cp312-win_amd64.whl", hash = "sha256:154e939c5f0053a383de4fd3d3da48d9427a7e985f58af8e94d0b3c9fcfcf4f9"},
|
||||
{file = "pillow-10.2.0-cp312-cp312-win_arm64.whl", hash = "sha256:f379abd2f1e3dddb2b61bc67977a6b5a0a3f7485538bcc6f39ec76163891ee48"},
|
||||
{file = "pillow-10.2.0-cp38-cp38-macosx_10_10_x86_64.whl", hash = "sha256:8373c6c251f7ef8bda6675dd6d2b3a0fcc31edf1201266b5cf608b62a37407f9"},
|
||||
{file = "pillow-10.2.0-cp38-cp38-macosx_11_0_arm64.whl", hash = "sha256:870ea1ada0899fd0b79643990809323b389d4d1d46c192f97342eeb6ee0b8483"},
|
||||
{file = "pillow-10.2.0-cp38-cp38-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:b4b6b1e20608493548b1f32bce8cca185bf0480983890403d3b8753e44077129"},
|
||||
{file = "pillow-10.2.0-cp38-cp38-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:3031709084b6e7852d00479fd1d310b07d0ba82765f973b543c8af5061cf990e"},
|
||||
{file = "pillow-10.2.0-cp38-cp38-manylinux_2_28_aarch64.whl", hash = "sha256:3ff074fc97dd4e80543a3e91f69d58889baf2002b6be64347ea8cf5533188213"},
|
||||
{file = "pillow-10.2.0-cp38-cp38-manylinux_2_28_x86_64.whl", hash = "sha256:cb4c38abeef13c61d6916f264d4845fab99d7b711be96c326b84df9e3e0ff62d"},
|
||||
{file = "pillow-10.2.0-cp38-cp38-musllinux_1_1_aarch64.whl", hash = "sha256:b1b3020d90c2d8e1dae29cf3ce54f8094f7938460fb5ce8bc5c01450b01fbaf6"},
|
||||
{file = "pillow-10.2.0-cp38-cp38-musllinux_1_1_x86_64.whl", hash = "sha256:170aeb00224ab3dc54230c797f8404507240dd868cf52066f66a41b33169bdbe"},
|
||||
{file = "pillow-10.2.0-cp38-cp38-win32.whl", hash = "sha256:c4225f5220f46b2fde568c74fca27ae9771536c2e29d7c04f4fb62c83275ac4e"},
|
||||
{file = "pillow-10.2.0-cp38-cp38-win_amd64.whl", hash = "sha256:0689b5a8c5288bc0504d9fcee48f61a6a586b9b98514d7d29b840143d6734f39"},
|
||||
{file = "pillow-10.2.0-cp39-cp39-macosx_10_10_x86_64.whl", hash = "sha256:b792a349405fbc0163190fde0dc7b3fef3c9268292586cf5645598b48e63dc67"},
|
||||
{file = "pillow-10.2.0-cp39-cp39-macosx_11_0_arm64.whl", hash = "sha256:c570f24be1e468e3f0ce7ef56a89a60f0e05b30a3669a459e419c6eac2c35364"},
|
||||
{file = "pillow-10.2.0-cp39-cp39-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:d8ecd059fdaf60c1963c58ceb8997b32e9dc1b911f5da5307aab614f1ce5c2fb"},
|
||||
{file = "pillow-10.2.0-cp39-cp39-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:c365fd1703040de1ec284b176d6af5abe21b427cb3a5ff68e0759e1e313a5e7e"},
|
||||
{file = "pillow-10.2.0-cp39-cp39-manylinux_2_28_aarch64.whl", hash = "sha256:70c61d4c475835a19b3a5aa42492409878bbca7438554a1f89d20d58a7c75c01"},
|
||||
{file = "pillow-10.2.0-cp39-cp39-manylinux_2_28_x86_64.whl", hash = "sha256:b6f491cdf80ae540738859d9766783e3b3c8e5bd37f5dfa0b76abdecc5081f13"},
|
||||
{file = "pillow-10.2.0-cp39-cp39-musllinux_1_1_aarch64.whl", hash = "sha256:9d189550615b4948f45252d7f005e53c2040cea1af5b60d6f79491a6e147eef7"},
|
||||
{file = "pillow-10.2.0-cp39-cp39-musllinux_1_1_x86_64.whl", hash = "sha256:49d9ba1ed0ef3e061088cd1e7538a0759aab559e2e0a80a36f9fd9d8c0c21591"},
|
||||
{file = "pillow-10.2.0-cp39-cp39-win32.whl", hash = "sha256:babf5acfede515f176833ed6028754cbcd0d206f7f614ea3447d67c33be12516"},
|
||||
{file = "pillow-10.2.0-cp39-cp39-win_amd64.whl", hash = "sha256:0304004f8067386b477d20a518b50f3fa658a28d44e4116970abfcd94fac34a8"},
|
||||
{file = "pillow-10.2.0-cp39-cp39-win_arm64.whl", hash = "sha256:0fb3e7fc88a14eacd303e90481ad983fd5b69c761e9e6ef94c983f91025da869"},
|
||||
{file = "pillow-10.2.0-pp310-pypy310_pp73-macosx_10_10_x86_64.whl", hash = "sha256:322209c642aabdd6207517e9739c704dc9f9db943015535783239022002f054a"},
|
||||
{file = "pillow-10.2.0-pp310-pypy310_pp73-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:3eedd52442c0a5ff4f887fab0c1c0bb164d8635b32c894bc1faf4c618dd89df2"},
|
||||
{file = "pillow-10.2.0-pp310-pypy310_pp73-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:cb28c753fd5eb3dd859b4ee95de66cc62af91bcff5db5f2571d32a520baf1f04"},
|
||||
{file = "pillow-10.2.0-pp310-pypy310_pp73-manylinux_2_28_aarch64.whl", hash = "sha256:33870dc4653c5017bf4c8873e5488d8f8d5f8935e2f1fb9a2208c47cdd66efd2"},
|
||||
{file = "pillow-10.2.0-pp310-pypy310_pp73-manylinux_2_28_x86_64.whl", hash = "sha256:3c31822339516fb3c82d03f30e22b1d038da87ef27b6a78c9549888f8ceda39a"},
|
||||
{file = "pillow-10.2.0-pp310-pypy310_pp73-win_amd64.whl", hash = "sha256:a2b56ba36e05f973d450582fb015594aaa78834fefe8dfb8fcd79b93e64ba4c6"},
|
||||
{file = "pillow-10.2.0-pp38-pypy38_pp73-win_amd64.whl", hash = "sha256:d8e6aeb9201e655354b3ad049cb77d19813ad4ece0df1249d3c793de3774f8c7"},
|
||||
{file = "pillow-10.2.0-pp39-pypy39_pp73-macosx_10_10_x86_64.whl", hash = "sha256:2247178effb34a77c11c0e8ac355c7a741ceca0a732b27bf11e747bbc950722f"},
|
||||
{file = "pillow-10.2.0-pp39-pypy39_pp73-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:15587643b9e5eb26c48e49a7b33659790d28f190fc514a322d55da2fb5c2950e"},
|
||||
{file = "pillow-10.2.0-pp39-pypy39_pp73-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:753cd8f2086b2b80180d9b3010dd4ed147efc167c90d3bf593fe2af21265e5a5"},
|
||||
{file = "pillow-10.2.0-pp39-pypy39_pp73-manylinux_2_28_aarch64.whl", hash = "sha256:7c8f97e8e7a9009bcacbe3766a36175056c12f9a44e6e6f2d5caad06dcfbf03b"},
|
||||
{file = "pillow-10.2.0-pp39-pypy39_pp73-manylinux_2_28_x86_64.whl", hash = "sha256:d1b35bcd6c5543b9cb547dee3150c93008f8dd0f1fef78fc0cd2b141c5baf58a"},
|
||||
{file = "pillow-10.2.0-pp39-pypy39_pp73-win_amd64.whl", hash = "sha256:fe4c15f6c9285dc54ce6553a3ce908ed37c8f3825b5a51a15c91442bb955b868"},
|
||||
{file = "pillow-10.2.0.tar.gz", hash = "sha256:e87f0b2c78157e12d7686b27d63c070fd65d994e8ddae6f328e0dcf4a0cd007e"},
|
||||
{file = "pillow-10.3.0-cp310-cp310-macosx_10_10_x86_64.whl", hash = "sha256:90b9e29824800e90c84e4022dd5cc16eb2d9605ee13f05d47641eb183cd73d45"},
|
||||
{file = "pillow-10.3.0-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:a2c405445c79c3f5a124573a051062300936b0281fee57637e706453e452746c"},
|
||||
{file = "pillow-10.3.0-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:78618cdbccaa74d3f88d0ad6cb8ac3007f1a6fa5c6f19af64b55ca170bfa1edf"},
|
||||
{file = "pillow-10.3.0-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:261ddb7ca91fcf71757979534fb4c128448b5b4c55cb6152d280312062f69599"},
|
||||
{file = "pillow-10.3.0-cp310-cp310-manylinux_2_28_aarch64.whl", hash = "sha256:ce49c67f4ea0609933d01c0731b34b8695a7a748d6c8d186f95e7d085d2fe475"},
|
||||
{file = "pillow-10.3.0-cp310-cp310-manylinux_2_28_x86_64.whl", hash = "sha256:b14f16f94cbc61215115b9b1236f9c18403c15dd3c52cf629072afa9d54c1cbf"},
|
||||
{file = "pillow-10.3.0-cp310-cp310-musllinux_1_1_aarch64.whl", hash = "sha256:d33891be6df59d93df4d846640f0e46f1a807339f09e79a8040bc887bdcd7ed3"},
|
||||
{file = "pillow-10.3.0-cp310-cp310-musllinux_1_1_x86_64.whl", hash = "sha256:b50811d664d392f02f7761621303eba9d1b056fb1868c8cdf4231279645c25f5"},
|
||||
{file = "pillow-10.3.0-cp310-cp310-win32.whl", hash = "sha256:ca2870d5d10d8726a27396d3ca4cf7976cec0f3cb706debe88e3a5bd4610f7d2"},
|
||||
{file = "pillow-10.3.0-cp310-cp310-win_amd64.whl", hash = "sha256:f0d0591a0aeaefdaf9a5e545e7485f89910c977087e7de2b6c388aec32011e9f"},
|
||||
{file = "pillow-10.3.0-cp310-cp310-win_arm64.whl", hash = "sha256:ccce24b7ad89adb5a1e34a6ba96ac2530046763912806ad4c247356a8f33a67b"},
|
||||
{file = "pillow-10.3.0-cp311-cp311-macosx_10_10_x86_64.whl", hash = "sha256:5f77cf66e96ae734717d341c145c5949c63180842a545c47a0ce7ae52ca83795"},
|
||||
{file = "pillow-10.3.0-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:e4b878386c4bf293578b48fc570b84ecfe477d3b77ba39a6e87150af77f40c57"},
|
||||
{file = "pillow-10.3.0-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:fdcbb4068117dfd9ce0138d068ac512843c52295ed996ae6dd1faf537b6dbc27"},
|
||||
{file = "pillow-10.3.0-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:9797a6c8fe16f25749b371c02e2ade0efb51155e767a971c61734b1bf6293994"},
|
||||
{file = "pillow-10.3.0-cp311-cp311-manylinux_2_28_aarch64.whl", hash = "sha256:9e91179a242bbc99be65e139e30690e081fe6cb91a8e77faf4c409653de39451"},
|
||||
{file = "pillow-10.3.0-cp311-cp311-manylinux_2_28_x86_64.whl", hash = "sha256:1b87bd9d81d179bd8ab871603bd80d8645729939f90b71e62914e816a76fc6bd"},
|
||||
{file = "pillow-10.3.0-cp311-cp311-musllinux_1_1_aarch64.whl", hash = "sha256:81d09caa7b27ef4e61cb7d8fbf1714f5aec1c6b6c5270ee53504981e6e9121ad"},
|
||||
{file = "pillow-10.3.0-cp311-cp311-musllinux_1_1_x86_64.whl", hash = "sha256:048ad577748b9fa4a99a0548c64f2cb8d672d5bf2e643a739ac8faff1164238c"},
|
||||
{file = "pillow-10.3.0-cp311-cp311-win32.whl", hash = "sha256:7161ec49ef0800947dc5570f86568a7bb36fa97dd09e9827dc02b718c5643f09"},
|
||||
{file = "pillow-10.3.0-cp311-cp311-win_amd64.whl", hash = "sha256:8eb0908e954d093b02a543dc963984d6e99ad2b5e36503d8a0aaf040505f747d"},
|
||||
{file = "pillow-10.3.0-cp311-cp311-win_arm64.whl", hash = "sha256:4e6f7d1c414191c1199f8996d3f2282b9ebea0945693fb67392c75a3a320941f"},
|
||||
{file = "pillow-10.3.0-cp312-cp312-macosx_10_10_x86_64.whl", hash = "sha256:e46f38133e5a060d46bd630faa4d9fa0202377495df1f068a8299fd78c84de84"},
|
||||
{file = "pillow-10.3.0-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:50b8eae8f7334ec826d6eeffaeeb00e36b5e24aa0b9df322c247539714c6df19"},
|
||||
{file = "pillow-10.3.0-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:9d3bea1c75f8c53ee4d505c3e67d8c158ad4df0d83170605b50b64025917f338"},
|
||||
{file = "pillow-10.3.0-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:19aeb96d43902f0a783946a0a87dbdad5c84c936025b8419da0a0cd7724356b1"},
|
||||
{file = "pillow-10.3.0-cp312-cp312-manylinux_2_28_aarch64.whl", hash = "sha256:74d28c17412d9caa1066f7a31df8403ec23d5268ba46cd0ad2c50fb82ae40462"},
|
||||
{file = "pillow-10.3.0-cp312-cp312-manylinux_2_28_x86_64.whl", hash = "sha256:ff61bfd9253c3915e6d41c651d5f962da23eda633cf02262990094a18a55371a"},
|
||||
{file = "pillow-10.3.0-cp312-cp312-musllinux_1_1_aarch64.whl", hash = "sha256:d886f5d353333b4771d21267c7ecc75b710f1a73d72d03ca06df49b09015a9ef"},
|
||||
{file = "pillow-10.3.0-cp312-cp312-musllinux_1_1_x86_64.whl", hash = "sha256:4b5ec25d8b17217d635f8935dbc1b9aa5907962fae29dff220f2659487891cd3"},
|
||||
{file = "pillow-10.3.0-cp312-cp312-win32.whl", hash = "sha256:51243f1ed5161b9945011a7360e997729776f6e5d7005ba0c6879267d4c5139d"},
|
||||
{file = "pillow-10.3.0-cp312-cp312-win_amd64.whl", hash = "sha256:412444afb8c4c7a6cc11a47dade32982439925537e483be7c0ae0cf96c4f6a0b"},
|
||||
{file = "pillow-10.3.0-cp312-cp312-win_arm64.whl", hash = "sha256:798232c92e7665fe82ac085f9d8e8ca98826f8e27859d9a96b41d519ecd2e49a"},
|
||||
{file = "pillow-10.3.0-cp38-cp38-macosx_10_10_x86_64.whl", hash = "sha256:4eaa22f0d22b1a7e93ff0a596d57fdede2e550aecffb5a1ef1106aaece48e96b"},
|
||||
{file = "pillow-10.3.0-cp38-cp38-macosx_11_0_arm64.whl", hash = "sha256:cd5e14fbf22a87321b24c88669aad3a51ec052eb145315b3da3b7e3cc105b9a2"},
|
||||
{file = "pillow-10.3.0-cp38-cp38-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:1530e8f3a4b965eb6a7785cf17a426c779333eb62c9a7d1bbcf3ffd5bf77a4aa"},
|
||||
{file = "pillow-10.3.0-cp38-cp38-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:5d512aafa1d32efa014fa041d38868fda85028e3f930a96f85d49c7d8ddc0383"},
|
||||
{file = "pillow-10.3.0-cp38-cp38-manylinux_2_28_aarch64.whl", hash = "sha256:339894035d0ede518b16073bdc2feef4c991ee991a29774b33e515f1d308e08d"},
|
||||
{file = "pillow-10.3.0-cp38-cp38-manylinux_2_28_x86_64.whl", hash = "sha256:aa7e402ce11f0885305bfb6afb3434b3cd8f53b563ac065452d9d5654c7b86fd"},
|
||||
{file = "pillow-10.3.0-cp38-cp38-musllinux_1_1_aarch64.whl", hash = "sha256:0ea2a783a2bdf2a561808fe4a7a12e9aa3799b701ba305de596bc48b8bdfce9d"},
|
||||
{file = "pillow-10.3.0-cp38-cp38-musllinux_1_1_x86_64.whl", hash = "sha256:c78e1b00a87ce43bb37642c0812315b411e856a905d58d597750eb79802aaaa3"},
|
||||
{file = "pillow-10.3.0-cp38-cp38-win32.whl", hash = "sha256:72d622d262e463dfb7595202d229f5f3ab4b852289a1cd09650362db23b9eb0b"},
|
||||
{file = "pillow-10.3.0-cp38-cp38-win_amd64.whl", hash = "sha256:2034f6759a722da3a3dbd91a81148cf884e91d1b747992ca288ab88c1de15999"},
|
||||
{file = "pillow-10.3.0-cp39-cp39-macosx_10_10_x86_64.whl", hash = "sha256:2ed854e716a89b1afcedea551cd85f2eb2a807613752ab997b9974aaa0d56936"},
|
||||
{file = "pillow-10.3.0-cp39-cp39-macosx_11_0_arm64.whl", hash = "sha256:dc1a390a82755a8c26c9964d457d4c9cbec5405896cba94cf51f36ea0d855002"},
|
||||
{file = "pillow-10.3.0-cp39-cp39-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:4203efca580f0dd6f882ca211f923168548f7ba334c189e9eab1178ab840bf60"},
|
||||
{file = "pillow-10.3.0-cp39-cp39-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:3102045a10945173d38336f6e71a8dc71bcaeed55c3123ad4af82c52807b9375"},
|
||||
{file = "pillow-10.3.0-cp39-cp39-manylinux_2_28_aarch64.whl", hash = "sha256:6fb1b30043271ec92dc65f6d9f0b7a830c210b8a96423074b15c7bc999975f57"},
|
||||
{file = "pillow-10.3.0-cp39-cp39-manylinux_2_28_x86_64.whl", hash = "sha256:1dfc94946bc60ea375cc39cff0b8da6c7e5f8fcdc1d946beb8da5c216156ddd8"},
|
||||
{file = "pillow-10.3.0-cp39-cp39-musllinux_1_1_aarch64.whl", hash = "sha256:b09b86b27a064c9624d0a6c54da01c1beaf5b6cadfa609cf63789b1d08a797b9"},
|
||||
{file = "pillow-10.3.0-cp39-cp39-musllinux_1_1_x86_64.whl", hash = "sha256:d3b2348a78bc939b4fed6552abfd2e7988e0f81443ef3911a4b8498ca084f6eb"},
|
||||
{file = "pillow-10.3.0-cp39-cp39-win32.whl", hash = "sha256:45ebc7b45406febf07fef35d856f0293a92e7417ae7933207e90bf9090b70572"},
|
||||
{file = "pillow-10.3.0-cp39-cp39-win_amd64.whl", hash = "sha256:0ba26351b137ca4e0db0342d5d00d2e355eb29372c05afd544ebf47c0956ffeb"},
|
||||
{file = "pillow-10.3.0-cp39-cp39-win_arm64.whl", hash = "sha256:50fd3f6b26e3441ae07b7c979309638b72abc1a25da31a81a7fbd9495713ef4f"},
|
||||
{file = "pillow-10.3.0-pp310-pypy310_pp73-macosx_10_10_x86_64.whl", hash = "sha256:6b02471b72526ab8a18c39cb7967b72d194ec53c1fd0a70b050565a0f366d355"},
|
||||
{file = "pillow-10.3.0-pp310-pypy310_pp73-macosx_11_0_arm64.whl", hash = "sha256:8ab74c06ffdab957d7670c2a5a6e1a70181cd10b727cd788c4dd9005b6a8acd9"},
|
||||
{file = "pillow-10.3.0-pp310-pypy310_pp73-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:048eeade4c33fdf7e08da40ef402e748df113fd0b4584e32c4af74fe78baaeb2"},
|
||||
{file = "pillow-10.3.0-pp310-pypy310_pp73-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:9e2ec1e921fd07c7cda7962bad283acc2f2a9ccc1b971ee4b216b75fad6f0463"},
|
||||
{file = "pillow-10.3.0-pp310-pypy310_pp73-manylinux_2_28_aarch64.whl", hash = "sha256:4c8e73e99da7db1b4cad7f8d682cf6abad7844da39834c288fbfa394a47bbced"},
|
||||
{file = "pillow-10.3.0-pp310-pypy310_pp73-manylinux_2_28_x86_64.whl", hash = "sha256:16563993329b79513f59142a6b02055e10514c1a8e86dca8b48a893e33cf91e3"},
|
||||
{file = "pillow-10.3.0-pp310-pypy310_pp73-win_amd64.whl", hash = "sha256:dd78700f5788ae180b5ee8902c6aea5a5726bac7c364b202b4b3e3ba2d293170"},
|
||||
{file = "pillow-10.3.0-pp39-pypy39_pp73-macosx_10_10_x86_64.whl", hash = "sha256:aff76a55a8aa8364d25400a210a65ff59d0168e0b4285ba6bf2bd83cf675ba32"},
|
||||
{file = "pillow-10.3.0-pp39-pypy39_pp73-macosx_11_0_arm64.whl", hash = "sha256:b7bc2176354defba3edc2b9a777744462da2f8e921fbaf61e52acb95bafa9828"},
|
||||
{file = "pillow-10.3.0-pp39-pypy39_pp73-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:793b4e24db2e8742ca6423d3fde8396db336698c55cd34b660663ee9e45ed37f"},
|
||||
{file = "pillow-10.3.0-pp39-pypy39_pp73-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:d93480005693d247f8346bc8ee28c72a2191bdf1f6b5db469c096c0c867ac015"},
|
||||
{file = "pillow-10.3.0-pp39-pypy39_pp73-manylinux_2_28_aarch64.whl", hash = "sha256:c83341b89884e2b2e55886e8fbbf37c3fa5efd6c8907124aeb72f285ae5696e5"},
|
||||
{file = "pillow-10.3.0-pp39-pypy39_pp73-manylinux_2_28_x86_64.whl", hash = "sha256:1a1d1915db1a4fdb2754b9de292642a39a7fb28f1736699527bb649484fb966a"},
|
||||
{file = "pillow-10.3.0-pp39-pypy39_pp73-win_amd64.whl", hash = "sha256:a0eaa93d054751ee9964afa21c06247779b90440ca41d184aeb5d410f20ff591"},
|
||||
{file = "pillow-10.3.0.tar.gz", hash = "sha256:9d2455fbf44c914840c793e89aa82d0e1763a14253a000743719ae5946814b2d"},
|
||||
]
|
||||
|
||||
[package.extras]
|
||||
|
|
@ -3645,28 +3643,28 @@ files = [
|
|||
|
||||
[[package]]
|
||||
name = "ruff"
|
||||
version = "0.3.2"
|
||||
version = "0.4.1"
|
||||
description = "An extremely fast Python linter and code formatter, written in Rust."
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
files = [
|
||||
{file = "ruff-0.3.2-py3-none-macosx_10_12_x86_64.macosx_11_0_arm64.macosx_10_12_universal2.whl", hash = "sha256:77f2612752e25f730da7421ca5e3147b213dca4f9a0f7e0b534e9562c5441f01"},
|
||||
{file = "ruff-0.3.2-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:9966b964b2dd1107797be9ca7195002b874424d1d5472097701ae8f43eadef5d"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:b83d17ff166aa0659d1e1deaf9f2f14cbe387293a906de09bc4860717eb2e2da"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:bb875c6cc87b3703aeda85f01c9aebdce3d217aeaca3c2e52e38077383f7268a"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:be75e468a6a86426430373d81c041b7605137a28f7014a72d2fc749e47f572aa"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:967978ac2d4506255e2f52afe70dda023fc602b283e97685c8447d036863a302"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:1231eacd4510f73222940727ac927bc5d07667a86b0cbe822024dd00343e77e9"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:2c6d613b19e9a8021be2ee1d0e27710208d1603b56f47203d0abbde906929a9b"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:c8439338a6303585d27b66b4626cbde89bb3e50fa3cae86ce52c1db7449330a7"},
|
||||
{file = "ruff-0.3.2-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:de8b480d8379620cbb5ea466a9e53bb467d2fb07c7eca54a4aa8576483c35d36"},
|
||||
{file = "ruff-0.3.2-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:b74c3de9103bd35df2bb05d8b2899bf2dbe4efda6474ea9681280648ec4d237d"},
|
||||
{file = "ruff-0.3.2-py3-none-musllinux_1_2_i686.whl", hash = "sha256:f380be9fc15a99765c9cf316b40b9da1f6ad2ab9639e551703e581a5e6da6745"},
|
||||
{file = "ruff-0.3.2-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:0ac06a3759c3ab9ef86bbeca665d31ad3aa9a4b1c17684aadb7e61c10baa0df4"},
|
||||
{file = "ruff-0.3.2-py3-none-win32.whl", hash = "sha256:9bd640a8f7dd07a0b6901fcebccedadeb1a705a50350fb86b4003b805c81385a"},
|
||||
{file = "ruff-0.3.2-py3-none-win_amd64.whl", hash = "sha256:0c1bdd9920cab5707c26c8b3bf33a064a4ca7842d91a99ec0634fec68f9f4037"},
|
||||
{file = "ruff-0.3.2-py3-none-win_arm64.whl", hash = "sha256:5f65103b1d76e0d600cabd577b04179ff592064eaa451a70a81085930e907d0b"},
|
||||
{file = "ruff-0.3.2.tar.gz", hash = "sha256:fa78ec9418eb1ca3db392811df3376b46471ae93792a81af2d1cbb0e5dcb5142"},
|
||||
{file = "ruff-0.4.1-py3-none-macosx_10_12_x86_64.macosx_11_0_arm64.macosx_10_12_universal2.whl", hash = "sha256:2d9ef6231e3fbdc0b8c72404a1a0c46fd0dcea84efca83beb4681c318ea6a953"},
|
||||
{file = "ruff-0.4.1-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:9485f54a7189e6f7433e0058cf8581bee45c31a25cd69009d2a040d1bd4bfaef"},
|
||||
{file = "ruff-0.4.1-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:d2921ac03ce1383e360e8a95442ffb0d757a6a7ddd9a5be68561a671e0e5807e"},
|
||||
{file = "ruff-0.4.1-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:eec8d185fe193ad053eda3a6be23069e0c8ba8c5d20bc5ace6e3b9e37d246d3f"},
|
||||
{file = "ruff-0.4.1-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:baa27d9d72a94574d250f42b7640b3bd2edc4c58ac8ac2778a8c82374bb27984"},
|
||||
{file = "ruff-0.4.1-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:f1ee41580bff1a651339eb3337c20c12f4037f6110a36ae4a2d864c52e5ef954"},
|
||||
{file = "ruff-0.4.1-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:0926cefb57fc5fced629603fbd1a23d458b25418681d96823992ba975f050c2b"},
|
||||
{file = "ruff-0.4.1-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:2c6e37f2e3cd74496a74af9a4fa67b547ab3ca137688c484749189bf3a686ceb"},
|
||||
{file = "ruff-0.4.1-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:efd703a5975ac1998c2cc5e9494e13b28f31e66c616b0a76e206de2562e0843c"},
|
||||
{file = "ruff-0.4.1-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:b92f03b4aa9fa23e1799b40f15f8b95cdc418782a567d6c43def65e1bbb7f1cf"},
|
||||
{file = "ruff-0.4.1-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:1c859f294f8633889e7d77de228b203eb0e9a03071b72b5989d89a0cf98ee262"},
|
||||
{file = "ruff-0.4.1-py3-none-musllinux_1_2_i686.whl", hash = "sha256:b34510141e393519a47f2d7b8216fec747ea1f2c81e85f076e9f2910588d4b64"},
|
||||
{file = "ruff-0.4.1-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:6e68d248ed688b9d69fd4d18737edcbb79c98b251bba5a2b031ce2470224bdf9"},
|
||||
{file = "ruff-0.4.1-py3-none-win32.whl", hash = "sha256:b90506f3d6d1f41f43f9b7b5ff845aeefabed6d2494307bc7b178360a8805252"},
|
||||
{file = "ruff-0.4.1-py3-none-win_amd64.whl", hash = "sha256:c7d391e5936af5c9e252743d767c564670dc3889aff460d35c518ee76e4b26d7"},
|
||||
{file = "ruff-0.4.1-py3-none-win_arm64.whl", hash = "sha256:a1eaf03d87e6a7cd5e661d36d8c6e874693cb9bc3049d110bc9a97b350680c43"},
|
||||
{file = "ruff-0.4.1.tar.gz", hash = "sha256:d592116cdbb65f8b1b7e2a2b48297eb865f6bdc20641879aa9d7b9c11d86db79"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
|
|
@ -3942,13 +3940,13 @@ files = [
|
|||
|
||||
[[package]]
|
||||
name = "tox"
|
||||
version = "4.14.1"
|
||||
version = "4.14.2"
|
||||
description = "tox is a generic virtualenv management and test command line tool"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "tox-4.14.1-py3-none-any.whl", hash = "sha256:b03754b6ee6dadc70f2611da82b4ed8f625fcafd247e15d1d0cb056f90a06d3b"},
|
||||
{file = "tox-4.14.1.tar.gz", hash = "sha256:f0ad758c3bbf7e237059c929d3595479363c3cdd5a06ac3e49d1dd020ffbee45"},
|
||||
{file = "tox-4.14.2-py3-none-any.whl", hash = "sha256:2900c4eb7b716af4a928a7fdc2ed248ad6575294ed7cfae2ea41203937422847"},
|
||||
{file = "tox-4.14.2.tar.gz", hash = "sha256:0defb44f6dafd911b61788325741cc6b2e12ea71f987ac025ad4d649f1f1a104"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
|
|
@ -4252,4 +4250,4 @@ desktop = ["opencv-python"]
|
|||
[metadata]
|
||||
lock-version = "2.0"
|
||||
python-versions = "^3.8"
|
||||
content-hash = "30b2e5864f20c0b0cf5ddff7658427a18e18c9d387da86725e8e9288f795086a"
|
||||
content-hash = "56ddae6824a9f28c9954badd4c642c57f687b099c6169f97fa0372e294500c17"
|
||||
|
|
|
|||
|
|
@ -1,6 +1,6 @@
|
|||
[tool.poetry]
|
||||
name = "supervision"
|
||||
version = "0.19.0"
|
||||
version = "0.20.0"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
authors = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
maintainers = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
|
|
@ -54,7 +54,7 @@ assets = ["requests","tqdm"]
|
|||
twine = ">=4.0.2,<6.0.0"
|
||||
pytest = ">=7.2.2,<9.0.0"
|
||||
wheel = ">=0.40,<0.44"
|
||||
build = ">=0.10,<1.2"
|
||||
build = ">=0.10,<1.3"
|
||||
ruff = ">=0.1.0"
|
||||
mypy = "^1.4.1"
|
||||
pre-commit = "^3.3.3"
|
||||
|
|
|
|||
|
|
@ -58,8 +58,8 @@ from supervision.detection.utils import (
|
|||
)
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import (
|
||||
calculate_dynamic_line_thickness,
|
||||
calculate_dynamic_text_scale,
|
||||
calculate_optimal_line_thickness,
|
||||
calculate_optimal_text_scale,
|
||||
draw_filled_rectangle,
|
||||
draw_image,
|
||||
draw_line,
|
||||
|
|
@ -69,10 +69,21 @@ from supervision.draw.utils import (
|
|||
)
|
||||
from supervision.geometry.core import Point, Position, Rect
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.keypoint.annotators import EdgeAnnotator, VertexAnnotator
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.metrics.detection import ConfusionMatrix, MeanAveragePrecision
|
||||
from supervision.tracker.byte_tracker.core import ByteTrack
|
||||
from supervision.utils.conversion import cv2_to_pillow, pillow_to_cv2
|
||||
from supervision.utils.file import list_files_with_extensions
|
||||
from supervision.utils.image import ImageSink, crop_image, place_image, resize_image
|
||||
from supervision.utils.image import (
|
||||
ImageSink,
|
||||
create_tiles,
|
||||
crop_image,
|
||||
letterbox_image,
|
||||
overlay_image,
|
||||
resize_image,
|
||||
scale_image,
|
||||
)
|
||||
from supervision.utils.notebook import plot_image, plot_images_grid
|
||||
from supervision.utils.video import (
|
||||
FPSMonitor,
|
||||
|
|
|
|||
|
|
@ -5,19 +5,15 @@ import cv2
|
|||
import numpy as np
|
||||
|
||||
from supervision.annotators.base import BaseAnnotator, ImageType
|
||||
from supervision.annotators.utils import (
|
||||
ColorLookup,
|
||||
Trace,
|
||||
resolve_color,
|
||||
scene_to_annotator_img_type,
|
||||
)
|
||||
from supervision.annotators.utils import ColorLookup, Trace, resolve_color
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD, ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import clip_boxes, mask_to_polygons
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import draw_polygon
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.utils.image import crop_image, place_image, resize_image
|
||||
from supervision.utils.conversion import convert_for_annotation_method
|
||||
from supervision.utils.image import crop_image, overlay_image, scale_image
|
||||
|
||||
|
||||
class BoundingBoxAnnotator(BaseAnnotator):
|
||||
|
|
@ -43,7 +39,7 @@ class BoundingBoxAnnotator(BaseAnnotator):
|
|||
self.thickness: int = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -124,7 +120,7 @@ class OrientedBoxAnnotator(BaseAnnotator):
|
|||
self.thickness: int = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -212,7 +208,7 @@ class MaskAnnotator(BaseAnnotator):
|
|||
self.opacity = opacity
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -299,7 +295,7 @@ class PolygonAnnotator(BaseAnnotator):
|
|||
self.thickness: int = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -385,7 +381,7 @@ class ColorAnnotator(BaseAnnotator):
|
|||
self.color_lookup: ColorLookup = color_lookup
|
||||
self.opacity = opacity
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -479,7 +475,7 @@ class HaloAnnotator(BaseAnnotator):
|
|||
self.color_lookup: ColorLookup = color_lookup
|
||||
self.kernel_size: int = kernel_size
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -577,7 +573,7 @@ class EllipseAnnotator(BaseAnnotator):
|
|||
self.end_angle: int = end_angle
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -668,7 +664,7 @@ class BoxCornerAnnotator(BaseAnnotator):
|
|||
self.corner_length: int = corner_length
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -756,7 +752,7 @@ class CircleAnnotator(BaseAnnotator):
|
|||
self.thickness: int = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -846,7 +842,7 @@ class DotAnnotator(BaseAnnotator):
|
|||
self.position: Position = position
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -914,6 +910,7 @@ class LabelAnnotator:
|
|||
text_padding: int = 10,
|
||||
text_position: Position = Position.TOP_LEFT,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
border_radius: int = 0,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
|
|
@ -927,7 +924,10 @@ class LabelAnnotator:
|
|||
Possible values are defined in the `Position` enum.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
border_radius (int): The radius to apply round edges. If the selected
|
||||
value is higher than the lower dimension, width or height, is clipped.
|
||||
"""
|
||||
self.border_radius: int = border_radius
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.text_color: Color = text_color
|
||||
self.text_scale: float = text_scale
|
||||
|
|
@ -989,7 +989,7 @@ class LabelAnnotator:
|
|||
center_y + text_h // 2,
|
||||
)
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -1015,15 +1015,22 @@ class LabelAnnotator:
|
|||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
|
||||
|
|
@ -1080,12 +1087,11 @@ class LabelAnnotator:
|
|||
text_x = text_background_xyxy[0] + self.text_padding
|
||||
text_y = text_background_xyxy[1] + self.text_padding + text_h
|
||||
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=(text_background_xyxy[0], text_background_xyxy[1]),
|
||||
pt2=(text_background_xyxy[2], text_background_xyxy[3]),
|
||||
self.draw_rounded_rectangle(
|
||||
scene=scene,
|
||||
xyxy=text_background_xyxy,
|
||||
color=color.as_bgr(),
|
||||
thickness=cv2.FILLED,
|
||||
border_radius=self.border_radius,
|
||||
)
|
||||
cv2.putText(
|
||||
img=scene,
|
||||
|
|
@ -1099,6 +1105,48 @@ class LabelAnnotator:
|
|||
)
|
||||
return scene
|
||||
|
||||
@staticmethod
|
||||
def draw_rounded_rectangle(
|
||||
scene: np.ndarray,
|
||||
xyxy: Tuple[int, int, int, int],
|
||||
color: Tuple[int, int, int],
|
||||
border_radius: int,
|
||||
) -> np.ndarray:
|
||||
x1, y1, x2, y2 = xyxy
|
||||
width = x2 - x1
|
||||
height = y2 - y1
|
||||
|
||||
border_radius = min(border_radius, min(width, height) // 2)
|
||||
|
||||
rectangle_coordinates = [
|
||||
((x1 + border_radius, y1), (x2 - border_radius, y2)),
|
||||
((x1, y1 + border_radius), (x2, y2 - border_radius)),
|
||||
]
|
||||
circle_centers = [
|
||||
(x1 + border_radius, y1 + border_radius),
|
||||
(x2 - border_radius, y1 + border_radius),
|
||||
(x1 + border_radius, y2 - border_radius),
|
||||
(x2 - border_radius, y2 - border_radius),
|
||||
]
|
||||
|
||||
for coordinates in rectangle_coordinates:
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=coordinates[0],
|
||||
pt2=coordinates[1],
|
||||
color=color,
|
||||
thickness=-1,
|
||||
)
|
||||
for center in circle_centers:
|
||||
cv2.circle(
|
||||
img=scene,
|
||||
center=center,
|
||||
radius=border_radius,
|
||||
color=color,
|
||||
thickness=-1,
|
||||
)
|
||||
return scene
|
||||
|
||||
|
||||
class BlurAnnotator(BaseAnnotator):
|
||||
"""
|
||||
|
|
@ -1112,7 +1160,7 @@ class BlurAnnotator(BaseAnnotator):
|
|||
"""
|
||||
self.kernel_size: int = kernel_size
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -1197,7 +1245,7 @@ class TraceAnnotator:
|
|||
self.thickness = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -1304,7 +1352,7 @@ class HeatMapAnnotator:
|
|||
self.top_hue = top_hue
|
||||
self.low_hue = low_hue
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(self, scene: ImageType, detections: Detections) -> ImageType:
|
||||
"""
|
||||
Annotates the scene with a heatmap based on the provided detections.
|
||||
|
|
@ -1380,7 +1428,7 @@ class PixelateAnnotator(BaseAnnotator):
|
|||
"""
|
||||
self.pixel_size: int = pixel_size
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -1468,7 +1516,7 @@ class TriangleAnnotator(BaseAnnotator):
|
|||
self.position: Position = position
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -1564,7 +1612,7 @@ class RoundBoxAnnotator(BaseAnnotator):
|
|||
raise ValueError("roundness attribute must be float between (0, 1.0]")
|
||||
self.roundness: float = roundness
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -1701,7 +1749,7 @@ class PercentageBarAnnotator(BaseAnnotator):
|
|||
if border_thickness is None:
|
||||
self.border_thickness = int(0.15 * self.height)
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
@ -1847,7 +1895,14 @@ class CropAnnotator(BaseAnnotator):
|
|||
A class for drawing scaled up crops of detections on the scene.
|
||||
"""
|
||||
|
||||
def __init__(self, position: Position = Position.TOP_CENTER, scale_factor: int = 2):
|
||||
def __init__(
|
||||
self,
|
||||
position: Position = Position.TOP_CENTER,
|
||||
scale_factor: int = 2,
|
||||
border_color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
border_thickness: int = 2,
|
||||
border_color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
position (Position): The anchor position for placing the cropped and scaled
|
||||
|
|
@ -1855,16 +1910,25 @@ class CropAnnotator(BaseAnnotator):
|
|||
scale_factor (int): The factor by which to scale the cropped image part. A
|
||||
factor of 2, for example, would double the size of the cropped area,
|
||||
allowing for a closer view of the detection.
|
||||
border_color (Union[Color, ColorPalette]): The color or color palette to
|
||||
use for annotating border around the cropped area.
|
||||
border_thickness (int): The thickness of the border around the cropped area.
|
||||
border_color_lookup (ColorLookup): Strategy for mapping colors to
|
||||
annotations. Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.position: Position = position
|
||||
self.scale_factor: int = scale_factor
|
||||
self.border_color: Union[Color, ColorPalette] = border_color
|
||||
self.border_thickness: int = border_thickness
|
||||
self.border_color_lookup: ColorLookup = border_color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
scene: ImageType,
|
||||
detections: Detections,
|
||||
) -> np.ndarray:
|
||||
custom_color_lookup: Optional[np.ndarray] = None,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Annotates the provided scene with scaled and cropped parts of the image based
|
||||
on the provided detections. Each detection is cropped from the original scene
|
||||
|
|
@ -1873,8 +1937,12 @@ class CropAnnotator(BaseAnnotator):
|
|||
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image where cropped detection will be placed.
|
||||
scene (ImageType): The image where cropped detection will be placed.
|
||||
`ImageType` is a flexible type, accepting either `numpy.ndarray`
|
||||
or `PIL.Image.Image`.
|
||||
detections (Detections): Object detections to annotate.
|
||||
custom_color_lookup (Optional[np.ndarray]): Custom color lookup array.
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
The annotated image.
|
||||
|
|
@ -1897,41 +1965,73 @@ class CropAnnotator(BaseAnnotator):
|
|||
crop_image(image=scene, xyxy=xyxy) for xyxy in detections.xyxy.astype(int)
|
||||
]
|
||||
resized_crops = [
|
||||
resize_image(image=crop, scale_factor=self.scale_factor) for crop in crops
|
||||
scale_image(image=crop, scale_factor=self.scale_factor) for crop in crops
|
||||
]
|
||||
anchors = detections.get_anchors_coordinates(anchor=self.position).astype(int)
|
||||
|
||||
for resized_crop, anchor in zip(resized_crops, anchors):
|
||||
for idx, (resized_crop, anchor) in enumerate(zip(resized_crops, anchors)):
|
||||
crop_wh = resized_crop.shape[1], resized_crop.shape[0]
|
||||
crop_anchor = self.calculate_crop_coordinates(
|
||||
(x1, y1), (x2, y2) = self.calculate_crop_coordinates(
|
||||
anchor=anchor, crop_wh=crop_wh, position=self.position
|
||||
)
|
||||
scene = place_image(scene=scene, image=resized_crop, anchor=crop_anchor)
|
||||
scene = overlay_image(
|
||||
scene=scene, inserted_image=resized_crop, anchor=(x1, y1)
|
||||
)
|
||||
color = resolve_color(
|
||||
color=self.border_color,
|
||||
detections=detections,
|
||||
detection_idx=idx,
|
||||
color_lookup=self.border_color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=(x1, y1),
|
||||
pt2=(x2, y2),
|
||||
color=color.as_bgr(),
|
||||
thickness=self.border_thickness,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
@staticmethod
|
||||
def calculate_crop_coordinates(
|
||||
anchor: Tuple[int, int], crop_wh: Tuple[int, int], position: Position
|
||||
) -> Tuple[int, int]:
|
||||
) -> Tuple[Tuple[int, int], Tuple[int, int]]:
|
||||
anchor_x, anchor_y = anchor
|
||||
width, height = crop_wh
|
||||
|
||||
if position == Position.TOP_LEFT:
|
||||
return anchor_x - width, anchor_y - height
|
||||
return (anchor_x - width, anchor_y - height), (anchor_x, anchor_y)
|
||||
elif position == Position.TOP_CENTER:
|
||||
return anchor_x - width // 2, anchor_y - height
|
||||
return (
|
||||
(anchor_x - width // 2, anchor_y - height),
|
||||
(anchor_x + width // 2, anchor_y),
|
||||
)
|
||||
elif position == Position.TOP_RIGHT:
|
||||
return anchor_x, anchor_y - height
|
||||
return (anchor_x, anchor_y - height), (anchor_x + width, anchor_y)
|
||||
elif position == Position.CENTER_LEFT:
|
||||
return anchor_x - width, anchor_y - height // 2
|
||||
return (
|
||||
(anchor_x - width, anchor_y - height // 2),
|
||||
(anchor_x, anchor_y + height // 2),
|
||||
)
|
||||
elif position == Position.CENTER or position == Position.CENTER_OF_MASS:
|
||||
return anchor_x - width // 2, anchor_y - height // 2
|
||||
return (
|
||||
(anchor_x - width // 2, anchor_y - height // 2),
|
||||
(anchor_x + width // 2, anchor_y + height // 2),
|
||||
)
|
||||
elif position == Position.CENTER_RIGHT:
|
||||
return anchor_x, anchor_y - height // 2
|
||||
return (
|
||||
(anchor_x, anchor_y - height // 2),
|
||||
(anchor_x + width, anchor_y + height // 2),
|
||||
)
|
||||
elif position == Position.BOTTOM_LEFT:
|
||||
return anchor_x - width, anchor_y
|
||||
return (anchor_x - width, anchor_y), (anchor_x, anchor_y + height)
|
||||
elif position == Position.BOTTOM_CENTER:
|
||||
return anchor_x - width // 2, anchor_y
|
||||
return (
|
||||
(anchor_x - width // 2, anchor_y),
|
||||
(anchor_x + width // 2, anchor_y + height),
|
||||
)
|
||||
elif position == Position.BOTTOM_RIGHT:
|
||||
return anchor_x, anchor_y
|
||||
return (anchor_x, anchor_y), (anchor_x + width, anchor_y + height)
|
||||
|
|
|
|||
|
|
@ -1,12 +1,8 @@
|
|||
from enum import Enum
|
||||
from functools import wraps
|
||||
from typing import Optional, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.geometry.core import Position
|
||||
|
|
@ -123,33 +119,3 @@ class Trace:
|
|||
|
||||
def get(self, tracker_id: int) -> np.ndarray:
|
||||
return self.xy[self.tracker_id == tracker_id]
|
||||
|
||||
|
||||
def pillow_to_cv2(image: Image.Image) -> np.ndarray:
|
||||
scene = np.array(image)
|
||||
scene = cv2.cvtColor(scene, cv2.COLOR_RGB2BGR)
|
||||
return scene
|
||||
|
||||
|
||||
def scene_to_annotator_img_type(annotate_func):
|
||||
"""
|
||||
Decorates `BaseAnnotator.annotate` implementations, converts scene to
|
||||
an image type used internally by the annotators, converts back when annotation
|
||||
is complete.
|
||||
"""
|
||||
|
||||
@wraps(annotate_func)
|
||||
def wrapper(self, scene: ImageType, *args, **kwargs):
|
||||
if isinstance(scene, np.ndarray):
|
||||
return annotate_func(self, scene, *args, **kwargs)
|
||||
|
||||
if isinstance(scene, Image.Image):
|
||||
scene = pillow_to_cv2(scene)
|
||||
annotated = annotate_func(self, scene, *args, **kwargs)
|
||||
annotated = cv2.cvtColor(annotated, cv2.COLOR_BGR2RGB)
|
||||
annotated = Image.fromarray(annotated)
|
||||
return annotated
|
||||
|
||||
raise ValueError(f"Unsupported image type: {type(scene)}")
|
||||
|
||||
return wrapper
|
||||
|
|
|
|||
|
|
@ -18,6 +18,8 @@ class VideoAssets(Enum):
|
|||
| `SUBWAY` | `subway.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/subway.mp4) |
|
||||
| `MARKET_SQUARE` | `market-square.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/market-square.mp4) |
|
||||
| `PEOPLE_WALKING` | `people-walking.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/people-walking.mp4) |
|
||||
| `BEACH` | `beach-1.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/beach-1.mp4) |
|
||||
| `BASKETBALL` | `basketball-1.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/basketball-1.mp4) |
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
VEHICLES = "vehicles.mp4"
|
||||
|
|
@ -27,6 +29,8 @@ class VideoAssets(Enum):
|
|||
SUBWAY = "subway.mp4"
|
||||
MARKET_SQUARE = "market-square.mp4"
|
||||
PEOPLE_WALKING = "people-walking.mp4"
|
||||
BEACH = "beach-1.mp4"
|
||||
BASKETBALL = "basketball-1.mp4"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
|
|
@ -62,4 +66,12 @@ VIDEO_ASSETS: Dict[str, Tuple[str, str]] = {
|
|||
f"{BASE_VIDEO_URL}{VideoAssets.PEOPLE_WALKING.value}",
|
||||
"0574c053c8686c3f1dc0aa3743e45cb9",
|
||||
),
|
||||
VideoAssets.BEACH.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.BEACH.value}",
|
||||
"4175d42fec4d450ed081523fd39e0cf8",
|
||||
),
|
||||
VideoAssets.BASKETBALL.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.BASKETBALL.value}",
|
||||
"60d94a3c7c47d16f09d342b088012ecc",
|
||||
),
|
||||
}
|
||||
|
|
|
|||
|
|
@ -3,16 +3,12 @@ from typing import List, Optional, Union
|
|||
import cv2
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.annotators.utils import scene_to_annotator_img_type
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.utils.conversion import convert_for_annotation_method
|
||||
from supervision.utils.internal import deprecated
|
||||
|
||||
|
||||
@deprecated(
|
||||
"`BoxAnnotator` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `BoundingBoxAnnotator` and `LabelAnnotator` instead"
|
||||
)
|
||||
class BoxAnnotator:
|
||||
"""
|
||||
A class for drawing bounding boxes on an image using detections provided.
|
||||
|
|
@ -46,7 +42,11 @@ class BoxAnnotator:
|
|||
self.text_thickness: int = text_thickness
|
||||
self.text_padding: int = text_padding
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
@deprecated(
|
||||
"`BoxAnnotator` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `BoundingBoxAnnotator` and `LabelAnnotator` instead"
|
||||
)
|
||||
@convert_for_annotation_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
|
|
|
|||
|
|
@ -14,46 +14,84 @@ from supervision.detection.utils import (
|
|||
get_data_item,
|
||||
is_data_equal,
|
||||
mask_non_max_suppression,
|
||||
mask_to_xyxy,
|
||||
merge_data,
|
||||
process_roboflow_result,
|
||||
validate_detections_fields,
|
||||
xywh_to_xyxy,
|
||||
)
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.utils.internal import deprecated
|
||||
from supervision.validators import validate_detections_fields
|
||||
|
||||
|
||||
@dataclass
|
||||
class Detections:
|
||||
"""
|
||||
The `sv.Detections` allows you to convert results from a variety of object detection
|
||||
and segmentation models into a single, unified format. The `sv.Detections` class
|
||||
enables easy data manipulation and filtering, and provides a consistent API for
|
||||
Supervision's tools like trackers, annotators, and zones.
|
||||
The `sv.Detections` class in the Supervision library standardizes results from
|
||||
various object detection and segmentation models into a consistent format. This
|
||||
class simplifies data manipulation and filtering, providing a uniform API for
|
||||
integration with Supervision [trackers](/trackers/), [annotators](/detection/annotators/), and [tools](/detection/tools/line_zone/).
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
=== "Inference"
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
annotator = sv.BoundingBoxAnnotator()
|
||||
Use [`sv.Detections.from_inference`](/detection/core/#supervision.detection.core.Detections.from_inference)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
annotated_image = annotator.annotate(image, detections)
|
||||
```
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
=== "Ultralytics"
|
||||
|
||||
In `sv.Detections`, detection data is categorized into two main field types:
|
||||
fixed and custom. The fixed fields include `xyxy`, `mask`, `confidence`,
|
||||
`class_id`, and `tracker_id`. For any additional data requirements, custom
|
||||
fields come into play, stored in the data field. These custom fields are easily
|
||||
accessible using the `detections[<FIELD_NAME>]` syntax, providing flexibility
|
||||
for diverse data handling needs.
|
||||
Use [`sv.Detections.from_ultralytics`](/detection/core/#supervision.detection.core.Detections.from_ultralytics)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
Use [`sv.Detections.from_transformers`](/detection/core/#supervision.detection.core.Detections.from_transformers)
|
||||
method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
```
|
||||
|
||||
Attributes:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
|
|
@ -69,15 +107,7 @@ class Detections:
|
|||
data (Dict[str, Union[np.ndarray, List]]): A dictionary containing additional
|
||||
data where each key is a string representing the data type, and the value
|
||||
is either a NumPy array or a list of corresponding data.
|
||||
|
||||
!!! warning
|
||||
|
||||
The `data` field in the `sv.Detections` class is currently in an experimental
|
||||
phase. Please be aware that its API and functionality are subject to change in
|
||||
future updates as we continue to refine and improve its capabilities.
|
||||
We encourage users to experiment with this feature and provide feedback, but
|
||||
also to be prepared for potential modifications in upcoming releases.
|
||||
"""
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
xyxy: np.ndarray
|
||||
mask: Optional[np.ndarray] = None
|
||||
|
|
@ -176,8 +206,8 @@ class Detections:
|
|||
@classmethod
|
||||
def from_ultralytics(cls, ultralytics_results) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
Creates a `sv.Detections` instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
|
||||
!!! Note
|
||||
|
||||
|
|
@ -188,7 +218,7 @@ class Detections:
|
|||
|
||||
Args:
|
||||
ultralytics_results (ultralytics.yolo.engine.results.Results):
|
||||
The output Results instance from YOLOv8
|
||||
The output Results instance from Ultralytics
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
|
|
@ -201,13 +231,16 @@ class Detections:
|
|||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
if ultralytics_results.obb is not None:
|
||||
if "obb" in ultralytics_results and ultralytics_results.obb is not None:
|
||||
class_id = ultralytics_results.obb.cls.cpu().numpy().astype(int)
|
||||
class_names = np.array([ultralytics_results.names[i] for i in class_id])
|
||||
oriented_box_coordinates = ultralytics_results.obb.xyxyxyxy.cpu().numpy()
|
||||
|
|
@ -388,20 +421,80 @@ class Detections:
|
|||
)
|
||||
|
||||
@classmethod
|
||||
def from_transformers(cls, transformers_results: dict) -> Detections:
|
||||
def from_transformers(
|
||||
cls, transformers_results: dict, id2label: Optional[Dict[int, str]] = None
|
||||
) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from object detection
|
||||
[transformer](https://github.com/huggingface/transformers) inference result.
|
||||
Creates a Detections instance from object detection or segmentation
|
||||
[Transformer](https://github.com/huggingface/transformers) inference result.
|
||||
|
||||
Args:
|
||||
transformers_results (dict): The output of Transformers model inference. A
|
||||
dictionary containing the `scores`, `labels`, `boxes` and `masks` keys.
|
||||
id2label (Optional[Dict[int, str]]): A dictionary mapping class IDs to
|
||||
class names. If provided, the resulting Detections object will contain
|
||||
`class_name` data field with the class names.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
"""
|
||||
|
||||
return cls(
|
||||
xyxy=transformers_results["boxes"].cpu().numpy(),
|
||||
confidence=transformers_results["scores"].cpu().numpy(),
|
||||
class_id=transformers_results["labels"].cpu().numpy().astype(int),
|
||||
)
|
||||
Example:
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label
|
||||
)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
class_ids = transformers_results["labels"].cpu().detach().numpy().astype(int)
|
||||
data = {}
|
||||
if id2label is not None:
|
||||
class_names = np.array([id2label[class_id] for class_id in class_ids])
|
||||
data[CLASS_NAME_DATA_FIELD] = class_names
|
||||
if "boxes" in transformers_results:
|
||||
return cls(
|
||||
xyxy=transformers_results["boxes"].cpu().detach().numpy(),
|
||||
confidence=transformers_results["scores"].cpu().detach().numpy(),
|
||||
class_id=class_ids,
|
||||
data=data,
|
||||
)
|
||||
elif "masks" in transformers_results:
|
||||
masks = transformers_results["masks"].cpu().detach().numpy().astype(bool)
|
||||
return cls(
|
||||
xyxy=mask_to_xyxy(masks),
|
||||
mask=masks,
|
||||
confidence=transformers_results["scores"].cpu().detach().numpy(),
|
||||
class_id=class_ids,
|
||||
data=data,
|
||||
)
|
||||
else:
|
||||
raise NotImplementedError(
|
||||
"Only object detection and semantic segmentation results are supported."
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_detectron2(cls, detectron2_results) -> Detections:
|
||||
|
|
@ -448,17 +541,12 @@ class Detections:
|
|||
@classmethod
|
||||
def from_inference(cls, roboflow_result: Union[dict, Any]) -> Detections:
|
||||
"""
|
||||
Create a Detections object from the [Roboflow](https://roboflow.com/)
|
||||
Create a `sv.Detections` object from the [Roboflow](https://roboflow.com/)
|
||||
API inference result or the [Inference](https://inference.roboflow.com/)
|
||||
package results. This method extracts bounding boxes, class IDs,
|
||||
confidences, and class names from the Roboflow API result and encapsulates
|
||||
them into a Detections object.
|
||||
|
||||
!!! note
|
||||
|
||||
Class names can be accessed using the key 'class_name' in the returned
|
||||
object's data attribute.
|
||||
|
||||
Args:
|
||||
roboflow_result (dict, any): The result from the
|
||||
Roboflow API or Inference package containing predictions.
|
||||
|
|
@ -471,14 +559,18 @@ class Detections:
|
|||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_roboflow_model(model_id="yolov8s-640")
|
||||
model = get_model(model_id="yolov8s-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
"""
|
||||
with suppress(AttributeError):
|
||||
roboflow_result = roboflow_result.dict(exclude_none=True, by_alias=True)
|
||||
|
|
@ -528,10 +620,10 @@ class Detections:
|
|||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_roboflow_model(model_id="yolov8s-640")
|
||||
model = get_model(model_id="yolov8s-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_roboflow(result)
|
||||
|
|
|
|||
|
|
@ -1,8 +1,10 @@
|
|||
import warnings
|
||||
from dataclasses import replace
|
||||
from typing import Iterable, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision import Detections
|
||||
from supervision.detection.utils import clip_boxes, polygon_to_mask
|
||||
|
|
@ -10,7 +12,7 @@ from supervision.draw.color import Color
|
|||
from supervision.draw.utils import draw_polygon, draw_text
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.utils.internal import deprecated_parameter
|
||||
from supervision.utils.internal import SupervisionWarnings, deprecated_parameter
|
||||
|
||||
|
||||
class PolygonZone:
|
||||
|
|
@ -20,7 +22,6 @@ class PolygonZone:
|
|||
Attributes:
|
||||
polygon (np.ndarray): A polygon represented by a numpy array of shape
|
||||
`(N, 2)`, containing the `x`, `y` coordinates of the points.
|
||||
frame_resolution_wh (Tuple[int, int]): The frame resolution (width, height)
|
||||
triggering_anchors (Iterable[sv.Position]): A list of positions specifying
|
||||
which anchors of the detections bounding box to consider when deciding on
|
||||
whether the detection fits within the PolygonZone
|
||||
|
|
@ -39,22 +40,30 @@ class PolygonZone:
|
|||
)
|
||||
def __init__(
|
||||
self,
|
||||
polygon: np.ndarray,
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
polygon: npt.NDArray[np.int64],
|
||||
frame_resolution_wh: Optional[Tuple[int, int]] = None,
|
||||
triggering_anchors: Iterable[Position] = (Position.BOTTOM_CENTER,),
|
||||
):
|
||||
if frame_resolution_wh is not None:
|
||||
warnings.warn(
|
||||
"The `frame_resolution_wh` parameter is no longer required and will be "
|
||||
"dropped in version supervision-0.24.0. The mask resolution is now "
|
||||
"calculated automatically based on the polygon coordinates.",
|
||||
category=SupervisionWarnings,
|
||||
)
|
||||
|
||||
self.polygon = polygon.astype(int)
|
||||
self.frame_resolution_wh = frame_resolution_wh
|
||||
self.triggering_anchors = triggering_anchors
|
||||
|
||||
self.current_count = 0
|
||||
|
||||
width, height = frame_resolution_wh
|
||||
x_max, y_max = np.max(polygon, axis=0)
|
||||
self.frame_resolution_wh = (x_max + 1, y_max + 1)
|
||||
self.mask = polygon_to_mask(
|
||||
polygon=polygon, resolution_wh=(width + 1, height + 1)
|
||||
polygon=polygon, resolution_wh=(x_max + 2, y_max + 2)
|
||||
)
|
||||
|
||||
def trigger(self, detections: Detections) -> np.ndarray:
|
||||
def trigger(self, detections: Detections) -> npt.NDArray[np.bool_]:
|
||||
"""
|
||||
Determines if the detections are within the polygon zone.
|
||||
|
||||
|
|
@ -78,13 +87,13 @@ class PolygonZone:
|
|||
]
|
||||
)
|
||||
|
||||
is_in_zone = (
|
||||
is_in_zone: npt.NDArray[np.bool_] = (
|
||||
self.mask[all_clipped_anchors[:, :, 1], all_clipped_anchors[:, :, 0]]
|
||||
.transpose()
|
||||
.astype(bool)
|
||||
)
|
||||
is_in_zone = np.all(is_in_zone, axis=1)
|
||||
|
||||
is_in_zone: npt.NDArray[np.bool_] = np.all(is_in_zone, axis=1)
|
||||
self.current_count = int(np.sum(is_in_zone))
|
||||
return is_in_zone.astype(bool)
|
||||
|
||||
|
|
|
|||
|
|
@ -1,5 +1,5 @@
|
|||
from itertools import chain
|
||||
from typing import Any, Dict, List, Optional, Tuple, Union
|
||||
from typing import Dict, List, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
|
@ -656,102 +656,6 @@ def calculate_masks_centroids(masks: np.ndarray) -> np.ndarray:
|
|||
return np.column_stack((centroid_x, centroid_y)).astype(int)
|
||||
|
||||
|
||||
def validate_xyxy(xyxy: Any) -> None:
|
||||
expected_shape = "(_, 4)"
|
||||
actual_shape = str(getattr(xyxy, "shape", None))
|
||||
is_valid = isinstance(xyxy, np.ndarray) and xyxy.ndim == 2 and xyxy.shape[1] == 4
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"xyxy must be a 2D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_mask(mask: Any, n: int) -> None:
|
||||
expected_shape = f"({n}, H, W)"
|
||||
actual_shape = str(getattr(mask, "shape", None))
|
||||
is_valid = mask is None or (
|
||||
isinstance(mask, np.ndarray) and len(mask.shape) == 3 and mask.shape[0] == n
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"mask must be a 3D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_class_id(class_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(class_id, "shape", None))
|
||||
is_valid = class_id is None or (
|
||||
isinstance(class_id, np.ndarray) and class_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"class_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_confidence(confidence: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(confidence, "shape", None))
|
||||
is_valid = confidence is None or (
|
||||
isinstance(confidence, np.ndarray) and confidence.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"confidence must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(tracker_id, "shape", None))
|
||||
is_valid = tracker_id is None or (
|
||||
isinstance(tracker_id, np.ndarray) and tracker_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"tracker_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_data(data: Dict[str, Any], n: int) -> None:
|
||||
for key, value in data.items():
|
||||
if isinstance(value, list):
|
||||
if len(value) != n:
|
||||
raise ValueError(f"Length of list for key '{key}' must be {n}")
|
||||
elif isinstance(value, np.ndarray):
|
||||
if value.ndim == 1 and value.shape[0] != n:
|
||||
raise ValueError(f"Shape of np.ndarray for key '{key}' must be ({n},)")
|
||||
elif value.ndim > 1 and value.shape[0] != n:
|
||||
raise ValueError(
|
||||
f"First dimension of np.ndarray for key '{key}' must have size {n}"
|
||||
)
|
||||
else:
|
||||
raise ValueError(f"Value for key '{key}' must be a list or np.ndarray")
|
||||
|
||||
|
||||
def validate_detections_fields(
|
||||
xyxy: Any,
|
||||
mask: Any,
|
||||
class_id: Any,
|
||||
confidence: Any,
|
||||
tracker_id: Any,
|
||||
data: Dict[str, Any],
|
||||
) -> None:
|
||||
validate_xyxy(xyxy)
|
||||
n = len(xyxy)
|
||||
validate_mask(mask, n)
|
||||
validate_class_id(class_id, n)
|
||||
validate_confidence(confidence, n)
|
||||
validate_tracker_id(tracker_id, n)
|
||||
validate_data(data, n)
|
||||
|
||||
|
||||
def is_data_equal(data_a: Dict[str, np.ndarray], data_b: Dict[str, np.ndarray]) -> bool:
|
||||
"""
|
||||
Compares the data payloads of two Detections instances.
|
||||
|
|
@ -845,8 +749,15 @@ def get_data_item(
|
|||
elif isinstance(value, list):
|
||||
if isinstance(index, slice):
|
||||
subset_data[key] = value[index]
|
||||
elif isinstance(index, (list, np.ndarray)):
|
||||
elif isinstance(index, list):
|
||||
subset_data[key] = [value[i] for i in index]
|
||||
elif isinstance(index, np.ndarray):
|
||||
if index.dtype == bool:
|
||||
subset_data[key] = [
|
||||
value[i] for i, index_value in enumerate(index) if index_value
|
||||
]
|
||||
else:
|
||||
subset_data[key] = [value[i] for i in index]
|
||||
elif isinstance(index, int):
|
||||
subset_data[key] = [value[index]]
|
||||
else:
|
||||
|
|
|
|||
|
|
@ -1,7 +1,7 @@
|
|||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import List, Tuple
|
||||
from typing import List, Tuple, Union
|
||||
|
||||
import matplotlib.pyplot as plt
|
||||
|
||||
|
|
@ -104,10 +104,13 @@ class Color:
|
|||
Create a Color instance from a hex string.
|
||||
|
||||
Args:
|
||||
color_hex (str): Hex string of the color.
|
||||
color_hex (str): The hex string representing the color. This string can
|
||||
start with '#' followed by either 3 or 6 hexadecimal characters. In
|
||||
case of 3 characters, each character is repeated to form the full
|
||||
6-character hex code.
|
||||
|
||||
Returns:
|
||||
Color: Instance representing the color.
|
||||
Color: An instance representing the color.
|
||||
|
||||
Example:
|
||||
```python
|
||||
|
|
@ -115,6 +118,9 @@ class Color:
|
|||
|
||||
sv.Color.from_hex('#ff00ff')
|
||||
# Color(r=255, g=0, b=255)
|
||||
|
||||
sv.Color.from_hex('#f0f')
|
||||
# Color(r=255, g=0, b=255)
|
||||
```
|
||||
"""
|
||||
_validate_color_hex(color_hex)
|
||||
|
|
@ -124,6 +130,52 @@ class Color:
|
|||
r, g, b = (int(color_hex[i : i + 2], 16) for i in range(0, 6, 2))
|
||||
return cls(r, g, b)
|
||||
|
||||
@classmethod
|
||||
def from_rgb_tuple(cls, color_tuple: Tuple[int, int, int]) -> Color:
|
||||
"""
|
||||
Create a Color instance from an RGB tuple.
|
||||
|
||||
Args:
|
||||
color_tuple (Tuple[int, int, int]): A tuple representing the color in RGB
|
||||
format, where each element is an integer in the range 0-255.
|
||||
|
||||
Returns:
|
||||
Color: An instance representing the color.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.Color.from_rgb_tuple((255, 255, 0))
|
||||
# Color(r=255, g=255, b=0)
|
||||
```
|
||||
"""
|
||||
r, g, b = color_tuple
|
||||
return cls(r=r, g=g, b=b)
|
||||
|
||||
@classmethod
|
||||
def from_bgr_tuple(cls, color_tuple: Tuple[int, int, int]) -> Color:
|
||||
"""
|
||||
Create a Color instance from a BGR tuple.
|
||||
|
||||
Args:
|
||||
color_tuple (Tuple[int, int, int]): A tuple representing the color in BGR
|
||||
format, where each element is an integer in the range 0-255.
|
||||
|
||||
Returns:
|
||||
Color: An instance representing the color.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.Color.from_bgr_tuple((0, 255, 255))
|
||||
# Color(r=255, g=255, b=0)
|
||||
```
|
||||
"""
|
||||
b, g, r = color_tuple
|
||||
return cls(r=r, g=g, b=b)
|
||||
|
||||
def as_hex(self) -> str:
|
||||
"""
|
||||
Converts the Color instance to a hex string.
|
||||
|
|
@ -176,31 +228,31 @@ class Color:
|
|||
return self.b, self.g, self.r
|
||||
|
||||
@classproperty
|
||||
def WHITE(cls):
|
||||
def WHITE(cls) -> Color:
|
||||
return Color.from_hex("#FFFFFF")
|
||||
|
||||
@classproperty
|
||||
def BLACK(cls):
|
||||
def BLACK(cls) -> Color:
|
||||
return Color.from_hex("#000000")
|
||||
|
||||
@classproperty
|
||||
def RED(cls):
|
||||
def RED(cls) -> Color:
|
||||
return Color.from_hex("#FF0000")
|
||||
|
||||
@classproperty
|
||||
def GREEN(cls):
|
||||
def GREEN(cls) -> Color:
|
||||
return Color.from_hex("#00FF00")
|
||||
|
||||
@classproperty
|
||||
def BLUE(cls):
|
||||
def BLUE(cls) -> Color:
|
||||
return Color.from_hex("#0000FF")
|
||||
|
||||
@classproperty
|
||||
def YELLOW(cls):
|
||||
def YELLOW(cls) -> Color:
|
||||
return Color.from_hex("#FFFF00")
|
||||
|
||||
@classproperty
|
||||
def ROBOFLOW(cls):
|
||||
def ROBOFLOW(cls) -> Color:
|
||||
return Color.from_hex("#A351FB")
|
||||
|
||||
@classmethod
|
||||
|
|
@ -396,3 +448,19 @@ class ColorPalette:
|
|||
raise ValueError("idx argument should not be negative")
|
||||
idx = idx % len(self.colors)
|
||||
return self.colors[idx]
|
||||
|
||||
|
||||
def unify_to_bgr(color: Union[Tuple[int, int, int], Color]) -> Tuple[int, int, int]:
|
||||
"""
|
||||
Converts a color input in multiple formats to a standardized BGR format.
|
||||
|
||||
Args:
|
||||
color (Union[Tuple[int, int, int], Color]): The color input to be converted,
|
||||
which can be either a tuple of RGB values or an instance of a Color class.
|
||||
|
||||
Returns:
|
||||
Tuple[int, int, int]: The color in BGR format as a tuple of three integers.
|
||||
"""
|
||||
if issubclass(type(color), Color):
|
||||
return color.as_bgr()
|
||||
return color
|
||||
|
|
|
|||
|
|
@ -238,13 +238,13 @@ def draw_image(
|
|||
return scene
|
||||
|
||||
|
||||
def calculate_dynamic_text_scale(resolution_wh: Tuple[int, int]) -> float:
|
||||
def calculate_optimal_text_scale(resolution_wh: Tuple[int, int]) -> float:
|
||||
"""
|
||||
Calculate a dynamic font scale based on the resolution of an image.
|
||||
Calculate font scale based on the resolution of an image.
|
||||
|
||||
Parameters:
|
||||
resolution_wh (Tuple[int, int]): A tuple representing the width and height
|
||||
of the image.
|
||||
of the image.
|
||||
|
||||
Returns:
|
||||
float: The calculated font scale factor.
|
||||
|
|
@ -252,25 +252,17 @@ def calculate_dynamic_text_scale(resolution_wh: Tuple[int, int]) -> float:
|
|||
return min(resolution_wh) * 1e-3
|
||||
|
||||
|
||||
def calculate_dynamic_line_thickness(resolution_wh: Tuple[int, int]) -> int:
|
||||
def calculate_optimal_line_thickness(resolution_wh: Tuple[int, int]) -> int:
|
||||
"""
|
||||
Calculate a dynamic line thickness based on the resolution of an image.
|
||||
Calculate line thickness based on the resolution of an image.
|
||||
|
||||
Parameters:
|
||||
resolution_wh (Tuple[int, int]): A tuple representing the width and height
|
||||
of the image.
|
||||
of the image.
|
||||
|
||||
Returns:
|
||||
int: The calculated line thickness in pixels.
|
||||
"""
|
||||
min_dimension = min(resolution_wh)
|
||||
if min_dimension < 480:
|
||||
if min(resolution_wh) < 1080:
|
||||
return 2
|
||||
if min_dimension < 720:
|
||||
return 2
|
||||
if min_dimension < 1080:
|
||||
return 2
|
||||
if min_dimension < 2160:
|
||||
return 4
|
||||
else:
|
||||
return 4
|
||||
return 4
|
||||
|
|
|
|||
|
|
@ -5,12 +5,8 @@ from supervision.geometry.core import Point
|
|||
|
||||
def get_polygon_center(polygon: np.ndarray) -> Point:
|
||||
"""
|
||||
Calculate the center of a polygon.
|
||||
|
||||
This function takes in a polygon as a 2-dimensional numpy ndarray and
|
||||
returns the center of the polygon as a Point object.
|
||||
The center is calculated as the mean of the polygon's vertices along each axis,
|
||||
and is rounded down to the nearest integer.
|
||||
Calculate the center of a polygon. The center is calculated as the center
|
||||
of the solid figure formed by the points of the polygon
|
||||
|
||||
Parameters:
|
||||
polygon (np.ndarray): A 2-dimensional numpy ndarray representing the
|
||||
|
|
@ -22,13 +18,24 @@ def get_polygon_center(polygon: np.ndarray) -> Point:
|
|||
|
||||
Examples:
|
||||
```python
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
vertices = np.array([[0, 0], [0, 1], [1, 1], [1, 0]])
|
||||
get_center(vertices)
|
||||
Point(x=0.5, y=0.5)
|
||||
polygon = np.array([[0, 0], [0, 2], [2, 2], [2, 0]])
|
||||
sv.get_polygon_center(polygon=polygon)
|
||||
# Point(x=1, y=1)
|
||||
```
|
||||
"""
|
||||
center = np.mean(polygon, axis=0).astype(int)
|
||||
|
||||
# This is one of the 3 candidate algorithms considered for centroid calculation.
|
||||
# For a more detailed discussion, see PR #1084 and commit eb33176
|
||||
|
||||
shift_polygon = np.roll(polygon, -1, axis=0)
|
||||
signed_areas = np.cross(polygon, shift_polygon) / 2
|
||||
if signed_areas.sum() == 0:
|
||||
center = np.mean(polygon, axis=0).round()
|
||||
return Point(x=center[0], y=center[1])
|
||||
centroids = (polygon + shift_polygon) / 3.0
|
||||
center = np.average(centroids, axis=0, weights=signed_areas).round()
|
||||
|
||||
return Point(x=center[0], y=center[1])
|
||||
|
|
|
|||
|
|
@ -0,0 +1,177 @@
|
|||
from abc import ABC, abstractmethod
|
||||
from logging import warn
|
||||
from typing import List, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.color import Color
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.keypoint.skeletons import SKELETONS_BY_VERTEX_COUNT
|
||||
from supervision.utils.conversion import convert_for_annotation_method
|
||||
|
||||
|
||||
class BaseKeyPointAnnotator(ABC):
|
||||
@abstractmethod
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
pass
|
||||
|
||||
|
||||
class VertexAnnotator(BaseKeyPointAnnotator):
|
||||
"""
|
||||
A class that specializes in drawing skeleton vertices on images. It uses
|
||||
specified key points to determine the locations where the vertices should be
|
||||
drawn.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Color = Color.ROBOFLOW,
|
||||
radius: int = 4,
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
color (Color, optional): The color to use for annotating key points.
|
||||
radius (int, optional): The radius of the circles used to represent the key
|
||||
points.
|
||||
"""
|
||||
self.color = color
|
||||
self.radius = radius
|
||||
|
||||
@convert_for_annotation_method
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene with skeleton vertices based on the provided key
|
||||
points. It draws circles at each key point location.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where bounding boxes will be drawn. `ImageType`
|
||||
is a flexible type, accepting either `numpy.ndarray` or
|
||||
`PIL.Image.Image`.
|
||||
key_points (KeyPoints): A collection of key points where each key point
|
||||
consists of x and y coordinates.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_annotator = sv.VertexAnnotator(color=sv.Color.GREEN, radius=10)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
for xy in key_points.xy:
|
||||
for x, y in xy:
|
||||
cv2.circle(
|
||||
img=scene,
|
||||
center=(int(x), int(y)),
|
||||
radius=self.radius,
|
||||
color=self.color.as_bgr(),
|
||||
thickness=-1,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
"""
|
||||
A class that specializes in drawing skeleton edges on images using specified key
|
||||
points. It connects key points with lines to form the skeleton structure.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Color = Color.ROBOFLOW,
|
||||
thickness: int = 2,
|
||||
edges: Optional[List[Tuple[int, int]]] = None,
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
color (Color, optional): The color to use for the edges.
|
||||
thickness (int, optional): The thickness of the edges.
|
||||
edges (Optional[List[Tuple[int, int]]]): The edges to draw.
|
||||
If set to `None`, will attempt to select automatically.
|
||||
"""
|
||||
self.color = color
|
||||
self.thickness = thickness
|
||||
self.edges = edges
|
||||
|
||||
@convert_for_annotation_method
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene by drawing lines between specified key points to form
|
||||
edges.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where bounding boxes will be drawn. `ImageType`
|
||||
is a flexible type, accepting either `numpy.ndarray` or
|
||||
`PIL.Image.Image`.
|
||||
key_points (KeyPoints): A collection of key points where each key point
|
||||
consists of x and y coordinates.
|
||||
|
||||
Returns:
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
for xy in key_points.xy:
|
||||
edges = self.edges
|
||||
if not edges:
|
||||
edges = SKELETONS_BY_VERTEX_COUNT.get(len(xy))
|
||||
if not edges:
|
||||
warn(f"No skeleton found with {len(xy)} vertices")
|
||||
return scene
|
||||
|
||||
for class_a, class_b in edges:
|
||||
xy_a = xy[class_a - 1]
|
||||
xy_b = xy[class_b - 1]
|
||||
missing_a = np.allclose(xy_a, 0)
|
||||
missing_b = np.allclose(xy_b, 0)
|
||||
if missing_a or missing_b:
|
||||
continue
|
||||
|
||||
cv2.line(
|
||||
img=scene,
|
||||
pt1=(int(xy_a[0]), int(xy_a[1])),
|
||||
pt2=(int(xy_b[0]), int(xy_b[1])),
|
||||
color=self.color.as_bgr(),
|
||||
thickness=self.thickness,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
|
@ -0,0 +1,233 @@
|
|||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any, Dict, Iterator, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.utils import get_data_item, is_data_equal
|
||||
from supervision.validators import validate_keypoints_fields
|
||||
|
||||
|
||||
@dataclass
|
||||
class KeyPoints:
|
||||
"""
|
||||
The `sv.KeyPoints` class in the Supervision library standardizes results from
|
||||
various keypoint detection and pose estimation models into a consistent format. This
|
||||
class simplifies data manipulation and filtering, providing a uniform API for
|
||||
integration with Supervision annotators.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
Use [`sv.KeyPoints.from_ultralytics`](/keypoint/core/#supervision.keypoint.core.KeyPoints.from_ultralytics)
|
||||
method, which accepts model results.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s-pose.pt')
|
||||
result = model(image)[0]
|
||||
key_points = sv.KeyPoints.from_ultralytics(result)
|
||||
```
|
||||
|
||||
Attributes:
|
||||
xy (np.ndarray): An array of shape `(n, 2)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1]`
|
||||
confidence (Optional[np.ndarray]): An array of shape
|
||||
`(n,)` containing the confidence scores of the keypoint keypoints.
|
||||
class_id (Optional[np.ndarray]): An array of shape
|
||||
`(n,)` containing the class ids of the keypoint keypoints.
|
||||
data (Dict[str, Union[np.ndarray, List]]): A dictionary containing additional
|
||||
data where each key is a string representing the data type, and the value
|
||||
is either a NumPy array or a list of corresponding data.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
xy: npt.NDArray[np.float32]
|
||||
class_id: Optional[npt.NDArray[np.int_]] = None
|
||||
confidence: Optional[npt.NDArray[np.float32]] = None
|
||||
data: Dict[str, Union[npt.NDArray[Any], List]] = field(default_factory=dict)
|
||||
|
||||
def __post_init__(self):
|
||||
validate_keypoints_fields(
|
||||
xy=self.xy,
|
||||
confidence=self.confidence,
|
||||
class_id=self.class_id,
|
||||
data=self.data,
|
||||
)
|
||||
|
||||
def __len__(self) -> int:
|
||||
"""
|
||||
Returns the number of keypoints in the keypoints object.
|
||||
"""
|
||||
return len(self.xy)
|
||||
|
||||
def __iter__(
|
||||
self,
|
||||
) -> Iterator[
|
||||
Tuple[
|
||||
np.ndarray,
|
||||
Optional[np.ndarray],
|
||||
Optional[float],
|
||||
Optional[int],
|
||||
Optional[int],
|
||||
Dict[str, Union[np.ndarray, List]],
|
||||
]
|
||||
]:
|
||||
"""
|
||||
Iterates over the Keypoint object and yield a tuple of
|
||||
`(xy, confidence, class_id, data)` for each keypoint detection.
|
||||
"""
|
||||
for i in range(len(self.xy)):
|
||||
yield (
|
||||
self.xy[i],
|
||||
self.confidence[i] if self.confidence is not None else None,
|
||||
self.class_id[i] if self.class_id is not None else None,
|
||||
get_data_item(self.data, i),
|
||||
)
|
||||
|
||||
def __eq__(self, other: KeyPoints) -> bool:
|
||||
return all(
|
||||
[
|
||||
np.array_equal(self.xy, other.xy),
|
||||
np.array_equal(self.class_id, other.class_id),
|
||||
np.array_equal(self.confidence, other.confidence),
|
||||
is_data_equal(self.data, other.data),
|
||||
]
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_ultralytics(cls, ultralytics_results) -> KeyPoints:
|
||||
"""
|
||||
Creates a Keypoints instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
|
||||
Args:
|
||||
ultralytics_results (ultralytics.engine.results.Keypoints):
|
||||
The output Results instance from YOLOv8
|
||||
|
||||
Returns:
|
||||
KeyPoints: A new Keypoints object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s-pose.pt')
|
||||
result = model(image)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
```
|
||||
"""
|
||||
if ultralytics_results.keypoints.xy.numel() == 0:
|
||||
return cls.empty()
|
||||
|
||||
xy = ultralytics_results.keypoints.xy.cpu().numpy()
|
||||
class_id = ultralytics_results.boxes.cls.cpu().numpy().astype(int)
|
||||
class_names = np.array([ultralytics_results.names[i] for i in class_id])
|
||||
|
||||
confidence = ultralytics_results.keypoints.conf.cpu().numpy()
|
||||
data = {CLASS_NAME_DATA_FIELD: class_names}
|
||||
return cls(xy, class_id, confidence, data)
|
||||
|
||||
def __getitem__(
|
||||
self, index: Union[int, slice, List[int], np.ndarray, str]
|
||||
) -> Union["KeyPoints", List, np.ndarray, None]:
|
||||
"""
|
||||
Get a subset of the KeyPoints object or access an item from its data field.
|
||||
|
||||
When provided with an integer, slice, list of integers, or a numpy array, this
|
||||
method returns a new KeyPoints object that represents a subset of the original
|
||||
keypoints. When provided with a string, it accesses the corresponding item in
|
||||
the data dictionary.
|
||||
|
||||
Args:
|
||||
index (Union[int, slice, List[int], np.ndarray, str]): The index, indices,
|
||||
or key to access a subset of the KeyPoints or an item from the data.
|
||||
|
||||
Returns:
|
||||
Union[KeyPoints, Any]: A subset of the KeyPoints object or an item from
|
||||
the data field.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
keypoints = sv.KeyPoints()
|
||||
|
||||
first_detection = keypoints[0]
|
||||
first_10_keypoints = keypoints[0:10]
|
||||
some_keypoints = keypoints[[0, 2, 4]]
|
||||
class_0_keypoints = keypoints[keypoints.class_id == 0]
|
||||
high_confidence_keypoints = keypoints[keypoints.confidence > 0.5]
|
||||
|
||||
feature_vector = keypoints['feature_vector']
|
||||
```
|
||||
"""
|
||||
if isinstance(index, str):
|
||||
return self.data.get(index)
|
||||
if isinstance(index, int):
|
||||
index = [index]
|
||||
return KeyPoints(
|
||||
xy=self.xy[index],
|
||||
confidence=self.confidence[index] if self.confidence is not None else None,
|
||||
class_id=self.class_id[index] if self.class_id is not None else None,
|
||||
data=get_data_item(self.data, index),
|
||||
)
|
||||
|
||||
def __setitem__(self, key: str, value: Union[np.ndarray, List]):
|
||||
"""
|
||||
Set a value in the data dictionary of the KeyPoints object.
|
||||
|
||||
Args:
|
||||
key (str): The key in the data dictionary to set.
|
||||
value (Union[np.ndarray, List]): The value to set for the key.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
|
||||
result = model(image)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
|
||||
keypoints['names'] = [
|
||||
model.model.names[class_id]
|
||||
for class_id
|
||||
in keypoints.class_id
|
||||
]
|
||||
```
|
||||
"""
|
||||
if not isinstance(value, (np.ndarray, list)):
|
||||
raise TypeError("Value must be a np.ndarray or a list")
|
||||
|
||||
if isinstance(value, list):
|
||||
value = np.array(value)
|
||||
|
||||
self.data[key] = value
|
||||
|
||||
@classmethod
|
||||
def empty(cls) -> KeyPoints:
|
||||
"""
|
||||
Create an empty Keypoints object with no keypoints.
|
||||
|
||||
Returns:
|
||||
(KeyPoints): An empty Keypoints object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
from supervision import Keypoints
|
||||
empty_keypoints = Keypoints.empty()
|
||||
```
|
||||
"""
|
||||
return cls(xy=np.empty((0, 0, 2), dtype=np.float32))
|
||||
|
|
@ -0,0 +1,36 @@
|
|||
from enum import Enum
|
||||
from typing import Dict, List, Tuple
|
||||
|
||||
Edges = List[Tuple[int, int]]
|
||||
|
||||
|
||||
class Skeleton(Enum):
|
||||
COCO = [
|
||||
(1, 2),
|
||||
(1, 3),
|
||||
(2, 3),
|
||||
(2, 4),
|
||||
(3, 5),
|
||||
(6, 12),
|
||||
(6, 7),
|
||||
(6, 8),
|
||||
(7, 13),
|
||||
(7, 9),
|
||||
(8, 10),
|
||||
(9, 11),
|
||||
(12, 13),
|
||||
(14, 12),
|
||||
(15, 13),
|
||||
(16, 14),
|
||||
(17, 15),
|
||||
]
|
||||
|
||||
|
||||
SKELETONS_BY_EDGE_COUNT: Dict[int, Edges] = {}
|
||||
SKELETONS_BY_VERTEX_COUNT: Dict[int, Edges] = {}
|
||||
|
||||
for skeleton in Skeleton:
|
||||
SKELETONS_BY_EDGE_COUNT[len(skeleton.value)] = skeleton.value
|
||||
|
||||
unique_vertices = set(vertex for edge in skeleton.value for vertex in edge)
|
||||
SKELETONS_BY_VERTEX_COUNT[len(unique_vertices)] = skeleton.value
|
||||
|
|
@ -3,6 +3,7 @@ from typing import List, Tuple
|
|||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import box_iou_batch
|
||||
from supervision.tracker.byte_tracker import matching
|
||||
from supervision.tracker.byte_tracker.basetrack import BaseTrack, TrackState
|
||||
from supervision.tracker.byte_tracker.kalman_filter import KalmanFilter
|
||||
|
|
@ -270,27 +271,28 @@ class ByteTrack:
|
|||
```
|
||||
"""
|
||||
|
||||
tracks = self.update_with_tensors(
|
||||
tensors=detections2boxes(detections=detections)
|
||||
)
|
||||
detections = Detections.empty()
|
||||
tensors = detections2boxes(detections=detections)
|
||||
tracks = self.update_with_tensors(tensors=tensors)
|
||||
|
||||
if len(tracks) > 0:
|
||||
detections.xyxy = np.array(
|
||||
[track.tlbr for track in tracks], dtype=np.float32
|
||||
)
|
||||
detections.class_id = np.array(
|
||||
[int(t.class_ids) for t in tracks], dtype=int
|
||||
)
|
||||
detections.tracker_id = np.array(
|
||||
[int(t.track_id) for t in tracks], dtype=int
|
||||
)
|
||||
detections.confidence = np.array(
|
||||
[t.score for t in tracks], dtype=np.float32
|
||||
)
|
||||
detection_bounding_boxes = np.asarray([det[:4] for det in tensors])
|
||||
track_bounding_boxes = np.asarray([track.tlbr for track in tracks])
|
||||
|
||||
ious = box_iou_batch(detection_bounding_boxes, track_bounding_boxes)
|
||||
|
||||
iou_costs = 1 - ious
|
||||
|
||||
matches, _, _ = matching.linear_assignment(iou_costs, 0.5)
|
||||
detections.tracker_id = np.full(len(detections), -1, dtype=int)
|
||||
for i_detection, i_track in matches:
|
||||
detections.tracker_id[i_detection] = int(tracks[i_track].track_id)
|
||||
|
||||
return detections[detections.tracker_id != -1]
|
||||
|
||||
else:
|
||||
detections.tracker_id = np.array([], dtype=int)
|
||||
|
||||
return detections
|
||||
return detections
|
||||
|
||||
def reset(self):
|
||||
"""
|
||||
|
|
|
|||
|
|
@ -0,0 +1,103 @@
|
|||
from functools import wraps
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
|
||||
|
||||
def convert_for_annotation_method(annotate_func):
|
||||
"""
|
||||
Decorates `BaseAnnotator.annotate` implementations, converts scene to
|
||||
an image type used internally by the annotators, converts back when annotation
|
||||
is complete.
|
||||
"""
|
||||
|
||||
@wraps(annotate_func)
|
||||
def wrapper(self, scene: ImageType, *args, **kwargs):
|
||||
if isinstance(scene, np.ndarray):
|
||||
return annotate_func(self, scene, *args, **kwargs)
|
||||
|
||||
if isinstance(scene, Image.Image):
|
||||
scene = pillow_to_cv2(scene)
|
||||
annotated = annotate_func(self, scene, *args, **kwargs)
|
||||
return cv2_to_pillow(image=annotated)
|
||||
|
||||
raise ValueError(f"Unsupported image type: {type(scene)}")
|
||||
|
||||
return wrapper
|
||||
|
||||
|
||||
def convert_for_image_processing(image_processing_fun):
|
||||
"""
|
||||
Decorates image processing functions that accept np.ndarray, converting `image` to
|
||||
np.ndarray, converts back when processing is complete.
|
||||
"""
|
||||
|
||||
@wraps(image_processing_fun)
|
||||
def wrapper(image: ImageType, *args, **kwargs):
|
||||
if isinstance(image, np.ndarray):
|
||||
return image_processing_fun(image, *args, **kwargs)
|
||||
|
||||
if isinstance(image, Image.Image):
|
||||
scene = pillow_to_cv2(image)
|
||||
annotated = image_processing_fun(scene, *args, **kwargs)
|
||||
return cv2_to_pillow(image=annotated)
|
||||
|
||||
raise ValueError(f"Unsupported image type: {type(image)}")
|
||||
|
||||
return wrapper
|
||||
|
||||
|
||||
def images_to_cv2(images: List[ImageType]) -> List[np.ndarray]:
|
||||
"""
|
||||
Converts images provided either as Pillow images or OpenCV
|
||||
images into OpenCV format.
|
||||
|
||||
Args:
|
||||
images (List[ImageType]): Images to be converted
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: List of input images in OpenCV format
|
||||
(with order preserved).
|
||||
|
||||
"""
|
||||
result = []
|
||||
for image in images:
|
||||
if issubclass(type(image), Image.Image):
|
||||
image = pillow_to_cv2(image=image)
|
||||
result.append(image)
|
||||
return result
|
||||
|
||||
|
||||
def pillow_to_cv2(image: Image.Image) -> np.ndarray:
|
||||
"""
|
||||
Converts Pillow image into OpenCV image, handling RGB -> BGR
|
||||
conversion.
|
||||
|
||||
Args:
|
||||
image (Image.Image): Pillow image (in RGB format).
|
||||
|
||||
Returns:
|
||||
(np.ndarray): Input image converted to OpenCV format.
|
||||
"""
|
||||
scene = np.array(image)
|
||||
scene = cv2.cvtColor(scene, cv2.COLOR_RGB2BGR)
|
||||
return scene
|
||||
|
||||
|
||||
def cv2_to_pillow(image: np.ndarray) -> Image.Image:
|
||||
"""
|
||||
Converts OpenCV image into Pillow image, handling BGR -> RGB
|
||||
conversion.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): OpenCV image (in BGR format).
|
||||
|
||||
Returns:
|
||||
(Image.Image): Input image converted to Pillow format.
|
||||
"""
|
||||
image = cv2.cvtColor(image, cv2.COLOR_BGR2RGB)
|
||||
return Image.fromarray(image)
|
||||
|
|
@ -1,107 +1,351 @@
|
|||
import itertools
|
||||
import math
|
||||
import os
|
||||
import shutil
|
||||
from typing import Optional, Tuple
|
||||
from functools import partial
|
||||
from typing import Callable, List, Literal, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.color import Color, unify_to_bgr
|
||||
from supervision.draw.utils import calculate_optimal_text_scale, draw_text
|
||||
from supervision.geometry.core import Point
|
||||
from supervision.utils.conversion import (
|
||||
convert_for_image_processing,
|
||||
cv2_to_pillow,
|
||||
images_to_cv2,
|
||||
)
|
||||
from supervision.utils.iterables import create_batches, fill
|
||||
|
||||
RelativePosition = Literal["top", "bottom"]
|
||||
|
||||
MAX_COLUMNS_FOR_SINGLE_ROW_GRID = 3
|
||||
|
||||
|
||||
def crop_image(image: np.ndarray, xyxy: np.ndarray) -> np.ndarray:
|
||||
@convert_for_image_processing
|
||||
def crop_image(
|
||||
image: ImageType,
|
||||
xyxy: Union[npt.NDArray[int], List[int], Tuple[int, int, int, int]],
|
||||
) -> ImageType:
|
||||
"""
|
||||
Crops the given image based on the given bounding box.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The image to be cropped, represented as a numpy array.
|
||||
xyxy (np.ndarray): A numpy array containing the bounding box coordinates
|
||||
in the format (x1, y1, x2, y2).
|
||||
image (ImageType): The image to be cropped. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
xyxy (Union[np.ndarray, List[int], Tuple[int, int, int, int]]): A bounding box
|
||||
coordinates in the format `(x_min, y_min, x_max, y_max)`, accepted as either
|
||||
a `numpy.ndarray`, a `list`, or a `tuple`.
|
||||
|
||||
Returns:
|
||||
(np.ndarray): The cropped image as a numpy array.
|
||||
(ImageType): The cropped image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
detection = sv.Detections(...)
|
||||
with sv.ImageSink(target_dir_path='target/directory/path') as sink:
|
||||
for xyxy in detection.xyxy:
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
sink.save_image(image=cropped_image)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
xyxy = [200, 400, 600, 800]
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
cropped_image.shape
|
||||
# (400, 400, 3)
|
||||
```
|
||||
"""
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
xyxy = [200, 400, 600, 800]
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
cropped_image.size
|
||||
# (400, 400)
|
||||
```
|
||||
|
||||
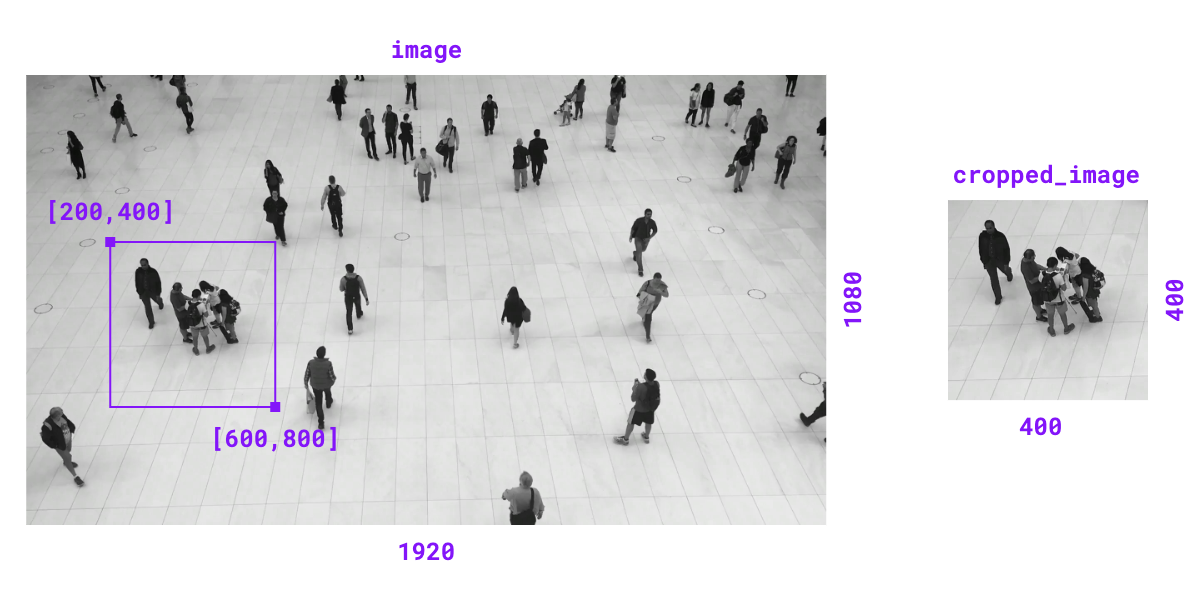{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
|
||||
if isinstance(xyxy, (list, tuple)):
|
||||
xyxy = np.array(xyxy)
|
||||
xyxy = np.round(xyxy).astype(int)
|
||||
x1, y1, x2, y2 = xyxy
|
||||
return image[y1:y2, x1:x2]
|
||||
x_min, y_min, x_max, y_max = xyxy.flatten()
|
||||
return image[y_min:y_max, x_min:x_max]
|
||||
|
||||
|
||||
def resize_image(image: np.ndarray, scale_factor: float) -> np.ndarray:
|
||||
@convert_for_image_processing
|
||||
def scale_image(image: ImageType, scale_factor: float) -> ImageType:
|
||||
"""
|
||||
Resizes an image by a given scale factor using cv2.INTER_LINEAR interpolation.
|
||||
Scales the given image based on the given scale factor.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The input image to be resized.
|
||||
scale_factor (float): The factor by which the image will be scaled. Scale factor
|
||||
> 1.0 zooms in, < 1.0 zooms out.
|
||||
image (ImageType): The image to be scaled. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
scale_factor (float): The factor by which the image will be scaled. Scale
|
||||
factor > `1.0` zooms in, < `1.0` zooms out.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The resized image.
|
||||
(ImageType): The scaled image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
Raises:
|
||||
ValueError: If the scale factor is non-positive.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
scaled_image = sv.scale_image(image=image, scale_factor=0.5)
|
||||
scaled_image.shape
|
||||
# (540, 960, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
scaled_image = sv.scale_image(image=image, scale_factor=0.5)
|
||||
scaled_image.size
|
||||
# (960, 540)
|
||||
```
|
||||
"""
|
||||
if scale_factor <= 0:
|
||||
raise ValueError("Scale factor must be positive.")
|
||||
|
||||
old_width, old_height = image.shape[1], image.shape[0]
|
||||
nwe_width = int(old_width * scale_factor)
|
||||
new_height = int(old_height * scale_factor)
|
||||
|
||||
return cv2.resize(image, (nwe_width, new_height), interpolation=cv2.INTER_LINEAR)
|
||||
width_old, height_old = image.shape[1], image.shape[0]
|
||||
width_new = int(width_old * scale_factor)
|
||||
height_new = int(height_old * scale_factor)
|
||||
return cv2.resize(image, (width_new, height_new), interpolation=cv2.INTER_LINEAR)
|
||||
|
||||
|
||||
def place_image(
|
||||
scene: np.ndarray, image: np.ndarray, anchor: Tuple[int, int]
|
||||
) -> np.ndarray:
|
||||
@convert_for_image_processing
|
||||
def resize_image(
|
||||
image: ImageType,
|
||||
resolution_wh: Tuple[int, int],
|
||||
keep_aspect_ratio: bool = False,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Resizes the given image to a specified resolution. Can maintain the original aspect
|
||||
ratio or resize directly to the desired dimensions.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be resized. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
resolution_wh (Tuple[int, int]): The target resolution as
|
||||
`(width, height)`.
|
||||
keep_aspect_ratio (bool, optional): Flag to maintain the image's original
|
||||
aspect ratio. Defaults to `False`.
|
||||
|
||||
Returns:
|
||||
(ImageType): The resized image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
resized_image = sv.resize_image(
|
||||
image=image, resolution_wh=(1000, 1000), keep_aspect_ratio=True
|
||||
)
|
||||
resized_image.shape
|
||||
# (562, 1000, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
resized_image = sv.resize_image(
|
||||
image=image, resolution_wh=(1000, 1000), keep_aspect_ratio=True
|
||||
)
|
||||
resized_image.size
|
||||
# (1000, 562)
|
||||
```
|
||||
|
||||
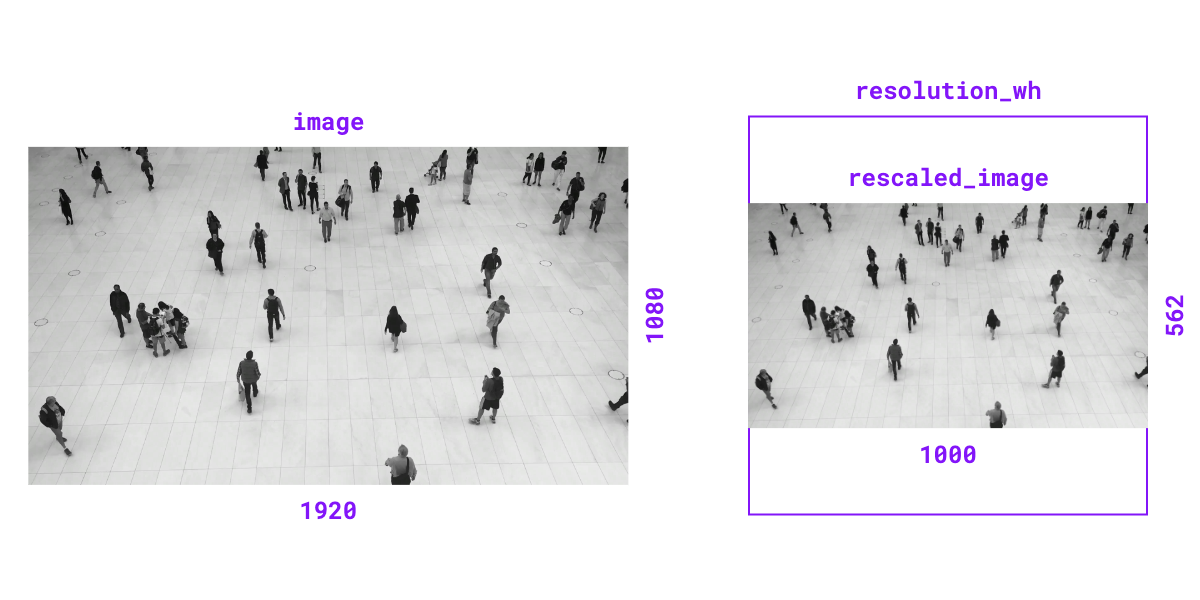{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
if keep_aspect_ratio:
|
||||
image_ratio = image.shape[1] / image.shape[0]
|
||||
target_ratio = resolution_wh[0] / resolution_wh[1]
|
||||
if image_ratio >= target_ratio:
|
||||
width_new = resolution_wh[0]
|
||||
height_new = int(resolution_wh[0] / image_ratio)
|
||||
else:
|
||||
height_new = resolution_wh[1]
|
||||
width_new = int(resolution_wh[1] * image_ratio)
|
||||
else:
|
||||
width_new, height_new = resolution_wh
|
||||
|
||||
return cv2.resize(image, (width_new, height_new), interpolation=cv2.INTER_LINEAR)
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def letterbox_image(
|
||||
image: ImageType,
|
||||
resolution_wh: Tuple[int, int],
|
||||
color: Union[Tuple[int, int, int], Color] = Color.BLACK,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Resizes and pads an image to a specified resolution with a given color, maintaining
|
||||
the original aspect ratio.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be resized. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
resolution_wh (Tuple[int, int]): The target resolution as
|
||||
`(width, height)`.
|
||||
color (Union[Tuple[int, int, int], Color]): The color to pad with. If tuple
|
||||
provided it should be in BGR format.
|
||||
|
||||
Returns:
|
||||
(ImageType): The resized image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
letterboxed_image = sv.letterbox_image(image=image, resolution_wh=(1000, 1000))
|
||||
letterboxed_image.shape
|
||||
# (1000, 1000, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
letterboxed_image = sv.letterbox_image(image=image, resolution_wh=(1000, 1000))
|
||||
letterboxed_image.size
|
||||
# (1000, 1000)
|
||||
```
|
||||
|
||||
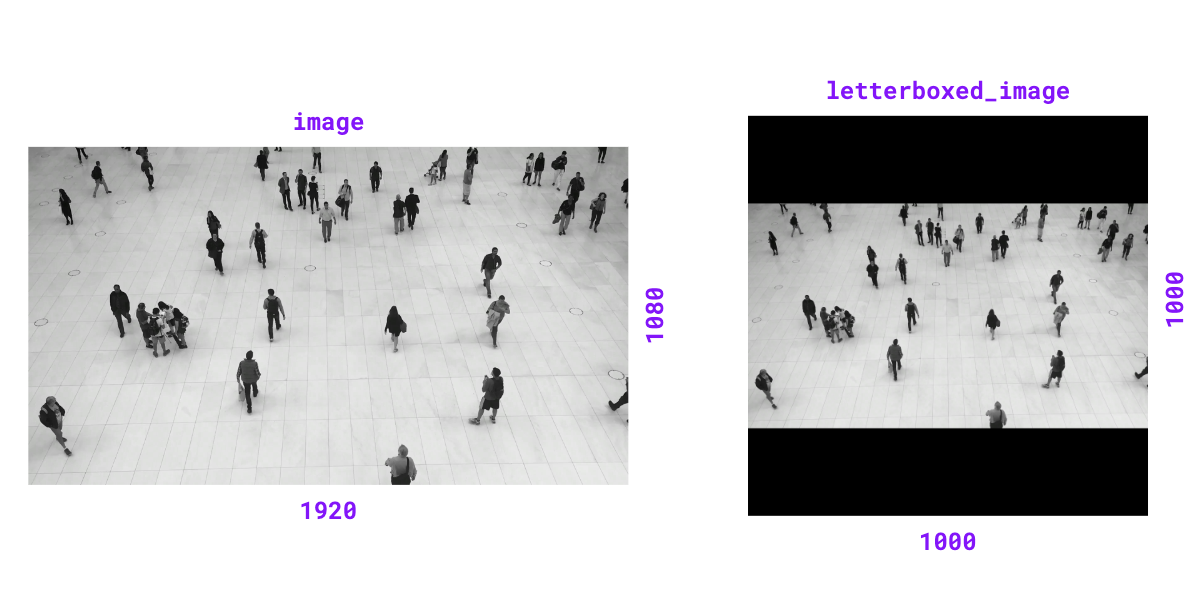{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
color = unify_to_bgr(color=color)
|
||||
resized_image = resize_image(
|
||||
image=image, resolution_wh=resolution_wh, keep_aspect_ratio=True
|
||||
)
|
||||
height_new, width_new = resized_image.shape[:2]
|
||||
padding_top = (resolution_wh[1] - height_new) // 2
|
||||
padding_bottom = resolution_wh[1] - height_new - padding_top
|
||||
padding_left = (resolution_wh[0] - width_new) // 2
|
||||
padding_right = resolution_wh[0] - width_new - padding_left
|
||||
return cv2.copyMakeBorder(
|
||||
resized_image,
|
||||
padding_top,
|
||||
padding_bottom,
|
||||
padding_left,
|
||||
padding_right,
|
||||
cv2.BORDER_CONSTANT,
|
||||
value=color,
|
||||
)
|
||||
|
||||
|
||||
def overlay_image(
|
||||
image: npt.NDArray[np.uint8],
|
||||
overlay: npt.NDArray[np.uint8],
|
||||
anchor: Tuple[int, int],
|
||||
) -> npt.NDArray[np.uint8]:
|
||||
"""
|
||||
Places an image onto a scene at a given anchor point, handling cases where
|
||||
the image's position is partially or completely outside the scene's bounds.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The background scene onto which the image is placed.
|
||||
image (np.ndarray): The image to be placed onto the scene.
|
||||
anchor (Tuple[int, int]): The (x, y) coordinates in the scene where the
|
||||
image (np.ndarray): The background scene onto which the image is placed.
|
||||
overlay (np.ndarray): The image to be placed onto the scene.
|
||||
anchor (Tuple[int, int]): The `(x, y)` coordinates in the scene where the
|
||||
top-left corner of the image will be placed.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The modified scene with the image placed at the anchor point,
|
||||
or unchanged if the image placement is completely outside the scene.
|
||||
"""
|
||||
scene_height, scene_width = scene.shape[:2]
|
||||
image_height, image_width = image.shape[:2]
|
||||
(np.ndarray): The result image with overlay.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
overlay = np.zeros((400, 400, 3), dtype=np.uint8)
|
||||
result_image = sv.overlay_image(image=image, overlay=overlay, anchor=(200, 400))
|
||||
```
|
||||
|
||||
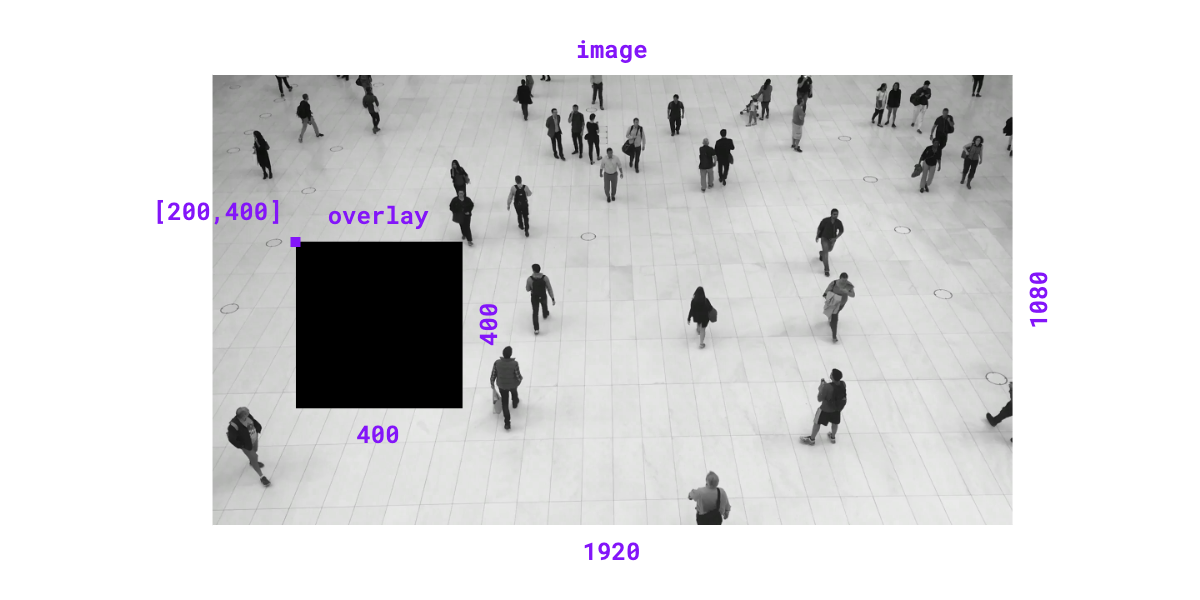{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
scene_height, scene_width = image.shape[:2]
|
||||
image_height, image_width = overlay.shape[:2]
|
||||
anchor_x, anchor_y = anchor
|
||||
|
||||
is_out_horizontally = anchor_x + image_width <= 0 or anchor_x >= scene_width
|
||||
is_out_vertically = anchor_y + image_height <= 0 or anchor_y >= scene_height
|
||||
|
||||
if is_out_horizontally or is_out_vertically:
|
||||
return scene
|
||||
return image
|
||||
|
||||
start_y = max(anchor_y, 0)
|
||||
start_x = max(anchor_x, 0)
|
||||
end_y = min(scene_height, anchor_y + image_height)
|
||||
end_x = min(scene_width, anchor_x + image_width)
|
||||
x_min = max(anchor_x, 0)
|
||||
y_min = max(anchor_y, 0)
|
||||
x_max = min(scene_width, anchor_x + image_width)
|
||||
y_max = min(scene_height, anchor_y + image_height)
|
||||
|
||||
crop_start_y = max(-anchor_y, 0)
|
||||
crop_start_x = max(-anchor_x, 0)
|
||||
crop_end_y = image_height - max((anchor_y + image_height) - scene_height, 0)
|
||||
crop_end_x = image_width - max((anchor_x + image_width) - scene_width, 0)
|
||||
crop_x_min = max(-anchor_x, 0)
|
||||
crop_y_min = max(-anchor_y, 0)
|
||||
crop_x_max = image_width - max((anchor_x + image_width) - scene_width, 0)
|
||||
crop_y_max = image_height - max((anchor_y + image_height) - scene_height, 0)
|
||||
|
||||
scene[start_y:end_y, start_x:end_x] = image[
|
||||
crop_start_y:crop_end_y, crop_start_x:crop_end_x
|
||||
image[y_min:y_max, x_min:x_max] = overlay[
|
||||
crop_y_min:crop_y_max, crop_x_min:crop_x_max
|
||||
]
|
||||
|
||||
return scene
|
||||
return image
|
||||
|
||||
|
||||
class ImageSink:
|
||||
|
|
@ -125,13 +369,13 @@ class ImageSink:
|
|||
```python
|
||||
import supervision as sv
|
||||
|
||||
with sv.ImageSink(target_dir_path='target/directory/path',
|
||||
overwrite=True) as sink:
|
||||
for image in sv.get_video_frames_generator(
|
||||
source_path='source_video.mp4', stride=2):
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>, stride=2)
|
||||
|
||||
with sv.ImageSink(target_dir_path=<TARGET_CROPS_DIRECTORY>) as sink:
|
||||
for image in frames_generator:
|
||||
sink.save_image(image=image)
|
||||
```
|
||||
"""
|
||||
""" # noqa E501 // docs
|
||||
|
||||
self.target_dir_path = target_dir_path
|
||||
self.overwrite = overwrite
|
||||
|
|
@ -153,7 +397,8 @@ class ImageSink:
|
|||
Save a given image in the target directory.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The image to be saved.
|
||||
image (np.ndarray): The image to be saved. The image must be in BGR color
|
||||
format.
|
||||
image_name (str, optional): The name to use for the saved image.
|
||||
If not provided, a name will be
|
||||
generated using the `image_name_pattern`.
|
||||
|
|
@ -167,3 +412,357 @@ class ImageSink:
|
|||
|
||||
def __exit__(self, exc_type, exc_value, exc_traceback):
|
||||
pass
|
||||
|
||||
|
||||
def create_tiles(
|
||||
images: List[ImageType],
|
||||
grid_size: Optional[Tuple[Optional[int], Optional[int]]] = None,
|
||||
single_tile_size: Optional[Tuple[int, int]] = None,
|
||||
tile_scaling: Literal["min", "max", "avg"] = "avg",
|
||||
tile_padding_color: Union[Tuple[int, int, int], Color] = Color.from_hex("#D9D9D9"),
|
||||
tile_margin: int = 10,
|
||||
tile_margin_color: Union[Tuple[int, int, int], Color] = Color.from_hex("#BFBEBD"),
|
||||
return_type: Literal["auto", "cv2", "pillow"] = "auto",
|
||||
titles: Optional[List[Optional[str]]] = None,
|
||||
titles_anchors: Optional[Union[Point, List[Optional[Point]]]] = None,
|
||||
titles_color: Union[Tuple[int, int, int], Color] = Color.from_hex("#262523"),
|
||||
titles_scale: Optional[float] = None,
|
||||
titles_thickness: int = 1,
|
||||
titles_padding: int = 10,
|
||||
titles_text_font: int = cv2.FONT_HERSHEY_SIMPLEX,
|
||||
titles_background_color: Union[Tuple[int, int, int], Color] = Color.from_hex(
|
||||
"#D9D9D9"
|
||||
),
|
||||
default_title_placement: RelativePosition = "top",
|
||||
) -> ImageType:
|
||||
"""
|
||||
Creates tiles mosaic from input images, automating grid placement and
|
||||
converting images to common resolution maintaining aspect ratio. It is
|
||||
also possible to render text titles on tiles, using optional set of
|
||||
parameters specifying text drawing (see parameters description).
|
||||
|
||||
Automated grid placement will try to maintain square shape of grid
|
||||
(with size being the nearest integer square root of #images), up to two exceptions:
|
||||
* if there are up to 3 images - images will be displayed in single row
|
||||
* if square-grid placement causes last row to be empty - number of rows is trimmed
|
||||
until last row has at least one image
|
||||
|
||||
Args:
|
||||
images (List[ImageType]): Images to create tiles. Elements can be either
|
||||
np.ndarray or PIL.Image, common representation will be agreed by the
|
||||
function.
|
||||
grid_size (Optional[Tuple[Optional[int], Optional[int]]]): Expected grid
|
||||
size in format (n_rows, n_cols). If not given - automated grid placement
|
||||
will be applied. One may also provide only one out of two elements of the
|
||||
tuple - then grid will be created with either n_rows or n_cols fixed,
|
||||
leaving the other dimension to be adjusted by the number of images
|
||||
single_tile_size (Optional[Tuple[int, int]]): sizeof a single tile element
|
||||
provided in (width, height) format. If not given - size of tile will be
|
||||
automatically calculated based on `tile_scaling` parameter.
|
||||
tile_scaling (Literal["min", "max", "avg"]): If `single_tile_size` is not
|
||||
given - parameter will be used to calculate tile size - using
|
||||
min / max / avg size of image provided in `images` list.
|
||||
tile_padding_color (Union[Tuple[int, int, int], sv.Color]): Color to be used in
|
||||
images letterbox procedure (while standardising tiles sizes) as a padding.
|
||||
If tuple provided - should be BGR.
|
||||
tile_margin (int): size of margin between tiles (in pixels)
|
||||
tile_margin_color (Union[Tuple[int, int, int], sv.Color]): Color of tile margin.
|
||||
If tuple provided - should be BGR.
|
||||
return_type (Literal["auto", "cv2", "pillow"]): Parameter dictates the format of
|
||||
return image. One may choose specific type ("cv2" or "pillow") to enforce
|
||||
conversion. "auto" mode takes a majority vote between types of elements in
|
||||
`images` list - resolving draws in favour of OpenCV format. "auto" can be
|
||||
safely used when all input images are of the same type.
|
||||
titles (Optional[List[Optional[str]]]): Optional titles to be added to tiles.
|
||||
Elements of that list may be empty - then specific tile (in order presented
|
||||
in `images` parameter) will not be filled with title. It is possible to
|
||||
provide list of titles shorter than `images` - then remaining titles will
|
||||
be assumed empty.
|
||||
titles_anchors (Optional[Union[Point, List[Optional[Point]]]]): Parameter to
|
||||
specify anchor points for titles. It is possible to specify anchor either
|
||||
globally or for specific tiles (following order of `images`).
|
||||
If not given (either globally, or for specific element of the list),
|
||||
it will be calculated automatically based on `default_title_placement`.
|
||||
titles_color (Union[Tuple[int, int, int], Color]): Color of titles text.
|
||||
If tuple provided - should be BGR.
|
||||
titles_scale (Optional[float]): Scale of titles. If not provided - value will
|
||||
be calculated using `calculate_optimal_text_scale(...)`.
|
||||
titles_thickness (int): Thickness of titles text.
|
||||
titles_padding (int): Size of titles padding.
|
||||
titles_text_font (int): Font to be used to render titles. Must be integer
|
||||
constant representing OpenCV font.
|
||||
(See docs: https://docs.opencv.org/4.x/d6/d6e/group__imgproc__draw.html)
|
||||
titles_background_color (Union[Tuple[int, int, int], Color]): Color of title
|
||||
text padding.
|
||||
default_title_placement (Literal["top", "bottom"]): Parameter specifies title
|
||||
anchor placement in case if explicit anchor is not provided.
|
||||
|
||||
Returns:
|
||||
ImageType: Image with all input images located in tails grid. The output type is
|
||||
determined by `return_type` parameter.
|
||||
|
||||
Raises:
|
||||
ValueError: In case when input images list is empty, provided `grid_size` is too
|
||||
small to fit all images, `tile_scaling` mode is invalid.
|
||||
"""
|
||||
if len(images) == 0:
|
||||
raise ValueError("Could not create image tiles from empty list of images.")
|
||||
if return_type == "auto":
|
||||
return_type = _negotiate_tiles_format(images=images)
|
||||
tile_padding_color = unify_to_bgr(color=tile_padding_color)
|
||||
tile_margin_color = unify_to_bgr(color=tile_margin_color)
|
||||
images = images_to_cv2(images=images)
|
||||
if single_tile_size is None:
|
||||
single_tile_size = _aggregate_images_shape(images=images, mode=tile_scaling)
|
||||
resized_images = [
|
||||
letterbox_image(
|
||||
image=i, resolution_wh=single_tile_size, color=tile_padding_color
|
||||
)
|
||||
for i in images
|
||||
]
|
||||
grid_size = _establish_grid_size(images=images, grid_size=grid_size)
|
||||
if len(images) > grid_size[0] * grid_size[1]:
|
||||
raise ValueError(
|
||||
f"Could not place {len(images)} in grid with size: {grid_size}."
|
||||
)
|
||||
if titles is not None:
|
||||
titles = fill(sequence=titles, desired_size=len(images), content=None)
|
||||
titles_anchors = (
|
||||
[titles_anchors]
|
||||
if not issubclass(type(titles_anchors), list)
|
||||
else titles_anchors
|
||||
)
|
||||
titles_anchors = fill(
|
||||
sequence=titles_anchors, desired_size=len(images), content=None
|
||||
)
|
||||
titles_color = unify_to_bgr(color=titles_color)
|
||||
titles_background_color = unify_to_bgr(color=titles_background_color)
|
||||
tiles = _generate_tiles(
|
||||
images=resized_images,
|
||||
grid_size=grid_size,
|
||||
single_tile_size=single_tile_size,
|
||||
tile_padding_color=tile_padding_color,
|
||||
tile_margin=tile_margin,
|
||||
tile_margin_color=tile_margin_color,
|
||||
titles=titles,
|
||||
titles_anchors=titles_anchors,
|
||||
titles_color=titles_color,
|
||||
titles_scale=titles_scale,
|
||||
titles_thickness=titles_thickness,
|
||||
titles_padding=titles_padding,
|
||||
titles_text_font=titles_text_font,
|
||||
titles_background_color=titles_background_color,
|
||||
default_title_placement=default_title_placement,
|
||||
)
|
||||
if return_type == "pillow":
|
||||
tiles = cv2_to_pillow(image=tiles)
|
||||
return tiles
|
||||
|
||||
|
||||
def _negotiate_tiles_format(images: List[ImageType]) -> Literal["cv2", "pillow"]:
|
||||
number_of_np_arrays = sum(issubclass(type(i), np.ndarray) for i in images)
|
||||
if number_of_np_arrays >= (len(images) // 2):
|
||||
return "cv2"
|
||||
return "pillow"
|
||||
|
||||
|
||||
def _calculate_aggregated_images_shape(
|
||||
images: List[np.ndarray], aggregator: Callable[[List[int]], float]
|
||||
) -> Tuple[int, int]:
|
||||
height = round(aggregator([i.shape[0] for i in images]))
|
||||
width = round(aggregator([i.shape[1] for i in images]))
|
||||
return width, height
|
||||
|
||||
|
||||
SHAPE_AGGREGATION_FUN = {
|
||||
"min": partial(_calculate_aggregated_images_shape, aggregator=np.min),
|
||||
"max": partial(_calculate_aggregated_images_shape, aggregator=np.max),
|
||||
"avg": partial(_calculate_aggregated_images_shape, aggregator=np.average),
|
||||
}
|
||||
|
||||
|
||||
def _aggregate_images_shape(
|
||||
images: List[np.ndarray], mode: Literal["min", "max", "avg"]
|
||||
) -> Tuple[int, int]:
|
||||
if mode not in SHAPE_AGGREGATION_FUN:
|
||||
raise ValueError(
|
||||
f"Could not aggregate images shape - provided unknown mode: {mode}. "
|
||||
f"Supported modes: {list(SHAPE_AGGREGATION_FUN.keys())}."
|
||||
)
|
||||
return SHAPE_AGGREGATION_FUN[mode](images)
|
||||
|
||||
|
||||
def _establish_grid_size(
|
||||
images: List[np.ndarray], grid_size: Optional[Tuple[Optional[int], Optional[int]]]
|
||||
) -> Tuple[int, int]:
|
||||
if grid_size is None or all(e is None for e in grid_size):
|
||||
return _negotiate_grid_size(images=images)
|
||||
if grid_size[0] is None:
|
||||
return math.ceil(len(images) / grid_size[1]), grid_size[1]
|
||||
if grid_size[1] is None:
|
||||
return grid_size[0], math.ceil(len(images) / grid_size[0])
|
||||
return grid_size
|
||||
|
||||
|
||||
def _negotiate_grid_size(images: List[np.ndarray]) -> Tuple[int, int]:
|
||||
if len(images) <= MAX_COLUMNS_FOR_SINGLE_ROW_GRID:
|
||||
return 1, len(images)
|
||||
nearest_sqrt = math.ceil(np.sqrt(len(images)))
|
||||
proposed_columns = nearest_sqrt
|
||||
proposed_rows = nearest_sqrt
|
||||
while proposed_columns * (proposed_rows - 1) >= len(images):
|
||||
proposed_rows -= 1
|
||||
return proposed_rows, proposed_columns
|
||||
|
||||
|
||||
def _generate_tiles(
|
||||
images: List[np.ndarray],
|
||||
grid_size: Tuple[int, int],
|
||||
single_tile_size: Tuple[int, int],
|
||||
tile_padding_color: Tuple[int, int, int],
|
||||
tile_margin: int,
|
||||
tile_margin_color: Tuple[int, int, int],
|
||||
titles: Optional[List[Optional[str]]],
|
||||
titles_anchors: List[Optional[Point]],
|
||||
titles_color: Tuple[int, int, int],
|
||||
titles_scale: Optional[float],
|
||||
titles_thickness: int,
|
||||
titles_padding: int,
|
||||
titles_text_font: int,
|
||||
titles_background_color: Tuple[int, int, int],
|
||||
default_title_placement: RelativePosition,
|
||||
) -> np.ndarray:
|
||||
images = _draw_texts(
|
||||
images=images,
|
||||
titles=titles,
|
||||
titles_anchors=titles_anchors,
|
||||
titles_color=titles_color,
|
||||
titles_scale=titles_scale,
|
||||
titles_thickness=titles_thickness,
|
||||
titles_padding=titles_padding,
|
||||
titles_text_font=titles_text_font,
|
||||
titles_background_color=titles_background_color,
|
||||
default_title_placement=default_title_placement,
|
||||
)
|
||||
rows, columns = grid_size
|
||||
tiles_elements = list(create_batches(sequence=images, batch_size=columns))
|
||||
while len(tiles_elements[-1]) < columns:
|
||||
tiles_elements[-1].append(
|
||||
_generate_color_image(shape=single_tile_size, color=tile_padding_color)
|
||||
)
|
||||
while len(tiles_elements) < rows:
|
||||
tiles_elements.append(
|
||||
[_generate_color_image(shape=single_tile_size, color=tile_padding_color)]
|
||||
* columns
|
||||
)
|
||||
return _merge_tiles_elements(
|
||||
tiles_elements=tiles_elements,
|
||||
grid_size=grid_size,
|
||||
single_tile_size=single_tile_size,
|
||||
tile_margin=tile_margin,
|
||||
tile_margin_color=tile_margin_color,
|
||||
)
|
||||
|
||||
|
||||
def _draw_texts(
|
||||
images: List[np.ndarray],
|
||||
titles: Optional[List[Optional[str]]],
|
||||
titles_anchors: List[Optional[Point]],
|
||||
titles_color: Tuple[int, int, int],
|
||||
titles_scale: Optional[float],
|
||||
titles_thickness: int,
|
||||
titles_padding: int,
|
||||
titles_text_font: int,
|
||||
titles_background_color: Tuple[int, int, int],
|
||||
default_title_placement: RelativePosition,
|
||||
) -> List[np.ndarray]:
|
||||
if titles is None:
|
||||
return images
|
||||
titles_anchors = _prepare_default_titles_anchors(
|
||||
images=images,
|
||||
titles_anchors=titles_anchors,
|
||||
default_title_placement=default_title_placement,
|
||||
)
|
||||
if titles_scale is None:
|
||||
image_height, image_width = images[0].shape[:2]
|
||||
titles_scale = calculate_optimal_text_scale(
|
||||
resolution_wh=(image_width, image_height)
|
||||
)
|
||||
result = []
|
||||
for image, text, anchor in zip(images, titles, titles_anchors):
|
||||
if text is None:
|
||||
result.append(image)
|
||||
continue
|
||||
processed_image = draw_text(
|
||||
scene=image,
|
||||
text=text,
|
||||
text_anchor=anchor,
|
||||
text_color=Color.from_bgr_tuple(titles_color),
|
||||
text_scale=titles_scale,
|
||||
text_thickness=titles_thickness,
|
||||
text_padding=titles_padding,
|
||||
text_font=titles_text_font,
|
||||
background_color=Color.from_bgr_tuple(titles_background_color),
|
||||
)
|
||||
result.append(processed_image)
|
||||
return result
|
||||
|
||||
|
||||
def _prepare_default_titles_anchors(
|
||||
images: List[np.ndarray],
|
||||
titles_anchors: List[Optional[Point]],
|
||||
default_title_placement: RelativePosition,
|
||||
) -> List[Point]:
|
||||
result = []
|
||||
for image, anchor in zip(images, titles_anchors):
|
||||
if anchor is not None:
|
||||
result.append(anchor)
|
||||
continue
|
||||
image_height, image_width = image.shape[:2]
|
||||
if default_title_placement == "top":
|
||||
default_anchor = Point(x=image_width / 2, y=image_height * 0.1)
|
||||
else:
|
||||
default_anchor = Point(x=image_width / 2, y=image_height * 0.9)
|
||||
result.append(default_anchor)
|
||||
return result
|
||||
|
||||
|
||||
def _merge_tiles_elements(
|
||||
tiles_elements: List[List[np.ndarray]],
|
||||
grid_size: Tuple[int, int],
|
||||
single_tile_size: Tuple[int, int],
|
||||
tile_margin: int,
|
||||
tile_margin_color: Tuple[int, int, int],
|
||||
) -> np.ndarray:
|
||||
vertical_padding = (
|
||||
np.ones((single_tile_size[1], tile_margin, 3)) * tile_margin_color
|
||||
)
|
||||
merged_rows = [
|
||||
np.concatenate(
|
||||
list(
|
||||
itertools.chain.from_iterable(
|
||||
zip(row, [vertical_padding] * grid_size[1])
|
||||
)
|
||||
)[:-1],
|
||||
axis=1,
|
||||
)
|
||||
for row in tiles_elements
|
||||
]
|
||||
row_width = merged_rows[0].shape[1]
|
||||
horizontal_padding = (
|
||||
np.ones((tile_margin, row_width, 3), dtype=np.uint8) * tile_margin_color
|
||||
)
|
||||
rows_with_paddings = []
|
||||
for row in merged_rows:
|
||||
rows_with_paddings.append(row)
|
||||
rows_with_paddings.append(horizontal_padding)
|
||||
return np.concatenate(
|
||||
rows_with_paddings[:-1],
|
||||
axis=0,
|
||||
).astype(np.uint8)
|
||||
|
||||
|
||||
def _generate_color_image(
|
||||
shape: Tuple[int, int], color: Tuple[int, int, int]
|
||||
) -> np.ndarray:
|
||||
return np.ones(shape[::-1] + (3,), dtype=np.uint8) * color
|
||||
|
|
|
|||
|
|
@ -0,0 +1,70 @@
|
|||
from typing import Generator, Iterable, List, TypeVar
|
||||
|
||||
V = TypeVar("V")
|
||||
|
||||
|
||||
def create_batches(
|
||||
sequence: Iterable[V], batch_size: int
|
||||
) -> Generator[List[V], None, None]:
|
||||
"""
|
||||
Provides a generator that yields chunks of the input sequence
|
||||
of the size specified by the `batch_size` parameter. The last
|
||||
chunk may be a smaller batch.
|
||||
|
||||
Args:
|
||||
sequence (Iterable[V]): The sequence to be split into batches.
|
||||
batch_size (int): The expected size of a batch.
|
||||
|
||||
Returns:
|
||||
(Generator[List[V], None, None]): A generator that yields chunks
|
||||
of `sequence` of size `batch_size`, up to the length of
|
||||
the input `sequence`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
list(create_batches([1, 2, 3, 4, 5], 2))
|
||||
# [[1, 2], [3, 4], [5]]
|
||||
|
||||
list(create_batches("abcde", 3))
|
||||
# [['a', 'b', 'c'], ['d', 'e']]
|
||||
```
|
||||
"""
|
||||
batch_size = max(batch_size, 1)
|
||||
current_batch = []
|
||||
for element in sequence:
|
||||
if len(current_batch) == batch_size:
|
||||
yield current_batch
|
||||
current_batch = []
|
||||
current_batch.append(element)
|
||||
if current_batch:
|
||||
yield current_batch
|
||||
|
||||
|
||||
def fill(sequence: List[V], desired_size: int, content: V) -> List[V]:
|
||||
"""
|
||||
Fill the sequence with padding elements until the sequence reaches
|
||||
the desired size.
|
||||
|
||||
Args:
|
||||
sequence (List[V]): The input sequence.
|
||||
desired_size (int): The expected size of the output list. The
|
||||
difference between this value and the actual length of `sequence`
|
||||
(if positive) dictates how many elements will be added as padding.
|
||||
content (V): The element to be placed at the end of the input
|
||||
`sequence` as padding.
|
||||
|
||||
Returns:
|
||||
(List[V]): A padded version of the input `sequence` (if needed).
|
||||
|
||||
Examples:
|
||||
```python
|
||||
fill([1, 2], 4, 0)
|
||||
# [1, 2, 0, 0]
|
||||
|
||||
fill(['a', 'b'], 3, 'c')
|
||||
# ['a', 'b', 'c']
|
||||
```
|
||||
"""
|
||||
missing_size = max(0, desired_size - len(sequence))
|
||||
sequence.extend([content] * missing_size)
|
||||
return sequence
|
||||
|
|
@ -5,7 +5,7 @@ import matplotlib.pyplot as plt
|
|||
from PIL import Image
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.annotators.utils import pillow_to_cv2
|
||||
from supervision.utils.conversion import pillow_to_cv2
|
||||
|
||||
|
||||
def plot_image(
|
||||
|
|
|
|||
|
|
@ -105,6 +105,13 @@ class VideoSink:
|
|||
return self
|
||||
|
||||
def write_frame(self, frame: np.ndarray):
|
||||
"""
|
||||
Writes a single video frame to the target video file.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The video frame to be written to the file. The frame
|
||||
must be in BGR color format.
|
||||
"""
|
||||
self.__writer.write(frame)
|
||||
|
||||
def __exit__(self, exc_type, exc_value, exc_traceback):
|
||||
|
|
|
|||
|
|
@ -0,0 +1,141 @@
|
|||
from typing import Any, Dict
|
||||
|
||||
import numpy as np
|
||||
|
||||
|
||||
def validate_xyxy(xyxy: Any) -> None:
|
||||
expected_shape = "(_, 4)"
|
||||
actual_shape = str(getattr(xyxy, "shape", None))
|
||||
is_valid = isinstance(xyxy, np.ndarray) and xyxy.ndim == 2 and xyxy.shape[1] == 4
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"xyxy must be a 2D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_mask(mask: Any, n: int) -> None:
|
||||
expected_shape = f"({n}, H, W)"
|
||||
actual_shape = str(getattr(mask, "shape", None))
|
||||
is_valid = mask is None or (
|
||||
isinstance(mask, np.ndarray) and len(mask.shape) == 3 and mask.shape[0] == n
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"mask must be a 3D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_class_id(class_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(class_id, "shape", None))
|
||||
is_valid = class_id is None or (
|
||||
isinstance(class_id, np.ndarray) and class_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"class_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_confidence(confidence: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(confidence, "shape", None))
|
||||
is_valid = confidence is None or (
|
||||
isinstance(confidence, np.ndarray) and confidence.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"confidence must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_keypoint_confidence(confidence: Any, n: int, m: int) -> None:
|
||||
expected_shape = f"({n,m})"
|
||||
actual_shape = str(getattr(confidence, "shape", None))
|
||||
|
||||
if confidence is not None:
|
||||
is_valid = isinstance(confidence, np.ndarray) and confidence.shape == (n, m)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"confidence must be a 1D np.ndarray with shape {expected_shape}, but "
|
||||
"got"
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(tracker_id, "shape", None))
|
||||
is_valid = tracker_id is None or (
|
||||
isinstance(tracker_id, np.ndarray) and tracker_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"tracker_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_data(data: Dict[str, Any], n: int) -> None:
|
||||
for key, value in data.items():
|
||||
if isinstance(value, list):
|
||||
if len(value) != n:
|
||||
raise ValueError(f"Length of list for key '{key}' must be {n}")
|
||||
elif isinstance(value, np.ndarray):
|
||||
if value.ndim == 1 and value.shape[0] != n:
|
||||
raise ValueError(f"Shape of np.ndarray for key '{key}' must be ({n},)")
|
||||
elif value.ndim > 1 and value.shape[0] != n:
|
||||
raise ValueError(
|
||||
f"First dimension of np.ndarray for key '{key}' must have size {n}"
|
||||
)
|
||||
else:
|
||||
raise ValueError(f"Value for key '{key}' must be a list or np.ndarray")
|
||||
|
||||
|
||||
def validate_xy(xy: Any, n: int, m: int) -> None:
|
||||
expected_shape = f"({n, m},)"
|
||||
actual_shape = str(getattr(xy, "shape", None))
|
||||
|
||||
is_valid = isinstance(xy, np.ndarray) and (
|
||||
xy.shape == (n, m, 2) or xy.shape == (n, m, 3)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"xy must be a 2D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_detections_fields(
|
||||
xyxy: Any,
|
||||
mask: Any,
|
||||
class_id: Any,
|
||||
confidence: Any,
|
||||
tracker_id: Any,
|
||||
data: Dict[str, Any],
|
||||
) -> None:
|
||||
validate_xyxy(xyxy)
|
||||
n = len(xyxy)
|
||||
validate_mask(mask, n)
|
||||
validate_class_id(class_id, n)
|
||||
validate_confidence(confidence, n)
|
||||
validate_tracker_id(tracker_id, n)
|
||||
validate_data(data, n)
|
||||
|
||||
|
||||
def validate_keypoints_fields(
|
||||
xy: Any,
|
||||
class_id: Any,
|
||||
confidence: Any,
|
||||
data: Dict[str, Any],
|
||||
) -> None:
|
||||
n = len(xy)
|
||||
m = len(xy[0]) if len(xy) > 0 else 0
|
||||
validate_xy(xy, n, m)
|
||||
validate_class_id(class_id, n)
|
||||
validate_keypoint_confidence(confidence, n, m)
|
||||
validate_data(data, n)
|
||||
|
|
@ -1045,7 +1045,7 @@ def test_merge_data(
|
|||
"test_1": [1],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
), # data dict with a single list field and integer index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
|
|
@ -1055,7 +1055,7 @@ def test_merge_data(
|
|||
"test_1": np.array([1]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
), # data dict with a single np.array field and integer index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
|
|
@ -1065,7 +1065,7 @@ def test_merge_data(
|
|||
"test_1": [1, 2],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
), # data dict with a single list field and slice index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
|
|
@ -1075,7 +1075,7 @@ def test_merge_data(
|
|||
"test_1": np.array([1, 2]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
), # data dict with a single np.array field and slice index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
|
|
@ -1085,7 +1085,7 @@ def test_merge_data(
|
|||
"test_1": [3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
), # data dict with a single list field and negative integer index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
|
|
@ -1095,7 +1095,7 @@ def test_merge_data(
|
|||
"test_1": np.array([3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
), # data dict with a single np.array field and negative integer index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
|
|
@ -1105,7 +1105,7 @@ def test_merge_data(
|
|||
"test_1": [1, 3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
), # data dict with a single list field and integer list index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
|
|
@ -1115,7 +1115,7 @@ def test_merge_data(
|
|||
"test_1": np.array([1, 3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
), # data dict with a single np.array field and integer list index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
|
|
@ -1125,7 +1125,7 @@ def test_merge_data(
|
|||
"test_1": [1, 3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
), # data dict with a single list field and integer np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
|
|
@ -1135,7 +1135,55 @@ def test_merge_data(
|
|||
"test_1": np.array([1, 3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
), # data dict with a single np.array field and integer np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
np.array([True, True, True]),
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and all-true bool np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
np.array([False, False, False]),
|
||||
{
|
||||
"test_1": np.array([]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and all-false bool np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
np.array([False, True, False]),
|
||||
{
|
||||
"test_1": np.array([2]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and mixed bool np.array index
|
||||
(
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": ["a", "b", "c"]},
|
||||
0,
|
||||
{"test_1": np.array([1]), "test_2": ["a"]},
|
||||
DoesNotRaise(),
|
||||
), # data dict with two fields and integer index
|
||||
(
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": ["a", "b", "c"]},
|
||||
-1,
|
||||
{"test_1": np.array([3]), "test_2": ["c"]},
|
||||
DoesNotRaise(),
|
||||
), # data dict with two fields and negative integer index
|
||||
(
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": ["a", "b", "c"]},
|
||||
np.array([False, True, False]),
|
||||
{"test_1": np.array([2]), "test_2": ["b"]},
|
||||
DoesNotRaise(),
|
||||
), # data dict with two fields and mixed bool np.array index
|
||||
],
|
||||
)
|
||||
def test_get_data_item(
|
||||
|
|
|
|||
|
|
@ -0,0 +1,52 @@
|
|||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.geometry.core import Point
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
|
||||
|
||||
def generate_test_polygon(n: int) -> np.ndarray:
|
||||
"""
|
||||
Generate a semicircle with a given number of points.
|
||||
|
||||
Parameters:
|
||||
n (int): amount of points in polygon
|
||||
|
||||
Returns:
|
||||
Polygon: test polygon in the form of a semicircle.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
import numpy as np
|
||||
|
||||
test_polygon = generate_test_data(1000)
|
||||
|
||||
get_polygon_center(test_polygon)
|
||||
Point(x=500, y=1212)
|
||||
```
|
||||
"""
|
||||
r: int = n // 2
|
||||
x_axis = np.linspace(0, 2 * r, n)
|
||||
y_axis = (r**2 - (x_axis - r) ** 2) ** 0.5 + 2 * r
|
||||
polygon = np.array([x_axis, y_axis]).T
|
||||
|
||||
return polygon
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"polygon, expected_result",
|
||||
[
|
||||
(generate_test_polygon(10), Point(x=5.0, y=12.0)),
|
||||
(generate_test_polygon(50), Point(x=25.0, y=61.0)),
|
||||
(generate_test_polygon(100), Point(x=50.0, y=121.0)),
|
||||
(generate_test_polygon(1000), Point(x=500.0, y=1212.0)),
|
||||
(generate_test_polygon(3000), Point(x=1500.0, y=3637.0)),
|
||||
(generate_test_polygon(10000), Point(x=5000.0, y=12122.0)),
|
||||
(generate_test_polygon(20000), Point(x=10000.0, y=24244.0)),
|
||||
(generate_test_polygon(50000), Point(x=25000.0, y=60610.0)),
|
||||
],
|
||||
)
|
||||
def test_get_polygon_center(polygon: np.ndarray, expected_result: Point) -> None:
|
||||
result = get_polygon_center(polygon)
|
||||
assert result == expected_result
|
||||
|
|
@ -3,6 +3,7 @@ from typing import Any, Dict, List, Optional
|
|||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
|
||||
|
||||
def mock_detections(
|
||||
|
|
@ -30,5 +31,24 @@ def mock_detections(
|
|||
)
|
||||
|
||||
|
||||
def mock_keypoints(
|
||||
xy: List[List[float]],
|
||||
confidence: Optional[List[float]] = None,
|
||||
class_id: Optional[List[int]] = None,
|
||||
data: Optional[Dict[str, List[Any]]] = None,
|
||||
) -> KeyPoints:
|
||||
def convert_data(data: Dict[str, List[Any]]):
|
||||
return {k: np.array(v) for k, v in data.items()}
|
||||
|
||||
return KeyPoints(
|
||||
xy=np.array(xy, dtype=np.float32),
|
||||
confidence=(
|
||||
confidence if confidence is None else np.array(confidence, dtype=np.float32)
|
||||
),
|
||||
class_id=(class_id if class_id is None else np.array(class_id, dtype=int)),
|
||||
data=convert_data(data) if data else {},
|
||||
)
|
||||
|
||||
|
||||
def assert_almost_equal(actual, expected, tolerance=1e-5):
|
||||
assert abs(actual - expected) < tolerance, f"Expected {expected}, but got {actual}."
|
||||
|
|
|
|||

|
After Width: | Height: | Size: 67 KiB |

|
After Width: | Height: | Size: 37 KiB |

|
After Width: | Height: | Size: 46 KiB |

|
After Width: | Height: | Size: 40 KiB |

|
After Width: | Height: | Size: 45 KiB |

|
After Width: | Height: | Size: 329 KiB |

|
After Width: | Height: | Size: 328 KiB |

|
After Width: | Height: | Size: 332 KiB |

|
After Width: | Height: | Size: 334 KiB |

|
After Width: | Height: | Size: 323 KiB |

|
After Width: | Height: | Size: 266 KiB |

|
After Width: | Height: | Size: 79 KiB |

|
After Width: | Height: | Size: 85 KiB |

|
After Width: | Height: | Size: 213 KiB |

|
After Width: | Height: | Size: 141 KiB |
|
|
@ -0,0 +1,99 @@
|
|||
import os
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from _pytest.fixtures import fixture
|
||||
from PIL import Image
|
||||
|
||||
ASSETS_DIR = os.path.abspath(os.path.join(os.path.dirname(__file__), "assets"))
|
||||
ALL_IMAGES_LIST = [os.path.join(ASSETS_DIR, f"{i}.jpg") for i in range(1, 6)]
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def empty_opencv_image() -> np.ndarray:
|
||||
return np.zeros((128, 128, 3), dtype=np.uint8)
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def empty_pillow_image() -> Image.Image:
|
||||
return Image.new(mode="RGB", size=(128, 128), color=(0, 0, 0))
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def all_images() -> List[np.ndarray]:
|
||||
return [cv2.imread(path) for path in ALL_IMAGES_LIST]
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def one_image() -> np.ndarray:
|
||||
return cv2.imread(ALL_IMAGES_LIST[0])
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def two_images() -> List[np.ndarray]:
|
||||
return [cv2.imread(path) for path in ALL_IMAGES_LIST[:2]]
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def three_images() -> List[np.ndarray]:
|
||||
return [cv2.imread(path) for path in ALL_IMAGES_LIST[:3]]
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def four_images() -> List[np.ndarray]:
|
||||
return [cv2.imread(path) for path in ALL_IMAGES_LIST[:4]]
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def all_images_tile() -> np.ndarray:
|
||||
return cv2.imread(os.path.join(ASSETS_DIR, "all_images_tile.png"))
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def all_images_tile_and_custom_colors() -> np.ndarray:
|
||||
return cv2.imread(os.path.join(ASSETS_DIR, "all_images_tile_and_custom_colors.png"))
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def all_images_tile_and_custom_grid() -> np.ndarray:
|
||||
return cv2.imread(os.path.join(ASSETS_DIR, "all_images_tile_and_custom_grid.png"))
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def four_images_tile() -> np.ndarray:
|
||||
return cv2.imread(os.path.join(ASSETS_DIR, "four_images_tile.png"))
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def single_image_tile() -> np.ndarray:
|
||||
return cv2.imread(os.path.join(ASSETS_DIR, "single_image_tile.png"))
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def single_image_tile_enforced_grid() -> np.ndarray:
|
||||
return cv2.imread(os.path.join(ASSETS_DIR, "single_image_tile_enforced_grid.png"))
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def three_images_tile() -> np.ndarray:
|
||||
return cv2.imread(os.path.join(ASSETS_DIR, "three_images_tile.png"))
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def two_images_tile() -> np.ndarray:
|
||||
return cv2.imread(os.path.join(ASSETS_DIR, "two_images_tile.png"))
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def all_images_tile_and_custom_colors_and_titles() -> np.ndarray:
|
||||
return cv2.imread(
|
||||
os.path.join(ASSETS_DIR, "all_images_tile_and_custom_colors_and_titles.png")
|
||||
)
|
||||
|
||||
|
||||
@fixture(scope="function")
|
||||
def all_images_tile_and_titles_with_custom_configs() -> np.ndarray:
|
||||
return cv2.imread(
|
||||
os.path.join(ASSETS_DIR, "all_images_tile_and_titles_with_custom_configs.png")
|
||||
)
|
||||
|
|
@ -0,0 +1,173 @@
|
|||
import numpy as np
|
||||
from PIL import Image, ImageChops
|
||||
|
||||
from supervision.utils.conversion import (
|
||||
convert_for_image_processing,
|
||||
cv2_to_pillow,
|
||||
images_to_cv2,
|
||||
pillow_to_cv2,
|
||||
)
|
||||
|
||||
|
||||
def test_convert_for_image_processing_when_pillow_image_submitted(
|
||||
empty_opencv_image: np.ndarray, empty_pillow_image: Image.Image
|
||||
) -> None:
|
||||
# given
|
||||
param_a_value = 3
|
||||
param_b_value = "some"
|
||||
|
||||
@convert_for_image_processing
|
||||
def my_custom_processing_function(
|
||||
image: np.ndarray,
|
||||
param_a: int,
|
||||
param_b: str,
|
||||
) -> np.ndarray:
|
||||
assert np.allclose(
|
||||
image, empty_opencv_image
|
||||
), "Expected conversion to OpenCV image to happen"
|
||||
assert (
|
||||
param_a == param_a_value
|
||||
), f"Parameter a expected to be {param_a_value} in target function"
|
||||
assert (
|
||||
param_b == param_b_value
|
||||
), f"Parameter b expected to be {param_b_value} in target function"
|
||||
return image
|
||||
|
||||
# when
|
||||
result = my_custom_processing_function(
|
||||
empty_pillow_image,
|
||||
param_a_value,
|
||||
param_b=param_b_value,
|
||||
)
|
||||
|
||||
# then
|
||||
difference = ImageChops.difference(result, empty_pillow_image)
|
||||
assert difference.getbbox() is None, (
|
||||
"Wrapper is expected to convert-back the OpenCV image "
|
||||
"into Pillow format without changes to content"
|
||||
)
|
||||
|
||||
|
||||
def test_convert_for_image_processing_when_opencv_image_submitted(
|
||||
empty_opencv_image: np.ndarray,
|
||||
) -> None:
|
||||
# given
|
||||
param_a_value = 3
|
||||
param_b_value = "some"
|
||||
|
||||
@convert_for_image_processing
|
||||
def my_custom_processing_function(
|
||||
image: np.ndarray,
|
||||
param_a: int,
|
||||
param_b: str,
|
||||
) -> np.ndarray:
|
||||
assert np.allclose(
|
||||
image, empty_opencv_image
|
||||
), "Expected conversion to OpenCV image to happen"
|
||||
assert (
|
||||
param_a == param_a_value
|
||||
), f"Parameter a expected to be {param_a_value} in target function"
|
||||
assert (
|
||||
param_b == param_b_value
|
||||
), f"Parameter b expected to be {param_b_value} in target function"
|
||||
return image
|
||||
|
||||
# when
|
||||
result = my_custom_processing_function(
|
||||
empty_opencv_image,
|
||||
param_a_value,
|
||||
param_b=param_b_value,
|
||||
)
|
||||
|
||||
# then
|
||||
assert (
|
||||
result is empty_opencv_image
|
||||
), "Expected to return OpenCV image without changes"
|
||||
|
||||
|
||||
def test_cv2_to_pillow(
|
||||
empty_opencv_image: np.ndarray, empty_pillow_image: Image.Image
|
||||
) -> None:
|
||||
# when
|
||||
result = cv2_to_pillow(image=empty_opencv_image)
|
||||
|
||||
# then
|
||||
difference = ImageChops.difference(result, empty_pillow_image)
|
||||
assert (
|
||||
difference.getbbox() is None
|
||||
), "Conversion to PIL.Image expected not to change the content of image"
|
||||
|
||||
|
||||
def test_pillow_to_cv2(
|
||||
empty_opencv_image: np.ndarray, empty_pillow_image: Image.Image
|
||||
) -> None:
|
||||
# when
|
||||
result = pillow_to_cv2(image=empty_pillow_image)
|
||||
|
||||
# then
|
||||
assert np.allclose(
|
||||
result, empty_opencv_image
|
||||
), "Conversion to OpenCV image expected not to change the content of image"
|
||||
|
||||
|
||||
def test_images_to_cv2_when_empty_input_provided() -> None:
|
||||
# when
|
||||
result = images_to_cv2(images=[])
|
||||
|
||||
# then
|
||||
assert result == [], "Expected empty output when empty input provided"
|
||||
|
||||
|
||||
def test_images_to_cv2_when_only_cv2_images_provided(
|
||||
empty_opencv_image: np.ndarray,
|
||||
) -> None:
|
||||
# given
|
||||
images = [empty_opencv_image] * 5
|
||||
|
||||
# when
|
||||
result = images_to_cv2(images=images)
|
||||
|
||||
# then
|
||||
assert len(result) == 5, "Expected the same number of output element as input ones"
|
||||
for result_element in result:
|
||||
assert (
|
||||
result_element is empty_opencv_image
|
||||
), "Expected CV images not to be touched by conversion"
|
||||
|
||||
|
||||
def test_images_to_cv2_when_only_pillow_images_provided(
|
||||
empty_pillow_image: Image.Image,
|
||||
empty_opencv_image: np.ndarray,
|
||||
) -> None:
|
||||
# given
|
||||
images = [empty_pillow_image] * 5
|
||||
|
||||
# when
|
||||
result = images_to_cv2(images=images)
|
||||
|
||||
# then
|
||||
assert len(result) == 5, "Expected the same number of output element as input ones"
|
||||
for result_element in result:
|
||||
assert np.allclose(
|
||||
result_element, empty_opencv_image
|
||||
), "Output images expected to be equal to empty OpenCV image"
|
||||
|
||||
|
||||
def test_images_to_cv2_when_mixed_input_provided(
|
||||
empty_pillow_image: Image.Image,
|
||||
empty_opencv_image: np.ndarray,
|
||||
) -> None:
|
||||
# given
|
||||
images = [empty_pillow_image, empty_opencv_image]
|
||||
|
||||
# when
|
||||
result = images_to_cv2(images=images)
|
||||
|
||||
# then
|
||||
assert len(result) == 2, "Expected the same number of output element as input ones"
|
||||
assert np.allclose(
|
||||
result[0], empty_opencv_image
|
||||
), "PIL image should be converted to OpenCV one, equal to example empty image"
|
||||
assert (
|
||||
result[1] is empty_opencv_image
|
||||
), "Expected CV images not to be touched by conversion"
|
||||
|
|
@ -0,0 +1,244 @@
|
|||
from typing import List
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
from PIL import Image, ImageChops
|
||||
|
||||
from supervision import Color, Point
|
||||
from supervision.utils.image import create_tiles, letterbox_image, resize_image
|
||||
|
||||
|
||||
def test_resize_image_for_opencv_image() -> None:
|
||||
# given
|
||||
image = np.zeros((480, 640, 3), dtype=np.uint8)
|
||||
expected_result = np.zeros((768, 1024, 3), dtype=np.uint8)
|
||||
|
||||
# when
|
||||
result = resize_image(
|
||||
image=image,
|
||||
resolution_wh=(1024, 1024),
|
||||
keep_aspect_ratio=True,
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(
|
||||
result, expected_result
|
||||
), "Expected output shape to be (w, h): (1024, 768)"
|
||||
|
||||
|
||||
def test_resize_image_for_pillow_image() -> None:
|
||||
# given
|
||||
image = Image.new(mode="RGB", size=(640, 480), color=(0, 0, 0))
|
||||
expected_result = Image.new(mode="RGB", size=(1024, 768), color=(0, 0, 0))
|
||||
|
||||
# when
|
||||
result = resize_image(
|
||||
image=image,
|
||||
resolution_wh=(1024, 1024),
|
||||
keep_aspect_ratio=True,
|
||||
)
|
||||
|
||||
# then
|
||||
assert result.size == (1024, 768), "Expected output shape to be (w, h): (1024, 768)"
|
||||
difference = ImageChops.difference(result, expected_result)
|
||||
assert (
|
||||
difference.getbbox() is None
|
||||
), "Expected no difference in resized image content as the image is all zeros"
|
||||
|
||||
|
||||
def test_letterbox_image_for_opencv_image() -> None:
|
||||
# given
|
||||
image = np.zeros((480, 640, 3), dtype=np.uint8)
|
||||
expected_result = np.concatenate(
|
||||
[
|
||||
np.ones((128, 1024, 3), dtype=np.uint8) * 255,
|
||||
np.zeros((768, 1024, 3), dtype=np.uint8),
|
||||
np.ones((128, 1024, 3), dtype=np.uint8) * 255,
|
||||
],
|
||||
axis=0,
|
||||
)
|
||||
|
||||
# when
|
||||
result = letterbox_image(
|
||||
image=image, resolution_wh=(1024, 1024), color=(255, 255, 255)
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(result, expected_result), (
|
||||
"Expected output shape to be (w, h): "
|
||||
"(1024, 1024) with padding added top and bottom"
|
||||
)
|
||||
|
||||
|
||||
def test_letterbox_image_for_pillow_image() -> None:
|
||||
# given
|
||||
image = Image.new(mode="RGB", size=(640, 480), color=(0, 0, 0))
|
||||
expected_result = Image.fromarray(
|
||||
np.concatenate(
|
||||
[
|
||||
np.ones((128, 1024, 3), dtype=np.uint8) * 255,
|
||||
np.zeros((768, 1024, 3), dtype=np.uint8),
|
||||
np.ones((128, 1024, 3), dtype=np.uint8) * 255,
|
||||
],
|
||||
axis=0,
|
||||
)
|
||||
)
|
||||
|
||||
# when
|
||||
result = letterbox_image(
|
||||
image=image, resolution_wh=(1024, 1024), color=(255, 255, 255)
|
||||
)
|
||||
|
||||
# then
|
||||
assert result.size == (
|
||||
1024,
|
||||
1024,
|
||||
), "Expected output shape to be (w, h): (1024, 1024)"
|
||||
difference = ImageChops.difference(result, expected_result)
|
||||
assert (
|
||||
difference.getbbox() is None
|
||||
), "Expected padding to be added top and bottom with padding added top and bottom"
|
||||
|
||||
|
||||
def test_create_tiles_with_one_image(
|
||||
one_image: np.ndarray, single_image_tile: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(images=[one_image], single_tile_size=(240, 240))
|
||||
|
||||
# # then
|
||||
assert np.allclose(result, single_image_tile, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_one_image_and_enforced_grid(
|
||||
one_image: np.ndarray, single_image_tile_enforced_grid: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(
|
||||
images=[one_image],
|
||||
grid_size=(None, 3),
|
||||
single_tile_size=(240, 240),
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(result, single_image_tile_enforced_grid, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_two_images(
|
||||
two_images: List[np.ndarray], two_images_tile: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(images=two_images, single_tile_size=(240, 240))
|
||||
|
||||
# then
|
||||
assert np.allclose(result, two_images_tile, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_three_images(
|
||||
three_images: List[np.ndarray], three_images_tile: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(images=three_images, single_tile_size=(240, 240))
|
||||
|
||||
# then
|
||||
assert np.allclose(result, three_images_tile, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_four_images(
|
||||
four_images: List[np.ndarray],
|
||||
four_images_tile: np.ndarray,
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(images=four_images, single_tile_size=(240, 240))
|
||||
|
||||
# then
|
||||
assert np.allclose(result, four_images_tile, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images(
|
||||
all_images: List[np.ndarray],
|
||||
all_images_tile: np.ndarray,
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(images=all_images, single_tile_size=(240, 240))
|
||||
|
||||
# then
|
||||
assert np.allclose(result, all_images_tile, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images_and_custom_grid(
|
||||
all_images: List[np.ndarray], all_images_tile_and_custom_grid: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(
|
||||
images=all_images,
|
||||
grid_size=(3, 3),
|
||||
single_tile_size=(240, 240),
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(result, all_images_tile_and_custom_grid, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images_and_custom_colors(
|
||||
all_images: List[np.ndarray], all_images_tile_and_custom_colors: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(
|
||||
images=all_images,
|
||||
tile_margin_color=(127, 127, 127),
|
||||
tile_padding_color=(224, 224, 224),
|
||||
single_tile_size=(240, 240),
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(result, all_images_tile_and_custom_colors, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images_and_titles(
|
||||
all_images: List[np.ndarray],
|
||||
all_images_tile_and_custom_colors_and_titles: np.ndarray,
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(
|
||||
images=all_images,
|
||||
titles=["Image 1", None, "Image 3", "Image 4"],
|
||||
single_tile_size=(240, 240),
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(result, all_images_tile_and_custom_colors_and_titles, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images_and_titles_with_custom_configs(
|
||||
all_images: List[np.ndarray],
|
||||
all_images_tile_and_titles_with_custom_configs: np.ndarray,
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(
|
||||
images=all_images,
|
||||
titles=["Image 1", None, "Image 3", "Image 4"],
|
||||
single_tile_size=(240, 240),
|
||||
titles_anchors=[
|
||||
Point(x=200, y=300),
|
||||
Point(x=300, y=400),
|
||||
None,
|
||||
Point(x=300, y=400),
|
||||
],
|
||||
titles_color=Color.RED,
|
||||
titles_scale=1.5,
|
||||
titles_thickness=3,
|
||||
titles_padding=20,
|
||||
titles_background_color=Color.BLACK,
|
||||
default_title_placement="bottom",
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(result, all_images_tile_and_titles_with_custom_configs, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images_and_custom_grid_to_small_to_fit_images(
|
||||
all_images: List[np.ndarray],
|
||||
) -> None:
|
||||
with pytest.raises(ValueError):
|
||||
_ = create_tiles(images=all_images, grid_size=(2, 2))
|
||||
|
|
@ -0,0 +1,43 @@
|
|||
import pytest
|
||||
|
||||
from supervision.utils.iterables import create_batches, fill
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"sequence, batch_size, expected",
|
||||
[
|
||||
# Empty sequence, non-zero batch size. Expect empty list.
|
||||
([], 4, []),
|
||||
# Non-zero size sequence, batch size of 0. Each item is its own batch.
|
||||
([1, 2, 3], 0, [[1], [2], [3]]),
|
||||
# Batch size larger than sequence. All items in a single batch.
|
||||
([1, 2], 4, [[1, 2]]),
|
||||
# Batch size evenly divides the sequence. Equal size batches.
|
||||
([1, 2, 3, 4], 2, [[1, 2], [3, 4]]),
|
||||
# Batch size doesn't evenly divide sequence. Last batch smaller.
|
||||
([1, 2, 3, 4], 3, [[1, 2, 3], [4]]),
|
||||
],
|
||||
)
|
||||
def test_create_batches(sequence, batch_size, expected) -> None:
|
||||
result = list(create_batches(sequence=sequence, batch_size=batch_size))
|
||||
assert result == expected
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"sequence, desired_size, content, expected",
|
||||
[
|
||||
# Empty sequence, desired size 0. Expect empty list.
|
||||
([], 0, 1, []),
|
||||
# Empty sequence, non-zero desired size. Filled with padding.
|
||||
([], 3, 1, [1, 1, 1]),
|
||||
# Sequence at desired size. No changes.
|
||||
([2, 2, 2], 3, 1, [2, 2, 2]),
|
||||
# Sequence exceeds desired size. No changes.
|
||||
([2, 2, 2, 2], 3, 1, [2, 2, 2, 2]),
|
||||
# Non-empty sequence, shorter than desired. Padding added.
|
||||
([2], 3, 1, [2, 1, 1]),
|
||||
],
|
||||
)
|
||||
def test_fill(sequence, desired_size, content, expected) -> None:
|
||||
result = fill(sequence=sequence, desired_size=desired_size, content=content)
|
||||
assert result == expected
|
||||