Merge pull request #1104 from roboflow/letterbox_pr_docs_improvements
docs improvements related to #1028 PR
This commit is contained in:
 Piotr Skalski
 GitHub
commit
10843c9989
|
|
@ -15,7 +15,7 @@ source image.
|
|||
|
||||
|
||||
|
||||
## Run Inference
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model.
|
||||
|
|
|
|||
|
|
@ -0,0 +1,299 @@
|
|||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
|
||||
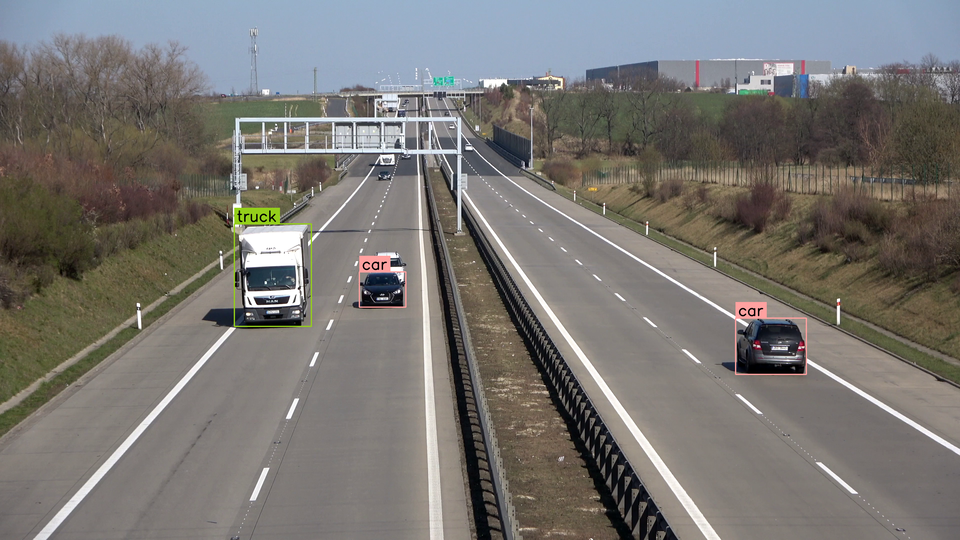
Supervision enables an easy way to save detections in .CSV and .JSON files for offline
|
||||
processing. This guide demonstrates how to perform video inference using the
|
||||
[Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages and save their results with
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. You can learn more on this topic in our
|
||||
[How to Detect and Annotate](/latest/how_to/detect_and_annotate.md) guide.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
```
|
||||
|
||||
## Save Detections as CSV
|
||||
|
||||
To save detections to a `.CSV` file, open our
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
and then pass the
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections)
|
||||
object resulting from the inference to it. Its fields are parsed and saved on disk.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car |
|
||||
|
||||
## Custom Fields
|
||||
|
||||
Besides regular fields in
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections),
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
also allows you to add custom information to each row, which can be passed via the
|
||||
`custom_data` dictionary. Let's utilize this feature to save information about the
|
||||
frame index from which the detections originate.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="10 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name | frame_index |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|-------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car | 0 |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck | 0 |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car | 0 |
|
||||
|
||||
## Save Detections as JSON
|
||||
|
||||
If you prefer to save the result in a `.JSON` file instead of a `.CSV` file, all you
|
||||
need to do is replace
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
with
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
|
@ -5,12 +5,6 @@ status: new
|
|||
|
||||
# Image Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ImageSink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>crop_image</h2>
|
||||
</div>
|
||||
|
|
@ -18,10 +12,10 @@ status: new
|
|||
:::supervision.utils.image.crop_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>letterbox_image</h2>
|
||||
<h2>scale_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.letterbox_image
|
||||
:::supervision.utils.image.scale_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>resize_image</h2>
|
||||
|
|
@ -30,7 +24,19 @@ status: new
|
|||
:::supervision.utils.image.resize_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>place_image</h2>
|
||||
<h2>letterbox_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.place_image
|
||||
:::supervision.utils.image.letterbox_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>overlay_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.overlay_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ImageSink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
|
|
|||
|
|
@ -38,9 +38,11 @@ nav:
|
|||
- Home: index.md
|
||||
- How to:
|
||||
- Detect and Annotate: how_to/detect_and_annotate.md
|
||||
- Save Detections: how_to/save_detections.md
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
- Detect Small Objects: how_to/detect_small_objects.md
|
||||
- Track Objects: how_to/track_objects.md
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
|
||||
- API:
|
||||
- Annotators: annotators.md
|
||||
- Classifications:
|
||||
|
|
|
|||
|
|
@ -71,15 +71,16 @@ from supervision.geometry.core import Point, Position, Rect
|
|||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.metrics.detection import ConfusionMatrix, MeanAveragePrecision
|
||||
from supervision.tracker.byte_tracker.core import ByteTrack
|
||||
from supervision.utils.conversion import cv2_to_pillow, pillow_to_cv2
|
||||
from supervision.utils.file import list_files_with_extensions
|
||||
from supervision.utils.image import (
|
||||
ImageSink,
|
||||
create_tiles,
|
||||
crop_image,
|
||||
letterbox_image,
|
||||
place_image,
|
||||
overlay_image,
|
||||
resize_image,
|
||||
resize_image_keeping_aspect_ratio,
|
||||
scale_image,
|
||||
)
|
||||
from supervision.utils.notebook import plot_image, plot_images_grid
|
||||
from supervision.utils.video import (
|
||||
|
|
|
|||
|
|
@ -13,7 +13,7 @@ from supervision.draw.color import Color, ColorPalette
|
|||
from supervision.draw.utils import draw_polygon
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.utils.conversion import convert_for_annotation_method
|
||||
from supervision.utils.image import crop_image, place_image, resize_image
|
||||
from supervision.utils.image import crop_image, overlay_image, scale_image
|
||||
|
||||
|
||||
class BoundingBoxAnnotator(BaseAnnotator):
|
||||
|
|
@ -1965,7 +1965,7 @@ class CropAnnotator(BaseAnnotator):
|
|||
crop_image(image=scene, xyxy=xyxy) for xyxy in detections.xyxy.astype(int)
|
||||
]
|
||||
resized_crops = [
|
||||
resize_image(image=crop, scale_factor=self.scale_factor) for crop in crops
|
||||
scale_image(image=crop, scale_factor=self.scale_factor) for crop in crops
|
||||
]
|
||||
anchors = detections.get_anchors_coordinates(anchor=self.position).astype(int)
|
||||
|
||||
|
|
@ -1974,7 +1974,9 @@ class CropAnnotator(BaseAnnotator):
|
|||
(x1, y1), (x2, y2) = self.calculate_crop_coordinates(
|
||||
anchor=anchor, crop_wh=crop_wh, position=self.position
|
||||
)
|
||||
scene = place_image(scene=scene, image=resized_crop, anchor=(x1, y1))
|
||||
scene = overlay_image(
|
||||
scene=scene, inserted_image=resized_crop, anchor=(x1, y1)
|
||||
)
|
||||
color = resolve_color(
|
||||
color=self.border_color,
|
||||
detections=detections,
|
||||
|
|
|
|||
|
|
@ -1,7 +1,7 @@
|
|||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import List, Tuple
|
||||
from typing import List, Tuple, Union
|
||||
|
||||
import matplotlib.pyplot as plt
|
||||
|
||||
|
|
@ -448,3 +448,19 @@ class ColorPalette:
|
|||
raise ValueError("idx argument should not be negative")
|
||||
idx = idx % len(self.colors)
|
||||
return self.colors[idx]
|
||||
|
||||
|
||||
def unify_to_bgr(color: Union[Tuple[int, int, int], Color]) -> Tuple[int, int, int]:
|
||||
"""
|
||||
Converts a color input in multiple formats to a standardized BGR format.
|
||||
|
||||
Args:
|
||||
color (Union[Tuple[int, int, int], Color]): The color input to be converted,
|
||||
which can be either a tuple of RGB values or an instance of a Color class.
|
||||
|
||||
Returns:
|
||||
Tuple[int, int, int]: The color in BGR format as a tuple of three integers.
|
||||
"""
|
||||
if issubclass(type(color), Color):
|
||||
return color.as_bgr()
|
||||
return color
|
||||
|
|
|
|||
|
|
@ -81,7 +81,7 @@ def pillow_to_cv2(image: Image.Image) -> np.ndarray:
|
|||
image (Image.Image): Pillow image (in RGB format).
|
||||
|
||||
Returns:
|
||||
np.ndarray: Input image converted to OpenCV format.
|
||||
(np.ndarray): Input image converted to OpenCV format.
|
||||
"""
|
||||
scene = np.array(image)
|
||||
scene = cv2.cvtColor(scene, cv2.COLOR_RGB2BGR)
|
||||
|
|
@ -97,7 +97,7 @@ def cv2_to_pillow(image: np.ndarray) -> Image.Image:
|
|||
image (np.ndarray): OpenCV image (in BGR format).
|
||||
|
||||
Returns:
|
||||
Image.Image: Input image converted to Pillow format.
|
||||
(Image.Image): Input image converted to Pillow format.
|
||||
"""
|
||||
image = cv2.cvtColor(image, cv2.COLOR_BGR2RGB)
|
||||
return Image.fromarray(image)
|
||||
|
|
|
|||
|
|
@ -7,9 +7,10 @@ from typing import Callable, List, Literal, Optional, Tuple, Union
|
|||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.color import Color, unify_to_bgr
|
||||
from supervision.draw.utils import calculate_optimal_text_scale, draw_text
|
||||
from supervision.geometry.core import Point
|
||||
from supervision.utils.conversion import (
|
||||
|
|
@ -25,103 +26,326 @@ MAX_COLUMNS_FOR_SINGLE_ROW_GRID = 3
|
|||
|
||||
|
||||
@convert_for_image_processing
|
||||
def crop_image(image: np.ndarray, xyxy: np.ndarray) -> np.ndarray:
|
||||
def crop_image(
|
||||
image: ImageType,
|
||||
xyxy: Union[npt.NDArray[int], List[int], Tuple[int, int, int, int]],
|
||||
) -> ImageType:
|
||||
"""
|
||||
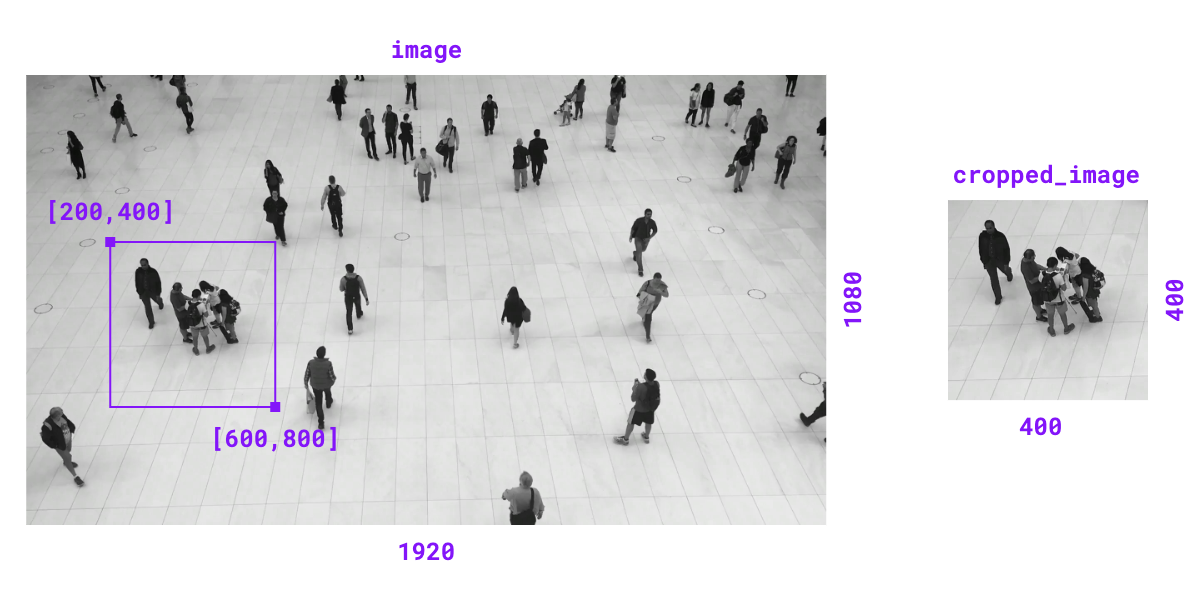
Crops the given image based on the given bounding box.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The image to be cropped, represented as a numpy array.
|
||||
xyxy (np.ndarray): A numpy array containing the bounding box coordinates
|
||||
in the format (x1, y1, x2, y2).
|
||||
image (ImageType): The image to be cropped. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
xyxy (Union[np.ndarray, List[int], Tuple[int, int, int, int]]): A bounding box
|
||||
coordinates in the format `(x_min, y_min, x_max, y_max)`, accepted as either
|
||||
a `numpy.ndarray`, a `list`, or a `tuple`.
|
||||
|
||||
Returns:
|
||||
(np.ndarray): The cropped image as a numpy array.
|
||||
(ImageType): The cropped image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
detection = sv.Detections(...)
|
||||
with sv.ImageSink(target_dir_path='target/directory/path') as sink:
|
||||
for xyxy in detection.xyxy:
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
sink.save_image(image=cropped_image)
|
||||
```
|
||||
"""
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
xyxy = [200, 400, 600, 800]
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
cropped_image.shape
|
||||
# (400, 400, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
xyxy = [200, 400, 600, 800]
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
cropped_image.size
|
||||
# (400, 400)
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
|
||||
if isinstance(xyxy, (list, tuple)):
|
||||
xyxy = np.array(xyxy)
|
||||
xyxy = np.round(xyxy).astype(int)
|
||||
x1, y1, x2, y2 = xyxy
|
||||
return image[y1:y2, x1:x2]
|
||||
x_min, y_min, x_max, y_max = xyxy.flatten()
|
||||
return image[y_min:y_max, x_min:x_max]
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def resize_image(image: np.ndarray, scale_factor: float) -> np.ndarray:
|
||||
def scale_image(image: ImageType, scale_factor: float) -> ImageType:
|
||||
"""
|
||||
Resizes an image by a given scale factor using cv2.INTER_LINEAR interpolation.
|
||||
Scales the given image based on the given scale factor.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The input image to be resized.
|
||||
image (ImageType): The image to be scaled. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
scale_factor (float): The factor by which the image will be scaled. Scale
|
||||
factor > 1.0 zooms in, < 1.0 zooms out.
|
||||
factor > `1.0` zooms in, < `1.0` zooms out.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The resized image.
|
||||
(ImageType): The scaled image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
Raises:
|
||||
ValueError: If the scale factor is non-positive.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
scaled_image = sv.scale_image(image=image, scale_factor=0.5)
|
||||
scaled_image.shape
|
||||
# (540, 960, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
scaled_image = sv.scale_image(image=image, scale_factor=0.5)
|
||||
scaled_image.size
|
||||
# (960, 540)
|
||||
```
|
||||
"""
|
||||
if scale_factor <= 0:
|
||||
raise ValueError("Scale factor must be positive.")
|
||||
|
||||
old_width, old_height = image.shape[1], image.shape[0]
|
||||
nwe_width = int(old_width * scale_factor)
|
||||
new_height = int(old_height * scale_factor)
|
||||
|
||||
return cv2.resize(image, (nwe_width, new_height), interpolation=cv2.INTER_LINEAR)
|
||||
width_old, height_old = image.shape[1], image.shape[0]
|
||||
width_new = int(width_old * scale_factor)
|
||||
height_new = int(height_old * scale_factor)
|
||||
return cv2.resize(image, (width_new, height_new), interpolation=cv2.INTER_LINEAR)
|
||||
|
||||
|
||||
def place_image(
|
||||
scene: np.ndarray, image: np.ndarray, anchor: Tuple[int, int]
|
||||
) -> np.ndarray:
|
||||
@convert_for_image_processing
|
||||
def resize_image(
|
||||
image: ImageType,
|
||||
resolution_wh: Tuple[int, int],
|
||||
keep_aspect_ratio: bool = False,
|
||||
) -> ImageType:
|
||||
"""
|
||||
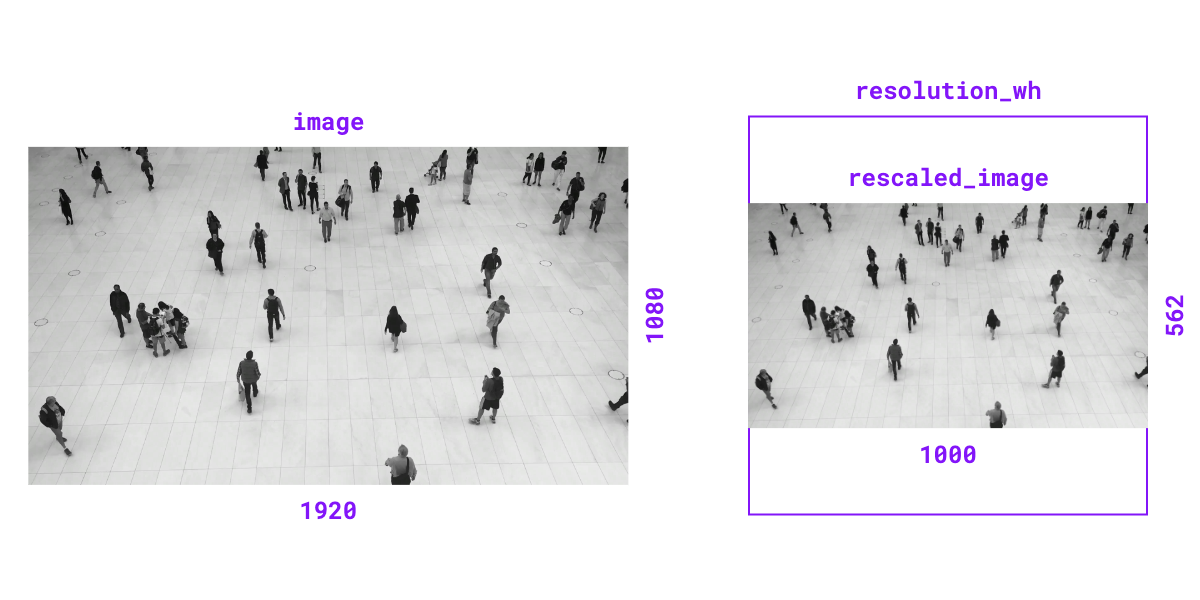
Resizes the given image to a specified resolution. Can maintain the original aspect
|
||||
ratio or resize directly to the desired dimensions.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be resized. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
resolution_wh (Tuple[int, int]): The target resolution as
|
||||
`(width, height)`.
|
||||
keep_aspect_ratio (bool, optional): Flag to maintain the image's original
|
||||
aspect ratio. Defaults to `False`.
|
||||
|
||||
Returns:
|
||||
(ImageType): The resized image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
resized_image = sv.resize_image(
|
||||
image=image, resolution_wh=(1000, 1000), keep_aspect_ratio=True
|
||||
)
|
||||
resized_image.shape
|
||||
# (562, 1000, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
resized_image = sv.resize_image(
|
||||
image=image, resolution_wh=(1000, 1000), keep_aspect_ratio=True
|
||||
)
|
||||
resized_image.size
|
||||
# (1000, 562)
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
if keep_aspect_ratio:
|
||||
image_ratio = image.shape[1] / image.shape[0]
|
||||
target_ratio = resolution_wh[0] / resolution_wh[1]
|
||||
if image_ratio >= target_ratio:
|
||||
width_new = resolution_wh[0]
|
||||
height_new = int(resolution_wh[0] / image_ratio)
|
||||
else:
|
||||
height_new = resolution_wh[1]
|
||||
width_new = int(resolution_wh[1] * image_ratio)
|
||||
else:
|
||||
width_new, height_new = resolution_wh
|
||||
|
||||
return cv2.resize(image, (width_new, height_new), interpolation=cv2.INTER_LINEAR)
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def letterbox_image(
|
||||
image: ImageType,
|
||||
resolution_wh: Tuple[int, int],
|
||||
color: Union[Tuple[int, int, int], Color] = Color.BLACK,
|
||||
) -> ImageType:
|
||||
"""
|
||||
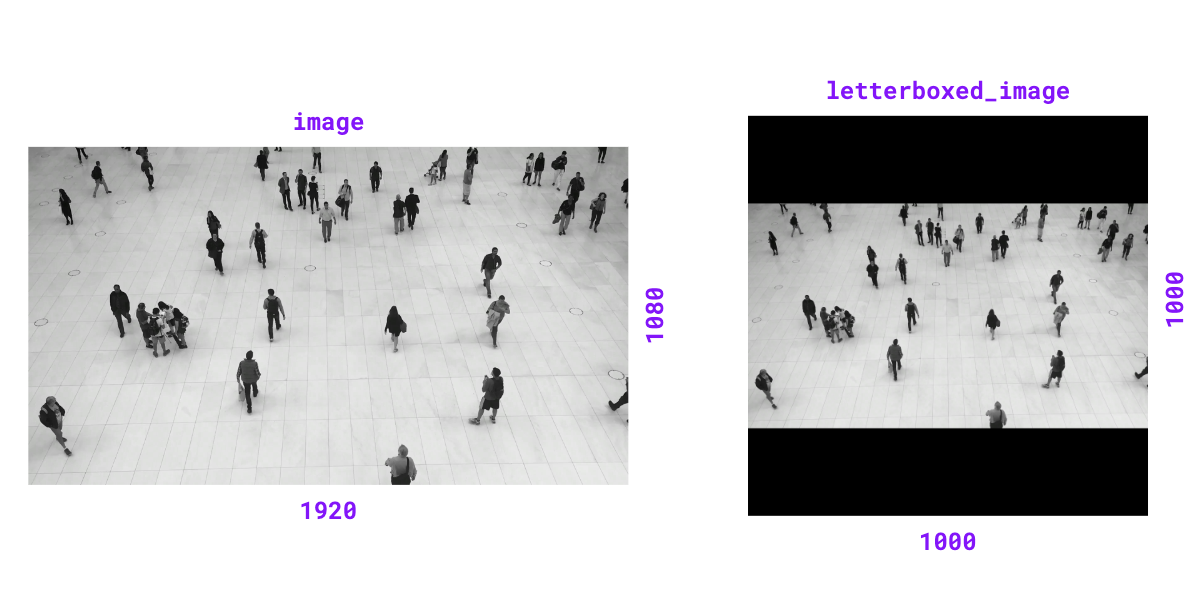
Resizes and pads an image to a specified resolution with a given color, maintaining
|
||||
the original aspect ratio.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be resized. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
resolution_wh (Tuple[int, int]): The target resolution as
|
||||
`(width, height)`.
|
||||
color (Union[Tuple[int, int, int], Color]): The color to pad with. If tuple
|
||||
provided it should be in BGR format.
|
||||
|
||||
Returns:
|
||||
(ImageType): The resized image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
letterboxed_image = sv.letterbox_image(image=image, resolution_wh=(1000, 1000))
|
||||
letterboxed_image.shape
|
||||
# (1000, 1000, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
letterboxed_image = sv.letterbox_image(image=image, resolution_wh=(1000, 1000))
|
||||
letterboxed_image.size
|
||||
# (1000, 1000)
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
color = unify_to_bgr(color=color)
|
||||
resized_image = resize_image(
|
||||
image=image, resolution_wh=resolution_wh, keep_aspect_ratio=True
|
||||
)
|
||||
height_new, width_new = resized_image.shape[:2]
|
||||
padding_top = (resolution_wh[1] - height_new) // 2
|
||||
padding_bottom = resolution_wh[1] - height_new - padding_top
|
||||
padding_left = (resolution_wh[0] - width_new) // 2
|
||||
padding_right = resolution_wh[0] - width_new - padding_left
|
||||
return cv2.copyMakeBorder(
|
||||
resized_image,
|
||||
padding_top,
|
||||
padding_bottom,
|
||||
padding_left,
|
||||
padding_right,
|
||||
cv2.BORDER_CONSTANT,
|
||||
value=color,
|
||||
)
|
||||
|
||||
|
||||
def overlay_image(
|
||||
image: npt.NDArray[np.uint8],
|
||||
overlay: npt.NDArray[np.uint8],
|
||||
anchor: Tuple[int, int],
|
||||
) -> npt.NDArray[np.uint8]:
|
||||
"""
|
||||
Places an image onto a scene at a given anchor point, handling cases where
|
||||
the image's position is partially or completely outside the scene's bounds.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The background scene onto which the image is placed.
|
||||
image (np.ndarray): The image to be placed onto the scene.
|
||||
anchor (Tuple[int, int]): The (x, y) coordinates in the scene where the
|
||||
image (np.ndarray): The background scene onto which the image is placed.
|
||||
overlay (np.ndarray): The image to be placed onto the scene.
|
||||
anchor (Tuple[int, int]): The `(x, y)` coordinates in the scene where the
|
||||
top-left corner of the image will be placed.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The modified scene with the image placed at the anchor point,
|
||||
or unchanged if the image placement is completely outside the scene.
|
||||
"""
|
||||
scene_height, scene_width = scene.shape[:2]
|
||||
image_height, image_width = image.shape[:2]
|
||||
(np.ndarray): The result image with overlay.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
overlay = np.zeros((400, 400, 3), dtype=np.uint8)
|
||||
result_image = sv.overlay_image(image=image, overlay=overlay, anchor=(200, 400))
|
||||
```
|
||||
|
||||
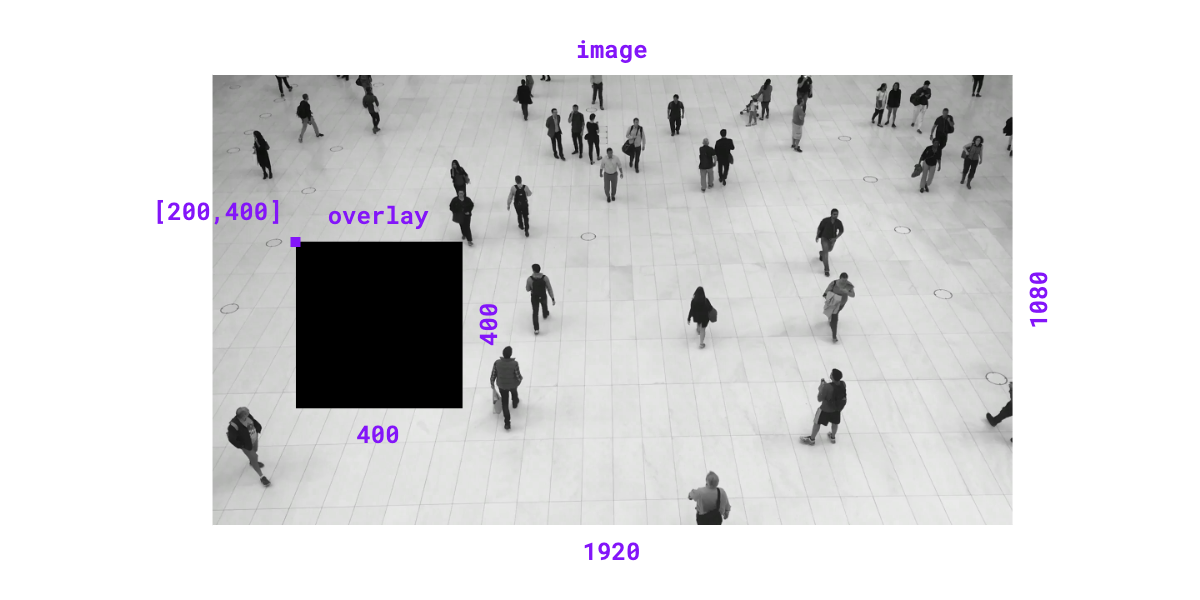{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
scene_height, scene_width = image.shape[:2]
|
||||
image_height, image_width = overlay.shape[:2]
|
||||
anchor_x, anchor_y = anchor
|
||||
|
||||
is_out_horizontally = anchor_x + image_width <= 0 or anchor_x >= scene_width
|
||||
is_out_vertically = anchor_y + image_height <= 0 or anchor_y >= scene_height
|
||||
|
||||
if is_out_horizontally or is_out_vertically:
|
||||
return scene
|
||||
return image
|
||||
|
||||
start_y = max(anchor_y, 0)
|
||||
start_x = max(anchor_x, 0)
|
||||
end_y = min(scene_height, anchor_y + image_height)
|
||||
end_x = min(scene_width, anchor_x + image_width)
|
||||
x_min = max(anchor_x, 0)
|
||||
y_min = max(anchor_y, 0)
|
||||
x_max = min(scene_width, anchor_x + image_width)
|
||||
y_max = min(scene_height, anchor_y + image_height)
|
||||
|
||||
crop_start_y = max(-anchor_y, 0)
|
||||
crop_start_x = max(-anchor_x, 0)
|
||||
crop_end_y = image_height - max((anchor_y + image_height) - scene_height, 0)
|
||||
crop_end_x = image_width - max((anchor_x + image_width) - scene_width, 0)
|
||||
crop_x_min = max(-anchor_x, 0)
|
||||
crop_y_min = max(-anchor_y, 0)
|
||||
crop_x_max = image_width - max((anchor_x + image_width) - scene_width, 0)
|
||||
crop_y_max = image_height - max((anchor_y + image_height) - scene_height, 0)
|
||||
|
||||
scene[start_y:end_y, start_x:end_x] = image[
|
||||
crop_start_y:crop_end_y, crop_start_x:crop_end_x
|
||||
image[y_min:y_max, x_min:x_max] = overlay[
|
||||
crop_y_min:crop_y_max, crop_x_min:crop_x_max
|
||||
]
|
||||
|
||||
return scene
|
||||
return image
|
||||
|
||||
|
||||
class ImageSink:
|
||||
|
|
@ -145,13 +369,13 @@ class ImageSink:
|
|||
```python
|
||||
import supervision as sv
|
||||
|
||||
with sv.ImageSink(target_dir_path='target/directory/path',
|
||||
overwrite=True) as sink:
|
||||
for image in sv.get_video_frames_generator(
|
||||
source_path='source_video.mp4', stride=2):
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>, stride=2)
|
||||
|
||||
with sv.ImageSink(target_dir_path=<TARGET_CROPS_DIRECTORY>) as sink:
|
||||
for image in frames_generator:
|
||||
sink.save_image(image=image)
|
||||
```
|
||||
"""
|
||||
""" # noqa E501 // docs
|
||||
|
||||
self.target_dir_path = target_dir_path
|
||||
self.overwrite = overwrite
|
||||
|
|
@ -285,14 +509,14 @@ def create_tiles(
|
|||
raise ValueError("Could not create image tiles from empty list of images.")
|
||||
if return_type == "auto":
|
||||
return_type = _negotiate_tiles_format(images=images)
|
||||
tile_padding_color = _color_to_bgr(color=tile_padding_color)
|
||||
tile_margin_color = _color_to_bgr(color=tile_margin_color)
|
||||
tile_padding_color = unify_to_bgr(color=tile_padding_color)
|
||||
tile_margin_color = unify_to_bgr(color=tile_margin_color)
|
||||
images = images_to_cv2(images=images)
|
||||
if single_tile_size is None:
|
||||
single_tile_size = _aggregate_images_shape(images=images, mode=tile_scaling)
|
||||
resized_images = [
|
||||
letterbox_image(
|
||||
image=i, desired_size=single_tile_size, color=tile_padding_color
|
||||
image=i, resolution_wh=single_tile_size, color=tile_padding_color
|
||||
)
|
||||
for i in images
|
||||
]
|
||||
|
|
@ -311,8 +535,8 @@ def create_tiles(
|
|||
titles_anchors = fill(
|
||||
sequence=titles_anchors, desired_size=len(images), content=None
|
||||
)
|
||||
titles_color = _color_to_bgr(color=titles_color)
|
||||
titles_background_color = _color_to_bgr(color=titles_background_color)
|
||||
titles_color = unify_to_bgr(color=titles_color)
|
||||
titles_background_color = unify_to_bgr(color=titles_background_color)
|
||||
tiles = _generate_tiles(
|
||||
images=resized_images,
|
||||
grid_size=grid_size,
|
||||
|
|
@ -542,92 +766,3 @@ def _generate_color_image(
|
|||
shape: Tuple[int, int], color: Tuple[int, int, int]
|
||||
) -> np.ndarray:
|
||||
return np.ones(shape[::-1] + (3,), dtype=np.uint8) * color
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def letterbox_image(
|
||||
image: np.ndarray,
|
||||
desired_size: Tuple[int, int],
|
||||
color: Union[Tuple[int, int, int], Color] = (0, 0, 0),
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Resize and pad image to fit the desired size, preserving its aspect
|
||||
ratio, adding padding of given color if needed to maintain aspect ratio.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): Input image (type will be adjusted by decorator,
|
||||
you can provide PIL.Image)
|
||||
desired_size (Tuple[int, int]): image size (width, height) representing
|
||||
the target dimensions.
|
||||
color (Union[Tuple[int, int, int], Color]): the color to pad with - If
|
||||
tuple provided - should be BGR.
|
||||
|
||||
Returns:
|
||||
np.ndarray: letterboxed image (type may be adjusted to PIL.Image by
|
||||
decorator if function was called with PIL.Image)
|
||||
"""
|
||||
color = _color_to_bgr(color=color)
|
||||
resized_img = resize_image_keeping_aspect_ratio(
|
||||
image=image,
|
||||
desired_size=desired_size,
|
||||
)
|
||||
new_height, new_width = resized_img.shape[:2]
|
||||
top_padding = (desired_size[1] - new_height) // 2
|
||||
bottom_padding = desired_size[1] - new_height - top_padding
|
||||
left_padding = (desired_size[0] - new_width) // 2
|
||||
right_padding = desired_size[0] - new_width - left_padding
|
||||
return cv2.copyMakeBorder(
|
||||
resized_img,
|
||||
top_padding,
|
||||
bottom_padding,
|
||||
left_padding,
|
||||
right_padding,
|
||||
cv2.BORDER_CONSTANT,
|
||||
value=color,
|
||||
)
|
||||
|
||||
|
||||
@convert_for_image_processing
|
||||
def resize_image_keeping_aspect_ratio(
|
||||
image: np.ndarray,
|
||||
desired_size: Tuple[int, int],
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Resize and pad image preserving its aspect ratio.
|
||||
|
||||
For example: input image is (640, 480) and we want to resize into
|
||||
(1024, 1024). If this rectangular image is just resized naively
|
||||
to square-shape output - aspect ratio would be altered. If we do not
|
||||
want this to happen - we may resize bigger dimension (640) to 1024.
|
||||
Ratio of change is 1.6. This ratio is later on used to calculate scaling
|
||||
in the other dimension. As a result we have (1024, 768) image.
|
||||
|
||||
Parameters:
|
||||
- image (np.ndarray): Input image (type will be adjusted by decorator,
|
||||
you can provide PIL.Image)
|
||||
- desired_size (Tuple[int, int]): image size (width, height) representing the
|
||||
target dimensions. Parameter will be used to dictate maximum size of
|
||||
output image. Output size may be smaller - to preserve aspect ratio of original
|
||||
image.
|
||||
|
||||
Returns:
|
||||
np.ndarray: resized image (type may be adjusted to PIL.Image by decorator
|
||||
if function was called with PIL.Image)
|
||||
"""
|
||||
if image.shape[:2] == desired_size[::-1]:
|
||||
return image
|
||||
img_ratio = image.shape[1] / image.shape[0]
|
||||
desired_ratio = desired_size[0] / desired_size[1]
|
||||
if img_ratio >= desired_ratio:
|
||||
new_width = desired_size[0]
|
||||
new_height = int(desired_size[0] / img_ratio)
|
||||
else:
|
||||
new_height = desired_size[1]
|
||||
new_width = int(desired_size[1] * img_ratio)
|
||||
return cv2.resize(image, (new_width, new_height))
|
||||
|
||||
|
||||
def _color_to_bgr(color: Union[Tuple[int, int, int], Color]) -> Tuple[int, int, int]:
|
||||
if issubclass(type(color), Color):
|
||||
return color.as_bgr()
|
||||
return color
|
||||
|
|
|
|||
|
|
@ -16,7 +16,7 @@ def create_batches(
|
|||
batch_size (int): The expected size of a batch.
|
||||
|
||||
Returns:
|
||||
Generator[List[V], None, None]: A generator that yields chunks
|
||||
(Generator[List[V], None, None]): A generator that yields chunks
|
||||
of `sequence` of size `batch_size`, up to the length of
|
||||
the input `sequence`.
|
||||
|
||||
|
|
@ -54,7 +54,7 @@ def fill(sequence: List[V], desired_size: int, content: V) -> List[V]:
|
|||
`sequence` as padding.
|
||||
|
||||
Returns:
|
||||
List[V]: A padded version of the input `sequence` (if needed).
|
||||
(List[V]): A padded version of the input `sequence` (if needed).
|
||||
|
||||
Examples:
|
||||
```python
|
||||
|
|
|
|||
|
|
@ -5,22 +5,19 @@ import pytest
|
|||
from PIL import Image, ImageChops
|
||||
|
||||
from supervision import Color, Point
|
||||
from supervision.utils.image import (
|
||||
create_tiles,
|
||||
letterbox_image,
|
||||
resize_image_keeping_aspect_ratio,
|
||||
)
|
||||
from supervision.utils.image import create_tiles, letterbox_image, resize_image
|
||||
|
||||
|
||||
def test_resize_image_keeping_aspect_ratio_for_opencv_image() -> None:
|
||||
def test_resize_image_for_opencv_image() -> None:
|
||||
# given
|
||||
image = np.zeros((480, 640, 3), dtype=np.uint8)
|
||||
expected_result = np.zeros((768, 1024, 3), dtype=np.uint8)
|
||||
|
||||
# when
|
||||
result = resize_image_keeping_aspect_ratio(
|
||||
result = resize_image(
|
||||
image=image,
|
||||
desired_size=(1024, 1024),
|
||||
resolution_wh=(1024, 1024),
|
||||
keep_aspect_ratio=True,
|
||||
)
|
||||
|
||||
# then
|
||||
|
|
@ -29,15 +26,16 @@ def test_resize_image_keeping_aspect_ratio_for_opencv_image() -> None:
|
|||
), "Expected output shape to be (w, h): (1024, 768)"
|
||||
|
||||
|
||||
def test_resize_image_keeping_aspect_ratio_for_pillow_image() -> None:
|
||||
def test_resize_image_for_pillow_image() -> None:
|
||||
# given
|
||||
image = Image.new(mode="RGB", size=(640, 480), color=(0, 0, 0))
|
||||
expected_result = Image.new(mode="RGB", size=(1024, 768), color=(0, 0, 0))
|
||||
|
||||
# when
|
||||
result = resize_image_keeping_aspect_ratio(
|
||||
result = resize_image(
|
||||
image=image,
|
||||
desired_size=(1024, 1024),
|
||||
resolution_wh=(1024, 1024),
|
||||
keep_aspect_ratio=True,
|
||||
)
|
||||
|
||||
# then
|
||||
|
|
@ -62,7 +60,7 @@ def test_letterbox_image_for_opencv_image() -> None:
|
|||
|
||||
# when
|
||||
result = letterbox_image(
|
||||
image=image, desired_size=(1024, 1024), color=(255, 255, 255)
|
||||
image=image, resolution_wh=(1024, 1024), color=(255, 255, 255)
|
||||
)
|
||||
|
||||
# then
|
||||
|
|
@ -88,7 +86,7 @@ def test_letterbox_image_for_pillow_image() -> None:
|
|||
|
||||
# when
|
||||
result = letterbox_image(
|
||||
image=image, desired_size=(1024, 1024), color=(255, 255, 255)
|
||||
image=image, resolution_wh=(1024, 1024), color=(255, 255, 255)
|
||||
)
|
||||
|
||||
# then
|
||||
|
|
|
|||
Loading…
Reference in New Issue