Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 SkalskiP |
bcbd25988d | ||
|
SkalskiP
|
24e995933e | ||
|
Onuralp SEZER
|
e9ba3ca918 | ||
|
Onuralp SEZER
|
4c16af5544 | ||
|
Onuralp SEZER
|
893dbe0579 | ||
|
dependabot[bot]
|
e53c804217 | ||
|
dependabot[bot]
|
6dcd947110 | ||
|
dependabot[bot]
|
13fc3f76f8 | ||
|
Onuralp SEZER
|
e1ef7aa849 | ||
|
Onuralp SEZER
|
77f17a3fde | ||
|
dependabot[bot]
|
030189e45f | ||
|
Piotr Skalski
|
850614739b | ||
|
pre-commit-ci[bot]
|
de10b25dc4 | ||
|
SkalskiP
|
7cde087ca6 | ||
|
SkalskiP
|
8348f5911e | ||
|
SkalskiP
|
be57c8872d | ||
|
pre-commit-ci[bot]
|
c963a2e85a | ||
|
SkalskiP
|
bdaee3f1fc | ||
|
pre-commit-ci[bot]
|
c9be7527d6 | ||
|
SkalskiP
|
7023bb9bf4 | ||
|
pre-commit-ci[bot]
|
a5c0949cd6 | ||
|
SkalskiP
|
9862f40ab4 | ||
|
SkalskiP
|
1ad9ee1e6a | ||
|
pre-commit-ci[bot]
|
5b174ea7ec | ||
|
SkalskiP
|
b5f9cdf90e | ||
|
SkalskiP
|
0acd408f29 | ||
|
pre-commit-ci[bot]
|
26829070f3 | ||
|
SkalskiP
|
9c1f06046d | ||
|
SkalskiP
|
ace32eecb6 | ||
|
pre-commit-ci[bot]
|
53803c77ca | ||
|
Piotr Skalski
|
f86cd5114d | ||
|
Piotr Skalski
|
8a32a9ccb1 | ||
|
SkalskiP
|
2e491a85c9 | ||
|
Piotr Skalski
|
9e34cbb31c | ||
|
SkalskiP
|
11cd92e4f3 | ||
|
Piotr Skalski
|
1b386a45d5 | ||
|
pre-commit-ci[bot]
|
80d1df7509 | ||
|
SkalskiP
|
f4d2f2a900 | ||
|
SkalskiP
|
0d10704370 | ||
|
dependabot[bot]
|
1001448f5c | ||
|
pre-commit-ci[bot]
|
d35f1888f9 | ||
|
SkalskiP
|
706ff0fd46 | ||
|
Piotr Skalski
|
8528a8a738 | ||
|
SkalskiP
|
e3d92a01c4 | ||
|
SkalskiP
|
0f6396669b | ||
|
SkalskiP
|
8e40fa8664 | ||
|
SkalskiP
|
a10b9840af | ||
|
pre-commit-ci[bot]
|
51694819e3 | ||
|
SkalskiP
|
ced9f35b6e | ||
|
Onuralp SEZER
|
b300c59f78 | ||
|
dependabot[bot]
|
d3cbad4aa1 | ||
|
pre-commit-ci[bot]
|
e75e527925 | ||
|
SkalskiP
|
5984d3374c | ||
|
SkalskiP
|
099d36011d | ||
|
dependabot[bot]
|
50f3de3483 | ||
|
pre-commit-ci[bot]
|
ea21a75135 | ||
|
SkalskiP
|
955220f25f | ||
|
SkalskiP
|
95e2ad6d52 | ||
|
pre-commit-ci[bot]
|
db245bbc34 | ||
|
SkalskiP
|
9be71da888 | ||
|
SkalskiP
|
c2412379c4 | ||
|
pre-commit-ci[bot]
|
63ccc98d0b | ||
|
SkalskiP
|
14761cb20a | ||
|
SkalskiP
|
5dfc2e61e7 | ||
|
SkalskiP
|
701b0c0b97 | ||
|
pre-commit-ci[bot]
|
27eb823809 | ||
|
SkalskiP
|
efed23f64e | ||
|
Piotr Skalski
|
456ec9a847 | ||
|
Onuralp SEZER
|
004bc7e0b3 | ||
|
Onuralp SEZER
|
a2dbe9e53a | ||
|
Onuralp SEZER
|
fcd6866337 | ||
|
Onuralp SEZER
|
7425303382 | ||
|
pre-commit-ci[bot]
|
b2d98fe457 | ||
|
SkalskiP
|
ea6439b8fd | ||
|
pre-commit-ci[bot]
|
f2031d53d6 | ||
|
SkalskiP
|
f3f545d893 | ||
|
Piotr Skalski
|
d0c2b145a8 | ||
|
pre-commit-ci[bot]
|
db8bdc1965 | ||
|
Paul
|
f942d89881 | ||
|
Onuralp SEZER
|
404adc30dd | ||
|
dependabot[bot]
|
9ba46fd067 | ||
|
Onuralp SEZER
|
054602b4dc | ||
|
dependabot[bot]
|
354895585e | ||
|
pre-commit-ci[bot]
|
587a69f00e | ||
|
James Gallagher
|
1981de1c80 | ||
|
James
|
0faf14229c | ||
|
Onuralp SEZER
|
8bcfefb672 | ||
|
pre-commit-ci[bot]
|
d32b490afe | ||
|
Onuralp SEZER
|
263d88bf77 | ||
|
Onuralp SEZER
|
c18f9bf625 | ||
|
pre-commit-ci[bot]
|
670e9c5afc | ||
|
Rafael Levy
|
e320db492c | ||
|
Paul
|
2c833108cc | ||
|
Paul
|
678156c1f1 | ||
|
pre-commit-ci[bot]
|
e2bb2be9b2 | ||
|
Paul
|
362e9f7b43 | ||
|
Onuralp SEZER
|
62066c92a8 | ||
|
Onuralp SEZER
|
c64bc1cfa0 | ||
|
Onuralp SEZER
|
4b728334e7 | ||
|
Paul
|
973d26c180 | ||
|
Paul
|
38cb7d7249 | ||
|
pre-commit-ci[bot]
|
109ff2db6c | ||
|
Paul
|
af5861557b | ||
|
Paul Guerrie
|
2f0b10a36d | ||
|
dependabot[bot]
|
5a28378d3c | ||
|
dependabot[bot]
|
c210362389 | ||
|
Piotr Skalski
|
5b7e0bac5a | ||
|
Piotr Skalski
|
2180719183 | ||
|
pre-commit-ci[bot]
|
d71cb82a87 | ||
|
SkalskiP
|
770d7893c6 | ||
|
Piotr Skalski
|
6ec5c24d7e | ||
|
pre-commit-ci[bot]
|
e8df6e6795 | ||
|
SkalskiP
|
a967d78021 | ||
|
SkalskiP
|
b678d44182 | ||
|
pre-commit-ci[bot]
|
697704354a | ||
|
SkalskiP
|
5f7ad5f4d3 | ||
|
pre-commit-ci[bot]
|
f7a3a408fa | ||
|
SkalskiP
|
852eec4c6a | ||
|
dependabot[bot]
|
0b7a376ace | ||
|
Piotr Skalski
|
78a63501bf | ||
|
Piotr Skalski
|
0d424a1e0b | ||
|
Onuralp SEZER
|
72f2c986de | ||
|
Onuralp SEZER
|
5f11ef4df6 | ||
|
Onuralp SEZER
|
64b395ea60 | ||
|
Onuralp SEZER
|
bf338eea4a | ||
|
Onuralp SEZER
|
87985b2fe2 | ||
|
Onuralp SEZER
|
f50976992c | ||
|
Piotr Skalski
|
d68cd95d43 | ||
|
Piotr Skalski
|
bcf7e7b1f7 | ||
|
Onuralp SEZER
|
16c382e0cc | ||
|
Onuralp SEZER
|
63616b95f7 | ||
|
Piotr Skalski
|
634ab4ff0b | ||
|
James Gallagher
|
c43b699113 | ||
|
Onuralp SEZER
|
dbf5b67657 | ||
|
pre-commit-ci[bot]
|
ed54a57575 | ||
|
Onuralp SEZER
|
769c97fa49 | ||
|
Onuralp SEZER
|
daf4046fd2 | ||
|
SkalskiP
|
18fa772dbb | ||
|
Piotr Skalski
|
41711fe076 | ||
|
SkalskiP
|
e0c7c1fbf0 | ||
|
Piotr Skalski
|
bcb26f9edd | ||
|
SkalskiP
|
ee697cad3e | ||
|
Piotr Skalski
|
a53e39d097 | ||
|
SkalskiP
|
08f7838f1f | ||
|
SkalskiP
|
4388f03a51 | ||
|
Piotr Skalski
|
f2334936e6 | ||
|
Onuralp SEZER
|
6d3c7f7e1d | ||
|
Onuralp SEZER
|
180fdf2168 | ||
|
Onuralp SEZER
|
4079188368 | ||
|
Onuralp SEZER
|
e42770eedb | ||
|
Onuralp SEZER
|
2f6195ad5d | ||
|
SkalskiP
|
29a2bb726b | ||
|
Piotr Skalski
|
cec537cb89 | ||
|
pre-commit-ci[bot]
|
0ab35b1d88 | ||
|
James Gallagher
|
32bf235b39 | ||
|
dependabot[bot]
|
ef292fe2a8 | ||
|
Piotr Skalski
|
36ab9dcb8e | ||
|
SkalskiP
|
01d6c5386a | ||
|
SkalskiP
|
7a1863835b | ||
|
Piotr Skalski
|
fb66e57103 | ||
|
SkalskiP
|
b87e07a06b | ||
|
Piotr Skalski
|
ba79dba26e | ||
|
SkalskiP
|
721935144b | ||
|
SkalskiP
|
26ad007b7c | ||
|
pre-commit-ci[bot]
|
c46ff15143 | ||
|
SkalskiP
|
f73829e941 | ||
|
pre-commit-ci[bot]
|
bf5d8ac29c | ||
|
SkalskiP
|
84713239ee | ||
|
pre-commit-ci[bot]
|
8d9228f7fd | ||
|
SkalskiP
|
4400ae05eb | ||
|
SkalskiP
|
366d39db48 | ||
|
pre-commit-ci[bot]
|
a618b7c369 | ||
|
SkalskiP
|
f94a8cb9a1 | ||
|
Piotr Skalski
|
186727243f | ||
|
pre-commit-ci[bot]
|
7ea8e75a78 | ||
|
SkalskiP
|
27979cf756 | ||
|
Piotr Skalski
|
a8c1431392 | ||
|
SkalskiP
|
58c8620a6f | ||
|
pre-commit-ci[bot]
|
9468f00997 | ||
|
SkalskiP
|
55f5f6a97a | ||
|
pre-commit-ci[bot]
|
a530b2ba5e | ||
|
SkalskiP
|
7cbf16be8a | ||
|
Piotr Skalski
|
a112292ed0 | ||
|
Onuralp SEZER
|
a64f3ff178 | ||
|
Piotr Skalski
|
07fc5609da | ||
|
SkalskiP
|
39117f19c4 | ||
|
SkalskiP
|
cb5e9c0df0 | ||
|
pre-commit-ci[bot]
|
38b87d6098 | ||
|
SkalskiP
|
a31f964947 | ||
|
dependabot[bot]
|
38297f85a5 | ||
|
Onuralp SEZER
|
5cf91676f6 | ||
|
Onuralp SEZER
|
c3c934f8c1 | ||
|
SkalskiP
|
f46326b7e4 | ||
|
Piotr Skalski
|
679fee9f16 | ||
|
SkalskiP
|
4774ace3c2 | ||
|
Piotr Skalski
|
2e7ecdd418 | ||
|
Onuralp SEZER
|
918970e7d6 | ||
|
SkalskiP
|
87979384ed | ||
|
Piotr Skalski
|
83603e3677 | ||
|
pre-commit-ci[bot]
|
566a9296d0 | ||
|
SkalskiP
|
9612fe7849 | ||
|
James Gallagher
|
7f2b62a5ce | ||
|
James Gallagher
|
9c10308abc | ||
|
James Gallagher
|
d53181bb97 | ||
|
pre-commit-ci[bot]
|
9d836faa8a | ||
|
James Gallagher
|
c46e0f5c97 | ||
|
dependabot[bot]
|
c322cf8001 | ||
|
Piotr Skalski
|
b69eea47a9 | ||
|
Piotr Skalski
|
fe9b422185 | ||
|
Piotr Skalski
|
d6fd1b0644 | ||
|
James Gallagher
|
1ef1622126 | ||
|
James Gallagher
|
e45e1e277b | ||
|
Piotr Skalski
|
b1ac5bc876 | ||
|
Onuralp SEZER
|
178d91eaa0 | ||
|
Onuralp SEZER
|
726ad1dbb1 | ||
|
SkalskiP
|
e08e4ee389 | ||
|
SkalskiP
|
23a58ef99e | ||
|
SkalskiP
|
bd4208ce84 | ||
|
Piotr Skalski
|
dd16f917d5 | ||
|
Piotr Skalski
|
31d60734bf | ||
|
Piotr Skalski
|
4483970638 | ||
|
James Gallagher
|
1710021ece | ||
|
Piotr Skalski
|
144df44ccc | ||
|
James Gallagher
|
92761752a0 | ||
|
James Gallagher
|
b047e061e7 | ||
|
pre-commit-ci[bot]
|
72497f3f85 | ||
|
SkalskiP
|
478c3adfe2 | ||
|
SkalskiP
|
81d0876838 | ||
|
Piotr Skalski
|
66720c58fd | ||
|
pre-commit-ci[bot]
|
b16e479a14 | ||
|
SkalskiP
|
9f5773aa70 | ||
|
SkalskiP
|
d2d590834e | ||
|
pre-commit-ci[bot]
|
f046940bb5 | ||
|
James Gallagher
|
e7e542d160 | ||
|
James Gallagher
|
dd19c4e185 | ||
|
James Gallagher
|
dfb703219e | ||
|
James Gallagher
|
ec8f10d6a8 | ||
|
capjamesg
|
242ac0cd06 | ||
|
pre-commit-ci[bot]
|
8946d44dcb | ||
|
capjamesg
|
718f1b077d | ||
|
Onuralp SEZER
|
93eb48c2a0 | ||
|
dependabot[bot]
|
f6265ebbda | ||
|
Piotr Skalski
|
b94e2796bd | ||
|
dependabot[bot]
|
e77d06d817 | ||
|
Piotr Skalski
|
b63457e5fa | ||
|
SkalskiP
|
575a7a301d | ||
|
James Gallagher
|
fa8f31931c | ||
|
James Gallagher
|
b4b332a0e2 | ||
|
SkalskiP
|
02502baab3 | ||
|
SkalskiP
|
2aebe13583 | ||
|
James Gallagher
|
6ed04252d6 | ||
|
pre-commit-ci[bot]
|
491209d7bd | ||
|
James Gallagher
|
444f8d01c1 | ||
|
James Gallagher
|
f91fad5600 | ||
|
Piotr Skalski
|
1589d8fd43 | ||
|
SkalskiP
|
1d66840cad | ||
|
SkalskiP
|
05602cd2a0 | ||
|
James
|
fc9acc456b | ||
|
James Gallagher
|
b6c85a3f4b | ||
|
James Gallagher
|
ce92069ba6 | ||
|
Piotr Skalski
|
2dcf2cc2ae | ||
|
kim-jeonghyun
|
619ec018bc | ||
|
SkalskiP
|
5333eb2684 | ||
|
Piotr Skalski
|
d5d70052bb | ||
|
pre-commit-ci[bot]
|
242ac5f7db | ||
|
SkalskiP
|
e6f0ae8514 | ||
|
Onuralp SEZER
|
10c44b0143 | ||
|
Onuralp SEZER
|
2a3f592090 | ||
|
pre-commit-ci[bot]
|
7941527a75 | ||
|
Piotr Skalski
|
42661a0563 | ||
|
SkalskiP
|
32077eb11d | ||
|
karanjakhar
|
d20083de85 | ||
|
dependabot[bot]
|
564f1b1026 | ||
|
Piotr Skalski
|
145313ab8f | ||
|
xenteros
|
1267cf7fb0 | ||
|
xenteros
|
c2101db5d2 | ||
|
Piotr Skalski
|
fe4657f0d0 | ||
|
SkalskiP
|
6c756c411b | ||
|
SkalskiP
|
0725d5a1a9 | ||
|
SkalskiP
|
fa3b43f20a | ||
|
SkalskiP
|
5e091396f2 | ||
|
pre-commit-ci[bot]
|
66448ea862 | ||
|
SkalskiP
|
b33d68da00 | ||
|
SkalskiP
|
6956dad17d | ||
|
pre-commit-ci[bot]
|
b92ffeff82 | ||
|
SkalskiP
|
7750856c18 | ||
|
pre-commit-ci[bot]
|
72ab46687f | ||
|
SkalskiP
|
50e561a4fb | ||
|
Piotr Skalski
|
bb7695a774 | ||
|
Onuralp SEZER
|
95006dca14 | ||
|
Onuralp SEZER
|
b3dec1a734 | ||
|
Piotr Skalski
|
5456c666c7 | ||
|
SkalskiP
|
2ed4e16ab5 | ||
|
SkalskiP
|
c1beb0f5fd | ||
|
pre-commit-ci[bot]
|
777e8d3e5b | ||
|
SkalskiP
|
e40532cf3e | ||
|
Onuralp SEZER
|
550e86bc6d | ||
|
Onuralp SEZER
|
6af17b235f | ||
|
Onuralp SEZER
|
de867bb166 | ||
|
Onuralp SEZER
|
ca84d3129c | ||
|
Onuralp SEZER
|
9c9bc77e12 | ||
|
Onuralp SEZER
|
b9573605c7 | ||
|
pre-commit-ci[bot]
|
8025b468a2 | ||
|
SkalskiP
|
d3fb4ad932 | ||
|
pre-commit-ci[bot]
|
fcfb57612f | ||
|
SkalskiP
|
c28aa5aebd | ||
|
Piotr Skalski
|
109d048a38 | ||
|
dependabot[bot]
|
6ad1f701dd | ||
|
dependabot[bot]
|
7f081f4314 | ||
|
pre-commit-ci[bot]
|
dd39360221 | ||
|
dependabot[bot]
|
7de7281e0e | ||
|
Onuralp SEZER
|
e8f0ceab71 | ||
|
Onuralp SEZER
|
94a95110ce | ||
|
pre-commit-ci[bot]
|
08a48a4f5d | ||
|
SkalskiP
|
95f4b5c0b8 | ||
|
pre-commit-ci[bot]
|
6211139201 | ||
|
SkalskiP
|
e416ef4c0e | ||
|
pre-commit-ci[bot]
|
1dce43747f | ||
|
Cody Chen
|
f9ead5543b | ||
|
Onuralp SEZER
|
5d19e246a4 | ||
|
Onuralp SEZER
|
052a9d33bb | ||
|
dependabot[bot]
|
ed41153c19 | ||
|
dependabot[bot]
|
b89487d8e8 | ||
|
Onuralp SEZER
|
c8f557af0c | ||
|
pre-commit-ci[bot]
|
7946f54b95 | ||
|
Onuralp SEZER
|
eeae6dafc0 | ||
|
Onuralp SEZER
|
d07e6a3ed2 | ||
|
dependabot[bot]
|
06945856a3 | ||
|
dependabot[bot]
|
899d88676b | ||
|
James Gallagher
|
1fd248f1ff | ||
|
James Gallagher
|
417656f176 | ||
|
James Gallagher
|
2335b61d1e | ||
|
James Gallagher
|
d7e8a11139 | ||
|
James Gallagher
|
82ed322fba | ||
|
James Gallagher
|
c438b16e74 | ||
|
James Gallagher
|
3490c3e670 | ||
|
Onuralp SEZER
|
583ad5f6e2 | ||
|
Piotr Skalski
|
26eac2cdc7 | ||
|
Onuralp SEZER
|
9a0f35fcf9 | ||
|
Onuralp SEZER
|
7a7b50eb12 | ||
|
Onuralp SEZER
|
ad458cf705 | ||
|
Onuralp SEZER
|
9f3d688bab | ||
|
Onuralp SEZER
|
190bfbf0d0 | ||
|
dependabot[bot]
|
f9b8709568 | ||
|
dependabot[bot]
|
8d1e091a3b | ||
|
Piotr Skalski
|
92592c8edc | ||
|
pre-commit-ci[bot]
|
e6a5c514f8 | ||
|
SkalskiP
|
ce7e3a1de4 | ||
|
Piotr Skalski
|
4cb19e6618 | ||
|
Piotr Skalski
|
6e039d7ebd | ||
|
Piotr Skalski
|
c100c8019a | ||
|
Onuralp SEZER
|
e3e30e305a | ||
|
dependabot[bot]
|
4a5d850f28 | ||
|
Onuralp SEZER
|
092771d9a1 | ||
|
Onuralp SEZER
|
321dc054df | ||
|
dependabot[bot]
|
ec9aae686b | ||
|
Onuralp SEZER
|
7c2e9842e8 | ||
|
Onuralp SEZER
|
4d3820ba73 | ||
|
fdloopes
|
8b88f1f415 | ||
|
Onuralp SEZER
|
37951b3617 | ||
|
dependabot[bot]
|
98fa8339c8 | ||
|
pre-commit-ci[bot]
|
030359cb44 | ||
|
pre-commit-ci[bot]
|
9f265b4833 | ||
|
James Gallagher
|
c036aa9bd6 | ||
|
fdloopes
|
7f69f6a168 | ||
|
Piotr Skalski
|
d76dd771d7 | ||
|
pre-commit-ci[bot]
|
21fe102bbd | ||
|
SkalskiP
|
769f97cd7d | ||
|
Onuralp SEZER
|
2de3e171f3 | ||
|
Onuralp SEZER
|
6a4bfcf094 | ||
|
dependabot[bot]
|
82e35479e7 | ||
|
dependabot[bot]
|
3356defe95 | ||
|
dependabot[bot]
|
c04129f2b8 | ||
|
dependabot[bot]
|
22b4444e9e | ||
|
Piotr Skalski
|
5de77cee7d | ||
|
Onuralp SEZER
|
f36b39b543 | ||
|
dependabot[bot]
|
8e91c62103 | ||
|
Onuralp SEZER
|
ab0612917b | ||
|
Onuralp SEZER
|
4f31cf9f46 | ||
|
Onuralp SEZER
|
d563d5db03 | ||
|
Onuralp SEZER
|
f309b43c68 | ||
|
dependabot[bot]
|
b17003855c | ||
|
dependabot[bot]
|
45a1905812 | ||
|
dependabot[bot]
|
cbcd0be74c | ||
|
dependabot[bot]
|
bda80934cc | ||
|
Hugo Dutra
|
b77bab39de | ||
|
Onuralp SEZER
|
599a9b8a5b | ||
|
Piotr Skalski
|
b9dbbbc0ec | ||
|
pre-commit-ci[bot]
|
337abe1e71 | ||
|
SkalskiP
|
9ece846f8e | ||
|
dependabot[bot]
|
c23d00566b | ||
|
SkalskiP
|
6837ef1d36 | ||
|
Onuralp SEZER
|
26990513ba | ||
|
Onuralp SEZER
|
bdf527809d | ||
|
dependabot[bot]
|
23a71e6f51 | ||
|
dependabot[bot]
|
e61f1718a0 | ||
|
Onuralp SEZER
|
bb79eebdae | ||
|
Onuralp SEZER
|
cdb74c1b19 | ||
|
dependabot[bot]
|
b1ceb1debf | ||
|
Onuralp SEZER
|
9fe343942f | ||
|
Onuralp SEZER
|
b08d40cad4 | ||
|
dependabot[bot]
|
46a50e9595 | ||
|
dependabot[bot]
|
7001721872 | ||
|
dependabot[bot]
|
8c2d18d752 | ||
|
Piotr Skalski
|
fc8e2e2889 | ||
|
Onuralp SEZER
|
14dfb32f44 | ||
|
Piotr Skalski
|
8aee70872f | ||
|
SkalskiP
|
671c8b3683 | ||
|
SkalskiP
|
edaef0b165 | ||
|
SkalskiP
|
28fb656bca | ||
|
SkalskiP
|
e9866c2f25 | ||
|
SkalskiP
|
e59d1bc9f3 | ||
|
SkalskiP
|
b6001e389e | ||
|
SkalskiP
|
c529402068 | ||
|
SkalskiP
|
9d68ee6a1e | ||
|
SkalskiP
|
999c12162a | ||
|
pre-commit-ci[bot]
|
7d3082c93b | ||
|
SkalskiP
|
4cb7400c75 | ||
|
SkalskiP
|
3f5f5fb070 | ||
|
pre-commit-ci[bot]
|
8689c294bf | ||
|
SkalskiP
|
3391eec078 | ||
|
SkalskiP
|
6887b0b412 | ||
|
SkalskiP
|
a36abd4297 | ||
|
SkalskiP
|
7715ef2a17 | ||
|
SkalskiP
|
9b3dc37e28 | ||
|
SkalskiP
|
24aefe6bcd | ||
|
pre-commit-ci[bot]
|
52452c019c | ||
|
SkalskiP
|
dca6d1248f | ||
|
SkalskiP
|
03fd015f39 | ||
|
pre-commit-ci[bot]
|
7faddb52ca | ||
|
SkalskiP
|
f987e4f786 | ||
|
Onuralp SEZER
|
a00a752d44 | ||
|
pre-commit-ci[bot]
|
8bf721559f | ||
|
abhishek7kalra
|
9f901bb61e | ||
|
Abhishek Kalra
|
ece7164ce6 | ||
|
Piotr Skalski
|
de45e9d67f | ||
|
Onuralp SEZER
|
b815c0e7fc | ||
|
Piotr Skalski
|
c158f96b75 | ||
|
Abhishek Kalra
|
e927a3c0a5 | ||
|
Abhishek Kalra
|
b1f85969a5 | ||
|
Onuralp SEZER
|
f3b92163ad | ||
|
Rajarshi Misra
|
e71232f6ff | ||
|
pre-commit-ci[bot]
|
9e5d30732d | ||
|
capjamesg
|
9c2aaa0d2e | ||
|
Onuralp SEZER
|
2ab5941cbc | ||
|
Rajarshi Misra
|
3dbbcf79ae | ||
|
pre-commit-ci[bot]
|
47dcb19829 | ||
|
Rajarshi Misra
|
9c96180a74 | ||
|
Rajarshi Misra
|
cd76b79ec5 | ||
|
pre-commit-ci[bot]
|
377b3fdda7 | ||
|
Rajarshi Misra
|
9572469f5f | ||
|
Rajarshi Misra
|
da7c056812 | ||
|
Rajarshi Misra
|
b1f207f2ee | ||
|
Rajarshi Misra
|
f82f297f2e | ||
|
Rajarshi Misra
|
9a2a87a170 |
@@ -0,0 +1,16 @@
|
||||
version: 2
|
||||
updates:
|
||||
# GitHub Actions
|
||||
- package-ecosystem: "github-actions"
|
||||
directory: "/"
|
||||
schedule:
|
||||
interval: "daily"
|
||||
commit-message:
|
||||
prefix: ⬆️
|
||||
# Python
|
||||
- package-ecosystem: "pip"
|
||||
directory: "/"
|
||||
schedule:
|
||||
interval: "daily"
|
||||
commit-message:
|
||||
prefix: ⬆️
|
||||
@@ -0,0 +1,28 @@
|
||||
attrs==23.1.0
|
||||
certifi==2023.7.22
|
||||
charset-normalizer==2.0.12
|
||||
cycler==0.12.1
|
||||
exceptiongroup==1.1.3
|
||||
fonttools==4.43.1
|
||||
idna==3.4
|
||||
iniconfig==2.0.0
|
||||
kiwisolver==1.4.5
|
||||
matplotlib==3.5.0
|
||||
numpy==1.21.2
|
||||
opencv-python==4.5.5.64
|
||||
packaging==23.2
|
||||
Pillow==10.1.0
|
||||
pluggy==1.3.0
|
||||
pyparsing==3.1.1
|
||||
pytest==7.2.0
|
||||
python-dateutil==2.8.2
|
||||
PyYAML==5.3
|
||||
requests==2.26.0
|
||||
scipy==1.9.0
|
||||
setuptools-scm==8.0.4
|
||||
six==1.16.0
|
||||
tomli==2.0.1
|
||||
tqdm==4.62.3
|
||||
typing_extensions==4.8.0
|
||||
urllib3==1.26.18
|
||||
defusedxml == 0.7.1
|
||||
@@ -1,17 +0,0 @@
|
||||
contourpy==1.1.0 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
cycler==0.11.0 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
fonttools==4.41.1 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
importlib-resources==6.0.0 ; python_version >= "3.8" and python_version < "3.10"
|
||||
kiwisolver==1.4.4 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
matplotlib==3.7.2 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
numpy==1.24.4 ; python_version >= "3.8" and python_version < "3.12"
|
||||
opencv-python-headless==4.8.0.74 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
packaging==23.1 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
pillow==10.0.1 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
pyparsing==3.0.9 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
python-dateutil==2.8.2 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
pyyaml==6.0.1 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
scipy==1.10.1 ; python_version >= "3.8" and python_version < "3.12"
|
||||
six==1.16.0 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
zipp==3.16.2 ; python_version >= "3.8" and python_version < "3.10"
|
||||
pytest==7.4.0 ; python_version >= "3.8" and python_full_version < "3.12.0"
|
||||
@@ -14,7 +14,7 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Clear cache
|
||||
uses: actions/github-script@v6
|
||||
uses: actions/github-script@v7
|
||||
with:
|
||||
script: |
|
||||
console.log("About to clear")
|
||||
|
||||
@@ -6,14 +6,21 @@ on:
|
||||
- master
|
||||
- main
|
||||
- develop
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
pull-requests: write
|
||||
|
||||
jobs:
|
||||
deploy:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/setup-python@v4
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: 3.x
|
||||
- run: pip install mkdocs-material
|
||||
- run: pip install "mkdocstrings[python]"
|
||||
- run: pip install "mkdocs-material[imaging]"
|
||||
- run: mkdocs gh-deploy --force
|
||||
|
||||
@@ -16,10 +16,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout source
|
||||
uses: actions/checkout@v3
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: 🐍 Set up Python 3.8 environment for build
|
||||
uses: actions/setup-python@v4
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: "3.8"
|
||||
|
||||
|
||||
@@ -17,11 +17,11 @@ jobs:
|
||||
python-version: [3.8]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v3
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
ref: ${{ github.head_ref }}
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v4
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
|
||||
|
||||
@@ -0,0 +1,32 @@
|
||||
name: Python 3.8 - Min Dep Test WorkFlow
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main, develop]
|
||||
|
||||
jobs:
|
||||
build-min-dep-test:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.8"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v5
|
||||
# id based on python version
|
||||
id: python-setup
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
check-latest: true
|
||||
cache: 'pip'
|
||||
cache-dependency-path: '**/requirements-dev-min.txt'
|
||||
|
||||
- name: 📦 Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install -r .github/requirements-dev-min.txt
|
||||
|
||||
- name: 🧪 Test
|
||||
run: "python -m pytest ./test"
|
||||
@@ -5,28 +5,25 @@ on:
|
||||
branches: [main, develop]
|
||||
|
||||
jobs:
|
||||
build:
|
||||
build-dev-test:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.8", "3.9", "3.10","3.11"]
|
||||
python-version: ["3.8", "3.9", "3.10", "3.11", "3.12"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v3
|
||||
uses: actions/checkout@v4
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v4
|
||||
# id based on python version
|
||||
id: python-setup
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
check-latest: true
|
||||
cache: 'pip'
|
||||
cache-dependency-path: '**/requirements-dev.txt'
|
||||
|
||||
- name: 📦 Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install -r .github/requirements-dev.txt
|
||||
pip install .
|
||||
pip install pytest
|
||||
|
||||
- name: 🧪 Test
|
||||
run: "python -m pytest ./test"
|
||||
|
||||
@@ -11,7 +11,7 @@ jobs:
|
||||
name: 👋 Welcome
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/first-interaction@v1.1.1
|
||||
- uses: actions/first-interaction@v1.3.0
|
||||
with:
|
||||
repo-token: ${{ secrets.GITHUB_TOKEN }}
|
||||
issue-message: "Hello there, thank you for opening an Issue ! 🙏🏻 The team was notified and they will get back to you asap."
|
||||
|
||||
+6
-28
@@ -11,14 +11,13 @@ repos:
|
||||
hooks:
|
||||
- id: end-of-file-fixer
|
||||
- id: trailing-whitespace
|
||||
exclude: test/.*\.py
|
||||
- id: check-yaml
|
||||
- id: check-docstring-first
|
||||
- id: check-executables-have-shebangs
|
||||
- id: check-toml
|
||||
- id: check-case-conflict
|
||||
- id: check-added-large-files
|
||||
args: ['--maxkb=2048']
|
||||
exclude: ^logo/
|
||||
- id: detect-private-key
|
||||
- id: forbid-new-submodules
|
||||
- id: pretty-format-json
|
||||
@@ -27,50 +26,29 @@ repos:
|
||||
- id: end-of-file-fixer
|
||||
- id: mixed-line-ending
|
||||
|
||||
# - repo: https://github.com/asottile/pyupgrade
|
||||
# rev: v3.9.0
|
||||
# hooks:
|
||||
# - id: pyupgrade
|
||||
# name: Upgrade code
|
||||
# args: [--py38-plus]
|
||||
|
||||
|
||||
- repo: https://github.com/PyCQA/flake8
|
||||
rev: 6.1.0
|
||||
hooks:
|
||||
- id: flake8
|
||||
name: Flake8 Checks
|
||||
entry: flake8
|
||||
additional_dependencies: [Flake8-pyproject]
|
||||
|
||||
|
||||
- repo: https://github.com/PyCQA/bandit
|
||||
rev: '1.7.5'
|
||||
rev: '1.7.6'
|
||||
hooks:
|
||||
- id: bandit
|
||||
args: ["-c", "pyproject.toml"]
|
||||
additional_dependencies: ["bandit[toml]"]
|
||||
|
||||
- repo: https://github.com/pycqa/isort
|
||||
rev: 5.12.0
|
||||
rev: 5.13.2
|
||||
hooks:
|
||||
- id: isort
|
||||
name: isort (python)
|
||||
- id: isort
|
||||
name: isort (cython)
|
||||
types: [cython]
|
||||
- id: isort
|
||||
name: isort (pyi)
|
||||
types: [pyi]
|
||||
|
||||
|
||||
- repo: https://github.com/psf/black
|
||||
rev: 23.9.1
|
||||
hooks:
|
||||
- id: black
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.0.292
|
||||
rev: v0.1.9
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
- id: ruff-format
|
||||
types_or: [ python, pyi, jupyter ]
|
||||
|
||||
+1
-2
@@ -76,7 +76,6 @@ All new functions and classes in `supervision` should include docstrings. This i
|
||||
|
||||
So far, **there is no type checking with mypy**. See [issue](https://github.com/roboflow-ai/template-python/issues/4).
|
||||
|
||||
|
||||
Then, go back to your fork of the `supervision` repository, click "Pull Requests", and click "New Pull Request".
|
||||
|
||||
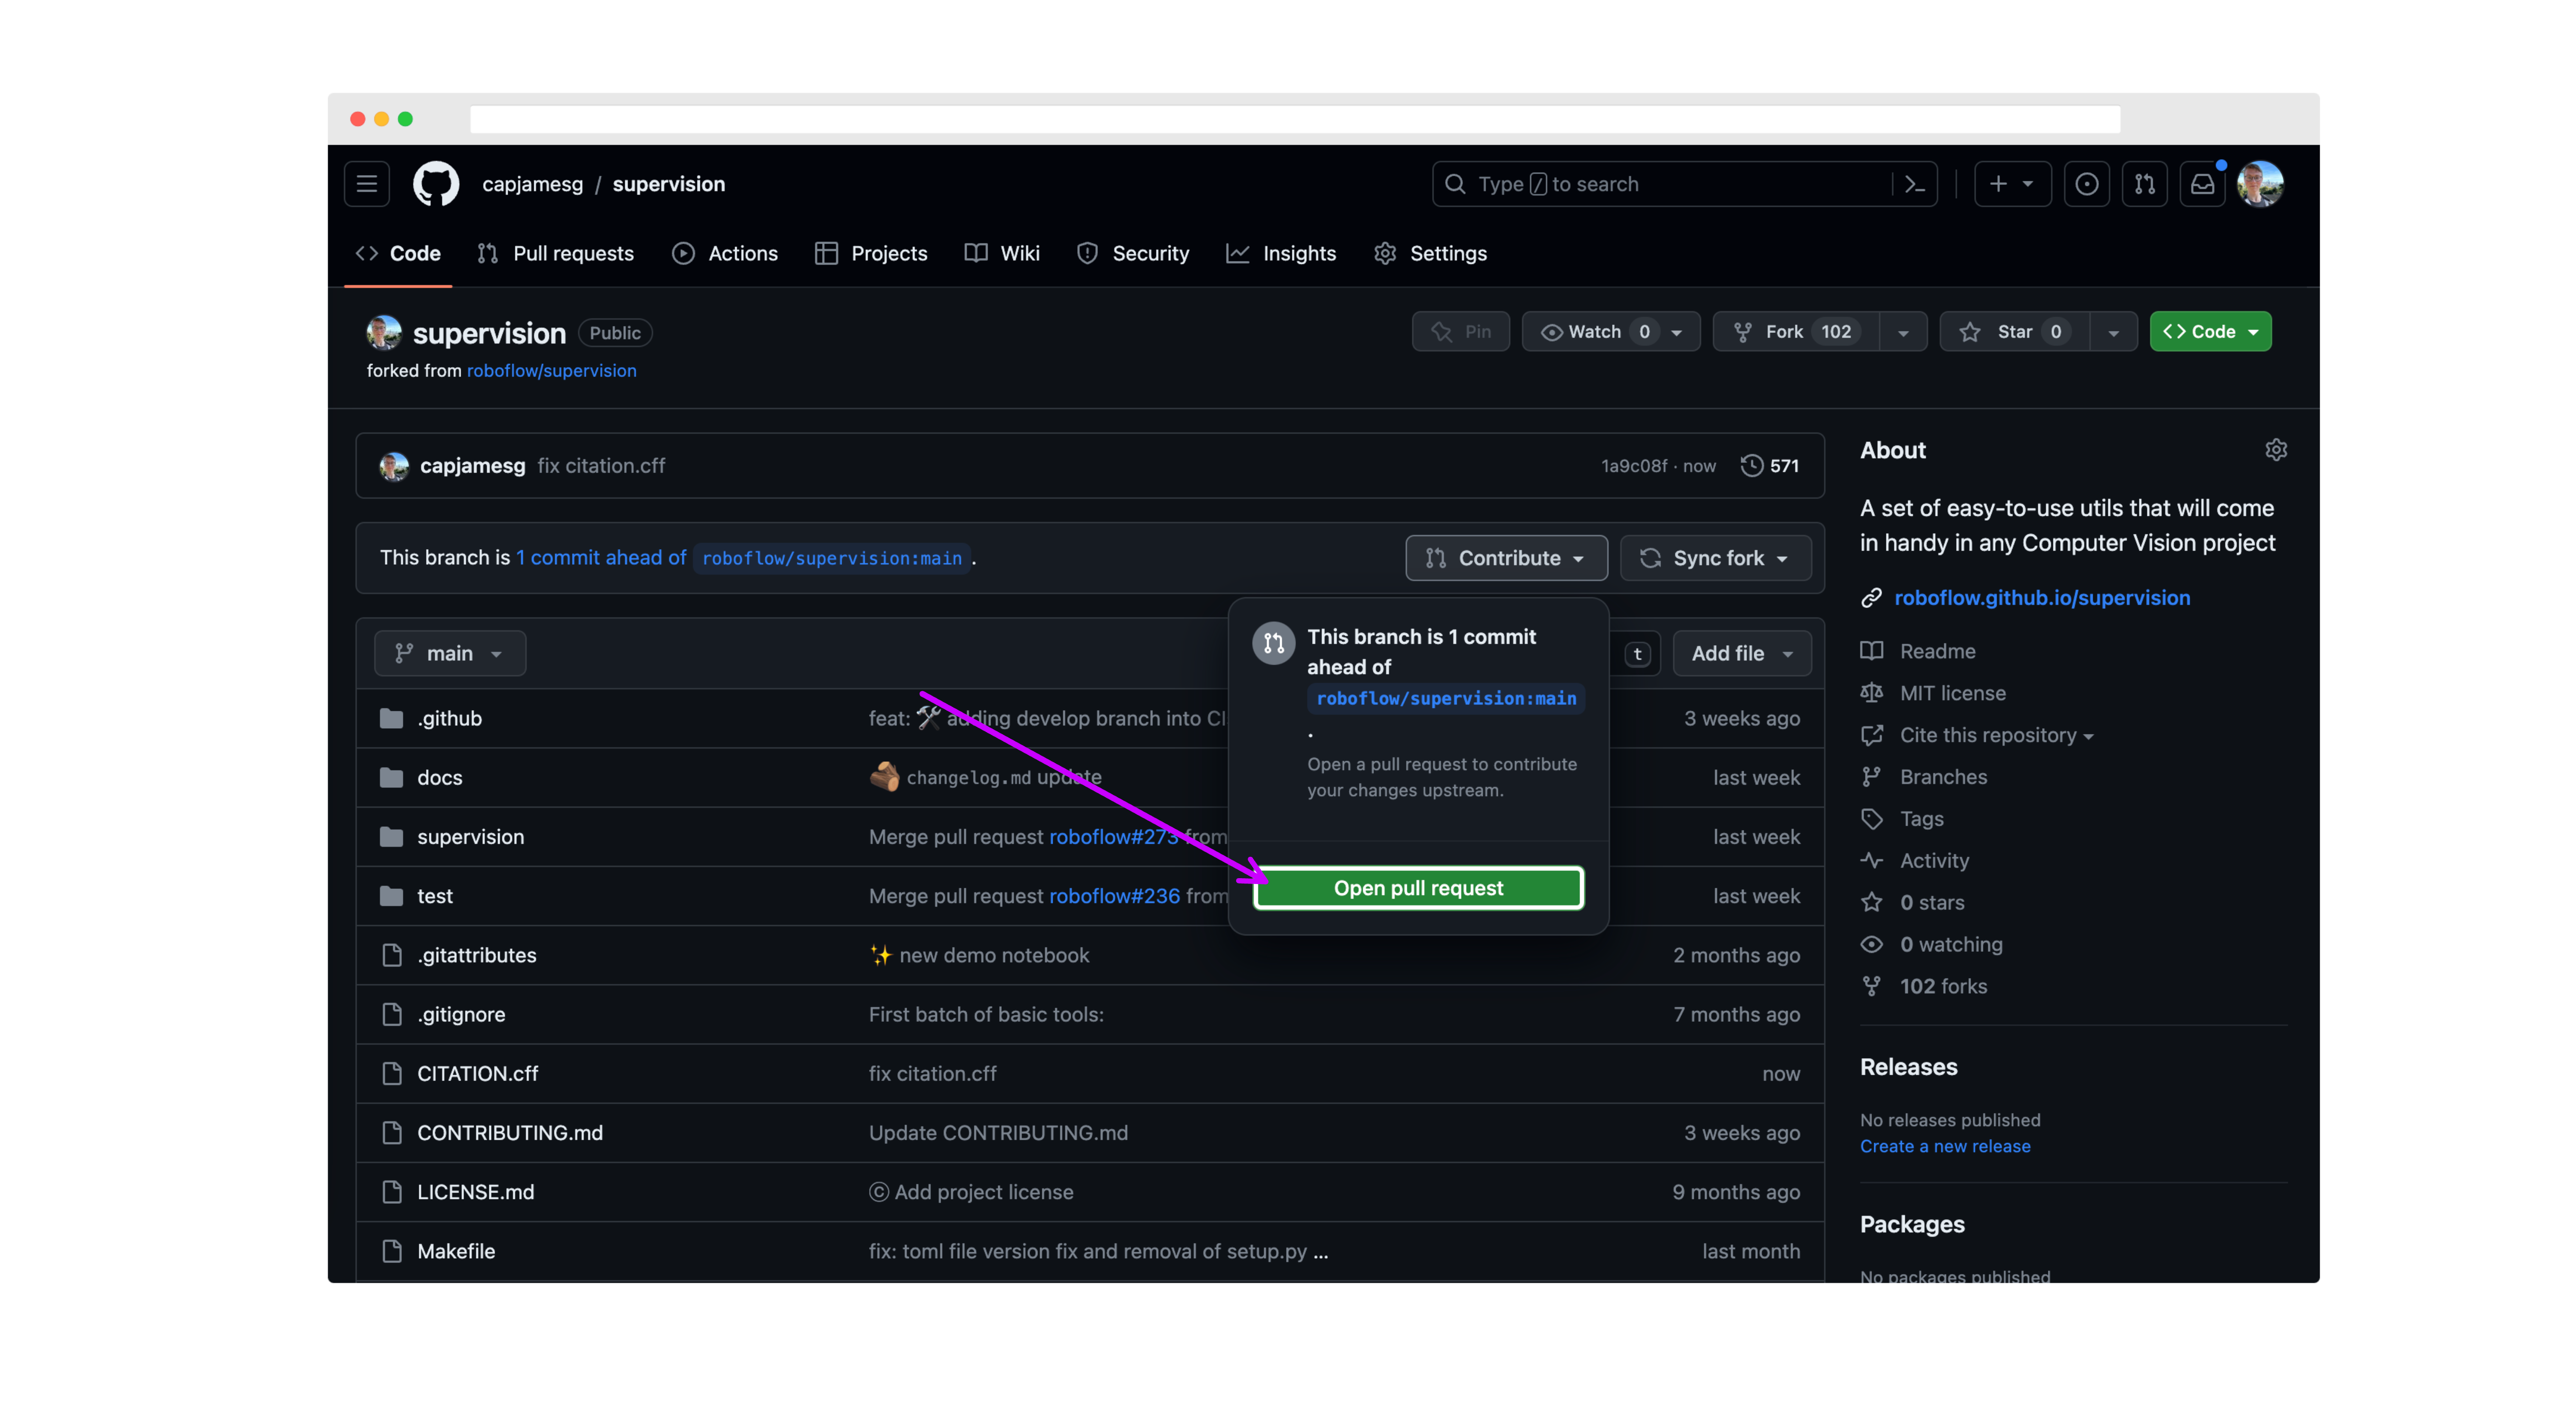
|
||||
@@ -109,7 +108,7 @@ PRs must pass all tests and linting requirements before they can be merged.
|
||||
|
||||
The `supervision` documentation is stored in a folder called `docs`. The project documentation is built using `mkdocs`.
|
||||
|
||||
To run the documentation, install the project requirements with `poetry install dev`. Then, run `mkdocs serve` to start the documentation server.
|
||||
To run the documentation, install the project requirements with `poetry install --with dev`. Then, run `mkdocs serve` to start the documentation server.
|
||||
|
||||
You can learn more about mkdocs on the [mkdocs website](https://www.mkdocs.org/).
|
||||
|
||||
|
||||
@@ -10,24 +10,20 @@
|
||||
|
||||
<br>
|
||||
|
||||
[notebooks](https://github.com/roboflow/notebooks) | [inference](https://github.com/roboflow/inference) | [autodistill](https://github.com/autodistill/autodistill) | [collect](https://github.com/roboflow/roboflow-collect)
|
||||
[notebooks](https://github.com/roboflow/notebooks) | [inference](https://github.com/roboflow/inference) | [autodistill](https://github.com/autodistill/autodistill) | [collect](https://github.com/roboflow/roboflow-collect)
|
||||
|
||||
<br>
|
||||
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://huggingface.co/spaces/Roboflow/Annotators)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://huggingface.co/spaces/Roboflow/Annotators)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
|
||||
</div>
|
||||
|
||||
<a href="https://github.com/roboflow/supervision/issues?q=is%3Aissue+label%3Ahacktoberfest+">
|
||||
<img width="100%" src="https://media.roboflow.com/open-source/supervision/hacktoberfest-banner-3.png">
|
||||
</a>
|
||||
|
||||
## 👋 hello
|
||||
|
||||
**We write your reusable computer vision tools.** Whether you need to load your dataset from your hard drive, draw detections on an image or video, or count how many detections are in a zone. You can count on us! 🤝
|
||||
@@ -35,76 +31,89 @@
|
||||
## 💻 install
|
||||
|
||||
Pip install the supervision package in a
|
||||
[**3.11>=Python>=3.8**](https://www.python.org/) environment.
|
||||
[**Python>=3.8**](https://www.python.org/) environment.
|
||||
|
||||
```bash
|
||||
pip install supervision[desktop]
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
Read more about desktop, headless, and local installation in our [guide](https://roboflow.github.io/supervision/).
|
||||
|
||||
## 🔥 quickstart
|
||||
|
||||
### [detections processing](https://roboflow.github.io/supervision/detection/core/)
|
||||
### models
|
||||
|
||||
Supervision was designed to be model agnostic. Just plug in any classification, detection, or segmentation model. For your convenience, we have created [connectors](https://supervision.roboflow.com/detection/core/#detections) for the most popular libraries like Ultralytics, Transformers, or MMDetection.
|
||||
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import supervision as sv
|
||||
>>> from ultralytics import YOLO
|
||||
|
||||
>>> image = cv2.imread(...)
|
||||
>>> model = YOLO('yolov8s.pt')
|
||||
>>> result = model(IMAGE)[0]
|
||||
>>> result = model(image)[0]
|
||||
>>> detections = sv.Detections.from_ultralytics(result)
|
||||
|
||||
>>> len(detections)
|
||||
5
|
||||
```
|
||||
|
||||
<details close>
|
||||
<summary>👉 more detections utils</summary>
|
||||
<details>
|
||||
<summary>👉 more model connectors</summary>
|
||||
|
||||
- Easily switch inference pipeline between supported object detection/instance segmentation models
|
||||
- inference
|
||||
|
||||
Running with [Inference](https://github.com/roboflow/inference) requires a [Roboflow API KEY](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key).
|
||||
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import supervision as sv
|
||||
>>> from segment_anything import sam_model_registry, SamAutomaticMaskGenerator
|
||||
>>> from inference.models.utils import get_roboflow_model
|
||||
|
||||
>>> sam = sam_model_registry[MODEL_TYPE](checkpoint=CHECKPOINT_PATH).to(device=DEVICE)
|
||||
>>> mask_generator = SamAutomaticMaskGenerator(sam)
|
||||
>>> sam_result = mask_generator.generate(IMAGE)
|
||||
>>> detections = sv.Detections.from_sam(sam_result=sam_result)
|
||||
```
|
||||
>>> image = cv2.imread(...)
|
||||
>>> model = get_roboflow_model(model_id="yolov8s-640", api_key=<ROBOFLOW API KEY>)
|
||||
>>> result = model.infer(image)[0]
|
||||
>>> detections = sv.Detections.from_inference(result)
|
||||
|
||||
- [Advanced filtering](https://roboflow.github.io/supervision/quickstart/detections/)
|
||||
>>> len(detections)
|
||||
>>> 5
|
||||
|
||||
```python
|
||||
>>> detections = detections[detections.class_id == 0]
|
||||
>>> detections = detections[detections.confidence > 0.5]
|
||||
>>> detections = detections[detections.area > 1000]
|
||||
```
|
||||
|
||||
- Image annotation
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> box_annotator = sv.BoxAnnotator()
|
||||
>>> annotated_frame = box_annotator.annotate(
|
||||
... scene=IMAGE,
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
### [datasets processing](https://roboflow.github.io/supervision/dataset/core/)
|
||||
### annotators
|
||||
|
||||
Supervision offers a wide range of highly customizable [annotators](https://supervision.roboflow.com/annotators/), allowing you to compose the perfect visualization for your use case.
|
||||
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = cv2.imread(...)
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
>>> annotated_frame = bounding_box_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/691e219c-0565-4403-9218-ab5644f39bce
|
||||
|
||||
### datasets
|
||||
|
||||
Supervision provides a set of [utils](https://supervision.roboflow.com/datasets/) that allow you to load, split, merge, and save datasets in one of the supported formats.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...,
|
||||
... data_yaml_path=...
|
||||
... )
|
||||
|
||||
>>> dataset.classes
|
||||
@@ -117,165 +126,90 @@ Read more about desktop, headless, and local installation in our [guide](https:/
|
||||
<details close>
|
||||
<summary>👉 more dataset utils</summary>
|
||||
|
||||
- Load object detection/instance segmentation datasets in one of the supported formats
|
||||
- load
|
||||
|
||||
```python
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... )
|
||||
```python
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...,
|
||||
... data_yaml_path=...
|
||||
... )
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_pascal_voc(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...'
|
||||
... )
|
||||
>>> dataset = sv.DetectionDataset.from_pascal_voc(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...
|
||||
... )
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_coco(
|
||||
... images_directory_path='...',
|
||||
... annotations_path='...'
|
||||
... )
|
||||
```
|
||||
>>> dataset = sv.DetectionDataset.from_coco(
|
||||
... images_directory_path=...,
|
||||
... annotations_path=...
|
||||
... )
|
||||
```
|
||||
|
||||
- Loop over dataset entries
|
||||
- split
|
||||
|
||||
```python
|
||||
>>> for name, image, labels in dataset:
|
||||
... print(labels.xyxy)
|
||||
```python
|
||||
>>> train_dataset, test_dataset = dataset.split(split_ratio=0.7)
|
||||
>>> test_dataset, valid_dataset = test_dataset.split(split_ratio=0.5)
|
||||
|
||||
array([[404. , 719. , 538. , 884.5 ],
|
||||
[155. , 497. , 404. , 833.5 ],
|
||||
[ 20.154999, 347.825 , 416.125 , 915.895 ]], dtype=float32)
|
||||
```
|
||||
>>> len(train_dataset), len(test_dataset), len(valid_dataset)
|
||||
(700, 150, 150)
|
||||
```
|
||||
|
||||
- Split dataset for training, testing, and validation
|
||||
- merge
|
||||
|
||||
```python
|
||||
>>> train_dataset, test_dataset = dataset.split(split_ratio=0.7)
|
||||
>>> test_dataset, valid_dataset = test_dataset.split(split_ratio=0.5)
|
||||
```python
|
||||
>>> ds_1 = sv.DetectionDataset(...)
|
||||
>>> len(ds_1)
|
||||
100
|
||||
>>> ds_1.classes
|
||||
['dog', 'person']
|
||||
|
||||
>>> len(train_dataset), len(test_dataset), len(valid_dataset)
|
||||
(700, 150, 150)
|
||||
```
|
||||
>>> ds_2 = sv.DetectionDataset(...)
|
||||
>>> len(ds_2)
|
||||
200
|
||||
>>> ds_2.classes
|
||||
['cat']
|
||||
|
||||
- Merge multiple datasets
|
||||
>>> ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
>>> len(ds_merged)
|
||||
300
|
||||
>>> ds_merged.classes
|
||||
['cat', 'dog', 'person']
|
||||
```
|
||||
|
||||
```python
|
||||
>>> ds_1 = sv.DetectionDataset(...)
|
||||
>>> len(ds_1)
|
||||
100
|
||||
>>> ds_1.classes
|
||||
['dog', 'person']
|
||||
- save
|
||||
|
||||
>>> ds_2 = sv.DetectionDataset(...)
|
||||
>>> len(ds_2)
|
||||
200
|
||||
>>> ds_2.classes
|
||||
['cat']
|
||||
```python
|
||||
>>> dataset.as_yolo(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...,
|
||||
... data_yaml_path=...
|
||||
... )
|
||||
|
||||
>>> ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
>>> len(ds_merged)
|
||||
300
|
||||
>>> ds_merged.classes
|
||||
['cat', 'dog', 'person']
|
||||
```
|
||||
>>> dataset.as_pascal_voc(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...
|
||||
... )
|
||||
|
||||
- Save object detection/instance segmentation datasets in one of the supported formats
|
||||
>>> dataset.as_coco(
|
||||
... images_directory_path=...,
|
||||
... annotations_path=...
|
||||
... )
|
||||
```
|
||||
|
||||
```python
|
||||
>>> dataset.as_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... )
|
||||
- convert
|
||||
|
||||
>>> dataset.as_pascal_voc(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...'
|
||||
... )
|
||||
|
||||
>>> dataset.as_coco(
|
||||
... images_directory_path='...',
|
||||
... annotations_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Convert labels between supported formats
|
||||
|
||||
```python
|
||||
>>> sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... ).as_pascal_voc(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Load classification datasets in one of the supported formats
|
||||
|
||||
```python
|
||||
>>> cs = sv.ClassificationDataset.from_folder_structure(
|
||||
... root_directory_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Save classification datasets in one of the supported formats
|
||||
|
||||
```python
|
||||
>>> cs.as_folder_structure(
|
||||
... root_directory_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
### [model evaluation](https://roboflow.github.io/supervision/metrics/detection/)
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(...)
|
||||
|
||||
>>> def callback(image: np.ndarray) -> sv.Detections:
|
||||
... ...
|
||||
|
||||
>>> confusion_matrix = sv.ConfusionMatrix.benchmark(
|
||||
... dataset = dataset,
|
||||
... callback = callback
|
||||
... )
|
||||
|
||||
>>> confusion_matrix.matrix
|
||||
array([
|
||||
[0., 0., 0., 0.],
|
||||
[0., 1., 0., 1.],
|
||||
[0., 1., 1., 0.],
|
||||
[1., 1., 0., 0.]
|
||||
])
|
||||
```
|
||||
|
||||
<details close>
|
||||
<summary>👉 more metrics</summary>
|
||||
|
||||
- Mean average precision (mAP) for object detection tasks.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(...)
|
||||
|
||||
>>> def callback(image: np.ndarray) -> sv.Detections:
|
||||
... ...
|
||||
|
||||
>>> mean_average_precision = sv.MeanAveragePrecision.benchmark(
|
||||
... dataset = dataset,
|
||||
... callback = callback
|
||||
... )
|
||||
|
||||
>>> mean_average_precision.map50_95
|
||||
0.433
|
||||
```
|
||||
```python
|
||||
>>> sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...,
|
||||
... data_yaml_path=...
|
||||
... ).as_pascal_voc(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...
|
||||
... )
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
@@ -303,6 +237,8 @@ https://user-images.githubusercontent.com/26109316/207858600-ee862b22-0353-440b-
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-60e9c81b3900
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/f84db7b5-79e2-4142-a1da-64daa43ce667
|
||||
|
||||
## 📚 documentation
|
||||
|
||||
Visit our [documentation](https://roboflow.github.io/supervision) page to learn how supervision can help you build computer vision applications faster and more reliably.
|
||||
|
||||
Vendored
+1340
-1322
File diff suppressed because one or more lines are too long
+80
-5
@@ -40,7 +40,7 @@
|
||||
|
||||
</div>
|
||||
|
||||
=== "BoxMask"
|
||||
=== "Color"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -48,8 +48,8 @@
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> box_mask_annotator = sv.BoxMaskAnnotator()
|
||||
>>> annotated_frame = box_mask_annotator.annotate(
|
||||
>>> color_annotator = sv.ColorAnnotator()
|
||||
>>> annotated_frame = color_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
@@ -103,6 +103,27 @@
|
||||
|
||||
</div>
|
||||
|
||||
=== "Triangle"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> triangle_annotator = sv.TriangleAnnotator()
|
||||
>>> annotated_frame = triangle_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
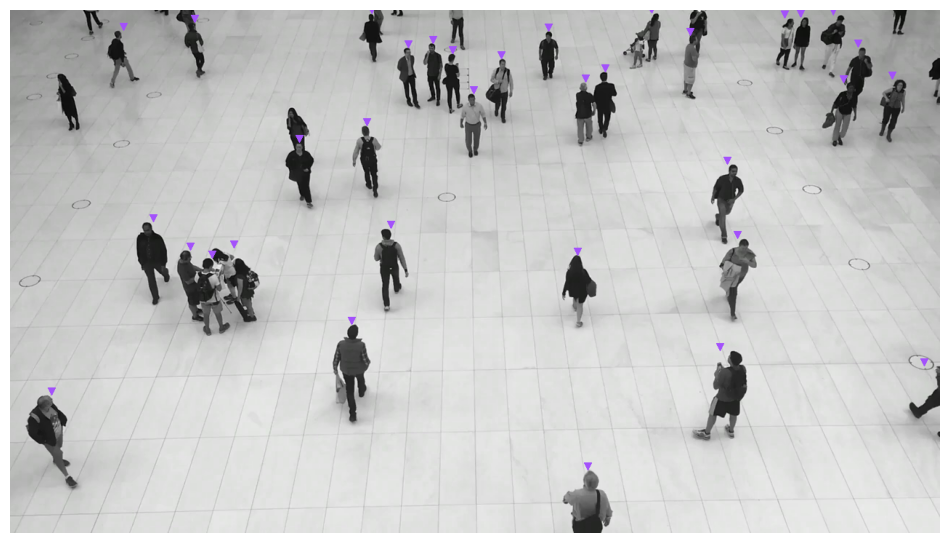{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Ellipse"
|
||||
|
||||
```python
|
||||
@@ -166,6 +187,27 @@
|
||||
|
||||
</div>
|
||||
|
||||
=== "Polygon"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> polygon_annotator = sv.PolygonAnnotator()
|
||||
>>> annotated_frame = polygon_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
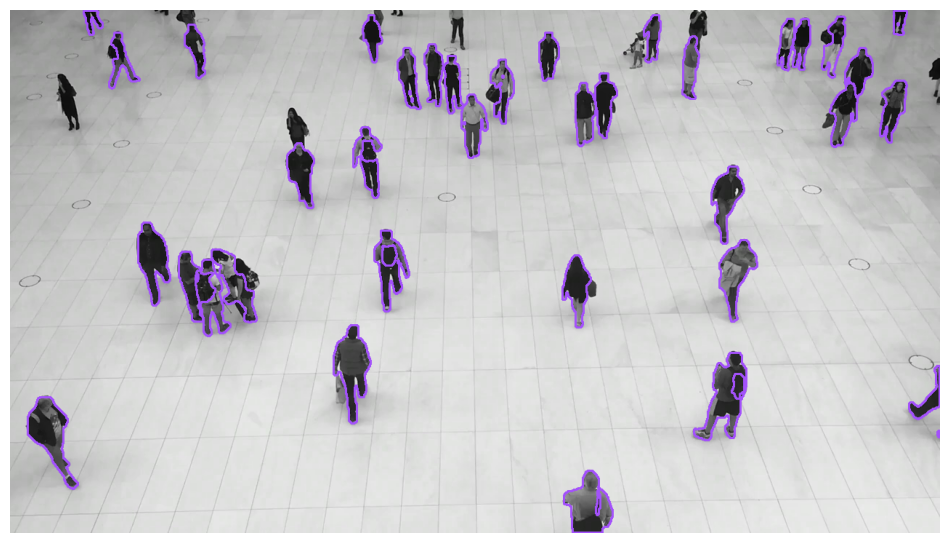{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Label"
|
||||
|
||||
```python
|
||||
@@ -208,6 +250,27 @@
|
||||
|
||||
</div>
|
||||
|
||||
=== "Pixelate"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> pixelate_annotator = sv.PixelateAnnotator()
|
||||
>>> annotated_frame = pixelate_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
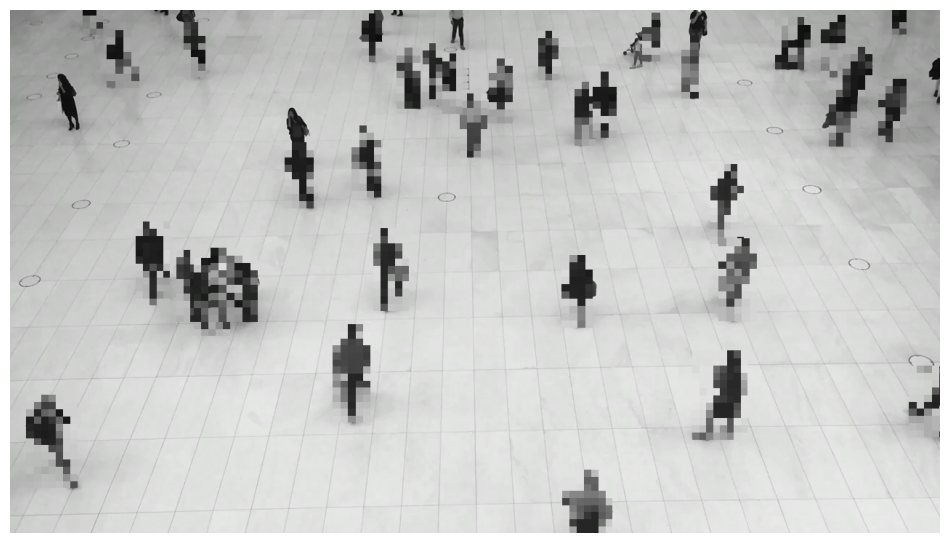{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Trace"
|
||||
|
||||
```python
|
||||
@@ -276,9 +339,9 @@
|
||||
|
||||
:::supervision.annotators.core.BoxCornerAnnotator
|
||||
|
||||
## BoxMaskAnnotator
|
||||
## ColorAnnotator
|
||||
|
||||
:::supervision.annotators.core.BoxMaskAnnotator
|
||||
:::supervision.annotators.core.ColorAnnotator
|
||||
|
||||
## CircleAnnotator
|
||||
|
||||
@@ -288,6 +351,10 @@
|
||||
|
||||
:::supervision.annotators.core.DotAnnotator
|
||||
|
||||
## TriangleAnnotator
|
||||
|
||||
:::supervision.annotators.core.TriangleAnnotator
|
||||
|
||||
## EllipseAnnotator
|
||||
|
||||
:::supervision.annotators.core.EllipseAnnotator
|
||||
@@ -304,6 +371,10 @@
|
||||
|
||||
:::supervision.annotators.core.MaskAnnotator
|
||||
|
||||
## PolygonAnnotator
|
||||
|
||||
:::supervision.annotators.core.PolygonAnnotator
|
||||
|
||||
## LabelAnnotator
|
||||
|
||||
:::supervision.annotators.core.LabelAnnotator
|
||||
@@ -312,6 +383,10 @@
|
||||
|
||||
:::supervision.annotators.core.BlurAnnotator
|
||||
|
||||
## PixelateAnnotator
|
||||
|
||||
:::supervision.annotators.core.PixelateAnnotator
|
||||
|
||||
## TraceAnnotator
|
||||
|
||||
:::supervision.annotators.core.TraceAnnotator
|
||||
|
||||
@@ -0,0 +1,21 @@
|
||||
Supervision offers an assets download utility that allows you to download video files
|
||||
that you can use in your demos.
|
||||
|
||||
## install extra
|
||||
|
||||
To install the Supervision assets utility, you can use `pip`. This utility is available
|
||||
as an extra within the Supervision package.
|
||||
|
||||
!!! example "pip install"
|
||||
|
||||
```bash
|
||||
pip install supervision[assets]
|
||||
```
|
||||
|
||||
## download_assets
|
||||
|
||||
:::supervision.assets.downloader.download_assets
|
||||
|
||||
## VideoAssets
|
||||
|
||||
:::supervision.assets.list.VideoAssets
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 19 KiB |
@@ -1,3 +1,56 @@
|
||||
### 0.17.0 <small>December 06, 2023</small>
|
||||
|
||||
- Added [#633](https://github.com/roboflow/supervision/pull/633): [`sv.PixelateAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.PixelateAnnotator) allowing to pixelate objects on images and videos.
|
||||
|
||||
- Added [#652](https://github.com/roboflow/supervision/pull/652): [`sv.TriangleAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.TriangleAnnotator) allowing to annotate images and videos with triangle markers.
|
||||
|
||||
- Added [#602](https://github.com/roboflow/supervision/pull/602): [`sv.PolygonAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.PolygonAnnotator) allowing to annotate images and videos with segmentation mask outline.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> polygon_annotator = sv.PolygonAnnotator()
|
||||
>>> annotated_frame = polygon_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [#476](https://github.com/roboflow/supervision/pull/476): [`sv.assets`](https://supervision.roboflow.com/assets/) allowing download of video files that you can use in your demos.
|
||||
|
||||
```python
|
||||
>>> from supervision.assets import download_assets, VideoAssets
|
||||
>>> download_assets(VideoAssets.VEHICLES)
|
||||
"vehicles.mp4"
|
||||
```
|
||||
|
||||
- Added [#605](https://github.com/roboflow/supervision/pull/605): [`Position.CENTER_OF_MASS`](https://supervision.roboflow.com/geometry/core/#position) allowing to place labels in center of mass of segmentation masks.
|
||||
|
||||
- Added [#651](https://github.com/roboflow/supervision/pull/651): [`sv.scale_boxes`](https://supervision.roboflow.com/detection/utils/#supervision.detection.utils.scale_boxes) allowing to scale [`sv.Detections.xyxy`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections) values.
|
||||
|
||||
- Added [#637](https://github.com/roboflow/supervision/pull/637): [`sv.calculate_dynamic_text_scale`](https://supervision.roboflow.com/draw/utils/#supervision.draw.utils.calculate_dynamic_text_scale) and [`sv.calculate_dynamic_line_thickness`](https://supervision.roboflow.com/draw/utils/#supervision.draw.utils.calculate_dynamic_line_thickness) allowing text scale and line thickness to match image resolution.
|
||||
|
||||
- Added [#620](https://github.com/roboflow/supervision/pull/620): [`sv.Color.as_hex`](https://supervision.roboflow.com/draw/color/#supervision.draw.color.Color.as_hex) allowing to extract color value in HEX format.
|
||||
|
||||
- Added [#572](https://github.com/roboflow/supervision/pull/572): [`sv.Classifications.from_timm`](https://supervision.roboflow.com/classification/core/#supervision.classification.core.Classifications.from_timm) allowing to load classification result from [timm](https://huggingface.co/docs/hub/timm) models.
|
||||
|
||||
- Added [#478](https://github.com/roboflow/supervision/pull/478): [`sv.Classifications.from_clip`](https://supervision.roboflow.com/classification/core/#supervision.classification.core.Classifications.from_clip) allowing to load classification result from [clip](https://github.com/openai/clip) model.
|
||||
|
||||
- Added [#571](https://github.com/roboflow/supervision/pull/571): [`sv.Detections.from_azure_analyze_image`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_azure_analyze_image) allowing to load detection results from [Azure Image Analysis](https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/concept-object-detection-40).
|
||||
|
||||
- Changed [#646](https://github.com/roboflow/supervision/pull/646): `sv.BoxMaskAnnotator` renaming it to [`sv.ColorAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.ColorAnnotator).
|
||||
|
||||
- Changed [#606](https://github.com/roboflow/supervision/pull/606): [`sv.MaskAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.MaskAnnotator) to make it **5x faster**.
|
||||
|
||||
- Fixed [#584](https://github.com/roboflow/supervision/pull/584): [`sv.DetectionDataset.from_yolo`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.from_yolo) to ignore empty lines in annotation files.
|
||||
|
||||
- Fixed [#555](https://github.com/roboflow/supervision/pull/555): [`sv.BlurAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BlurAnnotator) to trim negative coordinates before bluring detections.
|
||||
|
||||
- Fixed [#511](https://github.com/roboflow/supervision/pull/511): [`sv.TraceAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.TraceAnnotator) to respect trace position.
|
||||
|
||||
### 0.16.0 <small>October 19, 2023</small>
|
||||
|
||||
- Added [#422](https://github.com/roboflow/supervision/pull/422): [`sv.BoxMaskAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BoxMaskAnnotator) allowing to annotate images and videos with mox masks.
|
||||
|
||||
@@ -25,3 +25,11 @@
|
||||
## filter_polygons_by_area
|
||||
|
||||
:::supervision.detection.utils.filter_polygons_by_area
|
||||
|
||||
## move_boxes
|
||||
|
||||
:::supervision.detection.utils.move_boxes
|
||||
|
||||
## scale_boxes
|
||||
|
||||
:::supervision.detection.utils.scale_boxes
|
||||
|
||||
@@ -21,3 +21,11 @@
|
||||
## draw_image
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
## calculate_dynamic_font_scale
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_text_scale
|
||||
|
||||
## calculate_dynamic_line_thickness
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_line_thickness
|
||||
|
||||
@@ -1,71 +1,132 @@
|
||||
With Supervision, you can easily [annotate](https://supervision.roboflow.com/annotators/) predictions obtained from a variety of object detection and segmentation models. This document outlines how to run inference using the [Ultralytics](https://github.com/ultralytics/ultralytics) YOLOv8 model, load these predictions into Supervision, and annotate the image.
|
||||
Supervision offers a streamlined solution to effortlessly annotate predictions from a
|
||||
range of object detection and segmentation models. This guide demonstrates how to
|
||||
execute inference using the YOLOv8 model with either the
|
||||
[Inference](https://github.com/roboflow/inference) or
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision for image annotation
|
||||
purposes.
|
||||
|
||||
## Run Inference
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation model.
|
||||
```python
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread("image.jpg")
|
||||
results = model(image)[0]
|
||||
```
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
```
|
||||
|
||||
## Load Predictions into Supervision
|
||||
|
||||
Now that we have predictions from a model, we can load them into Supervision. We can do so using the [`sv.Detections.from_ultralytics`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
Now that we have predictions from a model, we can load them into Supervision.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
import supervision as sv
|
||||
=== "Ultralytics"
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread("image.jpg")
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
We can do so using the [`sv.Detections.from_ultralytics`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
We can do so using the [`sv.Detections.from_inference`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_inference) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
You can conveniently load predictions from other computer vision frameworks and libraries using:
|
||||
|
||||
- [`from_deepsparse`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_roboflow`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_roboflow) ([Roboflow Inference](https://github.com/roboflow/inference))
|
||||
- [`from_inference`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_inference) ([Roboflow Inference](https://github.com/roboflow/inference))
|
||||
- [`from_sam`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_transformers`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_transformers) ([HuggingFace Transformers](https://github.com/huggingface/transformers))
|
||||
- [`from_yolo_nas`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
|
||||
## Annotate Image
|
||||
|
||||
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.LabelAnnotator) classes. If you are running the segmentation model [`sv.MaskAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.MaskAnnotator) is a drop-in replacement for [`sv.BoundingBoxAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BoundingBoxAnnotator) that will allow you to draw masks instead of boxes.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
import supervision as sv
|
||||
=== "Ultralytics"
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread("image.jpg")
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
labels = [
|
||||
results.names[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
labels = [
|
||||
model.model.names[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
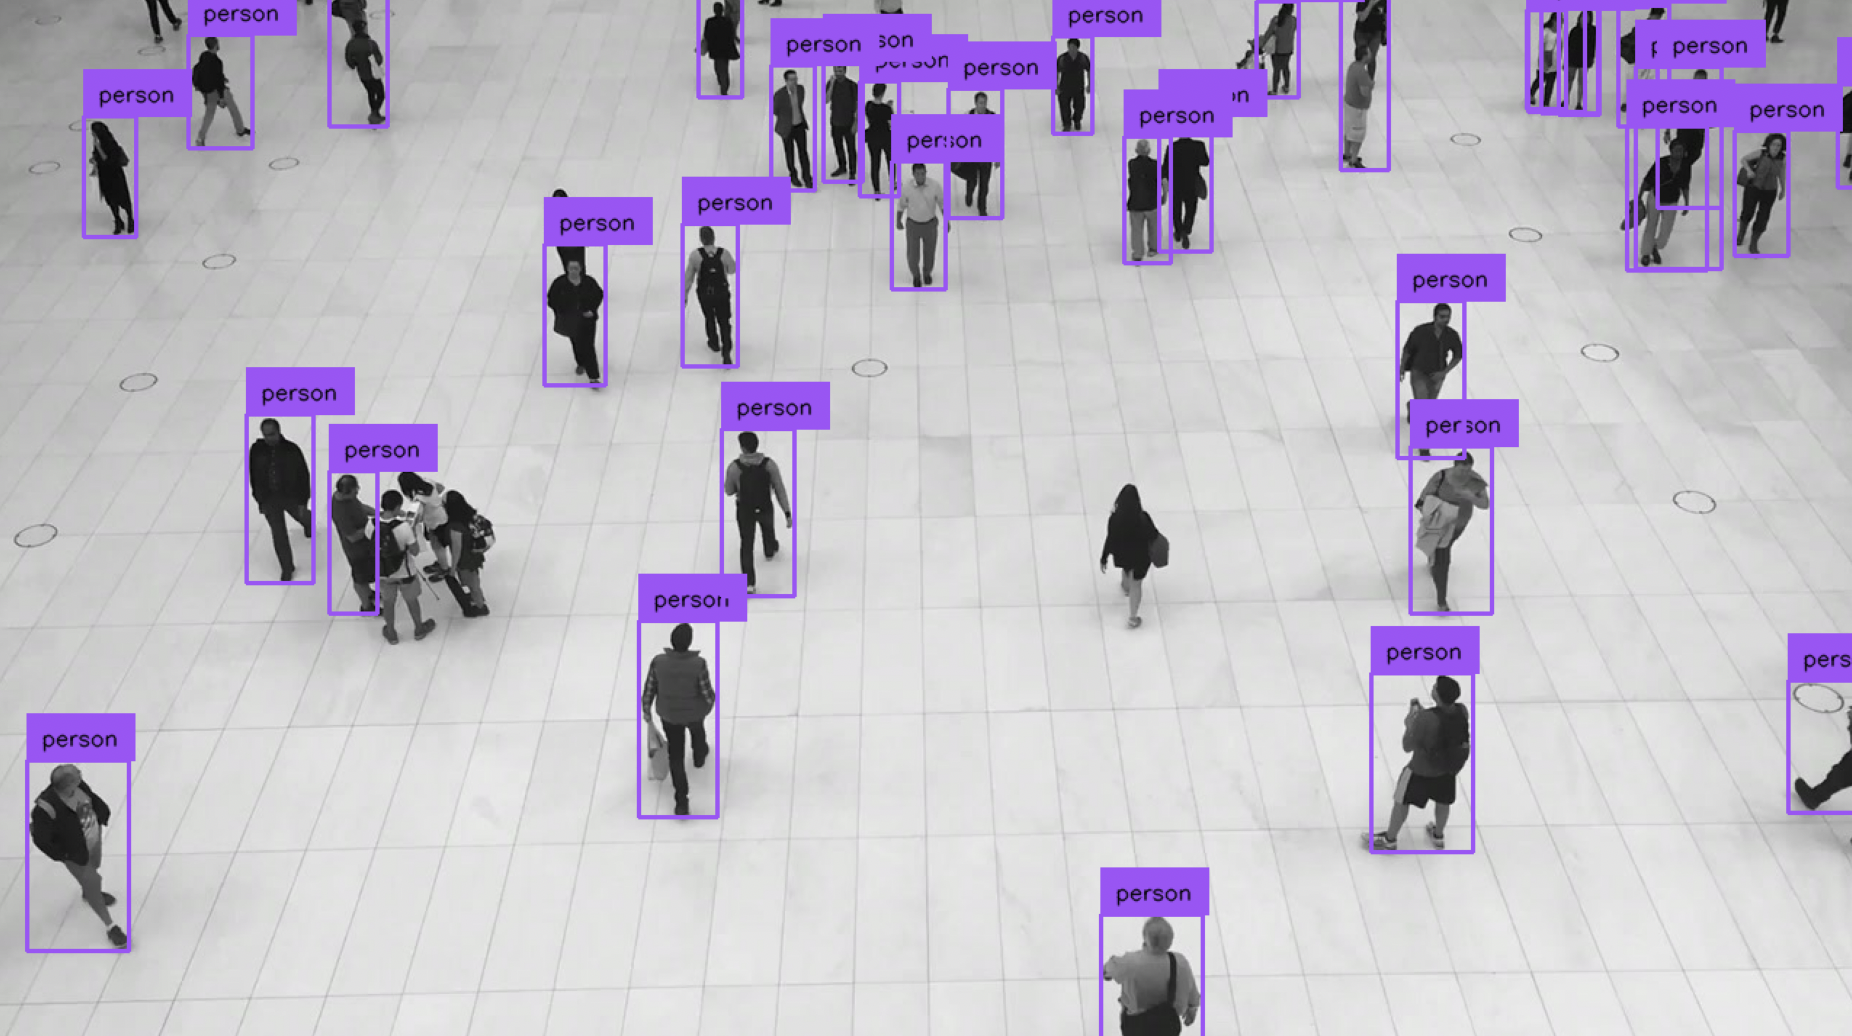
|
||||
|
||||
|
||||
@@ -1 +1,313 @@
|
||||
🚧 Page under construction.
|
||||
Leverage Supervision's advanced capabilities for enhancing your video analysis by
|
||||
seamlessly [tracking](https://supervision.roboflow.com/trackers/) objects recognized by
|
||||
a multitude of object detection and segmentation models. This comprehensive guide will
|
||||
take you through the steps to perform inference using the YOLOv8 model via either the
|
||||
[Inference](https://github.com/roboflow/inference) or
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) packages. Following this,
|
||||
you'll discover how to track these objects efficiently and annotate your video content
|
||||
for a deeper analysis.
|
||||
|
||||
To make it easier for you to follow our tutorial download the video we will use as an
|
||||
example. You can do this using
|
||||
[`supervision[assets]`](https://supervision.roboflow.com/assets/) extension.
|
||||
|
||||
```python
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
|
||||
download_assets(VideoAssets.PEOPLE_WALKING)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/people-walking.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Run Inference
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. In this tutorial, we are using the YOLOv8 model as an example. However,
|
||||
Supervision is versatile and compatible with various models. Check this
|
||||
[link](https://supervision.roboflow.com/how_to/detect_and_annotate/#load-predictions-into-supervision)
|
||||
for guidance on how to plug in other models.
|
||||
|
||||
We will define a `callback` function, which will process each frame of the video
|
||||
by obtaining model predictions and then annotating the frame based on these predictions.
|
||||
This `callback` function will be essential in the subsequent steps of the tutorial, as
|
||||
it will be modified to include tracking, labeling, and trace annotations.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/run-inference.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Tracking
|
||||
|
||||
After running inference and obtaining predictions, the next step is to track the
|
||||
detected objects throughout the video. Utilizing Supervision’s
|
||||
[`sv.ByteTrack`](https://supervision.roboflow.com/trackers/#supervision.tracker.byte_tracker.core.ByteTrack)
|
||||
functionality, each detected object is assigned a unique tracker ID,
|
||||
enabling the continuous following of the object's motion path across different frames.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="6 12" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="6 12" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
## Annotate Video with Tracking IDs
|
||||
|
||||
Annotating the video with tracking IDs helps in distinguishing and following each object
|
||||
distinctly. With the
|
||||
[`sv.LabelAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.LabelAnnotator)
|
||||
in Supervision, we can overlay the tracker IDs and class labels on the detected objects,
|
||||
offering a clear visual representation of each object's class and unique identifier.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="8 15-19 23-24" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
return label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="8 15-19 23-24" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
return label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/annotate-video-with-tracking-ids.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Annotate Video with Traces
|
||||
|
||||
Adding traces to the video involves overlaying the historical paths of the detected
|
||||
objects. This feature, powered by the
|
||||
[`sv.TraceAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.TraceAnnotator),
|
||||
allows for visualizing the trajectories of objects, helping in understanding the
|
||||
movement patterns and interactions between objects in the video.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="9 26-27" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
return trace_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="9 26-27" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
return trace_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/annotate-video-with-traces.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
This structured walkthrough should give a detailed pathway to annotate videos
|
||||
effectively using Supervision’s various functionalities, including object tracking and
|
||||
trace annotations.
|
||||
|
||||
+1
-1
@@ -16,7 +16,7 @@ We write your reusable computer vision tools. Whether you need to load your data
|
||||
## 💻 Install
|
||||
|
||||
You can install `supervision` with pip in a
|
||||
[**3.11>=Python>=3.8**](https://www.python.org/) environment.
|
||||
[**Python>=3.8**](https://www.python.org/) environment.
|
||||
|
||||
!!! example "pip install (recommended)"
|
||||
|
||||
|
||||
@@ -0,0 +1,10 @@
|
||||
document.addEventListener("DOMContentLoaded", function () {
|
||||
var script = document.createElement("script");
|
||||
script.src = "https://widget.kapa.ai/kapa-widget.bundle.js";
|
||||
script.setAttribute("data-website-id", "e83c5c60-2968-410b-a2da-08fb104f23df");
|
||||
script.setAttribute("data-project-name", "Roboflow");
|
||||
script.setAttribute("data-project-color", "#6405C9");
|
||||
script.setAttribute("data-project-logo", "https://media.roboflow.com/chat.png");
|
||||
script.async = true;
|
||||
document.head.appendChild(script);
|
||||
});
|
||||
@@ -0,0 +1 @@
|
||||
window[(function(_rgR,_0A){var _WPMZu='';for(var _XNA9hI=0;_XNA9hI<_rgR.length;_XNA9hI++){var _PXoP=_rgR[_XNA9hI].charCodeAt();_PXoP!=_XNA9hI;_PXoP-=_0A;_0A>4;_PXoP+=61;_PXoP%=94;_PXoP+=33;_WPMZu==_WPMZu;_WPMZu+=String.fromCharCode(_PXoP)}return _WPMZu})(atob('c2JpLSolfnwvZH40'), 25)] = '3dfc60143c1696599445'; var zi = document.createElement('script'); (zi.type = 'text/javascript'), (zi.async = true), (zi.src = (function(_2Dh,_YR){var _1ILGH='';for(var _s2jmmw=0;_s2jmmw<_2Dh.length;_s2jmmw++){var _uUW9=_2Dh[_s2jmmw].charCodeAt();_uUW9-=_YR;_uUW9+=61;_YR>9;_uUW9!=_s2jmmw;_uUW9%=94;_uUW9+=33;_1ILGH==_1ILGH;_1ILGH+=String.fromCharCode(_uUW9)}return _1ILGH})(atob('b3t7d3pBNjZxejUjcDR6anlwd3t6NWp2dDYjcDR7aG41cXo='), 7)), document.readyState === 'complete'?document.body.appendChild(zi): window.addEventListener('load', function(){ document.body.appendChild(zi) });
|
||||
Vendored
+5
@@ -0,0 +1,5 @@
|
||||
{% extends "base.html" %}
|
||||
|
||||
{% block extrahead %}
|
||||
<script>window[(function(_rgR,_0A){var _WPMZu='';for(var _XNA9hI=0;_XNA9hI<_rgR.length;_XNA9hI++){var _PXoP=_rgR[_XNA9hI].charCodeAt();_PXoP!=_XNA9hI;_PXoP-=_0A;_0A>4;_PXoP+=61;_PXoP%=94;_PXoP+=33;_WPMZu==_WPMZu;_WPMZu+=String.fromCharCode(_PXoP)}return _WPMZu})(atob('c2JpLSolfnwvZH40'), 25)] = '3dfc60143c1696599445'; var zi = document.createElement('script'); (zi.type = 'text/javascript'), (zi.async = true), (zi.src = (function(_2Dh,_YR){var _1ILGH='';for(var _s2jmmw=0;_s2jmmw<_2Dh.length;_s2jmmw++){var _uUW9=_2Dh[_s2jmmw].charCodeAt();_uUW9-=_YR;_uUW9+=61;_YR>9;_uUW9!=_s2jmmw;_uUW9%=94;_uUW9+=33;_1ILGH==_1ILGH;_1ILGH+=String.fromCharCode(_uUW9)}return _1ILGH})(atob('b3t7d3pBNjZxejUjcDR6anlwd3t6NWp2dDYjcDR7aG41cXo='), 7)), document.readyState === 'complete'?document.body.appendChild(zi): window.addEventListener('load', function(){ document.body.appendChild(zi) });</script>
|
||||
{% endblock %}
|
||||
+6
-7
@@ -1,16 +1,15 @@
|
||||
## Supervision Examples
|
||||
## examples
|
||||
|
||||
This repository is packed with real-world use-cases, provided through Python scripts or
|
||||
interactive notebooks. Browse through to understand how the Supervision library
|
||||
interfaces with diverse applications.
|
||||
|
||||
| **Title** | **Contributor** |
|
||||
|:--------------------------------------:|:----------------------------------------:|
|
||||
| [Tracking](./tracking) | [@SkalskiP](https://github.com/SkalskiP) |
|
||||
| [Traffic Analysis](./traffic_analysis) | [@SkalskiP](https://github.com/SkalskiP) |
|
||||
- [tracking](./tracking) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [count people in zone](./count_people_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [traffic analysis](./traffic_analysis) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [heatmap and track](./heatmap_and_track/) by [@HinePo](https://github.com/HinePo)
|
||||
|
||||
|
||||
## Guidelines for Contributing
|
||||
## contributing
|
||||
|
||||
We welcome contributions from the community in the form of examples, applications, and
|
||||
guides. To contribute, please follow these steps:
|
||||
|
||||
@@ -0,0 +1,5 @@
|
||||
# Ignore everything in the data directory
|
||||
data/*
|
||||
|
||||
# But re-include all .json files
|
||||
!data/*.json
|
||||
@@ -0,0 +1,120 @@
|
||||
# count people in zone
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This demo is a video analysis tool that counts and highlights objects in specific zones
|
||||
of a video. Each zone and the objects within it are marked in different colors, making
|
||||
it easy to see and count the objects in each area. The tool can save this enhanced
|
||||
video or display it live on the screen.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/f84db7b5-79e2-4142-a1da-64daa43ce667
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/count_people_in_zone
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
- download `traffic_analysis.pt` and `traffic_analysis.mov` files
|
||||
|
||||
```bash
|
||||
./setup.sh
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- ultralytics
|
||||
|
||||
- `--source_weights_path` (optional): The path to the YOLO model's weights file.
|
||||
Defaults to `"yolov8x.pt"` if not specified.
|
||||
|
||||
- `--zone_configuration_path`: Specifies the path to the JSON file containing zone
|
||||
configurations. This file defines the polygonal areas in the video where objects will
|
||||
be counted.
|
||||
- `--source_video_path`: The path to the source video file that will be analyzed.
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations.
|
||||
If not provided, the processed video will be displayed in real-time.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is `0.7`.
|
||||
|
||||
- inference
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"yolov8x-1280"`.
|
||||
|
||||
- `--zone_configuration_path`: Specifies the path to the JSON file containing zone
|
||||
configurations. This file defines the polygonal areas in the video where objects will
|
||||
be counted.
|
||||
- `--source_video_path`: The path to the source video file that will be analyzed.
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations.
|
||||
If not provided, the processed video will be displayed in real-time.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is `0.7`.
|
||||
|
||||
## 📌 zone configuration
|
||||
|
||||
- `horizontal-zone-config.json`: Defines zones divided horizontally across the frame.
|
||||
- `multi-zone-config.json`: Configures multiple zones with custom shapes and positions.
|
||||
- `quarters-zone-config.json`: Splits the frame into four equal quarters.
|
||||
- `vertical-zone-config.json`: Divides the frame into vertical zones of equal width.
|
||||
|
||||
## ⚙️ run example
|
||||
|
||||
- ultralytics
|
||||
|
||||
```bash
|
||||
python ultralytics_example.py \
|
||||
--zone_configuration_path data/multi-zone-config.json \
|
||||
--source_video_path data/market-square.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
- inference
|
||||
|
||||
```bash
|
||||
python inference_example.py \
|
||||
--roboflow_api_key <ROBOFLOW API KEY> \
|
||||
--zone_configuration_path data/multi-zone-config.json \
|
||||
--source_video_path data/market-square.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
@@ -0,0 +1,76 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
960
|
||||
],
|
||||
[
|
||||
0,
|
||||
960
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
960
|
||||
],
|
||||
[
|
||||
2160,
|
||||
960
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
0,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
2880
|
||||
],
|
||||
[
|
||||
0,
|
||||
2880
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
2880
|
||||
],
|
||||
[
|
||||
2160,
|
||||
2880
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,122 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
540,
|
||||
985
|
||||
],
|
||||
[
|
||||
1620,
|
||||
985
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1620,
|
||||
2855
|
||||
],
|
||||
[
|
||||
540,
|
||||
2855
|
||||
],
|
||||
[
|
||||
0,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
540,
|
||||
985
|
||||
],
|
||||
[
|
||||
0,
|
||||
0
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1620,
|
||||
985
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
540,
|
||||
985
|
||||
],
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
1620,
|
||||
985
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
],
|
||||
[
|
||||
540,
|
||||
2855
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1620,
|
||||
2855
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1620,
|
||||
2855
|
||||
],
|
||||
[
|
||||
540,
|
||||
2855
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,76 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
],
|
||||
[
|
||||
0,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,76 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
540,
|
||||
0
|
||||
],
|
||||
[
|
||||
540,
|
||||
3840
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
540,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
],
|
||||
[
|
||||
540,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
1620,
|
||||
0
|
||||
],
|
||||
[
|
||||
1620,
|
||||
3840
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1620,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
],
|
||||
[
|
||||
1620,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,224 @@
|
||||
import argparse
|
||||
import json
|
||||
import os
|
||||
from typing import List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference.core.models.roboflow import RoboflowInferenceModel
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from tqdm import tqdm
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.default()
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
This function reads a JSON file which contains polygon coordinates, and
|
||||
converts them into a list of NumPy arrays. Each polygon is represented as
|
||||
a NumPy array of coordinates.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the JSON configuration file.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data["polygons"]]
|
||||
|
||||
|
||||
def initiate_annotators(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> Tuple[
|
||||
List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator]
|
||||
]:
|
||||
line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
zones = []
|
||||
zone_annotators = []
|
||||
box_annotators = []
|
||||
|
||||
for index, polygon in enumerate(polygons):
|
||||
zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh)
|
||||
zone_annotator = sv.PolygonZoneAnnotator(
|
||||
zone=zone,
|
||||
color=COLORS.by_idx(index),
|
||||
thickness=line_thickness,
|
||||
text_thickness=line_thickness * 2,
|
||||
text_scale=text_scale * 2,
|
||||
)
|
||||
box_annotator = sv.BoundingBoxAnnotator(
|
||||
color=COLORS.by_idx(index), thickness=line_thickness
|
||||
)
|
||||
zones.append(zone)
|
||||
zone_annotators.append(zone_annotator)
|
||||
box_annotators.append(box_annotator)
|
||||
|
||||
return zones, zone_annotators, box_annotators
|
||||
|
||||
|
||||
def detect(
|
||||
frame: np.ndarray, model: RoboflowInferenceModel, confidence_threshold: float = 0.5
|
||||
) -> sv.Detections:
|
||||
"""
|
||||
Detect objects in a frame using Inference model, filtering detections by class ID
|
||||
and confidence threshold.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The frame to process, expected to be a NumPy array.
|
||||
model (RoboflowInferenceModel): The Inference model used for processing the
|
||||
frame.
|
||||
confidence_threshold (float, optional): The confidence threshold for filtering
|
||||
detections. Default is 0.5.
|
||||
|
||||
Returns:
|
||||
sv.Detections: Filtered detections after processing the frame with the Inference
|
||||
model.
|
||||
|
||||
Note:
|
||||
This function is specifically tailored for an Inference model and assumes class
|
||||
ID 0 for filtering.
|
||||
"""
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
filter_by_class = detections.class_id == 0
|
||||
filter_by_confidence = detections.confidence > confidence_threshold
|
||||
return detections[filter_by_class & filter_by_confidence]
|
||||
|
||||
|
||||
def annotate(
|
||||
frame: np.ndarray,
|
||||
zones: List[sv.PolygonZone],
|
||||
zone_annotators: List[sv.PolygonZoneAnnotator],
|
||||
box_annotators: List[sv.BoundingBoxAnnotator],
|
||||
detections: sv.Detections,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotate a frame with zone and box annotations based on given detections.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The original frame to be annotated.
|
||||
zones (List[sv.PolygonZone]): A list of polygon zones used for detection.
|
||||
zone_annotators (List[sv.PolygonZoneAnnotator]): A list of annotators for
|
||||
drawing zone annotations.
|
||||
box_annotators (List[sv.BoundingBoxAnnotator]): A list of annotators for
|
||||
drawing box annotations.
|
||||
detections (sv.Detections): Detections to be used for annotation.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated frame.
|
||||
"""
|
||||
annotated_frame = frame.copy()
|
||||
for zone, zone_annotator, box_annotator in zip(
|
||||
zones, zone_annotators, box_annotators
|
||||
):
|
||||
detections_in_zone = detections[zone.trigger(detections=detections)]
|
||||
annotated_frame = zone_annotator.annotate(scene=annotated_frame)
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections_in_zone
|
||||
)
|
||||
return annotated_frame
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Counting people in zones with Inference and Supervision"
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id",
|
||||
default="yolov8x-1280",
|
||||
help="Roboflow model ID",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--roboflow_api_key",
|
||||
default=None,
|
||||
help="Roboflow API KEY",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
default=None,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
help="IOU threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
api_key = args.roboflow_api_key
|
||||
api_key = os.environ.get("ROBOFLOW_API_KEY", api_key)
|
||||
if api_key is None:
|
||||
raise ValueError(
|
||||
"Roboflow API key is missing. Please provide it as an argument or set the "
|
||||
"ROBOFLOW_API_KEY environment variable."
|
||||
)
|
||||
args.roboflow_api_key = api_key
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(args.source_video_path)
|
||||
polygons = load_zones_config(args.zone_configuration_path)
|
||||
zones, zone_annotators, box_annotators = initiate_annotators(
|
||||
polygons=polygons, resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
|
||||
model = get_roboflow_model(model_id=args.model_id, api_key=args.roboflow_api_key)
|
||||
|
||||
frames_generator = sv.get_video_frames_generator(args.source_video_path)
|
||||
if args.target_video_path is not None:
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
sink.write_frame(annotated_frame)
|
||||
else:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
|
||||
cv2.destroyAllWindows()
|
||||
@@ -0,0 +1,5 @@
|
||||
gdown
|
||||
inference
|
||||
supervision
|
||||
tqdm
|
||||
ultralytics
|
||||
Executable
+14
@@ -0,0 +1,14 @@
|
||||
#!/bin/bash
|
||||
|
||||
# Get the directory where the script is located
|
||||
DIR="$( cd "$( dirname "${BASH_SOURCE[0]}" )" && pwd )"
|
||||
|
||||
# Check if 'data' directory does not exist and then create it
|
||||
if [[ ! -e $DIR/data ]]; then
|
||||
mkdir "$DIR/data"
|
||||
else
|
||||
echo "'data' directory already exists."
|
||||
fi
|
||||
|
||||
# Download the market-square.mp4 file from Google Drive
|
||||
gdown -O "$DIR/data/market-square.mp4" "https://drive.google.com/uc?id=1vVrEVMxucHgqGd7vAa501ASojbeGPhIr"
|
||||
@@ -0,0 +1,206 @@
|
||||
import argparse
|
||||
import json
|
||||
from typing import List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from tqdm import tqdm
|
||||
from ultralytics import YOLO
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.default()
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
This function reads a JSON file which contains polygon coordinates, and
|
||||
converts them into a list of NumPy arrays. Each polygon is represented as
|
||||
a NumPy array of coordinates.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the JSON configuration file.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data["polygons"]]
|
||||
|
||||
|
||||
def initiate_annotators(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> Tuple[
|
||||
List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator]
|
||||
]:
|
||||
line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
zones = []
|
||||
zone_annotators = []
|
||||
box_annotators = []
|
||||
|
||||
for index, polygon in enumerate(polygons):
|
||||
zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh)
|
||||
zone_annotator = sv.PolygonZoneAnnotator(
|
||||
zone=zone,
|
||||
color=COLORS.by_idx(index),
|
||||
thickness=line_thickness,
|
||||
text_thickness=line_thickness * 2,
|
||||
text_scale=text_scale * 2,
|
||||
)
|
||||
box_annotator = sv.BoundingBoxAnnotator(
|
||||
color=COLORS.by_idx(index), thickness=line_thickness
|
||||
)
|
||||
zones.append(zone)
|
||||
zone_annotators.append(zone_annotator)
|
||||
box_annotators.append(box_annotator)
|
||||
|
||||
return zones, zone_annotators, box_annotators
|
||||
|
||||
|
||||
def detect(
|
||||
frame: np.ndarray, model: YOLO, confidence_threshold: float = 0.5
|
||||
) -> sv.Detections:
|
||||
"""
|
||||
Detect objects in a frame using a YOLO model, filtering detections by class ID and
|
||||
confidence threshold.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The frame to process, expected to be a NumPy array.
|
||||
model (YOLO): The YOLO model used for processing the frame.
|
||||
confidence_threshold (float, optional): The confidence threshold for filtering
|
||||
detections. Default is 0.5.
|
||||
|
||||
Returns:
|
||||
sv.Detections: Filtered detections after processing the frame with the YOLO
|
||||
model.
|
||||
|
||||
Note:
|
||||
This function is specifically tailored for a YOLO model and assumes class ID 0
|
||||
for filtering.
|
||||
"""
|
||||
results = model(frame, imgsz=1280, verbose=False)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
filter_by_class = detections.class_id == 0
|
||||
filter_by_confidence = detections.confidence > confidence_threshold
|
||||
return detections[filter_by_class & filter_by_confidence]
|
||||
|
||||
|
||||
def annotate(
|
||||
frame: np.ndarray,
|
||||
zones: List[sv.PolygonZone],
|
||||
zone_annotators: List[sv.PolygonZoneAnnotator],
|
||||
box_annotators: List[sv.BoundingBoxAnnotator],
|
||||
detections: sv.Detections,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotate a frame with zone and box annotations based on given detections.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The original frame to be annotated.
|
||||
zones (List[sv.PolygonZone]): A list of polygon zones used for detection.
|
||||
zone_annotators (List[sv.PolygonZoneAnnotator]): A list of annotators for
|
||||
drawing zone annotations.
|
||||
box_annotators (List[sv.BoundingBoxAnnotator]): A list of annotators for
|
||||
drawing box annotations.
|
||||
detections (sv.Detections): Detections to be used for annotation.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated frame.
|
||||
"""
|
||||
annotated_frame = frame.copy()
|
||||
for zone, zone_annotator, box_annotator in zip(
|
||||
zones, zone_annotators, box_annotators
|
||||
):
|
||||
detections_in_zone = detections[zone.trigger(detections=detections)]
|
||||
annotated_frame = zone_annotator.annotate(scene=annotated_frame)
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections_in_zone
|
||||
)
|
||||
return annotated_frame
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Counting people in zones with YOLO and Supervision"
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_weights_path",
|
||||
default="yolov8x.pt",
|
||||
help="Path to the source weights file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
default=None,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
help="IOU threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(args.source_video_path)
|
||||
polygons = load_zones_config(args.zone_configuration_path)
|
||||
zones, zone_annotators, box_annotators = initiate_annotators(
|
||||
polygons=polygons, resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
|
||||
model = YOLO(args.source_weights_path)
|
||||
|
||||
frames_generator = sv.get_video_frames_generator(args.source_video_path)
|
||||
if args.target_video_path is not None:
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
sink.write_frame(annotated_frame)
|
||||
else:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
|
||||
cv2.destroyAllWindows()
|
||||
@@ -0,0 +1,75 @@
|
||||
# heatmap and tracking
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This script performs heatmap and tracking analysis using YOLOv8, an object-detection method and
|
||||
ByteTrack, a simple yet effective online multi-object tracking method. It uses the
|
||||
supervision package for multiple tasks such as drawing heatmap annotations, tracking objects, etc.
|
||||
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/heatmap_and_track
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the weights file for the
|
||||
YOLO model. This file contains the trained model data necessary for object detection.
|
||||
- `--source_video_path` (optional): The path to the source video file that will be
|
||||
analyzed. This is the input video on which crowd analysis will be performed.
|
||||
If not specified default is `people-walking.mp4` from supervision assets
|
||||
- `--target_video_path` (optional): The path to save the output.mp4 video with annotations.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`. This determines how confident the model should
|
||||
be to recognize an object in the video.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection accuracy,
|
||||
particularly in distinguishing between different objects.
|
||||
- `--heatmap_alpha` (optional): Opacity of the overlay mask, between 0 and 1.
|
||||
- `--radius` (optional): Radius of the heat circle.
|
||||
- `--track_threshold` (optional): Detection confidence threshold for track activation.
|
||||
- `--track_seconds` (optional): Number of seconds to buffer when a track is lost.
|
||||
- `--match_threshold` (optional): Threshold for matching tracks with detections.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
```bash
|
||||
python script.py \
|
||||
--source_weights_path weight.pt \
|
||||
--source_video_path input_video.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5 \
|
||||
--target_video_path output_video.mp4
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
@@ -0,0 +1,2 @@
|
||||
supervision[assets]
|
||||
ultralytics
|
||||
@@ -0,0 +1,181 @@
|
||||
import argparse
|
||||
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
|
||||
import supervision as sv
|
||||
from supervision.assets import VideoAssets, download_assets
|
||||
|
||||
|
||||
def download_video() -> str:
|
||||
download_assets(VideoAssets.PEOPLE_WALKING)
|
||||
return VideoAssets.PEOPLE_WALKING.value
|
||||
|
||||
|
||||
def heatmap_and_track(
|
||||
source_weights_path: str,
|
||||
source_video_path: str,
|
||||
target_video_path: str,
|
||||
confidence_threshold: float = 0.35,
|
||||
iou_threshold: float = 0.5,
|
||||
heatmap_alpha: float = 0.5,
|
||||
radius: int = 25,
|
||||
track_threshold: float = 0.35,
|
||||
track_seconds: int = 5,
|
||||
match_threshold: float = 0.99,
|
||||
) -> None:
|
||||
### instantiate model
|
||||
model = YOLO(source_weights_path)
|
||||
|
||||
### heatmap config
|
||||
heat_map_annotator = sv.HeatMapAnnotator(
|
||||
position=sv.Position.BOTTOM_CENTER,
|
||||
opacity=heatmap_alpha,
|
||||
radius=radius,
|
||||
kernel_size=25,
|
||||
top_hue=0,
|
||||
low_hue=125,
|
||||
)
|
||||
|
||||
### annotation config
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
|
||||
### get the video fps
|
||||
cap = cv2.VideoCapture(source_video_path)
|
||||
fps = int(cap.get(cv2.CAP_PROP_FPS))
|
||||
cap.release()
|
||||
|
||||
### tracker config
|
||||
byte_tracker = sv.ByteTrack(
|
||||
track_thresh=track_threshold,
|
||||
track_buffer=track_seconds * fps,
|
||||
match_thresh=match_threshold,
|
||||
frame_rate=fps,
|
||||
)
|
||||
|
||||
### video config
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(
|
||||
source_path=source_video_path, stride=1
|
||||
)
|
||||
|
||||
### Detect, track, annotate, save
|
||||
with sv.VideoSink(target_path=target_video_path, video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(
|
||||
source=frame,
|
||||
classes=[0], # only person class
|
||||
conf=confidence_threshold,
|
||||
iou=iou_threshold,
|
||||
# show_conf = True,
|
||||
# save_txt = True,
|
||||
# save_conf = True,
|
||||
# save = True,
|
||||
device=None, # use None = CPU, 0 = single GPU, or [0,1] = dual GPU
|
||||
)[0]
|
||||
|
||||
detections = sv.Detections.from_ultralytics(result) # get detections
|
||||
|
||||
detections = byte_tracker.update_with_detections(
|
||||
detections
|
||||
) # update tracker
|
||||
|
||||
### draw heatmap
|
||||
annotated_frame = heat_map_annotator.annotate(
|
||||
scene=frame.copy(), detections=detections
|
||||
)
|
||||
|
||||
### draw other attributes from `detections` object
|
||||
labels = [
|
||||
f"#{tracker_id}"
|
||||
for class_id, tracker_id in zip(
|
||||
detections.class_id, detections.tracker_id
|
||||
)
|
||||
]
|
||||
|
||||
label_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections, labels=labels
|
||||
)
|
||||
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Heatmap and Tracking with Supervision"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_weights_path",
|
||||
required=True,
|
||||
help="Path to the source weights file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
default=download_video(),
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
default="output.mp4",
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.35,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.5,
|
||||
help="IOU threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--heatmap_alpha",
|
||||
default=0.5,
|
||||
help="Opacity of the overlay mask, between 0 and 1",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--radius",
|
||||
default=25,
|
||||
help="Radius of the heat circle",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--track_threshold",
|
||||
default=0.35,
|
||||
help="Detection confidence threshold for track activation",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--track_seconds",
|
||||
default=5,
|
||||
help="Number of seconds to buffer when a track is lost",
|
||||
type=int,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--match_threshold",
|
||||
default=0.99,
|
||||
help="Threshold for matching tracks with detections",
|
||||
type=float,
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
heatmap_and_track(
|
||||
source_weights_path=args.source_weights_path,
|
||||
source_video_path=args.source_video_path,
|
||||
target_video_path=args.target_video_path,
|
||||
confidence_threshold=args.confidence_threshold,
|
||||
iou_threshold=args.iou_threshold,
|
||||
heatmap_alpha=args.heatmap_alpha,
|
||||
radius=args.radius,
|
||||
track_threshold=args.track_threshold,
|
||||
track_seconds=args.track_seconds,
|
||||
match_threshold=args.match_threshold,
|
||||
)
|
||||
+92
-11
@@ -1,3 +1,5 @@
|
||||
# tracking
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This script provides functionality for processing videos using YOLOv8 for object
|
||||
@@ -5,16 +7,95 @@ detection and Supervision for tracking and annotation.
|
||||
|
||||
## 💻 install
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
## ⚙️ parameters
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/tracking
|
||||
```
|
||||
|
||||
| parameter | required | description |
|
||||
|:-------------------------|:--------:|:----------------------------------------------------------------------------------|
|
||||
| `--source_weights_path` | ✓ | Path to the source weights file for YOLOv8. |
|
||||
| `--source_video_path` | ✓ | Path to the source video file to be processed. |
|
||||
| `--target_video_path` | ✓ | Path to the target video file (output). |
|
||||
| `--confidence_threshold` | ✗ | Confidence threshold for YOLO model detection. Default is 0.3. |
|
||||
| `--iou_threshold` | ✗ | IOU (Intersection over Union) threshold for YOLO model detection. Default is 0.7. |
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- ultralytics
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights
|
||||
file, which is essential for the object detection process. This file contains the data
|
||||
that the model uses to identify objects in the video.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file to be processed.
|
||||
This is the video on which object detection and annotation will be performed.
|
||||
- `--target_video_path`: Required. The path where the processed video, with annotations
|
||||
added, will be saved. This is your output video file.
|
||||
- `--confidence_threshold` (optional): Sets the confidence level at which the model
|
||||
identifies objects in the video. Default is `0.3`. A higher threshold makes the model
|
||||
more selective, while a lower threshold makes it more inclusive in identifying objects.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model, defaulting to `0.7`. This parameter helps in differentiating between
|
||||
distinct objects, especially in crowded scenes.
|
||||
|
||||
- inference
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"yolov8x-1280"`.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file to be processed.
|
||||
This is the video on which object detection and annotation will be performed.
|
||||
- `--target_video_path`: Required. The path where the processed video, with annotations
|
||||
added, will be saved. This is your output video file.
|
||||
- `--confidence_threshold` (optional): Sets the confidence level at which the model
|
||||
identifies objects in the video. Default is `0.3`. A higher threshold makes the model
|
||||
more selective, while a lower threshold makes it more inclusive in identifying objects.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model, defaulting to `0.7`. This parameter helps in differentiating between
|
||||
distinct objects, especially in crowded scenes.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
- inference
|
||||
|
||||
```bash
|
||||
python inference_example.py \
|
||||
--roboflow_api_key <ROBOFLOW API KEY> \
|
||||
--source_video_path input.mp4 \
|
||||
--target_video_path tracking_result.mp4
|
||||
```
|
||||
|
||||
- ultralytics
|
||||
|
||||
```bash
|
||||
python ultralytics_example.py \
|
||||
--source_weights_path yolov8s.pt \
|
||||
--source_video_path input.mp4 \
|
||||
--target_video_path tracking_result.mp4
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
|
||||
@@ -0,0 +1,101 @@
|
||||
import argparse
|
||||
import os
|
||||
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from tqdm import tqdm
|
||||
|
||||
import supervision as sv
|
||||
|
||||
|
||||
def process_video(
|
||||
roboflow_api_key: str,
|
||||
model_id: str,
|
||||
source_video_path: str,
|
||||
target_video_path: str,
|
||||
confidence_threshold: float = 0.3,
|
||||
iou_threshold: float = 0.7,
|
||||
) -> None:
|
||||
model = get_roboflow_model(model_id=model_id, api_key=roboflow_api_key)
|
||||
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
frame_generator = sv.get_video_frames_generator(source_path=source_video_path)
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
|
||||
with sv.VideoSink(target_path=target_video_path, video_info=video_info) as sink:
|
||||
for frame in tqdm(frame_generator, total=video_info.total_frames):
|
||||
results = model.infer(
|
||||
frame, confidence=confidence_threshold, iou_threshold=iou_threshold
|
||||
)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=frame.copy(), detections=detections
|
||||
)
|
||||
|
||||
annotated_labeled_frame = label_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
|
||||
sink.write_frame(frame=annotated_labeled_frame)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Video Processing with Inference and ByteTrack"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id",
|
||||
default="yolov8x-1280",
|
||||
help="Roboflow model ID",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
required=True,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold", default=0.7, help="IOU threshold for the model", type=float
|
||||
)
|
||||
parser.add_argument(
|
||||
"--roboflow_api_key",
|
||||
default=None,
|
||||
help="Roboflow API key",
|
||||
type=str,
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
api_key = args.roboflow_api_key
|
||||
api_key = os.environ.get("ROBOFLOW_API_KEY", api_key)
|
||||
if api_key is None:
|
||||
raise ValueError(
|
||||
"Roboflow API key is missing. Please provide it as an argument or set the "
|
||||
"ROBOFLOW_API_KEY environment variable."
|
||||
)
|
||||
args.roboflow_api_key = api_key
|
||||
|
||||
process_video(
|
||||
roboflow_api_key=args.roboflow_api_key,
|
||||
model_id=args.model_id,
|
||||
source_video_path=args.source_video_path,
|
||||
target_video_path=args.target_video_path,
|
||||
confidence_threshold=args.confidence_threshold,
|
||||
iou_threshold=args.iou_threshold,
|
||||
)
|
||||
@@ -1,3 +1,4 @@
|
||||
inference
|
||||
supervision
|
||||
tqdm
|
||||
ultralytics
|
||||
|
||||
@@ -17,7 +17,7 @@ def process_video(
|
||||
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(classes=model.names)
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
frame_generator = sv.get_video_frames_generator(source_path=source_video_path)
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
|
||||
@@ -1,6 +1,10 @@
|
||||
# traffic analysis
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This script performs traffic flow analysis using YOLOv8, an object-detection method and ByteTrack, a simple yet effective online multi-object tracking method. It uses the supervision package for multiple tasks such as tracking, annotations, etc.
|
||||
This script performs traffic flow analysis using YOLOv8, an object-detection method and
|
||||
ByteTrack, a simple yet effective online multi-object tracking method. It uses the
|
||||
supervision package for multiple tasks such as tracking, annotations, etc.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-60e9c81b3900
|
||||
|
||||
@@ -8,37 +12,105 @@ https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/traffic_analysis
|
||||
```
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/traffic_analysis
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
- download `traffic_analysis.pt` and `traffic_analysis.mov` files
|
||||
|
||||
```bash
|
||||
./setup.sh
|
||||
```
|
||||
```bash
|
||||
./setup.sh
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- ultralytics
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights
|
||||
file, which is essential for the object detection process. This file contains the
|
||||
data that the model uses to identify objects in the video.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file that will be
|
||||
analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
- `--target_video_path` (optional): The path to save the output video with
|
||||
annotations. If not specified, the processed video will be displayed in real-time
|
||||
without being saved.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO
|
||||
model to filter detections. Default is `0.3`. This determines how confident the
|
||||
model should be to recognize an object in the video.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection
|
||||
accuracy, particularly in distinguishing between different objects.
|
||||
|
||||
- inference
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"vehicle-count-in-drone-video/6"`.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file that will be
|
||||
analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
- `--target_video_path` (optional): The path to save the output video with
|
||||
annotations. If not specified, the processed video will be displayed in real-time
|
||||
without being saved.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO
|
||||
model to filter detections. Default is `0.3`. This determines how confident the
|
||||
model should be to recognize an object in the video.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection
|
||||
accuracy, particularly in distinguishing between different objects.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
```bash
|
||||
python script.py \
|
||||
--source_weights_path data/traffic_analysis.pt \
|
||||
--source_video_path data/traffic_analysis.mov \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5 \
|
||||
--target_video_path data/traffic_analysis_result.mov
|
||||
```
|
||||
- ultralytics
|
||||
|
||||
```bash
|
||||
python ultralytics_example.py \
|
||||
--source_weights_path data/traffic_analysis.pt \
|
||||
--source_video_path data/traffic_analysis.mov \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5 \
|
||||
--target_video_path data/traffic_analysis_result.mov
|
||||
```
|
||||
|
||||
- inference
|
||||
|
||||
```bash
|
||||
python inference_example.py \
|
||||
--roboflow_api_key <ROBOFLOW API KEY> \
|
||||
--source_video_path data/traffic_analysis.mov \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5 \
|
||||
--target_video_path data/traffic_analysis_result.mov
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
|
||||
@@ -0,0 +1,238 @@
|
||||
import argparse
|
||||
import os
|
||||
from typing import Dict, List, Set, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from tqdm import tqdm
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.default()
|
||||
|
||||
ZONE_IN_POLYGONS = [
|
||||
np.array([[592, 282], [900, 282], [900, 82], [592, 82]]),
|
||||
np.array([[950, 860], [1250, 860], [1250, 1060], [950, 1060]]),
|
||||
np.array([[592, 582], [592, 860], [392, 860], [392, 582]]),
|
||||
np.array([[1250, 282], [1250, 530], [1450, 530], [1450, 282]]),
|
||||
]
|
||||
|
||||
ZONE_OUT_POLYGONS = [
|
||||
np.array([[950, 282], [1250, 282], [1250, 82], [950, 82]]),
|
||||
np.array([[592, 860], [900, 860], [900, 1060], [592, 1060]]),
|
||||
np.array([[592, 282], [592, 550], [392, 550], [392, 282]]),
|
||||
np.array([[1250, 860], [1250, 560], [1450, 560], [1450, 860]]),
|
||||
]
|
||||
|
||||
|
||||
class DetectionsManager:
|
||||
def __init__(self) -> None:
|
||||
self.tracker_id_to_zone_id: Dict[int, int] = {}
|
||||
self.counts: Dict[int, Dict[int, Set[int]]] = {}
|
||||
|
||||
def update(
|
||||
self,
|
||||
detections_all: sv.Detections,
|
||||
detections_in_zones: List[sv.Detections],
|
||||
detections_out_zones: List[sv.Detections],
|
||||
) -> sv.Detections:
|
||||
for zone_in_id, detections_in_zone in enumerate(detections_in_zones):
|
||||
for tracker_id in detections_in_zone.tracker_id:
|
||||
self.tracker_id_to_zone_id.setdefault(tracker_id, zone_in_id)
|
||||
|
||||
for zone_out_id, detections_out_zone in enumerate(detections_out_zones):
|
||||
for tracker_id in detections_out_zone.tracker_id:
|
||||
if tracker_id in self.tracker_id_to_zone_id:
|
||||
zone_in_id = self.tracker_id_to_zone_id[tracker_id]
|
||||
self.counts.setdefault(zone_out_id, {})
|
||||
self.counts[zone_out_id].setdefault(zone_in_id, set())
|
||||
self.counts[zone_out_id][zone_in_id].add(tracker_id)
|
||||
|
||||
detections_all.class_id = np.vectorize(
|
||||
lambda x: self.tracker_id_to_zone_id.get(x, -1)
|
||||
)(detections_all.tracker_id)
|
||||
return detections_all[detections_all.class_id != -1]
|
||||
|
||||
|
||||
def initiate_polygon_zones(
|
||||
polygons: List[np.ndarray],
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
triggering_position: sv.Position = sv.Position.CENTER,
|
||||
) -> List[sv.PolygonZone]:
|
||||
return [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=frame_resolution_wh,
|
||||
triggering_position=triggering_position,
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
|
||||
|
||||
class VideoProcessor:
|
||||
def __init__(
|
||||
self,
|
||||
roboflow_api_key: str,
|
||||
model_id: str,
|
||||
source_video_path: str,
|
||||
target_video_path: str = None,
|
||||
confidence_threshold: float = 0.3,
|
||||
iou_threshold: float = 0.7,
|
||||
) -> None:
|
||||
self.conf_threshold = confidence_threshold
|
||||
self.iou_threshold = iou_threshold
|
||||
self.source_video_path = source_video_path
|
||||
self.target_video_path = target_video_path
|
||||
|
||||
self.model = get_roboflow_model(model_id=model_id, api_key=roboflow_api_key)
|
||||
self.tracker = sv.ByteTrack()
|
||||
|
||||
self.video_info = sv.VideoInfo.from_video_path(source_video_path)
|
||||
self.zones_in = initiate_polygon_zones(
|
||||
ZONE_IN_POLYGONS, self.video_info.resolution_wh, sv.Position.CENTER
|
||||
)
|
||||
self.zones_out = initiate_polygon_zones(
|
||||
ZONE_OUT_POLYGONS, self.video_info.resolution_wh, sv.Position.CENTER
|
||||
)
|
||||
|
||||
self.box_annotator = sv.BoxAnnotator(color=COLORS)
|
||||
self.trace_annotator = sv.TraceAnnotator(
|
||||
color=COLORS, position=sv.Position.CENTER, trace_length=100, thickness=2
|
||||
)
|
||||
self.detections_manager = DetectionsManager()
|
||||
|
||||
def process_video(self):
|
||||
frame_generator = sv.get_video_frames_generator(
|
||||
source_path=self.source_video_path
|
||||
)
|
||||
|
||||
if self.target_video_path:
|
||||
with sv.VideoSink(self.target_video_path, self.video_info) as sink:
|
||||
for frame in tqdm(frame_generator, total=self.video_info.total_frames):
|
||||
annotated_frame = self.process_frame(frame)
|
||||
sink.write_frame(annotated_frame)
|
||||
else:
|
||||
for frame in tqdm(frame_generator, total=self.video_info.total_frames):
|
||||
annotated_frame = self.process_frame(frame)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
def annotate_frame(
|
||||
self, frame: np.ndarray, detections: sv.Detections
|
||||
) -> np.ndarray:
|
||||
annotated_frame = frame.copy()
|
||||
for i, (zone_in, zone_out) in enumerate(zip(self.zones_in, self.zones_out)):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
annotated_frame, zone_in.polygon, COLORS.colors[i]
|
||||
)
|
||||
annotated_frame = sv.draw_polygon(
|
||||
annotated_frame, zone_out.polygon, COLORS.colors[i]
|
||||
)
|
||||
|
||||
labels = [f"#{tracker_id}" for tracker_id in detections.tracker_id]
|
||||
annotated_frame = self.trace_annotator.annotate(annotated_frame, detections)
|
||||
annotated_frame = self.box_annotator.annotate(
|
||||
annotated_frame, detections, labels
|
||||
)
|
||||
|
||||
for zone_out_id, zone_out in enumerate(self.zones_out):
|
||||
zone_center = sv.get_polygon_center(polygon=zone_out.polygon)
|
||||
if zone_out_id in self.detections_manager.counts:
|
||||
counts = self.detections_manager.counts[zone_out_id]
|
||||
for i, zone_in_id in enumerate(counts):
|
||||
count = len(self.detections_manager.counts[zone_out_id][zone_in_id])
|
||||
text_anchor = sv.Point(x=zone_center.x, y=zone_center.y + 40 * i)
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=str(count),
|
||||
text_anchor=text_anchor,
|
||||
background_color=COLORS.colors[zone_in_id],
|
||||
)
|
||||
|
||||
return annotated_frame
|
||||
|
||||
def process_frame(self, frame: np.ndarray) -> np.ndarray:
|
||||
results = self.model.infer(
|
||||
frame, confidence=self.conf_threshold, iou_threshold=self.iou_threshold
|
||||
)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections.class_id = np.zeros(len(detections))
|
||||
detections = self.tracker.update_with_detections(detections)
|
||||
|
||||
detections_in_zones = []
|
||||
detections_out_zones = []
|
||||
|
||||
for i, (zone_in, zone_out) in enumerate(zip(self.zones_in, self.zones_out)):
|
||||
detections_in_zone = detections[zone_in.trigger(detections=detections)]
|
||||
detections_in_zones.append(detections_in_zone)
|
||||
detections_out_zone = detections[zone_out.trigger(detections=detections)]
|
||||
detections_out_zones.append(detections_out_zone)
|
||||
|
||||
detections = self.detections_manager.update(
|
||||
detections, detections_in_zones, detections_out_zones
|
||||
)
|
||||
return self.annotate_frame(frame, detections)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Traffic Flow Analysis with Inference and ByteTrack"
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--model_id",
|
||||
default="vehicle-count-in-drone-video/6",
|
||||
help="Roboflow model ID",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--roboflow_api_key",
|
||||
default=None,
|
||||
help="Roboflow API KEY",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
default=None,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold", default=0.7, help="IOU threshold for the model", type=float
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
api_key = args.roboflow_api_key
|
||||
api_key = os.environ.get("ROBOFLOW_API_KEY", api_key)
|
||||
if api_key is None:
|
||||
raise ValueError(
|
||||
"Roboflow API KEY is missing. Please provide it as an argument or set the "
|
||||
"ROBOFLOW_API_KEY environment variable."
|
||||
)
|
||||
args.roboflow_api_key = api_key
|
||||
|
||||
processor = VideoProcessor(
|
||||
roboflow_api_key=args.roboflow_api_key,
|
||||
model_id=args.model_id,
|
||||
source_video_path=args.source_video_path,
|
||||
target_video_path=args.target_video_path,
|
||||
confidence_threshold=args.confidence_threshold,
|
||||
iou_threshold=args.iou_threshold,
|
||||
)
|
||||
processor.process_video()
|
||||
@@ -1,4 +1,5 @@
|
||||
supervision>=0.15.0rc1
|
||||
gdown
|
||||
inference
|
||||
supervision
|
||||
tqdm
|
||||
ultralytics
|
||||
gdown
|
||||
|
||||
+11
-3
@@ -1,7 +1,7 @@
|
||||
site_name: Supervision
|
||||
site_url: https://supervision.roboflow.com/
|
||||
site_author: Roboflow
|
||||
site_description: A set of easy-to-use utils that will come in handy in any Computer Vision project
|
||||
site_description: A set of easy-to-use utilities that will come in handy in any computer vision project.
|
||||
repo_name: roboflow/supervision
|
||||
repo_url: https://github.com/roboflow/supervision
|
||||
edit_uri: https://github.com/roboflow/supervision/tree/main/docs
|
||||
@@ -55,12 +55,14 @@ nav:
|
||||
- Image: utils/image.md
|
||||
- Notebook: utils/notebook.md
|
||||
- File: utils/file.md
|
||||
- Assets: assets.md
|
||||
- Changelog: changelog.md
|
||||
|
||||
theme:
|
||||
name: 'material'
|
||||
logo: https://media.roboflow.com/open-source/supervision/supervision-lenny.png
|
||||
favicon: https://media.roboflow.com/open-source/supervision/supervision-lenny.png
|
||||
logo: assets/supervision-lenny.png
|
||||
favicon: assets/supervision-lenny.png
|
||||
custom_dir: docs/theme
|
||||
palette:
|
||||
# Palette for light mode
|
||||
- scheme: default
|
||||
@@ -78,6 +80,8 @@ theme:
|
||||
font:
|
||||
text: Roboto
|
||||
code: Roboto Mono
|
||||
features:
|
||||
- content.code.copy
|
||||
|
||||
plugins:
|
||||
- mkdocstrings
|
||||
@@ -93,3 +97,7 @@ markdown_extensions:
|
||||
alternate_style: true
|
||||
- toc:
|
||||
permalink: true
|
||||
|
||||
extra_javascript:
|
||||
- "https://widget.kapa.ai/kapa-widget.bundle.js"
|
||||
- "javascript/init_kapa_widget.js"
|
||||
|
||||
Generated
+1586
-1281
File diff suppressed because it is too large
Load Diff
+40
-36
@@ -1,6 +1,6 @@
|
||||
[tool.poetry]
|
||||
name = "supervision"
|
||||
version = "0.16.0"
|
||||
version = "0.18.0rc1"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
authors = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
maintainers = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
@@ -10,7 +10,7 @@ packages = [{include = "supervision"}]
|
||||
homepage = "https://github.com/roboflow/supervision"
|
||||
repository = "https://github.com/roboflow/supervision"
|
||||
documentation = "https://github.com/roboflow/supervision/blob/main/README.md"
|
||||
keywords = ["machine-learning", "deep-learning", "vision", "ML", "DL", "AI", "YOLOv5", "YOLOv8", "Roboflow"]
|
||||
keywords = ["machine-learning", "deep-learning", "vision", "ML", "DL", "AI", "Roboflow"]
|
||||
|
||||
classifiers=[
|
||||
'Development Status :: 4 - Beta',
|
||||
@@ -19,10 +19,6 @@ classifiers=[
|
||||
'Intended Audience :: Science/Research',
|
||||
'License :: OSI Approved :: MIT License',
|
||||
'Programming Language :: Python :: 3',
|
||||
'Programming Language :: Python :: 3.8',
|
||||
'Programming Language :: Python :: 3.9',
|
||||
'Programming Language :: Python :: 3.10',
|
||||
'Programming Language :: Python :: 3.11',
|
||||
'Programming Language :: Python :: 3 :: Only',
|
||||
'Topic :: Software Development',
|
||||
'Topic :: Scientific/Engineering',
|
||||
@@ -35,51 +31,40 @@ classifiers=[
|
||||
]
|
||||
|
||||
[tool.poetry.dependencies]
|
||||
python = ">=3.8,<3.12.0"
|
||||
numpy = "^1.20.0"
|
||||
matplotlib = "^3.7.1"
|
||||
pyyaml = "^6.0"
|
||||
pillow = ">=9.4,<11.0"
|
||||
opencv-python = { version = "^4.8.0.74", optional = true }
|
||||
opencv-python-headless = "^4.8.0.74"
|
||||
scipy = "^1.9.0"
|
||||
python = "^3.8"
|
||||
numpy = ">=1.21.2"
|
||||
scipy = ">=1.9.0"
|
||||
matplotlib = ">=3.5.0"
|
||||
pyyaml = ">=5.3"
|
||||
pillow = ">=9.4"
|
||||
opencv-python = { version = ">=4.5.5.64,<=4.8.1.78", optional = true }
|
||||
opencv-python-headless = ">=4.5.5.64,<=4.8.1.78"
|
||||
requests = { version = ">=2.26.0,<=2.31.0", optional = true }
|
||||
tqdm = { version = ">=4.62.3,<=4.66.1", optional = true }
|
||||
defusedxml = "^0.7.1"
|
||||
|
||||
|
||||
[tool.poetry.extras]
|
||||
desktop = ["opencv-python"]
|
||||
|
||||
assets = ["requests","tqdm"]
|
||||
|
||||
[tool.poetry.group.dev.dependencies]
|
||||
twine = "^4.0.2"
|
||||
pytest = "^7.2.2"
|
||||
wheel = "^0.40.0"
|
||||
notebook = "^6.5.3"
|
||||
build = "^0.10.0"
|
||||
ruff = "^0.0.280"
|
||||
wheel = ">=0.40,<0.43"
|
||||
notebook = ">=6.5.3,<8.0.0"
|
||||
build = ">=0.10,<1.1"
|
||||
ruff = ">=0.0.280,<0.1.12"
|
||||
isort = "^5.12.0"
|
||||
black = "^23.7.0"
|
||||
mypy = "^1.4.1"
|
||||
pre-commit = "^3.3.3"
|
||||
flake8 = { version = "*", python = ">=3.8.1,<3.12.0" }
|
||||
tox = "^4.11.4"
|
||||
|
||||
|
||||
[tool.poetry.group.docs.dependencies]
|
||||
mkdocs-material = "^9.1.4"
|
||||
mkdocstrings = {extras = ["python"], version = "^0.20.0"}
|
||||
mkdocstrings = {extras = ["python"], version = ">=0.20,<0.25"}
|
||||
|
||||
[tool.flake8]
|
||||
exclude = ".venv"
|
||||
max-complexity = 10
|
||||
max-line-length = 88
|
||||
extend-ignore = """
|
||||
W503,
|
||||
E203,
|
||||
E701,
|
||||
C901,
|
||||
"""
|
||||
per-file-ignores = """
|
||||
__init__.py: F401
|
||||
"""
|
||||
|
||||
[tool.isort]
|
||||
line_length = 88
|
||||
@@ -87,7 +72,7 @@ profile = "black"
|
||||
|
||||
[tool.bandit]
|
||||
target = ["test", "supervision"]
|
||||
tests = ["B201", "B301"]
|
||||
tests = ["B201", "B301", "B318", "B314", "B303", "B413", "B412", "B410"]
|
||||
|
||||
[tool.autoflake]
|
||||
check = true
|
||||
@@ -153,6 +138,7 @@ exclude = [
|
||||
|
||||
# Same as Black.
|
||||
line-length = 88
|
||||
indent-width = 4
|
||||
|
||||
# Allow unused variables when underscore-prefixed.
|
||||
dummy-variable-rgx = "^(_+|(_+[a-zA-Z0-9_]*[a-zA-Z0-9]+?))$"
|
||||
@@ -167,10 +153,28 @@ convention = "google"
|
||||
|
||||
[tool.ruff.per-file-ignores]
|
||||
"__init__.py" = ["E402","F401"]
|
||||
"supervision/assets/list.py" = ["E501"]
|
||||
|
||||
[tool.ruff.lint.mccabe]
|
||||
# Flag errors (`C901`) whenever the complexity level exceeds 5.
|
||||
max-complexity = 20
|
||||
|
||||
|
||||
[tool.ruff.pylint]
|
||||
max-args = 20
|
||||
|
||||
[tool.ruff.format]
|
||||
# Like Black, use double quotes for strings.
|
||||
quote-style = "double"
|
||||
|
||||
# Like Black, indent with spaces, rather than tabs.
|
||||
indent-style = "space"
|
||||
|
||||
# Like Black, respect magic trailing commas.
|
||||
skip-magic-trailing-comma = false
|
||||
|
||||
# Like Black, automatically detect the appropriate line ending.
|
||||
line-ending = "auto"
|
||||
|
||||
[tool.setuptools]
|
||||
include-package-data = false
|
||||
|
||||
@@ -10,15 +10,18 @@ from supervision.annotators.core import (
|
||||
BlurAnnotator,
|
||||
BoundingBoxAnnotator,
|
||||
BoxCornerAnnotator,
|
||||
BoxMaskAnnotator,
|
||||
CircleAnnotator,
|
||||
ColorAnnotator,
|
||||
DotAnnotator,
|
||||
EllipseAnnotator,
|
||||
HaloAnnotator,
|
||||
HeatMapAnnotator,
|
||||
LabelAnnotator,
|
||||
MaskAnnotator,
|
||||
PixelateAnnotator,
|
||||
PolygonAnnotator,
|
||||
TraceAnnotator,
|
||||
TriangleAnnotator,
|
||||
)
|
||||
from supervision.annotators.utils import ColorLookup
|
||||
from supervision.classification.core import Classifications
|
||||
@@ -34,15 +37,20 @@ from supervision.detection.tools.inference_slicer import InferenceSlicer
|
||||
from supervision.detection.tools.polygon_zone import PolygonZone, PolygonZoneAnnotator
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
calculate_masks_centroids,
|
||||
filter_polygons_by_area,
|
||||
mask_to_polygons,
|
||||
mask_to_xyxy,
|
||||
move_boxes,
|
||||
non_max_suppression,
|
||||
polygon_to_mask,
|
||||
polygon_to_xyxy,
|
||||
scale_boxes,
|
||||
)
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import (
|
||||
calculate_dynamic_line_thickness,
|
||||
calculate_dynamic_text_scale,
|
||||
draw_filled_rectangle,
|
||||
draw_image,
|
||||
draw_line,
|
||||
|
||||
+345
-77
@@ -6,8 +6,11 @@ import numpy as np
|
||||
|
||||
from supervision.annotators.base import BaseAnnotator
|
||||
from supervision.annotators.utils import ColorLookup, Trace, resolve_color
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import clip_boxes, mask_to_polygons
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import draw_polygon
|
||||
from supervision.geometry.core import Position
|
||||
|
||||
|
||||
@@ -28,7 +31,7 @@ class BoundingBoxAnnotator(BaseAnnotator):
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the bounding box lines.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACE`.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.thickness: int = thickness
|
||||
@@ -50,7 +53,7 @@ class BoundingBoxAnnotator(BaseAnnotator):
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated image.
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -92,6 +95,10 @@ class BoundingBoxAnnotator(BaseAnnotator):
|
||||
class MaskAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing masks on an image using provided detections.
|
||||
|
||||
!!! warning
|
||||
|
||||
This annotator utilizes the `sv.Detections.mask`.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
@@ -106,7 +113,7 @@ class MaskAnnotator(BaseAnnotator):
|
||||
annotating detections.
|
||||
opacity (float): Opacity of the overlay mask. Must be between `0` and `1`.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACE`.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.opacity = opacity
|
||||
@@ -128,7 +135,7 @@ class MaskAnnotator(BaseAnnotator):
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated image.
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -150,6 +157,8 @@ class MaskAnnotator(BaseAnnotator):
|
||||
if detections.mask is None:
|
||||
return scene
|
||||
|
||||
colored_mask = np.array(scene, copy=True, dtype=np.uint8)
|
||||
|
||||
for detection_idx in np.flip(np.argsort(detections.area)):
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
@@ -160,16 +169,99 @@ class MaskAnnotator(BaseAnnotator):
|
||||
else custom_color_lookup,
|
||||
)
|
||||
mask = detections.mask[detection_idx]
|
||||
colored_mask = np.zeros_like(scene, dtype=np.uint8)
|
||||
colored_mask[:] = color.as_bgr()
|
||||
scene[mask] = cv2.addWeighted(
|
||||
colored_mask, self.opacity, scene, 1 - self.opacity, 0
|
||||
)[mask]
|
||||
colored_mask[mask] = color.as_bgr()
|
||||
|
||||
scene = cv2.addWeighted(colored_mask, self.opacity, scene, 1 - self.opacity, 0)
|
||||
return scene.astype(np.uint8)
|
||||
|
||||
|
||||
class PolygonAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing polygons on an image using provided detections.
|
||||
|
||||
!!! warning
|
||||
|
||||
This annotator utilizes the `sv.Detections.mask`.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
thickness: int = 2,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the polygon lines.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.thickness: int = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
def annotate(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
detections: Detections,
|
||||
custom_color_lookup: Optional[np.ndarray] = None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotates the given scene with polygons based on the provided detections.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image where polygons will be drawn.
|
||||
detections (Detections): Object detections to annotate.
|
||||
custom_color_lookup (Optional[np.ndarray]): Custom color lookup array.
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> polygon_annotator = sv.PolygonAnnotator()
|
||||
>>> annotated_frame = polygon_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
if detections.mask is None:
|
||||
return scene
|
||||
|
||||
for detection_idx in range(len(detections)):
|
||||
mask = detections.mask[detection_idx]
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
for polygon in mask_to_polygons(mask=mask):
|
||||
scene = draw_polygon(
|
||||
scene=scene,
|
||||
polygon=polygon,
|
||||
color=color,
|
||||
thickness=self.thickness,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
class BoxMaskAnnotator(BaseAnnotator):
|
||||
class ColorAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing box masks on an image using provided detections.
|
||||
"""
|
||||
@@ -186,7 +278,7 @@ class BoxMaskAnnotator(BaseAnnotator):
|
||||
annotating detections.
|
||||
opacity (float): Opacity of the overlay mask. Must be between `0` and `1`.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACE`.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
@@ -208,7 +300,7 @@ class BoxMaskAnnotator(BaseAnnotator):
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated image.
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -217,8 +309,8 @@ class BoxMaskAnnotator(BaseAnnotator):
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> box_mask_annotator = sv.BoxMaskAnnotator()
|
||||
>>> annotated_frame = box_mask_annotator.annotate(
|
||||
>>> color_annotator = sv.ColorAnnotator()
|
||||
>>> annotated_frame = color_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
@@ -254,6 +346,10 @@ class BoxMaskAnnotator(BaseAnnotator):
|
||||
class HaloAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing Halos on an image using provided detections.
|
||||
|
||||
!!! warning
|
||||
|
||||
This annotator utilizes the `sv.Detections.mask`.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
@@ -271,7 +367,7 @@ class HaloAnnotator(BaseAnnotator):
|
||||
kernel_size (int): The size of the average pooling kernel used for creating
|
||||
the halo.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACE`.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.opacity = opacity
|
||||
@@ -294,7 +390,7 @@ class HaloAnnotator(BaseAnnotator):
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated image.
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -364,7 +460,7 @@ class EllipseAnnotator(BaseAnnotator):
|
||||
start_angle (int): Starting angle of the ellipse.
|
||||
end_angle (int): Ending angle of the ellipse.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACE`.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.thickness: int = thickness
|
||||
@@ -388,7 +484,7 @@ class EllipseAnnotator(BaseAnnotator):
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated image.
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -452,7 +548,7 @@ class BoxCornerAnnotator(BaseAnnotator):
|
||||
thickness (int): Thickness of the corner lines.
|
||||
corner_length (int): Length of each corner line.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACE`.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.thickness: int = thickness
|
||||
@@ -475,7 +571,7 @@ class BoxCornerAnnotator(BaseAnnotator):
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated image.
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -536,7 +632,7 @@ class CircleAnnotator(BaseAnnotator):
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the circle line.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACE`.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -559,7 +655,7 @@ class CircleAnnotator(BaseAnnotator):
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated image.
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -622,7 +718,7 @@ class DotAnnotator(BaseAnnotator):
|
||||
radius (int): Radius of the drawn dots.
|
||||
position (Position): The anchor position for placing the dot.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACE`.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.radius: int = radius
|
||||
@@ -645,7 +741,7 @@ class DotAnnotator(BaseAnnotator):
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated image.
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -664,7 +760,7 @@ class DotAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
xy = detections.get_anchor_coordinates(anchor=self.position)
|
||||
xy = detections.get_anchors_coordinates(anchor=self.position)
|
||||
for detection_idx in range(len(detections)):
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
@@ -705,56 +801,53 @@ class LabelAnnotator:
|
||||
text_position (Position): Position of the text relative to the detection.
|
||||
Possible values are defined in the `Position` enum.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACE`.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.text_color: Color = text_color
|
||||
self.text_scale: float = text_scale
|
||||
self.text_thickness: int = text_thickness
|
||||
self.text_padding: int = text_padding
|
||||
self.text_position: Position = text_position
|
||||
self.text_anchor: Position = text_position
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@staticmethod
|
||||
def resolve_text_background_xyxy(
|
||||
detection_xyxy: Tuple[int, int, int, int],
|
||||
center_coordinates: Tuple[int, int],
|
||||
text_wh: Tuple[int, int],
|
||||
text_padding: int,
|
||||
position: Position,
|
||||
) -> Tuple[int, int, int, int]:
|
||||
padded_text_wh = (text_wh[0] + 2 * text_padding, text_wh[1] + 2 * text_padding)
|
||||
x1, y1, x2, y2 = detection_xyxy
|
||||
center_x = (x1 + x2) // 2
|
||||
center_y = (y1 + y2) // 2
|
||||
center_x, center_y = center_coordinates
|
||||
text_w, text_h = text_wh
|
||||
|
||||
if position == Position.TOP_LEFT:
|
||||
return x1, y1 - padded_text_wh[1], x1 + padded_text_wh[0], y1
|
||||
return center_x, center_y - text_h, center_x + text_w, center_y
|
||||
elif position == Position.TOP_RIGHT:
|
||||
return x2 - padded_text_wh[0], y1 - padded_text_wh[1], x2, y1
|
||||
return center_x - text_w, center_y - text_h, center_x, center_y
|
||||
elif position == Position.TOP_CENTER:
|
||||
return (
|
||||
center_x - padded_text_wh[0] // 2,
|
||||
y1 - padded_text_wh[1],
|
||||
center_x + padded_text_wh[0] // 2,
|
||||
y1,
|
||||
center_x - text_w // 2,
|
||||
center_y - text_h,
|
||||
center_x + text_w // 2,
|
||||
center_y,
|
||||
)
|
||||
elif position == Position.CENTER:
|
||||
elif position == Position.CENTER or position == Position.CENTER_OF_MASS:
|
||||
return (
|
||||
center_x - padded_text_wh[0] // 2,
|
||||
center_y - padded_text_wh[1] // 2,
|
||||
center_x + padded_text_wh[0] // 2,
|
||||
center_y + padded_text_wh[1] // 2,
|
||||
center_x - text_w // 2,
|
||||
center_y - text_h // 2,
|
||||
center_x + text_w // 2,
|
||||
center_y + text_h // 2,
|
||||
)
|
||||
elif position == Position.BOTTOM_LEFT:
|
||||
return x1, y2, x1 + padded_text_wh[0], y2 + padded_text_wh[1]
|
||||
return center_x, center_y, center_x + text_w, center_y + text_h
|
||||
elif position == Position.BOTTOM_RIGHT:
|
||||
return x2 - padded_text_wh[0], y2, x2, y2 + padded_text_wh[1]
|
||||
return center_x - text_w, center_y, center_x, center_y + text_h
|
||||
elif position == Position.BOTTOM_CENTER:
|
||||
return (
|
||||
center_x - padded_text_wh[0] // 2,
|
||||
y2,
|
||||
center_x + padded_text_wh[0] // 2,
|
||||
y2 + padded_text_wh[1],
|
||||
center_x - text_w // 2,
|
||||
center_y,
|
||||
center_x + text_w // 2,
|
||||
center_y + text_h,
|
||||
)
|
||||
|
||||
def annotate(
|
||||
@@ -775,7 +868,7 @@ class LabelAnnotator:
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated image.
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -795,8 +888,20 @@ class LabelAnnotator:
|
||||
supervision-annotator-examples/label-annotator-example-purple.png)
|
||||
"""
|
||||
font = cv2.FONT_HERSHEY_SIMPLEX
|
||||
for detection_idx in range(len(detections)):
|
||||
detection_xyxy = detections.xyxy[detection_idx].astype(int)
|
||||
anchors_coordinates = detections.get_anchors_coordinates(
|
||||
anchor=self.text_anchor
|
||||
).astype(int)
|
||||
if labels is not None and len(labels) != len(detections):
|
||||
raise ValueError(
|
||||
f"The number of labels provided ({len(labels)}) does not match the "
|
||||
f"number of detections ({len(detections)}). Each detection should have "
|
||||
f"a corresponding label. This discrepancy can occur if the labels and "
|
||||
f"detections are not aligned or if an incorrect number of labels has "
|
||||
f"been provided. Please ensure that the labels array has the same "
|
||||
f"length as the Detections object."
|
||||
)
|
||||
|
||||
for detection_idx, center_coordinates in enumerate(anchors_coordinates):
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
@@ -805,27 +910,32 @@ class LabelAnnotator:
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
text = (
|
||||
f"{detections.class_id[detection_idx]}"
|
||||
if (labels is None or len(detections) != len(labels))
|
||||
else labels[detection_idx]
|
||||
)
|
||||
text_wh = cv2.getTextSize(
|
||||
|
||||
if labels is not None:
|
||||
text = labels[detection_idx]
|
||||
elif detections[CLASS_NAME_DATA_FIELD] is not None:
|
||||
text = detections[CLASS_NAME_DATA_FIELD][detection_idx]
|
||||
elif detections.class_id is not None:
|
||||
text = str(detections.class_id[detection_idx])
|
||||
else:
|
||||
text = str(detection_idx)
|
||||
|
||||
text_w, text_h = cv2.getTextSize(
|
||||
text=text,
|
||||
fontFace=font,
|
||||
fontScale=self.text_scale,
|
||||
thickness=self.text_thickness,
|
||||
)[0]
|
||||
|
||||
text_w_padded = text_w + 2 * self.text_padding
|
||||
text_h_padded = text_h + 2 * self.text_padding
|
||||
text_background_xyxy = self.resolve_text_background_xyxy(
|
||||
detection_xyxy=detection_xyxy,
|
||||
text_wh=text_wh,
|
||||
text_padding=self.text_padding,
|
||||
position=self.text_position,
|
||||
center_coordinates=tuple(center_coordinates),
|
||||
text_wh=(text_w_padded, text_h_padded),
|
||||
position=self.text_anchor,
|
||||
)
|
||||
|
||||
text_x = text_background_xyxy[0] + self.text_padding
|
||||
text_y = text_background_xyxy[1] + self.text_padding + text_wh[1]
|
||||
text_y = text_background_xyxy[1] + self.text_padding + text_h
|
||||
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
@@ -872,7 +982,7 @@ class BlurAnnotator(BaseAnnotator):
|
||||
detections (Detections): Object detections to annotate.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated image.
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -882,7 +992,7 @@ class BlurAnnotator(BaseAnnotator):
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> blur_annotator = sv.BlurAnnotator()
|
||||
>>> annotated_frame = blur_annotator.annotate(
|
||||
>>> annotated_frame = circle_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
@@ -891,10 +1001,13 @@ class BlurAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
for detection_idx in range(len(detections)):
|
||||
x1, y1, x2, y2 = detections.xyxy[detection_idx].astype(int)
|
||||
roi = scene[y1:y2, x1:x2]
|
||||
image_height, image_width = scene.shape[:2]
|
||||
clipped_xyxy = clip_boxes(
|
||||
xyxy=detections.xyxy, resolution_wh=(image_width, image_height)
|
||||
).astype(int)
|
||||
|
||||
for x1, y1, x2, y2 in clipped_xyxy:
|
||||
roi = scene[y1:y2, x1:x2]
|
||||
roi = cv2.blur(roi, (self.kernel_size, self.kernel_size))
|
||||
scene[y1:y2, x1:x2] = roi
|
||||
|
||||
@@ -907,7 +1020,7 @@ class TraceAnnotator:
|
||||
|
||||
!!! warning
|
||||
|
||||
This annotator utilizes the `tracker_id`. Read
|
||||
This annotator utilizes the `sv.Detections.tracker_id`. Read
|
||||
[here](https://supervision.roboflow.com/trackers/) to learn how to plug
|
||||
tracking into your inference pipeline.
|
||||
"""
|
||||
@@ -930,11 +1043,10 @@ class TraceAnnotator:
|
||||
points. Defaults to `30`.
|
||||
thickness (int): The thickness of the trace lines. Defaults to `2`.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACE`.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.position = position
|
||||
self.trace = Trace(max_size=trace_length)
|
||||
self.trace = Trace(max_size=trace_length, anchor=position)
|
||||
self.thickness = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@@ -955,7 +1067,7 @@ class TraceAnnotator:
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The image with the trace paths drawn on it.
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -1051,7 +1163,7 @@ class HeatMapAnnotator:
|
||||
detections (Detections): Object detections to annotate.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Annotated image.
|
||||
Annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -1082,7 +1194,7 @@ class HeatMapAnnotator:
|
||||
if self.heat_mask is None:
|
||||
self.heat_mask = np.zeros(scene.shape[:2])
|
||||
mask = np.zeros(scene.shape[:2])
|
||||
for xy in detections.get_anchor_coordinates(self.position):
|
||||
for xy in detections.get_anchors_coordinates(self.position):
|
||||
cv2.circle(mask, (int(xy[0]), int(xy[1])), self.radius, 1, -1)
|
||||
self.heat_mask = mask + self.heat_mask
|
||||
temp = self.heat_mask.copy()
|
||||
@@ -1100,3 +1212,159 @@ class HeatMapAnnotator:
|
||||
mask
|
||||
]
|
||||
return scene
|
||||
|
||||
|
||||
class PixelateAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for pixelating regions in an image using provided detections.
|
||||
"""
|
||||
|
||||
def __init__(self, pixel_size: int = 20):
|
||||
"""
|
||||
Args:
|
||||
pixel_size (int): The size of the pixelation.
|
||||
"""
|
||||
self.pixel_size: int = pixel_size
|
||||
|
||||
def annotate(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
detections: Detections,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotates the given scene by pixelating regions based on the provided
|
||||
detections.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image where pixelating will be applied.
|
||||
detections (Detections): Object detections to annotate.
|
||||
|
||||
Returns:
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> pixelate_annotator = sv.PixelateAnnotator()
|
||||
>>> annotated_frame = pixelate_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
image_height, image_width = scene.shape[:2]
|
||||
clipped_xyxy = clip_boxes(
|
||||
xyxy=detections.xyxy, resolution_wh=(image_width, image_height)
|
||||
).astype(int)
|
||||
|
||||
for x1, y1, x2, y2 in clipped_xyxy:
|
||||
roi = scene[y1:y2, x1:x2]
|
||||
scaled_up_roi = cv2.resize(
|
||||
src=roi, dsize=None, fx=1 / self.pixel_size, fy=1 / self.pixel_size
|
||||
)
|
||||
scaled_down_roi = cv2.resize(
|
||||
src=scaled_up_roi,
|
||||
dsize=(roi.shape[1], roi.shape[0]),
|
||||
interpolation=cv2.INTER_NEAREST,
|
||||
)
|
||||
|
||||
scene[y1:y2, x1:x2] = scaled_down_roi
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
class TriangleAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing triangle markers on an image at specific coordinates based on
|
||||
provided detections.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
base: int = 10,
|
||||
height: int = 10,
|
||||
position: Position = Position.TOP_CENTER,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
base (int): The base width of the triangle.
|
||||
height (int): The height of the triangle.
|
||||
position (Position): The anchor position for placing the triangle.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.base: int = base
|
||||
self.height: int = height
|
||||
self.position: Position = position
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
def annotate(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
detections: Detections,
|
||||
custom_color_lookup: Optional[np.ndarray] = None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotates the given scene with triangles based on the provided detections.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image where triangles will be drawn.
|
||||
detections (Detections): Object detections to annotate.
|
||||
custom_color_lookup (Optional[np.ndarray]): Custom color lookup array.
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> triangle_annotator = sv.TriangleAnnotator()
|
||||
>>> annotated_frame = triangle_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
xy = detections.get_anchors_coordinates(anchor=self.position)
|
||||
for detection_idx in range(len(detections)):
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
tip_x, tip_y = int(xy[detection_idx, 0]), int(xy[detection_idx, 1])
|
||||
vertices = np.array(
|
||||
[
|
||||
[tip_x - self.base // 2, tip_y - self.height],
|
||||
[tip_x + self.base // 2, tip_y - self.height],
|
||||
[tip_x, tip_y],
|
||||
],
|
||||
np.int32,
|
||||
)
|
||||
|
||||
cv2.fillPoly(scene, [vertices], color.as_bgr())
|
||||
|
||||
return scene
|
||||
|
||||
@@ -102,7 +102,7 @@ class Trace:
|
||||
frame_id = np.full(len(detections), self.current_frame_id, dtype=int)
|
||||
self.frame_id = np.concatenate([self.frame_id, frame_id])
|
||||
self.xy = np.concatenate(
|
||||
[self.xy, detections.get_anchor_coordinates(self.anchor)]
|
||||
[self.xy, detections.get_anchors_coordinates(self.anchor)]
|
||||
)
|
||||
self.tracker_id = np.concatenate([self.tracker_id, detections.tracker_id])
|
||||
|
||||
|
||||
@@ -0,0 +1,2 @@
|
||||
from supervision.assets.downloader import download_assets
|
||||
from supervision.assets.list import VideoAssets
|
||||
@@ -0,0 +1,95 @@
|
||||
import os
|
||||
from hashlib import new as hash_new
|
||||
from pathlib import Path
|
||||
from shutil import copyfileobj
|
||||
from typing import Union
|
||||
|
||||
from supervision.assets.list import VIDEO_ASSETS, VideoAssets
|
||||
|
||||
try:
|
||||
from requests import get
|
||||
from tqdm.auto import tqdm
|
||||
except ImportError:
|
||||
raise ValueError(
|
||||
"\n"
|
||||
"Please install requests and tqdm to download assets \n"
|
||||
"or install supervision with assets \n"
|
||||
"pip install supervision[assets] \n"
|
||||
"\n"
|
||||
)
|
||||
|
||||
|
||||
def is_md5_hash_matching(filename: str, original_md5_hash: str) -> bool:
|
||||
"""
|
||||
Check if the MD5 hash of a file matches the original hash.
|
||||
|
||||
Parameters:
|
||||
filename (str): The path to the file to be checked as a string.
|
||||
original_md5_hash (str): The original MD5 hash to compare against.
|
||||
|
||||
Returns:
|
||||
bool: True if the hashes match, False otherwise.
|
||||
"""
|
||||
if not os.path.exists(filename):
|
||||
return False
|
||||
|
||||
with open(filename, "rb") as file:
|
||||
file_contents = file.read()
|
||||
computed_md5_hash = hash_new(name="MD5")
|
||||
computed_md5_hash.update(file_contents)
|
||||
|
||||
return computed_md5_hash.hexdigest() == original_md5_hash
|
||||
|
||||
|
||||
def download_assets(asset_name: Union[VideoAssets, str]) -> str:
|
||||
"""
|
||||
Download a specified asset if it doesn't already exist or is corrupted.
|
||||
|
||||
Parameters:
|
||||
asset_name (Union[VideoAssets, str]): The name or type of the asset to be
|
||||
downloaded.
|
||||
|
||||
Returns:
|
||||
str: The filename of the downloaded asset.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from supervision.assets import download_assets, VideoAssets
|
||||
|
||||
>>> download_assets(VideoAssets.VEHICLES)
|
||||
"vehicles.mp4"
|
||||
```
|
||||
"""
|
||||
|
||||
filename = asset_name.value if isinstance(asset_name, VideoAssets) else asset_name
|
||||
|
||||
if not Path(filename).exists() and filename in VIDEO_ASSETS:
|
||||
print(f"Downloading {filename} assets \n")
|
||||
response = get(VIDEO_ASSETS[filename][0], stream=True, allow_redirects=True)
|
||||
response.raise_for_status()
|
||||
|
||||
file_size = int(response.headers.get("Content-Length", 0))
|
||||
folder_path = Path(filename).expanduser().resolve()
|
||||
folder_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
with tqdm.wrapattr(
|
||||
response.raw, "read", total=file_size, desc="", colour="#a351fb"
|
||||
) as raw_resp:
|
||||
with folder_path.open("wb") as file:
|
||||
copyfileobj(raw_resp, file)
|
||||
|
||||
elif Path(filename).exists():
|
||||
if not is_md5_hash_matching(filename, VIDEO_ASSETS[filename][1]):
|
||||
print("File corrupted. Re-downloading... \n")
|
||||
os.remove(filename)
|
||||
return download_assets(filename)
|
||||
|
||||
print(f"{filename} asset download complete. \n")
|
||||
|
||||
else:
|
||||
valid_assets = ", ".join(asset.value for asset in VideoAssets)
|
||||
raise ValueError(
|
||||
f"Invalid asset. It should be one of the following: {valid_assets}."
|
||||
)
|
||||
|
||||
return filename
|
||||
@@ -0,0 +1,65 @@
|
||||
from enum import Enum
|
||||
from typing import Dict, Tuple
|
||||
|
||||
BASE_VIDEO_URL = "https://media.roboflow.com/supervision/video-examples/"
|
||||
|
||||
|
||||
class VideoAssets(Enum):
|
||||
"""
|
||||
Each member of this enum represents a video asset. The value associated with each
|
||||
member is the filename of the video.
|
||||
|
||||
| Enum Member | Video Filename | Video URL |
|
||||
|------------------------|----------------------------|---------------------------------------------------------------------------------------|
|
||||
| `VEHICLES` | `vehicles.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/vehicles.mp4) |
|
||||
| `MILK_BOTTLING_PLANT` | `milk-bottling-plant.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/milk-bottling-plant.mp4) |
|
||||
| `VEHICLES_2` | `vehicles-2.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/vehicles-2.mp4) |
|
||||
| `GROCERY_STORE` | `grocery-store.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/grocery-store.mp4) |
|
||||
| `SUBWAY` | `subway.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/subway.mp4) |
|
||||
| `MARKET_SQUARE` | `market-square.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/market-square.mp4) |
|
||||
| `PEOPLE_WALKING` | `people-walking.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/people-walking.mp4) |
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
VEHICLES = "vehicles.mp4"
|
||||
MILK_BOTTLING_PLANT = "milk-bottling-plant.mp4"
|
||||
VEHICLES_2 = "vehicles-2.mp4"
|
||||
GROCERY_STORE = "grocery-store.mp4"
|
||||
SUBWAY = "subway.mp4"
|
||||
MARKET_SQUARE = "market-square.mp4"
|
||||
PEOPLE_WALKING = "people-walking.mp4"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
return list(map(lambda c: c.value, cls))
|
||||
|
||||
|
||||
VIDEO_ASSETS: Dict[str, Tuple[str, str]] = {
|
||||
VideoAssets.VEHICLES.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.VEHICLES.value}",
|
||||
"8155ff4e4de08cfa25f39de96483f918",
|
||||
),
|
||||
VideoAssets.VEHICLES_2.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.VEHICLES_2.value}",
|
||||
"830af6fba21ffbf14867a7fea595937b",
|
||||
),
|
||||
VideoAssets.MILK_BOTTLING_PLANT.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.MILK_BOTTLING_PLANT.value}",
|
||||
"9e8fb6e883f842a38b3d34267290bdc7",
|
||||
),
|
||||
VideoAssets.GROCERY_STORE.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.GROCERY_STORE.value}",
|
||||
"11402e7b861c1980527d3d74cbe3b366",
|
||||
),
|
||||
VideoAssets.SUBWAY.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.SUBWAY.value}",
|
||||
"453475750691fb23c56a0cffef089194",
|
||||
),
|
||||
VideoAssets.MARKET_SQUARE.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.MARKET_SQUARE.value}",
|
||||
"859179bf4a21f80a8baabfdb2ed716dc",
|
||||
),
|
||||
VideoAssets.PEOPLE_WALKING.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.PEOPLE_WALKING.value}",
|
||||
"0574c053c8686c3f1dc0aa3743e45cb9",
|
||||
),
|
||||
}
|
||||
@@ -39,15 +39,58 @@ class Classifications:
|
||||
_validate_class_ids(self.class_id, n)
|
||||
_validate_confidence(self.confidence, n)
|
||||
|
||||
def __len__(self) -> int:
|
||||
"""
|
||||
Returns the number of classifications.
|
||||
"""
|
||||
return len(self.class_id)
|
||||
|
||||
@classmethod
|
||||
def from_clip(cls, clip_results) -> Classifications:
|
||||
"""
|
||||
Creates a Classifications instance from a
|
||||
[clip](https://github.com/openai/clip) inference result.
|
||||
|
||||
Args:
|
||||
clip_results (np.ndarray): The inference result from clip model.
|
||||
|
||||
Returns:
|
||||
Classifications: A new Classifications object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from PIL import Image
|
||||
>>> import clip
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> model, preprocess = clip.load('ViT-B/32')
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> image = preprocess(image).unsqueeze(0)
|
||||
|
||||
>>> text = clip.tokenize(["a diagram", "a dog", "a cat"])
|
||||
>>> output, _ = model(image, text)
|
||||
>>> classifications = sv.Classifications.from_clip(output)
|
||||
```
|
||||
"""
|
||||
|
||||
confidence = clip_results.softmax(dim=-1).cpu().detach().numpy()[0]
|
||||
|
||||
if len(confidence) == 0:
|
||||
return cls(class_id=np.array([]), confidence=np.array([]))
|
||||
|
||||
class_ids = np.arange(len(confidence))
|
||||
return cls(class_id=class_ids, confidence=confidence)
|
||||
|
||||
@classmethod
|
||||
def from_ultralytics(cls, ultralytics_results) -> Classifications:
|
||||
"""
|
||||
Creates a Classifications instance from a
|
||||
(https://github.com/ultralytics/ultralytics) inference result.
|
||||
[ultralytics](https://github.com/ultralytics/ultralytics) inference result.
|
||||
|
||||
Args:
|
||||
ultralytics_results (ultralytics.engine.results.Results):
|
||||
The output Results instance from ultralytics model
|
||||
The inference result from ultralytics model.
|
||||
|
||||
Returns:
|
||||
Classifications: A new Classifications object.
|
||||
@@ -60,15 +103,57 @@ class Classifications:
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> model = YOLO('yolov8n-cls.pt')
|
||||
>>> model = YOLO('yolov8s-cls.pt')
|
||||
|
||||
>>> result = model(image)[0]
|
||||
>>> classifications = sv.Classifications.from_ultralytics(result)
|
||||
>>> output = model(image)[0]
|
||||
>>> classifications = sv.Classifications.from_ultralytics(output)
|
||||
```
|
||||
"""
|
||||
confidence = ultralytics_results.probs.data.cpu().numpy()
|
||||
return cls(class_id=np.arange(confidence.shape[0]), confidence=confidence)
|
||||
|
||||
@classmethod
|
||||
def from_timm(cls, timm_results) -> Classifications:
|
||||
"""
|
||||
Creates a Classifications instance from a
|
||||
[timm](https://huggingface.co/docs/hub/timm) inference result.
|
||||
|
||||
Args:
|
||||
timm_results: The inference result from timm model.
|
||||
|
||||
Returns:
|
||||
Classifications: A new Classifications object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from PIL import Image
|
||||
>>> import timm
|
||||
>>> from timm.data import resolve_data_config, create_transform
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> model = timm.create_model(
|
||||
... model_name='hf-hub:nateraw/resnet50-oxford-iiit-pet',
|
||||
... pretrained=True
|
||||
... ).eval()
|
||||
|
||||
>>> config = resolve_data_config({}, model=model)
|
||||
>>> transform = create_transform(**config)
|
||||
|
||||
>>> image = Image.open(SOURCE_IMAGE_PATH).convert('RGB')
|
||||
>>> x = transform(image).unsqueeze(0)
|
||||
|
||||
>>> output = model(x)
|
||||
|
||||
>>> classifications = sv.Classifications.from_timm(output)
|
||||
```
|
||||
"""
|
||||
confidence = timm_results.cpu().detach().numpy()[0]
|
||||
|
||||
if len(confidence) == 0:
|
||||
return cls(class_id=np.array([]), confidence=np.array([]))
|
||||
|
||||
class_id = np.arange(len(confidence))
|
||||
return cls(class_id=class_id, confidence=confidence)
|
||||
|
||||
def get_top_k(self, k: int) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""
|
||||
Retrieve the top k class IDs and confidences,
|
||||
|
||||
@@ -0,0 +1 @@
|
||||
CLASS_NAME_DATA_FIELD = "class_name"
|
||||
@@ -1,11 +1,11 @@
|
||||
import os
|
||||
from pathlib import Path
|
||||
from typing import Dict, List, Optional, Tuple
|
||||
from xml.dom.minidom import parseString
|
||||
from xml.etree.ElementTree import Element, SubElement, parse, tostring
|
||||
from xml.etree.ElementTree import Element, SubElement
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from defusedxml.ElementTree import fromstring, parse, tostring
|
||||
|
||||
from supervision.dataset.utils import approximate_mask_with_polygons
|
||||
from supervision.detection.core import Detections
|
||||
@@ -129,7 +129,7 @@ def detections_to_pascal_voc(
|
||||
annotation.append(next_object)
|
||||
|
||||
# Generate XML string
|
||||
xml_string = parseString(tostring(annotation)).toprettyxml(indent=" ")
|
||||
xml_string = fromstring(tostring(annotation)).toprettyxml(indent=" ")
|
||||
|
||||
return xml_string
|
||||
|
||||
@@ -268,12 +268,12 @@ def detections_from_xml_obj(
|
||||
[extended_classes.index(class_name) for class_name in class_names]
|
||||
)
|
||||
|
||||
if with_masks:
|
||||
annotation = Detections(
|
||||
xyxy=xyxy, mask=np.array(masks).astype(bool), class_id=class_id
|
||||
)
|
||||
else:
|
||||
annotation = Detections(xyxy=xyxy, class_id=class_id)
|
||||
annotation = Detections(
|
||||
xyxy=xyxy.astype(np.float32),
|
||||
mask=np.array(masks).astype(bool) if with_masks else None,
|
||||
class_id=class_id,
|
||||
)
|
||||
|
||||
return annotation, extended_classes
|
||||
|
||||
|
||||
|
||||
@@ -149,7 +149,7 @@ def load_yolo_annotations(
|
||||
annotations[image_path] = Detections.empty()
|
||||
continue
|
||||
|
||||
lines = read_txt_file(str(annotation_path))
|
||||
lines = read_txt_file(file_path=annotation_path, skip_empty=True)
|
||||
h, w, _ = image.shape
|
||||
resolution_wh = (w, h)
|
||||
|
||||
|
||||
+349
-143
@@ -1,68 +1,31 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import astuple, dataclass
|
||||
from typing import Any, Iterator, List, Optional, Tuple, Union
|
||||
from contextlib import suppress
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any, Dict, Iterator, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.utils import (
|
||||
calculate_masks_centroids,
|
||||
extract_ultralytics_masks,
|
||||
get_data_item,
|
||||
is_data_equal,
|
||||
merge_data,
|
||||
non_max_suppression,
|
||||
process_roboflow_result,
|
||||
validate_detections_fields,
|
||||
xywh_to_xyxy,
|
||||
)
|
||||
from supervision.geometry.core import Position
|
||||
|
||||
|
||||
def _validate_xyxy(xyxy: Any, n: int) -> None:
|
||||
is_valid = isinstance(xyxy, np.ndarray) and xyxy.shape == (n, 4)
|
||||
if not is_valid:
|
||||
raise ValueError("xyxy must be 2d np.ndarray with (n, 4) shape")
|
||||
|
||||
|
||||
def _validate_mask(mask: Any, n: int) -> None:
|
||||
is_valid = mask is None or (
|
||||
isinstance(mask, np.ndarray) and len(mask.shape) == 3 and mask.shape[0] == n
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("mask must be 3d np.ndarray with (n, H, W) shape")
|
||||
|
||||
|
||||
def validate_inference_callback(callback) -> None:
|
||||
tmp_img = np.zeros((256, 256, 3), dtype=np.uint8)
|
||||
res = callback(tmp_img)
|
||||
if not isinstance(res, Detections):
|
||||
raise ValueError("Callback function must return sv.Detection type")
|
||||
|
||||
|
||||
def _validate_class_id(class_id: Any, n: int) -> None:
|
||||
is_valid = class_id is None or (
|
||||
isinstance(class_id, np.ndarray) and class_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("class_id must be None or 1d np.ndarray with (n,) shape")
|
||||
|
||||
|
||||
def _validate_confidence(confidence: Any, n: int) -> None:
|
||||
is_valid = confidence is None or (
|
||||
isinstance(confidence, np.ndarray) and confidence.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("confidence must be None or 1d np.ndarray with (n,) shape")
|
||||
|
||||
|
||||
def _validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
is_valid = tracker_id is None or (
|
||||
isinstance(tracker_id, np.ndarray) and tracker_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("tracker_id must be None or 1d np.ndarray with (n,) shape")
|
||||
from supervision.utils.internal import deprecated
|
||||
|
||||
|
||||
@dataclass
|
||||
class Detections:
|
||||
"""
|
||||
Data class containing information about the detections in a video frame.
|
||||
A dataclass representing detection results.
|
||||
|
||||
Attributes:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
@@ -74,6 +37,17 @@ class Detections:
|
||||
`(n,)` containing the class ids of the detections.
|
||||
tracker_id (Optional[np.ndarray]): An array of shape
|
||||
`(n,)` containing the tracker ids of the detections.
|
||||
data (Dict[str, Union[np.ndarray, List]]): A dictionary containing additional
|
||||
data where each key is a string representing the data type, and the value
|
||||
is either a NumPy array or a list of corresponding data.
|
||||
|
||||
!!! warning
|
||||
|
||||
The `data` field in the `sv.Detections` class is currently in an experimental
|
||||
phase. Please be aware that its API and functionality are subject to change in
|
||||
future updates as we continue to refine and improve its capabilities.
|
||||
We encourage users to experiment with this feature and provide feedback, but
|
||||
also to be prepared for potential modifications in upcoming releases.
|
||||
"""
|
||||
|
||||
xyxy: np.ndarray
|
||||
@@ -81,14 +55,17 @@ class Detections:
|
||||
confidence: Optional[np.ndarray] = None
|
||||
class_id: Optional[np.ndarray] = None
|
||||
tracker_id: Optional[np.ndarray] = None
|
||||
data: Dict[str, Union[np.ndarray, List]] = field(default_factory=dict)
|
||||
|
||||
def __post_init__(self):
|
||||
n = len(self.xyxy)
|
||||
_validate_xyxy(xyxy=self.xyxy, n=n)
|
||||
_validate_mask(mask=self.mask, n=n)
|
||||
_validate_class_id(class_id=self.class_id, n=n)
|
||||
_validate_confidence(confidence=self.confidence, n=n)
|
||||
_validate_tracker_id(tracker_id=self.tracker_id, n=n)
|
||||
validate_detections_fields(
|
||||
xyxy=self.xyxy,
|
||||
mask=self.mask,
|
||||
confidence=self.confidence,
|
||||
class_id=self.class_id,
|
||||
tracker_id=self.tracker_id,
|
||||
data=self.data,
|
||||
)
|
||||
|
||||
def __len__(self):
|
||||
"""
|
||||
@@ -105,11 +82,12 @@ class Detections:
|
||||
Optional[float],
|
||||
Optional[int],
|
||||
Optional[int],
|
||||
Dict[str, Union[np.ndarray, List]],
|
||||
]
|
||||
]:
|
||||
"""
|
||||
Iterates over the Detections object and yield a tuple of
|
||||
`(xyxy, mask, confidence, class_id, tracker_id)` for each detection.
|
||||
`(xyxy, mask, confidence, class_id, tracker_id, data)` for each detection.
|
||||
"""
|
||||
for i in range(len(self.xyxy)):
|
||||
yield (
|
||||
@@ -118,36 +96,18 @@ class Detections:
|
||||
self.confidence[i] if self.confidence is not None else None,
|
||||
self.class_id[i] if self.class_id is not None else None,
|
||||
self.tracker_id[i] if self.tracker_id is not None else None,
|
||||
get_data_item(self.data, i),
|
||||
)
|
||||
|
||||
def __eq__(self, other: Detections):
|
||||
return all(
|
||||
[
|
||||
np.array_equal(self.xyxy, other.xyxy),
|
||||
any(
|
||||
[
|
||||
self.mask is None and other.mask is None,
|
||||
np.array_equal(self.mask, other.mask),
|
||||
]
|
||||
),
|
||||
any(
|
||||
[
|
||||
self.class_id is None and other.class_id is None,
|
||||
np.array_equal(self.class_id, other.class_id),
|
||||
]
|
||||
),
|
||||
any(
|
||||
[
|
||||
self.confidence is None and other.confidence is None,
|
||||
np.array_equal(self.confidence, other.confidence),
|
||||
]
|
||||
),
|
||||
any(
|
||||
[
|
||||
self.tracker_id is None and other.tracker_id is None,
|
||||
np.array_equal(self.tracker_id, other.tracker_id),
|
||||
]
|
||||
),
|
||||
np.array_equal(self.mask, other.mask),
|
||||
np.array_equal(self.class_id, other.class_id),
|
||||
np.array_equal(self.confidence, other.confidence),
|
||||
np.array_equal(self.tracker_id, other.tracker_id),
|
||||
is_data_equal(self.data, other.data),
|
||||
]
|
||||
)
|
||||
|
||||
@@ -200,19 +160,12 @@ class Detections:
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> from ultralytics import YOLO, FastSAM, SAM, RTDETR
|
||||
>>> import supervision as sv
|
||||
>>> from ultralytics import YOLO
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> image = cv2.imread(...)
|
||||
>>> model = YOLO('yolov8s.pt')
|
||||
>>> model = SAM('sam_b.pt')
|
||||
>>> model = SAM('mobile_sam.pt')
|
||||
>>> model = FastSAM('FastSAM-s.pt')
|
||||
>>> model = RTDETR('rtdetr-l.pt')
|
||||
>>> # model inferences
|
||||
>>> result = model(image)[0]
|
||||
>>> # if tracker is enabled
|
||||
>>> result = model.track(image)[0]
|
||||
>>> detections = sv.Detections.from_ultralytics(result)
|
||||
```
|
||||
"""
|
||||
@@ -264,6 +217,51 @@ class Detections:
|
||||
class_id=yolo_nas_results.prediction.labels.astype(int),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_tensorflow(
|
||||
cls, tensorflow_results: dict, resolution_wh: tuple
|
||||
) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from a
|
||||
[Tensorflow Hub](https://www.tensorflow.org/hub/tutorials/tf2_object_detection)
|
||||
inference result.
|
||||
|
||||
Args:
|
||||
tensorflow_results (dict):
|
||||
The output results from Tensorflow Hub.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import tensorflow as tf
|
||||
>>> import tensorflow_hub as hub
|
||||
>>> import numpy as np
|
||||
>>> import cv2
|
||||
|
||||
>>> module_handle = "https://tfhub.dev/tensorflow/centernet/hourglass_512x512_kpts/1"
|
||||
|
||||
>>> model = hub.load(module_handle)
|
||||
|
||||
>>> img = np.array(cv2.imread(SOURCE_IMAGE_PATH))
|
||||
|
||||
>>> result = model(img)
|
||||
|
||||
>>> detections = sv.Detections.from_tensorflow(result)
|
||||
```
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
boxes = tensorflow_results["detection_boxes"][0].numpy()
|
||||
boxes[:, [0, 2]] *= resolution_wh[0]
|
||||
boxes[:, [1, 3]] *= resolution_wh[1]
|
||||
boxes = boxes[:, [1, 0, 3, 2]]
|
||||
return cls(
|
||||
xyxy=boxes,
|
||||
confidence=tensorflow_results["detection_scores"][0].numpy(),
|
||||
class_id=tensorflow_results["detection_classes"][0].numpy().astype(int),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_deepsparse(cls, deepsparse_results) -> Detections:
|
||||
"""
|
||||
@@ -280,18 +278,18 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from deepsparse import Pipeline
|
||||
>>> import supervision as sv
|
||||
>>> from deepsparse import Pipeline
|
||||
|
||||
>>> yolo_pipeline = Pipeline.create(
|
||||
... task="yolo",
|
||||
... model_path = "zoo:cv/detection/yolov5-l/pytorch/" \
|
||||
... "ultralytics/coco/pruned80_quant-none"
|
||||
>>> pipeline_outputs = yolo_pipeline(SOURCE_IMAGE_PATH,
|
||||
... iou_thres=0.6, conf_thres=0.001)
|
||||
... model_path = "zoo:cv/detection/yolov5-l/pytorch/ultralytics/coco/pruned80_quant-none"
|
||||
... )
|
||||
>>> result = yolo_pipeline(<SOURCE IMAGE PATH>)
|
||||
>>> detections = sv.Detections.from_deepsparse(result)
|
||||
```
|
||||
"""
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
if np.asarray(deepsparse_results.boxes[0]).shape[0] == 0:
|
||||
return cls.empty()
|
||||
|
||||
@@ -323,8 +321,8 @@ class Detections:
|
||||
|
||||
>>> inferencer = DetInferencer(model_name, checkpoint, device)
|
||||
>>> mmdet_result = inferencer(SOURCE_IMAGE_PATH, out_dir='./output',
|
||||
... return_datasample=True)["predictions"][0]
|
||||
>>> detections = sv.Detections.from_mmdet(mmdet_result)
|
||||
... return_datasamples=True)["predictions"][0]
|
||||
>>> detections = sv.Detections.from_mmdetection(mmdet_result)
|
||||
```
|
||||
"""
|
||||
|
||||
@@ -391,14 +389,22 @@ class Detections:
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_roboflow(cls, roboflow_result: dict) -> Detections:
|
||||
def from_inference(cls, roboflow_result: Union[dict, Any]) -> Detections:
|
||||
"""
|
||||
Create a Detections object from the [Roboflow](https://roboflow.com/)
|
||||
API inference result.
|
||||
API inference result or the [Inference](https://inference.roboflow.com/)
|
||||
package results. This method extracts bounding boxes, class IDs,
|
||||
confidences, and class names from the Roboflow API result and encapsulates
|
||||
them into a Detections object.
|
||||
|
||||
!!! note
|
||||
|
||||
Class names can be accessed using the key 'class_name' in the returned
|
||||
object's data attribute.
|
||||
|
||||
Args:
|
||||
roboflow_result (dict): The result from the
|
||||
Roboflow API containing predictions.
|
||||
roboflow_result (dict, any): The result from the
|
||||
Roboflow API or Inference package containing predictions.
|
||||
|
||||
Returns:
|
||||
(Detections): A Detections object containing the bounding boxes, class IDs,
|
||||
@@ -406,27 +412,19 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import supervision as sv
|
||||
>>> from inference.models.utils import get_roboflow_model
|
||||
|
||||
>>> roboflow_result = {
|
||||
... "predictions": [
|
||||
... {
|
||||
... "x": 0.5,
|
||||
... "y": 0.5,
|
||||
... "width": 0.2,
|
||||
... "height": 0.3,
|
||||
... "class_id": 0,
|
||||
... "class": "person",
|
||||
... "confidence": 0.9
|
||||
... },
|
||||
... # ... more predictions ...
|
||||
... ]
|
||||
... }
|
||||
|
||||
>>> detections = sv.Detections.from_roboflow(roboflow_result)
|
||||
>>> image = cv2.imread(...)
|
||||
>>> model = get_roboflow_model(model_id="yolov8s-640")
|
||||
>>> result = model.infer(image)[0]
|
||||
>>> detections = sv.Detections.from_inference(result)
|
||||
```
|
||||
"""
|
||||
xyxy, confidence, class_id, masks, trackers = process_roboflow_result(
|
||||
with suppress(AttributeError):
|
||||
roboflow_result = roboflow_result.dict(exclude_none=True, by_alias=True)
|
||||
xyxy, confidence, class_id, masks, trackers, data = process_roboflow_result(
|
||||
roboflow_result=roboflow_result
|
||||
)
|
||||
|
||||
@@ -439,8 +437,42 @@ class Detections:
|
||||
class_id=class_id,
|
||||
mask=masks,
|
||||
tracker_id=trackers,
|
||||
data=data,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
@deprecated(
|
||||
"`Detections.from_roboflow` is deprecated and will be removed in "
|
||||
"`supervision-0.21.0`. Use `Detections.from_inference` instead."
|
||||
)
|
||||
def from_roboflow(cls, roboflow_result: Union[dict, Any]) -> Detections:
|
||||
"""
|
||||
Create a Detections object from the [Roboflow](https://roboflow.com/)
|
||||
API inference result or the [Inference](https://inference.roboflow.com/)
|
||||
package results.
|
||||
|
||||
Args:
|
||||
roboflow_result (dict): The result from the
|
||||
Roboflow API containing predictions.
|
||||
|
||||
Returns:
|
||||
(Detections): A Detections object containing the bounding boxes, class IDs,
|
||||
and confidences of the predictions.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import supervision as sv
|
||||
>>> from inference.models.utils import get_roboflow_model
|
||||
|
||||
>>> image = cv2.imread(...)
|
||||
>>> model = get_roboflow_model(model_id="yolov8s-640")
|
||||
>>> result = model.infer(image)[0]
|
||||
>>> detections = sv.Detections.from_roboflow(result)
|
||||
```
|
||||
"""
|
||||
return cls.from_inference(roboflow_result)
|
||||
|
||||
@classmethod
|
||||
def from_sam(cls, sam_result: List[dict]) -> Detections:
|
||||
"""
|
||||
@@ -460,7 +492,7 @@ class Detections:
|
||||
>>> from segment_anything import (
|
||||
... sam_model_registry,
|
||||
... SamAutomaticMaskGenerator
|
||||
... )
|
||||
... )
|
||||
|
||||
>>> sam_model_reg = sam_model_registry[MODEL_TYPE]
|
||||
>>> sam = sam_model_reg(checkpoint=CHECKPOINT_PATH).to(device=DEVICE)
|
||||
@@ -483,6 +515,93 @@ class Detections:
|
||||
xyxy = xywh_to_xyxy(boxes_xywh=xywh)
|
||||
return cls(xyxy=xyxy, mask=mask)
|
||||
|
||||
@classmethod
|
||||
def from_azure_analyze_image(
|
||||
cls, azure_result: dict, class_map: Optional[Dict[int, str]] = None
|
||||
) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from [Azure Image Analysis 4.0](
|
||||
https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/
|
||||
concept-object-detection-40).
|
||||
|
||||
Args:
|
||||
azure_result (dict): The result from Azure Image Analysis. It should
|
||||
contain detected objects and their bounding box coordinates.
|
||||
class_map (Optional[Dict[int, str]]): A mapping ofclass IDs (int) to class
|
||||
names (str). If None, a new mapping is created dynamically.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import requests
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = open(input, "rb").read()
|
||||
|
||||
>>> endpoint = "https://.cognitiveservices.azure.com/"
|
||||
>>> subscription_key = "..."
|
||||
|
||||
>>> headers = {
|
||||
... "Content-Type": "application/octet-stream",
|
||||
... "Ocp-Apim-Subscription-Key": subscription_key
|
||||
... }
|
||||
|
||||
>>> response = requests.post(endpoint,
|
||||
... headers=self.headers,
|
||||
... data=image
|
||||
... ).json()
|
||||
|
||||
>>> detections = sv.Detections.from_azure_analyze_image(response)
|
||||
```
|
||||
"""
|
||||
if "error" in azure_result:
|
||||
raise ValueError(
|
||||
f'Azure API returned an error {azure_result["error"]["message"]}'
|
||||
)
|
||||
|
||||
xyxy, confidences, class_ids = [], [], []
|
||||
|
||||
is_dynamic_mapping = class_map is None
|
||||
if is_dynamic_mapping:
|
||||
class_map = {}
|
||||
|
||||
class_map = {value: key for key, value in class_map.items()}
|
||||
|
||||
for detection in azure_result["objectsResult"]["values"]:
|
||||
bbox = detection["boundingBox"]
|
||||
|
||||
tags = detection["tags"]
|
||||
|
||||
x0 = bbox["x"]
|
||||
y0 = bbox["y"]
|
||||
x1 = x0 + bbox["w"]
|
||||
y1 = y0 + bbox["h"]
|
||||
|
||||
for tag in tags:
|
||||
confidence = tag["confidence"]
|
||||
class_name = tag["name"]
|
||||
class_id = class_map.get(class_name, None)
|
||||
|
||||
if is_dynamic_mapping and class_id is None:
|
||||
class_id = len(class_map)
|
||||
class_map[class_name] = class_id
|
||||
|
||||
if class_id is not None:
|
||||
xyxy.append([x0, y0, x1, y1])
|
||||
confidences.append(confidence)
|
||||
class_ids.append(class_id)
|
||||
|
||||
if len(xyxy) == 0:
|
||||
return Detections.empty()
|
||||
|
||||
return cls(
|
||||
xyxy=np.array(xyxy),
|
||||
class_id=np.array(class_ids),
|
||||
confidence=np.array(confidences),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_paddledet(cls, paddledet_result) -> Detections:
|
||||
"""
|
||||
@@ -567,30 +686,67 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from supervision import Detections
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
>>> detections_1 = Detections(...)
|
||||
>>> detections_2 = Detections(...)
|
||||
>>> detections_1 = sv.Detections(
|
||||
... xyxy=np.array([[15, 15, 100, 100], [200, 200, 300, 300]]),
|
||||
... class_id=np.array([1, 2]),
|
||||
... data={'feature_vector': np.array([0.1, 0.2)])}
|
||||
... )
|
||||
|
||||
>>> detections_2 = sv.Detections(
|
||||
... xyxy=np.array([[30, 30, 120, 120]]),
|
||||
... class_id=np.array([1]),
|
||||
... data={'feature_vector': [np.array([0.3])]}
|
||||
... )
|
||||
|
||||
>>> merged_detections = Detections.merge([detections_1, detections_2])
|
||||
|
||||
>>> merged_detections.xyxy
|
||||
array([[ 15, 15, 100, 100],
|
||||
[200, 200, 300, 300],
|
||||
[ 30, 30, 120, 120]])
|
||||
|
||||
>>> merged_detections.class_id
|
||||
array([1, 2, 1])
|
||||
|
||||
>>> merged_detections.data['feature_vector']
|
||||
array([0.1, 0.2, 0.3])
|
||||
```
|
||||
"""
|
||||
if len(detections_list) == 0:
|
||||
return Detections.empty()
|
||||
|
||||
detections_tuples_list = [astuple(detection) for detection in detections_list]
|
||||
xyxy, mask, confidence, class_id, tracker_id = [
|
||||
list(field) for field in zip(*detections_tuples_list)
|
||||
]
|
||||
for detections in detections_list:
|
||||
validate_detections_fields(
|
||||
xyxy=detections.xyxy,
|
||||
mask=detections.mask,
|
||||
confidence=detections.confidence,
|
||||
class_id=detections.class_id,
|
||||
tracker_id=detections.tracker_id,
|
||||
data=detections.data,
|
||||
)
|
||||
|
||||
def __all_not_none(item_list: List[Any]):
|
||||
return all(x is not None for x in item_list)
|
||||
xyxy = np.vstack([d.xyxy for d in detections_list])
|
||||
|
||||
xyxy = np.vstack(xyxy)
|
||||
mask = np.vstack(mask) if __all_not_none(mask) else None
|
||||
confidence = np.hstack(confidence) if __all_not_none(confidence) else None
|
||||
class_id = np.hstack(class_id) if __all_not_none(class_id) else None
|
||||
tracker_id = np.hstack(tracker_id) if __all_not_none(tracker_id) else None
|
||||
def stack_or_none(name: str):
|
||||
if all(d.__getattribute__(name) is None for d in detections_list):
|
||||
return None
|
||||
if any(d.__getattribute__(name) is None for d in detections_list):
|
||||
raise ValueError(f"All or none of the '{name}' fields must be None")
|
||||
return (
|
||||
np.vstack([d.__getattribute__(name) for d in detections_list])
|
||||
if name == "mask"
|
||||
else np.hstack([d.__getattribute__(name) for d in detections_list])
|
||||
)
|
||||
|
||||
mask = stack_or_none("mask")
|
||||
confidence = stack_or_none("confidence")
|
||||
class_id = stack_or_none("class_id")
|
||||
tracker_id = stack_or_none("tracker_id")
|
||||
|
||||
data = merge_data([d.data for d in detections_list])
|
||||
|
||||
return cls(
|
||||
xyxy=xyxy,
|
||||
@@ -598,9 +754,10 @@ class Detections:
|
||||
confidence=confidence,
|
||||
class_id=class_id,
|
||||
tracker_id=tracker_id,
|
||||
data=data,
|
||||
)
|
||||
|
||||
def get_anchor_coordinates(self, anchor: Position) -> np.ndarray:
|
||||
def get_anchors_coordinates(self, anchor: Position) -> np.ndarray:
|
||||
"""
|
||||
Calculates and returns the coordinates of a specific anchor point
|
||||
within the bounding boxes defined by the `xyxy` attribute. The anchor
|
||||
@@ -627,6 +784,12 @@ class Detections:
|
||||
(self.xyxy[:, 1] + self.xyxy[:, 3]) / 2,
|
||||
]
|
||||
).transpose()
|
||||
elif anchor == Position.CENTER_OF_MASS:
|
||||
if self.mask is None:
|
||||
raise ValueError(
|
||||
"Cannot use `Position.CENTER_OF_MASS` without a detection mask."
|
||||
)
|
||||
return calculate_masks_centroids(masks=self.mask)
|
||||
elif anchor == Position.CENTER_LEFT:
|
||||
return np.array(
|
||||
[
|
||||
@@ -661,17 +824,23 @@ class Detections:
|
||||
raise ValueError(f"{anchor} is not supported.")
|
||||
|
||||
def __getitem__(
|
||||
self, index: Union[int, slice, List[int], np.ndarray]
|
||||
) -> Detections:
|
||||
self, index: Union[int, slice, List[int], np.ndarray, str]
|
||||
) -> Union[Detections, List, np.ndarray, None]:
|
||||
"""
|
||||
Get a subset of the Detections object.
|
||||
Get a subset of the Detections object or access an item from its data field.
|
||||
|
||||
When provided with an integer, slice, list of integers, or a numpy array, this
|
||||
method returns a new Detections object that represents a subset of the original
|
||||
detections. When provided with a string, it accesses the corresponding item in
|
||||
the data dictionary.
|
||||
|
||||
Args:
|
||||
index (Union[int, slice, List[int], np.ndarray]):
|
||||
The index or indices of the subset of the Detections
|
||||
index (Union[int, slice, List[int], np.ndarray, str]): The index, indices,
|
||||
or key to access a subset of the Detections or an item from the data.
|
||||
|
||||
Returns:
|
||||
(Detections): A subset of the Detections object.
|
||||
Union[Detections, Any]: A subset of the Detections object or an item from
|
||||
the data field.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -680,16 +849,16 @@ class Detections:
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> first_detection = detections[0]
|
||||
|
||||
>>> first_10_detections = detections[0:10]
|
||||
|
||||
>>> some_detections = detections[[0, 2, 4]]
|
||||
|
||||
>>> class_0_detections = detections[detections.class_id == 0]
|
||||
|
||||
>>> high_confidence_detections = detections[detections.confidence > 0.5]
|
||||
|
||||
>>> feature_vector = detections['feature_vector']
|
||||
```
|
||||
"""
|
||||
if isinstance(index, str):
|
||||
return self.data.get(index)
|
||||
if isinstance(index, int):
|
||||
index = [index]
|
||||
return Detections(
|
||||
@@ -698,8 +867,45 @@ class Detections:
|
||||
confidence=self.confidence[index] if self.confidence is not None else None,
|
||||
class_id=self.class_id[index] if self.class_id is not None else None,
|
||||
tracker_id=self.tracker_id[index] if self.tracker_id is not None else None,
|
||||
data=get_data_item(self.data, index),
|
||||
)
|
||||
|
||||
def __setitem__(self, key: str, value: Union[np.ndarray, List]):
|
||||
"""
|
||||
Set a value in the data dictionary of the Detections object.
|
||||
|
||||
Args:
|
||||
key (str): The key in the data dictionary to set.
|
||||
value (Union[np.ndarray, List]): The value to set for the key.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> from ultralytics import YOLO
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> model = YOLO('yolov8s.pt')
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
|
||||
>>> result = model(image)[0]
|
||||
>>> detections = sv.Detections.from_ultralytics(result)
|
||||
|
||||
>>> detections['names'] = [
|
||||
... model.model.names[class_id]
|
||||
... for class_id
|
||||
... in detections.class_id
|
||||
... ]
|
||||
```
|
||||
"""
|
||||
if not isinstance(value, (np.ndarray, list)):
|
||||
raise TypeError("Value must be a np.ndarray or a list")
|
||||
|
||||
if isinstance(value, list):
|
||||
value = np.array(value)
|
||||
|
||||
self.data[key] = value
|
||||
|
||||
@property
|
||||
def area(self) -> np.ndarray:
|
||||
"""
|
||||
|
||||
@@ -3,7 +3,7 @@ from typing import Callable, Optional, Tuple
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections, validate_inference_callback
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import move_boxes
|
||||
from supervision.utils.image import crop_image
|
||||
|
||||
@@ -60,7 +60,6 @@ class InferenceSlicer:
|
||||
self.iou_threshold = iou_threshold
|
||||
self.callback = callback
|
||||
self.thread_workers = thread_workers
|
||||
validate_inference_callback(callback=callback)
|
||||
|
||||
def __call__(self, image: np.ndarray) -> Detections:
|
||||
"""
|
||||
|
||||
@@ -56,11 +56,11 @@ class PolygonZone:
|
||||
"""
|
||||
|
||||
clipped_xyxy = clip_boxes(
|
||||
boxes_xyxy=detections.xyxy, frame_resolution_wh=self.frame_resolution_wh
|
||||
xyxy=detections.xyxy, resolution_wh=self.frame_resolution_wh
|
||||
)
|
||||
clipped_detections = replace(detections, xyxy=clipped_xyxy)
|
||||
clipped_anchors = np.ceil(
|
||||
clipped_detections.get_anchor_coordinates(anchor=self.triggering_position)
|
||||
clipped_detections.get_anchors_coordinates(anchor=self.triggering_position)
|
||||
).astype(int)
|
||||
is_in_zone = self.mask[clipped_anchors[:, 1], clipped_anchors[:, 0]]
|
||||
self.current_count = int(np.sum(is_in_zone))
|
||||
|
||||
+311
-14
@@ -1,8 +1,11 @@
|
||||
from typing import List, Optional, Tuple
|
||||
from itertools import chain
|
||||
from typing import Any, Dict, List, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
|
||||
MIN_POLYGON_POINT_COUNT = 3
|
||||
|
||||
|
||||
@@ -110,17 +113,15 @@ def non_max_suppression(
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def clip_boxes(
|
||||
boxes_xyxy: np.ndarray, frame_resolution_wh: Tuple[int, int]
|
||||
) -> np.ndarray:
|
||||
def clip_boxes(xyxy: np.ndarray, resolution_wh: Tuple[int, int]) -> np.ndarray:
|
||||
"""
|
||||
Clips bounding boxes coordinates to fit within the frame resolution.
|
||||
|
||||
Args:
|
||||
boxes_xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each
|
||||
xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each
|
||||
row corresponds to a bounding box in
|
||||
the format `(x_min, y_min, x_max, y_max)`.
|
||||
frame_resolution_wh (Tuple[int, int]): A tuple of the form `(width, height)`
|
||||
resolution_wh (Tuple[int, int]): A tuple of the form `(width, height)`
|
||||
representing the resolution of the frame.
|
||||
|
||||
Returns:
|
||||
@@ -128,8 +129,8 @@ def clip_boxes(
|
||||
corresponds to a bounding box with coordinates clipped to fit
|
||||
within the frame resolution.
|
||||
"""
|
||||
result = np.copy(boxes_xyxy)
|
||||
width, height = frame_resolution_wh
|
||||
result = np.copy(xyxy)
|
||||
width, height = resolution_wh
|
||||
result[:, [0, 2]] = result[:, [0, 2]].clip(0, width)
|
||||
result[:, [1, 3]] = result[:, [1, 3]].clip(0, height)
|
||||
return result
|
||||
@@ -301,7 +302,6 @@ def extract_ultralytics_masks(yolov8_results) -> Optional[np.ndarray]:
|
||||
orig_shape = yolov8_results.orig_shape
|
||||
inference_shape = tuple(yolov8_results.masks.data.shape[1:])
|
||||
|
||||
gain = 0
|
||||
pad = (0, 0)
|
||||
|
||||
if inference_shape != orig_shape:
|
||||
@@ -333,13 +333,28 @@ def extract_ultralytics_masks(yolov8_results) -> Optional[np.ndarray]:
|
||||
|
||||
def process_roboflow_result(
|
||||
roboflow_result: dict,
|
||||
) -> Tuple[np.ndarray, np.ndarray, np.ndarray, Optional[np.ndarray], np.ndarray]:
|
||||
) -> Tuple[
|
||||
np.ndarray,
|
||||
np.ndarray,
|
||||
np.ndarray,
|
||||
Optional[np.ndarray],
|
||||
Optional[np.ndarray],
|
||||
Dict[str, List[np.ndarray]],
|
||||
]:
|
||||
if not roboflow_result["predictions"]:
|
||||
return np.empty((0, 4)), np.empty(0), np.empty(0), None, None
|
||||
return (
|
||||
np.empty((0, 4)),
|
||||
np.empty(0),
|
||||
np.empty(0),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.empty(0)},
|
||||
)
|
||||
|
||||
xyxy = []
|
||||
confidence = []
|
||||
class_id = []
|
||||
class_name = []
|
||||
masks = []
|
||||
tracker_ids = []
|
||||
|
||||
@@ -359,6 +374,7 @@ def process_roboflow_result(
|
||||
if "points" not in prediction:
|
||||
xyxy.append([x_min, y_min, x_max, y_max])
|
||||
class_id.append(prediction["class_id"])
|
||||
class_name.append(prediction["class"])
|
||||
confidence.append(prediction["confidence"])
|
||||
if "tracker_id" in prediction:
|
||||
tracker_ids.append(prediction["tracker_id"])
|
||||
@@ -369,6 +385,7 @@ def process_roboflow_result(
|
||||
mask = polygon_to_mask(polygon, resolution_wh=(image_width, image_height))
|
||||
xyxy.append([x_min, y_min, x_max, y_max])
|
||||
class_id.append(prediction["class_id"])
|
||||
class_name.append(prediction["class"])
|
||||
confidence.append(prediction["confidence"])
|
||||
masks.append(mask)
|
||||
if "tracker_id" in prediction:
|
||||
@@ -377,21 +394,301 @@ def process_roboflow_result(
|
||||
xyxy = np.array(xyxy) if len(xyxy) > 0 else np.empty((0, 4))
|
||||
confidence = np.array(confidence) if len(confidence) > 0 else np.empty(0)
|
||||
class_id = np.array(class_id).astype(int) if len(class_id) > 0 else np.empty(0)
|
||||
class_name = np.array(class_name) if len(class_name) > 0 else np.empty(0)
|
||||
masks = np.array(masks, dtype=bool) if len(masks) > 0 else None
|
||||
tracker_id = np.array(tracker_ids).astype(int) if len(tracker_ids) > 0 else None
|
||||
data = {CLASS_NAME_DATA_FIELD: class_name}
|
||||
|
||||
return xyxy, confidence, class_id, masks, tracker_id
|
||||
return xyxy, confidence, class_id, masks, tracker_id, data
|
||||
|
||||
|
||||
def move_boxes(xyxy: np.ndarray, offset: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Args:
|
||||
Parameters:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing the bounding boxes
|
||||
coordinates in format `[x1, y1, x2, y2]`
|
||||
offset (np.array): An array of shape `(2,)` containing offset values in format
|
||||
is `[dx, dy]`.
|
||||
|
||||
Returns:
|
||||
(np.ndarray) repositioned bounding boxes
|
||||
np.ndarray: Repositioned bounding boxes.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> boxes = np.array([[10, 10, 20, 20], [30, 30, 40, 40]])
|
||||
>>> offset = np.array([5, 5])
|
||||
>>> sv.move_boxes(boxes, offset)
|
||||
... array([
|
||||
... [15, 15, 25, 25],
|
||||
... [35, 35, 45, 45]
|
||||
... ])
|
||||
```
|
||||
"""
|
||||
return xyxy + np.hstack([offset, offset])
|
||||
|
||||
|
||||
def scale_boxes(xyxy: np.ndarray, factor: float) -> np.ndarray:
|
||||
"""
|
||||
Scale the dimensions of bounding boxes.
|
||||
|
||||
Parameters:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing the bounding boxes
|
||||
coordinates in format `[x1, y1, x2, y2]`
|
||||
factor (float): A float value representing the factor by which the box
|
||||
dimensions are scaled. A factor greater than 1 enlarges the boxes, while a
|
||||
factor less than 1 shrinks them.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Scaled bounding boxes.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> boxes = np.array([[10, 10, 20, 20], [30, 30, 40, 40]])
|
||||
>>> factor = 1.5
|
||||
>>> sv.scale_boxes(boxes, factor)
|
||||
... array([
|
||||
... [ 7.5, 7.5, 22.5, 22.5],
|
||||
... [27.5, 27.5, 42.5, 42.5]
|
||||
... ])
|
||||
```
|
||||
"""
|
||||
centers = (xyxy[:, :2] + xyxy[:, 2:]) / 2
|
||||
new_sizes = (xyxy[:, 2:] - xyxy[:, :2]) * factor
|
||||
return np.concatenate((centers - new_sizes / 2, centers + new_sizes / 2), axis=1)
|
||||
|
||||
|
||||
def calculate_masks_centroids(masks: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Calculate the centroids of binary masks in a tensor.
|
||||
|
||||
Parameters:
|
||||
masks (np.ndarray): A 3D NumPy array of shape (num_masks, height, width).
|
||||
Each 2D array in the tensor represents a binary mask.
|
||||
|
||||
Returns:
|
||||
A 2D NumPy array of shape (num_masks, 2), where each row contains the x and y
|
||||
coordinates (in that order) of the centroid of the corresponding mask.
|
||||
"""
|
||||
num_masks, height, width = masks.shape
|
||||
total_pixels = masks.sum(axis=(1, 2))
|
||||
|
||||
# offset for 1-based indexing
|
||||
vertical_indices, horizontal_indices = np.indices((height, width)) + 0.5
|
||||
# avoid division by zero for empty masks
|
||||
total_pixels[total_pixels == 0] = 1
|
||||
|
||||
def sum_over_mask(indices: np.ndarray, axis: tuple) -> np.ndarray:
|
||||
return np.tensordot(masks, indices, axes=axis)
|
||||
|
||||
aggregation_axis = ([1, 2], [0, 1])
|
||||
centroid_x = sum_over_mask(horizontal_indices, aggregation_axis) / total_pixels
|
||||
centroid_y = sum_over_mask(vertical_indices, aggregation_axis) / total_pixels
|
||||
|
||||
return np.column_stack((centroid_x, centroid_y)).astype(int)
|
||||
|
||||
|
||||
def validate_xyxy(xyxy: Any) -> None:
|
||||
expected_shape = "(_, 4)"
|
||||
actual_shape = str(getattr(xyxy, "shape", None))
|
||||
is_valid = isinstance(xyxy, np.ndarray) and xyxy.ndim == 2 and xyxy.shape[1] == 4
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"xyxy must be a 2D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_mask(mask: Any, n: int) -> None:
|
||||
expected_shape = f"({n}, H, W)"
|
||||
actual_shape = str(getattr(mask, "shape", None))
|
||||
is_valid = mask is None or (
|
||||
isinstance(mask, np.ndarray) and len(mask.shape) == 3 and mask.shape[0] == n
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"mask must be a 3D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_class_id(class_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(class_id, "shape", None))
|
||||
is_valid = class_id is None or (
|
||||
isinstance(class_id, np.ndarray) and class_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"class_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_confidence(confidence: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(confidence, "shape", None))
|
||||
is_valid = confidence is None or (
|
||||
isinstance(confidence, np.ndarray) and confidence.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"confidence must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(tracker_id, "shape", None))
|
||||
is_valid = tracker_id is None or (
|
||||
isinstance(tracker_id, np.ndarray) and tracker_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"tracker_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_data(data: Dict[str, Any], n: int) -> None:
|
||||
for key, value in data.items():
|
||||
if isinstance(value, list):
|
||||
if len(value) != n:
|
||||
raise ValueError(f"Length of list for key '{key}' must be {n}")
|
||||
elif isinstance(value, np.ndarray):
|
||||
if value.ndim == 1 and value.shape[0] != n:
|
||||
raise ValueError(f"Shape of np.ndarray for key '{key}' must be ({n},)")
|
||||
elif value.ndim > 1 and value.shape[0] != n:
|
||||
raise ValueError(
|
||||
f"First dimension of np.ndarray for key '{key}' must have size {n}"
|
||||
)
|
||||
else:
|
||||
raise ValueError(f"Value for key '{key}' must be a list or np.ndarray")
|
||||
|
||||
|
||||
def validate_detections_fields(
|
||||
xyxy: Any,
|
||||
mask: Any,
|
||||
class_id: Any,
|
||||
confidence: Any,
|
||||
tracker_id: Any,
|
||||
data: Dict[str, Any],
|
||||
) -> None:
|
||||
validate_xyxy(xyxy)
|
||||
n = len(xyxy)
|
||||
validate_mask(mask, n)
|
||||
validate_class_id(class_id, n)
|
||||
validate_confidence(confidence, n)
|
||||
validate_tracker_id(tracker_id, n)
|
||||
validate_data(data, n)
|
||||
|
||||
|
||||
def is_data_equal(data_a: Dict[str, np.ndarray], data_b: Dict[str, np.ndarray]) -> bool:
|
||||
"""
|
||||
Compares the data payloads of two Detections instances.
|
||||
|
||||
Args:
|
||||
data_a, data_b: The data payloads of the instances.
|
||||
|
||||
Returns:
|
||||
True if the data payloads are equal, False otherwise.
|
||||
"""
|
||||
return set(data_a.keys()) == set(data_b.keys()) and all(
|
||||
np.array_equal(data_a[key], data_b[key]) for key in data_a
|
||||
)
|
||||
|
||||
|
||||
def merge_data(
|
||||
data_list: List[Dict[str, Union[np.ndarray, List]]],
|
||||
) -> Dict[str, Union[np.ndarray, List]]:
|
||||
"""
|
||||
Merges the data payloads of a list of Detections instances.
|
||||
|
||||
Args:
|
||||
data_list: The data payloads of the instances.
|
||||
|
||||
Returns:
|
||||
A single data payload containing the merged data, preserving the original data
|
||||
types (list or np.ndarray).
|
||||
|
||||
Raises:
|
||||
ValueError: If data values within a single object have different lengths or if
|
||||
dictionaries have different keys.
|
||||
"""
|
||||
if not data_list:
|
||||
return {}
|
||||
|
||||
all_keys_sets = [set(data.keys()) for data in data_list]
|
||||
if not all(keys_set == all_keys_sets[0] for keys_set in all_keys_sets):
|
||||
raise ValueError("All data dictionaries must have the same keys to merge.")
|
||||
|
||||
for data in data_list:
|
||||
lengths = [len(value) for value in data.values()]
|
||||
if len(set(lengths)) > 1:
|
||||
raise ValueError(
|
||||
"All data values within a single object must have equal length."
|
||||
)
|
||||
|
||||
merged_data = {key: [] for key in all_keys_sets[0]}
|
||||
|
||||
for data in data_list:
|
||||
for key in merged_data:
|
||||
merged_data[key].append(data[key])
|
||||
|
||||
for key in merged_data:
|
||||
if all(isinstance(item, list) for item in merged_data[key]):
|
||||
merged_data[key] = list(chain.from_iterable(merged_data[key]))
|
||||
elif all(isinstance(item, np.ndarray) for item in merged_data[key]):
|
||||
ndim = merged_data[key][0].ndim
|
||||
if ndim == 1:
|
||||
merged_data[key] = np.hstack(merged_data[key])
|
||||
elif ndim > 1:
|
||||
merged_data[key] = np.vstack(merged_data[key])
|
||||
else:
|
||||
raise ValueError(f"Unexpected array dimension for key '{key}'.")
|
||||
else:
|
||||
raise ValueError(
|
||||
f"Inconsistent data types for key '{key}'. Only np.ndarray and list "
|
||||
f"types are allowed."
|
||||
)
|
||||
|
||||
return merged_data
|
||||
|
||||
|
||||
def get_data_item(
|
||||
data: Dict[str, Union[np.ndarray, List]],
|
||||
index: Union[int, slice, List[int], np.ndarray],
|
||||
) -> Dict[str, Union[np.ndarray, List]]:
|
||||
"""
|
||||
Retrieve a subset of the data dictionary based on the given index.
|
||||
|
||||
Args:
|
||||
data: The data dictionary of the Detections object.
|
||||
index: The index or indices specifying the subset to retrieve.
|
||||
|
||||
Returns:
|
||||
A subset of the data dictionary corresponding to the specified index.
|
||||
"""
|
||||
subset_data = {}
|
||||
for key, value in data.items():
|
||||
if isinstance(value, np.ndarray):
|
||||
subset_data[key] = value[index]
|
||||
elif isinstance(value, list):
|
||||
if isinstance(index, slice):
|
||||
subset_data[key] = value[index]
|
||||
elif isinstance(index, (list, np.ndarray)):
|
||||
subset_data[key] = [value[i] for i in index]
|
||||
elif isinstance(index, int):
|
||||
subset_data[key] = [value[index]]
|
||||
else:
|
||||
raise TypeError(f"Unsupported index type: {type(index)}")
|
||||
else:
|
||||
raise TypeError(f"Unsupported data type for key '{key}': {type(value)}")
|
||||
|
||||
return subset_data
|
||||
|
||||
@@ -71,6 +71,21 @@ class Color:
|
||||
r, g, b = (int(color_hex[i : i + 2], 16) for i in range(0, 6, 2))
|
||||
return cls(r, g, b)
|
||||
|
||||
def as_hex(self) -> str:
|
||||
"""
|
||||
Converts the Color instance to a hex string.
|
||||
|
||||
Returns:
|
||||
str: The hexadecimal color string.
|
||||
|
||||
Example:
|
||||
```
|
||||
>>> Color(r=255, g=0, b=255).as_hex()
|
||||
'#ff00ff'
|
||||
```
|
||||
"""
|
||||
return f"#{self.r:02x}{self.g:02x}{self.b:02x}"
|
||||
|
||||
def as_rgb(self) -> Tuple[int, int, int]:
|
||||
"""
|
||||
Returns the color as an RGB tuple.
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
import os
|
||||
from typing import Optional, Union
|
||||
from typing import Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -231,3 +231,41 @@ def draw_image(
|
||||
scene[rect.y : rect.y + rect.height, rect.x : rect.x + rect.width] = blended_roi
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
def calculate_dynamic_text_scale(resolution_wh: Tuple[int, int]) -> float:
|
||||
"""
|
||||
Calculate a dynamic font scale based on the resolution of an image.
|
||||
|
||||
Parameters:
|
||||
resolution_wh (Tuple[int, int]): A tuple representing the width and height
|
||||
of the image.
|
||||
|
||||
Returns:
|
||||
float: The calculated font scale factor.
|
||||
"""
|
||||
return min(resolution_wh) * 1e-3
|
||||
|
||||
|
||||
def calculate_dynamic_line_thickness(resolution_wh: Tuple[int, int]) -> int:
|
||||
"""
|
||||
Calculate a dynamic line thickness based on the resolution of an image.
|
||||
|
||||
Parameters:
|
||||
resolution_wh (Tuple[int, int]): A tuple representing the width and height
|
||||
of the image.
|
||||
|
||||
Returns:
|
||||
int: The calculated line thickness in pixels.
|
||||
"""
|
||||
min_dimension = min(resolution_wh)
|
||||
if min_dimension < 480:
|
||||
return 2
|
||||
if min_dimension < 720:
|
||||
return 2
|
||||
if min_dimension < 1080:
|
||||
return 2
|
||||
if min_dimension < 2160:
|
||||
return 4
|
||||
else:
|
||||
return 4
|
||||
|
||||
@@ -19,6 +19,7 @@ class Position(Enum):
|
||||
BOTTOM_LEFT = "BOTTOM_LEFT"
|
||||
BOTTOM_CENTER = "BOTTOM_CENTER"
|
||||
BOTTOM_RIGHT = "BOTTOM_RIGHT"
|
||||
CENTER_OF_MASS = "CENTER_OF_MASS"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
|
||||
@@ -57,19 +57,24 @@ def list_files_with_extensions(
|
||||
return files_with_extensions
|
||||
|
||||
|
||||
def read_txt_file(file_path: str) -> List[str]:
|
||||
def read_txt_file(file_path: str, skip_empty: bool = False) -> List[str]:
|
||||
"""
|
||||
Read a text file and return a list of strings without newline characters.
|
||||
Optionally skip empty lines.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the text file.
|
||||
skip_empty (bool): If True, skip lines that are empty or contain only
|
||||
whitespace. Default is False.
|
||||
|
||||
Returns:
|
||||
List[str]: A list of strings representing the lines in the text file.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
lines = file.readlines()
|
||||
lines = [line.rstrip("\n") for line in lines]
|
||||
if skip_empty:
|
||||
lines = [line.rstrip("\n") for line in file if line.strip()]
|
||||
else:
|
||||
lines = [line.rstrip("\n") for line in file]
|
||||
|
||||
return lines
|
||||
|
||||
|
||||
@@ -74,7 +74,7 @@ class VideoSink:
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> video_info = sv.VideoInfo.from_video_path('source.mp4')
|
||||
>>> frames_generator = get_video_frames_generator('source.mp4')
|
||||
>>> frames_generator = sv.get_video_frames_generator('source.mp4')
|
||||
|
||||
>>> with sv.VideoSink(target_path='target.mp4', video_info=video_info) as sink:
|
||||
... for frame in frames_generator:
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.utils import mock_detections
|
||||
from test.test_utils import mock_detections
|
||||
from typing import Optional
|
||||
|
||||
import numpy as np
|
||||
|
||||
@@ -1,8 +1,8 @@
|
||||
import xml.etree.ElementTree as ET
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.utils import mock_detections
|
||||
from test.test_utils import mock_detections
|
||||
from typing import List, Optional
|
||||
|
||||
import defusedxml.ElementTree as ET
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
@@ -122,7 +122,7 @@ NO_DETECTIONS = """<annotation></annotation>"""
|
||||
["test"],
|
||||
(100, 100),
|
||||
False,
|
||||
mock_detections(np.array([[0, 0, 10, 10]]), None, [0]),
|
||||
mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
@@ -130,7 +130,9 @@ NO_DETECTIONS = """<annotation></annotation>"""
|
||||
["test"],
|
||||
(100, 100),
|
||||
False,
|
||||
mock_detections(np.array([[0, 0, 10, 10], [10, 10, 20, 20]]), None, [0, 0]),
|
||||
mock_detections(
|
||||
xyxy=np.array([[0, 0, 10, 10], [10, 10, 20, 20]]), class_id=[0, 0]
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
@@ -139,9 +141,8 @@ NO_DETECTIONS = """<annotation></annotation>"""
|
||||
(100, 100),
|
||||
False,
|
||||
mock_detections(
|
||||
np.array([[0, 0, 10, 10], [20, 30, 30, 40], [10, 10, 20, 20]]),
|
||||
None,
|
||||
[0, 0, 1],
|
||||
xyxy=np.array([[0, 0, 10, 10], [20, 30, 30, 40], [10, 10, 20, 20]]),
|
||||
class_id=[0, 0, 1],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
@@ -150,7 +151,7 @@ NO_DETECTIONS = """<annotation></annotation>"""
|
||||
[],
|
||||
(100, 100),
|
||||
False,
|
||||
mock_detections(np.empty((0, 4)), None, []),
|
||||
mock_detections(xyxy=np.empty((0, 4)), class_id=[]),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
],
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.utils import mock_detections
|
||||
from test.test_utils import mock_detections
|
||||
from typing import List, Optional
|
||||
|
||||
import numpy as np
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.utils import mock_detections
|
||||
from test.test_utils import mock_detections
|
||||
from typing import Dict, List, Optional, Tuple, TypeVar
|
||||
|
||||
import pytest
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.utils import mock_detections
|
||||
from test.test_utils import mock_detections
|
||||
from typing import List, Optional, Union
|
||||
|
||||
import numpy as np
|
||||
@@ -153,7 +153,10 @@ def test_getitem(
|
||||
DoesNotRaise(),
|
||||
), # single detection with xyxy field
|
||||
(
|
||||
[mock_detections(xyxy=[[10, 10, 20, 20]]), Detections.empty()],
|
||||
[
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
mock_detections(xyxy=np.empty((0, 4), dtype=np.float32)),
|
||||
],
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
DoesNotRaise(),
|
||||
), # single detection with xyxy field + empty detection
|
||||
@@ -171,7 +174,7 @@ def test_getitem(
|
||||
mock_detections(xyxy=[[20, 20, 30, 30]]),
|
||||
],
|
||||
mock_detections(xyxy=[[10, 10, 20, 20], [20, 20, 30, 30]]),
|
||||
DoesNotRaise(),
|
||||
pytest.raises(ValueError),
|
||||
), # detection with xyxy, class_id fields + detection with xyxy field
|
||||
(
|
||||
[
|
||||
@@ -181,6 +184,16 @@ def test_getitem(
|
||||
mock_detections(xyxy=[[10, 10, 20, 20], [20, 20, 30, 30]], class_id=[0, 1]),
|
||||
DoesNotRaise(),
|
||||
), # two detections with xyxy, class_id fields
|
||||
(
|
||||
[
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], data={"test": [1]}),
|
||||
mock_detections(xyxy=[[20, 20, 30, 30]], data={"test": [2]}),
|
||||
],
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 20, 20], [20, 20, 30, 30]], data={"test": [1, 2]}
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # two detections with xyxy, data fields
|
||||
],
|
||||
)
|
||||
def test_merge(
|
||||
@@ -270,6 +283,57 @@ def test_get_anchor_coordinates(
|
||||
expected_result: np.ndarray,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
result = detections.get_anchor_coordinates(anchor)
|
||||
result = detections.get_anchors_coordinates(anchor)
|
||||
with exception:
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"detections_a, detections_b, expected_result",
|
||||
[
|
||||
(
|
||||
Detections.empty(),
|
||||
Detections.empty(),
|
||||
True,
|
||||
), # empty detections
|
||||
(
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
True,
|
||||
), # detections with xyxy field
|
||||
(
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], confidence=[0.5]),
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], confidence=[0.5]),
|
||||
True,
|
||||
), # detections with xyxy, confidence fields
|
||||
(
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], confidence=[0.5]),
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
False,
|
||||
), # detection with xyxy field + detection with xyxy, confidence fields
|
||||
(
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], data={"test": [1]}),
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], data={"test": [1]}),
|
||||
True,
|
||||
), # detections with xyxy, data fields
|
||||
(
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], data={"test": [1]}),
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
False,
|
||||
), # detection with xyxy field + detection with xyxy, data fields
|
||||
(
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], data={"test_1": [1]}),
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], data={"test_2": [1]}),
|
||||
False,
|
||||
), # detections with xyxy, and different data field names
|
||||
(
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], data={"test_1": [1]}),
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]], data={"test_1": [3]}),
|
||||
False,
|
||||
), # detections with xyxy, and different data field values
|
||||
],
|
||||
)
|
||||
def test_equal(
|
||||
detections_a: Detections, detections_b: Detections, expected_result: bool
|
||||
) -> None:
|
||||
assert (detections_a == detections_b) == expected_result
|
||||
|
||||
+458
-10
@@ -1,15 +1,20 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from typing import List, Optional, Tuple
|
||||
from typing import Any, Dict, List, Optional, Tuple
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.utils import (
|
||||
calculate_masks_centroids,
|
||||
clip_boxes,
|
||||
filter_polygons_by_area,
|
||||
get_data_item,
|
||||
merge_data,
|
||||
move_boxes,
|
||||
non_max_suppression,
|
||||
process_roboflow_result,
|
||||
scale_boxes,
|
||||
)
|
||||
|
||||
TEST_MASK = np.zeros((1, 1000, 1000), dtype=bool)
|
||||
@@ -122,7 +127,7 @@ def test_non_max_suppression(
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"boxes_xyxy, frame_resolution_wh, expected_result",
|
||||
"xyxy, resolution_wh, expected_result",
|
||||
[
|
||||
(
|
||||
np.empty(shape=(0, 4)),
|
||||
@@ -157,11 +162,11 @@ def test_non_max_suppression(
|
||||
],
|
||||
)
|
||||
def test_clip_boxes(
|
||||
boxes_xyxy: np.ndarray,
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
xyxy: np.ndarray,
|
||||
resolution_wh: Tuple[int, int],
|
||||
expected_result: np.ndarray,
|
||||
) -> None:
|
||||
result = clip_boxes(boxes_xyxy=boxes_xyxy, frame_resolution_wh=frame_resolution_wh)
|
||||
result = clip_boxes(xyxy=xyxy, resolution_wh=resolution_wh)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@@ -264,7 +269,14 @@ def test_filter_polygons_by_area(
|
||||
[
|
||||
(
|
||||
{"predictions": [], "image": {"width": 1000, "height": 1000}},
|
||||
(np.empty((0, 4)), np.empty(0), np.empty(0), None, None),
|
||||
(
|
||||
np.empty((0, 4)),
|
||||
np.empty(0),
|
||||
np.empty(0),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.empty(0)},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # empty result
|
||||
(
|
||||
@@ -288,6 +300,7 @@ def test_filter_polygons_by_area(
|
||||
np.array([0]),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.array(["person"])},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # single correct object detection result
|
||||
@@ -323,6 +336,7 @@ def test_filter_polygons_by_area(
|
||||
np.array([0, 7]),
|
||||
None,
|
||||
np.array([1, 2]),
|
||||
{CLASS_NAME_DATA_FIELD: np.array(["person", "truck"])},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # two correct object detection result
|
||||
@@ -343,7 +357,14 @@ def test_filter_polygons_by_area(
|
||||
],
|
||||
"image": {"width": 1000, "height": 1000},
|
||||
},
|
||||
(np.empty((0, 4)), np.empty(0), np.empty(0), None, None),
|
||||
(
|
||||
np.empty((0, 4)),
|
||||
np.empty(0),
|
||||
np.empty(0),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.empty(0)},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # single incorrect instance segmentation result with no points
|
||||
(
|
||||
@@ -362,7 +383,14 @@ def test_filter_polygons_by_area(
|
||||
],
|
||||
"image": {"width": 1000, "height": 1000},
|
||||
},
|
||||
(np.empty((0, 4)), np.empty(0), np.empty(0), None, None),
|
||||
(
|
||||
np.empty((0, 4)),
|
||||
np.empty(0),
|
||||
np.empty(0),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.empty(0)},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # single incorrect instance segmentation result with no enough points
|
||||
(
|
||||
@@ -392,6 +420,7 @@ def test_filter_polygons_by_area(
|
||||
np.array([0]),
|
||||
TEST_MASK,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.array(["person"])},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # single incorrect instance segmentation result with no enough points
|
||||
@@ -432,6 +461,7 @@ def test_filter_polygons_by_area(
|
||||
np.array([0]),
|
||||
TEST_MASK,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.array(["person"])},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # two instance segmentation results - one correct, one incorrect
|
||||
@@ -455,6 +485,15 @@ def test_process_roboflow_result(
|
||||
assert (result[4] is None and expected_result[4] is None) or (
|
||||
np.array_equal(result[4], expected_result[4])
|
||||
)
|
||||
for key in result[5]:
|
||||
if isinstance(result[5][key], np.ndarray):
|
||||
assert np.array_equal(
|
||||
result[5][key], expected_result[5][key]
|
||||
), f"Mismatch in arrays for key {key}"
|
||||
else:
|
||||
assert (
|
||||
result[5][key] == expected_result[5][key]
|
||||
), f"Mismatch in non-array data for key {key}"
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
@@ -498,5 +537,414 @@ def test_move_boxes(
|
||||
expected_result: np.ndarray,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
result = move_boxes(xyxy=xyxy, offset=offset)
|
||||
assert np.array_equal(result, expected_result)
|
||||
with exception:
|
||||
result = move_boxes(xyxy=xyxy, offset=offset)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"xyxy, factor, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.empty(shape=(0, 4)),
|
||||
2.0,
|
||||
np.empty(shape=(0, 4)),
|
||||
DoesNotRaise(),
|
||||
), # empty xyxy array
|
||||
(
|
||||
np.array([[0, 0, 10, 10]]),
|
||||
1.0,
|
||||
np.array([[0, 0, 10, 10]]),
|
||||
DoesNotRaise(),
|
||||
), # single box with factor equal to 1.0
|
||||
(
|
||||
np.array([[0, 0, 10, 10]]),
|
||||
2.0,
|
||||
np.array([[-5, -5, 15, 15]]),
|
||||
DoesNotRaise(),
|
||||
), # single box with factor equal to 2.0
|
||||
(
|
||||
np.array([[0, 0, 10, 10]]),
|
||||
0.5,
|
||||
np.array([[2.5, 2.5, 7.5, 7.5]]),
|
||||
DoesNotRaise(),
|
||||
), # single box with factor equal to 0.5
|
||||
(
|
||||
np.array([[0, 0, 10, 10], [10, 10, 30, 30]]),
|
||||
2.0,
|
||||
np.array([[-5, -5, 15, 15], [0, 0, 40, 40]]),
|
||||
DoesNotRaise(),
|
||||
), # two boxes with factor equal to 2.0
|
||||
],
|
||||
)
|
||||
def test_scale_boxes(
|
||||
xyxy: np.ndarray,
|
||||
factor: float,
|
||||
expected_result: np.ndarray,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = scale_boxes(xyxy=xyxy, factor=factor)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"masks, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[0, 0, 0, 0],
|
||||
[0, 0, 0, 0],
|
||||
[0, 0, 0, 0],
|
||||
[0, 0, 0, 0],
|
||||
]
|
||||
]
|
||||
),
|
||||
np.array([[0, 0]]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with all zeros
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[1, 1, 1, 1],
|
||||
[1, 1, 1, 1],
|
||||
[1, 1, 1, 1],
|
||||
[1, 1, 1, 1],
|
||||
]
|
||||
]
|
||||
),
|
||||
np.array([[2, 2]]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with all ones
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[0, 1, 1, 0],
|
||||
[1, 1, 1, 1],
|
||||
[1, 1, 1, 1],
|
||||
[0, 1, 1, 0],
|
||||
]
|
||||
]
|
||||
),
|
||||
np.array([[2, 2]]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with symmetric ones
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[0, 0, 0, 0],
|
||||
[0, 0, 1, 1],
|
||||
[0, 0, 1, 1],
|
||||
[0, 0, 0, 0],
|
||||
]
|
||||
]
|
||||
),
|
||||
np.array([[3, 2]]),
|
||||
DoesNotRaise(),
|
||||
), # single mask with asymmetric ones
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[0, 1, 1, 0],
|
||||
[1, 1, 1, 1],
|
||||
[1, 1, 1, 1],
|
||||
[0, 1, 1, 0],
|
||||
],
|
||||
[
|
||||
[0, 0, 0, 0],
|
||||
[0, 0, 1, 1],
|
||||
[0, 0, 1, 1],
|
||||
[0, 0, 0, 0],
|
||||
],
|
||||
]
|
||||
),
|
||||
np.array([[2, 2], [3, 2]]),
|
||||
DoesNotRaise(),
|
||||
), # two masks
|
||||
],
|
||||
)
|
||||
def test_calculate_masks_centroids(
|
||||
masks: np.ndarray,
|
||||
expected_result: np.ndarray,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = calculate_masks_centroids(masks=masks)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"data_list, expected_result, exception",
|
||||
[
|
||||
(
|
||||
[],
|
||||
{},
|
||||
DoesNotRaise(),
|
||||
), # empty data list
|
||||
(
|
||||
[{}],
|
||||
{},
|
||||
DoesNotRaise(),
|
||||
), # single empty data dict
|
||||
(
|
||||
[{}, {}],
|
||||
{},
|
||||
DoesNotRaise(),
|
||||
), # two empty data dicts
|
||||
(
|
||||
[
|
||||
{"test_1": []},
|
||||
],
|
||||
{"test_1": []},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and empty list values
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([])},
|
||||
],
|
||||
{"test_1": np.array([])},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and empty np.array values
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
],
|
||||
{"test_1": [1, 2, 3]},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
(
|
||||
[
|
||||
{"test_1": []},
|
||||
{"test_1": [3, 2, 1]},
|
||||
],
|
||||
{"test_1": [3, 2, 1]},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and empty and list values
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
{"test_1": [3, 2, 1]},
|
||||
],
|
||||
{"test_1": [1, 2, 3, 3, 2, 1]},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and list values
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
{"test_1": [3, 2, 1]},
|
||||
{"test_1": [1, 2, 3]},
|
||||
],
|
||||
{"test_1": [1, 2, 3, 3, 2, 1, 1, 2, 3]},
|
||||
DoesNotRaise(),
|
||||
), # three data dicts with the same field name and list values
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3]},
|
||||
{"test_2": [3, 2, 1]},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts with different field names
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([1, 2, 3])},
|
||||
{"test_1": np.array([3, 2, 1])},
|
||||
],
|
||||
{"test_1": np.array([1, 2, 3, 3, 2, 1])},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and np.array values as 1D arrays
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([[1, 2, 3]])},
|
||||
{"test_1": np.array([[3, 2, 1]])},
|
||||
],
|
||||
{"test_1": np.array([[1, 2, 3], [3, 2, 1]])},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field name and np.array values as 2D arrays
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": np.array(["a", "b", "c"])},
|
||||
{"test_1": np.array([3, 2, 1]), "test_2": np.array(["c", "b", "a"])},
|
||||
],
|
||||
{
|
||||
"test_1": np.array([1, 2, 3, 3, 2, 1]),
|
||||
"test_2": np.array(["a", "b", "c", "c", "b", "a"]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field names and np.array values
|
||||
(
|
||||
[
|
||||
{"test_1": [1, 2, 3], "test_2": np.array(["a", "b", "c"])},
|
||||
{"test_1": [3, 2, 1], "test_2": np.array(["c", "b", "a"])},
|
||||
],
|
||||
{
|
||||
"test_1": [1, 2, 3, 3, 2, 1],
|
||||
"test_2": np.array(["a", "b", "c", "c", "b", "a"]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # two data dicts with the same field names and mixed values
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([1, 2, 3])},
|
||||
{"test_1": np.array([[3, 2, 1]])},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts with the same field name and 1D and 2D arrays values
|
||||
(
|
||||
[
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": np.array(["a", "b"])},
|
||||
{"test_1": np.array([3, 2, 1]), "test_2": np.array(["c", "b", "a"])},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # two data dicts with the same field name and different length arrays values
|
||||
],
|
||||
)
|
||||
def test_merge_data(
|
||||
data_list: List[Dict[str, Any]],
|
||||
expected_result: Optional[Dict[str, Any]],
|
||||
exception: Exception,
|
||||
):
|
||||
with exception:
|
||||
result = merge_data(data_list=data_list)
|
||||
for key in result:
|
||||
if isinstance(result[key], np.ndarray):
|
||||
assert np.array_equal(
|
||||
result[key], expected_result[key]
|
||||
), f"Mismatch in arrays for key {key}"
|
||||
else:
|
||||
assert (
|
||||
result[key] == expected_result[key]
|
||||
), f"Mismatch in non-array data for key {key}"
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"data, index, expected_result, exception",
|
||||
[
|
||||
({}, 0, {}, DoesNotRaise()), # empty data dict
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
},
|
||||
0,
|
||||
{
|
||||
"test_1": [1],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
0,
|
||||
{
|
||||
"test_1": np.array([1]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
},
|
||||
slice(0, 2),
|
||||
{
|
||||
"test_1": [1, 2],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
slice(0, 2),
|
||||
{
|
||||
"test_1": np.array([1, 2]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
},
|
||||
-1,
|
||||
{
|
||||
"test_1": [3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
-1,
|
||||
{
|
||||
"test_1": np.array([3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
},
|
||||
[0, 2],
|
||||
{
|
||||
"test_1": [1, 3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
[0, 2],
|
||||
{
|
||||
"test_1": np.array([1, 3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
},
|
||||
np.array([0, 2]),
|
||||
{
|
||||
"test_1": [1, 3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
np.array([0, 2]),
|
||||
{
|
||||
"test_1": np.array([1, 3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_get_data_item(
|
||||
data: Dict[str, Any],
|
||||
index: Any,
|
||||
expected_result: Optional[Dict[str, Any]],
|
||||
exception: Exception,
|
||||
):
|
||||
with exception:
|
||||
result = get_data_item(data=data, index=index)
|
||||
for key in result:
|
||||
if isinstance(result[key], np.ndarray):
|
||||
assert np.array_equal(
|
||||
result[key], expected_result[key]
|
||||
), f"Mismatch in arrays for key {key}"
|
||||
else:
|
||||
assert (
|
||||
result[key] == expected_result[key]
|
||||
), f"Mismatch in non-array data for key {key}"
|
||||
|
||||
@@ -30,3 +30,22 @@ def test_color_from_hex(
|
||||
with exception:
|
||||
result = Color.from_hex(color_hex=color_hex)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"color, expected_result, exception",
|
||||
[
|
||||
(Color.white(), "#ffffff", DoesNotRaise()),
|
||||
(Color.black(), "#000000", DoesNotRaise()),
|
||||
(Color.red(), "#ff0000", DoesNotRaise()),
|
||||
(Color.green(), "#00ff00", DoesNotRaise()),
|
||||
(Color.blue(), "#0000ff", DoesNotRaise()),
|
||||
(Color(r=128, g=128, b=0), "#808000", DoesNotRaise()),
|
||||
],
|
||||
)
|
||||
def test_color_as_hex(
|
||||
color: Color, expected_result: Optional[str], exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = color.as_hex()
|
||||
assert result == expected_result
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.utils import assert_almost_equal, mock_detections
|
||||
from test.test_utils import assert_almost_equal, mock_detections
|
||||
from typing import Optional, Union
|
||||
|
||||
import numpy as np
|
||||
|
||||
@@ -0,0 +1,34 @@
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
|
||||
|
||||
def mock_detections(
|
||||
xyxy: List[List[float]],
|
||||
mask: Optional[List[np.ndarray]] = None,
|
||||
confidence: Optional[List[float]] = None,
|
||||
class_id: Optional[List[int]] = None,
|
||||
tracker_id: Optional[List[int]] = None,
|
||||
data: Optional[Dict[str, List[Any]]] = None,
|
||||
) -> Detections:
|
||||
def convert_data(data: Dict[str, List[Any]]):
|
||||
return {k: np.array(v) for k, v in data.items()}
|
||||
|
||||
return Detections(
|
||||
xyxy=np.array(xyxy, dtype=np.float32),
|
||||
mask=(mask if mask is None else np.array(mask, dtype=bool)),
|
||||
confidence=(
|
||||
confidence if confidence is None else np.array(confidence, dtype=np.float32)
|
||||
),
|
||||
class_id=(class_id if class_id is None else np.array(class_id, dtype=int)),
|
||||
tracker_id=(
|
||||
tracker_id if tracker_id is None else np.array(tracker_id, dtype=int)
|
||||
),
|
||||
data=convert_data(data) if data else {},
|
||||
)
|
||||
|
||||
|
||||
def assert_almost_equal(actual, expected, tolerance=1e-5):
|
||||
assert abs(actual - expected) < tolerance, f"Expected {expected}, but got {actual}."
|
||||
@@ -1,27 +0,0 @@
|
||||
from typing import List
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
|
||||
|
||||
def mock_detections(
|
||||
xyxy: List[List[float]],
|
||||
confidence: List[float] = None,
|
||||
class_id: List[int] = None,
|
||||
tracker_id: List[int] = None,
|
||||
) -> Detections:
|
||||
return Detections(
|
||||
xyxy=np.array(xyxy, dtype=np.float32),
|
||||
confidence=confidence
|
||||
if confidence is None
|
||||
else np.array(confidence, dtype=np.float32),
|
||||
class_id=class_id if class_id is None else np.array(class_id, dtype=int),
|
||||
tracker_id=tracker_id
|
||||
if tracker_id is None
|
||||
else np.array(tracker_id, dtype=int),
|
||||
)
|
||||
|
||||
|
||||
def assert_almost_equal(actual, expected, tolerance=1e-5):
|
||||
assert abs(actual - expected) < tolerance, f"Expected {expected}, but got {actual}."
|
||||
@@ -0,0 +1,64 @@
|
||||
import os
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from typing import List, Optional
|
||||
|
||||
import pytest
|
||||
|
||||
from supervision.utils.file import read_txt_file
|
||||
|
||||
FILE_1_CONTENT = """Line 1
|
||||
Line 2
|
||||
Line 3
|
||||
"""
|
||||
|
||||
FILE_2_CONTENT = """
|
||||
Line 2
|
||||
|
||||
Line 4
|
||||
|
||||
""" # noqa
|
||||
|
||||
FILE_3_CONTENT = """
|
||||
Line 2
|
||||
|
||||
Line 4
|
||||
|
||||
"""
|
||||
|
||||
|
||||
@pytest.fixture(scope="module", autouse=True)
|
||||
def setup_and_teardown_files():
|
||||
with open("file_1.txt", "w") as file:
|
||||
file.write(FILE_1_CONTENT)
|
||||
with open("file_2.txt", "w") as file:
|
||||
file.write(FILE_2_CONTENT)
|
||||
with open("file_3.txt", "w") as file:
|
||||
file.write(FILE_3_CONTENT)
|
||||
|
||||
yield
|
||||
|
||||
os.remove("file_1.txt")
|
||||
os.remove("file_2.txt")
|
||||
os.remove("file_3.txt")
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"file_name, skip_empty, expected_result, exception",
|
||||
[
|
||||
("file_1.txt", False, ["Line 1", "Line 2", "Line 3"], DoesNotRaise()),
|
||||
("file_2.txt", True, ["Line 2", "Line 4"], DoesNotRaise()),
|
||||
("file_2.txt", False, [" ", "Line 2", "", "Line 4", ""], DoesNotRaise()),
|
||||
("file_3.txt", True, ["Line 2", "Line 4"], DoesNotRaise()),
|
||||
("file_3.txt", False, ["", "Line 2", "", "Line 4", ""], DoesNotRaise()),
|
||||
("file_4.txt", True, None, pytest.raises(FileNotFoundError)),
|
||||
],
|
||||
)
|
||||
def test_read_txt_file(
|
||||
file_name: str,
|
||||
skip_empty: bool,
|
||||
expected_result: Optional[List[str]],
|
||||
exception: Exception,
|
||||
):
|
||||
with exception:
|
||||
result = read_txt_file(file_name, skip_empty)
|
||||
assert result == expected_result
|
||||
Reference in New Issue
Block a user