Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Jirka Borovec |
49ecac0376 | ||
|
dependabot[bot]
|
9251893bd9 | ||
|
dependabot[bot]
|
ccd7098f2f | ||
|
jirka
|
07d182be56 | ||
|
Vikas sainiandpre-commit-ci[bot]
|
cca3c14911 | ||
|
|
44546a13f2 | ||
|
|
4b60bbc9cc | ||
|
|
6918d44190 | ||
|
|
a48532f6f5 | ||
|
|
11a586c133 | ||
|
|
31e84f7909 | ||
|
jirka
|
7e765eb054 | ||
|
|
393ff52954 | ||
|
|
c9962c9262 | ||
|
|
04b6d45ea2 | ||
|
|
2854932965 | ||
|
|
bcc785fbb5 | ||
|
|
c0df72b84a | ||
|
|
15cf80abac | ||
|
Jirka Borovec
|
b9c24ddafd | ||
|
|
c2490e6015 | ||
|
Jirka Borovec
|
a914a00ab8 | ||
|
dependabot[bot]
|
d3a0a84dd5 | ||
|
SkalskiP
|
1e551ec9c0 | ||
|
SkalskiP
|
1fa735d0d9 | ||
|
Piotr Skalski
|
62a24d7960 | ||
|
Piotr Skalski
|
3d07099cf9 | ||
|
|
483e3e9335 | ||
|
|
e0e1abd865 | ||
|
|
117a9baab8 | ||
|
dependabot[bot]
|
497f336d13 | ||
|
jirka
|
ef8ba557a1 | ||
|
|
caf060521d | ||
|
Jirka Borovec
|
b8ebc14489 | ||
|
|
8a4063086f | ||
|
|
a549f44792 | ||
|
|
cb9d3dccb8 | ||
|
|
ace3ebd03e | ||
|
Jirka Borovecandpre-commit-ci[bot]
|
9faa4f6133 | ||
|
|
97f4951f08 | ||
|
|
3b485f719a | ||
|
|
c92458b70e | ||
|
dependabot[bot]
|
eef8c96d95 | ||
|
|
b82d6f95be | ||
|
|
b18a30ea1a | ||
|
|
35006d7342 | ||
|
|
3410d92daa | ||
|
Piotr SkalskiandCursor
|
5a8e211a04 | ||
|
Piotr Skalski
|
1e8a48559b | ||
|
|
e03111e67c | ||
|
Lourdhu RajuandClaude Opus 4.7
|
0c67942d32 | ||
|
|
7d2259669b | ||
|
|
fb02e5c959 | ||
|
|
918b6139ef | ||
|
|
81218c5f1b | ||
|
|
2c3a2ef6f9 | ||
|
|
2fdb970430 | ||
|
dependabot[bot]
|
fb2dec9775 | ||
|
|
befdb7c661 | ||
|
|
cb259065a5 | ||
|
Madhav-C
|
4b856f1c04 | ||
|
|
6461d3fbac | ||
|
Jirka Borovec
|
2c13b269e6 | ||
|
Jirka Borovec
|
f1176270eb | ||
|
|
5b883fed5b | ||
|
Jirka Borovec
|
e7376d558e | ||
|
dependabot[bot]
|
17d7717515 | ||
|
dependabot[bot]
|
7e6df44d86 | ||
|
|
01ec36b31d | ||
|
|
f4b0767a88 | ||
|
|
7e28315595 | ||
|
|
b68b41ae7a | ||
|
dependabot[bot]
|
6fb4e80837 | ||
|
|
7dce60697f | ||
|
dependabot[bot]
|
26ae68a2b6 | ||
|
dependabot[bot]
|
878e6414da | ||
|
|
2beeda7851 | ||
|
dependabot[bot]
|
6ec8fa9a23 | ||
|
Jirka Borovec
|
1f199de502 | ||
|
Jirka Borovec
|
d8a25481c4 | ||
|
|
87b1b86f39 | ||
|
pre-commit-ci[bot]
|
1170a90ffc | ||
|
dependabot[bot]
|
2e0e8d9132 | ||
|
Jirka BorovecandCopilot
|
15730b2b5d | ||
|
|
2db1e3af34 | ||
|
jirka
|
840226afce | ||
|
|
dc03ceac31 | ||
|
dependabot[bot]
|
f9ab57afde | ||
|
pre-commit-ci[bot]
|
fb19852919 |
+25
-73
@@ -2,129 +2,81 @@
|
||||
|
||||
## Our Pledge
|
||||
|
||||
We as members, contributors, and leaders pledge to make participation in our
|
||||
community a harassment-free experience for everyone, regardless of age, body
|
||||
size, visible or invisible disability, ethnicity, sex characteristics, gender
|
||||
identity and expression, level of experience, education, socioeconomic status,
|
||||
nationality, personal appearance, race, caste, color, religion, or sexual
|
||||
identity and orientation.
|
||||
We as members, contributors, and leaders pledge to make participation in our community a harassment-free experience for everyone, regardless of age, body size, visible or invisible disability, ethnicity, sex characteristics, gender identity and expression, level of experience, education, socioeconomic status, nationality, personal appearance, race, caste, color, religion, or sexual identity and orientation.
|
||||
|
||||
We pledge to act and interact in ways that contribute to an open, welcoming,
|
||||
diverse, inclusive, and healthy community.
|
||||
We pledge to act and interact in ways that contribute to an open, welcoming, diverse, inclusive, and healthy community.
|
||||
|
||||
## Our Standards
|
||||
|
||||
Examples of behavior that contributes to a positive environment for our
|
||||
community include:
|
||||
Examples of behavior that contributes to a positive environment for our community include:
|
||||
|
||||
- Demonstrating empathy and kindness toward other people
|
||||
- Being respectful of differing opinions, viewpoints, and experiences
|
||||
- Giving and gracefully accepting constructive feedback
|
||||
- Accepting responsibility and apologizing to those affected by our mistakes,
|
||||
and learning from the experience
|
||||
- Focusing on what is best not just for us as individuals, but for the overall
|
||||
community
|
||||
- Accepting responsibility and apologizing to those affected by our mistakes, and learning from the experience
|
||||
- Focusing on what is best not just for us as individuals, but for the overall community
|
||||
|
||||
Examples of unacceptable behavior include:
|
||||
|
||||
- The use of sexualized language or imagery, and sexual attention or advances of
|
||||
any kind
|
||||
- The use of sexualized language or imagery, and sexual attention or advances of any kind
|
||||
- Trolling, insulting or derogatory comments, and personal or political attacks
|
||||
- Public or private harassment
|
||||
- Publishing others' private information, such as a physical or email address,
|
||||
without their explicit permission
|
||||
- Other conduct which could reasonably be considered inappropriate in a
|
||||
professional setting
|
||||
- Publishing others' private information, such as a physical or email address, without their explicit permission
|
||||
- Other conduct which could reasonably be considered inappropriate in a professional setting
|
||||
|
||||
## Enforcement Responsibilities
|
||||
|
||||
Community leaders are responsible for clarifying and enforcing our standards of
|
||||
acceptable behavior and will take appropriate and fair corrective action in
|
||||
response to any behavior that they deem inappropriate, threatening, offensive,
|
||||
or harmful.
|
||||
Community leaders are responsible for clarifying and enforcing our standards of acceptable behavior and will take appropriate and fair corrective action in response to any behavior that they deem inappropriate, threatening, offensive, or harmful.
|
||||
|
||||
Community leaders have the right and responsibility to remove, edit, or reject
|
||||
comments, commits, code, wiki edits, issues, and other contributions that are
|
||||
not aligned to this Code of Conduct, and will communicate reasons for moderation
|
||||
decisions when appropriate.
|
||||
Community leaders have the right and responsibility to remove, edit, or reject comments, commits, code, wiki edits, issues, and other contributions that are not aligned to this Code of Conduct, and will communicate reasons for moderation decisions when appropriate.
|
||||
|
||||
## Scope
|
||||
|
||||
This Code of Conduct applies within all community spaces, and also applies when
|
||||
an individual is officially representing the community in public spaces.
|
||||
Examples of representing our community include using an official e-mail address,
|
||||
posting via an official social media account, or acting as an appointed
|
||||
representative at an online or offline event.
|
||||
This Code of Conduct applies within all community spaces, and also applies when an individual is officially representing the community in public spaces. Examples of representing our community include using an official e-mail address, posting via an official social media account, or acting as an appointed representative at an online or offline event.
|
||||
|
||||
## Enforcement
|
||||
|
||||
Instances of abusive, harassing, or otherwise unacceptable behavior may be
|
||||
reported to the community leaders responsible for enforcement at
|
||||
community-reports@roboflow.com.
|
||||
Instances of abusive, harassing, or otherwise unacceptable behavior may be reported to the community leaders responsible for enforcement at community-reports@roboflow.com.
|
||||
|
||||
All complaints will be reviewed and investigated promptly and fairly.
|
||||
|
||||
All community leaders are obligated to respect the privacy and security of the
|
||||
reporter of any incident.
|
||||
All community leaders are obligated to respect the privacy and security of the reporter of any incident.
|
||||
|
||||
## Enforcement Guidelines
|
||||
|
||||
Community leaders will follow these Community Impact Guidelines in determining
|
||||
the consequences for any action they deem in violation of this Code of Conduct:
|
||||
Community leaders will follow these Community Impact Guidelines in determining the consequences for any action they deem in violation of this Code of Conduct:
|
||||
|
||||
### 1. Correction
|
||||
|
||||
**Community Impact**: Use of inappropriate language or other behavior deemed
|
||||
unprofessional or unwelcome in the community.
|
||||
**Community Impact**: Use of inappropriate language or other behavior deemed unprofessional or unwelcome in the community.
|
||||
|
||||
**Consequence**: A private, written warning from community leaders, providing
|
||||
clarity around the nature of the violation and an explanation of why the
|
||||
behavior was inappropriate. A public apology may be requested.
|
||||
**Consequence**: A private, written warning from community leaders, providing clarity around the nature of the violation and an explanation of why the behavior was inappropriate. A public apology may be requested.
|
||||
|
||||
### 2. Warning
|
||||
|
||||
**Community Impact**: A violation through a single incident or series of
|
||||
actions.
|
||||
**Community Impact**: A violation through a single incident or series of actions.
|
||||
|
||||
**Consequence**: A warning with consequences for continued behavior. No
|
||||
interaction with the people involved, including unsolicited interaction with
|
||||
those enforcing the Code of Conduct, for a specified period of time. This
|
||||
includes avoiding interactions in community spaces as well as external channels
|
||||
like social media. Violating these terms may lead to a temporary or permanent
|
||||
ban.
|
||||
**Consequence**: A warning with consequences for continued behavior. No interaction with the people involved, including unsolicited interaction with those enforcing the Code of Conduct, for a specified period of time. This includes avoiding interactions in community spaces as well as external channels like social media. Violating these terms may lead to a temporary or permanent ban.
|
||||
|
||||
### 3. Temporary Ban
|
||||
|
||||
**Community Impact**: A serious violation of community standards, including
|
||||
sustained inappropriate behavior.
|
||||
**Community Impact**: A serious violation of community standards, including sustained inappropriate behavior.
|
||||
|
||||
**Consequence**: A temporary ban from any sort of interaction or public
|
||||
communication with the community for a specified period of time. No public or
|
||||
private interaction with the people involved, including unsolicited interaction
|
||||
with those enforcing the Code of Conduct, is allowed during this period.
|
||||
Violating these terms may lead to a permanent ban.
|
||||
**Consequence**: A temporary ban from any sort of interaction or public communication with the community for a specified period of time. No public or private interaction with the people involved, including unsolicited interaction with those enforcing the Code of Conduct, is allowed during this period. Violating these terms may lead to a permanent ban.
|
||||
|
||||
### 4. Permanent Ban
|
||||
|
||||
**Community Impact**: Demonstrating a pattern of violation of community
|
||||
standards, including sustained inappropriate behavior, harassment of an
|
||||
individual, or aggression toward or disparagement of classes of individuals.
|
||||
**Community Impact**: Demonstrating a pattern of violation of community standards, including sustained inappropriate behavior, harassment of an individual, or aggression toward or disparagement of classes of individuals.
|
||||
|
||||
**Consequence**: A permanent ban from any sort of public interaction within the
|
||||
community.
|
||||
**Consequence**: A permanent ban from any sort of public interaction within the community.
|
||||
|
||||
## Attribution
|
||||
|
||||
This Code of Conduct is adapted from the [Contributor Covenant][homepage],
|
||||
version 2.1, available at
|
||||
[https://www.contributor-covenant.org/version/2/1/code_of_conduct.html][v2.1].
|
||||
This Code of Conduct is adapted from the [Contributor Covenant][homepage], version 2.1, available at [https://www.contributor-covenant.org/version/2/1/code_of_conduct.html][v2.1].
|
||||
|
||||
Community Impact Guidelines were inspired by
|
||||
[Mozilla's code of conduct enforcement ladder][mozilla coc].
|
||||
Community Impact Guidelines were inspired by [Mozilla's code of conduct enforcement ladder][mozilla coc].
|
||||
|
||||
For answers to common questions about this code of conduct, see the FAQ at
|
||||
[https://www.contributor-covenant.org/faq][faq]. Translations are available at
|
||||
[https://www.contributor-covenant.org/translations][translations].
|
||||
For answers to common questions about this code of conduct, see the FAQ at [https://www.contributor-covenant.org/faq][faq]. Translations are available at [https://www.contributor-covenant.org/translations][translations].
|
||||
|
||||
[faq]: https://www.contributor-covenant.org/faq
|
||||
[homepage]: https://www.contributor-covenant.org
|
||||
|
||||
+121
-4
@@ -12,6 +12,7 @@ Please read and adhere to our [Code of Conduct](https://supervision.roboflow.com
|
||||
|
||||
- [Contribution Guidelines](#contribution-guidelines)
|
||||
- [Contributing Features](#contributing-features)
|
||||
- [API Design Principles](#api-design-principles)
|
||||
- [How to Contribute Changes](#how-to-contribute-changes)
|
||||
- [Installation for Contributors](#installation-for-contributors)
|
||||
- [Code Style and Quality](#code-style-and-quality)
|
||||
@@ -41,6 +42,15 @@ For example, counting objects that cross a line anywhere on an image is a common
|
||||
|
||||
Before you contribute a new feature, consider submitting an Issue to discuss the feature so the community can weigh in and assist.
|
||||
|
||||
### API Design Principles
|
||||
|
||||
Supervision APIs should remain generic, composable, and predictable across model families. Before adding a new integration, annotator option, or data conversion method, check the existing `sv.Detections`, `sv.KeyPoints`, and annotator patterns and follow these principles:
|
||||
|
||||
1. **Model integrations normalize raw external outputs into existing Supervision containers.** Use `sv.Detections` for detection, segmentation, and other instance-level predictions that include boxes, masks, class ids, confidence scores, or extra per-instance fields. Use `sv.KeyPoints` for standalone keypoint or pose predictions when keypoints exist independently of detection boxes (e.g. pure pose estimation, landmark detection on pre-cropped images). Use `Detections.keypoints` when keypoints are always co-incident with boxes from the same model — the field stores an `(n, K, 2)` or `(n, K, 3)` array where the optional third channel is per-point confidence in `[0, 1]`.
|
||||
2. **Do not add a `from_<model>` method when the model already returns a Supervision object.** `from_*` methods are for converting raw outputs from external packages such as Ultralytics, Transformers, Inference, or MediaPipe. If a model's `predict()` method already returns `sv.Detections`, keep that result type and store additional structured payloads in `detections.data` or `detections.metadata` using documented keys.
|
||||
3. **Annotators render data; filtering and visibility are container state.** Filtering by confidence, class id, tracker id, geometry, or custom data should happen before annotation through the container slicing APIs, for example `detections[detections.confidence > 0.7]` or `key_points[key_points.confidence > 0.5]`. Per-point presentation state, such as a `KeyPoints.visible` mask, may live on the container and be honored consistently by annotators.
|
||||
4. **Annotator constructor arguments should describe visual presentation, not model-quality gates.** Use constructor arguments for color, thickness, opacity, text, position, style, and generic visualization parameters such as sigma levels. Annotators may skip invalid geometry defensively, including missing points, zero-area boxes, non-finite coordinates, or points marked invisible on the container. They should not introduce confidence thresholds or model-specific quality gates as rendering options.
|
||||
|
||||
## How to Contribute Changes
|
||||
|
||||
First, fork this repository to your own GitHub account. Click "fork" in the top corner of the `supervision` repository to get started:
|
||||
@@ -230,9 +240,37 @@ All new functions and classes in `supervision` should include docstrings. This i
|
||||
|
||||
`supervision` adheres to the [Google Python docstring style](https://google.github.io/styleguide/pyguide.html#383-functions-and-methods). Please refer to the style guide while writing docstrings for your contribution.
|
||||
|
||||
Every docstring should include a usage example. When the example only uses `supervision`, NumPy, and the standard library — no optional extras, no external files or network access — strongly prefer `>>>` doctest format so it is automatically verified by the test suite. See [Doctests](#doctests) below for syntax guidance and for when fenced ```` ```python ```` blocks are appropriate instead.
|
||||
|
||||
### Type checking
|
||||
|
||||
Currently, there is no systematic type checking with mypy implemented in the project. This is a known limitation that may be addressed in future updates.
|
||||
Type hints are required on all new code. mypy is enforced by the pre-commit hook configured in `.pre-commit-config.yaml` — your PR will fail CI if mypy reports errors.
|
||||
|
||||
### Performance
|
||||
|
||||
- Avoid unnecessary copies of NumPy arrays.
|
||||
- Prefer vectorized operations over Python loops in hot paths.
|
||||
- Lazy-import heavy framework dependencies (`torch`, `transformers`, `ultralytics`) inside the function that needs them — never at module top level.
|
||||
|
||||
### Deprecation policy
|
||||
|
||||
**Minimum window**: deprecated APIs must remain for at least **3 minor releases** before removal. Example: deprecated in `0.29.0` → removed in `0.32.0`.
|
||||
|
||||
Use the appropriate mechanism depending on what is being deprecated:
|
||||
|
||||
- **Module-level alias**: `supervision.utils.internal.warn_deprecated` in the deprecated module's `__init__.py`
|
||||
- **Renamed parameter**: `supervision.utils.internal.deprecated_parameter` decorator
|
||||
- **Public function, method, or class**: `@deprecated` from `pydeprecate`
|
||||
|
||||
Always specify both the deprecation version and the planned removal version in the message or decorator arguments.
|
||||
|
||||
### Deprecated module aliases
|
||||
|
||||
`supervision.keypoint` is deprecated since `0.27.0` and will be removed in `0.30.0`. Always import from `supervision.key_points`:
|
||||
|
||||
```python
|
||||
from supervision.key_points import KeyPoints # correct
|
||||
```
|
||||
|
||||
## 📝 Documentation
|
||||
|
||||
@@ -258,9 +296,7 @@ You can learn more about mkdocs on the [mkdocs website](https://www.mkdocs.org/)
|
||||
|
||||
## 🧑🍳 Cookbooks
|
||||
|
||||
We are always looking for new examples and cookbooks to add to the `supervision`
|
||||
documentation. If you have a use case that you think would be helpful to others, please
|
||||
submit a PR with your example. Here are some guidelines for submitting a new example:
|
||||
We are always looking for new examples and cookbooks to add to the `supervision` documentation. If you have a use case that you think would be helpful to others, please submit a PR with your example. Here are some guidelines for submitting a new example:
|
||||
|
||||
- Create a new notebook in the [`docs/notebooks`](https://github.com/roboflow/supervision/tree/develop/docs/notebooks) folder.
|
||||
- Add a link to the new notebook in [`docs/theme/cookbooks.html`](https://github.com/roboflow/supervision/blob/develop/docs/theme/cookbooks.html). Make sure to add the path to the new notebook, as well as a title, labels, author and supervision version.
|
||||
@@ -286,6 +322,87 @@ To run tests with coverage:
|
||||
uv run pytest --cov=supervision
|
||||
```
|
||||
|
||||
### Test Structure
|
||||
|
||||
Follow **Arrange-Act-Assert (AAA)**: one setup block, one action, one assertion group per test. Never put two independent actions in the same test.
|
||||
|
||||
**Class grouping:** Group related tests into a class. The class name carries the unit under test; method names describe the expected outcome only — not the mechanism.
|
||||
|
||||
```python
|
||||
class TestDetectionsWithNms:
|
||||
def test_keeps_highest_confidence_detection(self): ...
|
||||
def test_suppresses_lower_score_when_overlap_exceeds_threshold(self): ...
|
||||
def test_raises_when_confidence_missing(self): ...
|
||||
```
|
||||
|
||||
**Parametrize aggressively:** Three or more structurally identical tests should become a single `@pytest.mark.parametrize` case. Use `pytest.param(..., id="slug")` per case — not `ids=[...]` on the decorator — so the ID stays co-located with its arguments and survives reordering.
|
||||
|
||||
```python
|
||||
@pytest.mark.parametrize(
|
||||
("overlap_metric", "expected_keep"),
|
||||
[
|
||||
pytest.param(OverlapMetric.IOU, [True, True], id="iou-keeps-both"),
|
||||
pytest.param(OverlapMetric.IOS, [True, False], id="ios-suppresses-small"),
|
||||
],
|
||||
)
|
||||
def test_overlap_metric_determines_suppression(
|
||||
overlap_metric: OverlapMetric, expected_keep: list[bool]
|
||||
) -> None:
|
||||
"""Small box inside large: IOU keeps both; IOS suppresses small."""
|
||||
...
|
||||
```
|
||||
|
||||
**Docstrings:** Every test function/method requires at minimum a one-line docstring (within the project line length configured in `pyproject.toml`). Describe the scenario, not the implementation.
|
||||
|
||||
### Doctests
|
||||
|
||||
**Guidance:** when an example uses only `supervision`, NumPy, and the standard library — no optional extras (e.g. no `--extra metrics` packages), no external files, no network, no devices — prefer `>>>` doctest format so it is automatically verified by the test suite. Fenced ```` ```python ```` blocks are appropriate when the example cannot reasonably be executed (e.g. loading a third-party model, reading a video file) or when the primary purpose is demonstrating error/exception behaviour rather than return values.
|
||||
|
||||
Doctests run automatically as part of the test suite via `--doctest-modules` in `pyproject.toml`. The `ELLIPSIS` and `NORMALIZE_WHITESPACE` flags are enabled globally, so `...` matches any output fragment and minor whitespace differences are ignored.
|
||||
|
||||
```bash
|
||||
uv run pytest --doctest-modules src/
|
||||
```
|
||||
|
||||
**Writing a doctest**
|
||||
|
||||
Use the `Example:` section of a Google-style docstring. Prefix each input line with `>>>` and each continuation line with `...`. Place expected output immediately after the last input line with no blank line between them.
|
||||
|
||||
```python
|
||||
def clip_boxes(xyxy: np.ndarray, resolution_wh: tuple) -> np.ndarray:
|
||||
"""Clip bounding boxes to frame boundaries.
|
||||
|
||||
Args:
|
||||
xyxy: Box coordinates as (N, 4) float array.
|
||||
resolution_wh: Frame size as (width, height).
|
||||
|
||||
Returns:
|
||||
Clipped boxes as (N, 4) float array.
|
||||
|
||||
Example:
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> boxes = np.array([[-10, -5, 120, 80]], dtype=np.float32)
|
||||
>>> sv.clip_boxes(boxes, resolution_wh=(100, 60))
|
||||
array([[ 0., 0., 100., 60.]], dtype=float32)
|
||||
"""
|
||||
```
|
||||
|
||||
### Key rules
|
||||
|
||||
- **Single-line expression** — write the repr as expected output: `>>> len(result)` → `1`
|
||||
- **Multi-line statement** — use `...` continuation: `>>> arr = np.array([` / `... [1, 2],` / `... ])`
|
||||
- **Print output** — write the printed string as expected output (no quotes).
|
||||
- **`None` return** — no output line needed (suppress with assignment or `_ =`).
|
||||
- **Large/variable arrays** — use `ELLIPSIS`: `array([...])` matches any content.
|
||||
- **`# doctest: +SKIP`** — use only as a last resort for genuinely non-runnable lines (e.g. a GPU-only call inside an otherwise runnable example). Prefer splitting the example into two blocks instead.
|
||||
|
||||
Fenced ```` ```python ```` blocks remain appropriate for:
|
||||
|
||||
- Examples that import optional extras (`supervision[metrics]`, `torch`, `ultralytics`).
|
||||
- Examples that read files, capture video, or require a running service.
|
||||
- Illustrative pseudocode that is intentionally incomplete.
|
||||
|
||||
## 🔍 PR Review Guidelines
|
||||
|
||||
These guidelines help reviewers provide consistent, actionable feedback efficiently. Your goals: validate completeness, identify risks, provide actionable feedback, and highlight quality gaps.
|
||||
|
||||
@@ -141,6 +141,6 @@ Quick checklist:
|
||||
|
||||
## 🎯 Context-Aware Behavior
|
||||
|
||||
**For general development tasks**: Follow [AGENTS.md](../AGENTS.md)
|
||||
**For pull request reviews**: Follow [PR Review Guidelines](CONTRIBUTING.md#pr-review-guidelines)
|
||||
**For detailed processes**: Consult [CONTRIBUTING.md](CONTRIBUTING.md)
|
||||
- **For general development tasks**: Follow [AGENTS.md](../AGENTS.md)
|
||||
- **For pull request reviews**: Follow [PR Review Guidelines](CONTRIBUTING.md#pr-review-guidelines)
|
||||
- **For detailed processes**: Consult [CONTRIBUTING.md](CONTRIBUTING.md)
|
||||
|
||||
@@ -19,6 +19,7 @@ exclude = [
|
||||
"http://127.0.0.1:8000", # hint for local docs server
|
||||
"https://sam2.metademolab.com/", # returns 403 Forbidden
|
||||
"https://snyk.io/advisor/python/supervision/badge.svg", # badge URL
|
||||
"https://trendshift.io", # badge API times out in CI
|
||||
"https://universe.roboflow.com/",
|
||||
"https://universe.roboflow.com/model-examples/segmented-animals-basic",
|
||||
# fixme: this page returns 401 Unauthorized when accessed and 404 Not Found when accessed with browser,
|
||||
|
||||
@@ -20,10 +20,10 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: 📥 Checkout the repository
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v6.0.2
|
||||
uses: actions/checkout@9c091bb21b7c1c1d1991bb908d89e4e9dddfe3e0 # v7.0.0
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ inputs.python-version }}
|
||||
uses: astral-sh/setup-uv@08807647e7069bb48b6ef5acd8ec9567f424441b # v8.1.0
|
||||
uses: astral-sh/setup-uv@fac544c07dec837d0ccb6301d7b5580bf5edae39 # v8.2.0
|
||||
with:
|
||||
python-version: ${{ inputs.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
@@ -22,10 +22,10 @@ jobs:
|
||||
timeout-minutes: 10
|
||||
steps:
|
||||
- name: 📥 Checkout the repository
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v6.0.2
|
||||
uses: actions/checkout@9c091bb21b7c1c1d1991bb908d89e4e9dddfe3e0 # v7.0.0
|
||||
|
||||
- name: 🐍 Install uv and set Python
|
||||
uses: astral-sh/setup-uv@08807647e7069bb48b6ef5acd8ec9567f424441b # v8.1.0
|
||||
uses: astral-sh/setup-uv@fac544c07dec837d0ccb6301d7b5580bf5edae39 # v8.2.0
|
||||
with:
|
||||
python-version: "3.10"
|
||||
activate-environment: true
|
||||
|
||||
@@ -19,7 +19,7 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Checkout repository
|
||||
uses: actions/checkout@v6
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: 🔗 Link Checker
|
||||
uses: lycheeverse/lychee-action@v2
|
||||
|
||||
@@ -33,10 +33,10 @@ jobs:
|
||||
runs-on: ${{ matrix.os }}
|
||||
steps:
|
||||
- name: 📥 Checkout the repository
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v6.0.2
|
||||
uses: actions/checkout@9c091bb21b7c1c1d1991bb908d89e4e9dddfe3e0 # v7.0.0
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@08807647e7069bb48b6ef5acd8ec9567f424441b # v8.1.0
|
||||
uses: astral-sh/setup-uv@fac544c07dec837d0ccb6301d7b5580bf5edae39 # v8.2.0
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
@@ -56,7 +56,7 @@ jobs:
|
||||
coverage report
|
||||
|
||||
- name: Upload coverage to Codecov
|
||||
uses: codecov/codecov-action@v6
|
||||
uses: codecov/codecov-action@v7
|
||||
with:
|
||||
token: ${{ secrets.CODECOV_TOKEN }}
|
||||
files: "coverage.xml"
|
||||
|
||||
@@ -1,9 +1,15 @@
|
||||
name: Docs/Build and Publish
|
||||
|
||||
# Deploy matrix:
|
||||
# push develop -> mike deploy develop
|
||||
# push release/latest -> mike deploy latest
|
||||
# release published -> mike deploy <tag> only; does not move /latest/
|
||||
|
||||
on:
|
||||
push:
|
||||
branches:
|
||||
- develop
|
||||
- release/latest
|
||||
workflow_dispatch:
|
||||
release:
|
||||
types: [published]
|
||||
@@ -26,12 +32,12 @@ jobs:
|
||||
timeout-minutes: 10
|
||||
steps:
|
||||
- name: 📥 Checkout the repository
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v6.0.2
|
||||
uses: actions/checkout@9c091bb21b7c1c1d1991bb908d89e4e9dddfe3e0 # v7.0.0
|
||||
with:
|
||||
fetch-depth: 0
|
||||
|
||||
- name: 🐍 Install uv and set Python
|
||||
uses: astral-sh/setup-uv@08807647e7069bb48b6ef5acd8ec9567f424441b # v8.1.0
|
||||
uses: astral-sh/setup-uv@fac544c07dec837d0ccb6301d7b5580bf5edae39 # v8.2.0
|
||||
with:
|
||||
python-version: "3.10"
|
||||
activate-environment: true
|
||||
@@ -51,13 +57,37 @@ jobs:
|
||||
run: |
|
||||
mike deploy --push develop
|
||||
|
||||
- name: 🚀 Deploy Release Docs
|
||||
if: github.event_name == 'release' && github.event.action == 'published'
|
||||
- name: 🚀 Deploy Latest Docs
|
||||
if: github.event_name == 'push' && github.ref == 'refs/heads/release/latest'
|
||||
env:
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY: ${{ secrets.GITHUB_TOKEN }}
|
||||
run: |
|
||||
latest_tag=$(git tag --sort=-v:refname | grep -E '^[0-9]+\.[0-9]+\.[0-9]+$' | head -1)
|
||||
mike deploy --push --update-aliases $latest_tag latest
|
||||
if mike list | grep -Eq '^latest(\s|$)'; then mike delete latest; fi
|
||||
mike deploy --push latest
|
||||
|
||||
- name: 🏷️ Determine release deployment metadata
|
||||
id: release_metadata
|
||||
run: |
|
||||
is_rc=false
|
||||
release_tag=""
|
||||
if [[ "$GITHUB_EVENT_NAME" == "release" ]]; then
|
||||
release_tag="${GITHUB_REF_NAME#v}"
|
||||
release_tag="${release_tag%.post*}"
|
||||
release_tag_lower="${release_tag,,}"
|
||||
# Match RC suffixes with separators (1.0-rc1, 1.0.rc1) or compact form (1.0rc1).
|
||||
if [[ "$release_tag_lower" =~ (^|[._-])rc[0-9]+$ ]] || [[ "$release_tag_lower" =~ [0-9]rc[0-9]+$ ]]; then
|
||||
is_rc=true
|
||||
fi
|
||||
fi
|
||||
echo "is_rc=$is_rc" >> "$GITHUB_OUTPUT"
|
||||
echo "release_tag=$release_tag" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: 🚀 Deploy Release Docs
|
||||
if: github.event_name == 'release' && github.event.action == 'published' && steps.release_metadata.outputs.is_rc != 'true'
|
||||
env:
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY: ${{ secrets.GITHUB_TOKEN }}
|
||||
run: |
|
||||
mike deploy --push "${{ steps.release_metadata.outputs.release_tag }}"
|
||||
|
||||
# IndexNow key: 0d5d9799b1cc4a39825146388c6781eb
|
||||
# This key must stay in sync across three files:
|
||||
@@ -70,25 +100,55 @@ jobs:
|
||||
if: >
|
||||
(github.event_name == 'push' && github.ref == 'refs/heads/develop') ||
|
||||
github.event_name == 'workflow_dispatch' ||
|
||||
(github.event_name == 'release' && github.event.action == 'published')
|
||||
(github.event_name == 'push' && github.ref == 'refs/heads/release/latest') ||
|
||||
(github.event_name == 'release' && github.event.action == 'published' && steps.release_metadata.outputs.is_rc != 'true')
|
||||
run: |
|
||||
cp docs/robots.txt /tmp/robots.txt
|
||||
cp docs/llms.txt /tmp/llms.txt
|
||||
cp docs/llms.full.txt /tmp/llms.full.txt
|
||||
cp docs/llms-100k.txt /tmp/llms-100k.txt
|
||||
cp docs/_headers /tmp/headers.txt
|
||||
cp docs/0d5d9799b1cc4a39825146388c6781eb.txt /tmp/indexnow.txt
|
||||
if [[ "$GITHUB_REF" == "refs/heads/release/latest" ]]; then
|
||||
version_dir="latest"
|
||||
else
|
||||
version_dir=""
|
||||
fi
|
||||
git fetch origin gh-pages
|
||||
git checkout gh-pages
|
||||
cp /tmp/robots.txt robots.txt
|
||||
cp /tmp/llms.txt llms.txt
|
||||
cp /tmp/llms.full.txt llms.full.txt
|
||||
cp /tmp/llms-100k.txt llms-100k.txt
|
||||
cp /tmp/headers.txt _headers
|
||||
cp /tmp/indexnow.txt 0d5d9799b1cc4a39825146388c6781eb.txt
|
||||
git add robots.txt llms.txt 0d5d9799b1cc4a39825146388c6781eb.txt
|
||||
git diff --cached --quiet || git commit -m "chore: update GEO root files (robots.txt, llms.txt, indexnow)"
|
||||
if [[ -n "$version_dir" && -f "$version_dir/sitemap.xml" ]]; then
|
||||
cp "$version_dir/sitemap.xml" sitemap.xml
|
||||
gzip -9 -c sitemap.xml > sitemap.xml.gz
|
||||
fi
|
||||
files_to_add=(
|
||||
robots.txt
|
||||
llms.txt
|
||||
llms.full.txt
|
||||
llms-100k.txt
|
||||
_headers
|
||||
0d5d9799b1cc4a39825146388c6781eb.txt
|
||||
)
|
||||
if [[ -f "sitemap.xml" ]]; then
|
||||
files_to_add+=(sitemap.xml)
|
||||
fi
|
||||
if [[ -f "sitemap.xml.gz" ]]; then
|
||||
files_to_add+=(sitemap.xml.gz)
|
||||
fi
|
||||
git add "${files_to_add[@]}"
|
||||
git diff --cached --quiet || git commit -m "chore: update GEO root files"
|
||||
git push origin gh-pages
|
||||
|
||||
- name: 📡 Notify IndexNow
|
||||
if: >
|
||||
(github.event_name == 'push' && github.ref == 'refs/heads/develop') ||
|
||||
github.event_name == 'workflow_dispatch' ||
|
||||
(github.event_name == 'release' && github.event.action == 'published')
|
||||
(github.event_name == 'push' && github.ref == 'refs/heads/release/latest')
|
||||
run: |
|
||||
curl -s -o /dev/null -w "%{http_code}" -X POST "https://api.indexnow.org/IndexNow" \
|
||||
-H "Content-Type: application/json; charset=utf-8" \
|
||||
|
||||
@@ -40,7 +40,7 @@ jobs:
|
||||
|
||||
- name: 📦 Upload assets to Release
|
||||
if: github.event_name == 'release'
|
||||
uses: AButler/upload-release-assets@v3.0
|
||||
uses: AButler/upload-release-assets@v4.0
|
||||
with:
|
||||
files: "dist/*"
|
||||
repo-token: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
||||
@@ -169,3 +169,4 @@ _resolutions/
|
||||
_reviews/
|
||||
tasks/
|
||||
*.local.md
|
||||
scripts/test_multi_skeleton.py
|
||||
|
||||
@@ -13,11 +13,14 @@ repos:
|
||||
hooks:
|
||||
- id: trailing-whitespace
|
||||
- id: check-yaml
|
||||
exclude: mkdocs.yml
|
||||
args: ["--unsafe"]
|
||||
- id: check-executables-have-shebangs
|
||||
- id: check-json
|
||||
- id: check-toml
|
||||
- id: check-case-conflict
|
||||
- id: check-added-large-files
|
||||
args: ["--maxkb=500", "--enforce-all"]
|
||||
exclude: uv.lock|.*\.ipynb$
|
||||
- id: detect-private-key
|
||||
- id: pretty-format-json
|
||||
exclude: demo.ipynb
|
||||
@@ -26,7 +29,7 @@ repos:
|
||||
- id: mixed-line-ending
|
||||
|
||||
- repo: https://github.com/JoC0de/pre-commit-prettier
|
||||
rev: v3.8.2 # using tag; previously pinned SHA when tags were not persistent
|
||||
rev: v3.8.3 # using tag; previously pinned SHA when tags were not persistent
|
||||
hooks:
|
||||
- id: prettier
|
||||
files: \.(ya?ml|toml)$
|
||||
@@ -44,10 +47,10 @@ repos:
|
||||
- id: validate-pyproject
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.15.10
|
||||
rev: v0.15.12
|
||||
hooks:
|
||||
- id: ruff-check
|
||||
args: [--fix]
|
||||
args: ["--fix"]
|
||||
- id: ruff-format
|
||||
types_or: [python, pyi, jupyter]
|
||||
|
||||
@@ -58,11 +61,11 @@ repos:
|
||||
additional_dependencies:
|
||||
- "mdformat-mkdocs[recommended]>=2.1.0"
|
||||
- "mdformat-ruff"
|
||||
args: ["--number"]
|
||||
args: ["--number", "--wrap=no"]
|
||||
exclude: ^(docs/changelog\.md|docs/deprecated\.md)$
|
||||
|
||||
- repo: https://github.com/pre-commit/mirrors-mypy
|
||||
rev: v1.20.1
|
||||
rev: v1.20.2
|
||||
hooks:
|
||||
- id: mypy
|
||||
additional_dependencies:
|
||||
|
||||
@@ -1,98 +1,146 @@
|
||||
# Agent Guidelines for `supervision`
|
||||
|
||||
These instructions define how AI agents (GitHub Copilot, Claude, etc.) should behave when
|
||||
assigned an issue, task, or multi-step problem in this repository.
|
||||
|
||||
Behave like a senior contributor: precise, efficient, aligned with the project's
|
||||
philosophy, and focused on maintainability and clarity.
|
||||
Behave like a senior contributor: precise, efficient, maintainable. When this file and [CONTRIBUTING.md](.github/CONTRIBUTING.md) conflict, **CONTRIBUTING.md wins**.
|
||||
|
||||
---
|
||||
|
||||
## 1. Before You Code
|
||||
|
||||
- Read the task/issue thoroughly before acting.
|
||||
- Identify missing information; ask **one targeted clarification question** if needed.
|
||||
- Outline a step-by-step plan before making changes.
|
||||
- Check whether the feature or fix already exists under a different name.
|
||||
- Confirm alignment with the repository's architecture (`src/supervision/`).
|
||||
- Read the task thoroughly; group clarifications into one ask.
|
||||
- Outline a plan before making changes.
|
||||
- Check whether the feature already exists under a different name.
|
||||
- Confirm alignment with `src/supervision/` architecture.
|
||||
|
||||
---
|
||||
|
||||
## 2. Repository Conventions
|
||||
## 2. Repository Architecture
|
||||
|
||||
All work must follow the conventions of the `supervision` library
|
||||
(see [CONTRIBUTING.md](.github/CONTRIBUTING.md) for full details).
|
||||
**Package root**: `src/supervision/` — all library code. **Tests**: `tests/` — mirrors `src/supervision/`. **Public API**: `src/supervision/__init__.py`.
|
||||
|
||||
### Branching & Commits
|
||||
```
|
||||
src/supervision/
|
||||
├── detection/
|
||||
│ ├── core.py — Detections dataclass; all model connectors as classmethods
|
||||
│ ├── compact_mask.py — compact mask representation
|
||||
│ ├── vlm.py — VLM connectors (Florence-2, Gemini, Qwen, PaliGemma)
|
||||
│ ├── utils/ — pure NumPy helpers: boxes, converters, iou_and_nms, masks, polygons
|
||||
│ ├── line_zone.py — LineZone
|
||||
│ └── tools/ — InferenceSlicer, PolygonZone, CSVSink, JSONSink, DetectionsSmoother
|
||||
├── annotators/core.py — BoxAnnotator, MaskAnnotator, LabelAnnotator, … each: .annotate(scene, detections)
|
||||
├── key_points/ — KeyPoints, EdgeAnnotator, VertexAnnotator (use this, NOT keypoint/ — see §4)
|
||||
├── tracker/ — DEPRECATED
|
||||
├── dataset/core.py — DetectionDataset / ClassificationDataset (YOLO / COCO / Pascal VOC)
|
||||
├── geometry/core.py — Point, Rect, Vector, Position
|
||||
├── metrics/ — mAP, confusion matrix (requires --extra metrics)
|
||||
├── utils/internal.py — warn_deprecated, deprecated_parameter, internal helpers
|
||||
└── config.py — string constants; always import from here, never use literals
|
||||
```
|
||||
|
||||
- Branch from `develop` using prefixes: `feat/`, `fix/`, `docs/`, `refactor/`, `test/`, `chore/`.
|
||||
- Use **conventional commits**: `feat:`, `fix:`, `docs:`, `refactor:`, `perf:`, `test:`, `chore:`.
|
||||
- PRs must target the `develop` branch.
|
||||
### Key design patterns
|
||||
|
||||
### Code Style
|
||||
|
||||
- **Formatting and linting** are enforced by **pre-commit**.
|
||||
The hook chain typically includes: ruff-check, ruff-format, codespell, mdformat,
|
||||
prettier, pyproject-fmt, and standard pre-commit-hooks (trailing whitespace, YAML, TOML, etc.).
|
||||
- **Type hints**: required on all new code. Type checking with mypy is encouraged but not
|
||||
currently enforced systematically by pre-commit; see [.github/CONTRIBUTING.md](.github/CONTRIBUTING.md)
|
||||
for the latest type-checking expectations.
|
||||
- **Docstrings**: Google Python docstring style. Required for all new functions and classes.
|
||||
Docstrings should include usage examples demonstrating the function with primitive values
|
||||
so they serve as runnable documentation.
|
||||
|
||||
### API Consistency
|
||||
|
||||
- Follow existing naming patterns.
|
||||
- Maintain backward compatibility unless explicitly allowed.
|
||||
- Prefer functional utilities over complex classes unless justified.
|
||||
|
||||
### Performance
|
||||
|
||||
- Avoid unnecessary copies of NumPy arrays.
|
||||
- Prefer vectorized operations over Python loops in hot paths.
|
||||
- Use OpenCV operations efficiently.
|
||||
- **`Detections` is the lingua franca** — every connector, tracker, and annotator speaks `Detections`. New connector = `@classmethod from_<framework>(cls, result) -> Detections`.
|
||||
- **Annotators are composable** — receive `scene` (BGR `np.ndarray`) + `detections`, return annotated copy.
|
||||
- **`data` dict extensibility** — per-detection metadata in `detections.data` as `np.ndarray` aligned with `xyxy`. Keys are constants from `config.py`.
|
||||
- **Vectorized throughout** — NumPy arrays, no Python loops in hot paths. Never write `for det in detections`.
|
||||
- **Lazy-import heavy deps** — `torch`, `transformers`, `ultralytics` must be imported inside the function that needs them, never at module top level.
|
||||
|
||||
---
|
||||
|
||||
## 3. Implementing Features
|
||||
## 3. Agent-Critical Rules
|
||||
|
||||
- Provide a minimal, clean implementation.
|
||||
- Include type hints and Google-style docstrings with usage examples.
|
||||
- All new functionality must be covered with tests, including edge cases.
|
||||
- Add or update documentation (docstrings + mkdocs entries if applicable).
|
||||
- Ensure compatibility with core dependencies: NumPy, OpenCV, SciPy.
|
||||
These supplement [CONTRIBUTING.md](.github/CONTRIBUTING.md) — covering gaps or agent-specific failure modes.
|
||||
|
||||
**Doc headings**: `###` max in docstrings and docs. `####` renders identically to bold in mkdocs — use `**bold**` instead.
|
||||
|
||||
**Type hints**: required on all new code. mypy is enforced by pre-commit (`.pre-commit-config.yaml`).
|
||||
|
||||
**Doctest determinism** — output must be reproducible across platforms:
|
||||
|
||||
- Use `# doctest: +ELLIPSIS` for floats that vary by platform.
|
||||
- Seed any RNG before calling it.
|
||||
- Never assert `dict` or `set` iteration order.
|
||||
- No network or filesystem access outside `supervision/assets/`.
|
||||
|
||||
**⚠ Test structure** — agents frequently fail here; read [CONTRIBUTING.md §Tests](.github/CONTRIBUTING.md#-tests) carefully: AAA structure, class grouping, parametrize with `pytest.param(..., id="slug")`, one-line docstring per test.
|
||||
|
||||
For branching, commit, code style, and API design conventions see [CONTRIBUTING.md](.github/CONTRIBUTING.md).
|
||||
|
||||
---
|
||||
|
||||
## 4. Fixing Bugs
|
||||
## 4. Deprecated Module Aliases
|
||||
|
||||
1. Reproduce and understand the root cause.
|
||||
2. Write a test that reproduces the bug (it should fail before the fix).
|
||||
3. Apply a minimal, targeted fix.
|
||||
4. Verify the test passes and no other components break.
|
||||
`supervision.keypoint` deprecated since `0.27.0`, removed in `0.30.0`. Always import from `supervision.key_points`, not `supervision.keypoint`.
|
||||
|
||||
---
|
||||
|
||||
## 5. Refactoring
|
||||
## 5. Deprecating APIs
|
||||
|
||||
- Preserve behavior and API stability.
|
||||
- Improve readability or performance.
|
||||
- Reduce duplication.
|
||||
- Avoid large, sweeping refactors unless explicitly requested.
|
||||
**Minimum window**: deprecated APIs must remain for at least **3 minor releases** before removal. Example: deprecated in `0.29.0` → removed in `0.32.0`.
|
||||
|
||||
- Module-level: `supervision.utils.internal.warn_deprecated` in the deprecated module's own `__init__.py`
|
||||
- Parameter renamed (old→new): `supervision.utils.internal.deprecated_parameter` decorator
|
||||
- Public function, method, or class: `@deprecated` from `pydeprecate`
|
||||
|
||||
Always name the version introduced and the removal version:
|
||||
|
||||
```python
|
||||
warn_deprecated("'foo' deprecated in `0.29.0`, removed in `0.32.0`. Use 'bar'.")
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 6. Before You Commit
|
||||
## 6. Implementing Features
|
||||
|
||||
Always run these before committing:
|
||||
- Minimal implementation; type hints and Google docstrings with usage examples.
|
||||
- Tests covering new functionality and edge cases (see [CONTRIBUTING.md §Tests](.github/CONTRIBUTING.md#-tests)).
|
||||
- Update docstrings and mkdocs entries as needed.
|
||||
|
||||
**Extending `Detections`**: store metadata in `detections.data` as `np.ndarray` aligned with `xyxy`; define the key as a constant in `config.py` (e.g. `CLASS_NAME_DATA_FIELD`, `ORIENTED_BOX_COORDINATES`).
|
||||
|
||||
**New model connector** (`detection/core.py`):
|
||||
|
||||
```python
|
||||
@classmethod
|
||||
def from_myframework(cls, result) -> "Detections":
|
||||
import myframework # noqa: F401 — lazy import
|
||||
|
||||
xyxy = ... # (N, 4)
|
||||
return cls(
|
||||
xyxy=xyxy,
|
||||
confidence=...,
|
||||
class_id=...,
|
||||
data={CLASS_NAME_DATA_FIELD: np.array([...])},
|
||||
)
|
||||
```
|
||||
|
||||
VLM connectors go in `detection/vlm.py`, not `core.py`.
|
||||
|
||||
---
|
||||
|
||||
## 7. Bugs & Refactoring
|
||||
|
||||
**Bugs**: reproduce → write failing test → minimal fix → verify no regressions.
|
||||
|
||||
**Refactoring**: preserve behavior and API; reduce duplication; avoid sweeping changes unless requested; apply §5 deprecation when removing public API.
|
||||
|
||||
---
|
||||
|
||||
## 8. Before You Commit
|
||||
|
||||
```bash
|
||||
uv run pytest --cov=supervision
|
||||
uv run pre-commit run --all-files
|
||||
```
|
||||
|
||||
- All pre-commit hooks must pass (formatting, linting, type checking, spell check, etc.).
|
||||
- All tests must pass before opening a PR. Note: some existing tests in the repo may
|
||||
already be failing — your changes must not introduce new failures.
|
||||
- Fix any issues reported and re-run until clean.
|
||||
Capture a baseline before changes to avoid introducing new failures:
|
||||
|
||||
```bash
|
||||
STASH_BEFORE=$(git rev-parse refs/stash 2>/dev/null)
|
||||
git stash push --include-untracked
|
||||
uv run pytest -q 2>&1 | tee /tmp/baseline.txt
|
||||
[ "$(git rev-parse refs/stash 2>/dev/null)" != "$STASH_BEFORE" ] && git stash pop
|
||||
uv run pytest -q 2>&1 | tee /tmp/after.txt
|
||||
diff /tmp/baseline.txt /tmp/after.txt
|
||||
```
|
||||
|
||||
Any test passing in baseline but failing after = blocker.
|
||||
|
||||
+3
-15
@@ -2,20 +2,8 @@ MIT License
|
||||
|
||||
Copyright (c) 2022 Roboflow
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy of this software and associated documentation files (the "Software"), to deal in the Software without restriction, including without limitation the rights to use, copy, modify, merge, publish, distribute, sublicense, and/or sell copies of the Software, and to permit persons to whom the Software is furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
The above copyright notice and this permission notice shall be included in all copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
<div align="center">
|
||||
<p>
|
||||
<a align="center" href="" target="https://supervision.roboflow.com">
|
||||
<a align="center" href="https://supervision.roboflow.com" target="_blank">
|
||||
<img
|
||||
width="100%"
|
||||
src="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png?updatedAt=1678995927529"
|
||||
@@ -14,16 +14,9 @@
|
||||
|
||||
<br>
|
||||
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://codecov.io/gh/roboflow/supervision)
|
||||
[](https://badge.fury.io/py/supervision) [](https://pypistats.org/packages/supervision) [](LICENSE.md) [](https://badge.fury.io/py/supervision) [](https://codecov.io/gh/roboflow/supervision)
|
||||
|
||||
[](https://snyk.io/advisor/python/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://huggingface.co/spaces/Roboflow/Annotators)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
[](https://snyk.io/advisor/python/supervision) [](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb) [](https://huggingface.co/spaces/Roboflow/Annotators) [](https://discord.gg/GbfgXGJ8Bk)
|
||||
|
||||
<div align="center">
|
||||
<a href="https://trendshift.io/repositories/124" target="_blank"><img src="https://trendshift.io/api/badge/repositories/124" alt="roboflow%2Fsupervision | Trendshift" style="width: 250px; height: 55px;" width="250" height="55"/></a>
|
||||
@@ -31,14 +24,29 @@
|
||||
|
||||
</div>
|
||||
|
||||
## 👋 hello
|
||||
<details>
|
||||
<summary><strong>📑 Table of Contents</strong></summary>
|
||||
|
||||
**We write your reusable computer vision tools.** Whether you need to load your dataset from your hard drive, draw detections on an image or video, or count how many detections are in a zone. You can count on us! 🤝
|
||||
- [👋 Hello](#-hello)
|
||||
- [💻 Install](#-install)
|
||||
- [🔥 Quickstart](#-quickstart)
|
||||
- [Models](#models)
|
||||
- [Annotators](#annotators)
|
||||
- [Datasets](#datasets)
|
||||
- [🎬 Tutorials](#-tutorials)
|
||||
- [💜 Built with Supervision](#-built-with-supervision)
|
||||
- [📚 Documentation](#-documentation)
|
||||
- [🏆 Contribution](#-contribution)
|
||||
|
||||
## 💻 install
|
||||
</details>
|
||||
|
||||
Pip install the supervision package in a
|
||||
[**Python>=3.9**](https://www.python.org/) environment.
|
||||
## 👋 Hello
|
||||
|
||||
**We are your essential toolkit for computer vision.** From data loading to real-time zone counting, we provide the building blocks so you can focus on building applications around your models. 🤝
|
||||
|
||||
## 💻 Install
|
||||
|
||||
Pip install the supervision package in a [**Python>=3.9**](https://www.python.org/) environment.
|
||||
|
||||
```bash
|
||||
pip install supervision
|
||||
@@ -46,9 +54,9 @@ pip install supervision
|
||||
|
||||
Read more about conda, mamba, and installing from source in our [guide](https://roboflow.github.io/supervision/).
|
||||
|
||||
## 🔥 quickstart
|
||||
## 🔥 Quickstart
|
||||
|
||||
### models
|
||||
### Models
|
||||
|
||||
Supervision was designed to be model agnostic. Just plug in any classification, detection, or segmentation model. For your convenience, we have created [connectors](https://supervision.roboflow.com/latest/detection/core/#detections) for the most popular libraries like Ultralytics, Transformers, MMDetection, or Inference. Other integrations, like `rfdetr`, already return `sv.Detections` directly.
|
||||
|
||||
@@ -59,7 +67,7 @@ import supervision as sv
|
||||
from PIL import Image
|
||||
from rfdetr import RFDETRSmall
|
||||
|
||||
image = Image.open(...)
|
||||
image = Image.open("path/to/image.jpg")
|
||||
model = RFDETRSmall()
|
||||
detections = model.predict(image, threshold=0.5)
|
||||
|
||||
@@ -79,7 +87,7 @@ len(detections)
|
||||
from PIL import Image
|
||||
from inference import get_model
|
||||
|
||||
image = Image.open(...)
|
||||
image = Image.open("path/to/image.jpg")
|
||||
model = get_model(model_id="rfdetr-small", api_key="ROBOFLOW_API_KEY")
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
@@ -90,7 +98,7 @@ len(detections)
|
||||
|
||||
</details>
|
||||
|
||||
### annotators
|
||||
### Annotators
|
||||
|
||||
Supervision offers a wide range of highly customizable [annotators](https://supervision.roboflow.com/latest/detection/annotators/), allowing you to compose the perfect visualization for your use case.
|
||||
|
||||
@@ -98,7 +106,8 @@ Supervision offers a wide range of highly customizable [annotators](https://supe
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(...)
|
||||
image = cv2.imread("path/to/image.jpg")
|
||||
# Assuming detections are obtained from a model
|
||||
detections = sv.Detections(...)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
@@ -107,7 +116,7 @@ annotated_frame = box_annotator.annotate(scene=image.copy(), detections=detectio
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/691e219c-0565-4403-9218-ab5644f39bce
|
||||
|
||||
### datasets
|
||||
### Datasets
|
||||
|
||||
Supervision provides a set of [utils](https://supervision.roboflow.com/latest/datasets/core/) that allow you to load, split, merge, and save datasets in one of the supported formats.
|
||||
|
||||
@@ -131,7 +140,7 @@ for path, image, annotation in ds:
|
||||
pass
|
||||
```
|
||||
|
||||
<details close>
|
||||
<details>
|
||||
<summary>👉 more dataset utils</summary>
|
||||
|
||||
- load
|
||||
@@ -221,7 +230,7 @@ for path, image, annotation in ds:
|
||||
|
||||
</details>
|
||||
|
||||
## 🎬 tutorials
|
||||
## 🎬 Tutorials
|
||||
|
||||
Want to learn how to use Supervision? Explore our [how-to guides](https://supervision.roboflow.com/develop/how_to/detect_and_annotate/), [end-to-end examples](./examples), [cheatsheet](https://roboflow.github.io/cheatsheet-supervision/), and [cookbooks](https://supervision.roboflow.com/develop/cookbooks/)!
|
||||
|
||||
@@ -241,7 +250,7 @@ Want to learn how to use Supervision? Explore our [how-to guides](https://superv
|
||||
<div><strong>Created: 11 Jan 2024</strong></div>
|
||||
<br/>Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
|
||||
## 💜 built with supervision
|
||||
## 💜 Built with Supervision
|
||||
|
||||
Did you build something cool using supervision? [Let us know!](https://github.com/roboflow/supervision/discussions/categories/built-with-supervision)
|
||||
|
||||
@@ -251,11 +260,11 @@ https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/3ac6982f-4943-4108-9b7f-51787ef1a69f
|
||||
|
||||
## 📚 documentation
|
||||
## 📚 Documentation
|
||||
|
||||
Visit our [documentation](https://roboflow.github.io/supervision) page to learn how supervision can help you build computer vision applications faster and more reliably.
|
||||
|
||||
## 🏆 contribution
|
||||
## 🏆 Contribution
|
||||
|
||||
We love your input! Please see our [contributing guide](.github/CONTRIBUTING.md) to get started. Thank you 🙏 to all our contributors!
|
||||
|
||||
@@ -267,8 +276,6 @@ We love your input! Please see our [contributing guide](.github/CONTRIBUTING.md)
|
||||
|
||||
<br>
|
||||
|
||||
<div align="center">
|
||||
|
||||
<div align="center">
|
||||
<a href="https://youtube.com/roboflow">
|
||||
<img
|
||||
@@ -303,6 +310,7 @@ We love your input! Please see our [contributing guide](.github/CONTRIBUTING.md)
|
||||
src="https://media.roboflow.com/notebooks/template/icons/purple/forum.png?ik-sdk-version=javascript-1.4.3&updatedAt=1672949633584"
|
||||
width="3%"
|
||||
/>
|
||||
</a>
|
||||
<img src="https://raw.githubusercontent.com/ultralytics/assets/main/social/logo-transparent.png" width="3%"/>
|
||||
<a href="https://blog.roboflow.com">
|
||||
<img
|
||||
@@ -310,6 +318,4 @@ We love your input! Please see our [contributing guide](.github/CONTRIBUTING.md)
|
||||
width="3%"
|
||||
/>
|
||||
</a>
|
||||
</a>
|
||||
</div>
|
||||
</div>
|
||||
|
||||
@@ -0,0 +1,6 @@
|
||||
/*
|
||||
Strict-Transport-Security: max-age=31536000; includeSubDomains; preload
|
||||
X-Content-Type-Options: nosniff
|
||||
Referrer-Policy: strict-origin-when-cross-origin
|
||||
Permissions-Policy: camera=(), microphone=(), geolocation=()
|
||||
Content-Security-Policy: default-src 'self'; base-uri 'self'; object-src 'none'; frame-ancestors 'none'; img-src 'self' https: data:; media-src 'self' https: data:; font-src 'self' https: data:; style-src 'self'; script-src 'self'; connect-src 'self' https:;
|
||||
@@ -0,0 +1,27 @@
|
||||
---
|
||||
comments: true
|
||||
description: About Supervision, Roboflow's open-source Python library for building reusable computer vision workflows.
|
||||
---
|
||||
|
||||
# About Supervision
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for building computer vision applications. It gives developers a model-agnostic toolkit for loading predictions, annotating images and video, tracking objects, counting detections in zones, processing datasets, and evaluating model performance.
|
||||
|
||||
The project centers on a unified `Detections` API with converters for supported outputs from Ultralytics, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers such as Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. That common representation lets teams change models without rewriting annotation, filtering, tracking, dataset, or metrics code.
|
||||
|
||||
Supervision is maintained by Roboflow and an open-source contributor community. The library is MIT licensed, developed in public on GitHub, and published on PyPI.
|
||||
|
||||
## Project Links
|
||||
|
||||
- Source code: [github.com/roboflow/supervision](https://github.com/roboflow/supervision)
|
||||
- Package: [pypi.org/project/supervision](https://pypi.org/project/supervision/)
|
||||
- Community: [Roboflow Discord](https://discord.gg/GbfgXGJ8Bk)
|
||||
- Roboflow: [roboflow.com](https://roboflow.com/)
|
||||
|
||||
## Maintainers and Contributors
|
||||
|
||||
Supervision has been shaped by Roboflow engineers and community contributors, including Piotr Skalski, Borda, onuralpszr, Soumik Mandal, and many others. The complete contributor history is available in the GitHub repository.
|
||||
|
||||
## Citation
|
||||
|
||||
If Supervision helps your research or production system, cite the project using the citation block in [llms.txt](https://supervision.roboflow.com/llms.txt) or link to the GitHub repository.
|
||||
+2
-2
@@ -1,11 +1,11 @@
|
||||
---
|
||||
comments: true
|
||||
description: API reference for supervision's assets module — download sample video and image files for demos, testing, and tutorials.
|
||||
---
|
||||
|
||||
# Assets
|
||||
|
||||
Supervision offers an assets download utility that allows you to download image and video files
|
||||
that you can use in your demos.
|
||||
Supervision offers an assets download utility that allows you to download image and video files that you can use in your demos.
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.download_assets">download_assets</a></h2>
|
||||
|
||||
+150
-3
@@ -1,12 +1,119 @@
|
||||
---
|
||||
description: "Full version history of the supervision Python library — release notes, breaking changes, new features, and deprecations for every version."
|
||||
date_modified: 2026-06-16
|
||||
---
|
||||
|
||||
# Changelog
|
||||
|
||||
### 0.28.0 <small>Unreleased</small>
|
||||
### 0.29.1 <small>Jun 23, 2026</small>
|
||||
|
||||
- Changed [#2178](https://github.com/roboflow/supervision/pull/2178): [`sv.Detections.from_inference`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_inference) now supports compressed COCO RLE masks. Inference responses with `rle` or `rle_mask` fields containing a compressed counts string (as produced by `pycocotools`) are decoded directly into binary masks, avoiding a lossy polygon round-trip.
|
||||
- Added [#2338](https://github.com/roboflow/supervision/pull/2338): [`sv.KeyPoints.with_nms`](https://supervision.roboflow.com/latest/keypoint/core/#supervision.key_points.core.KeyPoints.with_nms) — non-maximum suppression for keypoint detections. Derives axis-aligned bounding boxes from valid (non-zero and visible) keypoints and applies `box_non_max_suppression`. Requires `detection_confidence`; supports class-aware and class-agnostic modes via `threshold`, `class_agnostic`, and `overlap_metric`.
|
||||
|
||||
- Fixed [#2342](https://github.com/roboflow/supervision/pull/2342): `sv.Detections.from_vlm` with `sv.VLM.GOOGLE_GEMINI_2_0`, `sv.VLM.GOOGLE_GEMINI_2_5`, and `sv.VLM.QWEN_2_5_VL` no longer raises when the model returns valid JSON of the wrong shape (non-list top-level or non-dict elements). A non-string or malformed `"mask"` value in Gemini 2.5 output no longer triggers `AttributeError`; invalid base64 or non-PNG mask data falls back to an empty mask, keeping `xyxy`, `confidence`, and `masks` arrays aligned.
|
||||
|
||||
- Fixed [#2341](https://github.com/roboflow/supervision/pull/2341): `sv.DetectionDataset.as_pascal_voc` no longer mutates the source `Detections.xyxy` by the 1-index offset on every call. Previously, repeated exports accumulated a `+1` shift in the caller's bounding boxes.
|
||||
|
||||
- Fixed [#2334](https://github.com/roboflow/supervision/pull/2334): `sv.JSONSink` now serializes NumPy scalars (e.g. `np.int64` frame indices) in `custom_data` as JSON numbers instead of raising `TypeError` at close time. File handle is now guaranteed to close even when serialization fails.
|
||||
|
||||
- Fixed [#2333](https://github.com/roboflow/supervision/pull/2333): [`sv.DetectionsSmoother`](https://supervision.roboflow.com/latest/detection/tools/smoother/#supervision.detection.tools.smoother.DetectionsSmoother) no longer raises when smoothing detections without `confidence`. Confidence is now averaged over the frames that carry it; when tracks in the same frame disagree on confidence presence, `confidence` is set to `None` for all smoothed detections.
|
||||
|
||||
- Fixed [#2332](https://github.com/roboflow/supervision/pull/2332): `sv.approximate_polygon` now returns a polygon within the requested point-count budget (at most `floor(N * (1 - percentage))` points, minimum 3). The function now also validates that `epsilon_step > 0`.
|
||||
|
||||
- Fixed [#2331](https://github.com/roboflow/supervision/pull/2331): `sv.Precision` and `sv.F1Score` now count predictions on background images (empty target set) as false positives, and count predictions of classes absent from ground truth as false positives under `MICRO` and `MACRO` averaging. Previously both edge cases were silently ignored, inflating scores. `WEIGHTED` averaging is unchanged — absent classes retain weight 0, consistent with scikit-learn. Users relying on previous scores should re-evaluate after upgrading; no API change is required.
|
||||
|
||||
- Fixed [#2322](https://github.com/roboflow/supervision/pull/2322): COCO export now preserves all polygon parts for multi-component masks. Previously, only the first polygon was written when a non-crowd mask had disjoint segments; all parts are now included.
|
||||
|
||||
- Performance [#2339](https://github.com/roboflow/supervision/pull/2339): `sv.HaloAnnotator` now uses the same CompactMask painting path as `sv.MaskAnnotator` via a shared `_paint_masks_by_area` helper. On a 1080p frame with 30 CompactMask detections, `HaloAnnotator` runs approximately 4× faster; annotated output is unchanged.
|
||||
|
||||
- Performance [#2330](https://github.com/roboflow/supervision/pull/2330): `sv.mask_to_xyxy` and `sv.KeyPoints.as_detections` are now vectorized. `mask_to_xyxy` uses batched occupancy-profile reductions instead of per-mask pixel scans; `KeyPoints.as_detections` computes all bounding boxes in a single batch operation. Both produce bit-identical results.
|
||||
|
||||
- Performance [#2323](https://github.com/roboflow/supervision/pull/2323): Mask IoU computation now uses matrix multiplication on flattened masks instead of an explicit `(N, M, H, W)` intersection tensor, reducing peak memory for large mask sets. For masks larger than 4096×4096 pixels, computation automatically promotes to float64 to preserve exact pixel counts. Results are numerically identical.
|
||||
|
||||
### 0.29.0.post0 <small>Jun 17, 2026</small>
|
||||
|
||||
- Fixed [#2335](https://github.com/roboflow/supervision/pull/2335): `sv.KeyPoints(confidence=...)` now works again. The `0.29.0` refactor accidentally dropped the deprecated `confidence` constructor kwarg; it is now accepted and mapped to `keypoint_confidence` with a deprecation warning.
|
||||
|
||||
### 0.29.0 <small>Jun 15, 2026</small>
|
||||
|
||||
- Added [#2314](https://github.com/roboflow/supervision/pull/2314): new cookbook **Oriented Bounding Boxes** showing how an oriented box differs from an axis-aligned one on a marina of boats: DOTA-pretrained detection, the effect on [`with_nms`](https://supervision.roboflow.com/0.29.0/detection/core/#supervision.detection.core.Detections.with_nms) and [`Detections.area`](https://supervision.roboflow.com/0.29.0/detection/core/#supervision.detection.core.Detections.area), and YOLO OBB dataset export.
|
||||
|
||||
- Fixed [#2306](https://github.com/roboflow/supervision/pull/2306): [`sv.Detections.area`](https://supervision.roboflow.com/0.29.0/detection/core/#supervision.detection.core.Detections.area) now returns the rotated body's area for detections carrying `data["xyxyxyxy"]` (oriented box corners) instead of the area of the derived axis-aligned bounding box, which overestimates by up to ~2x at 45° rotation. Affects annotator z-ordering inside [`MaskAnnotator`](https://supervision.roboflow.com/0.29.0/detection/annotators/#supervision.annotators.core.MaskAnnotator) and [`HaloAnnotator`](https://supervision.roboflow.com/0.29.0/detection/annotators/#supervision.annotators.core.HaloAnnotator), and any user code that filters or sorts OBB detections by area. The mask path and the non-OBB AABB fallback are unchanged.
|
||||
|
||||
- Added [#2277](https://github.com/roboflow/supervision/pull/2277), [#2286](https://github.com/roboflow/supervision/pull/2286): [`sv.VertexEllipseAreaAnnotator`](https://supervision.roboflow.com/0.29.0/keypoint/annotators/#supervision.key_points.annotators.VertexEllipseAreaAnnotator), [`sv.VertexEllipseOutlineAnnotator`](https://supervision.roboflow.com/0.29.0/keypoint/annotators/#supervision.key_points.annotators.VertexEllipseOutlineAnnotator), and [`sv.VertexEllipseHaloAnnotator`](https://supervision.roboflow.com/0.29.0/keypoint/annotators/#supervision.key_points.annotators.VertexEllipseHaloAnnotator) for visualizing keypoint uncertainty as covariance ellipses. Requires models that output keypoint uncertainty (e.g. RF-DETR keypoint models).
|
||||
|
||||
- Added [#2303](https://github.com/roboflow/supervision/pull/2303): [`sv.oriented_box_non_max_suppression`](https://supervision.roboflow.com/0.29.0/detection/utils/iou_and_nms/#supervision.detection.utils.iou_and_nms.oriented_box_non_max_suppression) and [`sv.oriented_box_non_max_merge`](https://supervision.roboflow.com/0.29.0/detection/utils/iou_and_nms/#supervision.detection.utils.iou_and_nms.oriented_box_non_max_merge) for performing NMS and NMM directly on oriented bounding boxes using oriented-box IoU instead of axis-aligned IoU.
|
||||
|
||||
- Added [#2247](https://github.com/roboflow/supervision/pull/2247): [`sv.ConfusionMatrix`](https://supervision.roboflow.com/0.29.0/detection/metrics/#supervision.metrics.detection.ConfusionMatrix) now supports `MetricTarget.ORIENTED_BOUNDING_BOXES`, computing IoU via `oriented_box_iou_batch` on `xyxyxyxy` corners. Previously, OBB inputs silently fell back to axis-aligned bounding-box IoU, producing incorrect match scores for rotated detections.
|
||||
|
||||
- Added [#2252](https://github.com/roboflow/supervision/pull/2252): [`sv.process_video`](https://supervision.roboflow.com/0.29.0/utils/video/#supervision.utils.video.process_video) gains a `preserve_audio` parameter. When enabled, the audio stream from the source video is muxed into the output using ffmpeg.
|
||||
|
||||
- Added [#2302](https://github.com/roboflow/supervision/pull/2302), [#2289](https://github.com/roboflow/supervision/pull/2289): [`sv.DetectionDataset.as_yolo`](https://supervision.roboflow.com/0.29.0/datasets/core/#supervision.dataset.core.DetectionDataset.as_yolo) gains an `is_obb` parameter for exporting oriented bounding box annotations in the YOLO OBB format (9-token lines with 4 corner coordinates).
|
||||
|
||||
- Added [#2312](https://github.com/roboflow/supervision/pull/2312): [`sv.xyxyxyxy_to_xyxy`](https://supervision.roboflow.com/0.29.0/detection/utils/boxes/#supervision.detection.utils.boxes.xyxyxyxy_to_xyxy) — vectorised utility that converts oriented bounding box corners `(N, 4, 2)` to axis-aligned bounding boxes `(N, 4)`.
|
||||
|
||||
- Changed [#2286](https://github.com/roboflow/supervision/pull/2286): [`sv.KeyPoints`](https://supervision.roboflow.com/0.29.0/keypoint/core/#supervision.key_points.core.KeyPoints) now separates keypoint-level and detection-level confidence into distinct fields: `keypoint_confidence` (shape `(n, m)`) and `detection_confidence` (shape `(n,)`). A new `visible` mask (shape `(n, m)`) controls per-keypoint visibility. The legacy `KeyPoints.confidence` property still works but is deprecated.
|
||||
|
||||
- Changed [#2286](https://github.com/roboflow/supervision/pull/2286): [`sv.EdgeAnnotator`](https://supervision.roboflow.com/0.29.0/keypoint/annotators/#supervision.key_points.annotators.EdgeAnnotator) and [`sv.VertexAnnotator`](https://supervision.roboflow.com/0.29.0/keypoint/annotators/#supervision.key_points.annotators.VertexAnnotator) now respect the `visible` mask. Invisible keypoints and their edges are skipped during rendering.
|
||||
|
||||
- Changed [#2286](https://github.com/roboflow/supervision/pull/2286): [`sv.EdgeAnnotator`](https://supervision.roboflow.com/0.29.0/keypoint/annotators/#supervision.key_points.annotators.EdgeAnnotator) and [`sv.VertexLabelAnnotator`](https://supervision.roboflow.com/0.29.0/keypoint/annotators/#supervision.key_points.annotators.VertexLabelAnnotator) now support per-class skeleton definitions, enabling correct rendering when multiple skeleton topologies (e.g. person + animal) coexist in one frame.
|
||||
|
||||
- Changed [#2303](https://github.com/roboflow/supervision/pull/2303): [`sv.Detections.with_nms`](https://supervision.roboflow.com/0.29.0/detection/core/#supervision.detection.core.Detections.with_nms) and [`sv.Detections.with_nmm`](https://supervision.roboflow.com/0.29.0/detection/core/#supervision.detection.core.Detections.with_nmm) now use oriented-box IoU when `data["xyxyxyxy"]` coordinates are present, instead of axis-aligned box IoU. Callers relying on the previous axis-aligned behaviour should remove `data["xyxyxyxy"]` before calling, or recalibrate any IoU thresholds.
|
||||
|
||||
- Changed [#2312](https://github.com/roboflow/supervision/pull/2312): [`sv.Detections.with_nmm`](https://supervision.roboflow.com/0.29.0/detection/core/#supervision.detection.core.Detections.with_nmm) now computes the merged oriented bounding box as the tightest rectangle at the winner's orientation enclosing all corners from every detection in a merge group.
|
||||
|
||||
- Changed [#2325](https://github.com/roboflow/supervision/pull/2325): [`sv.VertexEllipseAreaAnnotator`](https://supervision.roboflow.com/0.29.0/keypoint/annotators/#supervision.key_points.annotators.VertexEllipseAreaAnnotator), [`sv.VertexEllipseOutlineAnnotator`](https://supervision.roboflow.com/0.29.0/keypoint/annotators/#supervision.key_points.annotators.VertexEllipseOutlineAnnotator), and [`sv.VertexEllipseHaloAnnotator`](https://supervision.roboflow.com/0.29.0/keypoint/annotators/#supervision.key_points.annotators.VertexEllipseHaloAnnotator) now draw sigma levels level-by-level (outermost first) across all points, ensuring correct visual layering when ellipses overlap.
|
||||
|
||||
- Changed [#2256](https://github.com/roboflow/supervision/pull/2256): [`sv.InferenceSlicer`](https://supervision.roboflow.com/0.29.0/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) now detects OBB outputs from callbacks and automatically falls back to sequential processing to avoid thread-safety issues when `thread_workers > 1`.
|
||||
|
||||
- Changed [#2324](https://github.com/roboflow/supervision/pull/2324): Project-wide deprecation policy unified to a minimum 3-minor-release window. All current deprecations (including `KeyPoints.confidence` and `validate_*` helpers) are scheduled for removal in `0.32.0`.
|
||||
|
||||
- Fixed [#2252](https://github.com/roboflow/supervision/pull/2252): [`sv.process_video`](https://supervision.roboflow.com/0.29.0/utils/video/#supervision.utils.video.process_video) audio muxing path now correctly creates temp files on the same filesystem, decodes ffmpeg errors, and avoids muxing incomplete output.
|
||||
|
||||
- Fixed [#2282](https://github.com/roboflow/supervision/pull/2282), [#2317](https://github.com/roboflow/supervision/pull/2317): [`sv.oriented_box_iou_batch`](https://supervision.roboflow.com/0.29.0/detection/utils/iou_and_nms/#supervision.detection.utils.iou_and_nms.oriented_box_iou_batch) now computes exact IoU via convex polygon intersection (`cv2.intersectConvexConvex`) and uses an axis-aligned bounding box envelope gate to skip pairs that cannot overlap, improving both accuracy and performance. Previously, rasterization on a discrete grid was used, which assumed square dimensions and introduced quantisation noise.
|
||||
|
||||
- Fixed [#2239](https://github.com/roboflow/supervision/pull/2239): [`sv.Detections.from_vlm`](https://supervision.roboflow.com/0.29.0/detection/core/#supervision.detection.core.Detections.from_vlm) no longer returns `None` for `class_id` on empty VLM parses; now returns an empty int ndarray.
|
||||
|
||||
- Fixed [#2270](https://github.com/roboflow/supervision/pull/2270): [`sv.Detections.from_inference`](https://supervision.roboflow.com/0.29.0/detection/core/#supervision.detection.core.Detections.from_inference) now preserves `class_name` as a string-dtype array when predictions are empty.
|
||||
|
||||
- Fixed [#2269](https://github.com/roboflow/supervision/pull/2269): [`sv.HeatMapAnnotator`](https://supervision.roboflow.com/0.29.0/detection/annotators/#supervision.annotators.core.HeatMapAnnotator) no longer crashes with a divide-by-zero when called with empty detections.
|
||||
|
||||
- Fixed [#2276](https://github.com/roboflow/supervision/pull/2276): COCO export now emits 1-indexed `category_id` values as required by the COCO specification.
|
||||
|
||||
- Fixed [#2267](https://github.com/roboflow/supervision/pull/2267): COCO annotation and image IDs are now sequential across train/val/test splits via `starting_image_id` and `starting_annotation_id` parameters.
|
||||
|
||||
- Fixed [#2289](https://github.com/roboflow/supervision/pull/2289): [`sv.DetectionDataset.as_yolo`](https://supervision.roboflow.com/0.29.0/datasets/core/#supervision.dataset.core.DetectionDataset.as_yolo) no longer loses OBB rotation when exporting oriented bounding boxes.
|
||||
|
||||
- Fixed [#2296](https://github.com/roboflow/supervision/pull/2296): YOLO dataset loading now sorts class names by numeric keys when `data.yaml` uses integer class IDs.
|
||||
|
||||
- Fixed [#2297](https://github.com/roboflow/supervision/pull/2297): Letterbox utility now supports grayscale images.
|
||||
|
||||
- Fixed [#2298](https://github.com/roboflow/supervision/pull/2298): File extension filters now normalize casing (e.g. `.JPG` matches `.jpg`).
|
||||
|
||||
- Fixed [#2321](https://github.com/roboflow/supervision/pull/2321): [`sv.DetectionDataset.as_coco()`](https://supervision.roboflow.com/0.29.0/datasets/core/#supervision.dataset.core.DetectionDataset.as_coco) now round-trips polygon and RLE segmentation data. Segmentations loaded from COCO annotations are preserved in `detections.data["coco_raw_segmentation"]` and written back on export, preventing data loss in train/val/test split workflows.
|
||||
|
||||
- Deprecated: `KeyPoints.confidence` (use `KeyPoints.keypoint_confidence`), `merge_inner_detection_object_pair`, `merge_inner_detections_objects`, `merge_inner_detections_objects_without_iou`, `validate_detections_fields`, `validate_vlm_parameters`, `validate_fields_both_defined_or_none`, `validate_xyxy`, `validate_mask`, `validate_class_id`, `validate_confidence`, `validate_tracker_id`, `validate_data`, `validate_xy`, `validate_key_point_confidence`, `validate_key_points_fields`, `validate_resolution`, `validate_custom_values`, `validate_input_tensors`, and `validate_labels` are deprecated in `0.29.0` and will be removed in `0.32.0`.
|
||||
|
||||
### 0.28.0 <small>Apr 30, 2026</small>
|
||||
|
||||
- Added [#2159](https://github.com/roboflow/supervision/pull/2159): [`sv.CompactMask`](https://supervision.roboflow.com/latest/detection/compact_mask/#supervision.detection.compact_mask.CompactMask) for memory-efficient mask storage. Masks are stored as crop-region bounding boxes plus RLE-encoded data instead of full-resolution bitmaps, reducing memory by up to 240× for sparse masks. Integrates transparently with `sv.Detections.mask` — filtering, merging, and `area` all work without materialising the full array.
|
||||
|
||||
- Added [#2227](https://github.com/roboflow/supervision/pull/2227): [`sv.CompactMask.resize(new_image_shape)`](https://supervision.roboflow.com/latest/detection/compact_mask/#supervision.detection.compact_mask.CompactMask.resize) rescales all stored crops to match a new image resolution, enabling use across frames or after image resizing pipelines.
|
||||
|
||||
- Added [#2178](https://github.com/roboflow/supervision/pull/2178): [`sv.Detections.from_inference`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_inference) now supports compressed COCO RLE masks. Inference responses with `rle` or `rle_mask` fields containing a compressed counts string (as produced by `pycocotools`) are decoded directly into binary masks, avoiding a lossy polygon round-trip.
|
||||
|
||||
- Added [#2004](https://github.com/roboflow/supervision/pull/2004): [`sv.Color.from_hex`](https://supervision.roboflow.com/latest/utils/draw/#supervision.draw.color.Color.from_hex) now accepts 8-digit hexadecimal RGBA codes (e.g. `#ff00ff80`). [`Color.as_hex()`](https://supervision.roboflow.com/latest/utils/draw/#supervision.draw.color.Color.as_hex) serialises back, including alpha when not fully opaque. New utility functions `sv.hex_to_rgba`, `sv.rgba_to_hex`, and `sv.is_valid_hex` are exported at the top level.
|
||||
|
||||
- Added [#709](https://github.com/roboflow/supervision/pull/709): [`sv.BlurAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BlurAnnotator) and [`sv.PixelateAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.PixelateAnnotator) now support dynamic sizing. When `kernel_size=None` or `pixel_size=None` (the new default), the size is computed per detection as a fraction of the shorter bounding-box dimension, producing consistent visual results across objects of different sizes.
|
||||
|
||||
- Added [#2186](https://github.com/roboflow/supervision/pull/2186): [`sv.InferenceSlicer`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) now emits a warning when detections returned by the callback fall outside the tile boundaries, helping catch coordinate-system bugs in custom callbacks.
|
||||
|
||||
- Added [#2103](https://github.com/roboflow/supervision/pull/2103), [#2152](https://github.com/roboflow/supervision/pull/2152): New [`sv.Detections.from_sam3()`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_sam3) classmethod parses SAM3 PCS (text-prompted) and PVS (visual-prompted video segmentation) response formats into a standard `sv.Detections`, both from the local `inference` package and from Roboflow-hosted server responses.
|
||||
|
||||
- Added [#2154](https://github.com/roboflow/supervision/pull/2154): The library now uses Python's `logging` module instead of `print` for diagnostic output. Messages are emitted under the `supervision` logger so applications can capture, filter, or silence them through standard `logging` configuration.
|
||||
|
||||
- Added [#932](https://github.com/roboflow/supervision/pull/932): [`sv.ImageAssets`](https://supervision.roboflow.com/latest/assets/) for downloading sample images alongside existing video assets, useful for examples and tutorials.
|
||||
|
||||
- Changed [#2169](https://github.com/roboflow/supervision/pull/2169): [`sv.MeanAveragePrecisionResult`](https://supervision.roboflow.com/latest/metrics/mean_average_precision/) and related metric arrays (`mAP_scores`, `ap_per_class`, `iou_thresholds`, precision/recall) are now `float32` instead of `float64`. Reduces memory and speeds up computation; numerical results may differ in the last few digits.
|
||||
|
||||
- Changed [#2178](https://github.com/roboflow/supervision/pull/2178): [`sv.rle_to_mask`](https://supervision.roboflow.com/latest/detection/utils/converters/#supervision.detection.utils.converters.rle_to_mask) and [`sv.mask_to_rle`](https://supervision.roboflow.com/latest/detection/utils/converters/#supervision.detection.utils.converters.mask_to_rle) moved to `supervision.detection.utils.converters`. The old import path `supervision.dataset.utils` continues to work but is deprecated.
|
||||
|
||||
@@ -14,6 +121,46 @@ description: "Full version history of the supervision Python library — release
|
||||
|
||||
- Fixed [#2210](https://github.com/roboflow/supervision/pull/2210): [`sv.VideoInfo.fps`](https://supervision.roboflow.com/latest/utils/video/#supervision.utils.video.VideoInfo) now returns a `float` instead of a truncated `int`. Previously, frame rates like 23.976, 29.97, and 59.94 were silently truncated, causing frame-timing drift that accumulates over long videos. The type of `VideoInfo.fps` has changed from `int` to `float`; callers that pass `fps` to APIs requiring an integer (such as `deque(maxlen=...)` or `TraceAnnotator(trace_length=...)`) should wrap the value with `int()`.
|
||||
|
||||
- Fixed [#2209](https://github.com/roboflow/supervision/pull/2209): [`sv.Detections.is_empty()`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.is_empty) now returns `True` for detections filtered down to zero rows, even when `tracker_id` is an empty array. Previously this case incorrectly returned `False`.
|
||||
|
||||
- Fixed [#2199](https://github.com/roboflow/supervision/pull/2199): [`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) now correctly slices numpy array values in `custom_data` per row. Previously the full array was written for every detection.
|
||||
|
||||
- Fixed [#2216](https://github.com/roboflow/supervision/pull/2216): [`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and [`sv.JSONSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.json_sink.JSONSink) now slice plain Python `list` and `tuple` values in `custom_data` per detection row. Lists and tuples matching the detection count are indexed per row, consistent with `np.ndarray` behavior.
|
||||
|
||||
- Fixed [#2217](https://github.com/roboflow/supervision/pull/2217): [`sv.TraceAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.TraceAnnotator) no longer crashes in `smooth` mode when a tracker remains stationary. Duplicate consecutive points caused `splprep` to fail; the annotator now deduplicates anchor points and falls back to a raw polyline when fewer than 4 unique points are available.
|
||||
|
||||
- Fixed [#2218](https://github.com/roboflow/supervision/pull/2218): [`load_coco_annotations`](https://supervision.roboflow.com/latest/datasets/core/) now rejects COCO annotations whose `file_name` escapes the images directory via `../` traversal or absolute paths, preventing path-traversal attacks from malicious annotation files.
|
||||
|
||||
- Fixed [#2187](https://github.com/roboflow/supervision/pull/2187): Extreme memory usage when loading OBB (oriented bounding box) datasets, caused by allocating full-image masks for each rotated box, has been resolved.
|
||||
|
||||
- Fixed [#2188](https://github.com/roboflow/supervision/pull/2188): [`sv.KeyPoints`](https://supervision.roboflow.com/latest/keypoint/core/#supervision.key_points.core.KeyPoints) boolean mask indexing now works correctly when all instances have the same keypoint count (uniform-count selection).
|
||||
|
||||
- Fixed [#2185](https://github.com/roboflow/supervision/pull/2185): [`sv.DetectionDataset.as_coco()`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.as_coco) now preserves `area` and `iscrowd` fields instead of silently dropping them in the round-trip.
|
||||
|
||||
- Fixed [#1746](https://github.com/roboflow/supervision/pull/1746): Precision loss when converting annotations with `force_mask=True` in dataset format converters.
|
||||
|
||||
- Fixed [#1991](https://github.com/roboflow/supervision/pull/1991): [`sv.PolygonZone`](https://supervision.roboflow.com/latest/detection/tools/polygon_zone/) no longer double-counts the same object when multiple zones overlap. Detection bounding boxes were incorrectly clipped to each zone's ROI before anchor computation, causing the same detection to appear at a different anchor point in each zone; anchor is now computed from the original bounding box so containment is independent per zone.
|
||||
|
||||
- Fixed [#1868](https://github.com/roboflow/supervision/pull/1868): [`sv.LineZone`](https://supervision.roboflow.com/latest/detection/tools/line_zone/) no longer mis-attributes crossings when a tracker reuses the same `tracker_id` across different classes. Class-aware bookkeeping prevents a new object from inheriting another class's prior crossing state.
|
||||
|
||||
- Fixed [#2022](https://github.com/roboflow/supervision/pull/2022): [`sv.process_video`](https://supervision.roboflow.com/latest/utils/video/#supervision.utils.video.process_video) now raises immediately when the user callback throws, instead of silently swallowing the exception and hanging until the writer is flushed.
|
||||
|
||||
- Fixed [#2156](https://github.com/roboflow/supervision/pull/2156): [`sv.DetectionDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset) now populates `data["class_name"]` on every loaded annotation, matching what model connectors produce. Downstream code can rely on `class_name` being present whether detections come from a dataset or a model.
|
||||
|
||||
- Fixed [#1364](https://github.com/roboflow/supervision/pull/1364): [`sv.ByteTrack`](https://supervision.roboflow.com/latest/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) now preserves externally assigned `tracker_id` values instead of overwriting them with internal ids on the first update.
|
||||
|
||||
- Fixed [#1853](https://github.com/roboflow/supervision/pull/1853): [`sv.ConfusionMatrix`](https://supervision.roboflow.com/latest/detection/metrics/#supervision.metrics.detection.ConfusionMatrix) `evaluate_detection_batch` now matches predictions to ground truth correctly when multiple detections fall on the same target. Previously, double-counting inflated false-positive and false-negative counts.
|
||||
|
||||
- Fixed [#2136](https://github.com/roboflow/supervision/pull/2136): [`sv.MeanAverageRecall`](https://supervision.roboflow.com/latest/metrics/mean_average_recall/) now computes mAR@K using the top-K detections per image, matching the COCO definition. Previous values were inflated relative to `pycocotools`.
|
||||
|
||||
- Fixed [#1086](https://github.com/roboflow/supervision/pull/1086), [#265](https://github.com/roboflow/supervision/pull/265): COCO export and `force_masks` behaviour are now consistent across dataset formats. Empty polygons no longer raise during `as_coco`, and `force_masks=True` produces masks regardless of source format.
|
||||
|
||||
- Deprecated [#2215](https://github.com/roboflow/supervision/pull/2215): [`sv.ByteTrack`](https://supervision.roboflow.com/latest/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) is deprecated in favour of `ByteTrackTracker` from the external [`trackers`](https://pypi.org/project/trackers/) package (`pip install trackers`). The update method is renamed from `update_with_detections()` to `update()`. Removal planned for `supervision-0.30.0`.
|
||||
|
||||
- Deprecated [#2214](https://github.com/roboflow/supervision/pull/2214): `supervision.keypoint` module is deprecated; use `supervision.key_points` instead. `create_tiles` in `supervision.utils.image`, `ensure_cv2_image_for_processing` in `supervision.utils.conversion`, and keypoint validation utilities in `supervision.validators` are deprecated. The `LMM` enum (use `VLM`) and `from_lmm` method (use `from_vlm`) were deprecated in 0.26.0; this release migrates their deprecation mechanism to `pydeprecate`.
|
||||
|
||||
- Deprecated: `normalized_xyxy` argument in [`sv.denormalize_boxes`](https://supervision.roboflow.com/latest/detection/utils/boxes/#supervision.detection.utils.boxes.denormalize_boxes) renamed to `xyxy`. Passing `normalized_xyxy=` now emits a `FutureWarning`; support will be removed in `supervision-0.30.0`.
|
||||
|
||||
### 0.27.0 <small>Nov 16, 2025</small>
|
||||
|
||||
- Added [#2008](https://github.com/roboflow/supervision/pull/2008): [`sv.filter_segments_by_distance`](https://supervision.roboflow.com/0.27.0/detection/utils/masks/#supervision.detection.utils.masks.filter_segments_by_distance) to keep the largest connected component and nearby components within an absolute or relative distance threshold. Useful for cleaning segmentation predictions from models such as SAM, SAM2, YOLO segmentation, and RF-DETR segmentation.
|
||||
@@ -307,7 +454,7 @@ sv.process_video(
|
||||
|
||||
- Added `as_detections` method to [`KeyPoints`](https://supervision.roboflow.com/0.25.0/keypoint/core/#supervision.keypoint.core.KeyPoints) that converts `KeyPoints` to `Detections`. ([#1658](https://github.com/roboflow/supervision/pull/1658))
|
||||
|
||||
- Added a new video to `supervision[assets]`. ([#1657](https://github.com/roboflow/supervision/pull/1657))
|
||||
- Added a new video to the `supervision.assets` download catalog. ([#1657](https://github.com/roboflow/supervision/pull/1657))
|
||||
|
||||
```python
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
|
||||
@@ -0,0 +1,29 @@
|
||||
---
|
||||
comments: true
|
||||
description: Contact and support channels for Supervision documentation, bugs, feature requests, security reports, and community help.
|
||||
---
|
||||
|
||||
# Contact
|
||||
|
||||
Use the channel that matches the kind of request you have.
|
||||
|
||||
## Bugs and Feature Requests
|
||||
|
||||
Open a GitHub issue for reproducible bugs, API requests, documentation fixes, and feature proposals:
|
||||
|
||||
[github.com/roboflow/supervision/issues](https://github.com/roboflow/supervision/issues)
|
||||
|
||||
## Community Support
|
||||
|
||||
Join the Roboflow Discord for community questions, examples, and implementation discussion:
|
||||
|
||||
[discord.gg/GbfgXGJ8Bk](https://discord.gg/GbfgXGJ8Bk)
|
||||
|
||||
## Package and Source
|
||||
|
||||
- PyPI package: [pypi.org/project/supervision](https://pypi.org/project/supervision/)
|
||||
- GitHub repository: [github.com/roboflow/supervision](https://github.com/roboflow/supervision)
|
||||
|
||||
## Security Reports
|
||||
|
||||
For security-sensitive reports, avoid posting public exploit details in an issue. Use GitHub's private vulnerability reporting flow for the repository when available, or contact Roboflow through the security and support channels listed on [roboflow.com](https://roboflow.com/).
|
||||
@@ -1,6 +1,7 @@
|
||||
---
|
||||
template: cookbooks.html
|
||||
comments: true
|
||||
description: Collection of practical computer vision cookbooks — object tracking, zero-shot detection, SAHI small object detection, occupancy analytics, and more.
|
||||
hide:
|
||||
- navigation
|
||||
- toc
|
||||
|
||||
@@ -7,8 +7,7 @@ description: API reference for supervision's DetectionDataset and Classification
|
||||
|
||||
!!! warning
|
||||
|
||||
Dataset API is still fluid and may change. If you use Dataset API in your project until further notice, freeze the
|
||||
`supervision` version in your `requirements.txt` or `setup.py`.
|
||||
Dataset API is still fluid and may change. If you use Dataset API in your project until further notice, freeze the `supervision` version in your `requirements.txt` or `setup.py`.
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>DetectionDataset</h2>
|
||||
|
||||
+15
-4
@@ -5,20 +5,31 @@ status: deprecated
|
||||
|
||||
# Deprecated
|
||||
|
||||
These features are phased out due to better alternatives or potential issues in future versions. Deprecated functionalities are supported for **five subsequent releases**, providing time for users to transition to updated methods.
|
||||
These features are phased out due to better alternatives or potential issues in future versions. Deprecated functionalities are typically supported for multiple subsequent releases, providing time for users to transition to updated methods.
|
||||
|
||||
- `overlap_ratio_wh` in [`InferenceSlicer.__init__`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/) is deprecated and will be removed in `supervision-0.27.0`. Please set it to `None` and use `overlap_wh` instead.
|
||||
- [`sv.ByteTrack`](https://supervision.roboflow.com/latest/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) is deprecated in favour of `ByteTrackTracker` from the external [`trackers`](https://pypi.org/project/trackers/) package (`pip install trackers`). The update method is renamed from `update_with_detections()` to `update()`. Removal planned for `supervision-0.30.0`.
|
||||
- `supervision.keypoint` module is deprecated; use `supervision.key_points` instead. Will be removed in `supervision-0.30.0`.
|
||||
- `create_tiles` in `supervision.utils.image` is deprecated. Will be removed in `supervision-0.31.0`.
|
||||
- `ensure_cv2_image_for_processing` in `supervision.utils.conversion` is deprecated. Will be removed in `supervision-0.31.0`.
|
||||
- Keypoint validation utilities in `supervision.validators` are deprecated. Will be removed in `supervision-0.31.0`.
|
||||
- `normalized_xyxy` argument in [`sv.denormalize_boxes`](https://supervision.roboflow.com/latest/detection/utils/boxes/#supervision.detection.utils.boxes.denormalize_boxes) is renamed to `xyxy`. Passing `normalized_xyxy=` emits a `FutureWarning`; support will be removed in `supervision-0.30.0`.
|
||||
- `supervision.dataset.utils` import path for [`sv.rle_to_mask`](https://supervision.roboflow.com/latest/detection/utils/converters/#supervision.detection.utils.converters.rle_to_mask) and [`sv.mask_to_rle`](https://supervision.roboflow.com/latest/detection/utils/converters/#supervision.detection.utils.converters.mask_to_rle) is deprecated. These functions moved to `supervision.detection.utils.converters`. Will be removed in `supervision-0.30.0`.
|
||||
- `sv.LMM` enum is deprecated and will be removed in `supervision-0.31.0`. Use `sv.VLM` instead.
|
||||
- [`sv.Detections.from_lmm`](https://supervision.roboflow.com/0.26.0/detection/core/#supervision.detection.core.Detections.from_lmm) property is deprecated and will be removed in `supervision-0.31.0`. Use [`sv.Detections.from_vlm`](https://supervision.roboflow.com/0.26.0/detection/core/#supervision.detection.core.Detections.from_vlm) instead.
|
||||
- [`sv.Detections.from_lmm`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_lmm) property is deprecated and will be removed in `supervision-0.31.0`. Use [`sv.Detections.from_vlm`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_vlm) instead.
|
||||
- Public `validate_*` helper functions are deprecated and will be removed in `supervision-0.31.0`. Supervision internals now use private `_validate_*` helpers.
|
||||
|
||||
# Removed
|
||||
|
||||
### 0.27.0
|
||||
|
||||
- `overlap_ratio_wh` parameter in [`sv.InferenceSlicer`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/) has been removed. Use the pixel-based `overlap_wh` parameter instead.
|
||||
- `overlap_filter_strategy` parameter in [`sv.InferenceSlicer`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/) has been removed. Use `overlap_strategy` instead.
|
||||
|
||||
### 0.26.0
|
||||
|
||||
- The `sv.DetectionDataset.images` property has been removed in `supervision-0.26.0`. Please loop over images with `for path, image, annotation in dataset:`, as that does not require loading all images into memory. Also, constructing `sv.DetectionDataset` with parameter `images` as `Dict[str, np.ndarray]` is deprecated and has been removed in `supervision-0.26.0`. Please pass a list of paths `List[str]` instead.
|
||||
- The name `sv.BoundingBoxAnnotator` is deprecated and has been removed in `supervision-0.26.0`. It has been renamed to [`sv.BoxAnnotator`](https://supervision.roboflow.com/0.22.0/detection/annotators/#supervision.annotators.core.BoxAnnotator).
|
||||
|
||||
|
||||
### 0.24.0
|
||||
|
||||
- The `frame_resolution_wh ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) has been removed.
|
||||
|
||||
+445
-424
@@ -7,510 +7,531 @@ description: API reference for supervision's annotator classes — draw bounding
|
||||
|
||||
Annotators accept detections and apply box or mask visualizations to the detections. Annotators have many available styles.
|
||||
|
||||
=== "Box"
|
||||
=== "Outlines"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
=== "Box"
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "RoundBox"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
round_box_annotator = sv.RoundBoxAnnotator()
|
||||
annotated_frame = round_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "BoxCorner"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
corner_annotator = sv.BoxCornerAnnotator()
|
||||
annotated_frame = corner_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Color"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
color_annotator = sv.ColorAnnotator()
|
||||
annotated_frame = color_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Circle"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
circle_annotator = sv.CircleAnnotator()
|
||||
annotated_frame = circle_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Dot"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
dot_annotator = sv.DotAnnotator()
|
||||
annotated_frame = dot_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Triangle"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
triangle_annotator = sv.TriangleAnnotator()
|
||||
annotated_frame = triangle_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Ellipse"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
ellipse_annotator = sv.EllipseAnnotator()
|
||||
annotated_frame = ellipse_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Halo"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
halo_annotator = sv.HaloAnnotator()
|
||||
annotated_frame = halo_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "PercentageBar"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
percentage_bar_annotator = sv.PercentageBarAnnotator()
|
||||
annotated_frame = percentage_bar_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Mask"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
annotated_frame = mask_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Polygon"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
polygon_annotator = sv.PolygonAnnotator()
|
||||
annotated_frame = polygon_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Label"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence in zip(
|
||||
detections["class_name"],
|
||||
detections.confidence,
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
]
|
||||
```
|
||||
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(), detections=detections, labels=labels
|
||||
)
|
||||
```
|
||||
<div class="result" markdown>
|
||||
|
||||
<div class="result" markdown>
|
||||
{ align=center width="800" }
|
||||
|
||||
{ align=center width="800" }
|
||||
</div>
|
||||
|
||||
</div>
|
||||
=== "RoundBox"
|
||||
|
||||
=== "RichLabel"
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence in zip(
|
||||
detections["class_name"],
|
||||
detections.confidence,
|
||||
round_box_annotator = sv.RoundBoxAnnotator()
|
||||
annotated_frame = round_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
]
|
||||
```
|
||||
|
||||
rich_label_annotator = sv.RichLabelAnnotator(
|
||||
font_path="TTF_FONT_PATH",
|
||||
text_position=sv.Position.CENTER,
|
||||
)
|
||||
annotated_frame = rich_label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
labels=labels,
|
||||
)
|
||||
```
|
||||
<div class="result" markdown>
|
||||
|
||||
<div class="result" markdown>
|
||||
{ align=center width="800" }
|
||||
|
||||
{ align=center width="800" }
|
||||
</div>
|
||||
|
||||
</div>
|
||||
=== "BoxCorner"
|
||||
|
||||
=== "Icon"
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
corner_annotator = sv.BoxCornerAnnotator()
|
||||
annotated_frame = corner_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
icon_paths = ["<ICON_PATH>" for _ in detections]
|
||||
<div class="result" markdown>
|
||||
|
||||
icon_annotator = sv.IconAnnotator()
|
||||
annotated_frame = icon_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
icon_path=icon_paths,
|
||||
)
|
||||
```
|
||||
{ align=center width="800" }
|
||||
|
||||
<div class="result" markdown>
|
||||
</div>
|
||||
|
||||
{ align=center width="800" }
|
||||
=== "Circle"
|
||||
|
||||
</div>
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
<!-- === "Crop"
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
circle_annotator = sv.CircleAnnotator()
|
||||
annotated_frame = circle_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
<div class="result" markdown>
|
||||
|
||||
crop_annotator = sv.CropAnnotator()
|
||||
annotated_frame = crop_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
{ align=center width="800" }
|
||||
|
||||
<div class="result" markdown>
|
||||
</div>
|
||||
|
||||
{ align=center width="800" }
|
||||
=== "Ellipse"
|
||||
|
||||
</div>
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
-->
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
=== "Blur"
|
||||
ellipse_annotator = sv.EllipseAnnotator()
|
||||
annotated_frame = ellipse_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
<div class="result" markdown>
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
{ align=center width="800" }
|
||||
|
||||
blur_annotator = sv.BlurAnnotator()
|
||||
annotated_frame = (blur_annotator.annotate(scene=image.copy(), detections=detections),)
|
||||
```
|
||||
</div>
|
||||
|
||||
<div class="result" markdown>
|
||||
=== "Polygon"
|
||||
|
||||
{ align=center width="800" }
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
</div>
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
=== "Pixelate"
|
||||
polygon_annotator = sv.PolygonAnnotator()
|
||||
annotated_frame = polygon_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
<div class="result" markdown>
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
{ align=center width="800" }
|
||||
|
||||
pixelate_annotator = sv.PixelateAnnotator()
|
||||
annotated_frame = pixelate_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
</div>
|
||||
|
||||
<div class="result" markdown>
|
||||
=== "Shading"
|
||||
|
||||
{ align=center width="800" }
|
||||
=== "Color"
|
||||
|
||||
</div>
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
=== "Trace"
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
color_annotator = sv.ColorAnnotator()
|
||||
annotated_frame = color_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
<div class="result" markdown>
|
||||
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
{ align=center width="800" }
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path="...")
|
||||
frames_generator = sv.get_video_frames_generator(source_path="...")
|
||||
tracker = sv.ByteTrack()
|
||||
</div>
|
||||
|
||||
with sv.VideoSink(target_path="...", video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
annotated_frame = trace_annotator.annotate(
|
||||
scene=frame.copy(),
|
||||
detections=detections,
|
||||
=== "Halo"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
halo_annotator = sv.HaloAnnotator()
|
||||
annotated_frame = halo_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Mask"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
annotated_frame = mask_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
!!! note
|
||||
|
||||
`MaskAnnotator` expects `detections.mask` to contain instance segmentation masks aligned to the image passed to `annotate`. For dense masks, provide a boolean array of shape `(N, H, W)` where `(H, W)` matches the image height and width (it also accepts `sv.CompactMask`). If your model returns framework-specific results, convert them to `sv.Detections` first, for example with `sv.Detections.from_ultralytics(...)` or `sv.Detections.from_inference(...)`.
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Markers"
|
||||
|
||||
=== "Dot"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
dot_annotator = sv.DotAnnotator()
|
||||
annotated_frame = dot_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Triangle"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
triangle_annotator = sv.TriangleAnnotator()
|
||||
annotated_frame = triangle_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Labels"
|
||||
|
||||
=== "Label"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence in zip(
|
||||
detections["class_name"],
|
||||
detections.confidence,
|
||||
)
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
```
|
||||
]
|
||||
|
||||
<div class="result" markdown>
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(), detections=detections, labels=labels
|
||||
)
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
<div class="result" markdown>
|
||||
|
||||
</div>
|
||||
{ align=center width="800" }
|
||||
|
||||
=== "HeatMap"
|
||||
</div>
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
=== "RichLabel"
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
heat_map_annotator = sv.HeatMapAnnotator()
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path="...")
|
||||
frames_generator = sv.get_video_frames_generator(source_path="...")
|
||||
|
||||
with sv.VideoSink(target_path="...", video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
annotated_frame = heat_map_annotator.annotate(
|
||||
scene=frame.copy(),
|
||||
detections=detections,
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence in zip(
|
||||
detections["class_name"],
|
||||
detections.confidence,
|
||||
)
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
```
|
||||
]
|
||||
|
||||
<div class="result" markdown>
|
||||
rich_label_annotator = sv.RichLabelAnnotator(
|
||||
font_path="TTF_FONT_PATH",
|
||||
text_position=sv.Position.CENTER,
|
||||
)
|
||||
annotated_frame = rich_label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
labels=labels,
|
||||
)
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
<div class="result" markdown>
|
||||
|
||||
</div>
|
||||
{ align=center width="800" }
|
||||
|
||||
=== "Background Color"
|
||||
</div>
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
=== "Transformative"
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
=== "Blur"
|
||||
|
||||
background_overlay_annotator = sv.BackgroundOverlayAnnotator()
|
||||
annotated_frame = background_overlay_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
<div class="result" markdown>
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
{ align=center width="800" }
|
||||
blur_annotator = sv.BlurAnnotator()
|
||||
annotated_frame = blur_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
</div>
|
||||
<div class="result" markdown>
|
||||
|
||||
=== "Comparison"
|
||||
{ align=center width="800" }
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
</div>
|
||||
|
||||
image = ...
|
||||
detections_1 = sv.Detections(...)
|
||||
detections_2 = sv.Detections(...)
|
||||
=== "Pixelate"
|
||||
|
||||
comparison_annotator = sv.ComparisonAnnotator()
|
||||
annotated_frame = comparison_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections_1=detections_1,
|
||||
detections_2=detections_2,
|
||||
)
|
||||
```
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
<div class="result" markdown>
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
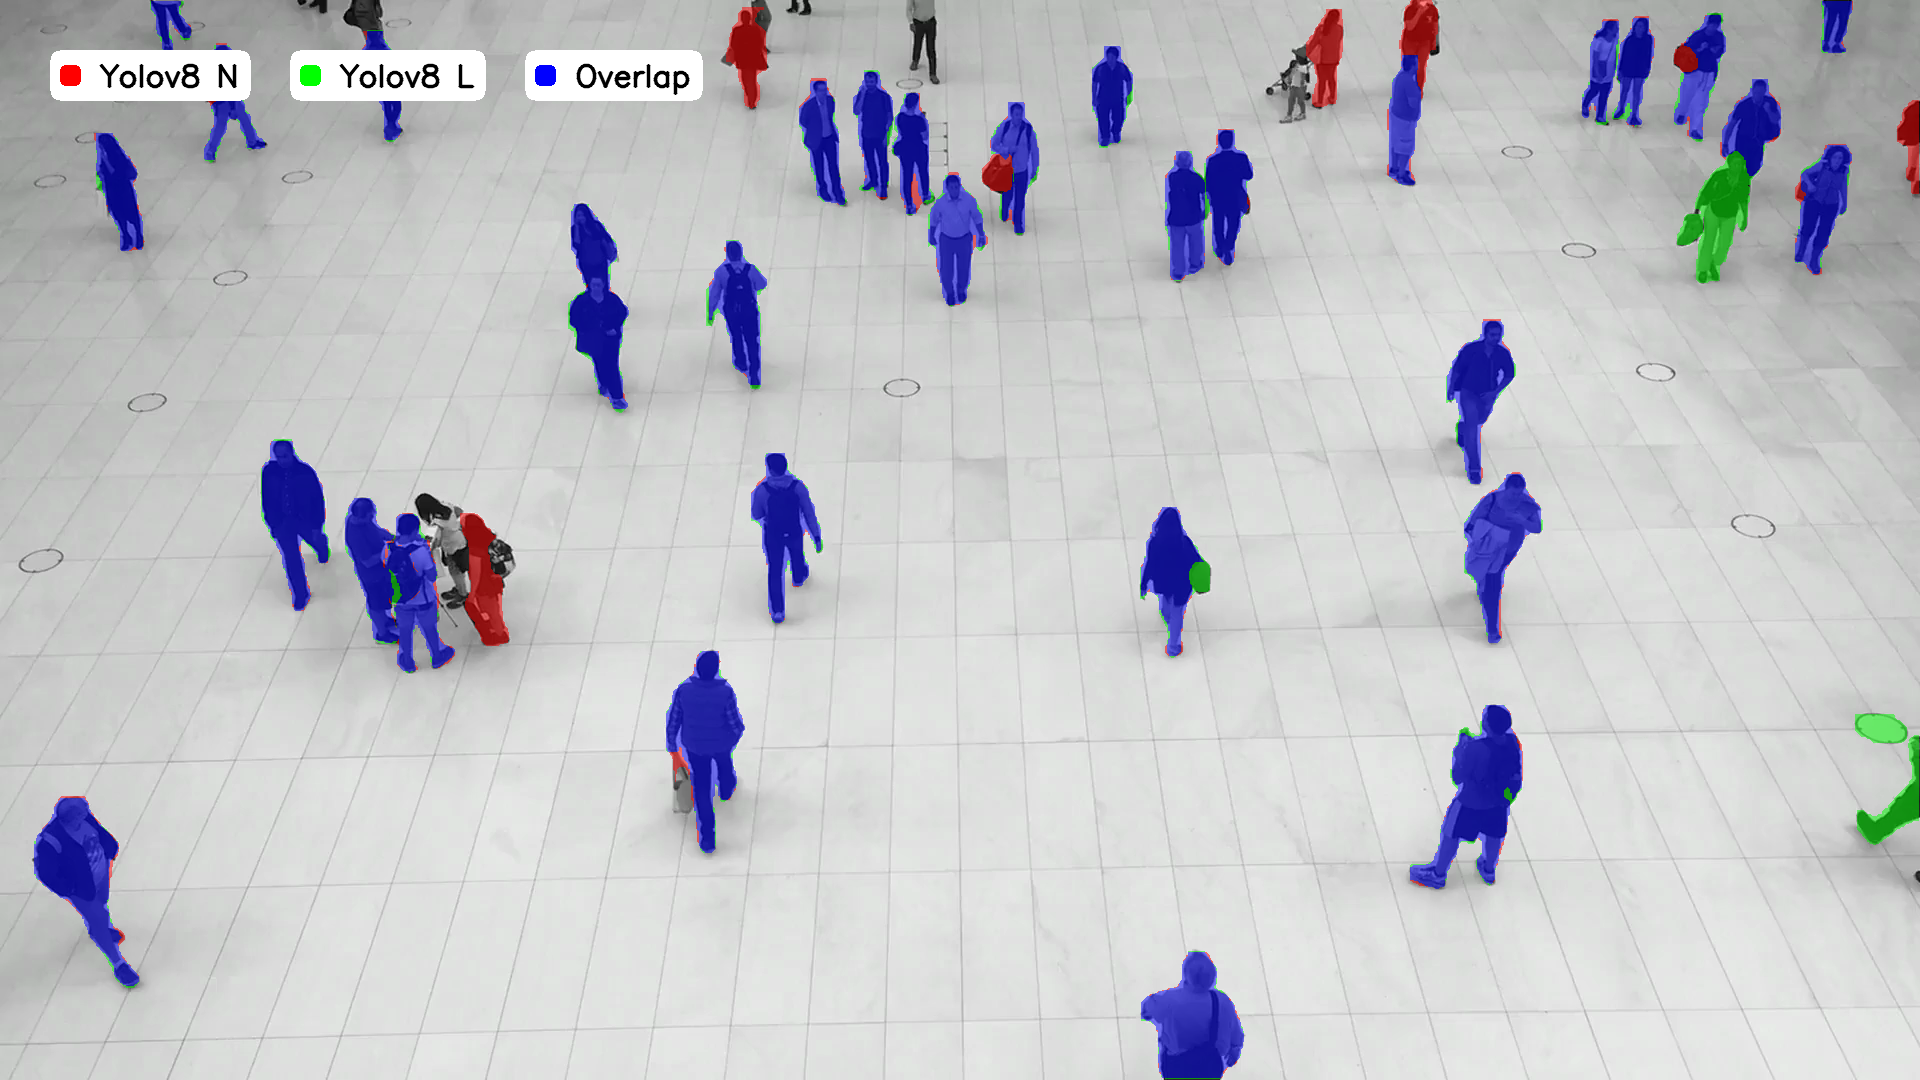{ align=center width="800" }
|
||||
pixelate_annotator = sv.PixelateAnnotator()
|
||||
annotated_frame = pixelate_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
</div>
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
<!-- === "Crop"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
crop_annotator = sv.CropAnnotator()
|
||||
annotated_frame = crop_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
-->
|
||||
|
||||
=== "Tracking & Aggregation"
|
||||
|
||||
=== "Trace"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path="...")
|
||||
frames_generator = sv.get_video_frames_generator(source_path="...")
|
||||
tracker = sv.ByteTrack()
|
||||
|
||||
with sv.VideoSink(target_path="...", video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
annotated_frame = trace_annotator.annotate(
|
||||
scene=frame.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "HeatMap"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
|
||||
heat_map_annotator = sv.HeatMapAnnotator()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path="...")
|
||||
frames_generator = sv.get_video_frames_generator(source_path="...")
|
||||
|
||||
with sv.VideoSink(target_path="...", video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
annotated_frame = heat_map_annotator.annotate(
|
||||
scene=frame.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Others"
|
||||
|
||||
=== "PercentageBar"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
percentage_bar_annotator = sv.PercentageBarAnnotator()
|
||||
annotated_frame = percentage_bar_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Icon"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
icon_paths = ["<ICON_PATH>" for _ in detections]
|
||||
|
||||
icon_annotator = sv.IconAnnotator()
|
||||
annotated_frame = icon_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
icon_path=icon_paths,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Background Color"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
background_overlay_annotator = sv.BackgroundOverlayAnnotator()
|
||||
annotated_frame = background_overlay_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Comparison"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections_1 = sv.Detections(...)
|
||||
detections_2 = sv.Detections(...)
|
||||
|
||||
comparison_annotator = sv.ComparisonAnnotator()
|
||||
annotated_frame = comparison_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections_1=detections_1,
|
||||
detections_2=detections_2,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>Try Supervision Annotators on your own image</h2>
|
||||
|
||||
@@ -4,8 +4,7 @@ comments: true
|
||||
|
||||
# Legacy Metrics
|
||||
|
||||
Starting with `0.23.0`, a new metrics module is being introduced to supervision.
|
||||
Metrics here are part of the legacy evaluation API and will be deprecated in the future.
|
||||
Starting with `0.23.0`, a new metrics module is being introduced to supervision. Metrics here are part of the legacy evaluation API and will be deprecated in the future.
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
|
||||
@@ -33,3 +33,9 @@ comments: true
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.boxes.denormalize_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.boxes.xyxyxyxy_to_xyxy">xyxyxyxy_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.boxes.xyxyxyxy_to_xyxy
|
||||
|
||||
@@ -69,3 +69,15 @@ comments: true
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.mask_non_max_merge
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.oriented_box_non_max_suppression">oriented_box_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.oriented_box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.oriented_box_non_max_merge">oriented_box_non_max_merge</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.oriented_box_non_max_merge
|
||||
|
||||
+58
@@ -0,0 +1,58 @@
|
||||
---
|
||||
comments: true
|
||||
description: Frequently asked questions about installing Supervision, supported computer vision models, datasets, tracking, metrics, and licensing.
|
||||
---
|
||||
|
||||
# Frequently Asked Questions
|
||||
|
||||
## What is Supervision?
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified `Detections` class with converters for supported object detection, segmentation, and VLM outputs.
|
||||
|
||||
## How do I install Supervision?
|
||||
|
||||
Install the base package with:
|
||||
|
||||
```bash
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
Use the `metrics` extra when you need optional metric dependencies:
|
||||
|
||||
```bash
|
||||
pip install "supervision[metrics]"
|
||||
```
|
||||
|
||||
Sample asset utilities are part of the base package under `supervision.assets`.
|
||||
|
||||
## Which object detection models work with Supervision?
|
||||
|
||||
Supervision is model agnostic. `sv.Detections` includes converters for Ultralytics YOLO, Roboflow Inference, Hugging Face Transformers outputs, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers including Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. Keypoint outputs have separate `sv.KeyPoints` converters, including MediaPipe.
|
||||
|
||||
## What can I do with Supervision?
|
||||
|
||||
You can annotate images and video, filter detections, track objects, count objects in zones or across lines, load and convert datasets, evaluate models with detection metrics, and export predictions for downstream analysis.
|
||||
|
||||
## How do I track objects across video frames?
|
||||
|
||||
Assign persistent tracker IDs before visualization. The built-in `sv.ByteTrack` wrapper accepts `Detections` through `update_with_detections()`. After tracking, combine the output with annotators such as `sv.TraceAnnotator`, `sv.BoxAnnotator`, and `sv.LabelAnnotator`.
|
||||
|
||||
## What dataset formats does Supervision support?
|
||||
|
||||
For detection datasets, Supervision supports YOLO, COCO JSON, and Pascal VOC. Use `DetectionDataset.from_yolo()`, `DetectionDataset.from_coco()`, or `DetectionDataset.from_pascal_voc()` to load datasets, and the matching `as_*` methods to export them.
|
||||
|
||||
## How do I count objects in a zone?
|
||||
|
||||
Use `sv.PolygonZone` for arbitrary polygon regions and `sv.LineZone` for line-crossing counts. Line crossing requires `detections.tracker_id`, so run a tracker before calling the line zone trigger.
|
||||
|
||||
## How do I benchmark a model?
|
||||
|
||||
Use `supervision.metrics.mean_average_precision.MeanAveragePrecision` for mAP and `sv.ConfusionMatrix` for confusion matrices. Accumulate predictions and ground-truth `Detections`, then call `compute()` to calculate metrics.
|
||||
|
||||
## Is Supervision free to use?
|
||||
|
||||
Yes. Supervision is free and open source under the MIT license.
|
||||
|
||||
## Where is the source code?
|
||||
|
||||
The source code is available at [github.com/roboflow/supervision](https://github.com/roboflow/supervision).
|
||||
@@ -1,6 +1,11 @@
|
||||
---
|
||||
comments: true
|
||||
description: Benchmark object detection models with supervision — compute mAP, confusion matrix, and per-class metrics to compare model performance.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
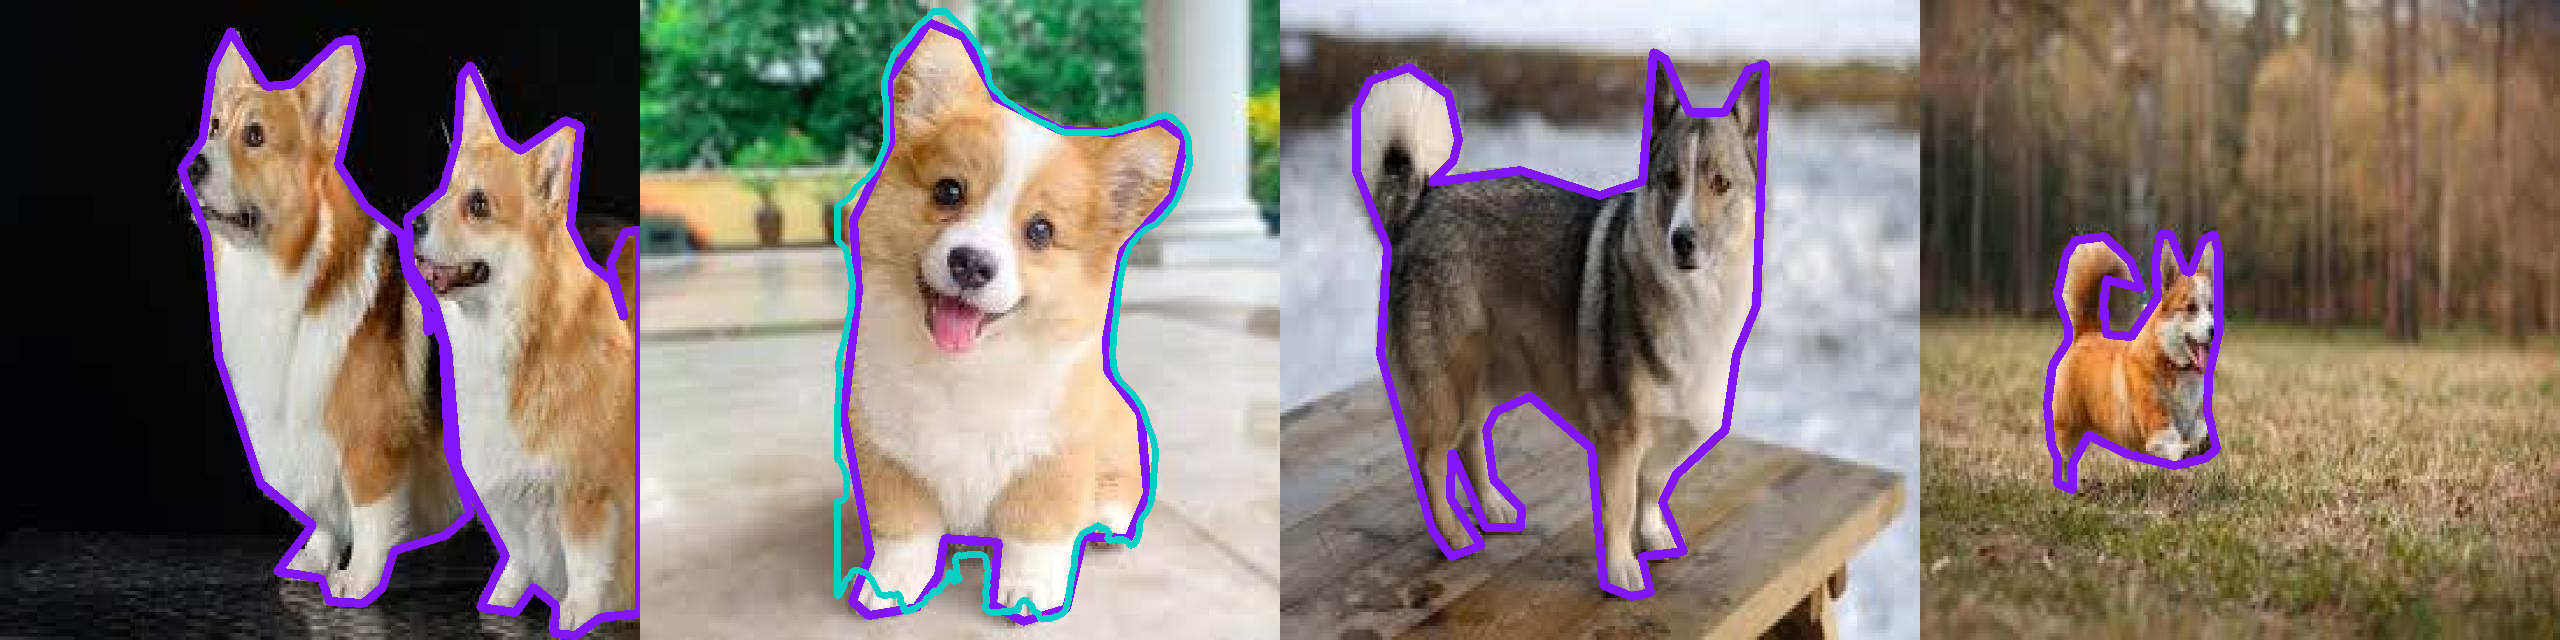
|
||||
@@ -125,8 +130,7 @@ Evaluating your model requires careful selection of the dataset. Which images sh
|
||||
- **Validation Set**: This is the set of images used to validate the model during training. Every Nth training epoch, the model is evaluated on the validation set. Often the training is stopped once the validation loss stops improving. Therefore, even while the images aren't used to train the model, it still indirectly influences the training outcome.
|
||||
- **Test Set**: This is the set of images kept aside for model testing. It is exactly the set you should use for benchmarking. If the dataset was split correctly, none of these images would be shown to the model during training.
|
||||
|
||||
Therefore, an unrelated dataset or the `test` set is the best choice for benchmarking.
|
||||
Several other problems may arise:
|
||||
Therefore, an unrelated dataset or the `test` set is the best choice for benchmarking. Several other problems may arise:
|
||||
|
||||
- **Extra Classes**: An unrelated dataset may contain additional classes which you may need to [filter out](https://supervision.roboflow.com/how_to/filter_detections/#by-set-of-classes) before computing metrics.
|
||||
- **Class Mismatch**: In an unrelated dataset, the class names or IDs may be different to what your model produces, you'll need to remap them, which is [shown in this guide](#running-a-model).
|
||||
@@ -140,8 +144,7 @@ At this stage, you should have:
|
||||
- A dataset of labeled images to evaluate the model.
|
||||
- A model prepared for benchmarking.
|
||||
|
||||
With these ready, we can now run the model and obtain predictions.
|
||||
We'll use `supervision` to create a dataset iterator, and then run the model on each image.
|
||||
With these ready, we can now run the model and obtain predictions. We'll use `supervision` to create a dataset iterator, and then run the model on each image.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
@@ -193,8 +196,7 @@ We'll use `supervision` to create a dataset iterator, and then run the model on
|
||||
|
||||
## Remapping classes
|
||||
|
||||
Did you notice an issue in the above logic?
|
||||
Since we're using an unrelated dataset, the class names and IDs may be different from what the model was trained on.
|
||||
Did you notice an issue in the above logic? Since we're using an unrelated dataset, the class names and IDs may be different from what the model was trained on.
|
||||
|
||||
We need to remap them to match the dataset classes. Here's how to do it:
|
||||
|
||||
@@ -254,8 +256,7 @@ Let's also remove the predictions that are not in the dataset classes.
|
||||
|
||||
Dataset class names and IDs can be found in the `data.yaml` file, or by printing `dataset.classes`.
|
||||
|
||||
Each model will have a different class mapping, so make sure to check the model's documentation. In this case, the model was trained on the COCO dataset, with a class
|
||||
configuration found [here](https://github.com/ultralytics/ultralytics/blob/main/ultralytics/cfg/datasets/coco8.yaml).
|
||||
Each model will have a different class mapping, so make sure to check the model's documentation. In this case, the model was trained on the COCO dataset, with a class configuration found [here](https://github.com/ultralytics/ultralytics/blob/main/ultralytics/cfg/datasets/coco8.yaml).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
@@ -288,8 +289,7 @@ Let's also remove the predictions that are not in the dataset classes.
|
||||
|
||||
## Visualizing Predictions
|
||||
|
||||
The first step in evaluating your model’s performance is to visualize its predictions.
|
||||
This gives an intuitive sense of how well your model is detecting objects and where it might be failing.
|
||||
The first step in evaluating your model’s performance is to visualize its predictions. This gives an intuitive sense of how well your model is detecting objects and where it might be failing.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
@@ -445,3 +445,25 @@ A condensed version of this guide is also available as a [Colab Notebook](https:
|
||||
For more details, be sure to check out our [documentation](https://supervision.roboflow.com/latest/) and join our community discussions. If you find any issues, please let us know on [GitHub](https://github.com/roboflow/supervision/issues).
|
||||
|
||||
Best of luck with your benchmarking!
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I benchmark a model with supervision?
|
||||
|
||||
Use `supervision.metrics.mean_average_precision.MeanAveragePrecision` — accumulate prediction and ground-truth `Detections` with `update(...)` and then call `compute()`. For confusion matrices, use `sv.ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes)`.
|
||||
|
||||
### What IoU thresholds does MeanAveragePrecision use?
|
||||
|
||||
It computes mAP over IoU thresholds from 0.50 to 0.95 in steps of 0.05 (mAP@50:95), plus mAP@50 and mAP@75 individually.
|
||||
|
||||
### Can I benchmark segmentation models?
|
||||
|
||||
Yes, if you want to evaluate their bounding boxes. Convert model outputs to `Detections` and pass them to `MeanAveragePrecision.update(...)`; the current mAP path prepares COCO-style bounding boxes from `detections.xyxy`.
|
||||
|
||||
### What is a ConfusionMatrix and how do I use it?
|
||||
|
||||
`sv.ConfusionMatrix` visualizes true positives, false positives, and false negatives per class. Create one with `sv.ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes, conf_threshold=0.5, iou_threshold=0.5)`, then call `metric.plot()` to render a heatmap.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,6 +1,11 @@
|
||||
---
|
||||
comments: true
|
||||
description: Count objects entering a polygon zone in images and video using supervision's PolygonZone — measure throughput and density in any region.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
With supervision, you can count the number of objects in a zone in an image or video. In this guide, we will show how to count the number of cars in a traffic video.
|
||||
@@ -132,3 +137,21 @@ Here is an example of inference run on the video:
|
||||
<video width="100%" loop muted autoplay>
|
||||
<source src="https://blog.roboflow.com/content/media/2023/03/trim-counting.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I count objects in a zone with supervision?
|
||||
|
||||
Create `sv.PolygonZone` with a polygon defining your region. Call `zone.trigger(detections)` on each frame — it returns a mask of detections inside the zone.
|
||||
|
||||
### Can I count objects crossing a line instead of entering a zone?
|
||||
|
||||
Yes. Use `sv.LineZone` — define a start and end point. `zone.trigger(detections)` returns a tuple of two boolean arrays, `(crossed_in, crossed_out)`, indicating which detections crossed the line in each direction. `LineZone` requires `detections.tracker_id`; run a tracker first so the same object can be matched across frames.
|
||||
|
||||
### Can I combine zone counting with tracking?
|
||||
|
||||
Yes. You can pass tracker IDs from `sv.ByteTrack` alongside your detections, but `sv.PolygonZone` still evaluates the zone on each frame and reports which objects are currently inside it. If you want to count each object only once when it first enters the zone, maintain a set of seen `tracker_id` values after filtering detections with `zone.trigger(detections)`, or use a dedicated entry/crossing counting tool such as `sv.LineZone` when it better matches your use case.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,24 +1,37 @@
|
||||
---
|
||||
comments: true
|
||||
description: Learn to load model predictions, create Detections objects, and annotate images with bounding boxes, labels, and masks using supervision.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
- name: Borda
|
||||
role: Open Source Engineer, Roboflow
|
||||
github: https://github.com/borda
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
# Detect and Annotate
|
||||
|
||||
Supervision provides a seamless process for annotating predictions generated by various
|
||||
object detection and segmentation models. This guide shows how to perform inference
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision and use them to annotate
|
||||
source image.
|
||||
!!! tip "Sample Image"
|
||||
|
||||
Don't have an image? Download the one used in this tutorial:
|
||||
|
||||
```bash
|
||||
wget https://media.roboflow.com/notebooks/examples/dog.jpeg
|
||||
```
|
||||
|
||||
```
|
||||
Then replace `<SOURCE_IMAGE_PATH>` with `"dog.jpeg"`.
|
||||
```
|
||||
|
||||
Supervision provides a seamless process for annotating predictions generated by various object detection and segmentation models. This guide shows how to perform inference with the [Inference](https://github.com/roboflow/inference), [Ultralytics](https://github.com/ultralytics/ultralytics) or [Transformers](https://github.com/huggingface/transformers) packages. Following this, you'll learn how to import these predictions into Supervision and use them to annotate source image.
|
||||
|
||||
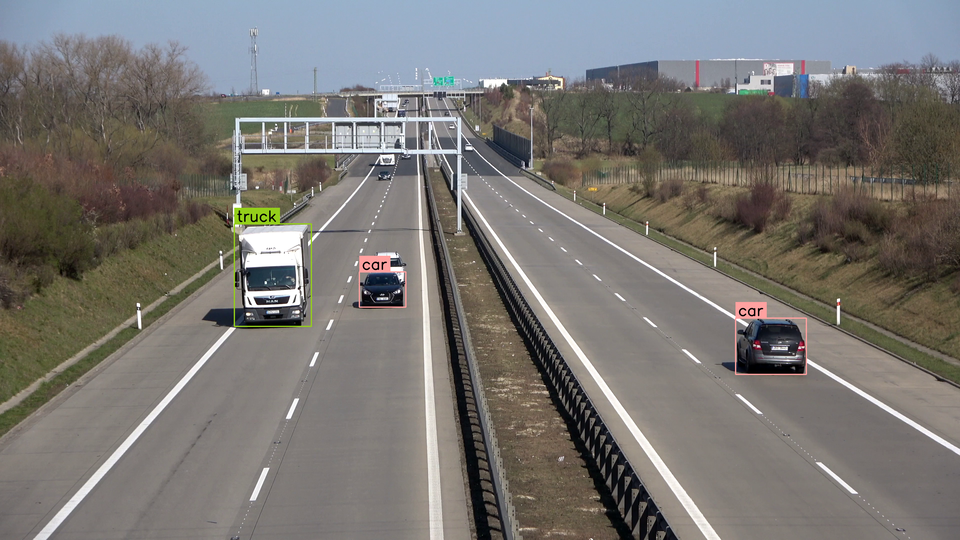
|
||||
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model.
|
||||
First, you'll need to obtain predictions from your object detection or segmentation model.
|
||||
|
||||
To run inference, initialize your chosen model and pass the source image to its predict or infer method. Supervision supports Roboflow Inference, Ultralytics YOLO, and Hugging Face Transformers -- select the tab matching your framework. The result is a framework-specific object you will convert to a `Detections` instance in the next step.
|
||||
|
||||
@@ -29,7 +42,7 @@ To run inference, initialize your chosen model and pass the source image to its
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
image = cv2.imread("dog.jpeg")
|
||||
results = model.infer(image)[0]
|
||||
```
|
||||
|
||||
@@ -40,7 +53,7 @@ To run inference, initialize your chosen model and pass the source image to its
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
image = cv2.imread("dog.jpeg")
|
||||
results = model(image)[0]
|
||||
```
|
||||
|
||||
@@ -54,7 +67,7 @@ To run inference, initialize your chosen model and pass the source image to its
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open("<SOURCE_IMAGE_PATH>")
|
||||
image = Image.open("dog.jpeg")
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
@@ -83,7 +96,7 @@ Each supported framework has a dedicated class method on `sv.Detections` that co
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
image = cv2.imread("dog.jpeg")
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
@@ -98,7 +111,7 @@ Each supported framework has a dedicated class method on `sv.Detections` that co
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
image = cv2.imread("dog.jpeg")
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
@@ -116,7 +129,7 @@ Each supported framework has a dedicated class method on `sv.Detections` that co
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open("<SOURCE_IMAGE_PATH>")
|
||||
image = Image.open("dog.jpeg")
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
@@ -153,7 +166,7 @@ To draw bounding boxes and class labels on your image, create a `BoxAnnotator` a
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
image = cv2.imread("dog.jpeg")
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
@@ -174,7 +187,7 @@ To draw bounding boxes and class labels on your image, create a `BoxAnnotator` a
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
image = cv2.imread("dog.jpeg")
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
@@ -198,7 +211,7 @@ To draw bounding boxes and class labels on your image, create a `BoxAnnotator` a
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open("<SOURCE_IMAGE_PATH>")
|
||||
image = Image.open("dog.jpeg")
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
@@ -225,9 +238,7 @@ To draw bounding boxes and class labels on your image, create a `BoxAnnotator` a
|
||||
|
||||
## Display Custom Labels
|
||||
|
||||
By default, [`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator)
|
||||
will label each detection with its `class_name` (if possible) or `class_id`. You can
|
||||
override this behavior by passing a list of custom `labels` to the `annotate` method.
|
||||
By default, [`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator) will label each detection with its `class_name` (if possible) or `class_id`. You can override this behavior by passing a list of custom `labels` to the `annotate` method.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
@@ -237,7 +248,7 @@ override this behavior by passing a list of custom `labels` to the `annotate` me
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
image = cv2.imread("dog.jpeg")
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
@@ -264,7 +275,7 @@ override this behavior by passing a list of custom `labels` to the `annotate` me
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
image = cv2.imread("dog.jpeg")
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
@@ -294,7 +305,7 @@ override this behavior by passing a list of custom `labels` to the `annotate` me
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open("<SOURCE_IMAGE_PATH>")
|
||||
image = Image.open("dog.jpeg")
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
@@ -327,11 +338,7 @@ override this behavior by passing a list of custom `labels` to the `annotate` me
|
||||
|
||||
## Annotate Image with Segmentations
|
||||
|
||||
If you are running the segmentation model
|
||||
[`sv.MaskAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.MaskAnnotator)
|
||||
is a drop-in replacement for
|
||||
[`sv.BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator)
|
||||
that will allow you to draw masks instead of boxes.
|
||||
If you are running the segmentation model [`sv.MaskAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.MaskAnnotator) is a drop-in replacement for [`sv.BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator) that will allow you to draw masks instead of boxes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
@@ -341,7 +348,7 @@ that will allow you to draw masks instead of boxes.
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-seg-640")
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
image = cv2.imread("dog.jpeg")
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
@@ -356,6 +363,7 @@ that will allow you to draw masks instead of boxes.
|
||||
scene=annotated_image,
|
||||
detections=detections,
|
||||
)
|
||||
sv.plot_image(annotated_image)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
@@ -366,7 +374,7 @@ that will allow you to draw masks instead of boxes.
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n-seg.pt")
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
image = cv2.imread("dog.jpeg")
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
@@ -394,7 +402,7 @@ that will allow you to draw masks instead of boxes.
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
|
||||
image = Image.open("<SOURCE_IMAGE_PATH>")
|
||||
image = Image.open("dog.jpeg")
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
@@ -427,3 +435,26 @@ that will allow you to draw masks instead of boxes.
|
||||
```
|
||||
|
||||
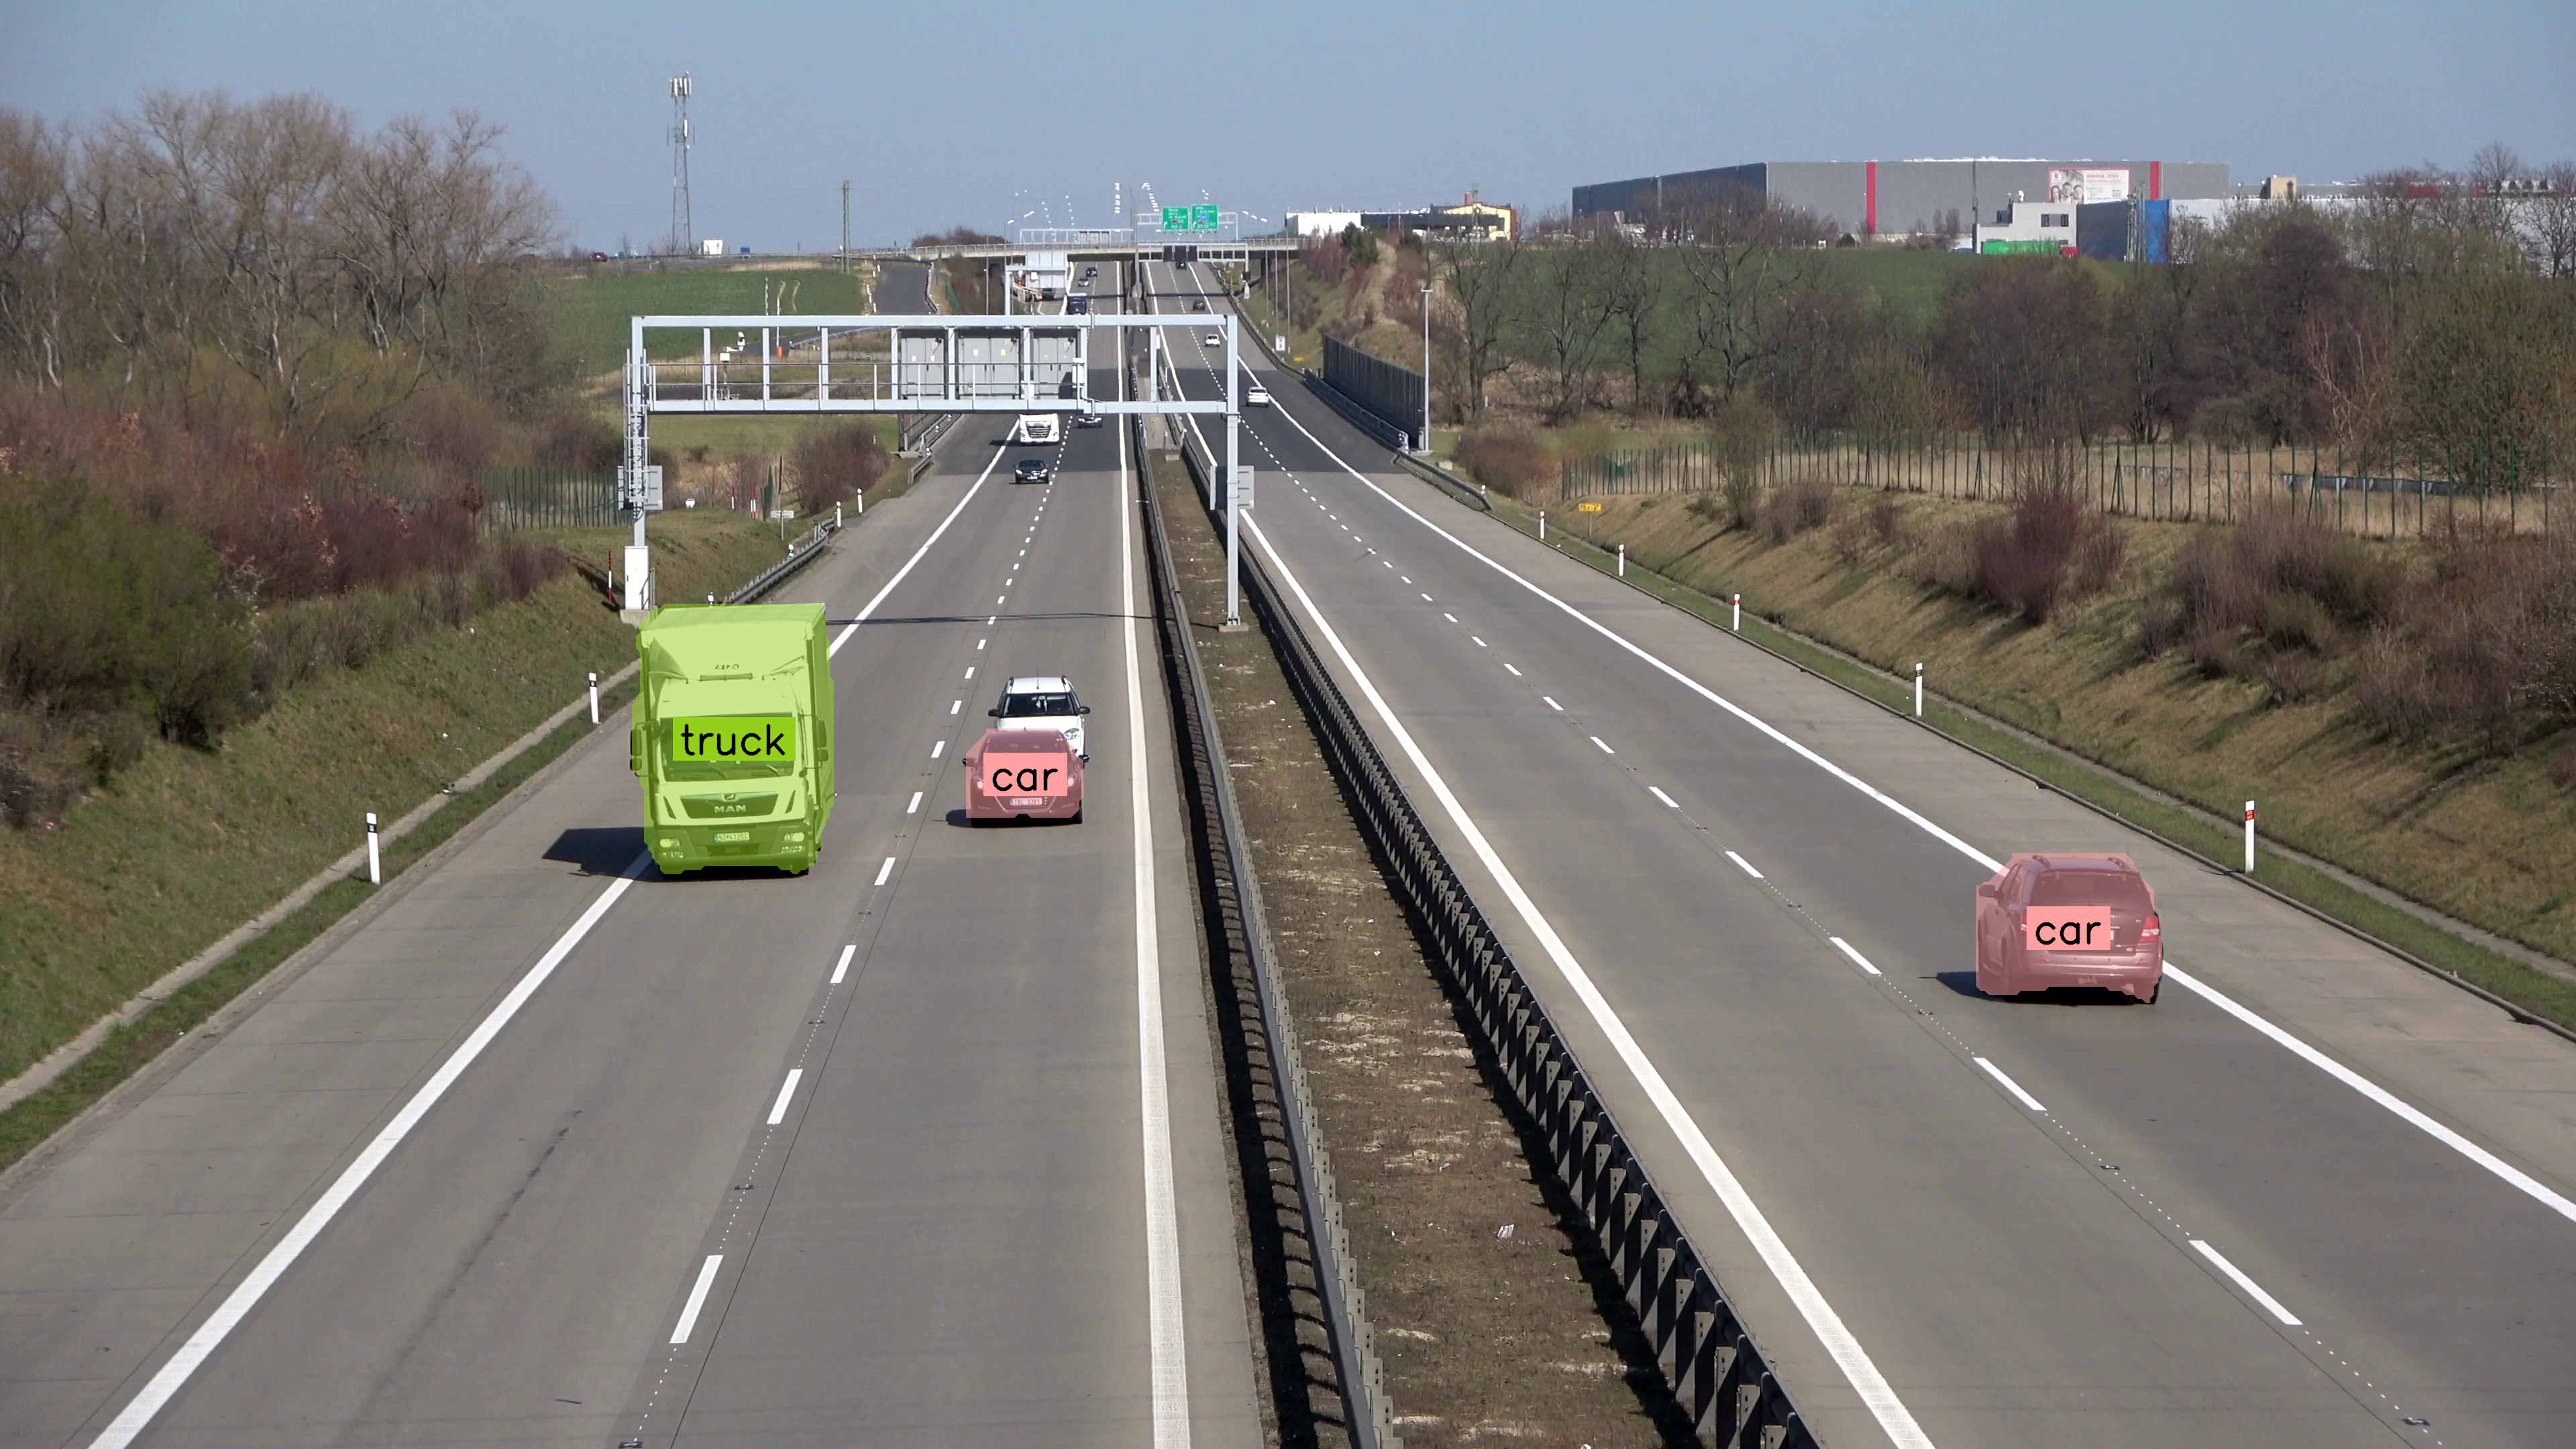
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I detect and annotate objects with supervision?
|
||||
|
||||
Pass any model's output to `sv.Detections.from_<model>()` to create a unified `Detections` object. Then pass it to `sv.BoxAnnotator` or `sv.MaskAnnotator` to draw predictions on an image.
|
||||
|
||||
### Can I annotate both bounding boxes and masks at the same time?
|
||||
|
||||
Yes. Chain annotators: first draw boxes with `BoxAnnotator`, then overlay masks with `MaskAnnotator` on the same scene.
|
||||
|
||||
### How do I label detections with class names?
|
||||
|
||||
Use `sv.LabelAnnotator` and pass custom text with the `labels` parameter. If a connector provides class names, they are stored in `detections["class_name"]` / `detections.data["class_name"]`; when `labels` is omitted, `LabelAnnotator` uses class names first, then class IDs, then detection indices.
|
||||
|
||||
### Can I use supervision with Hugging Face models?
|
||||
|
||||
Yes. `sv.Detections.from_transformers()` accepts supported Hugging Face object detection and segmentation outputs. Vision-language model outputs are handled through `sv.Detections.from_vlm(...)`, for example with `sv.VLM.FLORENCE_2` or `sv.VLM.PALIGEMMA`.
|
||||
|
||||
## Authors
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
- [Borda](https://github.com/borda) — Open Source Engineer, Roboflow
|
||||
|
||||
@@ -1,15 +1,16 @@
|
||||
---
|
||||
comments: true
|
||||
description: Detect small objects in images by applying SAHI inference slicing with supervision's InferenceSlicer — improve recall for tiny targets.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
# Detect Small Objects
|
||||
|
||||
This guide shows how to detect small objects
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages using
|
||||
[`InferenceSlicer`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer).
|
||||
This guide shows how to detect small objects with the [Inference](https://github.com/roboflow/inference), [Ultralytics](https://github.com/ultralytics/ultralytics) or [Transformers](https://github.com/huggingface/transformers) packages using [`InferenceSlicer`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer).
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example.mp4" type="video/mp4">
|
||||
@@ -17,8 +18,7 @@ with the [Inference](https://github.com/roboflow/inference),
|
||||
|
||||
## Baseline Detection
|
||||
|
||||
Small object detection in high-resolution images presents challenges due to the objects'
|
||||
size relative to the image resolution.
|
||||
Small object detection in high-resolution images presents challenges due to the objects' size relative to the image resolution.
|
||||
|
||||
Running a standard detection model on the full image establishes a baseline for comparison. Load your chosen model, pass the image through it, and convert the results into a `Detections` object. This baseline reveals how many small objects the model misses at native resolution, motivating the sliced inference approach shown later.
|
||||
|
||||
@@ -111,9 +111,7 @@ Running a standard detection model on the full image establishes a baseline for
|
||||
|
||||
## Input Resolution
|
||||
|
||||
Modifying the input resolution of images before detection can enhance small object
|
||||
identification at the cost of processing speed and increased memory usage. This method
|
||||
is less effective for ultra-high-resolution images (4K and above).
|
||||
Modifying the input resolution of images before detection can enhance small object identification at the cost of processing speed and increased memory usage. This method is less effective for ultra-high-resolution images (4K and above).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
@@ -161,9 +159,7 @@ is less effective for ultra-high-resolution images (4K and above).
|
||||
|
||||
## Inference Slicer
|
||||
|
||||
[`InferenceSlicer`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer)
|
||||
processes high-resolution images by dividing them into smaller segments, detecting
|
||||
objects within each, and aggregating the results.
|
||||
[`InferenceSlicer`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) processes high-resolution images by dividing them into smaller segments, detecting objects within each, and aggregating the results.
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example_2.mp4" type="video/mp4">
|
||||
@@ -331,3 +327,21 @@ objects within each, and aggregating the results.
|
||||
```
|
||||
|
||||
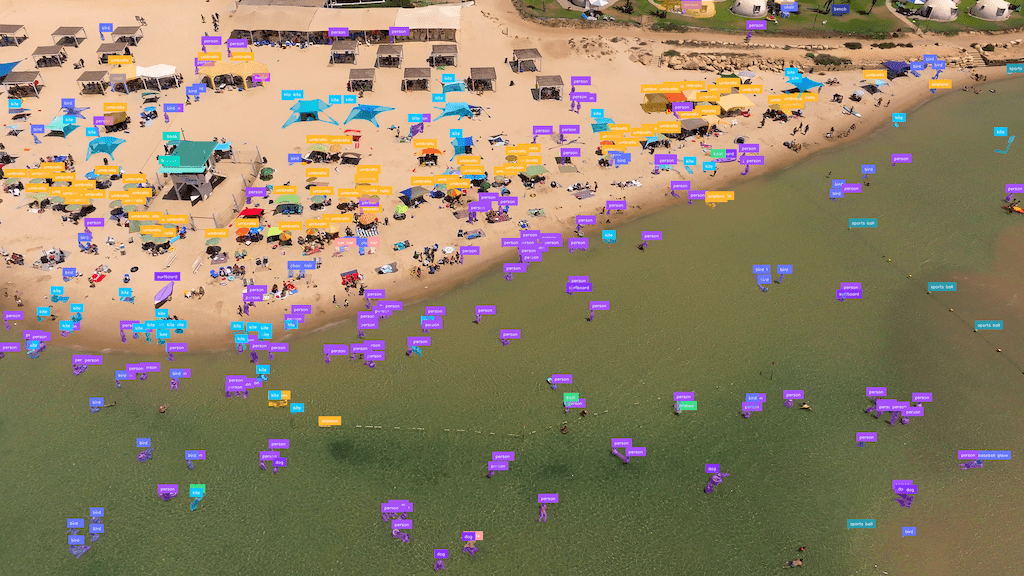
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I detect small objects with supervision?
|
||||
|
||||
Use `sv.InferenceSlicer` to split a high-resolution image into overlapping tiles, run detection on each tile, and merge results with non-maximum suppression. This dramatically improves recall for tiny targets.
|
||||
|
||||
### What overlap should I use between tiles?
|
||||
|
||||
`InferenceSlicer` takes overlap in pixels via `overlap_wh`, not as a percentage. The default is `100` pixels in both directions. Increase `overlap_wh` when objects are close to the tile size or often appear on tile boundaries, and decrease it when speed is more important.
|
||||
|
||||
### Can I use InferenceSlicer with any detection model?
|
||||
|
||||
Yes. Wrap any model or converter path that can produce `sv.Detections` in a callback, pass that callback to `sv.InferenceSlicer(callback=...)`, and then call the slicer with your image.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,15 +1,16 @@
|
||||
---
|
||||
comments: true
|
||||
description: Filter and query detection results by class, confidence, or spatial overlap using supervision's Detections API — clean predictions in one line.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
# Filter Detections
|
||||
|
||||
The advanced filtering capabilities of the `Detections` class offer users a versatile and efficient way to narrow down
|
||||
and refine object detections. This section outlines various filtering methods, including filtering by specific class
|
||||
or a set of classes, confidence, object area, bounding box area, relative area, box dimensions, and designated zones.
|
||||
Each method is demonstrated with concise code examples to provide users with a clear understanding of how to implement
|
||||
the filters in their applications.
|
||||
The advanced filtering capabilities of the `Detections` class offer users a versatile and efficient way to narrow down and refine object detections. This section outlines various filtering methods, including filtering by specific class or a set of classes, confidence, object area, bounding box area, relative area, box dimensions, and designated zones. Each method is demonstrated with concise code examples to provide users with a clear understanding of how to implement the filters in their applications.
|
||||
|
||||
### by specific class
|
||||
|
||||
@@ -119,8 +120,7 @@ Allows you to select detections with specific confidence value, for example high
|
||||
|
||||
### by area
|
||||
|
||||
Allows you to select detections based on their size. We define the area as the number of pixels occupied by the
|
||||
detection in the image. In the example below, we have sifted out the detections that are too small.
|
||||
Allows you to select detections based on their size. We define the area as the number of pixels occupied by the detection in the image. In the example below, we have sifted out the detections that are too small.
|
||||
|
||||
=== "After"
|
||||
|
||||
@@ -154,10 +154,7 @@ detection in the image. In the example below, we have sifted out the detections
|
||||
|
||||
### by relative area
|
||||
|
||||
Allows you to select detections based on their size in relation to the size of whole image. Sometimes the concept of
|
||||
detection size changes depending on the image. Detection occupying 10000 square px can be large on a 1280x720 image
|
||||
but small on a 3840x2160 image. In such cases, we can filter out detections based on the percentage of the image area
|
||||
occupied by them. In the example below, we remove too large detections.
|
||||
Allows you to select detections based on their size in relation to the size of whole image. Sometimes the concept of detection size changes depending on the image. Detection occupying 10000 square px can be large on a 1280x720 image but small on a 3840x2160 image. In such cases, we can filter out detections based on the percentage of the image area occupied by them. In the example below, we remove too large detections.
|
||||
|
||||
=== "After"
|
||||
|
||||
@@ -199,9 +196,7 @@ occupied by them. In the example below, we remove too large detections.
|
||||
|
||||
### by box dimensions
|
||||
|
||||
Allows you to select detections based on their dimensions. The size of the bounding box, as well as its coordinates,
|
||||
can be criteria for rejecting detection. Implementing such filtering requires a bit of custom code but is relatively
|
||||
simple and fast.
|
||||
Allows you to select detections based on their dimensions. The size of the bounding box, as well as its coordinates, can be criteria for rejecting detection. Implementing such filtering requires a bit of custom code but is relatively simple and fast.
|
||||
|
||||
=== "After"
|
||||
|
||||
@@ -239,8 +234,7 @@ simple and fast.
|
||||
|
||||
### by `PolygonZone`
|
||||
|
||||
Allows you to use `Detections` in combination with `PolygonZone` to weed out bounding boxes that are in and out of the
|
||||
zone. In the example below you can see how to filter out all detections located in the lower part of the image.
|
||||
Allows you to use `Detections` in combination with `PolygonZone` to weed out bounding boxes that are in and out of the zone. In the example below you can see how to filter out all detections located in the lower part of the image.
|
||||
|
||||
=== "After"
|
||||
|
||||
@@ -313,3 +307,29 @@ zone. In the example below you can see how to filter out all detections located
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I filter detections by class in supervision?
|
||||
|
||||
Use NumPy-style boolean indexing: `detections[detections.class_id == 0]` for class 0. Combine with `&` or `|` for multiple conditions.
|
||||
|
||||
### How do I filter by confidence threshold?
|
||||
|
||||
`detections[detections.confidence > 0.5]` returns only detections above the threshold. Chain with class filters for precise results.
|
||||
|
||||
### How do I filter by bounding box area?
|
||||
|
||||
`detections[detections.area > 1000]` filters by pixel area. If masks are present, `detections.area` uses mask area; otherwise it uses bounding box area from `xyxy`. Use `detections.box_area` when you specifically need bounding box area.
|
||||
|
||||
### Can I filter by box aspect ratio or dimensions?
|
||||
|
||||
Yes. Use `detections.box_aspect_ratio` for aspect ratio filtering. If you need explicit box dimensions, compute them from `detections.xyxy` as `width = detections.xyxy[:, 2] - detections.xyxy[:, 0]` and `height = detections.xyxy[:, 3] - detections.xyxy[:, 1]`.
|
||||
|
||||
### How do I remove duplicate detections (NMS) from my results?
|
||||
|
||||
Use `detections.with_nms(threshold=0.5)` — it applies non-maximum suppression on the `xyxy` boxes.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,29 +1,24 @@
|
||||
---
|
||||
comments: true
|
||||
description: Load, split, merge, and convert computer vision datasets between YOLO, COCO, and Pascal VOC formats using supervision's DetectionDataset.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
With Supervision, you can load and manipulate classification, object detection, and
|
||||
segmentation datasets. This tutorial will walk you through how to load, split, merge,
|
||||
visualize, and augment datasets in Supervision.
|
||||
With Supervision, you can load and manipulate classification, object detection, and segmentation datasets. This tutorial will walk you through how to load, split, merge, visualize, and augment datasets in Supervision.
|
||||
|
||||
## Download Dataset
|
||||
|
||||
In this tutorial, we will use a dataset from
|
||||
[Roboflow Universe](https://universe.roboflow.com/), a public repository of
|
||||
thousands of computer vision datasets. If you already have your dataset in
|
||||
[COCO](https://roboflow.com/formats/coco-json),
|
||||
[YOLO](https://roboflow.com/formats/yolov8-pytorch-txt),
|
||||
or [Pascal VOC](https://roboflow.com/formats/pascal-voc-xml) format, you can skip this
|
||||
section.
|
||||
In this tutorial, we will use a dataset from [Roboflow Universe](https://universe.roboflow.com/), a public repository of thousands of computer vision datasets. If you already have your dataset in [COCO](https://roboflow.com/formats/coco-json), [YOLO](https://roboflow.com/formats/yolov8-pytorch-txt), or [Pascal VOC](https://roboflow.com/formats/pascal-voc-xml) format, you can skip this section.
|
||||
|
||||
```bash
|
||||
pip install roboflow
|
||||
```
|
||||
|
||||
Next, log into your Roboflow account and download the dataset of your choice in the
|
||||
COCO, YOLO, or Pascal VOC format. You can customize the following code snippet with
|
||||
your workspace ID, project ID, and version number.
|
||||
Next, log into your Roboflow account and download the dataset of your choice in the COCO, YOLO, or Pascal VOC format. You can customize the following code snippet with your workspace ID, project ID, and version number.
|
||||
|
||||
=== "COCO"
|
||||
|
||||
@@ -63,10 +58,7 @@ your workspace ID, project ID, and version number.
|
||||
|
||||
## Load Dataset
|
||||
|
||||
The Supervision library provides convenient functions to load datasets in various
|
||||
formats. If your dataset is already split into train, test, and valid subsets, you can
|
||||
load each of those as separate [`sv.DetectionDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset)
|
||||
instances.
|
||||
The Supervision library provides convenient functions to load datasets in various formats. If your dataset is already split into train, test, and valid subsets, you can load each of those as separate [`sv.DetectionDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset) instances.
|
||||
|
||||
=== "COCO"
|
||||
|
||||
@@ -154,9 +146,7 @@ instances.
|
||||
|
||||
## Split Dataset
|
||||
|
||||
If your dataset is not already split into train, test, and valid subsets, you can
|
||||
easily do so using the [`sv.DetectionDataset.split`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.split)
|
||||
method. We can split it as follows, ensuring a random shuffle of the data.
|
||||
If your dataset is not already split into train, test, and valid subsets, you can easily do so using the [`sv.DetectionDataset.split`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.split) method. We can split it as follows, ensuring a random shuffle of the data.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
@@ -175,9 +165,7 @@ len(ds_train), len(ds_valid), len(ds_test)
|
||||
|
||||
## Merge Dataset
|
||||
|
||||
If you have multiple datasets that you would like to merge, you can do so using the
|
||||
[`sv.DetectionDataset.merge`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.merge)
|
||||
method.
|
||||
If you have multiple datasets that you would like to merge, you can do so using the [`sv.DetectionDataset.merge`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.merge) method.
|
||||
|
||||
=== "COCO"
|
||||
|
||||
@@ -283,10 +271,7 @@ method.
|
||||
|
||||
## Iterate over Dataset
|
||||
|
||||
There are two ways to loop over a `sv.DetectionDataset`: using a direct
|
||||
[for loop](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__iter__)
|
||||
called on the `sv.DetectionDataset` instance or loading `sv.DetectionDataset` entries
|
||||
[by index](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__getitem__).
|
||||
There are two ways to loop over a `sv.DetectionDataset`: using a direct [for loop](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__iter__) called on the `sv.DetectionDataset` instance or loading `sv.DetectionDataset` entries [by index](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__getitem__).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
@@ -305,13 +290,7 @@ for idx in range(len(ds)):
|
||||
|
||||
## Visualize Dataset
|
||||
|
||||
The Supervision library provides tools for easily visualizing your detection dataset.
|
||||
You can create a grid of annotated images to quickly inspect your data and labels.
|
||||
First, initialize the [`sv.BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator)
|
||||
and [`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator).
|
||||
Then, iterate through a subset of the dataset (e.g., the first 25 images), drawing
|
||||
bounding boxes and class labels on each image. Finally, combine the annotated images
|
||||
into a grid for display.
|
||||
The Supervision library provides tools for easily visualizing your detection dataset. You can create a grid of annotated images to quickly inspect your data and labels. First, initialize the [`sv.BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator) and [`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator). Then, iterate through a subset of the dataset (e.g., the first 25 images), drawing bounding boxes and class labels on each image. Finally, combine the annotated images into a grid for display.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
@@ -390,22 +369,13 @@ sv.plot_images_grid(
|
||||
|
||||
## Augment Dataset
|
||||
|
||||
In this section, we'll explore using Supervision in combination with Albumentations to
|
||||
augment our dataset. Data augmentation is a common technique in computer vision to
|
||||
increase the size and diversity of training datasets, leading to improved model
|
||||
performance and generalization.
|
||||
In this section, we'll explore using Supervision in combination with Albumentations to augment our dataset. Data augmentation is a common technique in computer vision to increase the size and diversity of training datasets, leading to improved model performance and generalization.
|
||||
|
||||
```bash
|
||||
pip install albumentations
|
||||
```
|
||||
|
||||
Albumentations provides a flexible and powerful API for image augmentation. The core of
|
||||
the library is the [`Compose`](https://albumentations.ai/docs/api-reference/albumentations/core/composition/#Compose)
|
||||
class, which allows you to chain multiple image transformations together. Each
|
||||
transformation is defined using a dedicated class, such as
|
||||
[`HorizontalFlip`](https://albumentations.ai/docs/api-reference/albumentations/augmentations/geometric/flip/#HorizontalFlip),
|
||||
[`RandomBrightnessContrast`](https://albumentations.ai/docs/api-reference/albumentations/augmentations/pixel/transforms/#RandomBrightnessContrast),
|
||||
or [`Perspective`](https://albumentations.ai/docs/api-reference/albumentations/augmentations/geometric/transforms/#Perspective).
|
||||
Albumentations provides a flexible and powerful API for image augmentation. The core of the library is the [`Compose`](https://albumentations.ai/docs/api-reference/albumentations/core/composition/#Compose) class, which allows you to chain multiple image transformations together. Each transformation is defined using a dedicated class, such as [`HorizontalFlip`](https://albumentations.ai/docs/api-reference/albumentations/augmentations/geometric/flip/#HorizontalFlip), [`RandomBrightnessContrast`](https://albumentations.ai/docs/api-reference/albumentations/augmentations/pixel/transforms/#RandomBrightnessContrast), or [`Perspective`](https://albumentations.ai/docs/api-reference/albumentations/augmentations/geometric/transforms/#Perspective).
|
||||
|
||||
```python
|
||||
import albumentations as A
|
||||
@@ -423,8 +393,7 @@ augmentation = A.Compose(
|
||||
)
|
||||
```
|
||||
|
||||
The key is to set `format='pascal_voc'`, which corresponds to the
|
||||
`[x_min, y_min, x_max, y_max]` bounding box format used in Supervision.
|
||||
The key is to set `format='pascal_voc'`, which corresponds to the `[x_min, y_min, x_max, y_max]` bounding box format used in Supervision.
|
||||
|
||||
```python
|
||||
import numpy as np
|
||||
@@ -450,3 +419,25 @@ augmented_annotations = replace(
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### What dataset formats does supervision support?
|
||||
|
||||
For detection datasets, supervision supports YOLO, COCO JSON, and Pascal VOC. Use `DetectionDataset.from_yolo()`, `from_coco()`, or `from_pascal_voc()` to load, and `as_yolo()`, `as_coco()`, or `as_pascal_voc()` to save. Classification datasets use `ClassificationDataset.from_folder_structure()` and `as_folder_structure()`.
|
||||
|
||||
### Can I split a dataset into train/val/test sets?
|
||||
|
||||
`DetectionDataset.split(split_ratio=0.8)` returns exactly two datasets: train (80%) and test (20%). If you need a validation set, split one of those subsets in a separate step.
|
||||
|
||||
### Can I merge two datasets together?
|
||||
|
||||
Yes. `DetectionDataset.merge([dataset_a, dataset_b])` combines multiple datasets into one. Useful for combining datasets from different sources.
|
||||
|
||||
### What augmentations are available?
|
||||
|
||||
Common augmentations such as flip, rotate, translate, scale, crop, color jitter, and Gaussian blur can be applied using an external library like Albumentations, as shown in the augmentation example above. Supervision does not provide an `sv.Augmenter` pipeline.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,23 +1,20 @@
|
||||
---
|
||||
comments: true
|
||||
description: Save object detection results to CSV or JSON with supervision's CSVSink and JSONSink — export predictions for analysis and downstream pipelines.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
|
||||
Supervision enables an easy way to save detections in .CSV and .JSON files for offline
|
||||
processing. This guide demonstrates how to perform video inference using the
|
||||
[Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages and save their results with
|
||||
[`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and
|
||||
[`sv.JSONSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
Supervision enables an easy way to save detections in .CSV and .JSON files for offline processing. This guide demonstrates how to perform video inference using the [Inference](https://github.com/roboflow/inference), [Ultralytics](https://github.com/ultralytics/ultralytics) or [Transformers](https://github.com/huggingface/transformers) packages and save their results with [`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and [`sv.JSONSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.json_sink.JSONSink).
|
||||
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. You can learn more on this topic in our
|
||||
[How to Detect and Annotate](https://supervision.roboflow.com/latest/how_to/detect_and_annotate/) guide.
|
||||
First, you'll need to obtain predictions from your object detection or segmentation model. You can learn more on this topic in our [How to Detect and Annotate](https://supervision.roboflow.com/latest/how_to/detect_and_annotate/) guide.
|
||||
|
||||
To generate predictions for saving, initialize your model and iterate over video frames using `sv.get_video_frames_generator`. Each frame is passed to the model, and the raw output is converted into a `sv.Detections` object. This detection loop forms the foundation for both CSV and JSON export workflows shown below.
|
||||
|
||||
@@ -77,11 +74,7 @@ To generate predictions for saving, initialize your model and iterate over video
|
||||
|
||||
## Save Detections as CSV
|
||||
|
||||
To save detections to a `.CSV` file, open our
|
||||
[`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
and then pass the
|
||||
[`sv.Detections`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections)
|
||||
object resulting from the inference to it. Its fields are parsed and saved on disk.
|
||||
To save detections to a `.CSV` file, open our [`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and then pass the [`sv.Detections`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections) object resulting from the inference to it. Its fields are parsed and saved on disk.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
@@ -153,12 +146,7 @@ object resulting from the inference to it. Its fields are parsed and saved on di
|
||||
|
||||
## Custom Fields
|
||||
|
||||
Besides regular fields in
|
||||
[`sv.Detections`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections),
|
||||
[`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
also allows you to add custom information to each row, which can be passed via the
|
||||
`custom_data` dictionary. Let's utilize this feature to save information about the
|
||||
frame index from which the detections originate.
|
||||
Besides regular fields in [`sv.Detections`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections), [`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) also allows you to add custom information to each row, which can be passed via the `custom_data` dictionary. Let's utilize this feature to save information about the frame index from which the detections originate.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
@@ -230,11 +218,7 @@ frame index from which the detections originate.
|
||||
|
||||
## Save Detections as JSON
|
||||
|
||||
If you prefer to save the result in a `.JSON` file instead of a `.CSV` file, all you
|
||||
need to do is replace
|
||||
[`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
with
|
||||
[`sv.JSONSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
If you prefer to save the result in a `.JSON` file instead of a `.CSV` file, all you need to do is replace [`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) with [`sv.JSONSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.json_sink.JSONSink).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
@@ -297,3 +281,25 @@ with
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I save detections to CSV with supervision?
|
||||
|
||||
Open `sv.CSVSink("output.csv")` as a context manager and call `sink.append(detections)` for each frame. The CSV includes box coordinates, confidence, class ID, tracker ID, and any fields stored in `detections.data`.
|
||||
|
||||
### Can I save detections to JSON instead?
|
||||
|
||||
Yes. Open `sv.JSONSink("output.json")` as a context manager and call `sink.append(detections)` for each frame. The file is written as a JSON array when the context exits.
|
||||
|
||||
### Can I add custom fields to the saved output?
|
||||
|
||||
Yes. Pass a dict as the second argument: `sink.append(detections, {"frame_index": 5})` — the keys become extra columns in the CSV or extra fields in the JSON.
|
||||
|
||||
### Can I save only specific classes or confidence levels?
|
||||
|
||||
Filter the `Detections` object before saving: `sink.append(detections[detections.confidence > 0.7])`.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,24 +1,23 @@
|
||||
---
|
||||
comments: true
|
||||
description: Track objects across video frames with ByteTrack in supervision — assign persistent IDs and analyze motion from any object detection model.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
- name: Soumik Mandal
|
||||
role: ML Engineer, Roboflow
|
||||
github: https://github.com/soumik12345
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
# Track Objects
|
||||
|
||||
Leverage Supervision's advanced capabilities for enhancing your video analysis by
|
||||
seamlessly [tracking](https://supervision.roboflow.com/latest/trackers/) objects recognized by
|
||||
a multitude of object detection, segmentation and keypoint models. This comprehensive guide will
|
||||
take you through the steps to perform inference using the YOLOv8 model via either the
|
||||
[Inference](https://github.com/roboflow/inference) or
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) packages. Following this,
|
||||
you'll discover how to track these objects efficiently and annotate your video content
|
||||
for a deeper analysis.
|
||||
Leverage Supervision's advanced capabilities for enhancing your video analysis by seamlessly [tracking](https://supervision.roboflow.com/latest/trackers/) objects recognized by a multitude of object detection, segmentation and keypoint models. This comprehensive guide will take you through the steps to perform inference using the YOLOv8 model via either the [Inference](https://github.com/roboflow/inference) or [Ultralytics](https://github.com/ultralytics/ultralytics) packages. Following this, you'll discover how to track these objects efficiently and annotate your video content for a deeper analysis.
|
||||
|
||||
## Object Detection & Segmentation
|
||||
|
||||
To make it easier for you to follow our tutorial download the video we will use as an
|
||||
example. You can do this using
|
||||
[`supervision[assets]`](https://supervision.roboflow.com/latest/assets/) extension.
|
||||
To make it easier for you to follow our tutorial download the video we will use as an example. You can do this using the [`supervision.assets`](https://supervision.roboflow.com/latest/assets/) module included in the base package.
|
||||
|
||||
This section demonstrates how to detect and segment objects in video frames using YOLOv8 with either the Inference or Ultralytics package. You will download a sample video, define a per-frame callback function that runs model prediction, and process the entire video to produce an annotated output file.
|
||||
|
||||
@@ -34,16 +33,9 @@ download_assets(VideoAssets.PEOPLE_WALKING)
|
||||
|
||||
### Run Inference
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. In this tutorial, we are using the YOLOv8 model as an example. However,
|
||||
Supervision is versatile and compatible with various models. Check this
|
||||
[link](https://supervision.roboflow.com/latest/how_to/detect_and_annotate/#load-predictions-into-supervision)
|
||||
for guidance on how to plug in other models.
|
||||
First, you'll need to obtain predictions from your object detection or segmentation model. In this tutorial, we are using the YOLOv8 model as an example. However, Supervision is versatile and compatible with various models. Check this [link](https://supervision.roboflow.com/latest/how_to/detect_and_annotate/#load-predictions-into-supervision) for guidance on how to plug in other models.
|
||||
|
||||
We will define a `callback` function, which will process each frame of the video
|
||||
by obtaining model predictions and then annotating the frame based on these predictions.
|
||||
This `callback` function will be essential in the subsequent steps of the tutorial, as
|
||||
it will be modified to include tracking, labeling, and trace annotations.
|
||||
We will define a `callback` function, which will process each frame of the video by obtaining model predictions and then annotating the frame based on these predictions. This `callback` function will be essential in the subsequent steps of the tutorial, as it will be modified to include tracking, labeling, and trace annotations.
|
||||
|
||||
!!! tip
|
||||
|
||||
@@ -99,11 +91,7 @@ it will be modified to include tracking, labeling, and trace annotations.
|
||||
|
||||
### Tracking
|
||||
|
||||
After running inference and obtaining predictions, the next step is to track the
|
||||
detected objects throughout the video. Utilizing Supervision’s
|
||||
[`sv.ByteTrack`](https://supervision.roboflow.com/latest/trackers/#supervision.tracker.byte_tracker.core.ByteTrack)
|
||||
functionality, each detected object is assigned a unique tracker ID,
|
||||
enabling the continuous following of the object's motion path across different frames.
|
||||
After running inference and obtaining predictions, the next step is to track the detected objects throughout the video. Utilizing Supervision’s [`sv.ByteTrack`](https://supervision.roboflow.com/latest/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) functionality, each detected object is assigned a unique tracker ID, enabling the continuous following of the object's motion path across different frames.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
@@ -155,11 +143,7 @@ enabling the continuous following of the object's motion path across different f
|
||||
|
||||
### Annotate Video with Tracking IDs
|
||||
|
||||
Annotating the video with tracking IDs helps in distinguishing and following each object
|
||||
distinctly. With the
|
||||
[`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator)
|
||||
in Supervision, we can overlay the tracker IDs and class labels on the detected objects,
|
||||
offering a clear visual representation of each object's class and unique identifier.
|
||||
Annotating the video with tracking IDs helps in distinguishing and following each object distinctly. With the [`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator) in Supervision, we can overlay the tracker IDs and class labels on the detected objects, offering a clear visual representation of each object's class and unique identifier.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
@@ -237,11 +221,7 @@ offering a clear visual representation of each object's class and unique identif
|
||||
|
||||
### Annotate Video with Traces
|
||||
|
||||
Adding traces to the video involves overlaying the historical paths of the detected
|
||||
objects. This feature, powered by the
|
||||
[`sv.TraceAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.TraceAnnotator),
|
||||
allows for visualizing the trajectories of objects, helping in understanding the
|
||||
movement patterns and interactions between objects in the video.
|
||||
Adding traces to the video involves overlaying the historical paths of the detected objects. This feature, powered by the [`sv.TraceAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.TraceAnnotator), allows for visualizing the trajectories of objects, helping in understanding the movement patterns and interactions between objects in the video.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
@@ -327,8 +307,7 @@ movement patterns and interactions between objects in the video.
|
||||
|
||||
Models aren't limited to object detection and segmentation. Keypoint detection allows for detailed analysis of body joints and connections, especially valuable for applications like human pose estimation. This section introduces keypoint tracking. We'll walk through the steps of annotating keypoints, converting them into bounding box detections compatible with `ByteTrack`, and applying detection smoothing for enhanced stability.
|
||||
|
||||
To make it easier for you to follow our tutorial, let's download the video we will use as an
|
||||
example. You can do this using [`supervision[assets]`](https://supervision.roboflow.com/latest/assets/) extension.
|
||||
To make it easier for you to follow our tutorial, let's download the video we will use as an example. You can do this using the [`supervision.assets`](https://supervision.roboflow.com/latest/assets/) module included in the base package.
|
||||
|
||||
```python
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
@@ -342,8 +321,7 @@ download_assets(VideoAssets.SKIING)
|
||||
|
||||
### Keypoint Detection
|
||||
|
||||
First, you'll need to obtain predictions from your keypoint detection model. In this tutorial, we are using the YOLOv8 model as an example. However,
|
||||
Supervision is versatile and compatible with various models. Check this [link](https://supervision.roboflow.com/latest/keypoint/core/) for guidance on how to plug in other models.
|
||||
First, you'll need to obtain predictions from your keypoint detection model. In this tutorial, we are using the YOLOv8 model as an example. However, Supervision is versatile and compatible with various models. Check this [link](https://supervision.roboflow.com/latest/keypoint/core/) for guidance on how to plug in other models.
|
||||
|
||||
We will define a `callback` function, which will process each frame of the video by obtaining model predictions and then annotating the frame based on these predictions.
|
||||
|
||||
@@ -656,3 +634,26 @@ We could stop here as we have successfully tracked the object detected by the ke
|
||||
</video>
|
||||
|
||||
This structured walkthrough should give a detailed pathway to annotate videos effectively using Supervision’s various functionalities, including object tracking and trace annotations.
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I track objects across video frames with supervision?
|
||||
|
||||
Pass `Detections` to `sv.ByteTrack.update_with_detections()` on each frame. The tracker assigns persistent IDs. Combine with `sv.TraceAnnotator` to visualize trajectories. `sv.ByteTrack` is deprecated in favor of `ByteTrackTracker` from the `trackers` package, where the update method is named `update()`.
|
||||
|
||||
### What should I know about ByteTrack?
|
||||
|
||||
ByteTrack uses low-confidence detections during association, which can improve continuity during missed or weak detections. Supervision's built-in `ByteTrack` wrapper is deprecated in favor of the external `trackers` package.
|
||||
|
||||
### Can I track instances instead of bounding boxes?
|
||||
|
||||
Yes. ByteTrack tracks bounding boxes. For instance masks, use `sv.MaskAnnotator` with the tracker IDs to color-code each tracked object consistently.
|
||||
|
||||
### Does ByteTrack work with any detection model?
|
||||
|
||||
Yes. ByteTrack is model-agnostic - it accepts any `Detections` object with bounding boxes, regardless of the supported converter or model output that produced it.
|
||||
|
||||
## Authors
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
- [Soumik Mandal](https://github.com/soumik12345) — ML Engineer, Roboflow
|
||||
|
||||
+7
-20
@@ -26,11 +26,11 @@ description: Open-source Python library providing computer vision tools for anno
|
||||
|
||||
## What is Supervision?
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for building computer vision applications. It provides a unified `Detections` object that works with YOLO, SAM, Grounding DINO, Transformers, and 20+ model frameworks — use any detector, get the same composable API.
|
||||
Supervision is an open-source Python library by Roboflow for building computer vision applications. It provides a unified `Detections` object with converters for supported outputs from Ultralytics, Roboflow Inference, Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers.
|
||||
|
||||
With Supervision you can annotate images and video with bounding boxes, masks, and labels; track objects across frames with persistent IDs; count and filter detections inside polygon zones; load and convert datasets between YOLO, COCO, and Pascal VOC formats; and benchmark model performance with mAP and confusion matrices.
|
||||
|
||||
Trusted by researchers (cited in 4,000+ papers) and practitioners (38,000+ GitHub stars, 1M+ monthly PyPI downloads), Supervision is the standard toolkit for production computer vision workflows.
|
||||
Supervision is MIT licensed, has 38,000+ GitHub stars, and over 1 million monthly PyPI downloads. It is developed in public on GitHub for production computer vision workflows.
|
||||
|
||||
## 👋 Hello
|
||||
|
||||
@@ -45,17 +45,13 @@ We write your reusable computer vision tools. Whether you need to load your data
|
||||
|
||||
## 💻 Install
|
||||
|
||||
You can install `supervision` in a
|
||||
[**Python>=3.9**](https://www.python.org/) environment.
|
||||
You can install `supervision` in a [**Python>=3.9**](https://www.python.org/) environment.
|
||||
|
||||
!!! example "Installation"
|
||||
|
||||
=== "pip (recommended)"
|
||||
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](../LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://badge.fury.io/py/supervision) [](https://pypistats.org/packages/supervision) [](../LICENSE.md) [](https://badge.fury.io/py/supervision)
|
||||
|
||||
```bash
|
||||
pip install supervision
|
||||
@@ -63,10 +59,7 @@ You can install `supervision` in a
|
||||
|
||||
=== "poetry"
|
||||
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](../LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://badge.fury.io/py/supervision) [](https://pypistats.org/packages/supervision) [](../LICENSE.md) [](https://badge.fury.io/py/supervision)
|
||||
|
||||
```bash
|
||||
poetry add supervision
|
||||
@@ -74,10 +67,7 @@ You can install `supervision` in a
|
||||
|
||||
=== "uv"
|
||||
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](../LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://badge.fury.io/py/supervision) [](https://pypistats.org/packages/supervision) [](../LICENSE.md) [](https://badge.fury.io/py/supervision)
|
||||
|
||||
```bash
|
||||
uv pip install supervision
|
||||
@@ -91,10 +81,7 @@ You can install `supervision` in a
|
||||
|
||||
=== "rye"
|
||||
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](../LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://badge.fury.io/py/supervision) [](https://pypistats.org/packages/supervision) [](../LICENSE.md) [](https://badge.fury.io/py/supervision)
|
||||
|
||||
```bash
|
||||
rye add supervision
|
||||
|
||||
@@ -77,6 +77,61 @@ comments: true
|
||||
|
||||
</div>
|
||||
|
||||
=== "VertexEllipseAreaAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
area_annotator = sv.VertexEllipseAreaAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
sigma=2.0,
|
||||
)
|
||||
annotated_frame = area_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points,
|
||||
)
|
||||
```
|
||||
|
||||
=== "VertexEllipseOutlineAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
outline_annotator = sv.VertexEllipseOutlineAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
sigma=2.0,
|
||||
thickness=2,
|
||||
)
|
||||
annotated_frame = outline_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points,
|
||||
)
|
||||
```
|
||||
|
||||
=== "VertexEllipseHaloAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
halo_annotator = sv.VertexEllipseHaloAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
sigma=2.0,
|
||||
)
|
||||
annotated_frame = halo_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points,
|
||||
)
|
||||
```
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.key_points.annotators.VertexAnnotator">VertexAnnotator</a></h2>
|
||||
</div>
|
||||
@@ -94,3 +149,21 @@ comments: true
|
||||
</div>
|
||||
|
||||
:::supervision.key_points.annotators.VertexLabelAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.key_points.annotators.VertexEllipseAreaAnnotator">VertexEllipseAreaAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.key_points.annotators.VertexEllipseAreaAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.key_points.annotators.VertexEllipseOutlineAnnotator">VertexEllipseOutlineAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.key_points.annotators.VertexEllipseOutlineAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.key_points.annotators.VertexEllipseHaloAnnotator">VertexEllipseHaloAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.key_points.annotators.VertexEllipseHaloAnnotator
|
||||
|
||||
@@ -0,0 +1,192 @@
|
||||
# supervision
|
||||
|
||||
> Large-context AI crawler summary for Supervision documentation.
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a model-agnostic `Detections` class and composable tools for object detection, instance segmentation, keypoint detection, annotation, tracking, zone counting, dataset conversion, and model evaluation.
|
||||
|
||||
Supervision is MIT licensed, published on PyPI, developed on GitHub, and used by researchers and practitioners in production computer vision systems. The library includes converters for supported outputs from Ultralytics, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers.
|
||||
|
||||
## Primary Links
|
||||
|
||||
- Latest stable docs: https://supervision.roboflow.com/latest/
|
||||
- Development docs: https://supervision.roboflow.com/develop/
|
||||
- Source code: https://github.com/roboflow/supervision
|
||||
- PyPI package: https://pypi.org/project/supervision/
|
||||
- Changelog: https://supervision.roboflow.com/latest/changelog/
|
||||
- Sitemap: https://supervision.roboflow.com/sitemap.xml
|
||||
- Standard LLM summary: https://supervision.roboflow.com/llms.txt
|
||||
- Full LLM summary: https://supervision.roboflow.com/llms.full.txt
|
||||
|
||||
## AI Access
|
||||
|
||||
The documentation is static HTML and is open for AI crawler consumption. `robots.txt` explicitly allows general crawlers plus GPTBot, ClaudeBot, PerplexityBot, Bytespider, CCBot, GoogleOther, and Applebot.
|
||||
|
||||
## Install
|
||||
|
||||
```bash
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
Optional extras:
|
||||
|
||||
```bash
|
||||
pip install "supervision[metrics]"
|
||||
```
|
||||
|
||||
Sample asset utilities are included in the base package under `supervision.assets`.
|
||||
|
||||
## Core Concepts
|
||||
|
||||
### `sv.Detections`
|
||||
|
||||
`sv.Detections` is the central data structure in Supervision. It stores bounding boxes, segmentation masks, confidence scores, class IDs, tracker IDs, and arbitrary per-detection metadata in a `data` dictionary. It supports NumPy-style indexing for filtering by confidence, class, area, and spatial constraints.
|
||||
|
||||
Most connectors, annotators, trackers, dataset tools, and metrics either accept or return `Detections`, which makes it possible to change the upstream model while keeping downstream processing code stable.
|
||||
|
||||
### Model Connectors
|
||||
|
||||
Supervision normalizes outputs from multiple computer vision frameworks into the same `Detections` API. Common constructors include:
|
||||
|
||||
- `sv.Detections.from_ultralytics(...)`
|
||||
- `sv.Detections.from_inference(...)`
|
||||
- `sv.Detections.from_transformers(...)`
|
||||
- `sv.Detections.from_vlm(...)`
|
||||
- `sv.Detections.from_sam(...)`
|
||||
- `sv.Detections.from_detectron2(...)`
|
||||
- `sv.Detections.from_mmdetection(...)`
|
||||
|
||||
### Annotation
|
||||
|
||||
Supervision includes annotators for drawing boxes, masks, labels, traces, zones, vertices, edges, and other overlays on images and video frames. Common annotators include:
|
||||
|
||||
- `sv.BoxAnnotator`
|
||||
- `sv.MaskAnnotator`
|
||||
- `sv.LabelAnnotator`
|
||||
- `sv.TraceAnnotator`
|
||||
- `sv.PolygonZoneAnnotator`
|
||||
- `sv.LineZoneAnnotator`
|
||||
|
||||
### Tracking
|
||||
|
||||
The built-in `sv.ByteTrack` wrapper assigns persistent IDs across video frames through `update_with_detections()`. The docs also note the migration path toward `ByteTrackTracker` from the external `trackers` package. Tracked detections can be passed to label, trace, zone, and line-counting annotators.
|
||||
|
||||
### Zones and Counting
|
||||
|
||||
`sv.PolygonZone` checks whether detections are inside an arbitrary polygon. `sv.LineZone` counts line crossings and requires `detections.tracker_id` so objects can be matched across frames. These tools are typically used with video callbacks and annotators to build traffic, occupancy, queue, and throughput analytics.
|
||||
|
||||
### Datasets
|
||||
|
||||
`sv.DetectionDataset` loads, merges, splits, and converts object detection datasets. Supported formats include YOLO, COCO JSON, and Pascal VOC. `sv.ClassificationDataset` supports folder-structured classification datasets.
|
||||
|
||||
### Metrics
|
||||
|
||||
Supervision includes detection metrics including mean average precision, mean average recall, precision, recall, F1 score, and confusion matrices. The current mAP workflow uses `supervision.metrics.mean_average_precision.MeanAveragePrecision` with `update(...)` and `compute()`.
|
||||
|
||||
## How-To Guides
|
||||
|
||||
- Detect and annotate: https://supervision.roboflow.com/latest/how_to/detect_and_annotate/
|
||||
- Track objects: https://supervision.roboflow.com/latest/how_to/track_objects/
|
||||
- Detect small objects: https://supervision.roboflow.com/latest/how_to/detect_small_objects/
|
||||
- Filter detections: https://supervision.roboflow.com/latest/how_to/filter_detections/
|
||||
- Save detections: https://supervision.roboflow.com/latest/how_to/save_detections/
|
||||
- Count in zone: https://supervision.roboflow.com/latest/how_to/count_in_zone/
|
||||
- Benchmark a model: https://supervision.roboflow.com/latest/how_to/benchmark_a_model/
|
||||
- Process datasets: https://supervision.roboflow.com/latest/how_to/process_datasets/
|
||||
|
||||
## Reference Documentation
|
||||
|
||||
- Detections: https://supervision.roboflow.com/latest/detection/core/
|
||||
- Detection annotators: https://supervision.roboflow.com/latest/detection/annotators/
|
||||
- Compact masks: https://supervision.roboflow.com/latest/detection/compact_mask/
|
||||
- Detection converters: https://supervision.roboflow.com/latest/detection/utils/converters/
|
||||
- IoU and NMS: https://supervision.roboflow.com/latest/detection/utils/iou_and_nms/
|
||||
- Boxes: https://supervision.roboflow.com/latest/detection/utils/boxes/
|
||||
- Masks: https://supervision.roboflow.com/latest/detection/utils/masks/
|
||||
- Polygons: https://supervision.roboflow.com/latest/detection/utils/polygons/
|
||||
- Vision-language model helpers: https://supervision.roboflow.com/latest/detection/utils/vlms/
|
||||
- Keypoint core: https://supervision.roboflow.com/latest/keypoint/core/
|
||||
- Keypoint annotators: https://supervision.roboflow.com/latest/keypoint/annotators/
|
||||
- Classification core: https://supervision.roboflow.com/latest/classification/core/
|
||||
- Trackers: https://supervision.roboflow.com/latest/trackers/
|
||||
- Dataset core: https://supervision.roboflow.com/latest/datasets/core/
|
||||
- Mean average precision: https://supervision.roboflow.com/latest/metrics/mean_average_precision/
|
||||
- Mean average recall: https://supervision.roboflow.com/latest/metrics/mean_average_recall/
|
||||
- Precision: https://supervision.roboflow.com/latest/metrics/precision/
|
||||
- Recall: https://supervision.roboflow.com/latest/metrics/recall/
|
||||
- F1 score: https://supervision.roboflow.com/latest/metrics/f1_score/
|
||||
- Common metric values: https://supervision.roboflow.com/latest/metrics/common_values/
|
||||
- Line zone: https://supervision.roboflow.com/latest/detection/tools/line_zone/
|
||||
- Polygon zone: https://supervision.roboflow.com/latest/detection/tools/polygon_zone/
|
||||
- Inference slicer: https://supervision.roboflow.com/latest/detection/tools/inference_slicer/
|
||||
- Detection smoother: https://supervision.roboflow.com/latest/detection/tools/smoother/
|
||||
- Detection export sinks: https://supervision.roboflow.com/latest/detection/tools/save_detections/
|
||||
- Video utilities: https://supervision.roboflow.com/latest/utils/video/
|
||||
- Image utilities: https://supervision.roboflow.com/latest/utils/image/
|
||||
- Iterable utilities: https://supervision.roboflow.com/latest/utils/iterables/
|
||||
- Notebook utilities: https://supervision.roboflow.com/latest/utils/notebook/
|
||||
- File utilities: https://supervision.roboflow.com/latest/utils/file/
|
||||
- Draw utilities: https://supervision.roboflow.com/latest/utils/draw/
|
||||
- Geometry utilities: https://supervision.roboflow.com/latest/utils/geometry/
|
||||
- Assets: https://supervision.roboflow.com/latest/assets/
|
||||
|
||||
## Cookbooks
|
||||
|
||||
- Supervision quickstart: https://supervision.roboflow.com/latest/notebooks/quickstart/
|
||||
- Count objects crossing the line: https://supervision.roboflow.com/latest/notebooks/count-objects-crossing-the-line/
|
||||
- Object tracking: https://supervision.roboflow.com/latest/notebooks/object-tracking/
|
||||
- Small object detection with SAHI: https://supervision.roboflow.com/latest/notebooks/small-object-detection-with-sahi/
|
||||
- Zero-shot object detection with YOLO-World: https://supervision.roboflow.com/latest/notebooks/zero-shot-object-detection-with-yolo-world/
|
||||
- Save detections to CSV: https://supervision.roboflow.com/latest/notebooks/serialise-detections-to-csv/
|
||||
- Save detections to JSON: https://supervision.roboflow.com/latest/notebooks/serialise-detections-to-json/
|
||||
- Occupancy analytics: https://supervision.roboflow.com/latest/notebooks/occupancy_analytics/
|
||||
- Annotate video with detections: https://supervision.roboflow.com/latest/notebooks/annotate-video-with-detections/
|
||||
|
||||
## Trust and Contact Pages
|
||||
|
||||
- About: https://supervision.roboflow.com/latest/about/
|
||||
- Contact: https://supervision.roboflow.com/latest/contact/
|
||||
- FAQ: https://supervision.roboflow.com/latest/faq/
|
||||
- License: https://github.com/roboflow/supervision/blob/develop/LICENSE.md
|
||||
- Issues: https://github.com/roboflow/supervision/issues
|
||||
- Community: https://discord.gg/GbfgXGJ8Bk
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### What is Supervision?
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified `Detections` class with converters for supported detection, segmentation, and VLM outputs.
|
||||
|
||||
### Is Supervision tied to one model provider?
|
||||
|
||||
No. Supervision is model agnostic. It is designed to normalize model outputs into a common API so downstream annotation, filtering, tracking, metrics, and dataset code can be reused.
|
||||
|
||||
### What dataset formats are supported?
|
||||
|
||||
For object detection datasets, Supervision supports YOLO, COCO JSON, and Pascal VOC import and export. For classification datasets, it supports folder-structure import and export.
|
||||
|
||||
### How do I detect small objects?
|
||||
|
||||
Use `sv.InferenceSlicer` to split large images into overlapping tiles, run inference on each tile, and merge the resulting detections with non-maximum suppression or non-maximum merge.
|
||||
|
||||
### How do I count objects crossing a line?
|
||||
|
||||
Run a tracker first to assign `detections.tracker_id`, then use `sv.LineZone.trigger(detections)` to calculate crossing events. Use `sv.LineZoneAnnotator` for visualization.
|
||||
|
||||
### How do I benchmark a model?
|
||||
|
||||
Load predictions and ground truth as `Detections`, update a `MeanAveragePrecision` metric object, and call `compute()`. Use `sv.ConfusionMatrix` when class-level confusion analysis is needed.
|
||||
|
||||
## Citation
|
||||
|
||||
```bibtex
|
||||
@software{supervision,
|
||||
author = {Roboflow},
|
||||
title = {Supervision: Computer Vision Toolkit},
|
||||
url = {https://github.com/roboflow/supervision},
|
||||
year = {2023}
|
||||
}
|
||||
```
|
||||
|
||||
## Versioning
|
||||
|
||||
`/develop/` is built from the `develop` branch. `/latest/` is built from the `release/latest` branch. Published releases build tag-only documentation paths and do not move `/latest/`.
|
||||
@@ -0,0 +1,188 @@
|
||||
# supervision
|
||||
|
||||
> Open-source Python library for computer vision — annotate, track, count, filter, and convert.
|
||||
|
||||
Supervision is a Python library by Roboflow that provides a model-agnostic `Detections` class and composable tools for object detection and segmentation workflows. It includes converters for supported outputs from Ultralytics, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers.
|
||||
|
||||
Supervision is MIT licensed, published on PyPI, and developed in public on GitHub.
|
||||
|
||||
## AI Access
|
||||
|
||||
The documentation is static HTML and open for AI consumption. `robots.txt` explicitly allows general crawlers plus selected AI crawlers.
|
||||
|
||||
- GPTBot: allowed
|
||||
- ClaudeBot: allowed
|
||||
- PerplexityBot: allowed
|
||||
- CCBot: allowed
|
||||
- GoogleOther: allowed
|
||||
|
||||
## Install
|
||||
|
||||
```bash
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
Extra: `pip install supervision[metrics]` for optional metric dependencies. Sample asset utilities are included in the base package under `supervision.assets`.
|
||||
|
||||
## Links
|
||||
|
||||
- GitHub: https://github.com/roboflow/supervision
|
||||
- PyPI: https://pypi.org/project/supervision
|
||||
- Docs (latest stable): https://supervision.roboflow.com/latest/
|
||||
- Docs (develop): https://supervision.roboflow.com/develop/
|
||||
- Changelog: https://supervision.roboflow.com/latest/changelog/
|
||||
- Sitemap: https://supervision.roboflow.com/sitemap.xml
|
||||
|
||||
## Key APIs
|
||||
|
||||
### sv.Detections
|
||||
|
||||
Core data structure for bounding boxes, masks, confidence scores, class IDs, tracker IDs, and arbitrary per-detection metadata stored in a `data` dict. The lingua franca of the entire library — every connector, annotator, and tracker accepts or returns `Detections`. Supports NumPy-style boolean indexing for filtering by class, confidence, area, and spatial regions.
|
||||
|
||||
### sv.BoxAnnotator, sv.MaskAnnotator, sv.LabelAnnotator
|
||||
|
||||
Draw bounding boxes, segmentation masks, and text labels on images. Annotators expose `annotate(scene=..., detections=...)`; pass an input image and a `Detections` object to get the annotated output. `LabelAnnotator` can use explicit `labels` or fall back to `detections["class_name"]`, class IDs, then detection indices. Colors can be assigned by class or manually specified.
|
||||
|
||||
### sv.ByteTrack
|
||||
|
||||
Object tracker wrapper that assigns persistent IDs across video frames. The built-in `sv.ByteTrack` accepts `Detections` via `update_with_detections()`, but it is deprecated in favor of `ByteTrackTracker` from the external `trackers` package, where the method is named `update()`. Use tracked `Detections` with `sv.TraceAnnotator` to visualize trajectories.
|
||||
|
||||
### sv.PolygonZone and sv.LineZone
|
||||
|
||||
Zone-based counting. `PolygonZone.trigger(detections)` returns a boolean mask for detections currently inside an arbitrary polygon. `LineZone.trigger(detections)` returns `(crossed_in, crossed_out)` arrays for line crossings and requires `detections.tracker_id` so objects can be matched across frames. Both are commonly paired with zone annotators for visualization.
|
||||
|
||||
### sv.DetectionDataset and sv.ClassificationDataset
|
||||
|
||||
For detection datasets, load, merge, split, and convert between YOLO, COCO JSON, and Pascal VOC formats. Classification datasets use folder-structure import and export via `ClassificationDataset.from_folder_structure()` and `as_folder_structure()`.
|
||||
|
||||
### sv.InferenceSlicer
|
||||
|
||||
SAHI-style inference slicing: split high-resolution images into overlapping tiles, run detection on each tile, merge results with non-maximum suppression or non-maximum merge. Configure tile overlap in pixels with `overlap_wh`.
|
||||
|
||||
### supervision.metrics.MeanAveragePrecision and sv.ConfusionMatrix
|
||||
|
||||
Benchmarking tools. For mAP@0.5:0.95, use `supervision.metrics.MeanAveragePrecision` with `update()` and `compute()` rather than the deprecated top-level `sv.MeanAveragePrecision.from_detections()`. `ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes)` generates a confusion matrix for detection results.
|
||||
|
||||
### sv.CSVSink and sv.JSONSink
|
||||
|
||||
Export detection results to structured files. Use `CSVSink` and `JSONSink` as context managers, call `sink.append(detections, custom_data=...)`, and they write one row/object per detection with box coordinates, confidence, class ID, tracker ID, and data fields.
|
||||
|
||||
## How-To Guides
|
||||
|
||||
- Detect and annotate: https://supervision.roboflow.com/latest/how_to/detect_and_annotate/
|
||||
- Track objects: https://supervision.roboflow.com/latest/how_to/track_objects/
|
||||
- Detect small objects: https://supervision.roboflow.com/latest/how_to/detect_small_objects/
|
||||
- Filter detections: https://supervision.roboflow.com/latest/how_to/filter_detections/
|
||||
- Save detections: https://supervision.roboflow.com/latest/how_to/save_detections/
|
||||
- Count in zone: https://supervision.roboflow.com/latest/how_to/count_in_zone/
|
||||
- Benchmark a model: https://supervision.roboflow.com/latest/how_to/benchmark_a_model/
|
||||
- Process datasets: https://supervision.roboflow.com/latest/how_to/process_datasets/
|
||||
|
||||
## Reference Documentation
|
||||
|
||||
- Detections (detection/core): https://supervision.roboflow.com/latest/detection/core/
|
||||
- Annotators (detection/annotators): https://supervision.roboflow.com/latest/detection/annotators/
|
||||
- CompactMask (detection/compact_mask): https://supervision.roboflow.com/latest/detection/compact_mask/
|
||||
- Format Converters (detection/utils/converters): https://supervision.roboflow.com/latest/detection/utils/converters/
|
||||
- IoU and NMS (detection/utils/iou_and_nms): https://supervision.roboflow.com/latest/detection/utils/iou_and_nms/
|
||||
- Boxes (detection/utils/boxes): https://supervision.roboflow.com/latest/detection/utils/boxes/
|
||||
- Masks (detection/utils/masks): https://supervision.roboflow.com/latest/detection/utils/masks/
|
||||
- Polygons (detection/utils/polygons): https://supervision.roboflow.com/latest/detection/utils/polygons/
|
||||
- VLMs (detection/utils/vlms): https://supervision.roboflow.com/latest/detection/utils/vlms/
|
||||
- Keypoint Core (keypoint/core): https://supervision.roboflow.com/latest/keypoint/core/
|
||||
- Keypoint Annotators (keypoint/annotators): https://supervision.roboflow.com/latest/keypoint/annotators/
|
||||
- Classification Core (classification/core): https://supervision.roboflow.com/latest/classification/core/
|
||||
- ByteTrack Tracker (trackers): https://supervision.roboflow.com/latest/trackers/
|
||||
- Datasets Core (datasets/core): https://supervision.roboflow.com/latest/datasets/core/
|
||||
- mAP (metrics/mean_average_precision): https://supervision.roboflow.com/latest/metrics/mean_average_precision/
|
||||
- mAR (metrics/mean_average_recall): https://supervision.roboflow.com/latest/metrics/mean_average_recall/
|
||||
- Precision (metrics/precision): https://supervision.roboflow.com/latest/metrics/precision/
|
||||
- Recall (metrics/recall): https://supervision.roboflow.com/latest/metrics/recall/
|
||||
- F1 Score (metrics/f1_score): https://supervision.roboflow.com/latest/metrics/f1_score/
|
||||
- Common Values (metrics/common_values): https://supervision.roboflow.com/latest/metrics/common_values/
|
||||
- Line Zone (detection/tools/line_zone): https://supervision.roboflow.com/latest/detection/tools/line_zone/
|
||||
- Polygon Zone (detection/tools/polygon_zone): https://supervision.roboflow.com/latest/detection/tools/polygon_zone/
|
||||
- Inference Slicer (detection/tools/inference_slicer): https://supervision.roboflow.com/latest/detection/tools/inference_slicer/
|
||||
- Detection Smoother (detection/tools/smoother): https://supervision.roboflow.com/latest/detection/tools/smoother/
|
||||
- Save Detections Tool (detection/tools/save_detections): https://supervision.roboflow.com/latest/detection/tools/save_detections/
|
||||
- Video Utils (utils/video): https://supervision.roboflow.com/latest/utils/video/
|
||||
- Image Utils (utils/image): https://supervision.roboflow.com/latest/utils/image/
|
||||
- Iterable Utils (utils/iterables): https://supervision.roboflow.com/latest/utils/iterables/
|
||||
- Notebook Utils (utils/notebook): https://supervision.roboflow.com/latest/utils/notebook/
|
||||
- File Utils (utils/file): https://supervision.roboflow.com/latest/utils/file/
|
||||
- Draw Utils (utils/draw): https://supervision.roboflow.com/latest/utils/draw/
|
||||
- Geometry (utils/geometry): https://supervision.roboflow.com/latest/utils/geometry/
|
||||
- Assets (assets): https://supervision.roboflow.com/latest/assets/
|
||||
|
||||
## Cookbooks
|
||||
|
||||
- Object tracking: https://supervision.roboflow.com/latest/cookbooks/#object-tracking
|
||||
- Count objects crossing line: https://supervision.roboflow.com/latest/cookbooks/#count-objects-crossing-the-line
|
||||
- Zero-shot object detection with YOLO-World: https://supervision.roboflow.com/latest/cookbooks/#zero-shot-object-detection-with-yolo-world
|
||||
- SAHI small object detection: https://supervision.roboflow.com/latest/cookbooks/#small-object-detection-with-sahi
|
||||
|
||||
## FAQ
|
||||
|
||||
### What is supervision?
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified `Detections` class with converters for supported detection, segmentation, and VLM outputs, plus tools for annotation, tracking, zone counting, dataset management, and model benchmarking.
|
||||
|
||||
### How do I install supervision?
|
||||
|
||||
Install with `pip install supervision`. For optional metric dependencies use `pip install supervision[metrics]`. Sample asset utilities are included in the base package under `supervision.assets`. The current package metadata requires Python 3.9+.
|
||||
|
||||
### What can I do with supervision?
|
||||
|
||||
Annotate images and video with bounding boxes, masks, and labels; track objects across frames with persistent IDs; count detections inside polygon zones or line crossings; filter and query detection results; load, split, and convert detection datasets between YOLO, COCO, and Pascal VOC formats; manage classification datasets with folder structures; and benchmark model performance with mAP and confusion matrices.
|
||||
|
||||
### Is supervision free to use?
|
||||
|
||||
Yes. Supervision is free and open-source under the MIT license. Source code is at https://github.com/roboflow/supervision.
|
||||
|
||||
### Which object detection models work with supervision?
|
||||
|
||||
Supervision is model-agnostic and works with supported outputs from Ultralytics YOLO, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers such as Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. Keypoint outputs have separate converters, including MediaPipe.
|
||||
|
||||
### How do I benchmark a model with supervision?
|
||||
|
||||
Use `supervision.metrics.mean_average_precision.MeanAveragePrecision` for mAP — accumulate predictions and ground truth with `update(...)` then call `compute()`. For confusion matrices, use `sv.ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes)`. See the Benchmark a Model how-to guide for a complete walkthrough.
|
||||
|
||||
### How do I track objects across video frames?
|
||||
|
||||
Use a tracker to assign persistent IDs. The built-in `sv.ByteTrack` wrapper accepts `Detections` with `update_with_detections()`, but it is deprecated in favor of `ByteTrackTracker` from the external `trackers` package. Combine tracked detections with `sv.TraceAnnotator` to visualize trajectories.
|
||||
|
||||
### What dataset formats does supervision support?
|
||||
|
||||
For detection datasets, supervision supports YOLO, COCO JSON, and Pascal VOC. Use `DetectionDataset.from_yolo()`, `from_coco()`, or `from_pascal_voc()` to load, and `as_yolo()`, `as_coco()`, or `as_pascal_voc()` to save. For classification datasets, use `ClassificationDataset.from_folder_structure()` and `as_folder_structure()`.
|
||||
|
||||
### How do I count objects in a zone?
|
||||
|
||||
Use `sv.PolygonZone` for arbitrary polygon zones. Use `sv.LineZone` for line-crossing counts after assigning tracker IDs, because `LineZone` needs `detections.tracker_id` to match objects across frames.
|
||||
|
||||
### How do I detect small objects with supervision?
|
||||
|
||||
Use `sv.InferenceSlicer` to split high-resolution images into overlapping tiles, run detection on each tile, and merge results with non-maximum suppression. Configure tile overlap in pixels with `overlap_wh`. See the Detect Small Objects how-to guide.
|
||||
|
||||
## Benchmarking
|
||||
|
||||
Supervision includes `supervision.metrics.MeanAveragePrecision` and `sv.ConfusionMatrix` for benchmarking object detection models. A curated [Model Leaderboard](https://leaderboard.roboflow.com/) compares YOLOv8, YOLOv11, and other models on standard datasets. The leaderboard repository is open source at https://github.com/roboflow/model-leaderboard.
|
||||
|
||||
## License
|
||||
|
||||
MIT — https://github.com/roboflow/supervision/blob/develop/LICENSE.md
|
||||
|
||||
## Citation
|
||||
|
||||
```bibtex
|
||||
@software{supervision,
|
||||
author = {Roboflow},
|
||||
title = {Supervision: Computer Vision Toolkit},
|
||||
url = {https://github.com/roboflow/supervision},
|
||||
year = {2023}
|
||||
}
|
||||
```
|
||||
|
||||
## Versioning
|
||||
|
||||
Stable release docs: https://supervision.roboflow.com/latest/
|
||||
Development branch: https://supervision.roboflow.com/develop/
|
||||
+129
-9
@@ -2,7 +2,19 @@
|
||||
|
||||
> Open-source Python library for computer vision — annotate, track, count, filter, and convert.
|
||||
|
||||
Supervision is a Python library by Roboflow that provides a model-agnostic `Detections` class and composable tools for object detection and segmentation workflows. Works with YOLO, SAM, Grounding DINO, Transformers, Inference, and 20+ other model frameworks.
|
||||
Supervision is a Python library by Roboflow that provides a model-agnostic `Detections` class and composable tools for object detection and segmentation workflows. It includes converters for supported outputs from Ultralytics, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers.
|
||||
|
||||
Supervision is MIT licensed, published on PyPI, and developed in public on GitHub.
|
||||
|
||||
## AI Access
|
||||
|
||||
The documentation is static HTML and open for AI consumption. `robots.txt` explicitly allows general crawlers plus selected AI crawlers.
|
||||
|
||||
- GPTBot: allowed
|
||||
- ClaudeBot: allowed
|
||||
- PerplexityBot: allowed
|
||||
- CCBot: allowed
|
||||
- GoogleOther: allowed
|
||||
|
||||
## Install
|
||||
|
||||
@@ -10,22 +22,41 @@ Supervision is a Python library by Roboflow that provides a model-agnostic `Dete
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
Extra: `pip install supervision[metrics]` for optional metric dependencies. Sample asset utilities are included in the base package under `supervision.assets`.
|
||||
|
||||
## Links
|
||||
|
||||
- GitHub: https://github.com/roboflow/supervision
|
||||
- PyPI: https://pypi.org/project/supervision
|
||||
- Docs: https://supervision.roboflow.com/latest/
|
||||
- Docs (latest stable): https://supervision.roboflow.com/latest/
|
||||
- Changelog: https://supervision.roboflow.com/latest/changelog/
|
||||
- Sitemap: https://supervision.roboflow.com/sitemap.xml
|
||||
|
||||
## Key APIs
|
||||
|
||||
- `sv.Detections` — core data structure for bounding boxes, masks, confidence scores, class IDs, and tracker IDs
|
||||
- `sv.BoxAnnotator`, `sv.MaskAnnotator`, `sv.LabelAnnotator` — draw predictions on images and video
|
||||
- `sv.ByteTrack`, `sv.SORT` — track objects across video frames with persistent IDs
|
||||
- `sv.PolygonZone`, `sv.LineZone` — count and filter detections by spatial region
|
||||
- `sv.DetectionDataset` — load, merge, split, and convert YOLO / COCO / Pascal VOC datasets
|
||||
- `sv.InferenceSlicer` — SAHI-style sliced inference for small object detection
|
||||
- `sv.CSVSink`, `sv.JSONSink` — export detection results to CSV or JSON
|
||||
### sv.Detections
|
||||
Core data structure for bounding boxes, masks, confidence scores, class IDs, tracker IDs, and arbitrary per-detection metadata stored in a `data` dict. The lingua franca of the entire library — every connector, annotator, and tracker accepts or returns `Detections`. Supports NumPy-style boolean indexing for filtering by class, confidence, area, and spatial regions.
|
||||
|
||||
### sv.BoxAnnotator, sv.MaskAnnotator, sv.LabelAnnotator
|
||||
Draw bounding boxes, segmentation masks, and text labels on images. Annotators expose `annotate(scene=..., detections=...)`; pass an input image and a `Detections` object to get the annotated output. `LabelAnnotator` can use explicit `labels` or fall back to `detections["class_name"]`, class IDs, then detection indices. Colors can be assigned by class or manually specified.
|
||||
|
||||
### sv.ByteTrack
|
||||
Object tracker wrapper that assigns persistent IDs across video frames. The built-in `sv.ByteTrack` accepts `Detections` via `update_with_detections()`, but it is deprecated in favor of `ByteTrackTracker` from the external `trackers` package, where the method is named `update()`. Use tracked `Detections` with `sv.TraceAnnotator` to visualize trajectories.
|
||||
|
||||
### sv.PolygonZone and sv.LineZone
|
||||
Zone-based counting. `PolygonZone.trigger(detections)` returns a boolean mask for detections currently inside an arbitrary polygon. `LineZone.trigger(detections)` returns `(crossed_in, crossed_out)` arrays for line crossings and requires `detections.tracker_id` so objects can be matched across frames. Both are commonly paired with zone annotators for visualization.
|
||||
|
||||
### sv.DetectionDataset and sv.ClassificationDataset
|
||||
For detection datasets, load, merge, split, and convert between YOLO, COCO JSON, and Pascal VOC formats. Classification datasets use folder-structure import and export via `ClassificationDataset.from_folder_structure()` and `as_folder_structure()`.
|
||||
|
||||
### sv.InferenceSlicer
|
||||
SAHI-style inference slicing: split high-resolution images into overlapping tiles, run detection on each tile, merge results with non-maximum suppression or non-maximum merge. Configure tile overlap in pixels with `overlap_wh`.
|
||||
|
||||
### supervision.metrics.MeanAveragePrecision and sv.ConfusionMatrix
|
||||
Benchmarking tools. For mAP@0.5:0.95, use `supervision.metrics.MeanAveragePrecision` with `update()` and `compute()` rather than the deprecated top-level `sv.MeanAveragePrecision.from_detections()`. `ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes)` generates a confusion matrix for detection results.
|
||||
|
||||
### sv.CSVSink and sv.JSONSink
|
||||
Export detection results to structured files. Use `CSVSink` and `JSONSink` as context managers, call `sink.append(detections, custom_data=...)`, and they write one row/object per detection with box coordinates, confidence, class ID, tracker ID, and data fields.
|
||||
|
||||
## How-To Guides
|
||||
|
||||
@@ -38,6 +69,95 @@ pip install supervision
|
||||
- Benchmark a model: https://supervision.roboflow.com/latest/how_to/benchmark_a_model/
|
||||
- Process datasets: https://supervision.roboflow.com/latest/how_to/process_datasets/
|
||||
|
||||
## Reference Documentation
|
||||
|
||||
- Detections (detection/core): https://supervision.roboflow.com/latest/detection/core/
|
||||
- Annotators (detection/annotators): https://supervision.roboflow.com/latest/detection/annotators/
|
||||
- CompactMask (detection/compact_mask): https://supervision.roboflow.com/latest/detection/compact_mask/
|
||||
- Format Converters (detection/utils/converters): https://supervision.roboflow.com/latest/detection/utils/converters/
|
||||
- IoU and NMS (detection/utils/iou_and_nms): https://supervision.roboflow.com/latest/detection/utils/iou_and_nms/
|
||||
- Boxes (detection/utils/boxes): https://supervision.roboflow.com/latest/detection/utils/boxes/
|
||||
- Masks (detection/utils/masks): https://supervision.roboflow.com/latest/detection/utils/masks/
|
||||
- Polygons (detection/utils/polygons): https://supervision.roboflow.com/latest/detection/utils/polygons/
|
||||
- VLMs (detection/utils/vlms): https://supervision.roboflow.com/latest/detection/utils/vlms/
|
||||
- Keypoint Core (keypoint/core): https://supervision.roboflow.com/latest/keypoint/core/
|
||||
- Keypoint Annotators (keypoint/annotators): https://supervision.roboflow.com/latest/keypoint/annotators/
|
||||
- Classification Core (classification/core): https://supervision.roboflow.com/latest/classification/core/
|
||||
- ByteTrack Tracker (trackers): https://supervision.roboflow.com/latest/trackers/
|
||||
- Datasets Core (datasets/core): https://supervision.roboflow.com/latest/datasets/core/
|
||||
- mAP (metrics/mean_average_precision): https://supervision.roboflow.com/latest/metrics/mean_average_precision/
|
||||
- mAR (metrics/mean_average_recall): https://supervision.roboflow.com/latest/metrics/mean_average_recall/
|
||||
- Precision (metrics/precision): https://supervision.roboflow.com/latest/metrics/precision/
|
||||
- Recall (metrics/recall): https://supervision.roboflow.com/latest/metrics/recall/
|
||||
- F1 Score (metrics/f1_score): https://supervision.roboflow.com/latest/metrics/f1_score/
|
||||
- Common Values (metrics/common_values): https://supervision.roboflow.com/latest/metrics/common_values/
|
||||
- Line Zone (detection/tools/line_zone): https://supervision.roboflow.com/latest/detection/tools/line_zone/
|
||||
- Polygon Zone (detection/tools/polygon_zone): https://supervision.roboflow.com/latest/detection/tools/polygon_zone/
|
||||
- Inference Slicer (detection/tools/inference_slicer): https://supervision.roboflow.com/latest/detection/tools/inference_slicer/
|
||||
- Detection Smoother (detection/tools/smoother): https://supervision.roboflow.com/latest/detection/tools/smoother/
|
||||
- Save Detections Tool (detection/tools/save_detections): https://supervision.roboflow.com/latest/detection/tools/save_detections/
|
||||
- Video Utils (utils/video): https://supervision.roboflow.com/latest/utils/video/
|
||||
- Image Utils (utils/image): https://supervision.roboflow.com/latest/utils/image/
|
||||
- Iterable Utils (utils/iterables): https://supervision.roboflow.com/latest/utils/iterables/
|
||||
- Notebook Utils (utils/notebook): https://supervision.roboflow.com/latest/utils/notebook/
|
||||
- File Utils (utils/file): https://supervision.roboflow.com/latest/utils/file/
|
||||
- Draw Utils (utils/draw): https://supervision.roboflow.com/latest/utils/draw/
|
||||
- Geometry (utils/geometry): https://supervision.roboflow.com/latest/utils/geometry/
|
||||
- Assets (assets): https://supervision.roboflow.com/latest/assets/
|
||||
|
||||
## Cookbooks
|
||||
|
||||
- Object tracking: https://supervision.roboflow.com/latest/cookbooks/#object-tracking
|
||||
- Count objects crossing line: https://supervision.roboflow.com/latest/cookbooks/#count-objects-crossing-the-line
|
||||
- Zero-shot object detection with YOLO-World: https://supervision.roboflow.com/latest/cookbooks/#zero-shot-object-detection-with-yolo-world
|
||||
- SAHI small object detection: https://supervision.roboflow.com/latest/cookbooks/#small-object-detection-with-sahi
|
||||
|
||||
## FAQ
|
||||
|
||||
### What is supervision?
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified `Detections` class with converters for supported detection, segmentation, and VLM outputs, plus tools for annotation, tracking, zone counting, dataset management, and model benchmarking.
|
||||
|
||||
### How do I install supervision?
|
||||
|
||||
Install with `pip install supervision`. For optional metric dependencies use `pip install supervision[metrics]`. Sample asset utilities are included in the base package under `supervision.assets`. The current package metadata requires Python 3.9+.
|
||||
|
||||
### What can I do with supervision?
|
||||
|
||||
Annotate images and video with bounding boxes, masks, and labels; track objects across frames with persistent IDs; count detections inside polygon zones or line crossings; filter and query detection results; load, split, and convert detection datasets between YOLO, COCO, and Pascal VOC formats; manage classification datasets with folder structures; and benchmark model performance with mAP and confusion matrices.
|
||||
|
||||
### Is supervision free to use?
|
||||
|
||||
Yes. Supervision is free and open-source under the MIT license. Source code is at https://github.com/roboflow/supervision.
|
||||
|
||||
### Which object detection models work with supervision?
|
||||
|
||||
Supervision is model-agnostic and works with supported outputs from Ultralytics YOLO, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers such as Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. Keypoint outputs have separate converters, including MediaPipe.
|
||||
|
||||
### How do I benchmark a model with supervision?
|
||||
|
||||
Use `supervision.metrics.mean_average_precision.MeanAveragePrecision` for mAP — accumulate predictions and ground truth with `update(...)` then call `compute()`. For confusion matrices, use `sv.ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes)`. See the Benchmark a Model how-to guide for a complete walkthrough.
|
||||
|
||||
### How do I track objects across video frames?
|
||||
|
||||
Use a tracker to assign persistent IDs. The built-in `sv.ByteTrack` wrapper accepts `Detections` with `update_with_detections()`, but it is deprecated in favor of `ByteTrackTracker` from the external `trackers` package. Combine tracked detections with `sv.TraceAnnotator` to visualize trajectories.
|
||||
|
||||
### What dataset formats does supervision support?
|
||||
|
||||
For detection datasets, supervision supports YOLO, COCO JSON, and Pascal VOC. Use `DetectionDataset.from_yolo()`, `from_coco()`, or `from_pascal_voc()` to load, and `as_yolo()`, `as_coco()`, or `as_pascal_voc()` to save. For classification datasets, use `ClassificationDataset.from_folder_structure()` and `as_folder_structure()`.
|
||||
|
||||
### How do I count objects in a zone?
|
||||
|
||||
Use `sv.PolygonZone` for arbitrary polygon zones. Use `sv.LineZone` for line-crossing counts after assigning tracker IDs, because `LineZone` needs `detections.tracker_id` to match objects across frames.
|
||||
|
||||
### How do I detect small objects with supervision?
|
||||
|
||||
Use `sv.InferenceSlicer` to split high-resolution images into overlapping tiles, run detection on each tile, and merge results with non-maximum suppression. Configure tile overlap in pixels with `overlap_wh`. See the Detect Small Objects how-to guide.
|
||||
|
||||
## Benchmarking
|
||||
|
||||
Supervision includes `supervision.metrics.MeanAveragePrecision` and `sv.ConfusionMatrix` for benchmarking object detection models. A curated [Model Leaderboard](https://leaderboard.roboflow.com/) compares YOLOv8, YOLOv11, and other models on standard datasets. The leaderboard repository is open source at https://github.com/roboflow/model-leaderboard.
|
||||
|
||||
## License
|
||||
|
||||
MIT — https://github.com/roboflow/supervision/blob/develop/LICENSE.md
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
description: API reference for MeanAveragePrecision — compute mAP for object detection benchmarking with bounding boxes.
|
||||
---
|
||||
|
||||
# Mean Average Precision
|
||||
|
||||
+715
File diff suppressed because one or more lines are too long
+311
File diff suppressed because one or more lines are too long
@@ -6,7 +6,7 @@
|
||||
"id": "kR-PyK7YXPVZ"
|
||||
},
|
||||
"source": [
|
||||
"# Underestand Visitors with YOLO-World\n",
|
||||
"# Understand Visitors with YOLO-World\n",
|
||||
"---\n",
|
||||
"[](https://colab.research.google.com/github/roboflow/supervision/blob/develop/docs/notebooks/zero-shot-object-detection-with-yolo-world.ipynb)\n",
|
||||
"[](https://blog.roboflow.com/what-is-yolo-world/)\n",
|
||||
|
||||
+3
-12
@@ -1,17 +1,5 @@
|
||||
User-agent: *
|
||||
Allow: /
|
||||
# Block all numeric versioned paths (/0.28.0/, /1.0.0/, etc.) — canonical URL is /latest/
|
||||
# robots.txt has no character classes, so one Disallow per leading digit is required.
|
||||
Disallow: /0.*/
|
||||
Disallow: /1.*/
|
||||
Disallow: /2.*/
|
||||
Disallow: /3.*/
|
||||
Disallow: /4.*/
|
||||
Disallow: /5.*/
|
||||
Disallow: /6.*/
|
||||
Disallow: /7.*/
|
||||
Disallow: /8.*/
|
||||
Disallow: /9.*/
|
||||
|
||||
User-agent: GPTBot
|
||||
Allow: /
|
||||
@@ -31,4 +19,7 @@ Allow: /
|
||||
User-agent: GoogleOther
|
||||
Allow: /
|
||||
|
||||
User-agent: Applebot
|
||||
Allow: /
|
||||
|
||||
Sitemap: https://supervision.roboflow.com/sitemap.xml
|
||||
|
||||
Vendored
+21
-13
@@ -11,53 +11,61 @@
|
||||
<h1>Supervision Cookbooks</h1>
|
||||
</div>
|
||||
<div class="custom-grid">
|
||||
<a href="/develop/notebooks/quickstart"> <p class="card repo-card" data-name="Supervision Quickstart" data-labels="ANNOTATOR,DETECTION,SAM"
|
||||
<a href="../notebooks/quickstart/"> <p class="card repo-card" data-name="Supervision Quickstart" data-labels="ANNOTATOR,DETECTION,SAM"
|
||||
data-version="v0.26.0" data-author="SkalskiP,onuralpszr"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/count-objects-crossing-the-line">
|
||||
<a href="../notebooks/count-objects-crossing-the-line/">
|
||||
<p class="card repo-card" data-name="Count Objects Crossing the Line"
|
||||
data-labels="ANNOTATORS,LINE ZONE,TRACKING" data-version="v0.26.0" data-author="SkalskiP"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/zero-shot-object-detection-with-yolo-world">
|
||||
<a href="../notebooks/zero-shot-object-detection-with-yolo-world/">
|
||||
<p class="card repo-card" data-name="Zero-Shot Object Detection with YOLO-World"
|
||||
data-labels="ANNOTATORS,DETECTION,INFERENCE" data-version="v0.26.0" data-author="SkalskiP"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/download-supervision-assets">
|
||||
<a href="../notebooks/download-supervision-assets/">
|
||||
<p class="card repo-card" data-name="Downloading Supervision Assets" data-labels="ASSETS" data-version="v0.18.0"
|
||||
data-author="nickherrig"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/annotate-video-with-detections">
|
||||
<a href="../notebooks/annotate-video-with-detections/">
|
||||
<p class="card repo-card" data-name="Annotate Video with Detections" data-labels="INFERENCE,YOLOV8"
|
||||
data-version="v0.26.0" data-author="nickherrig"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/object-tracking">
|
||||
<a href="../notebooks/object-tracking/">
|
||||
<p class="card repo-card" data-name="Object Tracking" data-labels="TRACKING, ANNOTATOR" data-version="v0.18.0"
|
||||
data-author="nickherrig"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/occupancy_analytics">
|
||||
<a href="../notebooks/occupancy_analytics/">
|
||||
<p class="card repo-card" data-name="Analyzing Zone Occupancy" data-labels="ANNOTATOR,DETECTION,ZONES"
|
||||
data-version="v0.26.0" data-author="stellasphere"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/evaluating-alignment-of-text-to-image-diffusion-models">
|
||||
<a href="../notebooks/evaluating-alignment-of-text-to-image-diffusion-models/">
|
||||
<p class="card repo-card" data-name="Evaluating Alignment of Text-to-image Diffusion Models"
|
||||
data-labels="ANNOTATORS,YOLO WORLD" data-version="v0.26.0" data-author="iamhatesz"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/serialise-detections-to-csv">
|
||||
<a href="../notebooks/serialise-detections-to-csv/">
|
||||
<p class="card repo-card" data-name="Serialise Detections to a CSV File"
|
||||
data-labels="DETECTIONS,CSV SINK,INFERENCE" data-version="v0.26.0" data-author="onuralpszr"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/serialise-detections-to-json">
|
||||
<a href="../notebooks/serialise-detections-to-json/">
|
||||
<p class="card repo-card" data-name="Serialise Detections to a JSON File"
|
||||
data-labels="DETECTIONS,JSON SINK,INFERENCE" data-version="v0.26.0" data-author="onuralpszr"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/small-object-detection-with-sahi">
|
||||
<a href="../notebooks/small-object-detection-with-sahi/">
|
||||
<p class="card repo-card" data-name="Small Object Detection with SAHI"
|
||||
data-labels="DETECTIONS,SAHI,SMALL,OBJECT,INFERENCE" data-version="v0.26.0" data-author="ediardo"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/underestand-visitors-with-yolo-world">
|
||||
<p class="card repo-card" data-name="Underestand visitors with YOLO-World"
|
||||
<a href="../notebooks/underestand-visitors-with-yolo-world/">
|
||||
<p class="card repo-card" data-name="Understand Visitors with YOLO-World"
|
||||
data-labels="ANNOTATORS,DETECTION,INFERENCE" data-version="v0.19.0" data-author="AdonaiVera"></p>
|
||||
</a>
|
||||
<a href="../notebooks/compact-mask-sam3/">
|
||||
<p class="card repo-card" data-name="Memory-Efficient Instance Segmentation"
|
||||
data-labels="COMPACT MASK,SAM3,SEGMENTATION" data-version="v0.28.0" data-author="Borda"></p>
|
||||
</a>
|
||||
<a href="../notebooks/oriented-bounding-boxes/">
|
||||
<p class="card repo-card" data-name="Oriented Bounding Boxes for Densely Packed Objects"
|
||||
data-labels="OBB,DETECTIONS,NMS,DATASET" data-version="v0.29.0" data-author="kounelisagis"></p>
|
||||
</a>
|
||||
</div>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
Vendored
+344
-24
@@ -13,29 +13,38 @@
|
||||
|
||||
{% block extrahead %}
|
||||
{{ super() }}
|
||||
|
||||
{% if page.meta is defined and page.meta is not none and page.meta is not undefined %}
|
||||
{% set _meta = page.meta %}
|
||||
{% else %}
|
||||
{% set _meta = {} %}
|
||||
{% endif %}
|
||||
{% set page_description = _meta.description | d(config.site_description) %}
|
||||
{# ── GEO: JSON-LD + OG tags (page context required — skip for theme templates like 404) #}
|
||||
{% if page %}
|
||||
|
||||
{# ── GEO: JSON-LD structured data ───────────────────────────────────────── #}
|
||||
{# ── GEO: JSON-LD structured data ──────────────────────────── #}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "Organization",
|
||||
"name": "Roboflow",
|
||||
"url": "https://roboflow.com",
|
||||
"logo": "https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png",
|
||||
"logo": {
|
||||
"@type": "ImageObject",
|
||||
"url": "https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png",
|
||||
"width": 1200,
|
||||
"height": 630
|
||||
},
|
||||
"sameAs": [
|
||||
"https://github.com/roboflow/supervision",
|
||||
"https://pypi.org/project/supervision",
|
||||
"https://twitter.com/roboflow",
|
||||
"https://www.youtube.com/roboflow",
|
||||
"https://en.wikipedia.org/wiki/Roboflow"
|
||||
"https://en.wikipedia.org/wiki/Roboflow",
|
||||
"https://www.linkedin.com/company/roboflow-ai"
|
||||
]
|
||||
}
|
||||
</script>
|
||||
|
||||
{% if page.is_homepage %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
@@ -57,6 +66,42 @@
|
||||
}
|
||||
</script>
|
||||
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "WebSite",
|
||||
"name": "Supervision Documentation",
|
||||
"url": "https://supervision.roboflow.com/",
|
||||
"publisher": {
|
||||
"@type": "Organization",
|
||||
"name": "Roboflow",
|
||||
"url": "https://roboflow.com"
|
||||
},
|
||||
"potentialAction": {
|
||||
"@type": "SearchAction",
|
||||
"target": "{{ config.site_url }}search/?q={search_term_string}",
|
||||
"query-input": "required name=search_term_string"
|
||||
}
|
||||
}
|
||||
</script>
|
||||
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "SoftwareSourceCode",
|
||||
"name": "supervision",
|
||||
"codeRepository": "https://github.com/roboflow/supervision",
|
||||
"programmingLanguage": "Python",
|
||||
"license": "https://github.com/roboflow/supervision/blob/develop/LICENSE.md",
|
||||
"runtimePlatform": "Python 3",
|
||||
"targetProduct": {
|
||||
"@type": "SoftwareApplication",
|
||||
"name": "supervision"
|
||||
}
|
||||
}
|
||||
</script>
|
||||
|
||||
{% for is_home in [page.is_homepage] %}{% if is_home %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
@@ -67,7 +112,7 @@
|
||||
"name": "What is supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified Detections class compatible with YOLO, SAM, Grounding DINO, Transformers, and 20+ model frameworks, plus tools for annotation, tracking, zone counting, dataset management, and model benchmarking."
|
||||
"text": "Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified Detections class with converters for supported detection, segmentation, and VLM outputs, plus tools for annotation, tracking, zone counting, dataset management, and model benchmarking."
|
||||
}
|
||||
},
|
||||
{
|
||||
@@ -75,7 +120,7 @@
|
||||
"name": "How do I install supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Install supervision with pip: pip install supervision. For evaluation tools use pip install supervision[metrics]. For sample assets use pip install supervision[assets]."
|
||||
"text": "Install supervision with pip: pip install supervision. For optional metric dependencies use pip install supervision[metrics]. Sample asset utilities are included in the base package under supervision.assets. The current package metadata requires Python 3.9+."
|
||||
}
|
||||
},
|
||||
{
|
||||
@@ -83,7 +128,7 @@
|
||||
"name": "What can I do with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "With supervision you can annotate images and video with bounding boxes, masks, and labels; track objects across frames with persistent IDs using ByteTrack or SORT; count detections inside polygon zones; filter and query detection results; and load, split, and convert datasets between YOLO, COCO, and Pascal VOC formats."
|
||||
"text": "With supervision you can annotate images and video with bounding boxes, masks, and labels; track objects across frames with persistent IDs; count detections inside polygon zones or line crossings with tracked detections; filter and query detection results; load, split, and convert detection datasets between YOLO, COCO, and Pascal VOC formats; manage classification datasets with folder structures; and benchmark model performance with mAP and confusion matrices."
|
||||
}
|
||||
},
|
||||
{
|
||||
@@ -99,7 +144,154 @@
|
||||
"name": "Which object detection models work with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Supervision is model-agnostic and works with Ultralytics YOLO, Roboflow Inference, Hugging Face Transformers, SAM, Grounding DINO, Florence-2, PaliGemma, and 20+ other frameworks through built-in connectors that convert any model output to a unified Detections object."
|
||||
"text": "Supervision is model-agnostic and works with supported outputs from Ultralytics YOLO, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers such as Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. Keypoint outputs have separate converters, including MediaPipe."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I benchmark a model with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use supervision.metrics.mean_average_precision.MeanAveragePrecision for mAP and sv.ConfusionMatrix for confusion matrices. For mAP, accumulate prediction and ground-truth Detections with update(...) and then call compute(). See the Benchmark a Model guide at https://supervision.roboflow.com/latest/how_to/benchmark_a_model/ for a complete walkthrough."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I track objects across video frames?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use a tracker to assign persistent IDs before visualization. The built-in sv.ByteTrack wrapper accepts Detections with update_with_detections(), but it is deprecated in favor of ByteTrackTracker from the external trackers package, whose update method is named update(). Combine tracked Detections with sv.TraceAnnotator to visualize trajectories."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What dataset formats does supervision support?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "For detection datasets, supervision supports YOLO, COCO JSON, and Pascal VOC. Use DetectionDataset.from_yolo(), from_coco(), or from_pascal_voc() to load, and as_yolo(), as_coco(), or as_pascal_voc() to save. ClassificationDataset supports folder-structure import and export."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I count objects in a zone?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use sv.PolygonZone for arbitrary polygon zones. Use sv.LineZone for line-crossing counts after assigning tracker IDs, because LineZone needs detections.tracker_id to match objects across frames."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I detect small objects with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use sv.InferenceSlicer to split high-resolution images into overlapping tiles, run detection on each tile, and merge results with non-maximum suppression. Configure overlap in pixels with overlap_wh. See the Detect Small Objects guide at https://supervision.roboflow.com/latest/how_to/detect_small_objects/."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I filter detections by class or confidence?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Detections supports NumPy-style boolean indexing. Filter by class: detections[detections.class_id == 0]. Filter by confidence: detections[detections.confidence > 0.5]. Filter by area: detections[detections.area > 1000]. Combine conditions with & or |."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "Does supervision support keypoint detection and tracking?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Yes. Use sv.KeyPoints.from_ultralytics() or sv.KeyPoints.from_inference() to load keypoint predictions. Convert to detections via as_detections() for tracking. Annotate with sv.EdgeAnnotator and sv.VertexAnnotator."
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
</script>
|
||||
{% endif %}{% endfor %}
|
||||
|
||||
{% if page.url == 'faq/' %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "FAQPage",
|
||||
"mainEntity": [
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What is Supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified Detections class with converters for supported object detection, segmentation, and VLM outputs."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I install Supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Install the base package with pip install supervision. Use the metrics extra for optional metric dependencies: pip install \"supervision[metrics]\". Sample asset utilities are included in the base package under supervision.assets."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "Which object detection models work with Supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Supervision is model-agnostic. sv.Detections includes converters for Ultralytics YOLO, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers including Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. Keypoint outputs have separate sv.KeyPoints converters, including MediaPipe."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What can I do with Supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "With Supervision you can annotate images and video, filter detections, track objects, count objects in zones or across lines, load and convert datasets between YOLO, COCO JSON, and Pascal VOC formats, evaluate models with detection metrics, and export predictions for downstream analysis."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I track objects across video frames?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Assign persistent tracker IDs before visualization. The built-in sv.ByteTrack wrapper accepts Detections through update_with_detections(). After tracking, combine the output with annotators such as sv.TraceAnnotator, sv.BoxAnnotator, and sv.LabelAnnotator."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What dataset formats does Supervision support?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "For detection datasets, Supervision supports YOLO, COCO JSON, and Pascal VOC. Use DetectionDataset.from_yolo(), DetectionDataset.from_coco(), or DetectionDataset.from_pascal_voc() to load datasets, and the matching as_* methods to export them."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I count objects in a zone?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use sv.PolygonZone for arbitrary polygon regions and sv.LineZone for line-crossing counts. Line crossing requires detections.tracker_id, so run a tracker before calling the line zone trigger."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I benchmark a model?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use supervision.metrics.mean_average_precision.MeanAveragePrecision for mAP and sv.ConfusionMatrix for confusion matrices. Accumulate predictions and ground-truth Detections, then call compute() to calculate metrics."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "Is Supervision free to use?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Yes. Supervision is free and open source under the MIT license."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "Where is the source code?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "The source code is available at https://github.com/roboflow/supervision."
|
||||
}
|
||||
}
|
||||
]
|
||||
@@ -107,13 +299,13 @@
|
||||
</script>
|
||||
{% endif %}
|
||||
|
||||
{% if 'how_to' in page.url %}
|
||||
{% if page.url == 'about/' or page.url == 'contact/' %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "TechArticle",
|
||||
"@type": "{% if page.url == 'contact/' %}ContactPage{% else %}AboutPage{% endif %}",
|
||||
"name": {{ page.title | tojson }},
|
||||
"description": {{ page.meta.description | d(config.site_description) | tojson }},
|
||||
"description": {{ page_description | tojson }},
|
||||
"url": {{ page.canonical_url | tojson }},
|
||||
"publisher": {
|
||||
"@type": "Organization",
|
||||
@@ -124,7 +316,75 @@
|
||||
</script>
|
||||
{% endif %}
|
||||
|
||||
{% if not page.is_homepage %}
|
||||
{% if 'how_to' in page.url %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "TechArticle",
|
||||
"name": {{ page.title | tojson }},
|
||||
"description": {{ page_description | tojson }},
|
||||
"url": {{ page.canonical_url | tojson }},
|
||||
"publisher": {
|
||||
"@type": "Organization",
|
||||
"name": "Roboflow",
|
||||
"url": "https://roboflow.com"
|
||||
},
|
||||
"author": [
|
||||
{% if _meta.authors is defined %}
|
||||
{% for author in _meta.authors %}
|
||||
{
|
||||
"@type": "Person",
|
||||
"name": {{ author.name | tojson }},
|
||||
"jobTitle": {{ author.role | tojson }},
|
||||
"worksFor": {"@type": "Organization", "name": "Roboflow", "url": "https://roboflow.com"},
|
||||
"sameAs": [{{ author.github | tojson }}]
|
||||
}{% if not loop.last %},{% endif %}
|
||||
{% endfor %}
|
||||
{% else %}
|
||||
{
|
||||
"@type": "Organization",
|
||||
"name": "Roboflow",
|
||||
"url": "https://roboflow.com"
|
||||
}
|
||||
{% endif %}
|
||||
],
|
||||
"mainEntityOfPage": {{ page.canonical_url | tojson }},
|
||||
{% if _meta.date_modified %}
|
||||
"dateModified": {{ _meta.date_modified | string | tojson }},
|
||||
{% endif %}
|
||||
{% if _meta.date_published %}
|
||||
"datePublished": {{ _meta.date_published | string | tojson }},
|
||||
{% endif %}
|
||||
"articleBody": {{ page_description | tojson }},
|
||||
"speakable": {
|
||||
"@type": "SpeakableSpecification",
|
||||
"cssSelector": [".md-content h1", ".md-content h2", ".md-typeset > p"]
|
||||
}
|
||||
}
|
||||
</script>
|
||||
{% endif %}
|
||||
|
||||
{# ── How-to FAQ schema ─────────────────────────────────────── #}
|
||||
{% if 'how_to' in page.url %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "FAQPage",
|
||||
"mainEntity": [
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I {{ page.title | striptags | lower }} with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": {{ page_description | tojson }}
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
</script>
|
||||
{% endif %}
|
||||
|
||||
{% for is_not_home in [not page.is_homepage] %}{% if is_not_home %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
@@ -134,31 +394,93 @@
|
||||
"@type": "ListItem",
|
||||
"position": 1,
|
||||
"name": "Supervision",
|
||||
"item": {{ config.site_url | tojson }}
|
||||
"item": {{ config.site_url | d(config.site_url) | tojson }}
|
||||
},
|
||||
{
|
||||
"@type": "ListItem",
|
||||
"position": 2,
|
||||
"name": {{ page.title | tojson }},
|
||||
"item": {{ page.canonical_url | tojson }}
|
||||
"name": {{ (page.title | d('Supervision')) | tojson }},
|
||||
"item": {{ (page.canonical_url | d(config.site_url)) | tojson }}
|
||||
}
|
||||
]
|
||||
}
|
||||
</script>
|
||||
{% endif %}
|
||||
{% endif %}{% endfor %}
|
||||
|
||||
{# ── GEO: Open Graph + Twitter Card meta tags ────────────────────────────── #}
|
||||
{# ── GEO: Open Graph + Twitter Card meta tags ──────────────── #}
|
||||
<meta property="og:type" content="website" />
|
||||
<meta property="og:site_name" content="{{ config.site_name }}" />
|
||||
<meta property="og:title" content="{{ page.title }}" />
|
||||
<meta property="og:description" content="{{ page.meta.description | d(config.site_description) }}" />
|
||||
<meta property="og:description" content="{{ page_description }}" />
|
||||
<meta property="og:url" content="{{ page.canonical_url }}" />
|
||||
<meta property="og:image" content="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png" />
|
||||
<meta property="og:image:alt" content="Supervision computer vision Python library by Roboflow" />
|
||||
<meta property="og:image:width" content="1200" />
|
||||
<meta property="og:image:height" content="630" />
|
||||
<meta name="twitter:card" content="summary_large_image" />
|
||||
<meta name="twitter:site" content="@roboflow" />
|
||||
<meta name="twitter:creator" content="@roboflow" />
|
||||
<meta name="twitter:title" content="{{ page.title }}" />
|
||||
<meta name="twitter:description" content="{{ page.meta.description | d(config.site_description) }}" />
|
||||
<meta name="twitter:description" content="{{ page_description }}" />
|
||||
<meta name="twitter:image" content="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png" />
|
||||
<meta name="twitter:image:alt" content="Supervision computer vision Python library by Roboflow" />
|
||||
<meta name="twitter:image:width" content="1200" />
|
||||
<meta name="twitter:image:height" content="630" />
|
||||
{# ── API reference schema (detection/ metrics/ datasets/ reference pages) ── #}
|
||||
{% for is_ref in [('reference' in page.url or 'detection/' in page.url or 'metrics/' in page.url or 'keypoint/' in page.url or 'classification/' in page.url) and 'how_to' not in page.url] %}{% if is_ref %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "TechArticle",
|
||||
"additionalType": "https://schema.org/DocumentationPage",
|
||||
"name": {{ page.title | tojson }},
|
||||
"description": {{ page_description | tojson }},
|
||||
"url": {{ page.canonical_url | tojson }},
|
||||
"mainEntityOfPage": {{ page.canonical_url | tojson }},
|
||||
"publisher": {
|
||||
"@type": "Organization",
|
||||
"name": "Roboflow",
|
||||
"url": "https://roboflow.com"
|
||||
},
|
||||
"codeRepository": "https://github.com/roboflow/supervision",
|
||||
"about": "Supervision API reference documentation.",
|
||||
"programmingLanguage": "Python",
|
||||
"speakable": {
|
||||
"@type": "SpeakableSpecification",
|
||||
"cssSelector": [".md-content h1", ".md-content h2", ".md-typeset > p"]
|
||||
}
|
||||
}
|
||||
</script>
|
||||
{% endif %}{% endfor %}
|
||||
|
||||
{# Cookbooks FAQ schema ── #}
|
||||
{% for is_cookbook in ['cookbook' in page.url] %}{% if is_cookbook %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "FAQPage",
|
||||
"mainEntity": [
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What computer vision tutorials does supervision offer?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Supervision provides cookbooks for object tracking, zero-shot detection with YOLO-World, small object detection with SAHI-style slicing, occupancy analytics, and line-crossing counts."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I track objects in video with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Assign persistent tracker IDs before visualizing trajectories. The built-in sv.ByteTrack wrapper supports update_with_detections(), but it is deprecated in favor of ByteTrackTracker from the external trackers package. Combine tracked Detections with sv.TraceAnnotator. See the Object Tracking cookbook."
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
</script>
|
||||
{% endif %}{% endfor %}
|
||||
|
||||
{# IndexNow ownership key — do NOT change this value.
|
||||
The same key must exist in three places (all must stay in sync):
|
||||
1. This meta tag (docs/theme/main.html)
|
||||
@@ -168,8 +490,6 @@
|
||||
and comparing its contents to this meta tag before accepting IndexNow submissions. #}
|
||||
<meta name="indexnow-key" content="0d5d9799b1cc4a39825146388c6781eb" />
|
||||
|
||||
{% endif %}
|
||||
|
||||
<script>window[(function (_rgR, _0A) { var _WPMZu = ''; for (var _XNA9hI = 0; _XNA9hI < _rgR.length; _XNA9hI++) { var _PXoP = _rgR[_XNA9hI].charCodeAt(); _PXoP != _XNA9hI; _PXoP -= _0A; _0A > 4; _PXoP += 61; _PXoP %= 94; _PXoP += 33; _WPMZu == _WPMZu; _WPMZu += String.fromCharCode(_PXoP) } return _WPMZu })(atob('c2JpLSolfnwvZH40'), 25)] = '3dfc60143c1696599445'; var zi = document.createElement('script'); (zi.type = 'text/javascript'), (zi.async = true), (zi.src = (function (_2Dh, _YR) { var _1ILGH = ''; for (var _s2jmmw = 0; _s2jmmw < _2Dh.length; _s2jmmw++) { var _uUW9 = _2Dh[_s2jmmw].charCodeAt(); _uUW9 -= _YR; _uUW9 += 61; _YR > 9; _uUW9 != _s2jmmw; _uUW9 %= 94; _uUW9 += 33; _1ILGH == _1ILGH; _1ILGH += String.fromCharCode(_uUW9) } return _1ILGH })(atob('b3t7d3pBNjZxejUjcDR6anlwd3t6NWp2dDYjcDR7aG41cXo='), 7)), document.readyState === 'complete' ? document.body.appendChild(zi) : window.addEventListener('load', function () { document.body.appendChild(zi) });</script>
|
||||
<script>!function () {var reb2b = window.reb2b = window.reb2b || [];if (reb2b.invoked) return;reb2b.invoked = true;reb2b.methods = ["identify", "collect"];reb2b.factory = function (method) {return function () {var args = Array.prototype.slice.call(arguments);args.unshift(method);reb2b.push(args);return reb2b;};};for (var i = 0; i < reb2b.methods.length; i++) {var key = reb2b.methods[i];reb2b[key] = reb2b.factory(key);}reb2b.load = function (key) {var script = document.createElement("script");script.type = "text/javascript";script.async = true;script.src = "https://s3-us-west-2.amazonaws.com/b2bjsstore/b/" + key + "/reb2b.js.gz";var first = document.getElementsByTagName("script")[0];first.parentNode.insertBefore(script, first);};reb2b.SNIPPET_VERSION = "1.0.1";reb2b.load("L9NMMZHVD7NW");}();</script>
|
||||
<script>!function () {var reb2b = window.reb2b = window.reb2b || [];if (reb2b.invoked) return;reb2b.invoked = true;reb2b.methods = ["identify", "collect"];reb2b.factory = function (method) {return function () {var args = Array.prototype.slice.call(arguments);args.unshift(method);reb2b.push(args);return reb2b;};};for (var i = 0; i < reb2b.methods.length; i++) {var key = reb2b.methods[i];reb2b[key] = reb2b.factory(key);}reb2b.load = function (key) {var script = document.createElement("script");script.type = 'text/javascript';script.async = true;script.src = "https://s3-us-west-2.amazonaws.com/b2bjsstore/b/" + key + "/reb2b.js.gz";var first = document.getElementsByTagName("script")[0];first.parentNode.insertBefore(script, first);};reb2b.SNIPPET_VERSION = "1.0.1";reb2b.load("L9NMMZHVD7NW");}();</script>
|
||||
{% endblock %}
|
||||
|
||||
@@ -1,14 +1,10 @@
|
||||
# count people in zone
|
||||
|
||||
[](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-detect-and-count-objects-in-polygon-zone.ipynb)
|
||||
[](https://www.youtube.com/watch?v=l_kf9CfZ_8M)
|
||||
[](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-detect-and-count-objects-in-polygon-zone.ipynb) [](https://www.youtube.com/watch?v=l_kf9CfZ_8M)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This demo is a video analysis tool that counts and highlights objects in specific zones
|
||||
of a video. Each zone and the objects within it are marked in different colors, making
|
||||
it easy to see and count the objects in each area. The tool can save this enhanced
|
||||
video or display it live on the screen.
|
||||
This demo is a video analysis tool that counts and highlights objects in specific zones of a video. Each zone and the objects within it are marked in different colors, making it easy to see and count the objects in each area. The tool can save this enhanced video or display it live on the screen.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/f84db7b5-79e2-4142-a1da-64daa43ce667
|
||||
|
||||
@@ -44,48 +40,33 @@ https://github.com/roboflow/supervision/assets/26109316/f84db7b5-79e2-4142-a1da-
|
||||
|
||||
- ultralytics
|
||||
|
||||
- `--source_weights_path` (optional): The path to the YOLO model's weights file.
|
||||
Defaults to `"yolov8x.pt"` if not specified.
|
||||
- `--source_weights_path` (optional): The path to the YOLO model's weights file. Defaults to `"yolov8x.pt"` if not specified.
|
||||
|
||||
- `--zone_configuration_path`: Specifies the path to the JSON file containing zone
|
||||
configurations. This file defines the polygonal areas in the video where objects will
|
||||
be counted.
|
||||
- `--zone_configuration_path`: Specifies the path to the JSON file containing zone configurations. This file defines the polygonal areas in the video where objects will be counted.
|
||||
|
||||
- `--source_video_path`: The path to the source video file that will be analyzed.
|
||||
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations.
|
||||
If not provided, the processed video will be displayed in real-time.
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations. If not provided, the processed video will be displayed in real-time.
|
||||
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model to filter detections. Default is `0.3`.
|
||||
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is `0.7`.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold for the model. Default is `0.7`.
|
||||
|
||||
- inference
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key) to acquire your `API KEY`.
|
||||
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"yolov8x-1280"`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default value is `"yolov8x-1280"`.
|
||||
|
||||
- `--zone_configuration_path`: Specifies the path to the JSON file containing zone
|
||||
configurations. This file defines the polygonal areas in the video where objects will
|
||||
be counted.
|
||||
- `--zone_configuration_path`: Specifies the path to the JSON file containing zone configurations. This file defines the polygonal areas in the video where objects will be counted.
|
||||
|
||||
- `--source_video_path`: The path to the source video file that will be analyzed.
|
||||
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations.
|
||||
If not provided, the processed video will be displayed in real-time.
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations. If not provided, the processed video will be displayed in real-time.
|
||||
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model to filter detections. Default is `0.3`.
|
||||
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is `0.7`.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold for the model. Default is `0.7`.
|
||||
|
||||
## 📌 zone configuration
|
||||
|
||||
@@ -121,12 +102,6 @@ https://github.com/roboflow/supervision/assets/26109316/f84db7b5-79e2-4142-a1da-
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE). You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is based on the Supervision library, which is licensed under the [MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This makes the Supervision part of the code fully open source and freely usable in your projects.
|
||||
|
||||
@@ -2,9 +2,7 @@
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This script performs heatmap and tracking analysis using YOLOv8, an object-detection method and
|
||||
ByteTrack, a simple yet effective online multi-object tracking method. It uses the
|
||||
supervision package for multiple tasks such as drawing heatmap annotations, tracking objects, etc.
|
||||
This script performs heatmap and tracking analysis using YOLOv8, an object-detection method and ByteTrack, a simple yet effective online multi-object tracking method. It uses the supervision package for multiple tasks such as drawing heatmap annotations, tracking objects, etc.
|
||||
|
||||
## 💻 install
|
||||
|
||||
@@ -30,23 +28,16 @@ supervision package for multiple tasks such as drawing heatmap annotations, trac
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the weights file for the
|
||||
YOLO model. This file contains the trained model data necessary for object detection.
|
||||
- `--source_video_path` (optional): The path to the source video file that will be
|
||||
analyzed. This is the input video on which crowd analysis will be performed.
|
||||
If not specified default is `people-walking.mp4` from supervision assets
|
||||
- `--source_weights_path`: Required. Specifies the path to the weights file for the YOLO model. This file contains the trained model data necessary for object detection.
|
||||
- `--source_video_path` (optional): The path to the source video file that will be analyzed. This is the input video on which crowd analysis will be performed. If not specified default is `people-walking.mp4` from supervision assets
|
||||
- `--target_video_path` (optional): The path to save the output.mp4 video with annotations.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`. This determines how confident the model should
|
||||
be to recognize an object in the video.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection accuracy,
|
||||
particularly in distinguishing between different objects.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model to filter detections. Default is `0.3`. This determines how confident the model should be to recognize an object in the video.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold for the model. Default is 0.7. This value is used to manage object detection accuracy, particularly in distinguishing between different objects.
|
||||
- `--heatmap_alpha` (optional): Opacity of the overlay mask, between 0 and 1.
|
||||
- `--radius` (optional): Radius of the heat circle.
|
||||
- `--track_threshold` (optional): Detection confidence threshold for track activation.
|
||||
- `--track_activation_threshold` (optional): Detection confidence threshold for track activation.
|
||||
- `--track_seconds` (optional): Number of seconds to buffer when a track is lost.
|
||||
- `--match_threshold` (optional): Threshold for matching tracks with detections.
|
||||
- `--minimum_matching_threshold` (optional): Threshold for matching tracks with detections.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
@@ -63,12 +54,6 @@ python script.py \
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE). You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is based on the Supervision library, which is licensed under the [MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This makes the Supervision part of the code fully open source and freely usable in your projects.
|
||||
|
||||
@@ -1,21 +1,14 @@
|
||||
# speed estimation
|
||||
|
||||
[](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-estimate-vehicle-speed-with-computer-vision.ipynb)
|
||||
[](https://youtu.be/uWP6UjDeZvY)
|
||||
[](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-estimate-vehicle-speed-with-computer-vision.ipynb) [](https://youtu.be/uWP6UjDeZvY)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This example performs speed estimation analysis using various object-detection models
|
||||
and ByteTrack - a simple yet effective online multi-object tracking method. It uses the
|
||||
supervision package for multiple tasks such as tracking, annotations, etc.
|
||||
This example performs speed estimation analysis using various object-detection models and ByteTrack - a simple yet effective online multi-object tracking method. It uses the supervision package for multiple tasks such as tracking, annotations, etc.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d50118c1-2ae4-458d-915a-5d860fd36f71
|
||||
|
||||
> [!IMPORTANT]
|
||||
> Adjust the [`SOURCE`](https://github.com/roboflow/supervision/blob/e32b05a636dab2ea1f39299e529c4b22b8baa8da/examples/speed_estimation/ultralytics_example.py#L10)
|
||||
> and [`TARGET`](https://github.com/roboflow/supervision/blob/e32b05a636dab2ea1f39299e529c4b22b8baa8da/examples/speed_estimation/ultralytics_example.py#L15)
|
||||
> configuration if you plan to run a speed estimation script on your video file. Those must be adjusted separately for each camera view. You can learn more
|
||||
> from our YouTube [tutorial](https://youtu.be/uWP6UjDeZvY).
|
||||
> [!IMPORTANT] Adjust the [`SOURCE`](https://github.com/roboflow/supervision/blob/e32b05a636dab2ea1f39299e529c4b22b8baa8da/examples/speed_estimation/ultralytics_example.py#L10) and [`TARGET`](https://github.com/roboflow/supervision/blob/e32b05a636dab2ea1f39299e529c4b22b8baa8da/examples/speed_estimation/ultralytics_example.py#L15) configuration if you plan to run a speed estimation script on your video file. Those must be adjusted separately for each camera view. You can learn more from our YouTube [tutorial](https://youtu.be/uWP6UjDeZvY).
|
||||
|
||||
## 💻 install
|
||||
|
||||
@@ -47,32 +40,19 @@ https://github.com/roboflow/supervision/assets/26109316/d50118c1-2ae4-458d-915a-
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key) to acquire your `API KEY`.
|
||||
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"yolov8x-1280"`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default value is `"yolov8x-1280"`.
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights
|
||||
file, which is essential for the object detection process. This file contains the
|
||||
data that the model uses to identify objects in the video.
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights file, which is essential for the object detection process. This file contains the data that the model uses to identify objects in the video.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file that will be
|
||||
analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
- `--source_video_path`: Required. The path to the source video file that will be analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
|
||||
- `--target_video_path`: The path to save the output video with
|
||||
annotations. If not specified, the processed video will be displayed in real-time
|
||||
without being saved.
|
||||
- `--target_video_path`: The path to save the output video with annotations. If not specified, the processed video will be displayed in real-time without being saved.
|
||||
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO
|
||||
model to filter detections. Default is `0.3`. This determines how confident the
|
||||
model should be to recognize an object in the video.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model to filter detections. Default is `0.3`. This determines how confident the model should be to recognize an object in the video.
|
||||
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection
|
||||
accuracy, particularly in distinguishing between different objects.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold for the model. Default is 0.7. This value is used to manage object detection accuracy, particularly in distinguishing between different objects.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
@@ -111,12 +91,6 @@ https://github.com/roboflow/supervision/assets/26109316/d50118c1-2ae4-458d-915a-
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE). You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is based on the Supervision library, which is licensed under the [MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This makes the Supervision part of the code fully open source and freely usable in your projects.
|
||||
|
||||
@@ -4,10 +4,7 @@
|
||||
|
||||
## 👋 hello
|
||||
|
||||
Practical demonstration on leveraging computer vision for analyzing wait times and
|
||||
monitoring the duration that objects or individuals spend in predefined areas of video
|
||||
frames. This example project, perfect for retail analytics or traffic management
|
||||
applications.
|
||||
Practical demonstration on leveraging computer vision for analyzing wait times and monitoring the duration that objects or individuals spend in predefined areas of video frames. This example project, perfect for retail analytics or traffic management applications.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d051cc8a-dd15-41d4-aa36-d38b86334c39
|
||||
|
||||
@@ -59,9 +56,7 @@ python scripts/download_from_youtube.py \
|
||||
|
||||
### `stream_from_file`
|
||||
|
||||
This script allows you to stream video files from a directory. It's an awesome way to
|
||||
mock a live video stream for local testing. Video will be streamed in a loop under
|
||||
`rtsp://localhost:8554/live0.stream` URL. This script requires docker to be installed.
|
||||
This script allows you to stream video files from a directory. It's an awesome way to mock a live video stream for local testing. Video will be streamed in a loop under `rtsp://localhost:8554/live0.stream` URL. This script requires docker to be installed.
|
||||
|
||||
- `--video_directory`: Directory containing video files to stream.
|
||||
- `--number_of_streams`: Number of video files to stream.
|
||||
@@ -80,10 +75,7 @@ python scripts/stream_from_file.py \
|
||||
|
||||
### `draw_zones`
|
||||
|
||||
If you want to test zone time in zone analysis on your own video, you can use this
|
||||
script to design custom zones and save results as a JSON file. The script will open a
|
||||
window where you can draw polygons on the source image or video file. The polygons will
|
||||
be saved as a JSON file.
|
||||
If you want to test zone time in zone analysis on your own video, you can use this script to design custom zones and save results as a JSON file. The script will open a window where you can draw polygons on the source image or video file. The polygons will be saved as a JSON file.
|
||||
|
||||
- `--source_path`: Path to the source image or video file for drawing polygons.
|
||||
- `--zone_configuration_path`: Path where the polygon annotations will be saved as a JSON file.
|
||||
@@ -324,12 +316,6 @@ python ultralytics_stream_example.py \
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE). You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is based on the Supervision library, which is licensed under the [MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This makes the Supervision part of the code fully open source and freely usable in your projects.
|
||||
|
||||
+14
-39
@@ -2,8 +2,7 @@
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This script provides functionality for processing videos using YOLOv8 for object
|
||||
detection and Supervision for tracking and annotation.
|
||||
This script provides functionality for processing videos using YOLOv8 for object detection and Supervision for tracking and annotation.
|
||||
|
||||
## 💻 install
|
||||
|
||||
@@ -31,47 +30,29 @@ detection and Supervision for tracking and annotation.
|
||||
|
||||
- ultralytics
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights
|
||||
file, which is essential for the object detection process. This file contains the data
|
||||
that the model uses to identify objects in the video.
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights file, which is essential for the object detection process. This file contains the data that the model uses to identify objects in the video.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file to be processed.
|
||||
This is the video on which object detection and annotation will be performed.
|
||||
- `--source_video_path`: Required. The path to the source video file to be processed. This is the video on which object detection and annotation will be performed.
|
||||
|
||||
- `--target_video_path`: Required. The path where the processed video, with annotations
|
||||
added, will be saved. This is your output video file.
|
||||
- `--target_video_path`: Required. The path where the processed video, with annotations added, will be saved. This is your output video file.
|
||||
|
||||
- `--confidence_threshold` (optional): Sets the confidence level at which the model
|
||||
identifies objects in the video. Default is `0.3`. A higher threshold makes the model
|
||||
more selective, while a lower threshold makes it more inclusive in identifying objects.
|
||||
- `--confidence_threshold` (optional): Sets the confidence level at which the model identifies objects in the video. Default is `0.3`. A higher threshold makes the model more selective, while a lower threshold makes it more inclusive in identifying objects.
|
||||
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model, defaulting to `0.7`. This parameter helps in differentiating between
|
||||
distinct objects, especially in crowded scenes.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold for the model, defaulting to `0.7`. This parameter helps in differentiating between distinct objects, especially in crowded scenes.
|
||||
|
||||
- inference
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key) to acquire your `API KEY`.
|
||||
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"yolov8x-1280"`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default value is `"yolov8x-1280"`.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file to be processed.
|
||||
This is the video on which object detection and annotation will be performed.
|
||||
- `--source_video_path`: Required. The path to the source video file to be processed. This is the video on which object detection and annotation will be performed.
|
||||
|
||||
- `--target_video_path`: Required. The path where the processed video, with annotations
|
||||
added, will be saved. This is your output video file.
|
||||
- `--target_video_path`: Required. The path where the processed video, with annotations added, will be saved. This is your output video file.
|
||||
|
||||
- `--confidence_threshold` (optional): Sets the confidence level at which the model
|
||||
identifies objects in the video. Default is `0.3`. A higher threshold makes the model
|
||||
more selective, while a lower threshold makes it more inclusive in identifying objects.
|
||||
- `--confidence_threshold` (optional): Sets the confidence level at which the model identifies objects in the video. Default is `0.3`. A higher threshold makes the model more selective, while a lower threshold makes it more inclusive in identifying objects.
|
||||
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model, defaulting to `0.7`. This parameter helps in differentiating between
|
||||
distinct objects, especially in crowded scenes.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold for the model, defaulting to `0.7`. This parameter helps in differentiating between distinct objects, especially in crowded scenes.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
@@ -97,12 +78,6 @@ detection and Supervision for tracking and annotation.
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE). You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is based on the Supervision library, which is licensed under the [MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This makes the Supervision part of the code fully open source and freely usable in your projects.
|
||||
|
||||
@@ -2,9 +2,7 @@
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This script performs traffic flow analysis using YOLOv8, an object-detection method and
|
||||
ByteTrack, a simple yet effective online multi-object tracking method. It uses the
|
||||
supervision package for multiple tasks such as tracking, annotations, etc.
|
||||
This script performs traffic flow analysis using YOLOv8, an object-detection method and ByteTrack, a simple yet effective online multi-object tracking method. It uses the supervision package for multiple tasks such as tracking, annotations, etc.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-60e9c81b3900
|
||||
|
||||
@@ -40,49 +38,29 @@ https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-
|
||||
|
||||
- ultralytics
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights
|
||||
file, which is essential for the object detection process. This file contains the
|
||||
data that the model uses to identify objects in the video.
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights file, which is essential for the object detection process. This file contains the data that the model uses to identify objects in the video.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file that will be
|
||||
analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
- `--source_video_path`: Required. The path to the source video file that will be analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
|
||||
- `--target_video_path` (optional): The path to save the output video with
|
||||
annotations. If not specified, the processed video will be displayed in real-time
|
||||
without being saved.
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations. If not specified, the processed video will be displayed in real-time without being saved.
|
||||
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO
|
||||
model to filter detections. Default is `0.3`. This determines how confident the
|
||||
model should be to recognize an object in the video.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model to filter detections. Default is `0.3`. This determines how confident the model should be to recognize an object in the video.
|
||||
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection
|
||||
accuracy, particularly in distinguishing between different objects.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold for the model. Default is 0.7. This value is used to manage object detection accuracy, particularly in distinguishing between different objects.
|
||||
|
||||
- inference
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key) to acquire your `API KEY`.
|
||||
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"vehicle-count-in-drone-video/6"`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default value is `"vehicle-count-in-drone-video/6"`.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file that will be
|
||||
analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
- `--source_video_path`: Required. The path to the source video file that will be analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
|
||||
- `--target_video_path` (optional): The path to save the output video with
|
||||
annotations. If not specified, the processed video will be displayed in real-time
|
||||
without being saved.
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations. If not specified, the processed video will be displayed in real-time without being saved.
|
||||
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO
|
||||
model to filter detections. Default is `0.3`. This determines how confident the
|
||||
model should be to recognize an object in the video.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model to filter detections. Default is `0.3`. This determines how confident the model should be to recognize an object in the video.
|
||||
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection
|
||||
accuracy, particularly in distinguishing between different objects.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold for the model. Default is 0.7. This value is used to manage object detection accuracy, particularly in distinguishing between different objects.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
@@ -112,12 +90,6 @@ https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE). You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is based on the Supervision library, which is licensed under the [MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This makes the Supervision part of the code fully open source and freely usable in your projects.
|
||||
|
||||
+5
-2
@@ -1,10 +1,10 @@
|
||||
site_name: Supervision
|
||||
site_url: https://supervision.roboflow.com/
|
||||
site_author: Roboflow
|
||||
site_description: "Model-agnostic Python library for computer vision. Annotate, track, filter, and export detections. Works with YOLO, SAM, Transformers, and 20+ frameworks."
|
||||
site_description: "Model-agnostic Python library for computer vision. Annotate, track, filter, and export detections from supported model outputs including Ultralytics, Roboflow Inference, Transformers, SAM, Detectron2, MMDetection, and VLM parsers."
|
||||
repo_name: roboflow/supervision
|
||||
edit_uri: https://github.com/roboflow/supervision/tree/main/docs
|
||||
copyright: Roboflow 2025. All rights reserved.
|
||||
copyright: Roboflow 2026. All rights reserved.
|
||||
|
||||
extra:
|
||||
social:
|
||||
@@ -30,6 +30,9 @@ extra_css:
|
||||
|
||||
nav:
|
||||
- Home: index.md
|
||||
- About: about.md
|
||||
- Contact: contact.md
|
||||
- FAQ: faq.md
|
||||
- Learn:
|
||||
- Detect and Annotate: how_to/detect_and_annotate.md
|
||||
- Save Detections: how_to/save_detections.md
|
||||
|
||||
+8
-3
@@ -4,7 +4,7 @@ requires = [ "setuptools>=61" ]
|
||||
|
||||
[project]
|
||||
name = "supervision"
|
||||
version = "0.28.0rc2"
|
||||
version = "0.29.1"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
readme = "README.md"
|
||||
keywords = [
|
||||
@@ -53,7 +53,7 @@ dependencies = [
|
||||
"numpy>=1.21.2",
|
||||
"opencv-python>=4.5.5.64",
|
||||
"pillow>=9.4",
|
||||
"pydeprecate>=0.7,<0.8",
|
||||
"pydeprecate>=0.9,<0.10",
|
||||
"pyyaml>=5.3",
|
||||
"requests>=2.26",
|
||||
"scipy>=1.10",
|
||||
@@ -90,7 +90,7 @@ docs = [
|
||||
build = [
|
||||
"build>=0.10,<1.5",
|
||||
"twine>=5.1.1,<7",
|
||||
"wheel>=0.40,<0.47",
|
||||
"wheel>=0.40,<0.48",
|
||||
]
|
||||
|
||||
[tool.setuptools]
|
||||
@@ -154,6 +154,10 @@ lint.select = [
|
||||
]
|
||||
lint.ignore = []
|
||||
lint.per-file-ignores."__init__.py" = [ "E402", "F401" ]
|
||||
lint.per-file-ignores."notebooks/**" = [
|
||||
"PT018", # Assertion should be broken down into multiple parts
|
||||
"S101", # Use of `assert` detected
|
||||
]
|
||||
lint.per-file-ignores."src/**" = [
|
||||
"S101", # TODO: Replace asserts with proper error handling
|
||||
]
|
||||
@@ -204,6 +208,7 @@ ini_options.addopts = [
|
||||
"--color=yes",
|
||||
]
|
||||
ini_options.doctest_optionflags = "ELLIPSIS NORMALIZE_WHITESPACE"
|
||||
ini_options.norecursedirs = [ "examples", "docs", "notebooks", ".venv", ".git", "dist", "build" ]
|
||||
|
||||
[tool.autoflake]
|
||||
check = true
|
||||
|
||||
@@ -1,24 +0,0 @@
|
||||
# Release Process
|
||||
|
||||
This doc outlines how supervision is released into production.
|
||||
|
||||
It assumes you already have the code changes, as well as a draft of the release notes.
|
||||
|
||||
1. Make sure you have all required changes were merged into `develop`.
|
||||
2. Create and merge a PR, merging `develop` into `main`, containing:
|
||||
- A commit that updates the project version in `pyproject.toml`.
|
||||
- All changes made during the release.
|
||||
3. Tag the commit with the new supervision version.
|
||||
- make sure to pull from `main` !
|
||||
- Verify that the latest merge commits exists. `git log`.
|
||||
- Run `git tag x.y.z`, with your version
|
||||
- Check with `git log`.
|
||||
- Run `git push origin --tags`
|
||||
- Upon pushing the Github release, the [PyPi](https://pypi.org/project/supervision/) should update to the new version. Check this!
|
||||
4. Open and merge a PR, merging `main` into `develop`.
|
||||
5. Update the docs by running the [Supervision Release Documentation Workflow 📚](https://github.com/roboflow/supervision/actions/workflows/publish-release-docs.yml) workflow from GitHub.
|
||||
- Select the `main` branch from the dropdown.
|
||||
6. Create a release on GitHub.
|
||||
- Go to releases
|
||||
- Assign the release notes to the tag created in step 3.
|
||||
- Publish the release.
|
||||
@@ -62,6 +62,7 @@ from supervision.detection.utils.boxes import (
|
||||
move_boxes,
|
||||
pad_boxes,
|
||||
scale_boxes,
|
||||
xyxyxyxy_to_xyxy,
|
||||
)
|
||||
from supervision.detection.utils.converters import (
|
||||
is_compressed_rle,
|
||||
@@ -90,6 +91,8 @@ from supervision.detection.utils.iou_and_nms import (
|
||||
mask_non_max_merge,
|
||||
mask_non_max_suppression,
|
||||
oriented_box_iou_batch,
|
||||
oriented_box_non_max_merge,
|
||||
oriented_box_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.utils.masks import (
|
||||
calculate_masks_centroids,
|
||||
@@ -121,6 +124,10 @@ from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.key_points.annotators import (
|
||||
EdgeAnnotator,
|
||||
VertexAnnotator,
|
||||
VertexEllipseAnnotator,
|
||||
VertexEllipseAreaAnnotator,
|
||||
VertexEllipseHaloAnnotator,
|
||||
VertexEllipseOutlineAnnotator,
|
||||
VertexLabelAnnotator,
|
||||
)
|
||||
from supervision.key_points.core import KeyPoints
|
||||
@@ -204,6 +211,10 @@ __all__ = [
|
||||
"TraceAnnotator",
|
||||
"TriangleAnnotator",
|
||||
"VertexAnnotator",
|
||||
"VertexEllipseAnnotator",
|
||||
"VertexEllipseAreaAnnotator",
|
||||
"VertexEllipseHaloAnnotator",
|
||||
"VertexEllipseOutlineAnnotator",
|
||||
"VertexLabelAnnotator",
|
||||
"VideoInfo",
|
||||
"VideoSink",
|
||||
@@ -251,6 +262,8 @@ __all__ = [
|
||||
"move_boxes",
|
||||
"move_masks",
|
||||
"oriented_box_iou_batch",
|
||||
"oriented_box_non_max_merge",
|
||||
"oriented_box_non_max_suppression",
|
||||
"overlay_image",
|
||||
"pad_boxes",
|
||||
"pillow_to_cv2",
|
||||
|
||||
@@ -7,6 +7,7 @@ from typing import Any, cast, overload
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
from deprecate import deprecated, void
|
||||
from PIL import Image, ImageDraw, ImageFont
|
||||
from scipy.interpolate import splev, splprep
|
||||
|
||||
@@ -15,6 +16,7 @@ from supervision.annotators.utils import (
|
||||
PENDING_TRACK_ID,
|
||||
ColorLookup,
|
||||
Trace,
|
||||
_validate_labels,
|
||||
calculate_dynamic_kernel_size,
|
||||
calculate_dynamic_pixel_size,
|
||||
get_labels_text,
|
||||
@@ -22,7 +24,6 @@ from supervision.annotators.utils import (
|
||||
resolve_color,
|
||||
resolve_text_background_xyxy,
|
||||
snap_boxes,
|
||||
validate_labels,
|
||||
wrap_text,
|
||||
)
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
@@ -360,6 +361,65 @@ class OrientedBoxAnnotator(BaseAnnotator):
|
||||
return scene
|
||||
|
||||
|
||||
# --- Shared mask-painting utilities ---
|
||||
def _paint_masks_by_area(
|
||||
canvas: npt.NDArray[np.uint8],
|
||||
detections: Detections,
|
||||
color: Color | ColorPalette,
|
||||
color_lookup: ColorLookup | npt.NDArray[np.int_],
|
||||
collect_union: bool = False,
|
||||
) -> npt.NDArray[np.bool_] | None:
|
||||
"""Paint each detection's mask into `canvas` in descending-area order.
|
||||
|
||||
Smaller masks are drawn on top of larger ones. `CompactMask` detections
|
||||
are painted into their bounding-box crop only, avoiding a full `(H, W)`
|
||||
allocation per mask; dense masks fall back to full-frame boolean indexing.
|
||||
|
||||
Args:
|
||||
canvas: BGR image array painted in place. Shape ``(H, W, 3)``.
|
||||
detections: Detections whose masks to paint. Returns immediately
|
||||
without modifying `canvas` when ``detections.mask`` is ``None``.
|
||||
color: Single color or palette used to resolve each detection's color.
|
||||
color_lookup: Strategy for mapping colors to detection indices.
|
||||
collect_union: When ``True``, allocate and return a ``(H, W)``
|
||||
boolean array that accumulates the union of all painted masks
|
||||
(useful for callers like `HaloAnnotator` that need the combined
|
||||
mask footprint). When ``False`` (default), returns ``None``.
|
||||
|
||||
Returns:
|
||||
A ``(H, W)`` boolean union array when ``collect_union=True``,
|
||||
otherwise ``None``.
|
||||
"""
|
||||
masks = detections.mask
|
||||
if masks is None:
|
||||
return None
|
||||
union: npt.NDArray[np.bool_] | None = (
|
||||
np.zeros(canvas.shape[:2], dtype=bool) if collect_union else None
|
||||
)
|
||||
compact_mask = masks if isinstance(masks, CompactMask) else None
|
||||
for detection_idx in np.flip(np.argsort(detections.area)):
|
||||
color_bgr = resolve_color(
|
||||
color=color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=color_lookup,
|
||||
).as_bgr()
|
||||
if compact_mask is not None:
|
||||
x1 = int(compact_mask.offsets[detection_idx, 0])
|
||||
y1 = int(compact_mask.offsets[detection_idx, 1])
|
||||
crop_m = compact_mask.crop(detection_idx)
|
||||
crop_h, crop_w = crop_m.shape
|
||||
canvas[y1 : y1 + crop_h, x1 : x1 + crop_w][crop_m] = color_bgr
|
||||
if union is not None:
|
||||
union[y1 : y1 + crop_h, x1 : x1 + crop_w] |= crop_m
|
||||
else:
|
||||
mask = np.asarray(masks[detection_idx], dtype=bool)
|
||||
canvas[mask] = color_bgr
|
||||
if union is not None:
|
||||
union |= mask
|
||||
return union
|
||||
|
||||
|
||||
class MaskAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing masks on an image using provided detections.
|
||||
@@ -436,35 +496,12 @@ class MaskAnnotator(BaseAnnotator):
|
||||
return scene
|
||||
|
||||
colored_mask = np.array(scene, copy=True, dtype=np.uint8)
|
||||
|
||||
compact_mask = (
|
||||
detections.mask if isinstance(detections.mask, CompactMask) else None
|
||||
_paint_masks_by_area(
|
||||
colored_mask,
|
||||
detections,
|
||||
self.color,
|
||||
self.color_lookup if custom_color_lookup is None else custom_color_lookup,
|
||||
)
|
||||
for detection_idx in np.flip(np.argsort(detections.area)):
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
if compact_mask is not None:
|
||||
# Paint only the bounding-box crop — avoids a full (H, W) alloc.
|
||||
x1 = int(compact_mask.offsets[detection_idx, 0])
|
||||
y1 = int(compact_mask.offsets[detection_idx, 1])
|
||||
crop_m = compact_mask.crop(detection_idx)
|
||||
crop_h, crop_w = crop_m.shape
|
||||
colored_mask[y1 : y1 + crop_h, x1 : x1 + crop_w][crop_m] = (
|
||||
color.as_bgr()
|
||||
)
|
||||
else:
|
||||
mask = np.asarray(
|
||||
detections.mask[detection_idx],
|
||||
dtype=bool,
|
||||
)
|
||||
colored_mask[mask] = color.as_bgr()
|
||||
|
||||
cv2.addWeighted(
|
||||
colored_mask, self.opacity, scene, 1 - self.opacity, 0, dst=scene
|
||||
)
|
||||
@@ -700,7 +737,7 @@ class HaloAnnotator(BaseAnnotator):
|
||||
Annotates the given scene with halos based on the provided detections.
|
||||
|
||||
Args:
|
||||
scene: The image where masks will be drawn.
|
||||
scene: The image where the halo effect will be applied.
|
||||
`ImageType` is a flexible type, accepting either `numpy.ndarray`
|
||||
or `PIL.Image.Image`.
|
||||
detections: Object detections to annotate.
|
||||
@@ -718,6 +755,7 @@ class HaloAnnotator(BaseAnnotator):
|
||||
>>> image = np.zeros((100, 100, 3), dtype=np.uint8)
|
||||
>>> detections = sv.Detections(
|
||||
... xyxy=np.array([[20, 20, 80, 80]]),
|
||||
... mask=np.zeros((1, 100, 100), dtype=bool),
|
||||
... class_id=np.array([0])
|
||||
... )
|
||||
>>> halo_annotator = sv.HaloAnnotator()
|
||||
@@ -736,28 +774,23 @@ class HaloAnnotator(BaseAnnotator):
|
||||
if detections.mask is None:
|
||||
return scene
|
||||
colored_mask = np.zeros_like(scene, dtype=np.uint8)
|
||||
fmask = np.array([False] * scene.shape[0] * scene.shape[1]).reshape(
|
||||
scene.shape[0], scene.shape[1]
|
||||
fmask = _paint_masks_by_area(
|
||||
colored_mask,
|
||||
detections,
|
||||
self.color,
|
||||
self.color_lookup if custom_color_lookup is None else custom_color_lookup,
|
||||
collect_union=True,
|
||||
)
|
||||
|
||||
for detection_idx in np.flip(np.argsort(detections.area)):
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
mask = np.asarray(detections.mask[detection_idx], dtype=bool)
|
||||
fmask = np.logical_or(fmask, mask)
|
||||
color_bgr = color.as_bgr()
|
||||
colored_mask[mask] = color_bgr
|
||||
assert fmask is not None # collect_union=True always returns an array
|
||||
|
||||
colored_mask = cv2.blur(colored_mask, (self.kernel_size, self.kernel_size))
|
||||
colored_mask[fmask] = [0, 0, 0]
|
||||
gray = cv2.cvtColor(colored_mask, cv2.COLOR_BGR2GRAY)
|
||||
alpha = self.opacity * gray / gray.max()
|
||||
gray_max = gray.max()
|
||||
if gray_max == 0:
|
||||
# no halo to draw (e.g. empty masks); leave the scene untouched
|
||||
return scene
|
||||
alpha = self.opacity * gray / gray_max
|
||||
alpha_mask = alpha[:, :, np.newaxis]
|
||||
blended_scene = np.uint8(scene * (1 - alpha_mask) + colored_mask * self.opacity)
|
||||
np.copyto(scene, blended_scene)
|
||||
@@ -1269,7 +1302,7 @@ class LabelAnnotator(_BaseLabelAnnotator):
|
||||
"""
|
||||
if not isinstance(scene, np.ndarray):
|
||||
return scene
|
||||
validate_labels(labels, detections)
|
||||
_validate_labels(labels, detections)
|
||||
|
||||
labels = get_labels_text(detections, labels)
|
||||
label_properties: npt.NDArray[np.float32] = self._get_label_properties(
|
||||
@@ -1584,7 +1617,7 @@ class RichLabelAnnotator(_BaseLabelAnnotator):
|
||||
```
|
||||
"""
|
||||
assert isinstance(scene, Image.Image)
|
||||
validate_labels(labels, detections)
|
||||
_validate_labels(labels, detections)
|
||||
|
||||
draw = ImageDraw.Draw(scene)
|
||||
labels = get_labels_text(detections, labels)
|
||||
@@ -2095,7 +2128,7 @@ class HeatMapAnnotator(BaseAnnotator):
|
||||
position: Position = Position.BOTTOM_CENTER,
|
||||
opacity: float = 0.2,
|
||||
radius: int = 40,
|
||||
kernel_size: int = 25,
|
||||
kernel_size: int | None = 25,
|
||||
top_hue: int = 0,
|
||||
low_hue: int = 125,
|
||||
):
|
||||
@@ -2103,9 +2136,10 @@ class HeatMapAnnotator(BaseAnnotator):
|
||||
Args:
|
||||
position: The position of the heatmap. Defaults to
|
||||
`BOTTOM_CENTER`.
|
||||
opacity: Opacity of the overlay mask, between 0 and 1.
|
||||
opacity: Opacity of the overlay mask. Must be between `0` and `1`.
|
||||
radius: Radius of the heat circle.
|
||||
kernel_size: Kernel size for blurring the heatmap.
|
||||
kernel_size: Kernel size for blurring the heatmap. Pass `None`
|
||||
to disable blurring entirely.
|
||||
top_hue: Hue at the top of the heatmap. Defaults to 0 (red).
|
||||
low_hue: Hue at the bottom of the heatmap. Defaults to 125 (blue).
|
||||
"""
|
||||
@@ -2132,6 +2166,10 @@ class HeatMapAnnotator(BaseAnnotator):
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Note:
|
||||
When `detections` is empty or no heat has accumulated yet, the
|
||||
scene is returned unchanged without raising a ``RuntimeWarning``.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
@@ -2174,7 +2212,9 @@ class HeatMapAnnotator(BaseAnnotator):
|
||||
)
|
||||
self.heat_mask = mask + self.heat_mask
|
||||
temp = self.heat_mask.copy()
|
||||
temp = self.low_hue - temp / temp.max() * (self.low_hue - self.top_hue)
|
||||
max_val = temp.max()
|
||||
if max_val > 0:
|
||||
temp = self.low_hue - temp / max_val * (self.low_hue - self.top_hue)
|
||||
temp = temp.astype(np.uint8)
|
||||
if self.kernel_size is not None:
|
||||
temp = cv2.blur(temp, (self.kernel_size, self.kernel_size))
|
||||
@@ -2633,7 +2673,7 @@ class PercentageBarAnnotator(BaseAnnotator):
|
||||
"""
|
||||
if not isinstance(scene, np.ndarray):
|
||||
return scene
|
||||
self.validate_custom_values(custom_values=custom_values, detections=detections)
|
||||
self._validate_custom_values(custom_values=custom_values, detections=detections)
|
||||
|
||||
anchors = detections.get_anchors_coordinates(anchor=self.position)
|
||||
for detection_idx in range(len(detections)):
|
||||
@@ -2708,7 +2748,7 @@ class PercentageBarAnnotator(BaseAnnotator):
|
||||
return (cx, cy), (cx + width, cy + height)
|
||||
|
||||
@staticmethod
|
||||
def validate_custom_values(
|
||||
def _validate_custom_values(
|
||||
custom_values: npt.NDArray[np.float64] | list[float] | None,
|
||||
detections: Detections,
|
||||
) -> None:
|
||||
@@ -2734,6 +2774,18 @@ class PercentageBarAnnotator(BaseAnnotator):
|
||||
if not all(0 <= value <= 1 for value in custom_values):
|
||||
raise ValueError("All values in custom_values must be between 0 and 1.")
|
||||
|
||||
@staticmethod
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_custom_values.__func__, # type: ignore[attr-defined]
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_custom_values(
|
||||
custom_values: npt.NDArray[np.float64] | list[float] | None,
|
||||
detections: Detections,
|
||||
) -> None:
|
||||
void(custom_values, detections)
|
||||
|
||||
|
||||
class CropAnnotator(BaseAnnotator):
|
||||
"""
|
||||
@@ -3007,7 +3059,7 @@ class ComparisonAnnotator:
|
||||
color_2: Color of areas only present in the second set of
|
||||
detections.
|
||||
color_overlap: Color of areas present in both sets of detections.
|
||||
opacity: Annotator opacity, from `0` to `1`.
|
||||
opacity: Opacity of the overlay mask. Must be between `0` and `1`.
|
||||
label_1: Label for the first set of detections.
|
||||
label_2: Label for the second set of detections.
|
||||
label_overlap: Label for areas present in both sets of detections.
|
||||
|
||||
@@ -7,6 +7,7 @@ from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
from deprecate import deprecated, void
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.core import Detections
|
||||
@@ -201,7 +202,7 @@ def wrap_text(text: Any, max_line_length: int | None = None) -> list[str]:
|
||||
return all_lines or [""]
|
||||
|
||||
|
||||
def validate_labels(labels: list[str] | None, detections: Detections) -> None:
|
||||
def _validate_labels(labels: list[str] | None, detections: Detections) -> None:
|
||||
"""
|
||||
Validates that the number of provided labels matches the number of detections.
|
||||
|
||||
@@ -222,6 +223,15 @@ def validate_labels(labels: list[str] | None, detections: Detections) -> None:
|
||||
)
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_labels,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_labels(labels: list[str] | None, detections: Detections) -> None:
|
||||
void(labels, detections)
|
||||
|
||||
|
||||
def get_labels_text(
|
||||
detections: Detections, custom_labels: list[str] | None
|
||||
) -> list[str]:
|
||||
|
||||
@@ -1,2 +1,13 @@
|
||||
CLASS_NAME_DATA_FIELD: str = "class_name"
|
||||
COCO_RAW_SEGMENTATION: str = "coco_raw_segmentation"
|
||||
#: Key for oriented bounding-box corner coordinates in ``Detections.data``.
|
||||
#:
|
||||
#: Value layout: ``np.ndarray`` of shape ``(N, 4, 2)``, dtype ``float32``, pixel
|
||||
#: coordinates ordered as ``[[x1, y1], [x2, y2], [x3, y3], [x4, y4]]`` per
|
||||
#: detection where the four points are the corners of the oriented box.
|
||||
#: Used by :func:`~supervision.dataset.formats.yolo.detections_to_yolo_annotations`
|
||||
#: (``is_obb=True``) and
|
||||
#: :func:`~supervision.dataset.formats.yolo.yolo_annotations_to_detections`
|
||||
#: (``is_obb=True``).
|
||||
#: Also triggers sequential mode in ``InferenceSlicer`` when present.
|
||||
ORIENTED_BOX_COORDINATES: str = "xyxyxyxy"
|
||||
|
||||
@@ -509,6 +509,7 @@ class DetectionDataset(BaseDataset):
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.0,
|
||||
is_obb: bool = False,
|
||||
) -> None:
|
||||
"""
|
||||
Exports the dataset to YOLO format. This method saves the
|
||||
@@ -537,7 +538,26 @@ class DetectionDataset(BaseDataset):
|
||||
be removed from the input polygon, in the range [0, 1).
|
||||
This is useful for simplifying the annotations.
|
||||
Argument is used only for segmentation datasets.
|
||||
is_obb: If True, exports annotations in OBB format
|
||||
(`class_id x1 y1 x2 y2 x3 y3 x4 y4`) using the oriented
|
||||
corners stored in `detections.data["xyxyxyxy"]`. Mirrors
|
||||
`from_yolo(..., is_obb=True)`. Masks are ignored when
|
||||
`is_obb=True`.
|
||||
"""
|
||||
if is_obb and (
|
||||
min_image_area_percentage != 0.0
|
||||
or max_image_area_percentage != 1.0
|
||||
or approximation_percentage != 0.0
|
||||
):
|
||||
import warnings
|
||||
|
||||
warnings.warn(
|
||||
"`min_image_area_percentage`, `max_image_area_percentage`, and "
|
||||
"`approximation_percentage` have no effect when `is_obb=True`; "
|
||||
"OBB annotations use corner coordinates directly.",
|
||||
UserWarning,
|
||||
stacklevel=2,
|
||||
)
|
||||
if images_directory_path is not None:
|
||||
save_dataset_images(
|
||||
dataset=self, images_directory_path=images_directory_path
|
||||
@@ -549,6 +569,7 @@ class DetectionDataset(BaseDataset):
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
is_obb=is_obb,
|
||||
)
|
||||
if data_yaml_path is not None:
|
||||
save_data_yaml(data_yaml_path=data_yaml_path, classes=self.classes)
|
||||
@@ -609,7 +630,9 @@ class DetectionDataset(BaseDataset):
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.0,
|
||||
) -> None:
|
||||
starting_image_id: int = 1,
|
||||
starting_annotation_id: int = 1,
|
||||
) -> tuple[int, int]:
|
||||
"""
|
||||
Exports the dataset to COCO format. This method saves the
|
||||
images and their corresponding annotations in COCO format.
|
||||
@@ -645,19 +668,59 @@ class DetectionDataset(BaseDataset):
|
||||
to be removed from the input polygon,
|
||||
in the range [0, 1). This is useful for simplifying the annotations.
|
||||
Argument is used only for segmentation datasets.
|
||||
starting_image_id: First image id to assign in the exported file.
|
||||
Defaults to ``1``. Override when exporting multiple splits into
|
||||
a coordinated COCO collection so ids remain unique across the
|
||||
set (see example below).
|
||||
starting_annotation_id: First annotation id to assign in the
|
||||
exported file. Defaults to ``1``. Override for the same
|
||||
multi-split reason as ``starting_image_id``.
|
||||
|
||||
Returns:
|
||||
A ``(next_image_id, next_annotation_id)`` tuple containing the
|
||||
first unused ids after this export. Feed them straight back into
|
||||
``starting_image_id`` and ``starting_annotation_id`` on the next
|
||||
split so ids stay globally unique. When ``annotations_path`` is
|
||||
``None`` (images-only export) the starting ids are returned
|
||||
unchanged so chaining still composes.
|
||||
|
||||
Example:
|
||||
```python
|
||||
# Exporting train, valid, and test splits with non-colliding ids
|
||||
# so the three annotation files can later be merged into one COCO.
|
||||
next_image_id, next_annotation_id = train_ds.as_coco(
|
||||
images_directory_path="out/train/images",
|
||||
annotations_path="out/train/annotations.json",
|
||||
)
|
||||
next_image_id, next_annotation_id = valid_ds.as_coco(
|
||||
images_directory_path="out/valid/images",
|
||||
annotations_path="out/valid/annotations.json",
|
||||
starting_image_id=next_image_id,
|
||||
starting_annotation_id=next_annotation_id,
|
||||
)
|
||||
_, _ = test_ds.as_coco(
|
||||
images_directory_path="out/test/images",
|
||||
annotations_path="out/test/annotations.json",
|
||||
starting_image_id=next_image_id,
|
||||
starting_annotation_id=next_annotation_id,
|
||||
) # return value not needed — no further split
|
||||
```
|
||||
"""
|
||||
if images_directory_path is not None:
|
||||
save_dataset_images(
|
||||
dataset=self, images_directory_path=images_directory_path
|
||||
)
|
||||
if annotations_path is not None:
|
||||
save_coco_annotations(
|
||||
return save_coco_annotations(
|
||||
dataset=self,
|
||||
annotation_path=annotations_path,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
starting_image_id=starting_image_id,
|
||||
starting_annotation_id=starting_annotation_id,
|
||||
)
|
||||
return starting_image_id, starting_annotation_id
|
||||
|
||||
|
||||
@dataclass
|
||||
|
||||
@@ -6,6 +6,7 @@ from typing import TYPE_CHECKING, Any, Union, cast
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.config import COCO_RAW_SEGMENTATION
|
||||
from supervision.dataset.utils import (
|
||||
approximate_mask_with_polygons,
|
||||
map_detections_class_id,
|
||||
@@ -45,13 +46,38 @@ def build_coco_class_index_mapping(
|
||||
|
||||
|
||||
def classes_to_coco_categories(classes: list[str]) -> list[CocoDict]:
|
||||
"""Convert a list of class names to COCO ``categories`` entries.
|
||||
|
||||
Category ids are emitted 1-indexed to comply with the COCO specification
|
||||
and tools such as CVAT, which require ``category_id`` values to start at
|
||||
``1``. The id assigned to the class at position ``class_index`` is
|
||||
``class_index + 1``, keeping it consistent with the ``category_id`` written
|
||||
by [`detections_to_coco_annotations`](#detections_to_coco_annotations).
|
||||
|
||||
Args:
|
||||
classes: Class names ordered by their internal (0-indexed) class id.
|
||||
|
||||
Returns:
|
||||
A list of COCO category dictionaries with 1-indexed ``id`` values.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
from supervision.dataset.formats.coco import classes_to_coco_categories
|
||||
|
||||
classes_to_coco_categories(classes=["cat", "dog"])
|
||||
# [
|
||||
# {"id": 1, "name": "cat", "supercategory": "common-objects"},
|
||||
# {"id": 2, "name": "dog", "supercategory": "common-objects"},
|
||||
# ]
|
||||
```
|
||||
"""
|
||||
return [
|
||||
{
|
||||
"id": class_id,
|
||||
"id": class_index + 1,
|
||||
"name": class_name,
|
||||
"supercategory": "common-objects",
|
||||
}
|
||||
for class_id, class_name in enumerate(classes)
|
||||
for class_index, class_name in enumerate(classes)
|
||||
]
|
||||
|
||||
|
||||
@@ -122,17 +148,43 @@ def coco_annotations_to_detections(
|
||||
with_masks: bool,
|
||||
use_iscrowd: bool = True,
|
||||
) -> Detections:
|
||||
"""Convert COCO annotation dicts for a single image into a `Detections` object.
|
||||
|
||||
.. warning::
|
||||
The returned ``Detections.class_id`` contains **raw COCO** ``category_id``
|
||||
values, not the final 0-indexed internal class ids. Callers **must** pass
|
||||
the result through :func:`map_detections_class_id` with the appropriate
|
||||
``source_to_target_mapping`` (built by
|
||||
:func:`build_coco_class_index_mapping`) before the ``class_id`` values are
|
||||
meaningful. Skipping the remap step yields 1-based ids in a field that the
|
||||
rest of supervision treats as 0-based.
|
||||
|
||||
Args:
|
||||
image_annotations: List of COCO annotation dicts for one image.
|
||||
resolution_wh: ``(width, height)`` of the image, used for mask decoding.
|
||||
with_masks: Whether to decode segmentation fields into binary masks.
|
||||
use_iscrowd: When ``True``, store ``iscrowd`` and ``area`` in
|
||||
``Detections.data``.
|
||||
|
||||
Returns:
|
||||
Detections with ``class_id`` set to raw COCO ``category_id`` values.
|
||||
Call :func:`map_detections_class_id` on the result before use.
|
||||
When ``with_masks=False``, ``detections.data[COCO_RAW_SEGMENTATION]`` is
|
||||
populated as an object array (shape ``(N,)``) holding the raw polygon list or
|
||||
RLE dict per annotation; consumed by :func:`detections_to_coco_annotations`
|
||||
for a coordinate-preserving round-trip.
|
||||
"""
|
||||
if not image_annotations:
|
||||
return Detections.empty()
|
||||
|
||||
class_ids = [
|
||||
image_annotation["category_id"] for image_annotation in image_annotations
|
||||
]
|
||||
xyxy = [image_annotation["bbox"] for image_annotation in image_annotations]
|
||||
xyxy = np.asarray(xyxy, dtype=np.float32)
|
||||
xyxy_list = [image_annotation["bbox"] for image_annotation in image_annotations]
|
||||
xyxy: npt.NDArray[np.float32] = np.asarray(xyxy_list, dtype=np.float32)
|
||||
xyxy[:, 2:4] += xyxy[:, 0:2]
|
||||
|
||||
data: dict[str, npt.NDArray[np.generic]] = {}
|
||||
data: dict[str, Union[npt.NDArray[np.generic], list[Any]]] = {}
|
||||
if use_iscrowd:
|
||||
iscrowd = [
|
||||
image_annotation["iscrowd"] for image_annotation in image_annotations
|
||||
@@ -148,6 +200,14 @@ def coco_annotations_to_detections(
|
||||
)
|
||||
else:
|
||||
mask = None
|
||||
# Preserve raw polygon/RLE data so as_coco() can round-trip without
|
||||
# binary-mask encoding. Stored as an object array (one entry per detection).
|
||||
raw_segs: npt.NDArray[np.object_] = np.empty(
|
||||
len(image_annotations), dtype=object
|
||||
)
|
||||
for k, _ann in enumerate(image_annotations):
|
||||
raw_segs[k] = _ann.get("segmentation", [])
|
||||
data[COCO_RAW_SEGMENTATION] = raw_segs
|
||||
|
||||
return Detections(
|
||||
class_id=np.asarray(class_ids, dtype=int), xyxy=xyxy, mask=mask, data=data
|
||||
@@ -162,6 +222,62 @@ def detections_to_coco_annotations(
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> tuple[list[CocoDict], int]:
|
||||
"""Convert `Detections` to COCO ``annotations`` entries.
|
||||
|
||||
The internal 0-indexed ``Detections.class_id`` is serialized as a 1-indexed
|
||||
COCO ``category_id`` (``category_id = class_id + 1``). This complies with the
|
||||
COCO specification and tools such as CVAT, and stays consistent with the ids
|
||||
emitted by [`classes_to_coco_categories`](#classes_to_coco_categories), so a
|
||||
detection with internal ``class_id=k`` maps to ``category_id=k + 1``.
|
||||
|
||||
Args:
|
||||
detections: The detections to convert. ``class_id`` must not be ``None``.
|
||||
image_id: COCO ``image_id`` shared by every produced annotation.
|
||||
annotation_id: First annotation id to assign; incremented per detection.
|
||||
min_image_area_percentage: Lower bound on detection area / image area,
|
||||
used only when approximating masks with polygons.
|
||||
max_image_area_percentage: Upper bound on detection area / image area,
|
||||
used only when approximating masks with polygons.
|
||||
approximation_percentage: Polygon-simplification ratio in ``[0, 1)``.
|
||||
|
||||
Returns:
|
||||
A ``(coco_annotations, next_annotation_id)`` tuple, where
|
||||
``next_annotation_id`` is one greater than the last id assigned.
|
||||
|
||||
Raises:
|
||||
ValueError: If any detection has ``class_id`` equal to ``None``.
|
||||
|
||||
Note:
|
||||
For ``iscrowd=0`` annotations, ``segmentation`` is a
|
||||
``list[list[float]]`` where each inner list encodes one polygon
|
||||
part as flat ``[x1, y1, x2, y2, ...]`` coordinates. A single
|
||||
object with *N* disjoint parts produces *N* inner lists.
|
||||
|
||||
When ``iscrowd`` is not in ``detections.data``, masks with holes
|
||||
or multiple disjoint segments are auto-encoded as RLE
|
||||
(``iscrowd=1``); simple single-region masks use polygon format
|
||||
(``iscrowd=0``). Supply ``data={"iscrowd": np.array([0])}`` to
|
||||
force polygon output regardless of mask topology.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
from supervision import Detections
|
||||
from supervision.dataset.formats.coco import (
|
||||
detections_to_coco_annotations,
|
||||
)
|
||||
|
||||
detections = Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
)
|
||||
annotations, next_id = detections_to_coco_annotations(
|
||||
detections=detections, image_id=1, annotation_id=1
|
||||
)
|
||||
annotations[0]["category_id"]
|
||||
# 1
|
||||
```
|
||||
"""
|
||||
coco_annotations: list[CocoDict] = []
|
||||
for xyxy, mask, _, class_id, _, data in detections:
|
||||
if class_id is None:
|
||||
@@ -169,21 +285,25 @@ def detections_to_coco_annotations(
|
||||
box_width, box_height = xyxy[2] - xyxy[0], xyxy[3] - xyxy[1]
|
||||
segmentation: Union[list[list[float]], dict[str, list[int]]] = []
|
||||
if mask is not None:
|
||||
mask_bool = cast(npt.NDArray[np.bool_], mask)
|
||||
if "iscrowd" in data:
|
||||
iscrowd = int(np.asarray(data["iscrowd"]).item())
|
||||
else:
|
||||
iscrowd = int(
|
||||
contains_holes(mask=mask) or contains_multiple_segments(mask=mask)
|
||||
contains_holes(mask=mask_bool)
|
||||
or contains_multiple_segments(mask=mask_bool)
|
||||
)
|
||||
|
||||
if iscrowd:
|
||||
segmentation = {
|
||||
"counts": cast(list[int], mask_to_rle(mask=mask, compressed=False)),
|
||||
"counts": cast(
|
||||
list[int], mask_to_rle(mask=mask_bool, compressed=False)
|
||||
),
|
||||
"size": list(mask.shape[:2]),
|
||||
}
|
||||
else:
|
||||
polygons = approximate_mask_with_polygons(
|
||||
mask=mask,
|
||||
mask=mask_bool,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
@@ -191,7 +311,8 @@ def detections_to_coco_annotations(
|
||||
# Small/noisy masks can be filtered out by approximation settings.
|
||||
# Guard against empty output and keep a valid COCO annotation record.
|
||||
if polygons:
|
||||
segmentation = [list(polygons[0].flatten())]
|
||||
# Export ALL polygons so disjoint mask components are preserved.
|
||||
segmentation = [list(p.flatten()) for p in polygons]
|
||||
else:
|
||||
warnings.warn(
|
||||
"Skipping COCO polygon segmentation for annotation "
|
||||
@@ -201,12 +322,28 @@ def detections_to_coco_annotations(
|
||||
)
|
||||
else:
|
||||
iscrowd = int(np.asarray(data.get("iscrowd", 0)).item())
|
||||
# When masks were not decoded during loading, fall back to the raw
|
||||
# polygon/RLE stored in data["segmentation"] for a lossless round-trip.
|
||||
raw_seg = data.get(COCO_RAW_SEGMENTATION)
|
||||
if raw_seg is not None and bool(raw_seg):
|
||||
if isinstance(raw_seg, dict):
|
||||
# RLE format — pass through unchanged
|
||||
segmentation = raw_seg
|
||||
elif (
|
||||
isinstance(raw_seg, list)
|
||||
and raw_seg
|
||||
and not isinstance(raw_seg[0], (list, tuple))
|
||||
):
|
||||
# Flat list shorthand [x1,y1,...] — wrap to list-of-lists
|
||||
segmentation = [list(raw_seg)]
|
||||
else:
|
||||
segmentation = list(raw_seg)
|
||||
|
||||
area: float = float(np.asarray(data.get("area", box_width * box_height)).item())
|
||||
coco_annotation = {
|
||||
"id": annotation_id,
|
||||
"image_id": image_id,
|
||||
"category_id": int(class_id),
|
||||
"category_id": int(class_id) + 1,
|
||||
"bbox": [xyxy[0], xyxy[1], box_width, box_height],
|
||||
"area": area,
|
||||
"segmentation": segmentation,
|
||||
@@ -372,8 +509,68 @@ def save_coco_annotations(
|
||||
annotation_path: str,
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> None:
|
||||
approximation_percentage: float = 0.0,
|
||||
starting_image_id: int = 1,
|
||||
starting_annotation_id: int = 1,
|
||||
) -> tuple[int, int]:
|
||||
"""Save a DetectionDataset to a COCO-format ``annotations.json`` file.
|
||||
|
||||
Args:
|
||||
dataset: The DetectionDataset to write.
|
||||
annotation_path: Output path for the COCO ``annotations.json``.
|
||||
min_image_area_percentage: Lower bound on detection area / image area;
|
||||
used only for segmentation datasets.
|
||||
max_image_area_percentage: Upper bound on detection area / image area;
|
||||
used only for segmentation datasets.
|
||||
approximation_percentage: Polygon-simplification ratio in ``[0, 1)``;
|
||||
used only for segmentation datasets.
|
||||
starting_image_id: First image id to assign in the exported file.
|
||||
Defaults to ``1``. Override when exporting multiple splits into
|
||||
a coordinated COCO collection so ids remain unique across the set.
|
||||
starting_annotation_id: First annotation id to assign in the exported
|
||||
file. Defaults to ``1``. Override for the same multi-split reason
|
||||
as ``starting_image_id``.
|
||||
|
||||
Returns:
|
||||
A ``(next_image_id, next_annotation_id)`` tuple. The returned values
|
||||
are one greater than the highest ids written, so they can be fed
|
||||
directly back into ``starting_image_id`` and ``starting_annotation_id``
|
||||
when exporting another split into a coordinated COCO collection
|
||||
(see ``DetectionDataset.as_coco`` for the chaining pattern). When the
|
||||
dataset is empty the starting ids are returned unchanged.
|
||||
|
||||
.. note::
|
||||
This function ensures globally unique integer ``id`` values across
|
||||
splits. It does **not** ensure unique ``file_name`` values — the
|
||||
``file_name`` field is set to the bare image basename, so splits
|
||||
that share filenames (e.g. ``000001.jpg`` in both train and valid)
|
||||
will have duplicate ``file_name`` values when their COCO files are
|
||||
merged. Use distinct output directories or rename images before
|
||||
merging if downstream tools require unique ``file_name`` keys.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
from supervision.dataset.formats.coco import save_coco_annotations
|
||||
|
||||
ds = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path="train/images",
|
||||
annotations_directory_path="train/labels",
|
||||
data_yaml_path="data.yaml",
|
||||
)
|
||||
next_img_id, next_ann_id = save_coco_annotations(
|
||||
dataset=ds, annotation_path="out/train/annotations.json"
|
||||
)
|
||||
# next_img_id and next_ann_id are the first unused ids — pass them
|
||||
# to the next split to keep ids globally unique across files.
|
||||
```
|
||||
"""
|
||||
if starting_image_id < 1 or starting_annotation_id < 1:
|
||||
raise ValueError(
|
||||
"starting_image_id and starting_annotation_id must be >= 1 "
|
||||
"(COCO spec requires 1-indexed ids); "
|
||||
f"got {starting_image_id=}, {starting_annotation_id=}"
|
||||
)
|
||||
Path(annotation_path).parent.mkdir(parents=True, exist_ok=True)
|
||||
licenses = [
|
||||
{
|
||||
@@ -387,7 +584,7 @@ def save_coco_annotations(
|
||||
coco_images = []
|
||||
coco_categories = classes_to_coco_categories(classes=dataset.classes)
|
||||
|
||||
image_id, annotation_id = 1, 1
|
||||
image_id, annotation_id = starting_image_id, starting_annotation_id
|
||||
for image_path, image, annotation in dataset:
|
||||
image_height, image_width, _ = image.shape
|
||||
image_name = f"{Path(image_path).stem}{Path(image_path).suffix}"
|
||||
@@ -421,3 +618,4 @@ def save_coco_annotations(
|
||||
"annotations": coco_annotations,
|
||||
}
|
||||
save_json_file(annotation_dict, file_path=annotation_path)
|
||||
return image_id, annotation_id
|
||||
|
||||
@@ -21,13 +21,41 @@ def object_to_pascal_voc(
|
||||
name: str,
|
||||
polygon: npt.NDArray[np.number] | None = None,
|
||||
) -> Element:
|
||||
"""Build a Pascal VOC ``<object>`` XML element for one detection.
|
||||
|
||||
Coordinates are converted to 1-indexed Pascal VOC convention before writing.
|
||||
The input arrays are never mutated; new arrays are allocated for the offset.
|
||||
|
||||
Args:
|
||||
xyxy: Bounding box in zero-indexed pixel coordinates ``[x1, y1, x2, y2]``.
|
||||
Shape ``(4,)``.
|
||||
name: Class label string written to the ``<name>`` child element.
|
||||
polygon: Optional segmentation polygon in zero-indexed pixel coordinates.
|
||||
Shape ``(N, 2)``.
|
||||
|
||||
Returns:
|
||||
An XML ``Element`` rooted at ``<object>`` containing ``<name>``,
|
||||
``<bndbox>``, and optionally ``<polygon>`` children.
|
||||
|
||||
Examples:
|
||||
>>> import numpy as np
|
||||
>>> from supervision.dataset.formats.pascal_voc import object_to_pascal_voc
|
||||
>>> elem = object_to_pascal_voc(np.array([0, 0, 9, 9]), name="cat")
|
||||
>>> elem.find("bndbox/xmin").text
|
||||
'1'
|
||||
>>> elem.find("bndbox/xmax").text
|
||||
'10'
|
||||
"""
|
||||
root = Element("object")
|
||||
|
||||
object_name = SubElement(root, "name")
|
||||
object_name.text = name
|
||||
|
||||
# https://github.com/roboflow/supervision/issues/144
|
||||
xyxy += 1
|
||||
# Pascal VOC coordinates are 1-indexed (https://github.com/roboflow/supervision/issues/144).
|
||||
# Rebind to a new array instead of `+= 1`: `xyxy` is a view into the source
|
||||
# `Detections.xyxy` (yielded by `Detections.__iter__`), so an in-place add
|
||||
# would corrupt the caller's detections by +1 on every export.
|
||||
xyxy = xyxy + 1
|
||||
|
||||
bndbox = SubElement(root, "bndbox")
|
||||
xmin = SubElement(bndbox, "xmin")
|
||||
@@ -40,8 +68,8 @@ def object_to_pascal_voc(
|
||||
ymax.text = str(int(xyxy[3]))
|
||||
|
||||
if polygon is not None:
|
||||
# https://github.com/roboflow/supervision/issues/144
|
||||
polygon += 1
|
||||
# 1-indexed, rebound to avoid mutating the caller's array (see above).
|
||||
polygon = polygon + 1
|
||||
object_polygon = SubElement(root, "polygon")
|
||||
for index, point in enumerate(polygon, start=1):
|
||||
x_coordinate, y_coordinate = point
|
||||
@@ -81,6 +109,11 @@ def detections_to_pascal_voc(
|
||||
polygon points to be removed from the input polygon, in the range [0, 1).
|
||||
Returns:
|
||||
An XML string in Pascal VOC format representing the detections.
|
||||
|
||||
Note:
|
||||
``detections`` is never mutated by this function; the source ``xyxy``
|
||||
array is unchanged after the call. The function is therefore safe to
|
||||
call multiple times on the same ``Detections`` object.
|
||||
"""
|
||||
height, width, depth = image_shape
|
||||
|
||||
|
||||
@@ -68,6 +68,25 @@ def _with_seg_mask(lines: list[str]) -> bool:
|
||||
|
||||
|
||||
def _extract_class_names(file_path: str) -> list[str]:
|
||||
"""Return class names from a YOLO data.yaml file ordered by class index.
|
||||
|
||||
Supports list and dict forms of the ``names`` field. Dict keys that are
|
||||
all int-like (plain ints or digit strings) are sorted numerically so
|
||||
class index 10 follows index 9. All-non-numeric keys are sorted
|
||||
lexicographically. Mixed numeric/non-numeric keys raise ``ValueError``.
|
||||
Boolean YAML keys (``true``/``false``) are excluded from numeric sorting
|
||||
because ``bool`` is a subclass of ``int`` in Python.
|
||||
|
||||
Args:
|
||||
file_path: Path to the data.yaml file.
|
||||
|
||||
Returns:
|
||||
Class names in class-index order.
|
||||
|
||||
Raises:
|
||||
ValueError: If the YAML root is not a mapping, if ``names`` is
|
||||
neither a list nor a dict, or if the dict has mixed key types.
|
||||
"""
|
||||
data: dict[str, Any] = read_yaml_file(file_path=file_path)
|
||||
if not isinstance(data, dict):
|
||||
raise ValueError(
|
||||
@@ -76,7 +95,33 @@ def _extract_class_names(file_path: str) -> list[str]:
|
||||
)
|
||||
names = data.get("names")
|
||||
if isinstance(names, dict):
|
||||
return [str(names[key]) for key in sorted(names.keys())]
|
||||
keys = list(names.keys())
|
||||
|
||||
def _is_int_like(key: Any) -> bool:
|
||||
# bool subclasses int; YAML `true`/`false` must not become class indices
|
||||
if isinstance(key, bool):
|
||||
return False
|
||||
if isinstance(key, int):
|
||||
return True
|
||||
if isinstance(key, str):
|
||||
stripped = key.strip()
|
||||
return stripped.isdigit()
|
||||
return False
|
||||
|
||||
int_like = [_is_int_like(k) for k in keys]
|
||||
if any(int_like) and not all(int_like):
|
||||
mixed_numeric = [k for k, il in zip(keys, int_like) if il][:3]
|
||||
mixed_other = [k for k, il in zip(keys, int_like) if not il][:3]
|
||||
raise ValueError(
|
||||
f"Expected 'names' dict in data.yaml at '{file_path}' to have either "
|
||||
f"all numeric or all non-numeric keys, got a mix: "
|
||||
f"numeric {mixed_numeric} and non-numeric {mixed_other} keys."
|
||||
)
|
||||
if all(int_like):
|
||||
sorted_keys = sorted(keys, key=lambda k: int(k))
|
||||
else:
|
||||
sorted_keys = sorted(keys, key=str)
|
||||
return [str(names[key]) for key in sorted_keys]
|
||||
if isinstance(names, list):
|
||||
return [str(name) for name in names]
|
||||
raise ValueError(
|
||||
@@ -254,9 +299,75 @@ def detections_to_yolo_annotations(
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
is_obb: bool = False,
|
||||
) -> list[str]:
|
||||
annotation = []
|
||||
for xyxy, mask, _, class_id, _, _ in detections:
|
||||
"""Convert detections to YOLO annotation lines.
|
||||
|
||||
Args:
|
||||
detections: The detections to serialize. Each detection must have a
|
||||
valid integer ``class_id``. When ``is_obb=True``, each non-empty
|
||||
detection must also carry ``detections.data['xyxyxyxy']`` with
|
||||
shape ``(N, 4, 2)``.
|
||||
image_shape: The ``(height, width, channels)`` shape of the source
|
||||
image, used to normalize coordinates to ``[0, 1]``.
|
||||
min_image_area_percentage: Minimum detection area as a fraction of the
|
||||
image area; smaller detections are omitted. Ignored when
|
||||
``is_obb=True``.
|
||||
max_image_area_percentage: Maximum detection area as a fraction of the
|
||||
image area; larger detections are omitted. Ignored when
|
||||
``is_obb=True``.
|
||||
approximation_percentage: Fraction of polygon points removed during
|
||||
contour approximation when saving mask annotations. Ignored when
|
||||
``is_obb=True``.
|
||||
is_obb: If ``True``, serializes oriented bounding-box corners from
|
||||
``detections.data['xyxyxyxy']`` as a 9-token YOLO OBB line
|
||||
``class_id x1 y1 x2 y2 x3 y3 x4 y4``. Mask data is ignored.
|
||||
|
||||
Returns:
|
||||
A list of YOLO annotation strings, one per detection (or one per
|
||||
polygon for instance-segmentation annotations).
|
||||
|
||||
Raises:
|
||||
ValueError: If any detection has ``class_id=None`` or a non-integer
|
||||
``class_id``.
|
||||
ValueError: If ``is_obb=True`` and any non-empty detection is missing
|
||||
``'xyxyxyxy'`` in ``detections.data``.
|
||||
|
||||
Examples:
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.core import Detections
|
||||
>>> from supervision.dataset.formats.yolo import detections_to_yolo_annotations
|
||||
>>> detections = Detections(
|
||||
... xyxy=np.array([[10, 10, 90, 90]], dtype=np.float32),
|
||||
... class_id=np.array([0]),
|
||||
... )
|
||||
>>> detections_to_yolo_annotations(detections, image_shape=(100, 100, 3))
|
||||
['0 0.50000 0.50000 0.80000 0.80000']
|
||||
"""
|
||||
if (
|
||||
is_obb
|
||||
and len(detections) > 0
|
||||
and ORIENTED_BOX_COORDINATES not in detections.data
|
||||
):
|
||||
raise ValueError(
|
||||
f"`is_obb=True` requires `'{ORIENTED_BOX_COORDINATES}'` in "
|
||||
"`detections.data` with shape (N, 4, 2). Load OBB datasets via "
|
||||
"`DetectionDataset.from_yolo(..., is_obb=True)` or set "
|
||||
f"`detections.data['{ORIENTED_BOX_COORDINATES}']` "
|
||||
"(shape (N, 4, 2)) before exporting."
|
||||
)
|
||||
|
||||
if is_obb and detections.mask is not None:
|
||||
warnings.warn(
|
||||
"`detections.mask` is ignored when `is_obb=True`; "
|
||||
"OBB annotations use corner coordinates from "
|
||||
f"`detections.data['{ORIENTED_BOX_COORDINATES}']`.",
|
||||
UserWarning,
|
||||
stacklevel=2,
|
||||
)
|
||||
|
||||
annotation: list[str] = []
|
||||
for xyxy, mask, _, class_id, _, data in detections:
|
||||
if class_id is None:
|
||||
raise ValueError("Class ID is required for YOLO annotations.")
|
||||
if not isinstance(class_id, (int, np.integer)):
|
||||
@@ -266,6 +377,24 @@ def detections_to_yolo_annotations(
|
||||
)
|
||||
class_id_int = int(class_id)
|
||||
|
||||
if is_obb:
|
||||
corners = np.asarray(data[ORIENTED_BOX_COORDINATES], dtype=np.float32)
|
||||
if corners.shape != (4, 2):
|
||||
raise ValueError(
|
||||
f"OBB data for each detection must have shape (4, 2), "
|
||||
f"got {corners.shape}. Ensure "
|
||||
f"`detections.data['{ORIENTED_BOX_COORDINATES}']` has "
|
||||
"shape (N, 4, 2) before exporting."
|
||||
)
|
||||
next_object = object_to_yolo(
|
||||
xyxy=xyxy,
|
||||
class_id=class_id_int,
|
||||
image_shape=image_shape,
|
||||
polygon=corners,
|
||||
)
|
||||
annotation.append(next_object)
|
||||
continue
|
||||
|
||||
if mask is not None:
|
||||
polygons = approximate_mask_with_polygons(
|
||||
mask=mask,
|
||||
@@ -296,7 +425,34 @@ def save_yolo_annotations(
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
is_obb: bool = False,
|
||||
) -> None:
|
||||
"""Save dataset annotations in YOLO format.
|
||||
|
||||
Args:
|
||||
dataset: The dataset whose annotations are saved.
|
||||
annotations_directory_path: Path to the directory where annotation
|
||||
``.txt`` files are written; created automatically if absent.
|
||||
min_image_area_percentage: Minimum detection area as a fraction of the
|
||||
image area; smaller detections are omitted. Ignored when
|
||||
``is_obb=True``.
|
||||
max_image_area_percentage: Maximum detection area as a fraction of the
|
||||
image area; larger detections are omitted. Ignored when
|
||||
``is_obb=True``.
|
||||
approximation_percentage: Fraction of polygon points removed during
|
||||
contour approximation when saving mask annotations. Ignored when
|
||||
``is_obb=True``.
|
||||
is_obb: If ``True``, writes oriented bounding-box annotations using
|
||||
the 9-token format ``class_id x1 y1 x2 y2 x3 y3 x4 y4``. Each
|
||||
non-empty detection must carry ``detections.data['xyxyxyxy']``
|
||||
with shape ``(N, 4, 2)``.
|
||||
|
||||
Examples:
|
||||
>>> from supervision.dataset.core import DetectionDataset
|
||||
>>> from supervision.dataset.formats.yolo import save_yolo_annotations
|
||||
>>> dataset = DetectionDataset(classes=["cat"], images={}, annotations={})
|
||||
>>> save_yolo_annotations(dataset, "/tmp/labels")
|
||||
"""
|
||||
Path(annotations_directory_path).mkdir(parents=True, exist_ok=True)
|
||||
for image_path, image, annotation in dataset:
|
||||
image_name = Path(image_path).name
|
||||
@@ -310,6 +466,7 @@ def save_yolo_annotations(
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
is_obb=is_obb,
|
||||
)
|
||||
save_text_file(lines=lines, file_path=yolo_annotations_path)
|
||||
|
||||
|
||||
@@ -7,6 +7,7 @@ from typing import Any, cast
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
from deprecate import deprecated, void
|
||||
|
||||
from supervision.config import (
|
||||
CLASS_NAME_DATA_FIELD,
|
||||
@@ -18,6 +19,7 @@ from supervision.detection.tools.transformers import (
|
||||
process_transformers_v4_segmentation_result,
|
||||
process_transformers_v5_segmentation_result,
|
||||
)
|
||||
from supervision.detection.utils.boxes import obb_polygon_area, xyxyxyxy_to_xyxy
|
||||
from supervision.detection.utils.converters import (
|
||||
mask_to_xyxy,
|
||||
polygon_to_mask,
|
||||
@@ -40,11 +42,14 @@ from supervision.detection.utils.iou_and_nms import (
|
||||
mask_iou_batch,
|
||||
mask_non_max_merge,
|
||||
mask_non_max_suppression,
|
||||
oriented_box_non_max_merge,
|
||||
oriented_box_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.utils.masks import calculate_masks_centroids
|
||||
from supervision.detection.vlm import (
|
||||
LMM,
|
||||
VLM,
|
||||
_validate_vlm_parameters,
|
||||
from_deepseek_vl_2,
|
||||
from_florence_2,
|
||||
from_google_gemini_2_0,
|
||||
@@ -53,11 +58,10 @@ from supervision.detection.vlm import (
|
||||
from_paligemma,
|
||||
from_qwen_2_5_vl,
|
||||
from_qwen_3_vl,
|
||||
validate_vlm_parameters,
|
||||
)
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.utils.internal import get_instance_variables, warn_deprecated
|
||||
from supervision.validators import validate_detections_fields, validate_resolution
|
||||
from supervision.validators import _validate_detections_fields, _validate_resolution
|
||||
|
||||
|
||||
@dataclass
|
||||
@@ -158,7 +162,7 @@ class Detections:
|
||||
metadata: dict[str, Any] = field(default_factory=dict)
|
||||
|
||||
def __post_init__(self) -> None:
|
||||
validate_detections_fields(
|
||||
_validate_detections_fields(
|
||||
xyxy=self.xyxy,
|
||||
mask=self.mask,
|
||||
confidence=self.confidence,
|
||||
@@ -324,7 +328,9 @@ class Detections:
|
||||
data={CLASS_NAME_DATA_FIELD: class_names},
|
||||
)
|
||||
|
||||
return cls.empty()
|
||||
empty = cls.empty()
|
||||
empty.data = {CLASS_NAME_DATA_FIELD: np.empty(0, dtype=str)}
|
||||
return empty
|
||||
|
||||
@classmethod
|
||||
def from_yolo_nas(cls, yolo_nas_results: Any) -> Detections:
|
||||
@@ -626,6 +632,10 @@ class Detections:
|
||||
Returns:
|
||||
A Detections object containing the bounding boxes, class IDs,
|
||||
and confidences of the predictions.
|
||||
`detections.data["class_name"]` is always present as a
|
||||
string-dtype NumPy array aligned with the detections; it is
|
||||
empty (shape `(0,)`, dtype str) when `predictions` is empty
|
||||
or absent.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -650,7 +660,7 @@ class Detections:
|
||||
|
||||
if np.asarray(xyxy).shape[0] == 0:
|
||||
empty_detection = cls.empty()
|
||||
empty_detection.data = {CLASS_NAME_DATA_FIELD: np.empty(0)}
|
||||
empty_detection.data = data
|
||||
return empty_detection
|
||||
|
||||
return cls(
|
||||
@@ -756,7 +766,7 @@ class Detections:
|
||||
)
|
||||
```
|
||||
"""
|
||||
width, height = validate_resolution(resolution_wh)
|
||||
width, height = _validate_resolution(resolution_wh)
|
||||
|
||||
masks = []
|
||||
confidences = []
|
||||
@@ -1870,7 +1880,7 @@ class Detections:
|
||||
|
||||
""" # noqa: E501
|
||||
|
||||
vlm = validate_vlm_parameters(vlm, result, kwargs)
|
||||
vlm = _validate_vlm_parameters(vlm, result, kwargs)
|
||||
|
||||
if vlm == VLM.PALIGEMMA:
|
||||
assert isinstance(result, str)
|
||||
@@ -1910,7 +1920,9 @@ class Detections:
|
||||
assert isinstance(result, dict)
|
||||
xyxy, labels, mask, xyxyxyxy = from_florence_2(result, **kwargs)
|
||||
if len(xyxy) == 0:
|
||||
return cls.empty()
|
||||
empty = cls.empty()
|
||||
empty.data = {CLASS_NAME_DATA_FIELD: np.empty(0, dtype=str)}
|
||||
return empty
|
||||
|
||||
data = {}
|
||||
if labels is not None:
|
||||
@@ -2156,7 +2168,7 @@ class Detections:
|
||||
return Detections.empty()
|
||||
|
||||
for detections in detections_list:
|
||||
validate_detections_fields(
|
||||
_validate_detections_fields(
|
||||
xyxy=detections.xyxy,
|
||||
mask=detections.mask,
|
||||
confidence=detections.confidence,
|
||||
@@ -2355,20 +2367,49 @@ class Detections:
|
||||
def area(self) -> npt.NDArray[np.generic]:
|
||||
"""
|
||||
Calculate the area of each detection in the set of object detections.
|
||||
If masks field is defined property returns are of each mask.
|
||||
If only box is given property return area of each box.
|
||||
|
||||
Selection order:
|
||||
|
||||
1. If ``mask`` is set, return the area of each mask.
|
||||
2. Else, if ``data[ORIENTED_BOX_COORDINATES]`` is set, return the area of
|
||||
the rotated body (shoelace formula on the four corners).
|
||||
3. Otherwise, return the axis-aligned box area (``box_area``).
|
||||
|
||||
**OBB dispatch contract**: presence of ``data[ORIENTED_BOX_COORDINATES]``
|
||||
with shape ``(N, 4, 2)`` is the canonical signal that a detection carries
|
||||
oriented bounding box geometry. The same presence-of-key check governs
|
||||
``with_nms``, ``with_nmm``, and this property — always store OBB corners
|
||||
under ``config.ORIENTED_BOX_COORDINATES`` with that shape.
|
||||
|
||||
**Return dtype**: ``float64`` (OBB branch), input dtype (AABB fallback),
|
||||
``int64`` (mask branch).
|
||||
|
||||
Returns:
|
||||
An array of floats containing the area of each detection
|
||||
An array containing the area of each detection
|
||||
in the format of `(area_1, area_2, ..., area_n)`,
|
||||
where n is the number of detections.
|
||||
|
||||
Example:
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> corners = np.array(
|
||||
... [[[0, 5], [5, 10], [10, 5], [5, 0]]], dtype=np.float32
|
||||
... )
|
||||
>>> detections = sv.Detections(
|
||||
... xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
... class_id=np.array([0]),
|
||||
... data={"xyxyxyxy": corners},
|
||||
... )
|
||||
>>> detections.area
|
||||
array([50.])
|
||||
"""
|
||||
if self.mask is not None:
|
||||
if isinstance(self.mask, CompactMask):
|
||||
return self.mask.area
|
||||
return np.array([np.sum(mask) for mask in self.mask])
|
||||
else:
|
||||
return self.box_area
|
||||
if ORIENTED_BOX_COORDINATES in self.data:
|
||||
return obb_polygon_area(self.data[ORIENTED_BOX_COORDINATES])
|
||||
return self.box_area
|
||||
|
||||
@property
|
||||
def box_area(self) -> npt.NDArray[np.generic]:
|
||||
@@ -2426,8 +2467,10 @@ class Detections:
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> Detections:
|
||||
"""
|
||||
Performs non-max suppression on detection set. If the detections result
|
||||
from a segmentation model, the IoU mask is applied. Otherwise, box IoU is used.
|
||||
Performs non-max suppression on detection set. Dispatch order: (1) if mask
|
||||
data present, IoU mask is used; (2) else if oriented-box coordinates
|
||||
(``data[ORIENTED_BOX_COORDINATES]``) present, oriented-box IoU is used; (3)
|
||||
otherwise, axis-aligned box IoU is used.
|
||||
|
||||
Args:
|
||||
threshold: The intersection-over-union threshold
|
||||
@@ -2476,6 +2519,15 @@ class Detections:
|
||||
iou_threshold=threshold,
|
||||
overlap_metric=overlap_metric,
|
||||
)
|
||||
elif ORIENTED_BOX_COORDINATES in self.data:
|
||||
indices = oriented_box_non_max_suppression(
|
||||
predictions=predictions,
|
||||
oriented_boxes=np.asarray(
|
||||
self.data[ORIENTED_BOX_COORDINATES], dtype=np.float32
|
||||
),
|
||||
iou_threshold=threshold,
|
||||
overlap_metric=overlap_metric,
|
||||
)
|
||||
else:
|
||||
indices = box_non_max_suppression(
|
||||
predictions=predictions,
|
||||
@@ -2493,6 +2545,9 @@ class Detections:
|
||||
) -> Detections:
|
||||
"""
|
||||
Perform non-maximum merging on the current set of object detections.
|
||||
Dispatch order: (1) if mask data present, IoU mask is used; (2) else if
|
||||
oriented-box coordinates (``data[ORIENTED_BOX_COORDINATES]``) present,
|
||||
oriented-box IoU is used; (3) otherwise, axis-aligned box IoU is used.
|
||||
|
||||
Args:
|
||||
threshold: The intersection-over-union threshold
|
||||
@@ -2507,6 +2562,17 @@ class Detections:
|
||||
A new Detections object containing the subset of detections
|
||||
after non-maximum merging.
|
||||
|
||||
Note:
|
||||
For detections carrying oriented bounding box data
|
||||
(``data[ORIENTED_BOX_COORDINATES]``), each merge group's output OBB
|
||||
is the tightest rectangle at the winner's orientation enclosing all
|
||||
corners contributed by every detection in the group. The winner is
|
||||
the highest-confidence detection in the group. The axis-aligned
|
||||
``xyxy`` field is updated to the tight bounding box of that rect.
|
||||
For zero-rotation OBBs this equals the axis-aligned union exactly;
|
||||
for rotated OBBs the merged rect inherits the winner's rotation angle.
|
||||
Groups of size 1 keep the original OBB unchanged.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `confidence` is None or `class_id` is None and
|
||||
class_agnostic is False.
|
||||
@@ -2542,6 +2608,15 @@ class Detections:
|
||||
iou_threshold=threshold,
|
||||
overlap_metric=overlap_metric,
|
||||
)
|
||||
elif ORIENTED_BOX_COORDINATES in self.data:
|
||||
merge_groups = oriented_box_non_max_merge(
|
||||
predictions=predictions,
|
||||
oriented_boxes=np.asarray(
|
||||
self.data[ORIENTED_BOX_COORDINATES], dtype=np.float32
|
||||
),
|
||||
iou_threshold=threshold,
|
||||
overlap_metric=overlap_metric,
|
||||
)
|
||||
else:
|
||||
merge_groups = box_non_max_merge(
|
||||
predictions=predictions,
|
||||
@@ -2551,15 +2626,144 @@ class Detections:
|
||||
|
||||
result: list[Detections] = []
|
||||
for merge_group in merge_groups:
|
||||
unmerged_detections = [cast(Detections, self[i]) for i in merge_group]
|
||||
merged_detections = merge_inner_detections_objects_without_iou(
|
||||
unmerged_detections
|
||||
)
|
||||
result.append(merged_detections)
|
||||
group = [cast(Detections, self[i]) for i in merge_group]
|
||||
result.append(_merge_detection_group(group))
|
||||
|
||||
return Detections.merge(result)
|
||||
|
||||
|
||||
def _merge_obb_corners(
|
||||
corners_list: list[npt.NDArray[np.floating]],
|
||||
) -> npt.NDArray[np.floating]:
|
||||
"""Merge multiple OBB corner arrays using winner-angle projection.
|
||||
|
||||
The first entry in *corners_list* is the winner. Its orientation angle
|
||||
(derived from its first edge) defines the local frame in which the
|
||||
tightest enclosing axis-aligned rectangle is computed. That rectangle is
|
||||
then rotated back to produce the merged OBB.
|
||||
|
||||
Args:
|
||||
corners_list: List of (4, 2) corner arrays. First is the winner.
|
||||
|
||||
Returns:
|
||||
Merged OBB corners as a (4, 2) float32 array.
|
||||
"""
|
||||
all_corners = np.concatenate(corners_list, axis=0).astype(np.float32)
|
||||
# Use winner's first edge to derive orientation angle -- avoids
|
||||
# cv2.minAreaRect surprises (e.g. 90-degree flip for wide rects).
|
||||
winner_edge = corners_list[0][1] - corners_list[0][0]
|
||||
angle = float(np.arctan2(winner_edge[1], winner_edge[0]))
|
||||
cos, sin = float(np.cos(angle)), float(np.sin(angle))
|
||||
|
||||
# De-rotate all corners into the winner's local frame
|
||||
to_local = np.array([[cos, -sin], [sin, cos]], dtype=np.float32)
|
||||
local_corners = all_corners @ to_local
|
||||
x_min = float(local_corners[:, 0].min())
|
||||
x_max = float(local_corners[:, 0].max())
|
||||
y_min = float(local_corners[:, 1].min())
|
||||
y_max = float(local_corners[:, 1].max())
|
||||
|
||||
# Rotate the enclosing AABB back to world frame
|
||||
to_world = np.array([[cos, sin], [-sin, cos]], dtype=np.float32)
|
||||
merged: npt.NDArray[np.floating] = (
|
||||
np.array(
|
||||
[[x_min, y_min], [x_max, y_min], [x_max, y_max], [x_min, y_max]],
|
||||
dtype=np.float32,
|
||||
)
|
||||
@ to_world
|
||||
)
|
||||
return merged
|
||||
|
||||
|
||||
def _merge_detection_group(detections: list[Detections]) -> Detections:
|
||||
"""Merge a group of single-object Detections into one merged detection.
|
||||
|
||||
Used internally by :meth:`Detections.with_nmm` to combine each merge group
|
||||
into a single output detection. The highest-confidence detection is the
|
||||
"winner" whose class_id, tracker_id, and data fields are preserved.
|
||||
|
||||
Args:
|
||||
detections: List of Detections, each containing exactly one object.
|
||||
|
||||
Returns:
|
||||
A single merged Detections object of length 1.
|
||||
"""
|
||||
if len(detections) == 1:
|
||||
return detections[0]
|
||||
|
||||
confidences = np.array(
|
||||
[d.confidence[0] if d.confidence is not None else 0.0 for d in detections],
|
||||
dtype=np.float64,
|
||||
)
|
||||
winner_idx = int(np.argmax(confidences))
|
||||
winner = detections[winner_idx]
|
||||
|
||||
# Area-weighted confidence: each box contributes proportionally to its
|
||||
# footprint so large overlapping boxes dominate over small slivers.
|
||||
all_xyxy = np.array([d.xyxy[0] for d in detections], dtype=np.float32)
|
||||
areas = (all_xyxy[:, 2] - all_xyxy[:, 0]) * (all_xyxy[:, 3] - all_xyxy[:, 1])
|
||||
|
||||
if winner.confidence is not None:
|
||||
total_area = float(areas.sum())
|
||||
if total_area > 0:
|
||||
confidence = np.array(
|
||||
[float(np.dot(areas, confidences) / total_area)],
|
||||
dtype=np.float32,
|
||||
)
|
||||
else:
|
||||
confidence = winner.confidence
|
||||
else:
|
||||
confidence = None
|
||||
|
||||
# OBB path: merge corners via winner-angle projection, then derive xyxy
|
||||
# from the merged OBB so both stay consistent.
|
||||
has_obb = ORIENTED_BOX_COORDINATES in winner.data
|
||||
if has_obb:
|
||||
corners_list = []
|
||||
for det in detections:
|
||||
c = np.asarray(det.data[ORIENTED_BOX_COORDINATES])
|
||||
if c.ndim != 3 or c.shape[1:] != (4, 2):
|
||||
raise ValueError(f"corners must have shape (N, 4, 2); got {c.shape}")
|
||||
corners_list.append(c[0].reshape(4, 2))
|
||||
merged_corners = _merge_obb_corners(corners_list)
|
||||
xyxy = xyxyxyxy_to_xyxy(merged_corners[np.newaxis])
|
||||
data = {**winner.data, ORIENTED_BOX_COORDINATES: merged_corners[np.newaxis]}
|
||||
else:
|
||||
# AABB path: union bounding box across all group members
|
||||
xyxy = np.array(
|
||||
[
|
||||
[
|
||||
all_xyxy[:, 0].min(),
|
||||
all_xyxy[:, 1].min(),
|
||||
all_xyxy[:, 2].max(),
|
||||
all_xyxy[:, 3].max(),
|
||||
]
|
||||
],
|
||||
dtype=np.float32,
|
||||
)
|
||||
data = winner.data
|
||||
|
||||
# Mask union via logical OR
|
||||
masks = [d.mask for d in detections if d.mask is not None]
|
||||
if masks:
|
||||
mask = np.logical_or.reduce(np.concatenate(masks, axis=0))[np.newaxis]
|
||||
else:
|
||||
mask = None
|
||||
|
||||
metadata = merge_metadata([d.metadata for d in detections])
|
||||
|
||||
return Detections(
|
||||
xyxy=xyxy,
|
||||
mask=mask,
|
||||
confidence=confidence,
|
||||
class_id=winner.class_id,
|
||||
tracker_id=winner.tracker_id,
|
||||
data=data,
|
||||
metadata=metadata,
|
||||
)
|
||||
|
||||
|
||||
@deprecated(deprecated_in="0.29.0", remove_in="0.32.0") # type: ignore[untyped-decorator]
|
||||
def merge_inner_detection_object_pair(
|
||||
detections_1: Detections, detections_2: Detections
|
||||
) -> Detections:
|
||||
@@ -2606,7 +2810,7 @@ def merge_inner_detection_object_pair(
|
||||
if len(detections_1) != 1 or len(detections_2) != 1:
|
||||
raise ValueError("Both Detections should have exactly 1 detected object.")
|
||||
|
||||
validate_fields_both_defined_or_none(detections_1, detections_2)
|
||||
_validate_fields_both_defined_or_none(detections_1, detections_2)
|
||||
|
||||
xyxy_1 = detections_1.xyxy[0]
|
||||
xyxy_2 = detections_2.xyxy[0]
|
||||
@@ -2652,6 +2856,7 @@ def merge_inner_detection_object_pair(
|
||||
)
|
||||
|
||||
|
||||
@deprecated(deprecated_in="0.29.0", remove_in="0.32.0") # type: ignore[untyped-decorator]
|
||||
def merge_inner_detections_objects(
|
||||
detections: list[Detections],
|
||||
threshold: float = 0.5,
|
||||
@@ -2679,6 +2884,7 @@ def merge_inner_detections_objects(
|
||||
return detections_1
|
||||
|
||||
|
||||
@deprecated(deprecated_in="0.29.0", remove_in="0.32.0") # type: ignore[untyped-decorator]
|
||||
def merge_inner_detections_objects_without_iou(
|
||||
detections: list[Detections],
|
||||
) -> Detections:
|
||||
@@ -2693,7 +2899,7 @@ def merge_inner_detections_objects_without_iou(
|
||||
return reduce(merge_inner_detection_object_pair, detections)
|
||||
|
||||
|
||||
def validate_fields_both_defined_or_none(
|
||||
def _validate_fields_both_defined_or_none(
|
||||
detections_1: Detections, detections_2: Detections
|
||||
) -> None:
|
||||
"""
|
||||
@@ -2715,3 +2921,14 @@ def validate_fields_both_defined_or_none(
|
||||
f"Field '{attribute}' should be consistently None or not None in both "
|
||||
"Detections."
|
||||
)
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_fields_both_defined_or_none,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_fields_both_defined_or_none(
|
||||
detections_1: Detections, detections_2: Detections
|
||||
) -> None:
|
||||
void(detections_1, detections_2)
|
||||
|
||||
@@ -84,6 +84,13 @@ class InferenceSlicer:
|
||||
iou_threshold: IOU threshold used in merging overlap filtering.
|
||||
overlap_metric: Metric to compute overlap (`IOU` or `IOS`).
|
||||
thread_workers: Number of threads for concurrent slice inference.
|
||||
Must be a positive integer. When the first slice returns oriented
|
||||
bounding boxes (OBB), Supervision probes additional slices until a
|
||||
non-empty result is found, then falls back to sequential processing
|
||||
for all remaining slices to avoid thread-safety issues in common OBB
|
||||
inference backends. Note: the first slice always runs synchronously
|
||||
regardless of this setting, so for grids with few slices
|
||||
(e.g. two-slice images) effective parallelism is reduced.
|
||||
compact_masks: If ``True``, dense ``(N, H, W)`` boolean mask
|
||||
arrays returned by the callback are immediately converted to a
|
||||
:class:`~supervision.detection.compact_mask.CompactMask`. This
|
||||
@@ -95,7 +102,8 @@ class InferenceSlicer:
|
||||
Defaults to ``False`` for backward compatibility.
|
||||
|
||||
Raises:
|
||||
ValueError: If `slice_wh` or `overlap_wh` are invalid or inconsistent.
|
||||
ValueError: If `slice_wh`, `overlap_wh`, or `thread_workers` are
|
||||
invalid or inconsistent.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -148,6 +156,12 @@ class InferenceSlicer:
|
||||
|
||||
self._validate_overlap(slice_wh=slice_wh_norm, overlap_wh=overlap_wh_norm)
|
||||
|
||||
if thread_workers < 1:
|
||||
raise ValueError(
|
||||
"`thread_workers` must be a positive integer. "
|
||||
f"Received: {thread_workers}"
|
||||
)
|
||||
|
||||
self.slice_wh = slice_wh_norm
|
||||
self.overlap_wh = overlap_wh_norm
|
||||
self.iou_threshold = iou_threshold
|
||||
@@ -158,11 +172,21 @@ class InferenceSlicer:
|
||||
self.compact_masks = compact_masks
|
||||
self._out_of_slice_bounds_warned: bool = False
|
||||
self._out_of_slice_bounds_lock = threading.Lock()
|
||||
self._obb_thread_workers_warned: bool = False
|
||||
self._obb_thread_workers_lock = threading.Lock()
|
||||
|
||||
def __call__(self, image: ImageType) -> Detections:
|
||||
"""
|
||||
Perform tiled inference on the full image and return merged detections.
|
||||
|
||||
The first slice always runs synchronously so the output type can be
|
||||
inspected before committing to a threading strategy. Detections are
|
||||
merged in a deterministic order: the first slice is always at index 0,
|
||||
followed by any probe slices, then the remaining slices in source order.
|
||||
If oriented bounding boxes are detected, all remaining slices are
|
||||
processed sequentially and a ``SupervisionWarnings`` warning is emitted
|
||||
once per slicer instance.
|
||||
|
||||
Args:
|
||||
image: The full image to run inference on.
|
||||
|
||||
@@ -178,12 +202,55 @@ class InferenceSlicer:
|
||||
overlap_wh=self.overlap_wh,
|
||||
)
|
||||
|
||||
with ThreadPoolExecutor(max_workers=self.thread_workers) as executor:
|
||||
futures = [
|
||||
executor.submit(self._run_callback, image, offset) for offset in offsets
|
||||
]
|
||||
for future in as_completed(futures):
|
||||
detections_list.append(future.result())
|
||||
first_offset = offsets[0]
|
||||
first_detections = self._run_callback(image, first_offset)
|
||||
detections_list.append(first_detections)
|
||||
|
||||
remaining_offsets = offsets[1:]
|
||||
obb_detected = ORIENTED_BOX_COORDINATES in first_detections.data
|
||||
should_run_sequentially = self.thread_workers <= 1 or obb_detected
|
||||
|
||||
probe_index = 0
|
||||
if not should_run_sequentially and len(first_detections) == 0:
|
||||
while probe_index < len(remaining_offsets):
|
||||
probe_offset = remaining_offsets[probe_index]
|
||||
probe_detections = self._run_callback(image, probe_offset)
|
||||
detections_list.append(probe_detections)
|
||||
probe_index += 1
|
||||
|
||||
if ORIENTED_BOX_COORDINATES in probe_detections.data:
|
||||
obb_detected = True
|
||||
should_run_sequentially = True
|
||||
break
|
||||
|
||||
if len(probe_detections) > 0:
|
||||
break
|
||||
|
||||
remaining_offsets = remaining_offsets[probe_index:]
|
||||
|
||||
if should_run_sequentially:
|
||||
if self.thread_workers > 1 and obb_detected:
|
||||
with self._obb_thread_workers_lock:
|
||||
if not self._obb_thread_workers_warned:
|
||||
self._obb_thread_workers_warned = True
|
||||
warnings.warn(
|
||||
"InferenceSlicer detected oriented bounding boxes while "
|
||||
"`thread_workers > 1`. Remaining slices will be processed "
|
||||
"sequentially because many OBB inference backends are not "
|
||||
"thread-safe and can crash when shared across threads.",
|
||||
category=SupervisionWarnings,
|
||||
stacklevel=2,
|
||||
)
|
||||
for offset in remaining_offsets:
|
||||
detections_list.append(self._run_callback(image, offset))
|
||||
else:
|
||||
with ThreadPoolExecutor(max_workers=self.thread_workers) as executor:
|
||||
futures = [
|
||||
executor.submit(self._run_callback, image, offset)
|
||||
for offset in remaining_offsets
|
||||
]
|
||||
for future in as_completed(futures):
|
||||
detections_list.append(future.result())
|
||||
|
||||
merged = Detections.merge(detections_list=detections_list)
|
||||
if self.overlap_filter == OverlapFilter.NONE:
|
||||
|
||||
@@ -24,6 +24,8 @@ class JSONSink:
|
||||
When a list or tuple value in custom_data (or detections.data) has the
|
||||
same length as the detection count, each element is written to the
|
||||
corresponding detection row; any other value is broadcast to all rows.
|
||||
NumPy scalars (e.g. ``np.int64``, ``np.float32``) are serialized as
|
||||
JSON numbers; NumPy arrays are serialized as JSON arrays.
|
||||
|
||||
Args:
|
||||
file_name: The name of the JSON file where the detections will be stored.
|
||||
@@ -79,13 +81,42 @@ class JSONSink:
|
||||
|
||||
self.file = open(self.file_name, "w")
|
||||
|
||||
@staticmethod
|
||||
def _json_default(value: Any) -> Any:
|
||||
"""Return a JSON-serializable equivalent of a NumPy scalar or array.
|
||||
|
||||
Called as the ``default`` hook by :func:`json.dump`. Converts
|
||||
:class:`numpy.generic` scalars via ``.item()`` and
|
||||
:class:`numpy.ndarray` instances via ``.tolist()``.
|
||||
|
||||
Args:
|
||||
value: Object the standard JSON encoder could not serialize.
|
||||
|
||||
Returns:
|
||||
A Python scalar or nested list equivalent of ``value``.
|
||||
|
||||
Raises:
|
||||
TypeError: If ``value`` is neither a NumPy scalar nor an ndarray.
|
||||
"""
|
||||
if isinstance(value, np.generic):
|
||||
return value.item()
|
||||
if isinstance(value, np.ndarray):
|
||||
return value.tolist()
|
||||
raise TypeError(
|
||||
f"Object of type {type(value).__name__} is not JSON serializable"
|
||||
)
|
||||
|
||||
def write_and_close(self) -> None:
|
||||
"""
|
||||
Write and close the JSON file.
|
||||
"""
|
||||
if self.file:
|
||||
json.dump(self.data, self.file, indent=4)
|
||||
self.file.close()
|
||||
try:
|
||||
json.dump(
|
||||
self.data, self.file, indent=4, default=JSONSink._json_default
|
||||
)
|
||||
finally:
|
||||
self.file.close()
|
||||
|
||||
@staticmethod
|
||||
def _slice_value(value: Any, i: int, n: int) -> Any:
|
||||
|
||||
@@ -36,25 +36,20 @@ class PolygonZone:
|
||||
mask: The 2D bool mask for the polygon zone
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
import numpy as np
|
||||
import cv2
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> polygon = np.array([[100, 200], [200, 100], [300, 200], [200, 300]])
|
||||
>>> polygon_zone = sv.PolygonZone(polygon=polygon)
|
||||
>>> detections = sv.Detections(
|
||||
... xyxy=np.array([[180, 100, 220, 200], [400, 400, 450, 500]])
|
||||
... )
|
||||
>>> is_detections_in_zone = polygon_zone.trigger(detections)
|
||||
>>> is_detections_in_zone
|
||||
array([ True, False])
|
||||
>>> polygon_zone.current_count
|
||||
1
|
||||
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
model = YOLO("yolo11s")
|
||||
tracker = sv.ByteTrack()
|
||||
|
||||
polygon = np.array([[100, 200], [200, 100], [300, 200], [200, 300]])
|
||||
polygon_zone = sv.PolygonZone(polygon=polygon)
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
is_detections_in_zone = polygon_zone.trigger(detections)
|
||||
print(polygon_zone.current_count)
|
||||
```
|
||||
"""
|
||||
|
||||
|
||||
@@ -29,6 +29,9 @@ class DetectionsSmoother:
|
||||
[Roboflow Trackers](/latest/trackers/) for
|
||||
information on integrating tracking into your inference pipeline.
|
||||
- This class is not compatible with segmentation models.
|
||||
- When detections in a frame disagree on confidence presence — some tracks
|
||||
carry confidence scores and others do not — `confidence` is set to `None`
|
||||
for all smoothed detections in that frame.
|
||||
|
||||
Example:
|
||||
```pycon
|
||||
@@ -128,6 +131,20 @@ class DetectionsSmoother:
|
||||
return self.get_smoothed_detections()
|
||||
|
||||
def get_track(self, track_id: int) -> Detections | None:
|
||||
"""Return the smoothed `Detections` for a single track.
|
||||
|
||||
Averages `xyxy` over all valid (non-`None`) frames in the track window.
|
||||
`confidence` is averaged only over frames that carry it; frames with
|
||||
`confidence=None` are excluded. Returns `None` when the track is unknown
|
||||
or its entire window is empty.
|
||||
|
||||
Args:
|
||||
track_id: The tracker ID whose smoothed detection to retrieve.
|
||||
|
||||
Returns:
|
||||
Smoothed `Detections` for the track, or `None` if the track is
|
||||
unknown or all frames in its window are empty.
|
||||
"""
|
||||
track = self.tracks.get(track_id, None)
|
||||
if track is None:
|
||||
return None
|
||||
@@ -138,7 +155,11 @@ class DetectionsSmoother:
|
||||
|
||||
ret = deepcopy(valid[0])
|
||||
ret.xyxy = np.mean([d.xyxy for d in valid], axis=0)
|
||||
ret.confidence = np.mean([d.confidence for d in valid], axis=0)
|
||||
# Average confidence only over frames that carry it; frames with
|
||||
# confidence=None contribute nothing to the mean. Retain None when
|
||||
# no frame in the window carries confidence.
|
||||
confidences = [d.confidence for d in valid if d.confidence is not None]
|
||||
ret.confidence = np.mean(np.array(confidences), axis=0) if confidences else None
|
||||
|
||||
return ret
|
||||
|
||||
@@ -149,6 +170,13 @@ class DetectionsSmoother:
|
||||
if track is not None:
|
||||
tracked_detections.append(track)
|
||||
|
||||
# Detections.merge requires all-or-none for optional fields.
|
||||
# When tracks disagree on confidence presence, drop it from all to
|
||||
# prevent ValueError inside Detections.merge (stack_or_none invariant).
|
||||
if tracked_detections and any(d.confidence is None for d in tracked_detections):
|
||||
for d in tracked_detections:
|
||||
d.confidence = None
|
||||
|
||||
detections = Detections.merge(tracked_detections)
|
||||
if len(detections) == 0:
|
||||
detections.tracker_id = np.array([], dtype=int)
|
||||
|
||||
@@ -2,6 +2,7 @@ from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
from deprecate import TargetMode, deprecated
|
||||
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch
|
||||
|
||||
@@ -95,10 +96,17 @@ def pad_boxes(
|
||||
return result
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=TargetMode.ARGS_REMAP,
|
||||
deprecated_in="0.27.0",
|
||||
remove_in="0.30.0",
|
||||
args_mapping={"normalized_xyxy": "xyxy"},
|
||||
)
|
||||
def denormalize_boxes(
|
||||
xyxy: npt.NDArray[np.number],
|
||||
resolution_wh: tuple[int, int],
|
||||
normalization_factor: float = 1.0,
|
||||
normalized_xyxy: npt.NDArray[np.number] | None = None,
|
||||
) -> npt.NDArray[np.number]:
|
||||
"""
|
||||
Convert normalized bounding box coordinates to absolute pixel coordinates.
|
||||
@@ -233,6 +241,74 @@ def move_oriented_boxes(
|
||||
return xyxyxyxy + offset
|
||||
|
||||
|
||||
def obb_polygon_area(corners: npt.NDArray) -> npt.NDArray[np.float64]:
|
||||
"""Compute the area of N oriented bounding boxes using the shoelace formula.
|
||||
|
||||
Args:
|
||||
corners: OBB corner coordinates with shape `(N, 4, 2)`.
|
||||
|
||||
Returns:
|
||||
Area of each box as a 1-D float64 array of shape `(N,)`.
|
||||
|
||||
Raises:
|
||||
ValueError: If `corners` does not have shape `(N, 4, 2)`.
|
||||
|
||||
Examples:
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.utils.boxes import obb_polygon_area
|
||||
>>> corners = np.array([[[0, 5], [5, 10], [10, 5], [5, 0]]], dtype=np.float32)
|
||||
>>> obb_polygon_area(corners)
|
||||
array([50.])
|
||||
"""
|
||||
corners = np.asarray(corners)
|
||||
if corners.ndim != 3 or corners.shape[-2:] != (4, 2):
|
||||
raise ValueError(f"corners must have shape (N, 4, 2); got {corners.shape}")
|
||||
x = corners[..., 0].astype(np.float64, copy=False)
|
||||
y = corners[..., 1].astype(np.float64, copy=False)
|
||||
cross = x * np.roll(y, -1, axis=-1) - y * np.roll(x, -1, axis=-1)
|
||||
return 0.5 * np.abs(np.sum(cross, axis=-1))
|
||||
|
||||
|
||||
def xyxyxyxy_to_xyxy(
|
||||
xyxyxyxy: npt.NDArray[np.number],
|
||||
) -> npt.NDArray[np.number]:
|
||||
"""Convert oriented bounding box corners to axis-aligned bounding boxes.
|
||||
|
||||
Args:
|
||||
xyxyxyxy: OBB corner coordinates with shape `(N, 4, 2)` where each
|
||||
box is represented as `[[x1, y1], [x2, y2], [x3, y3], [x4, y4]]`.
|
||||
|
||||
Returns:
|
||||
Axis-aligned bounding boxes as an array of shape `(N, 4)`
|
||||
in `(x_min, y_min, x_max, y_max)` format.
|
||||
|
||||
Raises:
|
||||
ValueError: If `xyxyxyxy` does not have shape `(N, 4, 2)`.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> corners = np.array([
|
||||
... [[0, 0], [10, 0], [10, 5], [0, 5]],
|
||||
... [[5, 5], [15, 5], [15, 10], [5, 10]],
|
||||
... ], dtype=np.float32)
|
||||
>>> sv.xyxyxyxy_to_xyxy(corners)
|
||||
array([[ 0., 0., 10., 5.],
|
||||
[ 5., 5., 15., 10.]], dtype=float32)
|
||||
|
||||
```
|
||||
"""
|
||||
xyxyxyxy = np.asarray(xyxyxyxy)
|
||||
if xyxyxyxy.ndim != 3 or xyxyxyxy.shape[-2:] != (4, 2):
|
||||
raise ValueError(f"xyxyxyxy must have shape (N, 4, 2); got {xyxyxyxy.shape}")
|
||||
x_min = xyxyxyxy[..., 0].min(axis=-1)
|
||||
y_min = xyxyxyxy[..., 1].min(axis=-1)
|
||||
x_max = xyxyxyxy[..., 0].max(axis=-1)
|
||||
y_max = xyxyxyxy[..., 1].max(axis=-1)
|
||||
return np.stack([x_min, y_min, x_max, y_max], axis=-1)
|
||||
|
||||
|
||||
def scale_boxes(
|
||||
xyxy: npt.NDArray[np.float64], factor: float
|
||||
) -> npt.NDArray[np.float64]:
|
||||
|
||||
@@ -204,23 +204,44 @@ def mask_to_xyxy(masks: npt.NDArray[np.bool_]) -> npt.NDArray[np.int_]:
|
||||
Converts a 3D `np.array` of 2D bool masks into a 2D `np.array` of bounding boxes.
|
||||
|
||||
Args:
|
||||
masks: A 3D `np.array` of shape `(N, W, H)` containing 2D bool masks.
|
||||
masks: A 3D `np.array` of shape `(N, H, W)` containing 2D bool masks.
|
||||
|
||||
Returns:
|
||||
A 2D `np.array` of shape `(N, 4)` containing the bounding boxes
|
||||
`(x_min, y_min, x_max, y_max)` for each mask.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> masks = np.array([
|
||||
... [[False, False, False],
|
||||
... [False, True, True],
|
||||
... [False, True, True]],
|
||||
... ])
|
||||
>>> sv.mask_to_xyxy(masks)
|
||||
array([[1, 1, 2, 2]])
|
||||
|
||||
```
|
||||
"""
|
||||
n = masks.shape[0]
|
||||
xyxy = np.zeros((n, 4), dtype=int)
|
||||
n, height, width = masks.shape
|
||||
if masks.size == 0:
|
||||
return np.zeros((n, 4), dtype=int)
|
||||
|
||||
for i, mask in enumerate(masks):
|
||||
rows, cols = np.where(mask)
|
||||
# Reduce the mask stack to per-row / per-column occupancy, then read the
|
||||
# tight bounds straight off those 1D profiles instead of scanning every
|
||||
# pixel of every mask with `np.where`.
|
||||
rows_any = cast(npt.NDArray[np.bool_], masks.any(axis=2)) # (N, H)
|
||||
cols_any = cast(npt.NDArray[np.bool_], masks.any(axis=1)) # (N, W)
|
||||
|
||||
if len(rows) > 0 and len(cols) > 0:
|
||||
x_min, x_max = int(np.min(cols)), int(np.max(cols))
|
||||
y_min, y_max = int(np.min(rows)), int(np.max(rows))
|
||||
xyxy[i, :] = [x_min, y_min, x_max, y_max]
|
||||
x_min = cols_any.argmax(axis=1)
|
||||
x_max = width - 1 - cols_any[:, ::-1].argmax(axis=1)
|
||||
y_min = rows_any.argmax(axis=1)
|
||||
y_max = height - 1 - rows_any[:, ::-1].argmax(axis=1)
|
||||
|
||||
xyxy = np.stack((x_min, y_min, x_max, y_max), axis=1).astype(int)
|
||||
# Empty masks have no bounds; keep the original all-zeros box for them.
|
||||
xyxy[~rows_any.any(axis=1)] = 0
|
||||
return xyxy
|
||||
|
||||
|
||||
|
||||
@@ -2,7 +2,7 @@ from __future__ import annotations
|
||||
|
||||
import logging
|
||||
from itertools import chain
|
||||
from typing import Any, cast
|
||||
from typing import Any, Union, cast
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -61,6 +61,29 @@ def process_roboflow_result(
|
||||
npt.NDArray[np.integer] | None,
|
||||
dict[str, npt.NDArray[np.generic]],
|
||||
]:
|
||||
"""Parse a Roboflow API or Inference package result into detection arrays.
|
||||
|
||||
The returned ``data`` dict always contains ``CLASS_NAME_DATA_FIELD`` as a
|
||||
string-dtype NumPy array. When ``predictions`` is empty, the array has
|
||||
shape ``(0,)`` with ``dtype=str``, preserving dtype contracts for callers
|
||||
that mix empty and non-empty results.
|
||||
|
||||
Args:
|
||||
roboflow_result: Raw dict from the Roboflow REST API or the Inference
|
||||
package (after ``.dict()`` serialisation).
|
||||
|
||||
Returns:
|
||||
A 6-tuple of ``(xyxy, confidence, class_id, masks, tracker_ids, data)``
|
||||
where each array is aligned with the others. ``masks`` and
|
||||
``tracker_ids`` are ``None`` when absent from the predictions.
|
||||
|
||||
Examples:
|
||||
>>> from supervision.detection.utils.internal import process_roboflow_result
|
||||
>>> result = {"predictions": [], "image": {"width": 100, "height": 100}}
|
||||
>>> _, _, _, _, _, data = process_roboflow_result(result)
|
||||
>>> data["class_name"].dtype.kind
|
||||
'U'
|
||||
"""
|
||||
if not roboflow_result["predictions"]:
|
||||
return (
|
||||
np.empty((0, 4), dtype=np.float64),
|
||||
@@ -133,12 +156,14 @@ def process_roboflow_result(
|
||||
polygon = np.array(
|
||||
[[point["x"], point["y"]] for point in prediction["points"]], dtype=int
|
||||
)
|
||||
mask = polygon_to_mask(polygon, resolution_wh=(image_width, image_height))
|
||||
mask = polygon_to_mask(
|
||||
polygon, resolution_wh=(image_width, image_height)
|
||||
).astype(bool)
|
||||
xyxy.append([x_min, y_min, x_max, y_max])
|
||||
class_id.append(prediction["class_id"])
|
||||
class_name.append(prediction["class"])
|
||||
confidence.append(prediction["confidence"])
|
||||
masks.append(mask.astype(bool))
|
||||
masks.append(mask)
|
||||
if "tracker_id" in prediction:
|
||||
tracker_ids.append(prediction["tracker_id"])
|
||||
|
||||
@@ -175,8 +200,8 @@ def process_roboflow_result(
|
||||
|
||||
|
||||
def is_data_equal(
|
||||
data_a: dict[str, npt.NDArray[np.generic]],
|
||||
data_b: dict[str, npt.NDArray[np.generic]],
|
||||
data_a: dict[str, npt.NDArray[np.generic] | list[Any]],
|
||||
data_b: dict[str, npt.NDArray[np.generic] | list[Any]],
|
||||
) -> bool:
|
||||
"""
|
||||
Compares the data payloads of two Detections instances.
|
||||
@@ -249,7 +274,7 @@ def merge_data(
|
||||
"All data values within a single object must have equal length."
|
||||
)
|
||||
|
||||
merged_data: dict[str, list[Any]] = {key: [] for key in all_keys_sets[0]}
|
||||
merged_data: dict[str, Any] = {key: [] for key in all_keys_sets[0]}
|
||||
for data in data_list:
|
||||
for key in data:
|
||||
merged_data[key].append(data[key])
|
||||
@@ -271,7 +296,7 @@ def merge_data(
|
||||
f"types are allowed."
|
||||
)
|
||||
|
||||
return merged_data
|
||||
return cast(dict[str, Union[npt.NDArray[np.generic], list[Any]]], merged_data)
|
||||
|
||||
|
||||
def merge_metadata(metadata_list: list[dict[str, Any]]) -> dict[str, Any]:
|
||||
|
||||
@@ -1,13 +1,15 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import warnings
|
||||
from collections.abc import Callable
|
||||
from enum import Enum
|
||||
from typing import Any, cast
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.compact_mask import CompactMask
|
||||
from supervision.detection.utils.converters import polygon_to_mask
|
||||
from supervision.detection.utils.masks import resize_masks
|
||||
|
||||
|
||||
@@ -358,47 +360,210 @@ def box_iou_batch_with_jaccard(
|
||||
return ious
|
||||
|
||||
|
||||
def _polygon_areas(polygons: npt.NDArray[np.floating]) -> npt.NDArray[np.floating]:
|
||||
"""Compute the area of each oriented-box polygon using the shoelace formula.
|
||||
|
||||
Args:
|
||||
polygons: ``(N, 4, 2)`` array of polygon corners.
|
||||
|
||||
Returns:
|
||||
``(N,)`` array of polygon areas.
|
||||
"""
|
||||
x = polygons[:, :, 0]
|
||||
y = polygons[:, :, 1]
|
||||
cross = x * np.roll(y, -1, axis=1) - np.roll(x, -1, axis=1) * y
|
||||
return cast(npt.NDArray[np.floating], 0.5 * np.abs(cross.sum(axis=1)))
|
||||
|
||||
|
||||
def _aabb_envelopes(polygons: npt.NDArray[np.floating]) -> npt.NDArray[np.floating]:
|
||||
"""Compute the axis-aligned bounding envelope of each oriented box.
|
||||
|
||||
Args:
|
||||
polygons: ``(N, 4, 2)`` array of polygon corners.
|
||||
|
||||
Returns:
|
||||
``(N, 4)`` array of ``(x_min, y_min, x_max, y_max)`` envelopes.
|
||||
"""
|
||||
xs = polygons[:, :, 0]
|
||||
ys = polygons[:, :, 1]
|
||||
return np.stack(
|
||||
[xs.min(axis=1), ys.min(axis=1), xs.max(axis=1), ys.max(axis=1)], axis=1
|
||||
)
|
||||
|
||||
|
||||
def _overlapping_envelope_pairs(
|
||||
envelopes_true: npt.NDArray[np.floating],
|
||||
envelopes_detection: npt.NDArray[np.floating],
|
||||
) -> tuple[npt.NDArray[np.intp], npt.NDArray[np.intp]]:
|
||||
"""Return index pairs ``(i, j)`` whose axis-aligned envelopes overlap.
|
||||
|
||||
Uses a fused boolean evaluation to halve peak transient memory compared to
|
||||
named-intermediate form (4 separate NxM float64 arrays vs 1 boolean array).
|
||||
|
||||
Note:
|
||||
This gate is a correctness guarantee, not an approximation: if two
|
||||
axis-aligned bounding boxes do not overlap, the convex polygons they
|
||||
contain cannot overlap either.
|
||||
|
||||
Args:
|
||||
envelopes_true: ``(N, 4)`` array of ``(x_min, y_min, x_max, y_max)``
|
||||
envelopes for the ground-truth boxes.
|
||||
envelopes_detection: ``(M, 4)`` array of ``(x_min, y_min, x_max, y_max)``
|
||||
envelopes for the detection boxes.
|
||||
|
||||
Returns:
|
||||
A pair of 1-D index arrays ``(rows, cols)`` identifying the overlapping
|
||||
pairs.
|
||||
"""
|
||||
et = envelopes_true[:, None, :]
|
||||
ed = envelopes_detection[None, :, :]
|
||||
overlap = (
|
||||
np.minimum(et[..., 2], ed[..., 2]) > np.maximum(et[..., 0], ed[..., 0])
|
||||
) & (np.minimum(et[..., 3], ed[..., 3]) > np.maximum(et[..., 1], ed[..., 1]))
|
||||
return cast(tuple[npt.NDArray[np.intp], npt.NDArray[np.intp]], np.nonzero(overlap))
|
||||
|
||||
|
||||
def oriented_box_iou_batch(
|
||||
boxes_true: npt.NDArray[np.number], boxes_detection: npt.NDArray[np.number]
|
||||
boxes_true: npt.NDArray[np.number],
|
||||
boxes_detection: npt.NDArray[np.number],
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> npt.NDArray[np.floating]:
|
||||
"""
|
||||
Compute Intersection over Union (IoU) of two sets of oriented bounding boxes -
|
||||
`boxes_true` and `boxes_detection`. Both sets of boxes are expected to be in
|
||||
Compute pairwise overlap scores between two sets of oriented bounding boxes
|
||||
using the configured `overlap_metric`.
|
||||
|
||||
Overlap areas are computed exactly via convex-polygon intersection, gated by
|
||||
a cheap axis-aligned envelope pre-filter — no rasterization is involved, so
|
||||
the result is exact (free of pixel-quantization error) and independent of the
|
||||
coordinate magnitudes.
|
||||
|
||||
`boxes_true` and `boxes_detection` are expected to be in
|
||||
`((x1, y1), (x2, y2), (x3, y3), (x4, y4))` format.
|
||||
|
||||
Note:
|
||||
Inputs must be **convex** quads with finite coordinates. Self-intersecting
|
||||
or non-convex polygons produce undefined results via
|
||||
``cv2.intersectConvexConvex``. NaN or Inf coordinates propagate silently
|
||||
as ``0.0`` — validate inputs before calling if needed.
|
||||
|
||||
When ``boxes_true is boxes_detection`` (the same Python object, not just
|
||||
equal values), the function computes only the upper triangle of the
|
||||
matrix and mirrors it. This optimization is used automatically by the
|
||||
NMS/NMM callers that pass the same array twice. A defensive ``.copy()``
|
||||
at the call site would disable the optimization silently — see the
|
||||
NMS caller comment for context.
|
||||
|
||||
Args:
|
||||
boxes_true: A `np.ndarray` representing ground-truth boxes.
|
||||
`shape = (N, 4, 2)` where `N` is number of true objects.
|
||||
Last axis convention: `[..., 0]` = x-coordinates,
|
||||
`[..., 1]` = y-coordinates.
|
||||
boxes_detection: A `np.ndarray` representing detection boxes.
|
||||
`shape = (M, 4, 2)` where `M` is number of detected objects.
|
||||
Last axis convention: `[..., 0]` = x-coordinates,
|
||||
`[..., 1]` = y-coordinates.
|
||||
overlap_metric: Metric used to compute the degree of overlap
|
||||
between pairs of oriented boxes (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
Pairwise IoU of boxes from `boxes_true` and `boxes_detection`.
|
||||
`shape = (N, M)` where `N` is number of true objects and
|
||||
`M` is number of detected objects.
|
||||
Overlap matrix of shape `(N, M)`, where entry `[i, j]` is the overlap
|
||||
score between `boxes_true[i]` and `boxes_detection[j]`, in the range
|
||||
`[0, 1]` under the configured :attr:`overlap_metric`.
|
||||
|
||||
Raises:
|
||||
ValueError: If ``boxes_true`` or ``boxes_detection`` is 3-D with inner
|
||||
dimensions other than ``(4, 2)``.
|
||||
ValueError: If ``boxes_true`` or ``boxes_detection`` is 2-D with a
|
||||
column count other than 8.
|
||||
ValueError: If ``boxes_true`` or ``boxes_detection`` is not 2-D or 3-D.
|
||||
ValueError: If ``overlap_metric`` is not
|
||||
:attr:`~supervision.config.OverlapMetric.IOU` or
|
||||
:attr:`~supervision.config.OverlapMetric.IOS`.
|
||||
|
||||
Examples:
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> a = np.array([[[0, 0], [2, 0], [2, 2], [0, 2]]], dtype=np.float32)
|
||||
>>> b = np.array([[[1, 0], [3, 0], [3, 2], [1, 2]]], dtype=np.float32)
|
||||
>>> sv.oriented_box_iou_batch(a, b) # doctest: +ELLIPSIS
|
||||
array([[0.333...]])
|
||||
"""
|
||||
|
||||
boxes_true = boxes_true.reshape(-1, 4, 2)
|
||||
boxes_detection = boxes_detection.reshape(-1, 4, 2)
|
||||
for name, arr in (("boxes_true", boxes_true), ("boxes_detection", boxes_detection)):
|
||||
if arr.ndim == 3 and arr.shape[1:] != (4, 2):
|
||||
raise ValueError(
|
||||
f"`{name}` has shape {arr.shape}; expected (N, 4, 2) "
|
||||
f"— each box must have exactly 4 corners with (x, y) coordinates."
|
||||
)
|
||||
elif arr.ndim == 2 and arr.shape[1] != 8:
|
||||
raise ValueError(
|
||||
f"`{name}` has shape {arr.shape}; expected (N, 8) for flat "
|
||||
f"YOLO format or (N, 4, 2) for corner format."
|
||||
)
|
||||
elif arr.ndim not in (2, 3):
|
||||
raise ValueError(
|
||||
f"`{name}` must be 2-D (N, 8) or 3-D (N, 4, 2), got shape {arr.shape}."
|
||||
)
|
||||
|
||||
max_height = int(max(boxes_true[:, :, 0].max(), boxes_detection[:, :, 0].max()) + 1)
|
||||
# adding 1 because we are 0-indexed
|
||||
max_width = int(max(boxes_true[:, :, 1].max(), boxes_detection[:, :, 1].max()) + 1)
|
||||
|
||||
mask_true = np.zeros((boxes_true.shape[0], max_height, max_width), dtype=np.uint8)
|
||||
for box_idx, box_true in enumerate(boxes_true):
|
||||
mask_true[box_idx] = polygon_to_mask(box_true, (max_width, max_height))
|
||||
|
||||
mask_detection = np.zeros(
|
||||
(boxes_detection.shape[0], max_height, max_width), dtype=np.uint8
|
||||
)
|
||||
for box_idx, box_detection in enumerate(boxes_detection):
|
||||
mask_detection[box_idx] = polygon_to_mask(
|
||||
box_detection, (max_width, max_height)
|
||||
if overlap_metric == OverlapMetric.IOU:
|
||||
normalize_by_union = True
|
||||
elif overlap_metric == OverlapMetric.IOS:
|
||||
normalize_by_union = False
|
||||
else:
|
||||
raise ValueError(
|
||||
f"overlap_metric {overlap_metric} is not supported, "
|
||||
"only 'IOU' and 'IOS' are supported"
|
||||
)
|
||||
|
||||
ious = mask_iou_batch(mask_true, mask_detection)
|
||||
return ious
|
||||
# Capture identity before reshape: NMS / NMM pass the same array twice, so
|
||||
# the matrix is symmetric and we can compute only its upper triangle.
|
||||
is_self_comparison = boxes_true is boxes_detection
|
||||
boxes_true = boxes_true.reshape(-1, 4, 2).astype(np.float64)
|
||||
boxes_detection = boxes_detection.reshape(-1, 4, 2).astype(np.float64)
|
||||
|
||||
n, m = len(boxes_true), len(boxes_detection)
|
||||
if n == 0 or m == 0:
|
||||
return np.zeros((n, m), dtype=np.float64)
|
||||
|
||||
areas_true = _polygon_areas(boxes_true)
|
||||
areas_detection = _polygon_areas(boxes_detection)
|
||||
|
||||
envelopes_true = _aabb_envelopes(boxes_true)
|
||||
envelopes_detection = (
|
||||
envelopes_true if is_self_comparison else _aabb_envelopes(boxes_detection)
|
||||
)
|
||||
rows, cols = _overlapping_envelope_pairs(envelopes_true, envelopes_detection)
|
||||
if is_self_comparison:
|
||||
upper = rows <= cols
|
||||
rows, cols = rows[upper], cols[upper]
|
||||
|
||||
polygons_true = [box.astype(np.float32) for box in boxes_true]
|
||||
polygons_detection = [box.astype(np.float32) for box in boxes_detection]
|
||||
|
||||
ious: npt.NDArray[np.float64] = np.zeros((n, m), dtype=np.float64)
|
||||
for i, j in zip(rows, cols):
|
||||
intersection, _ = cv2.intersectConvexConvex(
|
||||
polygons_true[i], polygons_detection[j]
|
||||
)
|
||||
if intersection <= 0:
|
||||
continue
|
||||
denominator = (
|
||||
areas_true[i] + areas_detection[j] - intersection
|
||||
if normalize_by_union
|
||||
else min(areas_true[i], areas_detection[j])
|
||||
)
|
||||
if denominator > 0:
|
||||
score = intersection / denominator
|
||||
ious[i, j] = score
|
||||
if is_self_comparison:
|
||||
ious[j, i] = score
|
||||
|
||||
# DO NOT remove this clip. cv2.intersectConvexConvex computes in float32
|
||||
# internally while polygon areas are computed in float64; the intersection
|
||||
# area can exceed the float64 area by ~25 ULP (~1e-7), producing raw IoU
|
||||
# or IoS values microscopically above 1.0 for identical boxes. The clip is
|
||||
# load-bearing, not defensive duplication.
|
||||
return cast(npt.NDArray[np.floating], np.clip(ious, 0.0, 1.0))
|
||||
|
||||
|
||||
def compact_mask_iou_batch(
|
||||
@@ -523,12 +688,23 @@ def _mask_iou_batch_split(
|
||||
Returns:
|
||||
Pairwise IoU of masks from `masks_true` and `masks_detection`.
|
||||
"""
|
||||
intersection_area = np.logical_and(masks_true[:, None], masks_detection).sum(
|
||||
axis=(2, 3)
|
||||
# The overlap of two binary masks is the dot product of their flattened
|
||||
# pixels, so the whole (N, M) intersection matrix is a single matmul.
|
||||
# float32 counts pixels exactly up to 2**24; for larger masks (beyond
|
||||
# ~4096x4096) we promote to float64 so the counts stay exact.
|
||||
pixels = int(np.prod(masks_true.shape[1:]))
|
||||
count_dtype = np.float32 if pixels <= 2**24 else np.float64
|
||||
true_flat = masks_true.reshape(masks_true.shape[0], pixels).astype(
|
||||
count_dtype, copy=False
|
||||
)
|
||||
detection_flat = masks_detection.reshape(masks_detection.shape[0], pixels).astype(
|
||||
count_dtype, copy=False
|
||||
)
|
||||
with np.errstate(divide="ignore", over="ignore", invalid="ignore"):
|
||||
intersection_area: npt.NDArray[np.floating[Any]] = true_flat @ detection_flat.T
|
||||
|
||||
masks_true_area = masks_true.sum(axis=(1, 2)) # (area1, area2, ...)
|
||||
masks_detection_area = masks_detection.sum(axis=(1, 2)) # (area1)
|
||||
masks_true_area = true_flat.sum(axis=1)
|
||||
masks_detection_area = detection_flat.sum(axis=1)
|
||||
|
||||
if overlap_metric == OverlapMetric.IOU:
|
||||
union_area = masks_true_area[:, None] + masks_detection_area - intersection_area
|
||||
@@ -579,10 +755,20 @@ def mask_iou_batch(
|
||||
overlap_metric: Metric used to compute the degree of overlap
|
||||
between pairs of masks (e.g., IoU, IoS).
|
||||
memory_limit: Memory limit in MB, default is 1024 * 5 MB (5GB).
|
||||
Ignored when both inputs are CompactMask.
|
||||
Controls chunking of ``masks_true`` so that flattened detection
|
||||
masks plus each chunk's buffers stay within this limit. A
|
||||
``UserWarning`` is raised when ``masks_detection`` alone
|
||||
exceeds the limit, as chunking cannot reduce peak memory
|
||||
below that floor. Ignored when both inputs are
|
||||
:class:`~supervision.detection.compact_mask.CompactMask`.
|
||||
|
||||
Returns:
|
||||
Pairwise IoU of masks from `masks_true` and `masks_detection`.
|
||||
|
||||
Raises:
|
||||
ValueError: If ``masks_true`` or ``masks_detection`` are not 3D
|
||||
``(N, H, W)`` arrays, or if they do not share the same
|
||||
spatial dimensions ``(H, W)``.
|
||||
"""
|
||||
|
||||
if isinstance(masks_true, CompactMask) and isinstance(masks_detection, CompactMask):
|
||||
@@ -594,29 +780,43 @@ def mask_iou_batch(
|
||||
if isinstance(masks_detection, CompactMask):
|
||||
masks_detection = np.asarray(masks_detection)
|
||||
|
||||
memory = (
|
||||
masks_true.shape[0]
|
||||
* masks_true.shape[1]
|
||||
* masks_true.shape[2]
|
||||
* masks_detection.shape[0]
|
||||
/ 1024
|
||||
/ 1024
|
||||
)
|
||||
if memory <= memory_limit:
|
||||
if masks_true.ndim != 3 or masks_detection.ndim != 3:
|
||||
raise ValueError(
|
||||
"masks_true and masks_detection must be 3D (N, H, W); got "
|
||||
f"ndim={masks_true.ndim} and ndim={masks_detection.ndim}."
|
||||
)
|
||||
if masks_true.shape[1:] != masks_detection.shape[1:]:
|
||||
raise ValueError(
|
||||
"masks_true and masks_detection must share the same (H, W); got "
|
||||
f"{masks_true.shape[1:]} and {masks_detection.shape[1:]}."
|
||||
)
|
||||
# A single pass already handles empty inputs and avoids np.vstack([]) below.
|
||||
if masks_true.shape[0] == 0 or masks_detection.shape[0] == 0:
|
||||
return _mask_iou_batch_split(masks_true, masks_detection, overlap_metric)
|
||||
|
||||
# Peak memory of a single matmul pass: the flattened detection masks (shared
|
||||
# across chunks) plus, per true-mask row, its flattened pixels and the three
|
||||
# (N, M) matrices it touches (intersection, denominator and output). The
|
||||
# previous (N, M, H, W) estimate overcounted by a factor of M and forced
|
||||
# needless chunking now that the intersection is a matmul.
|
||||
pixels = masks_true.shape[1] * masks_true.shape[2]
|
||||
itemsize = 4 if pixels <= 2**24 else 8
|
||||
limit_bytes = memory_limit * 1024 * 1024
|
||||
detection_bytes = masks_detection.shape[0] * pixels * itemsize
|
||||
per_true_row = pixels * itemsize + 3 * masks_detection.shape[0] * 8
|
||||
if detection_bytes > limit_bytes > 0:
|
||||
warnings.warn(
|
||||
f"detection masks ({detection_bytes // 1024 // 1024} MB) exceed "
|
||||
f"memory_limit ({memory_limit} MB); chunking cannot reduce peak "
|
||||
"memory below this floor.",
|
||||
UserWarning,
|
||||
stacklevel=2,
|
||||
)
|
||||
if detection_bytes + masks_true.shape[0] * per_true_row <= limit_bytes:
|
||||
return _mask_iou_batch_split(masks_true, masks_detection, overlap_metric)
|
||||
|
||||
ious = []
|
||||
step = max(
|
||||
memory_limit
|
||||
* 1024
|
||||
* 1024
|
||||
// (
|
||||
masks_detection.shape[0]
|
||||
* masks_detection.shape[1]
|
||||
* masks_detection.shape[2]
|
||||
),
|
||||
1,
|
||||
)
|
||||
step = max((limit_bytes - detection_bytes) // per_true_row, 1)
|
||||
for chunk_start in range(0, masks_true.shape[0], step):
|
||||
ious.append(
|
||||
_mask_iou_batch_split(
|
||||
@@ -696,6 +896,45 @@ def mask_non_max_suppression(
|
||||
return cast(npt.NDArray[np.bool_], keep[sort_index.argsort()])
|
||||
|
||||
|
||||
def _prepare_predictions_for_nms(
|
||||
predictions: npt.NDArray[np.floating],
|
||||
) -> tuple[npt.NDArray[np.int_], npt.NDArray[np.floating], npt.NDArray[np.floating]]:
|
||||
"""Add an agnostic class column when missing, sort by descending score.
|
||||
|
||||
Returns the score-descending sort index, the reordered predictions, and the
|
||||
category vector for the loop callers to consume.
|
||||
"""
|
||||
rows, columns = predictions.shape
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
sort_index = np.flip(predictions[:, 4].argsort())
|
||||
predictions = predictions[sort_index]
|
||||
categories = predictions[:, 5]
|
||||
return sort_index, predictions, categories
|
||||
|
||||
|
||||
def _nms_loop_from_iou_matrix(
|
||||
ious: npt.NDArray[np.floating],
|
||||
categories: npt.NDArray[np.floating],
|
||||
iou_threshold: float,
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
"""Greedy NMS suppression loop given a precomputed pairwise IoU matrix.
|
||||
|
||||
Assumes `ious` is square with row/column order matching `categories`.
|
||||
Detections sharing a category whose IoU exceeds `iou_threshold` are dropped
|
||||
in favour of the higher-confidence entry.
|
||||
"""
|
||||
rows = len(ious)
|
||||
ious = ious - np.eye(rows)
|
||||
keep: npt.NDArray[np.bool_] = np.ones(rows, dtype=bool)
|
||||
for index, (iou, category) in enumerate(zip(ious, categories)):
|
||||
if not keep[index]:
|
||||
continue
|
||||
condition = (iou > iou_threshold) & (categories == category)
|
||||
keep = keep & ~condition
|
||||
return keep
|
||||
|
||||
|
||||
def box_non_max_suppression(
|
||||
predictions: npt.NDArray[np.floating],
|
||||
iou_threshold: float = 0.5,
|
||||
@@ -725,32 +964,9 @@ def box_non_max_suppression(
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
# add column #5 - category filled with zeros for agnostic nms
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
# sort predictions column #4 - score
|
||||
sort_index = np.flip(predictions[:, 4].argsort())
|
||||
predictions = predictions[sort_index]
|
||||
|
||||
boxes = predictions[:, :4]
|
||||
categories = predictions[:, 5]
|
||||
ious = box_iou_batch(boxes, boxes, overlap_metric)
|
||||
ious = ious - np.eye(rows)
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
|
||||
for index, (iou, category) in enumerate(zip(ious, categories)):
|
||||
if not keep[index]:
|
||||
continue
|
||||
|
||||
# drop detections with iou > iou_threshold and
|
||||
# same category as current detections
|
||||
condition = (iou > iou_threshold) & (categories == category)
|
||||
keep = keep & ~condition
|
||||
|
||||
sort_index, predictions, categories = _prepare_predictions_for_nms(predictions)
|
||||
ious = box_iou_batch(predictions[:, :4], predictions[:, :4], overlap_metric)
|
||||
keep = _nms_loop_from_iou_matrix(ious, categories, iou_threshold)
|
||||
return cast(npt.NDArray[np.bool_], keep[sort_index.argsort()])
|
||||
|
||||
|
||||
@@ -886,6 +1102,70 @@ def mask_non_max_merge(
|
||||
return merge_groups
|
||||
|
||||
|
||||
def _greedy_nmm_via_iou_callback(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
iou_against_candidate: Callable[
|
||||
[npt.NDArray[np.int_], int], npt.NDArray[np.floating]
|
||||
],
|
||||
iou_threshold: float,
|
||||
) -> list[list[int]]:
|
||||
"""Greedy non-maximum merging loop, independent of how overlap is computed.
|
||||
|
||||
``iou_against_candidate(order_indices, candidate_idx)`` must return the IoU
|
||||
vector between every prediction in ``order_indices`` and the candidate at
|
||||
``candidate_idx``. Predictions whose IoU meets ``iou_threshold`` are
|
||||
grouped with the candidate.
|
||||
"""
|
||||
merge_groups: list[list[int]] = []
|
||||
scores = predictions[:, 4]
|
||||
order = scores.argsort()
|
||||
while len(order) > 0:
|
||||
idx = int(order[-1])
|
||||
order = order[:-1]
|
||||
if len(order) == 0:
|
||||
merge_groups.append([idx])
|
||||
break
|
||||
ious = iou_against_candidate(order, idx)
|
||||
above_threshold = ious >= iou_threshold
|
||||
merge_group = [idx, *np.flip(order[above_threshold]).tolist()]
|
||||
merge_groups.append(merge_group)
|
||||
order = order[~above_threshold]
|
||||
return merge_groups
|
||||
|
||||
|
||||
def _non_max_merge_per_category(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
group_within: Callable[[npt.NDArray[np.int_]], list[list[int]]],
|
||||
) -> list[list[int]]:
|
||||
"""Dispatch NMM grouping per class, then translate local indices back to
|
||||
the global row positions of ``predictions``.
|
||||
|
||||
``group_within(global_indices)`` must return merge groups expressed in
|
||||
terms of *positions inside `global_indices`*, not absolute row positions.
|
||||
When ``predictions`` has no class column, a single pass over all rows is
|
||||
performed instead of per-category iteration.
|
||||
"""
|
||||
if predictions.shape[1] == 5:
|
||||
global_indices = np.arange(len(predictions), dtype=int)
|
||||
return [
|
||||
global_indices[group].tolist() for group in group_within(global_indices)
|
||||
]
|
||||
|
||||
category_ids = predictions[:, 5]
|
||||
merge_groups: list[list[int]] = []
|
||||
for category_id in np.unique(category_ids):
|
||||
curr_indices = np.where(category_ids == category_id)[0]
|
||||
for local_group in group_within(curr_indices):
|
||||
merge_groups.append(curr_indices[local_group].tolist())
|
||||
|
||||
for merge_group in merge_groups:
|
||||
if len(merge_group) == 0:
|
||||
raise ValueError(
|
||||
f"Empty group detected when non-max-merging detections: {merge_groups}"
|
||||
)
|
||||
return merge_groups
|
||||
|
||||
|
||||
def _group_overlapping_boxes(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
@@ -908,30 +1188,19 @@ def _group_overlapping_boxes(
|
||||
Groups of prediction indices to be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
merge_groups: list[list[int]] = []
|
||||
|
||||
scores = predictions[:, 4]
|
||||
order = scores.argsort()
|
||||
def iou_against_candidate(
|
||||
order: npt.NDArray[np.int_], idx: int
|
||||
) -> npt.NDArray[np.floating]:
|
||||
return box_iou_batch(
|
||||
predictions[order][:, :4],
|
||||
predictions[idx : idx + 1, :4],
|
||||
overlap_metric,
|
||||
).flatten()
|
||||
|
||||
while len(order) > 0:
|
||||
idx = int(order[-1])
|
||||
|
||||
order = order[:-1]
|
||||
if len(order) == 0:
|
||||
merge_groups.append([idx])
|
||||
break
|
||||
|
||||
merge_candidate = np.expand_dims(predictions[idx], axis=0)
|
||||
ious = box_iou_batch(
|
||||
predictions[order][:, :4], merge_candidate[:, :4], overlap_metric
|
||||
)
|
||||
ious = ious.flatten()
|
||||
|
||||
above_threshold = ious >= iou_threshold
|
||||
merge_group = [idx, *np.flip(order[above_threshold]).tolist()]
|
||||
merge_groups.append(merge_group)
|
||||
order = order[~above_threshold]
|
||||
return merge_groups
|
||||
return _greedy_nmm_via_iou_callback(
|
||||
predictions, iou_against_candidate, iou_threshold
|
||||
)
|
||||
|
||||
|
||||
def box_non_max_merge(
|
||||
@@ -957,23 +1226,228 @@ def box_non_max_merge(
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
if predictions.shape[1] == 5:
|
||||
return _group_overlapping_boxes(predictions, iou_threshold, overlap_metric)
|
||||
|
||||
category_ids = predictions[:, 5]
|
||||
merge_groups = []
|
||||
for category_id in np.unique(category_ids):
|
||||
curr_indices = np.where(category_ids == category_id)[0]
|
||||
merge_class_groups = _group_overlapping_boxes(
|
||||
predictions[curr_indices], iou_threshold, overlap_metric
|
||||
def group_within(global_indices: npt.NDArray[np.int_]) -> list[list[int]]:
|
||||
return _group_overlapping_boxes(
|
||||
predictions[global_indices], iou_threshold, overlap_metric
|
||||
)
|
||||
|
||||
for merge_class_group in merge_class_groups:
|
||||
merge_groups.append(curr_indices[merge_class_group].tolist())
|
||||
return _non_max_merge_per_category(predictions, group_within)
|
||||
|
||||
for merge_group in merge_groups:
|
||||
if len(merge_group) == 0:
|
||||
|
||||
def oriented_box_non_max_suppression(
|
||||
predictions: npt.NDArray[np.floating],
|
||||
oriented_boxes: npt.NDArray[np.floating],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
"""
|
||||
Perform Non-Maximum Suppression on oriented bounding box predictions.
|
||||
|
||||
Overlap is computed via :func:`oriented_box_iou_batch` on the four
|
||||
corners of each box, so detections whose axis-aligned bounding boxes
|
||||
overlap heavily but whose oriented bodies do not are kept — unlike
|
||||
:func:`box_non_max_suppression`, which would suppress them.
|
||||
|
||||
Args:
|
||||
predictions: An array of object detection predictions in the
|
||||
format ``(x_min, y_min, x_max, y_max, score)`` or
|
||||
``(x_min, y_min, x_max, y_max, score, class)``. Shape ``(N, 5)``
|
||||
or ``(N, 6)``. Only the score (column 4) and optional class
|
||||
(column 5) are read; the axis-aligned coordinates are not used.
|
||||
oriented_boxes: Array of shape ``(N, 4, 2)`` containing the four
|
||||
``(x, y)`` corners of each oriented box, aligned with
|
||||
``predictions`` row-by-row.
|
||||
iou_threshold: The intersection-over-union threshold to use for
|
||||
non-maximum suppression.
|
||||
overlap_metric: Metric used to compute the degree of overlap
|
||||
between pairs of oriented boxes (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
A boolean array of shape ``(N,)`` indicating which predictions
|
||||
to keep after non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If ``iou_threshold`` is not within the closed
|
||||
range from 0 to 1.
|
||||
ValueError: If ``predictions`` and ``oriented_boxes`` have
|
||||
mismatched lengths or invalid shapes.
|
||||
|
||||
Examples:
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> oriented_boxes = np.array([
|
||||
... [[10, 10], [50, 10], [50, 30], [10, 30]],
|
||||
... [[11, 11], [51, 11], [51, 31], [11, 31]],
|
||||
... ], dtype=np.float32)
|
||||
>>> predictions = np.array([
|
||||
... [10, 10, 50, 30, 0.9, 0],
|
||||
... [11, 11, 51, 31, 0.8, 0],
|
||||
... ], dtype=np.float32)
|
||||
>>> keep = sv.oriented_box_non_max_suppression(
|
||||
... predictions=predictions,
|
||||
... oriented_boxes=oriented_boxes,
|
||||
... iou_threshold=0.5,
|
||||
... )
|
||||
>>> keep
|
||||
array([ True, False])
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
for name, arr in (("predictions", predictions), ("oriented_boxes", oriented_boxes)):
|
||||
if name == "predictions":
|
||||
if arr.ndim != 2 or arr.shape[1] not in (5, 6):
|
||||
raise ValueError(
|
||||
f"`{name}` has shape {arr.shape}; expected (N, 5) or (N, 6)."
|
||||
)
|
||||
continue
|
||||
if arr.ndim == 3 and arr.shape[1:] != (4, 2):
|
||||
raise ValueError(
|
||||
f"Empty group detected when non-max-merging detections: {merge_groups}"
|
||||
f"`{name}` has shape {arr.shape}; expected (N, 4, 2) "
|
||||
f"— each box must have exactly 4 corners with (x, y) coordinates."
|
||||
)
|
||||
return merge_groups
|
||||
elif arr.ndim == 2 and arr.shape[1] != 8:
|
||||
raise ValueError(
|
||||
f"`{name}` has shape {arr.shape}; expected (N, 8) for flat "
|
||||
f"YOLO format or (N, 4, 2) for corner format."
|
||||
)
|
||||
elif arr.ndim not in (2, 3):
|
||||
raise ValueError(
|
||||
f"`{name}` must be 2-D (N, 8) or 3-D (N, 4, 2), got shape {arr.shape}."
|
||||
)
|
||||
if len(predictions) != len(oriented_boxes):
|
||||
raise ValueError(
|
||||
f"`predictions` and `oriented_boxes` must have the same length, "
|
||||
f"got {len(predictions)} and {len(oriented_boxes)}."
|
||||
)
|
||||
sort_index, _, categories = _prepare_predictions_for_nms(predictions)
|
||||
oriented_boxes = oriented_boxes[sort_index]
|
||||
# same object intentional — triggers upper-triangle optimization
|
||||
ious = oriented_box_iou_batch(oriented_boxes, oriented_boxes, overlap_metric)
|
||||
keep = _nms_loop_from_iou_matrix(ious, categories, iou_threshold)
|
||||
return cast(npt.NDArray[np.bool_], keep[sort_index.argsort()])
|
||||
|
||||
|
||||
def _group_overlapping_oriented_boxes(
|
||||
predictions: npt.NDArray[np.floating],
|
||||
oriented_boxes: npt.NDArray[np.floating],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Greedy non-maximum merging on oriented boxes. Mirrors
|
||||
:func:`_group_overlapping_boxes` but uses :func:`oriented_box_iou_batch`.
|
||||
"""
|
||||
|
||||
def iou_against_candidate(
|
||||
order: npt.NDArray[np.int_], idx: int
|
||||
) -> npt.NDArray[np.floating]:
|
||||
return oriented_box_iou_batch(
|
||||
oriented_boxes[order],
|
||||
oriented_boxes[idx][None, ...],
|
||||
overlap_metric,
|
||||
).flatten()
|
||||
|
||||
return _greedy_nmm_via_iou_callback(
|
||||
predictions, iou_against_candidate, iou_threshold
|
||||
)
|
||||
|
||||
|
||||
def oriented_box_non_max_merge(
|
||||
predictions: npt.NDArray[np.floating],
|
||||
oriented_boxes: npt.NDArray[np.floating],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Perform Non-Maximum Merging on oriented bounding box predictions,
|
||||
grouped per category.
|
||||
|
||||
Mirrors :func:`box_non_max_merge` but uses oriented-box IoU, so groups
|
||||
of rotated detections sharing the same body — rather than the same
|
||||
axis-aligned bounding box — are merged.
|
||||
|
||||
Args:
|
||||
predictions: An array of shape ``(n, 5)`` or ``(n, 6)`` containing
|
||||
the axis-aligned coordinates ``[x1, y1, x2, y2]``, confidence
|
||||
scores, and optionally class ids. Only the score and optional
|
||||
class are used by the grouping logic; overlap is computed on
|
||||
``oriented_boxes``.
|
||||
oriented_boxes: Array of shape ``(N, 4, 2)`` containing the four
|
||||
``(x, y)`` corners of each oriented box.
|
||||
iou_threshold: The intersection-over-union threshold to use for
|
||||
non-maximum merging.
|
||||
overlap_metric: Metric used to compute the degree of overlap
|
||||
between pairs of oriented boxes (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
Groups of prediction indices to be merged. Each group may have 1
|
||||
or more elements.
|
||||
|
||||
Raises:
|
||||
AssertionError: If ``iou_threshold`` is not within the closed
|
||||
range from 0 to 1.
|
||||
ValueError: If ``predictions`` and ``oriented_boxes`` have
|
||||
mismatched lengths or invalid shapes.
|
||||
|
||||
Examples:
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> oriented_boxes = np.array([
|
||||
... [[10, 10], [50, 10], [50, 30], [10, 30]],
|
||||
... [[11, 11], [51, 11], [51, 31], [11, 31]],
|
||||
... ], dtype=np.float32)
|
||||
>>> predictions = np.array([
|
||||
... [10, 10, 50, 30, 0.9, 0],
|
||||
... [11, 11, 51, 31, 0.8, 0],
|
||||
... ], dtype=np.float32)
|
||||
>>> groups = sv.oriented_box_non_max_merge(
|
||||
... predictions=predictions,
|
||||
... oriented_boxes=oriented_boxes,
|
||||
... iou_threshold=0.5,
|
||||
... )
|
||||
>>> len(groups)
|
||||
1
|
||||
"""
|
||||
for name, arr in (("predictions", predictions), ("oriented_boxes", oriented_boxes)):
|
||||
if name == "predictions":
|
||||
if arr.ndim != 2 or arr.shape[1] not in (5, 6):
|
||||
raise ValueError(
|
||||
f"`{name}` has shape {arr.shape}; expected (N, 5) or (N, 6)."
|
||||
)
|
||||
continue
|
||||
if arr.ndim == 3 and arr.shape[1:] != (4, 2):
|
||||
raise ValueError(
|
||||
f"`{name}` has shape {arr.shape}; expected (N, 4, 2) "
|
||||
f"— each box must have exactly 4 corners with (x, y) coordinates."
|
||||
)
|
||||
elif arr.ndim == 2 and arr.shape[1] != 8:
|
||||
raise ValueError(
|
||||
f"`{name}` has shape {arr.shape}; expected (N, 8) for flat "
|
||||
f"YOLO format or (N, 4, 2) for corner format."
|
||||
)
|
||||
elif arr.ndim not in (2, 3):
|
||||
raise ValueError(
|
||||
f"`{name}` must be 2-D (N, 8) or 3-D (N, 4, 2), got shape {arr.shape}."
|
||||
)
|
||||
if len(predictions) != len(oriented_boxes):
|
||||
raise ValueError(
|
||||
f"`predictions` and `oriented_boxes` must have the same length, "
|
||||
f"got {len(predictions)} and {len(oriented_boxes)}."
|
||||
)
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
|
||||
def group_within(global_indices: npt.NDArray[np.int_]) -> list[list[int]]:
|
||||
return _group_overlapping_oriented_boxes(
|
||||
predictions[global_indices],
|
||||
oriented_boxes[global_indices],
|
||||
iou_threshold,
|
||||
overlap_metric,
|
||||
)
|
||||
|
||||
return _non_max_merge_per_category(predictions, group_within)
|
||||
|
||||
@@ -1,7 +1,5 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import cast
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
@@ -57,19 +55,47 @@ def approximate_polygon(
|
||||
the `x`, `y` coordinates of the input polygon's points.
|
||||
percentage: The percentage of points to be removed from the
|
||||
input polygon, in the range `[0, 1)`.
|
||||
epsilon_step: Approximation accuracy step.
|
||||
epsilon_step: Approximation accuracy step, must be positive.
|
||||
Epsilon is the maximum distance between the original curve
|
||||
and its approximation.
|
||||
|
||||
Returns:
|
||||
A new 2D NumPy array of shape `(M, 2)`,
|
||||
where `M <= N * (1 - percentage)`, containing
|
||||
the `x`, `y` coordinates of the
|
||||
approximated polygon's points.
|
||||
A new 2D NumPy array of shape `(M, 2)` containing the `x`, `y`
|
||||
coordinates of the approximated polygon's points. `M` is at most
|
||||
`floor(N * (1 - percentage))` (minimum 3). Because epsilon
|
||||
advances in discrete `epsilon_step` increments, `M` may be
|
||||
noticeably smaller than the budget when a single step crosses
|
||||
the target band. At least 3 points are always kept; when further
|
||||
simplification would collapse the polygon below 3 points the last
|
||||
valid approximation is returned and `M` may exceed the budget.
|
||||
|
||||
Raises:
|
||||
ValueError: If `percentage` is outside the range `[0, 1)`.
|
||||
ValueError: If `epsilon_step` is not positive.
|
||||
|
||||
Examples:
|
||||
Reduce a polygon to at most half its original point count:
|
||||
|
||||
>>> import numpy as np
|
||||
>>> polygon = np.array([[0, 0], [10, 0], [10, 10], [0, 10],
|
||||
... [5, 10], [5, 5], [3, 7], [1, 9]])
|
||||
>>> result = approximate_polygon(polygon, percentage=0.5)
|
||||
>>> result.shape[1]
|
||||
2
|
||||
>>> len(result) <= max(int(len(polygon) * 0.5), 3)
|
||||
True
|
||||
|
||||
Polygon already at or below target — returned unchanged:
|
||||
|
||||
>>> tiny = np.array([[0, 0], [5, 0], [2, 4]])
|
||||
>>> approximate_polygon(tiny, percentage=0.5) is tiny
|
||||
True
|
||||
"""
|
||||
|
||||
if percentage < 0 or percentage >= 1:
|
||||
raise ValueError("Percentage must be in the range [0, 1).")
|
||||
if epsilon_step <= 0:
|
||||
raise ValueError("epsilon_step must be positive.")
|
||||
|
||||
target_points = max(int(len(polygon) * (1 - percentage)), 3)
|
||||
|
||||
@@ -78,12 +104,13 @@ def approximate_polygon(
|
||||
|
||||
epsilon: float = 0
|
||||
approximated_points = polygon
|
||||
while True:
|
||||
while len(approximated_points) > target_points:
|
||||
epsilon += epsilon_step
|
||||
new_approximated_points = cv2.approxPolyDP(polygon, epsilon, closed=True)
|
||||
if len(new_approximated_points) > target_points:
|
||||
approximated_points = new_approximated_points
|
||||
else:
|
||||
candidate = np.squeeze(cv2.approxPolyDP(polygon, epsilon, closed=True), axis=1)
|
||||
# Stop before the approximation collapses below a valid polygon; keep the
|
||||
# last result with at least three points.
|
||||
if len(candidate) < 3:
|
||||
break
|
||||
approximated_points = candidate
|
||||
|
||||
return cast(npt.NDArray[np.number], np.squeeze(approximated_points, axis=1))
|
||||
return approximated_points
|
||||
|
||||
@@ -10,12 +10,13 @@ from typing import Any, cast
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
from deprecate import deprecated, void
|
||||
from PIL import Image
|
||||
|
||||
from supervision.detection.utils.boxes import denormalize_boxes
|
||||
from supervision.detection.utils.converters import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.utils.internal import warn_deprecated
|
||||
from supervision.validators import validate_resolution
|
||||
from supervision.validators import _validate_resolution
|
||||
|
||||
|
||||
class LMM(Enum):
|
||||
@@ -159,7 +160,9 @@ SUPPORTED_TASKS_FLORENCE_2 = [
|
||||
]
|
||||
|
||||
|
||||
def validate_vlm_parameters(vlm: VLM | str, result: Any, kwargs: dict[str, Any]) -> VLM:
|
||||
def _validate_vlm_parameters(
|
||||
vlm: VLM | str, result: Any, kwargs: dict[str, Any]
|
||||
) -> VLM:
|
||||
"""
|
||||
Validates the parameters and result type for a given Vision-Language Model (VLM).
|
||||
|
||||
@@ -200,6 +203,15 @@ def validate_vlm_parameters(vlm: VLM | str, result: Any, kwargs: dict[str, Any])
|
||||
return vlm
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_vlm_parameters,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_vlm_parameters(vlm: VLM | str, result: Any, kwargs: dict[str, Any]) -> VLM:
|
||||
return void(vlm, result, kwargs) # type: ignore[no-any-return]
|
||||
|
||||
|
||||
def from_paligemma(
|
||||
result: str, resolution_wh: tuple[int, int], classes: list[str] | None = None
|
||||
) -> tuple[npt.NDArray[Any], npt.NDArray[Any] | None, npt.NDArray[Any]]:
|
||||
@@ -220,29 +232,29 @@ def from_paligemma(
|
||||
is an array of shape `(n,)` with class labels.
|
||||
"""
|
||||
|
||||
w, h = validate_resolution(resolution_wh)
|
||||
w, h = _validate_resolution(resolution_wh)
|
||||
|
||||
pattern = re.compile(
|
||||
r"(?<!<loc\d{4}>)<loc(\d{4})><loc(\d{4})><loc(\d{4})><loc(\d{4})> ([\w\s\-]+)"
|
||||
)
|
||||
matches = pattern.findall(result)
|
||||
matches = np.array(matches) if matches else np.empty((0, 5))
|
||||
matches_arr: npt.NDArray[Any] = np.array(matches) if matches else np.empty((0, 5))
|
||||
|
||||
if matches.shape[0] == 0:
|
||||
return np.empty((0, 4)), None, np.empty(0, dtype=str)
|
||||
if matches_arr.shape[0] == 0:
|
||||
return np.empty((0, 4)), np.empty((0,), dtype=int), np.empty(0, dtype=str)
|
||||
|
||||
xyxy, class_name = matches[:, [1, 0, 3, 2]], matches[:, 4]
|
||||
xyxy = xyxy.astype(int) / 1024 * np.array([w, h, w, h])
|
||||
class_name = np.char.strip(class_name.astype(str))
|
||||
class_id = None
|
||||
xyxy_arr = np.array(matches_arr[:, [1, 0, 3, 2]], dtype=float)
|
||||
xyxy_arr = xyxy_arr.astype(int) / 1024 * np.array([w, h, w, h])
|
||||
class_name = np.char.strip(matches_arr[:, 4].astype(str))
|
||||
class_id: npt.NDArray[Any] | None = None
|
||||
|
||||
if classes is not None:
|
||||
mask = np.array([name in classes for name in class_name], dtype=bool)
|
||||
xyxy = xyxy[mask]
|
||||
xyxy_arr = xyxy_arr[mask]
|
||||
class_name = class_name[mask]
|
||||
class_id = np.array([classes.index(name) for name in class_name])
|
||||
|
||||
return xyxy, class_id, class_name
|
||||
return xyxy_arr, class_id, class_name
|
||||
|
||||
|
||||
def recover_truncated_qwen_2_5_vl_response(text: str) -> Any | None:
|
||||
@@ -322,8 +334,8 @@ def from_qwen_2_5_vl(
|
||||
`class_name` is an array of shape `(N,)` with class names.
|
||||
"""
|
||||
|
||||
in_w, in_h = validate_resolution(input_wh)
|
||||
out_w, out_h = validate_resolution(resolution_wh)
|
||||
in_w, in_h = _validate_resolution(input_wh)
|
||||
out_w, out_h = _validate_resolution(resolution_wh)
|
||||
|
||||
text = result.strip()
|
||||
text = re.sub(r"^```(json)?", "", text, flags=re.IGNORECASE).strip()
|
||||
@@ -357,7 +369,7 @@ def from_qwen_2_5_vl(
|
||||
labels_list = []
|
||||
|
||||
for item in data:
|
||||
if "bbox_2d" not in item or "label" not in item:
|
||||
if not isinstance(item, dict) or "bbox_2d" not in item or "label" not in item:
|
||||
continue
|
||||
boxes_list.append(item["bbox_2d"])
|
||||
labels_list.append(item["label"])
|
||||
@@ -448,12 +460,13 @@ def from_deepseek_vl_2(
|
||||
f"and det tags ({len(detection_segments)}) in the result must be equal."
|
||||
)
|
||||
|
||||
xyxy, class_name_list = [], []
|
||||
xyxy_list: list[list[float]] = []
|
||||
class_name_list: list[str] = []
|
||||
for label, detection_blob in zip(label_segments, detection_segments):
|
||||
current_class_name = label.strip()
|
||||
for box in re.findall(r"\[(.*?)\]", detection_blob):
|
||||
x1, y1, x2, y2 = map(float, box.strip("[]").split(","))
|
||||
xyxy.append(
|
||||
xyxy_list.append(
|
||||
[
|
||||
(x1 / 999 * width),
|
||||
(y1 / 999 * height),
|
||||
@@ -463,7 +476,7 @@ def from_deepseek_vl_2(
|
||||
)
|
||||
class_name_list.append(current_class_name)
|
||||
|
||||
xyxy = np.array(xyxy, dtype=np.float32)
|
||||
xyxy = np.array(xyxy_list, dtype=np.float32)
|
||||
class_name = np.array(class_name_list)
|
||||
|
||||
if classes is not None:
|
||||
@@ -529,15 +542,15 @@ def from_florence_2(
|
||||
return xyxy, labels, None, xyxyxyxy
|
||||
|
||||
if task in ["<REFERRING_EXPRESSION_SEGMENTATION>", "<REGION_TO_SEGMENTATION>"]:
|
||||
xyxy_list = []
|
||||
masks_list = []
|
||||
xyxy_list: list[npt.NDArray[Any]] = []
|
||||
masks_list: list[npt.NDArray[Any]] = []
|
||||
for polygons_of_same_class in result["polygons"]:
|
||||
for polygon in polygons_of_same_class:
|
||||
polygon = np.reshape(polygon, (-1, 2)).astype(np.int32)
|
||||
mask = polygon_to_mask(polygon, resolution_wh).astype(bool)
|
||||
masks_list.append(mask)
|
||||
xyxy = polygon_to_xyxy(polygon)
|
||||
xyxy_list.append(xyxy)
|
||||
xyxy_box = polygon_to_xyxy(polygon)
|
||||
xyxy_list.append(xyxy_box)
|
||||
# per-class labels also provided, but they are ["", "", "", ...]
|
||||
# when we figure out how to set class names, we can do
|
||||
# zip(result["labels"], result["polygons"])
|
||||
@@ -565,7 +578,7 @@ def from_florence_2(
|
||||
f"Expected string to end in location tags, but got {result}"
|
||||
)
|
||||
|
||||
w, h = validate_resolution(resolution_wh)
|
||||
w, h = _validate_resolution(resolution_wh)
|
||||
xyxy = np.array([match.groups()], dtype=np.float32)
|
||||
xyxy *= np.array([w, h, w, h]) / 1000
|
||||
result_string = result[: match.start()]
|
||||
@@ -614,7 +627,7 @@ def from_google_gemini_2_0(
|
||||
|
||||
"""
|
||||
|
||||
w, h = validate_resolution(resolution_wh)
|
||||
w, h = _validate_resolution(resolution_wh)
|
||||
|
||||
lines = result.splitlines()
|
||||
for i, line in enumerate(lines):
|
||||
@@ -626,13 +639,16 @@ def from_google_gemini_2_0(
|
||||
try:
|
||||
data = json.loads(result)
|
||||
except json.JSONDecodeError:
|
||||
return np.empty((0, 4)), None, np.empty((0,), dtype=str)
|
||||
return np.empty((0, 4)), np.empty((0,), dtype=int), np.empty((0,), dtype=str)
|
||||
|
||||
if not isinstance(data, list):
|
||||
return np.empty((0, 4)), np.empty((0,), dtype=int), np.empty((0,), dtype=str)
|
||||
|
||||
labels = []
|
||||
xyxy = []
|
||||
|
||||
for item in data:
|
||||
if "box_2d" not in item or "label" not in item:
|
||||
if not isinstance(item, dict) or "box_2d" not in item or "label" not in item:
|
||||
continue
|
||||
labels.append(item["label"])
|
||||
box = item["box_2d"]
|
||||
@@ -640,7 +656,7 @@ def from_google_gemini_2_0(
|
||||
xyxy.append([box[1], box[0], box[3], box[2]])
|
||||
|
||||
if len(xyxy) == 0:
|
||||
return np.empty((0, 4)), None, np.empty((0,), dtype=str)
|
||||
return np.empty((0, 4)), np.empty((0,), dtype=int), np.empty((0,), dtype=str)
|
||||
|
||||
xyxy = denormalize_boxes(
|
||||
np.array(xyxy, dtype=np.float64),
|
||||
@@ -702,7 +718,7 @@ def from_google_gemini_2_5(
|
||||
scores, and `masks` is an optional array of shape `(n, h, w)` with
|
||||
segmentation masks.
|
||||
"""
|
||||
w, h = validate_resolution(resolution_wh)
|
||||
w, h = _validate_resolution(resolution_wh)
|
||||
|
||||
lines = result.splitlines()
|
||||
for i, line in enumerate(lines):
|
||||
@@ -722,13 +738,22 @@ def from_google_gemini_2_5(
|
||||
None,
|
||||
)
|
||||
|
||||
if not isinstance(data, list):
|
||||
return (
|
||||
np.empty((0, 4)),
|
||||
np.array([], dtype=int),
|
||||
np.array([], dtype=str),
|
||||
np.array([], dtype=float),
|
||||
None,
|
||||
)
|
||||
|
||||
boxes_list: list[Any] = []
|
||||
labels_list: list[str] = []
|
||||
confidence_list: list[float] | None = []
|
||||
masks_list: list[npt.NDArray[Any]] | None = []
|
||||
|
||||
for item in data:
|
||||
if "box_2d" not in item or "label" not in item:
|
||||
if not isinstance(item, dict) or "box_2d" not in item or "label" not in item:
|
||||
continue
|
||||
labels_list.append(item["label"])
|
||||
box = item["box_2d"]
|
||||
@@ -743,29 +768,39 @@ def from_google_gemini_2_5(
|
||||
if "mask" in item:
|
||||
if masks_list is not None:
|
||||
png_str = item["mask"]
|
||||
if not png_str.startswith("data:image/png;base64,"):
|
||||
if not isinstance(png_str, str) or not png_str.startswith(
|
||||
"data:image/png;base64,"
|
||||
):
|
||||
# Malformed mask: keep an empty mask but still fall through to
|
||||
# the confidence handling below, so the per-item arrays stay
|
||||
# aligned (a `continue` here desynced confidence vs boxes).
|
||||
masks_list.append(np.zeros((h, w), dtype=bool))
|
||||
continue
|
||||
|
||||
png_str = png_str.removeprefix("data:image/png;base64,")
|
||||
png_str = base64.b64decode(png_str)
|
||||
mask_img = Image.open(io.BytesIO(png_str))
|
||||
|
||||
y_min, y_max = int(absolute_bbox[1]), int(absolute_bbox[3])
|
||||
x_min, x_max = int(absolute_bbox[0]), int(absolute_bbox[2])
|
||||
|
||||
bbox_height = y_max - y_min
|
||||
bbox_width = x_max - x_min
|
||||
|
||||
if bbox_height > 0 and bbox_width > 0:
|
||||
mask_img = mask_img.resize(
|
||||
(bbox_width, bbox_height), resample=Image.Resampling.BILINEAR
|
||||
)
|
||||
np_mask: npt.NDArray[np.bool_] = np.zeros((h, w), dtype=bool)
|
||||
np_mask[y_min:y_max, x_min:x_max] = np.array(mask_img) > 0
|
||||
masks_list.append(np_mask)
|
||||
else:
|
||||
masks_list.append(np.zeros((h, w), dtype=bool))
|
||||
png_str = png_str.removeprefix("data:image/png;base64,")
|
||||
try:
|
||||
png_bytes = base64.b64decode(png_str)
|
||||
mask_img = Image.open(io.BytesIO(png_bytes)).convert("L")
|
||||
except Exception:
|
||||
masks_list.append(np.zeros((h, w), dtype=bool))
|
||||
else:
|
||||
y_min, y_max = int(absolute_bbox[1]), int(absolute_bbox[3])
|
||||
x_min, x_max = int(absolute_bbox[0]), int(absolute_bbox[2])
|
||||
|
||||
bbox_height = y_max - y_min
|
||||
bbox_width = x_max - x_min
|
||||
|
||||
if bbox_height > 0 and bbox_width > 0:
|
||||
mask_img = mask_img.resize(
|
||||
(bbox_width, bbox_height),
|
||||
resample=Image.Resampling.BILINEAR,
|
||||
)
|
||||
np_mask: npt.NDArray[np.bool_] = np.zeros(
|
||||
(h, w), dtype=bool
|
||||
)
|
||||
np_mask[y_min:y_max, x_min:x_max] = np.array(mask_img) > 0
|
||||
masks_list.append(np_mask)
|
||||
else:
|
||||
masks_list.append(np.zeros((h, w), dtype=bool))
|
||||
else:
|
||||
masks_list = None
|
||||
|
||||
|
||||
@@ -2,7 +2,7 @@ from __future__ import annotations
|
||||
|
||||
from abc import ABC, abstractmethod
|
||||
from collections.abc import Sequence
|
||||
from typing import Any
|
||||
from typing import cast
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -51,7 +51,8 @@ class VertexAnnotator(BaseKeyPointAnnotator):
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene with skeleton vertices based on the provided key
|
||||
points. It draws circles at each key point location.
|
||||
points. It draws circles at each key point location. Anchors marked as
|
||||
not visible via ``key_points.visible`` are skipped.
|
||||
|
||||
Args:
|
||||
scene: The image where skeleton vertices will be drawn. `ImageType` is a
|
||||
@@ -67,20 +68,19 @@ class VertexAnnotator(BaseKeyPointAnnotator):
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> image = np.zeros((100, 100, 3), dtype=np.uint8)
|
||||
>>> image = np.zeros((800, 800, 3), dtype=np.uint8)
|
||||
>>> key_points = sv.KeyPoints(
|
||||
... xy=np.array([[[50, 50], [60, 60]]], dtype=np.float32)
|
||||
... xy=np.array(
|
||||
... [[[400, 200], [300, 500], [500, 500]]],
|
||||
... dtype=np.float32,
|
||||
... ),
|
||||
... class_id=np.array([0]),
|
||||
... visible=np.array([[True, True, True]]),
|
||||
... )
|
||||
>>> vertex_annotator = sv.VertexAnnotator(
|
||||
... color=sv.Color.GREEN,
|
||||
... radius=10
|
||||
>>> annotator = sv.VertexAnnotator(
|
||||
... color=sv.Color.ROBOFLOW, radius=10
|
||||
... )
|
||||
>>> annotated_frame = vertex_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... key_points=key_points
|
||||
... )
|
||||
>>> annotated_frame.shape
|
||||
(100, 100, 3)
|
||||
>>> result = annotator.annotate(image.copy(), key_points)
|
||||
|
||||
```
|
||||
"""
|
||||
@@ -88,8 +88,15 @@ class VertexAnnotator(BaseKeyPointAnnotator):
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
for xy in key_points.xy:
|
||||
for x, y in xy:
|
||||
for detection_index, xy in enumerate(key_points.xy):
|
||||
for point_index, (x, y) in enumerate(xy):
|
||||
if np.allclose((x, y), 0):
|
||||
continue
|
||||
if (
|
||||
key_points.visible is not None
|
||||
and not key_points.visible[detection_index, point_index]
|
||||
):
|
||||
continue
|
||||
cv2.circle(
|
||||
img=scene,
|
||||
center=(int(x), int(y)),
|
||||
@@ -111,14 +118,20 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
self,
|
||||
color: Color = Color.ROBOFLOW,
|
||||
thickness: int = 2,
|
||||
edges: Sequence[tuple[int, int]] | None = None,
|
||||
edges: (
|
||||
Sequence[tuple[int, int]] | dict[int, Sequence[tuple[int, int]]] | None
|
||||
) = None,
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
color: The color to use for the edges.
|
||||
thickness: The thickness of the edges.
|
||||
edges: The edges to draw. If set to `None`, will attempt to select
|
||||
automatically.
|
||||
edges: The edges to draw. If set to ``None``, will attempt to
|
||||
auto-detect the skeleton by vertex count. A
|
||||
``Sequence[tuple[int, int]]`` applies a single skeleton to
|
||||
every instance. A ``dict[int, Sequence[tuple[int, int]]]``
|
||||
maps ``class_id`` to skeleton edges, enabling correct
|
||||
rendering for datasets with multiple skeleton types.
|
||||
"""
|
||||
self.color = color
|
||||
self.thickness = thickness
|
||||
@@ -128,7 +141,8 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene by drawing lines between specified key points to form
|
||||
edges.
|
||||
edges. Edges where either endpoint is marked as not visible via
|
||||
``key_points.visible`` are skipped.
|
||||
|
||||
Args:
|
||||
scene: The image where skeleton edges will be drawn. `ImageType` is a
|
||||
@@ -141,23 +155,53 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
Single-skeleton example:
|
||||
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> image = np.zeros((100, 100, 3), dtype=np.uint8)
|
||||
>>> image = np.zeros((800, 800, 3), dtype=np.uint8)
|
||||
>>> key_points = sv.KeyPoints(
|
||||
... xy=np.array([[[50, 50], [60, 60]]], dtype=np.float32)
|
||||
... xy=np.array(
|
||||
... [[[400, 200], [300, 500], [500, 500]]],
|
||||
... dtype=np.float32,
|
||||
... ),
|
||||
... class_id=np.array([0]),
|
||||
... visible=np.array([[True, True, True]]),
|
||||
... )
|
||||
>>> edge_annotator = sv.EdgeAnnotator(
|
||||
... color=sv.Color.GREEN,
|
||||
... thickness=5
|
||||
>>> annotator = sv.EdgeAnnotator(
|
||||
... color=sv.Color.ROBOFLOW,
|
||||
... thickness=3,
|
||||
... edges=[(1, 2), (1, 3)],
|
||||
... )
|
||||
>>> annotated_frame = edge_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... key_points=key_points
|
||||
>>> result = annotator.annotate(image.copy(), key_points)
|
||||
|
||||
```
|
||||
|
||||
Multi-skeleton example with per-class edges:
|
||||
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> image = np.zeros((800, 800, 3), dtype=np.uint8)
|
||||
>>> key_points = sv.KeyPoints(
|
||||
... xy=np.array(
|
||||
... [[[400, 200], [300, 500], [500, 500]],
|
||||
... [[700, 300], [650, 500], [0, 0]]],
|
||||
... dtype=np.float32,
|
||||
... ),
|
||||
... class_id=np.array([0, 1]),
|
||||
... visible=np.array(
|
||||
... [[True, True, True],
|
||||
... [True, True, False]],
|
||||
... ),
|
||||
... )
|
||||
>>> annotated_frame.shape
|
||||
(100, 100, 3)
|
||||
>>> annotator = sv.EdgeAnnotator(
|
||||
... color=sv.Color.ROBOFLOW,
|
||||
... thickness=3,
|
||||
... edges={0: [(1, 2), (1, 3)], 1: [(1, 2)]},
|
||||
... )
|
||||
>>> result = annotator.annotate(image.copy(), key_points)
|
||||
|
||||
```
|
||||
"""
|
||||
@@ -165,21 +209,43 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
for xy in key_points.xy:
|
||||
edges = self.edges
|
||||
if not edges:
|
||||
edges = SKELETONS_BY_VERTEX_COUNT.get(len(xy))
|
||||
if not edges:
|
||||
logger.warning("No skeleton found with %d vertices", len(xy))
|
||||
return scene
|
||||
for detection_index, xy in enumerate(key_points.xy):
|
||||
if isinstance(self.edges, dict):
|
||||
class_id = (
|
||||
int(key_points.class_id[detection_index])
|
||||
if key_points.class_id is not None
|
||||
else None
|
||||
)
|
||||
if class_id is None:
|
||||
raise ValueError(
|
||||
"edges is a dict but class_id is None; "
|
||||
"KeyPoints must have class_id set."
|
||||
)
|
||||
if class_id not in self.edges:
|
||||
raise ValueError(f"No edges defined for class_id={class_id}.")
|
||||
edges = self.edges[class_id]
|
||||
elif self.edges:
|
||||
edges = self.edges
|
||||
else:
|
||||
_looked_up = SKELETONS_BY_VERTEX_COUNT.get(len(xy))
|
||||
if not _looked_up:
|
||||
logger.warning("No skeleton found with %d vertices", len(xy))
|
||||
continue
|
||||
edges = _looked_up
|
||||
|
||||
for class_a, class_b in edges:
|
||||
xy_a = xy[class_a - 1]
|
||||
xy_b = xy[class_b - 1]
|
||||
missing_a = np.allclose(xy_a, 0)
|
||||
missing_b = np.allclose(xy_b, 0)
|
||||
if missing_a or missing_b:
|
||||
idx_a = class_a - 1
|
||||
idx_b = class_b - 1
|
||||
xy_a = xy[idx_a]
|
||||
xy_b = xy[idx_b]
|
||||
if np.allclose(xy_a, 0) or np.allclose(xy_b, 0):
|
||||
continue
|
||||
if key_points.visible is not None:
|
||||
if (
|
||||
not key_points.visible[detection_index, idx_a]
|
||||
or not key_points.visible[detection_index, idx_b]
|
||||
):
|
||||
continue
|
||||
|
||||
cv2.line(
|
||||
img=scene,
|
||||
@@ -192,6 +258,448 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
return scene
|
||||
|
||||
|
||||
class _BaseVertexEllipseAnnotator(BaseKeyPointAnnotator):
|
||||
"""Private base for ellipse-based keypoint annotators.
|
||||
|
||||
Handles sigma/color validation, sorting, covariance extraction and
|
||||
eigendecomposition shared by all VertexEllipse* variants.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
sigma: float | Sequence[float] = (1.0, 2.0, 3.0),
|
||||
color: Color | Sequence[Color] = (Color.GREEN, Color.YELLOW, Color.RED),
|
||||
max_axis: float | None = None,
|
||||
) -> None:
|
||||
sigma_seq: Sequence[float] = (
|
||||
(sigma,) if isinstance(sigma, (int, float)) else sigma
|
||||
)
|
||||
color_seq: Sequence[Color] = (color,) if isinstance(color, Color) else color
|
||||
|
||||
if len(sigma_seq) == 0:
|
||||
raise ValueError("sigma must contain at least one value")
|
||||
if any(s <= 0 for s in sigma_seq):
|
||||
raise ValueError("All sigma values must be positive")
|
||||
if max_axis is not None and max_axis <= 0:
|
||||
raise ValueError("max_axis must be positive when provided")
|
||||
if len(color_seq) != len(sigma_seq):
|
||||
raise ValueError(
|
||||
f"color length ({len(color_seq)}) must match "
|
||||
f"sigma length ({len(sigma_seq)})"
|
||||
)
|
||||
|
||||
sorted_indices = sorted(
|
||||
range(len(sigma_seq)), key=lambda i: sigma_seq[i], reverse=True
|
||||
)
|
||||
self.sigma = [sigma_seq[i] for i in sorted_indices]
|
||||
self.color = [color_seq[i] for i in sorted_indices]
|
||||
self.max_axis = max_axis
|
||||
|
||||
def _get_covariances(self, key_points: KeyPoints) -> npt.NDArray[np.float32]:
|
||||
covariances = key_points.data.get("covariance")
|
||||
if covariances is None:
|
||||
raise ValueError(
|
||||
"key_points.data must contain 'covariance' with shape (N, K, 2, 2)."
|
||||
)
|
||||
covariances_array = cast(
|
||||
npt.NDArray[np.float32], np.asarray(covariances, dtype=np.float32)
|
||||
)
|
||||
expected_shape = (*key_points.xy.shape[:2], 2, 2)
|
||||
if covariances_array.shape != expected_shape:
|
||||
raise ValueError(
|
||||
f"Expected covariance shape {expected_shape}, "
|
||||
f"got {covariances_array.shape}."
|
||||
)
|
||||
return covariances_array
|
||||
|
||||
def _decompose_covariance(
|
||||
self, covariance: npt.NDArray[np.float32]
|
||||
) -> tuple[npt.NDArray[np.float64], npt.NDArray[np.float64]] | None:
|
||||
"""Eigendecompose a 2x2 covariance, returning sorted (eigenvalues, vectors)."""
|
||||
if not np.isfinite(covariance).all():
|
||||
return None
|
||||
try:
|
||||
eigenvalues, eigenvectors = np.linalg.eigh(covariance.astype(np.float64))
|
||||
except np.linalg.LinAlgError:
|
||||
return None
|
||||
if not np.isfinite(eigenvalues).all() or np.any(eigenvalues <= 0):
|
||||
return None
|
||||
order = np.argsort(eigenvalues)[::-1]
|
||||
return eigenvalues[order], eigenvectors[:, order]
|
||||
|
||||
def _iter_ellipse_params(
|
||||
self, key_points: KeyPoints
|
||||
) -> list[list[tuple[tuple[int, int], tuple[int, int], float, float, Color]]]:
|
||||
"""Return ellipse params grouped by sigma level (outermost first)."""
|
||||
covariances = self._get_covariances(key_points)
|
||||
levels: list[
|
||||
list[tuple[tuple[int, int], tuple[int, int], float, float, Color]]
|
||||
] = [[] for _ in self.sigma]
|
||||
for detection_index, xy in enumerate(key_points.xy):
|
||||
for point_index, (x, y) in enumerate(xy):
|
||||
if np.allclose((x, y), 0):
|
||||
continue
|
||||
if (
|
||||
key_points.visible is not None
|
||||
and not key_points.visible[detection_index, point_index]
|
||||
):
|
||||
continue
|
||||
covariance = covariances[detection_index, point_index]
|
||||
decomposition = self._decompose_covariance(covariance)
|
||||
if decomposition is None:
|
||||
continue
|
||||
eigenvalues, eigenvectors = decomposition
|
||||
angle = float(
|
||||
np.degrees(np.arctan2(eigenvectors[1, 0], eigenvectors[0, 0]))
|
||||
)
|
||||
center = (round(x), round(y))
|
||||
for level_idx, (sigma, color) in enumerate(zip(self.sigma, self.color)):
|
||||
axes = sigma * np.sqrt(eigenvalues)
|
||||
if self.max_axis is not None:
|
||||
axes = np.minimum(axes, self.max_axis)
|
||||
axis_lengths = (
|
||||
max(1, round(axes[0])),
|
||||
max(1, round(axes[1])),
|
||||
)
|
||||
levels[level_idx].append(
|
||||
(center, axis_lengths, angle, sigma, color)
|
||||
)
|
||||
return levels
|
||||
|
||||
|
||||
class VertexEllipseAreaAnnotator(_BaseVertexEllipseAnnotator):
|
||||
"""
|
||||
Draws filled semi-transparent covariance ellipses at multiple sigma levels
|
||||
around each keypoint, each ring in a different color. This produces a
|
||||
bullseye-like uncertainty visualization where inner rings represent higher
|
||||
probability density.
|
||||
|
||||
!!! warning
|
||||
|
||||
This annotator uses `key_points.data["covariance"]` with shape
|
||||
`(N, K, 2, 2)` in pixel coordinates.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
sigma: float | Sequence[float] = (1.0, 2.0, 3.0),
|
||||
color: Color | Sequence[Color] = (Color.GREEN, Color.YELLOW, Color.RED),
|
||||
opacity: float = 0.4,
|
||||
max_axis: float | None = None,
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
sigma: Sigma multipliers for each ring, drawn from outermost to
|
||||
innermost. Accepts a single float or a sequence of floats.
|
||||
Defaults to ``(1.0, 2.0, 3.0)``.
|
||||
color: The color for each sigma level. Accepts a single
|
||||
``Color`` or a sequence of colors (one per sigma level).
|
||||
Defaults to ``(Color.GREEN, Color.YELLOW, Color.RED)``.
|
||||
opacity: Opacity of the overlay mask. Must be between ``0`` and
|
||||
``1``.
|
||||
max_axis: Optional cap for ellipse semi-axis lengths in pixels.
|
||||
"""
|
||||
super().__init__(sigma=sigma, color=color, max_axis=max_axis)
|
||||
self.opacity = opacity
|
||||
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Draws filled semi-transparent covariance ellipses around each keypoint.
|
||||
|
||||
Args:
|
||||
scene: The image to annotate. ``ImageType`` accepts either
|
||||
``numpy.ndarray`` or ``PIL.Image.Image``.
|
||||
key_points: Key points with covariance data in
|
||||
``key_points.data["covariance"]``.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of ``scene``.
|
||||
|
||||
Example:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> image = np.zeros((800, 800, 3), dtype=np.uint8)
|
||||
>>> key_points = sv.KeyPoints(
|
||||
... xy=np.array(
|
||||
... [[[400, 200], [300, 500], [500, 500]]],
|
||||
... dtype=np.float32,
|
||||
... ),
|
||||
... class_id=np.array([0]),
|
||||
... visible=np.array([[True, True, True]]),
|
||||
... data={
|
||||
... "covariance": np.array(
|
||||
... [[[[800, 0], [0, 400]],
|
||||
... [[400, 0], [0, 800]],
|
||||
... [[600, 0], [0, 600]]]],
|
||||
... dtype=np.float32,
|
||||
... )
|
||||
... },
|
||||
... )
|
||||
>>> annotator = sv.VertexEllipseAreaAnnotator(
|
||||
... sigma=[1.0, 2.0],
|
||||
... color=[sv.Color.GREEN, sv.Color.RED],
|
||||
... )
|
||||
>>> result = annotator.annotate(image.copy(), key_points)
|
||||
|
||||
```
|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
overlay = scene.copy()
|
||||
for level in self._iter_ellipse_params(key_points):
|
||||
for center, axis_lengths, angle, _sigma, color in level:
|
||||
cv2.ellipse(
|
||||
img=overlay,
|
||||
center=center,
|
||||
axes=axis_lengths,
|
||||
angle=angle,
|
||||
startAngle=0,
|
||||
endAngle=360,
|
||||
color=color.as_bgr(),
|
||||
thickness=-1,
|
||||
lineType=cv2.LINE_AA,
|
||||
)
|
||||
|
||||
cv2.addWeighted(overlay, self.opacity, scene, 1 - self.opacity, 0, dst=scene)
|
||||
return scene
|
||||
|
||||
|
||||
class VertexEllipseOutlineAnnotator(_BaseVertexEllipseAnnotator):
|
||||
"""
|
||||
Draws stroke-only concentric covariance ellipse rings at multiple sigma
|
||||
levels around each keypoint.
|
||||
|
||||
!!! warning
|
||||
|
||||
This annotator uses `key_points.data["covariance"]` with shape
|
||||
`(N, K, 2, 2)` in pixel coordinates.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
sigma: float | Sequence[float] = (1.0, 2.0, 3.0),
|
||||
color: Color | Sequence[Color] = (Color.GREEN, Color.YELLOW, Color.RED),
|
||||
thickness: int = 2,
|
||||
max_axis: float | None = None,
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
sigma: Sigma multipliers for each ring, drawn from outermost to
|
||||
innermost. Accepts a single float or a sequence of floats.
|
||||
Defaults to ``(1.0, 2.0, 3.0)``.
|
||||
color: The color for each sigma level. Accepts a single
|
||||
``Color`` or a sequence of colors (one per sigma level).
|
||||
Defaults to ``(Color.GREEN, Color.YELLOW, Color.RED)``.
|
||||
thickness: Line thickness of the ellipse outlines.
|
||||
max_axis: Optional cap for ellipse semi-axis lengths in pixels.
|
||||
"""
|
||||
super().__init__(sigma=sigma, color=color, max_axis=max_axis)
|
||||
self.thickness = thickness
|
||||
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Draws stroke-only covariance ellipse outlines around each keypoint.
|
||||
|
||||
Args:
|
||||
scene: The image to annotate. ``ImageType`` accepts either
|
||||
``numpy.ndarray`` or ``PIL.Image.Image``.
|
||||
key_points: Key points with covariance data in
|
||||
``key_points.data["covariance"]``.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of ``scene``.
|
||||
|
||||
Example:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> image = np.zeros((800, 800, 3), dtype=np.uint8)
|
||||
>>> key_points = sv.KeyPoints(
|
||||
... xy=np.array(
|
||||
... [[[400, 200], [300, 500], [500, 500]]],
|
||||
... dtype=np.float32,
|
||||
... ),
|
||||
... class_id=np.array([0]),
|
||||
... visible=np.array([[True, True, True]]),
|
||||
... data={
|
||||
... "covariance": np.array(
|
||||
... [[[[800, 0], [0, 400]],
|
||||
... [[400, 0], [0, 800]],
|
||||
... [[600, 0], [0, 600]]]],
|
||||
... dtype=np.float32,
|
||||
... )
|
||||
... },
|
||||
... )
|
||||
>>> annotator = sv.VertexEllipseOutlineAnnotator(
|
||||
... sigma=[1.0, 2.0],
|
||||
... color=[sv.Color.GREEN, sv.Color.RED],
|
||||
... thickness=2,
|
||||
... )
|
||||
>>> result = annotator.annotate(image.copy(), key_points)
|
||||
|
||||
```
|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
for level in self._iter_ellipse_params(key_points):
|
||||
for center, axis_lengths, angle, _sigma, color in level:
|
||||
cv2.ellipse(
|
||||
img=scene,
|
||||
center=center,
|
||||
axes=axis_lengths,
|
||||
angle=angle,
|
||||
startAngle=0,
|
||||
endAngle=360,
|
||||
color=color.as_bgr(),
|
||||
thickness=self.thickness,
|
||||
lineType=cv2.LINE_AA,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
class VertexEllipseHaloAnnotator(_BaseVertexEllipseAnnotator):
|
||||
"""
|
||||
Draws filled covariance ellipses with a radial fade: full opacity at the
|
||||
center, smoothly falling off to zero at the ellipse boundary. The falloff
|
||||
follows a power curve controlled by ``decay``, producing a soft glow that
|
||||
is strongest near the keypoint.
|
||||
|
||||
!!! warning
|
||||
|
||||
This annotator uses `key_points.data["covariance"]` with shape
|
||||
`(N, K, 2, 2)` in pixel coordinates.
|
||||
"""
|
||||
|
||||
_DECAY: float = 2.0
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
sigma: float | Sequence[float] = (1.0, 2.0, 3.0),
|
||||
color: Color | Sequence[Color] = (Color.GREEN, Color.YELLOW, Color.RED),
|
||||
opacity: float = 0.6,
|
||||
max_axis: float | None = None,
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
sigma: Sigma multipliers for each ring, drawn from outermost to
|
||||
innermost. Accepts a single float or a sequence of floats.
|
||||
Defaults to ``(1.0, 2.0, 3.0)``.
|
||||
color: The color for each sigma level. Accepts a single
|
||||
``Color`` or a sequence of colors (one per sigma level).
|
||||
Defaults to ``(Color.GREEN, Color.YELLOW, Color.RED)``.
|
||||
opacity: Peak opacity at the ellipse center. Must be between ``0``
|
||||
and ``1``.
|
||||
max_axis: Optional cap for ellipse semi-axis lengths in pixels.
|
||||
"""
|
||||
super().__init__(sigma=sigma, color=color, max_axis=max_axis)
|
||||
self.opacity = opacity
|
||||
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Draws radially-fading covariance ellipses around each keypoint.
|
||||
|
||||
Args:
|
||||
scene: The image to annotate. ``ImageType`` accepts either
|
||||
``numpy.ndarray`` or ``PIL.Image.Image``.
|
||||
key_points: Key points with covariance data in
|
||||
``key_points.data["covariance"]``.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of ``scene``.
|
||||
|
||||
Example:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> image = np.zeros((800, 800, 3), dtype=np.uint8)
|
||||
>>> key_points = sv.KeyPoints(
|
||||
... xy=np.array(
|
||||
... [[[400, 200], [300, 500], [500, 500]]],
|
||||
... dtype=np.float32,
|
||||
... ),
|
||||
... class_id=np.array([0]),
|
||||
... visible=np.array([[True, True, True]]),
|
||||
... data={
|
||||
... "covariance": np.array(
|
||||
... [[[[800, 0], [0, 400]],
|
||||
... [[400, 0], [0, 800]],
|
||||
... [[600, 0], [0, 600]]]],
|
||||
... dtype=np.float32,
|
||||
... )
|
||||
... },
|
||||
... )
|
||||
>>> annotator = sv.VertexEllipseHaloAnnotator(
|
||||
... sigma=[1.0, 2.0],
|
||||
... color=[sv.Color.GREEN, sv.Color.RED],
|
||||
... )
|
||||
>>> result = annotator.annotate(image.copy(), key_points)
|
||||
|
||||
```
|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
h, w = scene.shape[:2]
|
||||
composite: npt.NDArray[np.float32] = scene.astype(np.float32)
|
||||
|
||||
for level in self._iter_ellipse_params(key_points):
|
||||
for center, axis_lengths, angle, _sigma, color in level:
|
||||
ax, ay = axis_lengths
|
||||
if ax == 0 or ay == 0:
|
||||
continue
|
||||
|
||||
pad = 2
|
||||
roi_half_w = ax + pad
|
||||
roi_half_h = ay + pad
|
||||
cx, cy = center
|
||||
|
||||
x_min = max(cx - roi_half_w, 0)
|
||||
x_max = min(cx + roi_half_w, w)
|
||||
y_min = max(cy - roi_half_h, 0)
|
||||
y_max = min(cy + roi_half_h, h)
|
||||
if x_min >= x_max or y_min >= y_max:
|
||||
continue
|
||||
|
||||
ys = np.arange(y_min, y_max, dtype=np.float32) - cy
|
||||
xs = np.arange(x_min, x_max, dtype=np.float32) - cx
|
||||
grid_x, grid_y = np.meshgrid(xs, ys)
|
||||
|
||||
angle_rad = np.radians(-angle)
|
||||
cos_a = np.cos(angle_rad)
|
||||
sin_a = np.sin(angle_rad)
|
||||
rx = grid_x * cos_a - grid_y * sin_a
|
||||
ry = grid_x * sin_a + grid_y * cos_a
|
||||
|
||||
dist_sq = (rx / ax) ** 2 + (ry / ay) ** 2
|
||||
inside = dist_sq <= 1.0
|
||||
|
||||
falloff = np.zeros_like(dist_sq)
|
||||
falloff[inside] = (1.0 - dist_sq[inside]) ** self._DECAY
|
||||
|
||||
scaled_alpha = falloff * self.opacity
|
||||
|
||||
bgr = np.array(color.as_bgr(), dtype=np.float32)
|
||||
roi = composite[y_min:y_max, x_min:x_max]
|
||||
alpha_3 = scaled_alpha[:, :, np.newaxis]
|
||||
roi[:] = roi * (1 - alpha_3) + bgr * alpha_3
|
||||
|
||||
np.copyto(scene, composite.astype(np.uint8))
|
||||
return scene
|
||||
|
||||
|
||||
VertexEllipseAnnotator = VertexEllipseAreaAnnotator
|
||||
|
||||
|
||||
class VertexLabelAnnotator:
|
||||
"""
|
||||
A class that draws labels of skeleton vertices on images. It uses specified key
|
||||
@@ -210,15 +718,15 @@ class VertexLabelAnnotator:
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
color: The color to use for each keypoint label. If a list is provided,
|
||||
the colors will be used in order for each keypoint.
|
||||
text_color: The color to use for the labels. If a list is provided, the
|
||||
colors will be used in order for each keypoint.
|
||||
color: The color to use for each keypoint label. If a list is
|
||||
provided, the colors will be used in order for each keypoint.
|
||||
text_color: The color to use for the labels. If a list is
|
||||
provided, the colors will be used in order for each keypoint.
|
||||
text_scale: The scale of the text.
|
||||
text_thickness: The thickness of the text.
|
||||
text_padding: The padding around the text.
|
||||
border_radius: The radius of the rounded corners of the boxes. Set to a
|
||||
high value to produce circles.
|
||||
border_radius: The radius of the rounded corners of the boxes.
|
||||
Set to a high value to produce circles.
|
||||
smart_position: Spread out the labels to avoid overlap.
|
||||
"""
|
||||
self.border_radius: int = border_radius
|
||||
@@ -233,96 +741,88 @@ class VertexLabelAnnotator:
|
||||
self,
|
||||
scene: ImageType,
|
||||
key_points: KeyPoints,
|
||||
labels: list[str] | None = None,
|
||||
labels: list[str] | dict[int, list[str]] | None = None,
|
||||
) -> ImageType:
|
||||
"""
|
||||
A class that draws labels of skeleton vertices on images. It uses specified key
|
||||
points to determine the locations where the vertices should be drawn.
|
||||
Draws labels at skeleton vertex positions on the image. Vertices
|
||||
marked not visible via ``key_points.visible`` are skipped.
|
||||
|
||||
Args:
|
||||
scene: The image where vertex labels will be drawn. `ImageType` is a
|
||||
flexible type, accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
key_points: A collection of key points where each key point consists of x
|
||||
and y coordinates.
|
||||
labels: A list of labels to be displayed on the annotated image. If not
|
||||
provided, keypoint indices will be used.
|
||||
labels: Labels to display at each keypoint. If ``None``, keypoint
|
||||
indices are used. A ``list[str]`` applies the same labels to
|
||||
every instance. A ``dict[int, list[str]]`` maps ``class_id``
|
||||
to per-class label lists, enabling correct labeling for
|
||||
datasets with multiple skeleton types.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
Single-skeleton example:
|
||||
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> image = np.zeros((100, 100, 3), dtype=np.uint8)
|
||||
>>> image = np.zeros((800, 800, 3), dtype=np.uint8)
|
||||
>>> key_points = sv.KeyPoints(
|
||||
... xy=np.array([[[50, 50], [60, 60]]], dtype=np.float32)
|
||||
... xy=np.array(
|
||||
... [[[400, 200], [300, 500], [500, 500]]],
|
||||
... dtype=np.float32,
|
||||
... ),
|
||||
... class_id=np.array([0]),
|
||||
... visible=np.array([[True, True, True]]),
|
||||
... )
|
||||
>>> vertex_label_annotator = sv.VertexLabelAnnotator(
|
||||
... color=sv.Color.GREEN,
|
||||
... text_color=sv.Color.BLACK,
|
||||
... border_radius=5
|
||||
>>> annotator = sv.VertexLabelAnnotator(
|
||||
... color=sv.Color.ROBOFLOW,
|
||||
... text_color=sv.Color.WHITE,
|
||||
... border_radius=5,
|
||||
... )
|
||||
>>> annotated_frame = vertex_label_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... key_points=key_points
|
||||
... )
|
||||
>>> annotated_frame.shape
|
||||
(100, 100, 3)
|
||||
|
||||
```
|
||||
|
||||
|
||||
|
||||
!!! tip
|
||||
|
||||
`VertexLabelAnnotator` allows to customize the color of each keypoint label
|
||||
values.
|
||||
|
||||
Example:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> image = np.zeros((100, 100, 3), dtype=np.uint8)
|
||||
>>> key_points = sv.KeyPoints(
|
||||
... xy=np.array([[[50, 50], [60, 60], [70, 70], [80, 80],
|
||||
... [90, 90], [40, 40], [30, 30], [20, 20],
|
||||
... [10, 10], [5, 5], [15, 15], [25, 25],
|
||||
... [35, 35], [45, 45], [55, 55], [65, 65],
|
||||
... [75, 75]]], dtype=np.float32)
|
||||
... )
|
||||
>>> LABELS = [
|
||||
... "nose", "left eye", "right eye", "left ear",
|
||||
... "right ear", "left shoulder", "right shoulder", "left elbow",
|
||||
... "right elbow", "left wrist", "right wrist", "left hip",
|
||||
... "right hip", "left knee", "right knee", "left ankle",
|
||||
... "right ankle"
|
||||
... ]
|
||||
>>> COLORS = [
|
||||
... "#FF6347", "#FF6347", "#FF6347", "#FF6347",
|
||||
... "#FF6347", "#FF1493", "#00FF00", "#FF1493",
|
||||
... "#00FF00", "#FF1493", "#00FF00", "#FFD700",
|
||||
... "#00BFFF", "#FFD700", "#00BFFF", "#FFD700",
|
||||
... "#00BFFF"
|
||||
... ]
|
||||
>>> COLORS = [sv.Color.from_hex(color_hex=c) for c in COLORS]
|
||||
>>> vertex_label_annotator = sv.VertexLabelAnnotator(
|
||||
... color=COLORS,
|
||||
... text_color=sv.Color.BLACK,
|
||||
... border_radius=5
|
||||
... )
|
||||
>>> annotated_frame = vertex_label_annotator.annotate(
|
||||
>>> result = annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... key_points=key_points,
|
||||
... labels=LABELS
|
||||
... labels=["head", "L-foot", "R-foot"],
|
||||
... )
|
||||
>>> annotated_frame.shape
|
||||
(100, 100, 3)
|
||||
|
||||
```
|
||||
|
||||
|
||||
Multi-skeleton example with per-class labels:
|
||||
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> image = np.zeros((800, 800, 3), dtype=np.uint8)
|
||||
>>> key_points = sv.KeyPoints(
|
||||
... xy=np.array(
|
||||
... [[[400, 200], [300, 500], [500, 500]],
|
||||
... [[700, 300], [650, 500], [0, 0]]],
|
||||
... dtype=np.float32,
|
||||
... ),
|
||||
... class_id=np.array([0, 1]),
|
||||
... visible=np.array(
|
||||
... [[True, True, True],
|
||||
... [True, True, False]],
|
||||
... ),
|
||||
... )
|
||||
>>> annotator = sv.VertexLabelAnnotator(
|
||||
... color=sv.Color.ROBOFLOW,
|
||||
... text_color=sv.Color.WHITE,
|
||||
... border_radius=5,
|
||||
... )
|
||||
>>> result = annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... key_points=key_points,
|
||||
... labels={
|
||||
... 0: ["head", "L-foot", "R-foot"],
|
||||
... 1: ["top", "bottom", "pad"],
|
||||
... },
|
||||
... )
|
||||
|
||||
```
|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
font = cv2.FONT_HERSHEY_SIMPLEX
|
||||
@@ -331,33 +831,39 @@ class VertexLabelAnnotator:
|
||||
if skeletons_count == 0:
|
||||
return scene
|
||||
|
||||
anchors = key_points.xy.reshape(points_count * skeletons_count, 2).astype(int)
|
||||
mask = np.all(anchors != 0, axis=1)
|
||||
all_anchors: list[tuple[int, int]] = []
|
||||
all_labels: list[str] = []
|
||||
all_colors: list[Color] = []
|
||||
all_text_colors: list[Color] = []
|
||||
|
||||
if not np.any(mask):
|
||||
for i in range(skeletons_count):
|
||||
xy = key_points.xy[i]
|
||||
|
||||
class_id = (
|
||||
int(key_points.class_id[i]) if key_points.class_id is not None else None
|
||||
)
|
||||
instance_labels = self._resolve_labels(labels, points_count, class_id)
|
||||
instance_colors = self._resolve_color_list(self.color, points_count)
|
||||
instance_text_colors = self._resolve_color_list(
|
||||
self.text_color, points_count
|
||||
)
|
||||
|
||||
for j in range(points_count):
|
||||
if key_points.visible is not None:
|
||||
if not key_points.visible[i, j]:
|
||||
continue
|
||||
elif np.allclose(xy[j], 0):
|
||||
continue
|
||||
|
||||
anchor = (int(xy[j][0]), int(xy[j][1]))
|
||||
all_anchors.append(anchor)
|
||||
all_labels.append(instance_labels[j])
|
||||
all_colors.append(instance_colors[j])
|
||||
all_text_colors.append(instance_text_colors[j])
|
||||
|
||||
if not all_anchors:
|
||||
return scene
|
||||
|
||||
colors = self.preprocess_and_validate_colors(
|
||||
colors=self.color,
|
||||
points_count=points_count,
|
||||
skeletons_count=skeletons_count,
|
||||
)
|
||||
|
||||
text_colors = self.preprocess_and_validate_colors(
|
||||
colors=self.text_color,
|
||||
points_count=points_count,
|
||||
skeletons_count=skeletons_count,
|
||||
)
|
||||
|
||||
processed_labels = self.preprocess_and_validate_labels(
|
||||
labels=labels, points_count=points_count, skeletons_count=skeletons_count
|
||||
)
|
||||
|
||||
anchors = anchors[mask]
|
||||
colors = colors[mask]
|
||||
text_colors = text_colors[mask]
|
||||
filtered_labels = processed_labels[mask]
|
||||
|
||||
xyxy = np.array(
|
||||
[
|
||||
self.get_text_bounding_box(
|
||||
@@ -365,9 +871,9 @@ class VertexLabelAnnotator:
|
||||
font=font,
|
||||
text_scale=self.text_scale,
|
||||
text_thickness=self.text_thickness,
|
||||
center_coordinates=tuple(anchor),
|
||||
center_coordinates=anchor,
|
||||
)
|
||||
for anchor, label in zip(anchors, filtered_labels)
|
||||
for anchor, label in zip(all_anchors, all_labels)
|
||||
]
|
||||
)
|
||||
xyxy_padded = pad_boxes(xyxy=xyxy, px=self.text_padding)
|
||||
@@ -377,7 +883,7 @@ class VertexLabelAnnotator:
|
||||
xyxy = pad_boxes(xyxy=xyxy_padded, px=-self.text_padding)
|
||||
|
||||
for text, color, text_color, box, box_padded in zip(
|
||||
filtered_labels, colors, text_colors, xyxy, xyxy_padded
|
||||
all_labels, all_colors, all_text_colors, xyxy, xyxy_padded
|
||||
):
|
||||
draw_rounded_rectangle(
|
||||
scene=scene,
|
||||
@@ -421,32 +927,46 @@ class VertexLabelAnnotator:
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def preprocess_and_validate_labels(
|
||||
labels: list[str] | None, points_count: int, skeletons_count: int
|
||||
) -> npt.NDArray[np.str_]:
|
||||
if labels and len(labels) != points_count:
|
||||
raise ValueError(
|
||||
f"Number of labels ({len(labels)}) must match number of key points "
|
||||
f"({points_count})."
|
||||
)
|
||||
def _resolve_labels(
|
||||
labels: list[str] | dict[int, list[str]] | None,
|
||||
points_count: int,
|
||||
class_id: int | None = None,
|
||||
) -> list[str]:
|
||||
"""Return the label list for a single instance."""
|
||||
if labels is None:
|
||||
labels = [str(i) for i in range(points_count)]
|
||||
return [str(j) for j in range(points_count)]
|
||||
|
||||
return np.array(labels * skeletons_count)
|
||||
resolved: list[str]
|
||||
if isinstance(labels, dict):
|
||||
if class_id is None:
|
||||
raise ValueError(
|
||||
"labels is a dict but class_id is None; "
|
||||
"KeyPoints must have class_id set."
|
||||
)
|
||||
if class_id not in labels:
|
||||
raise ValueError(f"No labels defined for class_id={class_id}.")
|
||||
resolved = labels[class_id]
|
||||
else:
|
||||
resolved = labels
|
||||
|
||||
if len(resolved) != points_count:
|
||||
raise ValueError(
|
||||
f"Number of labels ({len(resolved)}) must match "
|
||||
f"number of key points ({points_count})."
|
||||
)
|
||||
return resolved
|
||||
|
||||
@staticmethod
|
||||
def preprocess_and_validate_colors(
|
||||
colors: Color | list[Color] | None,
|
||||
def _resolve_color_list(
|
||||
colors: Color | list[Color],
|
||||
points_count: int,
|
||||
skeletons_count: int,
|
||||
) -> npt.NDArray[Any]:
|
||||
if isinstance(colors, list) and len(colors) != points_count:
|
||||
raise ValueError(
|
||||
f"Number of colors ({len(colors)}) must match number of key points "
|
||||
f"({points_count})."
|
||||
)
|
||||
return (
|
||||
np.array(colors * skeletons_count)
|
||||
if isinstance(colors, list)
|
||||
else np.array([colors] * points_count * skeletons_count)
|
||||
)
|
||||
) -> list[Color]:
|
||||
"""Return a per-keypoint color list for a single instance."""
|
||||
if isinstance(colors, list):
|
||||
if len(colors) != points_count:
|
||||
raise ValueError(
|
||||
f"Number of colors ({len(colors)}) must match "
|
||||
f"number of key points ({points_count})."
|
||||
)
|
||||
return colors
|
||||
return [colors] * points_count
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import logging
|
||||
from collections.abc import Iterable, Iterator
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any, Union, cast
|
||||
@@ -10,7 +11,14 @@ import numpy.typing as npt
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils.internal import get_data_item, is_data_equal
|
||||
from supervision.validators import validate_key_points_fields
|
||||
from supervision.detection.utils.iou_and_nms import (
|
||||
OverlapMetric,
|
||||
box_non_max_suppression,
|
||||
)
|
||||
from supervision.utils.internal import warn_deprecated
|
||||
from supervision.validators import _validate_keypoints_fields
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
Index1D = Union[
|
||||
int,
|
||||
@@ -21,9 +29,49 @@ Index1D = Union[
|
||||
npt.NDArray[np.bool_],
|
||||
]
|
||||
Index2D = tuple[Index1D, Index1D]
|
||||
_RowIndexInput = Union[
|
||||
int,
|
||||
np.integer[Any],
|
||||
npt.NDArray[np.generic],
|
||||
list[Any],
|
||||
slice,
|
||||
]
|
||||
_NormalizedRowIndex = Union[npt.NDArray[np.generic], list[Any], slice]
|
||||
|
||||
|
||||
@dataclass
|
||||
def _optional_array_equal(
|
||||
first: npt.NDArray[np.generic] | None,
|
||||
second: npt.NDArray[np.generic] | None,
|
||||
) -> bool:
|
||||
if first is None or second is None:
|
||||
return first is None and second is None
|
||||
return np.array_equal(first, second)
|
||||
|
||||
|
||||
def _normalize_row_index(
|
||||
i: _RowIndexInput,
|
||||
) -> _NormalizedRowIndex:
|
||||
"""Normalise *i* to a 1-D row index for 1-D per-object fields.
|
||||
|
||||
Handles:
|
||||
- Python int or np.integer scalar -> np.array([int(i)])
|
||||
- boolean np.ndarray (any shape) -> np.flatnonzero(i.ravel())
|
||||
- non-bool 0-d np.ndarray -> reshaped to shape (1,)
|
||||
- list of bool -> np.flatnonzero(np.array(i))
|
||||
- slice, list of ints, 1-D ndarray -> returned as-is
|
||||
"""
|
||||
if isinstance(i, (int, np.integer)):
|
||||
return cast(_NormalizedRowIndex, np.array([int(i)]))
|
||||
if isinstance(i, np.ndarray) and i.dtype == bool:
|
||||
return cast(_NormalizedRowIndex, np.flatnonzero(i.ravel()))
|
||||
if isinstance(i, np.ndarray) and i.ndim == 0:
|
||||
return cast(_NormalizedRowIndex, i.reshape(1))
|
||||
if isinstance(i, list) and i and all(isinstance(x, bool) for x in i):
|
||||
return cast(_NormalizedRowIndex, np.flatnonzero(np.array(i)))
|
||||
return i
|
||||
|
||||
|
||||
@dataclass(init=False)
|
||||
class KeyPoints:
|
||||
"""
|
||||
The `sv.KeyPoints` class in the Supervision library standardizes results from
|
||||
@@ -31,6 +79,23 @@ class KeyPoints:
|
||||
class simplifies data manipulation and filtering, providing a uniform API for
|
||||
integration with Supervision [keypoints annotators](/latest/keypoint/annotators).
|
||||
|
||||
=== "RF-DETR"
|
||||
|
||||
[RF-DETR](https://github.com/roboflow/rf-detr) keypoint models return
|
||||
`sv.KeyPoints` directly from `model.predict()` — no additional
|
||||
conversion is needed.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from rfdetr import RFDETRKeypointPreview
|
||||
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
model = RFDETRKeypointPreview()
|
||||
|
||||
key_points = model.predict(image)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
Use [`sv.KeyPoints.from_ultralytics`](/latest/keypoint/core/#supervision.key_points.core.KeyPoints.from_ultralytics)
|
||||
@@ -156,8 +221,14 @@ class KeyPoints:
|
||||
sets of key points, where each point is `[x, y]`.
|
||||
class_id: An array of shape
|
||||
`(n,)` containing the class ids of the detected objects.
|
||||
confidence: An array of shape
|
||||
keypoint_confidence: An array of shape
|
||||
`(n, m)` containing the confidence scores of each keypoint.
|
||||
detection_confidence: An array of shape
|
||||
`(n,)` containing the detection-level confidence scores.
|
||||
visible: An optional boolean array of shape
|
||||
`(n, m)` indicating which keypoints are visible. When ``None``,
|
||||
all keypoints are treated as visible. Set this to filter anchors
|
||||
without removing data: ``key_points.visible = key_points.keypoint_confidence > 0.3``.
|
||||
data: A dictionary containing additional
|
||||
data where each key is a string representing the data type, and the value
|
||||
is either a NumPy array or a list of corresponding data of length `n`
|
||||
@@ -166,17 +237,91 @@ class KeyPoints:
|
||||
|
||||
xy: npt.NDArray[np.float32]
|
||||
class_id: npt.NDArray[np.int_] | None = None
|
||||
confidence: npt.NDArray[np.float32] | None = None
|
||||
keypoint_confidence: npt.NDArray[np.float32] | None = None
|
||||
detection_confidence: npt.NDArray[np.float32] | None = None
|
||||
visible: npt.NDArray[np.bool_] | None = None
|
||||
data: dict[str, npt.NDArray[np.generic] | list[Any]] = field(default_factory=dict)
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
xy: npt.NDArray[np.float32],
|
||||
class_id: npt.NDArray[np.int_] | None = None,
|
||||
keypoint_confidence: npt.NDArray[np.float32] | None = None,
|
||||
detection_confidence: npt.NDArray[np.float32] | None = None,
|
||||
visible: npt.NDArray[np.bool_] | None = None,
|
||||
data: dict[str, npt.NDArray[np.generic] | list[Any]] | None = None,
|
||||
*,
|
||||
confidence: npt.NDArray[np.float32] | None = None,
|
||||
) -> None:
|
||||
"""Initialize KeyPoints.
|
||||
|
||||
Args:
|
||||
xy: Array of shape `(n, m, 2)` with keypoint coordinates.
|
||||
class_id: Array of shape `(n,)` with class IDs. Defaults to None.
|
||||
keypoint_confidence: Array of shape `(n, m)` with per-keypoint
|
||||
confidence scores. Defaults to None.
|
||||
detection_confidence: Array of shape `(n,)` with detection-level
|
||||
confidence scores. Defaults to None.
|
||||
visible: Boolean array of shape `(n, m)` indicating visible
|
||||
keypoints. Defaults to None.
|
||||
data: Dictionary of additional per-detection data arrays.
|
||||
Defaults to an empty dict.
|
||||
confidence: Deprecated since `0.29.0`, removed in `0.32.0`.
|
||||
Use ``keypoint_confidence`` instead. Raises ``ValueError``
|
||||
if passed together with ``keypoint_confidence``.
|
||||
|
||||
Raises:
|
||||
ValueError: If both ``confidence`` and ``keypoint_confidence``
|
||||
are provided.
|
||||
"""
|
||||
if confidence is not None:
|
||||
if keypoint_confidence is not None:
|
||||
raise ValueError(
|
||||
"Cannot pass both 'confidence' and 'keypoint_confidence'. "
|
||||
"'confidence' is deprecated — use 'keypoint_confidence' only."
|
||||
)
|
||||
warn_deprecated(
|
||||
"'confidence' parameter in `KeyPoints()` is deprecated since "
|
||||
"`0.29.0` and will be removed in `0.32.0`. Use "
|
||||
"'keypoint_confidence' instead."
|
||||
)
|
||||
keypoint_confidence = confidence
|
||||
|
||||
self.xy = xy
|
||||
self.class_id = class_id
|
||||
self.keypoint_confidence = keypoint_confidence
|
||||
self.detection_confidence = detection_confidence
|
||||
self.visible = visible
|
||||
self.data = data if data is not None else {}
|
||||
self.__post_init__()
|
||||
|
||||
def __post_init__(self) -> None:
|
||||
validate_key_points_fields(
|
||||
_validate_keypoints_fields(
|
||||
xy=self.xy,
|
||||
confidence=self.confidence,
|
||||
class_id=self.class_id,
|
||||
confidence=self.keypoint_confidence,
|
||||
detection_confidence=self.detection_confidence,
|
||||
visible=self.visible,
|
||||
data=self.data,
|
||||
)
|
||||
|
||||
@property
|
||||
def confidence(self) -> npt.NDArray[np.float32] | None:
|
||||
"""Deprecated since 0.29.0. Use ``keypoint_confidence`` instead."""
|
||||
warn_deprecated(
|
||||
"'KeyPoints.confidence' is deprecated since 0.29.0 and will be "
|
||||
"removed in 0.32.0. Use 'KeyPoints.keypoint_confidence' instead."
|
||||
)
|
||||
return self.keypoint_confidence
|
||||
|
||||
@confidence.setter
|
||||
def confidence(self, value: npt.NDArray[np.float32] | None) -> None:
|
||||
warn_deprecated(
|
||||
"'KeyPoints.confidence' is deprecated since 0.29.0 and will be "
|
||||
"removed in 0.32.0. Use 'KeyPoints.keypoint_confidence' instead."
|
||||
)
|
||||
self.keypoint_confidence = value
|
||||
|
||||
def __len__(self) -> int:
|
||||
"""
|
||||
Returns the number of objects in the `sv.KeyPoints` object.
|
||||
@@ -209,12 +354,14 @@ class KeyPoints:
|
||||
]:
|
||||
"""
|
||||
Iterates over the Keypoint object and yield a tuple of
|
||||
`(xy, confidence, class_id, data)` for each object detection.
|
||||
`(xy, keypoint_confidence, class_id, data)` for each object detection.
|
||||
"""
|
||||
for i in range(len(self.xy)):
|
||||
yield (
|
||||
self.xy[i],
|
||||
self.confidence[i] if self.confidence is not None else None,
|
||||
self.keypoint_confidence[i]
|
||||
if self.keypoint_confidence is not None
|
||||
else None,
|
||||
self.class_id[i] if self.class_id is not None else None,
|
||||
get_data_item(self.data, i),
|
||||
)
|
||||
@@ -225,8 +372,14 @@ class KeyPoints:
|
||||
return all(
|
||||
[
|
||||
np.array_equal(self.xy, other.xy),
|
||||
np.array_equal(self.class_id, other.class_id),
|
||||
np.array_equal(self.confidence, other.confidence),
|
||||
_optional_array_equal(self.class_id, other.class_id),
|
||||
_optional_array_equal(
|
||||
self.keypoint_confidence, other.keypoint_confidence
|
||||
),
|
||||
_optional_array_equal(
|
||||
self.detection_confidence, other.detection_confidence
|
||||
),
|
||||
_optional_array_equal(self.visible, other.visible),
|
||||
is_data_equal(self.data, other.data),
|
||||
]
|
||||
)
|
||||
@@ -304,11 +457,13 @@ class KeyPoints:
|
||||
class_id.append(prediction["class_id"])
|
||||
class_names.append(prediction["class"])
|
||||
|
||||
data = {CLASS_NAME_DATA_FIELD: np.array(class_names)}
|
||||
data: dict[str, npt.NDArray[np.generic] | list[Any]] = {
|
||||
CLASS_NAME_DATA_FIELD: np.array(class_names)
|
||||
}
|
||||
|
||||
return cls(
|
||||
xy=np.array(xy, dtype=np.float32),
|
||||
confidence=np.array(confidence, dtype=np.float32),
|
||||
keypoint_confidence=np.array(confidence, dtype=np.float32),
|
||||
class_id=np.array(class_id, dtype=int),
|
||||
data=data,
|
||||
)
|
||||
@@ -436,7 +591,7 @@ class KeyPoints:
|
||||
|
||||
return cls(
|
||||
xy=np.array(xy, dtype=np.float32),
|
||||
confidence=np.array(confidence, dtype=np.float32),
|
||||
keypoint_confidence=np.array(confidence, dtype=np.float32),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
@@ -473,8 +628,10 @@ class KeyPoints:
|
||||
class_names = np.array([ultralytics_results.names[i] for i in class_id])
|
||||
|
||||
confidence = ultralytics_results.keypoints.conf.cpu().numpy()
|
||||
data = {CLASS_NAME_DATA_FIELD: class_names}
|
||||
return cls(xy, class_id, confidence, data)
|
||||
data: dict[str, npt.NDArray[np.generic] | list[Any]] = {
|
||||
CLASS_NAME_DATA_FIELD: class_names
|
||||
}
|
||||
return cls(xy=xy, class_id=class_id, keypoint_confidence=confidence, data=data)
|
||||
|
||||
@classmethod
|
||||
def from_yolo_nas(cls, yolo_nas_results: Any) -> KeyPoints:
|
||||
@@ -519,7 +676,7 @@ class KeyPoints:
|
||||
else:
|
||||
class_id = None
|
||||
|
||||
data = {}
|
||||
data: dict[str, npt.NDArray[np.generic] | list[Any]] = {}
|
||||
if class_id is not None and yolo_nas_results.class_names is not None:
|
||||
class_names = []
|
||||
for c_id in class_id:
|
||||
@@ -529,7 +686,7 @@ class KeyPoints:
|
||||
|
||||
return cls(
|
||||
xy=xy,
|
||||
confidence=confidence,
|
||||
keypoint_confidence=confidence,
|
||||
class_id=class_id,
|
||||
data=data,
|
||||
)
|
||||
@@ -574,7 +731,7 @@ class KeyPoints:
|
||||
xy=detectron2_results["instances"]
|
||||
.pred_keypoints.cpu()
|
||||
.numpy()[:, :, :2],
|
||||
confidence=detectron2_results["instances"]
|
||||
keypoint_confidence=detectron2_results["instances"]
|
||||
.pred_keypoints.cpu()
|
||||
.numpy()[:, :, 2],
|
||||
class_id=detectron2_results["instances"]
|
||||
@@ -664,7 +821,7 @@ class KeyPoints:
|
||||
|
||||
return cls(
|
||||
xy=np.stack(xy).astype(np.float32),
|
||||
confidence=np.stack(scores).astype(np.float32),
|
||||
keypoint_confidence=np.stack(scores).astype(np.float32),
|
||||
class_id=np.arange(len(xy)).astype(int),
|
||||
)
|
||||
else:
|
||||
@@ -725,33 +882,93 @@ class KeyPoints:
|
||||
)
|
||||
k = int(counts[0]) if n > 0 else 0
|
||||
xy_selected = np.zeros((n, k, self.xy.shape[2]), dtype=self.xy.dtype)
|
||||
conf_selected: npt.NDArray[np.float32] | None = None
|
||||
if self.confidence is not None:
|
||||
conf_selected = cast(
|
||||
keypoint_confidence_selected: npt.NDArray[np.float32] | None = None
|
||||
if self.keypoint_confidence is not None:
|
||||
keypoint_confidence_selected = cast(
|
||||
npt.NDArray[np.float32],
|
||||
np.zeros((n, k), dtype=self.confidence.dtype),
|
||||
np.zeros((n, k), dtype=self.keypoint_confidence.dtype),
|
||||
)
|
||||
visible_selected: npt.NDArray[np.bool_] | None = None
|
||||
if self.visible is not None:
|
||||
visible_selected = np.zeros((n, k), dtype=bool)
|
||||
for row in range(n):
|
||||
row_indices = np.flatnonzero(mask[row])
|
||||
xy_selected[row] = self.xy[row, row_indices]
|
||||
if conf_selected is not None and self.confidence is not None:
|
||||
conf_selected[row] = self.confidence[row, row_indices]
|
||||
if (
|
||||
keypoint_confidence_selected is not None
|
||||
and self.keypoint_confidence is not None
|
||||
):
|
||||
keypoint_confidence_selected[row] = self.keypoint_confidence[
|
||||
row, row_indices
|
||||
]
|
||||
if visible_selected is not None and self.visible is not None:
|
||||
visible_selected[row] = self.visible[row, row_indices]
|
||||
detection_confidence_selected = None
|
||||
if self.detection_confidence is not None:
|
||||
detection_confidence_selected = self.detection_confidence.copy()
|
||||
|
||||
class_id_selected = None
|
||||
if self.class_id is not None:
|
||||
class_id_selected = self.class_id.copy()
|
||||
|
||||
data_selected = get_data_item(self.data, slice(None))
|
||||
|
||||
return KeyPoints(
|
||||
xy=xy_selected,
|
||||
confidence=conf_selected,
|
||||
class_id=self.class_id.copy() if self.class_id is not None else None,
|
||||
data=get_data_item(self.data, slice(None)),
|
||||
keypoint_confidence=keypoint_confidence_selected,
|
||||
detection_confidence=detection_confidence_selected,
|
||||
visible=visible_selected,
|
||||
class_id=class_id_selected,
|
||||
data=data_selected,
|
||||
)
|
||||
|
||||
def __getitem__(
|
||||
self,
|
||||
index: Index1D | Index2D | str,
|
||||
) -> KeyPoints | npt.NDArray[np.generic] | list[Any] | None:
|
||||
"""
|
||||
Get a subset of the KeyPoints object or access an item from its data field.
|
||||
|
||||
Supports detection-level (skeleton) filtering, keypoint-level (anchor)
|
||||
filtering, combined tuple indexing, and data field access by string key.
|
||||
|
||||
Args:
|
||||
index: The index, indices, or key to access a subset of the KeyPoints
|
||||
or an item from the data.
|
||||
|
||||
Returns:
|
||||
A subset of the KeyPoints object or an item from the data field.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
# detection-level filtering (returns KeyPoints)
|
||||
high_conf = key_points[key_points.detection_confidence > 0.5]
|
||||
class_0 = key_points[key_points.class_id == 0]
|
||||
|
||||
# keypoint-level filtering (returns KeyPoints)
|
||||
visible = key_points[key_points.keypoint_confidence > 0.3]
|
||||
|
||||
# indexing
|
||||
first = key_points[0]
|
||||
first_two = key_points[0:2]
|
||||
subset = key_points[[0, 2]]
|
||||
|
||||
# anchor selection (uniform across all skeletons)
|
||||
nose_and_eyes = key_points[:, [0, 1, 2]]
|
||||
|
||||
# data field access
|
||||
class_names = key_points['class_name']
|
||||
```
|
||||
"""
|
||||
if isinstance(index, str):
|
||||
return self.data.get(index)
|
||||
|
||||
if isinstance(index, np.ndarray) and index.ndim == 2 and index.dtype == bool:
|
||||
return self._get_by_2d_bool_mask(index)
|
||||
return self._get_by_2d_bool_mask(cast(npt.NDArray[np.bool_], index))
|
||||
|
||||
if not isinstance(index, tuple):
|
||||
index = (index, slice(None))
|
||||
@@ -771,43 +988,73 @@ class KeyPoints:
|
||||
if isinstance(j, np.ndarray) and j.dtype == bool:
|
||||
j = np.flatnonzero(j)
|
||||
|
||||
raw_i = i
|
||||
|
||||
if (
|
||||
isinstance(i, (list, np.ndarray))
|
||||
and isinstance(j, (list, np.ndarray))
|
||||
and not np.isscalar(i)
|
||||
and not np.isscalar(j)
|
||||
):
|
||||
i, j = np.ix_(i, j)
|
||||
i_ix, j_ix = np.ix_(cast(Any, i), cast(Any, j))
|
||||
i = cast(Any, i_ix)
|
||||
j = cast(Any, j_ix)
|
||||
|
||||
row_i = _normalize_row_index(raw_i)
|
||||
|
||||
xy_selected = self.xy[i, j]
|
||||
|
||||
conf_selected = self.confidence[i, j] if self.confidence is not None else None
|
||||
keypoint_confidence_selected = None
|
||||
if self.keypoint_confidence is not None:
|
||||
keypoint_confidence_selected = self.keypoint_confidence[i, j]
|
||||
|
||||
class_id_selected = self.class_id[i] if self.class_id is not None else None
|
||||
detection_confidence_selected = None
|
||||
if self.detection_confidence is not None:
|
||||
detection_confidence_selected = self.detection_confidence[row_i]
|
||||
|
||||
data_selected = get_data_item(self.data, i)
|
||||
visible_selected = None
|
||||
if self.visible is not None:
|
||||
visible_selected = self.visible[i, j]
|
||||
|
||||
class_id_selected = self.class_id[row_i] if self.class_id is not None else None
|
||||
|
||||
data_selected = get_data_item(self.data, cast(Any, row_i))
|
||||
|
||||
if xy_selected.ndim == 1:
|
||||
xy_selected = xy_selected.reshape(1, 1, 2)
|
||||
if conf_selected is not None:
|
||||
conf_selected = conf_selected.reshape(1, 1)
|
||||
if keypoint_confidence_selected is not None:
|
||||
keypoint_confidence_selected = keypoint_confidence_selected.reshape(
|
||||
1, 1
|
||||
)
|
||||
if visible_selected is not None:
|
||||
visible_selected = visible_selected.reshape(1, 1)
|
||||
elif xy_selected.ndim == 2:
|
||||
if np.isscalar(index[0]) or (
|
||||
isinstance(index[0], np.ndarray) and index[0].ndim == 0
|
||||
):
|
||||
xy_selected = xy_selected[np.newaxis, ...]
|
||||
if conf_selected is not None:
|
||||
conf_selected = conf_selected[np.newaxis, ...]
|
||||
if keypoint_confidence_selected is not None:
|
||||
keypoint_confidence_selected = keypoint_confidence_selected[
|
||||
np.newaxis, ...
|
||||
]
|
||||
if visible_selected is not None:
|
||||
visible_selected = visible_selected[np.newaxis, ...]
|
||||
elif np.isscalar(index[1]) or (
|
||||
isinstance(index[1], np.ndarray) and index[1].ndim == 0
|
||||
):
|
||||
xy_selected = xy_selected[:, np.newaxis, :]
|
||||
if conf_selected is not None:
|
||||
conf_selected = conf_selected[:, np.newaxis]
|
||||
if keypoint_confidence_selected is not None:
|
||||
keypoint_confidence_selected = keypoint_confidence_selected[
|
||||
:, np.newaxis
|
||||
]
|
||||
if visible_selected is not None:
|
||||
visible_selected = visible_selected[:, np.newaxis]
|
||||
|
||||
return KeyPoints(
|
||||
xy=xy_selected,
|
||||
confidence=conf_selected,
|
||||
keypoint_confidence=keypoint_confidence_selected,
|
||||
detection_confidence=detection_confidence_selected,
|
||||
visible=visible_selected,
|
||||
class_id=class_id_selected,
|
||||
data=data_selected,
|
||||
)
|
||||
@@ -886,6 +1133,94 @@ class KeyPoints:
|
||||
empty_key_points.data = self.data
|
||||
return self == empty_key_points
|
||||
|
||||
def with_nms(
|
||||
self,
|
||||
threshold: float = 0.5,
|
||||
class_agnostic: bool = False,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> KeyPoints:
|
||||
"""
|
||||
Performs non-max suppression on the keypoint detections. Bounding boxes
|
||||
are derived from valid keypoints of each skeleton, and standard box NMS
|
||||
is applied. A keypoint is considered valid when its coordinates are not
|
||||
all-zero and its `visible` flag is `True` (if `visible` is set).
|
||||
|
||||
Args:
|
||||
threshold: The intersection-over-union threshold to use for
|
||||
non-maximum suppression. Must be in [0, 1]. Defaults to 0.5.
|
||||
class_agnostic: Whether to perform class-agnostic non-maximum
|
||||
suppression. If True, the class_id of each detection will be
|
||||
ignored. Defaults to False.
|
||||
overlap_metric: Metric used to compute the degree of overlap
|
||||
between pairs of bounding boxes. Defaults to
|
||||
`OverlapMetric.IOU`.
|
||||
|
||||
Returns:
|
||||
A new `sv.KeyPoints` object after non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
ValueError: If `detection_confidence` is None.
|
||||
ValueError: If `class_agnostic` is False and `class_id`
|
||||
is None.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from rfdetr import RFDETRKeypointPreview
|
||||
|
||||
image = cv2.imread("<SOURCE_IMAGE_PATH>")
|
||||
model = RFDETRKeypointPreview()
|
||||
|
||||
key_points = model.predict(image)
|
||||
key_points = key_points.with_nms(threshold=0.5)
|
||||
```
|
||||
"""
|
||||
if len(self) == 0:
|
||||
return self
|
||||
|
||||
if self.detection_confidence is None:
|
||||
raise ValueError(
|
||||
"KeyPoints detection_confidence must be given for NMS to be executed."
|
||||
)
|
||||
|
||||
if not class_agnostic and self.class_id is None:
|
||||
raise ValueError(
|
||||
"KeyPoints class_id must be given for NMS to be executed. If "
|
||||
"you intended to perform class agnostic NMS set "
|
||||
"class_agnostic=True."
|
||||
)
|
||||
|
||||
xy = self.xy
|
||||
valid = ~np.all(xy == 0, axis=-1)
|
||||
if self.visible is not None:
|
||||
valid = valid & self.visible
|
||||
x_min = np.min(np.where(valid, xy[..., 0], np.inf), axis=1)
|
||||
y_min = np.min(np.where(valid, xy[..., 1], np.inf), axis=1)
|
||||
x_max = np.max(np.where(valid, xy[..., 0], -np.inf), axis=1)
|
||||
y_max = np.max(np.where(valid, xy[..., 1], -np.inf), axis=1)
|
||||
xyxy = np.stack([x_min, y_min, x_max, y_max], axis=1).astype(np.float32)
|
||||
|
||||
if class_agnostic:
|
||||
predictions = np.hstack([xyxy, self.detection_confidence.reshape(-1, 1)])
|
||||
else:
|
||||
class_id = cast(npt.NDArray[np.int_], self.class_id)
|
||||
predictions = np.hstack(
|
||||
[
|
||||
xyxy,
|
||||
self.detection_confidence.reshape(-1, 1),
|
||||
class_id.reshape(-1, 1),
|
||||
]
|
||||
)
|
||||
|
||||
keep = box_non_max_suppression(
|
||||
predictions=predictions,
|
||||
iou_threshold=threshold,
|
||||
overlap_metric=overlap_metric,
|
||||
)
|
||||
|
||||
return cast(KeyPoints, self[keep])
|
||||
|
||||
def as_detections(
|
||||
self, selected_keypoint_indices: Iterable[int] | None = None
|
||||
) -> Detections:
|
||||
@@ -898,7 +1233,9 @@ class KeyPoints:
|
||||
selected_keypoint_indices: The
|
||||
indices of the key points to include in the bounding box
|
||||
calculation. This helps focus on a subset of key points,
|
||||
e.g. when some are occluded. Captures all key points by default.
|
||||
e.g. when some are occluded. Captures all key points by
|
||||
default. An empty sequence (`[]`) is treated the same as
|
||||
`None` and selects all key points.
|
||||
|
||||
Returns:
|
||||
detections: The converted detections object.
|
||||
@@ -919,40 +1256,39 @@ class KeyPoints:
|
||||
if self.is_empty():
|
||||
return Detections.empty()
|
||||
|
||||
detections_list = []
|
||||
for i, xy in enumerate(self.xy):
|
||||
xy = self.xy
|
||||
if selected_keypoint_indices:
|
||||
indices = np.asarray(list(selected_keypoint_indices), dtype=np.intp)
|
||||
xy = xy[:, indices, :]
|
||||
|
||||
# [0, 0] is used by some frameworks to indicate a missing keypoint; those
|
||||
# points are excluded from each skeleton's bounding box.
|
||||
valid = ~np.all(xy == 0, axis=2) # (N, M)
|
||||
has_valid = valid.any(axis=1) # (N,)
|
||||
|
||||
x, y = xy[:, :, 0], xy[:, :, 1]
|
||||
x_min = np.where(valid, x, np.inf).min(axis=1)
|
||||
y_min = np.where(valid, y, np.inf).min(axis=1)
|
||||
x_max = np.where(valid, x, -np.inf).max(axis=1)
|
||||
y_max = np.where(valid, y, -np.inf).max(axis=1)
|
||||
|
||||
xyxy = np.stack((x_min, y_min, x_max, y_max), axis=1).astype(np.float32)
|
||||
# Skeletons with no valid keypoints keep the original empty [0, 0, 0, 0] box.
|
||||
xyxy[~has_valid] = 0.0
|
||||
|
||||
if self.detection_confidence is not None:
|
||||
confidence = self.detection_confidence.astype(np.float32)
|
||||
elif self.keypoint_confidence is not None:
|
||||
keypoint_confidence = self.keypoint_confidence
|
||||
if selected_keypoint_indices:
|
||||
xy = xy[selected_keypoint_indices]
|
||||
keypoint_confidence = keypoint_confidence[:, indices]
|
||||
confidence = keypoint_confidence.mean(axis=1).astype(np.float32)
|
||||
else:
|
||||
confidence = None
|
||||
|
||||
# [0, 0] used by some frameworks to indicate missing keypoints
|
||||
xy = xy[~np.all(xy == 0, axis=1)]
|
||||
if len(xy) == 0:
|
||||
xyxy = np.array([[0, 0, 0, 0]], dtype=np.float32)
|
||||
else:
|
||||
x_min = xy[:, 0].min()
|
||||
x_max = xy[:, 0].max()
|
||||
y_min = xy[:, 1].min()
|
||||
y_max = xy[:, 1].max()
|
||||
xyxy = np.array([[x_min, y_min, x_max, y_max]], dtype=np.float32)
|
||||
|
||||
if self.confidence is None:
|
||||
confidence = None
|
||||
else:
|
||||
confidence = self.confidence[i]
|
||||
if selected_keypoint_indices:
|
||||
confidence = confidence[selected_keypoint_indices]
|
||||
confidence = np.array([confidence.mean()], dtype=np.float32)
|
||||
|
||||
detections_list.append(
|
||||
Detections(
|
||||
xyxy=xyxy,
|
||||
confidence=confidence,
|
||||
)
|
||||
)
|
||||
|
||||
detections = Detections.merge(detections_list)
|
||||
detections = Detections(xyxy=xyxy, confidence=confidence)
|
||||
detections.class_id = self.class_id
|
||||
detections.data = self.data
|
||||
detections = cast(Detections, detections[detections.area > 0])
|
||||
detections = cast(Detections, detections[cast(Any, detections.area) > 0])
|
||||
|
||||
return detections
|
||||
|
||||
@@ -7,32 +7,130 @@ import matplotlib
|
||||
import matplotlib.pyplot as plt
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
from deprecate import deprecated_class
|
||||
from deprecate import TargetMode, deprecated, deprecated_class, void
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.dataset.core import DetectionDataset
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch
|
||||
from supervision.detection.utils.iou_and_nms import (
|
||||
box_iou_batch,
|
||||
oriented_box_iou_batch,
|
||||
)
|
||||
from supervision.metrics.core import MetricTarget
|
||||
|
||||
|
||||
def _assert_supported_target(metric_target: MetricTarget) -> None:
|
||||
if metric_target == MetricTarget.MASKS:
|
||||
raise ValueError(
|
||||
"MetricTarget.MASKS is not currently supported for ConfusionMatrix."
|
||||
)
|
||||
|
||||
|
||||
def detections_to_tensor(
|
||||
detections: Detections, with_confidence: bool = False
|
||||
detections: Detections,
|
||||
with_confidence: bool = False,
|
||||
metric_target: MetricTarget = MetricTarget.BOXES,
|
||||
) -> npt.NDArray[np.float32]:
|
||||
"""
|
||||
Convert Supervision Detections to numpy tensors for further computation
|
||||
Convert Supervision Detections to a numpy tensor for metric computation.
|
||||
|
||||
Args:
|
||||
detections: Detections/Targets in the format of sv.Detections
|
||||
with_confidence: Whether to include confidence in the tensor
|
||||
detections: Detections/Targets in the format of sv.Detections.
|
||||
with_confidence: Whether to include confidence as the last column.
|
||||
metric_target: The type of detection data to use.
|
||||
Supports `MetricTarget.BOXES` and
|
||||
`MetricTarget.ORIENTED_BOUNDING_BOXES`.
|
||||
|
||||
Returns:
|
||||
Detections as numpy tensors as in (xyxy, class_id, confidence) order
|
||||
Detections as a float32 numpy array. Shape depends on `metric_target`
|
||||
and `with_confidence`:
|
||||
|
||||
| `metric_target` | `with_confidence` | shape |
|
||||
|----------------------------------------|-------------------|-----------|
|
||||
| `MetricTarget.BOXES` | `False` | `(N, 5)` |
|
||||
| `MetricTarget.BOXES` | `True` | `(N, 6)` |
|
||||
| `MetricTarget.ORIENTED_BOUNDING_BOXES` | `False` | `(N, 9)` |
|
||||
| `MetricTarget.ORIENTED_BOUNDING_BOXES` | `True` | `(N, 10)` |
|
||||
|
||||
Column layout:
|
||||
|
||||
- `BOXES`: ``[x_min, y_min, x_max, y_max, class_id [, confidence]]``
|
||||
- `ORIENTED_BOUNDING_BOXES`:
|
||||
``[x1, y1, x2, y2, x3, y3, x4, y4, class_id [, confidence]]``
|
||||
|
||||
Raises:
|
||||
ValueError: If `metric_target` is `MetricTarget.MASKS`.
|
||||
ValueError: If `detections.class_id` is `None`.
|
||||
ValueError: If `with_confidence=True` and `detections.confidence` is `None`.
|
||||
ValueError: If `metric_target` is `MetricTarget.ORIENTED_BOUNDING_BOXES`
|
||||
and `detections.data` does not contain `ORIENTED_BOX_COORDINATES`,
|
||||
or if the stored array does not have exactly `N * 8` elements.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
>>> from supervision.metrics.core import MetricTarget
|
||||
>>> from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
>>> detections = sv.Detections(
|
||||
... xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
... class_id=np.array([0]),
|
||||
... confidence=np.array([0.9]),
|
||||
... )
|
||||
>>> tensor = detections_to_tensor(detections, with_confidence=True)
|
||||
>>> tensor.shape
|
||||
(1, 6)
|
||||
>>> obb_coords = np.array([[0, 0, 10, 0, 10, 10, 0, 10]], dtype=np.float32)
|
||||
>>> det_obb = sv.Detections(
|
||||
... xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
... class_id=np.array([0]),
|
||||
... data={ORIENTED_BOX_COORDINATES: obb_coords},
|
||||
... )
|
||||
>>> tensor_obb = detections_to_tensor(
|
||||
... det_obb, metric_target=MetricTarget.ORIENTED_BOUNDING_BOXES
|
||||
... )
|
||||
>>> tensor_obb.shape
|
||||
(1, 9)
|
||||
|
||||
```
|
||||
"""
|
||||
_assert_supported_target(metric_target)
|
||||
|
||||
if detections.class_id is None:
|
||||
raise ValueError(
|
||||
"ConfusionMatrix can only be calculated for Detections with class_id"
|
||||
)
|
||||
|
||||
arrays_to_concat = [detections.xyxy, np.expand_dims(detections.class_id, 1)]
|
||||
if metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
obb = detections.data.get(ORIENTED_BOX_COORDINATES)
|
||||
if obb is None:
|
||||
if len(detections) > 0:
|
||||
raise ValueError(
|
||||
"ORIENTED_BOUNDING_BOXES requested, but "
|
||||
f"{ORIENTED_BOX_COORDINATES} is missing from detections.data"
|
||||
)
|
||||
box_data = np.empty((0, 8), dtype=np.float32)
|
||||
else:
|
||||
obb_arr = np.asarray(obb, dtype=np.float32)
|
||||
# Normalize (N, 4, 2) → (N, 8) as produced by from_ultralytics.
|
||||
if obb_arr.ndim == 3 and obb_arr.shape[1:] == (4, 2):
|
||||
obb_arr = obb_arr.reshape(-1, 8)
|
||||
if obb_arr.size != len(detections) * 8:
|
||||
raise ValueError(
|
||||
f"Expected {ORIENTED_BOX_COORDINATES} to contain "
|
||||
f"{len(detections) * 8} elements "
|
||||
f"(N={len(detections)} detections x 8 coordinates), "
|
||||
f"but got {obb_arr.size}. "
|
||||
"Each OBB must be stored as [x1, y1, x2, y2, x3, y3, x4, y4]."
|
||||
)
|
||||
box_data = obb_arr.reshape(-1, 8)
|
||||
else:
|
||||
box_data = detections.xyxy
|
||||
|
||||
arrays_to_concat = [
|
||||
box_data,
|
||||
np.expand_dims(detections.class_id.astype(np.float32), 1),
|
||||
]
|
||||
|
||||
if with_confidence:
|
||||
if detections.confidence is None:
|
||||
@@ -45,9 +143,10 @@ def detections_to_tensor(
|
||||
return result
|
||||
|
||||
|
||||
def validate_input_tensors(
|
||||
def _validate_input_tensors(
|
||||
predictions: list[npt.NDArray[np.float32]],
|
||||
targets: list[npt.NDArray[np.float32]],
|
||||
metric_target: MetricTarget = MetricTarget.BOXES,
|
||||
) -> None:
|
||||
"""
|
||||
Checks for shape consistency of input tensors.
|
||||
@@ -62,20 +161,41 @@ def validate_input_tensors(
|
||||
targets[0], np.ndarray
|
||||
):
|
||||
raise ValueError(
|
||||
f"Predictions and targets must be lists of numpy arrays."
|
||||
"Predictions and targets must be lists of numpy arrays. "
|
||||
f"Got {type(predictions[0])} and {type(targets[0])} instead."
|
||||
)
|
||||
if predictions[0].shape[1] != 6:
|
||||
|
||||
expected_pred_cols = (
|
||||
10 if metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES else 6
|
||||
)
|
||||
expected_target_cols = (
|
||||
9 if metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES else 5
|
||||
)
|
||||
|
||||
if predictions[0].shape[1] != expected_pred_cols:
|
||||
raise ValueError(
|
||||
f"Predictions must have shape (N, 6)."
|
||||
f"Predictions must have shape (N, {expected_pred_cols}). "
|
||||
f"Got {predictions[0].shape} instead."
|
||||
)
|
||||
if targets[0].shape[1] != 5:
|
||||
if targets[0].shape[1] != expected_target_cols:
|
||||
raise ValueError(
|
||||
f"Targets must have shape (N, 5). Got {targets[0].shape} instead."
|
||||
f"Targets must have shape (N, {expected_target_cols}). "
|
||||
f"Got {targets[0].shape} instead."
|
||||
)
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_input_tensors,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_input_tensors(
|
||||
predictions: list[npt.NDArray[np.float32]],
|
||||
targets: list[npt.NDArray[np.float32]],
|
||||
) -> None:
|
||||
void(predictions, targets)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ConfusionMatrix:
|
||||
"""
|
||||
@@ -89,12 +209,30 @@ class ConfusionMatrix:
|
||||
Detections with lower confidence will be excluded from the matrix.
|
||||
iou_threshold: Detection IoU threshold between `0` and `1`.
|
||||
Detections with lower IoU will be classified as `FP`.
|
||||
metric_target: The type of detection data used for IoU computation.
|
||||
Informational metadata set by `from_detections` and `from_tensors`.
|
||||
Excluded from `__eq__` comparisons — two `ConfusionMatrix` instances
|
||||
with identical `matrix`, `classes`, `conf_threshold`, and
|
||||
`iou_threshold` compare as equal regardless of `metric_target`.
|
||||
"""
|
||||
|
||||
matrix: npt.NDArray[np.int32]
|
||||
classes: list[str]
|
||||
conf_threshold: float
|
||||
iou_threshold: float
|
||||
metric_target: MetricTarget = MetricTarget.BOXES
|
||||
|
||||
def __eq__(self, other: object) -> bool:
|
||||
if not isinstance(other, ConfusionMatrix):
|
||||
return NotImplemented
|
||||
return (
|
||||
np.array_equal(self.matrix, other.matrix)
|
||||
and self.classes == other.classes
|
||||
and self.conf_threshold == other.conf_threshold
|
||||
and self.iou_threshold == other.iou_threshold
|
||||
)
|
||||
|
||||
__hash__ = None # type: ignore[assignment]
|
||||
|
||||
@classmethod
|
||||
def from_detections(
|
||||
@@ -104,6 +242,7 @@ class ConfusionMatrix:
|
||||
classes: list[str],
|
||||
conf_threshold: float = 0.3,
|
||||
iou_threshold: float = 0.5,
|
||||
metric_target: MetricTarget = MetricTarget.BOXES,
|
||||
) -> ConfusionMatrix:
|
||||
"""
|
||||
Calculate confusion matrix based on predicted and ground-truth detections.
|
||||
@@ -116,6 +255,15 @@ class ConfusionMatrix:
|
||||
Detections with lower confidence will be excluded.
|
||||
iou_threshold: Detection IoU threshold between `0` and `1`.
|
||||
Detections with lower IoU will be classified as `FP`.
|
||||
metric_target: The type of detection data to use.
|
||||
Supports `MetricTarget.BOXES` (default) and
|
||||
`MetricTarget.ORIENTED_BOUNDING_BOXES`. When using
|
||||
`MetricTarget.ORIENTED_BOUNDING_BOXES`, each `Detections`
|
||||
object must include OBB coordinates in
|
||||
`detections.data[ORIENTED_BOX_COORDINATES]` as a float32
|
||||
array of shape `(N, 8)` (flat) or `(N, 4, 2)` (as stored by
|
||||
`from_ultralytics`); both are normalised to `(N, 8)` internally.
|
||||
`MetricTarget.MASKS` is not supported.
|
||||
|
||||
Returns:
|
||||
New instance of ConfusionMatrix.
|
||||
@@ -126,15 +274,15 @@ class ConfusionMatrix:
|
||||
>>> import supervision as sv
|
||||
>>> targets = [
|
||||
... sv.Detections(
|
||||
... xyxy=np.array([[0, 0, 10, 10]]),
|
||||
... class_id=np.array([0])
|
||||
... xyxy=np.array([[0, 0, 10, 10], [50, 50, 60, 60]]),
|
||||
... class_id=np.array([0, 0])
|
||||
... )
|
||||
... ]
|
||||
>>> predictions = [
|
||||
... sv.Detections(
|
||||
... xyxy=np.array([[0, 0, 10, 10]]),
|
||||
... class_id=np.array([0]),
|
||||
... confidence=np.array([0.9])
|
||||
... xyxy=np.array([[0, 0, 10, 10], [100, 100, 110, 110]]),
|
||||
... class_id=np.array([0, 0]),
|
||||
... confidence=np.array([0.9, 0.8])
|
||||
... )
|
||||
... ]
|
||||
>>> confusion_matrix = sv.ConfusionMatrix.from_detections(
|
||||
@@ -143,8 +291,8 @@ class ConfusionMatrix:
|
||||
... classes=['person']
|
||||
... )
|
||||
>>> confusion_matrix.matrix
|
||||
array([[1., 0.],
|
||||
[0., 0.]])
|
||||
array([[1., 1.],
|
||||
[1., 0.]])
|
||||
|
||||
```
|
||||
"""
|
||||
@@ -152,15 +300,22 @@ class ConfusionMatrix:
|
||||
target_tensors = []
|
||||
for prediction, target in zip(predictions, targets):
|
||||
prediction_tensors.append(
|
||||
detections_to_tensor(prediction, with_confidence=True)
|
||||
detections_to_tensor(
|
||||
prediction, with_confidence=True, metric_target=metric_target
|
||||
)
|
||||
)
|
||||
target_tensors.append(
|
||||
detections_to_tensor(
|
||||
target, with_confidence=False, metric_target=metric_target
|
||||
)
|
||||
)
|
||||
target_tensors.append(detections_to_tensor(target, with_confidence=False))
|
||||
return cls.from_tensors(
|
||||
predictions=prediction_tensors,
|
||||
targets=target_tensors,
|
||||
classes=classes,
|
||||
conf_threshold=conf_threshold,
|
||||
iou_threshold=iou_threshold,
|
||||
metric_target=metric_target,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
@@ -171,24 +326,34 @@ class ConfusionMatrix:
|
||||
classes: list[str],
|
||||
conf_threshold: float = 0.3,
|
||||
iou_threshold: float = 0.5,
|
||||
metric_target: MetricTarget = MetricTarget.BOXES,
|
||||
) -> ConfusionMatrix:
|
||||
"""
|
||||
Calculate confusion matrix based on predicted and ground-truth detections.
|
||||
|
||||
Args:
|
||||
predictions: Each element of the list describes a single
|
||||
image and has `shape = (M, 6)` where `M` is the number of detected
|
||||
objects. Each row is expected to be in
|
||||
image and has `shape = (M, 6)` or `shape = (M, 10)` depending on
|
||||
`metric_target`.
|
||||
If `MetricTarget.BOXES`, each row is in
|
||||
`(x_min, y_min, x_max, y_max, class, conf)` format.
|
||||
If `MetricTarget.ORIENTED_BOUNDING_BOXES`, each row is in
|
||||
`(x1, y1, x2, y2, x3, y3, x4, y4, class, conf)` format.
|
||||
targets: Each element of the list describes a single
|
||||
image and has `shape = (N, 5)` where `N` is the number of
|
||||
ground-truth objects. Each row is expected to be in
|
||||
image and has `shape = (N, 5)` or `shape = (N, 9)` depending on
|
||||
`metric_target`.
|
||||
If `MetricTarget.BOXES`, each row is in
|
||||
`(x_min, y_min, x_max, y_max, class)` format.
|
||||
If `MetricTarget.ORIENTED_BOUNDING_BOXES`, each row is in
|
||||
`(x1, y1, x2, y2, x3, y3, x4, y4, class)` format.
|
||||
classes: Model class names.
|
||||
conf_threshold: Detection confidence threshold between `0` and `1`.
|
||||
Detections with lower confidence will be excluded.
|
||||
iou_threshold: Detection iou threshold between `0` and `1`.
|
||||
iou_threshold: Detection iou threshold between `0` and `1`.
|
||||
Detections with lower iou will be classified as `FP`.
|
||||
metric_target: The type of detection data to use.
|
||||
Determines expected tensor shapes (see Args above for column
|
||||
layouts). `MetricTarget.MASKS` is not supported.
|
||||
|
||||
Returns:
|
||||
New instance of ConfusionMatrix.
|
||||
@@ -223,7 +388,8 @@ class ConfusionMatrix:
|
||||
|
||||
```
|
||||
"""
|
||||
validate_input_tensors(predictions, targets)
|
||||
_assert_supported_target(metric_target)
|
||||
_validate_input_tensors(predictions, targets, metric_target=metric_target)
|
||||
|
||||
num_classes = len(classes)
|
||||
matrix = np.zeros((num_classes + 1, num_classes + 1))
|
||||
@@ -234,12 +400,14 @@ class ConfusionMatrix:
|
||||
num_classes=num_classes,
|
||||
conf_threshold=conf_threshold,
|
||||
iou_threshold=iou_threshold,
|
||||
metric_target=metric_target,
|
||||
)
|
||||
return cls(
|
||||
matrix=matrix,
|
||||
classes=classes,
|
||||
conf_threshold=conf_threshold,
|
||||
iou_threshold=iou_threshold,
|
||||
metric_target=metric_target,
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
@@ -249,38 +417,70 @@ class ConfusionMatrix:
|
||||
num_classes: int,
|
||||
conf_threshold: float,
|
||||
iou_threshold: float,
|
||||
metric_target: MetricTarget = MetricTarget.BOXES,
|
||||
) -> npt.NDArray[np.int32]:
|
||||
"""
|
||||
Calculate confusion matrix for a batch of detections for a single image.
|
||||
|
||||
Args:
|
||||
predictions: Batch prediction. Describes a single image and
|
||||
has `shape = (M, 6)` where `M` is the number of detected objects.
|
||||
Each row is expected to be in
|
||||
has `shape = (M, 6)` or `shape = (M, 10)` depending on
|
||||
`metric_target`.
|
||||
If `MetricTarget.BOXES`, each row is in
|
||||
`(x_min, y_min, x_max, y_max, class, conf)` format.
|
||||
If `MetricTarget.ORIENTED_BOUNDING_BOXES`, each row is in
|
||||
`(x1, y1, x2, y2, x3, y3, x4, y4, class, conf)` format.
|
||||
targets: Batch target labels. Describes a single image and
|
||||
has `shape = (N, 5)` where `N` is the number of ground-truth objects.
|
||||
Each row is expected to be in
|
||||
has `shape = (N, 5)` or `shape = (N, 9)` depending on
|
||||
`metric_target`.
|
||||
If `MetricTarget.BOXES`, each row is in
|
||||
`(x_min, y_min, x_max, y_max, class)` format.
|
||||
If `MetricTarget.ORIENTED_BOUNDING_BOXES`, each row is in
|
||||
`(x1, y1, x2, y2, x3, y3, x4, y4, class)` format.
|
||||
num_classes: Number of classes.
|
||||
conf_threshold: Detection confidence threshold between `0` and `1`.
|
||||
Detections with lower confidence will be excluded.
|
||||
iou_threshold: Detection iou threshold between `0` and `1`.
|
||||
iou_threshold: Detection iou threshold between `0` and `1`.
|
||||
Detections with lower iou will be classified as `FP`.
|
||||
metric_target: The type of detection data to use.
|
||||
Determines IoU function (`box_iou_batch` vs
|
||||
`oriented_box_iou_batch`) and coordinate column count.
|
||||
`MetricTarget.MASKS` is not supported.
|
||||
|
||||
Returns:
|
||||
Confusion matrix based on a single image.
|
||||
"""
|
||||
_assert_supported_target(metric_target)
|
||||
|
||||
expected_pred_cols = (
|
||||
10 if metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES else 6
|
||||
)
|
||||
expected_target_cols = (
|
||||
9 if metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES else 5
|
||||
)
|
||||
if predictions.ndim != 2 or predictions.shape[1] != expected_pred_cols:
|
||||
raise ValueError(
|
||||
f"Predictions must have shape (M, {expected_pred_cols}). "
|
||||
f"Got {predictions.shape} instead."
|
||||
)
|
||||
if targets.ndim != 2 or targets.shape[1] != expected_target_cols:
|
||||
raise ValueError(
|
||||
f"Targets must have shape (N, {expected_target_cols}). "
|
||||
f"Got {targets.shape} instead."
|
||||
)
|
||||
|
||||
result_matrix = np.zeros((num_classes + 1, num_classes + 1))
|
||||
|
||||
# Filter predictions by confidence threshold
|
||||
conf_idx = 5
|
||||
coords_dim = 8 if metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES else 4
|
||||
class_id_idx = coords_dim
|
||||
conf_idx = coords_dim + 1
|
||||
|
||||
confidence = predictions[:, conf_idx]
|
||||
detection_batch_filtered = predictions[confidence >= conf_threshold]
|
||||
|
||||
if len(detection_batch_filtered) == 0:
|
||||
# No detections pass confidence threshold - all GT are FN
|
||||
class_id_idx = 4
|
||||
true_classes = np.array(targets[:, class_id_idx], dtype=np.int16)
|
||||
for gt_class in true_classes:
|
||||
result_matrix[gt_class, num_classes] += 1
|
||||
@@ -288,7 +488,6 @@ class ConfusionMatrix:
|
||||
|
||||
if len(targets) == 0:
|
||||
# No ground truth - all detections are FP
|
||||
class_id_idx = 4
|
||||
detection_classes = np.array(
|
||||
detection_batch_filtered[:, class_id_idx], dtype=np.int16
|
||||
)
|
||||
@@ -296,18 +495,22 @@ class ConfusionMatrix:
|
||||
result_matrix[num_classes, det_class] += 1
|
||||
return result_matrix
|
||||
|
||||
class_id_idx = 4
|
||||
true_classes = np.array(targets[:, class_id_idx], dtype=np.int16)
|
||||
detection_classes = np.array(
|
||||
detection_batch_filtered[:, class_id_idx], dtype=np.int16
|
||||
)
|
||||
true_boxes = targets[:, :class_id_idx]
|
||||
detection_boxes = detection_batch_filtered[:, :class_id_idx]
|
||||
true_boxes = targets[:, :coords_dim]
|
||||
detection_boxes = detection_batch_filtered[:, :coords_dim]
|
||||
|
||||
# Calculate IoU matrix
|
||||
iou_batch = box_iou_batch(
|
||||
boxes_true=true_boxes, boxes_detection=detection_boxes
|
||||
)
|
||||
if metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
iou_batch = oriented_box_iou_batch(
|
||||
boxes_true=true_boxes, boxes_detection=detection_boxes
|
||||
)
|
||||
else:
|
||||
iou_batch = box_iou_batch(
|
||||
boxes_true=true_boxes, boxes_detection=detection_boxes
|
||||
)
|
||||
|
||||
# Find all valid matches (IoU > threshold, regardless of class)
|
||||
# Use vectorized operations to avoid nested Python loops
|
||||
@@ -393,6 +596,7 @@ class ConfusionMatrix:
|
||||
callback: Callable[[npt.NDArray[np.uint8]], Detections],
|
||||
conf_threshold: float = 0.3,
|
||||
iou_threshold: float = 0.5,
|
||||
metric_target: MetricTarget = MetricTarget.BOXES,
|
||||
) -> ConfusionMatrix:
|
||||
"""
|
||||
Calculate confusion matrix from dataset and callback function.
|
||||
@@ -405,6 +609,10 @@ class ConfusionMatrix:
|
||||
Detections with lower confidence will be excluded.
|
||||
iou_threshold: Detection IoU threshold between `0` and `1`.
|
||||
Detections with lower IoU will be classified as `FP`.
|
||||
metric_target: The type of detection data to use.
|
||||
Supports `MetricTarget.BOXES` and
|
||||
`MetricTarget.ORIENTED_BOUNDING_BOXES`. Passed through to
|
||||
`from_detections`. `MetricTarget.MASKS` is not supported.
|
||||
|
||||
Returns:
|
||||
New instance of ConfusionMatrix.
|
||||
@@ -446,6 +654,7 @@ class ConfusionMatrix:
|
||||
classes=dataset.classes,
|
||||
conf_threshold=conf_threshold,
|
||||
iou_threshold=iou_threshold,
|
||||
metric_target=metric_target,
|
||||
)
|
||||
|
||||
def plot(
|
||||
@@ -539,7 +748,7 @@ class ConfusionMatrix:
|
||||
|
||||
|
||||
@deprecated_class(
|
||||
target=None,
|
||||
target=TargetMode.NOTIFY,
|
||||
deprecated_in="0.27.0",
|
||||
remove_in="0.31.0",
|
||||
)
|
||||
@@ -723,7 +932,7 @@ class MeanAveragePrecision:
|
||||
|
||||
```
|
||||
"""
|
||||
validate_input_tensors(predictions, targets)
|
||||
_validate_input_tensors(predictions, targets)
|
||||
iou_thresholds = np.linspace(0.5, 0.95, 10)
|
||||
stats = []
|
||||
|
||||
|
||||
@@ -152,6 +152,14 @@ class F1Score(Metric):
|
||||
def _compute(
|
||||
self, predictions_list: list[Detections], targets_list: list[Detections]
|
||||
) -> F1ScoreResult:
|
||||
"""Build per-image stats tuples and delegate to class-level computation.
|
||||
|
||||
Each stats tuple is ``(matches, confidence, class_ids, true_class_ids)``:
|
||||
- Both empty: skip (no information).
|
||||
- Targets empty, predictions present: all predictions are FPs; true_class_ids
|
||||
is ``zeros((0,))``.
|
||||
- Targets present: IoU matching produces ``matches`` array.
|
||||
"""
|
||||
iou_thresholds = np.linspace(0.5, 0.95, 10)
|
||||
stats: list[Any] = []
|
||||
|
||||
@@ -159,7 +167,22 @@ class F1Score(Metric):
|
||||
prediction_contents = self._detections_content(predictions)
|
||||
target_contents = self._detections_content(targets)
|
||||
|
||||
if len(targets) > 0:
|
||||
if len(targets) == 0 and len(predictions) > 0:
|
||||
# Only predictions are present (e.g. a background image); every
|
||||
# prediction is a false positive.
|
||||
if predictions.class_id is None or predictions.confidence is None:
|
||||
continue
|
||||
stats.append(
|
||||
(
|
||||
np.zeros(
|
||||
(len(predictions), iou_thresholds.size), dtype=np.bool_
|
||||
),
|
||||
predictions.confidence,
|
||||
predictions.class_id,
|
||||
np.zeros((0,), dtype=np.int32),
|
||||
)
|
||||
)
|
||||
elif len(targets) > 0:
|
||||
if len(predictions) == 0:
|
||||
stats.append(
|
||||
(
|
||||
@@ -244,10 +267,23 @@ class F1Score(Metric):
|
||||
npt.NDArray[np.float64],
|
||||
npt.NDArray[np.int32],
|
||||
]:
|
||||
"""Compute F1 scores from concatenated stats across all images.
|
||||
|
||||
``unique_classes`` is the union of GT and predicted classes so that
|
||||
predictions of classes absent from GT still count as false positives.
|
||||
"""
|
||||
sorted_indices = np.argsort(-prediction_confidence)
|
||||
matches = matches[sorted_indices]
|
||||
prediction_class_ids = prediction_class_ids[sorted_indices]
|
||||
unique_classes, class_counts = np.unique(true_class_ids, return_counts=True)
|
||||
# Predictions whose class never appears in the ground truth are still
|
||||
# false positives, so include those classes in the confusion matrix
|
||||
# (their true-instance count is zero).
|
||||
unique_classes = np.unique(
|
||||
np.concatenate((true_class_ids, prediction_class_ids))
|
||||
)
|
||||
true_classes, true_counts = np.unique(true_class_ids, return_counts=True)
|
||||
class_counts = np.zeros(unique_classes.shape[0], dtype=int)
|
||||
class_counts[np.searchsorted(unique_classes, true_classes)] = true_counts
|
||||
|
||||
# Shape: PxTh,P,C,C -> CxThx3
|
||||
confusion_matrix = self._compute_confusion_matrix(
|
||||
@@ -265,7 +301,13 @@ class F1Score(Metric):
|
||||
f1_scores = self._compute_f1(confusion_matrix_merged)
|
||||
elif self.averaging_method == AveragingMethod.WEIGHTED:
|
||||
class_counts = class_counts.astype(np.float32)
|
||||
f1_scores = np.average(f1_per_class, axis=0, weights=class_counts)
|
||||
if class_counts.sum() == 0:
|
||||
# No ground-truth support (e.g. only false-positive classes, or a
|
||||
# size bucket with predictions but no targets): weighting is
|
||||
# undefined, so report 0 as the empty case did before.
|
||||
f1_scores = np.zeros(f1_per_class.shape[1])
|
||||
else:
|
||||
f1_scores = np.average(f1_per_class, axis=0, weights=class_counts)
|
||||
|
||||
return f1_scores, f1_per_class, unique_classes
|
||||
|
||||
@@ -483,10 +525,12 @@ class F1ScoreResult:
|
||||
f1_scores: the F1 scores at each IoU threshold.
|
||||
Shape: `(num_iou_thresholds,)`
|
||||
f1_per_class: the F1 scores per class and IoU threshold.
|
||||
Shape: `(num_target_classes, num_iou_thresholds)`
|
||||
Shape: `(num_classes, num_iou_thresholds)`
|
||||
iou_thresholds: the IoU thresholds used in the calculations.
|
||||
matched_classes: the class IDs of all matched classes.
|
||||
Corresponds to the rows of `f1_per_class`.
|
||||
matched_classes: the class IDs present in either predictions or ground
|
||||
truth. Corresponds to the rows of `f1_per_class`. Classes that
|
||||
appear only in predictions (no ground-truth instances) are
|
||||
included; their per-threshold F1 values will be `0.0`.
|
||||
small_objects: the F1 metric results
|
||||
for small objects (area < 32²).
|
||||
medium_objects: the F1 metric results
|
||||
|
||||
@@ -155,6 +155,14 @@ class Precision(Metric):
|
||||
def _compute(
|
||||
self, predictions_list: list[Detections], targets_list: list[Detections]
|
||||
) -> PrecisionResult:
|
||||
"""Build per-image stats tuples and delegate to class-level computation.
|
||||
|
||||
Each stats tuple is ``(matches, confidence, class_ids, true_class_ids)``:
|
||||
- Both empty: skip (no information).
|
||||
- Targets empty, predictions present: all predictions are FPs; true_class_ids
|
||||
is ``zeros((0,))``.
|
||||
- Targets present: IoU matching produces ``matches`` array.
|
||||
"""
|
||||
iou_thresholds = np.linspace(0.5, 0.95, 10)
|
||||
stats: list[Any] = []
|
||||
|
||||
@@ -162,7 +170,22 @@ class Precision(Metric):
|
||||
prediction_contents = self._detections_content(predictions)
|
||||
target_contents = self._detections_content(targets)
|
||||
|
||||
if len(targets) > 0:
|
||||
if len(targets) == 0 and len(predictions) > 0:
|
||||
# Only predictions are present (e.g. a background image); every
|
||||
# prediction is a false positive.
|
||||
if predictions.class_id is None or predictions.confidence is None:
|
||||
continue
|
||||
stats.append(
|
||||
(
|
||||
np.zeros(
|
||||
(len(predictions), iou_thresholds.size), dtype=np.bool_
|
||||
),
|
||||
predictions.confidence,
|
||||
predictions.class_id,
|
||||
np.zeros((0,), dtype=np.int32),
|
||||
)
|
||||
)
|
||||
elif len(targets) > 0:
|
||||
if len(predictions) == 0:
|
||||
stats.append(
|
||||
(
|
||||
@@ -247,10 +270,23 @@ class Precision(Metric):
|
||||
npt.NDArray[np.float64],
|
||||
npt.NDArray[np.int32],
|
||||
]:
|
||||
"""Compute precision scores from concatenated stats across all images.
|
||||
|
||||
``unique_classes`` is the union of GT and predicted classes so that
|
||||
predictions of classes absent from GT still count as false positives.
|
||||
"""
|
||||
sorted_indices = np.argsort(-prediction_confidence)
|
||||
matches = matches[sorted_indices]
|
||||
prediction_class_ids = prediction_class_ids[sorted_indices]
|
||||
unique_classes, class_counts = np.unique(true_class_ids, return_counts=True)
|
||||
# Predictions whose class never appears in the ground truth are still
|
||||
# false positives, so include those classes in the confusion matrix
|
||||
# (their true-instance count is zero).
|
||||
unique_classes = np.unique(
|
||||
np.concatenate((true_class_ids, prediction_class_ids))
|
||||
)
|
||||
true_classes, true_counts = np.unique(true_class_ids, return_counts=True)
|
||||
class_counts = np.zeros(unique_classes.shape[0], dtype=int)
|
||||
class_counts[np.searchsorted(unique_classes, true_classes)] = true_counts
|
||||
|
||||
# Shape: PxTh,P,C,C -> CxThx3
|
||||
confusion_matrix = self._compute_confusion_matrix(
|
||||
@@ -268,9 +304,15 @@ class Precision(Metric):
|
||||
precision_scores = self._compute_precision(confusion_matrix_merged)
|
||||
elif self.averaging_method == AveragingMethod.WEIGHTED:
|
||||
class_counts = class_counts.astype(np.float32)
|
||||
precision_scores = np.average(
|
||||
precision_per_class, axis=0, weights=class_counts
|
||||
)
|
||||
if class_counts.sum() == 0:
|
||||
# No ground-truth support (e.g. only false-positive classes, or a
|
||||
# size bucket with predictions but no targets): weighting is
|
||||
# undefined, so report 0 as the empty case did before.
|
||||
precision_scores = np.zeros(precision_per_class.shape[1])
|
||||
else:
|
||||
precision_scores = np.average(
|
||||
precision_per_class, axis=0, weights=class_counts
|
||||
)
|
||||
|
||||
return precision_scores, precision_per_class, unique_classes
|
||||
|
||||
@@ -428,8 +470,6 @@ class Precision(Metric):
|
||||
|
||||
raise ValueError(f"Invalid metric target: {self._metric_target}")
|
||||
|
||||
raise ValueError(f"Invalid metric target: {self._metric_target}")
|
||||
|
||||
def _filter_detections_by_size(
|
||||
self, detections: Detections, size_category: ObjectSizeCategory
|
||||
) -> Detections:
|
||||
@@ -494,10 +534,12 @@ class PrecisionResult:
|
||||
precision_scores: the precision scores at each IoU threshold.
|
||||
Shape: `(num_iou_thresholds,)`
|
||||
precision_per_class: the precision scores per class and
|
||||
IoU threshold. Shape: `(num_target_classes, num_iou_thresholds)`
|
||||
IoU threshold. Shape: `(num_classes, num_iou_thresholds)`
|
||||
iou_thresholds: the IoU thresholds used in the calculations.
|
||||
matched_classes: the class IDs of all matched classes.
|
||||
Corresponds to the rows of `precision_per_class`.
|
||||
matched_classes: the class IDs present in either predictions or ground
|
||||
truth. Corresponds to the rows of `precision_per_class`. Classes
|
||||
that appear only in predictions (no ground-truth instances) are
|
||||
included; their per-threshold precision values will be `0.0`.
|
||||
small_objects: the Precision metric results
|
||||
for small objects (area < 32²).
|
||||
medium_objects: the Precision metric results
|
||||
|
||||
@@ -4,7 +4,7 @@ from typing import cast
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
from deprecate import deprecated_class
|
||||
from deprecate import TargetMode, deprecated_class
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch
|
||||
@@ -15,7 +15,7 @@ from supervision.tracker.byte_tracker.utils import IdCounter
|
||||
|
||||
|
||||
@deprecated_class(
|
||||
target=None,
|
||||
target=TargetMode.NOTIFY,
|
||||
deprecated_in="0.28.0",
|
||||
remove_in="0.30.0",
|
||||
)
|
||||
|
||||
@@ -158,7 +158,9 @@ def pillow_to_cv2(image: Image.Image) -> npt.NDArray[np.uint8]:
|
||||
"""
|
||||
scene = np.array(image)
|
||||
scene = cv2.cvtColor(scene, cv2.COLOR_RGB2BGR)
|
||||
return scene.astype(np.uint8)
|
||||
# cvtColor already returns uint8 here, so astype is a no-op other than the
|
||||
# full-image copy it forces; copy=False keeps the dtype guard without it.
|
||||
return scene.astype(np.uint8, copy=False)
|
||||
|
||||
|
||||
def cv2_to_pillow(image: npt.NDArray[np.uint8]) -> Image.Image:
|
||||
|
||||
@@ -28,8 +28,12 @@ def list_files_with_extensions(
|
||||
|
||||
Args:
|
||||
directory: The directory path as a string or Path object.
|
||||
extensions: A list of file extensions to filter.
|
||||
Default is None, which lists all files.
|
||||
extensions: A list of file extensions to filter. Extensions may be
|
||||
supplied with or without a leading dot (e.g. ``'jpg'`` and
|
||||
``'.jpg'`` are equivalent). Matching is case-insensitive.
|
||||
Multi-part extensions are supported (e.g. ``'tar.gz'``). Pass
|
||||
``None`` (default) to list all files; pass an empty list to
|
||||
return no files.
|
||||
|
||||
Returns:
|
||||
A list of Path objects for the matching files.
|
||||
@@ -50,9 +54,9 @@ def list_files_with_extensions(
|
||||
>>> files = sv.list_files_with_extensions(directory=tmpdir)
|
||||
>>> len(files)
|
||||
3
|
||||
>>> # List only files with '.txt' and '.md' extensions
|
||||
>>> # Leading dot accepted; matching is case-insensitive
|
||||
>>> files = sv.list_files_with_extensions(
|
||||
... directory=tmpdir, extensions=['txt', 'md'])
|
||||
... directory=tmpdir, extensions=['.txt', 'md'])
|
||||
>>> len(files)
|
||||
2
|
||||
|
||||
@@ -63,8 +67,22 @@ def list_files_with_extensions(
|
||||
files_with_extensions: list[Path] = []
|
||||
|
||||
if extensions is not None:
|
||||
candidates = [p for p in directory.glob("*") if p.is_file()]
|
||||
path_index: dict[Path, set[str]] = {}
|
||||
for path in candidates:
|
||||
suffixes = [suffix.lower().lstrip(".") for suffix in path.suffixes]
|
||||
path_index[path] = {
|
||||
".".join(suffixes[index:]) for index in range(len(suffixes))
|
||||
}
|
||||
seen_paths: set[Path] = set()
|
||||
for ext in extensions:
|
||||
files_with_extensions.extend(directory.glob(f"*.{ext}"))
|
||||
normalized_extension = ext.lower().lstrip(".")
|
||||
if not normalized_extension:
|
||||
continue
|
||||
for path, path_extensions in path_index.items():
|
||||
if path not in seen_paths and normalized_extension in path_extensions:
|
||||
files_with_extensions.append(path)
|
||||
seen_paths.add(path)
|
||||
else:
|
||||
files_with_extensions.extend(directory.glob("*"))
|
||||
|
||||
|
||||
@@ -11,7 +11,7 @@ from typing import Any, Literal, cast
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
from deprecate import deprecated
|
||||
from deprecate import TargetMode, deprecated
|
||||
from PIL import Image
|
||||
|
||||
from supervision.draw.base import ImageType
|
||||
@@ -217,14 +217,20 @@ def letterbox_image(
|
||||
maintaining aspect ratio.
|
||||
|
||||
Args:
|
||||
image: The image to resize and pad.
|
||||
image: The image to resize and pad. Accepts BGR arrays of shape
|
||||
``(H, W, 3)``, BGRA arrays of shape ``(H, W, 4)``, grayscale
|
||||
arrays of shape ``(H, W)``, or a PIL ``Image``.
|
||||
resolution_wh: Target resolution as `(width, height)`.
|
||||
color: Padding color. If tuple, should
|
||||
be in BGR format. Defaults to `Color.BLACK`.
|
||||
color: Padding color. If tuple, should be in BGR format.
|
||||
Defaults to `Color.BLACK`.
|
||||
|
||||
Returns:
|
||||
Letterboxed image matching input
|
||||
type.
|
||||
Letterboxed image matching input type.
|
||||
|
||||
Note:
|
||||
For BGRA inputs, the alpha channel in the padding region is set to
|
||||
0 (fully transparent). Grayscale inputs receive scalar padding
|
||||
from ``color[0]``.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
@@ -238,6 +244,9 @@ def letterbox_image(
|
||||
... )
|
||||
>>> letterboxed_image.shape
|
||||
(1000, 1000, 3)
|
||||
>>> gray = np.zeros((4, 6), dtype=np.uint8)
|
||||
>>> sv.letterbox_image(image=gray, resolution_wh=(10, 10)).shape
|
||||
(10, 10)
|
||||
|
||||
```
|
||||
|
||||
@@ -263,17 +272,11 @@ def letterbox_image(
|
||||
value=color,
|
||||
)
|
||||
|
||||
if image.shape[2] == 4:
|
||||
image[:padding_top, :, 3] = 0
|
||||
image[height_new - padding_bottom :, :, 3] = 0
|
||||
image[:, :padding_left, 3] = 0
|
||||
image[:, width_new - padding_right :, 3] = 0
|
||||
|
||||
return image_with_borders
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=None,
|
||||
target=TargetMode.NOTIFY,
|
||||
deprecated_in="0.27.0",
|
||||
remove_in="0.31.0",
|
||||
)
|
||||
@@ -555,7 +558,7 @@ class ImageSink:
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=None,
|
||||
target=TargetMode.NOTIFY,
|
||||
deprecated_in="0.27.0",
|
||||
remove_in="0.31.0",
|
||||
)
|
||||
|
||||
@@ -1,5 +1,9 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
import shutil
|
||||
import subprocess
|
||||
import tempfile
|
||||
import threading
|
||||
import time
|
||||
from collections import deque
|
||||
@@ -133,6 +137,73 @@ class VideoSink:
|
||||
self.__writer.release()
|
||||
|
||||
|
||||
def _mux_audio(source_path: str, video_path: str) -> None:
|
||||
"""Mux audio from `source_path` into `video_path` in-place using ffmpeg.
|
||||
|
||||
Args:
|
||||
source_path: Path to the original video file containing the audio stream.
|
||||
video_path: Path to the video-only file to be updated with audio.
|
||||
"""
|
||||
ffmpeg_path = shutil.which("ffmpeg")
|
||||
if ffmpeg_path is None:
|
||||
logger.warning(
|
||||
"ffmpeg not found on PATH. Audio will not be preserved. "
|
||||
"Install ffmpeg to enable audio preservation."
|
||||
)
|
||||
return
|
||||
|
||||
tmp_path = None
|
||||
try:
|
||||
tmp_fd, tmp_path = tempfile.mkstemp(
|
||||
suffix=os.path.splitext(video_path)[1],
|
||||
dir=os.path.dirname(os.path.abspath(video_path)),
|
||||
)
|
||||
os.close(tmp_fd)
|
||||
result = subprocess.run( # noqa: S603
|
||||
[
|
||||
ffmpeg_path,
|
||||
"-y",
|
||||
"-loglevel",
|
||||
"error",
|
||||
"-nostats",
|
||||
"-i",
|
||||
video_path,
|
||||
"-i",
|
||||
source_path,
|
||||
"-c:v",
|
||||
"copy",
|
||||
"-c:a",
|
||||
"copy",
|
||||
"-map",
|
||||
"0:v:0",
|
||||
"-map",
|
||||
"1:a:0?",
|
||||
"-shortest",
|
||||
tmp_path,
|
||||
],
|
||||
stdout=subprocess.DEVNULL,
|
||||
stderr=subprocess.PIPE,
|
||||
timeout=300,
|
||||
)
|
||||
if result.returncode != 0:
|
||||
stderr_msg = result.stderr.decode(errors="replace").strip()
|
||||
logger.warning(
|
||||
"ffmpeg failed to mux audio (return code %d)%s. "
|
||||
"The output video will not have audio.",
|
||||
result.returncode,
|
||||
f": {stderr_msg}" if stderr_msg else "",
|
||||
)
|
||||
return
|
||||
os.replace(tmp_path, video_path)
|
||||
except Exception as exc:
|
||||
logger.warning(
|
||||
"Audio muxing failed: %s. Output video will not have audio.", exc
|
||||
)
|
||||
finally:
|
||||
if tmp_path is not None and os.path.exists(tmp_path):
|
||||
os.remove(tmp_path)
|
||||
|
||||
|
||||
def _validate_and_setup_video(
|
||||
source_path: str, start: int, end: int | None, iterative_seek: bool = False
|
||||
) -> tuple[cv2.VideoCapture, int, int]:
|
||||
@@ -219,6 +290,7 @@ def process_video(
|
||||
writer_buffer: int = 32,
|
||||
show_progress: bool = False,
|
||||
progress_message: str = "Processing video",
|
||||
preserve_audio: bool = False,
|
||||
) -> None:
|
||||
"""
|
||||
Process video frames asynchronously using a threaded pipeline.
|
||||
@@ -252,13 +324,18 @@ def process_video(
|
||||
show_progress: Whether to display a tqdm progress bar during processing.
|
||||
Default is False.
|
||||
progress_message: Description shown in the progress bar.
|
||||
preserve_audio: If True, copy the audio stream from `source_path` into
|
||||
`target_path` after frame processing. Requires `ffmpeg` on PATH
|
||||
(e.g. `apt install ffmpeg`, `brew install ffmpeg`). If ffmpeg is
|
||||
not found or the mux step fails, a warning is logged and the output
|
||||
video is saved without audio — no exception is raised. Audio is
|
||||
truncated to match the processed video duration. Default is False.
|
||||
|
||||
Returns:
|
||||
None
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from rfdetr import RFDETRMedium
|
||||
|
||||
@@ -267,10 +344,11 @@ def process_video(
|
||||
def callback(frame, frame_index):
|
||||
return model.predict(frame)
|
||||
|
||||
process_video(
|
||||
sv.process_video(
|
||||
source_path="source.mp4",
|
||||
target_path="target.mp4",
|
||||
callback=callback,
|
||||
preserve_audio=True,
|
||||
)
|
||||
```
|
||||
"""
|
||||
@@ -368,6 +446,15 @@ def process_video(
|
||||
if exception_in_worker is not None:
|
||||
raise exception_in_worker
|
||||
|
||||
if preserve_audio:
|
||||
if writer_worker.is_alive():
|
||||
logger.warning(
|
||||
"Writer thread did not finish in time; skipping audio mux "
|
||||
"to avoid reading an incomplete output file."
|
||||
)
|
||||
else:
|
||||
_mux_audio(source_path=source_path, video_path=target_path)
|
||||
|
||||
|
||||
class FPSMonitor:
|
||||
"""
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
from typing import Any
|
||||
from typing import Any, Optional
|
||||
|
||||
import numpy as np
|
||||
from deprecate import deprecated, void
|
||||
@@ -7,11 +7,11 @@ from supervision.detection.compact_mask import CompactMask
|
||||
from supervision.utils.internal import warn_deprecated
|
||||
|
||||
|
||||
def validate_xyxy(xyxy: Any) -> None:
|
||||
def _validate_xyxy(xyxy: Any) -> None:
|
||||
"""Validate that xyxy is a 2D np.ndarray with shape (N, 4).
|
||||
|
||||
```pycon
|
||||
>>> validate_xyxy(np.array([[0, 0, 1, 1], [1, 1, 2, 2]]))
|
||||
>>> _validate_xyxy(np.array([[0, 0, 1, 1], [1, 1, 2, 2]]))
|
||||
|
||||
```
|
||||
"""
|
||||
@@ -25,7 +25,16 @@ def validate_xyxy(xyxy: Any) -> None:
|
||||
)
|
||||
|
||||
|
||||
def validate_mask(mask: Any, n: int) -> None:
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_xyxy,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_xyxy(xyxy: Any) -> None:
|
||||
void(xyxy)
|
||||
|
||||
|
||||
def _validate_mask(mask: Any, n: int) -> None:
|
||||
if mask is None:
|
||||
return
|
||||
|
||||
@@ -63,7 +72,16 @@ def validate_mask(mask: Any, n: int) -> None:
|
||||
)
|
||||
|
||||
|
||||
def validate_class_id(class_id: Any, n: int) -> None:
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_mask,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_mask(mask: Any, n: int) -> None:
|
||||
void(mask, n)
|
||||
|
||||
|
||||
def _validate_class_id(class_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(class_id, "shape", None))
|
||||
is_valid = class_id is None or (
|
||||
@@ -76,7 +94,17 @@ def validate_class_id(class_id: Any, n: int) -> None:
|
||||
)
|
||||
|
||||
|
||||
def validate_confidence(confidence: Any, n: int) -> None:
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_class_id,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_class_id(class_id: Any, n: int) -> None:
|
||||
void(class_id, n)
|
||||
|
||||
|
||||
def _validate_confidence(confidence: Any, n: int) -> None:
|
||||
"""Validate detection-level confidence: 1D ``np.ndarray`` with shape ``(n,)``."""
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(confidence, "shape", None))
|
||||
is_valid = confidence is None or (
|
||||
@@ -89,21 +117,48 @@ def validate_confidence(confidence: Any, n: int) -> None:
|
||||
)
|
||||
|
||||
|
||||
def validate_key_point_confidence(confidence: Any, n: int, m: int) -> None:
|
||||
expected_shape = f"({n, m})"
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_confidence,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_confidence(confidence: Any, n: int) -> None:
|
||||
void(confidence, n)
|
||||
|
||||
|
||||
def _validate_keypoint_confidence(confidence: Any, n: int, m: int) -> None:
|
||||
"""Validate per-keypoint confidence: 2D ``np.ndarray`` with shape ``(n, m)``."""
|
||||
actual_shape = str(getattr(confidence, "shape", None))
|
||||
|
||||
if confidence is not None:
|
||||
is_valid = isinstance(confidence, np.ndarray) and confidence.shape == (n, m)
|
||||
if not is_valid:
|
||||
if not isinstance(confidence, np.ndarray) or confidence.ndim != 2:
|
||||
raise ValueError(
|
||||
f"confidence must be a 1D np.ndarray with shape {expected_shape}, but "
|
||||
f"keypoint_confidence must be a 2D np.ndarray with shape (n, m), but "
|
||||
f"got shape {actual_shape}"
|
||||
)
|
||||
if confidence.shape[0] != n:
|
||||
raise ValueError(
|
||||
f"keypoint_confidence first dimension must be {n}, "
|
||||
f"but got shape {actual_shape}"
|
||||
)
|
||||
if n > 0 and confidence.shape[1] != m:
|
||||
raise ValueError(
|
||||
f"keypoint_confidence second dimension must be {m}, but "
|
||||
f"got shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=validate_key_point_confidence,
|
||||
target=_validate_keypoint_confidence,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_key_point_confidence(confidence: Any, n: int, m: int) -> None:
|
||||
void(confidence, n, m)
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_keypoint_confidence,
|
||||
deprecated_in="0.27.0",
|
||||
remove_in="0.31.0",
|
||||
)
|
||||
@@ -111,7 +166,7 @@ def validate_keypoint_confidence(confidence: Any, n: int, m: int) -> None:
|
||||
void(confidence, n, m)
|
||||
|
||||
|
||||
def validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
def _validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(tracker_id, "shape", None))
|
||||
is_valid = tracker_id is None or (
|
||||
@@ -124,7 +179,16 @@ def validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
)
|
||||
|
||||
|
||||
def validate_data(data: dict[str, Any], n: int) -> None:
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_tracker_id,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
void(tracker_id, n)
|
||||
|
||||
|
||||
def _validate_data(data: dict[str, Any], n: int) -> None:
|
||||
for key, value in data.items():
|
||||
if isinstance(value, list):
|
||||
if len(value) != n:
|
||||
@@ -140,20 +204,80 @@ def validate_data(data: dict[str, Any], n: int) -> None:
|
||||
raise ValueError(f"Value for key '{key}' must be a list or np.ndarray")
|
||||
|
||||
|
||||
def validate_xy(xy: Any, n: int, m: int) -> None:
|
||||
expected_shape = f"({n, m},)"
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_data,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_data(data: dict[str, Any], n: int) -> None:
|
||||
void(data, n)
|
||||
|
||||
|
||||
def _validate_xy(xy: Any, n: int, m: int) -> None:
|
||||
expected_shape = f"({n}, {m}, 2) or ({n}, {m}, 3)"
|
||||
actual_shape = str(getattr(xy, "shape", None))
|
||||
|
||||
is_valid = isinstance(xy, np.ndarray) and (
|
||||
xy.shape == (n, m, 2) or xy.shape == (n, m, 3)
|
||||
)
|
||||
if not is_valid:
|
||||
if not isinstance(xy, np.ndarray) or xy.ndim != 3 or xy.shape[2] not in (2, 3):
|
||||
raise ValueError(
|
||||
f"xy must be a 2D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"xy must be a 3D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_xy,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_xy(xy: Any, n: int, m: int) -> None:
|
||||
void(xy, n, m)
|
||||
|
||||
|
||||
def _validate_visible(visible: Any, n: int, m: int) -> None:
|
||||
"""Validate per-keypoint visibility mask.
|
||||
|
||||
Expects a 2D bool ``np.ndarray`` with shape ``(n, m)``.
|
||||
"""
|
||||
if visible is None:
|
||||
return
|
||||
actual_shape = str(getattr(visible, "shape", None))
|
||||
if not isinstance(visible, np.ndarray) or visible.ndim != 2:
|
||||
raise ValueError(
|
||||
"visible must be a 2D np.ndarray with shape (n, m), but "
|
||||
f"got shape {actual_shape}"
|
||||
)
|
||||
if visible.shape[0] != n:
|
||||
raise ValueError(
|
||||
f"visible first dimension must be {n}, but got shape {actual_shape}"
|
||||
)
|
||||
if n > 0 and visible.shape[1] != m:
|
||||
raise ValueError(
|
||||
f"visible second dimension must be {m}, but got shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def _validate_detections_fields(
|
||||
xyxy: Any,
|
||||
mask: Any,
|
||||
class_id: Any,
|
||||
confidence: Any,
|
||||
tracker_id: Any,
|
||||
data: dict[str, Any],
|
||||
) -> None:
|
||||
_validate_xyxy(xyxy)
|
||||
n = len(xyxy)
|
||||
_validate_mask(mask, n)
|
||||
_validate_class_id(class_id, n)
|
||||
_validate_confidence(confidence, n)
|
||||
_validate_tracker_id(tracker_id, n)
|
||||
_validate_data(data, n)
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_detections_fields,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_detections_fields(
|
||||
xyxy: Any,
|
||||
mask: Any,
|
||||
@@ -162,31 +286,42 @@ def validate_detections_fields(
|
||||
tracker_id: Any,
|
||||
data: dict[str, Any],
|
||||
) -> None:
|
||||
validate_xyxy(xyxy)
|
||||
n = len(xyxy)
|
||||
validate_mask(mask, n)
|
||||
validate_class_id(class_id, n)
|
||||
validate_confidence(confidence, n)
|
||||
validate_tracker_id(tracker_id, n)
|
||||
validate_data(data, n)
|
||||
void(xyxy, mask, class_id, confidence, tracker_id, data)
|
||||
|
||||
|
||||
def validate_key_points_fields(
|
||||
def _validate_keypoints_fields(
|
||||
xy: Any,
|
||||
class_id: Any,
|
||||
confidence: Any,
|
||||
data: dict[str, Any],
|
||||
detection_confidence: Any = None,
|
||||
visible: Any = None,
|
||||
data: Optional[dict[str, Any]] = None,
|
||||
) -> None:
|
||||
n = len(xy)
|
||||
m = len(xy[0]) if len(xy) > 0 else 0
|
||||
validate_xy(xy, n, m)
|
||||
validate_class_id(class_id, n)
|
||||
validate_key_point_confidence(confidence, n, m)
|
||||
validate_data(data, n)
|
||||
_validate_xy(xy, n, m)
|
||||
_validate_class_id(class_id, n)
|
||||
_validate_keypoint_confidence(confidence, n, m)
|
||||
if detection_confidence is not None:
|
||||
_validate_confidence(detection_confidence, n)
|
||||
_validate_visible(visible, n, m)
|
||||
if data is not None:
|
||||
_validate_data(data, n)
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=validate_key_points_fields,
|
||||
target=_validate_keypoints_fields,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_key_points_fields(
|
||||
xy: Any, class_id: Any, confidence: Any, data: dict[str, Any]
|
||||
) -> None:
|
||||
void(xy, class_id, confidence, data)
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_keypoints_fields,
|
||||
deprecated_in="0.27.0",
|
||||
remove_in="0.31.0",
|
||||
)
|
||||
@@ -196,7 +331,7 @@ def validate_keypoints_fields(
|
||||
void(xy, class_id, confidence, data)
|
||||
|
||||
|
||||
def validate_resolution(resolution: Any) -> tuple[int, int]:
|
||||
def _validate_resolution(resolution: Any) -> tuple[int, int]:
|
||||
if not (isinstance(resolution, tuple) and len(resolution) == 2):
|
||||
raise ValueError(
|
||||
f"""
|
||||
@@ -217,3 +352,12 @@ def validate_resolution(resolution: Any) -> tuple[int, int]:
|
||||
f"Both dimensions in resolution must be positive. Got ({w}, {h})."
|
||||
)
|
||||
return w, h
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=_validate_resolution,
|
||||
deprecated_in="0.29.0",
|
||||
remove_in="0.32.0",
|
||||
)
|
||||
def validate_resolution(resolution: Any) -> tuple[int, int]:
|
||||
return void(resolution) # type: ignore[no-any-return]
|
||||
|
||||
@@ -2,6 +2,8 @@
|
||||
Tests for supervision/annotators/core.py
|
||||
"""
|
||||
|
||||
import warnings
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
@@ -17,6 +19,7 @@ from supervision.annotators.core import (
|
||||
DotAnnotator,
|
||||
EllipseAnnotator,
|
||||
HaloAnnotator,
|
||||
HeatMapAnnotator,
|
||||
LabelAnnotator,
|
||||
MaskAnnotator,
|
||||
OrientedBoxAnnotator,
|
||||
@@ -27,8 +30,10 @@ from supervision.annotators.core import (
|
||||
RoundBoxAnnotator,
|
||||
TraceAnnotator,
|
||||
TriangleAnnotator,
|
||||
_paint_masks_by_area,
|
||||
)
|
||||
from supervision.annotators.utils import ColorLookup
|
||||
from supervision.detection.compact_mask import CompactMask
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.draw.color import Color
|
||||
from supervision.geometry.core import Position
|
||||
@@ -360,6 +365,216 @@ class TestHaloAnnotator:
|
||||
)
|
||||
assert np.array_equal(result_bool, result_uint8)
|
||||
|
||||
def test_annotate_with_all_false_mask_preserves_scene(self):
|
||||
"""Test that an all-False mask leaves the scene unchanged, not corrupted."""
|
||||
scene = np.full((100, 100, 3), 127, dtype=np.uint8)
|
||||
masks = [np.zeros((100, 100), dtype=bool)]
|
||||
detections = _create_detections(
|
||||
xyxy=[[10, 10, 90, 90]], mask=masks, class_id=[0]
|
||||
)
|
||||
result = HaloAnnotator().annotate(scene=scene.copy(), detections=detections)
|
||||
assert np.array_equal(result, scene)
|
||||
|
||||
|
||||
class TestPaintMasksByArea:
|
||||
"""Tests for the _paint_masks_by_area helper function."""
|
||||
|
||||
def test_paint_masks_by_area_is_noop_without_masks(self):
|
||||
"""_paint_masks_by_area is a no-op when detections carry no mask."""
|
||||
canvas = np.full((10, 10, 3), 7, dtype=np.uint8)
|
||||
detections = _create_detections(xyxy=[[1, 1, 8, 8]], class_id=[0])
|
||||
_paint_masks_by_area(canvas, detections, Color.RED, ColorLookup.INDEX)
|
||||
assert np.array_equal(canvas, np.full((10, 10, 3), 7, dtype=np.uint8))
|
||||
|
||||
def test_union_accumulation_dense(self):
|
||||
"""Dense path: collect_union=True returns array covering all painted pixels."""
|
||||
height, width = 50, 60
|
||||
canvas = np.zeros((height, width, 3), dtype=np.uint8)
|
||||
masks = [np.zeros((height, width), dtype=bool)]
|
||||
masks[0][5:20, 10:40] = True
|
||||
detections = _create_detections(
|
||||
xyxy=[[10.0, 5.0, 40.0, 20.0]], mask=masks, class_id=[0]
|
||||
)
|
||||
result_union = _paint_masks_by_area(
|
||||
canvas, detections, Color.RED, ColorLookup.INDEX, collect_union=True
|
||||
)
|
||||
assert result_union is not None
|
||||
# every painted pixel must be in the union (RED is BGR (0, 0, 255),
|
||||
# so detect painted pixels via any non-zero channel)
|
||||
painted = canvas.any(axis=-1)
|
||||
assert np.array_equal(painted, result_union)
|
||||
|
||||
def test_union_accumulation_compact(self):
|
||||
"""CompactMask path: collect_union=True returns array matching dense."""
|
||||
height, width = 50, 60
|
||||
mask = np.zeros((height, width), dtype=bool)
|
||||
mask[5:20, 10:40] = True
|
||||
xyxy = np.array([[10.0, 5.0, 40.0, 20.0]])
|
||||
|
||||
canvas_dense = np.zeros((height, width, 3), dtype=np.uint8)
|
||||
dense = _create_detections(xyxy=xyxy.tolist(), mask=[mask], class_id=[0])
|
||||
union_dense = _paint_masks_by_area(
|
||||
canvas_dense, dense, Color.RED, ColorLookup.INDEX, collect_union=True
|
||||
)
|
||||
|
||||
canvas_compact = np.zeros((height, width, 3), dtype=np.uint8)
|
||||
compact = _create_detections(xyxy=xyxy.tolist(), mask=[mask], class_id=[0])
|
||||
compact.mask = CompactMask.from_dense(
|
||||
np.array([mask]), compact.xyxy, (height, width)
|
||||
)
|
||||
union_compact = _paint_masks_by_area(
|
||||
canvas_compact, compact, Color.RED, ColorLookup.INDEX, collect_union=True
|
||||
)
|
||||
|
||||
assert union_dense is not None
|
||||
assert union_compact is not None
|
||||
# compact union must cover exactly the same pixels as dense union
|
||||
assert np.array_equal(union_dense, union_compact)
|
||||
|
||||
def test_compact_mask_drops_pixels_outside_bbox(self):
|
||||
"""CompactMask is lossy: True pixels outside xyxy bbox are silently dropped.
|
||||
|
||||
This test documents that compact and dense paths diverge when a mask has
|
||||
True pixels outside its bounding box — the 'bit-identical' claim holds
|
||||
only for bbox-contained masks.
|
||||
"""
|
||||
height, width = 50, 60
|
||||
mask = np.zeros((height, width), dtype=bool)
|
||||
mask[5:25, 10:40] = True # mask extends 5 rows beyond bbox bottom
|
||||
|
||||
bbox = [[10.0, 5.0, 40.0, 20.0]] # y2=20 clips the mask at row 20
|
||||
|
||||
canvas_dense = np.zeros((height, width, 3), dtype=np.uint8)
|
||||
dense = _create_detections(xyxy=bbox, mask=[mask], class_id=[0])
|
||||
_paint_masks_by_area(canvas_dense, dense, Color.RED, ColorLookup.INDEX)
|
||||
|
||||
canvas_compact = np.zeros((height, width, 3), dtype=np.uint8)
|
||||
compact = _create_detections(xyxy=bbox, mask=[mask], class_id=[0])
|
||||
compact.mask = CompactMask.from_dense(
|
||||
np.array([mask]), compact.xyxy, (height, width)
|
||||
)
|
||||
_paint_masks_by_area(canvas_compact, compact, Color.RED, ColorLookup.INDEX)
|
||||
|
||||
# Dense paints all True pixels incl. rows 21-24; compact only within bbox.
|
||||
assert not np.array_equal(canvas_dense, canvas_compact), (
|
||||
"Expected divergence: compact mask drops True pixels outside bbox"
|
||||
)
|
||||
# Compact subset: every pixel painted by compact is also painted by dense.
|
||||
compact_painted = canvas_compact.any(axis=-1)
|
||||
dense_painted = canvas_dense.any(axis=-1)
|
||||
assert np.all(dense_painted[compact_painted])
|
||||
|
||||
|
||||
class TestCompactMaskParity:
|
||||
"""Tests that CompactMask and dense mask produce identical annotator output."""
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"annotator_factory",
|
||||
[
|
||||
pytest.param(
|
||||
lambda: MaskAnnotator(opacity=1.0, color_lookup=ColorLookup.INDEX),
|
||||
id="mask",
|
||||
),
|
||||
pytest.param(
|
||||
lambda: HaloAnnotator(kernel_size=15, color_lookup=ColorLookup.INDEX),
|
||||
id="halo",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_annotator_compact_mask_matches_dense_mask(self, annotator_factory):
|
||||
"""CompactMask detections annotate identically to dense bool masks."""
|
||||
height, width = 120, 160
|
||||
rng = np.random.default_rng(0)
|
||||
scene = rng.integers(0, 256, (height, width, 3), dtype=np.uint8)
|
||||
boxes = [[10, 10, 70, 60], [40, 30, 150, 110], [90, 70, 140, 115]]
|
||||
masks = []
|
||||
for x1, y1, x2, y2 in boxes:
|
||||
mask = np.zeros((height, width), dtype=bool)
|
||||
mask[y1 : y2 + 1, x1 : x2 + 1] = True
|
||||
masks.append(mask)
|
||||
class_id = [0, 1, 2]
|
||||
xyxy = [[float(value) for value in box] for box in boxes]
|
||||
|
||||
dense = _create_detections(xyxy=xyxy, mask=masks, class_id=class_id)
|
||||
compact = _create_detections(xyxy=xyxy, mask=masks, class_id=class_id)
|
||||
compact.mask = CompactMask.from_dense(
|
||||
np.array(masks), compact.xyxy, (height, width)
|
||||
)
|
||||
|
||||
result_dense = annotator_factory().annotate(
|
||||
scene=scene.copy(), detections=dense
|
||||
)
|
||||
result_compact = annotator_factory().annotate(
|
||||
scene=scene.copy(), detections=compact
|
||||
)
|
||||
|
||||
assert not np.array_equal(result_dense, scene), "annotator painted nothing"
|
||||
assert np.array_equal(result_dense, result_compact)
|
||||
|
||||
def test_annotator_compact_mask_handles_edge_clipping(self):
|
||||
"""CompactMask detection straddling image edge paints via NumPy clip."""
|
||||
height, width = 50, 60
|
||||
rng = np.random.default_rng(42)
|
||||
scene = rng.integers(0, 256, (height, width, 3), dtype=np.uint8)
|
||||
|
||||
# Box extends 10 pixels beyond right/bottom edges
|
||||
mask = np.zeros((height, width), dtype=bool)
|
||||
mask[40:height, 50:width] = True
|
||||
bbox = [[50.0, 40.0, width + 10.0, height + 10.0]]
|
||||
|
||||
detections = _create_detections(xyxy=bbox, mask=[mask], class_id=[0])
|
||||
detections.mask = CompactMask.from_dense(
|
||||
np.array([mask]), detections.xyxy, (height, width)
|
||||
)
|
||||
|
||||
annotator = MaskAnnotator(opacity=1.0, color_lookup=ColorLookup.INDEX)
|
||||
result = annotator.annotate(scene=scene.copy(), detections=detections)
|
||||
# Result must differ from scene (something was painted) and must not raise
|
||||
assert not np.array_equal(result, scene), "Expected pixels to be painted"
|
||||
|
||||
|
||||
class TestHeatMapAnnotator:
|
||||
"""Tests for HeatMapAnnotator class"""
|
||||
|
||||
def test_annotate_with_no_detections_does_not_warn(
|
||||
self, test_image: np.ndarray
|
||||
) -> None:
|
||||
"""Empty detections must not trigger a divide-by-zero RuntimeWarning."""
|
||||
detections = Detections.empty()
|
||||
annotator = HeatMapAnnotator()
|
||||
with warnings.catch_warnings():
|
||||
warnings.simplefilter("error", RuntimeWarning)
|
||||
result = annotator.annotate(scene=test_image.copy(), detections=detections)
|
||||
assert np.array_equal(test_image, result)
|
||||
|
||||
def test_annotate_with_single_detection(self, test_image: np.ndarray) -> None:
|
||||
"""Single detection must produce visible heat — result differs from input."""
|
||||
annotator = HeatMapAnnotator()
|
||||
detections = _create_detections(xyxy=[[20, 20, 60, 60]])
|
||||
result = annotator.annotate(scene=test_image.copy(), detections=detections)
|
||||
assert not np.array_equal(test_image, result)
|
||||
|
||||
def test_annotate_state_preserved_after_empty_call(
|
||||
self, test_image: np.ndarray
|
||||
) -> None:
|
||||
"""Empty call must not poison accumulated heat."""
|
||||
annotator = HeatMapAnnotator()
|
||||
detections = _create_detections(xyxy=[[20, 20, 60, 60]])
|
||||
annotator.annotate(scene=test_image.copy(), detections=Detections.empty())
|
||||
result = annotator.annotate(scene=test_image.copy(), detections=detections)
|
||||
assert not np.array_equal(test_image, result)
|
||||
|
||||
def test_annotate_empty_after_real_does_not_warn(
|
||||
self, test_image: np.ndarray
|
||||
) -> None:
|
||||
"""Empty call after heat accumulated must not trigger RuntimeWarning."""
|
||||
annotator = HeatMapAnnotator()
|
||||
detections = _create_detections(xyxy=[[20, 20, 60, 60]])
|
||||
annotator.annotate(scene=test_image.copy(), detections=detections)
|
||||
with warnings.catch_warnings():
|
||||
warnings.simplefilter("error", RuntimeWarning)
|
||||
annotator.annotate(scene=test_image.copy(), detections=Detections.empty())
|
||||
|
||||
|
||||
class TestEllipseAnnotator:
|
||||
"""Tests for EllipseAnnotator class"""
|
||||
|
||||
@@ -0,0 +1,148 @@
|
||||
"""Regression tests for docs/detection/annotators.md tab structure."""
|
||||
|
||||
import ast
|
||||
import re
|
||||
from pathlib import Path
|
||||
|
||||
import pytest
|
||||
|
||||
_REPO_ROOT = Path(__file__).resolve().parent
|
||||
while not (_REPO_ROOT / "pyproject.toml").exists():
|
||||
_REPO_ROOT = _REPO_ROOT.parent
|
||||
|
||||
REPO_ROOT = _REPO_ROOT
|
||||
|
||||
EXPECTED_ANNOTATOR_TAB_GROUPS: dict[str, list[str]] = {
|
||||
"Outlines": [
|
||||
"Box",
|
||||
"RoundBox",
|
||||
"BoxCorner",
|
||||
"Circle",
|
||||
"Ellipse",
|
||||
"Polygon",
|
||||
],
|
||||
"Shading": ["Color", "Halo", "Mask"],
|
||||
"Markers": ["Dot", "Triangle"],
|
||||
"Labels": ["Label", "RichLabel"],
|
||||
"Transformative": ["Blur", "Pixelate"],
|
||||
"Tracking & Aggregation": ["Trace", "HeatMap"],
|
||||
"Others": [
|
||||
"PercentageBar",
|
||||
"Icon",
|
||||
"Background Color",
|
||||
"Comparison",
|
||||
],
|
||||
}
|
||||
|
||||
|
||||
def _extract_annotator_tab_groups() -> dict[str, list[str]]:
|
||||
"""Parse annotator tab structure from docs/detection/annotators.md.
|
||||
|
||||
Returns:
|
||||
Mapping of category name to list of annotator tab labels within that
|
||||
category.
|
||||
"""
|
||||
docs_path = REPO_ROOT / "docs" / "detection" / "annotators.md"
|
||||
content = docs_path.read_text(encoding="utf-8")
|
||||
|
||||
start_marker = '=== "Outlines"'
|
||||
end_marker = "Try Supervision Annotators on your own image"
|
||||
|
||||
start = content.find(start_marker)
|
||||
if start == -1:
|
||||
pytest.fail(
|
||||
f"Could not find start marker {start_marker!r} in {docs_path} while "
|
||||
"parsing annotator example tab groups."
|
||||
)
|
||||
|
||||
end = content.find(end_marker, start)
|
||||
if end == -1:
|
||||
pytest.fail(
|
||||
f"Could not find end marker {end_marker!r} in {docs_path} while "
|
||||
"parsing annotator example tab groups."
|
||||
)
|
||||
if end <= start:
|
||||
pytest.fail(
|
||||
f"End marker {end_marker!r} must appear after start marker "
|
||||
f"{start_marker!r} in {docs_path}."
|
||||
)
|
||||
|
||||
example_section = content[start:end]
|
||||
|
||||
groups: dict[str, list[str]] = {}
|
||||
current_group = None
|
||||
|
||||
for line in example_section.splitlines():
|
||||
if match := re.match(r'^(?P<indent>\s*)=== "(?P<label>[^"]+)"\s*$', line):
|
||||
indent = 1 if match.group("indent") else 0
|
||||
label = match.group("label")
|
||||
|
||||
if indent == 0:
|
||||
current_group = label
|
||||
groups[current_group] = []
|
||||
elif indent > 0 and current_group:
|
||||
groups[current_group].append(label)
|
||||
return groups
|
||||
|
||||
|
||||
def test_all_expected_annotators_have_tab_entries() -> None:
|
||||
"""Assert every annotator in EXPECTED_ANNOTATOR_TAB_GROUPS has a tab in the docs.
|
||||
|
||||
Tests flat membership only — does not enforce which category each annotator
|
||||
belongs to. Update EXPECTED_ANNOTATOR_TAB_GROUPS when adding or removing
|
||||
annotator tab entries.
|
||||
"""
|
||||
tab_groups = _extract_annotator_tab_groups()
|
||||
actual_tabs = {tab for group in tab_groups.values() for tab in group}
|
||||
expected_tabs = {
|
||||
tab for group in EXPECTED_ANNOTATOR_TAB_GROUPS.values() for tab in group
|
||||
}
|
||||
assert actual_tabs == expected_tabs, (
|
||||
f"Tab set mismatch. "
|
||||
f"Missing from docs: {expected_tabs - actual_tabs!r}. "
|
||||
f"Extra in docs (add to EXPECTED_ANNOTATOR_TAB_GROUPS): "
|
||||
f"{actual_tabs - expected_tabs!r}."
|
||||
)
|
||||
|
||||
|
||||
def test_annotator_example_tab_groups_stay_within_material_limit() -> None:
|
||||
"""Assert no tab group exceeds MkDocs Material's 20-tab rendering limit."""
|
||||
tab_groups = _extract_annotator_tab_groups()
|
||||
|
||||
# Outer-tab guard is defense-in-depth; the original failure was strictly an
|
||||
# inner-tab overflow (22 inner tabs in a single flat group).
|
||||
assert len(tab_groups) <= 20
|
||||
assert all(len(group) <= 20 for group in tab_groups.values())
|
||||
|
||||
|
||||
def test_annotator_code_examples_have_no_tuple_assignment() -> None:
|
||||
"""Assert no annotated_frame assignment wraps the call in a tuple.
|
||||
|
||||
Guards against the paren-comma typo: ``annotated_frame = (call(),)``
|
||||
which creates a 1-tuple instead of the annotated image.
|
||||
"""
|
||||
docs_path = REPO_ROOT / "docs" / "detection" / "annotators.md"
|
||||
content = docs_path.read_text(encoding="utf-8")
|
||||
|
||||
fenced_blocks = re.findall(r"```python\n(.*?)```", content, re.DOTALL)
|
||||
|
||||
for block_idx, block in enumerate(fenced_blocks, 1):
|
||||
try:
|
||||
tree = ast.parse(block)
|
||||
except SyntaxError:
|
||||
continue
|
||||
|
||||
for node in ast.walk(tree):
|
||||
if (
|
||||
isinstance(node, ast.Assign)
|
||||
and any(
|
||||
isinstance(t, ast.Name) and t.id == "annotated_frame"
|
||||
for t in node.targets
|
||||
)
|
||||
and isinstance(node.value, ast.Tuple)
|
||||
):
|
||||
pytest.fail(
|
||||
f"Block {block_idx}: 'annotated_frame' assigned a tuple "
|
||||
"(paren-comma typo). "
|
||||
"Use 'annotated_frame = call()' not 'annotated_frame = (call(),)'."
|
||||
)
|
||||
@@ -1,6 +1,9 @@
|
||||
import matplotlib
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
matplotlib.use("Agg")
|
||||
|
||||
import supervision as sv
|
||||
from tests.helpers import _create_key_points
|
||||
|
||||
|
||||
@@ -2,19 +2,23 @@ from __future__ import annotations
|
||||
|
||||
import json
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from pathlib import Path
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision import Detections
|
||||
from supervision import DetectionDataset, Detections
|
||||
from supervision.dataset.formats.coco import (
|
||||
build_coco_class_index_mapping,
|
||||
classes_to_coco_categories,
|
||||
coco_annotations_to_detections,
|
||||
coco_annotations_to_masks,
|
||||
coco_categories_to_classes,
|
||||
detections_to_coco_annotations,
|
||||
group_coco_annotations_by_image_id,
|
||||
load_coco_annotations,
|
||||
save_coco_annotations,
|
||||
)
|
||||
|
||||
|
||||
@@ -40,6 +44,14 @@ def mock_coco_annotation(
|
||||
}
|
||||
|
||||
|
||||
def _empty_raw_segs(n: int) -> np.ndarray:
|
||||
"""Object-dtype array of n empty lists for coco_raw_segmentation (bbox-only)."""
|
||||
arr = np.empty(n, dtype=object)
|
||||
for i in range(n):
|
||||
arr[i] = []
|
||||
return arr
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def coco_data_with_and_without_segmentation() -> dict[str, object]:
|
||||
return {
|
||||
@@ -279,6 +291,7 @@ def test_group_coco_annotations_by_image_id(
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 100, 100]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
data={"coco_raw_segmentation": _empty_raw_segs(1)},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # single image annotations
|
||||
@@ -297,6 +310,7 @@ def test_group_coco_annotations_by_image_id(
|
||||
data={
|
||||
"iscrowd": np.array([0], dtype=int),
|
||||
"area": np.array([100 * 100]),
|
||||
"coco_raw_segmentation": _empty_raw_segs(1),
|
||||
},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
@@ -318,6 +332,7 @@ def test_group_coco_annotations_by_image_id(
|
||||
[[0, 0, 100, 100], [100, 100, 200, 200]], dtype=np.float32
|
||||
),
|
||||
class_id=np.array([0, 0], dtype=int),
|
||||
data={"coco_raw_segmentation": _empty_raw_segs(2)},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # two image annotations
|
||||
@@ -341,6 +356,7 @@ def test_group_coco_annotations_by_image_id(
|
||||
data={
|
||||
"iscrowd": np.array([0, 0], dtype=int),
|
||||
"area": np.array([100 * 100, 100 * 100]),
|
||||
"coco_raw_segmentation": _empty_raw_segs(2),
|
||||
},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
@@ -830,11 +846,11 @@ def test_build_coco_class_index_mapping(
|
||||
0,
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0, bbox=(0, 0, 100, 100), area=100 * 100
|
||||
category_id=1, bbox=(0, 0, 100, 100), area=100 * 100
|
||||
)
|
||||
],
|
||||
DoesNotRaise(),
|
||||
), # no segmentation mask
|
||||
), # no segmentation mask; internal class_id 0 -> COCO category_id 1
|
||||
(
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 4, 5]], dtype=np.float32),
|
||||
@@ -856,7 +872,7 @@ def test_build_coco_class_index_mapping(
|
||||
0,
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0,
|
||||
category_id=1,
|
||||
bbox=(0, 0, 4, 5),
|
||||
area=4 * 5,
|
||||
segmentation=[[0, 0, 0, 4, 3, 4, 3, 0]],
|
||||
@@ -886,7 +902,7 @@ def test_build_coco_class_index_mapping(
|
||||
0,
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0,
|
||||
category_id=1,
|
||||
bbox=(0, 0, 5, 5),
|
||||
area=5 * 5,
|
||||
segmentation={
|
||||
@@ -919,7 +935,7 @@ def test_build_coco_class_index_mapping(
|
||||
0,
|
||||
[
|
||||
mock_coco_annotation(
|
||||
category_id=0,
|
||||
category_id=1,
|
||||
bbox=(0, 0, 5, 5),
|
||||
area=5 * 5,
|
||||
segmentation={
|
||||
@@ -980,6 +996,80 @@ def test_detections_to_coco_annotations_handles_empty_approximated_polygons() ->
|
||||
assert annotations[0]["iscrowd"] == 0
|
||||
|
||||
|
||||
_DISJOINT_2X2_MASK = np.array(
|
||||
[
|
||||
[
|
||||
[1, 1, 0, 0, 0],
|
||||
[1, 1, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 1, 1],
|
||||
[0, 0, 0, 1, 1],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
)
|
||||
|
||||
_SINGLE_COMPONENT_MASK = np.array(
|
||||
[
|
||||
[
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 0, 0],
|
||||
[1, 1, 1, 0, 0],
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
)
|
||||
|
||||
|
||||
def _make_iscrowd0_detections(mask: np.ndarray) -> Detections:
|
||||
"""Build a single-detection Detections with iscrowd=0 from a (1, H, W) mask."""
|
||||
_, h, w = mask.shape
|
||||
return Detections(
|
||||
xyxy=np.array([[0, 0, w, h]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=mask,
|
||||
data={"iscrowd": np.array([0])},
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("mask", "expected_segment_count"),
|
||||
[
|
||||
pytest.param(_DISJOINT_2X2_MASK, 2, id="disjoint-two-parts"),
|
||||
pytest.param(_SINGLE_COMPONENT_MASK, 1, id="single-component"),
|
||||
],
|
||||
)
|
||||
def test_detections_to_coco_annotations_segmentation_count(
|
||||
mask: np.ndarray, expected_segment_count: int
|
||||
) -> None:
|
||||
"""Non-crowd mask export produces one polygon list entry per connected component."""
|
||||
annotations, _ = detections_to_coco_annotations(
|
||||
detections=_make_iscrowd0_detections(mask), image_id=0, annotation_id=0
|
||||
)
|
||||
|
||||
segmentation = annotations[0]["segmentation"]
|
||||
assert annotations[0]["iscrowd"] == 0
|
||||
assert isinstance(segmentation, list)
|
||||
assert len(segmentation) == expected_segment_count
|
||||
assert all(len(part) >= 6 for part in segmentation)
|
||||
assert all(np.isfinite(c) for part in segmentation for c in part)
|
||||
|
||||
|
||||
def test_detections_to_coco_annotations_round_trip_disjoint_mask() -> None:
|
||||
"""Two-part disjoint mask round-trips through COCO export and import unchanged."""
|
||||
W, H = 5, 5
|
||||
annotations, _ = detections_to_coco_annotations(
|
||||
detections=_make_iscrowd0_detections(_DISJOINT_2X2_MASK),
|
||||
image_id=0,
|
||||
annotation_id=0,
|
||||
)
|
||||
reloaded = coco_annotations_to_masks([annotations[0]], resolution_wh=(W, H))
|
||||
|
||||
assert np.array_equal(reloaded[0], _DISJOINT_2X2_MASK[0])
|
||||
|
||||
|
||||
def test_detections_to_coco_annotations_preserves_area_from_data() -> None:
|
||||
"""area stored in detections.data should be used instead of bbox area."""
|
||||
detections = Detections(
|
||||
@@ -1329,3 +1419,686 @@ def test_load_coco_annotations_force_masks_handles_missing_segmentation(
|
||||
assert image_annotations.mask.shape == (1, 5, 5)
|
||||
assert not image_annotations.mask.any()
|
||||
assert np.array_equal(image_annotations.xyxy, np.array([[0, 0, 2, 2]], dtype=float))
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def coco_data_with_multi_segment_segmentation() -> dict[str, object]:
|
||||
return {
|
||||
"categories": [
|
||||
{
|
||||
"id": 1,
|
||||
"name": "cat_eye",
|
||||
"supercategory": "animal_parts",
|
||||
}
|
||||
],
|
||||
"images": [
|
||||
{
|
||||
"id": 1,
|
||||
"file_name": "image.jpg",
|
||||
"width": 5,
|
||||
"height": 5,
|
||||
}
|
||||
],
|
||||
"annotations": [
|
||||
{
|
||||
"id": 1,
|
||||
"image_id": 1,
|
||||
"category_id": 1,
|
||||
# bbox spans both segments; area = sum of two 1x1 polygon areas
|
||||
"bbox": [0, 0, 5, 5],
|
||||
"area": 2,
|
||||
"segmentation": [
|
||||
[0, 0, 1, 0, 1, 1, 0, 1],
|
||||
[3, 3, 4, 3, 4, 4, 3, 4],
|
||||
],
|
||||
"iscrowd": 0,
|
||||
}
|
||||
],
|
||||
}
|
||||
|
||||
|
||||
class TestFromCocoMasks:
|
||||
"""Integration: DetectionDataset.from_coco loads multi-segment masks."""
|
||||
|
||||
@pytest.mark.parametrize("force_masks", [False, True])
|
||||
def test_multi_segment_masks_merged(
|
||||
self,
|
||||
tmp_path,
|
||||
coco_data_with_multi_segment_segmentation: dict[str, object],
|
||||
force_masks: bool,
|
||||
) -> None:
|
||||
"""Multi-segment masks merge correctly for both force_masks values."""
|
||||
images_directory = tmp_path / "images"
|
||||
images_directory.mkdir()
|
||||
annotations_path = tmp_path / "annotations.json"
|
||||
|
||||
annotations_path.write_text(
|
||||
json.dumps(coco_data_with_multi_segment_segmentation), encoding="utf-8"
|
||||
)
|
||||
|
||||
dataset = DetectionDataset.from_coco(
|
||||
images_directory_path=str(images_directory),
|
||||
annotations_path=str(annotations_path),
|
||||
force_masks=force_masks,
|
||||
)
|
||||
|
||||
annotation = dataset.annotations[str(images_directory / "image.jpg")]
|
||||
assert annotation.mask is not None
|
||||
assert annotation.mask.shape == (1, 5, 5)
|
||||
np.testing.assert_array_equal(
|
||||
annotation.mask,
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[1, 1, 0, 0, 0],
|
||||
[1, 1, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 1, 1],
|
||||
[0, 0, 0, 1, 1],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
)
|
||||
|
||||
def test_multi_segment_masks_uneven_length_no_value_error(self, tmp_path) -> None:
|
||||
"""Uneven-length segments load without ValueError (issue #1209 regression)."""
|
||||
images_directory = tmp_path / "images"
|
||||
images_directory.mkdir()
|
||||
annotations_path = tmp_path / "annotations.json"
|
||||
|
||||
coco_data = {
|
||||
"categories": [
|
||||
{"id": 1, "name": "cat_eye", "supercategory": "animal_parts"}
|
||||
],
|
||||
"images": [{"id": 1, "file_name": "image.jpg", "width": 5, "height": 5}],
|
||||
"annotations": [
|
||||
{
|
||||
"id": 1,
|
||||
"image_id": 1,
|
||||
"category_id": 1,
|
||||
"bbox": [0, 0, 5, 5],
|
||||
"area": 2,
|
||||
"segmentation": [
|
||||
[0, 0, 1, 0, 1, 1, 0, 1], # 4 points (8 coords)
|
||||
[3, 3, 4, 3, 4, 4, 3, 4, 2, 4], # 5 points (10 coords)
|
||||
],
|
||||
"iscrowd": 0,
|
||||
}
|
||||
],
|
||||
}
|
||||
annotations_path.write_text(json.dumps(coco_data), encoding="utf-8")
|
||||
|
||||
dataset = DetectionDataset.from_coco(
|
||||
images_directory_path=str(images_directory),
|
||||
annotations_path=str(annotations_path),
|
||||
)
|
||||
|
||||
annotation = dataset.annotations[str(images_directory / "image.jpg")]
|
||||
assert annotation.mask is not None
|
||||
assert annotation.mask.shape == (1, 5, 5)
|
||||
|
||||
|
||||
# --- category_id 1-indexing (regression for #1181) ---
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("classes", "expected_ids"),
|
||||
[
|
||||
([], []), # empty classes
|
||||
(["object"], [1]), # single class starts at 1
|
||||
(["cat", "dog", "bird"], [1, 2, 3]), # ids are sequential and 1-indexed
|
||||
],
|
||||
)
|
||||
def test_classes_to_coco_categories_ids_start_at_one(
|
||||
classes: list[str], expected_ids: list[int]
|
||||
) -> None:
|
||||
"""COCO categories[].id must be 1-indexed (COCO spec / CVAT requirement)."""
|
||||
categories = classes_to_coco_categories(classes=classes)
|
||||
|
||||
assert [category["id"] for category in categories] == expected_ids
|
||||
|
||||
|
||||
def test_detections_to_coco_annotations_category_id_is_one_indexed() -> None:
|
||||
"""Internal class_id k must serialize to COCO category_id k + 1."""
|
||||
detections = Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10], [5, 5, 15, 15], [1, 1, 4, 4]], dtype=np.float32),
|
||||
class_id=np.array([0, 1, 2], dtype=int),
|
||||
)
|
||||
|
||||
annotations, _ = detections_to_coco_annotations(
|
||||
detections=detections,
|
||||
image_id=1,
|
||||
annotation_id=1,
|
||||
)
|
||||
|
||||
assert [annotation["category_id"] for annotation in annotations] == [1, 2, 3]
|
||||
|
||||
|
||||
def test_coco_round_trip_preserves_class_ids_and_writes_one_indexed_categories(
|
||||
tmp_path,
|
||||
) -> None:
|
||||
"""as_coco -> from_coco is lossless for internal class_ids while the
|
||||
on-disk COCO category ids are 1-indexed (regression for #1181)."""
|
||||
classes = ["cat", "dog"]
|
||||
image_paths: list[str] = []
|
||||
annotations: dict[str, Detections] = {}
|
||||
expected_class_ids = {}
|
||||
for index, class_id in enumerate([0, 1]):
|
||||
path = str(tmp_path / f"image_{index}.jpg")
|
||||
assert cv2.imwrite(path, np.zeros((10, 10, 3), dtype=np.uint8))
|
||||
image_paths.append(path)
|
||||
detections = Detections(
|
||||
xyxy=np.array([[0, 0, 5, 5]], dtype=np.float32),
|
||||
class_id=np.array([class_id], dtype=int),
|
||||
)
|
||||
annotations[path] = detections
|
||||
expected_class_ids[Path(path).name] = class_id
|
||||
dataset = DetectionDataset(
|
||||
classes=classes, images=image_paths, annotations=annotations
|
||||
)
|
||||
|
||||
annotation_path = tmp_path / "annotations.json"
|
||||
dataset.as_coco(annotations_path=str(annotation_path))
|
||||
|
||||
# On-disk COCO ids are 1-indexed.
|
||||
with open(annotation_path) as f:
|
||||
payload = json.load(f)
|
||||
assert sorted(category["id"] for category in payload["categories"]) == [1, 2]
|
||||
assert sorted(ann["category_id"] for ann in payload["annotations"]) == [1, 2]
|
||||
|
||||
# Reading back preserves internal 0-indexed class_ids losslessly.
|
||||
loaded = DetectionDataset.from_coco(
|
||||
images_directory_path=str(tmp_path),
|
||||
annotations_path=str(annotation_path),
|
||||
)
|
||||
assert loaded.classes == classes
|
||||
for image_path, _, detections in loaded:
|
||||
name = Path(image_path).name
|
||||
assert detections.class_id is not None
|
||||
assert detections.class_id.tolist() == [expected_class_ids[name]]
|
||||
|
||||
|
||||
# --- save_coco_annotations: cross-split id chaining (regression for #768) ---
|
||||
|
||||
|
||||
def _tiny_detection_dataset(
|
||||
tmp_path, prefix: str, num_images: int, dets_per_image: int
|
||||
) -> DetectionDataset:
|
||||
"""Build a DetectionDataset of ``num_images`` 10x10 RGB images on disk,
|
||||
each holding ``dets_per_image`` 1x1 detections of class 0. Image content
|
||||
is irrelevant; only the per-image Detections drive the COCO write path."""
|
||||
classes = ["object"]
|
||||
image_paths: list[str] = []
|
||||
annotations: dict[str, Detections] = {}
|
||||
for i in range(num_images):
|
||||
path = str(tmp_path / f"{prefix}_{i}.jpg")
|
||||
assert cv2.imwrite(path, np.zeros((10, 10, 3), dtype=np.uint8))
|
||||
image_paths.append(path)
|
||||
xyxy = np.array(
|
||||
[[float(j), 0.0, float(j) + 1.0, 1.0] for j in range(dets_per_image)],
|
||||
dtype=float,
|
||||
).reshape(-1, 4)
|
||||
annotations[path] = Detections(
|
||||
xyxy=xyxy,
|
||||
class_id=np.zeros(dets_per_image, dtype=int),
|
||||
confidence=np.ones(dets_per_image, dtype=float),
|
||||
)
|
||||
return DetectionDataset(
|
||||
classes=classes, images=image_paths, annotations=annotations
|
||||
)
|
||||
|
||||
|
||||
def _read_ids(annotation_path) -> tuple[list[int], list[int]]:
|
||||
with open(annotation_path) as f:
|
||||
payload = json.load(f)
|
||||
image_ids = [img["id"] for img in payload["images"]]
|
||||
annotation_ids = [ann["id"] for ann in payload["annotations"]]
|
||||
return image_ids, annotation_ids
|
||||
|
||||
|
||||
def test_save_coco_annotations_defaults_start_at_one(tmp_path):
|
||||
dataset = _tiny_detection_dataset(tmp_path, "img", num_images=2, dets_per_image=3)
|
||||
annotation_path = tmp_path / "annotations.json"
|
||||
|
||||
next_image_id, next_annotation_id = save_coco_annotations(
|
||||
dataset=dataset, annotation_path=str(annotation_path)
|
||||
)
|
||||
|
||||
image_ids, annotation_ids = _read_ids(annotation_path)
|
||||
assert image_ids == [1, 2]
|
||||
assert annotation_ids == [1, 2, 3, 4, 5, 6]
|
||||
# Returned ids are one greater than the highest written, ready to chain.
|
||||
assert next_image_id == 3
|
||||
assert next_annotation_id == 7
|
||||
|
||||
|
||||
def test_save_coco_annotations_respects_starting_ids(tmp_path):
|
||||
dataset = _tiny_detection_dataset(tmp_path, "img", num_images=2, dets_per_image=2)
|
||||
annotation_path = tmp_path / "annotations.json"
|
||||
|
||||
next_image_id, next_annotation_id = save_coco_annotations(
|
||||
dataset=dataset,
|
||||
annotation_path=str(annotation_path),
|
||||
starting_image_id=100,
|
||||
starting_annotation_id=500,
|
||||
)
|
||||
|
||||
image_ids, annotation_ids = _read_ids(annotation_path)
|
||||
assert image_ids == [100, 101]
|
||||
assert annotation_ids == [500, 501, 502, 503]
|
||||
assert next_image_id == 102
|
||||
assert next_annotation_id == 504
|
||||
|
||||
|
||||
def test_as_coco_chains_ids_across_splits_without_collision(tmp_path):
|
||||
"""Regression for #768: exporting train/valid/test splits with the
|
||||
returned ids fed forward yields globally unique image and annotation ids."""
|
||||
train = _tiny_detection_dataset(tmp_path, "train", num_images=3, dets_per_image=2)
|
||||
valid = _tiny_detection_dataset(tmp_path, "valid", num_images=2, dets_per_image=4)
|
||||
test = _tiny_detection_dataset(tmp_path, "test", num_images=1, dets_per_image=5)
|
||||
|
||||
train_path = tmp_path / "train.json"
|
||||
valid_path = tmp_path / "valid.json"
|
||||
test_path = tmp_path / "test.json"
|
||||
|
||||
next_image_id, next_annotation_id = train.as_coco(annotations_path=str(train_path))
|
||||
next_image_id, next_annotation_id = valid.as_coco(
|
||||
annotations_path=str(valid_path),
|
||||
starting_image_id=next_image_id,
|
||||
starting_annotation_id=next_annotation_id,
|
||||
)
|
||||
test.as_coco(
|
||||
annotations_path=str(test_path),
|
||||
starting_image_id=next_image_id,
|
||||
starting_annotation_id=next_annotation_id,
|
||||
)
|
||||
|
||||
all_image_ids: list[int] = []
|
||||
all_annotation_ids: list[int] = []
|
||||
for path in (train_path, valid_path, test_path):
|
||||
image_ids, annotation_ids = _read_ids(path)
|
||||
all_image_ids.extend(image_ids)
|
||||
all_annotation_ids.extend(annotation_ids)
|
||||
|
||||
assert len(all_image_ids) == len(set(all_image_ids)), (
|
||||
"image ids collide across splits"
|
||||
)
|
||||
assert len(all_annotation_ids) == len(set(all_annotation_ids)), (
|
||||
"annotation ids collide across splits"
|
||||
)
|
||||
# Concrete chained values.
|
||||
assert all_image_ids == [1, 2, 3, 4, 5, 6]
|
||||
assert all_annotation_ids == list(range(1, 6 + 8 + 5 + 1))
|
||||
|
||||
|
||||
def test_save_coco_annotations_empty_dataset_returns_starting_ids(tmp_path):
|
||||
"""An empty dataset writes a valid (but empty) COCO file and returns
|
||||
the starting ids unchanged so chaining still composes around it."""
|
||||
dataset = DetectionDataset(classes=["object"], images=[], annotations={})
|
||||
annotation_path = tmp_path / "annotations.json"
|
||||
|
||||
next_image_id, next_annotation_id = save_coco_annotations(
|
||||
dataset=dataset,
|
||||
annotation_path=str(annotation_path),
|
||||
starting_image_id=7,
|
||||
starting_annotation_id=42,
|
||||
)
|
||||
|
||||
image_ids, annotation_ids = _read_ids(annotation_path)
|
||||
assert image_ids == []
|
||||
assert annotation_ids == []
|
||||
assert next_image_id == 7
|
||||
assert next_annotation_id == 42
|
||||
|
||||
|
||||
def test_as_coco_without_annotations_path_returns_starting_ids(tmp_path):
|
||||
"""When only writing images, the starting ids round-trip unchanged so
|
||||
chaining still works in the images-only branch."""
|
||||
dataset = _tiny_detection_dataset(tmp_path, "img", num_images=2, dets_per_image=1)
|
||||
next_image_id, next_annotation_id = dataset.as_coco(
|
||||
images_directory_path=str(tmp_path / "imgs"),
|
||||
starting_image_id=42,
|
||||
starting_annotation_id=99,
|
||||
)
|
||||
assert next_image_id == 42
|
||||
assert next_annotation_id == 99
|
||||
|
||||
|
||||
def test_save_coco_annotations_annotation_image_id_references_correct_image(tmp_path):
|
||||
"""Every annotation's image_id must reference an image id present in the
|
||||
same file, even when a non-default starting_image_id is used."""
|
||||
dataset = _tiny_detection_dataset(tmp_path, "img", num_images=3, dets_per_image=2)
|
||||
annotation_path = tmp_path / "annotations.json"
|
||||
|
||||
save_coco_annotations(
|
||||
dataset=dataset,
|
||||
annotation_path=str(annotation_path),
|
||||
starting_image_id=100,
|
||||
starting_annotation_id=500,
|
||||
)
|
||||
|
||||
with open(annotation_path) as f:
|
||||
coco = json.load(f)
|
||||
image_id_set = {img["id"] for img in coco["images"]}
|
||||
annotation_image_ids = {ann["image_id"] for ann in coco["annotations"]}
|
||||
assert annotation_image_ids <= image_id_set, (
|
||||
"annotation image_id values reference unknown image ids"
|
||||
)
|
||||
|
||||
|
||||
def test_save_coco_annotations_zero_annotation_images(tmp_path):
|
||||
"""Dataset with images but zero detections per image: image ids are
|
||||
assigned sequentially but annotation list stays empty."""
|
||||
dataset = _tiny_detection_dataset(tmp_path, "img", num_images=2, dets_per_image=0)
|
||||
annotation_path = tmp_path / "annotations.json"
|
||||
|
||||
next_image_id, next_annotation_id = save_coco_annotations(
|
||||
dataset=dataset, annotation_path=str(annotation_path)
|
||||
)
|
||||
|
||||
image_ids, annotation_ids = _read_ids(annotation_path)
|
||||
assert image_ids == [1, 2]
|
||||
assert annotation_ids == []
|
||||
assert next_image_id == 3
|
||||
assert next_annotation_id == 1
|
||||
|
||||
|
||||
# --- Regression: legacy 0-indexed COCO files still load correctly (#1181) ---
|
||||
|
||||
|
||||
def test_from_coco_loads_legacy_zero_indexed_category_ids(tmp_path) -> None:
|
||||
"""COCO files with 0-indexed category ids (written by supervision <=0.28.x)
|
||||
must still load and produce correct internal 0-indexed class_ids."""
|
||||
images_dir = tmp_path / "images"
|
||||
images_dir.mkdir()
|
||||
img_path = images_dir / "img.jpg"
|
||||
assert cv2.imwrite(str(img_path), np.zeros((10, 10, 3), dtype=np.uint8))
|
||||
|
||||
coco_data = {
|
||||
"categories": [
|
||||
{"id": 0, "name": "cat", "supercategory": "none"},
|
||||
{"id": 1, "name": "dog", "supercategory": "none"},
|
||||
],
|
||||
"images": [{"id": 1, "file_name": "img.jpg", "width": 10, "height": 10}],
|
||||
"annotations": [
|
||||
{
|
||||
"id": 1,
|
||||
"image_id": 1,
|
||||
"category_id": 0,
|
||||
"bbox": [0, 0, 5, 5],
|
||||
"area": 25,
|
||||
"iscrowd": 0,
|
||||
},
|
||||
{
|
||||
"id": 2,
|
||||
"image_id": 1,
|
||||
"category_id": 1,
|
||||
"bbox": [1, 1, 3, 3],
|
||||
"area": 9,
|
||||
"iscrowd": 0,
|
||||
},
|
||||
],
|
||||
}
|
||||
annotations_path = tmp_path / "annotations.json"
|
||||
annotations_path.write_text(json.dumps(coco_data), encoding="utf-8")
|
||||
|
||||
dataset = DetectionDataset.from_coco(
|
||||
images_directory_path=str(images_dir),
|
||||
annotations_path=str(annotations_path),
|
||||
)
|
||||
|
||||
assert dataset.classes == ["cat", "dog"]
|
||||
dets = dataset.annotations[str(img_path)]
|
||||
assert dets.class_id is not None
|
||||
assert sorted(dets.class_id.tolist()) == [0, 1]
|
||||
|
||||
|
||||
# --- save_coco_annotations ValueError guards ---
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("starting_image_id", "starting_annotation_id"),
|
||||
[
|
||||
(0, 1),
|
||||
(1, 0),
|
||||
(0, 0),
|
||||
],
|
||||
)
|
||||
def test_save_coco_annotations_rejects_zero_starting_ids(
|
||||
tmp_path, starting_image_id: int, starting_annotation_id: int
|
||||
) -> None:
|
||||
"""starting_image_id and starting_annotation_id below 1 must raise ValueError."""
|
||||
dataset = DetectionDataset(classes=["object"], images=[], annotations={})
|
||||
annotation_path = tmp_path / "annotations.json"
|
||||
|
||||
with pytest.raises(ValueError, match="must be >= 1"):
|
||||
save_coco_annotations(
|
||||
dataset=dataset,
|
||||
annotation_path=str(annotation_path),
|
||||
starting_image_id=starting_image_id,
|
||||
starting_annotation_id=starting_annotation_id,
|
||||
)
|
||||
|
||||
|
||||
# --- detections_to_coco_annotations: class_id=None guard ---
|
||||
|
||||
|
||||
def test_detections_to_coco_annotations_raises_when_class_id_is_none() -> None:
|
||||
"""Detections with no class_id must raise ValueError before +1 arithmetic."""
|
||||
detections = Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
class_id=None,
|
||||
)
|
||||
|
||||
with pytest.raises(ValueError, match="class_id"):
|
||||
detections_to_coco_annotations(
|
||||
detections=detections,
|
||||
image_id=1,
|
||||
annotation_id=1,
|
||||
)
|
||||
|
||||
|
||||
# --- Round-trip: multi-class-per-image case ---
|
||||
|
||||
|
||||
def test_coco_round_trip_multi_class_single_image(tmp_path) -> None:
|
||||
"""Single image with two detections of different classes round-trips losslessly."""
|
||||
img_path = str(tmp_path / "img.jpg")
|
||||
assert cv2.imwrite(img_path, np.zeros((10, 10, 3), dtype=np.uint8))
|
||||
|
||||
dataset = DetectionDataset(
|
||||
classes=["cat", "dog"],
|
||||
images=[img_path],
|
||||
annotations={
|
||||
img_path: Detections(
|
||||
xyxy=np.array([[0, 0, 5, 5], [1, 1, 4, 4]], dtype=np.float32),
|
||||
class_id=np.array([0, 1], dtype=int),
|
||||
)
|
||||
},
|
||||
)
|
||||
|
||||
annotation_path = tmp_path / "annotations.json"
|
||||
dataset.as_coco(annotations_path=str(annotation_path))
|
||||
|
||||
with open(annotation_path) as f:
|
||||
payload = json.load(f)
|
||||
assert sorted(ann["category_id"] for ann in payload["annotations"]) == [1, 2]
|
||||
|
||||
loaded = DetectionDataset.from_coco(
|
||||
images_directory_path=str(tmp_path),
|
||||
annotations_path=str(annotation_path),
|
||||
)
|
||||
dets = loaded.annotations[img_path]
|
||||
assert dets.class_id is not None
|
||||
assert sorted(dets.class_id.tolist()) == [0, 1]
|
||||
|
||||
|
||||
# --- Regression: segmentation round-trip (#2285) ---
|
||||
|
||||
|
||||
def _coco_annotation_with_segmentation(
|
||||
segmentation: list[list[int]],
|
||||
bbox: tuple[float, float, float, float] = (0, 0, 5, 5),
|
||||
area: float = 25,
|
||||
) -> dict:
|
||||
return mock_coco_annotation(
|
||||
annotation_id=1,
|
||||
image_id=1,
|
||||
category_id=1,
|
||||
bbox=bbox,
|
||||
area=area,
|
||||
segmentation=segmentation,
|
||||
)
|
||||
|
||||
|
||||
def _single_image_coco_data(annotation: dict) -> dict[str, object]:
|
||||
return {
|
||||
"info": {},
|
||||
"licenses": [],
|
||||
"categories": [{"id": 1, "name": "cat", "supercategory": ""}],
|
||||
"images": [{"id": 1, "file_name": "img.jpg", "width": 10, "height": 10}],
|
||||
"annotations": [annotation],
|
||||
}
|
||||
|
||||
|
||||
def test_detections_to_coco_annotations_exports_all_polygons() -> None:
|
||||
"""All polygons from a multi-component mask must be exported, not just the first."""
|
||||
# Build a mask with two separate rectangles (disjoint components)
|
||||
mask = np.zeros((20, 20), dtype=bool)
|
||||
mask[1:4, 1:4] = True # top-left component
|
||||
mask[14:18, 14:18] = True # bottom-right component
|
||||
|
||||
detections = Detections(
|
||||
xyxy=np.array([[1, 1, 4, 4]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=np.array([mask]),
|
||||
data={"iscrowd": np.array([0], dtype=int)},
|
||||
)
|
||||
annotations, _ = detections_to_coco_annotations(
|
||||
detections=detections, image_id=1, annotation_id=1
|
||||
)
|
||||
assert len(annotations) == 1
|
||||
seg = annotations[0]["segmentation"]
|
||||
# Both components must appear as separate polygon entries (list of lists)
|
||||
assert isinstance(seg, list), "segmentation must be a list of polygons"
|
||||
assert len(seg) >= 2
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("segmentation", "bbox", "area", "expected_min_polygon_count"),
|
||||
[
|
||||
pytest.param(
|
||||
[[0, 0, 4, 0, 4, 4, 0, 4]],
|
||||
(0, 0, 5, 5),
|
||||
25,
|
||||
1,
|
||||
id="single-polygon",
|
||||
),
|
||||
pytest.param(
|
||||
[[0, 0, 4, 0, 4, 4, 0, 4], [6, 6, 9, 6, 9, 9, 6, 9]],
|
||||
(0, 0, 9, 9),
|
||||
32,
|
||||
2,
|
||||
id="multi-polygon",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_coco_polygon_segmentation_survives_roundtrip(
|
||||
tmp_path,
|
||||
segmentation: list[list[int]],
|
||||
bbox: tuple[float, float, float, float],
|
||||
area: float,
|
||||
expected_min_polygon_count: int,
|
||||
) -> None:
|
||||
"""COCO polygon segmentation survives the load/export sequence.
|
||||
|
||||
1. Write source COCO JSON with polygon segmentation.
|
||||
2. Load it through DetectionDataset.from_coco().
|
||||
3. Export it back to COCO JSON with as_coco().
|
||||
4. Assert the exported segmentation keeps the expected polygon component count.
|
||||
"""
|
||||
images_dir = tmp_path / "images"
|
||||
images_dir.mkdir()
|
||||
|
||||
img_path = images_dir / "img.jpg"
|
||||
assert cv2.imwrite(str(img_path), np.zeros((10, 10, 3), dtype=np.uint8))
|
||||
|
||||
# 1. Write source COCO JSON with polygon segmentation.
|
||||
ann_path = tmp_path / "annotations.json"
|
||||
ann_path.write_text(
|
||||
json.dumps(
|
||||
_single_image_coco_data(
|
||||
_coco_annotation_with_segmentation(
|
||||
segmentation=segmentation, bbox=bbox, area=area
|
||||
)
|
||||
)
|
||||
),
|
||||
encoding="utf-8",
|
||||
)
|
||||
|
||||
# 2. Load it through the internal DetectionDataset representation.
|
||||
ds = DetectionDataset.from_coco(
|
||||
images_directory_path=str(images_dir),
|
||||
annotations_path=str(ann_path),
|
||||
)
|
||||
|
||||
# 3. Export it back to COCO JSON.
|
||||
out_ann_path = tmp_path / "out_annotations.json"
|
||||
ds.as_coco(annotations_path=str(out_ann_path))
|
||||
|
||||
with open(out_ann_path) as f:
|
||||
out = json.load(f)
|
||||
|
||||
# 4. Assert polygon component count survives the load/export sequence.
|
||||
assert len(out["annotations"]) == 1
|
||||
seg = out["annotations"][0]["segmentation"]
|
||||
assert isinstance(seg, list)
|
||||
assert len(seg) >= expected_min_polygon_count
|
||||
|
||||
|
||||
def test_coco_raw_segmentation_preserved_when_masks_not_decoded() -> None:
|
||||
"""When masks are NOT decoded (with_masks=False), raw polygon data stored in
|
||||
data['segmentation'] is used as a lossless fallback so as_coco() still emits
|
||||
non-empty segmentation."""
|
||||
image_annotations = [
|
||||
_coco_annotation_with_segmentation(segmentation=[[0, 0, 4, 0, 4, 4, 0, 4]])
|
||||
]
|
||||
|
||||
# Load WITHOUT mask decoding — mask must be None
|
||||
detections = coco_annotations_to_detections(
|
||||
image_annotations=image_annotations,
|
||||
resolution_wh=(10, 10),
|
||||
with_masks=False,
|
||||
)
|
||||
assert detections.mask is None
|
||||
# Raw segmentation must be stored in data for fallback
|
||||
assert "coco_raw_segmentation" in detections.data
|
||||
|
||||
# Export must still produce non-empty segmentation via fallback
|
||||
annotations, _ = detections_to_coco_annotations(
|
||||
detections=detections, image_id=1, annotation_id=1
|
||||
)
|
||||
assert len(annotations) == 1
|
||||
assert annotations[0]["segmentation"] != []
|
||||
|
||||
|
||||
def test_coco_iscrowd_mask_exports_as_rle() -> None:
|
||||
"""Multi-segment mask exports segmentation as RLE dict (iscrowd inferred as 1)."""
|
||||
mask = np.zeros((10, 10), dtype=bool)
|
||||
mask[1:3, 1:3] = True # top-left component
|
||||
mask[7:9, 7:9] = True # bottom-right component (two separate regions)
|
||||
|
||||
detections = Detections(
|
||||
xyxy=np.array([[1, 1, 8, 8]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=np.array([mask]),
|
||||
)
|
||||
annotations, _ = detections_to_coco_annotations(
|
||||
detections=detections, image_id=1, annotation_id=1
|
||||
)
|
||||
assert len(annotations) == 1
|
||||
seg = annotations[0]["segmentation"]
|
||||
assert isinstance(seg, dict), "multi-segment mask must export as RLE dict, not list"
|
||||
assert "counts" in seg
|
||||
assert "size" in seg
|
||||
|
||||
@@ -8,6 +8,7 @@ from defusedxml import ElementTree
|
||||
|
||||
from supervision.dataset.formats.pascal_voc import (
|
||||
detections_from_xml_obj,
|
||||
detections_to_pascal_voc,
|
||||
object_to_pascal_voc,
|
||||
parse_polygon_points,
|
||||
)
|
||||
@@ -72,6 +73,47 @@ def test_object_to_pascal_voc(
|
||||
assert are_xml_elements_equal(result, expected_result)
|
||||
|
||||
|
||||
def test_object_to_pascal_voc_does_not_mutate_inputs():
|
||||
"""Serializing an object must not write the 1-index offset back into the inputs."""
|
||||
xyxy = np.array([10, 20, 30, 40], dtype=np.float32)
|
||||
polygon = np.array([[0, 0], [10, 0], [10, 10], [0, 10]], dtype=np.float32)
|
||||
|
||||
object_to_pascal_voc(xyxy=xyxy, name="test", polygon=polygon)
|
||||
|
||||
assert np.array_equal(xyxy, np.array([10, 20, 30, 40], dtype=np.float32))
|
||||
assert np.array_equal(
|
||||
polygon, np.array([[0, 0], [10, 0], [10, 10], [0, 10]], dtype=np.float32)
|
||||
)
|
||||
|
||||
|
||||
def test_object_to_pascal_voc_does_not_mutate_view_input():
|
||||
"""Mutation guard holds when xyxy is a NumPy row-view (the actual bug scenario)."""
|
||||
base = np.array([[10, 20, 30, 40]], dtype=np.float32)
|
||||
xyxy_view = base[0] # row-view, shares memory with base
|
||||
|
||||
object_to_pascal_voc(xyxy=xyxy_view, name="test", polygon=None)
|
||||
|
||||
assert np.array_equal(base[0], np.array([10, 20, 30, 40], dtype=np.float32)), (
|
||||
"object_to_pascal_voc mutated the source array via a view"
|
||||
)
|
||||
|
||||
|
||||
def test_detections_to_pascal_voc_does_not_mutate_detections():
|
||||
"""Exporting detections must not shift the source xyxy, and must be repeatable."""
|
||||
detections = _create_detections(xyxy=[[10, 20, 30, 40]], class_id=[0])
|
||||
expected_xyxy = detections.xyxy.copy()
|
||||
|
||||
first = detections_to_pascal_voc(
|
||||
detections, classes=["test"], filename="image.jpg", image_shape=(100, 100, 3)
|
||||
)
|
||||
second = detections_to_pascal_voc(
|
||||
detections, classes=["test"], filename="image.jpg", image_shape=(100, 100, 3)
|
||||
)
|
||||
|
||||
assert np.array_equal(detections.xyxy, expected_xyxy)
|
||||
assert first == second
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("polygon_element", "expected_result", "exception"),
|
||||
[
|
||||
|
||||
@@ -1,7 +1,5 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
import tempfile
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from pathlib import Path
|
||||
|
||||
@@ -9,7 +7,10 @@ import numpy as np
|
||||
import pytest
|
||||
from PIL import Image
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.dataset.core import DetectionDataset
|
||||
from supervision.dataset.formats.yolo import (
|
||||
_extract_class_names,
|
||||
_image_name_to_annotation_name,
|
||||
_with_seg_mask,
|
||||
detections_to_yolo_annotations,
|
||||
@@ -233,6 +234,50 @@ def test_image_name_to_annotation_name(
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("yaml_text", "expected_names", "exception"),
|
||||
[
|
||||
(
|
||||
"names:\n '0': background\n '1': person\n"
|
||||
" '2': car\n '10': traffic_light\n",
|
||||
["background", "person", "car", "traffic_light"],
|
||||
DoesNotRaise(),
|
||||
), # quoted string numeric keys sort by integer value, not lexicographically
|
||||
(
|
||||
"names:\n 0: background\n 2: car\n 10: traffic_light\n",
|
||||
["background", "car", "traffic_light"],
|
||||
DoesNotRaise(),
|
||||
), # native int keys (most common YOLO format from Ultralytics/Roboflow)
|
||||
(
|
||||
"names:\n cat: 0\n dog: 1\n",
|
||||
["0", "1"],
|
||||
DoesNotRaise(),
|
||||
), # non-numeric string keys fall back to lexicographic sort
|
||||
(
|
||||
"names: {}\n",
|
||||
[],
|
||||
DoesNotRaise(),
|
||||
), # empty names dict returns empty list
|
||||
(
|
||||
"names:\n '--1': ignore\n '0': person\n",
|
||||
None,
|
||||
pytest.raises(ValueError, match="mix"),
|
||||
), # mixed numeric/non-numeric keys raise ValueError
|
||||
],
|
||||
)
|
||||
def test_extract_class_names_sorts_numeric_string_keys(
|
||||
tmp_path: Path,
|
||||
yaml_text: str,
|
||||
expected_names: list[str] | None,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
"""_extract_class_names returns class names sorted by class index."""
|
||||
data_yaml_path = tmp_path / "data.yaml"
|
||||
data_yaml_path.write_text(yaml_text, encoding="utf-8")
|
||||
with exception:
|
||||
assert _extract_class_names(file_path=str(data_yaml_path)) == expected_names
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("xyxy", "class_id", "image_shape", "polygon", "expected_result", "exception"),
|
||||
[
|
||||
@@ -315,105 +360,53 @@ def test_detections_to_yolo_annotations_raises_for_non_integer_class_id() -> Non
|
||||
)
|
||||
|
||||
|
||||
def test_load_yolo_annotations_obb_does_not_generate_masks() -> None:
|
||||
"""OBB annotations must not produce mask arrays (memory regression test)."""
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
images_dir = os.path.join(tmp_dir, "images")
|
||||
labels_dir = os.path.join(tmp_dir, "labels")
|
||||
os.makedirs(images_dir)
|
||||
os.makedirs(labels_dir)
|
||||
@pytest.mark.parametrize(
|
||||
("annotation_line", "load_kwargs", "expect_mask"),
|
||||
[
|
||||
pytest.param(
|
||||
"0 0.4 0.4 0.6 0.4 0.6 0.6 0.4 0.6",
|
||||
{"is_obb": True},
|
||||
False,
|
||||
id="obb-no-mask",
|
||||
),
|
||||
pytest.param(
|
||||
"0 0.4 0.4 0.6 0.4 0.6 0.6 0.4 0.6",
|
||||
{"is_obb": True, "force_masks": True},
|
||||
False,
|
||||
id="obb-force_masks-ignored",
|
||||
),
|
||||
pytest.param(
|
||||
"0 0.1 0.1 0.9 0.1 0.9 0.9",
|
||||
{"is_obb": False},
|
||||
True,
|
||||
id="segmentation-produces-mask",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_load_yolo_annotations_mask_behaviour(
|
||||
tmp_path: Path,
|
||||
annotation_line: str,
|
||||
load_kwargs: dict,
|
||||
expect_mask: bool,
|
||||
) -> None:
|
||||
"""Mask presence depends on annotation format and OBB/segmentation flag."""
|
||||
images_dir = tmp_path / "images"
|
||||
labels_dir = tmp_path / "labels"
|
||||
images_dir.mkdir()
|
||||
labels_dir.mkdir()
|
||||
Image.new("RGB", (100, 100)).save(images_dir / "test.jpg")
|
||||
(labels_dir / "test.txt").write_text(annotation_line + "\n")
|
||||
(tmp_path / "data.yaml").write_text("names: ['object']\n")
|
||||
|
||||
# Create a small RGB image
|
||||
img = Image.new("RGB", (100, 100))
|
||||
img.save(os.path.join(images_dir, "test.jpg"))
|
||||
_, _, annotations = load_yolo_annotations(
|
||||
images_directory_path=str(images_dir),
|
||||
annotations_directory_path=str(labels_dir),
|
||||
data_yaml_path=str(tmp_path / "data.yaml"),
|
||||
**load_kwargs,
|
||||
)
|
||||
|
||||
# OBB annotation: class_id x1 y1 x2 y2 x3 y3 x4 y4 (9 values per line)
|
||||
with open(os.path.join(labels_dir, "test.txt"), "w") as f:
|
||||
f.write("0 0.4 0.4 0.6 0.4 0.6 0.6 0.4 0.6\n")
|
||||
|
||||
# Create a minimal data.yaml
|
||||
data_yaml_path = os.path.join(tmp_dir, "data.yaml")
|
||||
with open(data_yaml_path, "w") as f:
|
||||
f.write("names: ['object']\n")
|
||||
|
||||
_, _, annotations = load_yolo_annotations(
|
||||
images_directory_path=images_dir,
|
||||
annotations_directory_path=labels_dir,
|
||||
data_yaml_path=data_yaml_path,
|
||||
is_obb=True,
|
||||
)
|
||||
|
||||
assert len(annotations) == 1
|
||||
detection = next(iter(annotations.values()))
|
||||
assert detection.mask is None, (
|
||||
"OBB annotations must not produce mask arrays to avoid excessive memory use"
|
||||
)
|
||||
|
||||
|
||||
def test_load_yolo_annotations_obb_force_masks_ignored() -> None:
|
||||
"""force_masks=True must have no effect when is_obb=True."""
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
images_dir = os.path.join(tmp_dir, "images")
|
||||
labels_dir = os.path.join(tmp_dir, "labels")
|
||||
os.makedirs(images_dir)
|
||||
os.makedirs(labels_dir)
|
||||
|
||||
img = Image.new("RGB", (100, 100))
|
||||
img.save(os.path.join(images_dir, "test.jpg"))
|
||||
|
||||
with open(os.path.join(labels_dir, "test.txt"), "w") as f:
|
||||
f.write("0 0.4 0.4 0.6 0.4 0.6 0.6 0.4 0.6\n")
|
||||
|
||||
data_yaml_path = os.path.join(tmp_dir, "data.yaml")
|
||||
with open(data_yaml_path, "w") as f:
|
||||
f.write("names: ['object']\n")
|
||||
|
||||
_, _, annotations = load_yolo_annotations(
|
||||
images_directory_path=images_dir,
|
||||
annotations_directory_path=labels_dir,
|
||||
data_yaml_path=data_yaml_path,
|
||||
is_obb=True,
|
||||
force_masks=True,
|
||||
)
|
||||
|
||||
assert len(annotations) == 1
|
||||
detection = next(iter(annotations.values()))
|
||||
assert detection.mask is None, (
|
||||
"force_masks=True must be ignored for OBB annotations"
|
||||
)
|
||||
|
||||
|
||||
def test_load_yolo_annotations_segmentation_produces_masks() -> None:
|
||||
"""Segmentation annotations with is_obb=False must still produce masks."""
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
images_dir = os.path.join(tmp_dir, "images")
|
||||
labels_dir = os.path.join(tmp_dir, "labels")
|
||||
os.makedirs(images_dir)
|
||||
os.makedirs(labels_dir)
|
||||
|
||||
img = Image.new("RGB", (100, 100))
|
||||
img.save(os.path.join(images_dir, "test.jpg"))
|
||||
|
||||
# Polygon annotation: class_id + 3 x,y pairs (7 tokens > 5 triggers mask)
|
||||
with open(os.path.join(labels_dir, "test.txt"), "w") as f:
|
||||
f.write("0 0.1 0.1 0.9 0.1 0.9 0.9\n")
|
||||
|
||||
data_yaml_path = os.path.join(tmp_dir, "data.yaml")
|
||||
with open(data_yaml_path, "w") as f:
|
||||
f.write("names: ['object']\n")
|
||||
|
||||
_, _, annotations = load_yolo_annotations(
|
||||
images_directory_path=images_dir,
|
||||
annotations_directory_path=labels_dir,
|
||||
data_yaml_path=data_yaml_path,
|
||||
is_obb=False,
|
||||
)
|
||||
|
||||
assert len(annotations) == 1
|
||||
detection = next(iter(annotations.values()))
|
||||
assert detection.mask is not None, (
|
||||
"Segmentation annotations with is_obb=False must produce mask arrays"
|
||||
)
|
||||
detection = next(iter(annotations.values()))
|
||||
assert (detection.mask is not None) == expect_mask
|
||||
|
||||
|
||||
def test_polygons_to_masks_multiple_polygons_shape() -> None:
|
||||
@@ -538,3 +531,223 @@ def test_yolo_polygon_mask_precision_no_coord_drift_round_trip_iou(
|
||||
f"Mask IoU {iou:.6f} too low after YOLO load/save round-trip — "
|
||||
"precision regression in polygon mask conversion"
|
||||
)
|
||||
|
||||
|
||||
def test_detections_to_yolo_annotations_obb_emits_nine_tokens() -> None:
|
||||
"""`is_obb=True` must serialize the 4 corners from `data['xyxyxyxy']`."""
|
||||
corners = np.array(
|
||||
[[[50.0, 10.0], [90.0, 50.0], [50.0, 90.0], [10.0, 50.0]]], dtype=np.float32
|
||||
)
|
||||
detections = Detections(
|
||||
xyxy=np.array([[10.0, 10.0, 90.0, 90.0]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
data={ORIENTED_BOX_COORDINATES: corners},
|
||||
)
|
||||
|
||||
lines = detections_to_yolo_annotations(
|
||||
detections=detections, image_shape=(100, 100, 3), is_obb=True
|
||||
)
|
||||
|
||||
assert len(lines) == 1
|
||||
tokens = lines[0].split()
|
||||
assert len(tokens) == 9, (
|
||||
f"OBB export must produce 9 tokens (class + 4 (x,y) pairs), got {tokens}"
|
||||
)
|
||||
assert tokens[0] == "0"
|
||||
np.testing.assert_allclose(
|
||||
np.array(tokens[1:], dtype=np.float32),
|
||||
np.array([0.5, 0.1, 0.9, 0.5, 0.5, 0.9, 0.1, 0.5], dtype=np.float32),
|
||||
atol=1e-5,
|
||||
)
|
||||
|
||||
|
||||
def test_detections_to_yolo_annotations_obb_raises_without_corners() -> None:
|
||||
"""`is_obb=True` without `'xyxyxyxy'` in data must fail loudly, not silently."""
|
||||
detections = Detections(
|
||||
xyxy=np.array([[10.0, 10.0, 90.0, 90.0]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
)
|
||||
with pytest.raises(ValueError, match=ORIENTED_BOX_COORDINATES):
|
||||
detections_to_yolo_annotations(
|
||||
detections=detections, image_shape=(100, 100, 3), is_obb=True
|
||||
)
|
||||
|
||||
|
||||
def test_detections_to_yolo_annotations_obb_empty_emits_no_lines() -> None:
|
||||
"""`is_obb=True` on an empty `Detections` must not raise — image had no labels."""
|
||||
lines = detections_to_yolo_annotations(
|
||||
detections=Detections.empty(), image_shape=(100, 100, 3), is_obb=True
|
||||
)
|
||||
assert lines == []
|
||||
|
||||
|
||||
def test_detections_to_yolo_annotations_obb_multiple_detections() -> None:
|
||||
"""OBB export must correctly serialize N>1 detections per image."""
|
||||
corners = np.array(
|
||||
[
|
||||
[[50.0, 10.0], [90.0, 50.0], [50.0, 90.0], [10.0, 50.0]],
|
||||
[[20.0, 20.0], [80.0, 20.0], [80.0, 40.0], [20.0, 40.0]],
|
||||
],
|
||||
dtype=np.float32,
|
||||
)
|
||||
detections = Detections(
|
||||
xyxy=np.array(
|
||||
[[10.0, 10.0, 90.0, 90.0], [20.0, 20.0, 80.0, 40.0]], dtype=np.float32
|
||||
),
|
||||
class_id=np.array([0, 1], dtype=int),
|
||||
data={ORIENTED_BOX_COORDINATES: corners},
|
||||
)
|
||||
|
||||
lines = detections_to_yolo_annotations(
|
||||
detections=detections, image_shape=(100, 100, 3), is_obb=True
|
||||
)
|
||||
|
||||
assert len(lines) == 2, f"Expected 2 annotation lines, got {len(lines)}"
|
||||
for i, line in enumerate(lines):
|
||||
tokens = line.split()
|
||||
assert len(tokens) == 9, (
|
||||
f"Detection {i}: expected 9 tokens, got {len(tokens)}: {tokens}"
|
||||
)
|
||||
assert lines[0].split()[0] == "0"
|
||||
assert lines[1].split()[0] == "1"
|
||||
np.testing.assert_allclose(
|
||||
np.array(lines[1].split()[1:], dtype=np.float32),
|
||||
np.array([0.2, 0.2, 0.8, 0.2, 0.8, 0.4, 0.2, 0.4], dtype=np.float32),
|
||||
atol=1e-5,
|
||||
)
|
||||
|
||||
|
||||
def test_detections_to_yolo_annotations_obb_data_ignored_when_is_obb_false() -> None:
|
||||
"""OBB data in detections.data must be silently ignored when is_obb=False."""
|
||||
corners = np.array(
|
||||
[[[50.0, 10.0], [90.0, 50.0], [50.0, 90.0], [10.0, 50.0]]],
|
||||
dtype=np.float32,
|
||||
)
|
||||
detections = Detections(
|
||||
xyxy=np.array([[10.0, 10.0, 90.0, 90.0]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
data={ORIENTED_BOX_COORDINATES: corners},
|
||||
)
|
||||
|
||||
lines = detections_to_yolo_annotations(
|
||||
detections=detections, image_shape=(100, 100, 3), is_obb=False
|
||||
)
|
||||
|
||||
assert len(lines) == 1
|
||||
assert len(lines[0].split()) == 5, (
|
||||
"Without is_obb=True, OBB data must be ignored and bbox format (5 tokens) used"
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("is_obb_save", "expected_tokens"),
|
||||
[
|
||||
pytest.param(True, 9, id="obb-save-nine-tokens"),
|
||||
pytest.param(False, 5, id="default-save-five-tokens"),
|
||||
],
|
||||
)
|
||||
def test_dataset_as_yolo_obb_output_token_count(
|
||||
tmp_path: Path, is_obb_save: bool, expected_tokens: int
|
||||
) -> None:
|
||||
"""Token count in saved YOLO line reflects the is_obb flag at export time."""
|
||||
images_dir = tmp_path / "images"
|
||||
labels_dir = tmp_path / "labels"
|
||||
images_dir.mkdir()
|
||||
labels_dir.mkdir()
|
||||
Image.new("RGB", (100, 100)).save(images_dir / "test.jpg")
|
||||
(labels_dir / "test.txt").write_text("0 0.5 0.1 0.9 0.5 0.5 0.9 0.1 0.5\n")
|
||||
(tmp_path / "data.yaml").write_text("names: ['object']\n")
|
||||
|
||||
loaded = DetectionDataset.from_yolo(
|
||||
images_directory_path=str(images_dir),
|
||||
annotations_directory_path=str(labels_dir),
|
||||
data_yaml_path=str(tmp_path / "data.yaml"),
|
||||
is_obb=True,
|
||||
)
|
||||
|
||||
out_labels_dir = tmp_path / "out_labels"
|
||||
loaded.as_yolo(
|
||||
annotations_directory_path=str(out_labels_dir),
|
||||
data_yaml_path=str(tmp_path / "out_data.yaml"),
|
||||
is_obb=is_obb_save,
|
||||
)
|
||||
|
||||
tokens = (out_labels_dir / "test.txt").read_text().split()
|
||||
assert len(tokens) == expected_tokens, (
|
||||
f"expected {expected_tokens}-token line, got {len(tokens)}: {tokens}"
|
||||
)
|
||||
|
||||
|
||||
def test_dataset_as_yolo_obb_round_trip_corner_accuracy(tmp_path: Path) -> None:
|
||||
"""OBB round-trip via `from_yolo` -> `as_yolo` must preserve the 4 corners."""
|
||||
images_dir = tmp_path / "images"
|
||||
labels_dir = tmp_path / "labels"
|
||||
images_dir.mkdir()
|
||||
labels_dir.mkdir()
|
||||
# Non-square image and rotated rhombus exercise both axes.
|
||||
Image.new("RGB", (200, 100)).save(images_dir / "test.jpg")
|
||||
(labels_dir / "test.txt").write_text("0 0.5 0.1 0.9 0.5 0.5 0.9 0.1 0.5\n")
|
||||
(tmp_path / "data.yaml").write_text("names: ['object']\n")
|
||||
|
||||
loaded = DetectionDataset.from_yolo(
|
||||
images_directory_path=str(images_dir),
|
||||
annotations_directory_path=str(labels_dir),
|
||||
data_yaml_path=str(tmp_path / "data.yaml"),
|
||||
is_obb=True,
|
||||
)
|
||||
|
||||
out_labels_dir = tmp_path / "out_labels"
|
||||
loaded.as_yolo(
|
||||
annotations_directory_path=str(out_labels_dir),
|
||||
data_yaml_path=str(tmp_path / "out_data.yaml"),
|
||||
is_obb=True,
|
||||
)
|
||||
|
||||
reloaded = DetectionDataset.from_yolo(
|
||||
images_directory_path=str(images_dir),
|
||||
annotations_directory_path=str(out_labels_dir),
|
||||
data_yaml_path=str(tmp_path / "out_data.yaml"),
|
||||
is_obb=True,
|
||||
)
|
||||
original = next(iter(loaded.annotations.values()))
|
||||
round_tripped = next(iter(reloaded.annotations.values()))
|
||||
np.testing.assert_allclose(
|
||||
round_tripped.data[ORIENTED_BOX_COORDINATES],
|
||||
original.data[ORIENTED_BOX_COORDINATES],
|
||||
atol=1e-3,
|
||||
)
|
||||
|
||||
|
||||
def test_dataset_as_yolo_obb_round_trip_with_background_image(
|
||||
tmp_path: Path,
|
||||
) -> None:
|
||||
"""OBB round-trip with a label-less image must not raise ValueError."""
|
||||
images_dir = tmp_path / "images"
|
||||
labels_dir = tmp_path / "labels"
|
||||
images_dir.mkdir()
|
||||
labels_dir.mkdir()
|
||||
Image.new("RGB", (100, 100)).save(images_dir / "annotated.jpg")
|
||||
Image.new("RGB", (100, 100)).save(images_dir / "background.jpg")
|
||||
(labels_dir / "annotated.txt").write_text("0 0.5 0.1 0.9 0.5 0.5 0.9 0.1 0.5\n")
|
||||
# No labels/background.txt — background image has no annotations.
|
||||
(tmp_path / "data.yaml").write_text("names: ['object']\n")
|
||||
|
||||
loaded = DetectionDataset.from_yolo(
|
||||
images_directory_path=str(images_dir),
|
||||
annotations_directory_path=str(labels_dir),
|
||||
data_yaml_path=str(tmp_path / "data.yaml"),
|
||||
is_obb=True,
|
||||
)
|
||||
|
||||
out_labels_dir = tmp_path / "out_labels"
|
||||
loaded.as_yolo(
|
||||
annotations_directory_path=str(out_labels_dir),
|
||||
data_yaml_path=str(tmp_path / "out_data.yaml"),
|
||||
is_obb=True,
|
||||
)
|
||||
|
||||
bg_label = out_labels_dir / "background.txt"
|
||||
assert bg_label.exists(), "Background image must produce a label file"
|
||||
assert bg_label.read_text().strip() == "", (
|
||||
"Background image label file must be empty"
|
||||
)
|
||||
|
||||
@@ -6,7 +6,15 @@ from contextlib import ExitStack as DoesNotRaise
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.detection.core import Detections, merge_inner_detection_object_pair
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import (
|
||||
Detections,
|
||||
_merge_detection_group,
|
||||
_merge_obb_corners,
|
||||
merge_inner_detection_object_pair,
|
||||
)
|
||||
from supervision.detection.utils.boxes import xyxyxyxy_to_xyxy
|
||||
from supervision.detection.utils.iou_and_nms import OverlapMetric
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.utils.internal import SupervisionWarnings
|
||||
from tests.helpers import _create_detections
|
||||
@@ -933,3 +941,966 @@ def test_merge_inner_detection_object_pair(
|
||||
def test_is_empty(detections: Detections, expected: bool) -> None:
|
||||
"""Verify is_empty() returns True iff the Detections object has zero detections."""
|
||||
assert detections.is_empty() == expected
|
||||
|
||||
|
||||
def test_from_inference_empty_class_name_dtype_matches_non_empty() -> None:
|
||||
"""Empty and non-empty results should produce string-kind class_name arrays."""
|
||||
empty_result = {"predictions": [], "image": {"width": 100, "height": 100}}
|
||||
non_empty_result = {
|
||||
"predictions": [
|
||||
{
|
||||
"x": 50,
|
||||
"y": 50,
|
||||
"width": 20,
|
||||
"height": 20,
|
||||
"confidence": 0.9,
|
||||
"class": "cat",
|
||||
"class_id": 0,
|
||||
}
|
||||
],
|
||||
"image": {"width": 100, "height": 100},
|
||||
}
|
||||
empty = Detections.from_inference(empty_result)
|
||||
non_empty = Detections.from_inference(non_empty_result)
|
||||
|
||||
# null-safety: class_name must be an array, not None
|
||||
assert empty["class_name"] is not None
|
||||
assert non_empty["class_name"] is not None
|
||||
|
||||
# dtype kind must match between empty and non-empty paths
|
||||
assert empty["class_name"].dtype.kind == non_empty["class_name"].dtype.kind == "U"
|
||||
|
||||
# all data keys and dtypes must match between empty and non-empty paths
|
||||
assert set(empty.data.keys()) == set(non_empty.data.keys())
|
||||
for key in non_empty.data:
|
||||
assert empty.data[key].dtype.kind == non_empty.data[key].dtype.kind, key
|
||||
|
||||
# concatenation across empty+non-empty must produce a string-kind array
|
||||
concat = np.concatenate([empty["class_name"], non_empty["class_name"]])
|
||||
assert concat.dtype.kind == "U"
|
||||
|
||||
|
||||
def test_from_inference_sdk_dict_path_empty_preserves_class_name_dtype() -> None:
|
||||
"""SDK objects with .dict() and empty predictions produce string-kind class_name."""
|
||||
|
||||
class _FakeSdkResult:
|
||||
def dict(self, **kwargs: object) -> dict:
|
||||
return {"predictions": [], "image": {"width": 100, "height": 100}}
|
||||
|
||||
detections = Detections.from_inference(_FakeSdkResult())
|
||||
assert detections["class_name"] is not None
|
||||
assert detections["class_name"].dtype.kind == "U"
|
||||
|
||||
|
||||
def _rotated_rect(
|
||||
cx: float, cy: float, w: float, h: float, angle_deg: float
|
||||
) -> np.ndarray:
|
||||
angle = np.deg2rad(angle_deg)
|
||||
cos, sin = np.cos(angle), np.sin(angle)
|
||||
rot = np.array([[cos, -sin], [sin, cos]])
|
||||
corners = np.array(
|
||||
[[-w / 2, -h / 2], [w / 2, -h / 2], [w / 2, h / 2], [-w / 2, h / 2]]
|
||||
)
|
||||
return (corners @ rot.T + [cx, cy]).astype(np.float32)
|
||||
|
||||
|
||||
def _make_obb_detections(
|
||||
quads: list[np.ndarray], scores: list[float], class_ids: list[int]
|
||||
) -> Detections:
|
||||
"""Build OBB Detections from a list of (4, 2) corner arrays."""
|
||||
oriented_boxes = np.stack(quads)
|
||||
xyxy = xyxyxyxy_to_xyxy(oriented_boxes)
|
||||
return Detections(
|
||||
xyxy=xyxy,
|
||||
confidence=np.array(scores, dtype=np.float32),
|
||||
class_id=np.array(class_ids, dtype=int),
|
||||
data={ORIENTED_BOX_COORDINATES: oriented_boxes},
|
||||
)
|
||||
|
||||
|
||||
class TestDetectionsObbDispatch:
|
||||
"""Shared OBB-aware dispatch behaviour for `with_nms` and `with_nmm`."""
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"method",
|
||||
[
|
||||
pytest.param("with_nms", id="with_nms"),
|
||||
pytest.param("with_nmm", id="with_nmm"),
|
||||
],
|
||||
)
|
||||
def test_uses_obb_iou_when_oriented_box_coordinates_present(
|
||||
self, method: str
|
||||
) -> None:
|
||||
"""X-pattern OBBs: both survive under either method because OBB IoU < 0.5."""
|
||||
quad_a = _rotated_rect(50, 50, 100, 10, +45)
|
||||
quad_b = _rotated_rect(50, 50, 100, 10, -45)
|
||||
detections = _make_obb_detections([quad_a, quad_b], [0.9, 0.85], [0, 0])
|
||||
|
||||
result = getattr(detections, method)(threshold=0.5)
|
||||
|
||||
assert len(result) == 2
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"method",
|
||||
[
|
||||
pytest.param("with_nms", id="with_nms"),
|
||||
pytest.param("with_nmm", id="with_nmm"),
|
||||
],
|
||||
)
|
||||
def test_falls_back_without_obb_data(self, method: str) -> None:
|
||||
"""Non-OBB heavily-overlapping AABBs collapse to one under either method."""
|
||||
detections = Detections(
|
||||
xyxy=np.array([[0, 0, 100, 100], [10, 10, 110, 110]], dtype=np.float32),
|
||||
confidence=np.array([0.9, 0.85], dtype=np.float32),
|
||||
class_id=np.array([0, 0], dtype=int),
|
||||
)
|
||||
|
||||
result = getattr(detections, method)(threshold=0.5)
|
||||
|
||||
assert len(result) == 1
|
||||
|
||||
|
||||
class TestMergeObbCorners:
|
||||
"""_merge_obb_corners"""
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("corners_list", "expected"),
|
||||
[
|
||||
pytest.param(
|
||||
[np.array([[0, 0], [10, 0], [10, 5], [0, 5]], dtype=np.float32)],
|
||||
np.array([[0, 0], [10, 0], [10, 5], [0, 5]], dtype=np.float32),
|
||||
id="single-box-passthrough",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
np.array([[0, 0], [10, 0], [10, 5], [0, 5]], dtype=np.float32),
|
||||
np.array([[2, 2], [12, 2], [12, 7], [2, 7]], dtype=np.float32),
|
||||
],
|
||||
np.array([[0, 0], [12, 0], [12, 7], [0, 7]], dtype=np.float32),
|
||||
id="two-axis-aligned",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
_rotated_rect(50, 50, 40, 10, 45),
|
||||
_rotated_rect(55, 55, 40, 10, 45),
|
||||
],
|
||||
None,
|
||||
id="two-same-angle",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
_rotated_rect(50, 50, 40, 10, 30),
|
||||
_rotated_rect(55, 50, 40, 10, -15),
|
||||
],
|
||||
None,
|
||||
id="two-different-angles",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
np.array([[0, 0], [20, 0], [20, 10], [0, 10]], dtype=np.float32),
|
||||
np.array([[5, 5], [25, 5], [25, 15], [5, 15]], dtype=np.float32),
|
||||
np.array([[10, 0], [30, 0], [30, 10], [10, 10]], dtype=np.float32),
|
||||
],
|
||||
np.array([[0, 0], [30, 0], [30, 15], [0, 15]], dtype=np.float32),
|
||||
id="three-boxes-axis-aligned",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
np.array([[0, 0], [10, 0], [10, 5], [0, 5]], dtype=np.float32),
|
||||
np.array([[0, 0], [10, 0], [10, 5], [0, 5]], dtype=np.float32),
|
||||
],
|
||||
np.array([[0, 0], [10, 0], [10, 5], [0, 5]], dtype=np.float32),
|
||||
id="identical-boxes",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
np.array([[0, 0], [10, 0], [10, 5], [0, 5]], dtype=np.float32),
|
||||
np.array([[3, 3], [7, 3], [7, 3], [3, 3]], dtype=np.float32),
|
||||
],
|
||||
np.array([[0, 0], [10, 0], [10, 5], [0, 5]], dtype=np.float32),
|
||||
id="degenerate-collinear",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_merge(
|
||||
self, corners_list: list[np.ndarray], expected: np.ndarray | None
|
||||
) -> None:
|
||||
"""Produces correct merged OBB corners."""
|
||||
result = _merge_obb_corners(corners_list)
|
||||
assert result.shape == (4, 2)
|
||||
if expected is not None:
|
||||
assert np.allclose(result, expected, atol=0.5)
|
||||
else:
|
||||
assert result.dtype == np.float32
|
||||
|
||||
|
||||
class TestMergeDetectionGroup:
|
||||
"""_merge_detection_group"""
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("detections", "expected_detections"),
|
||||
[
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([1]),
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([1]),
|
||||
),
|
||||
id="single-passthrough",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[5, 5, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.7], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.8], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
id="two-aabb-merge",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[5, 5, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.8], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]], dtype=np.float32),
|
||||
confidence=np.array([0.7], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 20, 20]], dtype=np.float32),
|
||||
confidence=np.array([0.8], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
id="three-aabb-merge",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
mask=np.array([[[True, False], [False, False]]], dtype=bool),
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[5, 5, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.7], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
mask=np.array([[[False, True], [False, False]]], dtype=bool),
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.8], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
mask=np.array([[[True, True], [False, False]]], dtype=bool),
|
||||
),
|
||||
id="two-aabb-with-mask",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
_make_obb_detections(
|
||||
[
|
||||
np.array(
|
||||
[[0, 0], [10, 0], [10, 5], [0, 5]],
|
||||
dtype=np.float32,
|
||||
)
|
||||
],
|
||||
[0.9],
|
||||
[0],
|
||||
),
|
||||
_make_obb_detections(
|
||||
[
|
||||
np.array(
|
||||
[[2, 2], [12, 2], [12, 7], [2, 7]],
|
||||
dtype=np.float32,
|
||||
)
|
||||
],
|
||||
[0.7],
|
||||
[0],
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 12, 7]], dtype=np.float32),
|
||||
confidence=np.array([0.8], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
id="two-obb-axis-aligned",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
_make_obb_detections(
|
||||
[_rotated_rect(50, 50, 40, 10, 45)], [0.9], [0]
|
||||
),
|
||||
_make_obb_detections(
|
||||
[_rotated_rect(55, 55, 40, 10, 45)], [0.8], [0]
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[32.32, 32.32, 72.68, 72.68]], dtype=np.float32),
|
||||
confidence=np.array([0.85], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
id="two-obb-rotated",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([1]),
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[5, 5, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.5], dtype=np.float32),
|
||||
class_id=np.array([2]),
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.7], dtype=np.float32),
|
||||
class_id=np.array([1]),
|
||||
),
|
||||
id="winner-takes-class-id",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
tracker_id=np.array([42]),
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[5, 5, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.5], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
tracker_id=np.array([99]),
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.7], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
tracker_id=np.array([42]),
|
||||
),
|
||||
id="winner-takes-tracker-id",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
data={"class_name": np.array(["cat"])},
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[5, 5, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.5], dtype=np.float32),
|
||||
class_id=np.array([1]),
|
||||
data={"class_name": np.array(["dog"])},
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.7], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
data={"class_name": np.array(["cat"])},
|
||||
),
|
||||
id="winner-takes-data",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=None,
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[5, 5, 15, 15]], dtype=np.float32),
|
||||
confidence=None,
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 15, 15]], dtype=np.float32),
|
||||
confidence=None,
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
id="no-confidence",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=None,
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[5, 5, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.7], dtype=np.float32),
|
||||
class_id=None,
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.8], dtype=np.float32),
|
||||
class_id=None,
|
||||
),
|
||||
id="no-class-id",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
data={"score": np.array([1.5])},
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[5, 5, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.5], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
data={"score": np.array([2.5])},
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.7], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
data={"score": np.array([1.5])},
|
||||
),
|
||||
id="custom-data-field-preserved",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[5, 5, 5, 5]], dtype=np.float32),
|
||||
confidence=np.array([0.7], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
id="zero-area-box-in-group",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.9], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
metadata={"source": "model_a"},
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[5, 5, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.7], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
metadata={"source": "model_a"},
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 15, 15]], dtype=np.float32),
|
||||
confidence=np.array([0.8], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
),
|
||||
id="metadata-merge",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_merge(
|
||||
self,
|
||||
detections: list[Detections],
|
||||
expected_detections: Detections,
|
||||
) -> None:
|
||||
"""Merges detection group correctly."""
|
||||
result = _merge_detection_group(detections)
|
||||
assert len(result) == 1
|
||||
assert np.allclose(result.xyxy, expected_detections.xyxy, atol=0.5)
|
||||
if expected_detections.confidence is not None:
|
||||
assert np.allclose(
|
||||
result.confidence, expected_detections.confidence, atol=1e-3
|
||||
)
|
||||
else:
|
||||
assert result.confidence is None
|
||||
if expected_detections.class_id is not None:
|
||||
assert np.array_equal(result.class_id, expected_detections.class_id)
|
||||
else:
|
||||
assert result.class_id is None
|
||||
if expected_detections.tracker_id is not None:
|
||||
assert np.array_equal(result.tracker_id, expected_detections.tracker_id)
|
||||
else:
|
||||
assert result.tracker_id is None
|
||||
if expected_detections.mask is not None:
|
||||
assert np.array_equal(result.mask, expected_detections.mask)
|
||||
else:
|
||||
assert result.mask is None
|
||||
for key, val in expected_detections.data.items():
|
||||
assert np.array_equal(result.data[key], val)
|
||||
if ORIENTED_BOX_COORDINATES in result.data:
|
||||
corners = result.data[ORIENTED_BOX_COORDINATES]
|
||||
assert np.allclose(result.xyxy, xyxyxyxy_to_xyxy(corners), atol=1e-5)
|
||||
|
||||
|
||||
class TestDetectionsWithNMM:
|
||||
"""NMM-specific behaviour tests for `Detections.with_nmm`."""
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
(
|
||||
"corners",
|
||||
"confidence",
|
||||
"class_ids",
|
||||
"iou_threshold",
|
||||
"class_agnostic",
|
||||
"overlap_metric",
|
||||
"expected_corners",
|
||||
"expected_confidence",
|
||||
"exception",
|
||||
),
|
||||
[
|
||||
pytest.param(
|
||||
[
|
||||
[[10, 10], [50, 10], [50, 30], [10, 30]],
|
||||
[[11, 11], [51, 11], [51, 31], [11, 31]],
|
||||
],
|
||||
[0.9, 0.85],
|
||||
[0, 0],
|
||||
0.5,
|
||||
False,
|
||||
OverlapMetric.IOU,
|
||||
[[[10, 10], [51, 10], [51, 31], [10, 31]]],
|
||||
[0.875],
|
||||
DoesNotRaise(),
|
||||
id="axis-aligned-merge",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
_rotated_rect(50, 50, 40, 10, 45).tolist(),
|
||||
_rotated_rect(55, 55, 40, 10, 45).tolist(),
|
||||
],
|
||||
[0.9, 0.8],
|
||||
[0, 0],
|
||||
0.3,
|
||||
False,
|
||||
OverlapMetric.IOU,
|
||||
[[[39.39, 32.32], [72.68, 65.61], [65.61, 72.68], [32.32, 39.39]]],
|
||||
[0.85],
|
||||
DoesNotRaise(),
|
||||
id="rotated-45deg-merge",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
[[0, 0], [20, 0], [20, 10], [0, 10]],
|
||||
[[5, 5], [25, 5], [25, 15], [5, 15]],
|
||||
[[10, 0], [30, 0], [30, 10], [10, 10]],
|
||||
],
|
||||
[0.9, 0.8, 0.7],
|
||||
[0, 0, 0],
|
||||
0.2,
|
||||
False,
|
||||
OverlapMetric.IOU,
|
||||
[[[0, 0], [30, 0], [30, 15], [0, 15]]],
|
||||
[0.8],
|
||||
DoesNotRaise(),
|
||||
id="three-group-merge",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
[[10, 10], [50, 10], [50, 30], [10, 30]],
|
||||
],
|
||||
[0.9],
|
||||
[0],
|
||||
0.5,
|
||||
False,
|
||||
OverlapMetric.IOU,
|
||||
[[[10, 10], [50, 10], [50, 30], [10, 30]]],
|
||||
[0.9],
|
||||
DoesNotRaise(),
|
||||
id="single-passthrough",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
[[0, 0], [30, 0], [30, 20], [0, 20]],
|
||||
[[5, 5], [35, 5], [35, 25], [5, 25]],
|
||||
],
|
||||
[0.9, 0.8],
|
||||
[0, 1],
|
||||
0.3,
|
||||
True,
|
||||
OverlapMetric.IOU,
|
||||
[[[0, 0], [35, 0], [35, 25], [0, 25]]],
|
||||
[0.85],
|
||||
DoesNotRaise(),
|
||||
id="class-agnostic",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
[[0, 0], [40, 0], [40, 30], [0, 30]],
|
||||
[[10, 10], [30, 10], [30, 20], [10, 20]],
|
||||
],
|
||||
[0.9, 0.8],
|
||||
[0, 0],
|
||||
0.3,
|
||||
False,
|
||||
OverlapMetric.IOS,
|
||||
[[[0, 0], [40, 0], [40, 30], [0, 30]]],
|
||||
[0.885714],
|
||||
DoesNotRaise(),
|
||||
id="ios-metric",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
_rotated_rect(50, 50, 40, 15, 30).tolist(),
|
||||
_rotated_rect(55, 50, 40, 15, -15).tolist(),
|
||||
],
|
||||
[0.9, 0.7],
|
||||
[0, 0],
|
||||
0.2,
|
||||
False,
|
||||
OverlapMetric.IOU,
|
||||
[[[43.65, 20.99], [81.56, 42.88], [62.12, 76.56], [24.21, 54.68]]],
|
||||
[0.813652],
|
||||
DoesNotRaise(),
|
||||
id="mixed-angle-merge",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
[[0, 0], [30, 0], [30, 20], [0, 20]],
|
||||
[[5, 5], [35, 5], [35, 25], [5, 25]],
|
||||
[[200, 200], [240, 200], [240, 220], [200, 220]],
|
||||
[[205, 205], [245, 205], [245, 225], [205, 225]],
|
||||
],
|
||||
[0.9, 0.7, 0.85, 0.6],
|
||||
[0, 0, 0, 0],
|
||||
0.2,
|
||||
False,
|
||||
OverlapMetric.IOU,
|
||||
[
|
||||
[[0, 0], [35, 0], [35, 25], [0, 25]],
|
||||
[[200, 200], [245, 200], [245, 225], [200, 225]],
|
||||
],
|
||||
[0.8, 0.725],
|
||||
DoesNotRaise(),
|
||||
id="two-separate-groups",
|
||||
),
|
||||
pytest.param(
|
||||
[
|
||||
[[0, 0], [30, 0], [30, 20], [0, 20]],
|
||||
[[5, 10], [25, 10], [25, 10], [5, 10]],
|
||||
],
|
||||
[0.9, 0.7],
|
||||
[0, 0],
|
||||
0.01,
|
||||
False,
|
||||
OverlapMetric.IOU,
|
||||
# A zero-area (collinear) OBB scores IoU 0 (see
|
||||
# test_degenerate_boxes_score_zero), so it cannot group and the
|
||||
# two detections are not merged.
|
||||
[
|
||||
[[0, 0], [30, 0], [30, 20], [0, 20]],
|
||||
[[5, 10], [25, 10], [25, 10], [5, 10]],
|
||||
],
|
||||
[0.9, 0.7],
|
||||
DoesNotRaise(),
|
||||
id="degenerate-collinear-obb",
|
||||
),
|
||||
pytest.param(
|
||||
None,
|
||||
[0.9, 0.8],
|
||||
[0, 0],
|
||||
0.4,
|
||||
False,
|
||||
OverlapMetric.IOU,
|
||||
None,
|
||||
None,
|
||||
pytest.raises(ValueError, match="corners must have shape"),
|
||||
id="flat-n8-raises",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_obb_nmm_merge(
|
||||
self,
|
||||
corners: list[list[list[float]]] | None,
|
||||
confidence: list[float],
|
||||
class_ids: list[int],
|
||||
iou_threshold: float,
|
||||
class_agnostic: bool,
|
||||
overlap_metric: OverlapMetric,
|
||||
expected_corners: list[list[list[float]]] | None,
|
||||
expected_confidence: list[float] | None,
|
||||
exception: DoesNotRaise,
|
||||
) -> None:
|
||||
"""OBB NMM produces correct geometry and confidence."""
|
||||
if corners is None:
|
||||
xyxy = np.array(
|
||||
[[0, 0, 30, 20], [5, 5, 35, 25]],
|
||||
dtype=np.float32,
|
||||
)
|
||||
flat = np.array(
|
||||
[
|
||||
[0, 0, 30, 0, 30, 20, 0, 20],
|
||||
[5, 5, 35, 5, 35, 25, 5, 25],
|
||||
],
|
||||
dtype=np.float32,
|
||||
)
|
||||
detections = Detections(
|
||||
xyxy=xyxy,
|
||||
confidence=np.array(confidence, dtype=np.float32),
|
||||
class_id=np.array(class_ids),
|
||||
data={ORIENTED_BOX_COORDINATES: flat},
|
||||
)
|
||||
else:
|
||||
corner_arrays = [np.array(corner, dtype=np.float32) for corner in corners]
|
||||
detections = _make_obb_detections(corner_arrays, confidence, class_ids)
|
||||
|
||||
with exception:
|
||||
result = detections.with_nmm(
|
||||
threshold=iou_threshold,
|
||||
class_agnostic=class_agnostic,
|
||||
overlap_metric=overlap_metric,
|
||||
)
|
||||
|
||||
assert expected_confidence is not None
|
||||
assert expected_corners is not None
|
||||
assert len(result) == len(expected_confidence)
|
||||
for i, exp_c in enumerate(expected_confidence):
|
||||
assert result.confidence[i] == pytest.approx(exp_c, abs=1e-3)
|
||||
result_corners = result.data[ORIENTED_BOX_COORDINATES]
|
||||
expected_corner_array = np.array(expected_corners, dtype=np.float32)
|
||||
assert np.allclose(
|
||||
result_corners,
|
||||
expected_corner_array,
|
||||
atol=0.5,
|
||||
)
|
||||
|
||||
def test_obb_nmm_matches_aabb_for_axis_aligned(self) -> None:
|
||||
"""Axis-aligned OBB NMM produces same envelope as AABB NMM."""
|
||||
xyxy = np.array([[0, 0, 30, 20], [5, 5, 35, 25]], dtype=np.float32)
|
||||
confidence = np.array([0.9, 0.5], dtype=np.float32)
|
||||
class_id = np.array([0, 0])
|
||||
|
||||
aabb_detections = Detections(
|
||||
xyxy=xyxy,
|
||||
confidence=confidence,
|
||||
class_id=class_id,
|
||||
)
|
||||
obb_detections = _make_obb_detections(
|
||||
[
|
||||
np.array(
|
||||
[[0, 0], [30, 0], [30, 20], [0, 20]],
|
||||
dtype=np.float32,
|
||||
),
|
||||
np.array(
|
||||
[[5, 5], [35, 5], [35, 25], [5, 25]],
|
||||
dtype=np.float32,
|
||||
),
|
||||
],
|
||||
confidence.tolist(),
|
||||
class_id.tolist(),
|
||||
)
|
||||
|
||||
aabb_result = aabb_detections.with_nmm(threshold=0.4)
|
||||
obb_result = obb_detections.with_nmm(threshold=0.4)
|
||||
|
||||
assert len(aabb_result) == 1
|
||||
assert len(obb_result) == 1
|
||||
assert np.allclose(aabb_result.xyxy, obb_result.xyxy, atol=1e-4)
|
||||
|
||||
def test_staircase_obb_merge_within_union(self) -> None:
|
||||
"""Diagonal staircase OBBs: merged AABB equals axis-aligned union."""
|
||||
quads = [
|
||||
np.array(
|
||||
[[0, 0], [20, 0], [20, 20], [0, 20]],
|
||||
dtype=np.float32,
|
||||
),
|
||||
np.array(
|
||||
[[12, 12], [32, 12], [32, 32], [12, 32]],
|
||||
dtype=np.float32,
|
||||
),
|
||||
np.array(
|
||||
[[24, 24], [44, 24], [44, 44], [24, 44]],
|
||||
dtype=np.float32,
|
||||
),
|
||||
]
|
||||
detections = _make_obb_detections(quads, [0.7, 0.9, 0.8], [0, 0, 0])
|
||||
|
||||
result = detections.with_nmm(threshold=0.05)
|
||||
|
||||
assert len(result) == 1
|
||||
assert np.allclose(result.xyxy, [[0.0, 0.0, 44.0, 44.0]], atol=0.5)
|
||||
|
||||
def test_obb_nmm_empty_detections(self) -> None:
|
||||
"""Empty OBB detections return empty result."""
|
||||
dets = Detections(
|
||||
xyxy=np.empty((0, 4), dtype=np.float32),
|
||||
confidence=np.array([], dtype=np.float32),
|
||||
class_id=np.array([], dtype=int),
|
||||
data={ORIENTED_BOX_COORDINATES: np.empty((0, 4, 2), dtype=np.float32)},
|
||||
)
|
||||
|
||||
result = dets.with_nmm(threshold=0.5)
|
||||
|
||||
assert len(result) == 0
|
||||
|
||||
|
||||
class TestDetectionsArea:
|
||||
"""Selection order for the `area` property: mask → OBB → AABB."""
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("width", "height", "angle_deg", "expected_area"),
|
||||
[
|
||||
pytest.param(20, 10, 0, 200.0, id="axis-aligned"),
|
||||
pytest.param(20, 10, 45, 200.0, id="45-deg rotation"),
|
||||
pytest.param(20, 10, 30, 200.0, id="30-deg rotation"),
|
||||
pytest.param(20, 10, -60, 200.0, id="negative rotation"),
|
||||
],
|
||||
)
|
||||
def test_uses_oriented_box_corners_when_present(
|
||||
self, width: float, height: float, angle_deg: float, expected_area: float
|
||||
) -> None:
|
||||
"""Area equals the rotated body's area regardless of rotation, not the AABB."""
|
||||
quad = _rotated_rect(50, 50, width, height, angle_deg)
|
||||
detections = _make_obb_detections([quad], [0.9], [0])
|
||||
|
||||
assert np.allclose(detections.area, [expected_area])
|
||||
|
||||
def test_falls_back_to_box_area_without_obb_data(self) -> None:
|
||||
"""Without ORIENTED_BOX_COORDINATES, area mirrors box_area (AABB)."""
|
||||
detections = Detections(
|
||||
xyxy=np.array([[0, 0, 20, 10]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
)
|
||||
|
||||
assert np.allclose(detections.area, [200.0])
|
||||
assert np.allclose(detections.area, detections.box_area)
|
||||
|
||||
def test_mask_takes_precedence_over_oriented_box(self) -> None:
|
||||
"""When both `mask` and `ORIENTED_BOX_COORDINATES` are present, area is
|
||||
computed from the mask."""
|
||||
mask = np.zeros((40, 40), dtype=bool)
|
||||
mask[10:30, 10:25] = True # 20 rows x 15 cols = 300 pixels
|
||||
quad = _rotated_rect(20, 20, 20, 10, 0) # OBB area = 200
|
||||
detections = Detections(
|
||||
xyxy=np.array([[10, 10, 25, 30]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=mask[None, ...],
|
||||
data={ORIENTED_BOX_COORDINATES: quad[None, ...]},
|
||||
)
|
||||
|
||||
assert np.allclose(detections.area, [300.0])
|
||||
|
||||
def test_empty_detections_with_obb_data_returns_empty_array(self) -> None:
|
||||
"""Boundary case: empty Detections carrying an OBB data field must
|
||||
return an empty area array (matches the mask / box_area branches)."""
|
||||
detections = Detections(
|
||||
xyxy=np.empty((0, 4), dtype=np.float32),
|
||||
class_id=np.array([], dtype=int),
|
||||
data={ORIENTED_BOX_COORDINATES: np.empty((0, 4, 2), dtype=np.float32)},
|
||||
)
|
||||
|
||||
assert detections.area.shape == (0,)
|
||||
|
||||
def test_degenerate_oriented_box_has_zero_area(self) -> None:
|
||||
"""An OBB whose four corners coincide has zero area — the shoelace
|
||||
formula must not produce NaN or a negative value."""
|
||||
quad = np.full((4, 2), 5.0, dtype=np.float32)
|
||||
detections = _make_obb_detections([quad], [0.9], [0])
|
||||
|
||||
assert np.allclose(detections.area, [0.0])
|
||||
|
||||
def test_handles_batched_oriented_boxes(self) -> None:
|
||||
"""Multiple OBBs in one `Detections` each get their own correct area.
|
||||
Guards against the shoelace reduction collapsing across boxes instead
|
||||
of along the per-box corner axis."""
|
||||
quads = [
|
||||
_rotated_rect(50, 50, 20, 10, 0), # 200
|
||||
_rotated_rect(100, 100, 20, 10, 45), # 200 (rotation must not change it)
|
||||
_rotated_rect(150, 150, 30, 5, 30), # 150
|
||||
]
|
||||
detections = _make_obb_detections(quads, [0.9, 0.9, 0.9], [0, 0, 0])
|
||||
|
||||
assert np.allclose(detections.area, [200.0, 200.0, 150.0])
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"bad_shape",
|
||||
[
|
||||
pytest.param((1, 8), id="flat-N8"),
|
||||
pytest.param((1, 3, 2), id="triangle"),
|
||||
],
|
||||
)
|
||||
def test_raises_on_malformed_obb_coordinates_shape(self, bad_shape: tuple) -> None:
|
||||
"""ValueError when OBB data shape is wrong for area computation."""
|
||||
bad_corners = np.zeros(bad_shape, dtype=np.float32)
|
||||
detections = Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
data={ORIENTED_BOX_COORDINATES: bad_corners},
|
||||
)
|
||||
|
||||
with pytest.raises(ValueError, match="must have shape"):
|
||||
_ = detections.area
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("branch", "expected_dtype"),
|
||||
[
|
||||
pytest.param("obb", np.float64, id="obb-branch-float64"),
|
||||
pytest.param("aabb", np.float32, id="aabb-branch-preserves-input-dtype"),
|
||||
pytest.param("mask", np.int64, id="mask-branch-int64"),
|
||||
],
|
||||
)
|
||||
def test_area_return_dtype_per_branch(
|
||||
self, branch: str, expected_dtype: type
|
||||
) -> None:
|
||||
"""Area dtype matches the documented per-branch contract."""
|
||||
if branch == "obb":
|
||||
quad = _rotated_rect(50, 50, 20, 10, 0)
|
||||
detections = _make_obb_detections([quad], [0.9], [0])
|
||||
elif branch == "aabb":
|
||||
detections = Detections(
|
||||
xyxy=np.array([[0, 0, 20, 10]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
)
|
||||
else:
|
||||
mask = np.zeros((1, 40, 40), dtype=bool)
|
||||
mask[0, 10:30, 10:30] = True
|
||||
detections = Detections(
|
||||
xyxy=np.array([[10, 10, 30, 30]], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=mask,
|
||||
)
|
||||
|
||||
assert detections.area.dtype == expected_dtype
|
||||
|
||||
@@ -395,6 +395,53 @@ def test_json_sink(
|
||||
assert_json_equal(file_name, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("scalar", "expected"),
|
||||
[
|
||||
pytest.param(np.int64(7), 7, id="np_int64"),
|
||||
pytest.param(np.float32(0.5), pytest.approx(0.5), id="np_float32"),
|
||||
pytest.param(np.float64(1.5), pytest.approx(1.5), id="np_float64"),
|
||||
pytest.param(np.int32(3), 3, id="np_int32"),
|
||||
pytest.param(np.bool_(True), True, id="np_bool"),
|
||||
],
|
||||
)
|
||||
def test_json_sink_serializes_numpy_scalar_custom_data(
|
||||
tmp_path: Any, scalar: Any, expected: Any
|
||||
) -> None:
|
||||
"""NumPy scalar in custom_data serializes as a JSON number or boolean."""
|
||||
file_name = str(tmp_path / "test_numpy_scalar.json")
|
||||
detections = sv.Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
confidence=np.array([0.9]),
|
||||
)
|
||||
with sv.JSONSink(file_name) as sink:
|
||||
sink.append(detections, custom_data={"value": scalar})
|
||||
with open(file_name) as f:
|
||||
data = json.load(f)
|
||||
assert data[0]["value"] == expected
|
||||
|
||||
|
||||
def test_json_sink_serializes_nested_numpy_array_custom_data(tmp_path: Any) -> None:
|
||||
"""NumPy array nested inside a custom_data dict value serializes as a JSON array."""
|
||||
file_name = str(tmp_path / "test_nested_array.json")
|
||||
detections = sv.Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
class_id=np.array([0]),
|
||||
)
|
||||
with sv.JSONSink(file_name) as sink:
|
||||
sink.append(detections, custom_data={"meta": {"arr": np.array([1, 2, 3])}})
|
||||
with open(file_name) as f:
|
||||
data = json.load(f)
|
||||
assert data[0]["meta"]["arr"] == [1, 2, 3]
|
||||
|
||||
|
||||
def test_json_default_raises_for_unserializable_type() -> None:
|
||||
"""_json_default raises TypeError for non-numpy objects."""
|
||||
with pytest.raises(TypeError, match="is not JSON serializable"):
|
||||
sv.JSONSink._json_default(object())
|
||||
|
||||
|
||||
def assert_json_equal(file_name, expected_rows):
|
||||
with open(file_name) as file:
|
||||
data = json.load(file)
|
||||
|
||||
+56
-10
@@ -27,49 +27,49 @@ from supervision.detection.vlm import (
|
||||
"",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
(np.empty((0, 4)), np.empty((0,), dtype=int), np.empty(0).astype(str)),
|
||||
), # empty text
|
||||
(
|
||||
does_not_raise(),
|
||||
"",
|
||||
(1000, 1000),
|
||||
["cat", "dog"],
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
(np.empty((0, 4)), np.empty((0,), dtype=int), np.empty(0).astype(str)),
|
||||
), # empty text, classes
|
||||
(
|
||||
does_not_raise(),
|
||||
"\n",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
(np.empty((0, 4)), np.empty((0,), dtype=int), np.empty(0).astype(str)),
|
||||
), # newline only
|
||||
(
|
||||
does_not_raise(),
|
||||
"the quick brown fox jumps over the lazy dog.",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
(np.empty((0, 4)), np.empty((0,), dtype=int), np.empty(0).astype(str)),
|
||||
), # random text, no location
|
||||
(
|
||||
does_not_raise(),
|
||||
"<loc0256><loc0768><loc0768> cat",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
(np.empty((0, 4)), np.empty((0,), dtype=int), np.empty(0).astype(str)),
|
||||
), # partial location
|
||||
(
|
||||
does_not_raise(),
|
||||
"<loc0256><loc0256><loc0768><loc0768><loc0768> cat",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
(np.empty((0, 4)), np.empty((0,), dtype=int), np.empty(0).astype(str)),
|
||||
), # extra loc
|
||||
(
|
||||
does_not_raise(),
|
||||
"<loc0256><loc0256><loc0768><loc0768>",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0).astype(str)),
|
||||
(np.empty((0, 4)), np.empty((0,), dtype=int), np.empty(0).astype(str)),
|
||||
), # no class
|
||||
(
|
||||
does_not_raise(),
|
||||
@@ -436,21 +436,21 @@ def test_from_qwen_2_5_vl(
|
||||
"random text",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0, dtype=str)),
|
||||
(np.empty((0, 4)), np.empty((0,), dtype=int), np.empty(0, dtype=str)),
|
||||
), # random text without JSON format
|
||||
(
|
||||
does_not_raise(),
|
||||
"```json\ninvalid json\n```",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0, dtype=str)),
|
||||
(np.empty((0, 4)), np.empty((0,), dtype=int), np.empty(0, dtype=str)),
|
||||
), # invalid JSON within code blocks
|
||||
(
|
||||
does_not_raise(),
|
||||
"```json\n[]\n```",
|
||||
(1000, 1000),
|
||||
None,
|
||||
(np.empty((0, 4)), None, np.empty(0, dtype=str)),
|
||||
(np.empty((0, 4)), np.empty((0,), dtype=int), np.empty(0, dtype=str)),
|
||||
), # empty JSON array
|
||||
(
|
||||
does_not_raise(),
|
||||
@@ -1297,3 +1297,49 @@ def test_from_deepseek_vl_2(
|
||||
detections.data[CLASS_NAME_DATA_FIELD],
|
||||
expected_detections.data[CLASS_NAME_DATA_FIELD],
|
||||
)
|
||||
|
||||
|
||||
def test_from_google_gemini_2_5_malformed_mask_keeps_confidence_aligned():
|
||||
"""A non-data-URI mask must not skip the item's confidence and desync arrays."""
|
||||
result = (
|
||||
'[{"box_2d": [10, 10, 100, 100], "label": "cat", "mask": "bad", '
|
||||
'"confidence": 0.8}, {"box_2d": [20, 20, 120, 120], "label": "dog", '
|
||||
'"mask": "bad", "confidence": 0.9}]'
|
||||
)
|
||||
|
||||
xyxy, _, _, confidence, masks = from_google_gemini_2_5(
|
||||
result=result, resolution_wh=(640, 480)
|
||||
)
|
||||
|
||||
assert xyxy.shape == (2, 4)
|
||||
assert confidence is not None
|
||||
assert confidence.shape == (2,)
|
||||
assert np.allclose(confidence, [0.8, 0.9])
|
||||
assert masks is not None
|
||||
assert masks.shape == (2, 480, 640)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("parser", "result"),
|
||||
[
|
||||
pytest.param(
|
||||
from_google_gemini_2_0, "[1, 2, 3]", id="gemini_2_0_non_dict_items"
|
||||
),
|
||||
pytest.param(from_google_gemini_2_0, "42", id="gemini_2_0_non_list"),
|
||||
pytest.param(
|
||||
from_google_gemini_2_5, "[1, 2, 3]", id="gemini_2_5_non_dict_items"
|
||||
),
|
||||
pytest.param(from_google_gemini_2_5, "42", id="gemini_2_5_non_list"),
|
||||
pytest.param(from_qwen_2_5_vl, "[1, 2, 3]", id="qwen_2_5_non_dict_items"),
|
||||
pytest.param(from_qwen_2_5_vl, "42", id="qwen_2_5_non_list"),
|
||||
],
|
||||
)
|
||||
def test_vlm_parsers_degrade_on_malformed_json(parser, result):
|
||||
"""Valid JSON of the wrong shape should yield empty results, not raise."""
|
||||
kwargs: dict = {"resolution_wh": (640, 480)}
|
||||
if parser is from_qwen_2_5_vl:
|
||||
kwargs["input_wh"] = (640, 480)
|
||||
|
||||
xyxy = parser(result=result, **kwargs)[0]
|
||||
|
||||
assert xyxy.shape == (0, 4)
|
||||
|
||||
@@ -1,12 +1,15 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import threading
|
||||
import warnings
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.tools.inference_slicer import InferenceSlicer
|
||||
from supervision.detection.utils.iou_and_nms import OverlapFilter
|
||||
from supervision.utils.internal import SupervisionWarnings
|
||||
|
||||
|
||||
@@ -382,3 +385,115 @@ def test_run_callback_does_not_rewarn_on_second_call() -> None:
|
||||
and "outside the slice bounds" in str(w.message)
|
||||
]
|
||||
assert len(out_of_bounds_warnings) == 1
|
||||
|
||||
|
||||
def test_obb_callbacks_run_sequentially_even_with_multiple_workers() -> None:
|
||||
"""Test that OBB callbacks are serialized even when thread_workers > 1."""
|
||||
|
||||
active_calls = 0
|
||||
max_active_calls = 0
|
||||
concurrent_callbacks = 0
|
||||
callback_lock = threading.Lock()
|
||||
|
||||
def obb_callback(_: np.ndarray) -> Detections:
|
||||
nonlocal active_calls, max_active_calls, concurrent_callbacks
|
||||
|
||||
with callback_lock:
|
||||
active_calls += 1
|
||||
max_active_calls = max(max_active_calls, active_calls)
|
||||
if active_calls > 1:
|
||||
concurrent_callbacks += 1
|
||||
|
||||
with callback_lock:
|
||||
active_calls -= 1
|
||||
|
||||
return Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=float),
|
||||
confidence=np.array([0.9]),
|
||||
class_id=np.array([0]),
|
||||
data={
|
||||
ORIENTED_BOX_COORDINATES: np.array(
|
||||
[[[0, 0], [10, 0], [10, 10], [0, 10]]], dtype=float
|
||||
)
|
||||
},
|
||||
)
|
||||
|
||||
image = np.zeros((128, 128, 3), dtype=np.uint8)
|
||||
slicer = InferenceSlicer(
|
||||
callback=obb_callback,
|
||||
slice_wh=64,
|
||||
overlap_wh=0,
|
||||
thread_workers=4,
|
||||
)
|
||||
|
||||
with pytest.warns(SupervisionWarnings, match="oriented bounding boxes"):
|
||||
detections = slicer(image)
|
||||
|
||||
assert max_active_calls == 1
|
||||
assert concurrent_callbacks == 0
|
||||
assert len(detections) == 4
|
||||
|
||||
|
||||
def _rotated_rect(
|
||||
cx: float, cy: float, w: float, h: float, angle_deg: float
|
||||
) -> np.ndarray:
|
||||
angle = np.deg2rad(angle_deg)
|
||||
cos, sin = np.cos(angle), np.sin(angle)
|
||||
rot = np.array([[cos, -sin], [sin, cos]])
|
||||
corners = np.array(
|
||||
[[-w / 2, -h / 2], [w / 2, -h / 2], [w / 2, h / 2], [-w / 2, h / 2]]
|
||||
)
|
||||
return (corners @ rot.T + [cx, cy]).astype(np.float32)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"overlap_filter",
|
||||
[OverlapFilter.NON_MAX_SUPPRESSION, OverlapFilter.NON_MAX_MERGE],
|
||||
)
|
||||
def test_inference_slicer_keeps_crossed_obb_detections(
|
||||
overlap_filter: OverlapFilter,
|
||||
) -> None:
|
||||
"""Regression for issue #1679: the SAHI workflow with OBB detections
|
||||
dropped valid detections at the merge step because `with_nms`/`with_nmm`
|
||||
historically used axis-aligned IoU. For crossed thin rectangles the AABBs
|
||||
are nearly identical (IoU ≈ 1.0) while the OBBs barely overlap (IoU ≈ 0.06)
|
||||
— so AABB-NMS suppressed one of them.
|
||||
|
||||
Both crossed OBBs must survive end-to-end through `InferenceSlicer`.
|
||||
"""
|
||||
quad_a = _rotated_rect(50, 50, 80, 8, +45)
|
||||
quad_b = _rotated_rect(50, 50, 80, 8, -45)
|
||||
aabb_a = [
|
||||
quad_a[:, 0].min(),
|
||||
quad_a[:, 1].min(),
|
||||
quad_a[:, 0].max(),
|
||||
quad_a[:, 1].max(),
|
||||
]
|
||||
aabb_b = [
|
||||
quad_b[:, 0].min(),
|
||||
quad_b[:, 1].min(),
|
||||
quad_b[:, 0].max(),
|
||||
quad_b[:, 1].max(),
|
||||
]
|
||||
|
||||
def callback(_: np.ndarray) -> Detections:
|
||||
return Detections(
|
||||
xyxy=np.array([aabb_a, aabb_b], dtype=np.float32),
|
||||
confidence=np.array([0.9, 0.85], dtype=np.float32),
|
||||
class_id=np.array([0, 0], dtype=int),
|
||||
data={ORIENTED_BOX_COORDINATES: np.stack([quad_a, quad_b])},
|
||||
)
|
||||
|
||||
image = np.zeros((100, 100, 3), dtype=np.uint8)
|
||||
slicer = InferenceSlicer(
|
||||
callback=callback,
|
||||
slice_wh=100,
|
||||
overlap_wh=0,
|
||||
thread_workers=1,
|
||||
overlap_filter=overlap_filter,
|
||||
iou_threshold=0.5,
|
||||
)
|
||||
|
||||
detections = slicer(image)
|
||||
|
||||
assert len(detections) == 2
|
||||
|
||||
@@ -0,0 +1,128 @@
|
||||
"""Tests for DetectionsSmoother bounding-box and confidence smoothing."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
from numpy.testing import assert_allclose
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.tools.smoother import DetectionsSmoother
|
||||
from supervision.utils.internal import SupervisionWarnings
|
||||
|
||||
|
||||
class TestDetectionsSmoother:
|
||||
@pytest.mark.parametrize(
|
||||
("conf1", "conf2", "expected_confidence"),
|
||||
[
|
||||
pytest.param(
|
||||
np.array([0.5]),
|
||||
np.array([0.7]),
|
||||
np.array([0.6]),
|
||||
id="with_confidence",
|
||||
),
|
||||
pytest.param(
|
||||
None,
|
||||
None,
|
||||
None,
|
||||
id="no_confidence",
|
||||
),
|
||||
pytest.param(
|
||||
np.array([0.5]),
|
||||
None,
|
||||
np.array([0.5]),
|
||||
id="mixed_window_averages_present",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_smoother_confidence_scenarios(
|
||||
self,
|
||||
conf1: np.ndarray | None,
|
||||
conf2: np.ndarray | None,
|
||||
expected_confidence: np.ndarray | None,
|
||||
) -> None:
|
||||
"""Boxes average over window; confidence averages present values or None."""
|
||||
smoother = DetectionsSmoother(length=3)
|
||||
smoother.update_with_detections(
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=conf1,
|
||||
tracker_id=np.array([1]),
|
||||
)
|
||||
)
|
||||
smoothed = smoother.update_with_detections(
|
||||
Detections(
|
||||
xyxy=np.array([[2, 2, 12, 12]], dtype=np.float32),
|
||||
confidence=conf2,
|
||||
tracker_id=np.array([1]),
|
||||
)
|
||||
)
|
||||
|
||||
assert_allclose(smoothed.xyxy, np.array([[1, 1, 11, 11]]), atol=1e-5)
|
||||
if expected_confidence is None:
|
||||
assert smoothed.confidence is None
|
||||
else:
|
||||
assert smoothed.confidence is not None
|
||||
assert_allclose(smoothed.confidence, expected_confidence, atol=1e-5)
|
||||
|
||||
def test_smoother_multi_track_mixed_confidence_does_not_crash(self) -> None:
|
||||
"""Two tracks with different confidence presence must not raise on merge."""
|
||||
smoother = DetectionsSmoother(length=3)
|
||||
smoother.update_with_detections(
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.5]),
|
||||
tracker_id=np.array([1]),
|
||||
)
|
||||
)
|
||||
smoothed = smoother.update_with_detections(
|
||||
Detections(
|
||||
xyxy=np.array([[20, 20, 30, 30]], dtype=np.float32),
|
||||
tracker_id=np.array([2]),
|
||||
)
|
||||
)
|
||||
|
||||
assert len(smoothed) == 2
|
||||
assert smoothed.confidence is None
|
||||
|
||||
def test_smoother_tracker_id_none_warns_and_returns_unchanged(self) -> None:
|
||||
"""update_with_detections warns and returns input when tracker_id is None."""
|
||||
smoother = DetectionsSmoother(length=3)
|
||||
detections = Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
tracker_id=None,
|
||||
)
|
||||
|
||||
with pytest.warns(SupervisionWarnings):
|
||||
result = smoother.update_with_detections(detections)
|
||||
|
||||
assert result is detections
|
||||
|
||||
def test_smoother_window_full_averages_all_frames(self) -> None:
|
||||
"""Full window (length=3) averages all 3 frames, not just the last two."""
|
||||
smoother = DetectionsSmoother(length=3)
|
||||
smoother.update_with_detections(
|
||||
Detections(
|
||||
xyxy=np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
confidence=np.array([0.3]),
|
||||
tracker_id=np.array([1]),
|
||||
)
|
||||
)
|
||||
smoother.update_with_detections(
|
||||
Detections(
|
||||
xyxy=np.array([[3, 3, 13, 13]], dtype=np.float32),
|
||||
confidence=np.array([0.6]),
|
||||
tracker_id=np.array([1]),
|
||||
)
|
||||
)
|
||||
smoothed = smoother.update_with_detections(
|
||||
Detections(
|
||||
xyxy=np.array([[6, 6, 16, 16]], dtype=np.float32),
|
||||
confidence=np.array([0.9]),
|
||||
tracker_id=np.array([1]),
|
||||
)
|
||||
)
|
||||
|
||||
assert_allclose(smoothed.xyxy, np.array([[3, 3, 13, 13]]), atol=1e-5)
|
||||
assert smoothed.confidence is not None
|
||||
assert_allclose(smoothed.confidence, np.array([0.6]), atol=1e-5)
|
||||
@@ -10,6 +10,7 @@ from supervision.detection.utils.boxes import (
|
||||
denormalize_boxes,
|
||||
move_boxes,
|
||||
scale_boxes,
|
||||
xyxyxyxy_to_xyxy,
|
||||
)
|
||||
|
||||
|
||||
@@ -232,3 +233,40 @@ def test_denormalize_boxes(
|
||||
normalization_factor=normalization_factor,
|
||||
)
|
||||
assert np.allclose(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("corners", "expected"),
|
||||
[
|
||||
pytest.param(
|
||||
np.array([[[0, 0], [10, 0], [10, 5], [0, 5]]], dtype=np.float32),
|
||||
np.array([[0, 0, 10, 5]], dtype=np.float32),
|
||||
id="single-axis-aligned",
|
||||
),
|
||||
pytest.param(
|
||||
np.array(
|
||||
[
|
||||
[[0, 0], [10, 0], [10, 5], [0, 5]],
|
||||
[[5, 5], [15, 5], [15, 10], [5, 10]],
|
||||
],
|
||||
dtype=np.float32,
|
||||
),
|
||||
np.array([[0, 0, 10, 5], [5, 5, 15, 10]], dtype=np.float32),
|
||||
id="batch-axis-aligned",
|
||||
),
|
||||
pytest.param(
|
||||
np.array([[[5, 0], [10, 5], [5, 10], [0, 5]]], dtype=np.float32),
|
||||
np.array([[0, 0, 10, 10]], dtype=np.float32),
|
||||
id="rotated-diamond",
|
||||
),
|
||||
pytest.param(
|
||||
np.empty((0, 4, 2), dtype=np.float32),
|
||||
np.empty((0, 4), dtype=np.float32),
|
||||
id="empty-input",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_xyxyxyxy_to_xyxy(corners: np.ndarray, expected: np.ndarray) -> None:
|
||||
"""Converts OBB corners to axis-aligned bounding boxes."""
|
||||
result = xyxyxyxy_to_xyxy(corners)
|
||||
assert np.allclose(result, expected, atol=1e-5)
|
||||
|
||||
@@ -15,6 +15,7 @@ from supervision.detection.utils.converters import (
|
||||
_rle_counts_to_mask,
|
||||
is_compressed_rle,
|
||||
mask_to_rle,
|
||||
mask_to_xyxy,
|
||||
rle_to_mask,
|
||||
xcycwh_to_xyxy,
|
||||
xywh_to_xyxy,
|
||||
@@ -315,6 +316,86 @@ def test_xyxy_to_mask(boxes: np.ndarray, resolution_wh, expected: np.ndarray) ->
|
||||
np.testing.assert_array_equal(result, expected)
|
||||
|
||||
|
||||
def _mask_to_xyxy_reference(masks: np.ndarray) -> np.ndarray:
|
||||
"""Per-mask `np.where` loop used as a ground-truth oracle."""
|
||||
xyxy = np.zeros((masks.shape[0], 4), dtype=int)
|
||||
for i, mask in enumerate(masks):
|
||||
rows, cols = np.where(mask)
|
||||
if len(rows) > 0 and len(cols) > 0:
|
||||
xyxy[i, :] = [
|
||||
int(cols.min()),
|
||||
int(rows.min()),
|
||||
int(cols.max()),
|
||||
int(rows.max()),
|
||||
]
|
||||
return xyxy
|
||||
|
||||
|
||||
class TestMaskToXyxy:
|
||||
@pytest.mark.parametrize(
|
||||
("masks", "expected"),
|
||||
[
|
||||
pytest.param(
|
||||
np.zeros((0, 5, 5), dtype=bool),
|
||||
np.zeros((0, 4), dtype=int),
|
||||
id="no-masks",
|
||||
),
|
||||
pytest.param(
|
||||
np.zeros((2, 5, 5), dtype=bool),
|
||||
np.zeros((2, 4), dtype=int),
|
||||
id="all-empty-masks",
|
||||
),
|
||||
pytest.param(
|
||||
np.array([[[False, False], [False, True]]], dtype=bool),
|
||||
np.array([[1, 1, 1, 1]], dtype=int),
|
||||
id="single-pixel-bottom-right",
|
||||
),
|
||||
pytest.param(
|
||||
np.array([[[True, False], [False, False]]], dtype=bool),
|
||||
np.array([[0, 0, 0, 0]], dtype=int),
|
||||
id="single-pixel-top-left",
|
||||
),
|
||||
pytest.param(
|
||||
np.array([[[False, True], [False, False]]], dtype=bool),
|
||||
np.array([[1, 0, 1, 0]], dtype=int),
|
||||
id="single-pixel-top-right",
|
||||
),
|
||||
pytest.param(
|
||||
np.array([[[False, False], [True, False]]], dtype=bool),
|
||||
np.array([[0, 1, 0, 1]], dtype=int),
|
||||
id="single-pixel-bottom-left",
|
||||
),
|
||||
pytest.param(
|
||||
np.ones((1, 4, 6), dtype=bool),
|
||||
np.array([[0, 0, 5, 3]], dtype=int),
|
||||
id="full-mask",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_mask_to_xyxy_known_values(
|
||||
self, masks: np.ndarray, expected: np.ndarray
|
||||
) -> None:
|
||||
"""Known boxes for empty, single-pixel, and full masks."""
|
||||
result = mask_to_xyxy(masks)
|
||||
|
||||
assert result.dtype == expected.dtype
|
||||
assert result.shape == expected.shape
|
||||
np.testing.assert_array_equal(result, expected)
|
||||
|
||||
@pytest.mark.parametrize("seed", [0, 1, 2, 3, 4])
|
||||
def test_mask_to_xyxy_matches_reference(self, seed: int) -> None:
|
||||
"""Vectorized output is bit-identical to the per-mask scalar loop."""
|
||||
rng = np.random.default_rng(seed)
|
||||
masks = rng.random((6, 30, 40)) < 0.1
|
||||
masks[0] = False # include an empty mask in the batch
|
||||
|
||||
result = mask_to_xyxy(masks)
|
||||
reference = _mask_to_xyxy_reference(masks)
|
||||
|
||||
assert result.dtype == reference.dtype
|
||||
np.testing.assert_array_equal(result, reference)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("mask", "compressed", "expected_rle", "exception"),
|
||||
[
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user