Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Piotr Skalski |
7b50eed7d9 | ||
|
Piotr Skalski
|
7c2711745b | ||
|
Piotr Skalski
|
dbade52364 | ||
|
pre-commit-ci[bot]
|
63392ab640 | ||
|
SkalskiP
|
b466076383 | ||
|
Onuralp SEZER
|
14b3c0cf8a | ||
|
Anirudh
|
092085efb1 | ||
|
Alex Norell
|
b8d62f6e29 | ||
|
Onuralp SEZER
|
6f55d9de9e | ||
|
Alex Norell
|
4b75b9bd82 | ||
|
Alex Norell
|
55378df392 | ||
|
Onuralp SEZER
|
4fd1450f80 | ||
|
Alex Norell
|
c894a7a763 | ||
|
LinasKo
|
a4a2d8c05d | ||
|
pre-commit-ci[bot]
|
30010b9773 | ||
|
Onuralp SEZER
|
fd61460cc2 | ||
|
Onuralp SEZER
|
a80be9422f | ||
|
Onuralp SEZER
|
eb3b172139 | ||
|
LinasKo
|
3c4793a092 | ||
|
LinasKo
|
b6a6746f8b | ||
|
LinasKo
|
a9831323f3 | ||
|
dependabot[bot]
|
e6f29a45a3 | ||
|
pre-commit-ci[bot]
|
06f678e5d2 | ||
|
Sachin Agarwal
|
47c98173ea | ||
|
Alex Norell
|
c9ea75e3ca | ||
|
Alex Norell
|
517b25f27f | ||
|
Alex Norell
|
40340ef8a6 | ||
|
Alex Norell
|
3d62caf4f3 | ||
|
Alex Norell
|
dab2194f47 | ||
|
Alex Norell
|
c257221fe0 | ||
|
Alex Norell
|
7c5320409c | ||
|
Alex Norell
|
10f372fe28 | ||
|
LinasKo
|
64dc2e91c8 | ||
|
LinasKo
|
9a4781f2a5 | ||
|
LinasKo
|
1633522768 | ||
|
LinasKo
|
d061a4c89b | ||
|
pre-commit-ci[bot]
|
059633435c | ||
|
LinasKo
|
001f85ad0f | ||
|
LinasKo
|
d519861b1e | ||
|
Onuralp SEZER
|
12509e756a | ||
|
LinasKo
|
fcf8b7f378 | ||
|
pre-commit-ci[bot]
|
ea3b9a5584 | ||
|
pre-commit-ci[bot]
|
f7d7786c56 | ||
|
Sachin Agarwal
|
a713d3650a | ||
|
Onuralp SEZER
|
5385ca744b | ||
|
Onuralp SEZER
|
34229c7ad7 | ||
|
LinasKo
|
4c88e03b6c | ||
|
dependabot[bot]
|
37943b2d6f | ||
|
LinasKo
|
f3d27d8381 | ||
|
LinasKo
|
c416474b63 | ||
|
LinasKo
|
ae8e6b2976 | ||
|
LinasKo
|
7141f11c0b | ||
|
Soham
|
37eadfe305 | ||
|
LinasKo
|
a4dfcacbfd | ||
|
Onuralp SEZER
|
3d1416790b | ||
|
pre-commit-ci[bot]
|
348069fb07 | ||
|
LinasKo
|
fac1581fcd | ||
|
LinasKo
|
d075eb1e47 | ||
|
Onuralp SEZER
|
eac2691c6e | ||
|
Onuralp SEZER
|
a0242b0594 | ||
|
Onuralp SEZER
|
1e2bdeee35 | ||
|
Onuralp SEZER
|
62a396fe90 | ||
|
Onuralp SEZER
|
9941417ced | ||
|
Onuralp SEZER
|
79390062ce | ||
|
dependabot[bot]
|
66e02b77b0 | ||
|
dependabot[bot]
|
816a990083 | ||
|
dependabot[bot]
|
93d0313460 | ||
|
dependabot[bot]
|
d229d2b069 | ||
|
Soham
|
28fa054fdc | ||
|
Onuralp SEZER
|
6889e33da5 | ||
|
Onuralp SEZER
|
228b4cff0c | ||
|
LinasKo
|
a5948c8992 | ||
|
LinasKo
|
853cbc428f | ||
|
LinasKo
|
d3f6570a89 | ||
|
LinasKo
|
d1c8adb33a | ||
|
Onuralp SEZER
|
5cd6844ff4 | ||
|
Onuralp SEZER
|
c0d5a7fd25 | ||
|
Onuralp SEZER
|
159c507d7f | ||
|
Onuralp SEZER
|
fdd317e53e | ||
|
Onuralp SEZER
|
370996358b | ||
|
Onuralp SEZER
|
def1cc4b33 | ||
|
Onuralp SEZER
|
5f0f90b699 | ||
|
Onuralp SEZER
|
ae9628e537 | ||
|
LinasKo
|
32eaf4eb50 | ||
|
LinasKo
|
02dac5adfe | ||
|
Erol444
|
b3d12ed652 | ||
|
Onuralp SEZER
|
7bca2fe765 | ||
|
dependabot[bot]
|
a90b8717ee | ||
|
pre-commit-ci[bot]
|
b7e02add30 | ||
|
Onuralp SEZER
|
7626c32a56 | ||
|
Onuralp SEZER
|
fe93979e0b | ||
|
pre-commit-ci[bot]
|
684522a7e8 | ||
|
LinasKo
|
bbbb37434c | ||
|
LinasKo
|
4bfee1096e | ||
|
Onuralp SEZER
|
dd0ab6a2a7 | ||
|
Onuralp SEZER
|
cdf66fd78d | ||
|
Onuralp SEZER
|
6d4b08c753 | ||
|
dependabot[bot]
|
7c57a1b8de | ||
|
dependabot[bot]
|
17e35e2bcf | ||
|
dependabot[bot]
|
69017093e1 | ||
|
Onuralp SEZER
|
e54ce38458 | ||
|
Onuralp SEZER
|
46416e430c | ||
|
dependabot[bot]
|
2ad5b60c66 | ||
|
Onuralp SEZER
|
60b9b716e9 | ||
|
Onuralp SEZER
|
4b64d4ddca | ||
|
dependabot[bot]
|
9ded219dfb | ||
|
dependabot[bot]
|
987a8f269f | ||
|
Onuralp SEZER
|
a57f4f22ae | ||
|
Onuralp SEZER
|
88f113d14b | ||
|
pre-commit-ci[bot]
|
8d18328dff | ||
|
Onuralp SEZER
|
7ea4b2ac13 | ||
|
LinasKo
|
284901c06b | ||
|
pre-commit-ci[bot]
|
b2dc1b2a17 | ||
|
LinasKo
|
d9e3ee9465 | ||
|
LinasKo
|
37b5dd477b | ||
|
LinasKo
|
092809b2be | ||
|
Onuralp SEZER
|
742a824d2c | ||
|
Onuralp SEZER
|
c88de3641c | ||
|
Onuralp SEZER
|
aec0bc3529 | ||
|
Onuralp SEZER
|
89769e49f7 | ||
|
LinasKo
|
86f95f914a | ||
|
LinasKo
|
eaeb51a8db | ||
|
LinasKo
|
8d562c16a6 | ||
|
LinasKo
|
dd4ffc6d97 | ||
|
LinasKo
|
2d50beeaa9 | ||
|
LinasKo
|
7b3d88602b | ||
|
LinasKo
|
90168644de | ||
|
LinasKo
|
aae3c69ee3 | ||
|
LinasKo
|
3bb22abe0f | ||
|
Onuralp SEZER
|
d99565dcd1 | ||
|
LinasKo
|
3692fb65f9 | ||
|
pre-commit-ci[bot]
|
1af9c7d629 | ||
|
LinasKo
|
1d9f0b1994 | ||
|
Onuralp SEZER
|
77c71dacac | ||
|
Onuralp SEZER
|
cfb462ca0b | ||
|
LinasKo
|
c12c562e29 | ||
|
LinasKo
|
10652efbc4 | ||
|
LinasKo
|
3532130b2d | ||
|
LinasKo
|
79b45a4ea8 | ||
|
dependabot[bot]
|
cc8be562b0 | ||
|
dependabot[bot]
|
a1d8c69654 | ||
|
LinasKo
|
4326b87191 | ||
|
LinasKo
|
38dbf5d05d | ||
|
LinasKo
|
5e76f86ff9 | ||
|
LinasKo
|
01c2912a64 | ||
|
LinasKo
|
5fedfe5220 | ||
|
LinasKo
|
c43ca06609 | ||
|
LinasKo
|
b72ad4656b | ||
|
Onuralp SEZER
|
fdb036ecd5 | ||
|
LinasKo
|
e4cf743c1c | ||
|
LinasKo
|
19677bede5 | ||
|
LinasKo
|
a6e1f037d7 | ||
|
LinasKo
|
0bfcdeab6f | ||
|
LinasKo
|
83d4386fa2 | ||
|
LinasKo
|
42bb4c2865 | ||
|
LinasKo
|
4ed05e76fd | ||
|
LinasKo
|
2084f57d76 | ||
|
LinasKo
|
1b101b49ac | ||
|
LinasKo
|
abcb055815 | ||
|
LinasKo
|
c3d7dc0ee3 | ||
|
LinasKo
|
c6c447c527 | ||
|
LinasKo
|
b66702c5ff | ||
|
pre-commit-ci[bot]
|
920a2c0cda | ||
|
LinasKo
|
6728527f36 | ||
|
Onuralp SEZER
|
b9b802e9ea | ||
|
dependabot[bot]
|
11978410f0 | ||
|
KshitijAucharmal
|
ecf5b1334f | ||
|
KshitijAucharmal
|
a2e2e3725a | ||
|
KshitijAucharmal
|
ba559c2658 |
@@ -0,0 +1,4 @@
|
||||
# These owners will be the default owners for everything in
|
||||
# the repo. They will be requested for review when someone
|
||||
# opens a pull request.
|
||||
* @SkalskiP @onuralpszr
|
||||
@@ -4,13 +4,15 @@ updates:
|
||||
- package-ecosystem: "github-actions"
|
||||
directory: "/"
|
||||
schedule:
|
||||
interval: "daily"
|
||||
interval: "weekly"
|
||||
commit-message:
|
||||
prefix: ⬆️
|
||||
target-branch: "develop"
|
||||
# Python
|
||||
- package-ecosystem: "pip"
|
||||
directory: "/"
|
||||
schedule:
|
||||
interval: "daily"
|
||||
interval: "weekly"
|
||||
commit-message:
|
||||
prefix: ⬆️
|
||||
target-branch: "develop"
|
||||
|
||||
@@ -1,33 +1,42 @@
|
||||
|
||||
name: Clear cache
|
||||
|
||||
on:
|
||||
schedule:
|
||||
- cron: '0 0 1 * *'
|
||||
workflow_dispatch:
|
||||
schedule:
|
||||
- cron: "0 0 1 * *" # Run at midnight on the first day of every month
|
||||
workflow_dispatch:
|
||||
|
||||
# Restrict permissions by default
|
||||
permissions:
|
||||
actions: write
|
||||
actions: write # Required for cache management
|
||||
|
||||
jobs:
|
||||
clear-cache:
|
||||
name: Clear cache
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
steps:
|
||||
- name: Clear cache
|
||||
uses: actions/github-script@v7
|
||||
uses: actions/github-script@60a0d83039c74a4aee543508d2ffcb1c3799cdea # v7.0.1
|
||||
with:
|
||||
script: |
|
||||
console.log("About to clear")
|
||||
console.log("Starting cache cleanup...")
|
||||
const caches = await github.rest.actions.getActionsCacheList({
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
})
|
||||
|
||||
let deletedCount = 0
|
||||
for (const cache of caches.data.actions_caches) {
|
||||
console.log(cache)
|
||||
github.rest.actions.deleteActionsCacheById({
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
cache_id: cache.id,
|
||||
})
|
||||
console.log(`Deleting cache: ${cache.key} (${cache.size_in_bytes} bytes)`)
|
||||
try {
|
||||
await github.rest.actions.deleteActionsCacheById({
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
cache_id: cache.id,
|
||||
})
|
||||
deletedCount++
|
||||
} catch (error) {
|
||||
console.error(`Failed to delete cache ${cache.key}: ${error.message}`)
|
||||
}
|
||||
}
|
||||
console.log("Clear completed")
|
||||
console.log(`Cache cleanup completed. Deleted ${deletedCount} caches.`)
|
||||
|
||||
@@ -0,0 +1,22 @@
|
||||
name: Combine Dependabot PRs
|
||||
|
||||
on:
|
||||
schedule:
|
||||
- cron: "0 1 * * 3" # Wednesday at 01:00
|
||||
workflow_dispatch: # allows you to manually trigger the workflow
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pull-requests: write
|
||||
checks: read
|
||||
|
||||
jobs:
|
||||
combine-prs:
|
||||
name: Combine
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: combine-prs
|
||||
id: combine-prs
|
||||
uses: github/combine-prs@2909f404763c3177a456e052bdb7f2e85d3a7cb3 # v5.2.0
|
||||
with:
|
||||
labels: combined-pr
|
||||
@@ -1,64 +0,0 @@
|
||||
name: Notebook Check Pull Request
|
||||
|
||||
on:
|
||||
pull_request_target:
|
||||
types: [opened, reopened]
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
comment-welcome:
|
||||
permissions:
|
||||
contents: read
|
||||
pull-requests: write
|
||||
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Fetch pull request branch
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
repository: ${{ github.event.pull_request.head.repo.full_name }}
|
||||
ref: ${{ github.event.pull_request.head.sha }}
|
||||
- name: Fetch base develop branch
|
||||
run: git fetch -u "$GITHUB_SERVER_URL/$GITHUB_REPOSITORY" develop:develop
|
||||
- name: Create message
|
||||
env:
|
||||
HEAD_REPOSITORY: ${{ github.event.pull_request.head.repo.full_name }}
|
||||
HEAD_REF: ${{ github.event.pull_request.head.ref }}
|
||||
PR_NUM: ${{ github.event.pull_request.number }}
|
||||
run: |
|
||||
# Preview links and tool usage only needed for notebook changes.
|
||||
readarray -t changed_notebooks < <(git diff --name-only develop | grep '\.ipynb$' || true)
|
||||
if [[ ${#changed_notebooks[@]} == 0 ]]; then
|
||||
echo "No notebooks modified in this pull request."
|
||||
else
|
||||
msg="<h4>Preview</h4>\n"
|
||||
msg+="Preview and run these notebook edits with Google Colab:\n<ul>\n"
|
||||
# Link to PR branch in user's fork that is always current.
|
||||
for fp in "${changed_notebooks[@]}"; do
|
||||
gh_path="${HEAD_REPOSITORY}/blob/${HEAD_REF}/${fp}"
|
||||
colab_url="https://colab.research.google.com/github/${gh_path}"
|
||||
msg+="<li><a href='${colab_url}'>${fp}</a></li>\n"
|
||||
done
|
||||
msg+="</ul>\n"
|
||||
|
||||
reviewnb_url="https://app.reviewnb.com/${GITHUB_REPOSITORY}/pull/${PR_NUM}/files/"
|
||||
msg+="Rendered <a href='${reviewnb_url}'>notebook diffs</a> available on ReviewNB.com.\n"
|
||||
|
||||
msg+="If commits are added to the pull request, synchronize your local branch: <code>git pull origin $HEAD_REF</code>\n"
|
||||
fi
|
||||
echo "MESSAGE=$msg" >> $GITHUB_ENV
|
||||
- name: Post comment
|
||||
env:
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
ISSUE_URL: ${{ github.event.pull_request.issue_url }}
|
||||
run: |
|
||||
# Env var defined in previous step. Escape string for JSON.
|
||||
body="$(echo -n -e $MESSAGE | python3 -c 'import json,sys; print(json.dumps(sys.stdin.read()))')"
|
||||
# Add comment to pull request.
|
||||
curl -X POST \
|
||||
-H "Accept: application/vnd.github.v3+json" \
|
||||
-H "Authorization: token $GITHUB_TOKEN" \
|
||||
"${ISSUE_URL}/comments" \
|
||||
--data "{\"body\": $body}"
|
||||
@@ -2,16 +2,18 @@ name: 🔧 Poetry Check and Installation Test Workflow
|
||||
on:
|
||||
push:
|
||||
paths:
|
||||
- 'poetry.lock'
|
||||
- 'pyproject.toml'
|
||||
- "poetry.lock"
|
||||
- "pyproject.toml"
|
||||
pull_request:
|
||||
paths:
|
||||
- 'poetry.lock'
|
||||
- 'pyproject.toml'
|
||||
- "poetry.lock"
|
||||
- "pyproject.toml"
|
||||
workflow_dispatch:
|
||||
|
||||
jobs:
|
||||
poetry-tests:
|
||||
name: Poetry install and check
|
||||
timeout-minutes: 10
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
@@ -20,18 +22,21 @@ jobs:
|
||||
runs-on: ${{ matrix.os }}
|
||||
steps:
|
||||
- name: 📥 Checkout the repository
|
||||
uses: actions/checkout@v4
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v5
|
||||
uses: actions/setup-python@0b93645e9fea7318ecaed2b359559ac225c90a2b # v5.3.0
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
|
||||
- name: 📦 Install the base dependencies
|
||||
run: python -m pip install --upgrade poetry
|
||||
- name: 📜 Setup Poetry
|
||||
uses: abatilo/actions-poetry@e78f54a89cb052fff327414dd9ff010b5d2b4dbd # v3.0.1
|
||||
|
||||
- name: 🔍 Check the correctness of the project config
|
||||
run: poetry check
|
||||
|
||||
- name: 🚀 Do Install the package Test
|
||||
run: poetry install
|
||||
run: poetry install --with dev --extras metrics
|
||||
|
||||
- name: 🧪 Run the Import test
|
||||
run: poetry run python -c "import supervision; from supervision import assets; from supervision import metrics; print(supervision.__version__)"
|
||||
|
||||
@@ -1,53 +0,0 @@
|
||||
name: Docs WorkFlow - Develop Tag 📚
|
||||
|
||||
on:
|
||||
push:
|
||||
branches:
|
||||
- develop
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event_name == 'push' && github.ref}}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
pull-requests: write
|
||||
|
||||
|
||||
jobs:
|
||||
deploy:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: 🔄 Checkout code
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
fetch-depth: 0
|
||||
- name: 🐍 Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
run: pip install "mkdocs-material[imaging]"
|
||||
- name: 📦 Install mike
|
||||
run: pip install "mike"
|
||||
- name: 📦 Install mkdocs-git-revision-date-localized-plugin
|
||||
run: pip install "mkdocs-git-revision-date-localized-plugin"
|
||||
- name: 📦 Install JupyterLab
|
||||
run: pip install jupyterlab
|
||||
- name: 📦 Install mkdocs-jupyter
|
||||
run: pip install mkdocs-jupyter
|
||||
- name: 📦 Install mkdocs-git-committers-plugin-2
|
||||
run: pip install mkdocs-git-committers-plugin-2
|
||||
- name: ⚙️ Configure git for github-actions
|
||||
run: |
|
||||
git config --global user.name "github-actions[bot]"
|
||||
git config --global user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
- name: 🚀 Deploy MkDoc-Material with mike
|
||||
run: |
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY=${{ secrets.GITHUB_TOKEN }} mike deploy --push develop
|
||||
@@ -0,0 +1,62 @@
|
||||
name: Build and Publish Docs
|
||||
|
||||
on:
|
||||
push:
|
||||
branches:
|
||||
- develop
|
||||
workflow_dispatch:
|
||||
release:
|
||||
types: [published]
|
||||
|
||||
# Ensure only one concurrent deployment
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event_name == 'push' && github.ref}}
|
||||
cancel-in-progress: true
|
||||
|
||||
# Restrict permissions by default
|
||||
permissions:
|
||||
contents: write # Required for committing to gh-pages
|
||||
pages: write # Required for deploying to Pages
|
||||
pull-requests: write # Required for PR comments
|
||||
|
||||
jobs:
|
||||
deploy:
|
||||
name: Publish Docs
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 📥 Checkout the repository
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
with:
|
||||
fetch-depth: 0
|
||||
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@0b93645e9fea7318ecaed2b359559ac225c90a2b # v5.3.0
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
|
||||
- name: 📜 Setup Poetry
|
||||
uses: abatilo/actions-poetry@e78f54a89cb052fff327414dd9ff010b5d2b4dbd # v3.0.1
|
||||
|
||||
- name: 📦 Install dependencies
|
||||
run: |
|
||||
poetry install --with=docs
|
||||
|
||||
- name: ⚙️ Configure git for github-actions
|
||||
run: |
|
||||
git config --global user.name "github-actions[bot]"
|
||||
git config --global user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
|
||||
- name: 🚀 Deploy Development Docs
|
||||
if: (github.event_name == 'push' && github.ref == 'refs/heads/develop') || github.event_name == 'workflow_dispatch'
|
||||
run: |
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY=${{ secrets.GITHUB_TOKEN }} poetry run mike deploy --push develop
|
||||
|
||||
- name: 🚀 Deploy Release Docs
|
||||
if: github.event_name == 'release' && github.event.action == 'published'
|
||||
run: |
|
||||
latest_tag=$(git describe --tags `git rev-list --tags --max-count=1`)
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY=${{ secrets.GITHUB_TOKEN }} poetry run mike deploy --push --update-aliases $latest_tag latest
|
||||
@@ -1,55 +0,0 @@
|
||||
name: Supervision Release Documentation Workflow 📚
|
||||
on:
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event_name == 'push' && github.ref}}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
pull-requests: write
|
||||
|
||||
|
||||
jobs:
|
||||
doc-build-deploy:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
fetch-depth: 0
|
||||
ref: ${{ github.head_ref }}
|
||||
|
||||
- name: 🐍 Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
run: pip install "mkdocs-material[imaging]"
|
||||
- name: 📦 Install mike
|
||||
run: pip install "mike"
|
||||
- name: 📦 Install mkdocs-git-revision-date-localized-plugin
|
||||
run: pip install "mkdocs-git-revision-date-localized-plugin"
|
||||
- name: 📦 Install JupyterLab
|
||||
run: pip install jupyterlab
|
||||
- name: 📦 Install mkdocs-jupyter
|
||||
run: pip install mkdocs-jupyter
|
||||
- name: 📦 Install mkdocs-git-committers-plugin-2
|
||||
run: pip install mkdocs-git-committers-plugin-2
|
||||
- name: ⚙️ Configure git for github-actions 👷
|
||||
run: |
|
||||
git config --global user.name "github-actions[bot]"
|
||||
git config --global user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
- name: 🚀 Deploy MkDoc-Material 📚
|
||||
run: |
|
||||
latest_tag=$(git describe --tags `git rev-list --tags --max-count=1`)
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY=${{ secrets.GITHUB_TOKEN }} mike deploy --push --update-aliases $latest_tag latest
|
||||
@@ -1,43 +1,52 @@
|
||||
name: Publish Supervision Pre-Releases to PyPI and TestPyPI
|
||||
|
||||
on:
|
||||
push:
|
||||
tags:
|
||||
- "[0-9]+.[0-9]+[0-9]+.[0-9]+a[0-9]"
|
||||
- "[0-9]+.[0-9]+[0-9]+.[0-9]+b[0-9]"
|
||||
- "[0-9]+.[0-9]+[0-9]+.[0-9]+rc[0-9]"
|
||||
|
||||
workflow_dispatch:
|
||||
|
||||
permissions: {} # Explicitly remove all permissions by default
|
||||
|
||||
jobs:
|
||||
build-and-publish-pre-release-pypi:
|
||||
name: Build and publish to PyPI
|
||||
build-and-publish-pre-release:
|
||||
name: Publish Pre-releasePackage
|
||||
runs-on: ubuntu-latest
|
||||
environment: test
|
||||
environment: release
|
||||
timeout-minutes: 10
|
||||
permissions:
|
||||
id-token: write
|
||||
id-token: write # Required for PyPI publishing
|
||||
contents: read # Required for checkout
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
ref: ${{ github.head_ref }}
|
||||
- name: 📥 Checkout the repository
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v5
|
||||
uses: actions/setup-python@0b93645e9fea7318ecaed2b359559ac225c90a2b # v5.3.0
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
|
||||
- name: 📜 Setup Poetry
|
||||
uses: abatilo/actions-poetry@e78f54a89cb052fff327414dd9ff010b5d2b4dbd # v3.0.1
|
||||
|
||||
- name: 🏗️ Build source and wheel distributions
|
||||
run: |
|
||||
python -m pip install --upgrade build twine
|
||||
python -m build
|
||||
poetry install --with=build
|
||||
poetry build
|
||||
twine check --strict dist/*
|
||||
|
||||
- name: 🚀 Publish to PyPi
|
||||
uses: pypa/gh-action-pypi-publish@release/v1.10
|
||||
uses: pypa/gh-action-pypi-publish@67339c736fd9354cd4f8cb0b744f2b82a74b5c70 # v1.12.3
|
||||
with:
|
||||
attestations: true
|
||||
|
||||
- name: 🚀 Publish to Test-PyPi
|
||||
uses: pypa/gh-action-pypi-publish@release/v1.10
|
||||
uses: pypa/gh-action-pypi-publish@67339c736fd9354cd4f8cb0b744f2b82a74b5c70 # v1.12.3
|
||||
with:
|
||||
repository-url: https://test.pypi.org/legacy/
|
||||
attestations: true
|
||||
|
||||
@@ -1,40 +1,50 @@
|
||||
name: Publish Supervision Releases to PyPI and TestPyPI
|
||||
|
||||
on:
|
||||
push:
|
||||
tags:
|
||||
- "[0-9]+.[0-9]+[0-9]+.[0-9]"
|
||||
|
||||
workflow_dispatch:
|
||||
|
||||
permissions: {} # Explicitly remove all permissions by default
|
||||
|
||||
jobs:
|
||||
build-and-publish-pre-release:
|
||||
name: Publish Release Package
|
||||
runs-on: ubuntu-latest
|
||||
environment: release
|
||||
timeout-minutes: 10
|
||||
permissions:
|
||||
id-token: write
|
||||
id-token: write # Required for PyPI publishing
|
||||
contents: read # Required for checkout
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
ref: ${{ github.head_ref }}
|
||||
- name: 📥 Checkout the repository
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v5
|
||||
uses: actions/setup-python@0b93645e9fea7318ecaed2b359559ac225c90a2b # v5.3.0
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
|
||||
- name: 📜 Setup Poetry
|
||||
uses: abatilo/actions-poetry@e78f54a89cb052fff327414dd9ff010b5d2b4dbd # v3.0.1
|
||||
|
||||
- name: 🏗️ Build source and wheel distributions
|
||||
run: |
|
||||
python -m pip install --upgrade build twine
|
||||
python -m build
|
||||
poetry install --with=build
|
||||
poetry build
|
||||
twine check --strict dist/*
|
||||
|
||||
- name: 🚀 Publish to PyPi
|
||||
uses: pypa/gh-action-pypi-publish@release/v1.10
|
||||
uses: pypa/gh-action-pypi-publish@67339c736fd9354cd4f8cb0b744f2b82a74b5c70 # v1.12.3
|
||||
with:
|
||||
attestations: true
|
||||
|
||||
- name: 🚀 Publish to Test-PyPi
|
||||
uses: pypa/gh-action-pypi-publish@release/v1.10
|
||||
uses: pypa/gh-action-pypi-publish@67339c736fd9354cd4f8cb0b744f2b82a74b5c70 # v1.12.3
|
||||
with:
|
||||
repository-url: https://test.pypi.org/legacy/
|
||||
attestations: true
|
||||
|
||||
@@ -4,18 +4,37 @@ on:
|
||||
pull_request:
|
||||
branches: [main, develop]
|
||||
|
||||
# Restrict permissions by default
|
||||
permissions:
|
||||
contents: read # Required for checkout
|
||||
checks: write # Required for test reporting
|
||||
|
||||
jobs:
|
||||
docs-build-test:
|
||||
name: Test docs build
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🔄 Checkout code
|
||||
uses: actions/checkout@v4
|
||||
- name: 🐍 Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
- name: 📥 Checkout the repository
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 🏗️ Install dependencies and Test Docs Build
|
||||
fetch-depth: 0
|
||||
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@0b93645e9fea7318ecaed2b359559ac225c90a2b # v5.3.0
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
|
||||
- name: 📜 Setup Poetry
|
||||
uses: abatilo/actions-poetry@e78f54a89cb052fff327414dd9ff010b5d2b4dbd # v3.0.1
|
||||
|
||||
- name: 🏗️ Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install "mkdocs-material" "mkdocstrings[python]" "mkdocs-material[imaging]" mike "mkdocs-git-revision-date-localized-plugin" jupyterlab mkdocs-jupyter mkdocs-git-committers-plugin-2
|
||||
mkdocs build --verbose
|
||||
poetry install --with=docs
|
||||
|
||||
- name: 🧪 Test Docs Build
|
||||
run: |
|
||||
poetry run mkdocs build --verbose
|
||||
|
||||
@@ -1,58 +0,0 @@
|
||||
name: Python 3.8 - Min Dep Test WorkFlow
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [main, develop]
|
||||
|
||||
jobs:
|
||||
build-min-dep-test:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.8"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v5
|
||||
# id based on python version
|
||||
id: python-setup
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
check-latest: true
|
||||
|
||||
- name: 📦 Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install \
|
||||
attrs==23.1.0 \
|
||||
certifi==2023.7.22 \
|
||||
charset-normalizer==2.0.12 \
|
||||
cycler==0.12.1 \
|
||||
exceptiongroup==1.1.3 \
|
||||
fonttools==4.43.1 \
|
||||
idna==3.4 \
|
||||
iniconfig==2.0.0 \
|
||||
kiwisolver==1.4.5 \
|
||||
matplotlib==3.5.0 \
|
||||
numpy==1.21.2 \
|
||||
opencv-python==4.5.5.64 \
|
||||
Pillow==10.1.0 \
|
||||
packaging==23.2 \
|
||||
pluggy==1.3.0 \
|
||||
pyparsing==3.1.1 \
|
||||
pytest==7.2.0 \
|
||||
python-dateutil==2.8.2 \
|
||||
PyYAML==5.3 \
|
||||
requests==2.26.0 \
|
||||
scipy==1.10.0 \
|
||||
setuptools-scm==8.0.4 \
|
||||
six==1.16.0 \
|
||||
tomli==2.0.1 \
|
||||
tqdm==4.62.3 \
|
||||
typing_extensions==4.8.0 \
|
||||
urllib3==1.26.18 \
|
||||
defusedxml==0.7.1
|
||||
|
||||
- name: 🧪 Test
|
||||
run: "python -m pytest ./test"
|
||||
+29
-11
@@ -4,26 +4,44 @@ on:
|
||||
pull_request:
|
||||
branches: [main, develop]
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
checks: write # Required for test reporting
|
||||
pull-requests: write # Required for PR comments
|
||||
|
||||
jobs:
|
||||
build-dev-test:
|
||||
runs-on: ubuntu-latest
|
||||
pytest:
|
||||
name: PyTest
|
||||
timeout-minutes: 10
|
||||
strategy:
|
||||
matrix:
|
||||
os: [ubuntu-latest, windows-latest, macos-latest]
|
||||
python-version: ["3.8", "3.9", "3.10", "3.11", "3.12", "3.13"]
|
||||
fail-fast: false # Continue with other versions if one fails
|
||||
runs-on: ${{ matrix.os }}
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
- name: 📥 Checkout the repository
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v5
|
||||
uses: actions/setup-python@0b93645e9fea7318ecaed2b359559ac225c90a2b # v5.3.0
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
check-latest: true
|
||||
|
||||
- name: 📜 Setup Poetry
|
||||
uses: abatilo/actions-poetry@e78f54a89cb052fff327414dd9ff010b5d2b4dbd # v3.0.1
|
||||
|
||||
- name: 📦 Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install .
|
||||
pip install pytest
|
||||
poetry install --with=test
|
||||
|
||||
- name: 🧪 Test
|
||||
run: "python -m pytest ./test"
|
||||
- name: Run pytest
|
||||
uses: pavelzw/pytest-action@510c5e90c360a185039bea56ce8b3e7e51a16507 # v2.2.0
|
||||
with:
|
||||
verbose: true
|
||||
emoji: true
|
||||
job-summary: true
|
||||
custom-arguments: "-q"
|
||||
click-to-expand: true
|
||||
report-title: "Test Report"
|
||||
custom-pytest: "poetry run pytest"
|
||||
|
||||
@@ -25,14 +25,14 @@ repos:
|
||||
- id: mixed-line-ending
|
||||
|
||||
- repo: https://github.com/PyCQA/bandit
|
||||
rev: '1.7.10'
|
||||
rev: '1.8.0'
|
||||
hooks:
|
||||
- id: bandit
|
||||
args: ["-c", "pyproject.toml"]
|
||||
additional_dependencies: ["bandit[toml]"]
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.7.2
|
||||
rev: v0.8.2
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
|
||||
+14
-3
@@ -128,15 +128,26 @@ PRs must pass all tests and linting requirements before they can be merged.
|
||||
|
||||
Before starting your work on the project, set up your development environment:
|
||||
|
||||
1. Clone your fork of the project:
|
||||
1. Clone your fork of the project (recommended to use shallow clone of develop branch):
|
||||
|
||||
**Option A: Recommended for most contributors (shallow clone of develop branch):**
|
||||
|
||||
```bash
|
||||
git clone --depth 1 -b develop https://github.com/YOUR_USERNAME/supervision.git
|
||||
cd supervision
|
||||
```
|
||||
|
||||
Replace `YOUR_USERNAME` with your GitHub username.
|
||||
|
||||
> Note: Using `--depth 1` creates a shallow clone with minimal history and `-b develop` ensures you start with the development branch. This significantly reduces download size while providing everything needed to contribute.
|
||||
|
||||
**Option B: Full repository clone (if you need complete history):**
|
||||
|
||||
```bash
|
||||
git clone https://github.com/YOUR_USERNAME/supervision.git
|
||||
cd supervision
|
||||
```
|
||||
|
||||
Replace `YOUR_USERNAME` with your GitHub username.
|
||||
|
||||
2. Create and activate a virtual environment:
|
||||
|
||||
```bash
|
||||
|
||||
@@ -21,7 +21,7 @@
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://huggingface.co/spaces/Roboflow/Annotators)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
[](https://squidfunk.github.io/mkdocs-material/)
|
||||
|
||||
<div align="center">
|
||||
@@ -135,88 +135,88 @@ for path, image, annotation in ds:
|
||||
|
||||
- load
|
||||
|
||||
```python
|
||||
dataset = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
)
|
||||
```python
|
||||
dataset = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
)
|
||||
|
||||
dataset = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
dataset = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
|
||||
dataset = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=...,
|
||||
annotations_path=...
|
||||
)
|
||||
```
|
||||
dataset = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=...,
|
||||
annotations_path=...
|
||||
)
|
||||
```
|
||||
|
||||
- split
|
||||
|
||||
```python
|
||||
train_dataset, test_dataset = dataset.split(split_ratio=0.7)
|
||||
test_dataset, valid_dataset = test_dataset.split(split_ratio=0.5)
|
||||
```python
|
||||
train_dataset, test_dataset = dataset.split(split_ratio=0.7)
|
||||
test_dataset, valid_dataset = test_dataset.split(split_ratio=0.5)
|
||||
|
||||
len(train_dataset), len(test_dataset), len(valid_dataset)
|
||||
# (700, 150, 150)
|
||||
```
|
||||
len(train_dataset), len(test_dataset), len(valid_dataset)
|
||||
# (700, 150, 150)
|
||||
```
|
||||
|
||||
- merge
|
||||
|
||||
```python
|
||||
ds_1 = sv.DetectionDataset(...)
|
||||
len(ds_1)
|
||||
# 100
|
||||
ds_1.classes
|
||||
# ['dog', 'person']
|
||||
```python
|
||||
ds_1 = sv.DetectionDataset(...)
|
||||
len(ds_1)
|
||||
# 100
|
||||
ds_1.classes
|
||||
# ['dog', 'person']
|
||||
|
||||
ds_2 = sv.DetectionDataset(...)
|
||||
len(ds_2)
|
||||
# 200
|
||||
ds_2.classes
|
||||
# ['cat']
|
||||
ds_2 = sv.DetectionDataset(...)
|
||||
len(ds_2)
|
||||
# 200
|
||||
ds_2.classes
|
||||
# ['cat']
|
||||
|
||||
ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
len(ds_merged)
|
||||
# 300
|
||||
ds_merged.classes
|
||||
# ['cat', 'dog', 'person']
|
||||
```
|
||||
ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
len(ds_merged)
|
||||
# 300
|
||||
ds_merged.classes
|
||||
# ['cat', 'dog', 'person']
|
||||
```
|
||||
|
||||
- save
|
||||
|
||||
```python
|
||||
dataset.as_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
)
|
||||
```python
|
||||
dataset.as_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
)
|
||||
|
||||
dataset.as_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
dataset.as_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
|
||||
dataset.as_coco(
|
||||
images_directory_path=...,
|
||||
annotations_path=...
|
||||
)
|
||||
```
|
||||
dataset.as_coco(
|
||||
images_directory_path=...,
|
||||
annotations_path=...
|
||||
)
|
||||
```
|
||||
|
||||
- convert
|
||||
|
||||
```python
|
||||
sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
).as_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
```
|
||||
```python
|
||||
sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
).as_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
Vendored
+1
-1
@@ -353,7 +353,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q ultralytics"
|
||||
"!pip install -q \"ultralytics<=8.3.40\""
|
||||
]
|
||||
},
|
||||
{
|
||||
|
||||
@@ -7,16 +7,6 @@ comments: true
|
||||
Supervision offers an assets download utility that allows you to download video files
|
||||
that you can use in your demos.
|
||||
|
||||
## Install extra
|
||||
|
||||
To install the Supervision assets utility, you can use `pip`. This utility is available
|
||||
as an extra within the Supervision package.
|
||||
|
||||
!!! example "pip install"
|
||||
```bash
|
||||
pip install "supervision[assets]"
|
||||
```
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.download_assets">download_assets</a></h2>
|
||||
</div>
|
||||
|
||||
@@ -1,5 +1,149 @@
|
||||
# CHANGELOG
|
||||
|
||||
### 0.25.0 <small>Nov 12, 2024</small>
|
||||
|
||||
- No removals or deprecations in this release!
|
||||
|
||||
- Essential update to the [`LineZone`](https://supervision.roboflow.com/0.25.0/detection/tools/line_zone/): when computing line crossings, detections that jitter might be counted twice (or more). This can now be solved with the `minimum_crossing_threshold` argument. If you set it to `2` or more, extra frames will be used to confirm the crossing, improving the accuracy significantly. ([#1540](https://github.com/roboflow/supervision/pull/1540))
|
||||
|
||||
- It is now possible to track objects detected as [`KeyPoints`](https://supervision.roboflow.com/0.25.0/keypoint/core/#supervision.keypoint.core.KeyPoints). See the complete step-by-step guide in the [Object Tracking Guide](https://supervision.roboflow.com/latest/how_to/track_objects/#keypoints). ([#1658](https://github.com/roboflow/supervision/pull/1658))
|
||||
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8m-pose.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
key_points = sv.KeyPoints.from_ultralytics(results)
|
||||
|
||||
detections = key_points.as_detections()
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_image = trace_annotator.annotate(frame.copy(), detections)
|
||||
return annotated_image
|
||||
|
||||
sv.process_video(
|
||||
source_path="input_video.mp4",
|
||||
target_path="output_video.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
- Added `is_empty` method to [`KeyPoints`](https://supervision.roboflow.com/0.25.0/keypoint/core/#supervision.keypoint.core.KeyPoints) to check if there are any keypoints in the object. ([#1658](https://github.com/roboflow/supervision/pull/1658))
|
||||
|
||||
- Added `as_detections` method to [`KeyPoints`](https://supervision.roboflow.com/0.25.0/keypoint/core/#supervision.keypoint.core.KeyPoints) that converts `KeyPoints` to `Detections`. ([#1658](https://github.com/roboflow/supervision/pull/1658))
|
||||
|
||||
- Added a new video to `supervision[assets]`. ([#1657](https://github.com/roboflow/supervision/pull/1657))
|
||||
|
||||
```python
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
|
||||
path_to_video = download_assets(VideoAssets.SKIING)
|
||||
```
|
||||
|
||||
- Supervision can now be used with [`Python 3.13`](https://docs.python.org/3/whatsnew/3.13.html). The most renowned update is the ability to run Python [without Global Interpreter Lock (GIL)](https://docs.python.org/3/whatsnew/3.13.html#whatsnew313-free-threaded-cpython). We expect support for this among our dependencies to be inconsistent, but if you do attempt it - let us know the results! ([#1595](https://github.com/roboflow/supervision/pull/1595))
|
||||
|
||||
- Added [`Mean Average Recall`](https://supervision.roboflow.com/latest/metrics/mean_average_recall/) mAR metric, which returns a recall score, averaged over IoU thresholds, detected object classes, and limits imposed on maximum considered detections. ([#1661](https://github.com/roboflow/supervision/pull/1661))
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from supervision.metrics import MeanAverageRecall
|
||||
|
||||
predictions = sv.Detections(...)
|
||||
targets = sv.Detections(...)
|
||||
|
||||
map_metric = MeanAverageRecall()
|
||||
map_result = map_metric.update(predictions, targets).compute()
|
||||
|
||||
map_result.plot()
|
||||
```
|
||||
|
||||
- Added [`Precision`](https://supervision.roboflow.com/latest/metrics/precision/) and [`Recall`](https://supervision.roboflow.com/latest/metrics/recall/) metrics, providing a baseline for comparing model outputs to ground truth or another model ([#1609](https://github.com/roboflow/supervision/pull/1609))
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from supervision.metrics import Recall
|
||||
|
||||
predictions = sv.Detections(...)
|
||||
targets = sv.Detections(...)
|
||||
|
||||
recall_metric = Recall()
|
||||
recall_result = recall_metric.update(predictions, targets).compute()
|
||||
|
||||
recall_result.plot()
|
||||
```
|
||||
|
||||
- All Metrics now support Oriented Bounding Boxes (OBB) ([#1593](https://github.com/roboflow/supervision/pull/1593))
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from supervision.metrics import F1_Score
|
||||
|
||||
predictions = sv.Detections(...)
|
||||
targets = sv.Detections(...)
|
||||
|
||||
f1_metric = MeanAverageRecall(metric_target=sv.MetricTarget.ORIENTED_BOUNDING_BOXES)
|
||||
f1_result = f1_metric.update(predictions, targets).compute()
|
||||
```
|
||||
|
||||
- Introducing Smart Labels! When `smart_position` is set for [`LabelAnnotator`](https://supervision.roboflow.com/0.25.0/detection/annotators/#supervision.annotators.core.LabelAnnotator), [`RichLabelAnnotator`](https://supervision.roboflow.com/0.25.0/detection/annotators/#supervision.annotators.core.RichLabelAnnotator) or [`VertexLabelAnnotator`](https://supervision.roboflow.com/0.25.0/detection/annotators/#supervision.annotators.core.RichLabelAnnotator), the labels will move around to avoid overlapping others. ([#1625](https://github.com/roboflow/supervision/pull/1625))
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread("image.jpg")
|
||||
|
||||
label_annotator = sv.LabelAnnotator(smart_position=True)
|
||||
|
||||
model = YOLO("yolo11m.pt")
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
annotated_frame = label_annotator.annotate(first_frame.copy(), detections)
|
||||
sv.plot_image(annotated_frame)
|
||||
```
|
||||
|
||||
- Added the `metadata` variable to [`Detections`](https://supervision.roboflow.com/0.25.0/detection/core/#supervision.detection.core.Detections). It allows you to store custom data per-image, rather than per-detected-object as was possible with `data` variable. For example, `metadata` could be used to store the source video path, camera model or camera parameters. ([#1589](https://github.com/roboflow/supervision/pull/1589))
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8m")
|
||||
|
||||
result = model("image.png")[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
|
||||
# Items in `data` must match length of detections
|
||||
object_ids = [num for num in range(len(detections))]
|
||||
detections.data["object_number"] = object_ids
|
||||
|
||||
# Items in `metadata` can be of any length.
|
||||
detections.metadata["camera_model"] = "Luxonis OAK-D"
|
||||
```
|
||||
|
||||
- Added a `py.typed` type hints metafile. It should provide a stronger signal to type annotators and IDEs that type support is available. ([#1586](https://github.com/roboflow/supervision/pull/1586))
|
||||
|
||||
- `ByteTrack` no longer requires `detections` to have a `class_id` ([#1637](https://github.com/roboflow/supervision/pull/1637))
|
||||
- `draw_line`, `draw_rectangle`, `draw_filled_rectangle`, `draw_polygon`, `draw_filled_polygon` and `PolygonZoneAnnotator` now comes with a default color ([#1591](https://github.com/roboflow/supervision/pull/1591))
|
||||
- Dataset classes are treated as case-sensitive when merging multiple datasets. ([#1643](https://github.com/roboflow/supervision/pull/1643))
|
||||
- Expanded [metrics documentation](https://supervision.roboflow.com/0.25.0/metrics/f1_score/) with example plots and printed results ([#1660](https://github.com/roboflow/supervision/pull/1660))
|
||||
- Added usage example for polygon zone ([#1608](https://github.com/roboflow/supervision/pull/1608))
|
||||
- Small improvements to error handling in polygons: ([#1602](https://github.com/roboflow/supervision/pull/1602))
|
||||
|
||||
- Updated [`ByteTrack`](https://supervision.roboflow.com/0.25.0/trackers/#supervision.tracker.byte_tracker.core.ByteTrack), removing shared variables. Previously, multiple instances of `ByteTrack` would share some date, requiring liberal use of `tracker.reset()`. ([#1603](https://github.com/roboflow/supervision/pull/1603)), ([#1528](https://github.com/roboflow/supervision/pull/1528))
|
||||
- Fixed a bug where `class_agnostic` setting in `MeanAveragePrecision` would not work. ([#1577](https://github.com/roboflow/supervision/pull/1577)) hacktoberfest
|
||||
- Removed welcome workflow from our CI system. ([#1596](https://github.com/roboflow/supervision/pull/1596))
|
||||
|
||||
- Large refactor of `ByteTrack`: STrack moved to separate class, removed superfluous `BaseTrack` class, removed unused variables ([#1603](https://github.com/roboflow/supervision/pull/1603))
|
||||
- Large refactor of `RichLabelAnnotator`, matching its contents with `LabelAnnotator`. ([#1625](https://github.com/roboflow/supervision/pull/1625))
|
||||
|
||||
### 0.24.0 <small>Oct 4, 2024</small>
|
||||
|
||||
- Added [F1 score](https://supervision.roboflow.com/0.24.0/metrics/f1_score/#supervision.metrics.f1_score.F1Score) as a new metric for detection and segmentation. [#1521](https://github.com/roboflow/supervision/pull/1521)
|
||||
|
||||
@@ -19,6 +19,10 @@ These features are phased out due to better alternatives or potential issues in
|
||||
|
||||
# Removed
|
||||
|
||||
### 0.25.0
|
||||
|
||||
No removals in this version!
|
||||
|
||||
### 0.24.0
|
||||
|
||||
- The `frame_resolution_wh ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) has been removed.
|
||||
|
||||
@@ -28,26 +28,28 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
</div>
|
||||
|
||||
=== "RoundBox"
|
||||
<!--
|
||||
=== "RoundBox"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
round_box_annotator = sv.RoundBoxAnnotator()
|
||||
annotated_frame = round_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
round_box_annotator = sv.RoundBoxAnnotator()
|
||||
annotated_frame = round_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
<div class="result" markdown>
|
||||
|
||||
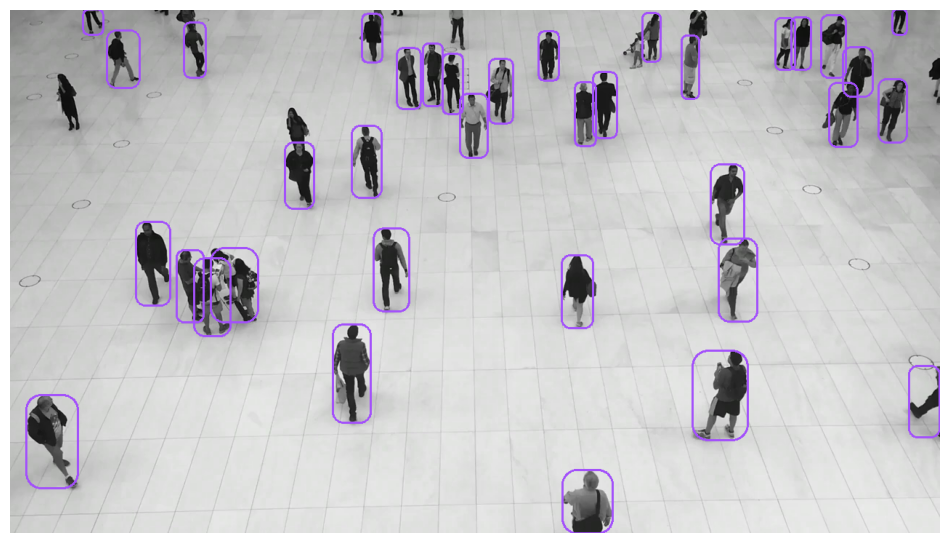{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
</div>
|
||||
-->
|
||||
|
||||
=== "BoxCorner"
|
||||
|
||||
@@ -234,7 +236,8 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
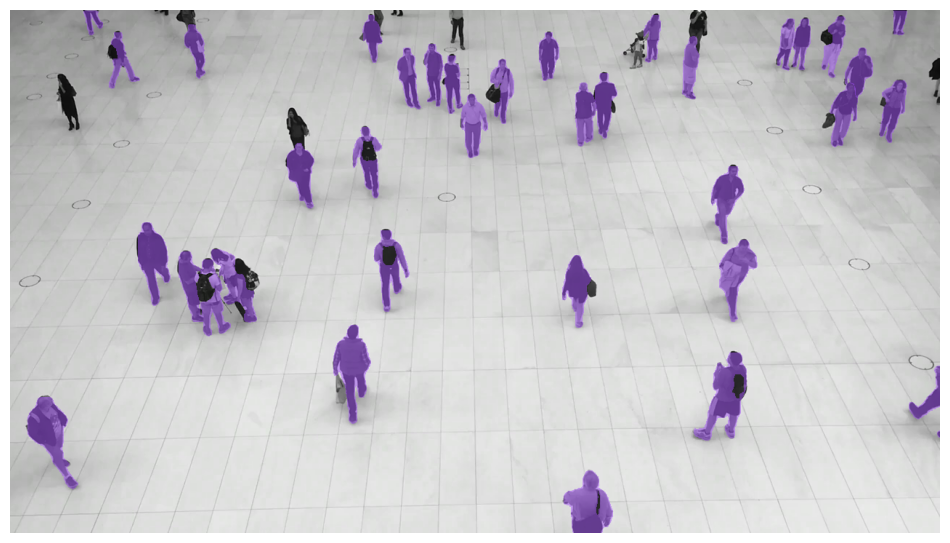{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
@@ -255,7 +258,8 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
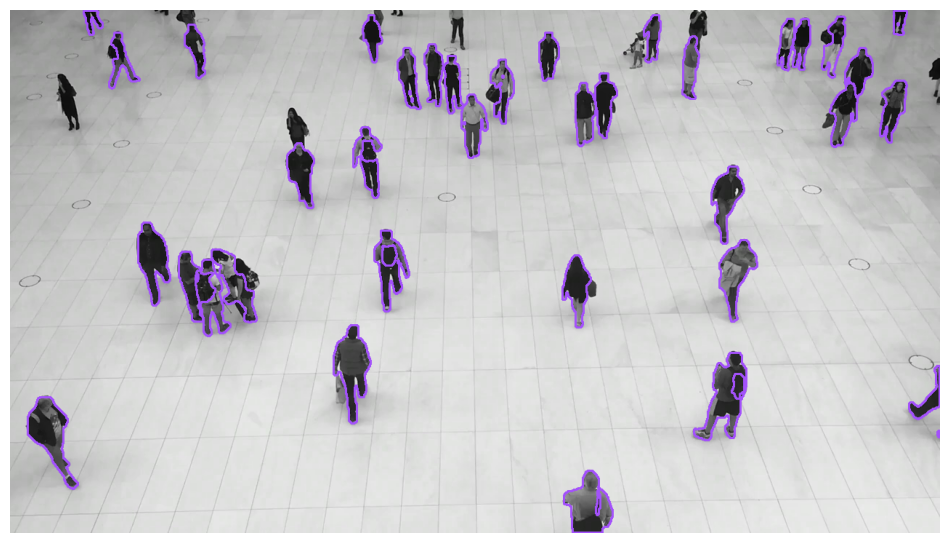{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
@@ -283,7 +287,8 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
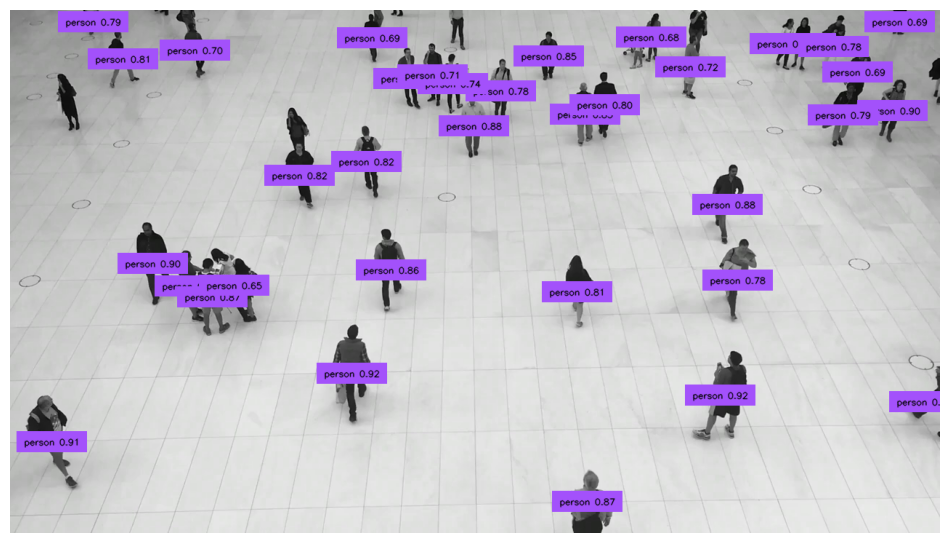{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
@@ -314,7 +319,8 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
@@ -341,24 +347,32 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Crop"
|
||||
<!-- === "Crop"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
crop_annotator = sv.CropAnnotator()
|
||||
annotated_frame = crop_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
crop_annotator = sv.CropAnnotator()
|
||||
annotated_frame = crop_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
-->
|
||||
|
||||
=== "Blur"
|
||||
|
||||
@@ -377,7 +391,8 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
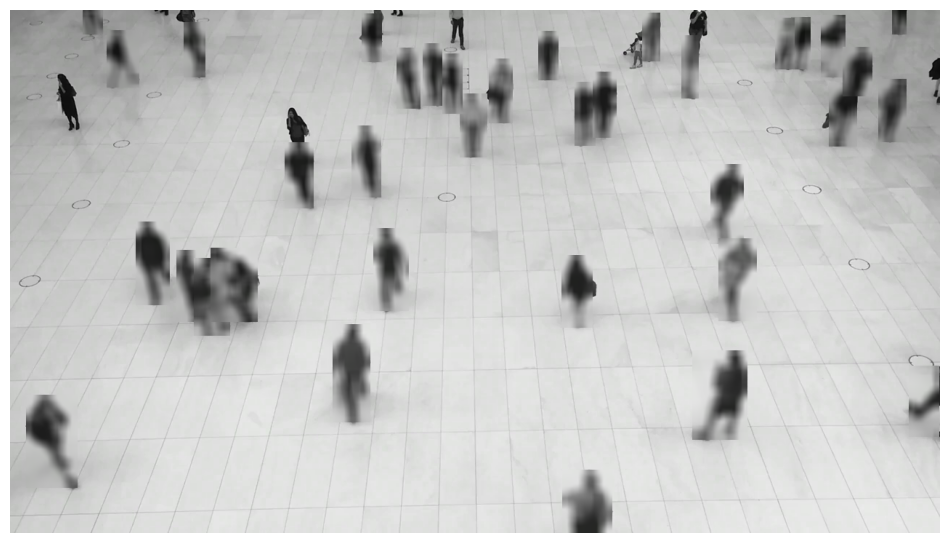{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
@@ -398,7 +413,8 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
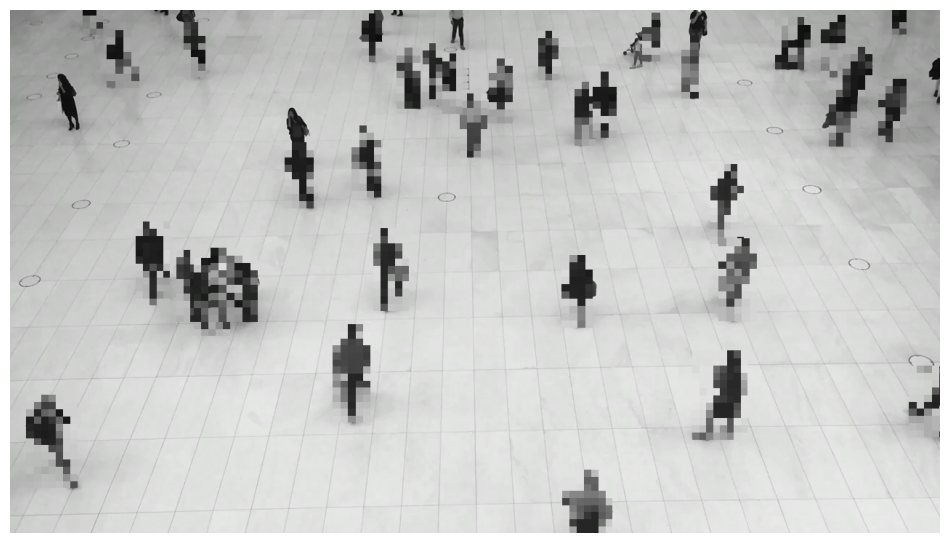{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
@@ -429,7 +445,8 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
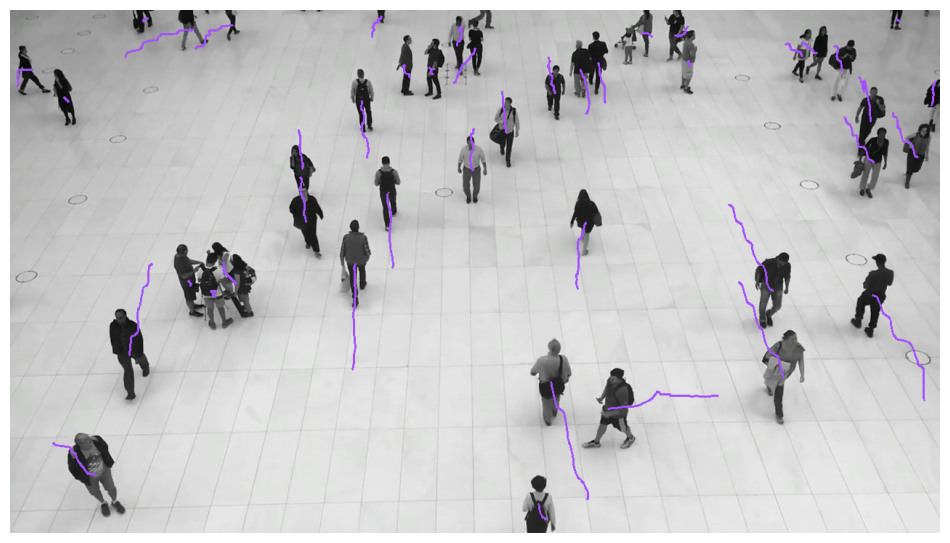{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
@@ -458,7 +475,8 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
@@ -479,7 +497,31 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Comparison"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections_1 = sv.Detections(...)
|
||||
detections_2 = sv.Detections(...)
|
||||
|
||||
comparison_annotator = sv.ComparisonAnnotator()
|
||||
annotated_frame = comparison_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections_1=detections_1,
|
||||
detections_2=detections_2
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
@@ -622,6 +664,12 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
:::supervision.annotators.core.BackgroundOverlayAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.ComparisonAnnotator">ComparisonAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.ComparisonAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.ColorLookup">ColorLookup</a></h2>
|
||||
</div>
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# InferenceSlicer
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
|
||||
@@ -0,0 +1,441 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
|
||||
|
||||
# Benchmark a Model
|
||||
|
||||
Have you ever trained multiple detection models and wondered which one performs best on your specific use case? Or maybe you've downloaded a pre-trained model and want to verify its performance on your dataset? Model benchmarking is essential for making informed decisions about which model to deploy in production.
|
||||
|
||||
This guide will show an easy way to benchmark your results using `supervision`. It will go over:
|
||||
|
||||
1. [Loading a dataset](#loading-a-dataset)
|
||||
2. [Loading a model](#loading-a-model)
|
||||
3. [Benchmarking Basics](#benchmarking-basics)
|
||||
4. [Running a Model](#running-a-model)
|
||||
5. [Remapping Classes](#remapping-classes)
|
||||
6. [Visual Benchmarking](#visual-benchmarking)
|
||||
7. [Benchmarking Metrics](#benchmarking-metrics)
|
||||
8. [Mean Average Precision (mAP)](#mean-average-precision-map)
|
||||
9. [F1 Score](#f1-score)
|
||||
10. [Bonus: Model Leaderboard](#model-leaderboard)
|
||||
|
||||
This guide will use an instance segmentation model, but it applies to object detection, instance segmentation, and oriented bounding box models (OBB) too.
|
||||
|
||||
A condensed version of this guide is available as a [Colab Notebook](https://colab.research.google.com/drive/1HoOY9pZoVwGiRMmLHtir0qT6Uj45w6Ps?usp=sharing).
|
||||
|
||||
## Loading a Dataset
|
||||
|
||||
Suppose you start with a dataset. Perhaps you found it on [Universe](https://universe.roboflow.com/); perhaps you [labeled your own](https://roboflow.com/how-to-label/yolo11). In either case, this guide assumes you know of a labelled dataset at hand.
|
||||
|
||||
We'll use the following libraries:
|
||||
|
||||
- `roboflow` to manage the dataset and deploy models
|
||||
- `inference` to run the models
|
||||
- `supervision` to evaluate the model results
|
||||
|
||||
```bash
|
||||
pip install roboflow supervision
|
||||
pip install git+https://github.com/roboflow/inference.git@linas/allow-latest-rc-supervision
|
||||
```
|
||||
|
||||
!!! info
|
||||
|
||||
We're updating `inference` at the moment. Please install it as shown above.
|
||||
|
||||
Here's how you can download a dataset:
|
||||
|
||||
```python
|
||||
from roboflow import Roboflow
|
||||
|
||||
rf = Roboflow(api_key="<YOUR_API_KEY>")
|
||||
project = rf.workspace("<WORKSPACE_NAME>").project("<PROJECT_NAME>")
|
||||
dataset = project.version(<DATASET_VERSION_NUMBER>).download("<FORMAT>")
|
||||
```
|
||||
|
||||
If your dataset is from Universe, go to `Dataset` > `Download Dataset` > select the format (e.g. `YOLOv11`) > `Show download code`.
|
||||
|
||||
If labeling your own data, go to the [dashboard](https://app.roboflow.com/) and check this [guide](https://docs.roboflow.com/api-reference/workspace-and-project-ids) to find your workspace and project IDs.
|
||||
|
||||
In this guide, we shall use a small [Corgi v2](https://universe.roboflow.com/model-examples/segmented-animals-basic) dataset. It is well-labeled and comes with a test set.
|
||||
|
||||
```python
|
||||
from roboflow import Roboflow
|
||||
|
||||
rf = Roboflow(api_key="<YOUR_API_KEY>")
|
||||
project = rf.workspace("fbamse1-gm2os").project("corgi-v2")
|
||||
dataset = project.version(4).download("yolov11")
|
||||
```
|
||||
|
||||
This will create a folder called `Corgi-v2-4` with the dataset in the current working directory, with `train`, `test`, and `valid` folders and a `data.yaml` file.
|
||||
|
||||
## Loading a Model
|
||||
|
||||
Let's load a model.
|
||||
|
||||
=== "Inference, Local"
|
||||
|
||||
Roboflow supports a range of state-of-the-art [pre-trained models](https://inference.roboflow.com/quickstart/aliases/) for object detection, instance segmentation, and pose tracking. You don't even need an API key!
|
||||
|
||||
Let's load such a model with inference [`inference`](https://inference.roboflow.com/).
|
||||
|
||||
```python
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov11s-seg-640")
|
||||
```
|
||||
|
||||
=== "Inference, Deployed"
|
||||
|
||||
You can train and deploy a model without leaving the Roboflow platform. See this [guide](https://docs.roboflow.com/train/train/train-from-scratch) for more details.
|
||||
|
||||
To load a model, you can use inference:
|
||||
|
||||
```python
|
||||
from inference import get_model
|
||||
|
||||
model_id = "<PROJECT_NAME>/<MODEL_VERSION>"
|
||||
model = get_model(model_id=model_id)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
Similarly to Inference, Ultralytics allows you to run a variety of models.
|
||||
|
||||
```bash
|
||||
pip install "ultralytics<=8.3.40"
|
||||
```
|
||||
|
||||
```python
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolo11s-seg.pt")
|
||||
```
|
||||
|
||||
## Benchmarking Basics
|
||||
|
||||
Evaluating your model requires careful selection of the dataset. Which images should you use?Let's go over the different scenarios.
|
||||
|
||||
- **Unrelated Dataset**: If you have a dataset that was not used to train the model, this is the best choice.
|
||||
- **Training Set**: This is the set of images used to train the model. This is fine if the model was not trained on this dataset. Otherwise, **never** use it for benchmarking - the results will seem unrealistically good.
|
||||
- **Validation Set**: This is the set of images used to validate the model during training. Every Nth training epoch, the model is evaluated on the validation set. Often the training is stopped once the validation loss stops improving. Therefore, even while the images aren't used to train the model, it still indirectly influences the training outcome.
|
||||
- **Test Set**: This is the set of images kept aside for model testing. It is exactly the set you should use for benchmarking. If the dataset was split correctly, none of these images would be shown to the model during training.
|
||||
|
||||
Therefore, an unrelated dataset or the `test` set is the best choice for benchmarking.
|
||||
Several other problems may arise:
|
||||
|
||||
- **Extra Classes**: An unrelated dataset may contain additional classes which you may need to [filter out](https://supervision.roboflow.com/how_to/filter_detections/#by-set-of-classes) before computing metrics.
|
||||
- **Class Mismatch**: In an unrelated dataset, the class names or IDs may be different to what your model produces, you'll need to remap them, which is [shown in this guide](#running-a-model).
|
||||
- **Data Contamination**: The `test` set may not be split correctly, with images from the test set also present in `training` or `validation` set and used during training. In this case, the results will be overly optimistic. This also applies when **very similar** images are used for training and testing - e.g. those taken in the same environment, same lighting conditions, similar angle, etc.
|
||||
- **Missing Test Set**: Some datasets do not come with a test set. In this case, you should collect and [label](https://roboflow.com/annotate) your own data. Alternatively, a validation set could be used, but the results could be overly optimistic. Make sure to test in the real world as soon as possible.
|
||||
|
||||
## Running a Model
|
||||
|
||||
At this stage, you should have:
|
||||
|
||||
- A dataset of labeled images to evaluate the model.
|
||||
- A model prepared for benchmarking.
|
||||
|
||||
With these ready, we can now run the model and obtain predictions.
|
||||
We'll use `supervision` to create a dataset iterator, and then run the model on each image.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
test_set = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
|
||||
image_paths = []
|
||||
predictions_list = []
|
||||
targets_list = []
|
||||
|
||||
for image_path, image, label in test_set:
|
||||
result = model.infer(image)[0]
|
||||
predictions = sv.Detections.from_inference(result)
|
||||
|
||||
image_paths.append(image_path)
|
||||
predictions_list.append(predictions)
|
||||
targets_list.append(label)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
test_set = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
|
||||
image_paths = []
|
||||
predictions_list = []
|
||||
targets_list = []
|
||||
|
||||
for image_path, image, label in test_set:
|
||||
result = model(image)[0]
|
||||
predictions = sv.Detections.from_ultralytics(result)
|
||||
|
||||
image_paths.append(image_path)
|
||||
predictions_list.append(predictions)
|
||||
targets_list.append(label)
|
||||
```
|
||||
|
||||
## Remapping classes
|
||||
|
||||
Did you notice an issue in the above logic?
|
||||
Since we're using an unrelated dataset, the class names and IDs may be different from what the model was trained on.
|
||||
|
||||
We need to remap them to match the dataset classes. Here's how to do it:
|
||||
|
||||
```python
|
||||
def remap_classes(
|
||||
detections: sv.Detections,
|
||||
class_ids_from_to: dict[int, int],
|
||||
class_names_from_to: dict[str, str]
|
||||
) -> None:
|
||||
new_class_ids = [
|
||||
class_ids_from_to.get(class_id, class_id) for class_id in detections.class_id]
|
||||
detections.class_id = np.array(new_class_ids)
|
||||
|
||||
new_class_names = [
|
||||
class_names_from_to.get(name, name) for name in detections["class_name"]]
|
||||
predictions["class_name"] = np.array(new_class_names)
|
||||
```
|
||||
|
||||
Let's also remove the predictions that are not in the dataset classes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
Dataset class names and IDs can be found in the `data.yaml` file, or by printing `dataset.classes`.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
test_set = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
|
||||
image_paths = []
|
||||
predictions_list = []
|
||||
targets_list = []
|
||||
|
||||
for image_path, image, label in test_set:
|
||||
result = model.infer(image)[0]
|
||||
predictions = sv.Detections.from_inference(result)
|
||||
|
||||
remap_classes(
|
||||
detections=predictions,
|
||||
class_ids_from_to={16: 0},
|
||||
class_names_from_to={"dog": "Corgi"}
|
||||
)
|
||||
predictions = predictions[
|
||||
np.isin(predictions["class_name"], test_set.classes)
|
||||
]
|
||||
|
||||
image_paths.append(image_path)
|
||||
predictions_list.append(predictions)
|
||||
targets_list.append(label)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
Dataset class names and IDs can be found in the `data.yaml` file, or by printing `dataset.classes`.
|
||||
|
||||
Each model will have a different class mapping, so make sure to check the model's documentation. In this case, the model was trained on the COCO dataset, with a class
|
||||
configuration found [here](https://github.com/ultralytics/ultralytics/blob/main/ultralytics/cfg/datasets/coco8.yaml).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
test_set = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
|
||||
image_paths = []
|
||||
predictions_list = []
|
||||
targets_list = []
|
||||
|
||||
for image_path, image, label in test_set:
|
||||
result = model(image)[0]
|
||||
predictions = sv.Detections.from_ultralytics(result)
|
||||
|
||||
remap_classes(
|
||||
detections=predictions,
|
||||
class_ids_from_to={16: 0},
|
||||
class_names_from_to={"dog": "Corgi"}
|
||||
)
|
||||
predictions = predictions[
|
||||
np.isin(predictions["class_name"], test_set.classes)
|
||||
]
|
||||
|
||||
image_paths.append(image_path)
|
||||
predictions_list.append(predictions)
|
||||
targets_list.append(label)
|
||||
```
|
||||
|
||||
## Visualizing Predictions
|
||||
|
||||
The first step in evaluating your model’s performance is to visualize its predictions.
|
||||
This gives an intuitive sense of how well your model is detecting objects and where it might be failing.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
N = 9
|
||||
GRID_SIZE = (3, 3)
|
||||
|
||||
target_annotator = sv.PolygonAnnotator(color=sv.Color.from_hex("#8315f9"), thickness=8)
|
||||
prediction_annotator = sv.PolygonAnnotator(color=sv.Color.from_hex("#00cfc6"), thickness=6)
|
||||
|
||||
|
||||
annotated_images = []
|
||||
for image_path, predictions, targets in zip(
|
||||
image_paths[:N], predictions_list[:N], targets_list[:N]
|
||||
):
|
||||
annotated_image = cv2.imread(image_path)
|
||||
annotated_image = target_annotator.annotate(scene=annotated_image, detections=targets)
|
||||
annotated_image = prediction_annotator.annotate(scene=annotated_image, detections=prediction)
|
||||
annotated_images.append(annotated_image)
|
||||
|
||||
sv.plot_images_grid(images=annotated_images, grid_size=GRID_SIZE)
|
||||
```
|
||||
|
||||
Here, predictions in purple are targets (ground truth), and predictions in teal are model predictions.
|
||||
|
||||
|
||||
|
||||
!!! tip
|
||||
|
||||
Use `sv.BoxAnnotator` for object detection and `sv.OrientedBoxAnnotator` for OBB.
|
||||
|
||||
See [annotator documentation](https://supervision.roboflow.com/latest/detection/annotators/) for even more options.
|
||||
|
||||
## Benchmarking Metrics
|
||||
|
||||
With multiple models, fine details matter. Visual inspection may not be enough. `supervision` provides a collection of metrics that help obtain precise numerical results of model performance.
|
||||
|
||||
### Mean Average Precision (mAP)
|
||||
|
||||
We'll start with [MeanAveragePrecision (mAP)](https://supervision.roboflow.com/latest/metrics/mean_average_precision/#supervision.metrics.mean_average_precision.MeanAveragePrecision), which is the most commonly used metric for object detection. It measures the average precision across all classes and IoU thresholds.
|
||||
|
||||
For a thorough explanation, check out our [blog](https://blog.roboflow.com/mean-average-precision/) and [Youtube video](https://www.youtube.com/watch?v=oqXDdxF_Wuw).
|
||||
|
||||
Here, the most popular value is `mAP 50:95`. It represents the average precision across all classes and IoU thresholds (`0.5` to `0.95`), whereas other values such as `mAP 50` or `mAP 75` only consider a single IoU threshold (`0.5` and `0.75` respectively).
|
||||
|
||||
Let's compute the mAP:
|
||||
|
||||
```python
|
||||
from supervision.metrics import MeanAveragePrecision, MetricTarget
|
||||
|
||||
map_metric = MeanAveragePrecision(metric_target=MetricTarget.MASKS)
|
||||
map_result = map_metric.update(predictions_list, targets_list).compute()
|
||||
```
|
||||
|
||||
Try printing the result to see it at a glance:
|
||||
|
||||
```python
|
||||
print(map_result)
|
||||
```
|
||||
|
||||
```
|
||||
MeanAveragePrecisionResult:
|
||||
Metric target: MetricTarget.MASKS
|
||||
Class agnostic: False
|
||||
mAP @ 50:95: 0.2409
|
||||
mAP @ 50: 0.3591
|
||||
mAP @ 75: 0.2915
|
||||
mAP scores: [0.35909 0.3468 0.34556 ...]
|
||||
IoU thresh: [0.5 0.55 0.6 ...]
|
||||
AP per class:
|
||||
0: [0.35909 0.3468 0.34556 ...]
|
||||
...
|
||||
Small objects: ...
|
||||
Medium objects: ...
|
||||
Large objects: ...
|
||||
```
|
||||
|
||||
You can also plot the results:
|
||||
|
||||
```python
|
||||
map_result.plot()
|
||||
```
|
||||
|
||||
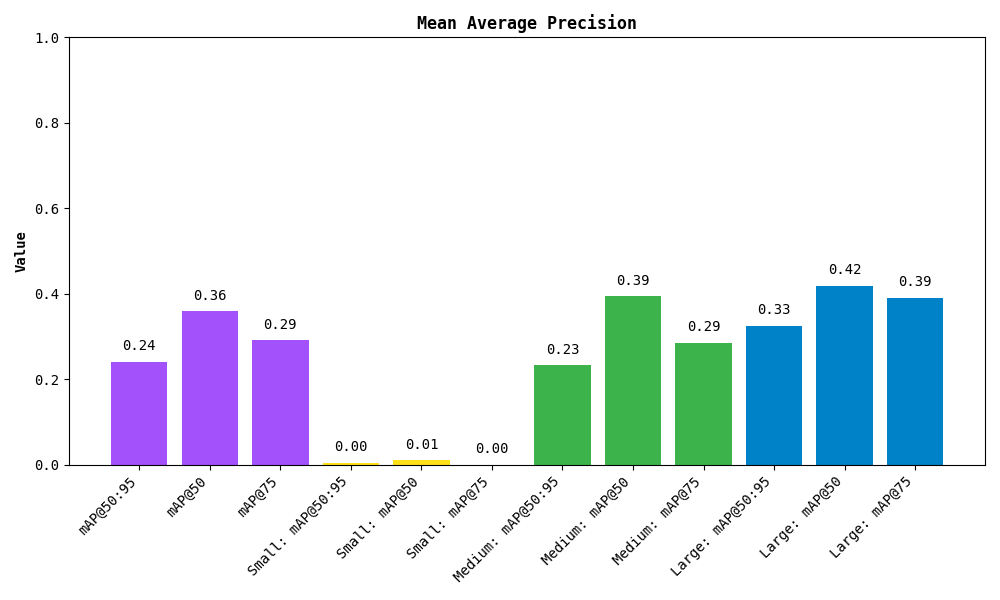
|
||||
|
||||
The metric also breaks down the results by detected object area. Small, medium and large are simply those with area less than 32², between 32² and 96², and greater than 96² pixels respectively.
|
||||
|
||||
### F1 Score
|
||||
|
||||
The [F1 Score](https://supervision.roboflow.com/latest/metrics/f1_score/) is another useful metric, especially when dealing with an imbalance between false positives and false negatives. It’s the harmonic mean of **precision** (how many predictions are correct) and **recall** (how many actual instances were detected).
|
||||
|
||||
Here's how you can compute the F1 score:
|
||||
|
||||
```python
|
||||
from supervision.metrics import F1Score, MetricTarget
|
||||
|
||||
f1_metric = F1Score(metric_target=MetricTarget.MASKS)
|
||||
f1_result = f1_metric.update(predictions_list, targets_list).compute()
|
||||
```
|
||||
|
||||
As with mAP, you can also print the result:
|
||||
|
||||
```python
|
||||
print(f1_result)
|
||||
```
|
||||
|
||||
```
|
||||
F1ScoreResult:
|
||||
Metric target: MetricTarget.MASKS
|
||||
Averaging method: AveragingMethod.WEIGHTED
|
||||
F1 @ 50: 0.5341
|
||||
F1 @ 75: 0.4636
|
||||
F1 @ thresh: [0.53406 0.5278 0.52153 ...]
|
||||
IoU thresh: [0.5 0.55 0.6 ...]
|
||||
F1 per class:
|
||||
0: [0.53406 0.5278 0.52153 ...]
|
||||
...
|
||||
Small objects: ...
|
||||
Medium objects: ...
|
||||
Large objects: ...
|
||||
```
|
||||
|
||||
Similarly, you can plot the results:
|
||||
|
||||
```python
|
||||
f1_result.plot()
|
||||
```
|
||||
|
||||
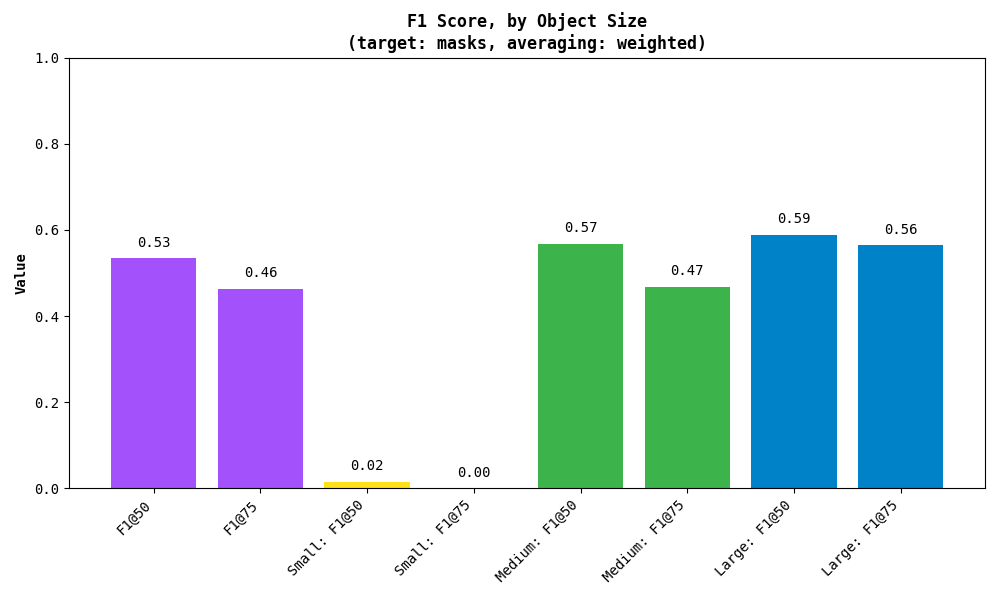
|
||||
|
||||
As with mAP, the metric also breaks down the results by detected object area. Small, medium and large are simply those with area less than 32², between 32² and 96², and greater than 96² pixels respectively.
|
||||
|
||||
## Model Leaderboard
|
||||
|
||||
Here to compare the basic models? We've got you covered. Check out our [Model Leaderboard](https://leaderboard.roboflow.com/) to see how different models perform and to get a sense of the state-of-the-art results. It's a great place to understand what the leading models can achieve and to compare your own results.
|
||||
|
||||
Even better, the repository is open source! You can see how the models were benchmarked, run the evaluation yourself, and even add your own models to the leaderboard. Check it out on [GitHub](https://github.com/roboflow/model-leaderboard)!
|
||||
|
||||
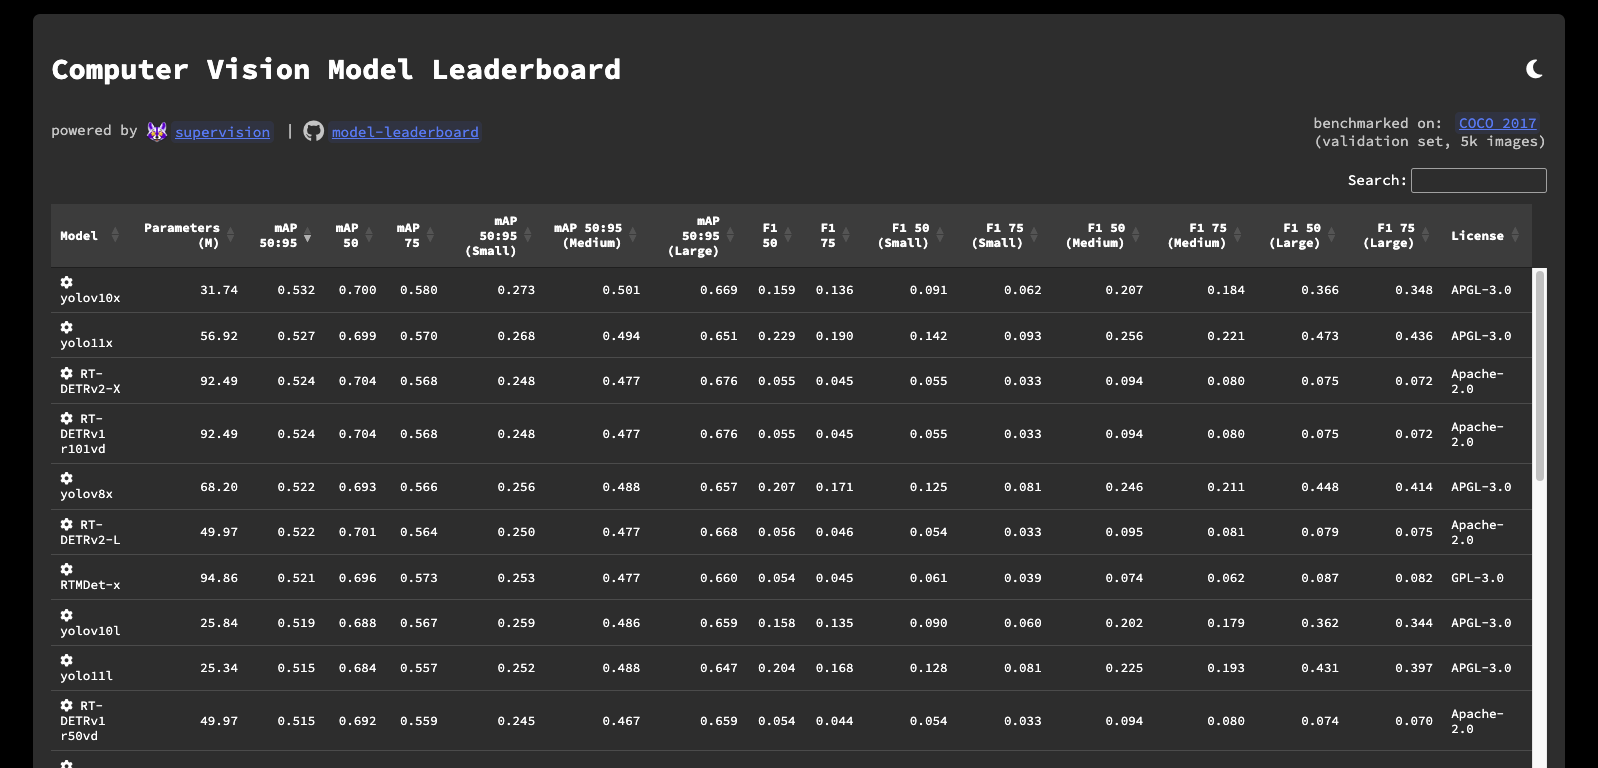
|
||||
|
||||
## Conclusion
|
||||
|
||||
In this guide, you've learned how to set up your environment, train or use pre-trained models, visualize predictions, and evaluate model performance with metrics like [mAP](https://supervision.roboflow.com/latest/metrics/mean_average_precision/), [F1 score](https://supervision.roboflow.com/latest/metrics/f1_score/), and got to know our Model Leaderboard.
|
||||
|
||||
A condensed version of this guide is also available as a [Colab Notebook](https://colab.research.google.com/drive/1HoOY9pZoVwGiRMmLHtir0qT6Uj45w6Ps?usp=sharing).
|
||||
|
||||
For more details, be sure to check out our [documentation](https://supervision.roboflow.com/latest/) and join our community discussions. If you find any issues, please let us know on [GitHub](https://github.com/roboflow/supervision/issues).
|
||||
|
||||
Best of luck with your benchmarking!
|
||||
+284
-43
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Track Objects
|
||||
@@ -13,6 +14,8 @@ take you through the steps to perform inference using the YOLOv8 model via eithe
|
||||
you'll discover how to track these objects efficiently and annotate your video content
|
||||
for a deeper analysis.
|
||||
|
||||
## Object Detection & Segmentation
|
||||
|
||||
To make it easier for you to follow our tutorial download the video we will use as an
|
||||
example. You can do this using
|
||||
[`supervision[assets]`](/latest/assets/) extension.
|
||||
@@ -21,14 +24,13 @@ example. You can do this using
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
|
||||
download_assets(VideoAssets.PEOPLE_WALKING)
|
||||
download_assets(VideoAssets.SKIING)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/people-walking.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Run Inference
|
||||
### Run Inference
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. In this tutorial, we are using the YOLOv8 model as an example. However,
|
||||
@@ -41,6 +43,10 @@ by obtaining model predictions and then annotating the frame based on these pred
|
||||
This `callback` function will be essential in the subsequent steps of the tutorial, as
|
||||
it will be modified to include tracking, labeling, and trace annotations.
|
||||
|
||||
!!! tip
|
||||
|
||||
Both object detection and segmentation models are supported. Try it with `yolov8n.pt` or `yolov8n-640-seg`!
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py }
|
||||
@@ -89,7 +95,7 @@ it will be modified to include tracking, labeling, and trace annotations.
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/run-inference.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Tracking
|
||||
### Tracking
|
||||
|
||||
After running inference and obtaining predictions, the next step is to track the
|
||||
detected objects throughout the video. Utilizing Supervision’s
|
||||
@@ -145,7 +151,7 @@ enabling the continuous following of the object's motion path across different f
|
||||
)
|
||||
```
|
||||
|
||||
## Annotate Video with Tracking IDs
|
||||
### Annotate Video with Tracking IDs
|
||||
|
||||
Annotating the video with tracking IDs helps in distinguishing and following each object
|
||||
distinctly. With the
|
||||
@@ -227,7 +233,7 @@ offering a clear visual representation of each object's class and unique identif
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/annotate-video-with-tracking-ids.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Annotate Video with Traces
|
||||
### Annotate Video with Traces
|
||||
|
||||
Adding traces to the video involves overlaying the historical paths of the detected
|
||||
objects. This feature, powered by the
|
||||
@@ -315,9 +321,96 @@ movement patterns and interactions between objects in the video.
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/annotate-video-with-traces.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Tracking Key Points
|
||||
## Keypoints
|
||||
|
||||
Keypoint tracking is currently supported via the conversion of `KeyPoints` to `Detections`. This is achieved with the [`keypoints_to_detections`](/latest/utils/datatypes/#supervision.utils.datatypes.keypoints_to_detections) function. We'll use a different video as well as [`DetectionsSmoother`](/latest/detection/tools/smoother/) to stabilize the boxes.
|
||||
Models aren't limited to object detection and segmentation. Keypoint detection allows for detailed analysis of body joints and connections, especially valuable for applications like human pose estimation. This section introduces keypoint tracking. We'll walk through the steps of annotating keypoints, converting them into bounding box detections compatible with `ByteTrack`, and applying detection smoothing for enhanced stability.
|
||||
|
||||
To make it easier for you to follow our tutorial, let's download the video we will use as an
|
||||
example. You can do this using [`supervision[assets]`](/latest/assets/) extension.
|
||||
|
||||
```python
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
|
||||
download_assets(VideoAssets.SKIING)
|
||||
```
|
||||
|
||||
<video controls muted>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/skiing-hd.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
### Keypoint Detection
|
||||
|
||||
First, you'll need to obtain predictions from your keypoint detection model. In this tutorial, we are using the YOLOv8 model as an example. However,
|
||||
Supervision is versatile and compatible with various models. Check this [link](/latest/keypoint/core/) for guidance on how to plug in other models.
|
||||
|
||||
We will define a `callback` function, which will process each frame of the video by obtaining model predictions and then annotating the frame based on these predictions.
|
||||
|
||||
Let's immediately visualize the results with our [`EdgeAnnotator`](/latest/keypoint/annotators/#supervision.keypoint.annotators.EdgeAnnotator) and [`VertexAnnotator`](https://supervision.roboflow.com/latest/keypoint/annotators/#supervision.keypoint.annotators.VertexAnnotator).
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="5 10-11" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8m-pose.pt")
|
||||
edge_annotator = sv.EdgeAnnotator()
|
||||
vertex_annotator = sv.VertexAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
key_points = sv.KeyPoints.from_ultralytics(results)
|
||||
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
frame.copy(), key_points=key_points)
|
||||
return vertex_annotator.annotate(
|
||||
annotated_frame, key_points=key_points)
|
||||
|
||||
sv.process_video(
|
||||
source_path="skiing.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="5-6 11-12" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(
|
||||
model_id="yolov8m-pose-640", api_key=<ROBOFLOW API KEY>)
|
||||
edge_annotator = sv.EdgeAnnotator()
|
||||
vertex_annotator = sv.VertexAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
key_points = sv.KeyPoints.from_inference(results)
|
||||
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
frame.copy(), key_points=key_points)
|
||||
return vertex_annotator.annotate(
|
||||
annotated_frame, key_points=key_points)
|
||||
|
||||
sv.process_video(
|
||||
source_path="skiing.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/track-keypoints-only-keypoints.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
### Convert to Detections
|
||||
|
||||
Keypoint tracking is currently supported via the conversion of `KeyPoints` to `Detections`. This is achieved with the [`KeyPoints.as_detections()`](/latest/keypoint/core/#supervision.keypoint.core.KeyPoints.as_detections) function.
|
||||
|
||||
Let's convert to detections and visualize the results with our [`BoxAnnotator`](/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator).
|
||||
|
||||
!!! tip
|
||||
|
||||
@@ -325,35 +418,102 @@ Keypoint tracking is currently supported via the conversion of `KeyPoints` to `D
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="5 7 14-15 17 33" }
|
||||
```{ .py hl_lines="8 13 19-20" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8m-pose.pt")
|
||||
edge_annotator = sv.EdgeAnnotator()
|
||||
vertex_annotator = sv.VertexAnnotator()
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
key_points = sv.KeyPoints.from_ultralytics(results)
|
||||
detections = key_points.as_detections()
|
||||
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
frame.copy(), key_points=key_points)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
annotated_frame, key_points=key_points)
|
||||
return box_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="skiing.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="9 14 20-21" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(
|
||||
model_id="yolov8m-pose-640", api_key=<ROBOFLOW API KEY>)
|
||||
edge_annotator = sv.EdgeAnnotator()
|
||||
vertex_annotator = sv.VertexAnnotator()
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
key_points = sv.KeyPoints.from_inference(results)
|
||||
detections = key_points.as_detections()
|
||||
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
frame.copy(), key_points=key_points)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
annotated_frame, key_points=key_points)
|
||||
return box_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="skiing.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/track-keypoints-converted-to-detections.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
### Keypoint Tracking
|
||||
|
||||
Now that we have a `Detections` object, we can track it throughout the video. Utilizing Supervision’s [`sv.ByteTrack`](/latest/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) functionality, each detected object is assigned a unique tracker ID, enabling the continuous following of the object's motion path across different frames. We shall visualize the result with `TraceAnnotator`.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="10-11 17 25-26" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8m-pose.pt")
|
||||
edge_annotator = sv.EdgeAnnotator()
|
||||
vertex_annotator = sv.VertexAnnotator()
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
|
||||
tracker = sv.ByteTrack()
|
||||
smoother = sv.DetectionsSmoother()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(results)
|
||||
detections = sv.keypoints_to_detections(keypoints)
|
||||
key_points = sv.KeyPoints.from_ultralytics(results)
|
||||
detections = key_points.as_detections()
|
||||
detections = tracker.update_with_detections(detections)
|
||||
detections = smoother.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
frame.copy(), key_points=key_points)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
annotated_frame, key_points=key_points)
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
annotated_frame, detections=detections)
|
||||
return trace_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
@@ -366,36 +526,32 @@ Keypoint tracking is currently supported via the conversion of `KeyPoints` to `D
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="5-6 8 15-16 18 34" }
|
||||
```{ .py hl_lines="11-12 18 26-27" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(
|
||||
model_id="yolov8m-pose-640", api_key=<ROBOFLOW API KEY>)
|
||||
edge_annotator = sv.EdgeAnnotator()
|
||||
vertex_annotator = sv.VertexAnnotator()
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
|
||||
tracker = sv.ByteTrack()
|
||||
smoother = sv.DetectionsSmoother()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
keypoints = sv.KeyPoints.from_inference(results)
|
||||
detections = sv.keypoints_to_detections(keypoints)
|
||||
key_points = sv.KeyPoints.from_inference(results)
|
||||
detections = key_points.as_detections()
|
||||
detections = tracker.update_with_detections(detections)
|
||||
detections = smoother.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
frame.copy(), key_points=key_points)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
annotated_frame, key_points=key_points)
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
annotated_frame, detections=detections)
|
||||
return trace_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
@@ -407,9 +563,94 @@ Keypoint tracking is currently supported via the conversion of `KeyPoints` to `D
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/track-keypoints.mp4" type="video/mp4">
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/track-keypoints-with-tracking.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
This structured walkthrough should give a detailed pathway to annotate videos
|
||||
effectively using Supervision’s various functionalities, including object tracking and
|
||||
trace annotations.
|
||||
### Bonus: Smoothing
|
||||
|
||||
We could stop here as we have successfully tracked the object detected by the keypoint model. However, we can further enhance the stability of the boxes by applying [`DetectionsSmoother`](/latest/detection/tools/smoother/). This tool helps in stabilizing the boxes by smoothing the bounding box coordinates across frames. It is very simple to use:
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="11 19" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8m-pose.pt")
|
||||
edge_annotator = sv.EdgeAnnotator()
|
||||
vertex_annotator = sv.VertexAnnotator()
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
|
||||
tracker = sv.ByteTrack()
|
||||
smoother = sv.DetectionsSmoother()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
key_points = sv.KeyPoints.from_ultralytics(results)
|
||||
detections = key_points.as_detections()
|
||||
detections = tracker.update_with_detections(detections)
|
||||
detections = smoother.update_with_detections(detections)
|
||||
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
frame.copy(), key_points=key_points)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
annotated_frame, key_points=key_points)
|
||||
annotated_frame = box_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
return trace_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="skiing.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="12 20" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(
|
||||
model_id="yolov8m-pose-640", api_key=<ROBOFLOW API KEY>)
|
||||
edge_annotator = sv.EdgeAnnotator()
|
||||
vertex_annotator = sv.VertexAnnotator()
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
|
||||
tracker = sv.ByteTrack()
|
||||
smoother = sv.DetectionsSmoother()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
key_points = sv.KeyPoints.from_inference(results)
|
||||
detections = key_points.as_detections()
|
||||
detections = tracker.update_with_detections(detections)
|
||||
detections = smoother.update_with_detections(detections)
|
||||
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
frame.copy(), key_points=key_points)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
annotated_frame, key_points=key_points)
|
||||
annotated_frame = box_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
return trace_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="skiing.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/track-keypoints-with-smoothing.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
This structured walkthrough should give a detailed pathway to annotate videos effectively using Supervision’s various functionalities, including object tracking and trace annotations.
|
||||
|
||||
+42
-4
@@ -33,8 +33,9 @@ We write your reusable computer vision tools. Whether you need to load your data
|
||||
You can install `supervision` in a
|
||||
[**Python>=3.8**](https://www.python.org/) environment.
|
||||
|
||||
!!! example "pip install (recommended)"
|
||||
=== "pip"
|
||||
!!! example "Installation"
|
||||
|
||||
=== "pip (recommended)"
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
@@ -44,6 +45,43 @@ You can install `supervision` in a
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
=== "poetry"
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
|
||||
```bash
|
||||
poetry add supervision
|
||||
```
|
||||
|
||||
=== "uv"
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
|
||||
```bash
|
||||
uv pip install supervision
|
||||
```
|
||||
|
||||
For uv projects:
|
||||
|
||||
```bash
|
||||
uv add supervision
|
||||
```
|
||||
|
||||
=== "rye"
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
|
||||
```bash
|
||||
rye add supervision
|
||||
```
|
||||
|
||||
|
||||
!!! example "conda/mamba install"
|
||||
=== "conda"
|
||||
[](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision)
|
||||
@@ -63,7 +101,7 @@ You can install `supervision` in a
|
||||
=== "virtualenv"
|
||||
```bash
|
||||
# clone repository and navigate to root directory
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
git clone --depth 1 -b develop https://github.com/roboflow/supervision.git
|
||||
cd supervision
|
||||
|
||||
# setup python environment and activate it
|
||||
@@ -78,7 +116,7 @@ You can install `supervision` in a
|
||||
=== "poetry"
|
||||
```bash
|
||||
# clone repository and navigate to root directory
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
git clone --depth 1 -b develop https://github.com/roboflow/supervision.git
|
||||
cd supervision
|
||||
|
||||
# setup python environment and activate it
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Keypoint Detection
|
||||
|
||||
@@ -0,0 +1,18 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Mean Average Recall
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.mean_average_recall.MeanAverageRecall">MeanAverageRecall</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.mean_average_recall.MeanAverageRecall
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.mean_average_recall.MeanAverageRecallResult">MeanAverageRecallResult</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.mean_average_recall.MeanAverageRecallResult
|
||||
+1
-1
@@ -130,7 +130,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q ultralytics supervision==0.18.0"
|
||||
"!pip install -q \"ultralytics<=8.3.40\" \"supervision==0.18.0\""
|
||||
]
|
||||
},
|
||||
{
|
||||
|
||||
Vendored
+1
-1
@@ -300,7 +300,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q ultralytics"
|
||||
"!pip install -q \"ultralytics<=8.3.40\""
|
||||
]
|
||||
},
|
||||
{
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# ByteTrack
|
||||
|
||||
@@ -1,12 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Data Types Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.datatypes.keypoints_to_detections">keypoints_to_detections</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.datatypes.keypoints_to_detections
|
||||
@@ -17,7 +17,7 @@ https://github.com/roboflow/supervision/assets/26109316/f84db7b5-79e2-4142-a1da-
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
git clone --depth 1 -b develop https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/count_people_in_zone
|
||||
```
|
||||
|
||||
|
||||
@@ -2,4 +2,4 @@ gdown
|
||||
inference==0.9.17
|
||||
supervision>=0.20.0
|
||||
tqdm
|
||||
ultralytics
|
||||
ultralytics<=8.3.40
|
||||
|
||||
@@ -11,7 +11,7 @@ supervision package for multiple tasks such as drawing heatmap annotations, trac
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
git clone --depth 1 -b develop https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/heatmap_and_track
|
||||
```
|
||||
|
||||
|
||||
@@ -1,2 +1,2 @@
|
||||
supervision[assets]==0.19.0
|
||||
ultralytics
|
||||
ultralytics<=8.3.40
|
||||
|
||||
@@ -22,7 +22,7 @@ https://github.com/roboflow/supervision/assets/26109316/d50118c1-2ae4-458d-915a-
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
git clone --depth 1 -b develop https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/speed_estimation
|
||||
```
|
||||
|
||||
|
||||
@@ -16,7 +16,7 @@ https://github.com/roboflow/supervision/assets/26109316/d051cc8a-dd15-41d4-aa36-
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
git clone --depth 1 -b develop https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/time_in_zone
|
||||
```
|
||||
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
opencv-python
|
||||
supervision>=0.20.0
|
||||
ultralytics
|
||||
ultralytics<=8.3.40
|
||||
inference==0.9.17
|
||||
pytube
|
||||
|
||||
@@ -10,7 +10,7 @@ detection and Supervision for tracking and annotation.
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
git clone --depth 1 -b develop https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/tracking
|
||||
```
|
||||
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
inference==0.9.17
|
||||
supervision==0.19.0
|
||||
tqdm
|
||||
ultralytics
|
||||
ultralytics<=8.3.40
|
||||
|
||||
@@ -13,7 +13,7 @@ https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
git clone --depth 1 -b develop https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/traffic_analysis
|
||||
```
|
||||
|
||||
|
||||
@@ -2,4 +2,4 @@ gdown
|
||||
inference==0.9.17
|
||||
supervision>=0.20.0
|
||||
tqdm
|
||||
ultralytics
|
||||
ultralytics<=8.3.40
|
||||
|
||||
+4
-3
@@ -42,6 +42,7 @@ nav:
|
||||
- Detect Small Objects: how_to/detect_small_objects.md
|
||||
- Track Objects on Video: how_to/track_objects.md
|
||||
- Process Datasets: how_to/process_datasets.md
|
||||
- Benchmark a Model: how_to/benchmark_a_model.md
|
||||
|
||||
- Reference - Code API:
|
||||
- Detection and Segmentation:
|
||||
@@ -66,6 +67,7 @@ nav:
|
||||
- Utils: datasets/utils.md
|
||||
- Metrics:
|
||||
- mAP: metrics/mean_average_precision.md
|
||||
- mAR: metrics/mean_average_recall.md
|
||||
- Precision: metrics/precision.md
|
||||
- Recall: metrics/recall.md
|
||||
- F1 Score: metrics/f1_score.md
|
||||
@@ -79,7 +81,6 @@ nav:
|
||||
- File: utils/file.md
|
||||
- Draw: utils/draw.md
|
||||
- Geometry: utils/geometry.md
|
||||
- Datatypes: utils/datatypes.md
|
||||
- Assets: assets.md
|
||||
- Cookbooks: cookbooks.md
|
||||
- Cheatsheet: https://roboflow.github.io/cheatsheet-supervision/
|
||||
@@ -177,8 +178,8 @@ markdown_extensions:
|
||||
anchor_linenums: true
|
||||
|
||||
extra_javascript:
|
||||
- "https://widget.kapa.ai/kapa-widget.bundle.js"
|
||||
- "javascripts/init_kapa_widget.js"
|
||||
# disabled until 0.27.0, so we can test its functionality
|
||||
# - "javascripts/init_kapa_widget.js"
|
||||
- "javascripts/cookbooks-card.js"
|
||||
- "https://cdnjs.cloudflare.com/ajax/libs/dompurify/3.0.8/purify.min.js"
|
||||
|
||||
|
||||
Generated
+1009
-709
File diff suppressed because it is too large
Load Diff
+35
-14
@@ -1,6 +1,6 @@
|
||||
[tool.poetry]
|
||||
name = "supervision"
|
||||
version = "0.25.0rc2"
|
||||
version = "0.26.0rc2"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
authors = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
maintainers = [
|
||||
@@ -43,11 +43,14 @@ classifiers = [
|
||||
|
||||
[tool.poetry.dependencies]
|
||||
python = "^3.8"
|
||||
|
||||
# For Python versions 3.13 and above, use numpy versions 2.1.0,
|
||||
# required for poetry to not fail.
|
||||
numpy = [
|
||||
{ version = ">=1.21.2,<1.23.3", python = "<=3.10" },
|
||||
{ version = ">=1.23.3", python = ">3.10" },
|
||||
{ version = ">=1.21.2", python = "<3.13" },
|
||||
{ version = ">=2.1.0", python = ">=3.13" },
|
||||
]
|
||||
|
||||
scipy = [
|
||||
{ version = "1.10.0", python = "<3.9" },
|
||||
{ version = "^1.10.0", python = ">=3.9" },
|
||||
@@ -62,29 +65,44 @@ scipy = [
|
||||
# For Python 3.8 and above, we use version 1.0.7 or higher, as it is the lowest major version that supports Python 3.8.
|
||||
# For Python 3.13 and above, we use version 1.3.0 or higher, as it is the first version that explicitly supports Python 3.13.
|
||||
contourpy = [
|
||||
{ version = ">=1.0.7", python = ">=3.8" },
|
||||
{ version = ">=1.0.7", python = ">=3.8,<3.13" },
|
||||
{ version = ">=1.3.0", python = ">=3.13" },
|
||||
]
|
||||
|
||||
matplotlib = ">=3.6.0"
|
||||
matplotlib = [
|
||||
{ version = ">=3.6.0,<3.8.0", python = "3.8" },
|
||||
{ version = ">=3.6.0", python = ">=3.9" },
|
||||
{ version = ">=3.7.3", python = ">=3.12" },
|
||||
{ version = ">=3.9.2", python = ">=3.13" },
|
||||
]
|
||||
|
||||
|
||||
pyyaml = ">=5.3"
|
||||
defusedxml = "^0.7.1"
|
||||
pillow = ">=9.4"
|
||||
requests = { version = ">=2.26.0,<=2.32.3", optional = true }
|
||||
tqdm = { version = ">=4.62.3,<=4.66.6", optional = true }
|
||||
requests = ">=2.26.0"
|
||||
tqdm = ">=4.62.3"
|
||||
# pandas: picked lowest major version that supports Python 3.8
|
||||
pandas = { version = ">=2.0.0", optional = true }
|
||||
pandas-stubs = { version = ">=2.0.0.230412", optional = true }
|
||||
# pandas 2.2.3 has been released with support for Python 3.13
|
||||
pandas = [
|
||||
{ version = ">=2.0.0", python = "<3.13", optional = true },
|
||||
{ version = ">=2.2.3", python = ">=3.13", optional = true },
|
||||
]
|
||||
|
||||
opencv-python = ">=4.5.5.64"
|
||||
|
||||
[tool.poetry.extras]
|
||||
assets = ["requests", "tqdm"]
|
||||
metrics = ["pandas", "pandas-stubs"]
|
||||
metrics = ["pandas"]
|
||||
|
||||
[tool.poetry.group.test.dependencies]
|
||||
pytest = ">=7.2.2,<9.0.0"
|
||||
pytest-md = "^0.2.0"
|
||||
pytest-emoji = "^0.2.0"
|
||||
|
||||
[tool.poetry.group.dev.dependencies]
|
||||
twine = "^5.1.1"
|
||||
twine = ">=5.1.1,<7.0.0"
|
||||
pytest = ">=7.2.2,<9.0.0"
|
||||
wheel = ">=0.40,<0.45"
|
||||
wheel = ">=0.40,<0.46"
|
||||
build = ">=0.10,<1.3"
|
||||
ruff = ">=0.1.0"
|
||||
mypy = "^1.4.1"
|
||||
@@ -105,7 +123,7 @@ mkdocstrings = ">=0.25.2,<0.27.0"
|
||||
mkdocstrings-python = "^1.10.9"
|
||||
mike = "^2.0.0"
|
||||
# For Documentation Development use Python 3.10 or above
|
||||
# Use Latest mkdocs-jupyter min 0.24.6 for Jupyter Notebook Theme support
|
||||
# Use Latest mkdocs-jupyter min 0.24.6 for Jupyter Notebook Theme support
|
||||
mkdocs-jupyter = "^0.24.3"
|
||||
mkdocs-git-committers-plugin-2 = "^2.4.1"
|
||||
mkdocs-git-revision-date-localized-plugin = "^1.2.4"
|
||||
@@ -118,7 +136,10 @@ types-pyyaml = "^6.0.12.20240808"
|
||||
types-cffi = "^1.16.0.20240331"
|
||||
types-requests = "^2.32.0.20240712"
|
||||
types-tqdm = "^4.66.0.20240417"
|
||||
pandas-stubs = ">=2.0.0.230412"
|
||||
|
||||
[tool.poetry.group.build.dependencies]
|
||||
twine = ">=5.1.1,<7.0.0"
|
||||
|
||||
[tool.bandit]
|
||||
target = ["test", "supervision"]
|
||||
|
||||
+109
-1
@@ -14,6 +14,7 @@ from supervision.annotators.core import (
|
||||
BoxCornerAnnotator,
|
||||
CircleAnnotator,
|
||||
ColorAnnotator,
|
||||
ComparisonAnnotator,
|
||||
CropAnnotator,
|
||||
DotAnnotator,
|
||||
EllipseAnnotator,
|
||||
@@ -76,6 +77,7 @@ from supervision.detection.utils import (
|
||||
scale_boxes,
|
||||
xcycwh_to_xyxy,
|
||||
xywh_to_xyxy,
|
||||
xyxy_to_polygons,
|
||||
)
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import (
|
||||
@@ -100,7 +102,6 @@ from supervision.keypoint.core import KeyPoints
|
||||
from supervision.metrics.detection import ConfusionMatrix, MeanAveragePrecision
|
||||
from supervision.tracker.byte_tracker.core import ByteTrack
|
||||
from supervision.utils.conversion import cv2_to_pillow, pillow_to_cv2
|
||||
from supervision.utils.datatypes import keypoints_to_detections
|
||||
from supervision.utils.file import list_files_with_extensions
|
||||
from supervision.utils.image import (
|
||||
ImageSink,
|
||||
@@ -119,3 +120,110 @@ from supervision.utils.video import (
|
||||
get_video_frames_generator,
|
||||
process_video,
|
||||
)
|
||||
|
||||
__all__ = [
|
||||
"LMM",
|
||||
"BackgroundOverlayAnnotator",
|
||||
"BaseDataset",
|
||||
"BlurAnnotator",
|
||||
"BoundingBoxAnnotator",
|
||||
"BoxAnnotator",
|
||||
"BoxCornerAnnotator",
|
||||
"ByteTrack",
|
||||
"CSVSink",
|
||||
"CircleAnnotator",
|
||||
"ClassificationDataset",
|
||||
"Classifications",
|
||||
"Color",
|
||||
"ColorAnnotator",
|
||||
"ColorLookup",
|
||||
"ColorPalette",
|
||||
"ComparisonAnnotator",
|
||||
"ConfusionMatrix",
|
||||
"CropAnnotator",
|
||||
"DetectionDataset",
|
||||
"Detections",
|
||||
"DetectionsSmoother",
|
||||
"DotAnnotator",
|
||||
"EdgeAnnotator",
|
||||
"EllipseAnnotator",
|
||||
"FPSMonitor",
|
||||
"HaloAnnotator",
|
||||
"HeatMapAnnotator",
|
||||
"IconAnnotator",
|
||||
"ImageSink",
|
||||
"InferenceSlicer",
|
||||
"JSONSink",
|
||||
"KeyPoints",
|
||||
"LabelAnnotator",
|
||||
"LineZone",
|
||||
"LineZoneAnnotator",
|
||||
"LineZoneAnnotatorMulticlass",
|
||||
"MaskAnnotator",
|
||||
"MeanAveragePrecision",
|
||||
"OrientedBoxAnnotator",
|
||||
"OverlapFilter",
|
||||
"PercentageBarAnnotator",
|
||||
"PixelateAnnotator",
|
||||
"Point",
|
||||
"PolygonAnnotator",
|
||||
"PolygonZone",
|
||||
"PolygonZoneAnnotator",
|
||||
"Position",
|
||||
"Rect",
|
||||
"RichLabelAnnotator",
|
||||
"RoundBoxAnnotator",
|
||||
"TraceAnnotator",
|
||||
"TriangleAnnotator",
|
||||
"VertexAnnotator",
|
||||
"VertexLabelAnnotator",
|
||||
"VideoInfo",
|
||||
"VideoSink",
|
||||
"box_iou_batch",
|
||||
"box_non_max_merge",
|
||||
"box_non_max_suppression",
|
||||
"calculate_masks_centroids",
|
||||
"calculate_optimal_line_thickness",
|
||||
"calculate_optimal_text_scale",
|
||||
"clip_boxes",
|
||||
"contains_holes",
|
||||
"contains_multiple_segments",
|
||||
"create_tiles",
|
||||
"crop_image",
|
||||
"cv2_to_pillow",
|
||||
"draw_filled_polygon",
|
||||
"draw_filled_rectangle",
|
||||
"draw_image",
|
||||
"draw_line",
|
||||
"draw_polygon",
|
||||
"draw_rectangle",
|
||||
"draw_text",
|
||||
"filter_polygons_by_area",
|
||||
"get_polygon_center",
|
||||
"get_video_frames_generator",
|
||||
"letterbox_image",
|
||||
"list_files_with_extensions",
|
||||
"mask_iou_batch",
|
||||
"mask_non_max_suppression",
|
||||
"mask_to_polygons",
|
||||
"mask_to_rle",
|
||||
"mask_to_xyxy",
|
||||
"move_boxes",
|
||||
"move_masks",
|
||||
"oriented_box_iou_batch",
|
||||
"overlay_image",
|
||||
"pad_boxes",
|
||||
"pillow_to_cv2",
|
||||
"plot_image",
|
||||
"plot_images_grid",
|
||||
"polygon_to_mask",
|
||||
"polygon_to_xyxy",
|
||||
"process_video",
|
||||
"resize_image",
|
||||
"rle_to_mask",
|
||||
"scale_boxes",
|
||||
"scale_image",
|
||||
"xcycwh_to_xyxy",
|
||||
"xywh_to_xyxy",
|
||||
"xyxy_to_polygons",
|
||||
]
|
||||
|
||||
+522
-118
@@ -16,10 +16,16 @@ from supervision.annotators.utils import (
|
||||
)
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD, ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import clip_boxes, mask_to_polygons
|
||||
from supervision.detection.utils import (
|
||||
clip_boxes,
|
||||
mask_to_polygons,
|
||||
polygon_to_mask,
|
||||
spread_out_boxes,
|
||||
xyxy_to_polygons,
|
||||
)
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import draw_polygon
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.draw.utils import draw_polygon, draw_rounded_rectangle, draw_text
|
||||
from supervision.geometry.core import Point, Position, Rect
|
||||
from supervision.utils.conversion import (
|
||||
ensure_cv2_image_for_annotation,
|
||||
ensure_pil_image_for_annotation,
|
||||
@@ -32,6 +38,8 @@ from supervision.utils.image import (
|
||||
)
|
||||
from supervision.utils.internal import deprecated
|
||||
|
||||
CV2_FONT = cv2.FONT_HERSHEY_SIMPLEX
|
||||
|
||||
|
||||
class BoxAnnotator(BaseAnnotator):
|
||||
"""
|
||||
@@ -1054,6 +1062,7 @@ class LabelAnnotator(BaseAnnotator):
|
||||
text_position: Position = Position.TOP_LEFT,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
border_radius: int = 0,
|
||||
smart_position: bool = False,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
@@ -1070,6 +1079,7 @@ class LabelAnnotator(BaseAnnotator):
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
border_radius (int): The radius to apply round edges. If the selected
|
||||
value is higher than the lower dimension, width or height, is clipped.
|
||||
smart_position (bool): Spread out the labels to avoid overlapping.
|
||||
"""
|
||||
self.border_radius: int = border_radius
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -1079,6 +1089,7 @@ class LabelAnnotator(BaseAnnotator):
|
||||
self.text_padding: int = text_padding
|
||||
self.text_anchor: Position = text_position
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
self.smart_position = smart_position
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
def annotate(
|
||||
@@ -1128,11 +1139,29 @@ class LabelAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
|
||||
assert isinstance(scene, np.ndarray)
|
||||
font = cv2.FONT_HERSHEY_SIMPLEX
|
||||
anchors_coordinates = detections.get_anchors_coordinates(
|
||||
anchor=self.text_anchor
|
||||
).astype(int)
|
||||
self._validate_labels(labels, detections)
|
||||
|
||||
labels = self._get_labels_text(detections, labels)
|
||||
label_properties = self._get_label_properties(detections, labels)
|
||||
|
||||
if self.smart_position:
|
||||
xyxy = label_properties[:, :4]
|
||||
xyxy = spread_out_boxes(xyxy)
|
||||
label_properties[:, :4] = xyxy
|
||||
|
||||
self._draw_labels(
|
||||
scene=scene,
|
||||
labels=labels,
|
||||
label_properties=label_properties,
|
||||
detections=detections,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
def _validate_labels(self, labels: Optional[List[str]], detections: Detections):
|
||||
if labels is not None and len(labels) != len(detections):
|
||||
raise ValueError(
|
||||
f"The number of labels ({len(labels)}) does not match the "
|
||||
@@ -1140,72 +1169,121 @@ class LabelAnnotator(BaseAnnotator):
|
||||
f"should have exactly 1 label."
|
||||
)
|
||||
|
||||
for detection_idx, center_coordinates in enumerate(anchors_coordinates):
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=(
|
||||
self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup
|
||||
),
|
||||
)
|
||||
def _get_label_properties(
|
||||
self,
|
||||
detections: Detections,
|
||||
labels: List[str],
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Calculate the numerical properties required to draw the labels on the image.
|
||||
|
||||
text_color = resolve_color(
|
||||
color=self.text_color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=(
|
||||
self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup
|
||||
),
|
||||
)
|
||||
Returns:
|
||||
(np.ndarray): An array of label properties, containing columns:
|
||||
`min_x`, `min_y`, `max_x`, `max_y`, `padded_text_height`.
|
||||
"""
|
||||
label_properties = []
|
||||
anchors_coordinates = detections.get_anchors_coordinates(
|
||||
anchor=self.text_anchor
|
||||
).astype(int)
|
||||
|
||||
if labels is not None:
|
||||
text = labels[detection_idx]
|
||||
elif CLASS_NAME_DATA_FIELD in detections.data:
|
||||
text = detections.data[CLASS_NAME_DATA_FIELD][detection_idx]
|
||||
elif detections.class_id is not None:
|
||||
text = str(detections.class_id[detection_idx])
|
||||
else:
|
||||
text = str(detection_idx)
|
||||
|
||||
text_w, text_h = cv2.getTextSize(
|
||||
text=text,
|
||||
fontFace=font,
|
||||
for label, center_coords in zip(labels, anchors_coordinates):
|
||||
(text_w, text_h) = cv2.getTextSize(
|
||||
text=label,
|
||||
fontFace=CV2_FONT,
|
||||
fontScale=self.text_scale,
|
||||
thickness=self.text_thickness,
|
||||
)[0]
|
||||
text_w_padded = text_w + 2 * self.text_padding
|
||||
text_h_padded = text_h + 2 * self.text_padding
|
||||
|
||||
width_padded = text_w + 2 * self.text_padding
|
||||
height_padded = text_h + 2 * self.text_padding
|
||||
|
||||
text_background_xyxy = resolve_text_background_xyxy(
|
||||
center_coordinates=tuple(center_coordinates),
|
||||
text_wh=(text_w_padded, text_h_padded),
|
||||
center_coordinates=tuple(center_coords),
|
||||
text_wh=(width_padded, height_padded),
|
||||
position=self.text_anchor,
|
||||
)
|
||||
|
||||
text_x = text_background_xyxy[0] + self.text_padding
|
||||
text_y = text_background_xyxy[1] + self.text_padding + text_h
|
||||
label_properties.append(
|
||||
[
|
||||
*text_background_xyxy,
|
||||
text_h,
|
||||
]
|
||||
)
|
||||
|
||||
return np.array(label_properties).reshape(-1, 5)
|
||||
|
||||
@staticmethod
|
||||
def _get_labels_text(
|
||||
detections: Detections, custom_labels: Optional[List[str]]
|
||||
) -> List[str]:
|
||||
if custom_labels is not None:
|
||||
return custom_labels
|
||||
|
||||
labels = []
|
||||
for idx in range(len(detections)):
|
||||
if CLASS_NAME_DATA_FIELD in detections.data:
|
||||
labels.append(detections.data[CLASS_NAME_DATA_FIELD][idx])
|
||||
elif detections.class_id is not None:
|
||||
labels.append(str(detections.class_id[idx]))
|
||||
else:
|
||||
labels.append(str(idx))
|
||||
return labels
|
||||
|
||||
def _draw_labels(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
labels: List[str],
|
||||
label_properties: np.ndarray,
|
||||
detections: Detections,
|
||||
custom_color_lookup: Optional[np.ndarray],
|
||||
) -> None:
|
||||
assert len(labels) == len(label_properties) == len(detections), (
|
||||
f"Number of label properties ({len(label_properties)}), "
|
||||
f"labels ({len(labels)}) and detections ({len(detections)}) "
|
||||
"do not match."
|
||||
)
|
||||
|
||||
color_lookup = (
|
||||
custom_color_lookup
|
||||
if custom_color_lookup is not None
|
||||
else self.color_lookup
|
||||
)
|
||||
|
||||
for idx, label_property in enumerate(label_properties):
|
||||
background_color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
detection_idx=idx,
|
||||
color_lookup=color_lookup,
|
||||
)
|
||||
text_color = resolve_color(
|
||||
color=self.text_color,
|
||||
detections=detections,
|
||||
detection_idx=idx,
|
||||
color_lookup=color_lookup,
|
||||
)
|
||||
|
||||
box_xyxy = label_property[:4]
|
||||
text_height_padded = label_property[4]
|
||||
self.draw_rounded_rectangle(
|
||||
scene=scene,
|
||||
xyxy=text_background_xyxy,
|
||||
color=color.as_bgr(),
|
||||
xyxy=box_xyxy,
|
||||
color=background_color.as_bgr(),
|
||||
border_radius=self.border_radius,
|
||||
)
|
||||
|
||||
text_x = box_xyxy[0] + self.text_padding
|
||||
text_y = box_xyxy[1] + self.text_padding + text_height_padded
|
||||
cv2.putText(
|
||||
img=scene,
|
||||
text=text,
|
||||
text=labels[idx],
|
||||
org=(text_x, text_y),
|
||||
fontFace=font,
|
||||
fontFace=CV2_FONT,
|
||||
fontScale=self.text_scale,
|
||||
color=text_color.as_bgr(),
|
||||
thickness=self.text_thickness,
|
||||
lineType=cv2.LINE_AA,
|
||||
)
|
||||
return scene
|
||||
|
||||
@staticmethod
|
||||
def draw_rounded_rectangle(
|
||||
@@ -1266,6 +1344,7 @@ class RichLabelAnnotator(BaseAnnotator):
|
||||
text_position: Position = Position.TOP_LEFT,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
border_radius: int = 0,
|
||||
smart_position: bool = False,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
@@ -1282,6 +1361,7 @@ class RichLabelAnnotator(BaseAnnotator):
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
border_radius (int): The radius to apply round edges. If the selected
|
||||
value is higher than the lower dimension, width or height, is clipped.
|
||||
smart_position (bool): Spread out the labels to avoid overlapping.
|
||||
"""
|
||||
self.color = color
|
||||
self.text_color = text_color
|
||||
@@ -1289,14 +1369,8 @@ class RichLabelAnnotator(BaseAnnotator):
|
||||
self.text_anchor = text_position
|
||||
self.color_lookup = color_lookup
|
||||
self.border_radius = border_radius
|
||||
if font_path is not None:
|
||||
try:
|
||||
self.font = ImageFont.truetype(font_path, font_size)
|
||||
except OSError:
|
||||
print(f"Font path '{font_path}' not found. Using PIL's default font.")
|
||||
self.font = self._load_default_font(font_size)
|
||||
else:
|
||||
self.font = self._load_default_font(font_size)
|
||||
self.smart_position = smart_position
|
||||
self.font = self._load_font(font_size, font_path)
|
||||
|
||||
@ensure_pil_image_for_annotation
|
||||
def annotate(
|
||||
@@ -1346,88 +1420,157 @@ class RichLabelAnnotator(BaseAnnotator):
|
||||
|
||||
"""
|
||||
assert isinstance(scene, Image.Image)
|
||||
self._validate_labels(labels, detections)
|
||||
|
||||
draw = ImageDraw.Draw(scene)
|
||||
anchors_coordinates = detections.get_anchors_coordinates(
|
||||
anchor=self.text_anchor
|
||||
).astype(int)
|
||||
labels = self._get_labels_text(detections, labels)
|
||||
label_properties = self._get_label_properties(draw, detections, labels)
|
||||
|
||||
if self.smart_position:
|
||||
xyxy = label_properties[:, :4]
|
||||
xyxy = spread_out_boxes(xyxy)
|
||||
label_properties[:, :4] = xyxy
|
||||
|
||||
self._draw_labels(
|
||||
draw=draw,
|
||||
labels=labels,
|
||||
label_properties=label_properties,
|
||||
detections=detections,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
def _validate_labels(self, labels: Optional[List[str]], detections: Detections):
|
||||
if labels is not None and len(labels) != len(detections):
|
||||
raise ValueError(
|
||||
f"The number of labels provided ({len(labels)}) does not match the "
|
||||
f"number of detections ({len(detections)}). Each detection should have "
|
||||
f"a corresponding label."
|
||||
)
|
||||
for detection_idx, center_coordinates in enumerate(anchors_coordinates):
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=(
|
||||
self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup
|
||||
),
|
||||
f"The number of labels ({len(labels)}) does not match the "
|
||||
f"number of detections ({len(detections)}). Each detection "
|
||||
f"should have exactly 1 label."
|
||||
)
|
||||
|
||||
text_color = resolve_color(
|
||||
color=self.text_color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=(
|
||||
self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup
|
||||
),
|
||||
def _get_label_properties(
|
||||
self, draw, detections: Detections, labels: List[str]
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Calculate the numerical properties required to draw the labels on the image.
|
||||
|
||||
Returns:
|
||||
(np.ndarray): An array of label properties, containing columns:
|
||||
`min_x`, `min_y`, `max_x`, `max_y`, `text_left_coordinate`,
|
||||
`text_top_coordinate`. The first 4 values are already padded
|
||||
with `text_padding`.
|
||||
"""
|
||||
label_properties = []
|
||||
|
||||
anchor_coordinates = detections.get_anchors_coordinates(
|
||||
anchor=self.text_anchor
|
||||
).astype(int)
|
||||
|
||||
for label, center_coords in zip(labels, anchor_coordinates):
|
||||
text_left, text_top, text_right, text_bottom = draw.textbbox(
|
||||
(0, 0), label, font=self.font
|
||||
)
|
||||
text_width = text_right - text_left
|
||||
text_height = text_bottom - text_top
|
||||
width_padded = text_width + 2 * self.text_padding
|
||||
height_padded = text_height + 2 * self.text_padding
|
||||
|
||||
if labels is not None:
|
||||
text = labels[detection_idx]
|
||||
elif CLASS_NAME_DATA_FIELD in detections.data:
|
||||
text = detections.data[CLASS_NAME_DATA_FIELD][detection_idx]
|
||||
elif detections.class_id is not None:
|
||||
text = str(detections.class_id[detection_idx])
|
||||
else:
|
||||
text = str(detection_idx)
|
||||
|
||||
left, top, right, bottom = draw.textbbox((0, 0), text, font=self.font)
|
||||
text_width = right - left
|
||||
text_height = bottom - top
|
||||
text_w_padded = text_width + 2 * self.text_padding
|
||||
text_h_padded = text_height + 2 * self.text_padding
|
||||
text_background_xyxy = resolve_text_background_xyxy(
|
||||
center_coordinates=tuple(center_coordinates),
|
||||
text_wh=(text_w_padded, text_h_padded),
|
||||
center_coordinates=tuple(center_coords),
|
||||
text_wh=(width_padded, height_padded),
|
||||
position=self.text_anchor,
|
||||
)
|
||||
|
||||
text_x = text_background_xyxy[0] + self.text_padding - left
|
||||
text_y = text_background_xyxy[1] + self.text_padding - top
|
||||
label_properties.append([*text_background_xyxy, text_left, text_top])
|
||||
|
||||
return np.array(label_properties).reshape(-1, 6)
|
||||
|
||||
@staticmethod
|
||||
def _get_labels_text(
|
||||
detections: Detections, custom_labels: Optional[List[str]]
|
||||
) -> List[str]:
|
||||
if custom_labels is not None:
|
||||
return custom_labels
|
||||
|
||||
labels = []
|
||||
for idx in range(len(detections)):
|
||||
if CLASS_NAME_DATA_FIELD in detections.data:
|
||||
labels.append(detections.data[CLASS_NAME_DATA_FIELD][idx])
|
||||
elif detections.class_id is not None:
|
||||
labels.append(str(detections.class_id[idx]))
|
||||
else:
|
||||
labels.append(str(idx))
|
||||
return labels
|
||||
|
||||
def _draw_labels(
|
||||
self,
|
||||
draw,
|
||||
labels: List[str],
|
||||
label_properties: np.ndarray,
|
||||
detections: Detections,
|
||||
custom_color_lookup: Optional[np.ndarray],
|
||||
) -> None:
|
||||
assert len(labels) == len(label_properties) == len(detections), (
|
||||
f"Number of label properties ({len(label_properties)}), "
|
||||
f"labels ({len(labels)}) and detections ({len(detections)}) "
|
||||
"do not match."
|
||||
)
|
||||
color_lookup = (
|
||||
custom_color_lookup
|
||||
if custom_color_lookup is not None
|
||||
else self.color_lookup
|
||||
)
|
||||
|
||||
for idx, label_property in enumerate(label_properties):
|
||||
background_color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
detection_idx=idx,
|
||||
color_lookup=color_lookup,
|
||||
)
|
||||
text_color = resolve_color(
|
||||
color=self.text_color,
|
||||
detections=detections,
|
||||
detection_idx=idx,
|
||||
color_lookup=color_lookup,
|
||||
)
|
||||
|
||||
box_xyxy = label_property[:4]
|
||||
text_left = label_property[4]
|
||||
text_top = label_property[5]
|
||||
label_x_position = box_xyxy[0] + self.text_padding - text_left
|
||||
label_y_position = box_xyxy[1] + self.text_padding - text_top
|
||||
|
||||
draw.rounded_rectangle(
|
||||
text_background_xyxy,
|
||||
tuple(box_xyxy),
|
||||
radius=self.border_radius,
|
||||
fill=color.as_rgb(),
|
||||
fill=background_color.as_rgb(),
|
||||
outline=None,
|
||||
)
|
||||
draw.text(
|
||||
xy=(text_x, text_y),
|
||||
text=text,
|
||||
xy=(label_x_position, label_y_position),
|
||||
text=labels[idx],
|
||||
font=self.font,
|
||||
fill=text_color.as_rgb(),
|
||||
)
|
||||
return scene
|
||||
|
||||
@staticmethod
|
||||
def _load_default_font(size):
|
||||
"""
|
||||
PIL either loads a font that accepts a size (e.g. on my machine)
|
||||
or raises an error saying `load_default` does not accept arguments
|
||||
(e.g. in Colab).
|
||||
"""
|
||||
def _load_font(font_size: int, font_path: Optional[str]):
|
||||
def load_default_font(size):
|
||||
try:
|
||||
return ImageFont.load_default(size)
|
||||
except TypeError:
|
||||
return ImageFont.load_default()
|
||||
|
||||
if font_path is None:
|
||||
return load_default_font(font_size)
|
||||
|
||||
try:
|
||||
font = ImageFont.load_default(size)
|
||||
except TypeError:
|
||||
font = ImageFont.load_default()
|
||||
return font
|
||||
return ImageFont.truetype(font_path, font_size)
|
||||
except OSError:
|
||||
print(f"Font path '{font_path}' not found. Using PIL's default font.")
|
||||
return load_default_font(font_size)
|
||||
|
||||
|
||||
class IconAnnotator(BaseAnnotator):
|
||||
@@ -2390,6 +2533,9 @@ class CropAnnotator(BaseAnnotator):
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
crops = [
|
||||
@@ -2546,3 +2692,261 @@ class BackgroundOverlayAnnotator(BaseAnnotator):
|
||||
|
||||
np.copyto(scene, colored_mask)
|
||||
return scene
|
||||
|
||||
|
||||
class ComparisonAnnotator:
|
||||
"""
|
||||
Highlights the differences between two sets of detections.
|
||||
Useful for comparing results from two different models, or the difference
|
||||
between a ground truth and a prediction.
|
||||
|
||||
If present, uses the oriented bounding box data.
|
||||
Otherwise, if present, uses a mask.
|
||||
Otherwise, uses the bounding box data.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color_1: Color = Color.RED,
|
||||
color_2: Color = Color.GREEN,
|
||||
color_overlap: Color = Color.BLUE,
|
||||
*,
|
||||
opacity: float = 0.75,
|
||||
label_1: str = "",
|
||||
label_2: str = "",
|
||||
label_overlap: str = "",
|
||||
label_scale: float = 1.0,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
color_1 (Color): Color of areas only present in the first set of
|
||||
detections.
|
||||
color_2 (Color): Color of areas only present in the second set of
|
||||
detections.
|
||||
color_overlap (Color): Color of areas present in both sets of detections.
|
||||
opacity (float): Annotator opacity, from `0` to `1`.
|
||||
label_1 (str): Label for the first set of detections.
|
||||
label_2 (str): Label for the second set of detections.
|
||||
label_overlap (str): Label for areas present in both sets of detections.
|
||||
label_scale (float): Controls how large the labels are.
|
||||
"""
|
||||
|
||||
self.color_1 = color_1
|
||||
self.color_2 = color_2
|
||||
self.color_overlap = color_overlap
|
||||
|
||||
self.opacity = opacity
|
||||
self.label_1 = label_1
|
||||
self.label_2 = label_2
|
||||
self.label_overlap = label_overlap
|
||||
self.label_scale = label_scale
|
||||
self.text_thickness = int(self.label_scale + 1.2)
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
def annotate(
|
||||
self, scene: ImageType, detections_1: Detections, detections_2: Detections
|
||||
) -> ImageType:
|
||||
"""
|
||||
Highlights the differences between two sets of detections.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where detections will be drawn.
|
||||
`ImageType` is a flexible type, accepting either `numpy.ndarray`
|
||||
or `PIL.Image.Image`.
|
||||
detections_1 (Detections): The first set of detections or predictions.
|
||||
detections_2 (Detections): The second set of detections to compare or
|
||||
ground truth.
|
||||
|
||||
Returns:
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections_1 = sv.Detections(...)
|
||||
detections_2 = sv.Detections(...)
|
||||
|
||||
comparison_annotator = sv.ComparisonAnnotator()
|
||||
annotated_frame = comparison_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections_1=detections_1,
|
||||
detections_2=detections_2
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if detections_1.is_empty() and detections_2.is_empty():
|
||||
return scene
|
||||
|
||||
use_obb = self._use_obb(detections_1, detections_2)
|
||||
use_mask = self._use_mask(detections_1, detections_2)
|
||||
|
||||
if use_obb:
|
||||
mask_1 = self._mask_from_obb(scene, detections_1)
|
||||
mask_2 = self._mask_from_obb(scene, detections_2)
|
||||
|
||||
elif use_mask:
|
||||
mask_1 = self._mask_from_mask(scene, detections_1)
|
||||
mask_2 = self._mask_from_mask(scene, detections_2)
|
||||
|
||||
else:
|
||||
mask_1 = self._mask_from_xyxy(scene, detections_1)
|
||||
mask_2 = self._mask_from_xyxy(scene, detections_2)
|
||||
|
||||
mask_overlap = mask_1 & mask_2
|
||||
mask_1 = mask_1 & ~mask_overlap
|
||||
mask_2 = mask_2 & ~mask_overlap
|
||||
|
||||
color_layer = np.zeros_like(scene, dtype=np.uint8)
|
||||
color_layer[mask_overlap] = self.color_overlap.as_bgr()
|
||||
color_layer[mask_1] = self.color_1.as_bgr()
|
||||
color_layer[mask_2] = self.color_2.as_bgr()
|
||||
|
||||
scene[mask_overlap] = (1 - self.opacity) * scene[
|
||||
mask_overlap
|
||||
] + self.opacity * color_layer[mask_overlap]
|
||||
scene[mask_1] = (1 - self.opacity) * scene[mask_1] + self.opacity * color_layer[
|
||||
mask_1
|
||||
]
|
||||
scene[mask_2] = (1 - self.opacity) * scene[mask_2] + self.opacity * color_layer[
|
||||
mask_2
|
||||
]
|
||||
|
||||
self._draw_labels(scene)
|
||||
|
||||
return scene
|
||||
|
||||
@staticmethod
|
||||
def _use_obb(detections_1: Detections, detections_2: Detections) -> bool:
|
||||
assert not detections_1.is_empty() or not detections_2.is_empty()
|
||||
is_obb_1 = ORIENTED_BOX_COORDINATES in detections_1.data
|
||||
is_obb_2 = ORIENTED_BOX_COORDINATES in detections_2.data
|
||||
return (
|
||||
(is_obb_1 and is_obb_2)
|
||||
or (is_obb_1 and detections_2.is_empty())
|
||||
or (detections_1.is_empty() and is_obb_2)
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _use_mask(detections_1: Detections, detections_2: Detections) -> bool:
|
||||
assert not detections_1.is_empty() or not detections_2.is_empty()
|
||||
is_mask_1 = detections_1.mask is not None
|
||||
is_mask_2 = detections_2.mask is not None
|
||||
return (
|
||||
(is_mask_1 and is_mask_2)
|
||||
or (is_mask_1 and detections_2.is_empty())
|
||||
or (detections_1.is_empty() and is_mask_2)
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _mask_from_xyxy(scene: np.ndarray, detections: Detections) -> np.ndarray:
|
||||
mask = np.zeros(scene.shape[:2], dtype=np.bool_)
|
||||
if detections.is_empty():
|
||||
return mask
|
||||
|
||||
resolution_wh = scene.shape[1], scene.shape[0]
|
||||
polygons = xyxy_to_polygons(detections.xyxy)
|
||||
|
||||
for polygon in polygons:
|
||||
polygon_mask = polygon_to_mask(polygon, resolution_wh=resolution_wh)
|
||||
mask |= polygon_mask.astype(np.bool_)
|
||||
return mask
|
||||
|
||||
@staticmethod
|
||||
def _mask_from_obb(scene: np.ndarray, detections: Detections) -> np.ndarray:
|
||||
mask = np.zeros(scene.shape[:2], dtype=np.bool_)
|
||||
if detections.is_empty():
|
||||
return mask
|
||||
|
||||
resolution_wh = scene.shape[1], scene.shape[0]
|
||||
|
||||
for polygon in detections.data[ORIENTED_BOX_COORDINATES]:
|
||||
polygon_mask = polygon_to_mask(polygon, resolution_wh=resolution_wh)
|
||||
mask |= polygon_mask.astype(np.bool_)
|
||||
return mask
|
||||
|
||||
@staticmethod
|
||||
def _mask_from_mask(scene: np.ndarray, detections: Detections) -> np.ndarray:
|
||||
mask = np.zeros(scene.shape[:2], dtype=np.bool_)
|
||||
if detections.is_empty():
|
||||
return mask
|
||||
assert detections.mask is not None
|
||||
|
||||
for detections_mask in detections.mask:
|
||||
mask |= detections_mask.astype(np.bool_)
|
||||
return mask
|
||||
|
||||
def _draw_labels(self, scene: np.ndarray) -> None:
|
||||
"""
|
||||
Draw the labels, explaining what each color represents, with automatically
|
||||
computed positions.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image where the labels will be drawn.
|
||||
"""
|
||||
margin = int(50 * self.label_scale)
|
||||
gap = int(40 * self.label_scale)
|
||||
y0 = int(50 * self.label_scale)
|
||||
height = int(50 * self.label_scale)
|
||||
|
||||
marker_size = int(20 * self.label_scale)
|
||||
padding = int(10 * self.label_scale)
|
||||
text_box_corner_radius = int(10 * self.label_scale)
|
||||
marker_corner_radius = int(4 * self.label_scale)
|
||||
text_scale = self.label_scale
|
||||
|
||||
label_color_pairs = [
|
||||
(self.label_1, self.color_1),
|
||||
(self.label_2, self.color_2),
|
||||
(self.label_overlap, self.color_overlap),
|
||||
]
|
||||
|
||||
x0 = margin
|
||||
for text, color in label_color_pairs:
|
||||
if not text:
|
||||
continue
|
||||
|
||||
(text_w, _) = cv2.getTextSize(
|
||||
text=text,
|
||||
fontFace=CV2_FONT,
|
||||
fontScale=self.label_scale,
|
||||
thickness=self.text_thickness,
|
||||
)[0]
|
||||
|
||||
width = text_w + marker_size + padding * 4
|
||||
center_x = x0 + width // 2
|
||||
center_y = y0 + height // 2
|
||||
|
||||
draw_rounded_rectangle(
|
||||
scene=scene,
|
||||
rect=Rect(x=x0, y=y0, width=width, height=height),
|
||||
color=Color.WHITE,
|
||||
border_radius=text_box_corner_radius,
|
||||
)
|
||||
|
||||
draw_rounded_rectangle(
|
||||
scene=scene,
|
||||
rect=Rect(
|
||||
x=x0 + padding,
|
||||
y=center_y - marker_size / 2,
|
||||
width=marker_size,
|
||||
height=marker_size,
|
||||
),
|
||||
color=color,
|
||||
border_radius=marker_corner_radius,
|
||||
)
|
||||
|
||||
draw_text(
|
||||
scene,
|
||||
text,
|
||||
text_anchor=Point(x=center_x + marker_size, y=center_y),
|
||||
text_scale=text_scale,
|
||||
text_thickness=self.text_thickness,
|
||||
)
|
||||
|
||||
x0 += width + gap
|
||||
|
||||
@@ -1,2 +1,4 @@
|
||||
from supervision.assets.downloader import download_assets
|
||||
from supervision.assets.list import VideoAssets
|
||||
|
||||
__all__ = ["VideoAssets", "download_assets"]
|
||||
|
||||
@@ -4,19 +4,10 @@ from pathlib import Path
|
||||
from shutil import copyfileobj
|
||||
from typing import Union
|
||||
|
||||
from supervision.assets.list import VIDEO_ASSETS, VideoAssets
|
||||
from requests import get
|
||||
from tqdm.auto import tqdm
|
||||
|
||||
try:
|
||||
from requests import get
|
||||
from tqdm.auto import tqdm
|
||||
except ImportError:
|
||||
raise ValueError(
|
||||
"\n"
|
||||
"Please install requests and tqdm to download assets \n"
|
||||
"or install supervision with assets \n"
|
||||
"pip install supervision[assets] \n"
|
||||
"\n"
|
||||
)
|
||||
from supervision.assets.list import VIDEO_ASSETS, VideoAssets
|
||||
|
||||
|
||||
def is_md5_hash_matching(filename: str, original_md5_hash: str) -> bool:
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from contextlib import suppress
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any, Dict, Iterator, List, Optional, Tuple, Union
|
||||
|
||||
@@ -117,7 +116,7 @@ class Detections:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
mask: (Optional[np.ndarray]): An array of shape
|
||||
`(n, H, W)` containing the segmentation masks.
|
||||
`(n, H, W)` containing the segmentation masks (`bool` data type).
|
||||
confidence (Optional[np.ndarray]): An array of shape
|
||||
`(n,)` containing the confidence scores of the detections.
|
||||
class_id (Optional[np.ndarray]): An array of shape
|
||||
@@ -606,8 +605,10 @@ class Detections:
|
||||
detections = sv.Detections.from_inference(result)
|
||||
```
|
||||
"""
|
||||
with suppress(AttributeError):
|
||||
if hasattr(roboflow_result, "dict"):
|
||||
roboflow_result = roboflow_result.dict(exclude_none=True, by_alias=True)
|
||||
elif hasattr(roboflow_result, "json"):
|
||||
roboflow_result = roboflow_result.json()
|
||||
xyxy, confidence, class_id, masks, trackers, data = process_roboflow_result(
|
||||
roboflow_result=roboflow_result
|
||||
)
|
||||
@@ -1201,6 +1202,8 @@ class Detections:
|
||||
"""
|
||||
if isinstance(index, str):
|
||||
return self.data.get(index)
|
||||
if self.is_empty():
|
||||
return Detections.empty()
|
||||
if isinstance(index, int):
|
||||
index = [index]
|
||||
return Detections(
|
||||
|
||||
@@ -42,6 +42,10 @@ class LineZone:
|
||||
to inside.
|
||||
out_count (int): The number of objects that have crossed the line from inside
|
||||
to outside.
|
||||
in_count_per_class (Dict[int, int]): Number of objects of each class that have
|
||||
crossed the line from outside to inside.
|
||||
out_count_per_class (Dict[int, int]): Number of objects of each class that have
|
||||
crossed the line from inside to outside.
|
||||
|
||||
Example:
|
||||
```python
|
||||
@@ -75,7 +79,7 @@ class LineZone:
|
||||
Position.BOTTOM_LEFT,
|
||||
Position.BOTTOM_RIGHT,
|
||||
),
|
||||
crossing_acceptance_threshold: int = 1,
|
||||
minimum_crossing_threshold: int = 1,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
@@ -86,7 +90,7 @@ class LineZone:
|
||||
to consider when deciding on whether the detection
|
||||
has passed the line counter or not. By default, this
|
||||
contains the four corners of the detection's bounding box
|
||||
crossing_acceptance_threshold (int): Detection needs to be seen
|
||||
minimum_crossing_threshold (int): Detection needs to be seen
|
||||
on the other side of the line for this many frames to be
|
||||
considered as having crossed the line. This is useful when
|
||||
dealing with unstable bounding boxes or when detections
|
||||
@@ -94,7 +98,7 @@ class LineZone:
|
||||
"""
|
||||
self.vector = Vector(start=start, end=end)
|
||||
self.limits = self._calculate_region_of_interest_limits(vector=self.vector)
|
||||
self.crossing_history_length = max(2, crossing_acceptance_threshold + 1)
|
||||
self.crossing_history_length = max(2, minimum_crossing_threshold + 1)
|
||||
self.crossing_state_history: Dict[int, Deque[bool]] = defaultdict(
|
||||
lambda: deque(maxlen=self.crossing_history_length)
|
||||
)
|
||||
@@ -107,34 +111,18 @@ class LineZone:
|
||||
|
||||
@property
|
||||
def in_count(self) -> int:
|
||||
"""
|
||||
Number of objects that have crossed the line from
|
||||
outside to inside.
|
||||
"""
|
||||
return sum(self._in_count_per_class.values())
|
||||
|
||||
@property
|
||||
def out_count(self) -> int:
|
||||
"""
|
||||
Number of objects that have crossed the line from
|
||||
inside to outside.
|
||||
"""
|
||||
return sum(self._out_count_per_class.values())
|
||||
|
||||
@property
|
||||
def in_count_per_class(self) -> Dict[int, int]:
|
||||
"""
|
||||
Number of objects of each class that have crossed
|
||||
the line from outside to inside.
|
||||
"""
|
||||
return dict(self._in_count_per_class)
|
||||
|
||||
@property
|
||||
def out_count_per_class(self) -> Dict[int, int]:
|
||||
"""
|
||||
Number of objects of each class that have crossed the line
|
||||
from inside to outside.
|
||||
"""
|
||||
return dict(self._out_count_per_class)
|
||||
|
||||
def trigger(self, detections: Detections) -> Tuple[np.ndarray, np.ndarray]:
|
||||
|
||||
+151
-14
@@ -11,6 +11,25 @@ from supervision.geometry.core import Vector
|
||||
MIN_POLYGON_POINT_COUNT = 3
|
||||
|
||||
|
||||
def xyxy_to_polygons(box: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Convert an array of boxes to an array of polygons.
|
||||
Retains the input datatype.
|
||||
|
||||
Args:
|
||||
box (np.ndarray): An array of boxes (N, 4), where each box is represented as a
|
||||
list of four coordinates in the format `(x_min, y_min, x_max, y_max)`.
|
||||
|
||||
Returns:
|
||||
np.ndarray: An array of polygons (N, 4, 2), where each polygon is
|
||||
represented as a list of four coordinates in the format `(x, y)`.
|
||||
"""
|
||||
polygon = np.zeros((box.shape[0], 4, 2), dtype=box.dtype)
|
||||
polygon[:, :, 0] = box[:, [0, 2, 2, 0]]
|
||||
polygon[:, :, 1] = box[:, [1, 1, 3, 3]]
|
||||
return polygon
|
||||
|
||||
|
||||
def polygon_to_mask(polygon: np.ndarray, resolution_wh: Tuple[int, int]) -> np.ndarray:
|
||||
"""Generate a mask from a polygon.
|
||||
|
||||
@@ -701,25 +720,71 @@ def move_masks(
|
||||
masks (npt.NDArray[np.bool_]): A 3D array of binary masks corresponding to the
|
||||
predictions. Shape: `(N, H, W)`, where N is the number of predictions, and
|
||||
H, W are the dimensions of each mask.
|
||||
offset (npt.NDArray[np.int32]): An array of shape `(2,)` containing non-negative
|
||||
int values `[dx, dy]`.
|
||||
offset (npt.NDArray[np.int32]): An array of shape `(2,)` containing int values
|
||||
`[dx, dy]`. Supports both positive and negative values for bidirectional
|
||||
movement.
|
||||
resolution_wh (Tuple[int, int]): The width and height of the desired mask
|
||||
resolution.
|
||||
|
||||
Returns:
|
||||
(npt.NDArray[np.bool_]) repositioned masks, optionally padded to the specified
|
||||
shape.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([[[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False]]], dtype=bool)
|
||||
|
||||
offset = np.array([1, 1])
|
||||
sv.move_masks(mask, offset, resolution_wh=(4, 4))
|
||||
# array([[[False, False, False, False],
|
||||
# [False, False, False, False],
|
||||
# [False, False, True, True],
|
||||
# [False, False, True, True]]], dtype=bool)
|
||||
|
||||
offset = np.array([-2, 2])
|
||||
sv.move_masks(mask, offset, resolution_wh=(4, 4))
|
||||
# array([[[False, False, False, False],
|
||||
# [False, False, False, False],
|
||||
# [False, False, False, False],
|
||||
# [True, False, False, False]]], dtype=bool)
|
||||
```
|
||||
"""
|
||||
|
||||
if offset[0] < 0 or offset[1] < 0:
|
||||
raise ValueError(f"Offset values must be non-negative integers. Got: {offset}")
|
||||
|
||||
mask_array = np.full((masks.shape[0], resolution_wh[1], resolution_wh[0]), False)
|
||||
mask_array[
|
||||
:,
|
||||
offset[1] : masks.shape[1] + offset[1],
|
||||
offset[0] : masks.shape[2] + offset[0],
|
||||
] = masks
|
||||
|
||||
if offset[0] < 0:
|
||||
source_x_start = -offset[0]
|
||||
source_x_end = min(masks.shape[2], resolution_wh[0] - offset[0])
|
||||
destination_x_start = 0
|
||||
destination_x_end = min(resolution_wh[0], masks.shape[2] + offset[0])
|
||||
else:
|
||||
source_x_start = 0
|
||||
source_x_end = min(masks.shape[2], resolution_wh[0] - offset[0])
|
||||
destination_x_start = offset[0]
|
||||
destination_x_end = offset[0] + source_x_end - source_x_start
|
||||
|
||||
if offset[1] < 0:
|
||||
source_y_start = -offset[1]
|
||||
source_y_end = min(masks.shape[1], resolution_wh[1] - offset[1])
|
||||
destination_y_start = 0
|
||||
destination_y_end = min(resolution_wh[1], masks.shape[1] + offset[1])
|
||||
else:
|
||||
source_y_start = 0
|
||||
source_y_end = min(masks.shape[1], resolution_wh[1] - offset[1])
|
||||
destination_y_start = offset[1]
|
||||
destination_y_end = offset[1] + source_y_end - source_y_start
|
||||
|
||||
if source_x_end > source_x_start and source_y_end > source_y_start:
|
||||
mask_array[
|
||||
:,
|
||||
destination_y_start:destination_y_end,
|
||||
destination_x_start:destination_x_end,
|
||||
] = masks[:, source_y_start:source_y_end, source_x_start:source_x_end]
|
||||
|
||||
return mask_array
|
||||
|
||||
@@ -919,11 +984,27 @@ def merge_metadata(metadata_list: List[Dict[str, Any]]) -> Dict[str, Any]:
|
||||
merged_metadata: Dict[str, Any] = {}
|
||||
for metadata in metadata_list:
|
||||
for key, value in metadata.items():
|
||||
if key in merged_metadata:
|
||||
if key not in merged_metadata:
|
||||
merged_metadata[key] = value
|
||||
continue
|
||||
|
||||
other_value = merged_metadata[key]
|
||||
if isinstance(value, np.ndarray) and isinstance(other_value, np.ndarray):
|
||||
if not np.array_equal(merged_metadata[key], value):
|
||||
raise ValueError(
|
||||
f"Conflicting metadata for key: '{key}': "
|
||||
"{type(value)}, {type(other_value)}."
|
||||
)
|
||||
elif isinstance(value, np.ndarray) or isinstance(other_value, np.ndarray):
|
||||
# Since [] == np.array([]).
|
||||
raise ValueError(
|
||||
f"Conflicting metadata for key: '{key}': "
|
||||
"{type(value)}, {type(other_value)}."
|
||||
)
|
||||
else:
|
||||
print("hm")
|
||||
if merged_metadata[key] != value:
|
||||
raise ValueError(f"Conflicting metadata for key: '{key}'.")
|
||||
else:
|
||||
merged_metadata[key] = value
|
||||
|
||||
return merged_metadata
|
||||
|
||||
@@ -1101,3 +1182,59 @@ def cross_product(anchors: np.ndarray, vector: Vector) -> np.ndarray:
|
||||
)
|
||||
vector_start = np.array([vector.start.x, vector.start.y])
|
||||
return np.cross(vector_at_zero, anchors - vector_start)
|
||||
|
||||
|
||||
def spread_out_boxes(
|
||||
xyxy: np.ndarray,
|
||||
max_iterations: int = 100,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Spread out boxes that overlap with each other.
|
||||
|
||||
Args:
|
||||
xyxy: Numpy array of shape (N, 4) where N is the number of boxes.
|
||||
max_iterations: Maximum number of iterations to run the algorithm for.
|
||||
"""
|
||||
if len(xyxy) == 0:
|
||||
return xyxy
|
||||
|
||||
xyxy_padded = pad_boxes(xyxy, px=1)
|
||||
for _ in range(max_iterations):
|
||||
# NxN
|
||||
iou = box_iou_batch(xyxy_padded, xyxy_padded)
|
||||
np.fill_diagonal(iou, 0)
|
||||
if np.all(iou == 0):
|
||||
break
|
||||
|
||||
overlap_mask = iou > 0
|
||||
|
||||
# Nx2
|
||||
centers = (xyxy_padded[:, :2] + xyxy_padded[:, 2:]) / 2
|
||||
|
||||
# NxNx2
|
||||
delta_centers = centers[:, np.newaxis, :] - centers[np.newaxis, :, :]
|
||||
delta_centers *= overlap_mask[:, :, np.newaxis]
|
||||
|
||||
# Nx2
|
||||
delta_sum = np.sum(delta_centers, axis=1)
|
||||
delta_magnitude = np.linalg.norm(delta_sum, axis=1, keepdims=True)
|
||||
direction_vectors = np.divide(
|
||||
delta_sum,
|
||||
delta_magnitude,
|
||||
out=np.zeros_like(delta_sum),
|
||||
where=delta_magnitude != 0,
|
||||
)
|
||||
|
||||
force_vectors = np.sum(iou, axis=1)
|
||||
force_vectors = force_vectors[:, np.newaxis] * direction_vectors
|
||||
|
||||
force_vectors *= 10
|
||||
force_vectors[(force_vectors > 0) & (force_vectors < 2)] = 2
|
||||
force_vectors[(force_vectors < 0) & (force_vectors > -2)] = -2
|
||||
|
||||
force_vectors = force_vectors.astype(int)
|
||||
|
||||
xyxy_padded[:, [0, 1]] += force_vectors
|
||||
xyxy_padded[:, [2, 3]] += force_vectors
|
||||
|
||||
return pad_boxes(xyxy_padded, px=-1)
|
||||
|
||||
@@ -5,10 +5,11 @@ from typing import List, Optional, Tuple, Union
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision import Rect, pad_boxes
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.detection.utils import pad_boxes, spread_out_boxes
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_rounded_rectangle
|
||||
from supervision.geometry.core import Rect
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.keypoint.skeletons import SKELETONS_BY_VERTEX_COUNT
|
||||
from supervision.utils.conversion import ensure_cv2_image_for_annotation
|
||||
@@ -201,6 +202,7 @@ class VertexLabelAnnotator:
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
border_radius: int = 0,
|
||||
smart_position: bool = False,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
@@ -215,6 +217,7 @@ class VertexLabelAnnotator:
|
||||
text_padding (int): The padding around the text.
|
||||
border_radius (int): The radius of the rounded corners of the
|
||||
boxes. Set to a high value to produce circles.
|
||||
smart_position (bool): Spread out the labels to avoid overlap.
|
||||
"""
|
||||
self.border_radius: int = border_radius
|
||||
self.color: Union[Color, List[Color]] = color
|
||||
@@ -222,6 +225,7 @@ class VertexLabelAnnotator:
|
||||
self.text_scale: float = text_scale
|
||||
self.text_thickness: int = text_thickness
|
||||
self.text_padding: int = text_padding
|
||||
self.smart_position = smart_position
|
||||
|
||||
def annotate(
|
||||
self,
|
||||
@@ -356,9 +360,12 @@ class VertexLabelAnnotator:
|
||||
for anchor, label in zip(anchors, labels)
|
||||
]
|
||||
)
|
||||
|
||||
xyxy_padded = pad_boxes(xyxy=xyxy, px=self.text_padding)
|
||||
|
||||
if self.smart_position:
|
||||
xyxy_padded = spread_out_boxes(xyxy_padded)
|
||||
xyxy = pad_boxes(xyxy=xyxy_padded, px=-self.text_padding)
|
||||
|
||||
for text, color, text_color, box, box_padded in zip(
|
||||
labels, colors, text_colors, xyxy, xyxy_padded
|
||||
):
|
||||
|
||||
@@ -1,13 +1,13 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from contextlib import suppress
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any, Dict, Iterator, List, Optional, Tuple, Union
|
||||
from typing import Any, Dict, Iterable, Iterator, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import get_data_item, is_data_equal
|
||||
from supervision.validators import validate_keypoints_fields
|
||||
|
||||
@@ -203,9 +203,10 @@ class KeyPoints:
|
||||
"You can retrieve it like so: inference_result = model.infer(image)[0]"
|
||||
)
|
||||
|
||||
with suppress(AttributeError):
|
||||
if hasattr(inference_result, "dict"):
|
||||
inference_result = inference_result.dict(exclude_none=True, by_alias=True)
|
||||
|
||||
elif hasattr(inference_result, "json"):
|
||||
inference_result = inference_result.json()
|
||||
if not inference_result.get("predictions"):
|
||||
return cls.empty()
|
||||
|
||||
@@ -620,3 +621,67 @@ class KeyPoints:
|
||||
empty_keypoints = KeyPoints.empty()
|
||||
empty_keypoints.data = self.data
|
||||
return self == empty_keypoints
|
||||
|
||||
def as_detections(
|
||||
self, selected_keypoint_indices: Optional[Iterable[int]] = None
|
||||
) -> Detections:
|
||||
"""
|
||||
Convert a KeyPoints object to a Detections object. This
|
||||
approximates the bounding box of the detected object by
|
||||
taking the bounding box that fits all keypoints.
|
||||
|
||||
Arguments:
|
||||
selected_keypoint_indices (Optional[Iterable[int]]): The
|
||||
indices of the keypoints to include in the bounding box
|
||||
calculation. This helps focus on a subset of keypoints,
|
||||
e.g. when some are occluded. Captures all keypoints by default.
|
||||
|
||||
Returns:
|
||||
detections (Detections): The converted detections object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
keypoints = sv.KeyPoints.from_inference(...)
|
||||
detections = keypoints.as_detections()
|
||||
```
|
||||
"""
|
||||
if self.is_empty():
|
||||
return Detections.empty()
|
||||
|
||||
detections_list = []
|
||||
for i, xy in enumerate(self.xy):
|
||||
if selected_keypoint_indices:
|
||||
xy = xy[selected_keypoint_indices]
|
||||
|
||||
# [0, 0] used by some frameworks to indicate missing keypoints
|
||||
xy = xy[~np.all(xy == 0, axis=1)]
|
||||
if len(xy) == 0:
|
||||
xyxy = np.array([[0, 0, 0, 0]], dtype=np.float32)
|
||||
else:
|
||||
x_min = xy[:, 0].min()
|
||||
x_max = xy[:, 0].max()
|
||||
y_min = xy[:, 1].min()
|
||||
y_max = xy[:, 1].max()
|
||||
xyxy = np.array([[x_min, y_min, x_max, y_max]], dtype=np.float32)
|
||||
|
||||
if self.confidence is None:
|
||||
confidence = None
|
||||
else:
|
||||
confidence = self.confidence[i]
|
||||
if selected_keypoint_indices:
|
||||
confidence = confidence[selected_keypoint_indices]
|
||||
confidence = np.array([confidence.mean()], dtype=np.float32)
|
||||
|
||||
detections_list.append(
|
||||
Detections(
|
||||
xyxy=xyxy,
|
||||
confidence=confidence,
|
||||
)
|
||||
)
|
||||
|
||||
detections = Detections.merge(detections_list)
|
||||
detections.class_id = self.class_id
|
||||
detections.data = self.data
|
||||
detections = detections[detections.area > 0]
|
||||
|
||||
return detections
|
||||
|
||||
@@ -8,6 +8,10 @@ from supervision.metrics.mean_average_precision import (
|
||||
MeanAveragePrecision,
|
||||
MeanAveragePrecisionResult,
|
||||
)
|
||||
from supervision.metrics.mean_average_recall import (
|
||||
MeanAverageRecall,
|
||||
MeanAverageRecallResult,
|
||||
)
|
||||
from supervision.metrics.precision import Precision, PrecisionResult
|
||||
from supervision.metrics.recall import Recall, RecallResult
|
||||
from supervision.metrics.utils.object_size import (
|
||||
@@ -15,3 +19,22 @@ from supervision.metrics.utils.object_size import (
|
||||
get_detection_size_category,
|
||||
get_object_size_category,
|
||||
)
|
||||
|
||||
__all__ = [
|
||||
"AveragingMethod",
|
||||
"F1Score",
|
||||
"F1ScoreResult",
|
||||
"MeanAveragePrecision",
|
||||
"MeanAveragePrecisionResult",
|
||||
"MeanAverageRecall",
|
||||
"MeanAverageRecallResult",
|
||||
"Metric",
|
||||
"MetricTarget",
|
||||
"ObjectSizeCategory",
|
||||
"Precision",
|
||||
"PrecisionResult",
|
||||
"Recall",
|
||||
"RecallResult",
|
||||
"get_detection_size_category",
|
||||
"get_object_size_category",
|
||||
]
|
||||
|
||||
@@ -47,10 +47,30 @@ class F1Score(Metric):
|
||||
f1_metric = F1Score()
|
||||
f1_result = f1_metric.update(predictions, targets).compute()
|
||||
|
||||
print(f1_result)
|
||||
print(f1_result.f1_50)
|
||||
print(f1_result.small_objects.f1_50)
|
||||
# 0.7618
|
||||
|
||||
print(f1_result)
|
||||
# F1ScoreResult:
|
||||
# Metric target: MetricTarget.BOXES
|
||||
# Averaging method: AveragingMethod.WEIGHTED
|
||||
# F1 @ 50: 0.7618
|
||||
# F1 @ 75: 0.7487
|
||||
# F1 @ thresh: [0.76175 0.76068 0.76068]
|
||||
# IoU thresh: [0.5 0.55 0.6 ...]
|
||||
# F1 per class:
|
||||
# 0: [0.70968 0.70968 0.70968 ...]
|
||||
# ...
|
||||
# Small objects: ...
|
||||
# Medium objects: ...
|
||||
# Large objects: ...
|
||||
|
||||
f1_result.plot()
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
@@ -456,11 +476,11 @@ class F1ScoreResult:
|
||||
matched_classes (np.ndarray): the class IDs of all matched classes.
|
||||
Corresponds to the rows of `f1_per_class`.
|
||||
small_objects (Optional[F1ScoreResult]): the F1 metric results
|
||||
for small objects.
|
||||
for small objects (area < 32²).
|
||||
medium_objects (Optional[F1ScoreResult]): the F1 metric results
|
||||
for medium objects.
|
||||
for medium objects (32² ≤ area < 96²).
|
||||
large_objects (Optional[F1ScoreResult]): the F1 metric results
|
||||
for large objects.
|
||||
for large objects (area ≥ 96²).
|
||||
"""
|
||||
|
||||
metric_target: MetricTarget
|
||||
@@ -490,6 +510,19 @@ class F1ScoreResult:
|
||||
Example:
|
||||
```python
|
||||
print(f1_result)
|
||||
# F1ScoreResult:
|
||||
# Metric target: MetricTarget.BOXES
|
||||
# Averaging method: AveragingMethod.WEIGHTED
|
||||
# F1 @ 50: 0.7618
|
||||
# F1 @ 75: 0.7487
|
||||
# F1 @ thresh: [0.76175 0.76068 0.76068]
|
||||
# IoU thresh: [0.5 0.55 0.6 ...]
|
||||
# F1 per class:
|
||||
# 0: [0.70968 0.70968 0.70968 ...]
|
||||
# ...
|
||||
# Small objects: ...
|
||||
# Medium objects: ...
|
||||
# Large objects: ...
|
||||
```
|
||||
"""
|
||||
out_str = (
|
||||
@@ -553,6 +586,10 @@ class F1ScoreResult:
|
||||
def plot(self):
|
||||
"""
|
||||
Plot the F1 results.
|
||||
|
||||
{ align=center width="800" }
|
||||
"""
|
||||
|
||||
labels = ["F1@50", "F1@75"]
|
||||
|
||||
@@ -42,10 +42,31 @@ class MeanAveragePrecision(Metric):
|
||||
map_metric = MeanAveragePrecision()
|
||||
map_result = map_metric.update(predictions, targets).compute()
|
||||
|
||||
print(map_result)
|
||||
print(map_result.map50_95)
|
||||
# 0.4674
|
||||
|
||||
print(map_result)
|
||||
# MeanAveragePrecisionResult:
|
||||
# Metric target: MetricTarget.BOXES
|
||||
# Class agnostic: False
|
||||
# mAP @ 50:95: 0.4674
|
||||
# mAP @ 50: 0.5048
|
||||
# mAP @ 75: 0.4796
|
||||
# mAP scores: [0.50485 0.50377 0.50377 ...]
|
||||
# IoU thresh: [0.5 0.55 0.6 ...]
|
||||
# AP per class:
|
||||
# 0: [0.67699 0.67699 0.67699 ...]
|
||||
# ...
|
||||
# Small objects: ...
|
||||
# Medium objects: ...
|
||||
# Large objects: ...
|
||||
|
||||
map_result.plot()
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
@@ -419,11 +440,11 @@ class MeanAveragePrecisionResult:
|
||||
matched_classes (np.ndarray): the class IDs of all matched classes.
|
||||
Corresponds to the rows of `ap_per_class`.
|
||||
small_objects (Optional[MeanAveragePrecisionResult]): the mAP results
|
||||
for small objects.
|
||||
for small objects (area < 32²).
|
||||
medium_objects (Optional[MeanAveragePrecisionResult]): the mAP results
|
||||
for medium objects.
|
||||
for medium objects (32² ≤ area < 96²).
|
||||
large_objects (Optional[MeanAveragePrecisionResult]): the mAP results
|
||||
for large objects.
|
||||
for large objects (area ≥ 96²).
|
||||
"""
|
||||
|
||||
metric_target: MetricTarget
|
||||
@@ -456,6 +477,20 @@ class MeanAveragePrecisionResult:
|
||||
Example:
|
||||
```python
|
||||
print(map_result)
|
||||
# MeanAveragePrecisionResult:
|
||||
# Metric target: MetricTarget.BOXES
|
||||
# Class agnostic: False
|
||||
# mAP @ 50:95: 0.4674
|
||||
# mAP @ 50: 0.5048
|
||||
# mAP @ 75: 0.4796
|
||||
# mAP scores: [0.50485 0.50377 0.50377 ...]
|
||||
# IoU thresh: [0.5 0.55 0.6 ...]
|
||||
# AP per class:
|
||||
# 0: [0.67699 0.67699 0.67699 ...]
|
||||
# ...
|
||||
# Small objects: ...
|
||||
# Medium objects: ...
|
||||
# Large objects: ...
|
||||
```
|
||||
"""
|
||||
|
||||
@@ -527,6 +562,10 @@ class MeanAveragePrecisionResult:
|
||||
def plot(self):
|
||||
"""
|
||||
Plot the mAP results.
|
||||
|
||||
{ align=center width="800" }
|
||||
"""
|
||||
|
||||
labels = ["mAP@50:95", "mAP@50", "mAP@75"]
|
||||
|
||||
@@ -0,0 +1,697 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from copy import deepcopy
|
||||
from dataclasses import dataclass
|
||||
from typing import TYPE_CHECKING, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
from matplotlib import pyplot as plt
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
mask_iou_batch,
|
||||
oriented_box_iou_batch,
|
||||
)
|
||||
from supervision.draw.color import LEGACY_COLOR_PALETTE
|
||||
from supervision.metrics.core import Metric, MetricTarget
|
||||
from supervision.metrics.utils.object_size import (
|
||||
ObjectSizeCategory,
|
||||
get_detection_size_category,
|
||||
)
|
||||
from supervision.metrics.utils.utils import ensure_pandas_installed
|
||||
|
||||
if TYPE_CHECKING:
|
||||
import pandas as pd
|
||||
|
||||
|
||||
class MeanAverageRecall(Metric):
|
||||
"""
|
||||
Mean Average Recall (mAR) measures how well the model detects
|
||||
and retrieves relevant objects by averaging recall over multiple
|
||||
IoU thresholds, classes and detection limits.
|
||||
|
||||
Intuitively, while Recall measures the ability to find all relevant
|
||||
objects, mAR narrows down how many detections are considered for each
|
||||
class. For example, mAR @ 100 considers the top 100 highest confidence
|
||||
detections for each class. mAR @ 1 considers only the highest
|
||||
confidence detection for each class.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
from supervision.metrics import MeanAverageRecall
|
||||
|
||||
predictions = sv.Detections(...)
|
||||
targets = sv.Detections(...)
|
||||
|
||||
map_metric = MeanAverageRecall()
|
||||
map_result = map_metric.update(predictions, targets).compute()
|
||||
|
||||
print(mar_results.mar_at_100)
|
||||
# 0.5241
|
||||
|
||||
print(mar_results)
|
||||
# MeanAverageRecallResult:
|
||||
# Metric target: MetricTarget.BOXES
|
||||
# mAR @ 1: 0.1362
|
||||
# mAR @ 10: 0.4239
|
||||
# mAR @ 100: 0.5241
|
||||
# max detections: [1 10 100]
|
||||
# IoU thresh: [0.5 0.55 0.6 ...]
|
||||
# mAR per class:
|
||||
# 0: [0.78571 0.78571 0.78571 ...]
|
||||
# ...
|
||||
# Small objects: ...
|
||||
# Medium objects: ...
|
||||
# Large objects: ...
|
||||
|
||||
mar_results.plot()
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
metric_target: MetricTarget = MetricTarget.BOXES,
|
||||
):
|
||||
"""
|
||||
Initialize the Mean Average Recall metric.
|
||||
|
||||
Args:
|
||||
metric_target (MetricTarget): The type of detection data to use.
|
||||
"""
|
||||
self._metric_target = metric_target
|
||||
|
||||
self._predictions_list: List[Detections] = []
|
||||
self._targets_list: List[Detections] = []
|
||||
|
||||
self.max_detections = np.array([1, 10, 100])
|
||||
|
||||
def reset(self) -> None:
|
||||
"""
|
||||
Reset the metric to its initial state, clearing all stored data.
|
||||
"""
|
||||
self._predictions_list = []
|
||||
self._targets_list = []
|
||||
|
||||
def update(
|
||||
self,
|
||||
predictions: Union[Detections, List[Detections]],
|
||||
targets: Union[Detections, List[Detections]],
|
||||
) -> MeanAverageRecall:
|
||||
"""
|
||||
Add new predictions and targets to the metric, but do not compute the result.
|
||||
|
||||
Args:
|
||||
predictions (Union[Detections, List[Detections]]): The predicted detections.
|
||||
targets (Union[Detections, List[Detections]]): The target detections.
|
||||
|
||||
Returns:
|
||||
(Recall): The updated metric instance.
|
||||
"""
|
||||
if not isinstance(predictions, list):
|
||||
predictions = [predictions]
|
||||
if not isinstance(targets, list):
|
||||
targets = [targets]
|
||||
|
||||
if len(predictions) != len(targets):
|
||||
raise ValueError(
|
||||
f"The number of predictions ({len(predictions)}) and"
|
||||
f" targets ({len(targets)}) during the update must be the same."
|
||||
)
|
||||
|
||||
self._predictions_list.extend(predictions)
|
||||
self._targets_list.extend(targets)
|
||||
|
||||
return self
|
||||
|
||||
def compute(self) -> MeanAverageRecallResult:
|
||||
"""
|
||||
Calculate the Mean Average Recall metric based on the stored predictions
|
||||
and ground-truth, at different IoU thresholds and maximum detection counts.
|
||||
|
||||
Returns:
|
||||
(MeanAverageRecallResult): The Mean Average Recall metric result.
|
||||
"""
|
||||
result = self._compute(self._predictions_list, self._targets_list)
|
||||
|
||||
small_predictions, small_targets = self._filter_predictions_and_targets_by_size(
|
||||
self._predictions_list, self._targets_list, ObjectSizeCategory.SMALL
|
||||
)
|
||||
result.small_objects = self._compute(small_predictions, small_targets)
|
||||
|
||||
medium_predictions, medium_targets = (
|
||||
self._filter_predictions_and_targets_by_size(
|
||||
self._predictions_list, self._targets_list, ObjectSizeCategory.MEDIUM
|
||||
)
|
||||
)
|
||||
result.medium_objects = self._compute(medium_predictions, medium_targets)
|
||||
|
||||
large_predictions, large_targets = self._filter_predictions_and_targets_by_size(
|
||||
self._predictions_list, self._targets_list, ObjectSizeCategory.LARGE
|
||||
)
|
||||
result.large_objects = self._compute(large_predictions, large_targets)
|
||||
|
||||
return result
|
||||
|
||||
def _compute(
|
||||
self, predictions_list: List[Detections], targets_list: List[Detections]
|
||||
) -> MeanAverageRecallResult:
|
||||
iou_thresholds = np.linspace(0.5, 0.95, 10)
|
||||
stats = []
|
||||
|
||||
for predictions, targets in zip(predictions_list, targets_list):
|
||||
prediction_contents = self._detections_content(predictions)
|
||||
target_contents = self._detections_content(targets)
|
||||
|
||||
if len(targets) > 0:
|
||||
if len(predictions) == 0:
|
||||
stats.append(
|
||||
(
|
||||
np.zeros((0, iou_thresholds.size), dtype=bool),
|
||||
np.zeros((0,), dtype=np.float32),
|
||||
np.zeros((0,), dtype=int),
|
||||
targets.class_id,
|
||||
)
|
||||
)
|
||||
|
||||
else:
|
||||
if self._metric_target == MetricTarget.BOXES:
|
||||
iou = box_iou_batch(target_contents, prediction_contents)
|
||||
elif self._metric_target == MetricTarget.MASKS:
|
||||
iou = mask_iou_batch(target_contents, prediction_contents)
|
||||
elif self._metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
iou = oriented_box_iou_batch(
|
||||
target_contents, prediction_contents
|
||||
)
|
||||
else:
|
||||
raise ValueError(
|
||||
"Unsupported metric target for IoU calculation"
|
||||
)
|
||||
|
||||
matches = self._match_detection_batch(
|
||||
predictions.class_id, targets.class_id, iou, iou_thresholds
|
||||
)
|
||||
stats.append(
|
||||
(
|
||||
matches,
|
||||
predictions.confidence,
|
||||
predictions.class_id,
|
||||
targets.class_id,
|
||||
)
|
||||
)
|
||||
|
||||
if not stats:
|
||||
return MeanAverageRecallResult(
|
||||
metric_target=self._metric_target,
|
||||
recall_scores=np.zeros(iou_thresholds.shape[0]),
|
||||
recall_per_class=np.zeros((0, iou_thresholds.shape[0])),
|
||||
max_detections=self.max_detections,
|
||||
iou_thresholds=iou_thresholds,
|
||||
matched_classes=np.array([], dtype=int),
|
||||
small_objects=None,
|
||||
medium_objects=None,
|
||||
large_objects=None,
|
||||
)
|
||||
|
||||
concatenated_stats = [np.concatenate(items, 0) for items in zip(*stats)]
|
||||
recall_scores_per_k, recall_per_class, unique_classes = (
|
||||
self._compute_average_recall_for_classes(*concatenated_stats)
|
||||
)
|
||||
|
||||
return MeanAverageRecallResult(
|
||||
metric_target=self._metric_target,
|
||||
recall_scores=recall_scores_per_k,
|
||||
recall_per_class=recall_per_class,
|
||||
max_detections=self.max_detections,
|
||||
iou_thresholds=iou_thresholds,
|
||||
matched_classes=unique_classes,
|
||||
small_objects=None,
|
||||
medium_objects=None,
|
||||
large_objects=None,
|
||||
)
|
||||
|
||||
def _compute_average_recall_for_classes(
|
||||
self,
|
||||
matches: np.ndarray,
|
||||
prediction_confidence: np.ndarray,
|
||||
prediction_class_ids: np.ndarray,
|
||||
true_class_ids: np.ndarray,
|
||||
) -> Tuple[np.ndarray, np.ndarray, np.ndarray]:
|
||||
sorted_indices = np.argsort(-prediction_confidence)
|
||||
matches = matches[sorted_indices]
|
||||
prediction_class_ids = prediction_class_ids[sorted_indices]
|
||||
unique_classes, class_counts = np.unique(true_class_ids, return_counts=True)
|
||||
|
||||
recalls_at_k = []
|
||||
for max_detections in self.max_detections:
|
||||
# Shape: PxTh,P,C,C -> CxThx3
|
||||
confusion_matrix = self._compute_confusion_matrix(
|
||||
matches,
|
||||
prediction_class_ids,
|
||||
unique_classes,
|
||||
class_counts,
|
||||
max_detections=max_detections,
|
||||
)
|
||||
|
||||
# Shape: CxThx3 -> CxTh
|
||||
recall_per_class = self._compute_recall(confusion_matrix)
|
||||
recalls_at_k.append(recall_per_class)
|
||||
|
||||
# Shape: KxCxTh -> KxC
|
||||
recalls_at_k = np.array(recalls_at_k)
|
||||
average_recall_per_class = np.mean(recalls_at_k, axis=2)
|
||||
|
||||
# Shape: KxC -> K
|
||||
recall_scores = np.mean(average_recall_per_class, axis=1)
|
||||
|
||||
return recall_scores, recall_per_class, unique_classes
|
||||
|
||||
@staticmethod
|
||||
def _match_detection_batch(
|
||||
predictions_classes: np.ndarray,
|
||||
target_classes: np.ndarray,
|
||||
iou: np.ndarray,
|
||||
iou_thresholds: np.ndarray,
|
||||
) -> np.ndarray:
|
||||
num_predictions, num_iou_levels = (
|
||||
predictions_classes.shape[0],
|
||||
iou_thresholds.shape[0],
|
||||
)
|
||||
correct = np.zeros((num_predictions, num_iou_levels), dtype=bool)
|
||||
correct_class = target_classes[:, None] == predictions_classes
|
||||
|
||||
for i, iou_level in enumerate(iou_thresholds):
|
||||
matched_indices = np.where((iou >= iou_level) & correct_class)
|
||||
|
||||
if matched_indices[0].shape[0]:
|
||||
combined_indices = np.stack(matched_indices, axis=1)
|
||||
iou_values = iou[matched_indices][:, None]
|
||||
matches = np.hstack([combined_indices, iou_values])
|
||||
|
||||
if matched_indices[0].shape[0] > 1:
|
||||
matches = matches[matches[:, 2].argsort()[::-1]]
|
||||
matches = matches[np.unique(matches[:, 1], return_index=True)[1]]
|
||||
matches = matches[np.unique(matches[:, 0], return_index=True)[1]]
|
||||
|
||||
correct[matches[:, 1].astype(int), i] = True
|
||||
|
||||
return correct
|
||||
|
||||
@staticmethod
|
||||
def _compute_confusion_matrix(
|
||||
sorted_matches: np.ndarray,
|
||||
sorted_prediction_class_ids: np.ndarray,
|
||||
unique_classes: np.ndarray,
|
||||
class_counts: np.ndarray,
|
||||
max_detections: Optional[int] = None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Compute the confusion matrix for each class and IoU threshold.
|
||||
|
||||
Assumes the matches and prediction_class_ids are sorted by confidence
|
||||
in descending order.
|
||||
|
||||
Args:
|
||||
sorted_matches: np.ndarray, bool, shape (P, Th), that is True
|
||||
if the prediction is a true positive at the given IoU threshold.
|
||||
sorted_prediction_class_ids: np.ndarray, int, shape (P,), containing
|
||||
the class id for each prediction.
|
||||
unique_classes: np.ndarray, int, shape (C,), containing the unique
|
||||
class ids.
|
||||
class_counts: np.ndarray, int, shape (C,), containing the number
|
||||
of true instances for each class.
|
||||
max_detections: Optional[int], the maximum number of detections to
|
||||
consider for each class. Extra detections are considered false
|
||||
positives. By default, all detections are considered.
|
||||
|
||||
Returns:
|
||||
np.ndarray, shape (C, Th, 3), containing the true positives, false
|
||||
positives, and false negatives for each class and IoU threshold.
|
||||
"""
|
||||
num_thresholds = sorted_matches.shape[1]
|
||||
num_classes = unique_classes.shape[0]
|
||||
|
||||
confusion_matrix = np.zeros((num_classes, num_thresholds, 3))
|
||||
for class_idx, class_id in enumerate(unique_classes):
|
||||
is_class = sorted_prediction_class_ids == class_id
|
||||
num_true = class_counts[class_idx]
|
||||
num_predictions = is_class.sum()
|
||||
|
||||
if num_predictions == 0:
|
||||
true_positives = np.zeros(num_thresholds)
|
||||
false_positives = np.zeros(num_thresholds)
|
||||
false_negatives = np.full(num_thresholds, num_true)
|
||||
elif num_true == 0:
|
||||
true_positives = np.zeros(num_thresholds)
|
||||
false_positives = np.full(num_thresholds, num_predictions)
|
||||
false_negatives = np.zeros(num_thresholds)
|
||||
else:
|
||||
limited_matches = sorted_matches[is_class][slice(max_detections)]
|
||||
true_positives = limited_matches.sum(0)
|
||||
|
||||
false_positives = (1 - limited_matches).sum(0)
|
||||
false_negatives = num_true - true_positives
|
||||
false_negatives = num_true - true_positives
|
||||
confusion_matrix[class_idx] = np.stack(
|
||||
[true_positives, false_positives, false_negatives], axis=1
|
||||
)
|
||||
|
||||
return confusion_matrix
|
||||
|
||||
@staticmethod
|
||||
def _compute_recall(confusion_matrix: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Broadcastable function, computing the recall from the confusion matrix.
|
||||
|
||||
Arguments:
|
||||
confusion_matrix: np.ndarray, shape (N, ..., 3), where the last dimension
|
||||
contains the true positives, false positives, and false negatives.
|
||||
|
||||
Returns:
|
||||
np.ndarray, shape (N, ...), containing the recall for each element.
|
||||
"""
|
||||
if not confusion_matrix.shape[-1] == 3:
|
||||
raise ValueError(
|
||||
f"Confusion matrix must have shape (..., 3), got "
|
||||
f"{confusion_matrix.shape}"
|
||||
)
|
||||
true_positives = confusion_matrix[..., 0]
|
||||
false_negatives = confusion_matrix[..., 2]
|
||||
|
||||
denominator = true_positives + false_negatives
|
||||
recall = np.where(denominator == 0, 0, true_positives / denominator)
|
||||
|
||||
return recall
|
||||
|
||||
def _detections_content(self, detections: Detections) -> np.ndarray:
|
||||
"""Return boxes, masks or oriented bounding boxes from detections."""
|
||||
if self._metric_target == MetricTarget.BOXES:
|
||||
return detections.xyxy
|
||||
if self._metric_target == MetricTarget.MASKS:
|
||||
return (
|
||||
detections.mask
|
||||
if detections.mask is not None
|
||||
else self._make_empty_content()
|
||||
)
|
||||
if self._metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
obb = detections.data.get(ORIENTED_BOX_COORDINATES)
|
||||
if obb is not None and len(obb) > 0:
|
||||
return np.array(obb, dtype=np.float32)
|
||||
return self._make_empty_content()
|
||||
raise ValueError(f"Invalid metric target: {self._metric_target}")
|
||||
|
||||
def _make_empty_content(self) -> np.ndarray:
|
||||
if self._metric_target == MetricTarget.BOXES:
|
||||
return np.empty((0, 4), dtype=np.float32)
|
||||
if self._metric_target == MetricTarget.MASKS:
|
||||
return np.empty((0, 0, 0), dtype=bool)
|
||||
if self._metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
return np.empty((0, 4, 2), dtype=np.float32)
|
||||
raise ValueError(f"Invalid metric target: {self._metric_target}")
|
||||
|
||||
def _filter_detections_by_size(
|
||||
self, detections: Detections, size_category: ObjectSizeCategory
|
||||
) -> Detections:
|
||||
"""Return a copy of detections with contents filtered by object size."""
|
||||
new_detections = deepcopy(detections)
|
||||
if detections.is_empty() or size_category == ObjectSizeCategory.ANY:
|
||||
return new_detections
|
||||
|
||||
sizes = get_detection_size_category(new_detections, self._metric_target)
|
||||
size_mask = sizes == size_category.value
|
||||
|
||||
new_detections.xyxy = new_detections.xyxy[size_mask]
|
||||
if new_detections.mask is not None:
|
||||
new_detections.mask = new_detections.mask[size_mask]
|
||||
if new_detections.class_id is not None:
|
||||
new_detections.class_id = new_detections.class_id[size_mask]
|
||||
if new_detections.confidence is not None:
|
||||
new_detections.confidence = new_detections.confidence[size_mask]
|
||||
if new_detections.tracker_id is not None:
|
||||
new_detections.tracker_id = new_detections.tracker_id[size_mask]
|
||||
if new_detections.data is not None:
|
||||
for key, value in new_detections.data.items():
|
||||
new_detections.data[key] = np.array(value)[size_mask]
|
||||
|
||||
return new_detections
|
||||
|
||||
def _filter_predictions_and_targets_by_size(
|
||||
self,
|
||||
predictions_list: List[Detections],
|
||||
targets_list: List[Detections],
|
||||
size_category: ObjectSizeCategory,
|
||||
) -> Tuple[List[Detections], List[Detections]]:
|
||||
new_predictions_list = []
|
||||
new_targets_list = []
|
||||
for predictions, targets in zip(predictions_list, targets_list):
|
||||
new_predictions_list.append(
|
||||
self._filter_detections_by_size(predictions, size_category)
|
||||
)
|
||||
new_targets_list.append(
|
||||
self._filter_detections_by_size(targets, size_category)
|
||||
)
|
||||
return new_predictions_list, new_targets_list
|
||||
|
||||
|
||||
@dataclass
|
||||
class MeanAverageRecallResult:
|
||||
# """
|
||||
# The results of the recall metric calculation.
|
||||
|
||||
# Defaults to `0` if no detections or targets were provided.
|
||||
|
||||
# Attributes:
|
||||
# metric_target (MetricTarget): the type of data used for the metric -
|
||||
# boxes, masks or oriented bounding boxes.
|
||||
# averaging_method (AveragingMethod): the averaging method used to compute the
|
||||
# recall. Determines how the recall is aggregated across classes.
|
||||
# recall_at_50 (float): the recall at IoU threshold of `0.5`.
|
||||
# recall_at_75 (float): the recall at IoU threshold of `0.75`.
|
||||
# recall_scores (np.ndarray): the recall scores at each IoU threshold.
|
||||
# Shape: `(num_iou_thresholds,)`
|
||||
# recall_per_class (np.ndarray): the recall scores per class and IoU threshold.
|
||||
# Shape: `(num_target_classes, num_iou_thresholds)`
|
||||
# iou_thresholds (np.ndarray): the IoU thresholds used in the calculations.
|
||||
# matched_classes (np.ndarray): the class IDs of all matched classes.
|
||||
# Corresponds to the rows of `recall_per_class`.
|
||||
# small_objects (Optional[RecallResult]): the Recall metric results
|
||||
# for small objects.
|
||||
# medium_objects (Optional[RecallResult]): the Recall metric results
|
||||
# for medium objects.
|
||||
# large_objects (Optional[RecallResult]): the Recall metric results
|
||||
# for large objects.
|
||||
# """
|
||||
"""
|
||||
The results of the Mean Average Recall metric calculation.
|
||||
|
||||
Defaults to `0` if no detections or targets were provided.
|
||||
|
||||
Attributes:
|
||||
metric_target (MetricTarget): the type of data used for the metric -
|
||||
boxes, masks or oriented bounding boxes.
|
||||
mAR_at_1 (float): the Mean Average Recall, when considering only the top
|
||||
highest confidence detection for each class.
|
||||
mAR_at_10 (float): the Mean Average Recall, when considering top 10
|
||||
highest confidence detections for each class.
|
||||
mAR_at_100 (float): the Mean Average Recall, when considering top 100
|
||||
highest confidence detections for each class.
|
||||
recall_per_class (np.ndarray): the recall scores per class and IoU threshold.
|
||||
Shape: `(num_target_classes, num_iou_thresholds)`
|
||||
max_detections (np.ndarray): the array with maximum number of detections
|
||||
considered.
|
||||
iou_thresholds (np.ndarray): the IoU thresholds used in the calculations.
|
||||
matched_classes (np.ndarray): the class IDs of all matched classes.
|
||||
Corresponds to the rows of `recall_per_class`.
|
||||
small_objects (Optional[MeanAverageRecallResult]): the Mean Average Recall
|
||||
metric results for small objects (area < 32²).
|
||||
medium_objects (Optional[MeanAverageRecallResult]): the Mean Average Recall
|
||||
metric results for medium objects (32² ≤ area < 96²).
|
||||
large_objects (Optional[MeanAverageRecallResult]): the Mean Average Recall
|
||||
metric results for large objects (area ≥ 96²).
|
||||
"""
|
||||
|
||||
metric_target: MetricTarget
|
||||
|
||||
@property
|
||||
def mAR_at_1(self) -> float:
|
||||
return self.recall_scores[0]
|
||||
|
||||
@property
|
||||
def mAR_at_10(self) -> float:
|
||||
return self.recall_scores[1]
|
||||
|
||||
@property
|
||||
def mAR_at_100(self) -> float:
|
||||
return self.recall_scores[2]
|
||||
|
||||
recall_scores: np.ndarray
|
||||
recall_per_class: np.ndarray
|
||||
max_detections: np.ndarray
|
||||
iou_thresholds: np.ndarray
|
||||
matched_classes: np.ndarray
|
||||
|
||||
small_objects: Optional[MeanAverageRecallResult]
|
||||
medium_objects: Optional[MeanAverageRecallResult]
|
||||
large_objects: Optional[MeanAverageRecallResult]
|
||||
|
||||
def __str__(self) -> str:
|
||||
"""
|
||||
Format as a pretty string.
|
||||
|
||||
Example:
|
||||
```python
|
||||
# MeanAverageRecallResult:
|
||||
# Metric target: MetricTarget.BOXES
|
||||
# mAR @ 1: 0.1362
|
||||
# mAR @ 10: 0.4239
|
||||
# mAR @ 100: 0.5241
|
||||
# max detections: [1 10 100]
|
||||
# IoU thresh: [0.5 0.55 0.6 ...]
|
||||
# mAR per class:
|
||||
# 0: [0.78571 0.78571 0.78571 ...]
|
||||
# ...
|
||||
# Small objects: ...
|
||||
# Medium objects: ...
|
||||
# Large objects: ...
|
||||
```
|
||||
"""
|
||||
out_str = (
|
||||
f"{self.__class__.__name__}:\n"
|
||||
f"Metric target: {self.metric_target}\n"
|
||||
f"mAR @ 1: {self.mAR_at_1:.4f}\n"
|
||||
f"mAR @ 10: {self.mAR_at_10:.4f}\n"
|
||||
f"mAR @ 100: {self.mAR_at_100:.4f}\n"
|
||||
f"max detections: {self.max_detections}\n"
|
||||
f"IoU thresh: {self.iou_thresholds}\n"
|
||||
f"mAR per class:\n"
|
||||
)
|
||||
if self.recall_per_class.size == 0:
|
||||
out_str += " No results\n"
|
||||
for class_id, recall_of_class in zip(
|
||||
self.matched_classes, self.recall_per_class
|
||||
):
|
||||
out_str += f" {class_id}: {recall_of_class}\n"
|
||||
|
||||
indent = " "
|
||||
if self.small_objects is not None:
|
||||
indented = indent + str(self.small_objects).replace("\n", f"\n{indent}")
|
||||
out_str += f"\nSmall objects:\n{indented}"
|
||||
if self.medium_objects is not None:
|
||||
indented = indent + str(self.medium_objects).replace("\n", f"\n{indent}")
|
||||
out_str += f"\nMedium objects:\n{indented}"
|
||||
if self.large_objects is not None:
|
||||
indented = indent + str(self.large_objects).replace("\n", f"\n{indent}")
|
||||
out_str += f"\nLarge objects:\n{indented}"
|
||||
|
||||
return out_str
|
||||
|
||||
def to_pandas(self) -> "pd.DataFrame":
|
||||
"""
|
||||
Convert the result to a pandas DataFrame.
|
||||
|
||||
Returns:
|
||||
(pd.DataFrame): The result as a DataFrame.
|
||||
"""
|
||||
ensure_pandas_installed()
|
||||
import pandas as pd
|
||||
|
||||
pandas_data = {
|
||||
"mAR @ 1": self.mAR_at_1,
|
||||
"mAR @ 10": self.mAR_at_10,
|
||||
"mAR @ 100": self.mAR_at_100,
|
||||
}
|
||||
|
||||
if self.small_objects is not None:
|
||||
small_objects_df = self.small_objects.to_pandas()
|
||||
for key, value in small_objects_df.items():
|
||||
pandas_data[f"small_objects_{key}"] = value
|
||||
if self.medium_objects is not None:
|
||||
medium_objects_df = self.medium_objects.to_pandas()
|
||||
for key, value in medium_objects_df.items():
|
||||
pandas_data[f"medium_objects_{key}"] = value
|
||||
if self.large_objects is not None:
|
||||
large_objects_df = self.large_objects.to_pandas()
|
||||
for key, value in large_objects_df.items():
|
||||
pandas_data[f"large_objects_{key}"] = value
|
||||
|
||||
return pd.DataFrame(pandas_data, index=[0])
|
||||
|
||||
def plot(self):
|
||||
"""
|
||||
Plot the Mean Average Recall results.
|
||||
|
||||
{ align=center width="800" }
|
||||
"""
|
||||
labels = ["mAR @ 1", "mAR @ 10", "mAR @ 100"]
|
||||
values = [self.mAR_at_1, self.mAR_at_10, self.mAR_at_100]
|
||||
colors = [LEGACY_COLOR_PALETTE[0]] * 3
|
||||
|
||||
if self.small_objects is not None:
|
||||
small_objects = self.small_objects
|
||||
labels += ["Small: mAR @ 1", "Small: mAR @ 10", "Small: mAR @ 100"]
|
||||
values += [
|
||||
small_objects.mAR_at_1,
|
||||
small_objects.mAR_at_10,
|
||||
small_objects.mAR_at_100,
|
||||
]
|
||||
colors += [LEGACY_COLOR_PALETTE[3]] * 3
|
||||
|
||||
if self.medium_objects is not None:
|
||||
medium_objects = self.medium_objects
|
||||
labels += ["Medium: mAR @ 1", "Medium: mAR @ 10", "Medium: mAR @ 100"]
|
||||
values += [
|
||||
medium_objects.mAR_at_1,
|
||||
medium_objects.mAR_at_10,
|
||||
medium_objects.mAR_at_100,
|
||||
]
|
||||
colors += [LEGACY_COLOR_PALETTE[2]] * 3
|
||||
|
||||
if self.large_objects is not None:
|
||||
large_objects = self.large_objects
|
||||
labels += ["Large: mAR @ 1", "Large: mAR @ 10", "Large: mAR @ 100"]
|
||||
values += [
|
||||
large_objects.mAR_at_1,
|
||||
large_objects.mAR_at_10,
|
||||
large_objects.mAR_at_100,
|
||||
]
|
||||
colors += [LEGACY_COLOR_PALETTE[4]] * 3
|
||||
|
||||
plt.rcParams["font.family"] = "monospace"
|
||||
|
||||
_, ax = plt.subplots(figsize=(10, 6))
|
||||
ax.set_ylim(0, 1)
|
||||
ax.set_ylabel("Value", fontweight="bold")
|
||||
title = (
|
||||
f"Mean Average Recall, by Object Size"
|
||||
f"\n(target: {self.metric_target.value})"
|
||||
)
|
||||
ax.set_title(title, fontweight="bold")
|
||||
|
||||
x_positions = range(len(labels))
|
||||
bars = ax.bar(x_positions, values, color=colors, align="center")
|
||||
|
||||
ax.set_xticks(x_positions)
|
||||
ax.set_xticklabels(labels, rotation=45, ha="right")
|
||||
|
||||
for bar in bars:
|
||||
y_value = bar.get_height()
|
||||
ax.text(
|
||||
bar.get_x() + bar.get_width() / 2,
|
||||
y_value + 0.02,
|
||||
f"{y_value:.2f}",
|
||||
ha="center",
|
||||
va="bottom",
|
||||
)
|
||||
|
||||
plt.rcParams["font.family"] = "sans-serif"
|
||||
|
||||
plt.tight_layout()
|
||||
plt.show()
|
||||
@@ -50,10 +50,30 @@ class Precision(Metric):
|
||||
precision_metric = Precision()
|
||||
precision_result = precision_metric.update(predictions, targets).compute()
|
||||
|
||||
print(precision_result)
|
||||
print(precision_result.precision_at_50)
|
||||
# 0.8099
|
||||
|
||||
print(precision_result)
|
||||
# PrecisionResult:
|
||||
# Metric target: MetricTarget.BOXES
|
||||
# Averaging method: AveragingMethod.WEIGHTED
|
||||
# P @ 50: 0.8099
|
||||
# P @ 75: 0.7969
|
||||
# P @ thresh: [0.80992 0.80905 0.80905 ...]
|
||||
# IoU thresh: [0.5 0.55 0.6 ...]
|
||||
# Precision per class:
|
||||
# 0: [0.64706 0.64706 0.64706 ...]
|
||||
# ...
|
||||
# Small objects: ...
|
||||
# Medium objects: ...
|
||||
# Large objects: ...
|
||||
|
||||
print(precision_result.small_objects.precision_at_50)
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
@@ -459,11 +479,11 @@ class PrecisionResult:
|
||||
matched_classes (np.ndarray): the class IDs of all matched classes.
|
||||
Corresponds to the rows of `precision_per_class`.
|
||||
small_objects (Optional[PrecisionResult]): the Precision metric results
|
||||
for small objects.
|
||||
for small objects (area < 32²).
|
||||
medium_objects (Optional[PrecisionResult]): the Precision metric results
|
||||
for medium objects.
|
||||
for medium objects (32² ≤ area < 96²).
|
||||
large_objects (Optional[PrecisionResult]): the Precision metric results
|
||||
for large objects.
|
||||
for large objects (area ≥ 96²).
|
||||
"""
|
||||
|
||||
metric_target: MetricTarget
|
||||
@@ -493,6 +513,19 @@ class PrecisionResult:
|
||||
Example:
|
||||
```python
|
||||
print(precision_result)
|
||||
# PrecisionResult:
|
||||
# Metric target: MetricTarget.BOXES
|
||||
# Averaging method: AveragingMethod.WEIGHTED
|
||||
# P @ 50: 0.8099
|
||||
# P @ 75: 0.7969
|
||||
# P @ thresh: [0.80992 0.80905 0.80905 ...]
|
||||
# IoU thresh: [0.5 0.55 0.6 ...]
|
||||
# Precision per class:
|
||||
# 0: [0.64706 0.64706 0.64706 ...]
|
||||
# ...
|
||||
# Small objects: ...
|
||||
# Medium objects: ...
|
||||
# Large objects: ...
|
||||
```
|
||||
"""
|
||||
out_str = (
|
||||
@@ -558,6 +591,10 @@ class PrecisionResult:
|
||||
def plot(self):
|
||||
"""
|
||||
Plot the precision results.
|
||||
|
||||
{ align=center width="800" }
|
||||
"""
|
||||
|
||||
labels = ["Precision@50", "Precision@75"]
|
||||
|
||||
@@ -50,10 +50,31 @@ class Recall(Metric):
|
||||
recall_metric = Recall()
|
||||
recall_result = recall_metric.update(predictions, targets).compute()
|
||||
|
||||
print(recall_result)
|
||||
print(recall_result.recall_at_50)
|
||||
print(recall_result.small_objects.recall_at_50)
|
||||
# 0.7615
|
||||
|
||||
print(recall_result)
|
||||
# RecallResult:
|
||||
# Metric target: MetricTarget.BOXES
|
||||
# Averaging method: AveragingMethod.WEIGHTED
|
||||
# R @ 50: 0.7615
|
||||
# R @ 75: 0.7462
|
||||
# R @ thresh: [0.76151 0.76011 0.76011 0.75732 ...]
|
||||
# IoU thresh: [0.5 0.55 0.6 ...]
|
||||
# Recall per class:
|
||||
# 0: [0.78571 0.78571 0.78571 ...]
|
||||
# ...
|
||||
# Small objects: ...
|
||||
# Medium objects: ...
|
||||
# Large objects: ...
|
||||
|
||||
recall_result.plot()
|
||||
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
@@ -115,11 +136,11 @@ class Recall(Metric):
|
||||
|
||||
def compute(self) -> RecallResult:
|
||||
"""
|
||||
Calculate the precision metric based on the stored predictions and ground-truth
|
||||
Calculate the recall metric based on the stored predictions and ground-truth
|
||||
data, at different IoU thresholds.
|
||||
|
||||
Returns:
|
||||
(RecallResult): The precision metric result.
|
||||
(RecallResult): The recall metric result.
|
||||
"""
|
||||
result = self._compute(self._predictions_list, self._targets_list)
|
||||
|
||||
@@ -457,11 +478,11 @@ class RecallResult:
|
||||
matched_classes (np.ndarray): the class IDs of all matched classes.
|
||||
Corresponds to the rows of `recall_per_class`.
|
||||
small_objects (Optional[RecallResult]): the Recall metric results
|
||||
for small objects.
|
||||
for small objects (area < 32²).
|
||||
medium_objects (Optional[RecallResult]): the Recall metric results
|
||||
for medium objects.
|
||||
for medium objects (32² ≤ area < 96²).
|
||||
large_objects (Optional[RecallResult]): the Recall metric results
|
||||
for large objects.
|
||||
for large objects (area ≥ 96²).
|
||||
"""
|
||||
|
||||
metric_target: MetricTarget
|
||||
@@ -491,6 +512,19 @@ class RecallResult:
|
||||
Example:
|
||||
```python
|
||||
print(recall_result)
|
||||
# RecallResult:
|
||||
# Metric target: MetricTarget.BOXES
|
||||
# Averaging method: AveragingMethod.WEIGHTED
|
||||
# R @ 50: 0.7615
|
||||
# R @ 75: 0.7462
|
||||
# R @ thresh: [0.76151 0.76011 0.76011 0.75732 ...]
|
||||
# IoU thresh: [0.5 0.55 0.6 ...]
|
||||
# Recall per class:
|
||||
# 0: [0.78571 0.78571 0.78571 ...]
|
||||
# ...
|
||||
# Small objects: ...
|
||||
# Medium objects: ...
|
||||
# Large objects: ...
|
||||
```
|
||||
"""
|
||||
out_str = (
|
||||
@@ -556,6 +590,10 @@ class RecallResult:
|
||||
def plot(self):
|
||||
"""
|
||||
Plot the recall results.
|
||||
|
||||
{ align=center width="800" }
|
||||
"""
|
||||
|
||||
labels = ["Recall@50", "Recall@75"]
|
||||
|
||||
@@ -1,72 +0,0 @@
|
||||
from typing import Iterable, Optional
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
|
||||
|
||||
def keypoints_to_detections(
|
||||
keypoints: KeyPoints, selected_keypoint_indices: Optional[Iterable[int]] = None
|
||||
) -> Detections:
|
||||
"""
|
||||
Convert a KeyPoints object to a Detections object. This
|
||||
approximates the bounding box of the detected object by
|
||||
taking the bounding box that fits all keypoints.
|
||||
|
||||
Arguments:
|
||||
keypoints (KeyPoints): The keypoints to convert to detections.
|
||||
selected_keypoint_indices (Optional[Iterable[int]]): The
|
||||
indices of the keypoints to include in the bounding box
|
||||
calculation. This helps focus on a subset of keypoints,
|
||||
e.g. when some are occluded. Captures all keypoints by default.
|
||||
|
||||
Returns:
|
||||
detections (Detections): The converted detections object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
keypoints = sv.KeyPoints.from_inference(...)
|
||||
detections = keypoints_to_detections(keypoints)
|
||||
```
|
||||
"""
|
||||
if keypoints.is_empty():
|
||||
return Detections.empty()
|
||||
|
||||
detections_list = []
|
||||
for i, xy in enumerate(keypoints.xy):
|
||||
if selected_keypoint_indices:
|
||||
xy = xy[selected_keypoint_indices]
|
||||
|
||||
# [0, 0] used by some frameworks to indicate missing keypoints
|
||||
xy = xy[~np.all(xy == 0, axis=1)]
|
||||
if len(xy) == 0:
|
||||
xyxy = np.array([[0, 0, 0, 0]], dtype=np.float32)
|
||||
else:
|
||||
x_min = xy[:, 0].min()
|
||||
x_max = xy[:, 0].max()
|
||||
y_min = xy[:, 1].min()
|
||||
y_max = xy[:, 1].max()
|
||||
xyxy = np.array([[x_min, y_min, x_max, y_max]], dtype=np.float32)
|
||||
|
||||
if keypoints.confidence is None:
|
||||
confidence = None
|
||||
else:
|
||||
confidence = keypoints.confidence[i]
|
||||
if selected_keypoint_indices:
|
||||
confidence = confidence[selected_keypoint_indices]
|
||||
confidence = np.array([confidence.mean()], dtype=np.float32)
|
||||
|
||||
detections_list.append(
|
||||
Detections(
|
||||
xyxy=xyxy,
|
||||
confidence=confidence,
|
||||
)
|
||||
)
|
||||
|
||||
detections = Detections.merge(detections_list)
|
||||
detections.class_id = keypoints.class_id
|
||||
detections.data = keypoints.data
|
||||
detections = detections[detections.area > 0]
|
||||
|
||||
return detections
|
||||
+211
-2
@@ -106,6 +106,26 @@ TEST_DET_DIFFERENT_DATA = Detections(
|
||||
"never_seen_key": [9],
|
||||
},
|
||||
)
|
||||
TEST_DET_WITH_METADATA = Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
class_id=np.array([1]),
|
||||
metadata={"source": "camera1"},
|
||||
)
|
||||
|
||||
TEST_DET_WITH_METADATA_2 = Detections(
|
||||
xyxy=np.array([[30, 30, 40, 40]]),
|
||||
class_id=np.array([2]),
|
||||
metadata={"source": "camera1"},
|
||||
)
|
||||
TEST_DET_NO_METADATA = Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
class_id=np.array([1]),
|
||||
)
|
||||
TEST_DET_DIFFERENT_METADATA = Detections(
|
||||
xyxy=np.array([[50, 50, 60, 60]]),
|
||||
class_id=np.array([3]),
|
||||
metadata={"source": "camera2"},
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
@@ -203,6 +223,12 @@ TEST_DET_DIFFERENT_DATA = Detections(
|
||||
None,
|
||||
pytest.raises(IndexError),
|
||||
),
|
||||
(
|
||||
Detections.empty(),
|
||||
np.isin(Detections.empty()["class_name"], ["cat", "dog"]),
|
||||
Detections.empty(),
|
||||
DoesNotRaise(),
|
||||
), # Filter an empty detections by specific class names
|
||||
],
|
||||
)
|
||||
def test_getitem(
|
||||
@@ -258,6 +284,11 @@ def test_getitem(
|
||||
TEST_DET_1,
|
||||
DoesNotRaise(),
|
||||
), # Single detection and empty-array fields
|
||||
(
|
||||
[TEST_DET_ZERO_LENGTH, TEST_DET_ZERO_LENGTH],
|
||||
TEST_DET_ZERO_LENGTH,
|
||||
DoesNotRaise(),
|
||||
), # Zero-length fields across all Detections
|
||||
(
|
||||
[
|
||||
TEST_DET_1,
|
||||
@@ -287,12 +318,190 @@ def test_getitem(
|
||||
Detections.empty(),
|
||||
],
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 20, 20]],
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
class_id=[1],
|
||||
mask=[np.zeros((4, 4), dtype=bool)],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # Segmentation + Empty
|
||||
# Metadata
|
||||
(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
class_id=np.array([1]),
|
||||
metadata={"source": "camera1"},
|
||||
),
|
||||
Detections.empty(),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
class_id=np.array([1]),
|
||||
metadata={"source": "camera1"},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # Metadata merge with empty detections
|
||||
(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
class_id=np.array([1]),
|
||||
metadata={"source": "camera1"},
|
||||
),
|
||||
Detections(xyxy=np.array([[30, 30, 40, 40]]), class_id=np.array([2])),
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # Empty and non-empty metadata
|
||||
(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
class_id=np.array([1]),
|
||||
metadata={"source": "camera1"},
|
||||
)
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
class_id=np.array([1]),
|
||||
metadata={"source": "camera1"},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # Single detection with metadata
|
||||
(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
class_id=np.array([1]),
|
||||
metadata={"source": "camera1"},
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[30, 30, 40, 40]]),
|
||||
class_id=np.array([2]),
|
||||
metadata={"source": "camera1"},
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20], [30, 30, 40, 40]]),
|
||||
class_id=np.array([1, 2]),
|
||||
metadata={"source": "camera1"},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # Multiple metadata entries with identical values
|
||||
(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
class_id=np.array([1]),
|
||||
metadata={"source": "camera1"},
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[50, 50, 60, 60]]),
|
||||
class_id=np.array([3]),
|
||||
metadata={"source": "camera2"},
|
||||
),
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # Different metadata values
|
||||
(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
metadata={"source": "camera1", "resolution": "1080p"},
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[30, 30, 40, 40]]),
|
||||
metadata={"source": "camera1", "resolution": "1080p"},
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20], [30, 30, 40, 40]]),
|
||||
metadata={"source": "camera1", "resolution": "1080p"},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # Large metadata with multiple identical entries
|
||||
(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]), metadata={"source": "camera1"}
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[30, 30, 40, 40]]), metadata={"source": ["camera1"]}
|
||||
),
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # Inconsistent types in metadata values
|
||||
(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]), metadata={"source": "camera1"}
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[30, 30, 40, 40]]), metadata={"location": "indoor"}
|
||||
),
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # Metadata key mismatch
|
||||
(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
metadata={
|
||||
"source": "camera1",
|
||||
"settings": {"resolution": "1080p", "fps": 30},
|
||||
},
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[30, 30, 40, 40]]),
|
||||
metadata={
|
||||
"source": "camera1",
|
||||
"settings": {"resolution": "1080p", "fps": 30},
|
||||
},
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20], [30, 30, 40, 40]]),
|
||||
metadata={
|
||||
"source": "camera1",
|
||||
"settings": {"resolution": "1080p", "fps": 30},
|
||||
},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # multi-field metadata
|
||||
(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
metadata={"calibration_matrix": np.array([[1, 0], [0, 1]])},
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[30, 30, 40, 40]]),
|
||||
metadata={"calibration_matrix": np.array([[1, 0], [0, 1]])},
|
||||
),
|
||||
],
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20], [30, 30, 40, 40]]),
|
||||
metadata={"calibration_matrix": np.array([[1, 0], [0, 1]])},
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # Identical 2D numpy arrays in metadata
|
||||
(
|
||||
[
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 20, 20]]),
|
||||
metadata={"calibration_matrix": np.array([[1, 0], [0, 1]])},
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[30, 30, 40, 40]]),
|
||||
metadata={"calibration_matrix": np.array([[2, 0], [0, 2]])},
|
||||
),
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # Mismatching 2D numpy arrays in metadata
|
||||
],
|
||||
)
|
||||
def test_merge(
|
||||
@@ -302,7 +511,7 @@ def test_merge(
|
||||
) -> None:
|
||||
with exception:
|
||||
result = Detections.merge(detections_list=detections_list)
|
||||
assert result == expected_result
|
||||
assert result == expected_result, f"Expected: {expected_result}, Got: {result}"
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
|
||||
@@ -493,7 +493,7 @@ def test_line_zone_multiple_detections(
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"vector, xyxy_sequence, triggering_anchors, crossing_acceptance_threshold, "
|
||||
"vector, xyxy_sequence, triggering_anchors, minimum_crossing_threshold, "
|
||||
"expected_crossed_in, expected_crossed_out",
|
||||
[
|
||||
( # Detection lingers around line, all crosses counted
|
||||
@@ -578,7 +578,7 @@ def test_line_zone_one_detection_long_horizon(
|
||||
vector: Vector,
|
||||
xyxy_sequence: List[List[float]],
|
||||
triggering_anchors: List[Position],
|
||||
crossing_acceptance_threshold: int,
|
||||
minimum_crossing_threshold: int,
|
||||
expected_crossed_in: List[bool],
|
||||
expected_crossed_out: List[bool],
|
||||
) -> None:
|
||||
@@ -586,7 +586,7 @@ def test_line_zone_one_detection_long_horizon(
|
||||
start=vector.start,
|
||||
end=vector.end,
|
||||
triggering_anchors=triggering_anchors,
|
||||
crossing_acceptance_threshold=crossing_acceptance_threshold,
|
||||
minimum_crossing_threshold=minimum_crossing_threshold,
|
||||
)
|
||||
|
||||
crossed_in_list = []
|
||||
@@ -609,7 +609,7 @@ def test_line_zone_one_detection_long_horizon(
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"vector, xyxy_sequence, anchors, crossing_acceptance_threshold, "
|
||||
"vector, xyxy_sequence, anchors, minimum_crossing_threshold, "
|
||||
"expected_crossed_in, expected_crossed_out, expected_count_in, "
|
||||
"expected_count_out, exception",
|
||||
[
|
||||
@@ -743,7 +743,7 @@ def test_line_zone_long_horizon_disappearing_detections(
|
||||
vector: Vector,
|
||||
xyxy_sequence: List[List[Optional[List[float]]]],
|
||||
anchors: List[Position],
|
||||
crossing_acceptance_threshold: int,
|
||||
minimum_crossing_threshold: int,
|
||||
expected_crossed_in: List[List[bool]],
|
||||
expected_crossed_out: List[List[bool]],
|
||||
expected_count_in: List[int],
|
||||
@@ -755,7 +755,7 @@ def test_line_zone_long_horizon_disappearing_detections(
|
||||
start=vector.start,
|
||||
end=vector.end,
|
||||
triggering_anchors=anchors,
|
||||
crossing_acceptance_threshold=crossing_acceptance_threshold,
|
||||
minimum_crossing_threshold=minimum_crossing_threshold,
|
||||
)
|
||||
crossed_in_list = []
|
||||
crossed_out_list = []
|
||||
|
||||
@@ -14,7 +14,9 @@ from supervision.detection.utils import (
|
||||
filter_polygons_by_area,
|
||||
get_data_item,
|
||||
merge_data,
|
||||
merge_metadata,
|
||||
move_boxes,
|
||||
move_masks,
|
||||
process_roboflow_result,
|
||||
scale_boxes,
|
||||
xcycwh_to_xyxy,
|
||||
@@ -441,6 +443,268 @@ def test_move_boxes(
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"masks, offset, resolution_wh, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([0, 0]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-1, -1]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[True, True, False, False],
|
||||
[True, True, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-2, -2]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[True, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-3, -3]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-2, -1]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[True, False, False, False],
|
||||
[True, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-1, -2]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[True, True, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([-2, 2]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[True, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([3, 3]),
|
||||
(4, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
np.array([3, 3]),
|
||||
(6, 6),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False, False],
|
||||
[False, False, False, False, False, False],
|
||||
[False, False, False, False, False, False],
|
||||
[False, False, False, False, False, False],
|
||||
[False, False, False, False, True, True],
|
||||
[False, False, False, False, True, True],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_move_masks(
|
||||
masks: np.ndarray,
|
||||
offset: np.ndarray,
|
||||
resolution_wh: Tuple[int, int],
|
||||
expected_result: np.ndarray,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = move_masks(masks=masks, offset=offset, resolution_wh=resolution_wh)
|
||||
np.testing.assert_array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"xyxy, factor, expected_result, exception",
|
||||
[
|
||||
@@ -1138,3 +1402,163 @@ def test_xywh_to_xyxy(xywh: np.ndarray, expected_result: np.ndarray) -> None:
|
||||
def test_xcycwh_to_xyxy(xcycwh: np.ndarray, expected_result: np.ndarray) -> None:
|
||||
result = xcycwh_to_xyxy(xcycwh)
|
||||
np.testing.assert_array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"metadata_list, expected_result, exception",
|
||||
[
|
||||
# Identical metadata with a single key
|
||||
([{"key1": "value1"}, {"key1": "value1"}], {"key1": "value1"}, DoesNotRaise()),
|
||||
# Identical metadata with multiple keys
|
||||
(
|
||||
[
|
||||
{"key1": "value1", "key2": "value2"},
|
||||
{"key1": "value1", "key2": "value2"},
|
||||
],
|
||||
{"key1": "value1", "key2": "value2"},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Conflicting values for the same key
|
||||
([{"key1": "value1"}, {"key1": "value2"}], None, pytest.raises(ValueError)),
|
||||
# Different sets of keys across dictionaries
|
||||
([{"key1": "value1"}, {"key2": "value2"}], None, pytest.raises(ValueError)),
|
||||
# Empty metadata list
|
||||
([], {}, DoesNotRaise()),
|
||||
# Empty metadata dictionaries
|
||||
([{}, {}], {}, DoesNotRaise()),
|
||||
# Different declaration order for keys
|
||||
(
|
||||
[
|
||||
{"key1": "value1", "key2": "value2"},
|
||||
{"key2": "value2", "key1": "value1"},
|
||||
],
|
||||
{"key1": "value1", "key2": "value2"},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Nested metadata dictionaries
|
||||
(
|
||||
[{"key1": {"sub_key": "sub_value"}}, {"key1": {"sub_key": "sub_value"}}],
|
||||
{"key1": {"sub_key": "sub_value"}},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Large metadata dictionaries with many keys
|
||||
(
|
||||
[
|
||||
{f"key{i}": f"value{i}" for i in range(100)},
|
||||
{f"key{i}": f"value{i}" for i in range(100)},
|
||||
],
|
||||
{f"key{i}": f"value{i}" for i in range(100)},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Mixed types in list metadata values
|
||||
(
|
||||
[{"key1": ["value1", 2, True]}, {"key1": ["value1", 2, True]}],
|
||||
{"key1": ["value1", 2, True]},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Identical lists across metadata dictionaries
|
||||
(
|
||||
[{"key1": [1, 2, 3]}, {"key1": [1, 2, 3]}],
|
||||
{"key1": [1, 2, 3]},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Identical numpy arrays across metadata dictionaries
|
||||
(
|
||||
[{"key1": np.array([1, 2, 3])}, {"key1": np.array([1, 2, 3])}],
|
||||
{"key1": np.array([1, 2, 3])},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Identical numpy arrays across metadata dictionaries, different datatype
|
||||
(
|
||||
[
|
||||
{"key1": np.array([1, 2, 3], dtype=np.int32)},
|
||||
{"key1": np.array([1, 2, 3], dtype=np.int64)},
|
||||
],
|
||||
{"key1": np.array([1, 2, 3])},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Conflicting lists for the same key
|
||||
([{"key1": [1, 2, 3]}, {"key1": [4, 5, 6]}], None, pytest.raises(ValueError)),
|
||||
# Conflicting numpy arrays for the same key
|
||||
(
|
||||
[{"key1": np.array([1, 2, 3])}, {"key1": np.array([4, 5, 6])}],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
# Mixed data types: list and numpy array for the same key
|
||||
(
|
||||
[{"key1": [1, 2, 3]}, {"key1": np.array([1, 2, 3])}],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
# Empty lists and numpy arrays for the same key
|
||||
([{"key1": []}, {"key1": np.array([])}], None, pytest.raises(ValueError)),
|
||||
# Identical multi-dimensional lists across metadata dictionaries
|
||||
(
|
||||
[{"key1": [[1, 2], [3, 4]]}, {"key1": [[1, 2], [3, 4]]}],
|
||||
{"key1": [[1, 2], [3, 4]]},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Identical multi-dimensional numpy arrays across metadata dictionaries
|
||||
(
|
||||
[
|
||||
{"key1": np.arange(4).reshape(2, 2)},
|
||||
{"key1": np.arange(4).reshape(2, 2)},
|
||||
],
|
||||
{"key1": np.arange(4).reshape(2, 2)},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Conflicting multi-dimensional lists for the same key
|
||||
(
|
||||
[{"key1": [[1, 2], [3, 4]]}, {"key1": [[5, 6], [7, 8]]}],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
# Conflicting multi-dimensional numpy arrays for the same key
|
||||
(
|
||||
[
|
||||
{"key1": np.arange(4).reshape(2, 2)},
|
||||
{"key1": np.arange(4, 8).reshape(2, 2)},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
# Mixed types with multi-dimensional list and array for the same key
|
||||
(
|
||||
[{"key1": [[1, 2], [3, 4]]}, {"key1": np.arange(4).reshape(2, 2)}],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
# Identical higher-dimensional (3D) numpy arrays across
|
||||
# metadata dictionaries
|
||||
(
|
||||
[
|
||||
{"key1": np.arange(8).reshape(2, 2, 2)},
|
||||
{"key1": np.arange(8).reshape(2, 2, 2)},
|
||||
],
|
||||
{"key1": np.arange(8).reshape(2, 2, 2)},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# Differently-shaped higher-dimensional (3D) numpy arrays
|
||||
# across metadata dictionaries
|
||||
(
|
||||
[
|
||||
{"key1": np.arange(8).reshape(2, 2, 2)},
|
||||
{"key1": np.arange(8).reshape(4, 1, 2)},
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_merge_metadata(metadata_list, expected_result, exception):
|
||||
with exception:
|
||||
result = merge_metadata(metadata_list)
|
||||
if expected_result is None:
|
||||
assert result is None, f"Expected an error, but got a result {result}"
|
||||
for key, value in result.items():
|
||||
assert key in expected_result
|
||||
if isinstance(value, np.ndarray):
|
||||
np.testing.assert_array_equal(value, expected_result[key])
|
||||
else:
|
||||
assert value == expected_result[key]
|
||||
|
||||
@@ -22,33 +22,26 @@ def mock_callback():
|
||||
@pytest.mark.parametrize(
|
||||
"slice_wh, overlap_ratio_wh, overlap_wh, expected_overlap, exception",
|
||||
[
|
||||
# Valid case: overlap_ratio_wh provided, overlap calculated from the ratio
|
||||
((128, 128), (0.2, 0.2), None, None, DoesNotRaise()),
|
||||
# Valid case: overlap_wh in pixels, no ratio provided
|
||||
# Valid case: explicit overlap_wh in pixels
|
||||
((128, 128), None, (26, 26), (26, 26), DoesNotRaise()),
|
||||
# Valid case: overlap_wh in pixels
|
||||
((128, 128), None, (20, 20), (20, 20), DoesNotRaise()),
|
||||
# Invalid case: overlap_ratio_wh greater than 1, should raise ValueError
|
||||
((128, 128), (1.1, 0.5), None, None, pytest.raises(ValueError)),
|
||||
# Invalid case: negative overlap_wh, should raise ValueError
|
||||
((128, 128), None, (-10, 20), None, pytest.raises(ValueError)),
|
||||
# Invalid case:
|
||||
# overlap_ratio_wh and overlap_wh provided, should raise ValueError
|
||||
((128, 128), (0.5, 0.5), (20, 20), (20, 20), pytest.raises(ValueError)),
|
||||
# Valid case: no overlap_ratio_wh, overlap_wh = 50 pixels
|
||||
((256, 256), None, (50, 50), (50, 50), DoesNotRaise()),
|
||||
# Valid case: overlap_ratio_wh provided, overlap calculated from (0.3, 0.3)
|
||||
((200, 200), (0.3, 0.3), None, None, DoesNotRaise()),
|
||||
# Valid case: small overlap_ratio_wh values
|
||||
((100, 100), (0.1, 0.1), None, None, DoesNotRaise()),
|
||||
# Invalid case: negative overlap_ratio_wh value, should raise ValueError
|
||||
((128, 128), (-0.1, 0.2), None, None, pytest.raises(ValueError)),
|
||||
# Invalid case: negative overlap_ratio_wh with overlap_wh provided
|
||||
((128, 128), (-0.1, 0.2), (30, 30), None, pytest.raises(ValueError)),
|
||||
# Invalid case: overlap_wh greater than slice size, should raise ValueError
|
||||
((128, 128), None, (150, 150), (150, 150), DoesNotRaise()),
|
||||
# Valid case: overlap_ratio_wh is 0, no overlap
|
||||
((128, 128), (0.0, 0.0), None, None, DoesNotRaise()),
|
||||
# Invalid case: no overlaps defined, no overlap
|
||||
# Invalid case: no overlaps defined
|
||||
((128, 128), None, None, None, pytest.raises(ValueError)),
|
||||
# Valid case: overlap_wh = 50 pixels
|
||||
((256, 256), None, (50, 50), (50, 50), DoesNotRaise()),
|
||||
# Valid case: overlap_wh = 60 pixels
|
||||
((200, 200), None, (60, 60), (60, 60), DoesNotRaise()),
|
||||
# Valid case: small overlap_wh values
|
||||
((100, 100), None, (0.1, 0.1), (0.1, 0.1), DoesNotRaise()),
|
||||
# Invalid case: negative overlap_wh values
|
||||
((128, 128), None, (-10, -10), None, pytest.raises(ValueError)),
|
||||
# Invalid case: overlap_wh greater than slice size
|
||||
((128, 128), None, (150, 150), (150, 150), DoesNotRaise()),
|
||||
# Valid case: zero overlap
|
||||
((128, 128), None, (0, 0), (0, 0), DoesNotRaise()),
|
||||
],
|
||||
)
|
||||
def test_inference_slicer_overlap(
|
||||
|
||||
Reference in New Issue
Block a user