Update model benchmarking guide with model running and metrics
* Install inference directly for now
This commit is contained in:
 LinasKo
parent
d1c8adb33a
commit
d3f6570a89
|
|
@ -7,34 +7,42 @@ status: new
|
|||
|
||||
## Overview
|
||||
|
||||
Have you ever trained multiple object detection models and wondered which one performs best on your specific use case? Or maybe you've downloaded a pre-trained model and want to verify its performance on your dataset? Model benchmarking is essential for making informed decisions about which model to deploy in production.
|
||||
Have you ever trained multiple detection models and wondered which one performs best on your specific use case? Or maybe you've downloaded a pre-trained model and want to verify its performance on your dataset? Model benchmarking is essential for making informed decisions about which model to deploy in production.
|
||||
|
||||
This guide will show an easy way to benchmark your results using `supervision`. It will go over:
|
||||
|
||||
1. [Loading a dataset](#loading-a-dataset)
|
||||
2. [Loading a model](#loading-a-model)
|
||||
3. [Benchmarking Basics](#benchmarking-basics)
|
||||
4. [Visual Benchmarking](#visual-benchmarking)
|
||||
5. [Metric: Mean Average Precision (mAP)](#metric-mean-average-precision-map)
|
||||
6. [Metric: F1 Score](#metric-f1-score)
|
||||
7. [Bonus: Model Leaderboard](#model-leaderboard)
|
||||
4. [Running a Model](#running-a-model)
|
||||
5. [Remapping Classes](#remapping-classes)
|
||||
6. [Visual Benchmarking](#visual-benchmarking)
|
||||
7. [Benchmarking Metrics](#benchmarking-metrics)
|
||||
8. [Mean Average Precision (mAP)](#mean-average-precision-map)
|
||||
9. [F1 Score](#f1-score)
|
||||
10. [Bonus: Model Leaderboard](#model-leaderboard)
|
||||
|
||||
This guide applies to object detection, instance segmentation, and oriented bounding box models (OBB).
|
||||
This guide will use an instance segmentation model, but it applies to object detection, instance segmentation, and oriented bounding box models (OBB) too.
|
||||
|
||||
## Loading a Dataset
|
||||
|
||||
Suppose you start with a dataset. Perhaps you found it on [Universe](https://universe.roboflow.com/); perhaps you [labeled your own](https://roboflow.com/how-to-label/yolo11). In either case, this guide assumes you have a dataset with labels in your [Roboflow Workspace](https://app.roboflow.com/).
|
||||
Suppose you start with a dataset. Perhaps you found it on [Universe](https://universe.roboflow.com/); perhaps you [labeled your own](https://roboflow.com/how-to-label/yolo11). In either case, this guide assumes you know of a labelled dataset at hand.
|
||||
|
||||
Let's use the following libraries:
|
||||
We'll use the following libraries:
|
||||
|
||||
- `roboflow` to manage the dataset and deploy models
|
||||
- `inference` to run the models
|
||||
- `supervision` to evaluate the model results
|
||||
|
||||
```bash
|
||||
pip install roboflow inference supervision
|
||||
pip install roboflow supervision
|
||||
pip install git+https://github.com/roboflow/inference.git@linas/allow-latest-rc-supervision
|
||||
```
|
||||
|
||||
!!! info
|
||||
|
||||
We're updating `inference` at the moment. Please install it as shown above.
|
||||
|
||||
Here's how you can download a dataset:
|
||||
|
||||
```python
|
||||
|
|
@ -45,23 +53,27 @@ project = rf.workspace("<WORKSPACE_NAME>").project("<PROJECT_NAME>")
|
|||
dataset = project.version(<DATASET_VERSION_NUMBER>).download("<FORMAT>")
|
||||
```
|
||||
|
||||
In this guide, we shall use the [car part segmentation dataset](https://universe.roboflow.com/alpaco5-f3woi/part-autolabeld).
|
||||
If your dataset is fromUniverse, go to `Dataset > Download Dataset > select the format (e.g. YOLOv11) > Show download code.
|
||||
|
||||
If labeling your own data, go to the [dashboard](https://app.roboflow.com/) and check this [guide](https://docs.roboflow.com/api-reference/workspace-and-project-ids) to find your workspace and project IDs.
|
||||
|
||||
In this guide, we shall use a small [Corgi v2](https://universe.roboflow.com/model-examples/segmented-animals-basic) dataset. It is well-labeled and comes with a test set.
|
||||
|
||||
```python
|
||||
from roboflow import Roboflow
|
||||
|
||||
rf = Roboflow(api_key="<YOUR_API_KEY>")
|
||||
project = rf.workspace("alpaco5-f3woi").project("part-autolabeld")
|
||||
dataset = project.version(5).download("yolov11")
|
||||
project = rf.workspace("fbamse1-gm2os").project("corgi-v2")
|
||||
dataset = project.version(4).download("yolov11")
|
||||
```
|
||||
|
||||
This will create a folder called `part-autolabeld` with the dataset in the current working directory, with `train`, `test`, and `valid` folders and `data.yaml` file.
|
||||
This will create a folder called `Corgi-v2-4` with the dataset in the current working directory, with `train`, `test`, and `valid` folders and a `data.yaml` file.
|
||||
|
||||
## Loading a Model
|
||||
|
||||
Let's load a single model, and see how to evaluate it. To evaluate another, simply return to this step.
|
||||
Let's load a model.
|
||||
|
||||
=== "Pretrained Model"
|
||||
=== "Inference, Local"
|
||||
|
||||
Roboflow supports a range of state-of-the-art [pre-trained models](https://inference.roboflow.com/quickstart/aliases/) for object detection, instance segmentation, and pose tracking. You don't even need an API key!
|
||||
|
||||
|
|
@ -70,10 +82,10 @@ Let's load a single model, and see how to evaluate it. To evaluate another, simp
|
|||
```python
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov11s-640")
|
||||
model = get_model(model_id="yolov11s-seg-640")
|
||||
```
|
||||
|
||||
=== "Trained on Roboflow Platform"
|
||||
=== "Inference, Deployed"
|
||||
|
||||
You can train and deploy a model without leaving the Roboflow platform. See this [guide](https://docs.roboflow.com/train/train/train-from-scratch) for more details.
|
||||
|
||||
|
|
@ -86,54 +98,48 @@ Let's load a single model, and see how to evaluate it. To evaluate another, simp
|
|||
model = get_model(model_id=model_id)
|
||||
```
|
||||
|
||||
=== "Locally Trained Model"
|
||||
=== "Ultralytics"
|
||||
|
||||
To train a model locally, we can use ultralytics. Run the following code in your terminal. Note that it applies to segmentation, but can also be used for object detection and oriented bounding box models, if you change `task` and `model` arguments.
|
||||
Similarly to Inference, Ultralytics allows you to run a variety of models.
|
||||
|
||||
```bash
|
||||
pip install ultralytics
|
||||
yolo task=segment mode=train model=yolo11s-seg.pt data=part-autolabeld/data.yaml epochs=10 imgsz=640
|
||||
```
|
||||
|
||||
Once the model is trained, you can deploy it to Roboflow, making it available anywhere.
|
||||
|
||||
Note: if using other model types, change to `-obb` or remove suffix in `model_type` and replace `segment` with `obb`or `detect`. Multiple runs also produce multiple folders such as `segment`, `segment1`, `segment2`, etc.
|
||||
|
||||
```python
|
||||
project.version(dataset.version).deploy(
|
||||
model_type="yolov11-seg", model_path=f"runs/segment/train/weights/best.pt"
|
||||
)
|
||||
from ultralytics import YOLO
|
||||
|
||||
from inference import get_model
|
||||
model_id = project.id.split("/")[1] + "/" + dataset.version
|
||||
model = get_model(model_id=model_id)
|
||||
model = YOLO("yolo11s-seg.pt")
|
||||
```
|
||||
|
||||
## Benchmarking Basics
|
||||
|
||||
Evaluating your model requires careful selection of the dataset. Which images should you use?Let's go over the different subsets of a dataset.
|
||||
Evaluating your model requires careful selection of the dataset. Which images should you use?Let's go over the different scenarios.
|
||||
|
||||
- **Training Set**: This is the set of images used to train the model. Since the model learns to maximize its accuracy on this set, it should **never** be used for validation - the results will seem unrealistically good.
|
||||
- **Validation Set**: This is the set of images used to validate the model during training. Every Nth training epoch, the model is evaluated on the validation set. Often the training is stopped once the validation loss stops improving. Therefore, even while the images aren't used to train the model, it still influences the training outcome.
|
||||
- **Unrelated Dataset**: If you have a dataset that was not used to train the model, this is the best choice.
|
||||
- **Training Set**: This is the set of images used to train the model. This is fine if the model was not trained on this dataset. Otherwise, **never** use it for benchmarking - the results will seem unrealistically good.
|
||||
- **Validation Set**: This is the set of images used to validate the model during training. Every Nth training epoch, the model is evaluated on the validation set. Often the training is stopped once the validation loss stops improving. Therefore, even while the images aren't used to train the model, it still indirectly influences the training outcome.
|
||||
- **Test Set**: This is the set of images kept aside for model testing. It is exactly the set you should use for benchmarking. If the dataset was split correctly, none of these images would be shown to the model during training.
|
||||
|
||||
Therefore, the `test` set is the best choice for benchmarking.
|
||||
Therefore, an unrelated dataset or the `test` set is the best choice for benchmarking.
|
||||
Several other problems may arise:
|
||||
|
||||
- **Data Contamination**: It's possible that the dataset was not split correctly and some images from the test set were used during training. In this case, the results will be overly optimistic. It also covers the case where **very similar** images were used for training and testing - e.g. those taken in the same environment.
|
||||
- **Missing Test Set**: Some datasets do not come with a test set. In this case, you should collect and [label](https://roboflow.com/annotate) your own data. Alternatively, a validation set could be used, but the results could be overly optimistic. Make sure to test in the real world asap.
|
||||
- **Extra Classes**: An unrelated dataset may contain additional classes which you may need to [filter out](https://supervision.roboflow.com/how_to/filter_detections/#by-set-of-classes) before computing metrics.
|
||||
- **Class Mismatch**: In an unrelated dataset, the class names or IDs may be different to what your model produces, you'll need to remap them, which is [shown in this guide](#running-a-model).
|
||||
- **Data Contamination**: The `test` set may not be split correctly, with images from the test set also present in `training` or `validation` set and used during training. In this case, the results will be overly optimistic. This also applies when **very similar** images are used for training and testing - e.g. those taken in the same environment, same lighting conditions, similar angle, etc.
|
||||
- **Missing Test Set**: Some datasets do not come with a test set. In this case, you should collect and [label](https://roboflow.com/annotate) your own data. Alternatively, a validation set could be used, but the results could be overly optimistic. Make sure to test in the real world as soon as possible.
|
||||
|
||||
## Running a Model
|
||||
|
||||
At this stage, we should have:
|
||||
At this stage, you should have:
|
||||
|
||||
- A set of labeled images we'll use to evaluate the model.
|
||||
- The model we wish to benchmark.
|
||||
- A dataset of labeled images to evaluate the model.
|
||||
- A model prepared for benchmarking.
|
||||
|
||||
Let's run the model and obtain the predictions.
|
||||
We'll use `supervision` to iterate over the images.
|
||||
With these ready, we can now run the model and obtain predictions.
|
||||
We'll use `supervision` to create a dataset iterator, and then run the model on each image.
|
||||
|
||||
=== "Roboflow Inference"
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
|
@ -181,6 +187,103 @@ We'll use `supervision` to iterate over the images.
|
|||
targets_list.append(label)
|
||||
```
|
||||
|
||||
## Remapping classes
|
||||
|
||||
Did you notice an issue in the above logic?
|
||||
Since we're using an unrelated dataset, the class names and IDs may be different from what the model was trained on.
|
||||
|
||||
We need to remap them to match the dataset classes. Here's how to do it:
|
||||
|
||||
```python
|
||||
def remap_classes(
|
||||
detections: sv.Detections,
|
||||
class_ids_from_to: dict[int, int],
|
||||
class_names_from_to: dict[str, str]
|
||||
) -> None:
|
||||
new_class_ids = [
|
||||
class_ids_from_to.get(class_id, class_id) for class_id in detections.class_id]
|
||||
detections.class_id = np.array(new_class_ids)
|
||||
|
||||
new_class_names = [
|
||||
class_names_from_to.get(name, name) for name in detections["class_name"]]
|
||||
predictions["class_name"] = np.array(new_class_names)
|
||||
```
|
||||
|
||||
Let's also remove the predictions that are not in the dataset classes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
Dataset class names and IDs can be found in the `data.yaml` file, or by printing `dataset.classes`.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
test_set = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
|
||||
image_paths = []
|
||||
predictions_list = []
|
||||
targets_list = []
|
||||
|
||||
for image_path, image, label in test_set:
|
||||
result = model.infer(image)[0]
|
||||
predictions = sv.Detections.from_inference(result)
|
||||
|
||||
remap_classes(
|
||||
detections=predictions,
|
||||
class_ids_from_to={16: 0},
|
||||
class_names_from_to={"dog": "Corgi"}
|
||||
)
|
||||
predictions = predictions[
|
||||
np.isin(predictions["class_name"], test_set.classes)
|
||||
]
|
||||
|
||||
image_paths.append(image_path)
|
||||
predictions_list.append(predictions)
|
||||
targets_list.append(label)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
Dataset class names and IDs can be found in the `data.yaml` file, or by printing `dataset.classes`.
|
||||
|
||||
Each model will have a different class mapping, so make sure to check the model's documentation. In this case, the model was trained on the COCO dataset, with a class
|
||||
configuration found [here](https://github.com/ultralytics/ultralytics/blob/main/ultralytics/cfg/datasets/coco8.yaml).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
test_set = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
|
||||
image_paths = []
|
||||
predictions_list = []
|
||||
targets_list = []
|
||||
|
||||
for image_path, image, label in test_set:
|
||||
result = model(image)[0]
|
||||
predictions = sv.Detections.from_ultralytics(result)
|
||||
|
||||
remap_classes(
|
||||
detections=predictions,
|
||||
class_ids_from_to={27: 0},
|
||||
class_names_from_to={"dog": "Corgi"}
|
||||
)
|
||||
predictions = predictions[
|
||||
np.isin(predictions["class_name"], test_set.classes)
|
||||
]
|
||||
|
||||
image_paths.append(image_path)
|
||||
predictions_list.append(predictions)
|
||||
targets_list.append(label)
|
||||
```
|
||||
|
||||
## Visualizing Predictions
|
||||
|
||||
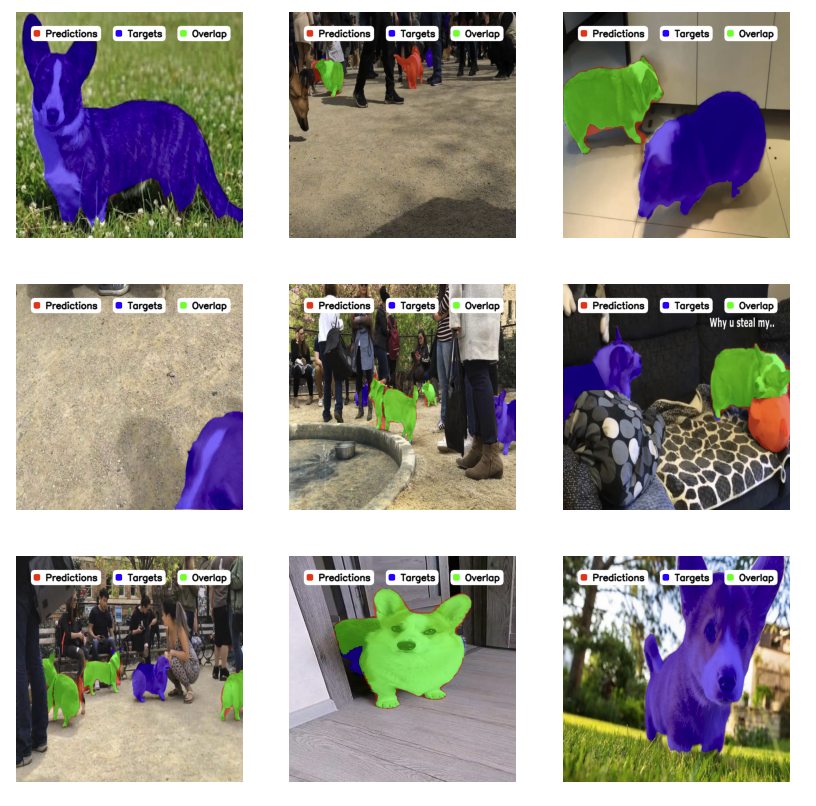
The first step in evaluating your model’s performance is to visualize its predictions.
|
||||
|
|
@ -192,31 +295,31 @@ import supervision as sv
|
|||
N = 9
|
||||
GRID_SIZE = (3, 3)
|
||||
|
||||
box_annotator_predictions = sv.BoxAnnotator(color=sv.Color.BLUE)
|
||||
box_annotator_targets = sv.BoxAnnotator(color=sv.Color.GREEN)
|
||||
target_annotator = sv.PolygonAnnotator(color=sv.Color.from_hex("#8315f9"), thickness=8)
|
||||
prediction_annotator = sv.PolygonAnnotator(color=sv.Color.from_hex("#00cfc6"), thickness=6)
|
||||
|
||||
|
||||
annotated_images = []
|
||||
for image_path, predictions, targets in zip(
|
||||
image_paths[:N], predictions_list[:N], targets_list[:N]
|
||||
):
|
||||
annotated_image = cv2.imread(image_path)
|
||||
annotated_image = box_annotator_targets.annotate(
|
||||
scene=annotated_image, detections=targets
|
||||
)
|
||||
annotated_image = box_annotator_predictions.annotate(
|
||||
scene=annotated_image, detections=predictions
|
||||
)
|
||||
annotated_image = target_annotator.annotate(scene=annotated_image, detections=targets)
|
||||
annotated_image = prediction_annotator.annotate(scene=annotated_image, detections=prediction)
|
||||
annotated_images.append(annotated_image)
|
||||
|
||||
sv.plot_images_grid(images=annotated_images, grid_size=GRID_SIZE)
|
||||
```
|
||||
|
||||
<!-- TODO: grid example -->
|
||||
Here, predictions in purple are targets (ground truth), and predictions in teal are model predictions.
|
||||
|
||||
|
||||
|
||||
!!! tip
|
||||
|
||||
Use `sv.MaskAnnotator` for segmentation and `sv.OrientedBoxAnnotator` for OBB.
|
||||
Use `sv.BoxAnnotator` for object detection and `sv.OrientedBoxAnnotator` for OBB.
|
||||
|
||||
See [annotator documentation](https://supervision.roboflow.com/latest/detection/annotators/) for more details.
|
||||
See [annotator documentation](https://supervision.roboflow.com/latest/detection/annotators/) for even more options.
|
||||
|
||||
## Benchmarking Metrics
|
||||
|
||||
|
|
@ -226,16 +329,16 @@ With multiple models, fine details matter. Visual inspection may not be enough.
|
|||
|
||||
We'll start with [MeanAveragePrecision (mAP)](https://supervision.roboflow.com/latest/metrics/mean_average_precision/#supervision.metrics.mean_average_precision.MeanAveragePrecision), which is the most commonly used metric for object detection. It measures the average precision across all classes and IoU thresholds.
|
||||
|
||||
For a thorough explanation, check out our [blog](https://blog.roboflow.com/mean-average-precision/) or [Youtube video](https://www.youtube.com/watch?v=oqXDdxF_Wuw).
|
||||
For a thorough explanation, check out our [blog](https://blog.roboflow.com/mean-average-precision/) and [Youtube video](https://www.youtube.com/watch?v=oqXDdxF_Wuw).
|
||||
|
||||
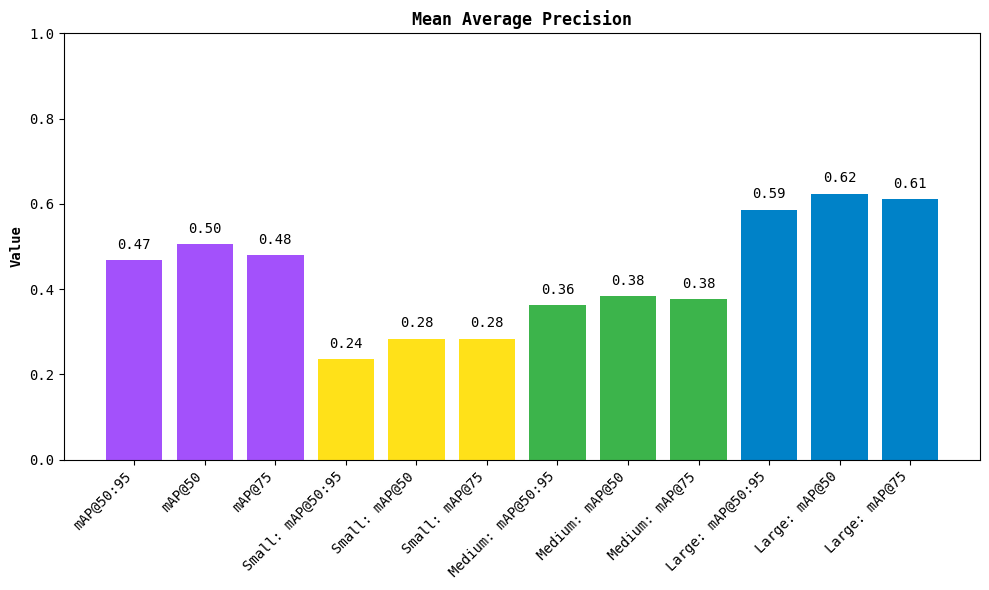
Here, the most important value is `mAP 50:95`. It represents the average precision across all classes and IoU thresholds (`0.5` to `0.95`), whereas other values such as `mAP 50` or `mAP 75` only consider a single IoU threshold (`0.5` and `0.75` respectively).
|
||||
Here, the most popular value is `mAP 50:95`. It represents the average precision across all classes and IoU thresholds (`0.5` to `0.95`), whereas other values such as `mAP 50` or `mAP 75` only consider a single IoU threshold (`0.5` and `0.75` respectively).
|
||||
|
||||
Let's compute the mAP:
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from supervision.metrics import MeanAveragePrecision, MetricTarget
|
||||
|
||||
map_metric = sv.metrics.MeanAveragePrecision()
|
||||
map_metric = MeanAveragePrecision(metric_target=MetricTarget.MASKS)
|
||||
map_result = map_metric.update(predictions_list, targets_list).compute()
|
||||
```
|
||||
|
||||
|
|
@ -247,15 +350,15 @@ print(map_result)
|
|||
|
||||
```
|
||||
MeanAveragePrecisionResult:
|
||||
Metric target: MetricTarget.BOXES
|
||||
Metric target: MetricTarget.MASKS
|
||||
Class agnostic: False
|
||||
mAP @ 50:95: 0.4674
|
||||
mAP @ 50: 0.5048
|
||||
mAP @ 75: 0.4796
|
||||
mAP scores: [0.50485 0.50377 0.50377 ...]
|
||||
IoU thresh: [0.5 0.55 0.6 ...]
|
||||
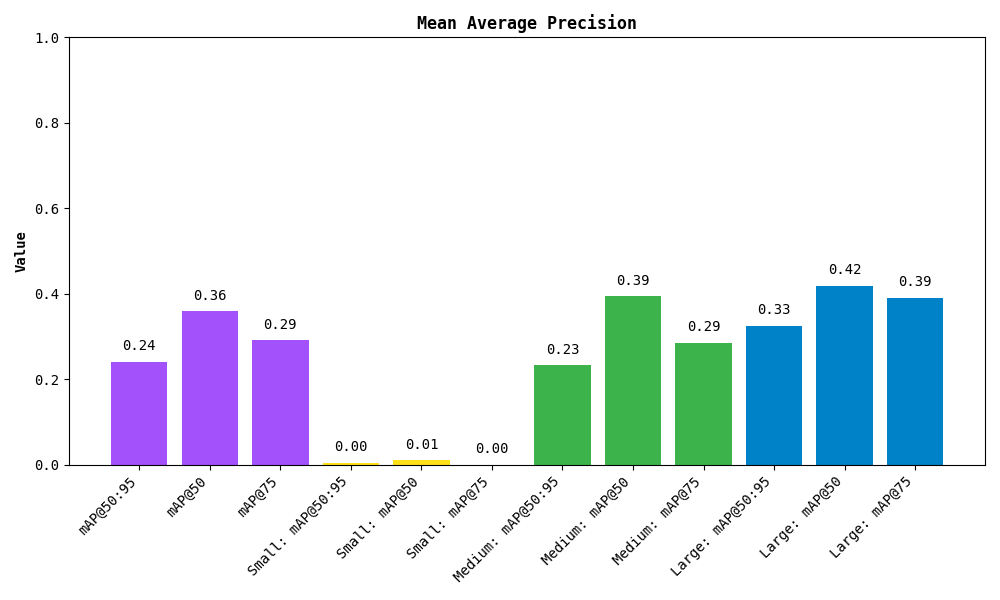
mAP @ 50:95: 0.2409
|
||||
mAP @ 50: 0.3591
|
||||
mAP @ 75: 0.2915
|
||||
mAP scores: [0.35909 0.3468 0.34556 ...]
|
||||
IoU thresh: [0.5 0.55 0.6 ...]
|
||||
AP per class:
|
||||
0: [0.67699 0.67699 0.67699 ...]
|
||||
0: [0.35909 0.3468 0.34556 ...]
|
||||
...
|
||||
Small objects: ...
|
||||
Medium objects: ...
|
||||
|
|
@ -268,7 +371,7 @@ You can also plot the results:
|
|||
map_result.plot()
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
The metric also breaks down the results by detected object area. Small, medium and large are simply those with area less than 32², between 32² and 96², and greater than 96² pixels respectively.
|
||||
|
||||
|
|
@ -279,9 +382,9 @@ The [F1 Score](https://supervision.roboflow.com/latest/metrics/f1_score/) is ano
|
|||
Here's how you can compute the F1 score:
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from supervision.metrics import F1Score, MetricTarget
|
||||
|
||||
f1_metric = sv.metrics.F1Score()
|
||||
f1_metric = F1Score(metric_target=MetricTarget.MASKS)
|
||||
f1_result = f1_metric.update(predictions_list, targets_list).compute()
|
||||
```
|
||||
|
||||
|
|
@ -293,14 +396,14 @@ print(f1_result)
|
|||
|
||||
```
|
||||
F1ScoreResult:
|
||||
Metric target: MetricTarget.BOXES
|
||||
Metric target: MetricTarget.MASKS
|
||||
Averaging method: AveragingMethod.WEIGHTED
|
||||
F1 @ 50: 0.7618
|
||||
F1 @ 75: 0.7487
|
||||
F1 @ thresh: [0.76175 0.76068 0.76068]
|
||||
IoU thresh: [0.5 0.55 0.6 ...]
|
||||
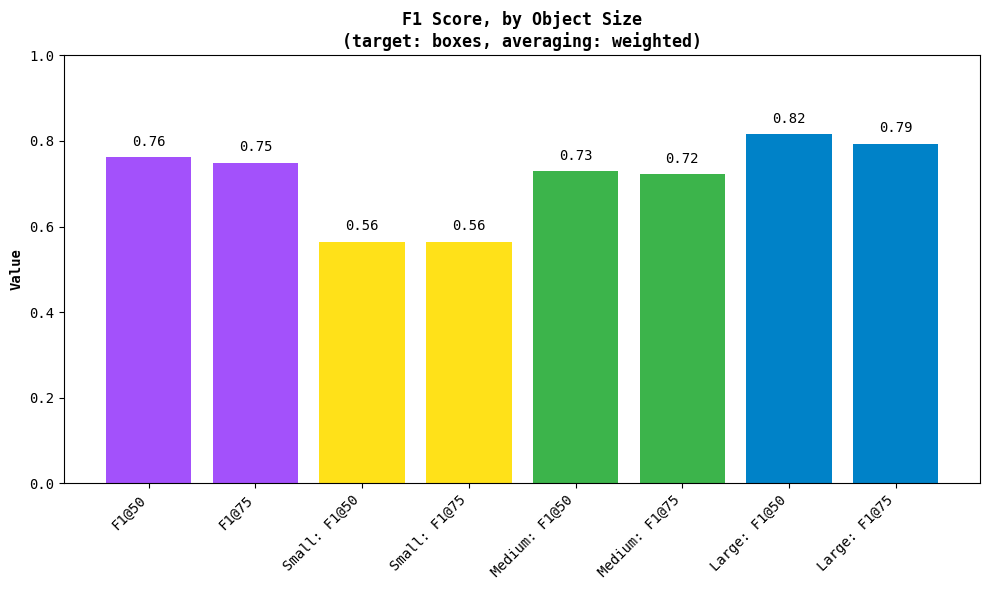
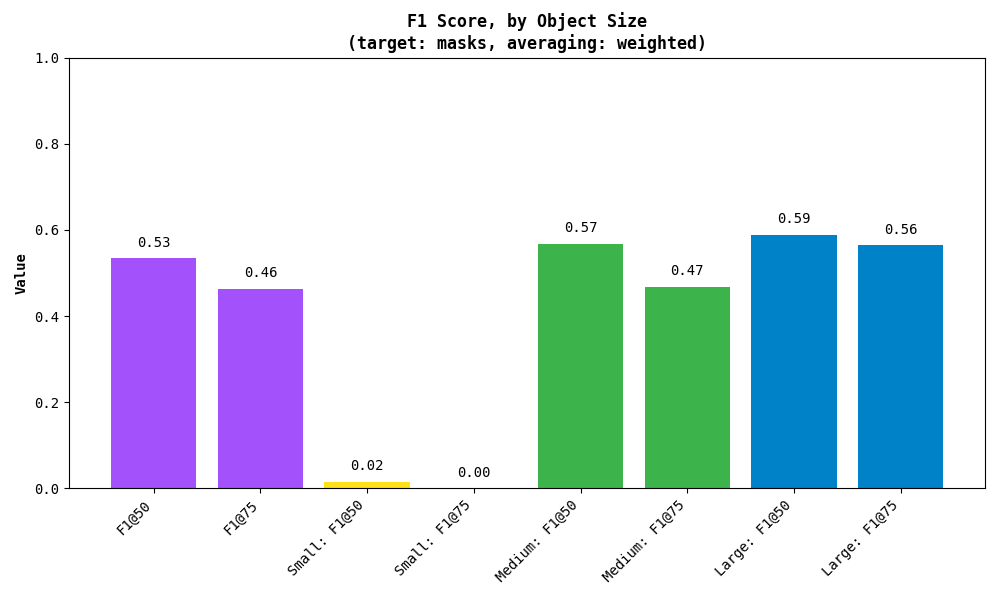
F1 @ 50: 0.5341
|
||||
F1 @ 75: 0.4636
|
||||
F1 @ thresh: [0.53406 0.5278 0.52153 ...]
|
||||
IoU thresh: [0.5 0.55 0.6 ...]
|
||||
F1 per class:
|
||||
0: [0.70968 0.70968 0.70968 ...]
|
||||
0: [0.53406 0.5278 0.52153 ...]
|
||||
...
|
||||
Small objects: ...
|
||||
Medium objects: ...
|
||||
|
|
@ -313,7 +416,7 @@ Similarly, you can plot the results:
|
|||
f1_result.plot()
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
As with mAP, the metric also breaks down the results by detected object area. Small, medium and large are simply those with area less than 32², between 32² and 96², and greater than 96² pixels respectively.
|
||||
|
||||
|
|
|
|||
Loading…
Reference in New Issue