
1533 lines
53 KiB
Python
1533 lines
53 KiB
Python
from __future__ import annotations
|
|
|
|
from dataclasses import dataclass, field
|
|
from typing import Any, Dict, Iterator, List, Optional, Tuple, Union
|
|
|
|
import numpy as np
|
|
|
|
from supervision.config import (
|
|
CLASS_NAME_DATA_FIELD,
|
|
ORIENTED_BOX_COORDINATES,
|
|
)
|
|
from supervision.detection.lmm import (
|
|
LMM,
|
|
from_florence_2,
|
|
from_paligemma,
|
|
validate_lmm_parameters,
|
|
)
|
|
from supervision.detection.overlap_filter import (
|
|
box_non_max_merge,
|
|
box_non_max_suppression,
|
|
mask_non_max_suppression,
|
|
)
|
|
from supervision.detection.tools.transformers import (
|
|
process_transformers_detection_result,
|
|
process_transformers_v4_segmentation_result,
|
|
process_transformers_v5_segmentation_result,
|
|
)
|
|
from supervision.detection.utils import (
|
|
box_iou_batch,
|
|
calculate_masks_centroids,
|
|
extract_ultralytics_masks,
|
|
get_data_item,
|
|
is_data_equal,
|
|
is_metadata_equal,
|
|
mask_to_xyxy,
|
|
merge_data,
|
|
merge_metadata,
|
|
process_roboflow_result,
|
|
xywh_to_xyxy,
|
|
)
|
|
from supervision.geometry.core import Position
|
|
from supervision.utils.internal import get_instance_variables
|
|
from supervision.validators import validate_detections_fields
|
|
|
|
|
|
@dataclass
|
|
class Detections:
|
|
"""
|
|
The `sv.Detections` class in the Supervision library standardizes results from
|
|
various object detection and segmentation models into a consistent format. This
|
|
class simplifies data manipulation and filtering, providing a uniform API for
|
|
integration with Supervision [trackers](/trackers/), [annotators](/latest/detection/annotators/), and [tools](/detection/tools/line_zone/).
|
|
|
|
=== "Inference"
|
|
|
|
Use [`sv.Detections.from_inference`](/detection/core/#supervision.detection.core.Detections.from_inference)
|
|
method, which accepts model results from both detection and segmentation models.
|
|
|
|
```python
|
|
import cv2
|
|
import supervision as sv
|
|
from inference import get_model
|
|
|
|
model = get_model(model_id="yolov8n-640")
|
|
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
|
results = model.infer(image)[0]
|
|
detections = sv.Detections.from_inference(results)
|
|
```
|
|
|
|
=== "Ultralytics"
|
|
|
|
Use [`sv.Detections.from_ultralytics`](/detection/core/#supervision.detection.core.Detections.from_ultralytics)
|
|
method, which accepts model results from both detection and segmentation models.
|
|
|
|
```python
|
|
import cv2
|
|
import supervision as sv
|
|
from ultralytics import YOLO
|
|
|
|
model = YOLO("yolov8n.pt")
|
|
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
|
results = model(image)[0]
|
|
detections = sv.Detections.from_ultralytics(results)
|
|
```
|
|
|
|
=== "Transformers"
|
|
|
|
Use [`sv.Detections.from_transformers`](/detection/core/#supervision.detection.core.Detections.from_transformers)
|
|
method, which accepts model results from both detection and segmentation models.
|
|
|
|
```python
|
|
import torch
|
|
import supervision as sv
|
|
from PIL import Image
|
|
from transformers import DetrImageProcessor, DetrForObjectDetection
|
|
|
|
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
|
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
|
|
|
image = Image.open(<SOURCE_IMAGE_PATH>)
|
|
inputs = processor(images=image, return_tensors="pt")
|
|
|
|
with torch.no_grad():
|
|
outputs = model(**inputs)
|
|
|
|
width, height = image.size
|
|
target_size = torch.tensor([[height, width]])
|
|
results = processor.post_process_object_detection(
|
|
outputs=outputs, target_sizes=target_size)[0]
|
|
detections = sv.Detections.from_transformers(
|
|
transformers_results=results,
|
|
id2label=model.config.id2label)
|
|
```
|
|
|
|
Attributes:
|
|
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
|
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
|
mask: (Optional[np.ndarray]): An array of shape
|
|
`(n, H, W)` containing the segmentation masks (`bool` data type).
|
|
confidence (Optional[np.ndarray]): An array of shape
|
|
`(n,)` containing the confidence scores of the detections.
|
|
class_id (Optional[np.ndarray]): An array of shape
|
|
`(n,)` containing the class ids of the detections.
|
|
tracker_id (Optional[np.ndarray]): An array of shape
|
|
`(n,)` containing the tracker ids of the detections.
|
|
data (Dict[str, Union[np.ndarray, List]]): A dictionary containing additional
|
|
data where each key is a string representing the data type, and the value
|
|
is either a NumPy array or a list of corresponding data.
|
|
metadata (Dict[str, Any]): A dictionary containing collection-level metadata
|
|
that applies to the entire set of detections. This may include information such
|
|
as the video name, camera parameters, timestamp, or other global metadata.
|
|
""" # noqa: E501 // docs
|
|
|
|
xyxy: np.ndarray
|
|
mask: Optional[np.ndarray] = None
|
|
confidence: Optional[np.ndarray] = None
|
|
class_id: Optional[np.ndarray] = None
|
|
tracker_id: Optional[np.ndarray] = None
|
|
data: Dict[str, Union[np.ndarray, List]] = field(default_factory=dict)
|
|
metadata: Dict[str, Any] = field(default_factory=dict)
|
|
|
|
def __post_init__(self):
|
|
validate_detections_fields(
|
|
xyxy=self.xyxy,
|
|
mask=self.mask,
|
|
confidence=self.confidence,
|
|
class_id=self.class_id,
|
|
tracker_id=self.tracker_id,
|
|
data=self.data,
|
|
)
|
|
|
|
def __len__(self):
|
|
"""
|
|
Returns the number of detections in the Detections object.
|
|
"""
|
|
return len(self.xyxy)
|
|
|
|
def __iter__(
|
|
self,
|
|
) -> Iterator[
|
|
Tuple[
|
|
np.ndarray,
|
|
Optional[np.ndarray],
|
|
Optional[float],
|
|
Optional[int],
|
|
Optional[int],
|
|
Dict[str, Union[np.ndarray, List]],
|
|
]
|
|
]:
|
|
"""
|
|
Iterates over the Detections object and yield a tuple of
|
|
`(xyxy, mask, confidence, class_id, tracker_id, data)` for each detection.
|
|
"""
|
|
for i in range(len(self.xyxy)):
|
|
yield (
|
|
self.xyxy[i],
|
|
self.mask[i] if self.mask is not None else None,
|
|
self.confidence[i] if self.confidence is not None else None,
|
|
self.class_id[i] if self.class_id is not None else None,
|
|
self.tracker_id[i] if self.tracker_id is not None else None,
|
|
get_data_item(self.data, i),
|
|
)
|
|
|
|
def __eq__(self, other: Detections):
|
|
return all(
|
|
[
|
|
np.array_equal(self.xyxy, other.xyxy),
|
|
np.array_equal(self.mask, other.mask),
|
|
np.array_equal(self.class_id, other.class_id),
|
|
np.array_equal(self.confidence, other.confidence),
|
|
np.array_equal(self.tracker_id, other.tracker_id),
|
|
is_data_equal(self.data, other.data),
|
|
is_metadata_equal(self.metadata, other.metadata),
|
|
]
|
|
)
|
|
|
|
@classmethod
|
|
def from_yolov5(cls, yolov5_results) -> Detections:
|
|
"""
|
|
Creates a Detections instance from a
|
|
[YOLOv5](https://github.com/ultralytics/yolov5) inference result.
|
|
|
|
Args:
|
|
yolov5_results (yolov5.models.common.Detections):
|
|
The output Detections instance from YOLOv5
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import cv2
|
|
import torch
|
|
import supervision as sv
|
|
|
|
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
|
model = torch.hub.load('ultralytics/yolov5', 'yolov5s')
|
|
result = model(image)
|
|
detections = sv.Detections.from_yolov5(result)
|
|
```
|
|
"""
|
|
yolov5_detections_predictions = yolov5_results.pred[0].cpu().cpu().numpy()
|
|
|
|
return cls(
|
|
xyxy=yolov5_detections_predictions[:, :4],
|
|
confidence=yolov5_detections_predictions[:, 4],
|
|
class_id=yolov5_detections_predictions[:, 5].astype(int),
|
|
)
|
|
|
|
@classmethod
|
|
def from_ultralytics(cls, ultralytics_results) -> Detections:
|
|
"""
|
|
Creates a `sv.Detections` instance from a
|
|
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
|
|
|
!!! Note
|
|
|
|
`from_ultralytics` is compatible with
|
|
[detection](https://docs.ultralytics.com/tasks/detect/),
|
|
[segmentation](https://docs.ultralytics.com/tasks/segment/), and
|
|
[OBB](https://docs.ultralytics.com/tasks/obb/) models.
|
|
|
|
Args:
|
|
ultralytics_results (ultralytics.yolo.engine.results.Results):
|
|
The output Results instance from Ultralytics
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import cv2
|
|
import supervision as sv
|
|
from ultralytics import YOLO
|
|
|
|
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
|
model = YOLO('yolov8s.pt')
|
|
results = model(image)[0]
|
|
detections = sv.Detections.from_ultralytics(results)
|
|
```
|
|
"""
|
|
|
|
if hasattr(ultralytics_results, "obb") and ultralytics_results.obb is not None:
|
|
class_id = ultralytics_results.obb.cls.cpu().numpy().astype(int)
|
|
class_names = np.array([ultralytics_results.names[i] for i in class_id])
|
|
oriented_box_coordinates = ultralytics_results.obb.xyxyxyxy.cpu().numpy()
|
|
return cls(
|
|
xyxy=ultralytics_results.obb.xyxy.cpu().numpy(),
|
|
confidence=ultralytics_results.obb.conf.cpu().numpy(),
|
|
class_id=class_id,
|
|
tracker_id=ultralytics_results.obb.id.int().cpu().numpy()
|
|
if ultralytics_results.obb.id is not None
|
|
else None,
|
|
data={
|
|
ORIENTED_BOX_COORDINATES: oriented_box_coordinates,
|
|
CLASS_NAME_DATA_FIELD: class_names,
|
|
},
|
|
)
|
|
|
|
if hasattr(ultralytics_results, "boxes") and ultralytics_results.boxes is None:
|
|
masks = extract_ultralytics_masks(ultralytics_results)
|
|
return cls(
|
|
xyxy=mask_to_xyxy(masks),
|
|
mask=masks,
|
|
class_id=np.arange(len(ultralytics_results)),
|
|
)
|
|
|
|
class_id = ultralytics_results.boxes.cls.cpu().numpy().astype(int)
|
|
class_names = np.array([ultralytics_results.names[i] for i in class_id])
|
|
return cls(
|
|
xyxy=ultralytics_results.boxes.xyxy.cpu().numpy(),
|
|
confidence=ultralytics_results.boxes.conf.cpu().numpy(),
|
|
class_id=class_id,
|
|
mask=extract_ultralytics_masks(ultralytics_results),
|
|
tracker_id=ultralytics_results.boxes.id.int().cpu().numpy()
|
|
if ultralytics_results.boxes.id is not None
|
|
else None,
|
|
data={CLASS_NAME_DATA_FIELD: class_names},
|
|
)
|
|
|
|
@classmethod
|
|
def from_yolo_nas(cls, yolo_nas_results) -> Detections:
|
|
"""
|
|
Creates a Detections instance from a
|
|
[YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md)
|
|
inference result.
|
|
|
|
Args:
|
|
yolo_nas_results (ImageDetectionPrediction):
|
|
The output Results instance from YOLO-NAS
|
|
ImageDetectionPrediction is coming from
|
|
'super_gradients.training.models.prediction_results'
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import cv2
|
|
from super_gradients.training import models
|
|
import supervision as sv
|
|
|
|
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
|
model = models.get('yolo_nas_l', pretrained_weights="coco")
|
|
|
|
result = list(model.predict(image, conf=0.35))[0]
|
|
detections = sv.Detections.from_yolo_nas(result)
|
|
```
|
|
"""
|
|
if np.asarray(yolo_nas_results.prediction.bboxes_xyxy).shape[0] == 0:
|
|
return cls.empty()
|
|
|
|
return cls(
|
|
xyxy=yolo_nas_results.prediction.bboxes_xyxy,
|
|
confidence=yolo_nas_results.prediction.confidence,
|
|
class_id=yolo_nas_results.prediction.labels.astype(int),
|
|
)
|
|
|
|
@classmethod
|
|
def from_tensorflow(
|
|
cls, tensorflow_results: dict, resolution_wh: tuple
|
|
) -> Detections:
|
|
"""
|
|
Creates a Detections instance from a
|
|
[Tensorflow Hub](https://www.tensorflow.org/hub/tutorials/tf2_object_detection)
|
|
inference result.
|
|
|
|
Args:
|
|
tensorflow_results (dict):
|
|
The output results from Tensorflow Hub.
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import tensorflow as tf
|
|
import tensorflow_hub as hub
|
|
import numpy as np
|
|
import cv2
|
|
|
|
module_handle = "https://tfhub.dev/tensorflow/centernet/hourglass_512x512_kpts/1"
|
|
model = hub.load(module_handle)
|
|
img = np.array(cv2.imread(SOURCE_IMAGE_PATH))
|
|
result = model(img)
|
|
detections = sv.Detections.from_tensorflow(result)
|
|
```
|
|
"""
|
|
|
|
boxes = tensorflow_results["detection_boxes"][0].numpy()
|
|
boxes[:, [0, 2]] *= resolution_wh[0]
|
|
boxes[:, [1, 3]] *= resolution_wh[1]
|
|
boxes = boxes[:, [1, 0, 3, 2]]
|
|
return cls(
|
|
xyxy=boxes,
|
|
confidence=tensorflow_results["detection_scores"][0].numpy(),
|
|
class_id=tensorflow_results["detection_classes"][0].numpy().astype(int),
|
|
)
|
|
|
|
@classmethod
|
|
def from_deepsparse(cls, deepsparse_results) -> Detections:
|
|
"""
|
|
Creates a Detections instance from a
|
|
[DeepSparse](https://github.com/neuralmagic/deepsparse)
|
|
inference result.
|
|
|
|
Args:
|
|
deepsparse_results (deepsparse.yolo.schemas.YOLOOutput):
|
|
The output Results instance from DeepSparse.
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import supervision as sv
|
|
from deepsparse import Pipeline
|
|
|
|
yolo_pipeline = Pipeline.create(
|
|
task="yolo",
|
|
model_path = "zoo:cv/detection/yolov5-l/pytorch/ultralytics/coco/pruned80_quant-none"
|
|
)
|
|
result = yolo_pipeline(<SOURCE IMAGE PATH>)
|
|
detections = sv.Detections.from_deepsparse(result)
|
|
```
|
|
""" # noqa: E501 // docs
|
|
|
|
if np.asarray(deepsparse_results.boxes[0]).shape[0] == 0:
|
|
return cls.empty()
|
|
|
|
return cls(
|
|
xyxy=np.array(deepsparse_results.boxes[0]),
|
|
confidence=np.array(deepsparse_results.scores[0]),
|
|
class_id=np.array(deepsparse_results.labels[0]).astype(float).astype(int),
|
|
)
|
|
|
|
@classmethod
|
|
def from_mmdetection(cls, mmdet_results) -> Detections:
|
|
"""
|
|
Creates a Detections instance from a
|
|
[mmdetection](https://github.com/open-mmlab/mmdetection) and
|
|
[mmyolo](https://github.com/open-mmlab/mmyolo) inference result.
|
|
|
|
Args:
|
|
mmdet_results (mmdet.structures.DetDataSample):
|
|
The output Results instance from MMDetection.
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import cv2
|
|
import supervision as sv
|
|
from mmdet.apis import init_detector, inference_detector
|
|
|
|
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
|
model = init_detector(<CONFIG_PATH>, <WEIGHTS_PATH>, device=<DEVICE>)
|
|
|
|
result = inference_detector(model, image)
|
|
detections = sv.Detections.from_mmdetection(result)
|
|
```
|
|
"""
|
|
|
|
return cls(
|
|
xyxy=mmdet_results.pred_instances.bboxes.cpu().numpy(),
|
|
confidence=mmdet_results.pred_instances.scores.cpu().numpy(),
|
|
class_id=mmdet_results.pred_instances.labels.cpu().numpy().astype(int),
|
|
mask=mmdet_results.pred_instances.masks.cpu().numpy()
|
|
if "masks" in mmdet_results.pred_instances
|
|
else None,
|
|
)
|
|
|
|
@classmethod
|
|
def from_transformers(
|
|
cls, transformers_results: dict, id2label: Optional[Dict[int, str]] = None
|
|
) -> Detections:
|
|
"""
|
|
Creates a Detections instance from object detection or panoptic, semantic
|
|
and instance segmentation
|
|
[Transformer](https://github.com/huggingface/transformers) inference result.
|
|
|
|
Args:
|
|
transformers_results (Union[dict, torch.Tensor]): Inference results from
|
|
your Transformers model. This can be either a dictionary containing
|
|
valuable outputs like `scores`, `labels`, `boxes`, `masks`,
|
|
`segments_info`, and `segmentation`, or a `torch.Tensor` holding a
|
|
segmentation map where values represent class IDs.
|
|
id2label (Optional[Dict[int, str]]): A dictionary mapping class IDs to
|
|
labels, typically part of the `transformers` model configuration. If
|
|
provided, the resulting dictionary will include class names.
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import torch
|
|
import supervision as sv
|
|
from PIL import Image
|
|
from transformers import DetrImageProcessor, DetrForObjectDetection
|
|
|
|
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
|
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
|
|
|
image = Image.open(<SOURCE_IMAGE_PATH>)
|
|
inputs = processor(images=image, return_tensors="pt")
|
|
|
|
with torch.no_grad():
|
|
outputs = model(**inputs)
|
|
|
|
width, height = image.size
|
|
target_size = torch.tensor([[height, width]])
|
|
results = processor.post_process_object_detection(
|
|
outputs=outputs, target_sizes=target_size)[0]
|
|
|
|
detections = sv.Detections.from_transformers(
|
|
transformers_results=results,
|
|
id2label=model.config.id2label
|
|
)
|
|
```
|
|
"""
|
|
|
|
if (
|
|
transformers_results.__class__.__name__ == "Tensor"
|
|
or "segmentation" in transformers_results
|
|
):
|
|
return cls(
|
|
**process_transformers_v5_segmentation_result(
|
|
transformers_results, id2label
|
|
)
|
|
)
|
|
|
|
if "masks" in transformers_results or "png_string" in transformers_results:
|
|
return cls(
|
|
**process_transformers_v4_segmentation_result(
|
|
transformers_results, id2label
|
|
)
|
|
)
|
|
|
|
if "boxes" in transformers_results:
|
|
return cls(
|
|
**process_transformers_detection_result(transformers_results, id2label)
|
|
)
|
|
|
|
else:
|
|
raise ValueError(
|
|
"The provided Transformers results do not contain any valid fields."
|
|
" Expected fields are 'boxes', 'masks', 'segments_info' or"
|
|
" 'segmentation'."
|
|
)
|
|
|
|
@classmethod
|
|
def from_detectron2(cls, detectron2_results: Any) -> Detections:
|
|
"""
|
|
Create a Detections object from the
|
|
[Detectron2](https://github.com/facebookresearch/detectron2) inference result.
|
|
|
|
Args:
|
|
detectron2_results (Any): The output of a
|
|
Detectron2 model containing instances with prediction data.
|
|
|
|
Returns:
|
|
(Detections): A Detections object containing the bounding boxes,
|
|
class IDs, and confidences of the predictions.
|
|
|
|
Example:
|
|
```python
|
|
import cv2
|
|
import supervision as sv
|
|
from detectron2.engine import DefaultPredictor
|
|
from detectron2.config import get_cfg
|
|
|
|
|
|
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
|
cfg = get_cfg()
|
|
cfg.merge_from_file(<CONFIG_PATH>)
|
|
cfg.MODEL.WEIGHTS = <WEIGHTS_PATH>
|
|
predictor = DefaultPredictor(cfg)
|
|
|
|
result = predictor(image)
|
|
detections = sv.Detections.from_detectron2(result)
|
|
```
|
|
"""
|
|
|
|
return cls(
|
|
xyxy=detectron2_results["instances"].pred_boxes.tensor.cpu().numpy(),
|
|
confidence=detectron2_results["instances"].scores.cpu().numpy(),
|
|
mask=detectron2_results["instances"].pred_masks.cpu().numpy()
|
|
if hasattr(detectron2_results["instances"], "pred_masks")
|
|
else None,
|
|
class_id=detectron2_results["instances"]
|
|
.pred_classes.cpu()
|
|
.numpy()
|
|
.astype(int),
|
|
)
|
|
|
|
@classmethod
|
|
def from_inference(cls, roboflow_result: Union[dict, Any]) -> Detections:
|
|
"""
|
|
Create a `sv.Detections` object from the [Roboflow](https://roboflow.com/)
|
|
API inference result or the [Inference](https://inference.roboflow.com/)
|
|
package results. This method extracts bounding boxes, class IDs,
|
|
confidences, and class names from the Roboflow API result and encapsulates
|
|
them into a Detections object.
|
|
|
|
Args:
|
|
roboflow_result (dict, any): The result from the
|
|
Roboflow API or Inference package containing predictions.
|
|
|
|
Returns:
|
|
(Detections): A Detections object containing the bounding boxes, class IDs,
|
|
and confidences of the predictions.
|
|
|
|
Example:
|
|
```python
|
|
import cv2
|
|
import supervision as sv
|
|
from inference import get_model
|
|
|
|
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
|
model = get_model(model_id="yolov8s-640")
|
|
|
|
result = model.infer(image)[0]
|
|
detections = sv.Detections.from_inference(result)
|
|
```
|
|
"""
|
|
if hasattr(roboflow_result, "dict"):
|
|
roboflow_result = roboflow_result.dict(exclude_none=True, by_alias=True)
|
|
elif hasattr(roboflow_result, "json"):
|
|
roboflow_result = roboflow_result.json()
|
|
xyxy, confidence, class_id, masks, trackers, data = process_roboflow_result(
|
|
roboflow_result=roboflow_result
|
|
)
|
|
|
|
if np.asarray(xyxy).shape[0] == 0:
|
|
empty_detection = cls.empty()
|
|
empty_detection.data = {CLASS_NAME_DATA_FIELD: np.empty(0)}
|
|
return empty_detection
|
|
|
|
return cls(
|
|
xyxy=xyxy,
|
|
confidence=confidence,
|
|
class_id=class_id,
|
|
mask=masks,
|
|
tracker_id=trackers,
|
|
data=data,
|
|
)
|
|
|
|
@classmethod
|
|
def from_sam(cls, sam_result: List[dict]) -> Detections:
|
|
"""
|
|
Creates a Detections instance from
|
|
[Segment Anything Model](https://github.com/facebookresearch/segment-anything)
|
|
inference result.
|
|
|
|
Args:
|
|
sam_result (List[dict]): The output Results instance from SAM
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import supervision as sv
|
|
from segment_anything import (
|
|
sam_model_registry,
|
|
SamAutomaticMaskGenerator
|
|
)
|
|
|
|
sam_model_reg = sam_model_registry[MODEL_TYPE]
|
|
sam = sam_model_reg(checkpoint=CHECKPOINT_PATH).to(device=DEVICE)
|
|
mask_generator = SamAutomaticMaskGenerator(sam)
|
|
sam_result = mask_generator.generate(IMAGE)
|
|
detections = sv.Detections.from_sam(sam_result=sam_result)
|
|
```
|
|
"""
|
|
|
|
sorted_generated_masks = sorted(
|
|
sam_result, key=lambda x: x["area"], reverse=True
|
|
)
|
|
|
|
xywh = np.array([mask["bbox"] for mask in sorted_generated_masks])
|
|
mask = np.array([mask["segmentation"] for mask in sorted_generated_masks])
|
|
|
|
if np.asarray(xywh).shape[0] == 0:
|
|
return cls.empty()
|
|
|
|
xyxy = xywh_to_xyxy(xywh=xywh)
|
|
return cls(xyxy=xyxy, mask=mask)
|
|
|
|
@classmethod
|
|
def from_azure_analyze_image(
|
|
cls, azure_result: dict, class_map: Optional[Dict[int, str]] = None
|
|
) -> Detections:
|
|
"""
|
|
Creates a Detections instance from [Azure Image Analysis 4.0](
|
|
https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/
|
|
concept-object-detection-40).
|
|
|
|
Args:
|
|
azure_result (dict): The result from Azure Image Analysis. It should
|
|
contain detected objects and their bounding box coordinates.
|
|
class_map (Optional[Dict[int, str]]): A mapping ofclass IDs (int) to class
|
|
names (str). If None, a new mapping is created dynamically.
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import requests
|
|
import supervision as sv
|
|
|
|
image = open(input, "rb").read()
|
|
|
|
endpoint = "https://.cognitiveservices.azure.com/"
|
|
subscription_key = ""
|
|
|
|
headers = {
|
|
"Content-Type": "application/octet-stream",
|
|
"Ocp-Apim-Subscription-Key": subscription_key
|
|
}
|
|
|
|
response = requests.post(endpoint,
|
|
headers=self.headers,
|
|
data=image
|
|
).json()
|
|
|
|
detections = sv.Detections.from_azure_analyze_image(response)
|
|
```
|
|
"""
|
|
if "error" in azure_result:
|
|
raise ValueError(
|
|
f'Azure API returned an error {azure_result["error"]["message"]}'
|
|
)
|
|
|
|
xyxy, confidences, class_ids = [], [], []
|
|
|
|
is_dynamic_mapping = class_map is None
|
|
if is_dynamic_mapping:
|
|
class_map = {}
|
|
|
|
class_map = {value: key for key, value in class_map.items()}
|
|
|
|
for detection in azure_result["objectsResult"]["values"]:
|
|
bbox = detection["boundingBox"]
|
|
|
|
tags = detection["tags"]
|
|
|
|
x0 = bbox["x"]
|
|
y0 = bbox["y"]
|
|
x1 = x0 + bbox["w"]
|
|
y1 = y0 + bbox["h"]
|
|
|
|
for tag in tags:
|
|
confidence = tag["confidence"]
|
|
class_name = tag["name"]
|
|
class_id = class_map.get(class_name, None)
|
|
|
|
if is_dynamic_mapping and class_id is None:
|
|
class_id = len(class_map)
|
|
class_map[class_name] = class_id
|
|
|
|
if class_id is not None:
|
|
xyxy.append([x0, y0, x1, y1])
|
|
confidences.append(confidence)
|
|
class_ids.append(class_id)
|
|
|
|
if len(xyxy) == 0:
|
|
return Detections.empty()
|
|
|
|
return cls(
|
|
xyxy=np.array(xyxy),
|
|
class_id=np.array(class_ids),
|
|
confidence=np.array(confidences),
|
|
)
|
|
|
|
@classmethod
|
|
def from_paddledet(cls, paddledet_result) -> Detections:
|
|
"""
|
|
Creates a Detections instance from
|
|
[PaddleDetection](https://github.com/PaddlePaddle/PaddleDetection)
|
|
inference result.
|
|
|
|
Args:
|
|
paddledet_result (List[dict]): The output Results instance from PaddleDet
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import supervision as sv
|
|
import paddle
|
|
from ppdet.engine import Trainer
|
|
from ppdet.core.workspace import load_config
|
|
|
|
weights = ()
|
|
config = ()
|
|
|
|
cfg = load_config(config)
|
|
trainer = Trainer(cfg, mode='test')
|
|
trainer.load_weights(weights)
|
|
|
|
paddledet_result = trainer.predict([images])[0]
|
|
|
|
detections = sv.Detections.from_paddledet(paddledet_result)
|
|
```
|
|
"""
|
|
|
|
if np.asarray(paddledet_result["bbox"][:, 2:6]).shape[0] == 0:
|
|
return cls.empty()
|
|
|
|
return cls(
|
|
xyxy=paddledet_result["bbox"][:, 2:6],
|
|
confidence=paddledet_result["bbox"][:, 1],
|
|
class_id=paddledet_result["bbox"][:, 0].astype(int),
|
|
)
|
|
|
|
@classmethod
|
|
def from_lmm(
|
|
cls, lmm: Union[LMM, str], result: Union[str, dict], **kwargs: Any
|
|
) -> Detections:
|
|
"""
|
|
Creates a Detections object from the given result string based on the specified
|
|
Large Multimodal Model (LMM).
|
|
|
|
Args:
|
|
lmm (Union[LMM, str]): The type of LMM (Large Multimodal Model) to use.
|
|
result (str): The result string containing the detection data.
|
|
**kwargs (Any): Additional keyword arguments required by the specified LMM.
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Raises:
|
|
ValueError: If the LMM is invalid, required arguments are missing, or
|
|
disallowed arguments are provided.
|
|
ValueError: If the specified LMM is not supported.
|
|
|
|
Examples:
|
|
```python
|
|
import supervision as sv
|
|
|
|
paligemma_result = "<loc0256><loc0256><loc0768><loc0768> cat"
|
|
detections = sv.Detections.from_lmm(
|
|
sv.LMM.PALIGEMMA,
|
|
paligemma_result,
|
|
resolution_wh=(1000, 1000),
|
|
classes=['cat', 'dog']
|
|
)
|
|
detections.xyxy
|
|
# array([[250., 250., 750., 750.]])
|
|
|
|
detections.class_id
|
|
# array([0])
|
|
```
|
|
"""
|
|
lmm = validate_lmm_parameters(lmm, result, kwargs)
|
|
|
|
if lmm == LMM.PALIGEMMA:
|
|
assert isinstance(result, str)
|
|
xyxy, class_id, class_name = from_paligemma(result, **kwargs)
|
|
data = {CLASS_NAME_DATA_FIELD: class_name}
|
|
return cls(xyxy=xyxy, class_id=class_id, data=data)
|
|
|
|
if lmm == LMM.FLORENCE_2:
|
|
assert isinstance(result, dict)
|
|
xyxy, labels, mask, xyxyxyxy = from_florence_2(result, **kwargs)
|
|
if len(xyxy) == 0:
|
|
return cls.empty()
|
|
|
|
data = {}
|
|
if labels is not None:
|
|
data[CLASS_NAME_DATA_FIELD] = labels
|
|
if xyxyxyxy is not None:
|
|
data[ORIENTED_BOX_COORDINATES] = xyxyxyxy
|
|
|
|
return cls(xyxy=xyxy, mask=mask, data=data)
|
|
|
|
raise ValueError(f"Unsupported LMM: {lmm}")
|
|
|
|
@classmethod
|
|
def from_easyocr(cls, easyocr_results: list) -> Detections:
|
|
"""
|
|
Create a Detections object from the
|
|
[EasyOCR](https://github.com/JaidedAI/EasyOCR) result.
|
|
|
|
Results are placed in the `data` field with the key `"class_name"`.
|
|
|
|
Args:
|
|
easyocr_results (List): The output Results instance from EasyOCR
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import supervision as sv
|
|
import easyocr
|
|
|
|
reader = easyocr.Reader(['en'])
|
|
results = reader.readtext(<SOURCE_IMAGE_PATH>)
|
|
detections = sv.Detections.from_easyocr(results)
|
|
detected_text = detections["class_name"]
|
|
```
|
|
"""
|
|
if len(easyocr_results) == 0:
|
|
return cls.empty()
|
|
|
|
bbox = np.array([result[0] for result in easyocr_results])
|
|
xyxy = np.hstack((np.min(bbox, axis=1), np.max(bbox, axis=1)))
|
|
confidence = np.array(
|
|
[
|
|
result[2] if len(result) > 2 and result[2] else 0
|
|
for result in easyocr_results
|
|
]
|
|
)
|
|
ocr_text = np.array([result[1] for result in easyocr_results])
|
|
|
|
return cls(
|
|
xyxy=xyxy.astype(np.float32),
|
|
confidence=confidence.astype(np.float32),
|
|
data={
|
|
CLASS_NAME_DATA_FIELD: ocr_text,
|
|
},
|
|
)
|
|
|
|
@classmethod
|
|
def from_ncnn(cls, ncnn_results) -> Detections:
|
|
"""
|
|
Creates a Detections instance from the
|
|
[ncnn](https://github.com/Tencent/ncnn) inference result.
|
|
Supports object detection models.
|
|
|
|
Arguments:
|
|
ncnn_results (dict): The output Results instance from ncnn.
|
|
|
|
Returns:
|
|
Detections: A new Detections object.
|
|
|
|
Example:
|
|
```python
|
|
import cv2
|
|
from ncnn.model_zoo import get_model
|
|
import supervision as sv
|
|
|
|
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
|
model = get_model(
|
|
"yolov8s",
|
|
target_size=640
|
|
prob_threshold=0.5,
|
|
nms_threshold=0.45,
|
|
num_threads=4,
|
|
use_gpu=True,
|
|
)
|
|
result = model(image)
|
|
detections = sv.Detections.from_ncnn(result)
|
|
```
|
|
"""
|
|
|
|
xywh, confidences, class_ids = [], [], []
|
|
|
|
if len(ncnn_results) == 0:
|
|
return cls.empty()
|
|
|
|
for ncnn_result in ncnn_results:
|
|
rect = ncnn_result.rect
|
|
xywh.append(
|
|
[
|
|
rect.x.astype(np.float32),
|
|
rect.y.astype(np.float32),
|
|
rect.w.astype(np.float32),
|
|
rect.h.astype(np.float32),
|
|
]
|
|
)
|
|
|
|
confidences.append(ncnn_result.prob)
|
|
class_ids.append(ncnn_result.label)
|
|
|
|
return cls(
|
|
xyxy=xywh_to_xyxy(np.array(xywh, dtype=np.float32)),
|
|
confidence=np.array(confidences, dtype=np.float32),
|
|
class_id=np.array(class_ids, dtype=int),
|
|
)
|
|
|
|
@classmethod
|
|
def empty(cls) -> Detections:
|
|
"""
|
|
Create an empty Detections object with no bounding boxes,
|
|
confidences, or class IDs.
|
|
|
|
Returns:
|
|
(Detections): An empty Detections object.
|
|
|
|
Example:
|
|
```python
|
|
from supervision import Detections
|
|
|
|
empty_detections = Detections.empty()
|
|
```
|
|
"""
|
|
return cls(
|
|
xyxy=np.empty((0, 4), dtype=np.float32),
|
|
confidence=np.array([], dtype=np.float32),
|
|
class_id=np.array([], dtype=int),
|
|
)
|
|
|
|
def is_empty(self) -> bool:
|
|
"""
|
|
Returns `True` if the `Detections` object is considered empty.
|
|
"""
|
|
empty_detections = Detections.empty()
|
|
empty_detections.data = self.data
|
|
empty_detections.metadata = self.metadata
|
|
return self == empty_detections
|
|
|
|
@classmethod
|
|
def merge(cls, detections_list: List[Detections]) -> Detections:
|
|
"""
|
|
Merge a list of Detections objects into a single Detections object.
|
|
|
|
This method takes a list of Detections objects and combines their
|
|
respective fields (`xyxy`, `mask`, `confidence`, `class_id`, and `tracker_id`)
|
|
into a single Detections object.
|
|
|
|
For example, if merging Detections with 3 and 4 detected objects, this method
|
|
will return a Detections with 7 objects (7 entries in `xyxy`, `mask`, etc).
|
|
|
|
!!! Note
|
|
|
|
When merging, empty `Detections` objects are ignored.
|
|
|
|
Args:
|
|
detections_list (List[Detections]): A list of Detections objects to merge.
|
|
|
|
Returns:
|
|
(Detections): A single Detections object containing
|
|
the merged data from the input list.
|
|
|
|
Example:
|
|
```python
|
|
import numpy as np
|
|
import supervision as sv
|
|
|
|
detections_1 = sv.Detections(
|
|
xyxy=np.array([[15, 15, 100, 100], [200, 200, 300, 300]]),
|
|
class_id=np.array([1, 2]),
|
|
data={'feature_vector': np.array([0.1, 0.2)])}
|
|
)
|
|
|
|
detections_2 = sv.Detections(
|
|
xyxy=np.array([[30, 30, 120, 120]]),
|
|
class_id=np.array([1]),
|
|
data={'feature_vector': [np.array([0.3])]}
|
|
)
|
|
|
|
merged_detections = Detections.merge([detections_1, detections_2])
|
|
|
|
merged_detections.xyxy
|
|
array([[ 15, 15, 100, 100],
|
|
[200, 200, 300, 300],
|
|
[ 30, 30, 120, 120]])
|
|
|
|
merged_detections.class_id
|
|
array([1, 2, 1])
|
|
|
|
merged_detections.data['feature_vector']
|
|
array([0.1, 0.2, 0.3])
|
|
```
|
|
"""
|
|
detections_list = [
|
|
detections for detections in detections_list if not detections.is_empty()
|
|
]
|
|
|
|
if len(detections_list) == 0:
|
|
return Detections.empty()
|
|
|
|
for detections in detections_list:
|
|
validate_detections_fields(
|
|
xyxy=detections.xyxy,
|
|
mask=detections.mask,
|
|
confidence=detections.confidence,
|
|
class_id=detections.class_id,
|
|
tracker_id=detections.tracker_id,
|
|
data=detections.data,
|
|
)
|
|
|
|
xyxy = np.vstack([d.xyxy for d in detections_list])
|
|
|
|
def stack_or_none(name: str):
|
|
if all(d.__getattribute__(name) is None for d in detections_list):
|
|
return None
|
|
if any(d.__getattribute__(name) is None for d in detections_list):
|
|
raise ValueError(f"All or none of the '{name}' fields must be None")
|
|
return (
|
|
np.vstack([d.__getattribute__(name) for d in detections_list])
|
|
if name == "mask"
|
|
else np.hstack([d.__getattribute__(name) for d in detections_list])
|
|
)
|
|
|
|
mask = stack_or_none("mask")
|
|
confidence = stack_or_none("confidence")
|
|
class_id = stack_or_none("class_id")
|
|
tracker_id = stack_or_none("tracker_id")
|
|
|
|
data = merge_data([d.data for d in detections_list])
|
|
|
|
metadata_list = [detections.metadata for detections in detections_list]
|
|
metadata = merge_metadata(metadata_list)
|
|
|
|
return cls(
|
|
xyxy=xyxy,
|
|
mask=mask,
|
|
confidence=confidence,
|
|
class_id=class_id,
|
|
tracker_id=tracker_id,
|
|
data=data,
|
|
metadata=metadata,
|
|
)
|
|
|
|
def get_anchors_coordinates(self, anchor: Position) -> np.ndarray:
|
|
"""
|
|
Calculates and returns the coordinates of a specific anchor point
|
|
within the bounding boxes defined by the `xyxy` attribute. The anchor
|
|
point can be any of the predefined positions in the `Position` enum,
|
|
such as `CENTER`, `CENTER_LEFT`, `BOTTOM_RIGHT`, etc.
|
|
|
|
Args:
|
|
anchor (Position): An enum specifying the position of the anchor point
|
|
within the bounding box. Supported positions are defined in the
|
|
`Position` enum.
|
|
|
|
Returns:
|
|
np.ndarray: An array of shape `(n, 2)`, where `n` is the number of bounding
|
|
boxes. Each row contains the `[x, y]` coordinates of the specified
|
|
anchor point for the corresponding bounding box.
|
|
|
|
Raises:
|
|
ValueError: If the provided `anchor` is not supported.
|
|
"""
|
|
if anchor == Position.CENTER:
|
|
return np.array(
|
|
[
|
|
(self.xyxy[:, 0] + self.xyxy[:, 2]) / 2,
|
|
(self.xyxy[:, 1] + self.xyxy[:, 3]) / 2,
|
|
]
|
|
).transpose()
|
|
elif anchor == Position.CENTER_OF_MASS:
|
|
if self.mask is None:
|
|
raise ValueError(
|
|
"Cannot use `Position.CENTER_OF_MASS` without a detection mask."
|
|
)
|
|
return calculate_masks_centroids(masks=self.mask)
|
|
elif anchor == Position.CENTER_LEFT:
|
|
return np.array(
|
|
[
|
|
self.xyxy[:, 0],
|
|
(self.xyxy[:, 1] + self.xyxy[:, 3]) / 2,
|
|
]
|
|
).transpose()
|
|
elif anchor == Position.CENTER_RIGHT:
|
|
return np.array(
|
|
[
|
|
self.xyxy[:, 2],
|
|
(self.xyxy[:, 1] + self.xyxy[:, 3]) / 2,
|
|
]
|
|
).transpose()
|
|
elif anchor == Position.BOTTOM_CENTER:
|
|
return np.array(
|
|
[(self.xyxy[:, 0] + self.xyxy[:, 2]) / 2, self.xyxy[:, 3]]
|
|
).transpose()
|
|
elif anchor == Position.BOTTOM_LEFT:
|
|
return np.array([self.xyxy[:, 0], self.xyxy[:, 3]]).transpose()
|
|
elif anchor == Position.BOTTOM_RIGHT:
|
|
return np.array([self.xyxy[:, 2], self.xyxy[:, 3]]).transpose()
|
|
elif anchor == Position.TOP_CENTER:
|
|
return np.array(
|
|
[(self.xyxy[:, 0] + self.xyxy[:, 2]) / 2, self.xyxy[:, 1]]
|
|
).transpose()
|
|
elif anchor == Position.TOP_LEFT:
|
|
return np.array([self.xyxy[:, 0], self.xyxy[:, 1]]).transpose()
|
|
elif anchor == Position.TOP_RIGHT:
|
|
return np.array([self.xyxy[:, 2], self.xyxy[:, 1]]).transpose()
|
|
|
|
raise ValueError(f"{anchor} is not supported.")
|
|
|
|
def __getitem__(
|
|
self, index: Union[int, slice, List[int], np.ndarray, str]
|
|
) -> Union[Detections, List, np.ndarray, None]:
|
|
"""
|
|
Get a subset of the Detections object or access an item from its data field.
|
|
|
|
When provided with an integer, slice, list of integers, or a numpy array, this
|
|
method returns a new Detections object that represents a subset of the original
|
|
detections. When provided with a string, it accesses the corresponding item in
|
|
the data dictionary.
|
|
|
|
Args:
|
|
index (Union[int, slice, List[int], np.ndarray, str]): The index, indices,
|
|
or key to access a subset of the Detections or an item from the data.
|
|
|
|
Returns:
|
|
Union[Detections, Any]: A subset of the Detections object or an item from
|
|
the data field.
|
|
|
|
Example:
|
|
```python
|
|
import supervision as sv
|
|
|
|
detections = sv.Detections()
|
|
|
|
first_detection = detections[0]
|
|
first_10_detections = detections[0:10]
|
|
some_detections = detections[[0, 2, 4]]
|
|
class_0_detections = detections[detections.class_id == 0]
|
|
high_confidence_detections = detections[detections.confidence > 0.5]
|
|
|
|
feature_vector = detections['feature_vector']
|
|
```
|
|
"""
|
|
if isinstance(index, str):
|
|
return self.data.get(index)
|
|
if self.is_empty():
|
|
return Detections.empty()
|
|
if isinstance(index, int):
|
|
index = [index]
|
|
return Detections(
|
|
xyxy=self.xyxy[index],
|
|
mask=self.mask[index] if self.mask is not None else None,
|
|
confidence=self.confidence[index] if self.confidence is not None else None,
|
|
class_id=self.class_id[index] if self.class_id is not None else None,
|
|
tracker_id=self.tracker_id[index] if self.tracker_id is not None else None,
|
|
data=get_data_item(self.data, index),
|
|
metadata=self.metadata,
|
|
)
|
|
|
|
def __setitem__(self, key: str, value: Union[np.ndarray, List]):
|
|
"""
|
|
Set a value in the data dictionary of the Detections object.
|
|
|
|
Args:
|
|
key (str): The key in the data dictionary to set.
|
|
value (Union[np.ndarray, List]): The value to set for the key.
|
|
|
|
Example:
|
|
```python
|
|
import cv2
|
|
import supervision as sv
|
|
from ultralytics import YOLO
|
|
|
|
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
|
model = YOLO('yolov8s.pt')
|
|
|
|
result = model(image)[0]
|
|
detections = sv.Detections.from_ultralytics(result)
|
|
|
|
detections['names'] = [
|
|
model.model.names[class_id]
|
|
for class_id
|
|
in detections.class_id
|
|
]
|
|
```
|
|
"""
|
|
if not isinstance(value, (np.ndarray, list)):
|
|
raise TypeError("Value must be a np.ndarray or a list")
|
|
|
|
if isinstance(value, list):
|
|
value = np.array(value)
|
|
|
|
self.data[key] = value
|
|
|
|
@property
|
|
def area(self) -> np.ndarray:
|
|
"""
|
|
Calculate the area of each detection in the set of object detections.
|
|
If masks field is defined property returns are of each mask.
|
|
If only box is given property return area of each box.
|
|
|
|
Returns:
|
|
np.ndarray: An array of floats containing the area of each detection
|
|
in the format of `(area_1, area_2, , area_n)`,
|
|
where n is the number of detections.
|
|
"""
|
|
if self.mask is not None:
|
|
return np.array([np.sum(mask) for mask in self.mask])
|
|
else:
|
|
return self.box_area
|
|
|
|
@property
|
|
def box_area(self) -> np.ndarray:
|
|
"""
|
|
Calculate the area of each bounding box in the set of object detections.
|
|
|
|
Returns:
|
|
np.ndarray: An array of floats containing the area of each bounding
|
|
box in the format of `(area_1, area_2, , area_n)`,
|
|
where n is the number of detections.
|
|
"""
|
|
return (self.xyxy[:, 3] - self.xyxy[:, 1]) * (self.xyxy[:, 2] - self.xyxy[:, 0])
|
|
|
|
def with_nms(
|
|
self, threshold: float = 0.5, class_agnostic: bool = False
|
|
) -> Detections:
|
|
"""
|
|
Performs non-max suppression on detection set. If the detections result
|
|
from a segmentation model, the IoU mask is applied. Otherwise, box IoU is used.
|
|
|
|
Args:
|
|
threshold (float): The intersection-over-union threshold
|
|
to use for non-maximum suppression. I'm the lower the value the more
|
|
restrictive the NMS becomes. Defaults to 0.5.
|
|
class_agnostic (bool): Whether to perform class-agnostic
|
|
non-maximum suppression. If True, the class_id of each detection
|
|
will be ignored. Defaults to False.
|
|
|
|
Returns:
|
|
Detections: A new Detections object containing the subset of detections
|
|
after non-maximum suppression.
|
|
|
|
Raises:
|
|
AssertionError: If `confidence` is None and class_agnostic is False.
|
|
If `class_id` is None and class_agnostic is False.
|
|
"""
|
|
if len(self) == 0:
|
|
return self
|
|
|
|
assert (
|
|
self.confidence is not None
|
|
), "Detections confidence must be given for NMS to be executed."
|
|
|
|
if class_agnostic:
|
|
predictions = np.hstack((self.xyxy, self.confidence.reshape(-1, 1)))
|
|
else:
|
|
assert self.class_id is not None, (
|
|
"Detections class_id must be given for NMS to be executed. If you"
|
|
" intended to perform class agnostic NMS set class_agnostic=True."
|
|
)
|
|
predictions = np.hstack(
|
|
(
|
|
self.xyxy,
|
|
self.confidence.reshape(-1, 1),
|
|
self.class_id.reshape(-1, 1),
|
|
)
|
|
)
|
|
|
|
if self.mask is not None:
|
|
indices = mask_non_max_suppression(
|
|
predictions=predictions, masks=self.mask, iou_threshold=threshold
|
|
)
|
|
else:
|
|
indices = box_non_max_suppression(
|
|
predictions=predictions, iou_threshold=threshold
|
|
)
|
|
|
|
return self[indices]
|
|
|
|
def with_nmm(
|
|
self, threshold: float = 0.5, class_agnostic: bool = False
|
|
) -> Detections:
|
|
"""
|
|
Perform non-maximum merging on the current set of object detections.
|
|
|
|
Args:
|
|
threshold (float): The intersection-over-union threshold
|
|
to use for non-maximum merging. Defaults to 0.5.
|
|
class_agnostic (bool): Whether to perform class-agnostic
|
|
non-maximum merging. If True, the class_id of each detection
|
|
will be ignored. Defaults to False.
|
|
|
|
Returns:
|
|
Detections: A new Detections object containing the subset of detections
|
|
after non-maximum merging.
|
|
|
|
Raises:
|
|
AssertionError: If `confidence` is None or `class_id` is None and
|
|
class_agnostic is False.
|
|
|
|
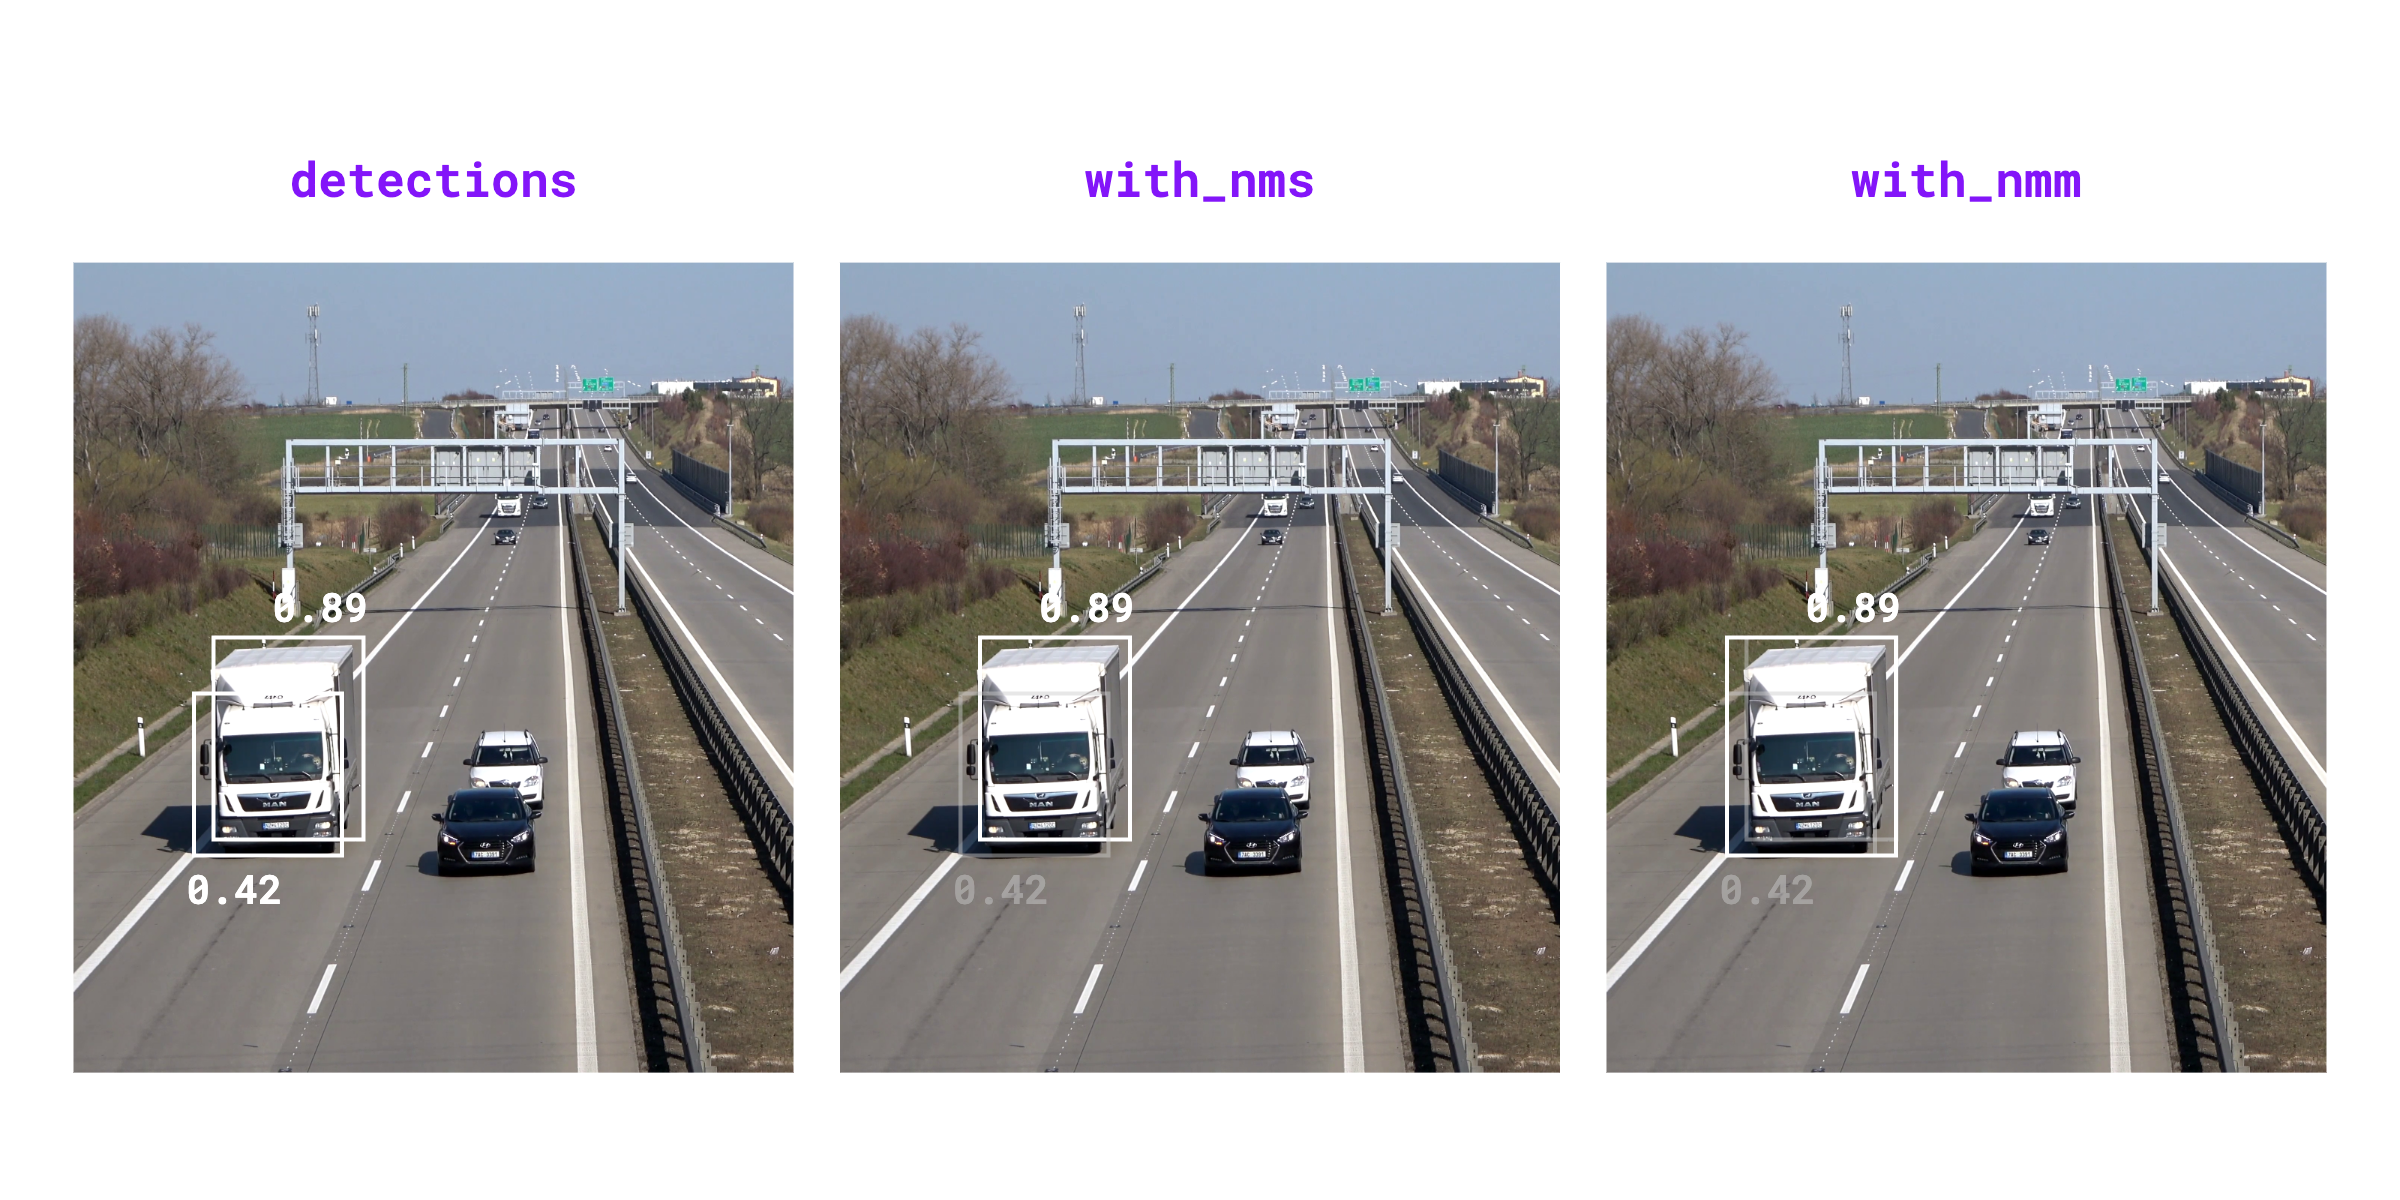{ align=center width="800" }
|
|
""" # noqa: E501 // docs
|
|
if len(self) == 0:
|
|
return self
|
|
|
|
assert (
|
|
self.confidence is not None
|
|
), "Detections confidence must be given for NMM to be executed."
|
|
|
|
if class_agnostic:
|
|
predictions = np.hstack((self.xyxy, self.confidence.reshape(-1, 1)))
|
|
else:
|
|
assert self.class_id is not None, (
|
|
"Detections class_id must be given for NMM to be executed. If you"
|
|
" intended to perform class agnostic NMM set class_agnostic=True."
|
|
)
|
|
predictions = np.hstack(
|
|
(
|
|
self.xyxy,
|
|
self.confidence.reshape(-1, 1),
|
|
self.class_id.reshape(-1, 1),
|
|
)
|
|
)
|
|
|
|
merge_groups = box_non_max_merge(
|
|
predictions=predictions, iou_threshold=threshold
|
|
)
|
|
|
|
result = []
|
|
for merge_group in merge_groups:
|
|
unmerged_detections = [self[i] for i in merge_group]
|
|
merged_detections = merge_inner_detections_objects(
|
|
unmerged_detections, threshold
|
|
)
|
|
result.append(merged_detections)
|
|
|
|
return Detections.merge(result)
|
|
|
|
|
|
def merge_inner_detection_object_pair(
|
|
detections_1: Detections, detections_2: Detections
|
|
) -> Detections:
|
|
"""
|
|
Merges two Detections object into a single Detections object.
|
|
Assumes each Detections contains exactly one object.
|
|
|
|
A `winning` detection is determined based on the confidence score of the two
|
|
input detections. This winning detection is then used to specify which
|
|
`class_id`, `tracker_id`, and `data` to include in the merged Detections object.
|
|
|
|
The resulting `confidence` of the merged object is calculated by the weighted
|
|
contribution of ea detection to the merged object.
|
|
The bounding boxes and masks of the two input detections are merged into a
|
|
single bounding box and mask, respectively.
|
|
|
|
Args:
|
|
detections_1 (Detections):
|
|
The first Detections object
|
|
detections_2 (Detections):
|
|
The second Detections object
|
|
|
|
Returns:
|
|
Detections: A new Detections object, with merged attributes.
|
|
|
|
Raises:
|
|
ValueError: If the input Detections objects do not have exactly 1 detected
|
|
object.
|
|
|
|
Example:
|
|
```python
|
|
import cv2
|
|
import supervision as sv
|
|
from inference import get_model
|
|
|
|
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
|
model = get_model(model_id="yolov8s-640")
|
|
|
|
result = model.infer(image)[0]
|
|
detections = sv.Detections.from_inference(result)
|
|
|
|
merged_detections = merge_object_detection_pair(
|
|
detections[0], detections[1])
|
|
```
|
|
"""
|
|
if len(detections_1) != 1 or len(detections_2) != 1:
|
|
raise ValueError("Both Detections should have exactly 1 detected object.")
|
|
|
|
validate_fields_both_defined_or_none(detections_1, detections_2)
|
|
|
|
xyxy_1 = detections_1.xyxy[0]
|
|
xyxy_2 = detections_2.xyxy[0]
|
|
if detections_1.confidence is None and detections_2.confidence is None:
|
|
merged_confidence = None
|
|
else:
|
|
detection_1_area = (xyxy_1[2] - xyxy_1[0]) * (xyxy_1[3] - xyxy_1[1])
|
|
detections_2_area = (xyxy_2[2] - xyxy_2[0]) * (xyxy_2[3] - xyxy_2[1])
|
|
merged_confidence = (
|
|
detection_1_area * detections_1.confidence[0]
|
|
+ detections_2_area * detections_2.confidence[0]
|
|
) / (detection_1_area + detections_2_area)
|
|
merged_confidence = np.array([merged_confidence])
|
|
|
|
merged_x1, merged_y1 = np.minimum(xyxy_1[:2], xyxy_2[:2])
|
|
merged_x2, merged_y2 = np.maximum(xyxy_1[2:], xyxy_2[2:])
|
|
merged_xyxy = np.array([[merged_x1, merged_y1, merged_x2, merged_y2]])
|
|
|
|
if detections_1.mask is None and detections_2.mask is None:
|
|
merged_mask = None
|
|
else:
|
|
merged_mask = np.logical_or(detections_1.mask, detections_2.mask)
|
|
|
|
if detections_1.confidence is None and detections_2.confidence is None:
|
|
winning_detection = detections_1
|
|
elif detections_1.confidence[0] >= detections_2.confidence[0]:
|
|
winning_detection = detections_1
|
|
else:
|
|
winning_detection = detections_2
|
|
|
|
metadata = merge_metadata([detections_1.metadata, detections_2.metadata])
|
|
|
|
return Detections(
|
|
xyxy=merged_xyxy,
|
|
mask=merged_mask,
|
|
confidence=merged_confidence,
|
|
class_id=winning_detection.class_id,
|
|
tracker_id=winning_detection.tracker_id,
|
|
data=winning_detection.data,
|
|
metadata=metadata,
|
|
)
|
|
|
|
|
|
def merge_inner_detections_objects(
|
|
detections: List[Detections], threshold=0.5
|
|
) -> Detections:
|
|
"""
|
|
Given N detections each of length 1 (exactly one object inside), combine them into a
|
|
single detection object of length 1. The contained inner object will be the merged
|
|
result of all the input detections.
|
|
|
|
For example, this lets you merge N boxes into one big box, N masks into one mask,
|
|
etc.
|
|
"""
|
|
detections_1 = detections[0]
|
|
for detections_2 in detections[1:]:
|
|
box_iou = box_iou_batch(detections_1.xyxy, detections_2.xyxy)[0]
|
|
if box_iou < threshold:
|
|
break
|
|
detections_1 = merge_inner_detection_object_pair(detections_1, detections_2)
|
|
return detections_1
|
|
|
|
|
|
def validate_fields_both_defined_or_none(
|
|
detections_1: Detections, detections_2: Detections
|
|
) -> None:
|
|
"""
|
|
Verify that for each optional field in the Detections, both instances either have
|
|
the field set to None or both have it set to non-None values.
|
|
|
|
`data` field is ignored.
|
|
|
|
Raises:
|
|
ValueError: If one field is None and the other is not, for any of the fields.
|
|
"""
|
|
attributes = get_instance_variables(detections_1)
|
|
for attribute in attributes:
|
|
value_1 = getattr(detections_1, attribute)
|
|
value_2 = getattr(detections_2, attribute)
|
|
|
|
if (value_1 is None) != (value_2 is None):
|
|
raise ValueError(
|
|
f"Field '{attribute}' should be consistently None or not None in both "
|
|
"Detections."
|
|
)
|