Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 LinasKo |
27c68f293d | ||
|
LinasKo
|
ee3d1768e3 | ||
|
LinasKo
|
f1124e04df | ||
|
LinasKo
|
55c8c07b90 | ||
|
LinasKo
|
6bb5929e09 | ||
|
LinasKo
|
6ac0f84e27 | ||
|
LinasKo
|
162f9ed6d2 | ||
|
Onuralp SEZER
|
7600bef8e7 | ||
|
dependabot[bot]
|
9df96572ac | ||
|
LinasKo
|
8ff0d31e57 | ||
|
LinasKo
|
5160d20fbc | ||
|
LinasKo
|
9f730b9fb5 | ||
|
LinasKo
|
a7ecc57432 | ||
|
LinasKo
|
ec5790a90c | ||
|
LinasKo
|
57e5c108de | ||
|
LinasKo
|
84bb44d222 | ||
|
LinasKo
|
026a243f81 | ||
|
LinasKo
|
d1e5e031e3 | ||
|
LinasKo
|
a5bb93ddec | ||
|
LinasKo
|
fe27e44081 | ||
|
LinasKo
|
d21a6b1ee8 | ||
|
Onuralp SEZER
|
395d90b5a6 | ||
|
LinasKo
|
635272b892 | ||
|
Onuralp SEZER
|
0edb590bb5 | ||
|
LinasKo
|
5aa4216c86 | ||
|
LinasKo
|
1ae8fc798e | ||
|
LinasKo
|
e8ec271f0b | ||
|
Onuralp SEZER
|
9e3a150196 | ||
|
Onuralp SEZER
|
acd23bf662 | ||
|
Onuralp SEZER
|
5532731910 | ||
|
Onuralp SEZER
|
029abbd614 | ||
|
Onuralp SEZER
|
46ecb808f7 | ||
|
LinasKo
|
5befed7332 | ||
|
LinasKo
|
15a192c63a | ||
|
LinasKo
|
317485b122 | ||
|
Onuralp SEZER
|
0f23c6d425 | ||
|
pre-commit-ci[bot]
|
44d531fdb8 | ||
|
LinasKo
|
a3262a8f9c | ||
|
pre-commit-ci[bot]
|
7e9dca632b | ||
|
LinasKo
|
cc7de0edb7 | ||
|
Onuralp SEZER
|
808814bce7 | ||
|
Onuralp SEZER
|
89000c1c33 | ||
|
dependabot[bot]
|
71cbd82ef4 | ||
|
dependabot[bot]
|
dff15cb8d6 | ||
|
Onuralp SEZER
|
befa12bb23 | ||
|
Ju Hoon Park
|
f86a2d3a82 | ||
|
Onuralp SEZER
|
3d7c1ba1ec | ||
|
Onuralp SEZER
|
a64a2fc243 | ||
|
Onuralp SEZER
|
b65d2cc73f | ||
|
LinasKo
|
207260aca1 | ||
|
Onuralp SEZER
|
81b27340e5 | ||
|
Onuralp SEZER
|
a92665e85c | ||
|
dependabot[bot]
|
e7bf00aa95 | ||
|
dependabot[bot]
|
392c6930bb | ||
|
LinasKo
|
ed253fef99 | ||
|
Ju Hoon Park
|
cef25cc601 | ||
|
Onuralp SEZER
|
e1b13e369c | ||
|
Onuralp SEZER
|
ed09f05424 | ||
|
Onuralp SEZER
|
369831eb76 | ||
|
pre-commit-ci[bot]
|
0d17a8e6b5 | ||
|
venkatram-dev
|
2e4f05e8ec | ||
|
dependabot[bot]
|
1891b2edde | ||
|
dependabot[bot]
|
477faee1c7 | ||
|
Onuralp SEZER
|
5957b250f0 | ||
|
pre-commit-ci[bot]
|
7d27e67966 | ||
|
Onuralp SEZER
|
c31d96dabe | ||
|
Onuralp SEZER
|
4ab9ae5a71 | ||
|
dependabot[bot]
|
888da4e208 | ||
|
LinasKo
|
8f480ead6a | ||
|
LinasKo
|
cdc3b4d6b1 | ||
|
LinasKo
|
bae1797e83 | ||
|
LinasKo
|
7319a026ab | ||
|
LinasKo
|
509b6da063 | ||
|
Kader Miyanyedi
|
10ea37b732 | ||
|
Kader Miyanyedi
|
6ce126d6d8 | ||
|
LinasKo
|
ab76a47eb8 | ||
|
Onuralp SEZER
|
5261efebc3 | ||
|
dependabot[bot]
|
ca5486dc5a | ||
|
Onuralp SEZER
|
eecc0dea91 | ||
|
Onuralp SEZER
|
cf7c95e700 | ||
|
Onuralp SEZER
|
366bc21d1e | ||
|
Onuralp SEZER
|
526ddacd2f | ||
|
Onuralp SEZER
|
ab45b19e7e | ||
|
Christoforos Aristeidou
|
6289d9cab0 | ||
|
LinasKo
|
85e0a544fe | ||
|
LinasKo
|
6f47cd318a | ||
|
LinasKo
|
66758448cb | ||
|
LinasKo
|
c8673fe517 | ||
|
LinasKo
|
b5a958745b | ||
|
LinasKo
|
cfd079bbcb | ||
|
LinasKo
|
0e8365ff80 | ||
|
LinasKo
|
758b9d60bd | ||
|
LinasKo
|
b40cddd144 | ||
|
LinasKo
|
dabd18c0de | ||
|
LinasKo
|
e1ffd0e8a9 | ||
|
LinasKo
|
731d580a83 | ||
|
LinasKo
|
d4f95eca45 | ||
|
LinasKo
|
0477499b77 | ||
|
LinasKo
|
29de4d245e | ||
|
LinasKo
|
2012ec7bcb | ||
|
LinasKo
|
5b3ce80a34 | ||
|
LinasKo
|
c3641de724 | ||
|
LinasKo
|
822dd4d555 | ||
|
Onuralp SEZER
|
09e88da71a | ||
|
Onuralp SEZER
|
31a2b26144 | ||
|
dependabot[bot]
|
f7713a32aa | ||
|
dependabot[bot]
|
c97a885f9e | ||
|
Bhavay Malhotra
|
b1cc5c3564 | ||
|
LinasKo
|
91d8691bc4 | ||
|
pre-commit-ci[bot]
|
072072e9b2 | ||
|
LinasKo
|
148bb63aa8 | ||
|
Bhavay Malhotra
|
d60443751a | ||
|
Bhavay Malhotra
|
1421f2c743 | ||
|
pre-commit-ci[bot]
|
751ea27263 | ||
|
Bhavay Malhotra
|
78b6020ea4 | ||
|
Onuralp SEZER
|
d08d22dec6 | ||
|
pre-commit-ci[bot]
|
ee1f15eebe | ||
|
Christoforos Aristeidou
|
d755bca7c8 | ||
|
LinasKo
|
5565241ef5 | ||
|
pre-commit-ci[bot]
|
a4cf2604ee | ||
|
LinasKo
|
3e860a5449 | ||
|
LinasKo
|
0305ceed45 | ||
|
pre-commit-ci[bot]
|
4add8c871e | ||
|
LinasKo
|
6f566b5518 | ||
|
pre-commit-ci[bot]
|
d6d71a0366 | ||
|
LinasKo
|
4c903cf7f2 | ||
|
pre-commit-ci[bot]
|
b061f4fd84 | ||
|
Bhavay Malhotra
|
2b73aea438 | ||
|
Onuralp SEZER
|
db958d9df8 | ||
|
dependabot[bot]
|
f699f087db | ||
|
LinasKo
|
7d7e5f17a5 | ||
|
Piotr Skalski
|
d486dd1083 | ||
|
SkalskiP
|
5123085037 | ||
|
Piotr Skalski
|
43041c26c5 | ||
|
Onuralp SEZER
|
ca2902cc46 | ||
|
dependabot[bot]
|
2365ed47e1 | ||
|
pre-commit-ci[bot]
|
78689590e6 | ||
|
Bhavay Malhotra
|
d73187f3dd | ||
|
Bhavay Malhotra
|
d1df96a953 | ||
|
pre-commit-ci[bot]
|
c1650d3770 | ||
|
Bhavay Malhotra
|
a72c5044f4 | ||
|
Bhavay Malhotra
|
4e7f69a502 | ||
|
pre-commit-ci[bot]
|
6d719fcd60 | ||
|
Bhavay Malhotra
|
ac09b58620 | ||
|
LinasKo
|
b9cc02ecb9 | ||
|
LinasKo
|
00b00d2f9a | ||
|
pre-commit-ci[bot]
|
5a9e85a60f | ||
|
James
|
fea77d86a7 | ||
|
James
|
11466ff261 | ||
|
James
|
80549933fc | ||
|
pre-commit-ci[bot]
|
a428fac98d | ||
|
James
|
a109b264ef | ||
|
James
|
389b8968c2 | ||
|
James
|
b000d162e7 | ||
|
Onuralp SEZER
|
66e1672f37 | ||
|
dependabot[bot]
|
52e7fe1d30 | ||
|
SkalskiP
|
b61c5f23c6 | ||
|
SkalskiP
|
0285bfa50a | ||
|
pre-commit-ci[bot]
|
0069d6b289 | ||
|
SkalskiP
|
ebba78528e | ||
|
SkalskiP
|
da2bc575e0 | ||
|
SkalskiP
|
25ea63042d | ||
|
pre-commit-ci[bot]
|
24debfe377 | ||
|
SkalskiP
|
414ee9166d | ||
|
pre-commit-ci[bot]
|
edc4dd33b0 | ||
|
SkalskiP
|
22b970e4d4 | ||
|
Onuralp SEZER
|
e367e307fb | ||
|
dependabot[bot]
|
69ffca50d5 | ||
|
Onuralp SEZER
|
01fd82c43b | ||
|
pre-commit-ci[bot]
|
f04bdb2491 | ||
|
Piotr Skalski
|
aa6c673316 | ||
|
pre-commit-ci[bot]
|
b2752ac6c6 | ||
|
SkalskiP
|
7c038f1d45 | ||
|
pre-commit-ci[bot]
|
b6547ba58e | ||
|
SkalskiP
|
fde9cd4735 | ||
|
SkalskiP
|
1d3e423617 | ||
|
pre-commit-ci[bot]
|
9fc66563dd | ||
|
SkalskiP
|
8a82f4a516 | ||
|
Onuralp SEZER
|
17d1934ed5 | ||
|
dependabot[bot]
|
21fcf1bd04 | ||
|
Onuralp SEZER
|
ebd606ff00 | ||
|
Onuralp SEZER
|
f1241e4fe8 | ||
|
Onuralp SEZER
|
9de14b5c67 | ||
|
dependabot[bot]
|
706c2d19b9 | ||
|
dependabot[bot]
|
7a81c13543 | ||
|
dependabot[bot]
|
4648276cc6 | ||
|
Shadab
|
2c235dfce9 | ||
|
pre-commit-ci[bot]
|
dacd8f5455 | ||
|
Shadab
|
da261ff8cf | ||
|
shaddu
|
a5ae72d7ae | ||
|
pre-commit-ci[bot]
|
fd568e2419 | ||
|
Shadab
|
7c7c3d83ef | ||
|
Onuralp SEZER
|
03dba9c7a2 | ||
|
Onuralp SEZER
|
1d0616640e | ||
|
shaddu
|
f6437ab778 | ||
|
LinasKo
|
7ad22c73a8 | ||
|
LinasKo
|
54903b1cc0 | ||
|
dependabot[bot]
|
e566ac9eb3 | ||
|
shaddu
|
f95f81eaf3 | ||
|
Onuralp SEZER
|
f2ede43d0e | ||
|
dependabot[bot]
|
f2ef9f817c | ||
|
shaddu
|
7bba367f98 | ||
|
pre-commit-ci[bot]
|
977892ad1f | ||
|
Linas Kondrackis
|
2ca696e064 | ||
|
Shadab
|
3bb384d789 | ||
|
pre-commit-ci[bot]
|
ac1fa2edca | ||
|
Shadab
|
4ce9d76b65 | ||
|
shaddu
|
1a1a2d27ce | ||
|
arthurcerveira
|
c9598ef732 | ||
|
pre-commit-ci[bot]
|
4c01eb4a3d | ||
|
Bhavay Malhotra
|
f9471184d7 | ||
|
Piotr Skalski
|
bb0e4ec059 | ||
|
Onuralp SEZER
|
7f8b6d3c5e | ||
|
Onuralp SEZER
|
c6a756352a | ||
|
Onuralp SEZER
|
66456a893c | ||
|
dependabot[bot]
|
8704a46e96 | ||
|
dependabot[bot]
|
3de8ca609f | ||
|
dependabot[bot]
|
586387ab3a | ||
|
Bhavay Malhotra
|
37a988fd9f | ||
|
Piotr Skalski
|
cb6045b026 | ||
|
Bhavay Malhotra
|
9956d5dd82 | ||
|
Bhavay Malhotra
|
b103ce4eb7 | ||
|
Onuralp SEZER
|
22df9a5252 | ||
|
Onuralp SEZER
|
b030d1dc9f | ||
|
Rohan Gupta
|
387a759614 | ||
|
Piotr Skalski
|
5dd8910e02 | ||
|
SkalskiP
|
b19c812f58 | ||
|
SkalskiP
|
e58939235f | ||
|
pre-commit-ci[bot]
|
b8e1612511 | ||
|
Bhavay Malhotra
|
a0abf2dee7 | ||
|
dependabot[bot]
|
f5bced4510 | ||
|
Onuralp SEZER
|
a8d91b0ae5 | ||
|
pre-commit-ci[bot]
|
307821ca25 | ||
|
Bhavay Malhotra
|
c5d052ed16 | ||
|
Bhavay Malhotra
|
e2f33faa67 | ||
|
Bhavay Malhotra
|
1f6694ba50 | ||
|
pre-commit-ci[bot]
|
01922f849e | ||
|
Bhavay Malhotra
|
3fb6a7ba6e | ||
|
Bhavay Malhotra
|
16b8102900 | ||
|
Onuralp SEZER
|
acb5dd0dd4 | ||
|
Onuralp SEZER
|
b325eebe00 | ||
|
Onuralp SEZER
|
eb0041d275 | ||
|
dependabot[bot]
|
3ccd74d93e | ||
|
dependabot[bot]
|
e0d06f9a64 | ||
|
dependabot[bot]
|
d63e7b4677 | ||
|
pre-commit-ci[bot]
|
0210f51944 | ||
|
Bhavay Malhotra
|
073500bf75 | ||
|
Bhavay Malhotra
|
60d33ca140 | ||
|
pre-commit-ci[bot]
|
e65892c80d | ||
|
shaddu
|
24320405b4 | ||
|
Shadab
|
b5ea2cd1cb | ||
|
James
|
c26814da87 | ||
|
pre-commit-ci[bot]
|
da8761bd96 | ||
|
James
|
b8a2fb50d4 | ||
|
Piotr Skalski
|
310b566c9b | ||
|
pre-commit-ci[bot]
|
43c31f933c | ||
|
SkalskiP
|
3a54afe506 | ||
|
SkalskiP
|
891b8523f0 | ||
|
Onuralp SEZER
|
bc12bd38b4 | ||
|
dependabot[bot]
|
0cb66e5551 | ||
|
Piotr Skalski
|
b81e92ca94 | ||
|
Piotr Skalski
|
7ca5b01a75 | ||
|
Onuralp SEZER
|
44753536f3 | ||
|
Piotr Skalski
|
d774c91d7b | ||
|
Brad Dwyer
|
2abb76e167 | ||
|
Piotr Skalski
|
75d4b9f20a | ||
|
Piotr Skalski
|
056401a858 | ||
|
pre-commit-ci[bot]
|
b678ac929e | ||
|
SkalskiP
|
b7b19b0357 | ||
|
Bhavay Malhotra
|
46ac1812d8 | ||
|
Eric Criteser
|
b21a478528 | ||
|
Piotr Skalski
|
65f2bbba57 | ||
|
SkalskiP
|
d0111bf41d | ||
|
Piotr Skalski
|
31db574e63 | ||
|
pre-commit-ci[bot]
|
c930dd06ec | ||
|
SkalskiP
|
83dd92726e | ||
|
pre-commit-ci[bot]
|
59f3e19d2d | ||
|
SkalskiP
|
73ba5f039b | ||
|
Onuralp SEZER
|
e76dec7e15 | ||
|
dependabot[bot]
|
8a67ca073a | ||
|
Onuralp SEZER
|
2b7cd6ab23 | ||
|
Eric Criteser
|
9b0568c5e7 | ||
|
pre-commit-ci[bot]
|
48f6c8d3c1 | ||
|
Eric Criteser
|
2544d7293d | ||
|
Eric Criteser
|
c71d9458c8 | ||
|
Onuralp SEZER
|
c28c9abd5b | ||
|
Onuralp SEZER
|
c69ee8046a | ||
|
Onuralp SEZER
|
65894c9e39 | ||
|
Onuralp SEZER
|
55fd9fca1f | ||
|
pre-commit-ci[bot]
|
f24e846272 | ||
|
SkalskiP
|
d91113c9e7 | ||
|
SkalskiP
|
94a9b73117 | ||
|
Piotr Skalski
|
4ef027462f | ||
|
Onuralp SEZER
|
a788623ea3 | ||
|
Onuralp SEZER
|
94d3f3829b | ||
|
dependabot[bot]
|
321e01157a | ||
|
dependabot[bot]
|
97b2ba2d6a | ||
|
pre-commit-ci[bot]
|
5ee8fcfea2 | ||
|
Eric Criteser
|
c9d4f2b82e | ||
|
Linas Kondrackis
|
aa003d0161 | ||
|
Linas Kondrackis
|
7decfc7d1e | ||
|
Eric Criteser
|
cea854edf5 | ||
|
Eric Criteser
|
9a61b3c41b | ||
|
Eric Criteser
|
113d4b697a | ||
|
LinasKo
|
2260cdd3de | ||
|
Eric Criteser
|
377ca27cc9 | ||
|
Eric Criteser
|
9d5a477064 | ||
|
Eric Criteser
|
7fa7907219 | ||
|
Eric Criteser
|
60d5660286 | ||
|
Onuralp SEZER
|
94b4c22594 | ||
|
David Freilich
|
b85035c45e | ||
|
David Freilich
|
687f8d9621 | ||
|
David Freilich
|
668f2f063f | ||
|
David Freilich
|
f93c712dca | ||
|
David Freilich
|
88f995803f | ||
|
pre-commit-ci[bot]
|
c5ac30c303 | ||
|
SkalskiP
|
0d72846b40 | ||
|
pre-commit-ci[bot]
|
5d8da9633c | ||
|
James Gallagher
|
325bd46740 |
@@ -0,0 +1,64 @@
|
||||
name: Notebook Check Pull Request
|
||||
|
||||
on:
|
||||
pull_request_target:
|
||||
types: [opened, reopened]
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
comment-welcome:
|
||||
permissions:
|
||||
contents: read
|
||||
pull-requests: write
|
||||
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Fetch pull request branch
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
repository: ${{ github.event.pull_request.head.repo.full_name }}
|
||||
ref: ${{ github.event.pull_request.head.sha }}
|
||||
- name: Fetch base develop branch
|
||||
run: git fetch -u "$GITHUB_SERVER_URL/$GITHUB_REPOSITORY" develop:develop
|
||||
- name: Create message
|
||||
env:
|
||||
HEAD_REPOSITORY: ${{ github.event.pull_request.head.repo.full_name }}
|
||||
HEAD_REF: ${{ github.event.pull_request.head.ref }}
|
||||
PR_NUM: ${{ github.event.pull_request.number }}
|
||||
run: |
|
||||
# Preview links and tool usage only needed for notebook changes.
|
||||
readarray -t changed_notebooks < <(git diff --name-only develop | grep '\.ipynb$' || true)
|
||||
if [[ ${#changed_notebooks[@]} == 0 ]]; then
|
||||
echo "No notebooks modified in this pull request."
|
||||
else
|
||||
msg="<h4>Preview</h4>\n"
|
||||
msg+="Preview and run these notebook edits with Google Colab:\n<ul>\n"
|
||||
# Link to PR branch in user's fork that is always current.
|
||||
for fp in "${changed_notebooks[@]}"; do
|
||||
gh_path="${HEAD_REPOSITORY}/blob/${HEAD_REF}/${fp}"
|
||||
colab_url="https://colab.research.google.com/github/${gh_path}"
|
||||
msg+="<li><a href='${colab_url}'>${fp}</a></li>\n"
|
||||
done
|
||||
msg+="</ul>\n"
|
||||
|
||||
reviewnb_url="https://app.reviewnb.com/${GITHUB_REPOSITORY}/pull/${PR_NUM}/files/"
|
||||
msg+="Rendered <a href='${reviewnb_url}'>notebook diffs</a> available on ReviewNB.com.\n"
|
||||
|
||||
msg+="If commits are added to the pull request, synchronize your local branch: <code>git pull origin $HEAD_REF</code>\n"
|
||||
fi
|
||||
echo "MESSAGE=$msg" >> $GITHUB_ENV
|
||||
- name: Post comment
|
||||
env:
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
ISSUE_URL: ${{ github.event.pull_request.issue_url }}
|
||||
run: |
|
||||
# Env var defined in previous step. Escape string for JSON.
|
||||
body="$(echo -n -e $MESSAGE | python3 -c 'import json,sys; print(json.dumps(sys.stdin.read()))')"
|
||||
# Add comment to pull request.
|
||||
curl -X POST \
|
||||
-H "Accept: application/vnd.github.v3+json" \
|
||||
-H "Authorization: token $GITHUB_TOKEN" \
|
||||
"${ISSUE_URL}/comments" \
|
||||
--data "{\"body\": $body}"
|
||||
@@ -14,21 +14,8 @@ jobs:
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material[all]"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
run: pip install "mkdocs-material[imaging]"
|
||||
- name: 📦 Install mike
|
||||
run: pip install "mike"
|
||||
- name: 📦 Install mkdocs-git-revision-date-localized-plugin
|
||||
run: pip install "mkdocs-git-revision-date-localized-plugin"
|
||||
- name: 📦 Install JupyterLab
|
||||
run: pip install jupyterlab
|
||||
- name: 📦 Install mkdocs-jupyter
|
||||
run: pip install mkdocs-jupyter
|
||||
- name: 📦 Install mkdocs-git-committers-plugin-2
|
||||
run: pip install mkdocs-git-committers-plugin-2
|
||||
- name: 🧪 Test documentation build
|
||||
run: mkdocs build --verbose
|
||||
- name: 🏗️ Install dependencies and Test Docs Build
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install "mkdocs-material" "mkdocstrings[python]" "mkdocs-material[imaging]" mike "mkdocs-git-revision-date-localized-plugin" jupyterlab mkdocs-jupyter mkdocs-git-committers-plugin-2
|
||||
mkdocs build --verbose
|
||||
|
||||
+1
-14
@@ -9,7 +9,6 @@ repos:
|
||||
- repo: https://github.com/pre-commit/pre-commit-hooks
|
||||
rev: v4.6.0
|
||||
hooks:
|
||||
- id: end-of-file-fixer
|
||||
- id: trailing-whitespace
|
||||
exclude: test/.*\.py
|
||||
- id: check-yaml
|
||||
@@ -19,14 +18,12 @@ repos:
|
||||
- id: check-case-conflict
|
||||
- id: check-added-large-files
|
||||
- id: detect-private-key
|
||||
- id: forbid-new-submodules
|
||||
- id: pretty-format-json
|
||||
exclude: demo.ipynb
|
||||
args: ['--autofix', '--no-sort-keys', '--indent=4']
|
||||
- id: end-of-file-fixer
|
||||
- id: mixed-line-ending
|
||||
|
||||
|
||||
- repo: https://github.com/PyCQA/bandit
|
||||
rev: '1.7.9'
|
||||
hooks:
|
||||
@@ -34,18 +31,8 @@ repos:
|
||||
args: ["-c", "pyproject.toml"]
|
||||
additional_dependencies: ["bandit[toml]"]
|
||||
|
||||
- repo: https://github.com/pycqa/isort
|
||||
rev: 5.13.2
|
||||
hooks:
|
||||
- id: isort
|
||||
name: isort (python)
|
||||
- id: isort
|
||||
name: isort (pyi)
|
||||
types: [pyi]
|
||||
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.5.1
|
||||
rev: v0.6.2
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
|
||||
+1
-1
@@ -173,7 +173,7 @@ Furthermore, we have integrated a pre-commit GitHub Action into our workflow. Th
|
||||
|
||||
To run the pre-commit tool, follow these steps:
|
||||
|
||||
1. Install pre-commit by running the following command: `poetry install`. It will not only install pre-commit but also install all the deps and dev-deps of project
|
||||
1. Install pre-commit by running the following command: `poetry install --with dev`. It will not only install pre-commit but also install all the deps and dev-deps of project
|
||||
|
||||
2. Once pre-commit is installed, navigate to the project's root directory.
|
||||
|
||||
|
||||
@@ -16,6 +16,7 @@
|
||||
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://snyk.io/advisor/python/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
@@ -110,18 +111,21 @@ Supervision provides a set of [utils](https://supervision.roboflow.com/latest/da
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from roboflow import Roboflow
|
||||
|
||||
dataset = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
project = Roboflow().workspace(<WORKSPACE_ID>).project(<PROJECT_ID>)
|
||||
dataset = project.version(<PROJECT_VERSION>).download("coco")
|
||||
|
||||
ds = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f"{dataset.location}/train",
|
||||
annotations_path=f"{dataset.location}/train/_annotations.coco.json",
|
||||
)
|
||||
|
||||
dataset.classes
|
||||
['dog', 'person']
|
||||
path, image, annotation = ds[0]
|
||||
# loads image on demand
|
||||
|
||||
len(dataset)
|
||||
# 1000
|
||||
for path, image, annotation in ds:
|
||||
# loads image on demand
|
||||
```
|
||||
|
||||
<details close>
|
||||
|
||||
Vendored
+1
-1
@@ -972,7 +972,7 @@
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from supervision.assets import download_assets, VideoAssets\n",
|
||||
"from supervision.assets import VideoAssets, download_assets\n",
|
||||
"\n",
|
||||
"download_assets(VideoAssets.VEHICLES)\n",
|
||||
"VIDEO_PATH = VideoAssets.VEHICLES.value"
|
||||
|
||||
+134
-1
@@ -1,3 +1,136 @@
|
||||
### 0.23.0 <small>Aug 28, 2024</small>
|
||||
|
||||
- Added [#930](https://github.com/roboflow/supervision/pull/930): `IconAnnotator`, a [new annotator](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.IconAnnotator) that allows drawing icons on each detection. Useful if you want to draw a specific icon for each class.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
image = <SOURCE_IMAGE_PATH>
|
||||
icon_dog = <DOG_PNG_PATH>
|
||||
icon_cat = <CAT_PNG_PATH>
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
icon_paths = []
|
||||
for class_name in detections.data["class_name"]:
|
||||
if class_name == "dog":
|
||||
icon_paths.append(icon_dog)
|
||||
elif class_name == "cat":
|
||||
icon_paths.append(icon_cat)
|
||||
else:
|
||||
icon_paths.append("")
|
||||
|
||||
icon_annotator = sv.IconAnnotator()
|
||||
annotated_frame = icon_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
icon_path=icon_paths
|
||||
)
|
||||
```
|
||||
|
||||
- Added [#1385](https://github.com/roboflow/supervision/pull/1385): [`BackgroundColorAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BackgroundColorAnnotator), that draws an overlay on the background images of the detections.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
image = <SOURCE_IMAGE_PATH>
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
background_overlay_annotator = sv.BackgroundOverlayAnnotator()
|
||||
annotated_frame = background_overlay_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
- Added [#1386](https://github.com/roboflow/supervision/pull/1386): Support for Transformers v5 functions in [`sv.Detections.from_transformers`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_transformers). This includes the `DetrImageProcessor` methods `post_process_object_detection`, `post_process_panoptic_segmentation`, `post_process_semantic_segmentation`, and `post_process_instance_segmentation`.
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
```
|
||||
|
||||
- Added [#1354](https://github.com/roboflow/supervision/pull/1354): Ultralytics SAM (Segment Anything Model) support in [`sv.Detections.from_ultralytics`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_ultralytics). [SAM2](https://sam2.metademolab.com/) was released during this update, and is already supported via [`sv.Detections.from_sam`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_sam).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from segment_anything import (
|
||||
sam_model_registry,
|
||||
SamAutomaticMaskGenerator
|
||||
)
|
||||
|
||||
sam_model_reg = sam_model_registry[MODEL_TYPE]
|
||||
sam = sam_model_reg(checkpoint=CHECKPOINT_PATH).to(device=DEVICE)
|
||||
mask_generator = SamAutomaticMaskGenerator(sam)
|
||||
sam_result = mask_generator.generate(IMAGE)
|
||||
detections = sv.Detections.from_sam(sam_result=sam_result)
|
||||
```
|
||||
|
||||
- Added [#1458](https://github.com/roboflow/supervision/pull/1458): `outline_color` options for [`TriangleAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.TriangleAnnotator) and [`DotAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.DotAnnotator).
|
||||
|
||||
- Added [#1409](https://github.com/roboflow/supervision/pull/1409): `text_color` option for [`VertexLabelAnnotator`](https://supervision.roboflow.com/latest/keypoint/annotators/#supervision.keypoint.annotators.VertexLabelAnnotator) keypoint annotator.
|
||||
|
||||
- Changed [#1434](https://github.com/roboflow/supervision/pull/1434): [`InferenceSlicer`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/) now features an `overlap_ratio_wh` parameter, making it easier to compute slice sizes when handling overlapping slices.
|
||||
|
||||
- Fix [#1448](https://github.com/roboflow/supervision/pull/1448): Various annotator type issues have been resolved, supporting expanded error handling.
|
||||
|
||||
- Fix [#1348](https://github.com/roboflow/supervision/pull/1348): Introduced a new method for [seeking to a specific video frame](https://supervision.roboflow.com/latest/utils/video/#supervision.utils.video.get_video_frames_generator), addressing cases where traditional seek methods were failing. It can be enabled with `iterative_seek=True`.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
for frame in sv.get_video_frames_generator(
|
||||
source_path=<SOURCE_VIDEO_PATH>,
|
||||
start=60,
|
||||
iterative_seek=True
|
||||
):
|
||||
...
|
||||
```
|
||||
|
||||
- Fix [#1424](https://github.com/roboflow/supervision/pull/1424): `plot_image` function now clearly indicates that the size is in inches.
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
The `track_buffer`, `track_thresh`, and `match_thresh` parameters in [`ByteTrack`](trackers.md/#supervision.tracker.byte_tracker.core.ByteTrack) are deprecated and were removed as of `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
The `triggering_position ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) was removed as of `supervision-0.23.0`. Use `triggering_anchors ` instead.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
`overlap_filter_strategy` in `InferenceSlicer.__init__` is deprecated and will be removed in `supervision-0.27.0`. Use `overlap_strategy` instead.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
`overlap_ratio_wh` in `InferenceSlicer.__init__` is deprecated and will be removed in `supervision-0.27.0`. Use `overlap_wh` instead.
|
||||
|
||||
### 0.22.0 <small>Jul 12, 2024</small>
|
||||
|
||||
- Added [#1326](https://github.com/roboflow/supervision/pull/1326): [`sv.DetectionsDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset) and [`sv.ClassificationDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.ClassificationDataset) allowing to load the images into memory only when necessary (lazy loading).
|
||||
@@ -360,7 +493,7 @@ annotated_frame = crop_annotator.annotate(
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `track_buffer`, `track_thresh`, and `match_thresh` parameters in `sv.ByterTrack` are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
The `track_buffer`, `track_thresh`, and `match_thresh` parameters in `sv.ByteTrack` are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
|
||||
- Changed [#910](https://github.com/roboflow/supervision/pull/910): [`sv.PolygonZone`](/0.19.0/detection/tools/polygon_zone/#supervision.detection.tools.polygon_zone.PolygonZone) to now accept a list of specific box anchors that must be in zone for a detection to be counted.
|
||||
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Datasets
|
||||
|
||||
+13
-4
@@ -7,15 +7,24 @@ status: deprecated
|
||||
|
||||
These features are phased out due to better alternatives or potential issues in future versions. Deprecated functionalities are supported for **five subsequent releases**, providing time for users to transition to updated methods.
|
||||
|
||||
- The `track_buffer`, `track_thresh`, and `match_thresh` parameters in [`ByterTrack`](trackers.md/#supervision.tracker.byte_tracker.core.ByteTrack) are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
- The `triggering_position ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) will be removed in `supervision-0.23.0`. Use `triggering_anchors ` instead.
|
||||
- The `frame_resolution_wh ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) will be removed in `supervision-0.24.0`.
|
||||
- Constructing `DetectionDataset` and `ClassificationDataset` with parameter `images` as `Dict[str, np.ndarray]` will be removed in `supervision-0.26.0`. Please pass a list of paths `List[str]` instead.
|
||||
|
||||
- Constructing [`DetectionDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset) and [`ClassificationDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.ClassificationDataset) with parameter `images` as `Dict[str, np.ndarray]` will be removed in `supervision-0.26.0`. Please pass a list of paths `List[str]` instead.
|
||||
- The `DetectionDataset.images` property will be removed in `supervision-0.26.0`. Please loop over images with `for path, image, annotation in dataset:`, as that does not require loading all images into memory.
|
||||
- `BoundingBoxAnnotator` has been renamed to `BoxAnnotator` after the old implementation of `BoxAnnotator` has been removed. `BoundingBoxAnnotator` will be removed in `supervision-0.26.0`.
|
||||
- `BoundingBoxAnnotator` has been renamed to `BoxAnnotator` after the old implementation of [`BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator) has been removed. `BoundingBoxAnnotator` will be removed in `supervision-0.26.0`.
|
||||
|
||||
- `overlap_filter_strategy` in [`InferenceSlicer.__init__`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/) is deprecated and will be removed in `supervision-0.27.0`. Use `overlap_strategy` instead.
|
||||
- `overlap_ratio_wh` in [`InferenceSlicer.__init__`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/) is deprecated and will be removed in `supervision-0.27.0`. Use `overlap_wh` instead.
|
||||
|
||||
# Removed
|
||||
|
||||
### 0.23.0
|
||||
|
||||
- The `track_buffer`, `track_thresh`, and `match_thresh` parameters in [`ByteTrack`](trackers.md/#supervision.tracker.byte_tracker.core.ByteTrack) are deprecated and were removed as of `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
- The `triggering_position ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) was removed as of `supervision-0.23.0`. Use `triggering_anchors ` instead.
|
||||
|
||||
### 0.22.0
|
||||
|
||||
- [`Detections.from_froboflow`](detection/core.md/#supervision.detection.core.Detections.from_roboflow) is removed as of `supervision-0.22.0`. Use [`Detections.from_inference`](detection/core.md/#supervision.detection.core.Detections.from_inference) instead.
|
||||
- The method `Color.white()` was removed as of `supervision-0.22.0`. Use the constant `Color.WHITE` instead.
|
||||
- The method `Color.black()` was removed as of `supervision-0.22.0`. Use the constant `Color.BLACK` instead.
|
||||
|
||||
@@ -303,7 +303,7 @@ status: new
|
||||
font_path="<TTF_FONT_PATH>",
|
||||
text_position=sv.Position.CENTER
|
||||
)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
annotated_frame = rich_label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
labels=labels
|
||||
@@ -316,6 +316,33 @@ status: new
|
||||
|
||||
</div>
|
||||
|
||||
=== "Icon"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
icon_paths = [
|
||||
"<ICON_PATH>"
|
||||
for _ in detections
|
||||
]
|
||||
|
||||
icon_annotator = sv.IconAnnotator()
|
||||
annotated_frame = icon_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
icon_path=icon_paths
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
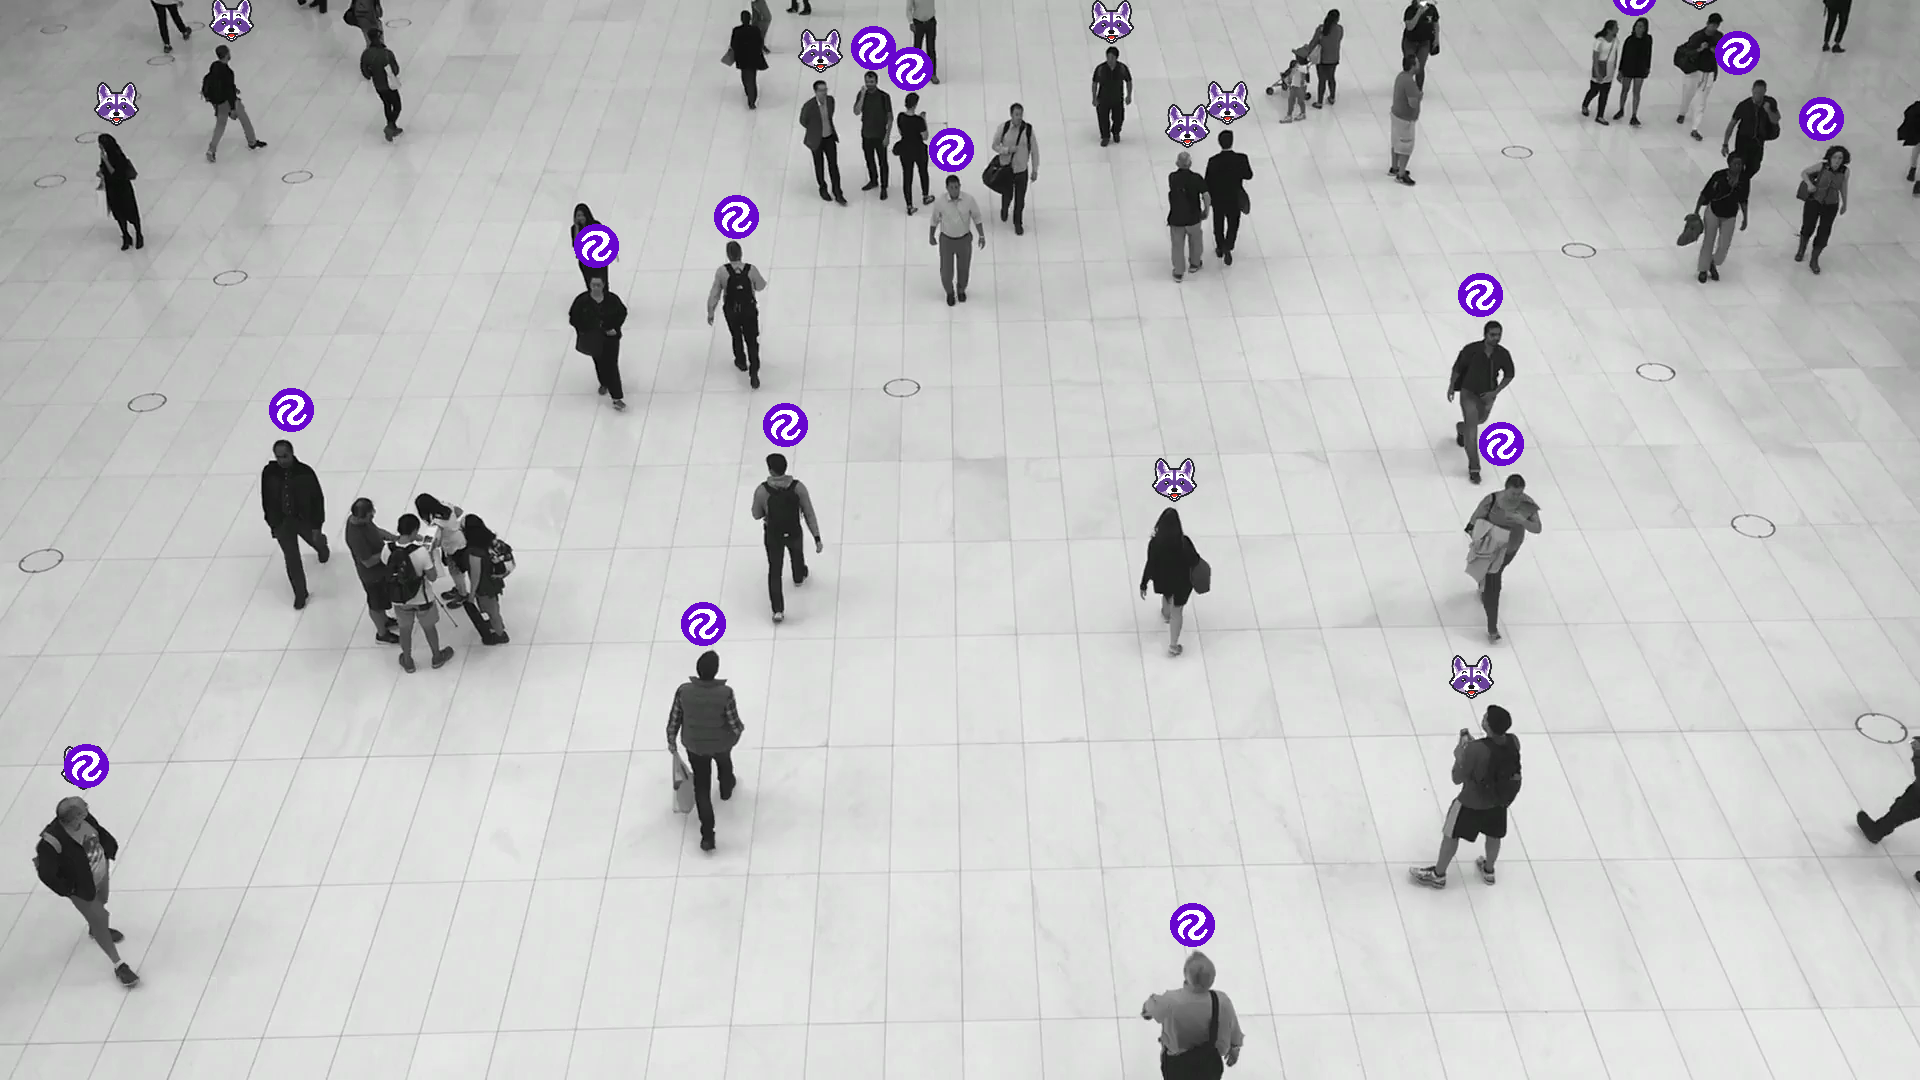{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Crop"
|
||||
|
||||
```python
|
||||
@@ -384,7 +411,7 @@ status: new
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
frames_generator = get_video_frames_generator(source_path='...')
|
||||
frames_generator = sv.get_video_frames_generator(source_path='...')
|
||||
tracker = sv.ByteTrack()
|
||||
|
||||
with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
@@ -415,7 +442,7 @@ status: new
|
||||
heat_map_annotator = sv.HeatMapAnnotator()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
frames_generator = get_video_frames_generator(source_path='...')
|
||||
frames_generator = sv.get_video_frames_generator(source_path='...')
|
||||
|
||||
with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
@@ -433,6 +460,27 @@ status: new
|
||||
|
||||
</div>
|
||||
|
||||
=== "Background Color"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
background_overlay_annotator = sv.BackgroundOverlayAnnotator()
|
||||
annotated_frame = background_overlay_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
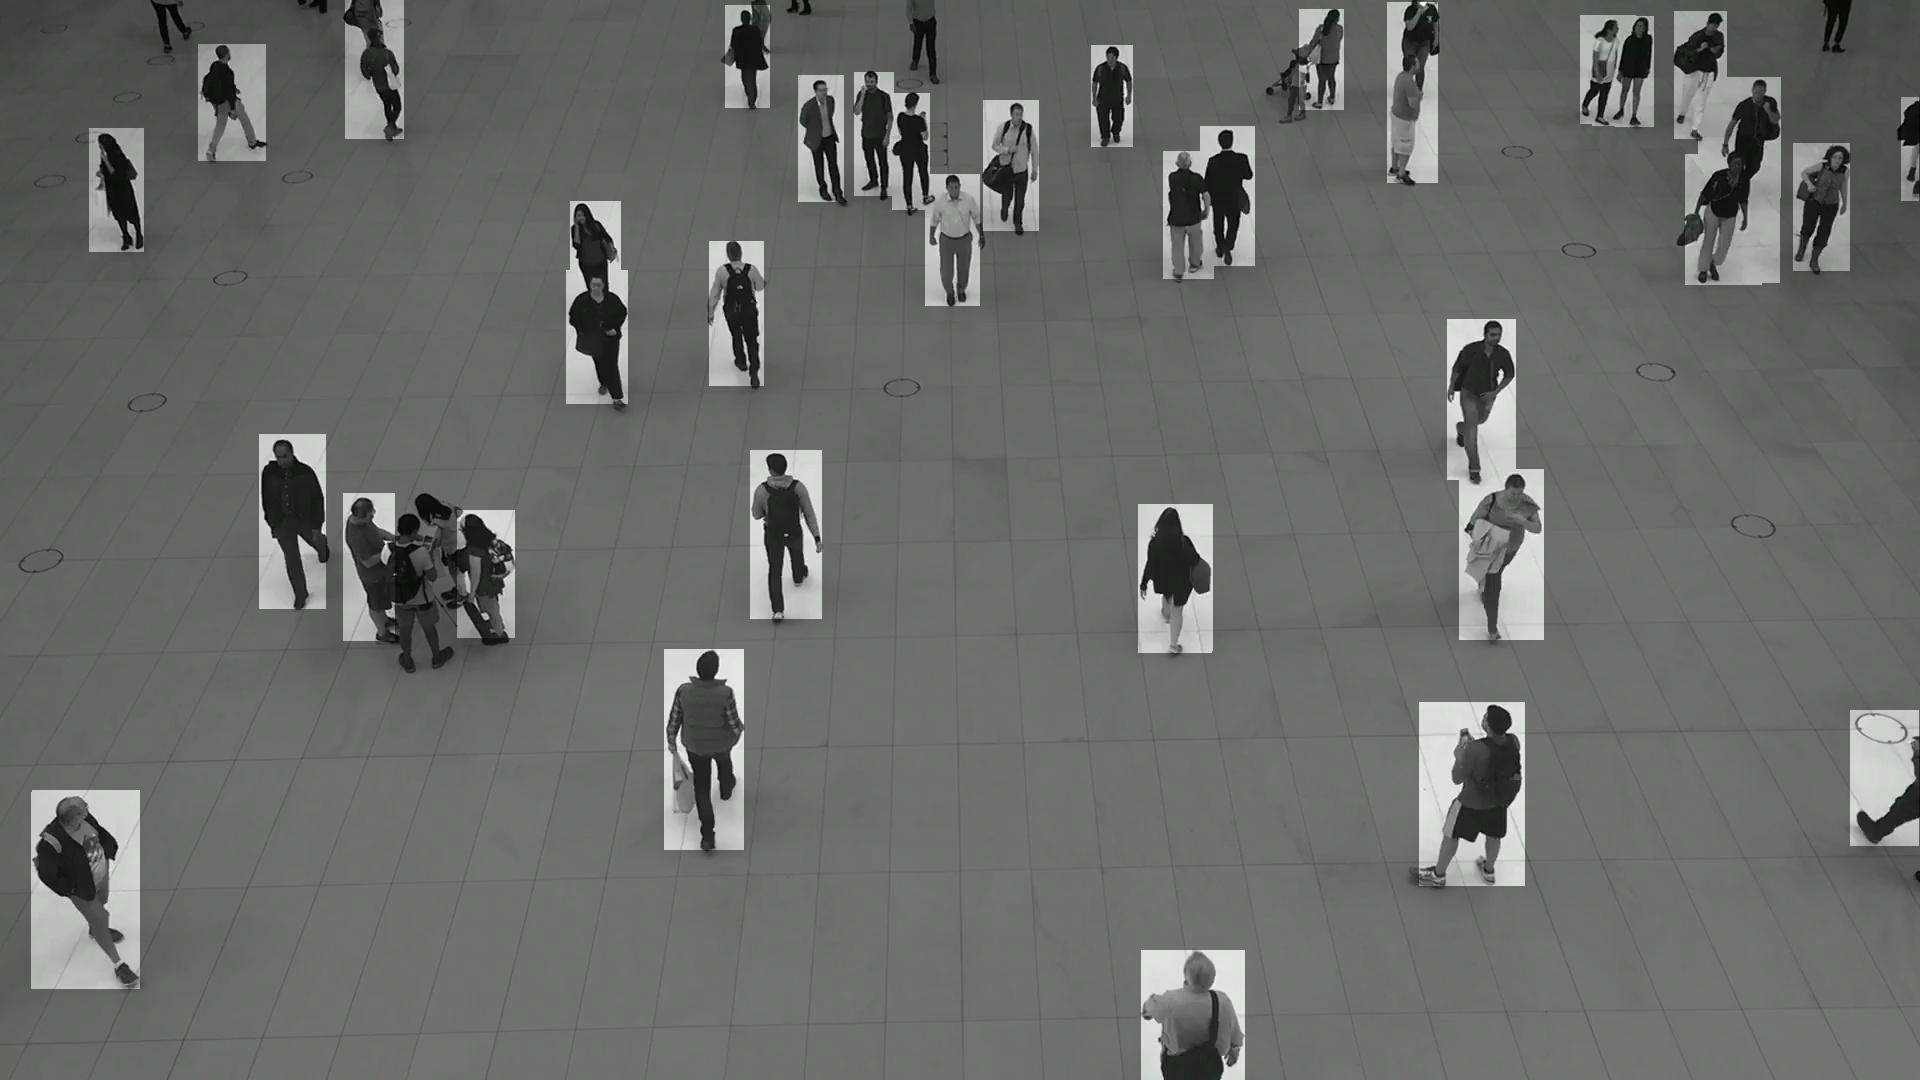
|
||||
|
||||
</div>
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BoxAnnotator">BoxAnnotator</a></h2>
|
||||
</div>
|
||||
@@ -529,6 +577,12 @@ status: new
|
||||
|
||||
:::supervision.annotators.core.RichLabelAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.IconAnnotator">IconAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.IconAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BlurAnnotator">BlurAnnotator</a></h2>
|
||||
</div>
|
||||
@@ -553,6 +607,12 @@ status: new
|
||||
|
||||
:::supervision.annotators.core.CropAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BackgroundOverlayAnnotator">BackgroundOverlayAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.BackgroundOverlayAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.ColorLookup">ColorLookup</a></h2>
|
||||
</div>
|
||||
|
||||
@@ -2,7 +2,10 @@
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Metrics
|
||||
# Legacy Metrics
|
||||
|
||||
Starting with `0.23.0`, a new metrics module is being introduced to supervision.
|
||||
Metrics here are part of the legacy evaluation API and will be deprecated in the future.
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# InferenceSlicer
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detection Utils
|
||||
@@ -78,19 +77,19 @@ status: new
|
||||
:::supervision.detection.utils.pad_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.contains_holes">contains_holes</a></h2>
|
||||
<h2><a href="#supervision.detection.utils.xywh_to_xyxy">xywh_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.xywh_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.xywh_to_xyxy">xywh_to_xyxy</a></h2>
|
||||
<h2><a href="#supervision.detection.utils.xcycwh_to_xyxy">xcycwh_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.xcycwh_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.xcycwh_to_xyxy">xcycwh_to_xyxy</a></h2>
|
||||
<h2><a href="#supervision.detection.utils.contains_holes">contains_holes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.contains_holes
|
||||
|
||||
@@ -0,0 +1,454 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
With Supervision, you can load and manipulate classification, object detection, and
|
||||
segmentation datasets. This tutorial will walk you through how to load, split, merge,
|
||||
visualize, and augment datasets in Supervision.
|
||||
|
||||
## Download Dataset
|
||||
|
||||
In this tutorial, we will use a dataset from
|
||||
[Roboflow Universe](https://universe.roboflow.com/), a public repository of
|
||||
thousands of computer vision datasets. If you already have your dataset in
|
||||
[COCO](https://roboflow.com/formats/coco-json),
|
||||
[YOLO](https://roboflow.com/formats/yolov8-pytorch-txt),
|
||||
or [Pascal VOC](https://roboflow.com/formats/pascal-voc-xml) format, you can skip this
|
||||
section.
|
||||
|
||||
```bash
|
||||
pip install roboflow
|
||||
```
|
||||
|
||||
Next, log into your Roboflow account and download the dataset of your choice in the
|
||||
COCO, YOLO, or Pascal VOC format. You can customize the following code snippet with
|
||||
your workspace ID, project ID, and version number.
|
||||
|
||||
=== "COCO"
|
||||
|
||||
```python
|
||||
import roboflow
|
||||
|
||||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace('<WORKSPACE_ID>').project('<PROJECT_ID>')
|
||||
dataset = project.version('<PROJECT_VERSION>').download("coco")
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
||||
```python
|
||||
import roboflow
|
||||
|
||||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace('<WORKSPACE_ID>').project('<PROJECT_ID>')
|
||||
dataset = project.version('<PROJECT_VERSION>').download("yolov8")
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
```python
|
||||
import roboflow
|
||||
|
||||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace('<WORKSPACE_ID>').project('<PROJECT_ID>')
|
||||
dataset = project.version('<PROJECT_VERSION>').download("voc")
|
||||
```
|
||||
|
||||
## Load Dataset
|
||||
|
||||
The Supervision library provides convenient functions to load datasets in various
|
||||
formats. If your dataset is already split into train, test, and valid subsets, you can
|
||||
load each of those as separate [`sv.DetectionDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset)
|
||||
instances.
|
||||
|
||||
=== "COCO"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.from_coco`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.from_coco) to load annotations in [COCO](https://roboflow.com/formats/coco-json) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/train',
|
||||
annotations_path=f'{dataset.location}/train/_annotations.coco.json',
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/valid',
|
||||
annotations_path=f'{dataset.location}/valid/_annotations.coco.json',
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/test',
|
||||
annotations_path=f'{dataset.location}/test/_annotations.coco.json',
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.from_yolo`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.from_yolo) to load annotations in [YOLO](https://roboflow.com/formats/yolov8-pytorch-txt) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.from_pascal_voc`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.from_pascal_voc) to load annotations in [Pascal VOC](https://roboflow.com/formats/pascal-voc-xml) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
## Split Dataset
|
||||
|
||||
If your dataset is not already split into train, test, and valid subsets, you can
|
||||
easily do so using the [`sv.DetectionDataset.split`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.split)
|
||||
method. We can split it as follows, ensuring a random shuffle of the data.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
len(ds)
|
||||
# 1000
|
||||
|
||||
ds_train, ds = ds.split(split_ratio=0.8, shuffle=True)
|
||||
ds_valid, ds_test = ds.split(split_ratio=0.5, shuffle=True)
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
## Merge Dataset
|
||||
|
||||
If you have multiple datasets that you would like to merge, you can do so using the
|
||||
[`sv.DetectionDataset.merge`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.merge)
|
||||
method.
|
||||
|
||||
=== "COCO"
|
||||
|
||||
```{ .py hl_lines="22-28" }
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/train',
|
||||
annotations_path=f'{dataset.location}/train/_annotations.coco.json',
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/valid',
|
||||
annotations_path=f'{dataset.location}/valid/_annotations.coco.json',
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/test',
|
||||
annotations_path=f'{dataset.location}/test/_annotations.coco.json',
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
|
||||
ds = sv.DetectionDataset.merge([ds_train, ds_valid, ds_test])
|
||||
|
||||
ds.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds)
|
||||
# 1000
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
||||
```{ .py hl_lines="25-31" }
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
|
||||
ds = sv.DetectionDataset.merge([ds_train, ds_valid, ds_test])
|
||||
|
||||
ds.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds)
|
||||
# 1000
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
```{ .py hl_lines="22-28" }
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
|
||||
ds = sv.DetectionDataset.merge([ds_train, ds_valid, ds_test])
|
||||
|
||||
ds.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds)
|
||||
# 1000
|
||||
```
|
||||
|
||||
## Iterate over Dataset
|
||||
|
||||
There are two ways to loop over a `sv.DetectionDataset`: using a direct
|
||||
[for loop](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__iter__)
|
||||
called on the `sv.DetectionDataset` instance or loading `sv.DetectionDataset` entries
|
||||
[by index](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__getitem__).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
# Option 1
|
||||
for image_path, image, annotations in ds:
|
||||
... # Process each image and its annotations
|
||||
|
||||
# Option 2
|
||||
for idx in range(len(ds)):
|
||||
image_path, image, annotations = ds[idx]
|
||||
... # Process the image and annotations at index `idx`
|
||||
```
|
||||
|
||||
## Visualize Dataset
|
||||
|
||||
The Supervision library provides tools for easily visualizing your detection dataset.
|
||||
You can create a grid of annotated images to quickly inspect your data and labels.
|
||||
First, initialize the [`sv.BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator)
|
||||
and [`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator).
|
||||
Then, iterate through a subset of the dataset (e.g., the first 25 images), drawing
|
||||
bounding boxes and class labels on each image. Finally, combine the annotated images
|
||||
into a grid for display.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_images = []
|
||||
for i in range(16):
|
||||
_, image, annotations = ds[i]
|
||||
|
||||
labels = [ds.classes[class_id] for class_id in annotations.class_id]
|
||||
|
||||
annotated_image = image.copy()
|
||||
annotated_image = box_annotator.annotate(annotated_image, annotations)
|
||||
annotated_image = label_annotator.annotate(annotated_image, annotations, labels)
|
||||
annotated_images.append(annotated_image)
|
||||
|
||||
grid = sv.create_tiles(
|
||||
annotated_images,
|
||||
grid_size=(4, 4),
|
||||
single_tile_size=(400, 400),
|
||||
tile_padding_color=sv.Color.WHITE,
|
||||
tile_margin_color=sv.Color.WHITE
|
||||
)
|
||||
```
|
||||
|
||||
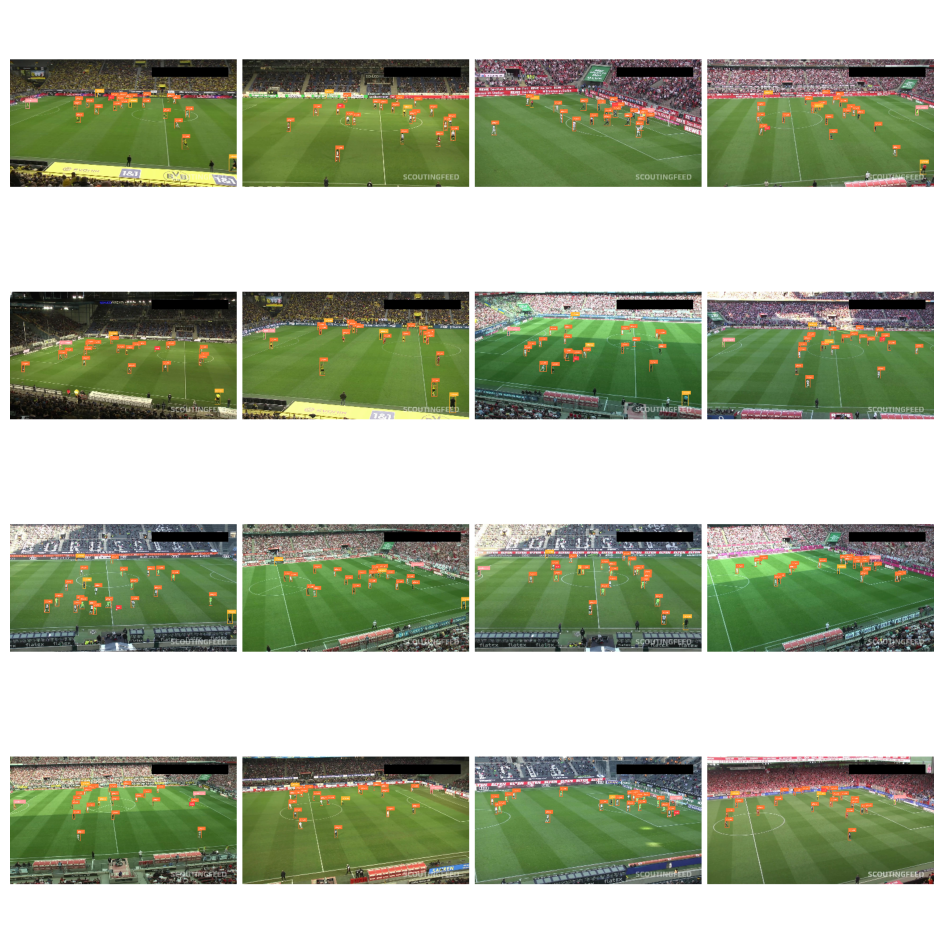
|
||||
|
||||
## Save Dataset
|
||||
|
||||
=== "COCO"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.as_coco`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_coco) method to save annotations in [COCO](https://roboflow.com/formats/coco-json) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
ds.as_coco(
|
||||
images_directory_path='<IMAGE_DIRECTORY_PATH>',
|
||||
annotations_path='<ANNOTATIONS_PATH>'
|
||||
)
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.as_yolo`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_yolo) method to save annotations in [YOLO](https://roboflow.com/formats/yolov8-pytorch-txt) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
ds.as_yolo(
|
||||
images_directory_path='<IMAGE_DIRECTORY_PATH>',
|
||||
annotations_directory_path='<ANNOTATIONS_DIRECTORY_PATH>',
|
||||
data_yaml_path='<DATA_YAML_PATH>'
|
||||
)
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.as_pascal_voc`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_pascal_voc) method to save annotations in [Pascal VOC](https://roboflow.com/formats/pascal-voc-xml) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
ds.as_pascal_voc(
|
||||
images_directory_path='<IMAGE_DIRECTORY_PATH>',
|
||||
annotations_directory_path='<ANNOTATIONS_DIRECTORY_PATH>'
|
||||
)
|
||||
```
|
||||
|
||||
## Augment Dataset
|
||||
|
||||
In this section, we'll explore using Supervision in combination with Albumentations to
|
||||
augment our dataset. Data augmentation is a common technique in computer vision to
|
||||
increase the size and diversity of training datasets, leading to improved model
|
||||
performance and generalization.
|
||||
|
||||
```bash
|
||||
pip install augmentation
|
||||
```
|
||||
|
||||
Albumentations provides a flexible and powerful API for image augmentation. The core of
|
||||
the library is the [`Compose`](https://albumentations.ai/docs/api_reference/full_reference/?h=compose#albumentations.core.composition.Compose)
|
||||
class, which allows you to chain multiple image transformations together. Each
|
||||
transformation is defined using a dedicated class, such as
|
||||
[`HorizontalFlip`](https://albumentations.ai/docs/api_reference/full_reference/?h=horizontalflip#albumentations.augmentations.geometric.transforms.HorizontalFlip),
|
||||
[`RandomBrightnessContrast`](https://albumentations.ai/docs/api_reference/full_reference/?h=horizontalflip#albumentations.augmentations.transforms.RandomBrightnessContrast),
|
||||
or [`Perspective`](https://albumentations.ai/docs/api_reference/full_reference/?h=horizontalflip#albumentations.augmentations.geometric.transforms.Perspective).
|
||||
|
||||
```python
|
||||
import albumentations as A
|
||||
|
||||
augmentation = A.Compose(
|
||||
transforms=[
|
||||
A.Perspective(p=0.1),
|
||||
A.HorizontalFlip(p=0.5),
|
||||
A.RandomBrightnessContrast(p=0.5)
|
||||
],
|
||||
bbox_params=A.BboxParams(
|
||||
format='pascal_voc',
|
||||
label_fields=['category']
|
||||
),
|
||||
)
|
||||
```
|
||||
|
||||
The key is to set `format='pascal_voc'`, which corresponds to the
|
||||
`[x_min, y_min, x_max, y_max]` bounding box format used in Supervision.
|
||||
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from dataclasses import replace
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
_, original_image, original_annotations = ds[0]
|
||||
|
||||
output = augmentation(
|
||||
image=original_image,
|
||||
bboxes=original_annotations.xyxy,
|
||||
category=original_annotations.class_id
|
||||
)
|
||||
|
||||
augmented_image = output['image']
|
||||
augmented_annotations = replace(
|
||||
original_annotations,
|
||||
xyxy=np.array(output['bboxes']),
|
||||
class_id=np.array(output['category'])
|
||||
)
|
||||
```
|
||||
|
||||
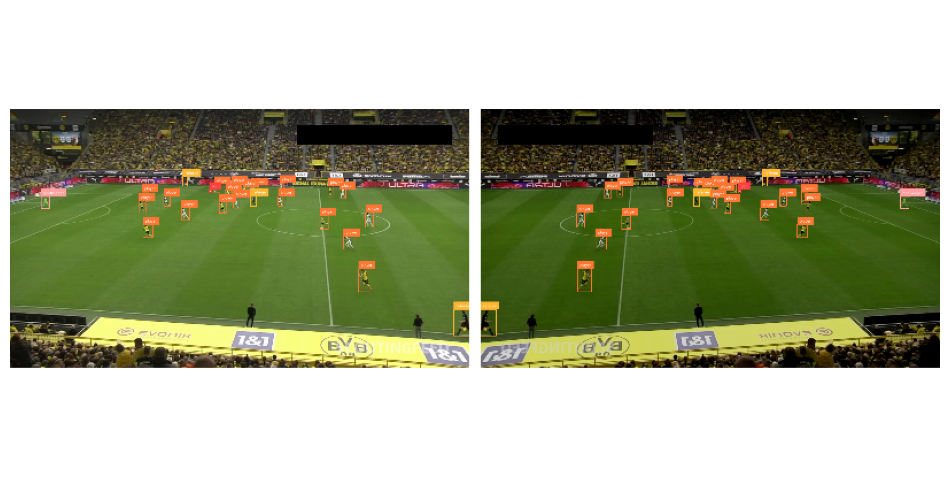
|
||||
@@ -32,7 +32,7 @@ download_assets(VideoAssets.PEOPLE_WALKING)
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. In this tutorial, we are using the YOLOv8 model as an example. However,
|
||||
Supervision is versatile and compatible with various models. Check this
|
||||
[link](latest/how_to/detect_and_annotate/#load-predictions-into-supervision)
|
||||
[link](/latest/how_to/detect_and_annotate/#load-predictions-into-supervision)
|
||||
for guidance on how to plug in other models.
|
||||
|
||||
We will define a `callback` function, which will process each frame of the video
|
||||
|
||||
@@ -28,16 +28,15 @@ document.addEventListener("DOMContentLoaded", function () {
|
||||
}, {});
|
||||
|
||||
|
||||
async function renderCard(element, elementIndex) {
|
||||
const url = element.getAttribute('data-url');
|
||||
const name = element.getAttribute('data-name');
|
||||
const labels = element.getAttribute('data-labels');
|
||||
const version = element.getAttribute('data-version');
|
||||
const authors = element.getAttribute('data-author');
|
||||
async function renderCard(element, elementIndex) {
|
||||
const name = element.getAttribute('data-name');
|
||||
const labels = element.getAttribute('data-labels');
|
||||
const version = element.getAttribute('data-version');
|
||||
const authors = element.getAttribute('data-author');
|
||||
|
||||
const labelHTML = labels ? labels.split(',').filter(label => label !== '').map((label, index) => {
|
||||
const color = labelToColor[label.trim()];
|
||||
return `
|
||||
const labelHTML = labels ? labels.split(',').filter(label => label !== '').map((label, index) => {
|
||||
const color = labelToColor[label.trim()];
|
||||
return `
|
||||
<span
|
||||
class="label non-selectable-text"
|
||||
style="background-color: ${color}"
|
||||
@@ -45,18 +44,18 @@ document.addEventListener("DOMContentLoaded", function () {
|
||||
${label.trim()}
|
||||
</span>
|
||||
`;
|
||||
}).join(' ') : '';
|
||||
}).join(' ') : '';
|
||||
|
||||
const authorArray = authors.split(',');
|
||||
const authorDataArray = await Promise.all(authorArray.map(async (author) => {
|
||||
const response = await fetch(`https://api.github.com/users/${author.trim()}`);
|
||||
return await response.json();
|
||||
}));
|
||||
const authorArray = authors.split(',');
|
||||
const authorDataArray = await Promise.all(authorArray.map(async (author) => {
|
||||
const response = await fetch(`https://api.github.com/users/${author.trim()}`);
|
||||
return await response.json();
|
||||
}));
|
||||
|
||||
let authorAvatarsHTML = authorDataArray.map((authorData, index) => {
|
||||
const marginLeft = index === 0 ? '0' : '-10px';
|
||||
const zIndex = 4 - index;
|
||||
return `
|
||||
let authorAvatarsHTML = authorDataArray.map((authorData, index) => {
|
||||
const marginLeft = index === 0 ? '0' : '-10px';
|
||||
const zIndex = 4 - index;
|
||||
return `
|
||||
<div
|
||||
class="author-container"
|
||||
data-login="${authorData.login}-${elementIndex}"
|
||||
@@ -75,10 +74,10 @@ document.addEventListener("DOMContentLoaded", function () {
|
||||
</a>
|
||||
</div>
|
||||
`;
|
||||
}).join('');
|
||||
}).join('');
|
||||
|
||||
let authorNamesHTML = authorDataArray.map(
|
||||
authorData => `
|
||||
let authorNamesHTML = authorDataArray.map(
|
||||
authorData => `
|
||||
<span
|
||||
class="author-name"
|
||||
data-login="${authorData.login}-${elementIndex}"
|
||||
@@ -88,54 +87,52 @@ document.addEventListener("DOMContentLoaded", function () {
|
||||
${authorData.login}
|
||||
</a>
|
||||
</span>`
|
||||
).join(', ');
|
||||
).join(', ');
|
||||
|
||||
let authorsHTML = `
|
||||
let authorsHTML = `
|
||||
<div class="authors">
|
||||
${authorAvatarsHTML}
|
||||
<div class="author-names">${authorNamesHTML}</div>
|
||||
</div>
|
||||
`;
|
||||
`;
|
||||
|
||||
element.innerText = `
|
||||
<a style="text-decoration: none; color: inherit;" href="${url}">
|
||||
<div style="flex-direction: column; height: 100%; display: flex;
|
||||
font-family: -apple-system,BlinkMacSystemFont,Segoe UI,Helvetica,Arial,sans-serif,Apple Color Emoji,Segoe UI Emoji; background: ${theme.background}; font-size: 14px; line-height: 1.5; color: ${theme.color}">
|
||||
<div style="display: flex; align-items: center;">
|
||||
<span style="font-weight: 700; font-size: 1rem; color: ${theme.linkColor};">
|
||||
${name}
|
||||
</span>
|
||||
</div>
|
||||
${authorsHTML}
|
||||
<div style="font-size: 12px; color: ${theme.color}; display: flex; flex: 0; justify-content: space-between">
|
||||
element.innerText = `
|
||||
<div style="flex-direction: column; height: 100%; display: flex;
|
||||
font-family: -apple-system,BlinkMacSystemFont,Segoe UI,Helvetica,Arial,sans-serif,Apple Color Emoji,Segoe UI Emoji; background: ${theme.background}; font-size: 14px; line-height: 1.5; color: ${theme.color}">
|
||||
<div style="display: flex; align-items: center;">
|
||||
<img src="/assets/supervision-lenny.png" aria-label="stars" width="20" height="20" role="img" />
|
||||
|
||||
<span style="margin-left: 4px">${version}</span>
|
||||
<span style="font-weight: 700; font-size: 1rem; color: ${theme.linkColor};">
|
||||
${name}
|
||||
</span>
|
||||
</div>
|
||||
<div style="display: flex; align-items: center; flex-wrap: wrap">
|
||||
${labelHTML}
|
||||
${authorsHTML}
|
||||
<div style="font-size: 12px; color: ${theme.color}; display: flex; flex: 0; justify-content: space-between">
|
||||
<div style="display: flex; align-items: center;">
|
||||
<img src="/assets/supervision-lenny.png" aria-label="stars" width="20" height="20" role="img" />
|
||||
|
||||
<span style="margin-left: 4px">${version}</span>
|
||||
</div>
|
||||
<div style="display: flex; align-items: center; flex-wrap: wrap">
|
||||
${labelHTML}
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
</a>
|
||||
`
|
||||
`;
|
||||
|
||||
let sanitizedHTML = DOMPurify.sanitize(element.innerText);
|
||||
element.innerHTML = sanitizedHTML;
|
||||
let sanitizedHTML = DOMPurify.sanitize(element.innerText);
|
||||
element.innerHTML = sanitizedHTML;
|
||||
|
||||
document.querySelectorAll('.author-name').forEach(element => {
|
||||
element.addEventListener('mouseenter', function() {
|
||||
const login = this.getAttribute('data-login');
|
||||
document.querySelector(`.author-container[data-login="${login}"]`).classList.add('hover');
|
||||
document.querySelectorAll('.author-name').forEach(element => {
|
||||
element.addEventListener('mouseenter', function () {
|
||||
const login = this.getAttribute('data-login');
|
||||
document.querySelector(`.author-container[data-login="${login}"]`).classList.add('hover');
|
||||
});
|
||||
|
||||
element.addEventListener('mouseleave', function () {
|
||||
const login = this.getAttribute('data-login');
|
||||
document.querySelector(`.author-container[data-login="${login}"]`).classList.remove('hover');
|
||||
});
|
||||
});
|
||||
|
||||
element.addEventListener('mouseleave', function() {
|
||||
const login = this.getAttribute('data-login');
|
||||
document.querySelector(`.author-container[data-login="${login}"]`).classList.remove('hover');
|
||||
});
|
||||
});
|
||||
}
|
||||
}
|
||||
repoCards.forEach((element, index) => {
|
||||
renderCard(element, index);
|
||||
});
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Keypoint Detection
|
||||
|
||||
@@ -0,0 +1,18 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Mean Average Precision
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.mean_average_precision.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.mean_average_precision.MeanAveragePrecision
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.mean_average_precision.MeanAveragePrecisionResult">MeanAveragePrecisionResult</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.mean_average_precision.MeanAveragePrecisionResult
|
||||
Vendored
+324
-331
File diff suppressed because one or more lines are too long
+1
-1
@@ -10,7 +10,7 @@
|
||||
"\n",
|
||||
"---\n",
|
||||
"\n",
|
||||
"[](https://colab.research.google.com/github/roboflow/supervision/blob/develop/docs/notebooks/detections-to-jsonsink.ipynb)\n",
|
||||
"[](https://colab.research.google.com/github/roboflow/supervision/blob/develop/docs/notebooks/serialise-detections-to-csv.ipynb)\n",
|
||||
"\n",
|
||||
"This cookbook introduce [sv.CSVSink](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) tool designed to write captured object detection data to file from video streams/file"
|
||||
]
|
||||
|
||||
+1
-1
@@ -10,7 +10,7 @@
|
||||
"\n",
|
||||
"---\n",
|
||||
"\n",
|
||||
"[](https://colab.research.google.com/github/roboflow/supervision/blob/develop/docs/notebooks/detections-to-jsonsink.ipynb)\n",
|
||||
"[](https://colab.research.google.com/github/roboflow/supervision/blob/develop/docs/notebooks/serialise-detections-to-json.ipynb)\n",
|
||||
"\n",
|
||||
"This cookbook introduce [sv.JSONSink](https://supervision.roboflow.com/develop/detection/tools/save_detections/#supervision.detection.tools.json_sink.JSONSink) tool designed to write captured object detection data to file from video streams/file"
|
||||
]
|
||||
|
||||
@@ -19,6 +19,16 @@
|
||||
}
|
||||
}
|
||||
|
||||
.custom-grid a {
|
||||
color: inherit;
|
||||
text-decoration: none;
|
||||
display: block;
|
||||
}
|
||||
|
||||
.custom-grid a:hover {
|
||||
color: inherit; /* Ensure color does not change on hover */
|
||||
}
|
||||
|
||||
.repo-card {
|
||||
background: radial-gradient(at right top, #A351FB25, #A5F9EA25);
|
||||
border-radius: 0.5rem;
|
||||
|
||||
Vendored
+39
-11
@@ -11,17 +11,45 @@
|
||||
<h1>Supervision Cookbooks</h1>
|
||||
</div>
|
||||
<div class="custom-grid">
|
||||
<p class="card repo-card" data-url="/develop/notebooks/quickstart" data-name="Supervision Quickstart" data-labels="ANNOTATOR,DETECTION,SAM" data-version="v0.18.0" data-author="SkalskiP,onuralpszr"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/count-objects-crossing-the-line" data-name="Count Objects Crossing the Line" data-labels="ANNOTATORS,LINE ZONE,TRACKING" data-version="v0.18.0" data-author="SkalskiP"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/zero-shot-object-detection-with-yolo-world" data-name="Zero-Shot Object Detection with YOLO-World" data-labels="ANNOTATORS,DETECTION,INFERENCE" data-version="v0.19.0" data-author="SkalskiP"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/download-supervision-assets" data-name="Downloading Supervision Assets" data-labels="ASSETS" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/annotate-video-with-detections" data-name="Annotate Video with Detections" data-labels="INFERENCE,YOLOV8" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/object-tracking" data-name="Object Tracking" data-labels="TRACKING, ANNOTATOR" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/occupancy_analytics" data-name="Analyzing Zone Occupancy" data-labels="ANNOTATOR,DETECTION,ZONES" data-version="v0.19.0" data-author="stellasphere"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/evaluating-alignment-of-text-to-image-diffusion-models" data-name="Evaluating Alignment of Text-to-image Diffusion Models" data-labels="ANNOTATORS,YOLO WORLD" data-version="v0.19.0rc5" data-author="iamhatesz"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/serialise-detections-to-csv" data-name="Serialise Detections to a CSV File" data-labels="DETECTIONS,CSV SINK,INFERENCE" data-version="v0.21.0" data-author="onuralpszr"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/serialise-detections-to-json" data-name="Serialise Detections to a JSON File" data-labels="DETECTIONS,JSON SINK,INFERENCE" data-version="v0.21.0" data-author="onuralpszr"></p>
|
||||
|
||||
<a href="/develop/notebooks/quickstart"> <p class="card repo-card" data-name="Supervision Quickstart" data-labels="ANNOTATOR,DETECTION,SAM"
|
||||
data-version="v0.18.0" data-author="SkalskiP,onuralpszr"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/count-objects-crossing-the-line">
|
||||
<p class="card repo-card" data-name="Count Objects Crossing the Line"
|
||||
data-labels="ANNOTATORS,LINE ZONE,TRACKING" data-version="v0.18.0" data-author="SkalskiP"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/zero-shot-object-detection-with-yolo-world">
|
||||
<p class="card repo-card" data-name="Zero-Shot Object Detection with YOLO-World"
|
||||
data-labels="ANNOTATORS,DETECTION,INFERENCE" data-version="v0.19.0" data-author="SkalskiP"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/download-supervision-assets">
|
||||
<p class="card repo-card" data-name="Downloading Supervision Assets" data-labels="ASSETS" data-version="v0.18.0"
|
||||
data-author="nickherrig"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/annotate-video-with-detections">
|
||||
<p class="card repo-card" data-name="Annotate Video with Detections" data-labels="INFERENCE,YOLOV8"
|
||||
data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/object-tracking">
|
||||
<p class="card repo-card" data-name="Object Tracking" data-labels="TRACKING, ANNOTATOR" data-version="v0.18.0"
|
||||
data-author="nickherrig"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/occupancy_analytics">
|
||||
<p class="card repo-card" data-name="Analyzing Zone Occupancy" data-labels="ANNOTATOR,DETECTION,ZONES"
|
||||
data-version="v0.19.0" data-author="stellasphere"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/evaluating-alignment-of-text-to-image-diffusion-models">
|
||||
<p class="card repo-card" data-name="Evaluating Alignment of Text-to-image Diffusion Models"
|
||||
data-labels="ANNOTATORS,YOLO WORLD" data-version="v0.19.0rc5" data-author="iamhatesz"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/serialise-detections-to-csv">
|
||||
<p class="card repo-card" data-name="Serialise Detections to a CSV File"
|
||||
data-labels="DETECTIONS,CSV SINK,INFERENCE" data-version="v0.21.0" data-author="onuralpszr"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/serialise-detections-to-json">
|
||||
<p class="card repo-card" data-name="Serialise Detections to a JSON File"
|
||||
data-labels="DETECTIONS,JSON SINK,INFERENCE" data-version="v0.21.0" data-author="onuralpszr"></p>
|
||||
</a>
|
||||
</div>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# File Utils
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Image Utils
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Video Utils
|
||||
|
||||
@@ -75,7 +75,7 @@ def detect(
|
||||
frame (np.ndarray): The frame to process, expected to be a NumPy array.
|
||||
model (RoboflowInferenceModel): The Inference model used for processing the
|
||||
frame.
|
||||
confidence_threshold (float, optional): The confidence threshold for filtering
|
||||
confidence_threshold (float): The confidence threshold for filtering
|
||||
detections. Default is 0.5.
|
||||
|
||||
Returns:
|
||||
|
||||
@@ -72,7 +72,7 @@ def detect(
|
||||
Args:
|
||||
frame (np.ndarray): The frame to process, expected to be a NumPy array.
|
||||
model (YOLO): The YOLO model used for processing the frame.
|
||||
confidence_threshold (float, optional): The confidence threshold for filtering
|
||||
confidence_threshold (float): The confidence threshold for filtering
|
||||
detections. Default is 0.5.
|
||||
|
||||
Returns:
|
||||
|
||||
@@ -20,9 +20,9 @@ def heatmap_and_track(
|
||||
iou_threshold: float = 0.5,
|
||||
heatmap_alpha: float = 0.5,
|
||||
radius: int = 25,
|
||||
track_threshold: float = 0.35,
|
||||
track_activation_threshold: float = 0.35,
|
||||
track_seconds: int = 5,
|
||||
match_threshold: float = 0.99,
|
||||
minimum_matching_threshold: float = 0.99,
|
||||
) -> None:
|
||||
### instantiate model
|
||||
model = YOLO(source_weights_path)
|
||||
@@ -47,9 +47,9 @@ def heatmap_and_track(
|
||||
|
||||
### tracker config
|
||||
byte_tracker = sv.ByteTrack(
|
||||
track_thresh=track_threshold,
|
||||
track_buffer=track_seconds * fps,
|
||||
match_thresh=match_threshold,
|
||||
track_activation_threshold=track_activation_threshold,
|
||||
lost_track_buffer=track_seconds * fps,
|
||||
minimum_matching_threshold=minimum_matching_threshold,
|
||||
frame_rate=fps,
|
||||
)
|
||||
|
||||
@@ -175,7 +175,7 @@ if __name__ == "__main__":
|
||||
iou_threshold=args.iou_threshold,
|
||||
heatmap_alpha=args.heatmap_alpha,
|
||||
radius=args.radius,
|
||||
track_threshold=args.track_threshold,
|
||||
track_activation_threshold=args.track_threshold,
|
||||
track_seconds=args.track_seconds,
|
||||
match_threshold=args.match_threshold,
|
||||
minimum_matching_threshold=args.match_threshold,
|
||||
)
|
||||
|
||||
@@ -95,7 +95,7 @@ if __name__ == "__main__":
|
||||
model = get_roboflow_model(model_id=args.model_id, api_key=args.roboflow_api_key)
|
||||
|
||||
byte_track = sv.ByteTrack(
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
frame_rate=video_info.fps, track_activation_threshold=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_optimal_line_thickness(
|
||||
|
||||
@@ -73,7 +73,7 @@ if __name__ == "__main__":
|
||||
model = YOLO("yolov8x.pt")
|
||||
|
||||
byte_track = sv.ByteTrack(
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
frame_rate=video_info.fps, track_activation_threshold=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_optimal_line_thickness(
|
||||
|
||||
@@ -74,7 +74,7 @@ if __name__ == "__main__":
|
||||
model = models.get(Models.YOLO_NAS_L, pretrained_weights="coco")
|
||||
|
||||
byte_track = sv.ByteTrack(
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
frame_rate=video_info.fps, track_activation_threshold=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_optimal_line_thickness(
|
||||
|
||||
@@ -22,7 +22,7 @@ class FPSBasedTimer:
|
||||
"""Initializes the FPSBasedTimer with the specified frames per second rate.
|
||||
|
||||
Args:
|
||||
fps (int, optional): The frame rate of the video stream. Defaults to 30.
|
||||
fps (int): The frame rate of the video stream. Defaults to 30.
|
||||
"""
|
||||
self.fps = fps
|
||||
self.frame_id = 0
|
||||
|
||||
+45
-48
@@ -33,7 +33,6 @@ extra_css:
|
||||
- stylesheets/extra.css
|
||||
- stylesheets/cookbooks-card.css
|
||||
|
||||
|
||||
nav:
|
||||
- Supervision: index.md
|
||||
- Learn:
|
||||
@@ -42,52 +41,53 @@ nav:
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
- Detect Small Objects: how_to/detect_small_objects.md
|
||||
- Track Objects on Video: how_to/track_objects.md
|
||||
- Process Datasets: how_to/process_datasets.md
|
||||
|
||||
- Reference - Code API:
|
||||
- Detection and Segmentation:
|
||||
- Core: detection/core.md
|
||||
- Annotators: detection/annotators.md
|
||||
- Metrics: detection/metrics.md
|
||||
- Double Detection Filter: detection/double_detection_filter.md
|
||||
- Utils: detection/utils.md
|
||||
- Keypoint Detection:
|
||||
- Core: keypoint/core.md
|
||||
- Annotators: keypoint/annotators.md
|
||||
- Classification:
|
||||
- Core: classification/core.md
|
||||
- Tools:
|
||||
- Line Zone: detection/tools/line_zone.md
|
||||
- Polygon Zone: detection/tools/polygon_zone.md
|
||||
- Inference Slicer: detection/tools/inference_slicer.md
|
||||
- Detection Smoother: detection/tools/smoother.md
|
||||
- Save Detections: detection/tools/save_detections.md
|
||||
- Trackers: trackers.md
|
||||
- Datasets:
|
||||
- Core: datasets/core.md
|
||||
- Utils: datasets/utils.md
|
||||
- Utils:
|
||||
- Video: utils/video.md
|
||||
- Image: utils/image.md
|
||||
- Iterables: utils/iterables.md
|
||||
- Notebook: utils/notebook.md
|
||||
- File: utils/file.md
|
||||
- Draw: utils/draw.md
|
||||
- Geometry: utils/geometry.md
|
||||
- Assets: assets.md
|
||||
- Detection and Segmentation:
|
||||
- Core: detection/core.md
|
||||
- Annotators: detection/annotators.md
|
||||
- Double Detection Filter: detection/double_detection_filter.md
|
||||
- Utils: detection/utils.md
|
||||
- Keypoint Detection:
|
||||
- Core: keypoint/core.md
|
||||
- Annotators: keypoint/annotators.md
|
||||
- Classification:
|
||||
- Core: classification/core.md
|
||||
- Tools:
|
||||
- Line Zone: detection/tools/line_zone.md
|
||||
- Polygon Zone: detection/tools/polygon_zone.md
|
||||
- Inference Slicer: detection/tools/inference_slicer.md
|
||||
- Detection Smoother: detection/tools/smoother.md
|
||||
- Save Detections: detection/tools/save_detections.md
|
||||
- Trackers: trackers.md
|
||||
- Datasets:
|
||||
- Core: datasets/core.md
|
||||
- Utils: datasets/utils.md
|
||||
- Metrics:
|
||||
- mAP: metrics/mean_average_precision.md
|
||||
- Legacy Metrics: detection/metrics.md
|
||||
- Utils:
|
||||
- Video: utils/video.md
|
||||
- Image: utils/image.md
|
||||
- Iterables: utils/iterables.md
|
||||
- Notebook: utils/notebook.md
|
||||
- File: utils/file.md
|
||||
- Draw: utils/draw.md
|
||||
- Geometry: utils/geometry.md
|
||||
- Assets: assets.md
|
||||
- Cookbooks: cookbooks.md
|
||||
- Cheatsheet: https://roboflow.github.io/cheatsheet-supervision/
|
||||
- Contribute:
|
||||
- Contributing: contributing.md
|
||||
- Code of Conduct: code_of_conduct.md
|
||||
- License: license.md
|
||||
- Contributing: contributing.md
|
||||
- Code of Conduct: code_of_conduct.md
|
||||
- License: license.md
|
||||
- Release Notes:
|
||||
- Changelog: changelog.md
|
||||
- Deprecated: deprecated.md
|
||||
|
||||
|
||||
- Changelog: changelog.md
|
||||
- Deprecated: deprecated.md
|
||||
|
||||
theme:
|
||||
name: 'material'
|
||||
name: "material"
|
||||
icon:
|
||||
edit: material/pencil
|
||||
logo: assets/supervision-lenny.png
|
||||
@@ -104,19 +104,18 @@ theme:
|
||||
palette:
|
||||
# Palette for light mode
|
||||
- scheme: default
|
||||
primary: 'custom'
|
||||
primary: "custom"
|
||||
toggle:
|
||||
icon: material/brightness-7
|
||||
name: Switch to dark mode
|
||||
|
||||
# Palette toggle for dark mode
|
||||
- scheme: slate
|
||||
primary: 'custom'
|
||||
primary: "custom"
|
||||
toggle:
|
||||
icon: material/brightness-4
|
||||
name: Switch to light mode
|
||||
|
||||
|
||||
font:
|
||||
text: Roboto
|
||||
code: Roboto Mono
|
||||
@@ -127,10 +126,10 @@ theme:
|
||||
plugins:
|
||||
- search
|
||||
- mkdocs-jupyter:
|
||||
kernel_name: python3
|
||||
execute: false
|
||||
include_source: True
|
||||
include_requirejs: true
|
||||
kernel_name: python3
|
||||
execute: false
|
||||
include_source: True
|
||||
include_requirejs: true
|
||||
- mkdocstrings:
|
||||
default_handler: python
|
||||
handlers:
|
||||
@@ -154,8 +153,6 @@ plugins:
|
||||
- git-revision-date-localized:
|
||||
enable_creation_date: true
|
||||
|
||||
|
||||
|
||||
markdown_extensions:
|
||||
- admonition
|
||||
- pymdownx.details
|
||||
|
||||
Generated
+1024
-824
File diff suppressed because it is too large
Load Diff
+27
-11
@@ -1,6 +1,6 @@
|
||||
[tool.poetry]
|
||||
name = "supervision"
|
||||
version = "0.22.0"
|
||||
version = "0.23.0"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
authors = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
maintainers = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
@@ -40,7 +40,10 @@ classifiers = [
|
||||
|
||||
[tool.poetry.dependencies]
|
||||
python = "^3.8"
|
||||
numpy = ">=1.21.2"
|
||||
numpy = [
|
||||
{ version = ">=1.21.2,<1.23.3", python = "<=3.10" },
|
||||
{ version = ">=1.23.3", python = ">3.10" },
|
||||
]
|
||||
scipy = [
|
||||
{ version = "1.10.0", python = "<3.9" },
|
||||
{ version = "^1.10.0", python = ">=3.9" },
|
||||
@@ -48,20 +51,24 @@ scipy = [
|
||||
matplotlib = ">=3.6.0"
|
||||
pyyaml = ">=5.3"
|
||||
defusedxml = "^0.7.1"
|
||||
pillow = ">=9.4"
|
||||
opencv-python = { version = ">=4.5.5.64", optional = true }
|
||||
opencv-python-headless = ">=4.5.5.64"
|
||||
requests = { version = ">=2.26.0,<=2.32.3", optional = true }
|
||||
tqdm = { version = ">=4.62.3,<=4.66.4", optional = true }
|
||||
pillow = ">=9.4"
|
||||
tqdm = { version = ">=4.62.3,<=4.66.5", optional = true }
|
||||
# pandas: picked lowest major version that supports Python 3.8
|
||||
pandas = { version = ">=2.0.0", optional = true }
|
||||
pandas-stubs = { version = ">=2.0.0.230412", optional = true }
|
||||
|
||||
[tool.poetry.extras]
|
||||
desktop = ["opencv-python"]
|
||||
assets = ["requests", "tqdm"]
|
||||
metrics = ["pandas", "pandas-stubs"]
|
||||
|
||||
[tool.poetry.group.dev.dependencies]
|
||||
twine = "^5.1.1"
|
||||
pytest = ">=7.2.2,<9.0.0"
|
||||
wheel = ">=0.40,<0.44"
|
||||
wheel = ">=0.40,<0.45"
|
||||
build = ">=0.10,<1.3"
|
||||
ruff = ">=0.1.0"
|
||||
mypy = "^1.4.1"
|
||||
@@ -76,10 +83,9 @@ docutils = [
|
||||
{ version = "^0.21.1", python = ">=3.9" },
|
||||
]
|
||||
|
||||
|
||||
[tool.poetry.group.docs.dependencies]
|
||||
mkdocs-material = { extras = ["imaging"], version = "^9.5.5" }
|
||||
mkdocstrings = { extras = ["python"], version = ">=0.20,<0.26" }
|
||||
mkdocstrings = { extras = ["python"], version = "^0.25.2" }
|
||||
mike = "^2.0.0"
|
||||
# For Documentation Development use Python 3.10 or above
|
||||
# Use Latest mkdocs-jupyter min 0.24.6 for Jupyter Notebook Theme support
|
||||
@@ -87,9 +93,15 @@ mkdocs-jupyter = "^0.24.3"
|
||||
mkdocs-git-committers-plugin-2 = "^2.2.3"
|
||||
mkdocs-git-revision-date-localized-plugin = "^1.2.4"
|
||||
|
||||
[tool.isort]
|
||||
line_length = 88
|
||||
profile = "black"
|
||||
[tool.poetry.group.typecheck]
|
||||
optional = true
|
||||
|
||||
[tool.poetry.group.typecheck.dependencies]
|
||||
types-pyyaml = "^6.0.12.20240808"
|
||||
types-cffi = "^1.16.0.20240331"
|
||||
types-requests = "^2.32.0.20240712"
|
||||
types-tqdm = "^4.66.0.20240417"
|
||||
|
||||
|
||||
[tool.bandit]
|
||||
target = ["test", "supervision"]
|
||||
@@ -154,7 +166,7 @@ indent-width = 4
|
||||
|
||||
[tool.ruff.lint]
|
||||
# Enable pycodestyle (`E`) and Pyflakes (`F`) codes by default.
|
||||
select = ["E", "F"]
|
||||
select = ["E", "F", "I", "A", "Q", "W"]
|
||||
ignore = []
|
||||
# Allow autofix for all enabled rules (when `--fix`) is provided.
|
||||
fixable = [
|
||||
@@ -223,6 +235,10 @@ convention = "google"
|
||||
# Flag errors (`C901`) whenever the complexity level exceeds 5.
|
||||
max-complexity = 20
|
||||
|
||||
[tool.ruff.lint.isort]
|
||||
order-by-type = true
|
||||
no-sections = false
|
||||
|
||||
[tool.ruff.format]
|
||||
# Like Black, use double quotes for strings.
|
||||
quote-style = "double"
|
||||
|
||||
+6
-1
@@ -9,10 +9,15 @@ It assumes you already have the code changes, as well as a draft of the release
|
||||
- A commit that updates the project version in `pyproject.toml`.
|
||||
- All changes made during the release.
|
||||
3. Tag the commit with the new supervision version.
|
||||
- make sure to pull from `main` !
|
||||
- Verify that the latest merge commits exists. `git log`.
|
||||
- Run `git tag x.y.z`, with your version
|
||||
- Check with `git log`.
|
||||
- Run `git push origin --tags`
|
||||
- Upon pushing the tag, the [PyPi](https://pypi.org/project/supervision/) should update to the new version. Check this!
|
||||
4. Open and merge a PR, merging `main` into `develop`.
|
||||
5. Update the docs by running the [Supervision Release Documentation Workflow 📚](https://github.com/roboflow/supervision/actions/workflows/publish-release-docs.yml) workflow from GitHub.
|
||||
- Select the `main` branch from the dropdown.
|
||||
- Select the `main` branch from the dropdown.
|
||||
6. Create a release on GitHub.
|
||||
- Go to releases
|
||||
- Assign the release notes to the tag created in step 3.
|
||||
|
||||
@@ -7,6 +7,7 @@ except importlib_metadata.PackageNotFoundError:
|
||||
__version__ = "development"
|
||||
|
||||
from supervision.annotators.core import (
|
||||
BackgroundOverlayAnnotator,
|
||||
BlurAnnotator,
|
||||
BoundingBoxAnnotator,
|
||||
BoxAnnotator,
|
||||
@@ -18,6 +19,7 @@ from supervision.annotators.core import (
|
||||
EllipseAnnotator,
|
||||
HaloAnnotator,
|
||||
HeatMapAnnotator,
|
||||
IconAnnotator,
|
||||
LabelAnnotator,
|
||||
MaskAnnotator,
|
||||
OrientedBoxAnnotator,
|
||||
|
||||
+341
-55
@@ -1,9 +1,11 @@
|
||||
from functools import lru_cache
|
||||
from math import sqrt
|
||||
from typing import List, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from PIL import ImageDraw, ImageFont
|
||||
import numpy.typing as npt
|
||||
from PIL import Image, ImageDraw, ImageFont
|
||||
|
||||
from supervision.annotators.base import BaseAnnotator, ImageType
|
||||
from supervision.annotators.utils import (
|
||||
@@ -22,7 +24,12 @@ from supervision.utils.conversion import (
|
||||
ensure_cv2_image_for_annotation,
|
||||
ensure_pil_image_for_annotation,
|
||||
)
|
||||
from supervision.utils.image import crop_image, overlay_image, scale_image
|
||||
from supervision.utils.image import (
|
||||
crop_image,
|
||||
letterbox_image,
|
||||
overlay_image,
|
||||
scale_image,
|
||||
)
|
||||
from supervision.utils.internal import deprecated
|
||||
|
||||
|
||||
@@ -42,7 +49,7 @@ class BoxAnnotator(BaseAnnotator):
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the bounding box lines.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -87,6 +94,7 @@ class BoxAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
for detection_idx in range(len(detections)):
|
||||
x1, y1, x2, y2 = detections.xyxy[detection_idx].astype(int)
|
||||
color = resolve_color(
|
||||
@@ -127,7 +135,7 @@ class BoundingBoxAnnotator(BaseAnnotator):
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the bounding box lines.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -172,6 +180,7 @@ class BoundingBoxAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
for detection_idx in range(len(detections)):
|
||||
x1, y1, x2, y2 = detections.xyxy[detection_idx].astype(int)
|
||||
color = resolve_color(
|
||||
@@ -208,7 +217,7 @@ class OrientedBoxAnnotator(BaseAnnotator):
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the bounding box lines.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -256,12 +265,13 @@ class OrientedBoxAnnotator(BaseAnnotator):
|
||||
)
|
||||
```
|
||||
""" # noqa E501 // docs
|
||||
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if detections.data is None or ORIENTED_BOX_COORDINATES not in detections.data:
|
||||
return scene
|
||||
obb_boxes = np.array(detections.data[ORIENTED_BOX_COORDINATES]).astype(int)
|
||||
|
||||
for detection_idx in range(len(detections)):
|
||||
bbox = np.intp(detections.data.get(ORIENTED_BOX_COORDINATES)[detection_idx])
|
||||
obb = obb_boxes[detection_idx]
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
@@ -271,7 +281,7 @@ class OrientedBoxAnnotator(BaseAnnotator):
|
||||
else custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.drawContours(scene, [bbox], 0, color.as_bgr(), self.thickness)
|
||||
cv2.drawContours(scene, [obb], 0, color.as_bgr(), self.thickness)
|
||||
|
||||
return scene
|
||||
|
||||
@@ -296,7 +306,7 @@ class MaskAnnotator(BaseAnnotator):
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
opacity (float): Opacity of the overlay mask. Must be between `0` and `1`.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -342,6 +352,7 @@ class MaskAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if detections.mask is None:
|
||||
return scene
|
||||
|
||||
@@ -385,7 +396,7 @@ class PolygonAnnotator(BaseAnnotator):
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the polygon lines.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -431,6 +442,7 @@ class PolygonAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if detections.mask is None:
|
||||
return scene
|
||||
|
||||
@@ -471,7 +483,7 @@ class ColorAnnotator(BaseAnnotator):
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
opacity (float): Opacity of the overlay mask. Must be between `0` and `1`.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -517,6 +529,7 @@ class ColorAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
scene_with_boxes = scene.copy()
|
||||
for detection_idx in range(len(detections)):
|
||||
x1, y1, x2, y2 = detections.xyxy[detection_idx].astype(int)
|
||||
@@ -565,7 +578,7 @@ class HaloAnnotator(BaseAnnotator):
|
||||
opacity (float): Opacity of the overlay mask. Must be between `0` and `1`.
|
||||
kernel_size (int): The size of the average pooling kernel used for creating
|
||||
the halo.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -612,6 +625,7 @@ class HaloAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if detections.mask is None:
|
||||
return scene
|
||||
colored_mask = np.zeros_like(scene, dtype=np.uint8)
|
||||
@@ -663,7 +677,7 @@ class EllipseAnnotator(BaseAnnotator):
|
||||
thickness (int): Thickness of the ellipse lines.
|
||||
start_angle (int): Starting angle of the ellipse.
|
||||
end_angle (int): Ending angle of the ellipse.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -711,6 +725,7 @@ class EllipseAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
for detection_idx in range(len(detections)):
|
||||
x1, y1, x2, y2 = detections.xyxy[detection_idx].astype(int)
|
||||
color = resolve_color(
|
||||
@@ -755,7 +770,7 @@ class BoxCornerAnnotator(BaseAnnotator):
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the corner lines.
|
||||
corner_length (int): Length of each corner line.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -802,6 +817,7 @@ class BoxCornerAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
for detection_idx in range(len(detections)):
|
||||
x1, y1, x2, y2 = detections.xyxy[detection_idx].astype(int)
|
||||
color = resolve_color(
|
||||
@@ -843,7 +859,7 @@ class CircleAnnotator(BaseAnnotator):
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the circle line.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
|
||||
@@ -891,6 +907,7 @@ class CircleAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
for detection_idx in range(len(detections)):
|
||||
x1, y1, x2, y2 = detections.xyxy[detection_idx].astype(int)
|
||||
center = ((x1 + x2) // 2, (y1 + y2) // 2)
|
||||
@@ -927,6 +944,7 @@ class DotAnnotator(BaseAnnotator):
|
||||
position: Position = Position.CENTER,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
outline_thickness: int = 0,
|
||||
outline_color: Union[Color, ColorPalette] = Color.BLACK,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
@@ -937,12 +955,16 @@ class DotAnnotator(BaseAnnotator):
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
outline_thickness (int): Thickness of the outline of the dot.
|
||||
outline_color (Union[Color, ColorPalette]): The color or color palette to
|
||||
use for outline. It is activated by setting outline_thickness to a value
|
||||
greater than 0.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.radius: int = radius
|
||||
self.position: Position = position
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
self.outline_thickness = outline_thickness
|
||||
self.outline_color: Union[Color, ColorPalette] = outline_color
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
def annotate(
|
||||
@@ -983,6 +1005,7 @@ class DotAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
xy = detections.get_anchors_coordinates(anchor=self.position)
|
||||
for detection_idx in range(len(detections)):
|
||||
color = resolve_color(
|
||||
@@ -997,8 +1020,20 @@ class DotAnnotator(BaseAnnotator):
|
||||
|
||||
cv2.circle(scene, center, self.radius, color.as_bgr(), -1)
|
||||
if self.outline_thickness:
|
||||
outline_color = resolve_color(
|
||||
color=self.outline_color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
cv2.circle(
|
||||
scene, center, self.radius, (0, 0, 0), self.outline_thickness
|
||||
scene,
|
||||
center,
|
||||
self.radius,
|
||||
outline_color.as_bgr(),
|
||||
self.outline_thickness,
|
||||
)
|
||||
return scene
|
||||
|
||||
@@ -1011,7 +1046,7 @@ class LabelAnnotator(BaseAnnotator):
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
text_color: Color = Color.WHITE,
|
||||
text_color: Union[Color, ColorPalette] = Color.WHITE,
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
@@ -1023,20 +1058,21 @@ class LabelAnnotator(BaseAnnotator):
|
||||
Args:
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating the text background.
|
||||
text_color (Color): The color to use for the text.
|
||||
text_color (Union[Color, ColorPalette]): The color or color palette to use
|
||||
for the text.
|
||||
text_scale (float): Font scale for the text.
|
||||
text_thickness (int): Thickness of the text characters.
|
||||
text_padding (int): Padding around the text within its background box.
|
||||
text_position (Position): Position of the text relative to the detection.
|
||||
Possible values are defined in the `Position` enum.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
border_radius (int): The radius to apply round edges. If the selected
|
||||
value is higher than the lower dimension, width or height, is clipped.
|
||||
"""
|
||||
self.border_radius: int = border_radius
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.text_color: Color = text_color
|
||||
self.text_color: Union[Color, ColorPalette] = text_color
|
||||
self.text_scale: float = text_scale
|
||||
self.text_thickness: int = text_thickness
|
||||
self.text_padding: int = text_padding
|
||||
@@ -1091,6 +1127,7 @@ class LabelAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
font = cv2.FONT_HERSHEY_SIMPLEX
|
||||
anchors_coordinates = detections.get_anchors_coordinates(
|
||||
anchor=self.text_anchor
|
||||
@@ -1114,10 +1151,21 @@ class LabelAnnotator(BaseAnnotator):
|
||||
),
|
||||
)
|
||||
|
||||
text_color = resolve_color(
|
||||
color=self.text_color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=(
|
||||
self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup
|
||||
),
|
||||
)
|
||||
|
||||
if labels is not None:
|
||||
text = labels[detection_idx]
|
||||
elif detections[CLASS_NAME_DATA_FIELD] is not None:
|
||||
text = detections[CLASS_NAME_DATA_FIELD][detection_idx]
|
||||
elif CLASS_NAME_DATA_FIELD in detections.data:
|
||||
text = detections.data[CLASS_NAME_DATA_FIELD][detection_idx]
|
||||
elif detections.class_id is not None:
|
||||
text = str(detections.class_id[detection_idx])
|
||||
else:
|
||||
@@ -1152,7 +1200,7 @@ class LabelAnnotator(BaseAnnotator):
|
||||
org=(text_x, text_y),
|
||||
fontFace=font,
|
||||
fontScale=self.text_scale,
|
||||
color=self.text_color.as_rgb(),
|
||||
color=text_color.as_bgr(),
|
||||
thickness=self.text_thickness,
|
||||
lineType=cv2.LINE_AA,
|
||||
)
|
||||
@@ -1210,7 +1258,7 @@ class RichLabelAnnotator(BaseAnnotator):
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
text_color: Color = Color.WHITE,
|
||||
text_color: Union[Color, ColorPalette] = Color.WHITE,
|
||||
font_path: Optional[str] = None,
|
||||
font_size: int = 10,
|
||||
text_padding: int = 10,
|
||||
@@ -1222,7 +1270,7 @@ class RichLabelAnnotator(BaseAnnotator):
|
||||
Args:
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating the text background.
|
||||
text_color (Color): The color to use for the text.
|
||||
text_color (Union[Color, ColorPalette]): The color to use for the text.
|
||||
font_path (Optional[str]): Path to the font file (e.g., ".ttf" or ".otf")
|
||||
to use for rendering text. If `None`, the default PIL font will be used.
|
||||
font_size (int): Font size for the text.
|
||||
@@ -1296,6 +1344,7 @@ class RichLabelAnnotator(BaseAnnotator):
|
||||
```
|
||||
|
||||
"""
|
||||
assert isinstance(scene, Image.Image)
|
||||
draw = ImageDraw.Draw(scene)
|
||||
anchors_coordinates = detections.get_anchors_coordinates(
|
||||
anchor=self.text_anchor
|
||||
@@ -1317,10 +1366,22 @@ class RichLabelAnnotator(BaseAnnotator):
|
||||
else custom_color_lookup
|
||||
),
|
||||
)
|
||||
|
||||
text_color = resolve_color(
|
||||
color=self.text_color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=(
|
||||
self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup
|
||||
),
|
||||
)
|
||||
|
||||
if labels is not None:
|
||||
text = labels[detection_idx]
|
||||
elif detections[CLASS_NAME_DATA_FIELD] is not None:
|
||||
text = detections[CLASS_NAME_DATA_FIELD][detection_idx]
|
||||
elif CLASS_NAME_DATA_FIELD in detections.data:
|
||||
text = detections.data[CLASS_NAME_DATA_FIELD][detection_idx]
|
||||
elif detections.class_id is not None:
|
||||
text = str(detections.class_id[detection_idx])
|
||||
else:
|
||||
@@ -1350,7 +1411,7 @@ class RichLabelAnnotator(BaseAnnotator):
|
||||
xy=(text_x, text_y),
|
||||
text=text,
|
||||
font=self.font,
|
||||
fill=self.text_color.as_rgb(),
|
||||
fill=text_color.as_rgb(),
|
||||
)
|
||||
return scene
|
||||
|
||||
@@ -1368,6 +1429,106 @@ class RichLabelAnnotator(BaseAnnotator):
|
||||
return font
|
||||
|
||||
|
||||
class IconAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing an icon on an image, using provided detections.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
icon_resolution_wh: Tuple[int, int] = (64, 64),
|
||||
icon_position: Position = Position.TOP_CENTER,
|
||||
offset_xy: Tuple[int, int] = (0, 0),
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
icon_resolution_wh (Tuple[int, int]): The size of drawn icons.
|
||||
All icons will be resized to this resolution, keeping the aspect ratio.
|
||||
icon_position (Position): The position of the icon.
|
||||
offset_xy (Tuple[int, int]): The offset to apply to the icon position,
|
||||
in pixels. Can be both positive and negative.
|
||||
"""
|
||||
self.icon_resolution_wh = icon_resolution_wh
|
||||
self.position = icon_position
|
||||
self.offset_xy = offset_xy
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
def annotate(
|
||||
self, scene: ImageType, detections: Detections, icon_path: Union[str, List[str]]
|
||||
) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene with given icons.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where labels will be drawn.
|
||||
`ImageType` is a flexible type, accepting either `numpy.ndarray`
|
||||
or `PIL.Image.Image`.
|
||||
detections (Detections): Object detections to annotate.
|
||||
icon_path (Union[str, List[str]]): The path to the PNG image to use as an
|
||||
icon. Must be a single path or a list of paths, one for each detection.
|
||||
Pass an empty string `""` to draw nothing.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
available_icons = ["roboflow.png", "lenny.png"]
|
||||
icon_paths = [np.random.choice(available_icons) for _ in detections]
|
||||
|
||||
icon_annotator = sv.IconAnnotator()
|
||||
annotated_frame = icon_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
icon_path=icon_paths
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if isinstance(icon_path, list) and len(icon_path) != len(detections):
|
||||
raise ValueError(
|
||||
f"The number of icon paths provided ({len(icon_path)}) does not match "
|
||||
f"the number of detections ({len(detections)}). Either provide a single"
|
||||
f" icon path or one for each detection."
|
||||
)
|
||||
|
||||
xy = detections.get_anchors_coordinates(anchor=self.position).astype(int)
|
||||
|
||||
for detection_idx in range(len(detections)):
|
||||
current_path = (
|
||||
icon_path if isinstance(icon_path, str) else icon_path[detection_idx]
|
||||
)
|
||||
if current_path == "":
|
||||
continue
|
||||
icon = self._load_icon(current_path)
|
||||
icon_h, icon_w = icon.shape[:2]
|
||||
|
||||
x = int(xy[detection_idx, 0] - icon_w / 2 + self.offset_xy[0])
|
||||
y = int(xy[detection_idx, 1] - icon_h / 2 + self.offset_xy[1])
|
||||
|
||||
scene[:] = overlay_image(scene, icon, (x, y))
|
||||
return scene
|
||||
|
||||
@lru_cache
|
||||
def _load_icon(self, icon_path: str) -> np.ndarray:
|
||||
icon = cv2.imread(icon_path, cv2.IMREAD_UNCHANGED)
|
||||
if icon is None:
|
||||
raise FileNotFoundError(
|
||||
f"Error: Couldn't load the icon image from {icon_path}"
|
||||
)
|
||||
icon = letterbox_image(image=icon, resolution_wh=self.icon_resolution_wh)
|
||||
return icon
|
||||
|
||||
|
||||
class BlurAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for blurring regions in an image using provided detections.
|
||||
@@ -1416,6 +1577,7 @@ class BlurAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
image_height, image_width = scene.shape[:2]
|
||||
clipped_xyxy = clip_boxes(
|
||||
xyxy=detections.xyxy, resolution_wh=(image_width, image_height)
|
||||
@@ -1457,7 +1619,7 @@ class TraceAnnotator(BaseAnnotator):
|
||||
trace_length (int): The maximum length of the trace in terms of historical
|
||||
points. Defaults to `30`.
|
||||
thickness (int): The thickness of the trace lines. Defaults to `2`.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
@@ -1514,8 +1676,14 @@ class TraceAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
self.trace.put(detections)
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if detections.tracker_id is None:
|
||||
raise ValueError(
|
||||
"The `tracker_id` field is missing in the provided detections."
|
||||
" See more: https://supervision.roboflow.com/latest/how_to/track_objects"
|
||||
)
|
||||
|
||||
self.trace.put(detections)
|
||||
for detection_idx in range(len(detections)):
|
||||
tracker_id = int(detections.tracker_id[detection_idx])
|
||||
color = resolve_color(
|
||||
@@ -1568,9 +1736,9 @@ class HeatMapAnnotator(BaseAnnotator):
|
||||
self.opacity = opacity
|
||||
self.radius = radius
|
||||
self.kernel_size = kernel_size
|
||||
self.heat_mask = None
|
||||
self.top_hue = top_hue
|
||||
self.low_hue = low_hue
|
||||
self.heat_mask: Optional[npt.NDArray[np.float32]] = None
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
def annotate(self, scene: ImageType, detections: Detections) -> ImageType:
|
||||
@@ -1597,7 +1765,7 @@ class HeatMapAnnotator(BaseAnnotator):
|
||||
heat_map_annotator = sv.HeatMapAnnotator()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
frames_generator = get_video_frames_generator(source_path='...')
|
||||
frames_generator = sv.get_video_frames_generator(source_path='...')
|
||||
|
||||
with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
@@ -1612,12 +1780,20 @@ class HeatMapAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if self.heat_mask is None:
|
||||
self.heat_mask = np.zeros(scene.shape[:2])
|
||||
self.heat_mask = np.zeros(scene.shape[:2], dtype=np.float32)
|
||||
|
||||
mask = np.zeros(scene.shape[:2])
|
||||
for xy in detections.get_anchors_coordinates(self.position):
|
||||
cv2.circle(mask, (int(xy[0]), int(xy[1])), self.radius, 1, -1)
|
||||
x, y = int(xy[0]), int(xy[1])
|
||||
cv2.circle(
|
||||
img=mask,
|
||||
center=(x, y),
|
||||
radius=self.radius,
|
||||
color=(1,),
|
||||
thickness=-1, # fill
|
||||
)
|
||||
self.heat_mask = mask + self.heat_mask
|
||||
temp = self.heat_mask.copy()
|
||||
temp = self.low_hue - temp / temp.max() * (self.low_hue - self.top_hue)
|
||||
@@ -1685,6 +1861,7 @@ class PixelateAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
image_height, image_width = scene.shape[:2]
|
||||
clipped_xyxy = clip_boxes(
|
||||
xyxy=detections.xyxy, resolution_wh=(image_width, image_height)
|
||||
@@ -1720,6 +1897,7 @@ class TriangleAnnotator(BaseAnnotator):
|
||||
position: Position = Position.TOP_CENTER,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
outline_thickness: int = 0,
|
||||
outline_color: Union[Color, ColorPalette] = Color.BLACK,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
@@ -1731,6 +1909,9 @@ class TriangleAnnotator(BaseAnnotator):
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
outline_thickness (int): Thickness of the outline of the triangle.
|
||||
outline_color (Union[Color, ColorPalette]): The color or color palette to
|
||||
use for outline. It is activated by setting outline_thickness to a value
|
||||
greater than 0.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.base: int = base
|
||||
@@ -1738,6 +1919,7 @@ class TriangleAnnotator(BaseAnnotator):
|
||||
self.position: Position = position
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
self.outline_thickness: int = outline_thickness
|
||||
self.outline_color: Union[Color, ColorPalette] = outline_color
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
def annotate(
|
||||
@@ -1778,6 +1960,7 @@ class TriangleAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
xy = detections.get_anchors_coordinates(anchor=self.position)
|
||||
for detection_idx in range(len(detections)):
|
||||
color = resolve_color(
|
||||
@@ -1800,8 +1983,20 @@ class TriangleAnnotator(BaseAnnotator):
|
||||
|
||||
cv2.fillPoly(scene, [vertices], color.as_bgr())
|
||||
if self.outline_thickness:
|
||||
outline_color = resolve_color(
|
||||
color=self.outline_color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
cv2.polylines(
|
||||
scene, [vertices], True, (0, 0, 0), thickness=self.outline_thickness
|
||||
scene,
|
||||
[vertices],
|
||||
True,
|
||||
outline_color.as_bgr(),
|
||||
thickness=self.outline_thickness,
|
||||
)
|
||||
return scene
|
||||
|
||||
@@ -1824,7 +2019,7 @@ class RoundBoxAnnotator(BaseAnnotator):
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the bounding box lines.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
roundness (float): Percent of roundness for edges of bounding box.
|
||||
Value must be float 0 < roundness <= 1.0
|
||||
@@ -1878,7 +2073,7 @@ class RoundBoxAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
|
||||
assert isinstance(scene, np.ndarray)
|
||||
for detection_idx in range(len(detections)):
|
||||
x1, y1, x2, y2 = detections.xyxy[detection_idx].astype(int)
|
||||
color = resolve_color(
|
||||
@@ -1951,7 +2146,7 @@ class PercentageBarAnnotator(BaseAnnotator):
|
||||
border_color: Color = Color.BLACK,
|
||||
position: Position = Position.TOP_CENTER,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
border_thickness: int = None,
|
||||
border_thickness: Optional[int] = None,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
@@ -1961,9 +2156,9 @@ class PercentageBarAnnotator(BaseAnnotator):
|
||||
annotating detections.
|
||||
border_color (Color): The color of the border lines.
|
||||
position (Position): The anchor position of drawing the percentage bar.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
border_thickness (int): The thickness of the border lines.
|
||||
border_thickness (Optional[int]): The thickness of the border lines.
|
||||
"""
|
||||
self.height: int = height
|
||||
self.width: int = width
|
||||
@@ -2022,9 +2217,9 @@ class PercentageBarAnnotator(BaseAnnotator):
|
||||

|
||||
"""
|
||||
self.validate_custom_values(
|
||||
custom_values=custom_values, detections_count=len(detections)
|
||||
)
|
||||
assert isinstance(scene, np.ndarray)
|
||||
self.validate_custom_values(custom_values=custom_values, detections=detections)
|
||||
|
||||
anchors = detections.get_anchors_coordinates(anchor=self.position)
|
||||
for detection_idx in range(len(detections)):
|
||||
anchor = anchors[detection_idx]
|
||||
@@ -2035,11 +2230,11 @@ class PercentageBarAnnotator(BaseAnnotator):
|
||||
)
|
||||
border_width = border_coordinates[1][0] - border_coordinates[0][0]
|
||||
|
||||
value = (
|
||||
custom_values[detection_idx]
|
||||
if custom_values is not None
|
||||
else detections.confidence[detection_idx]
|
||||
)
|
||||
if custom_values is not None:
|
||||
value = custom_values[detection_idx]
|
||||
else:
|
||||
assert detections.confidence is not None # MyPy type hint
|
||||
value = detections.confidence[detection_idx]
|
||||
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
@@ -2099,15 +2294,23 @@ class PercentageBarAnnotator(BaseAnnotator):
|
||||
|
||||
@staticmethod
|
||||
def validate_custom_values(
|
||||
custom_values: Optional[Union[np.ndarray, List[float]]], detections_count: int
|
||||
custom_values: Optional[Union[np.ndarray, List[float]]], detections: Detections
|
||||
) -> None:
|
||||
if custom_values is not None:
|
||||
if custom_values is None:
|
||||
if detections.confidence is None:
|
||||
raise ValueError(
|
||||
"The provided detections do not contain confidence values. "
|
||||
"Please provide `custom_values` or ensure that the detections "
|
||||
"contain confidence values (e.g. by using a different model)."
|
||||
)
|
||||
|
||||
else:
|
||||
if not isinstance(custom_values, (np.ndarray, list)):
|
||||
raise TypeError(
|
||||
"custom_values must be either a numpy array or a list of floats."
|
||||
)
|
||||
|
||||
if len(custom_values) != detections_count:
|
||||
if len(custom_values) != len(detections):
|
||||
raise ValueError(
|
||||
"The length of custom_values must match the number of detections."
|
||||
)
|
||||
@@ -2124,7 +2327,7 @@ class CropAnnotator(BaseAnnotator):
|
||||
def __init__(
|
||||
self,
|
||||
position: Position = Position.TOP_CENTER,
|
||||
scale_factor: int = 2,
|
||||
scale_factor: float = 2.0,
|
||||
border_color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
border_thickness: int = 2,
|
||||
border_color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
@@ -2133,7 +2336,7 @@ class CropAnnotator(BaseAnnotator):
|
||||
Args:
|
||||
position (Position): The anchor position for placing the cropped and scaled
|
||||
part of the detection in the scene.
|
||||
scale_factor (int): The factor by which to scale the cropped image part. A
|
||||
scale_factor (float): The factor by which to scale the cropped image part. A
|
||||
factor of 2, for example, would double the size of the cropped area,
|
||||
allowing for a closer view of the detection.
|
||||
border_color (Union[Color, ColorPalette]): The color or color palette to
|
||||
@@ -2143,7 +2346,7 @@ class CropAnnotator(BaseAnnotator):
|
||||
annotations. Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.position: Position = position
|
||||
self.scale_factor: int = scale_factor
|
||||
self.scale_factor: float = scale_factor
|
||||
self.border_color: Union[Color, ColorPalette] = border_color
|
||||
self.border_thickness: int = border_thickness
|
||||
self.border_color_lookup: ColorLookup = border_color_lookup
|
||||
@@ -2187,6 +2390,7 @@ class CropAnnotator(BaseAnnotator):
|
||||
)
|
||||
```
|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
crops = [
|
||||
crop_image(image=scene, xyxy=xyxy) for xyxy in detections.xyxy.astype(int)
|
||||
]
|
||||
@@ -2259,3 +2463,85 @@ class CropAnnotator(BaseAnnotator):
|
||||
)
|
||||
elif position == Position.BOTTOM_RIGHT:
|
||||
return (anchor_x, anchor_y), (anchor_x + width, anchor_y + height)
|
||||
|
||||
|
||||
class BackgroundOverlayAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing a colored overlay on the background of an image outside
|
||||
the region of detections.
|
||||
|
||||
If masks are provided, the background is colored outside the masks.
|
||||
If masks are not provided, the background is colored outside the bounding boxes.
|
||||
|
||||
You can use the `force_box` parameter to force the annotator to use bounding boxes.
|
||||
|
||||
!!! warning
|
||||
|
||||
This annotator uses `sv.Detections.mask`.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Color = Color.BLACK,
|
||||
opacity: float = 0.5,
|
||||
force_box: bool = False,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
color (Color): The color to use for annotating detections.
|
||||
opacity (float): Opacity of the overlay mask. Must be between `0` and `1`.
|
||||
force_box (bool): If `True`, forces the annotator to use bounding boxes when
|
||||
masks are provided in the supplied sv.Detections.
|
||||
"""
|
||||
self.color: Color = color
|
||||
self.opacity = opacity
|
||||
self.force_box = force_box
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
def annotate(self, scene: ImageType, detections: Detections) -> ImageType:
|
||||
"""
|
||||
Applies a colored overlay to the scene outside of the detected regions.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where masks will be drawn.
|
||||
`ImageType` is a flexible type, accepting either `numpy.ndarray`
|
||||
or `PIL.Image.Image`.
|
||||
detections (Detections): Object detections to annotate.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
background_overlay_annotator = sv.BackgroundOverlayAnnotator()
|
||||
annotated_frame = background_overlay_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
colored_mask = np.full_like(scene, self.color.as_bgr(), dtype=np.uint8)
|
||||
|
||||
cv2.addWeighted(
|
||||
scene, 1 - self.opacity, colored_mask, self.opacity, 0, dst=colored_mask
|
||||
)
|
||||
|
||||
if detections.mask is None or self.force_box:
|
||||
for x1, y1, x2, y2 in detections.xyxy.astype(int):
|
||||
colored_mask[y1:y2, x1:x2] = scene[y1:y2, x1:x2]
|
||||
else:
|
||||
for mask in detections.mask:
|
||||
colored_mask[mask] = scene[mask]
|
||||
|
||||
np.copyto(scene, colored_mask)
|
||||
return scene
|
||||
|
||||
+22
-13
@@ -43,7 +43,10 @@ class BaseDataset(ABC):
|
||||
|
||||
@abstractmethod
|
||||
def split(
|
||||
self, split_ratio=0.8, random_state=None, shuffle: bool = True
|
||||
self,
|
||||
split_ratio: float = 0.8,
|
||||
random_state: Optional[int] = None,
|
||||
shuffle: bool = True,
|
||||
) -> Tuple[BaseDataset, BaseDataset]:
|
||||
pass
|
||||
|
||||
@@ -174,18 +177,21 @@ class DetectionDataset(BaseDataset):
|
||||
return True
|
||||
|
||||
def split(
|
||||
self, split_ratio=0.8, random_state=None, shuffle: bool = True
|
||||
self,
|
||||
split_ratio: float = 0.8,
|
||||
random_state: Optional[int] = None,
|
||||
shuffle: bool = True,
|
||||
) -> Tuple[DetectionDataset, DetectionDataset]:
|
||||
"""
|
||||
Splits the dataset into two parts (training and testing)
|
||||
using the provided split_ratio.
|
||||
|
||||
Args:
|
||||
split_ratio (float, optional): The ratio of the training
|
||||
split_ratio (float): The ratio of the training
|
||||
set to the entire dataset.
|
||||
random_state (int, optional): The seed for the random number generator.
|
||||
random_state (Optional[int]): The seed for the random number generator.
|
||||
This is used for reproducibility.
|
||||
shuffle (bool, optional): Whether to shuffle the data before splitting.
|
||||
shuffle (bool): Whether to shuffle the data before splitting.
|
||||
|
||||
Returns:
|
||||
Tuple[DetectionDataset, DetectionDataset]: A tuple containing
|
||||
@@ -396,7 +402,7 @@ class DetectionDataset(BaseDataset):
|
||||
images_directory_path (str): Path to the directory containing the images.
|
||||
annotations_directory_path (str): Path to the directory
|
||||
containing the PASCAL VOC XML annotations.
|
||||
force_masks (bool, optional): If True, forces masks to
|
||||
force_masks (bool): If True, forces masks to
|
||||
be loaded for all annotations, regardless of whether they are present.
|
||||
|
||||
Returns:
|
||||
@@ -455,10 +461,10 @@ class DetectionDataset(BaseDataset):
|
||||
containing the YOLO annotation files.
|
||||
data_yaml_path (str): The path to the data
|
||||
YAML file containing class information.
|
||||
force_masks (bool, optional): If True, forces
|
||||
force_masks (bool): If True, forces
|
||||
masks to be loaded for all annotations,
|
||||
regardless of whether they are present.
|
||||
is_obb (bool, optional): If True, loads the annotations in OBB format.
|
||||
is_obb (bool): If True, loads the annotations in OBB format.
|
||||
OBB annotations are defined as `[class_id, x, y, x, y, x, y, x, y]`,
|
||||
where pairs of [x, y] are box corners.
|
||||
|
||||
@@ -565,7 +571,7 @@ class DetectionDataset(BaseDataset):
|
||||
images_directory_path (str): The path to the
|
||||
directory containing the images.
|
||||
annotations_path (str): The path to the json annotation files.
|
||||
force_masks (bool, optional): If True,
|
||||
force_masks (bool): If True,
|
||||
forces masks to be loaded for all annotations,
|
||||
regardless of whether they are present.
|
||||
|
||||
@@ -777,18 +783,21 @@ class ClassificationDataset(BaseDataset):
|
||||
return True
|
||||
|
||||
def split(
|
||||
self, split_ratio=0.8, random_state=None, shuffle: bool = True
|
||||
self,
|
||||
split_ratio: float = 0.8,
|
||||
random_state: Optional[int] = None,
|
||||
shuffle: bool = True,
|
||||
) -> Tuple[ClassificationDataset, ClassificationDataset]:
|
||||
"""
|
||||
Splits the dataset into two parts (training and testing)
|
||||
using the provided split_ratio.
|
||||
|
||||
Args:
|
||||
split_ratio (float, optional): The ratio of the training
|
||||
split_ratio (float): The ratio of the training
|
||||
set to the entire dataset.
|
||||
random_state (int, optional): The seed for the
|
||||
random_state (Optional[int]): The seed for the
|
||||
random number generator. This is used for reproducibility.
|
||||
shuffle (bool, optional): Whether to shuffle the data before splitting.
|
||||
shuffle (bool): Whether to shuffle the data before splitting.
|
||||
|
||||
Returns:
|
||||
Tuple[ClassificationDataset, ClassificationDataset]: A tuple containing
|
||||
|
||||
@@ -147,7 +147,7 @@ def load_pascal_voc_annotations(
|
||||
images_directory_path (str): The path to the directory containing the images.
|
||||
annotations_directory_path (str): The path to the directory containing the
|
||||
PASCAL VOC annotation files.
|
||||
force_masks (bool, optional): If True, forces masks to be loaded for all
|
||||
force_masks (bool): If True, forces masks to be loaded for all
|
||||
annotations, regardless of whether they are present.
|
||||
|
||||
Returns:
|
||||
|
||||
@@ -138,9 +138,9 @@ def load_yolo_annotations(
|
||||
containing the YOLO annotation files.
|
||||
data_yaml_path (str): The path to the data
|
||||
YAML file containing class information.
|
||||
force_masks (bool, optional): If True, forces masks to be loaded
|
||||
force_masks (bool): If True, forces masks to be loaded
|
||||
for all annotations, regardless of whether they are present.
|
||||
is_obb (bool, optional): If True, loads the annotations in OBB format.
|
||||
is_obb (bool): If True, loads the annotations in OBB format.
|
||||
OBB annotations are defined as `[class_id, x, y, x, y, x, y, x, y]`,
|
||||
where pairs of [x, y] are box corners.
|
||||
|
||||
|
||||
@@ -18,6 +18,11 @@ from supervision.detection.overlap_filter import (
|
||||
box_non_max_suppression,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.tools.transformers import (
|
||||
process_transformers_detection_result,
|
||||
process_transformers_v4_segmentation_result,
|
||||
process_transformers_v5_segmentation_result,
|
||||
)
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
calculate_masks_centroids,
|
||||
@@ -244,10 +249,6 @@ class Detections:
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
if hasattr(ultralytics_results, "obb") and ultralytics_results.obb is not None:
|
||||
@@ -267,6 +268,14 @@ class Detections:
|
||||
},
|
||||
)
|
||||
|
||||
if hasattr(ultralytics_results, "boxes") and ultralytics_results.boxes is None:
|
||||
masks = extract_ultralytics_masks(ultralytics_results)
|
||||
return cls(
|
||||
xyxy=mask_to_xyxy(masks),
|
||||
mask=masks,
|
||||
class_id=np.arange(len(ultralytics_results)),
|
||||
)
|
||||
|
||||
class_id = ultralytics_results.boxes.cls.cpu().numpy().astype(int)
|
||||
class_names = np.array([ultralytics_results.names[i] for i in class_id])
|
||||
return cls(
|
||||
@@ -438,15 +447,19 @@ class Detections:
|
||||
cls, transformers_results: dict, id2label: Optional[Dict[int, str]] = None
|
||||
) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from object detection or segmentation
|
||||
Creates a Detections instance from object detection or panoptic, semantic
|
||||
and instance segmentation
|
||||
[Transformer](https://github.com/huggingface/transformers) inference result.
|
||||
|
||||
Args:
|
||||
transformers_results (dict): The output of Transformers model inference. A
|
||||
dictionary containing the `scores`, `labels`, `boxes` and `masks` keys.
|
||||
transformers_results (Union[dict, torch.Tensor]): Inference results from
|
||||
your Transformers model. This can be either a dictionary containing
|
||||
valuable outputs like `scores`, `labels`, `boxes`, `masks`,
|
||||
`segments_info`, and `segmentation`, or a `torch.Tensor` holding a
|
||||
segmentation map where values represent class IDs.
|
||||
id2label (Optional[Dict[int, str]]): A dictionary mapping class IDs to
|
||||
class names. If provided, the resulting Detections object will contain
|
||||
`class_name` data field with the class names.
|
||||
labels, typically part of the `transformers` model configuration. If
|
||||
provided, the resulting dictionary will include class names.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
@@ -477,36 +490,28 @@ class Detections:
|
||||
id2label=model.config.id2label
|
||||
)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
class_ids = transformers_results["labels"].cpu().detach().numpy().astype(int)
|
||||
data = {}
|
||||
if id2label is not None:
|
||||
class_names = np.array([id2label[class_id] for class_id in class_ids])
|
||||
data[CLASS_NAME_DATA_FIELD] = class_names
|
||||
if (
|
||||
transformers_results.__class__.__name__ == "Tensor"
|
||||
or "segmentation" in transformers_results
|
||||
):
|
||||
return cls(
|
||||
**process_transformers_v5_segmentation_result(
|
||||
transformers_results, id2label
|
||||
)
|
||||
)
|
||||
|
||||
if "masks" in transformers_results or "png_string" in transformers_results:
|
||||
return cls(
|
||||
**process_transformers_v4_segmentation_result(
|
||||
transformers_results, id2label
|
||||
)
|
||||
)
|
||||
|
||||
if "boxes" in transformers_results:
|
||||
return cls(
|
||||
xyxy=transformers_results["boxes"].cpu().detach().numpy(),
|
||||
confidence=transformers_results["scores"].cpu().detach().numpy(),
|
||||
class_id=class_ids,
|
||||
data=data,
|
||||
)
|
||||
elif "masks" in transformers_results:
|
||||
masks = transformers_results["masks"].cpu().detach().numpy().astype(bool)
|
||||
return cls(
|
||||
xyxy=mask_to_xyxy(masks),
|
||||
mask=masks,
|
||||
confidence=transformers_results["scores"].cpu().detach().numpy(),
|
||||
class_id=class_ids,
|
||||
data=data,
|
||||
)
|
||||
else:
|
||||
raise NotImplementedError(
|
||||
"Only object detection and semantic segmentation results are supported."
|
||||
**process_transformers_detection_result(transformers_results, id2label)
|
||||
)
|
||||
|
||||
@classmethod
|
||||
@@ -583,10 +588,6 @@ class Detections:
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
Class names values can be accessed using `detections["class_name"]`.
|
||||
"""
|
||||
with suppress(AttributeError):
|
||||
roboflow_result = roboflow_result.dict(exclude_none=True, by_alias=True)
|
||||
@@ -1157,10 +1158,10 @@ class Detections:
|
||||
from a segmentation model, the IoU mask is applied. Otherwise, box IoU is used.
|
||||
|
||||
Args:
|
||||
threshold (float, optional): The intersection-over-union threshold
|
||||
threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. I'm the lower the value the more
|
||||
restrictive the NMS becomes. Defaults to 0.5.
|
||||
class_agnostic (bool, optional): Whether to perform class-agnostic
|
||||
class_agnostic (bool): Whether to perform class-agnostic
|
||||
non-maximum suppression. If True, the class_id of each detection
|
||||
will be ignored. Defaults to False.
|
||||
|
||||
@@ -1212,9 +1213,9 @@ class Detections:
|
||||
Perform non-maximum merging on the current set of object detections.
|
||||
|
||||
Args:
|
||||
threshold (float, optional): The intersection-over-union threshold
|
||||
threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum merging. Defaults to 0.5.
|
||||
class_agnostic (bool, optional): Whether to perform class-agnostic
|
||||
class_agnostic (bool): Whether to perform class-agnostic
|
||||
non-maximum merging. If True, the class_id of each detection
|
||||
will be ignored. Defaults to False.
|
||||
|
||||
|
||||
@@ -1,3 +1,5 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from enum import Enum
|
||||
from typing import List, Union
|
||||
|
||||
@@ -53,9 +55,9 @@ def mask_non_max_suppression(
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
mask_dimension (int, optional): The dimension to which the masks should be
|
||||
mask_dimension (int): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
|
||||
Returns:
|
||||
@@ -101,7 +103,7 @@ def box_non_max_suppression(
|
||||
predictions (np.ndarray): An array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
|
||||
Returns:
|
||||
@@ -156,7 +158,7 @@ def group_overlapping_boxes(
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
and the confidence scores.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
|
||||
Returns:
|
||||
@@ -200,7 +202,7 @@ def box_non_max_merge(
|
||||
containing the bounding boxes coordinates in format `[x1, y1, x2, y2]`,
|
||||
the confidence scores and class_ids. Omit class_id column to allow
|
||||
detections of different classes to be merged.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
|
||||
Returns:
|
||||
@@ -248,16 +250,21 @@ class OverlapFilter(Enum):
|
||||
NON_MAX_SUPPRESSION = "non_max_suppression"
|
||||
NON_MAX_MERGE = "non_max_merge"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
return list(map(lambda c: c.value, cls))
|
||||
|
||||
def validate_overlap_filter(
|
||||
strategy: Union[OverlapFilter, str],
|
||||
) -> OverlapFilter:
|
||||
if isinstance(strategy, str):
|
||||
try:
|
||||
strategy = OverlapFilter(strategy.lower())
|
||||
except ValueError:
|
||||
raise ValueError(
|
||||
f"Invalid strategy value: {strategy}. Must be one of "
|
||||
f"{[e.value for e in OverlapFilter]}"
|
||||
)
|
||||
return strategy
|
||||
@classmethod
|
||||
def from_value(cls, value: Union[OverlapFilter, str]) -> OverlapFilter:
|
||||
if isinstance(value, cls):
|
||||
return value
|
||||
if isinstance(value, str):
|
||||
value = value.lower()
|
||||
try:
|
||||
return cls(value)
|
||||
except ValueError:
|
||||
raise ValueError(f"Invalid value: {value}. Must be one of {cls.list()}")
|
||||
raise ValueError(
|
||||
f"Invalid value type: {type(value)}. Must be an instance of "
|
||||
f"{cls.__name__} or str."
|
||||
)
|
||||
|
||||
@@ -4,11 +4,16 @@ from typing import Callable, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.overlap_filter import OverlapFilter, validate_overlap_filter
|
||||
from supervision.detection.utils import move_boxes, move_masks
|
||||
from supervision.detection.overlap_filter import OverlapFilter
|
||||
from supervision.detection.utils import move_boxes, move_masks, move_oriented_boxes
|
||||
from supervision.utils.image import crop_image
|
||||
from supervision.utils.internal import SupervisionWarnings
|
||||
from supervision.utils.internal import (
|
||||
SupervisionWarnings,
|
||||
deprecated_parameter,
|
||||
warn_deprecated,
|
||||
)
|
||||
|
||||
|
||||
def move_detections(
|
||||
@@ -28,6 +33,10 @@ def move_detections(
|
||||
(sv.Detections) repositioned Detections object.
|
||||
"""
|
||||
detections.xyxy = move_boxes(xyxy=detections.xyxy, offset=offset)
|
||||
if ORIENTED_BOX_COORDINATES in detections.data:
|
||||
detections.data[ORIENTED_BOX_COORDINATES] = move_oriented_boxes(
|
||||
xyxyxyxy=detections.data[ORIENTED_BOX_COORDINATES], offset=offset
|
||||
)
|
||||
if detections.mask is not None:
|
||||
if resolution_wh is None:
|
||||
raise ValueError(
|
||||
@@ -49,11 +58,16 @@ class InferenceSlicer:
|
||||
slice, and then merging the detections.
|
||||
|
||||
Args:
|
||||
slice_wh (Tuple[int, int]): Dimensions of each slice in the format
|
||||
`(width, height)`.
|
||||
overlap_ratio_wh (Tuple[float, float]): Overlap ratio between consecutive
|
||||
slices in the format `(width_ratio, height_ratio)`.
|
||||
overlap_filter_strategy (Union[OverlapFilter, str]): Strategy for
|
||||
slice_wh (Tuple[int, int]): Dimensions of each slice measured in pixels. The
|
||||
tuple should be in the format `(width, height)`.
|
||||
overlap_ratio_wh (Optional[Tuple[float, float]]): A tuple representing the
|
||||
desired overlap ratio for width and height between consecutive slices.
|
||||
Each value should be in the range [0, 1), where 0 means no overlap and
|
||||
a value close to 1 means high overlap.
|
||||
overlap_wh (Optional[Tuple[int, int]]): A tuple representing the desired
|
||||
overlap for width and height between consecutive slices measured in pixels.
|
||||
Each value should be greater than or equal to 0.
|
||||
overlap_filter (Union[OverlapFilter, str]): Strategy for
|
||||
filtering or merging overlapping detections in slices.
|
||||
iou_threshold (float): Intersection over Union (IoU) threshold
|
||||
used when filtering by overlap.
|
||||
@@ -68,23 +82,37 @@ class InferenceSlicer:
|
||||
not a multiple of the slice's width or height minus the overlap.
|
||||
"""
|
||||
|
||||
@deprecated_parameter(
|
||||
old_parameter="overlap_filter_strategy",
|
||||
new_parameter="overlap_filter",
|
||||
map_function=lambda x: x,
|
||||
warning_message="`{old_parameter}` in `{function_name}` is deprecated and will "
|
||||
"be removed in `supervision-0.27.0`. Use '{new_parameter}' "
|
||||
"instead.",
|
||||
)
|
||||
def __init__(
|
||||
self,
|
||||
callback: Callable[[np.ndarray], Detections],
|
||||
slice_wh: Tuple[int, int] = (320, 320),
|
||||
overlap_ratio_wh: Tuple[float, float] = (0.2, 0.2),
|
||||
overlap_filter_strategy: Union[
|
||||
OverlapFilter, str
|
||||
] = OverlapFilter.NON_MAX_SUPPRESSION,
|
||||
overlap_ratio_wh: Optional[Tuple[float, float]] = (0.2, 0.2),
|
||||
overlap_wh: Optional[Tuple[int, int]] = None,
|
||||
overlap_filter: Union[OverlapFilter, str] = OverlapFilter.NON_MAX_SUPPRESSION,
|
||||
iou_threshold: float = 0.5,
|
||||
thread_workers: int = 1,
|
||||
):
|
||||
overlap_filter_strategy = validate_overlap_filter(overlap_filter_strategy)
|
||||
if overlap_ratio_wh is not None:
|
||||
warn_deprecated(
|
||||
"`overlap_ratio_wh` in `InferenceSlicer.__init__` is deprecated and "
|
||||
"will be removed in `supervision-0.27.0`. Use `overlap_wh` instead."
|
||||
)
|
||||
|
||||
self._validate_overlap(overlap_ratio_wh, overlap_wh)
|
||||
self.overlap_ratio_wh = overlap_ratio_wh
|
||||
self.overlap_wh = overlap_wh
|
||||
|
||||
self.slice_wh = slice_wh
|
||||
self.overlap_ratio_wh = overlap_ratio_wh
|
||||
self.iou_threshold = iou_threshold
|
||||
self.overlap_filter_strategy = overlap_filter_strategy
|
||||
self.overlap_filter = OverlapFilter.from_value(overlap_filter)
|
||||
self.callback = callback
|
||||
self.thread_workers = thread_workers
|
||||
|
||||
@@ -129,6 +157,7 @@ class InferenceSlicer:
|
||||
resolution_wh=resolution_wh,
|
||||
slice_wh=self.slice_wh,
|
||||
overlap_ratio_wh=self.overlap_ratio_wh,
|
||||
overlap_wh=self.overlap_wh,
|
||||
)
|
||||
|
||||
with ThreadPoolExecutor(max_workers=self.thread_workers) as executor:
|
||||
@@ -139,15 +168,15 @@ class InferenceSlicer:
|
||||
detections_list.append(future.result())
|
||||
|
||||
merged = Detections.merge(detections_list=detections_list)
|
||||
if self.overlap_filter_strategy == OverlapFilter.NONE:
|
||||
if self.overlap_filter == OverlapFilter.NONE:
|
||||
return merged
|
||||
elif self.overlap_filter_strategy == OverlapFilter.NON_MAX_SUPPRESSION:
|
||||
elif self.overlap_filter == OverlapFilter.NON_MAX_SUPPRESSION:
|
||||
return merged.with_nms(threshold=self.iou_threshold)
|
||||
elif self.overlap_filter_strategy == OverlapFilter.NON_MAX_MERGE:
|
||||
elif self.overlap_filter == OverlapFilter.NON_MAX_MERGE:
|
||||
return merged.with_nmm(threshold=self.iou_threshold)
|
||||
else:
|
||||
warnings.warn(
|
||||
f"Invalid overlap filter strategy: {self.overlap_filter_strategy}",
|
||||
f"Invalid overlap filter strategy: {self.overlap_filter}",
|
||||
category=SupervisionWarnings,
|
||||
)
|
||||
return merged
|
||||
@@ -177,7 +206,8 @@ class InferenceSlicer:
|
||||
def _generate_offset(
|
||||
resolution_wh: Tuple[int, int],
|
||||
slice_wh: Tuple[int, int],
|
||||
overlap_ratio_wh: Tuple[float, float],
|
||||
overlap_ratio_wh: Optional[Tuple[float, float]],
|
||||
overlap_wh: Optional[Tuple[int, int]],
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Generate offset coordinates for slicing an image based on the given resolution,
|
||||
@@ -186,12 +216,15 @@ class InferenceSlicer:
|
||||
Args:
|
||||
resolution_wh (Tuple[int, int]): A tuple representing the width and height
|
||||
of the image to be sliced.
|
||||
slice_wh (Tuple[int, int]): A tuple representing the desired width and
|
||||
height of each slice.
|
||||
overlap_ratio_wh (Tuple[float, float]): A tuple representing the desired
|
||||
overlap ratio for width and height between consecutive slices. Each
|
||||
value should be in the range [0, 1), where 0 means no overlap and a
|
||||
value close to 1 means high overlap.
|
||||
slice_wh (Tuple[int, int]): Dimensions of each slice measured in pixels. The
|
||||
tuple should be in the format `(width, height)`.
|
||||
overlap_ratio_wh (Optional[Tuple[float, float]]): A tuple representing the
|
||||
desired overlap ratio for width and height between consecutive slices.
|
||||
Each value should be in the range [0, 1), where 0 means no overlap and
|
||||
a value close to 1 means high overlap.
|
||||
overlap_wh (Optional[Tuple[int, int]]): A tuple representing the desired
|
||||
overlap for width and height between consecutive slices measured in
|
||||
pixels. Each value should be greater than or equal to 0.
|
||||
|
||||
Returns:
|
||||
np.ndarray: An array of shape `(n, 4)` containing coordinates for each
|
||||
@@ -206,10 +239,19 @@ class InferenceSlicer:
|
||||
"""
|
||||
slice_width, slice_height = slice_wh
|
||||
image_width, image_height = resolution_wh
|
||||
overlap_ratio_width, overlap_ratio_height = overlap_ratio_wh
|
||||
overlap_width = (
|
||||
overlap_wh[0]
|
||||
if overlap_wh is not None
|
||||
else int(overlap_ratio_wh[0] * slice_width)
|
||||
)
|
||||
overlap_height = (
|
||||
overlap_wh[1]
|
||||
if overlap_wh is not None
|
||||
else int(overlap_ratio_wh[1] * slice_height)
|
||||
)
|
||||
|
||||
width_stride = slice_width - int(overlap_ratio_width * slice_width)
|
||||
height_stride = slice_height - int(overlap_ratio_height * slice_height)
|
||||
width_stride = slice_width - overlap_width
|
||||
height_stride = slice_height - overlap_height
|
||||
|
||||
ws = np.arange(0, image_width, width_stride)
|
||||
hs = np.arange(0, image_height, height_stride)
|
||||
@@ -221,3 +263,32 @@ class InferenceSlicer:
|
||||
offsets = np.stack([xmin, ymin, xmax, ymax], axis=-1).reshape(-1, 4)
|
||||
|
||||
return offsets
|
||||
|
||||
@staticmethod
|
||||
def _validate_overlap(
|
||||
overlap_ratio_wh: Optional[Tuple[float, float]],
|
||||
overlap_wh: Optional[Tuple[int, int]],
|
||||
) -> None:
|
||||
if overlap_ratio_wh is not None and overlap_wh is not None:
|
||||
raise ValueError(
|
||||
"Both `overlap_ratio_wh` and `overlap_wh` cannot be provided. "
|
||||
"Please provide only one of them."
|
||||
)
|
||||
if overlap_ratio_wh is None and overlap_wh is None:
|
||||
raise ValueError(
|
||||
"Either `overlap_ratio_wh` or `overlap_wh` must be provided. "
|
||||
"Please provide one of them."
|
||||
)
|
||||
|
||||
if overlap_ratio_wh is not None:
|
||||
if not (0 <= overlap_ratio_wh[0] < 1 and 0 <= overlap_ratio_wh[1] < 1):
|
||||
raise ValueError(
|
||||
"Overlap ratios must be in the range [0, 1). "
|
||||
f"Received: {overlap_ratio_wh}"
|
||||
)
|
||||
if overlap_wh is not None:
|
||||
if not (overlap_wh[0] >= 0 and overlap_wh[1] >= 0):
|
||||
raise ValueError(
|
||||
"Overlap values must be greater than or equal to 0. "
|
||||
f"Received: {overlap_wh}"
|
||||
)
|
||||
|
||||
@@ -12,7 +12,7 @@ from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_polygon, draw_text
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.utils.internal import SupervisionWarnings, deprecated_parameter
|
||||
from supervision.utils.internal import SupervisionWarnings
|
||||
|
||||
|
||||
class PolygonZone:
|
||||
@@ -30,14 +30,6 @@ class PolygonZone:
|
||||
mask (np.ndarray): The 2D bool mask for the polygon zone
|
||||
"""
|
||||
|
||||
@deprecated_parameter(
|
||||
old_parameter="triggering_position",
|
||||
new_parameter="triggering_anchors",
|
||||
map_function=lambda x: [x],
|
||||
warning_message="`{old_parameter}` in `{function_name}` is deprecated and will "
|
||||
"be remove in `supervision-0.23.0`. Use '{new_parameter}' "
|
||||
"instead.",
|
||||
)
|
||||
def __init__(
|
||||
self,
|
||||
polygon: npt.NDArray[np.int64],
|
||||
@@ -147,7 +139,7 @@ class PolygonZoneAnnotator:
|
||||
|
||||
Parameters:
|
||||
scene (np.ndarray): The image on which the polygon zone will be annotated
|
||||
label (Optional[str]): An optional label for the count of detected objects
|
||||
label (Optional[str]): A label for the count of detected objects
|
||||
within the polygon zone (default: None)
|
||||
|
||||
Returns:
|
||||
|
||||
@@ -0,0 +1,247 @@
|
||||
import io
|
||||
from typing import Any, Dict, Optional
|
||||
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.utils import mask_to_xyxy
|
||||
|
||||
|
||||
def process_transformers_detection_result(
|
||||
detection_result: dict, id2label: Optional[Dict[int, str]]
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of Transformers object detection functions such as
|
||||
`post_process` (v4) and `post_process_detection` (v5).
|
||||
|
||||
Args:
|
||||
detection_result (dict): Dictionary containing detection results with keys
|
||||
'boxes', 'labels', and 'scores'.
|
||||
id2label (Optional[Dict[int, str]]): A dictionary mapping class IDs to labels,
|
||||
typically part of the `transformers` model configuration. If provided, the
|
||||
resulting dictionary will include class names.
|
||||
|
||||
Returns:
|
||||
dict: Processed detection result including bounding boxes, confidence scores,
|
||||
class IDs, and data.
|
||||
"""
|
||||
class_ids = detection_result["labels"].cpu().detach().numpy().astype(int)
|
||||
data = append_class_names_to_data(class_ids, id2label, {})
|
||||
|
||||
return dict(
|
||||
xyxy=detection_result["boxes"].cpu().detach().numpy(),
|
||||
confidence=detection_result["scores"].cpu().detach().numpy(),
|
||||
class_id=class_ids,
|
||||
data=data,
|
||||
)
|
||||
|
||||
|
||||
def process_transformers_v4_segmentation_result(
|
||||
segmentation_result: dict, id2label: Optional[Dict[int, str]]
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of Transformers segmentation functions such as
|
||||
`post_process_panoptic`, `post_process_segmentation`, and `post_process_instance`
|
||||
(v4).
|
||||
|
||||
Args:
|
||||
segmentation_result (dict): Dictionary containing segmentation results with keys
|
||||
'masks', 'labels', and 'scores'.
|
||||
id2label (Optional[Dict[int, str]]): A dictionary mapping class IDs to labels,
|
||||
typically part of the `transformers` model configuration. If provided, the
|
||||
resulting dictionary will include class names.
|
||||
|
||||
Returns:
|
||||
dict: Processed segmentation result including bounding boxes, masks, confidence
|
||||
scores, class IDs, and data.
|
||||
"""
|
||||
if "png_string" in segmentation_result:
|
||||
return process_transformers_v4_panoptic_segmentation_result(
|
||||
segmentation_result, id2label
|
||||
)
|
||||
else:
|
||||
boxes = None
|
||||
if "boxes" in segmentation_result:
|
||||
boxes = segmentation_result["boxes"].cpu().detach().numpy()
|
||||
masks = segmentation_result["masks"].cpu().detach().numpy().astype(bool)
|
||||
class_ids = segmentation_result["labels"].cpu().detach().numpy().astype(int)
|
||||
|
||||
return dict(
|
||||
xyxy=boxes if boxes is not None else mask_to_xyxy(masks),
|
||||
mask=np.squeeze(masks, axis=1) if boxes is not None else masks,
|
||||
confidence=segmentation_result["scores"].cpu().detach().numpy(),
|
||||
class_id=class_ids,
|
||||
data=append_class_names_to_data(class_ids, id2label, {}),
|
||||
)
|
||||
|
||||
|
||||
def process_transformers_v5_segmentation_result(
|
||||
segmentation_result: dict, id2label: Optional[Dict[int, str]]
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of Transformers segmentation functions such as
|
||||
`post_process_semantic_segmentation`, `post_process_instance_segmentation`, and
|
||||
`post_process_panoptic_segmentation` (v5).
|
||||
|
||||
Args:
|
||||
segmentation_result (Union[dict, np.ndarray]): Either a dictionary containing
|
||||
segmentation results or an ndarray representing a segmentation map.
|
||||
id2label (Optional[Dict[int, str]]): A dictionary mapping class IDs to labels,
|
||||
typically part of the `transformers` model configuration. If provided, the
|
||||
resulting dictionary will include class names.
|
||||
|
||||
Returns:
|
||||
dict: Processed segmentation result including bounding boxes, masks, confidence
|
||||
scores, class IDs, and data.
|
||||
"""
|
||||
if segmentation_result.__class__.__name__ == "Tensor":
|
||||
segmentation_array = segmentation_result.cpu().detach().numpy()
|
||||
return process_transformers_v5_panoptic_segmentation_result(
|
||||
segmentation_array, id2label
|
||||
)
|
||||
|
||||
return process_transformers_v5_semantic_or_instance_segmentation_result(
|
||||
segmentation_result, id2label
|
||||
)
|
||||
|
||||
|
||||
def process_transformers_v5_semantic_or_instance_segmentation_result(
|
||||
segmentation_result: dict, id2label: Optional[Dict[int, str]]
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of Transformers segmentation functions such as
|
||||
`post_process_semantic_segmentation` and `post_process_instance_segmentation` (v5).
|
||||
|
||||
Args:
|
||||
segmentation_result (dict): Dictionary containing segmentation results with keys
|
||||
`segments_info` and `segmentation`.
|
||||
id2label (Optional[Dict[int, str]]): A dictionary mapping class IDs to labels,
|
||||
typically part of the `transformers` model configuration. If provided, the
|
||||
resulting dictionary will include class names.
|
||||
|
||||
Returns:
|
||||
dict: Processed segmentation result including bounding boxes, masks, confidence
|
||||
scores, class IDs, and data.
|
||||
"""
|
||||
segments_info = segmentation_result["segments_info"]
|
||||
scores = np.array([segment["score"] for segment in segments_info])
|
||||
class_ids = np.array([segment["label_id"] for segment in segments_info])
|
||||
segmentation_array = segmentation_result["segmentation"].cpu().detach().numpy()
|
||||
masks = np.array(
|
||||
[segmentation_array == segment["id"] for segment in segments_info]
|
||||
).astype(bool)
|
||||
data = append_class_names_to_data(class_ids, id2label, {})
|
||||
|
||||
return dict(
|
||||
xyxy=mask_to_xyxy(masks),
|
||||
mask=masks,
|
||||
confidence=scores,
|
||||
class_id=class_ids,
|
||||
data=data,
|
||||
)
|
||||
|
||||
|
||||
def process_transformers_v4_panoptic_segmentation_result(
|
||||
segmentation_result: dict, id2label: Optional[Dict[int, str]]
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of the Transformers function `post_process_panoptic` (v4).
|
||||
|
||||
Args:
|
||||
segmentation_result (dict): Dictionary containing segmentation results with keys
|
||||
such as 'png_string' and 'segments_info'.
|
||||
id2label (Optional[Dict[int, str]]): A dictionary mapping class IDs to labels,
|
||||
typically part of the `transformers` model configuration. If provided, the
|
||||
resulting dictionary will include class names.
|
||||
|
||||
Returns:
|
||||
dict: Processed segmentation result including bounding boxes, masks,
|
||||
class IDs, and data.
|
||||
"""
|
||||
segments_info = segmentation_result["segments_info"]
|
||||
png_string = segmentation_result["png_string"]
|
||||
class_ids = np.array([segment["category_id"] for segment in segments_info])
|
||||
segmentation_array = png_string_to_segmentation_array(png_string=png_string)
|
||||
masks = np.array(
|
||||
[segmentation_array == segment["id"] for segment in segments_info]
|
||||
).astype(bool)
|
||||
data = append_class_names_to_data(class_ids, id2label, {})
|
||||
|
||||
return dict(
|
||||
xyxy=mask_to_xyxy(masks),
|
||||
mask=masks,
|
||||
class_id=class_ids,
|
||||
data=data,
|
||||
)
|
||||
|
||||
|
||||
def process_transformers_v5_panoptic_segmentation_result(
|
||||
segmentation_array: np.ndarray, id2label: Optional[Dict[int, str]]
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of the Transformers function
|
||||
`post_process_panoptic_segmentation` (v5).
|
||||
|
||||
Args:
|
||||
segmentation_array (np.ndarray): Segmentation array.
|
||||
id2label (Optional[Dict[int, str]]): A dictionary mapping class IDs to labels,
|
||||
typically part of the `transformers` model configuration. If provided, the
|
||||
resulting dictionary will include class names.
|
||||
|
||||
Returns:
|
||||
dict: Processed segmentation result including bounding boxes, masks,
|
||||
class IDs, and data.
|
||||
"""
|
||||
class_ids = np.unique(segmentation_array)
|
||||
masks = np.stack(
|
||||
[segmentation_array == class_id for class_id in class_ids], axis=0
|
||||
).astype(bool)
|
||||
data = append_class_names_to_data(class_ids, id2label, {})
|
||||
return dict(xyxy=mask_to_xyxy(masks), mask=masks, class_id=class_ids, data=data)
|
||||
|
||||
|
||||
def png_string_to_segmentation_array(png_string: bytes) -> np.ndarray:
|
||||
"""
|
||||
Convert a PNG byte string to a label mask array.
|
||||
|
||||
Args:
|
||||
png_string (bytes): A byte string representing the PNG image.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A label mask array with shape (H, W), where H and W
|
||||
are the height and width of the image. Each unique value in the array
|
||||
represents a different object or category.
|
||||
"""
|
||||
image = Image.open(io.BytesIO(png_string))
|
||||
mask = np.array(image, dtype=np.uint8)
|
||||
return mask[:, :, 0]
|
||||
|
||||
|
||||
def append_class_names_to_data(
|
||||
class_ids: np.ndarray,
|
||||
id2label: Optional[Dict[int, str]],
|
||||
data: Optional[Dict[str, Any]] = None,
|
||||
) -> Dict[str, Any]:
|
||||
"""
|
||||
Helper function to create or append to a data dictionary with class names if
|
||||
available.
|
||||
|
||||
Args:
|
||||
class_ids (np.ndarray): Array of class IDs.
|
||||
id2label (Optional[Dict[int, str]]): A dictionary mapping class IDs to labels,
|
||||
typically part of the `transformers` model configuration. If provided, the
|
||||
resulting dictionary will include class names.
|
||||
data (Optional[Dict[str, Any]]): An existing data dictionary to append to.
|
||||
|
||||
Returns:
|
||||
Dict[str, Any]: Dictionary containing class names if id2label is provided.
|
||||
"""
|
||||
if data is None:
|
||||
data = {}
|
||||
|
||||
if id2label is not None:
|
||||
class_names = np.array([id2label[class_id] for class_id in class_ids])
|
||||
data[CLASS_NAME_DATA_FIELD] = class_names
|
||||
|
||||
return data
|
||||
@@ -106,7 +106,7 @@ def mask_iou_batch(
|
||||
Args:
|
||||
masks_true (np.ndarray): 3D `np.ndarray` representing ground-truth masks.
|
||||
masks_detection (np.ndarray): 3D `np.ndarray` representing detection masks.
|
||||
memory_limit (int, optional): memory limit in MB, default is 1024 * 5 MB (5GB).
|
||||
memory_limit (int): memory limit in MB, default is 1024 * 5 MB (5GB).
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of masks from `masks_true` and `masks_detection`.
|
||||
@@ -596,6 +596,61 @@ def move_boxes(
|
||||
return xyxy + np.hstack([offset, offset])
|
||||
|
||||
|
||||
def move_oriented_boxes(
|
||||
xyxyxyxy: npt.NDArray[np.float64], offset: npt.NDArray[np.int32]
|
||||
) -> npt.NDArray[np.float64]:
|
||||
"""
|
||||
Parameters:
|
||||
xyxyxyxy (npt.NDArray[np.float64]): An array of shape `(n, 4, 2)` containing the
|
||||
oriented bounding boxes coordinates in format
|
||||
`[[x1, y1], [x2, y2], [x3, y3], [x3, y3]]`
|
||||
offset (np.array): An array of shape `(2,)` containing offset values in format
|
||||
is `[dx, dy]`.
|
||||
|
||||
Returns:
|
||||
npt.NDArray[np.float64]: Repositioned bounding boxes.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxyxyxy = np.array([
|
||||
[
|
||||
[20, 10],
|
||||
[10, 20],
|
||||
[20, 30],
|
||||
[30, 20]
|
||||
],
|
||||
[
|
||||
[30 ,30],
|
||||
[20, 40],
|
||||
[30, 50],
|
||||
[40, 40]
|
||||
]
|
||||
])
|
||||
offset = np.array([5, 5])
|
||||
|
||||
sv.move_oriented_boxes(xyxy=xyxy, offset=offset)
|
||||
# array([
|
||||
# [
|
||||
# [25, 15],
|
||||
# [15, 25],
|
||||
# [25, 35],
|
||||
# [35, 25]
|
||||
# ],
|
||||
# [
|
||||
# [35, 35],
|
||||
# [25, 45],
|
||||
# [35, 55],
|
||||
# [45, 45]
|
||||
# ]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
return xyxyxyxy + offset
|
||||
|
||||
|
||||
def move_masks(
|
||||
masks: npt.NDArray[np.bool_],
|
||||
offset: npt.NDArray[np.int32],
|
||||
|
||||
@@ -352,11 +352,15 @@ class ColorPalette:
|
||||
supervision-annotator-examples/visualized_color_palette.png)
|
||||
""" # noqa: E501 // docs
|
||||
mpl_palette = plt.get_cmap(palette_name, color_count)
|
||||
colors = [
|
||||
Color(int(r * 255), int(g * 255), int(b * 255))
|
||||
for r, g, b, _ in mpl_palette.colors
|
||||
]
|
||||
return cls(colors)
|
||||
|
||||
if hasattr(mpl_palette, "colors"):
|
||||
colors = mpl_palette.colors
|
||||
else:
|
||||
colors = [mpl_palette(i / (color_count - 1)) for i in range(color_count)]
|
||||
|
||||
return cls(
|
||||
[Color(int(r * 255), int(g * 255), int(b * 255)) for r, g, b, _ in colors]
|
||||
)
|
||||
|
||||
def by_idx(self, idx: int) -> Color:
|
||||
"""
|
||||
|
||||
@@ -142,7 +142,7 @@ def draw_polygon(
|
||||
scene (np.ndarray): The scene to draw the polygon on.
|
||||
polygon (np.ndarray): The polygon to be drawn, given as a list of vertices.
|
||||
color (Color): The color of the polygon.
|
||||
thickness (int, optional): The thickness of the polygon lines, by default 2.
|
||||
thickness (int): The thickness of the polygon lines, by default 2.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The scene with the polygon drawn on it.
|
||||
@@ -172,14 +172,14 @@ def draw_text(
|
||||
text (str): The text to be drawn.
|
||||
text_anchor (Point): The anchor point for the text, represented as a
|
||||
Point object with x and y attributes.
|
||||
text_color (Color, optional): The color of the text. Defaults to black.
|
||||
text_scale (float, optional): The scale of the text. Defaults to 0.5.
|
||||
text_thickness (int, optional): The thickness of the text. Defaults to 1.
|
||||
text_padding (int, optional): The amount of padding to add around the text
|
||||
text_color (Color): The color of the text. Defaults to black.
|
||||
text_scale (float): The scale of the text. Defaults to 0.5.
|
||||
text_thickness (int): The thickness of the text. Defaults to 1.
|
||||
text_padding (int): The amount of padding to add around the text
|
||||
when drawing a rectangle in the background. Defaults to 10.
|
||||
text_font (int, optional): The font to use for the text.
|
||||
text_font (int): The font to use for the text.
|
||||
Defaults to cv2.FONT_HERSHEY_SIMPLEX.
|
||||
background_color (Color, optional): The color of the background rectangle,
|
||||
background_color (Optional[Color]): The color of the background rectangle,
|
||||
if one is to be drawn. Defaults to None.
|
||||
|
||||
Returns:
|
||||
|
||||
@@ -34,8 +34,8 @@ class VertexAnnotator(BaseKeyPointAnnotator):
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
color (Color, optional): The color to use for annotating key points.
|
||||
radius (int, optional): The radius of the circles used to represent the key
|
||||
color (Color): The color to use for annotating key points.
|
||||
radius (int): The radius of the circles used to represent the key
|
||||
points.
|
||||
"""
|
||||
self.color = color
|
||||
@@ -78,6 +78,7 @@ class VertexAnnotator(BaseKeyPointAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
@@ -108,8 +109,8 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
color (Color, optional): The color to use for the edges.
|
||||
thickness (int, optional): The thickness of the edges.
|
||||
color (Color): The color to use for the edges.
|
||||
thickness (int): The thickness of the edges.
|
||||
edges (Optional[List[Tuple[int, int]]]): The edges to draw.
|
||||
If set to `None`, will attempt to select automatically.
|
||||
"""
|
||||
@@ -155,6 +156,7 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
if len(key_points) == 0:
|
||||
return scene
|
||||
|
||||
@@ -194,7 +196,7 @@ class VertexLabelAnnotator:
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, List[Color]] = Color.ROBOFLOW,
|
||||
text_color: Color = Color.WHITE,
|
||||
text_color: Union[Color, List[Color]] = Color.WHITE,
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
@@ -202,25 +204,30 @@ class VertexLabelAnnotator:
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
color (Union[Color, List[Color]], optional): The color to use for each
|
||||
color (Union[Color, List[Color]]): The color to use for each
|
||||
keypoint label. If a list is provided, the colors will be used in order
|
||||
for each keypoint.
|
||||
text_color (Color, optional): The color to use for the labels.
|
||||
text_scale (float, optional): The scale of the text.
|
||||
text_thickness (int, optional): The thickness of the text.
|
||||
text_padding (int, optional): The padding around the text.
|
||||
border_radius (int, optional): The radius of the rounded corners of the
|
||||
text_color (Union[Color, List[Color]]): The color to use
|
||||
for the labels. If a list is provided, the colors will be used in order
|
||||
for each keypoint.
|
||||
text_scale (float): The scale of the text.
|
||||
text_thickness (int): The thickness of the text.
|
||||
text_padding (int): The padding around the text.
|
||||
border_radius (int): The radius of the rounded corners of the
|
||||
boxes. Set to a high value to produce circles.
|
||||
"""
|
||||
self.border_radius: int = border_radius
|
||||
self.color: Union[Color, List[Color]] = color
|
||||
self.text_color: Color = text_color
|
||||
self.text_color: Union[Color, List[Color]] = text_color
|
||||
self.text_scale: float = text_scale
|
||||
self.text_thickness: int = text_thickness
|
||||
self.text_padding: int = text_padding
|
||||
|
||||
def annotate(
|
||||
self, scene: ImageType, key_points: KeyPoints, labels: List[str] = None
|
||||
self,
|
||||
scene: ImageType,
|
||||
key_points: KeyPoints,
|
||||
labels: Optional[List[str]] = None,
|
||||
) -> ImageType:
|
||||
"""
|
||||
A class that draws labels of skeleton vertices on images. It uses specified key
|
||||
@@ -232,7 +239,7 @@ class VertexLabelAnnotator:
|
||||
`PIL.Image.Image`.
|
||||
key_points (KeyPoints): A collection of key points where each key point
|
||||
consists of x and y coordinates.
|
||||
labels (List[str], optional): A list of labels to be displayed on the
|
||||
labels (Optional[List[str]]): A list of labels to be displayed on the
|
||||
annotated image. If not provided, keypoint indices will be used.
|
||||
|
||||
Returns:
|
||||
@@ -303,6 +310,7 @@ class VertexLabelAnnotator:
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
font = cv2.FONT_HERSHEY_SIMPLEX
|
||||
|
||||
skeletons_count, points_count, _ = key_points.xy.shape
|
||||
@@ -321,12 +329,19 @@ class VertexLabelAnnotator:
|
||||
skeletons_count=skeletons_count,
|
||||
)
|
||||
|
||||
text_colors = self.preprocess_and_validate_colors(
|
||||
colors=self.text_color,
|
||||
points_count=points_count,
|
||||
skeletons_count=skeletons_count,
|
||||
)
|
||||
|
||||
labels = self.preprocess_and_validate_labels(
|
||||
labels=labels, points_count=points_count, skeletons_count=skeletons_count
|
||||
)
|
||||
|
||||
anchors = anchors[mask]
|
||||
colors = colors[mask]
|
||||
text_colors = text_colors[mask]
|
||||
labels = labels[mask]
|
||||
|
||||
xyxy = np.array(
|
||||
@@ -344,7 +359,9 @@ class VertexLabelAnnotator:
|
||||
|
||||
xyxy_padded = pad_boxes(xyxy=xyxy, px=self.text_padding)
|
||||
|
||||
for text, color, box, box_padded in zip(labels, colors, xyxy, xyxy_padded):
|
||||
for text, color, text_color, box, box_padded in zip(
|
||||
labels, colors, text_colors, xyxy, xyxy_padded
|
||||
):
|
||||
draw_rounded_rectangle(
|
||||
scene=scene,
|
||||
rect=Rect.from_xyxy(box_padded),
|
||||
@@ -354,10 +371,10 @@ class VertexLabelAnnotator:
|
||||
cv2.putText(
|
||||
img=scene,
|
||||
text=text,
|
||||
org=(box[0], box[1] + self.text_padding),
|
||||
org=(box[0], box[3]),
|
||||
fontFace=font,
|
||||
fontScale=self.text_scale,
|
||||
color=self.text_color.as_rgb(),
|
||||
color=text_color.as_bgr(),
|
||||
thickness=self.text_thickness,
|
||||
lineType=cv2.LINE_AA,
|
||||
)
|
||||
@@ -389,7 +406,7 @@ class VertexLabelAnnotator:
|
||||
@staticmethod
|
||||
def preprocess_and_validate_labels(
|
||||
labels: Optional[List[str]], points_count: int, skeletons_count: int
|
||||
) -> np.array:
|
||||
) -> np.ndarray:
|
||||
if labels and len(labels) != points_count:
|
||||
raise ValueError(
|
||||
f"Number of labels ({len(labels)}) must match number of key points "
|
||||
@@ -405,7 +422,7 @@ class VertexLabelAnnotator:
|
||||
colors: Optional[Union[Color, List[Color]]],
|
||||
points_count: int,
|
||||
skeletons_count: int,
|
||||
) -> np.array:
|
||||
) -> np.ndarray:
|
||||
if isinstance(colors, list) and len(colors) != points_count:
|
||||
raise ValueError(
|
||||
f"Number of colors ({len(colors)}) must match number of key points "
|
||||
|
||||
@@ -88,15 +88,17 @@ class KeyPoints:
|
||||
```
|
||||
|
||||
Attributes:
|
||||
xy (np.ndarray): An array of shape `(n, 2)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1]`
|
||||
xy (np.ndarray): An array of shape `(n, m, 2)` containing
|
||||
`n` detected objects, each composed of `m` equally-sized
|
||||
sets of keypoints, where each point is `[x, y]`.
|
||||
confidence (Optional[np.ndarray]): An array of shape
|
||||
`(n,)` containing the confidence scores of the keypoint keypoints.
|
||||
`(n, m)` containing the confidence scores of each keypoint.
|
||||
class_id (Optional[np.ndarray]): An array of shape
|
||||
`(n,)` containing the class ids of the keypoint keypoints.
|
||||
`(n,)` containing the class ids of the detected objects.
|
||||
data (Dict[str, Union[np.ndarray, List]]): A dictionary containing additional
|
||||
data where each key is a string representing the data type, and the value
|
||||
is either a NumPy array or a list of corresponding data.
|
||||
is either a NumPy array or a list of corresponding data of length `n`
|
||||
(one entry per detected object).
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
xy: npt.NDArray[np.float32]
|
||||
@@ -132,7 +134,7 @@ class KeyPoints:
|
||||
]:
|
||||
"""
|
||||
Iterates over the Keypoint object and yield a tuple of
|
||||
`(xy, confidence, class_id, data)` for each keypoint detection.
|
||||
`(xy, confidence, class_id, data)` for each object detection.
|
||||
"""
|
||||
for i in range(len(self.xy)):
|
||||
yield (
|
||||
|
||||
@@ -0,0 +1,10 @@
|
||||
from supervision.metrics.core import CLASS_ID_NONE, Metric, MetricTarget
|
||||
from supervision.metrics.mean_average_precision import (
|
||||
MeanAveragePrecision,
|
||||
MeanAveragePrecisionResult,
|
||||
)
|
||||
from supervision.metrics.utils.object_size import (
|
||||
ObjectSizeCategory,
|
||||
get_detection_size_category,
|
||||
get_object_size_category,
|
||||
)
|
||||
|
||||
@@ -0,0 +1,50 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from abc import ABC, abstractmethod
|
||||
from enum import Enum
|
||||
from typing import Any
|
||||
|
||||
CLASS_ID_NONE = -1
|
||||
"""Used by metrics module as class ID, when none is present"""
|
||||
|
||||
|
||||
class Metric(ABC):
|
||||
"""
|
||||
The base class for all supervision metrics.
|
||||
"""
|
||||
|
||||
@abstractmethod
|
||||
def update(self, *args, **kwargs) -> "Metric":
|
||||
"""
|
||||
Add data to the metric, without computing the result.
|
||||
Return the metric itself to allow method chaining.
|
||||
"""
|
||||
raise NotImplementedError
|
||||
|
||||
@abstractmethod
|
||||
def reset(self) -> None:
|
||||
"""
|
||||
Reset internal metric state.
|
||||
"""
|
||||
raise NotImplementedError
|
||||
|
||||
@abstractmethod
|
||||
def compute(self, *args, **kwargs) -> Any:
|
||||
"""
|
||||
Compute the metric from the internal state and return the result.
|
||||
"""
|
||||
raise NotImplementedError
|
||||
|
||||
|
||||
class MetricTarget(Enum):
|
||||
"""
|
||||
Specifies what type of detection is used to compute the metric.
|
||||
|
||||
* BOXES: xyxy bounding boxes
|
||||
* MASKS: Binary masks
|
||||
* ORIENTED_BOUNDING_BOXES: Oriented bounding boxes (OBB)
|
||||
"""
|
||||
|
||||
BOXES = "boxes"
|
||||
MASKS = "masks"
|
||||
ORIENTED_BOUNDING_BOXES = "obb"
|
||||
@@ -391,11 +391,10 @@ class ConfusionMatrix:
|
||||
```
|
||||
"""
|
||||
predictions, targets = [], []
|
||||
for img_name, img in dataset.images.items():
|
||||
predictions_batch = callback(img)
|
||||
for _, image, annotation in dataset:
|
||||
predictions_batch = callback(image)
|
||||
predictions.append(predictions_batch)
|
||||
targets_batch = dataset.annotations[img_name]
|
||||
targets.append(targets_batch)
|
||||
targets.append(annotation)
|
||||
return cls.from_detections(
|
||||
predictions=predictions,
|
||||
targets=targets,
|
||||
@@ -604,11 +603,10 @@ class MeanAveragePrecision:
|
||||
```
|
||||
"""
|
||||
predictions, targets = [], []
|
||||
for img_name, img in dataset.images.items():
|
||||
predictions_batch = callback(img)
|
||||
for _, image, annotation in dataset:
|
||||
predictions_batch = callback(image)
|
||||
predictions.append(predictions_batch)
|
||||
targets_batch = dataset.annotations[img_name]
|
||||
targets.append(targets_batch)
|
||||
targets.append(annotation)
|
||||
return cls.from_detections(
|
||||
predictions=predictions,
|
||||
targets=targets,
|
||||
@@ -666,12 +664,12 @@ class MeanAveragePrecision:
|
||||
np.array([[1.0, 1.0, 2.0, 2.0, 2, 0.8]])
|
||||
]
|
||||
|
||||
mean_average_precison = sv.MeanAveragePrecision.from_tensors(
|
||||
mean_average_precision = sv.MeanAveragePrecision.from_tensors(
|
||||
predictions=predictions,
|
||||
targets=targets,
|
||||
)
|
||||
|
||||
print(mean_average_precison.map50_95)
|
||||
print(mean_average_precision.map50_95)
|
||||
# 0.6649
|
||||
```
|
||||
"""
|
||||
@@ -808,7 +806,7 @@ class MeanAveragePrecision:
|
||||
prediction_confidence (np.ndarray): Objectness value from 0-1.
|
||||
prediction_class_ids (np.ndarray): Predicted object classes.
|
||||
true_class_ids (np.ndarray): True object classes.
|
||||
eps (float, optional): Small value to prevent division by zero.
|
||||
eps (float): Small value to prevent division by zero.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Average precision for different IoU levels.
|
||||
|
||||
@@ -0,0 +1,562 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from copy import deepcopy
|
||||
from dataclasses import dataclass
|
||||
from typing import TYPE_CHECKING, List, Optional, Union
|
||||
|
||||
import numpy as np
|
||||
from matplotlib import pyplot as plt
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import box_iou_batch, mask_iou_batch
|
||||
from supervision.draw.color import LEGACY_COLOR_PALETTE
|
||||
from supervision.metrics.core import Metric, MetricTarget
|
||||
from supervision.metrics.utils.object_size import (
|
||||
ObjectSizeCategory,
|
||||
get_detection_size_category,
|
||||
)
|
||||
from supervision.metrics.utils.utils import ensure_pandas_installed
|
||||
|
||||
if TYPE_CHECKING:
|
||||
import pandas as pd
|
||||
|
||||
|
||||
class MeanAveragePrecision(Metric):
|
||||
def __init__(
|
||||
self,
|
||||
metric_target: MetricTarget = MetricTarget.BOXES,
|
||||
class_agnostic: bool = False,
|
||||
):
|
||||
"""
|
||||
Initialize the Mean Average Precision metric.
|
||||
|
||||
Args:
|
||||
metric_target (MetricTarget): The type of detection data to use.
|
||||
class_agnostic (bool): Whether to treat all data as a single class.
|
||||
"""
|
||||
self._metric_target = metric_target
|
||||
if self._metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
raise NotImplementedError(
|
||||
"Mean Average Precision is not implemented for oriented bounding boxes."
|
||||
)
|
||||
|
||||
self._class_agnostic = class_agnostic
|
||||
|
||||
self._predictions_list: List[Detections] = []
|
||||
self._targets_list: List[Detections] = []
|
||||
|
||||
def reset(self) -> None:
|
||||
self._predictions_list = []
|
||||
self._targets_list = []
|
||||
|
||||
def update(
|
||||
self,
|
||||
predictions: Union[Detections, List[Detections]],
|
||||
targets: Union[Detections, List[Detections]],
|
||||
) -> MeanAveragePrecision:
|
||||
"""
|
||||
Add new predictions and targets to the metric, but do not compute the result.
|
||||
|
||||
Args:
|
||||
predictions (Union[Detections, List[Detections]]): The predicted detections.
|
||||
targets (Union[Detections, List[Detections]]): The ground-truth detections.
|
||||
|
||||
Returns:
|
||||
(MeanAveragePrecision): The updated metric instance.
|
||||
"""
|
||||
if not isinstance(predictions, list):
|
||||
predictions = [predictions]
|
||||
if not isinstance(targets, list):
|
||||
targets = [targets]
|
||||
|
||||
if len(predictions) != len(targets):
|
||||
raise ValueError(
|
||||
f"The number of predictions ({len(predictions)}) and"
|
||||
f" targets ({len(targets)}) during the update must be the same."
|
||||
)
|
||||
|
||||
self._predictions_list.extend(predictions)
|
||||
self._targets_list.extend(targets)
|
||||
|
||||
return self
|
||||
|
||||
def compute(
|
||||
self,
|
||||
) -> MeanAveragePrecisionResult:
|
||||
"""
|
||||
Calculate Mean Average Precision based on predicted and ground-truth
|
||||
detections at different threshold.
|
||||
|
||||
Args:
|
||||
predictions (List[np.ndarray]): Each element of the list describes
|
||||
a single image and has `shape = (M, 6)` where `M` is
|
||||
the number of detected objects. Each row is expected to be
|
||||
in `(x_min, y_min, x_max, y_max, class, conf)` format.
|
||||
targets (List[np.ndarray]): Each element of the list describes a single
|
||||
image and has `shape = (N, 5)` where `N` is the
|
||||
number of ground-truth objects. Each row is expected to be in
|
||||
`(x_min, y_min, x_max, y_max, class)` format.
|
||||
Returns:
|
||||
(MeanAveragePrecision): New instance of MeanAveragePrecision.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
from supervision.metrics import MeanAveragePrecision
|
||||
|
||||
predictions = sv.Detections(...)
|
||||
targets = sv.Detections(...)
|
||||
|
||||
map_metric = MeanAveragePrecision()
|
||||
map_result = map_metric.update(predictions, targets).compute()
|
||||
|
||||
print(map_result)
|
||||
print(map_result.map50_95)
|
||||
map_result.plot()
|
||||
```
|
||||
"""
|
||||
result = self._compute(self._predictions_list, self._targets_list)
|
||||
|
||||
small_predictions = []
|
||||
small_targets = []
|
||||
for predictions, targets in zip(self._predictions_list, self._targets_list):
|
||||
small_predictions.append(
|
||||
self._filter_detections_by_size(predictions, ObjectSizeCategory.SMALL)
|
||||
)
|
||||
small_targets.append(
|
||||
self._filter_detections_by_size(targets, ObjectSizeCategory.SMALL)
|
||||
)
|
||||
result.small_objects = self._compute(small_predictions, small_targets)
|
||||
|
||||
medium_predictions = []
|
||||
medium_targets = []
|
||||
for predictions, targets in zip(self._predictions_list, self._targets_list):
|
||||
medium_predictions.append(
|
||||
self._filter_detections_by_size(predictions, ObjectSizeCategory.MEDIUM)
|
||||
)
|
||||
medium_targets.append(
|
||||
self._filter_detections_by_size(targets, ObjectSizeCategory.MEDIUM)
|
||||
)
|
||||
result.medium_objects = self._compute(medium_predictions, medium_targets)
|
||||
|
||||
large_predictions = []
|
||||
large_targets = []
|
||||
for predictions, targets in zip(self._predictions_list, self._targets_list):
|
||||
large_predictions.append(
|
||||
self._filter_detections_by_size(predictions, ObjectSizeCategory.LARGE)
|
||||
)
|
||||
large_targets.append(
|
||||
self._filter_detections_by_size(targets, ObjectSizeCategory.LARGE)
|
||||
)
|
||||
result.large_objects = self._compute(large_predictions, large_targets)
|
||||
|
||||
return result
|
||||
|
||||
def _compute(
|
||||
self,
|
||||
predictions_list: List[Detections],
|
||||
targets_list: List[Detections],
|
||||
) -> MeanAveragePrecisionResult:
|
||||
iou_thresholds = np.linspace(0.5, 0.95, 10)
|
||||
stats = []
|
||||
|
||||
for predictions, targets in zip(predictions_list, targets_list):
|
||||
prediction_contents = self._detections_content(predictions)
|
||||
target_contents = self._detections_content(targets)
|
||||
|
||||
if len(targets) > 0:
|
||||
if len(predictions) == 0:
|
||||
stats.append(
|
||||
(
|
||||
np.zeros((0, iou_thresholds.size), dtype=bool),
|
||||
np.zeros((0,), dtype=np.float32),
|
||||
np.zeros((0,), dtype=int),
|
||||
targets.class_id,
|
||||
)
|
||||
)
|
||||
|
||||
else:
|
||||
if self._metric_target == MetricTarget.BOXES:
|
||||
iou = box_iou_batch(target_contents, prediction_contents)
|
||||
elif self._metric_target == MetricTarget.MASKS:
|
||||
iou = mask_iou_batch(target_contents, prediction_contents)
|
||||
else:
|
||||
raise NotImplementedError(
|
||||
"Unsupported metric target for IoU calculation"
|
||||
)
|
||||
|
||||
matches = self._match_detection_batch(
|
||||
predictions.class_id, targets.class_id, iou, iou_thresholds
|
||||
)
|
||||
stats.append(
|
||||
(
|
||||
matches,
|
||||
predictions.confidence,
|
||||
predictions.class_id,
|
||||
targets.class_id,
|
||||
)
|
||||
)
|
||||
|
||||
# Compute average precisions if any matches exist
|
||||
if stats:
|
||||
concatenated_stats = [np.concatenate(items, 0) for items in zip(*stats)]
|
||||
average_precisions = self._average_precisions_per_class(*concatenated_stats)
|
||||
map50 = average_precisions[:, 0].mean()
|
||||
map75 = average_precisions[:, 5].mean()
|
||||
map50_95 = average_precisions.mean()
|
||||
else:
|
||||
map50, map75, map50_95 = 0, 0, 0
|
||||
average_precisions = np.empty((0, len(iou_thresholds)), dtype=np.float32)
|
||||
|
||||
return MeanAveragePrecisionResult(
|
||||
iou_thresholds=iou_thresholds,
|
||||
map50_95=map50_95,
|
||||
map50=map50,
|
||||
map75=map75,
|
||||
per_class_ap50_95=average_precisions,
|
||||
metric_target=self._metric_target,
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def compute_average_precision(recall: np.ndarray, precision: np.ndarray) -> float:
|
||||
"""
|
||||
Compute the average precision using 101-point interpolation (COCO), given
|
||||
the recall and precision curves.
|
||||
|
||||
Args:
|
||||
recall (np.ndarray): The recall curve.
|
||||
precision (np.ndarray): The precision curve.
|
||||
|
||||
Returns:
|
||||
(float): Average precision.
|
||||
"""
|
||||
extended_recall = np.concatenate(([0.0], recall, [1.0]))
|
||||
extended_precision = np.concatenate(([1.0], precision, [0.0]))
|
||||
max_accumulated_precision = np.flip(
|
||||
np.maximum.accumulate(np.flip(extended_precision))
|
||||
)
|
||||
interpolated_recall_levels = np.linspace(0, 1, 101)
|
||||
interpolated_precision = np.interp(
|
||||
interpolated_recall_levels, extended_recall, max_accumulated_precision
|
||||
)
|
||||
average_precision = np.trapz(interpolated_precision, interpolated_recall_levels)
|
||||
return average_precision
|
||||
|
||||
@staticmethod
|
||||
def _match_detection_batch(
|
||||
predictions_classes: np.ndarray,
|
||||
target_classes: np.ndarray,
|
||||
iou: np.ndarray,
|
||||
iou_thresholds: np.ndarray,
|
||||
) -> np.ndarray:
|
||||
num_predictions, num_iou_levels = (
|
||||
predictions_classes.shape[0],
|
||||
iou_thresholds.shape[0],
|
||||
)
|
||||
correct = np.zeros((num_predictions, num_iou_levels), dtype=bool)
|
||||
correct_class = target_classes[:, None] == predictions_classes
|
||||
|
||||
for i, iou_level in enumerate(iou_thresholds):
|
||||
matched_indices = np.where((iou >= iou_level) & correct_class)
|
||||
|
||||
if matched_indices[0].shape[0]:
|
||||
combined_indices = np.stack(matched_indices, axis=1)
|
||||
iou_values = iou[matched_indices][:, None]
|
||||
matches = np.hstack([combined_indices, iou_values])
|
||||
|
||||
if matched_indices[0].shape[0] > 1:
|
||||
matches = matches[matches[:, 2].argsort()[::-1]]
|
||||
matches = matches[np.unique(matches[:, 1], return_index=True)[1]]
|
||||
matches = matches[np.unique(matches[:, 0], return_index=True)[1]]
|
||||
|
||||
correct[matches[:, 1].astype(int), i] = True
|
||||
|
||||
return correct
|
||||
|
||||
@staticmethod
|
||||
def _average_precisions_per_class(
|
||||
matches: np.ndarray,
|
||||
prediction_confidence: np.ndarray,
|
||||
prediction_class_ids: np.ndarray,
|
||||
true_class_ids: np.ndarray,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Compute the average precision, given the recall and precision curves.
|
||||
Source: https://github.com/rafaelpadilla/Object-Detection-Metrics.
|
||||
|
||||
Args:
|
||||
matches (np.ndarray): True positives.
|
||||
prediction_confidence (np.ndarray): Objectness value from 0-1.
|
||||
prediction_class_ids (np.ndarray): Predicted object classes.
|
||||
true_class_ids (np.ndarray): True object classes.
|
||||
eps (float, optional): Small value to prevent division by zero.
|
||||
|
||||
Returns:
|
||||
(np.ndarray): Average precision for different IoU levels.
|
||||
"""
|
||||
eps = 1e-16
|
||||
|
||||
sorted_indices = np.argsort(-prediction_confidence)
|
||||
matches = matches[sorted_indices]
|
||||
prediction_class_ids = prediction_class_ids[sorted_indices]
|
||||
|
||||
unique_classes, class_counts = np.unique(true_class_ids, return_counts=True)
|
||||
num_classes = unique_classes.shape[0]
|
||||
|
||||
average_precisions = np.zeros((num_classes, matches.shape[1]))
|
||||
|
||||
for class_idx, class_id in enumerate(unique_classes):
|
||||
is_class = prediction_class_ids == class_id
|
||||
total_true = class_counts[class_idx]
|
||||
total_prediction = is_class.sum()
|
||||
|
||||
if total_prediction == 0 or total_true == 0:
|
||||
continue
|
||||
|
||||
false_positives = (1 - matches[is_class]).cumsum(0)
|
||||
true_positives = matches[is_class].cumsum(0)
|
||||
true_negatives = total_true - true_positives
|
||||
|
||||
recall = true_positives / (true_positives + true_negatives + eps)
|
||||
precision = true_positives / (true_positives + false_positives)
|
||||
|
||||
for iou_level_idx in range(matches.shape[1]):
|
||||
average_precisions[class_idx, iou_level_idx] = (
|
||||
MeanAveragePrecision.compute_average_precision(
|
||||
recall[:, iou_level_idx], precision[:, iou_level_idx]
|
||||
)
|
||||
)
|
||||
|
||||
return average_precisions
|
||||
|
||||
def _detections_content(self, detections: Detections) -> np.ndarray:
|
||||
"""Return boxes, masks or oriented bounding boxes from detections."""
|
||||
if self._metric_target == MetricTarget.BOXES:
|
||||
return detections.xyxy
|
||||
if self._metric_target == MetricTarget.MASKS:
|
||||
return (
|
||||
detections.mask
|
||||
if detections.mask is not None
|
||||
else self._make_empty_content()
|
||||
)
|
||||
if self._metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
if obb := detections.data.get(ORIENTED_BOX_COORDINATES):
|
||||
return np.ndarray(obb, dtype=np.float32)
|
||||
return self._make_empty_content()
|
||||
raise ValueError(f"Invalid metric target: {self._metric_target}")
|
||||
|
||||
def _make_empty_content(self) -> np.ndarray:
|
||||
if self._metric_target == MetricTarget.BOXES:
|
||||
return np.empty((0, 4), dtype=np.float32)
|
||||
if self._metric_target == MetricTarget.MASKS:
|
||||
return np.empty((0, 0, 0), dtype=bool)
|
||||
if self._metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
return np.empty((0, 8), dtype=np.float32)
|
||||
raise ValueError(f"Invalid metric target: {self._metric_target}")
|
||||
|
||||
def _filter_detections_by_size(
|
||||
self, detections: Detections, size_category: ObjectSizeCategory
|
||||
) -> Detections:
|
||||
"""Return a copy of detections with contents filtered by object size."""
|
||||
new_detections = deepcopy(detections)
|
||||
if detections.is_empty() or size_category == ObjectSizeCategory.ANY:
|
||||
return new_detections
|
||||
|
||||
sizes = get_detection_size_category(new_detections, self._metric_target)
|
||||
size_mask = sizes == size_category.value
|
||||
|
||||
new_detections.xyxy = new_detections.xyxy[size_mask]
|
||||
if new_detections.mask is not None:
|
||||
new_detections.mask = new_detections.mask[size_mask]
|
||||
if new_detections.class_id is not None:
|
||||
new_detections.class_id = new_detections.class_id[size_mask]
|
||||
if new_detections.confidence is not None:
|
||||
new_detections.confidence = new_detections.confidence[size_mask]
|
||||
if new_detections.tracker_id is not None:
|
||||
new_detections.tracker_id = new_detections.tracker_id[size_mask]
|
||||
if new_detections.data is not None:
|
||||
for key, value in new_detections.data.items():
|
||||
new_detections.data[key] = np.array(value)[size_mask]
|
||||
|
||||
return new_detections
|
||||
|
||||
|
||||
@dataclass
|
||||
class MeanAveragePrecisionResult:
|
||||
iou_thresholds: np.ndarray
|
||||
"""Array of IoU thresholds used in the calculations"""
|
||||
map50_95: float
|
||||
"""Mean Average Precision over IoU thresholds from 0.5 to 0.95"""
|
||||
|
||||
map50: float
|
||||
"""Mean Average Precision at IoU threshold of 0.5"""
|
||||
|
||||
map75: float
|
||||
"""Mean Average Precision at IoU threshold of 0.75"""
|
||||
|
||||
per_class_ap50_95: np.ndarray
|
||||
"""Average precision for each class at different IoU thresholds"""
|
||||
|
||||
metric_target: MetricTarget
|
||||
"""
|
||||
Defines the type of data used for the metric - boxes, masks or
|
||||
oriented bounding boxes.
|
||||
"""
|
||||
|
||||
small_objects: Optional[MeanAveragePrecisionResult] = None
|
||||
"""Mean Average Precision results for small objects"""
|
||||
|
||||
medium_objects: Optional[MeanAveragePrecisionResult] = None
|
||||
"""Mean Average Precision results for medium objects"""
|
||||
|
||||
large_objects: Optional[MeanAveragePrecisionResult] = None
|
||||
"""Mean Average Precision results for large objects"""
|
||||
|
||||
def __str__(self) -> str:
|
||||
"""
|
||||
Format the mAP results as a pretty string.
|
||||
|
||||
Example:
|
||||
```python
|
||||
print(map_result)
|
||||
```
|
||||
"""
|
||||
|
||||
out_str = (
|
||||
f"{self.__class__.__name__}:\n"
|
||||
f"iou_thresholds: {self.iou_thresholds}\n"
|
||||
f"map50_95: {self.map50_95:.4f}\n"
|
||||
f"map50: {self.map50:.4f}\n"
|
||||
f"map75: {self.map75:.4f}\n"
|
||||
f"per_class_ap50_95:"
|
||||
)
|
||||
|
||||
for class_id, ap in enumerate(self.per_class_ap50_95):
|
||||
out_str += f"\n {class_id}: {ap}"
|
||||
|
||||
indent = " "
|
||||
if self.small_objects is not None:
|
||||
indented_str = indent + str(self.small_objects).replace("\n", f"\n{indent}")
|
||||
out_str += f"\nSmall objects:\n{indented_str}"
|
||||
if self.medium_objects is not None:
|
||||
indented_str = indent + str(self.medium_objects).replace(
|
||||
"\n", f"\n{indent}"
|
||||
)
|
||||
out_str += f"\nMedium objects:\n{indented_str}"
|
||||
if self.large_objects is not None:
|
||||
indented_str = indent + str(self.large_objects).replace("\n", f"\n{indent}")
|
||||
out_str += f"\nLarge objects:\n{indented_str}"
|
||||
|
||||
return out_str
|
||||
|
||||
def to_pandas(self) -> "pd.DataFrame":
|
||||
"""
|
||||
Convert the result to a pandas DataFrame.
|
||||
|
||||
Returns:
|
||||
(pd.DataFrame): The result as a DataFrame.
|
||||
"""
|
||||
ensure_pandas_installed()
|
||||
import pandas as pd
|
||||
|
||||
pandas_data = {
|
||||
"mAP_50_95": self.map50_95,
|
||||
"mAP_50": self.map50,
|
||||
"mAP_75": self.map75,
|
||||
}
|
||||
if self.small_objects is not None:
|
||||
small_objects_df = self.small_objects.to_pandas()
|
||||
for key, value in small_objects_df.items():
|
||||
pandas_data[f"small_objects_{key}"] = value
|
||||
if self.medium_objects is not None:
|
||||
medium_objects_df = self.medium_objects.to_pandas()
|
||||
for key, value in medium_objects_df.items():
|
||||
pandas_data[f"medium_objects_{key}"] = value
|
||||
if self.large_objects is not None:
|
||||
large_objects_df = self.large_objects.to_pandas()
|
||||
for key, value in large_objects_df.items():
|
||||
pandas_data[f"large_objects_{key}"] = value
|
||||
|
||||
# Average precisions are currently not included in the DataFrame.
|
||||
|
||||
return pd.DataFrame(
|
||||
pandas_data,
|
||||
index=[0],
|
||||
)
|
||||
|
||||
def plot(self):
|
||||
"""
|
||||
Plot the mAP results.
|
||||
"""
|
||||
|
||||
labels = ["mAP_50_95", "mAP_50", "mAP_75"]
|
||||
values = [self.map50_95, self.map50, self.map75]
|
||||
colors = [LEGACY_COLOR_PALETTE[0]] * 3
|
||||
|
||||
if self.small_objects is not None:
|
||||
labels += [
|
||||
"small_objects_mAP_50_95",
|
||||
"small_objects_mAP_50",
|
||||
"small_objects_mAP_75",
|
||||
]
|
||||
values += [
|
||||
self.small_objects.map50_95,
|
||||
self.small_objects.map50,
|
||||
self.small_objects.map75,
|
||||
]
|
||||
colors += [LEGACY_COLOR_PALETTE[3]] * 3
|
||||
|
||||
if self.medium_objects is not None:
|
||||
labels += [
|
||||
"medium_objects_mAP_50_95",
|
||||
"medium_objects_mAP_50",
|
||||
"medium_objects_mAP_75",
|
||||
]
|
||||
values += [
|
||||
self.medium_objects.map50_95,
|
||||
self.medium_objects.map50,
|
||||
self.medium_objects.map75,
|
||||
]
|
||||
colors += [LEGACY_COLOR_PALETTE[2]] * 3
|
||||
|
||||
if self.large_objects is not None:
|
||||
labels += [
|
||||
"large_objects_mAP_50_95",
|
||||
"large_objects_mAP_50",
|
||||
"large_objects_mAP_75",
|
||||
]
|
||||
values += [
|
||||
self.large_objects.map50_95,
|
||||
self.large_objects.map50,
|
||||
self.large_objects.map75,
|
||||
]
|
||||
colors += [LEGACY_COLOR_PALETTE[4]] * 3
|
||||
|
||||
plt.rcParams["font.family"] = "monospace"
|
||||
|
||||
_, ax = plt.subplots(figsize=(10, 6))
|
||||
ax.set_ylim(0, 1)
|
||||
ax.set_ylabel("Value", fontweight="bold")
|
||||
ax.set_title("Mean Average Precision", fontweight="bold")
|
||||
|
||||
x_positions = range(len(labels))
|
||||
bars = ax.bar(x_positions, values, color=colors, align="center")
|
||||
|
||||
ax.set_xticks(x_positions)
|
||||
ax.set_xticklabels(labels, rotation=45, ha="right")
|
||||
|
||||
for bar in bars:
|
||||
y_value = bar.get_height()
|
||||
ax.text(
|
||||
bar.get_x() + bar.get_width() / 2,
|
||||
y_value + 0.02,
|
||||
f"{y_value:.2f}",
|
||||
ha="center",
|
||||
va="bottom",
|
||||
)
|
||||
|
||||
plt.rcParams["font.family"] = "sans-serif"
|
||||
|
||||
plt.tight_layout()
|
||||
plt.show()
|
||||
@@ -0,0 +1,300 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import TYPE_CHECKING, List, Optional, Set, Tuple
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.metrics.core import CLASS_ID_NONE, MetricTarget
|
||||
from supervision.metrics.utils.object_size import (
|
||||
ObjectSizeCategory,
|
||||
get_object_size_category,
|
||||
)
|
||||
from supervision.metrics.utils.utils import unify_pad_masks_shape
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from supervision.detection.core import Detections
|
||||
|
||||
|
||||
class MetricData:
|
||||
"""
|
||||
A container for detection contents, decouple from `Detections`.
|
||||
"""
|
||||
|
||||
def __init__(self, metric_target: MetricTarget, class_agnostic: bool = False):
|
||||
self._metric_target = metric_target
|
||||
self._class_agnostic = class_agnostic
|
||||
self._content_list: List[npt.NDArray] = []
|
||||
self._confidence_list: List[npt.NDArray[np.float32]] = []
|
||||
self._class_id_list: List[npt.NDArray[np.int_]] = []
|
||||
|
||||
def update(self, detections: Detections):
|
||||
"""Add new detections to the store."""
|
||||
if detections.is_empty() or len(detections) == 0:
|
||||
return
|
||||
|
||||
# Relies on Detections to ensure that member vars are equal in length
|
||||
# or None/empty.
|
||||
self._validate_new_entry(detections)
|
||||
|
||||
new_content = self._detections_content(detections)
|
||||
self._validate_shape(new_content)
|
||||
self._content_list.append(new_content)
|
||||
|
||||
if detections.confidence is not None:
|
||||
self._confidence_list.append(detections.confidence)
|
||||
|
||||
if detections.class_id is not None:
|
||||
if self._class_agnostic:
|
||||
self._class_id_list.append(
|
||||
np.full(len(detections.class_id), CLASS_ID_NONE, dtype=int)
|
||||
)
|
||||
else:
|
||||
self._class_id_list.append(detections.class_id)
|
||||
|
||||
def get_classes(self) -> Set[int]:
|
||||
"""Return all class IDs."""
|
||||
if self._class_agnostic:
|
||||
return {CLASS_ID_NONE}
|
||||
return set.union(*[set(class_id) for class_id in self._class_id_list])
|
||||
|
||||
def get(
|
||||
self, class_id: Optional[int] = None, size_category=ObjectSizeCategory.ANY
|
||||
) -> Tuple[npt.NDArray, npt.NDArray, npt.NDArray]:
|
||||
"""
|
||||
Get the contents, class_ids and confidences, optionally filtered by
|
||||
class_id and/or size.
|
||||
|
||||
Args:
|
||||
class_id (Optional[int]): The class ID for the data to retrieve
|
||||
size_category (ObjectSizeCategory): The size of the objects to retrieve.
|
||||
|
||||
Returns:
|
||||
(np.ndarray): Boxes, masks or obb, all stacked in a single array.
|
||||
"""
|
||||
if self._metric_target in [
|
||||
MetricTarget.BOXES,
|
||||
MetricTarget.ORIENTED_BOUNDING_BOXES,
|
||||
]:
|
||||
self._merge_boxes()
|
||||
if len(self._content_list) == 0:
|
||||
content = self._make_empty_content()
|
||||
else:
|
||||
content = self._content_list[0]
|
||||
|
||||
elif self._metric_target == MetricTarget.MASKS:
|
||||
self._merge_masks()
|
||||
if len(self._content_list) == 0:
|
||||
content = self._make_empty_content()
|
||||
else:
|
||||
content = self._content_list[0]
|
||||
|
||||
size_mask = np.full(len(content), True)
|
||||
if size_category != ObjectSizeCategory.ANY:
|
||||
sizes = get_object_size_category(content, self._metric_target)
|
||||
size_mask = sizes == size_category.value
|
||||
|
||||
class_mask = np.full(len(content), True)
|
||||
if class_id is not None:
|
||||
self._merge_class_id()
|
||||
class_ids = self._class_id_list[0]
|
||||
class_mask = class_ids == class_id
|
||||
|
||||
content = content[(size_mask & class_mask)]
|
||||
|
||||
self._merge_class_id()
|
||||
if len(self._class_id_list) == 0:
|
||||
class_ids = np.array([], dtype=int)
|
||||
else:
|
||||
class_ids = self._class_id_list[0]
|
||||
if len(class_ids) > 0:
|
||||
class_ids = class_ids[(size_mask & class_mask)]
|
||||
|
||||
self._merge_confidence()
|
||||
if len(self._confidence_list) == 0:
|
||||
confidences = np.array([], dtype=float)
|
||||
else:
|
||||
confidences = self._confidence_list[0]
|
||||
if len(confidences) > 0:
|
||||
confidences = confidences[(size_mask & class_mask)]
|
||||
|
||||
return content, class_ids, confidences
|
||||
|
||||
def get_class_id(self) -> npt.NDArray[np.int_]:
|
||||
self._merge_class_id()
|
||||
if len(self._class_id_list) == 0:
|
||||
return np.array([], dtype=int)
|
||||
return self._class_id_list[0]
|
||||
|
||||
def get_confidence(self) -> npt.NDArray[np.float32]:
|
||||
self._merge_confidence()
|
||||
if len(self._confidence_list) == 0:
|
||||
return np.array([], dtype=float)
|
||||
return self._confidence_list[0]
|
||||
|
||||
def _detections_content(self, detections: Detections) -> npt.NDArray:
|
||||
"""Return boxes, masks or oriented bounding boxes from detections."""
|
||||
if self._metric_target == MetricTarget.BOXES:
|
||||
return detections.xyxy
|
||||
if self._metric_target == MetricTarget.MASKS:
|
||||
return (
|
||||
detections.mask
|
||||
if detections.mask is not None
|
||||
else self._make_empty_content()
|
||||
)
|
||||
if self._metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
if obb := detections.data.get(ORIENTED_BOX_COORDINATES):
|
||||
return np.ndarray(obb, dtype=np.float32)
|
||||
return self._make_empty_content()
|
||||
raise ValueError(f"Invalid metric target: {self._metric_target}")
|
||||
|
||||
def _make_empty_content(self) -> npt.NDArray:
|
||||
if self._metric_target == MetricTarget.BOXES:
|
||||
return np.empty((0, 4), dtype=np.float32)
|
||||
if self._metric_target == MetricTarget.MASKS:
|
||||
return np.empty((0, 0, 0), dtype=bool)
|
||||
if self._metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
return np.empty((0, 8), dtype=np.float32)
|
||||
raise ValueError(f"Invalid metric target: {self._metric_target}")
|
||||
|
||||
def _validate_new_entry(self, detections: Detections) -> None:
|
||||
if (
|
||||
len(self._content_list) == 0
|
||||
or detections.is_empty()
|
||||
or len(detections) == 0
|
||||
):
|
||||
return
|
||||
|
||||
is_self_class_empty = len(self._class_id_list) == 0
|
||||
is_self_confidence_empty = len(self._confidence_list) == 0
|
||||
is_detection_class_empty = (
|
||||
detections.class_id is None or len(detections.class_id) == 0
|
||||
)
|
||||
is_detection_confidence_empty = (
|
||||
detections.confidence is None or len(detections.confidence) == 0
|
||||
)
|
||||
|
||||
if is_self_confidence_empty and not is_detection_confidence_empty:
|
||||
raise ValueError(
|
||||
"Previously stored detections without confidence,"
|
||||
" but new detections have it."
|
||||
)
|
||||
if is_self_class_empty and not is_detection_class_empty:
|
||||
raise ValueError(
|
||||
"Previously stored detections without class ID,"
|
||||
" but new detections have it."
|
||||
)
|
||||
if not is_self_class_empty and is_detection_class_empty:
|
||||
raise ValueError(
|
||||
"Started storing detections with class ID, but"
|
||||
" new detections do not have it."
|
||||
)
|
||||
if not is_self_confidence_empty and is_detection_confidence_empty:
|
||||
raise ValueError(
|
||||
"Started storing detections with confidence,"
|
||||
" but new detections do not have it."
|
||||
)
|
||||
|
||||
def _validate_shape(self, data: npt.NDArray) -> None:
|
||||
if self._metric_target == MetricTarget.BOXES:
|
||||
if len(data.shape) != 2 or data.shape[1] != 4:
|
||||
raise ValueError(f"Invalid xyxy shape: {data.shape}. Expected: (N, 4)")
|
||||
elif self._metric_target == MetricTarget.MASKS:
|
||||
if len(data.shape) != 3:
|
||||
raise ValueError(
|
||||
f"Invalid mask shape: {data.shape}. Expected: (N, H, W)"
|
||||
)
|
||||
elif self._metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
if len(data.shape) != 2 or data.shape[1] != 8:
|
||||
raise ValueError(f"Invalid obb shape: {data.shape}. Expected: (N, 8)")
|
||||
else:
|
||||
raise ValueError(f"Invalid metric target: {self._metric_target}")
|
||||
|
||||
def _merge_boxes(self):
|
||||
"""Merge all boxes into a single array."""
|
||||
if self._metric_target not in (
|
||||
MetricTarget.BOXES,
|
||||
MetricTarget.ORIENTED_BOUNDING_BOXES,
|
||||
):
|
||||
raise ValueError("Invalid metric target for merging boxes")
|
||||
if len(self._content_list) < 2:
|
||||
return
|
||||
self._content_list = [np.vstack(self._content_list)]
|
||||
|
||||
def _merge_masks(self):
|
||||
"""Merge all masks into a single array."""
|
||||
if self._metric_target != MetricTarget.MASKS:
|
||||
raise ValueError("Invalid metric target for merging masks")
|
||||
if len(self._content_list) < 2:
|
||||
return
|
||||
|
||||
mew_mask_list = unify_pad_masks_shape(*self._content_list)
|
||||
self._content_list = [np.vstack(mew_mask_list)]
|
||||
|
||||
def _merge_class_id(self):
|
||||
"""Merge all class IDs into a single array."""
|
||||
if len(self._class_id_list) < 2:
|
||||
return
|
||||
self._class_id_list = [np.hstack(self._class_id_list)]
|
||||
|
||||
def _merge_confidence(self):
|
||||
"""Merge all confidences into a single array."""
|
||||
if len(self._confidence_list) < 2:
|
||||
return
|
||||
self._confidence_list = [np.hstack(self._confidence_list)]
|
||||
|
||||
|
||||
class MetricDataStore:
|
||||
"""
|
||||
Stores internal data for metrics.
|
||||
|
||||
Provides a class-agnostic way to access it.
|
||||
"""
|
||||
|
||||
def __init__(self, metric_target: MetricTarget, class_agnostic: bool = False):
|
||||
self._metric_target = metric_target
|
||||
self._class_agnostic = class_agnostic
|
||||
self._data_1: MetricData
|
||||
self._data_2: MetricData
|
||||
self.reset()
|
||||
|
||||
def reset(self) -> None:
|
||||
self._data_1 = MetricData(self._metric_target, self._class_agnostic)
|
||||
self._data_2 = MetricData(self._metric_target, self._class_agnostic)
|
||||
|
||||
def update(self, data_1: Detections, data_2: Detections) -> None:
|
||||
"""
|
||||
Add new data to the store.
|
||||
|
||||
Use sv.Detections.empty() if only one set of data is available.
|
||||
"""
|
||||
self._data_1.update(data_1)
|
||||
self._data_2.update(data_2)
|
||||
|
||||
def get(
|
||||
self,
|
||||
class_id: Optional[int] = None,
|
||||
size_category: ObjectSizeCategory = ObjectSizeCategory.ANY,
|
||||
) -> Tuple[
|
||||
Tuple[npt.NDArray, npt.NDArray, npt.NDArray],
|
||||
Tuple[npt.NDArray, npt.NDArray, npt.NDArray],
|
||||
]:
|
||||
"""
|
||||
Get the data for both sets, optionally filtered by class_id and/or size.
|
||||
"""
|
||||
|
||||
data_1, class_id_1, confidence_1 = self._data_1.get(class_id, size_category)
|
||||
data_2, class_id_2, confidence_2 = self._data_2.get(class_id, size_category)
|
||||
|
||||
if self._metric_target == MetricTarget.MASKS:
|
||||
data_1, data_2 = unify_pad_masks_shape(data_1, data_2)
|
||||
|
||||
return (
|
||||
(data_1, class_id_1, confidence_1),
|
||||
(data_2, class_id_2, confidence_2),
|
||||
)
|
||||
|
||||
def get_classes(self) -> Set[int]:
|
||||
"""Return all class IDs."""
|
||||
return self._data_1.get_classes() | self._data_2.get_classes()
|
||||
@@ -0,0 +1,155 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from enum import Enum
|
||||
from typing import TYPE_CHECKING
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.metrics.core import MetricTarget
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from supervision.detection.core import Detections
|
||||
|
||||
SIZE_THRESHOLDS = (32**2, 96**2)
|
||||
|
||||
|
||||
class ObjectSizeCategory(Enum):
|
||||
ANY = -1
|
||||
SMALL = 1
|
||||
MEDIUM = 2
|
||||
LARGE = 3
|
||||
|
||||
|
||||
def get_object_size_category(
|
||||
data: npt.NDArray, metric_target: MetricTarget
|
||||
) -> npt.NDArray[np.int_]:
|
||||
"""
|
||||
Get the size category of an object. Distinguish based on the metric target.
|
||||
|
||||
Args:
|
||||
data (np.ndarray): The object data, shaped (N, ...).
|
||||
metric_target (MetricTarget): Determines whether boxes, masks or
|
||||
oriented bounding boxes are used.
|
||||
|
||||
Returns:
|
||||
(np.ndarray) The size category of each object, matching
|
||||
the enum values of ObjectSizeCategory. Shaped (N,).
|
||||
"""
|
||||
if metric_target == MetricTarget.BOXES:
|
||||
return get_bbox_size_category(data)
|
||||
if metric_target == MetricTarget.MASKS:
|
||||
return get_mask_size_category(data)
|
||||
if metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
return get_obb_size_category(data)
|
||||
raise ValueError("Invalid metric type")
|
||||
|
||||
|
||||
def get_bbox_size_category(xyxy: npt.NDArray[np.float32]) -> npt.NDArray[np.int_]:
|
||||
"""
|
||||
Get the size category of a bounding boxes array.
|
||||
|
||||
Args:
|
||||
xyxy (np.ndarray): The bounding boxes array shaped (N, 4).
|
||||
|
||||
Returns:
|
||||
(np.ndarray) The size category of each bounding box, matching
|
||||
the enum values of ObjectSizeCategory. Shaped (N,).
|
||||
"""
|
||||
if len(xyxy.shape) != 2 or xyxy.shape[1] != 4:
|
||||
raise ValueError("Bounding boxes must be shaped (N, 4)")
|
||||
|
||||
width = xyxy[:, 2] - xyxy[:, 0]
|
||||
height = xyxy[:, 3] - xyxy[:, 1]
|
||||
areas = width * height
|
||||
|
||||
result = np.full(areas.shape, ObjectSizeCategory.ANY.value)
|
||||
SM, LG = SIZE_THRESHOLDS
|
||||
result[areas < SM] = ObjectSizeCategory.SMALL.value
|
||||
result[(areas >= SM) & (areas < LG)] = ObjectSizeCategory.MEDIUM.value
|
||||
result[areas >= LG] = ObjectSizeCategory.LARGE.value
|
||||
return result
|
||||
|
||||
|
||||
def get_mask_size_category(mask: npt.NDArray[np.bool_]) -> npt.NDArray[np.int_]:
|
||||
"""
|
||||
Get the size category of detection masks.
|
||||
|
||||
Args:
|
||||
mask (np.ndarray): The mask array shaped (N, H, W).
|
||||
|
||||
Returns:
|
||||
(np.ndarray) The size category of each mask, matching
|
||||
the enum values of ObjectSizeCategory. Shaped (N,).
|
||||
"""
|
||||
if len(mask.shape) != 3:
|
||||
raise ValueError("Masks must be shaped (N, H, W)")
|
||||
|
||||
areas = np.sum(mask, axis=(1, 2))
|
||||
|
||||
result = np.full(areas.shape, ObjectSizeCategory.ANY.value)
|
||||
SM, LG = SIZE_THRESHOLDS
|
||||
result[areas < SM] = ObjectSizeCategory.SMALL.value
|
||||
result[(areas >= SM) & (areas < LG)] = ObjectSizeCategory.MEDIUM.value
|
||||
result[areas >= LG] = ObjectSizeCategory.LARGE.value
|
||||
return result
|
||||
|
||||
|
||||
def get_obb_size_category(xyxyxyxy: npt.NDArray[np.float32]) -> npt.NDArray[np.int_]:
|
||||
"""
|
||||
Get the size category of a oriented bounding boxes array.
|
||||
|
||||
Args:
|
||||
xyxyxyxy (np.ndarray): The bounding boxes array shaped (N, 8).
|
||||
|
||||
Returns:
|
||||
(np.ndarray) The size category of each bounding box, matching
|
||||
the enum values of ObjectSizeCategory. Shaped (N,).
|
||||
"""
|
||||
if len(xyxyxyxy.shape) != 2 or xyxyxyxy.shape[1] != 8:
|
||||
raise ValueError("Oriented bounding boxes must be shaped (N, 8)")
|
||||
|
||||
# Shoelace formula
|
||||
x1, y1, x2, y2, x3, y3, x4, y4 = xyxyxyxy.T
|
||||
areas = 0.5 * np.abs(
|
||||
(x1 * y2 + x2 * y3 + x3 * y4 + x4 * y1)
|
||||
- (x2 * y1 + x3 * y2 + x4 * y3 + x1 * y4)
|
||||
)
|
||||
|
||||
result = np.full(areas.shape, ObjectSizeCategory.ANY.value)
|
||||
SM, LG = SIZE_THRESHOLDS
|
||||
result[areas < SM] = ObjectSizeCategory.SMALL.value
|
||||
result[(areas >= SM) & (areas < LG)] = ObjectSizeCategory.MEDIUM.value
|
||||
result[areas >= LG] = ObjectSizeCategory.LARGE.value
|
||||
return result
|
||||
|
||||
|
||||
def get_detection_size_category(
|
||||
detections: Detections, metric_target: MetricTarget = MetricTarget.BOXES
|
||||
) -> npt.NDArray[np.int_]:
|
||||
"""
|
||||
Get the size category of a detections object.
|
||||
|
||||
Args:
|
||||
xyxyxyxy (np.ndarray): The bounding boxes array shaped (N, 8).
|
||||
metric_target (MetricTarget): Determines whether boxes, masks or
|
||||
oriented bounding boxes are used.
|
||||
|
||||
Returns:
|
||||
(np.ndarray) The size category of each bounding box, matching
|
||||
the enum values of ObjectSizeCategory. Shaped (N,).
|
||||
"""
|
||||
if metric_target == MetricTarget.BOXES:
|
||||
return get_bbox_size_category(detections.xyxy)
|
||||
if metric_target == MetricTarget.MASKS:
|
||||
if detections.mask is None:
|
||||
raise ValueError("Detections mask is not available")
|
||||
return get_mask_size_category(detections.mask)
|
||||
if metric_target == MetricTarget.ORIENTED_BOUNDING_BOXES:
|
||||
if detections.data.get(ORIENTED_BOX_COORDINATES) is None:
|
||||
raise ValueError("Detections oriented bounding boxes are not available")
|
||||
return get_obb_size_category(
|
||||
np.array(detections.data[ORIENTED_BOX_COORDINATES])
|
||||
)
|
||||
raise ValueError("Invalid metric type")
|
||||
@@ -0,0 +1,70 @@
|
||||
from typing import List, Tuple
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
|
||||
def ensure_pandas_installed():
|
||||
try:
|
||||
import pandas # noqa
|
||||
except ImportError:
|
||||
raise ImportError(
|
||||
"`metrics` extra is required to run the function."
|
||||
" Run `pip install 'supervision[metrics]'` or"
|
||||
" `poetry add supervision -E metrics`"
|
||||
)
|
||||
|
||||
|
||||
def pad_mask(mask: npt.NDArray, new_shape: Tuple[int, int]) -> npt.NDArray:
|
||||
"""Pad a mask to a new shape, inserting zeros on the right and bottom."""
|
||||
if len(mask.shape) != 3:
|
||||
raise ValueError(f"Invalid mask shape: {mask.shape}. Expected: (N, H, W)")
|
||||
|
||||
new_mask = np.pad(
|
||||
mask,
|
||||
(
|
||||
(0, 0),
|
||||
(0, new_shape[0] - mask.shape[1]),
|
||||
(0, new_shape[1] - mask.shape[2]),
|
||||
),
|
||||
mode="constant",
|
||||
constant_values=0,
|
||||
)
|
||||
|
||||
return new_mask
|
||||
|
||||
|
||||
def unify_pad_masks_shape(
|
||||
*masks: npt.NDArray[np.bool_],
|
||||
) -> List[npt.NDArray[np.bool_]]:
|
||||
"""
|
||||
Given any number of (N, H, W) mask objects, return copies of the
|
||||
same (H, W), padded to the largest dimensions.
|
||||
|
||||
Args:
|
||||
*masks (np.ndarray): The mask arrays to unify. Each shaped (_, H, W),
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: The masks, padded to the largest dimensions.
|
||||
Each list element shaped (_, H_max, W_max)
|
||||
"""
|
||||
new_h = 0
|
||||
new_w = 0
|
||||
for mask in masks:
|
||||
if len(mask.shape) != 3:
|
||||
raise ValueError(f"Invalid mask shape: {mask.shape}. Expected: (N, H, W)")
|
||||
|
||||
_, h, w = mask.shape
|
||||
new_h = max(new_h, h)
|
||||
new_w = max(new_w, w)
|
||||
|
||||
results = []
|
||||
for mask in masks:
|
||||
results.append(pad_mask(mask, (new_h, new_w)))
|
||||
|
||||
return results
|
||||
|
||||
|
||||
def len0_like(data: npt.NDArray) -> npt.NDArray:
|
||||
"""Create an empty array with the same shape as input, but with 0 rows."""
|
||||
return np.empty((0, *data.shape[1:]), dtype=data.dtype)
|
||||
@@ -7,7 +7,6 @@ from supervision.detection.utils import box_iou_batch
|
||||
from supervision.tracker.byte_tracker import matching
|
||||
from supervision.tracker.byte_tracker.basetrack import BaseTrack, TrackState
|
||||
from supervision.tracker.byte_tracker.kalman_filter import KalmanFilter
|
||||
from supervision.utils.internal import deprecated_parameter
|
||||
|
||||
|
||||
class STrack(BaseTrack):
|
||||
@@ -197,48 +196,24 @@ class ByteTrack:
|
||||
</video>
|
||||
|
||||
Parameters:
|
||||
track_activation_threshold (float, optional): Detection confidence threshold
|
||||
track_activation_threshold (float): Detection confidence threshold
|
||||
for track activation. Increasing track_activation_threshold improves accuracy
|
||||
and stability but might miss true detections. Decreasing it increases
|
||||
completeness but risks introducing noise and instability.
|
||||
lost_track_buffer (int, optional): Number of frames to buffer when a track is lost.
|
||||
lost_track_buffer (int): Number of frames to buffer when a track is lost.
|
||||
Increasing lost_track_buffer enhances occlusion handling, significantly
|
||||
reducing the likelihood of track fragmentation or disappearance caused
|
||||
by brief detection gaps.
|
||||
minimum_matching_threshold (float, optional): Threshold for matching tracks with detections.
|
||||
minimum_matching_threshold (float): Threshold for matching tracks with detections.
|
||||
Increasing minimum_matching_threshold improves accuracy but risks fragmentation.
|
||||
Decreasing it improves completeness but risks false positives and drift.
|
||||
frame_rate (int, optional): The frame rate of the video.
|
||||
minimum_consecutive_frames (int, optional): Number of consecutive frames that an object must
|
||||
frame_rate (int): The frame rate of the video.
|
||||
minimum_consecutive_frames (int): Number of consecutive frames that an object must
|
||||
be tracked before it is considered a 'valid' track.
|
||||
Increasing minimum_consecutive_frames prevents the creation of accidental tracks from
|
||||
false detection or double detection, but risks missing shorter tracks.
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
@deprecated_parameter(
|
||||
old_parameter="track_buffer",
|
||||
new_parameter="lost_track_buffer",
|
||||
map_function=lambda x: x,
|
||||
warning_message="`{old_parameter}` in `{function_name}` is deprecated and will "
|
||||
"be remove in `supervision-0.23.0`. Use '{new_parameter}' "
|
||||
"instead.",
|
||||
)
|
||||
@deprecated_parameter(
|
||||
old_parameter="track_thresh",
|
||||
new_parameter="track_activation_threshold",
|
||||
map_function=lambda x: x,
|
||||
warning_message="`{old_parameter}` in `{function_name}` is deprecated and will "
|
||||
"be remove in `supervision-0.23.0`. Use '{new_parameter}' "
|
||||
"instead.",
|
||||
)
|
||||
@deprecated_parameter(
|
||||
old_parameter="match_thresh",
|
||||
new_parameter="minimum_matching_threshold",
|
||||
map_function=lambda x: x,
|
||||
warning_message="`{old_parameter}` in `{function_name}` is deprecated and will "
|
||||
"be remove in `supervision-0.23.0`. Use '{new_parameter}' "
|
||||
"instead.",
|
||||
)
|
||||
def __init__(
|
||||
self,
|
||||
track_activation_threshold: float = 0.25,
|
||||
|
||||
@@ -158,7 +158,7 @@ def resize_image(
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
resolution_wh (Tuple[int, int]): The target resolution as
|
||||
`(width, height)`.
|
||||
keep_aspect_ratio (bool, optional): Flag to maintain the image's original
|
||||
keep_aspect_ratio (bool): Flag to maintain the image's original
|
||||
aspect ratio. Defaults to `False`.
|
||||
|
||||
Returns:
|
||||
@@ -270,6 +270,7 @@ def letterbox_image(
|
||||
|
||||
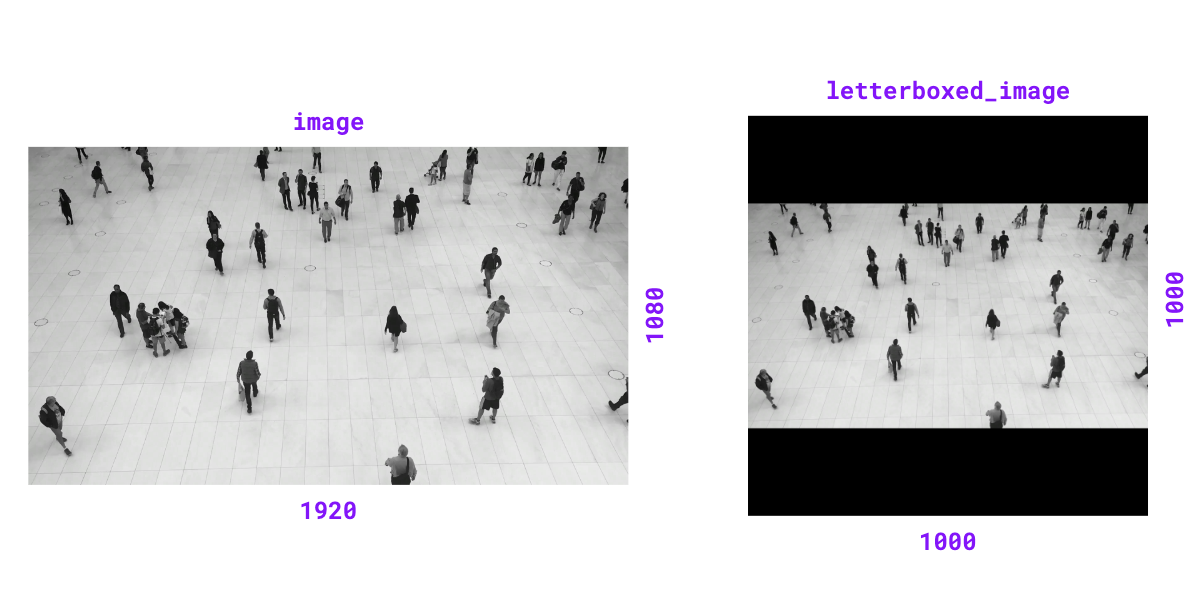{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
assert isinstance(image, np.ndarray)
|
||||
color = unify_to_bgr(color=color)
|
||||
resized_image = resize_image(
|
||||
image=image, resolution_wh=resolution_wh, keep_aspect_ratio=True
|
||||
@@ -279,7 +280,7 @@ def letterbox_image(
|
||||
padding_bottom = resolution_wh[1] - height_new - padding_top
|
||||
padding_left = (resolution_wh[0] - width_new) // 2
|
||||
padding_right = resolution_wh[0] - width_new - padding_left
|
||||
return cv2.copyMakeBorder(
|
||||
image_with_borders = cv2.copyMakeBorder(
|
||||
resized_image,
|
||||
padding_top,
|
||||
padding_bottom,
|
||||
@@ -289,6 +290,14 @@ def letterbox_image(
|
||||
value=color,
|
||||
)
|
||||
|
||||
if image.shape[2] == 4:
|
||||
image[:padding_top, :, 3] = 0
|
||||
image[height_new - padding_bottom :, :, 3] = 0
|
||||
image[:, :padding_left, 3] = 0
|
||||
image[:, width_new - padding_right :, 3] = 0
|
||||
|
||||
return image_with_borders
|
||||
|
||||
|
||||
def overlay_image(
|
||||
image: npt.NDArray[np.uint8],
|
||||
@@ -341,9 +350,20 @@ def overlay_image(
|
||||
crop_x_max = image_width - max((anchor_x + image_width) - scene_width, 0)
|
||||
crop_y_max = image_height - max((anchor_y + image_height) - scene_height, 0)
|
||||
|
||||
image[y_min:y_max, x_min:x_max] = overlay[
|
||||
crop_y_min:crop_y_max, crop_x_min:crop_x_max
|
||||
]
|
||||
if overlay.shape[2] == 4:
|
||||
b, g, r, alpha = cv2.split(
|
||||
overlay[crop_y_min:crop_y_max, crop_x_min:crop_x_max]
|
||||
)
|
||||
alpha = alpha[:, :, None] / 255.0
|
||||
overlay_color = cv2.merge((b, g, r))
|
||||
|
||||
roi = image[y_min:y_max, x_min:x_max]
|
||||
roi[:] = roi * (1 - alpha) + overlay_color * alpha
|
||||
image[y_min:y_max, x_min:x_max] = roi
|
||||
else:
|
||||
image[y_min:y_max, x_min:x_max] = overlay[
|
||||
crop_y_min:crop_y_max, crop_x_min:crop_x_max
|
||||
]
|
||||
|
||||
return image
|
||||
|
||||
@@ -360,9 +380,9 @@ class ImageSink:
|
||||
|
||||
Args:
|
||||
target_dir_path (str): The target directory where images will be saved.
|
||||
overwrite (bool, optional): Whether to overwrite the existing directory.
|
||||
overwrite (bool): Whether to overwrite the existing directory.
|
||||
Defaults to False.
|
||||
image_name_pattern (str, optional): The image file name pattern.
|
||||
image_name_pattern (str): The image file name pattern.
|
||||
Defaults to "image_{:05d}.png".
|
||||
|
||||
Examples:
|
||||
@@ -399,7 +419,7 @@ class ImageSink:
|
||||
Args:
|
||||
image (np.ndarray): The image to be saved. The image must be in BGR color
|
||||
format.
|
||||
image_name (str, optional): The name to use for the saved image.
|
||||
image_name (Optional[str]): The name to use for the saved image.
|
||||
If not provided, a name will be
|
||||
generated using the `image_name_pattern`.
|
||||
"""
|
||||
|
||||
@@ -2,7 +2,7 @@ import functools
|
||||
import inspect
|
||||
import os
|
||||
import warnings
|
||||
from typing import Any, Callable, Set
|
||||
from typing import Any, Callable, Generic, Optional, Set, TypeVar
|
||||
|
||||
|
||||
class SupervisionWarnings(Warning):
|
||||
@@ -56,9 +56,9 @@ def deprecated_parameter(
|
||||
Parameters:
|
||||
old_parameter (str): The name of the deprecated parameter.
|
||||
new_parameter (str): The name of the parameter that should be used instead.
|
||||
map_function (Callable, optional): A function used to map the value of the old
|
||||
map_function (Callable): A function used to map the value of the old
|
||||
parameter to the new parameter. Defaults to the identity function.
|
||||
warning_message (str, optional): The warning message to be displayed when the
|
||||
warning_message (str): The warning message to be displayed when the
|
||||
deprecated parameter is used. Defaults to a generic warning message with
|
||||
placeholders for the old parameter, new parameter, and function name.
|
||||
**message_kwargs: Additional keyword arguments that can be used to customize
|
||||
@@ -122,7 +122,10 @@ def deprecated(reason: str):
|
||||
return decorator
|
||||
|
||||
|
||||
class classproperty(property):
|
||||
T = TypeVar("T")
|
||||
|
||||
|
||||
class classproperty(Generic[T]):
|
||||
"""
|
||||
A decorator that combines @classmethod and @property.
|
||||
It allows a method to be accessed as a property of the class,
|
||||
@@ -134,17 +137,27 @@ class classproperty(property):
|
||||
...
|
||||
"""
|
||||
|
||||
def __get__(self, owner_self: object, owner_cls: type) -> object:
|
||||
def __init__(self, fget: Callable[..., T]):
|
||||
"""
|
||||
Args:
|
||||
The function that is called when the property is accessed.
|
||||
"""
|
||||
self.fget = fget
|
||||
|
||||
def __get__(self, owner_self: Any, owner_cls: Optional[type] = None) -> T:
|
||||
"""
|
||||
Override the __get__ method to return the result of the function call.
|
||||
|
||||
Args:
|
||||
owner_self: The instance through which the attribute was accessed, or None.
|
||||
owner_cls: The class through which the attribute was accessed.
|
||||
owner_self: The instance through which the attribute was accessed, or None.
|
||||
Irrelevant for class properties.
|
||||
owner_cls: The class through which the attribute was accessed.
|
||||
|
||||
Returns:
|
||||
The result of calling the function stored in 'fget' with 'owner_cls'.
|
||||
The result of calling the function stored in 'fget' with 'owner_cls'.
|
||||
"""
|
||||
if self.fget is None:
|
||||
raise AttributeError("unreadable attribute")
|
||||
return self.fget(owner_cls)
|
||||
|
||||
|
||||
|
||||
@@ -17,7 +17,7 @@ def plot_image(
|
||||
Args:
|
||||
image (ImageType): The frame to be displayed ImageType
|
||||
is a flexible type, accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
size (Tuple[int, int]): The size of the plot.
|
||||
size (Tuple[int, int]): The size of the plot in inches.
|
||||
cmap (str): the colormap to use for single channel images.
|
||||
|
||||
Examples:
|
||||
|
||||
@@ -19,7 +19,7 @@ class VideoInfo:
|
||||
width (int): width of the video in pixels
|
||||
height (int): height of the video in pixels
|
||||
fps (int): frames per second of the video
|
||||
total_frames (int, optional): total number of frames in the video,
|
||||
total_frames (Optional[int]): total number of frames in the video,
|
||||
default is None
|
||||
|
||||
Examples:
|
||||
@@ -116,7 +116,9 @@ class VideoSink:
|
||||
self.__writer.release()
|
||||
|
||||
|
||||
def _validate_and_setup_video(source_path: str, start: int, end: Optional[int]):
|
||||
def _validate_and_setup_video(
|
||||
source_path: str, start: int, end: Optional[int], iterative_seek: bool = False
|
||||
):
|
||||
video = cv2.VideoCapture(source_path)
|
||||
if not video.isOpened():
|
||||
raise Exception(f"Could not open video at {source_path}")
|
||||
@@ -125,12 +127,25 @@ def _validate_and_setup_video(source_path: str, start: int, end: Optional[int]):
|
||||
raise Exception("Requested frames are outbound")
|
||||
start = max(start, 0)
|
||||
end = min(end, total_frames) if end is not None else total_frames
|
||||
video.set(cv2.CAP_PROP_POS_FRAMES, start)
|
||||
|
||||
if iterative_seek:
|
||||
while start > 0:
|
||||
success = video.grab()
|
||||
if not success:
|
||||
break
|
||||
start -= 1
|
||||
elif start > 0:
|
||||
video.set(cv2.CAP_PROP_POS_FRAMES, start)
|
||||
|
||||
return video, start, end
|
||||
|
||||
|
||||
def get_video_frames_generator(
|
||||
source_path: str, stride: int = 1, start: int = 0, end: Optional[int] = None
|
||||
source_path: str,
|
||||
stride: int = 1,
|
||||
start: int = 0,
|
||||
end: Optional[int] = None,
|
||||
iterative_seek: bool = False,
|
||||
) -> Generator[np.ndarray, None, None]:
|
||||
"""
|
||||
Get a generator that yields the frames of the video.
|
||||
@@ -143,6 +158,9 @@ def get_video_frames_generator(
|
||||
video should generate frames
|
||||
end (Optional[int]): Indicates the ending position at which video
|
||||
should stop generating frames. If None, video will be read to the end.
|
||||
iterative_seek (bool): If True, the generator will seek to the
|
||||
`start` frame by grabbing each frame, which is much slower. This is a
|
||||
workaround for videos that don't open at all when you set the `start` value.
|
||||
|
||||
Returns:
|
||||
(Generator[np.ndarray, None, None]): A generator that yields the
|
||||
@@ -156,7 +174,9 @@ def get_video_frames_generator(
|
||||
...
|
||||
```
|
||||
"""
|
||||
video, start, end = _validate_and_setup_video(source_path, start, end)
|
||||
video, start, end = _validate_and_setup_video(
|
||||
source_path, start, end, iterative_seek
|
||||
)
|
||||
frame_position = start
|
||||
while True:
|
||||
success, frame = video.read()
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.test_utils import mock_detections
|
||||
from typing import Optional
|
||||
|
||||
import numpy as np
|
||||
@@ -7,6 +6,7 @@ import pytest
|
||||
|
||||
from supervision.annotators.utils import ColorLookup, resolve_color_idx
|
||||
from supervision.detection.core import Detections
|
||||
from test.test_utils import mock_detections
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
|
||||
@@ -1,16 +1,16 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.test_utils import mock_detections
|
||||
from typing import List, Optional
|
||||
|
||||
import defusedxml.ElementTree as ET
|
||||
import numpy as np
|
||||
import pytest
|
||||
from defusedxml import ElementTree
|
||||
|
||||
from supervision.dataset.formats.pascal_voc import (
|
||||
detections_from_xml_obj,
|
||||
object_to_pascal_voc,
|
||||
parse_polygon_points,
|
||||
)
|
||||
from test.test_utils import mock_detections
|
||||
|
||||
|
||||
def are_xml_elements_equal(elem1, elem2):
|
||||
@@ -36,7 +36,7 @@ def are_xml_elements_equal(elem1, elem2):
|
||||
np.array([0, 0, 10, 10]),
|
||||
"test",
|
||||
None,
|
||||
ET.fromstring(
|
||||
ElementTree.fromstring(
|
||||
"""<object><name>test</name><bndbox><xmin>1</xmin><ymin>1</ymin>
|
||||
<xmax>11</xmax><ymax>11</ymax></bndbox></object>"""
|
||||
),
|
||||
@@ -46,7 +46,7 @@ def are_xml_elements_equal(elem1, elem2):
|
||||
np.array([0, 0, 10, 10]),
|
||||
"test",
|
||||
np.array([[0, 0], [10, 0], [10, 10], [0, 10]]),
|
||||
ET.fromstring(
|
||||
ElementTree.fromstring(
|
||||
"""<object><name>test</name><bndbox><xmin>1</xmin><ymin>1</ymin>
|
||||
<xmax>11</xmax><ymax>11</ymax>
|
||||
</bndbox><polygon><x1>1</x1><y1>1</y1><x2>11</x2>
|
||||
@@ -73,7 +73,7 @@ def test_object_to_pascal_voc(
|
||||
"polygon_element, expected_result, exception",
|
||||
[
|
||||
(
|
||||
ET.fromstring(
|
||||
ElementTree.fromstring(
|
||||
"""<polygon><x1>0</x1><y1>0</y1><x2>10</x2><y2>0</y2><x3>10</x3>
|
||||
<y3>10</y3><x4>0</x4><y4>10</y4></polygon>"""
|
||||
),
|
||||
@@ -160,6 +160,6 @@ def test_detections_from_xml_obj(
|
||||
xml_string, classes, resolution_wh, force_masks, expected_result, exception
|
||||
):
|
||||
with exception:
|
||||
root = ET.fromstring(xml_string)
|
||||
root = ElementTree.fromstring(xml_string)
|
||||
result, _ = detections_from_xml_obj(root, classes, resolution_wh, force_masks)
|
||||
assert result == expected_result
|
||||
|
||||
@@ -13,7 +13,7 @@ from supervision.dataset.formats.yolo import (
|
||||
from supervision.detection.core import Detections
|
||||
|
||||
|
||||
def _mock_simple_mask(resolution_wh: Tuple[int, int], box: List[int]) -> np.array:
|
||||
def _mock_simple_mask(resolution_wh: Tuple[int, int], box: List[int]) -> np.ndarray:
|
||||
x_min, y_min, x_max, y_max = box
|
||||
mask = np.full(resolution_wh, False, dtype=bool)
|
||||
mask[y_min:y_max, x_min:x_max] = True
|
||||
|
||||
@@ -1,11 +1,11 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.test_utils import mock_detections
|
||||
from typing import List, Optional
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision import DetectionDataset
|
||||
from test.test_utils import mock_detections
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.test_utils import mock_detections
|
||||
from typing import Dict, List, Optional, Tuple, TypeVar
|
||||
|
||||
import numpy as np
|
||||
@@ -15,6 +14,7 @@ from supervision.dataset.utils import (
|
||||
rle_to_mask,
|
||||
train_test_split,
|
||||
)
|
||||
from test.test_utils import mock_detections
|
||||
|
||||
T = TypeVar("T")
|
||||
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.test_utils import mock_detections
|
||||
from typing import List, Optional, Union
|
||||
|
||||
import numpy as np
|
||||
@@ -7,6 +6,7 @@ import pytest
|
||||
|
||||
from supervision.detection.core import Detections, merge_inner_detection_object_pair
|
||||
from supervision.geometry.core import Position
|
||||
from test.test_utils import mock_detections
|
||||
|
||||
PREDICTIONS = np.array(
|
||||
[
|
||||
|
||||
@@ -1,11 +1,11 @@
|
||||
import csv
|
||||
import os
|
||||
from test.test_utils import mock_detections
|
||||
from typing import Any, Dict, List
|
||||
|
||||
import pytest
|
||||
|
||||
import supervision as sv
|
||||
from test.test_utils import mock_detections
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
|
||||
@@ -1,11 +1,11 @@
|
||||
import json
|
||||
import os
|
||||
from test.test_utils import mock_detections
|
||||
from typing import Any, Dict, List
|
||||
|
||||
import pytest
|
||||
|
||||
import supervision as sv
|
||||
from test.test_utils import mock_detections
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
|
||||
@@ -1,11 +1,11 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.test_utils import mock_detections
|
||||
from typing import List, Optional, Tuple
|
||||
|
||||
import pytest
|
||||
|
||||
from supervision import LineZone
|
||||
from supervision.geometry.core import Point, Position, Vector
|
||||
from test.test_utils import mock_detections
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
|
||||
@@ -1,10 +1,10 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.test_utils import mock_detections
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
import supervision as sv
|
||||
from test.test_utils import mock_detections
|
||||
|
||||
DETECTION_BOXES = np.array(
|
||||
[
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from test.test_utils import assert_almost_equal, mock_detections
|
||||
from typing import Optional, Union
|
||||
|
||||
import numpy as np
|
||||
@@ -11,6 +10,7 @@ from supervision.metrics.detection import (
|
||||
MeanAveragePrecision,
|
||||
detections_to_tensor,
|
||||
)
|
||||
from test.test_utils import assert_almost_equal, mock_detections
|
||||
|
||||
CLASSES = np.arange(80)
|
||||
NUM_CLASSES = len(CLASSES)
|
||||
|
||||
+3
-2
@@ -1,13 +1,14 @@
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
|
||||
|
||||
def mock_detections(
|
||||
xyxy: List[List[float]],
|
||||
xyxy: npt.NDArray[np.float32],
|
||||
mask: Optional[List[np.ndarray]] = None,
|
||||
confidence: Optional[List[float]] = None,
|
||||
class_id: Optional[List[int]] = None,
|
||||
@@ -32,7 +33,7 @@ def mock_detections(
|
||||
|
||||
|
||||
def mock_keypoints(
|
||||
xy: List[List[float]],
|
||||
xy: npt.NDArray[np.float32],
|
||||
confidence: Optional[List[float]] = None,
|
||||
class_id: Optional[List[int]] = None,
|
||||
data: Optional[Dict[str, List[Any]]] = None,
|
||||
|
||||
Reference in New Issue
Block a user