ready to merge
This commit is contained in:
 SkalskiP
parent
73ba5f039b
commit
891b8523f0
|
|
@ -33,8 +33,8 @@ your workspace ID, project ID, and version number.
|
|||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace(<WORKSPACE_ID>).project(<PROJECT_ID>)
|
||||
dataset = project.version(<PROJECT_VERSION>).download("coco")
|
||||
project = rf.workspace('<WORKSPACE_ID>').project('<PROJECT_ID>')
|
||||
dataset = project.version('<PROJECT_VERSION>').download("coco")
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
|
@ -45,8 +45,8 @@ your workspace ID, project ID, and version number.
|
|||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace(<WORKSPACE_ID>).project(<PROJECT_ID>)
|
||||
dataset = project.version(<PROJECT_VERSION>).download("yolov8")
|
||||
project = rf.workspace('<WORKSPACE_ID>').project('<PROJECT_ID>')
|
||||
dataset = project.version('<PROJECT_VERSION>').download("yolov8")
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
|
@ -57,8 +57,8 @@ your workspace ID, project ID, and version number.
|
|||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace(<WORKSPACE_ID>).project(<PROJECT_ID>)
|
||||
dataset = project.version(<PROJECT_VERSION>).download("voc")
|
||||
project = rf.workspace('<WORKSPACE_ID>').project('<PROJECT_ID>')
|
||||
dataset = project.version('<PROJECT_VERSION>').download("voc")
|
||||
```
|
||||
|
||||
## Load Dataset
|
||||
|
|
@ -76,16 +76,16 @@ instances.
|
|||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f"{dataset.location}/train",
|
||||
annotations_path=f"{dataset.location}/train/_annotations.coco.json",
|
||||
images_directory_path=f'{dataset.location}/train',
|
||||
annotations_path=f'{dataset.location}/train/_annotations.coco.json',
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f"{dataset.location}/valid",
|
||||
annotations_path=f"{dataset.location}/valid/_annotations.coco.json",
|
||||
images_directory_path=f'{dataset.location}/valid',
|
||||
annotations_path=f'{dataset.location}/valid/_annotations.coco.json',
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f"{dataset.location}/test",
|
||||
annotations_path=f"{dataset.location}/test/_annotations.coco.json",
|
||||
images_directory_path=f'{dataset.location}/test',
|
||||
annotations_path=f'{dataset.location}/test/_annotations.coco.json',
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
|
|
@ -103,19 +103,19 @@ instances.
|
|||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/train/images",
|
||||
annotations_directory_path=f"{dataset.location}/train/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/valid/images",
|
||||
annotations_directory_path=f"{dataset.location}/valid/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
|
|
@ -133,16 +133,16 @@ instances.
|
|||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f"{dataset.location}/train/images",
|
||||
annotations_directory_path=f"{dataset.location}/train/labels"
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f"{dataset.location}/valid/images",
|
||||
annotations_directory_path=f"{dataset.location}/valid/labels"
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels"
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
|
|
@ -156,9 +156,7 @@ instances.
|
|||
|
||||
If your dataset is not already split into train, test, and valid subsets, you can
|
||||
easily do so using the [`sv.DetectionDataset.split`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.split)
|
||||
method. Let's assume we have a DetectionDataset named ds containing 1000 images. We
|
||||
can split it as follows, ensuring a random shuffle of the data.
|
||||
|
||||
method. We can split it as follows, ensuring a random shuffle of the data.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
|
@ -175,13 +173,120 @@ len(ds_train), len(ds_valid), len(ds_test)
|
|||
# 800, 100, 100
|
||||
```
|
||||
|
||||
## Iterate Over Dataset
|
||||
## Merge Dataset
|
||||
|
||||
There are two ways to loop over a `sv.DetectionDataset`:
|
||||
If you have multiple datasets that you would like to merge, you can do so using the
|
||||
[`sv.DetectionDataset.merge`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.merge)
|
||||
method.
|
||||
|
||||
- using a direct [for loop](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__iter__)
|
||||
called on the `sv.DetectionDataset` instance
|
||||
- loading `sv.DetectionDataset` entries [by index](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__getitem__).
|
||||
=== "COCO"
|
||||
|
||||
```{ .py hl_lines="22-28" }
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/train',
|
||||
annotations_path=f'{dataset.location}/train/_annotations.coco.json',
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/valid',
|
||||
annotations_path=f'{dataset.location}/valid/_annotations.coco.json',
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/test',
|
||||
annotations_path=f'{dataset.location}/test/_annotations.coco.json',
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
|
||||
ds = sv.DetectionDataset.merge([ds_train, ds_valid, ds_test])
|
||||
|
||||
ds.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds)
|
||||
# 1000
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
||||
```{ .py hl_lines="25-31" }
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
|
||||
ds = sv.DetectionDataset.merge([ds_train, ds_valid, ds_test])
|
||||
|
||||
ds.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds)
|
||||
# 1000
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
```{ .py hl_lines="22-28" }
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
|
||||
ds = sv.DetectionDataset.merge([ds_train, ds_valid, ds_test])
|
||||
|
||||
ds.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds)
|
||||
# 1000
|
||||
```
|
||||
|
||||
## Iterate over Dataset
|
||||
|
||||
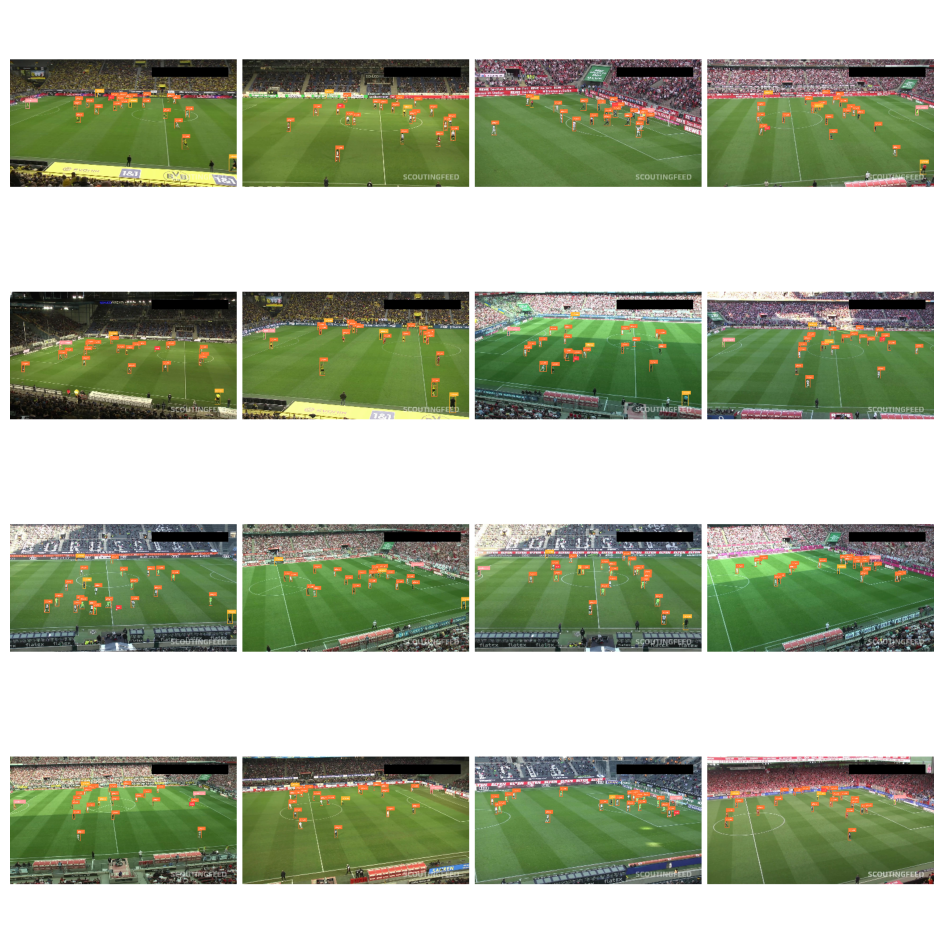
There are two ways to loop over a `sv.DetectionDataset`: using a direct
|
||||
[for loop](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__iter__)
|
||||
called on the `sv.DetectionDataset` instance or loading `sv.DetectionDataset` entries
|
||||
[by index](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__getitem__).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
|
@ -217,7 +322,7 @@ box_annotator = sv.BoxAnnotator()
|
|||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_images = []
|
||||
for i in range(25):
|
||||
for i in range(16):
|
||||
_, image, annotations = ds[i]
|
||||
|
||||
labels = [ds.classes[class_id] for class_id in annotations.class_id]
|
||||
|
|
@ -229,29 +334,122 @@ for i in range(25):
|
|||
|
||||
grid = sv.create_tiles(
|
||||
annotated_images,
|
||||
grid_size=(5, 5),
|
||||
grid_size=(4, 4),
|
||||
single_tile_size=(400, 400),
|
||||
tile_padding_color=sv.Color.WHITE,
|
||||
tile_margin_color=sv.Color.WHITE
|
||||
)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Save Dataset
|
||||
|
||||
- [`DetectionDataset.as_coco`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_coco)
|
||||
- [`DetectionDataset.as_yolo`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_yolo)
|
||||
- [`DetectionDataset.as_pascal`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_pascal)
|
||||
=== "COCO"
|
||||
|
||||
TODO
|
||||
We can do so using the [`sv.DetectionDataset.as_coco`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_coco) method to save annotations in [COCO](https://roboflow.com/formats/coco-json) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
ds.as_coco(
|
||||
images_directory_path='<IMAGE_DIRECTORY_PATH>',
|
||||
annotations_path='<ANNOTATIONS_PATH>'
|
||||
)
|
||||
```
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
=== "YOLO"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.as_yolo`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_yolo) method to save annotations in [YOLO](https://roboflow.com/formats/yolov8-pytorch-txt) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
ds.as_yolo(
|
||||
images_directory_path='<IMAGE_DIRECTORY_PATH>',
|
||||
annotations_directory_path='<ANNOTATIONS_DIRECTORY_PATH>',
|
||||
data_yaml_path='<DATA_YAML_PATH>'
|
||||
)
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.as_pascal_voc`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_pascal_voc) method to save annotations in [Pascal VOC](https://roboflow.com/formats/pascal-voc-xml) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
ds.as_pascal_voc(
|
||||
images_directory_path='<IMAGE_DIRECTORY_PATH>',
|
||||
annotations_directory_path='<ANNOTATIONS_DIRECTORY_PATH>'
|
||||
)
|
||||
```
|
||||
|
||||
## Augment Dataset
|
||||
|
||||
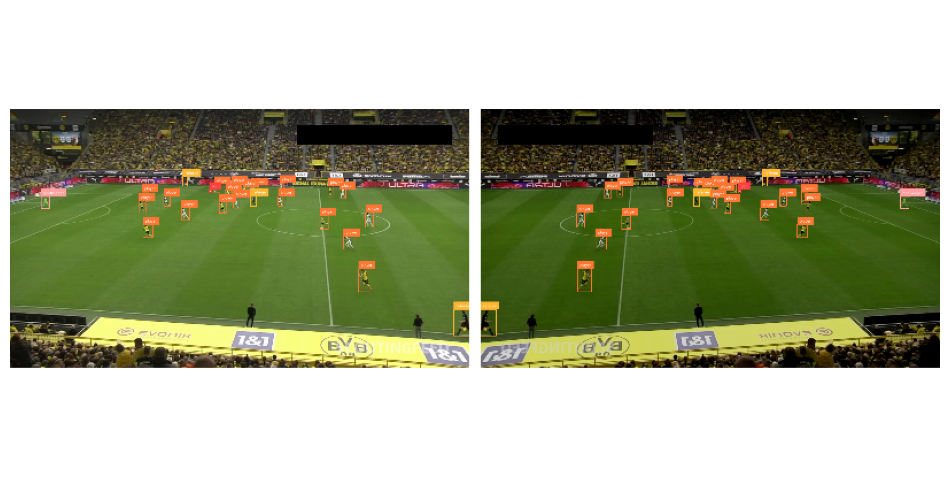
In this section, we'll explore using Supervision in combination with Albumentations to
|
||||
augment our dataset. Data augmentation is a common technique in computer vision to
|
||||
increase the size and diversity of training datasets, leading to improved model
|
||||
performance and generalization.
|
||||
|
||||
```bash
|
||||
pip install augmentation
|
||||
```
|
||||
|
||||
## Merge Dataset
|
||||
|
||||
TODO
|
||||
Albumentations provides a flexible and powerful API for image augmentation. The core of
|
||||
the library is the [`Compose`](https://albumentations.ai/docs/api_reference/full_reference/?h=compose#albumentations.core.composition.Compose)
|
||||
class, which allows you to chain multiple image transformations together. Each
|
||||
transformation is defined using a dedicated class, such as
|
||||
[`HorizontalFlip`](https://albumentations.ai/docs/api_reference/full_reference/?h=horizontalflip#albumentations.augmentations.geometric.transforms.HorizontalFlip),
|
||||
[`RandomBrightnessContrast`](https://albumentations.ai/docs/api_reference/full_reference/?h=horizontalflip#albumentations.augmentations.transforms.RandomBrightnessContrast),
|
||||
or [`Perspective`](https://albumentations.ai/docs/api_reference/full_reference/?h=horizontalflip#albumentations.augmentations.geometric.transforms.Perspective).
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import albumentations as A
|
||||
|
||||
augmentation = A.Compose(
|
||||
transforms=[
|
||||
A.Perspective(p=0.1),
|
||||
A.HorizontalFlip(p=0.5),
|
||||
A.RandomBrightnessContrast(p=0.5)
|
||||
],
|
||||
bbox_params=A.BboxParams(
|
||||
format='pascal_voc',
|
||||
label_fields=['category']
|
||||
),
|
||||
)
|
||||
```
|
||||
|
||||
The key is to set `format='pascal_voc'`, which corresponds to the
|
||||
`[x_min, y_min, x_max, y_max]` bounding box format used in Supervision.
|
||||
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from dataclasses import replace
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
_, original_image, original_annotations = ds[0]
|
||||
|
||||
output = augmentation(
|
||||
image=original_image,
|
||||
bboxes=original_annotations.xyxy,
|
||||
category=original_annotations.class_id
|
||||
)
|
||||
|
||||
augmented_image = output['image']
|
||||
augmented_annotations = replace(
|
||||
original_annotations,
|
||||
xyxy=np.array(output['bboxes']),
|
||||
class_id=np.array(output['category'])
|
||||
)
|
||||
```
|
||||
|
||||
|
||||
Loading…
Reference in New Issue