updates
This commit is contained in:
 SkalskiP
parent
d91113c9e7
commit
73ba5f039b
|
|
@ -1,53 +1,239 @@
|
|||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
With Supervision, you can load and manipulate classification, object detection, and
|
||||
segmentation datasets. This tutorial will walk you through how to load, split, merge,
|
||||
and visualize datasets in Supervision.
|
||||
visualize, and augment datasets in Supervision.
|
||||
|
||||
## Download Dataset
|
||||
|
||||
TODO
|
||||
In this tutorial, we will use a dataset from
|
||||
[Roboflow Universe](https://universe.roboflow.com/), a public repository of
|
||||
thousands of computer vision datasets. If you already have your dataset in
|
||||
[COCO](https://roboflow.com/formats/coco-json),
|
||||
[YOLO](https://roboflow.com/formats/yolov8-pytorch-txt),
|
||||
or [Pascal VOC](https://roboflow.com/formats/pascal-voc-xml) format, you can skip this
|
||||
section.
|
||||
|
||||
```bash
|
||||
pip install roboflow
|
||||
```
|
||||
|
||||
TODO
|
||||
Next, log into your Roboflow account and download the dataset of your choice in the
|
||||
COCO, YOLO, or Pascal VOC format. You can customize the following code snippet with
|
||||
your workspace ID, project ID, and version number.
|
||||
|
||||
```python
|
||||
>>> import roboflow
|
||||
=== "COCO"
|
||||
|
||||
>>> roboflow.login()
|
||||
```python
|
||||
import roboflow
|
||||
|
||||
>>> rf = roboflow.Roboflow()
|
||||
>>> project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
>>> dataset = project.version(PROJECT_VERSION).download("coco")
|
||||
```
|
||||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace(<WORKSPACE_ID>).project(<PROJECT_ID>)
|
||||
dataset = project.version(<PROJECT_VERSION>).download("coco")
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
||||
```python
|
||||
import roboflow
|
||||
|
||||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace(<WORKSPACE_ID>).project(<PROJECT_ID>)
|
||||
dataset = project.version(<PROJECT_VERSION>).download("yolov8")
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
```python
|
||||
import roboflow
|
||||
|
||||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace(<WORKSPACE_ID>).project(<PROJECT_ID>)
|
||||
dataset = project.version(<PROJECT_VERSION>).download("voc")
|
||||
```
|
||||
|
||||
## Load Dataset
|
||||
|
||||
- [`DetectionDataset.from_coco`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.from_coco) ([COCO](https://roboflow.com/formats/coco-json))
|
||||
- [`DetectionDataset.from_yolo`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.from_yolo) ([YOLO](https://roboflow.com/formats/yolov8-pytorch-txt))
|
||||
- [`DetectionDataset.from_pascal`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.from_pascal) ([Pascal](https://roboflow.com/formats/pascal-voc-xml))
|
||||
The Supervision library provides convenient functions to load datasets in various
|
||||
formats. If your dataset is already split into train, test, and valid subsets, you can
|
||||
load each of those as separate [`sv.DetectionDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset)
|
||||
instances.
|
||||
|
||||
=== "COCO"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.from_coco`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.from_coco) to load annotations in [COCO](https://roboflow.com/formats/coco-json) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f"{dataset.location}/train",
|
||||
annotations_path=f"{dataset.location}/train/_annotations.coco.json",
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f"{dataset.location}/valid",
|
||||
annotations_path=f"{dataset.location}/valid/_annotations.coco.json",
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f"{dataset.location}/test",
|
||||
annotations_path=f"{dataset.location}/test/_annotations.coco.json",
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.from_yolo`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.from_yolo) to load annotations in [YOLO](https://roboflow.com/formats/yolov8-pytorch-txt) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/train/images",
|
||||
annotations_directory_path=f"{dataset.location}/train/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/valid/images",
|
||||
annotations_directory_path=f"{dataset.location}/valid/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.from_pascal_voc`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.from_pascal_voc) to load annotations in [Pascal VOC](https://roboflow.com/formats/pascal-voc-xml) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f"{dataset.location}/train/images",
|
||||
annotations_directory_path=f"{dataset.location}/train/labels"
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f"{dataset.location}/valid/images",
|
||||
annotations_directory_path=f"{dataset.location}/valid/labels"
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f"{dataset.location}/test/images",
|
||||
annotations_directory_path=f"{dataset.location}/test/labels"
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
## Split Dataset
|
||||
|
||||
If your dataset is not already split into train, test, and valid subsets, you can
|
||||
easily do so using the [`sv.DetectionDataset.split`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.split)
|
||||
method. Let's assume we have a DetectionDataset named ds containing 1000 images. We
|
||||
can split it as follows, ensuring a random shuffle of the data.
|
||||
|
||||
TODO
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> ds = sv.DetectionDataset.from_coco(
|
||||
... images_directory_path=f"{dataset.location}/train",
|
||||
... annotations_path=f"{dataset.location}/train/_annotations.coco.json",
|
||||
... )
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
>>> ds.classes
|
||||
['dog', 'person']
|
||||
len(ds)
|
||||
# 1000
|
||||
|
||||
ds_train, ds = ds.split(split_ratio=0.8, shuffle=True)
|
||||
ds_valid, ds_test = ds.split(split_ratio=0.5, shuffle=True)
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
## Iterate Over Dataset
|
||||
|
||||
There are two ways to loop over a `sv.DetectionDataset`:
|
||||
|
||||
- using a direct [for loop](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__iter__)
|
||||
called on the `sv.DetectionDataset` instance
|
||||
- loading `sv.DetectionDataset` entries [by index](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__getitem__).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
# Option 1
|
||||
for image_path, image, annotations in ds:
|
||||
... # Process each image and its annotations
|
||||
|
||||
# Option 2
|
||||
for idx in range(len(ds)):
|
||||
image_path, image, annotations = ds[idx]
|
||||
... # Process the image and annotations at index `idx`
|
||||
```
|
||||
|
||||
## Visualize Dataset
|
||||
|
||||
TODO
|
||||
The Supervision library provides tools for easily visualizing your detection dataset.
|
||||
You can create a grid of annotated images to quickly inspect your data and labels.
|
||||
First, initialize the [`sv.BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator)
|
||||
and [`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator).
|
||||
Then, iterate through a subset of the dataset (e.g., the first 25 images), drawing
|
||||
bounding boxes and class labels on each image. Finally, combine the annotated images
|
||||
into a grid for display.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_images = []
|
||||
for i in range(25):
|
||||
_, image, annotations = ds[i]
|
||||
|
||||
labels = [ds.classes[class_id] for class_id in annotations.class_id]
|
||||
|
||||
annotated_image = image.copy()
|
||||
annotated_image = box_annotator.annotate(annotated_image, annotations)
|
||||
annotated_image = label_annotator.annotate(annotated_image, annotations, labels)
|
||||
annotated_images.append(annotated_image)
|
||||
|
||||
grid = sv.create_tiles(
|
||||
annotated_images,
|
||||
grid_size=(5, 5),
|
||||
single_tile_size=(400, 400),
|
||||
tile_padding_color=sv.Color.WHITE,
|
||||
tile_margin_color=sv.Color.WHITE
|
||||
)
|
||||
```
|
||||
|
||||
## Save Dataset
|
||||
|
|
@ -62,20 +248,6 @@ TODO
|
|||
>>> import supervision as sv
|
||||
```
|
||||
|
||||
## Split Dataset
|
||||
|
||||
TODO
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> train_ds, test_ds = ds.split(
|
||||
... split_ratio=0.7,
|
||||
... random_state=42,
|
||||
... shuffle=True
|
||||
... )
|
||||
```
|
||||
|
||||
## Merge Dataset
|
||||
|
||||
TODO
|
||||
|
|
@ -83,184 +255,3 @@ TODO
|
|||
```python
|
||||
>>> import supervision as sv
|
||||
```
|
||||
|
||||
## Classification Dataset
|
||||
|
||||
TODO
|
||||
|
||||
```python
|
||||
>>> import roboflow
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> roboflow.login()
|
||||
|
||||
>>> rf = roboflow.Roboflow()
|
||||
>>> project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
>>> dataset = project.version(PROJECT_VERSION).download("folder")
|
||||
|
||||
>>> cd = sv.ClassificationDataset.from_folder_structure(
|
||||
... root_directory_path=f"{dataset.location}/train"
|
||||
... )
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
supervision enables you to both process detections from a model and datasets. Dataset processing is implemented in the `sv.DetectionDataset` (object detection and segmentation) and `sv.ClassificationDataset` (classification) APIs.
|
||||
|
||||
The supervision `sv.DetectionDataset` and `sv.ClassificationDataset` APIs enables you to:
|
||||
|
||||
1. Load full datasets into supervision
|
||||
2. Split datasets into train/test sets
|
||||
3. Merge datasets together
|
||||
|
||||
Each image in a `DetectionDataset` object is assigned an [sv.Detections](https://supervision.roboflow.com/detection/core/) object that you can manipulate. Each image in a `ClassificationDataset` object is assigned a [Classifications](https://supervision.roboflow.com/classification/core/) object that you can manipulate.
|
||||
|
||||
In this guide, we will walk through how to accomplish all of the above tasks in supervision.
|
||||
|
||||
## Processing Detection Datasets
|
||||
|
||||
### Load a Dataset into Supervision
|
||||
|
||||
To load a dataset into supervision, you need to use a data loader. For this guide, we will load a COCO dataset, so we will use the `DetectionDataset.from_coco` data loader.
|
||||
|
||||
The following data loaders are supported:
|
||||
|
||||
- `DetectionDataset.from_coco` ([COCO JSON](https://roboflow.com/formats/coco-json))
|
||||
- `DetectionDataset.from_yolo` ([YOLO PyTorch TXT](https://roboflow.com/formats/yolov8-pytorch-txt))
|
||||
- `DetectionDataset.from_pascal_voc` ([Pascal VOC XML](https://roboflow.com/formats/pascal-voc-xml))
|
||||
|
||||
Create a new Python file and add the following code:
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
DATASET_PATH = "football-players-detection"
|
||||
|
||||
ds = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{DATASET_PATH}/train/images",
|
||||
annotations_directory_path=f"{DATASET_PATH}/train/labels",
|
||||
data_yaml_path=f"{DATASET_PATH}/data.yaml"
|
||||
)
|
||||
|
||||
print(ds.classes)
|
||||
# ['ball', 'goalkeeper', 'player', 'referee']
|
||||
```
|
||||
|
||||
This code loads a dataset stored in the YOLOv8 PyTorch TXT format into an `sv.DetectionDataset` object. Then, the classes in the dataset are printed out to the console.
|
||||
|
||||
### Split a Dataset into Train/Test Sets
|
||||
|
||||
To split a dataset into train/test datasets, you can use the `sv.DetectionDataset.split` method.
|
||||
|
||||
```python
|
||||
train_ds, test_ds = ds.split(
|
||||
split_ratio=0.7,
|
||||
random_state=42,
|
||||
shuffle=True
|
||||
)
|
||||
```
|
||||
|
||||
This code creates two `sv.DetectionDataset` instances. The first contains a train dataset and the second contains the test dataset. We have specified a 0.7 split, which means 70% of images will go to the test set.
|
||||
|
||||
You can use `random_state` to set a seed you can use to reproduce the same split. You can use `shuffle` to shuffle the dataset before splitting.
|
||||
|
||||
### Visualize Annotations
|
||||
|
||||
You can visualize annotations from an object detection and segmentation dataset using the `sv.BoundingBoxAnnotator` and `sv.MaskAnnotator` methods. See documentation for supervision anontators.
|
||||
|
||||
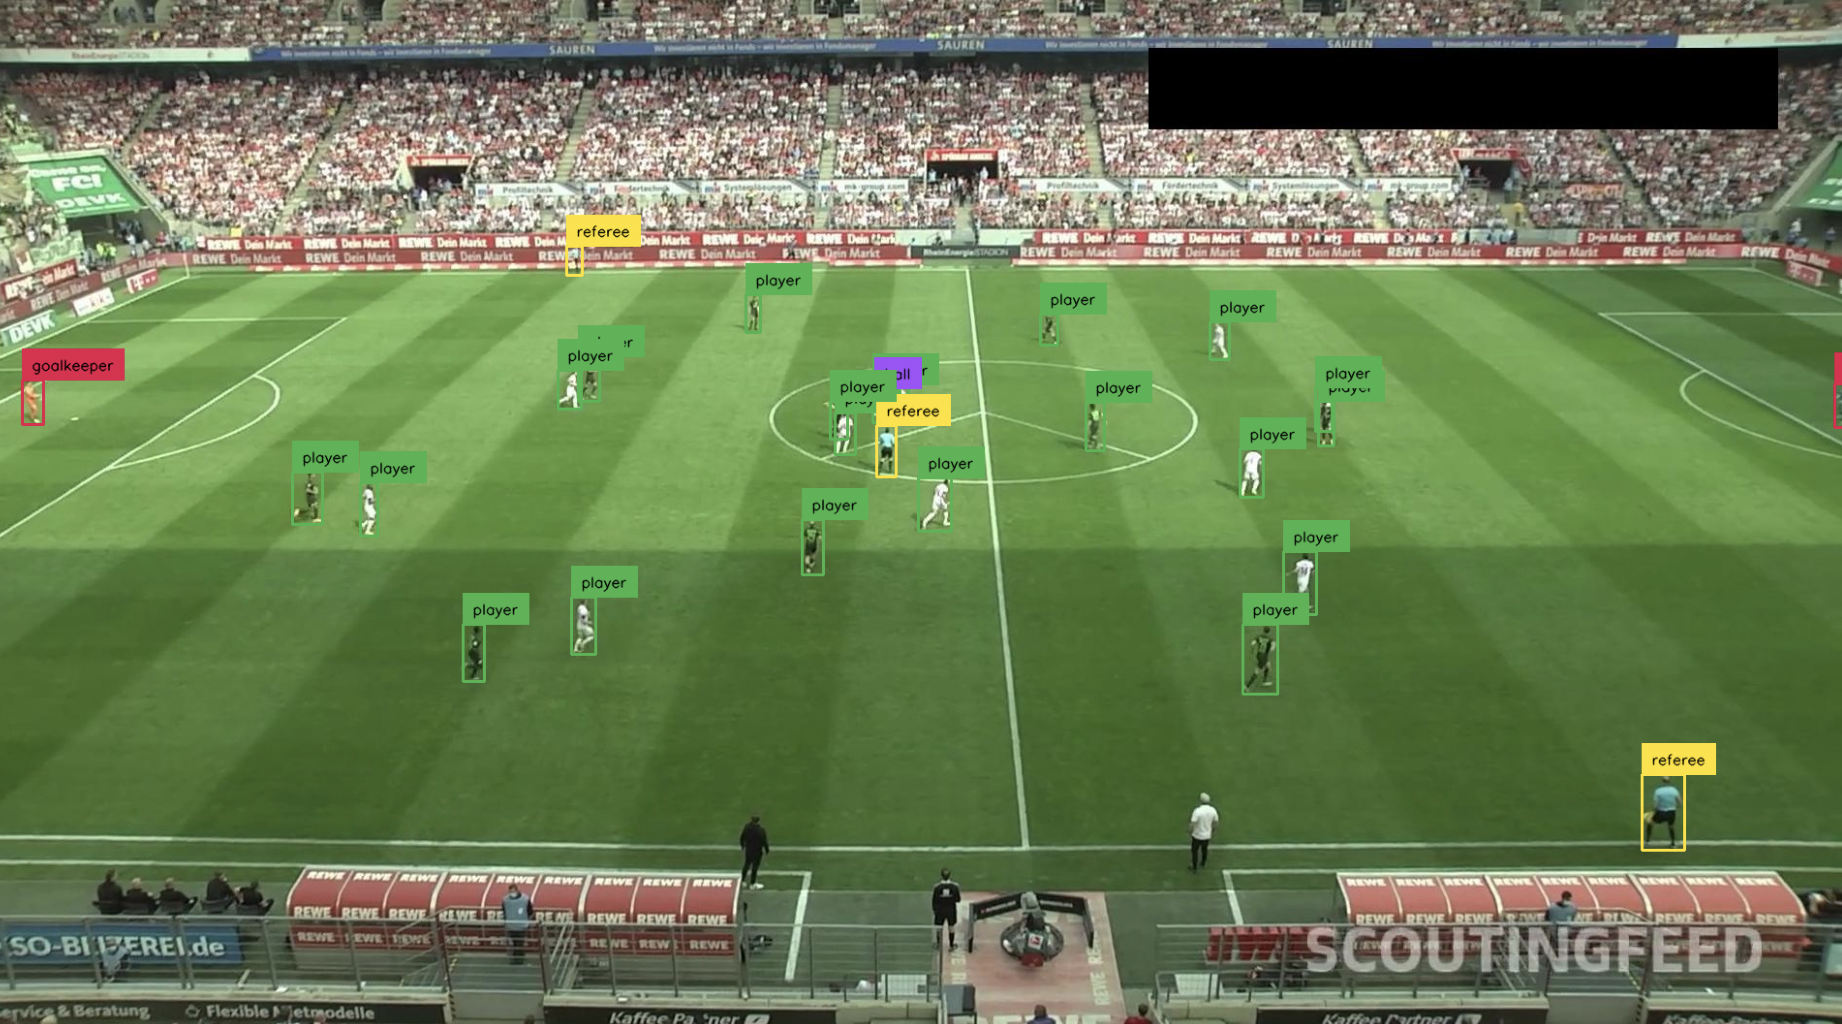
Let's visualize an image in a object detection dataset.
|
||||
|
||||
```python
|
||||
image_name = DATASET_PATH + "/train/images/42ba34_9_9_png.rf.1f36573ac36d8b56c1f0a2f11bd480d4.jpg"
|
||||
|
||||
image = ds.images[image_name]
|
||||
annotations = ds.annotations[image_name]
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
ds.classes[class_id]
|
||||
for class_id
|
||||
in annotations.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=annotations)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=annotations, labels=labels)
|
||||
|
||||
sv.plot_image(annotated_image)
|
||||
```
|
||||
|
||||
Here is the output:
|
||||
|
||||
|
||||
|
||||
In the code above, we use retrieve an image from the dataset through the `ds.images` dictionary and its associated annotations (represented as a `sv.Detections` object) through the `ds.annotations` dictionary.
|
||||
|
||||
We use the `sv.BoundingBoxAnnotator` and `sv.LabelAnnotator` to annotate the image with bounding boxes and labels. We then plot the image using the `sv.plot_image` method.
|
||||
|
||||
## Merge Datasets
|
||||
|
||||
You can merge two detection datasets together using the `sv.DetectionDataset.merge` method.
|
||||
|
||||
```python
|
||||
merged_ds = sv.ClassificationDataset.merge(
|
||||
[cd_train, cd_test]
|
||||
)
|
||||
```
|
||||
|
||||
## Processing Classification Datasets
|
||||
|
||||
You can work with classification datasets using the `sv.ClassificationDataset` API.
|
||||
|
||||
### Load a Dataset into Supervision
|
||||
|
||||
To load a dataset into supervision, you need to use a data loader. You can load detections from a classification dataset using the `sv.ClassificationDataset.from_folder_structure` data loader.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
cd_train = sv.ClassificationDataset.from_folder_structure(
|
||||
"artwork/train"
|
||||
)
|
||||
cd_test = sv.ClassificationDataset.from_folder_structure(
|
||||
"artwork/test"
|
||||
)
|
||||
cd_valid = sv.ClassificationDataset.from_folder_structure(
|
||||
"artwork/valid"
|
||||
)
|
||||
|
||||
print(cd_train.classes)
|
||||
# ['abstract', 'abstract digital', 'abstract digital landscape surrealism', 'abstract digital surrealism', ...]
|
||||
```
|
||||
|
||||
`dataset/` is the path where your classification folder dataset is stored.
|
||||
|
||||
### Split a Dataset into Train/Test Sets
|
||||
|
||||
To split a dataset into train/test datasets, you can use the `sv.ClassificationDataset.split` method.
|
||||
|
||||
```python
|
||||
train_ds, test_ds = ds.split(
|
||||
split_ratio=0.7,
|
||||
random_state=42,
|
||||
shuffle=True
|
||||
)
|
||||
```
|
||||
|
||||
This code creates two `sv.ClassificationDataset` instances. The first contains a train dataset and the second contains the test dataset. We have specified a 0.7 split, which means 70% of images will go to the test set.
|
||||
|
||||
### Retrieve Annotations
|
||||
|
||||
You can retrieve annotations from a classification dataset using the `sv.ClassificationDataset.annotations` dictionary.
|
||||
|
||||
```python
|
||||
image = "artwork/train/abstract digital/03c8e4c4430d631029694e64f4d29b97_jpg.rf.378dcf12b0adb97ee966d84fb63a0e28.jpg"
|
||||
|
||||
classes = cd_train.classes
|
||||
|
||||
print(classes[cd_train.annotations[image].class_id[0]])
|
||||
# ['abstract digital']
|
||||
```
|
||||
|
|
|
|||
Loading…
Reference in New Issue