Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 SkalskiP |
b1b69ad972 | ||
|
SkalskiP
|
52be9dc818 | ||
|
Piotr Skalski
|
c7e95483bf | ||
|
SkalskiP
|
65f6e418a1 | ||
|
pre-commit-ci[bot]
|
1fef946a19 | ||
|
SkalskiP
|
4c3d51f186 | ||
|
pre-commit-ci[bot]
|
9340cb962b | ||
|
SkalskiP
|
6578b4ea52 | ||
|
SkalskiP
|
0bd60874ca | ||
|
Piotr Skalski
|
b02ec93b30 | ||
|
pre-commit-ci[bot]
|
89ee57f519 | ||
|
SkalskiP
|
1c8398942a | ||
|
pre-commit-ci[bot]
|
3e7e4caf3f | ||
|
SkalskiP
|
a3ea8cdb1f | ||
|
SkalskiP
|
32dca290ef | ||
|
Piotr Skalski
|
171687f3ab | ||
|
Kshitij Aucharmal
|
421ad21c98 | ||
|
Piotr Skalski
|
deb1c9c4f4 | ||
|
pre-commit-ci[bot]
|
6679b1f5a9 | ||
|
Piotr Skalski
|
c7de70ed20 | ||
|
SkalskiP
|
2cdb70eb91 | ||
|
SkalskiP
|
2ef029ef4b | ||
|
pre-commit-ci[bot]
|
dce96d462e | ||
|
SkalskiP
|
3fcbef9482 | ||
|
SkalskiP
|
c8b966be1a | ||
|
pre-commit-ci[bot]
|
72621dce32 | ||
|
SkalskiP
|
098d5e3eb1 | ||
|
SkalskiP
|
8c49465d49 | ||
|
pre-commit-ci[bot]
|
4ad36db3bb | ||
|
SkalskiP
|
a933b93234 | ||
|
SkalskiP
|
cbb58a8c6f | ||
|
SkalskiP
|
8fc22f0281 | ||
|
SkalskiP
|
4b7b347aea | ||
|
SkalskiP
|
5c6745291b | ||
|
SkalskiP
|
83d490dadc | ||
|
SkalskiP
|
005cdbd37a | ||
|
Piotr Skalski
|
ade2668ae3 | ||
|
pre-commit-ci[bot]
|
46e5965680 | ||
|
SkalskiP
|
aab3160cd7 | ||
|
pre-commit-ci[bot]
|
13ab215fdf | ||
|
SkalskiP
|
a08cda30fb | ||
|
SkalskiP
|
e1393691a4 | ||
|
Piotr Skalski
|
90f8582e4f | ||
|
Ashp116
|
0c9fea4d9f | ||
|
Ashp116
|
cdca2e6b51 | ||
|
pre-commit-ci[bot]
|
8407d5a692 | ||
|
Ashp116
|
eaf6cdd477 | ||
|
pre-commit-ci[bot]
|
f447b6fa95 | ||
|
Ashp116
|
8c6ac2dd29 | ||
|
Ashp116
|
22b6d3d464 | ||
|
Piotr Skalski
|
dda3900943 | ||
|
Piotr Skalski
|
ac0c367e81 | ||
|
SkalskiP
|
6f2490cc23 | ||
|
Piotr Skalski
|
4a9d06eb50 | ||
|
pre-commit-ci[bot]
|
21e311a319 | ||
|
SkalskiP
|
71a14812fe | ||
|
SkalskiP
|
35fdcb0a1a | ||
|
Piotr Skalski
|
6d26a9766c | ||
|
SkalskiP
|
1cfaef9405 | ||
|
pre-commit-ci[bot]
|
063e2092c8 | ||
|
soumik12345
|
cb215d26f3 | ||
|
Soumik Rakshit
|
8bbe80e683 | ||
|
Alex Bodner
|
9a0483446a | ||
|
pre-commit-ci[bot]
|
f4561f9ba7 | ||
|
SkalskiP
|
beaf89cb22 | ||
|
dependabot[bot]
|
96b58c2860 | ||
|
Piotr Skalski
|
8873da4a30 | ||
|
Piotr Skalski
|
1362850986 | ||
|
Piotr Skalski
|
98a4391677 | ||
|
SkalskiP
|
036a956473 | ||
|
Piotr Skalski
|
b381fa198f | ||
|
pre-commit-ci[bot]
|
8ca2e9fe8d | ||
|
soumik12345
|
bc1d73a307 | ||
|
Piotr Skalski
|
9679cd5c4e | ||
|
pre-commit-ci[bot]
|
00817df9e2 | ||
|
SkalskiP
|
ec189bf388 | ||
|
SkalskiP
|
58bdce5707 | ||
|
pre-commit-ci[bot]
|
8262b6e64b | ||
|
SkalskiP
|
72fe0bf47f | ||
|
soumik12345
|
137078602b | ||
|
soumik12345
|
8fa21dd165 | ||
|
soumik12345
|
da70389546 | ||
|
soumik12345
|
cc1525707a | ||
|
soumik12345
|
b3aee43c3b | ||
|
Soumik Rakshit
|
932c1aa91e | ||
|
rcvsq
|
76ee05420d | ||
|
soumik12345
|
a470bc2976 | ||
|
Soumik Rakshit
|
cf725dd4db | ||
|
Piotr Skalski
|
317ac0810e | ||
|
SkalskiP
|
cb6018ef04 | ||
|
pre-commit-ci[bot]
|
580fcdde4c | ||
|
soumik12345
|
ad4f44644c | ||
|
Piotr Skalski
|
0c8a9d34a6 | ||
|
soumik12345
|
d067f32678 | ||
|
Piotr Skalski
|
d251677774 | ||
|
pre-commit-ci[bot]
|
b1780fbae5 | ||
|
SkalskiP
|
e8cb962fcc | ||
|
dependabot[bot]
|
1e84351d60 | ||
|
Piotr Skalski
|
baa0402d5a | ||
|
pre-commit-ci[bot]
|
c54d16c57e | ||
|
SkalskiP
|
1adb75520f | ||
|
pre-commit-ci[bot]
|
db51a9ff98 | ||
|
Onuralp SEZER
|
f044398c17 | ||
|
pre-commit-ci[bot]
|
704652a0d2 | ||
|
Balthasar
|
6e3001194d | ||
|
Balthasar
|
d7774381cc | ||
|
Soumik Rakshit
|
1c8ec0a287 | ||
|
Balthasar
|
118e3a496c | ||
|
pre-commit-ci[bot]
|
a139fb0b49 | ||
|
Balthasar
|
afdbb0a75c | ||
|
Balthasar
|
001a4254f8 | ||
|
Balthasar
|
2e72e70893 | ||
|
pre-commit-ci[bot]
|
2907c40ecc | ||
|
Balthasar
|
2c67cee720 | ||
|
Balthasar
|
0ddbcb2010 | ||
|
pre-commit-ci[bot]
|
40d4c6f554 | ||
|
Balthasar
|
bf88636487 | ||
|
Balthasar
|
a444b3bde8 | ||
|
pre-commit-ci[bot]
|
4009f9d886 | ||
|
Balthasar
|
3f926c618a | ||
|
Balthasar
|
71d6670e7d | ||
|
Piotr Skalski
|
08226e9199 | ||
|
Onuralp SEZER
|
535cb2a91b | ||
|
pre-commit-ci[bot]
|
8e845caeeb | ||
|
Onuralp SEZER
|
9e2a535044 | ||
|
SkalskiP
|
f737782ae8 |
+1
-1
@@ -1,4 +1,4 @@
|
||||
# These owners will be the default owners for everything in
|
||||
# the repo. They will be requested for review when someone
|
||||
# opens a pull request.
|
||||
* @SkalskiP @onuralpszr
|
||||
* @SkalskiP @soumik12345
|
||||
|
||||
@@ -34,7 +34,7 @@ jobs:
|
||||
fetch-depth: 0
|
||||
|
||||
- name: 🐍 Install uv and set Python ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
uses: astral-sh/setup-uv@e92bafb6253dcd438e0484186d7669ea7a8ca1cc # v6.4.3
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
@@ -29,7 +29,7 @@ jobs:
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
uses: astral-sh/setup-uv@e92bafb6253dcd438e0484186d7669ea7a8ca1cc # v6.4.3
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
@@ -27,7 +27,7 @@ jobs:
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
uses: astral-sh/setup-uv@e92bafb6253dcd438e0484186d7669ea7a8ca1cc # v6.4.3
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
@@ -24,7 +24,7 @@ jobs:
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
uses: astral-sh/setup-uv@e92bafb6253dcd438e0484186d7669ea7a8ca1cc # v6.4.3
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
@@ -24,7 +24,7 @@ jobs:
|
||||
fetch-depth: 0
|
||||
|
||||
- name: 🐍 Install uv and set Python ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
uses: astral-sh/setup-uv@e92bafb6253dcd438e0484186d7669ea7a8ca1cc # v6.4.3
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
@@ -19,7 +19,7 @@ jobs:
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
uses: astral-sh/setup-uv@e92bafb6253dcd438e0484186d7669ea7a8ca1cc # v6.4.3
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
@@ -32,7 +32,7 @@ repos:
|
||||
additional_dependencies: ["bandit[toml]"]
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.12.3
|
||||
rev: v0.12.5
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
|
||||
+19
-7
@@ -1,5 +1,17 @@
|
||||
# Changelog
|
||||
|
||||
### 0.26.1 <small>Jul 22, 2025</small>
|
||||
|
||||
- Fixed [1894](https://github.com/roboflow/supervision/pull/1894): Error in [`sv.MeanAveragePrecision`](https://supervision.roboflow.com/0.26.1/metrics/mean_average_precision/#supervision.metrics.mean_average_precision.MeanAveragePrecision) where the area used for size-specific evaluation (small / medium / large) was always zero unless explicitly provided in `sv.Detections.data`.
|
||||
|
||||
- Fixed [1895](https://github.com/roboflow/supervision/pull/1895): `ID=0` bug in [`sv.MeanAveragePrecision`](https://supervision.roboflow.com/0.26.1/metrics/mean_average_precision/#supervision.metrics.mean_average_precision.MeanAveragePrecision) where objects were getting `0.0` mAP despite perfect IoU matches due to a bug in annotation ID assignment.
|
||||
|
||||
- Fixed [1898](https://github.com/roboflow/supervision/pull/1898): Issue where [`sv.MeanAveragePrecision`](https://supervision.roboflow.com/0.26.1/metrics/mean_average_precision/#supervision.metrics.mean_average_precision.MeanAveragePrecision) could return negative values when certain object size categories have no data.
|
||||
|
||||
- Fixed [1901](https://github.com/roboflow/supervision/pull/1901): `match_metric` support for [`sv.Detections.with_nms`](https://supervision.roboflow.com/0.26.1/metrics/mean_average_precision/#supervision.detection.core.Detections.with_nms).
|
||||
|
||||
- Fixed [1906](https://github.com/roboflow/supervision/pull/1906): `border_thickness` parameter usage for [`sv.PercentageBarAnnotator`](https://supervision.roboflow.com/0.26.1/metrics/mean_average_precision/#supervision.annotators.core.PercentageBarAnnotator).
|
||||
|
||||
### 0.26.0 <small>Jul 16, 2025</small>
|
||||
|
||||
!!! failure "Removed"
|
||||
@@ -153,7 +165,7 @@
|
||||
|
||||
- Changed [#1786](https://github.com/roboflow/supervision/pull/1786): Significantly improved the speed of HSV color mapping in [`sv.HeatMapAnnotator`](https://supervision.roboflow.com/0.26.0/detection/annotators/#supervision.annotators.core.HeatMapAnnotator), achieving approximately 28x faster performance on 1920x1080 frames.
|
||||
|
||||
- Fix [#1834](https://github.com/roboflow/supervision/pull/1834): Supervision’s [`sv.MeanAveragePrecision`](https://supervision.roboflow.com/0.26.0/metrics/mean_average_precision/#supervision.metrics.mean_average_precision.MeanAveragePrecision) is now fully aligned with [pycocotools](https://github.com/ppwwyyxx/cocoapi), the official COCO evaluation tool, ensuring accurate and standardized metrics. This update enabled us to launch a new version of the [Computer Vision Model Leaderboard](https://leaderboard.roboflow.com/).
|
||||
- Fixed [#1834](https://github.com/roboflow/supervision/pull/1834): Supervision’s [`sv.MeanAveragePrecision`](https://supervision.roboflow.com/0.26.0/metrics/mean_average_precision/#supervision.metrics.mean_average_precision.MeanAveragePrecision) is now fully aligned with [pycocotools](https://github.com/ppwwyyxx/cocoapi), the official COCO evaluation tool, ensuring accurate and standardized metrics. This update enabled us to launch a new version of the [Computer Vision Model Leaderboard](https://leaderboard.roboflow.com/).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
@@ -173,7 +185,7 @@
|
||||
# Average Precision (AP) @[ IoU=0.50:0.95 | area= large | maxDets=100 ] = 0.629
|
||||
```
|
||||
|
||||
- Fix [#1767](https://github.com/roboflow/supervision/pull/1767): Fixed losing `sv.Detections.data` when detections filtering.
|
||||
- Fixed [#1767](https://github.com/roboflow/supervision/pull/1767): Fixed losing `sv.Detections.data` when detections filtering.
|
||||
|
||||
### 0.25.0 <small>Nov 12, 2024</small>
|
||||
|
||||
@@ -557,9 +569,9 @@ detections = sv.Detections.from_sam(sam_result=sam_result)
|
||||
|
||||
- Changed [#1434](https://github.com/roboflow/supervision/pull/1434): [`InferenceSlicer`](https://supervision.roboflow.com/0.23.0/detection/tools/inference_slicer/) now features an `overlap_wh` parameter, making it easier to compute slice sizes when handling overlapping slices.
|
||||
|
||||
- Fix [#1448](https://github.com/roboflow/supervision/pull/1448): Various annotator type issues have been resolved, supporting expanded error handling.
|
||||
- Fixed [#1448](https://github.com/roboflow/supervision/pull/1448): Various annotator type issues have been resolved, supporting expanded error handling.
|
||||
|
||||
- Fix [#1348](https://github.com/roboflow/supervision/pull/1348): Introduced a new method for [seeking to a specific video frame](https://supervision.roboflow.com/0.23.0/utils/video/#supervision.utils.video.get_video_frames_generator), addressing cases where traditional seek methods were failing. It can be enabled with `iterative_seek=True`.
|
||||
- Fixed [#1348](https://github.com/roboflow/supervision/pull/1348): Introduced a new method for [seeking to a specific video frame](https://supervision.roboflow.com/0.23.0/utils/video/#supervision.utils.video.get_video_frames_generator), addressing cases where traditional seek methods were failing. It can be enabled with `iterative_seek=True`.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
@@ -572,7 +584,7 @@ for frame in sv.get_video_frames_generator(
|
||||
...
|
||||
```
|
||||
|
||||
- Fix [#1424](https://github.com/roboflow/supervision/pull/1424): `plot_image` function now clearly indicates that the size is in inches.
|
||||
- Fixed [#1424](https://github.com/roboflow/supervision/pull/1424): `plot_image` function now clearly indicates that the size is in inches.
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
@@ -1285,7 +1297,7 @@ array([
|
||||
|
||||
### 0.11.1 <small>June 29, 2023</small>
|
||||
|
||||
- Fix [#165](https://github.com/roboflow/supervision/pull/165): [`as_folder_structure`](/0.11.1/dataset/core/#supervision.dataset.core.ClassificationDataset.as_folder_structure) fails to save [`sv.ClassificationDataset`](/0.11.1/dataset/core/#classificationdataset) when it is result of inference.
|
||||
- Fixed [#165](https://github.com/roboflow/supervision/pull/165): [`as_folder_structure`](/0.11.1/dataset/core/#supervision.dataset.core.ClassificationDataset.as_folder_structure) fails to save [`sv.ClassificationDataset`](/0.11.1/dataset/core/#classificationdataset) when it is result of inference.
|
||||
|
||||
### 0.11.0 <small>June 28, 2023</small>
|
||||
|
||||
@@ -1331,7 +1343,7 @@ array([
|
||||
|
||||
- Added [#162](https://github.com/roboflow/supervision/pull/162): additional `start` and `end` arguments to [`sv.get_video_frames_generator`](/0.11.0/utils/video/#get_video_frames_generator) allowing to generate frames only for a selected part of the video.
|
||||
|
||||
- Fix [#157](https://github.com/roboflow/supervision/pull/157): incorrect loading of YOLO dataset class names from `data.yaml`.
|
||||
- Fixed [#157](https://github.com/roboflow/supervision/pull/157): incorrect loading of YOLO dataset class names from `data.yaml`.
|
||||
|
||||
### 0.10.0 <small>June 14, 2023</small>
|
||||
|
||||
|
||||
@@ -58,3 +58,9 @@ status: new
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.converters.polygon_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.converters.xyxy_to_mask">xyxy_to_mask</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.converters.xyxy_to_mask
|
||||
|
||||
@@ -22,3 +22,9 @@ status: new
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.masks.contains_multiple_segments
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.masks.filter_segments_by_distance">filter_segments_by_distance</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.masks.filter_segments_by_distance
|
||||
|
||||
@@ -0,0 +1,18 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# VLMs Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.vlms.edit_distance">edit_distance</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.vlms.edit_distance
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.vlms.fuzzy_match_index">fuzzy_match_index</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.vlms.fuzzy_match_index
|
||||
@@ -331,12 +331,9 @@ for i in range(16):
|
||||
annotated_image = label_annotator.annotate(annotated_image, annotations, labels)
|
||||
annotated_images.append(annotated_image)
|
||||
|
||||
grid = sv.create_tiles(
|
||||
sv.plot_images_grid(
|
||||
annotated_images,
|
||||
grid_size=(4, 4),
|
||||
single_tile_size=(400, 400),
|
||||
tile_padding_color=sv.Color.WHITE,
|
||||
tile_margin_color=sv.Color.WHITE
|
||||
)
|
||||
```
|
||||
|
||||
|
||||
@@ -345,7 +345,7 @@ Supervision is versatile and compatible with various models. Check this [link](/
|
||||
|
||||
We will define a `callback` function, which will process each frame of the video by obtaining model predictions and then annotating the frame based on these predictions.
|
||||
|
||||
Let's immediately visualize the results with our [`EdgeAnnotator`](/latest/keypoint/annotators/#supervision.keypoint.annotators.EdgeAnnotator) and [`VertexAnnotator`](https://supervision.roboflow.com/latest/keypoint/annotators/#supervision.keypoint.annotators.VertexAnnotator).
|
||||
Let's immediately visualize the results with our [`EdgeAnnotator`](/latest/keypoint/annotators/#supervision.key_points.annotators.EdgeAnnotator) and [`VertexAnnotator`](https://supervision.roboflow.com/latest/keypoint/annotators/#supervision.key_points.annotators.VertexAnnotator).
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
@@ -408,7 +408,7 @@ Let's immediately visualize the results with our [`EdgeAnnotator`](/latest/keypo
|
||||
|
||||
### Convert to Detections
|
||||
|
||||
Keypoint tracking is currently supported via the conversion of `KeyPoints` to `Detections`. This is achieved with the [`KeyPoints.as_detections()`](/latest/keypoint/core/#supervision.keypoint.core.KeyPoints.as_detections) function.
|
||||
Keypoint tracking is currently supported via the conversion of `KeyPoints` to `Detections`. This is achieved with the [`KeyPoints.as_detections()`](/latest/keypoint/core/#supervision.key_points.core.KeyPoints.as_detections) function.
|
||||
|
||||
Let's convert to detections and visualize the results with our [`BoxAnnotator`](/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator).
|
||||
|
||||
|
||||
@@ -78,19 +78,19 @@ comments: true
|
||||
</div>
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.VertexAnnotator">VertexAnnotator</a></h2>
|
||||
<h2><a href="#supervision.key_points.annotators.VertexAnnotator">VertexAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.VertexAnnotator
|
||||
:::supervision.key_points.annotators.VertexAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.EdgeAnnotator">EdgeAnnotator</a></h2>
|
||||
<h2><a href="#supervision.key_points.annotators.EdgeAnnotator">EdgeAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.EdgeAnnotator
|
||||
:::supervision.key_points.annotators.EdgeAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.VertexLabelAnnotator">VertexLabelAnnotator</a></h2>
|
||||
<h2><a href="#supervision.key_points.annotators.VertexLabelAnnotator">VertexLabelAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.VertexLabelAnnotator
|
||||
:::supervision.key_points.annotators.VertexLabelAnnotator
|
||||
|
||||
@@ -5,4 +5,4 @@ status: new
|
||||
|
||||
# Keypoint Detection
|
||||
|
||||
:::supervision.keypoint.core.KeyPoints
|
||||
:::supervision.key_points.core.KeyPoints
|
||||
|
||||
+9
-2
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Image Utils
|
||||
@@ -29,10 +30,16 @@ comments: true
|
||||
:::supervision.utils.image.letterbox_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.overlay_image">overlay_image</a></h2>
|
||||
<h2><a href="#supervision.utils.image.tint_image">tint_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.overlay_image
|
||||
:::supervision.utils.image.tint_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.grayscale_image">grayscale_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.grayscale_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.ImageSink">ImageSink</a></h2>
|
||||
|
||||
@@ -1,4 +1,6 @@
|
||||
supervision
|
||||
ultralytics
|
||||
inference
|
||||
pytube
|
||||
# https://github.com/pytube/pytube/issues/2044
|
||||
# pytube
|
||||
pytubefix
|
||||
|
||||
@@ -3,7 +3,7 @@ from __future__ import annotations
|
||||
import argparse
|
||||
import os
|
||||
|
||||
from pytube import YouTube
|
||||
from pytubefix import YouTube
|
||||
|
||||
|
||||
def main(url: str, output_path: str | None, file_name: str | None) -> None:
|
||||
|
||||
+2
-1
@@ -26,7 +26,7 @@ extra:
|
||||
|
||||
extra_css:
|
||||
- stylesheets/extra.css
|
||||
- stylesheets/cookbooks-card.css
|
||||
- stylesheets/cookbooks_card.css
|
||||
|
||||
nav:
|
||||
- Home: index.md
|
||||
@@ -47,6 +47,7 @@ nav:
|
||||
- Boxes: detection/utils/boxes.md
|
||||
- Masks: detection/utils/masks.md
|
||||
- Polygons: detection/utils/polygons.md
|
||||
- VLMs: detection/utils/vlms.md
|
||||
- Keypoint Detection:
|
||||
- Core: keypoint/core.md
|
||||
- Annotators: keypoint/annotators.md
|
||||
|
||||
+1
-1
@@ -2,7 +2,7 @@
|
||||
name = "supervision"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
license = { text = "MIT" }
|
||||
version = "0.26.0"
|
||||
version = "0.27.0rc4"
|
||||
readme = "README.md"
|
||||
requires-python = ">=3.9"
|
||||
authors = [
|
||||
|
||||
+13
-4
@@ -65,6 +65,7 @@ from supervision.detection.utils.converters import (
|
||||
polygon_to_xyxy,
|
||||
xcycwh_to_xyxy,
|
||||
xywh_to_xyxy,
|
||||
xyxy_to_mask,
|
||||
xyxy_to_polygons,
|
||||
xyxy_to_xcycarh,
|
||||
xyxy_to_xywh,
|
||||
@@ -86,12 +87,14 @@ from supervision.detection.utils.masks import (
|
||||
calculate_masks_centroids,
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
filter_segments_by_distance,
|
||||
move_masks,
|
||||
)
|
||||
from supervision.detection.utils.polygons import (
|
||||
approximate_polygon,
|
||||
filter_polygons_by_area,
|
||||
)
|
||||
from supervision.detection.utils.vlms import edit_distance, fuzzy_match_index
|
||||
from supervision.detection.vlm import LMM, VLM
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import (
|
||||
@@ -107,24 +110,25 @@ from supervision.draw.utils import (
|
||||
)
|
||||
from supervision.geometry.core import Point, Position, Rect
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.keypoint.annotators import (
|
||||
from supervision.key_points.annotators import (
|
||||
EdgeAnnotator,
|
||||
VertexAnnotator,
|
||||
VertexLabelAnnotator,
|
||||
)
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.key_points.core import KeyPoints
|
||||
from supervision.metrics.detection import ConfusionMatrix, MeanAveragePrecision
|
||||
from supervision.tracker.byte_tracker.core import ByteTrack
|
||||
from supervision.utils.conversion import cv2_to_pillow, pillow_to_cv2
|
||||
from supervision.utils.file import list_files_with_extensions
|
||||
from supervision.utils.image import (
|
||||
ImageSink,
|
||||
create_tiles,
|
||||
crop_image,
|
||||
grayscale_image,
|
||||
letterbox_image,
|
||||
overlay_image,
|
||||
resize_image,
|
||||
scale_image,
|
||||
tint_image,
|
||||
)
|
||||
from supervision.utils.notebook import plot_image, plot_images_grid
|
||||
from supervision.utils.video import (
|
||||
@@ -205,7 +209,6 @@ __all__ = [
|
||||
"clip_boxes",
|
||||
"contains_holes",
|
||||
"contains_multiple_segments",
|
||||
"create_tiles",
|
||||
"crop_image",
|
||||
"cv2_to_pillow",
|
||||
"draw_filled_polygon",
|
||||
@@ -215,10 +218,14 @@ __all__ = [
|
||||
"draw_polygon",
|
||||
"draw_rectangle",
|
||||
"draw_text",
|
||||
"edit_distance",
|
||||
"filter_polygons_by_area",
|
||||
"filter_segments_by_distance",
|
||||
"fuzzy_match_index",
|
||||
"get_coco_class_index_mapping",
|
||||
"get_polygon_center",
|
||||
"get_video_frames_generator",
|
||||
"grayscale_image",
|
||||
"letterbox_image",
|
||||
"list_files_with_extensions",
|
||||
"mask_iou_batch",
|
||||
@@ -242,8 +249,10 @@ __all__ = [
|
||||
"rle_to_mask",
|
||||
"scale_boxes",
|
||||
"scale_image",
|
||||
"tint_image",
|
||||
"xcycwh_to_xyxy",
|
||||
"xywh_to_xyxy",
|
||||
"xyxy_to_mask",
|
||||
"xyxy_to_polygons",
|
||||
"xyxy_to_xcycarh",
|
||||
"xyxy_to_xywh",
|
||||
|
||||
@@ -1,19 +1,7 @@
|
||||
from abc import ABC, abstractmethod
|
||||
from typing import TypeVar
|
||||
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
|
||||
ImageType = TypeVar("ImageType", np.ndarray, Image.Image)
|
||||
"""
|
||||
An image of type `np.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
Unlike a `Union`, ensures the type remains consistent. If a function
|
||||
takes an `ImageType` argument and returns an `ImageType`, when you
|
||||
pass an `np.ndarray`, you will get an `np.ndarray` back.
|
||||
"""
|
||||
from supervision.draw.base import ImageType
|
||||
|
||||
|
||||
class BaseAnnotator(ABC):
|
||||
|
||||
+208
-53
@@ -7,8 +7,9 @@ import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
from PIL import Image, ImageDraw, ImageFont
|
||||
from scipy.interpolate import splev, splprep
|
||||
|
||||
from supervision.annotators.base import BaseAnnotator, ImageType
|
||||
from supervision.annotators.base import BaseAnnotator
|
||||
from supervision.annotators.utils import (
|
||||
PENDING_TRACK_ID,
|
||||
ColorLookup,
|
||||
@@ -28,12 +29,13 @@ from supervision.detection.utils.converters import (
|
||||
polygon_to_mask,
|
||||
xyxy_to_polygons,
|
||||
)
|
||||
from supervision.draw.base import ImageType
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import draw_polygon, draw_rounded_rectangle, draw_text
|
||||
from supervision.geometry.core import Point, Position, Rect
|
||||
from supervision.utils.conversion import (
|
||||
ensure_cv2_image_for_annotation,
|
||||
ensure_pil_image_for_annotation,
|
||||
ensure_cv2_image_for_class_method,
|
||||
ensure_pil_image_for_class_method,
|
||||
)
|
||||
from supervision.utils.image import (
|
||||
crop_image,
|
||||
@@ -51,25 +53,28 @@ class _BaseLabelAnnotator(BaseAnnotator):
|
||||
|
||||
Attributes:
|
||||
color (Union[Color, ColorPalette]): The color to use for the label background.
|
||||
color_lookup (ColorLookup): The method used to determine the color of the label.
|
||||
text_color (Union[Color, ColorPalette]): The color to use for the label text.
|
||||
text_padding (int): The padding around the label text, in pixels.
|
||||
text_anchor (Position): The position of the text relative to the detection
|
||||
bounding box.
|
||||
color_lookup (ColorLookup): The method used to determine the color of the label.
|
||||
bounding box.
|
||||
text_offset (Tuple[int, int]): A tuple of 2D coordinates `(x, y)` to
|
||||
offset the text position from the anchor point, in pixels.
|
||||
border_radius (int): The radius of the label background corners, in pixels.
|
||||
smart_position (bool): Whether to intelligently adjust the label position to
|
||||
avoid overlapping with other elements.
|
||||
avoid overlapping with other elements.
|
||||
max_line_length (Optional[int]): Maximum number of characters per line before
|
||||
wrapping the text. None means no wrapping.
|
||||
wrapping the text. None means no wrapping.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Color | ColorPalette = ColorPalette.DEFAULT,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
text_color: Color | ColorPalette = Color.WHITE,
|
||||
text_padding: int = 10,
|
||||
text_position: Position = Position.TOP_LEFT,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
text_offset: tuple[int, int] = (0, 0),
|
||||
border_radius: int = 0,
|
||||
smart_position: bool = False,
|
||||
max_line_length: int | None = None,
|
||||
@@ -79,27 +84,29 @@ class _BaseLabelAnnotator(BaseAnnotator):
|
||||
|
||||
Args:
|
||||
color (Union[Color, ColorPalette], optional): The color to use for the label
|
||||
background.
|
||||
background.
|
||||
color_lookup (ColorLookup, optional): The method used to determine the color
|
||||
of the label
|
||||
text_color (Union[Color, ColorPalette], optional): The color to use for the
|
||||
label text.
|
||||
label text.
|
||||
text_padding (int, optional): The padding around the label text, in pixels.
|
||||
text_position (Position, optional): The position of the text relative to the
|
||||
detection bounding box.
|
||||
color_lookup (ColorLookup, optional): The method used to determine the color
|
||||
of the label
|
||||
detection bounding box.
|
||||
text_offset (Tuple[int, int], optional): A tuple of 2D coordinates
|
||||
`(x, y)` to offset the text position from the anchor point, in pixels.
|
||||
border_radius (int, optional): The radius of the label background corners,
|
||||
in pixels.
|
||||
in pixels.
|
||||
smart_position (bool, optional): Whether to intelligently adjust the label
|
||||
position to avoid overlapping with other elements.
|
||||
position to avoid overlapping with other elements.
|
||||
max_line_length (Optional[int], optional): Maximum number of characters per
|
||||
line before wrapping the text. None means no wrapping.
|
||||
|
||||
line before wrapping the text. None means no wrapping.
|
||||
"""
|
||||
self.color: Color | ColorPalette = color
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
self.text_color: Color | ColorPalette = text_color
|
||||
self.text_padding: int = text_padding
|
||||
self.text_anchor: Position = text_position
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
self.text_offset: tuple[int, int] = text_offset
|
||||
self.border_radius: int = border_radius
|
||||
self.smart_position = smart_position
|
||||
self.max_line_length: int | None = max_line_length
|
||||
@@ -171,7 +178,7 @@ class BoxAnnotator(BaseAnnotator):
|
||||
self.thickness: int = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -254,7 +261,7 @@ class OrientedBoxAnnotator(BaseAnnotator):
|
||||
self.thickness: int = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -343,7 +350,7 @@ class MaskAnnotator(BaseAnnotator):
|
||||
self.opacity = opacity
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -433,7 +440,7 @@ class PolygonAnnotator(BaseAnnotator):
|
||||
self.thickness: int = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -520,7 +527,7 @@ class ColorAnnotator(BaseAnnotator):
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
self.opacity = opacity
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -616,7 +623,7 @@ class HaloAnnotator(BaseAnnotator):
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
self.kernel_size: int = kernel_size
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -716,7 +723,7 @@ class EllipseAnnotator(BaseAnnotator):
|
||||
self.end_angle: int = end_angle
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -808,7 +815,7 @@ class BoxCornerAnnotator(BaseAnnotator):
|
||||
self.corner_length: int = corner_length
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -897,7 +904,7 @@ class CircleAnnotator(BaseAnnotator):
|
||||
self.thickness: int = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -996,7 +1003,7 @@ class DotAnnotator(BaseAnnotator):
|
||||
self.outline_thickness = outline_thickness
|
||||
self.outline_color: Color | ColorPalette = outline_color
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -1076,37 +1083,100 @@ class LabelAnnotator(_BaseLabelAnnotator):
|
||||
def __init__(
|
||||
self,
|
||||
color: Color | ColorPalette = ColorPalette.DEFAULT,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
text_color: Color | ColorPalette = Color.WHITE,
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
text_position: Position = Position.TOP_LEFT,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
text_offset: tuple[int, int] = (0, 0),
|
||||
border_radius: int = 0,
|
||||
smart_position: bool = False,
|
||||
max_line_length: int | None = None,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating the text background.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
text_color (Union[Color, ColorPalette]): The color or color palette to use
|
||||
for the text.
|
||||
text_scale (float): Font scale for the text.
|
||||
text_thickness (int): Thickness of the text characters.
|
||||
text_padding (int): Padding around the text within its background box.
|
||||
text_position (Position): Position of the text relative to the detection.
|
||||
Possible values are defined in the `Position` enum.
|
||||
text_offset (Tuple[int, int]): A tuple of 2D coordinates `(x, y)` to
|
||||
offset the text position from the anchor point, in pixels.
|
||||
border_radius (int): The radius to apply round edges. If the selected
|
||||
value is higher than the lower dimension, width or height, is clipped.
|
||||
smart_position (bool): Spread out the labels to avoid overlapping.
|
||||
max_line_length (Optional[int]): Maximum number of characters per line
|
||||
before wrapping the text. None means no wrapping.
|
||||
"""
|
||||
self.text_scale: float = text_scale
|
||||
self.text_thickness: int = text_thickness
|
||||
super().__init__(
|
||||
color=color,
|
||||
color_lookup=color_lookup,
|
||||
text_color=text_color,
|
||||
text_padding=text_padding,
|
||||
text_position=text_position,
|
||||
color_lookup=color_lookup,
|
||||
text_offset=text_offset,
|
||||
border_radius=border_radius,
|
||||
smart_position=smart_position,
|
||||
max_line_length=max_line_length,
|
||||
)
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType, # Ensure scene is initially a NumPy array here
|
||||
scene: ImageType,
|
||||
detections: Detections,
|
||||
labels: list[str] | None = None,
|
||||
custom_color_lookup: np.ndarray | None = None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotates the given scene with labels based on the provided detections.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where labels will be drawn.
|
||||
`ImageType` is a flexible type, accepting either `numpy.ndarray`
|
||||
or `PIL.Image.Image`.
|
||||
detections (Detections): Object detections to annotate.
|
||||
labels (Optional[List[str]]): Custom labels for each detection.
|
||||
custom_color_lookup (Optional[np.ndarray]): Custom color lookup array.
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
assert isinstance(scene, np.ndarray)
|
||||
validate_labels(labels, detections)
|
||||
|
||||
@@ -1144,7 +1214,12 @@ class LabelAnnotator(_BaseLabelAnnotator):
|
||||
anchor=self.text_anchor
|
||||
).astype(int)
|
||||
|
||||
for label, center_coords in zip(labels, anchors_coordinates):
|
||||
for label, center_coordinates in zip(labels, anchors_coordinates):
|
||||
center_coordinates = (
|
||||
center_coordinates[0] + self.text_offset[0],
|
||||
center_coordinates[1] + self.text_offset[1],
|
||||
)
|
||||
|
||||
wrapped_lines = wrap_text(label, self.max_line_length)
|
||||
line_heights = []
|
||||
line_widths = []
|
||||
@@ -1170,7 +1245,7 @@ class LabelAnnotator(_BaseLabelAnnotator):
|
||||
height_padded = total_height + 2 * self.text_padding
|
||||
|
||||
text_background_xyxy = resolve_text_background_xyxy(
|
||||
center_coordinates=tuple(center_coords),
|
||||
center_coordinates=center_coordinates,
|
||||
text_wh=(width_padded, height_padded),
|
||||
position=self.text_anchor,
|
||||
)
|
||||
@@ -1317,31 +1392,54 @@ class RichLabelAnnotator(_BaseLabelAnnotator):
|
||||
def __init__(
|
||||
self,
|
||||
color: Color | ColorPalette = ColorPalette.DEFAULT,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
text_color: Color | ColorPalette = Color.WHITE,
|
||||
font_path: str | None = None,
|
||||
font_size: int = 10,
|
||||
text_padding: int = 10,
|
||||
text_position: Position = Position.TOP_LEFT,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
text_offset: tuple[int, int] = (0, 0),
|
||||
border_radius: int = 0,
|
||||
smart_position: bool = False,
|
||||
max_line_length: int | None = None,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating the text background.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
text_color (Union[Color, ColorPalette]): The color to use for the text.
|
||||
font_path (Optional[str]): Path to the font file (e.g., ".ttf" or ".otf")
|
||||
to use for rendering text. If `None`, the default PIL font will be used.
|
||||
font_size (int): Font size for the text.
|
||||
text_padding (int): Padding around the text within its background box.
|
||||
text_position (Position): Position of the text relative to the detection.
|
||||
Possible values are defined in the `Position` enum.
|
||||
text_offset (Tuple[int, int]): A tuple of 2D coordinates `(x, y)` to
|
||||
offset the text position from the anchor point, in pixels.
|
||||
border_radius (int): The radius to apply round edges. If the selected
|
||||
value is higher than the lower dimension, width or height, is clipped.
|
||||
smart_position (bool): Spread out the labels to avoid overlapping.
|
||||
max_line_length (Optional[int]): Maximum number of characters per line
|
||||
before wrapping the text. None means no wrapping.
|
||||
"""
|
||||
self.font_path = font_path
|
||||
self.font_size = font_size
|
||||
self.font = self._load_font(font_size, font_path)
|
||||
super().__init__(
|
||||
color=color,
|
||||
color_lookup=color_lookup,
|
||||
text_color=text_color,
|
||||
text_padding=text_padding,
|
||||
text_position=text_position,
|
||||
color_lookup=color_lookup,
|
||||
text_offset=text_offset,
|
||||
border_radius=border_radius,
|
||||
smart_position=smart_position,
|
||||
max_line_length=max_line_length,
|
||||
)
|
||||
|
||||
@ensure_pil_image_for_annotation
|
||||
@ensure_pil_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -1349,6 +1447,44 @@ class RichLabelAnnotator(_BaseLabelAnnotator):
|
||||
labels: list[str] | None = None,
|
||||
custom_color_lookup: np.ndarray | None = None,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene with labels based on the provided
|
||||
detections, with support for Unicode characters.
|
||||
|
||||
Args:
|
||||
scene (ImageType): The image where labels will be drawn.
|
||||
`ImageType` is a flexible type, accepting either `numpy.ndarray`
|
||||
or `PIL.Image.Image`.
|
||||
detections (Detections): Object detections to annotate.
|
||||
labels (Optional[List[str]]): Custom labels for each detection.
|
||||
custom_color_lookup (Optional[np.ndarray]): Custom color lookup array.
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
The annotated image, matching the type of `scene` (`numpy.ndarray`
|
||||
or `PIL.Image.Image`)
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
rich_label_annotator = sv.RichLabelAnnotator(font_path="path/to/font.ttf")
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
"""
|
||||
assert isinstance(scene, Image.Image)
|
||||
validate_labels(labels, detections)
|
||||
|
||||
@@ -1386,7 +1522,12 @@ class RichLabelAnnotator(_BaseLabelAnnotator):
|
||||
anchor=self.text_anchor
|
||||
).astype(int)
|
||||
|
||||
for label, center_coords in zip(labels, anchor_coordinates):
|
||||
for label, center_coordinates in zip(labels, anchor_coordinates):
|
||||
center_coordinates = (
|
||||
center_coordinates[0] + self.text_offset[0],
|
||||
center_coordinates[1] + self.text_offset[1],
|
||||
)
|
||||
|
||||
wrapped_lines = wrap_text(label, self.max_line_length)
|
||||
|
||||
# Calculate the total text height and maximum width
|
||||
@@ -1409,7 +1550,7 @@ class RichLabelAnnotator(_BaseLabelAnnotator):
|
||||
height_padded = int(total_height + 2 * self.text_padding)
|
||||
|
||||
text_background_xyxy = resolve_text_background_xyxy(
|
||||
center_coordinates=tuple(center_coords),
|
||||
center_coordinates=center_coordinates,
|
||||
text_wh=(width_padded, height_padded),
|
||||
position=self.text_anchor,
|
||||
)
|
||||
@@ -1525,7 +1666,7 @@ class IconAnnotator(BaseAnnotator):
|
||||
self.position = icon_position
|
||||
self.offset_xy = offset_xy
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self, scene: ImageType, detections: Detections, icon_path: str | list[str]
|
||||
) -> ImageType:
|
||||
@@ -1614,7 +1755,7 @@ class BlurAnnotator(BaseAnnotator):
|
||||
"""
|
||||
self.kernel_size: int = kernel_size
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -1681,6 +1822,7 @@ class TraceAnnotator(BaseAnnotator):
|
||||
position: Position = Position.CENTER,
|
||||
trace_length: int = 30,
|
||||
thickness: int = 2,
|
||||
smooth: bool = False,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
):
|
||||
"""
|
||||
@@ -1692,15 +1834,17 @@ class TraceAnnotator(BaseAnnotator):
|
||||
trace_length (int): The maximum length of the trace in terms of historical
|
||||
points. Defaults to `30`.
|
||||
thickness (int): The thickness of the trace lines. Defaults to `2`.
|
||||
smooth (bool): Smooth the trace lines.
|
||||
color_lookup (ColorLookup): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Color | ColorPalette = color
|
||||
self.trace = Trace(max_size=trace_length, anchor=position)
|
||||
self.thickness = thickness
|
||||
self.smooth = smooth
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -1769,10 +1913,18 @@ class TraceAnnotator(BaseAnnotator):
|
||||
else custom_color_lookup,
|
||||
)
|
||||
xy = self.trace.get(tracker_id=tracker_id)
|
||||
spline_points = xy.astype(np.int32)
|
||||
|
||||
if len(xy) > 3 and self.smooth:
|
||||
x, y = xy[:, 0], xy[:, 1]
|
||||
tck, u = splprep([x, y], s=20)
|
||||
x_new, y_new = splev(np.linspace(0, 1, 100), tck)
|
||||
spline_points = np.stack([x_new, y_new], axis=1).astype(np.int32)
|
||||
|
||||
if len(xy) > 1:
|
||||
scene = cv2.polylines(
|
||||
scene,
|
||||
[xy.astype(np.int32)],
|
||||
[spline_points],
|
||||
False,
|
||||
color=color.as_bgr(),
|
||||
thickness=self.thickness,
|
||||
@@ -1814,7 +1966,7 @@ class HeatMapAnnotator(BaseAnnotator):
|
||||
self.low_hue = low_hue
|
||||
self.heat_mask: npt.NDArray[np.float32] | None = None
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(self, scene: ImageType, detections: Detections) -> ImageType:
|
||||
"""
|
||||
Annotates the scene with a heatmap based on the provided detections.
|
||||
@@ -1896,7 +2048,7 @@ class PixelateAnnotator(BaseAnnotator):
|
||||
"""
|
||||
self.pixel_size: int = pixel_size
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -1993,7 +2145,7 @@ class TriangleAnnotator(BaseAnnotator):
|
||||
self.outline_thickness: int = outline_thickness
|
||||
self.outline_color: Color | ColorPalette = outline_color
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -2105,7 +2257,7 @@ class RoundBoxAnnotator(BaseAnnotator):
|
||||
raise ValueError("roundness attribute must be float between (0, 1.0]")
|
||||
self.roundness: float = roundness
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -2239,10 +2391,13 @@ class PercentageBarAnnotator(BaseAnnotator):
|
||||
self.position: Position = position
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
if border_thickness is None:
|
||||
self.border_thickness = int(0.15 * self.height)
|
||||
self.border_thickness = (
|
||||
border_thickness
|
||||
if border_thickness is not None
|
||||
else int(0.15 * self.height)
|
||||
)
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -2423,7 +2578,7 @@ class CropAnnotator(BaseAnnotator):
|
||||
self.border_thickness: int = border_thickness
|
||||
self.border_color_lookup: ColorLookup = border_color_lookup
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self,
|
||||
scene: ImageType,
|
||||
@@ -2572,7 +2727,7 @@ class BackgroundOverlayAnnotator(BaseAnnotator):
|
||||
self.opacity = opacity
|
||||
self.force_box = force_box
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(self, scene: ImageType, detections: Detections) -> ImageType:
|
||||
"""
|
||||
Applies a colored overlay to the scene outside of the detected regions.
|
||||
@@ -2670,7 +2825,7 @@ class ComparisonAnnotator:
|
||||
self.label_scale = label_scale
|
||||
self.text_thickness = int(self.label_scale + 1.2)
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(
|
||||
self, scene: ImageType, detections_1: Detections, detections_2: Detections
|
||||
) -> ImageType:
|
||||
|
||||
@@ -2,6 +2,7 @@ from __future__ import annotations
|
||||
|
||||
import textwrap
|
||||
from enum import Enum
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
|
||||
@@ -142,35 +143,45 @@ def resolve_color(
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=color_lookup,
|
||||
)
|
||||
if color_lookup == ColorLookup.TRACK and idx == PENDING_TRACK_ID:
|
||||
if (
|
||||
isinstance(color_lookup, ColorLookup)
|
||||
and color_lookup == ColorLookup.TRACK
|
||||
and idx == PENDING_TRACK_ID
|
||||
):
|
||||
return PENDING_TRACK_COLOR
|
||||
return get_color_by_index(color=color, idx=idx)
|
||||
|
||||
|
||||
def wrap_text(text: str, max_line_length=None) -> list[str]:
|
||||
def wrap_text(text: Any, max_line_length=None) -> list[str]:
|
||||
"""
|
||||
Wraps text to the specified maximum line length, respecting existing newlines.
|
||||
Uses the textwrap library for robust text wrapping.
|
||||
Wrap `text` to the specified maximum line length, respecting existing
|
||||
newlines. Falls back to str() if `text` is not already a string.
|
||||
|
||||
Args:
|
||||
text (str): The text to wrap.
|
||||
text (Any): The text (or object) to wrap.
|
||||
max_line_length (int | None): Maximum width for each wrapped line.
|
||||
|
||||
Returns:
|
||||
List[str]: A list of text lines after wrapping.
|
||||
list[str]: Wrapped lines.
|
||||
"""
|
||||
|
||||
if not text:
|
||||
return [""]
|
||||
|
||||
if not isinstance(text, str):
|
||||
text = str(text)
|
||||
|
||||
if max_line_length is None:
|
||||
return text.splitlines() or [""]
|
||||
|
||||
if max_line_length <= 0:
|
||||
raise ValueError("max_line_length must be a positive integer")
|
||||
|
||||
paragraphs = text.split("\n")
|
||||
all_lines = []
|
||||
all_lines: list[str] = []
|
||||
|
||||
for paragraph in paragraphs:
|
||||
if not paragraph:
|
||||
# Keep empty lines
|
||||
if paragraph == "":
|
||||
all_lines.append("")
|
||||
continue
|
||||
|
||||
@@ -182,12 +193,9 @@ def wrap_text(text: str, max_line_length=None) -> list[str]:
|
||||
drop_whitespace=True,
|
||||
)
|
||||
|
||||
if wrapped:
|
||||
all_lines.extend(wrapped)
|
||||
else:
|
||||
all_lines.append("")
|
||||
all_lines.extend(wrapped or [""])
|
||||
|
||||
return all_lines if all_lines else [""]
|
||||
return all_lines or [""]
|
||||
|
||||
|
||||
def validate_labels(labels: list[str] | None, detections: Detections):
|
||||
|
||||
@@ -40,6 +40,7 @@ from supervision.detection.utils.masks import calculate_masks_centroids
|
||||
from supervision.detection.vlm import (
|
||||
LMM,
|
||||
VLM,
|
||||
from_deepseek_vl_2,
|
||||
from_florence_2,
|
||||
from_google_gemini_2_0,
|
||||
from_google_gemini_2_5,
|
||||
@@ -830,6 +831,7 @@ class Detections:
|
||||
| Google Gemini 2.0 | `GOOGLE_GEMINI_2_0` | detection | `resolution_wh` | `classes` |
|
||||
| Google Gemini 2.5 | `GOOGLE_GEMINI_2_5` | detection, segmentation | `resolution_wh` | `classes` |
|
||||
| Moondream | `MOONDREAM` | detection | `resolution_wh` | |
|
||||
| DeepSeek-VL2 | `DEEPSEEK_VL_2` | detection | `resolution_wh` | `classes` |
|
||||
|
||||
Args:
|
||||
lmm (Union[LMM, str]): The type of LMM (Large Multimodal Model) to use.
|
||||
@@ -1117,6 +1119,47 @@ class Detections:
|
||||
# array([[1752.28, 818.82, 2165.72, 1229.14],
|
||||
# [1908.01, 1346.67, 2585.99, 2024.11]])
|
||||
```
|
||||
|
||||
!!! example "DeepSeek-VL2"
|
||||
|
||||
|
||||
??? tip "Prompt engineering"
|
||||
|
||||
To get the best results from DeepSeek-VL2, use optimized prompts that leverage
|
||||
its object detection and visual grounding capabilities effectively.
|
||||
|
||||
**For general object detection, use the following user prompt:**
|
||||
|
||||
```
|
||||
<image>\\n<|ref|>The giraffe at the front<|/ref|>
|
||||
```
|
||||
|
||||
**For visual grounding, use the following user prompt:**
|
||||
|
||||
```
|
||||
<image>\\n<|grounding|>Detect the giraffes
|
||||
```
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
deepseek_vl2_result = "<|ref|>The giraffe at the back<|/ref|><|det|>[[580, 270, 999, 904]]<|/det|><|ref|>The giraffe at the front<|/ref|><|det|>[[26, 31, 632, 998]]<|/det|><|end▁of▁sentence|>"
|
||||
|
||||
detections = sv.Detections.from_vlm(
|
||||
vlm=sv.VLM.DEEPSEEK_VL_2, result=deepseek_vl2_result, resolution_wh=image.size
|
||||
)
|
||||
|
||||
detections.xyxy
|
||||
# array([[ 420, 293, 724, 982],
|
||||
# [ 18, 33, 458, 1084]])
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['The giraffe at the back', 'The giraffe at the front'], dtype='<U24')}
|
||||
```
|
||||
""" # noqa: E501
|
||||
|
||||
# filler logic mapping old from_lmm to new from_vlm
|
||||
@@ -1124,6 +1167,7 @@ class Detections:
|
||||
LMM.PALIGEMMA: VLM.PALIGEMMA,
|
||||
LMM.FLORENCE_2: VLM.FLORENCE_2,
|
||||
LMM.QWEN_2_5_VL: VLM.QWEN_2_5_VL,
|
||||
LMM.DEEPSEEK_VL_2: VLM.DEEPSEEK_VL_2,
|
||||
LMM.GOOGLE_GEMINI_2_0: VLM.GOOGLE_GEMINI_2_0,
|
||||
LMM.GOOGLE_GEMINI_2_5: VLM.GOOGLE_GEMINI_2_5,
|
||||
}
|
||||
@@ -1164,6 +1208,7 @@ class Detections:
|
||||
| Google Gemini 2.0 | `GOOGLE_GEMINI_2_0` | detection | `resolution_wh` | `classes` |
|
||||
| Google Gemini 2.5 | `GOOGLE_GEMINI_2_5` | detection, segmentation | `resolution_wh` | `classes` |
|
||||
| Moondream | `MOONDREAM` | detection | `resolution_wh` | |
|
||||
| DeepSeek-VL2 | `DEEPSEEK_VL_2` | detection | `resolution_wh` | `classes` |
|
||||
|
||||
Args:
|
||||
vlm (Union[VLM, str]): The type of VLM (Vision Language Model) to use.
|
||||
@@ -1452,6 +1497,47 @@ class Detections:
|
||||
# [1908.01, 1346.67, 2585.99, 2024.11]])
|
||||
```
|
||||
|
||||
!!! example "DeepSeek-VL2"
|
||||
|
||||
|
||||
??? tip "Prompt engineering"
|
||||
|
||||
To get the best results from DeepSeek-VL2, use optimized prompts that leverage
|
||||
its object detection and visual grounding capabilities effectively.
|
||||
|
||||
**For general object detection, use the following user prompt:**
|
||||
|
||||
```
|
||||
<image>\\n<|ref|>The giraffe at the front<|/ref|>
|
||||
```
|
||||
|
||||
**For visual grounding, use the following user prompt:**
|
||||
|
||||
```
|
||||
<image>\\n<|grounding|>Detect the giraffes
|
||||
```
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
deepseek_vl2_result = "<|ref|>The giraffe at the back<|/ref|><|det|>[[580, 270, 999, 904]]<|/det|><|ref|>The giraffe at the front<|/ref|><|det|>[[26, 31, 632, 998]]<|/det|><|end▁of▁sentence|>"
|
||||
|
||||
detections = sv.Detections.from_vlm(
|
||||
vlm=sv.VLM.DEEPSEEK_VL_2, result=deepseek_vl2_result, resolution_wh=image.size
|
||||
)
|
||||
|
||||
detections.xyxy
|
||||
# array([[ 420, 293, 724, 982],
|
||||
# [ 18, 33, 458, 1084]])
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['The giraffe at the back', 'The giraffe at the front'], dtype='<U24')}
|
||||
```
|
||||
|
||||
""" # noqa: E501
|
||||
|
||||
vlm = validate_vlm_parameters(vlm, result, kwargs)
|
||||
@@ -1466,6 +1552,11 @@ class Detections:
|
||||
data = {CLASS_NAME_DATA_FIELD: class_name}
|
||||
return cls(xyxy=xyxy, class_id=class_id, data=data)
|
||||
|
||||
if vlm == VLM.DEEPSEEK_VL_2:
|
||||
xyxy, class_id, class_name = from_deepseek_vl_2(result, **kwargs)
|
||||
data = {CLASS_NAME_DATA_FIELD: class_name}
|
||||
return cls(xyxy=xyxy, class_id=class_id, data=data)
|
||||
|
||||
if vlm == VLM.FLORENCE_2:
|
||||
xyxy, labels, mask, xyxyxyxy = from_florence_2(result, **kwargs)
|
||||
if len(xyxy) == 0:
|
||||
@@ -1939,8 +2030,8 @@ class Detections:
|
||||
class_agnostic (bool): Whether to perform class-agnostic
|
||||
non-maximum suppression. If True, the class_id of each detection
|
||||
will be ignored. Defaults to False.
|
||||
overlap_metric (OverlapMetric): Metric used for measuring overlap between
|
||||
detections in slices.
|
||||
overlap_metric (OverlapMetric): Metric used to compute the degree of
|
||||
overlap between pairs of masks or boxes (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object containing the subset of detections
|
||||
@@ -2003,8 +2094,8 @@ class Detections:
|
||||
class_agnostic (bool): Whether to perform class-agnostic
|
||||
non-maximum merging. If True, the class_id of each detection
|
||||
will be ignored. Defaults to False.
|
||||
overlap_metric (OverlapMetric): Metric used for measuring overlap between
|
||||
detections in slices.
|
||||
overlap_metric (OverlapMetric): Metric used to compute the degree of
|
||||
overlap between pairs of masks or boxes (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object containing the subset of detections
|
||||
|
||||
@@ -9,7 +9,7 @@ import numpy as np
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils.boxes import move_boxes, move_oriented_boxes
|
||||
from supervision.detection.utils.iou_and_nms import OverlapFilter
|
||||
from supervision.detection.utils.iou_and_nms import OverlapFilter, OverlapMetric
|
||||
from supervision.detection.utils.masks import move_masks
|
||||
from supervision.utils.image import crop_image
|
||||
from supervision.utils.internal import (
|
||||
@@ -75,8 +75,8 @@ class InferenceSlicer:
|
||||
filtering or merging overlapping detections in slices.
|
||||
iou_threshold (float): Intersection over Union (IoU) threshold
|
||||
used when filtering by overlap.
|
||||
match_metric (str): Metric used for matching detections in slices.
|
||||
"IOU" or "IOS". Defaults "IOU".
|
||||
overlap_metric (Union[OverlapMetric, str]): Metric used for matching detections
|
||||
in slices.
|
||||
callback (Callable): A function that performs inference on a given image
|
||||
slice and returns detections.
|
||||
thread_workers (int): Number of threads for parallel execution.
|
||||
@@ -96,7 +96,7 @@ class InferenceSlicer:
|
||||
overlap_wh: tuple[int, int] | None = None,
|
||||
overlap_filter: OverlapFilter | str = OverlapFilter.NON_MAX_SUPPRESSION,
|
||||
iou_threshold: float = 0.5,
|
||||
match_metric: str = "IOU",
|
||||
overlap_metric: OverlapMetric | str = OverlapMetric.IOU,
|
||||
thread_workers: int = 1,
|
||||
):
|
||||
if overlap_ratio_wh is not None:
|
||||
@@ -112,7 +112,7 @@ class InferenceSlicer:
|
||||
|
||||
self.slice_wh = slice_wh
|
||||
self.iou_threshold = iou_threshold
|
||||
self.match_metric = match_metric
|
||||
self.overlap_metric = OverlapMetric.from_value(overlap_metric)
|
||||
self.overlap_filter = OverlapFilter.from_value(overlap_filter)
|
||||
self.callback = callback
|
||||
self.thread_workers = thread_workers
|
||||
@@ -173,11 +173,11 @@ class InferenceSlicer:
|
||||
return merged
|
||||
elif self.overlap_filter == OverlapFilter.NON_MAX_SUPPRESSION:
|
||||
return merged.with_nms(
|
||||
threshold=self.iou_threshold, match_metric=self.match_metric
|
||||
threshold=self.iou_threshold, overlap_metric=self.overlap_metric
|
||||
)
|
||||
elif self.overlap_filter == OverlapFilter.NON_MAX_MERGE:
|
||||
return merged.with_nmm(
|
||||
threshold=self.iou_threshold, match_metric=self.match_metric
|
||||
threshold=self.iou_threshold, overlap_metric=self.overlap_metric
|
||||
)
|
||||
else:
|
||||
warnings.warn(
|
||||
|
||||
@@ -0,0 +1,3 @@
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch
|
||||
|
||||
__all__ = ["box_iou_batch"]
|
||||
|
||||
@@ -229,6 +229,70 @@ def mask_to_xyxy(masks: np.ndarray) -> np.ndarray:
|
||||
return xyxy
|
||||
|
||||
|
||||
def xyxy_to_mask(boxes: np.ndarray, resolution_wh: tuple[int, int]) -> np.ndarray:
|
||||
"""
|
||||
Converts a 2D `np.ndarray` of bounding boxes into a 3D `np.ndarray` of bool masks.
|
||||
|
||||
Parameters:
|
||||
boxes (np.ndarray): A 2D `np.ndarray` of shape `(N, 4)`
|
||||
containing bounding boxes `(x_min, y_min, x_max, y_max)`
|
||||
resolution_wh (Tuple[int, int]): A tuple `(width, height)` specifying
|
||||
the resolution of the output masks
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 3D `np.ndarray` of shape `(N, height, width)`
|
||||
containing 2D bool masks for each bounding box
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
boxes = np.array([[0, 0, 2, 2]])
|
||||
|
||||
sv.xyxy_to_mask(boxes, (5, 5))
|
||||
# array([
|
||||
# [[ True, True, True, False, False],
|
||||
# [ True, True, True, False, False],
|
||||
# [ True, True, True, False, False],
|
||||
# [False, False, False, False, False],
|
||||
# [False, False, False, False, False]]
|
||||
# ])
|
||||
|
||||
boxes = np.array([[0, 0, 1, 1], [3, 3, 4, 4]])
|
||||
|
||||
sv.xyxy_to_mask(boxes, (5, 5))
|
||||
# array([
|
||||
# [[ True, True, False, False, False],
|
||||
# [ True, True, False, False, False],
|
||||
# [False, False, False, False, False],
|
||||
# [False, False, False, False, False],
|
||||
# [False, False, False, False, False]],
|
||||
#
|
||||
# [[False, False, False, False, False],
|
||||
# [False, False, False, False, False],
|
||||
# [False, False, False, False, False],
|
||||
# [False, False, False, True, True],
|
||||
# [False, False, False, True, True]]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
width, height = resolution_wh
|
||||
n = boxes.shape[0]
|
||||
masks = np.zeros((n, height, width), dtype=bool)
|
||||
|
||||
for i, (x_min, y_min, x_max, y_max) in enumerate(boxes):
|
||||
x_min = max(0, int(x_min))
|
||||
y_min = max(0, int(y_min))
|
||||
x_max = min(width - 1, int(x_max))
|
||||
y_max = min(height - 1, int(y_max))
|
||||
|
||||
if x_max >= x_min and y_max >= y_min:
|
||||
masks[i, y_min : y_max + 1, x_min : x_max + 1] = True
|
||||
|
||||
return masks
|
||||
|
||||
|
||||
def mask_to_polygons(mask: np.ndarray) -> list[np.ndarray]:
|
||||
"""
|
||||
Converts a binary mask to a list of polygons.
|
||||
|
||||
@@ -271,7 +271,6 @@ def merge_metadata(metadata_list: list[dict[str, Any]]) -> dict[str, Any]:
|
||||
"{type(value)}, {type(other_value)}."
|
||||
)
|
||||
else:
|
||||
print("hm")
|
||||
if merged_metadata[key] != value:
|
||||
raise ValueError(f"Conflicting metadata for key: '{key}'.")
|
||||
|
||||
|
||||
@@ -164,7 +164,8 @@ def box_iou_batch(
|
||||
`shape = (N, 4)` where `N` is number of true objects.
|
||||
boxes_detection (np.ndarray): 2D `np.ndarray` representing detection boxes.
|
||||
`shape = (M, 4)` where `M` is number of detected objects.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
overlap_metric (OverlapMetric): Metric used to compute the degree of overlap
|
||||
between pairs of boxes (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of boxes from `boxes_true` and `boxes_detection`.
|
||||
@@ -381,7 +382,8 @@ def _mask_iou_batch_split(
|
||||
Args:
|
||||
masks_true (np.ndarray): 3D `np.ndarray` representing ground-truth masks.
|
||||
masks_detection (np.ndarray): 3D `np.ndarray` representing detection masks.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
overlap_metric (OverlapMetric): Metric used to compute the degree of overlap
|
||||
between pairs of masks (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of masks from `masks_true` and `masks_detection`.
|
||||
@@ -433,7 +435,8 @@ def mask_iou_batch(
|
||||
Args:
|
||||
masks_true (np.ndarray): 3D `np.ndarray` representing ground-truth masks.
|
||||
masks_detection (np.ndarray): 3D `np.ndarray` representing detection masks.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
overlap_metric (OverlapMetric): Metric used to compute the degree of overlap
|
||||
between pairs of masks (e.g., IoU, IoS).
|
||||
memory_limit (int): memory limit in MB, default is 1024 * 5 MB (5GB).
|
||||
|
||||
Returns:
|
||||
@@ -492,7 +495,8 @@ def mask_non_max_suppression(
|
||||
dimensions of each mask.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
overlap_metric (OverlapMetric): Metric used to compute the degree of overlap
|
||||
between pairs of masks (e.g., IoU, IoS).
|
||||
mask_dimension (int): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
|
||||
@@ -543,7 +547,8 @@ def box_non_max_suppression(
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
overlap_metric (OverlapMetric): Metric used to compute the degree of overlap
|
||||
between pairs of boxes (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after n
|
||||
@@ -603,7 +608,8 @@ def _group_overlapping_masks(
|
||||
the predictions.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
overlap_metric (OverlapMetric): Metric used to compute the degree of overlap
|
||||
between pairs of masks (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
@@ -664,7 +670,8 @@ def mask_non_max_merge(
|
||||
to use for non-maximum suppression.
|
||||
mask_dimension (int): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
overlap_metric (OverlapMetric): Metric used to compute the degree of overlap
|
||||
between pairs of masks (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after
|
||||
@@ -717,7 +724,8 @@ def _group_overlapping_boxes(
|
||||
and the confidence scores.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
overlap_metric (OverlapMetric): Metric used to compute the degree of overlap
|
||||
between pairs of boxes (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
@@ -765,7 +773,8 @@ def box_non_max_merge(
|
||||
detections of different classes to be merged.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
overlap_metric (OverlapMetric): Metric used to compute the degree of overlap
|
||||
between pairs of boxes (e.g., IoU, IoS).
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
|
||||
@@ -1,5 +1,7 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Literal
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
@@ -260,3 +262,139 @@ def resize_masks(masks: np.ndarray, max_dimension: int = 640) -> np.ndarray:
|
||||
resized_masks = masks[:, yv, xv]
|
||||
|
||||
return resized_masks.reshape(masks.shape[0], new_height, new_width)
|
||||
|
||||
|
||||
def filter_segments_by_distance(
|
||||
mask: npt.NDArray[np.bool_],
|
||||
absolute_distance: float | None = 100.0,
|
||||
relative_distance: float | None = None,
|
||||
connectivity: int = 8,
|
||||
mode: Literal["edge", "centroid"] = "edge",
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
"""
|
||||
Keep the largest connected component and any other components within a distance
|
||||
threshold.
|
||||
|
||||
Distance can be absolute in pixels or relative to the image diagonal.
|
||||
|
||||
Args:
|
||||
mask: Boolean mask HxW.
|
||||
absolute_distance: Max allowed distance in pixels to the main component.
|
||||
Ignored if `relative_distance` is provided.
|
||||
relative_distance: Fraction of the diagonal. If set, threshold = fraction * sqrt(H^2 + W^2).
|
||||
connectivity: Defines which neighboring pixels are considered connected.
|
||||
- 4-connectedness: Only orthogonal neighbors.
|
||||
```
|
||||
[ ][X][ ]
|
||||
[X][O][X]
|
||||
[ ][X][ ]
|
||||
```
|
||||
- 8-connectedness: Includes diagonal neighbors.
|
||||
```
|
||||
[X][X][X]
|
||||
[X][O][X]
|
||||
[X][X][X]
|
||||
```
|
||||
Default is 8.
|
||||
mode: Defines how distance between components is measured.
|
||||
- "edge": Uses distance between nearest edges (via distance transform).
|
||||
- "centroid": Uses distance between component centroids.
|
||||
|
||||
Returns:
|
||||
Boolean mask after filtering.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0, 1, 1, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0, 1, 1, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0, 1, 1, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0, 1, 1, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
], dtype=bool)
|
||||
|
||||
sv.filter_segments_by_distance(
|
||||
mask,
|
||||
absolute_distance=2,
|
||||
mode="edge",
|
||||
connectivity=8
|
||||
).astype(int)
|
||||
|
||||
# np.array([
|
||||
# [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
# [0, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
# [0, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
# [0, 1, 1, 1, 0, 0, 1, 1, 0, 0, 0, 0],
|
||||
# [0, 0, 0, 0, 0, 0, 1, 1, 0, 0, 0, 0],
|
||||
# [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
# [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
# [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
# [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
# [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
# [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
# [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
# ], dtype=bool)
|
||||
|
||||
# The nearby 2×2 block at columns 6–7 is kept because its edge distance
|
||||
# is within 2 pixels. The distant block at columns 9-10 is removed.
|
||||
```
|
||||
""" # noqa E501 // docs
|
||||
if mask.dtype != bool:
|
||||
raise TypeError("mask must be boolean")
|
||||
|
||||
height, width = mask.shape
|
||||
if not np.any(mask):
|
||||
return mask.copy()
|
||||
|
||||
image = mask.astype(np.uint8)
|
||||
num_labels, labels, stats, centroids = cv2.connectedComponentsWithStats(
|
||||
image, connectivity=connectivity
|
||||
)
|
||||
|
||||
if num_labels <= 1:
|
||||
return mask.copy()
|
||||
|
||||
areas = stats[1:, cv2.CC_STAT_AREA]
|
||||
main_label = 1 + int(np.argmax(areas))
|
||||
|
||||
if relative_distance is not None:
|
||||
diagonal = float(np.hypot(height, width))
|
||||
threshold = float(relative_distance) * diagonal
|
||||
else:
|
||||
threshold = float(absolute_distance)
|
||||
|
||||
keep_labels = np.zeros(num_labels, dtype=bool)
|
||||
keep_labels[main_label] = True
|
||||
|
||||
if mode == "centroid":
|
||||
differences = centroids[1:] - centroids[main_label]
|
||||
distances = np.sqrt(np.sum(differences**2, axis=1))
|
||||
nearby = 1 + np.where(distances <= threshold)[0]
|
||||
keep_labels[nearby] = True
|
||||
elif mode == "edge":
|
||||
main_mask = (labels == main_label).astype(np.uint8)
|
||||
inverse = 1 - main_mask
|
||||
distance_transform = cv2.distanceTransform(inverse, cv2.DIST_L2, 3)
|
||||
for label in range(1, num_labels):
|
||||
if label == main_label:
|
||||
continue
|
||||
component = labels == label
|
||||
if not np.any(component):
|
||||
continue
|
||||
min_distance = float(distance_transform[component].min())
|
||||
if min_distance <= threshold:
|
||||
keep_labels[label] = True
|
||||
else:
|
||||
raise ValueError("mode must be 'edge' or 'centroid'")
|
||||
|
||||
return keep_labels[labels]
|
||||
|
||||
@@ -0,0 +1,105 @@
|
||||
from __future__ import annotations
|
||||
|
||||
|
||||
def edit_distance(string_1: str, string_2: str, case_sensitive: bool = True) -> int:
|
||||
"""
|
||||
Calculates the minimum number of single-character edits required
|
||||
to transform one string into another. Allowed operations are insertion,
|
||||
deletion, and substitution.
|
||||
|
||||
Args:
|
||||
string_1 (str): The source string to be transformed.
|
||||
string_2 (str): The target string to transform into.
|
||||
case_sensitive (bool, optional): Whether comparison should be case-sensitive.
|
||||
Defaults to True.
|
||||
|
||||
Returns:
|
||||
int: The minimum number of edits required to convert `string_1`
|
||||
into `string_2`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.edit_distance("hello", "hello")
|
||||
# 0
|
||||
|
||||
sv.edit_distance("Test", "test", case_sensitive=True)
|
||||
# 1
|
||||
|
||||
sv.edit_distance("abc", "xyz")
|
||||
# 3
|
||||
|
||||
sv.edit_distance("hello", "")
|
||||
# 5
|
||||
|
||||
sv.edit_distance("", "")
|
||||
# 0
|
||||
|
||||
sv.edit_distance("hello world", "helloworld")
|
||||
# 1
|
||||
```
|
||||
"""
|
||||
if not case_sensitive:
|
||||
string_1 = string_1.lower()
|
||||
string_2 = string_2.lower()
|
||||
|
||||
if len(string_1) < len(string_2):
|
||||
string_1, string_2 = string_2, string_1
|
||||
|
||||
prev_row = list(range(len(string_2) + 1))
|
||||
curr_row = [0] * (len(string_2) + 1)
|
||||
|
||||
for i in range(1, len(string_1) + 1):
|
||||
curr_row[0] = i
|
||||
for j in range(1, len(string_2) + 1):
|
||||
if string_1[i - 1] == string_2[j - 1]:
|
||||
substitution_cost = 0
|
||||
else:
|
||||
substitution_cost = 1
|
||||
curr_row[j] = min(
|
||||
prev_row[j] + 1,
|
||||
curr_row[j - 1] + 1,
|
||||
prev_row[j - 1] + substitution_cost,
|
||||
)
|
||||
prev_row, curr_row = curr_row, prev_row
|
||||
|
||||
return prev_row[len(string_2)]
|
||||
|
||||
|
||||
def fuzzy_match_index(
|
||||
candidates: list[str],
|
||||
query: str,
|
||||
threshold: int,
|
||||
case_sensitive: bool = True,
|
||||
) -> int | None:
|
||||
"""
|
||||
Searches for the first string in `candidates` whose edit distance
|
||||
to `query` is less than or equal to `threshold`.
|
||||
|
||||
Args:
|
||||
candidates (list[str]): List of strings to search.
|
||||
query (str): String to compare against the candidates.
|
||||
threshold (int): Maximum allowed edit distance for a match.
|
||||
case_sensitive (bool, optional): Whether matching should be case-sensitive.
|
||||
|
||||
Returns:
|
||||
Optional[int]: Index of the first matching string in candidates,
|
||||
or None if no match is found.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
fuzzy_match_index(["cat", "dog", "rat"], "dat", threshold=1)
|
||||
# 0
|
||||
|
||||
fuzzy_match_index(["alpha", "beta", "gamma"], "bata", threshold=1)
|
||||
# 1
|
||||
|
||||
fuzzy_match_index(["one", "two", "three"], "ten", threshold=2)
|
||||
# None
|
||||
```
|
||||
"""
|
||||
for idx, candidate in enumerate(candidates):
|
||||
if edit_distance(candidate, query, case_sensitive=case_sensitive) <= threshold:
|
||||
return idx
|
||||
return None
|
||||
@@ -36,6 +36,7 @@ class LMM(Enum):
|
||||
PALIGEMMA = "paligemma"
|
||||
FLORENCE_2 = "florence_2"
|
||||
QWEN_2_5_VL = "qwen_2_5_vl"
|
||||
DEEPSEEK_VL_2 = "deepseek_vl_2"
|
||||
GOOGLE_GEMINI_2_0 = "gemini_2_0"
|
||||
GOOGLE_GEMINI_2_5 = "gemini_2_5"
|
||||
MOONDREAM = "moondream"
|
||||
@@ -76,6 +77,7 @@ class VLM(Enum):
|
||||
PALIGEMMA = "paligemma"
|
||||
FLORENCE_2 = "florence_2"
|
||||
QWEN_2_5_VL = "qwen_2_5_vl"
|
||||
DEEPSEEK_VL_2 = "deepseek_vl_2"
|
||||
GOOGLE_GEMINI_2_0 = "gemini_2_0"
|
||||
GOOGLE_GEMINI_2_5 = "gemini_2_5"
|
||||
MOONDREAM = "moondream"
|
||||
@@ -104,6 +106,7 @@ RESULT_TYPES: dict[VLM, type] = {
|
||||
VLM.PALIGEMMA: str,
|
||||
VLM.FLORENCE_2: dict,
|
||||
VLM.QWEN_2_5_VL: str,
|
||||
VLM.DEEPSEEK_VL_2: str,
|
||||
VLM.GOOGLE_GEMINI_2_0: str,
|
||||
VLM.GOOGLE_GEMINI_2_5: str,
|
||||
VLM.MOONDREAM: dict,
|
||||
@@ -113,6 +116,7 @@ REQUIRED_ARGUMENTS: dict[VLM, list[str]] = {
|
||||
VLM.PALIGEMMA: ["resolution_wh"],
|
||||
VLM.FLORENCE_2: ["resolution_wh"],
|
||||
VLM.QWEN_2_5_VL: ["input_wh", "resolution_wh"],
|
||||
VLM.DEEPSEEK_VL_2: ["resolution_wh"],
|
||||
VLM.GOOGLE_GEMINI_2_0: ["resolution_wh"],
|
||||
VLM.GOOGLE_GEMINI_2_5: ["resolution_wh"],
|
||||
VLM.MOONDREAM: ["resolution_wh"],
|
||||
@@ -122,6 +126,7 @@ ALLOWED_ARGUMENTS: dict[VLM, list[str]] = {
|
||||
VLM.PALIGEMMA: ["resolution_wh", "classes"],
|
||||
VLM.FLORENCE_2: ["resolution_wh"],
|
||||
VLM.QWEN_2_5_VL: ["input_wh", "resolution_wh", "classes"],
|
||||
VLM.DEEPSEEK_VL_2: ["resolution_wh", "classes"],
|
||||
VLM.GOOGLE_GEMINI_2_0: ["resolution_wh", "classes"],
|
||||
VLM.GOOGLE_GEMINI_2_5: ["resolution_wh", "classes"],
|
||||
VLM.MOONDREAM: ["resolution_wh"],
|
||||
@@ -310,6 +315,79 @@ def from_qwen_2_5_vl(
|
||||
return xyxy, class_id, class_name
|
||||
|
||||
|
||||
def from_deepseek_vl_2(
|
||||
result: str, resolution_wh: tuple[int, int], classes: list[str] | None = None
|
||||
) -> tuple[np.ndarray, np.ndarray | None, np.ndarray]:
|
||||
"""
|
||||
Parse bounding boxes from deepseek-vl2-formatted text, scale them to the specified
|
||||
resolution, and optionally filter by classes.
|
||||
|
||||
The DeepSeek-VL2 output typically contains pairs of <|ref|> ... <|/ref|> labels
|
||||
and <|det|> ... <|/det|> bounding box definitions. Each <|det|> section may
|
||||
contain one or more bounding boxes in the form [[x1, y1, x2, y2], [x1, y1, x2, y2], ...]
|
||||
(scaled to 0..999). For example:
|
||||
|
||||
```
|
||||
<|ref|>The giraffe at the back<|/ref|><|det|>[[580, 270, 999, 904]]<|/det|><|ref|>The giraffe at the front<|/ref|><|det|>[[26, 31, 632, 998]]<|/det|><|end▁of▁sentence|>
|
||||
```
|
||||
|
||||
Args:
|
||||
result: String containing deepseek-vl2-formatted locations and labels.
|
||||
resolution_wh: Tuple (width, height) to which we scale the box coordinates.
|
||||
classes: Optional list of valid class names. If provided, boxes and labels not
|
||||
in this list are filtered out.
|
||||
|
||||
Returns:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`.
|
||||
class_id (Optional[np.ndarray]): An array of shape `(n,)` containing
|
||||
the class indices for each bounding box (or `None` if classes is not
|
||||
provided).
|
||||
class_name (np.ndarray): An array of shape `(n,)` containing
|
||||
the class labels for each bounding box.
|
||||
""" # noqa: E501
|
||||
|
||||
width, height = resolution_wh
|
||||
label_segments = re.findall(r"<\|ref\|>(.*?)<\|/ref\|>", result, flags=re.S)
|
||||
detection_segments = re.findall(r"<\|det\|>(.*?)<\|/det\|>", result, flags=re.S)
|
||||
|
||||
if len(label_segments) != len(detection_segments):
|
||||
raise ValueError(
|
||||
f"Number of ref tags ({len(label_segments)}) "
|
||||
f"and det tags ({len(detection_segments)}) in the result must be equal."
|
||||
)
|
||||
|
||||
xyxy, class_name_list = [], []
|
||||
for label, detection_blob in zip(label_segments, detection_segments):
|
||||
current_class_name = label.strip()
|
||||
for box in re.findall(r"\[(.*?)\]", detection_blob):
|
||||
x1, y1, x2, y2 = map(float, box.strip("[]").split(","))
|
||||
xyxy.append(
|
||||
[
|
||||
(x1 / 999 * width),
|
||||
(y1 / 999 * height),
|
||||
(x2 / 999 * width),
|
||||
(y2 / 999 * height),
|
||||
]
|
||||
)
|
||||
class_name_list.append(current_class_name)
|
||||
|
||||
xyxy = np.array(xyxy, dtype=np.float32)
|
||||
class_name = np.array(class_name_list)
|
||||
|
||||
if classes is not None:
|
||||
mask = np.array([name in classes for name in class_name], dtype=bool)
|
||||
xyxy = xyxy[mask]
|
||||
class_name = class_name[mask]
|
||||
class_id = np.array([classes.index(name) for name in class_name])
|
||||
else:
|
||||
unique_classes = sorted(list(set(class_name)))
|
||||
class_to_id = {name: i for i, name in enumerate(unique_classes)}
|
||||
class_id = np.array([class_to_id[name] for name in class_name])
|
||||
|
||||
return xyxy, class_id, class_name
|
||||
|
||||
|
||||
def from_florence_2(
|
||||
result: dict, resolution_wh: tuple[int, int]
|
||||
) -> tuple[np.ndarray, np.ndarray | None, np.ndarray | None, np.ndarray | None]:
|
||||
|
||||
@@ -0,0 +1,13 @@
|
||||
from typing import TypeVar
|
||||
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
ImageType = TypeVar("ImageType", np.ndarray, Image.Image)
|
||||
"""
|
||||
An image of type `np.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
Unlike a `Union`, ensures the type remains consistent. If a function
|
||||
takes an `ImageType` argument and returns an `ImageType`, when you
|
||||
pass an `np.ndarray`, you will get an `np.ndarray` back.
|
||||
"""
|
||||
+32
-10
@@ -346,28 +346,50 @@ def draw_image(
|
||||
|
||||
def calculate_optimal_text_scale(resolution_wh: tuple[int, int]) -> float:
|
||||
"""
|
||||
Calculate font scale based on the resolution of an image.
|
||||
Calculate optimal font scale based on image resolution. Adjusts font scale
|
||||
proportionally to the smallest dimension of the given image resolution for
|
||||
consistent readability.
|
||||
|
||||
Parameters:
|
||||
resolution_wh (Tuple[int, int]): A tuple representing the width and height
|
||||
of the image.
|
||||
Args:
|
||||
resolution_wh (tuple[int, int]): (width, height) of the image in pixels
|
||||
|
||||
Returns:
|
||||
float: The calculated font scale factor.
|
||||
float: recommended font scale factor
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.calculate_optimal_text_scale((1920, 1080))
|
||||
# 1.08
|
||||
sv.calculate_optimal_text_scale((640, 480))
|
||||
# 0.48
|
||||
```
|
||||
"""
|
||||
return min(resolution_wh) * 1e-3
|
||||
|
||||
|
||||
def calculate_optimal_line_thickness(resolution_wh: tuple[int, int]) -> int:
|
||||
"""
|
||||
Calculate line thickness based on the resolution of an image.
|
||||
Calculate optimal line thickness based on image resolution. Adjusts the line
|
||||
thickness for readability depending on the smallest dimension of the provided
|
||||
image resolution.
|
||||
|
||||
Parameters:
|
||||
resolution_wh (Tuple[int, int]): A tuple representing the width and height
|
||||
of the image.
|
||||
Args:
|
||||
resolution_wh (tuple[int, int]): (width, height) of the image in pixels
|
||||
|
||||
Returns:
|
||||
int: The calculated line thickness in pixels.
|
||||
int: recommended line thickness in pixels
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.calculate_optimal_line_thickness((1920, 1080))
|
||||
# 4
|
||||
sv.calculate_optimal_line_thickness((640, 480))
|
||||
# 2
|
||||
```
|
||||
"""
|
||||
if min(resolution_wh) < 1080:
|
||||
return 2
|
||||
|
||||
@@ -6,14 +6,14 @@ from logging import warn
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.detection.utils.boxes import pad_boxes, spread_out_boxes
|
||||
from supervision.draw.base import ImageType
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_rounded_rectangle
|
||||
from supervision.geometry.core import Rect
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.keypoint.skeletons import SKELETONS_BY_VERTEX_COUNT
|
||||
from supervision.utils.conversion import ensure_cv2_image_for_annotation
|
||||
from supervision.key_points.core import KeyPoints
|
||||
from supervision.key_points.skeletons import SKELETONS_BY_VERTEX_COUNT
|
||||
from supervision.utils.conversion import ensure_cv2_image_for_class_method
|
||||
|
||||
|
||||
class BaseKeyPointAnnotator(ABC):
|
||||
@@ -43,7 +43,7 @@ class VertexAnnotator(BaseKeyPointAnnotator):
|
||||
self.color = color
|
||||
self.radius = radius
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene with skeleton vertices based on the provided key
|
||||
@@ -120,7 +120,7 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
self.thickness = thickness
|
||||
self.edges = edges
|
||||
|
||||
@ensure_cv2_image_for_annotation
|
||||
@ensure_cv2_image_for_class_method
|
||||
def annotate(self, scene: ImageType, key_points: KeyPoints) -> ImageType:
|
||||
"""
|
||||
Annotates the given scene by drawing lines between specified key points to form
|
||||
@@ -10,7 +10,7 @@ import numpy.typing as npt
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils.internal import get_data_item, is_data_equal
|
||||
from supervision.validators import validate_keypoints_fields
|
||||
from supervision.validators import validate_key_points_fields
|
||||
|
||||
|
||||
@dataclass
|
||||
@@ -23,7 +23,7 @@ class KeyPoints:
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
Use [`sv.KeyPoints.from_ultralytics`](/latest/keypoint/core/#supervision.keypoint.core.KeyPoints.from_ultralytics)
|
||||
Use [`sv.KeyPoints.from_ultralytics`](/latest/keypoint/core/#supervision.key_points.core.KeyPoints.from_ultralytics)
|
||||
method, which accepts [YOLOv8-pose](https://docs.ultralytics.com/models/yolov8/), [YOLO11-pose](https://docs.ultralytics.com/models/yolo11/)
|
||||
[pose](https://docs.ultralytics.com/tasks/pose/) result.
|
||||
|
||||
@@ -41,7 +41,7 @@ class KeyPoints:
|
||||
|
||||
=== "Inference"
|
||||
|
||||
Use [`sv.KeyPoints.from_inference`](/latest/keypoint/core/#supervision.keypoint.core.KeyPoints.from_inference)
|
||||
Use [`sv.KeyPoints.from_inference`](/latest/keypoint/core/#supervision.key_points.core.KeyPoints.from_inference)
|
||||
method, which accepts [Inference](https://inference.roboflow.com/) pose result.
|
||||
|
||||
```python
|
||||
@@ -58,7 +58,7 @@ class KeyPoints:
|
||||
|
||||
=== "MediaPipe"
|
||||
|
||||
Use [`sv.KeyPoints.from_mediapipe`](/latest/keypoint/core/#supervision.keypoint.core.KeyPoints.from_mediapipe)
|
||||
Use [`sv.KeyPoints.from_mediapipe`](/latest/keypoint/core/#supervision.key_points.core.KeyPoints.from_mediapipe)
|
||||
method, which accepts [MediaPipe](https://github.com/google-ai-edge/mediapipe)
|
||||
pose result.
|
||||
|
||||
@@ -89,10 +89,61 @@ class KeyPoints:
|
||||
pose_landmarker_result, (image_width, image_height))
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
Use [`sv.KeyPoints.from_transformers`](/latest/keypoint/core/#supervision.key_points.core.KeyPoints.from_transformers)
|
||||
method, which accepts [ViTPose](https://huggingface.co/docs/transformers/en/model_doc/vitpose) result.
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import requests
|
||||
import supervision as sv
|
||||
import torch
|
||||
from transformers import (
|
||||
AutoProcessor,
|
||||
RTDetrForObjectDetection,
|
||||
VitPoseForPoseEstimation,
|
||||
)
|
||||
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
DETECTION_MODEL_ID = "PekingU/rtdetr_r50vd_coco_o365"
|
||||
|
||||
detection_processor = AutoProcessor.from_pretrained(DETECTION_MODEL_ID, use_fast=True)
|
||||
detection_model = RTDetrForObjectDetection.from_pretrained(DETECTION_MODEL_ID, device_map=DEVICE)
|
||||
|
||||
inputs = detection_processor(images=frame, return_tensors="pt").to(DEVICE)
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = detection_model(**inputs)
|
||||
|
||||
target_size = torch.tensor([(frame.height, frame.width)])
|
||||
results = detection_processor.post_process_object_detection(
|
||||
outputs, target_sizes=target_size, threshold=0.3)
|
||||
|
||||
detections = sv.Detections.from_transformers(results[0])
|
||||
boxes = sv.xyxy_to_xywh(detections[detections.class_id == 0].xyxy)
|
||||
|
||||
POSE_ESTIMATION_MODEL_ID = "usyd-community/vitpose-base-simple"
|
||||
|
||||
pose_estimation_processor = AutoProcessor.from_pretrained(POSE_ESTIMATION_MODEL_ID)
|
||||
pose_estimation_model = VitPoseForPoseEstimation.from_pretrained(
|
||||
POSE_ESTIMATION_MODEL_ID, device_map=DEVICE)
|
||||
|
||||
inputs = pose_estimation_processor(frame, boxes=[boxes], return_tensors="pt").to(DEVICE)
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = pose_estimation_model(**inputs)
|
||||
|
||||
results = pose_estimation_processor.post_process_pose_estimation(outputs, boxes=[boxes])
|
||||
key_point = sv.KeyPoints.from_transformers(results[0])
|
||||
```
|
||||
|
||||
Attributes:
|
||||
xy (np.ndarray): An array of shape `(n, m, 2)` containing
|
||||
`n` detected objects, each composed of `m` equally-sized
|
||||
sets of keypoints, where each point is `[x, y]`.
|
||||
sets of key points, where each point is `[x, y]`.
|
||||
class_id (Optional[np.ndarray]): An array of shape
|
||||
`(n,)` containing the class ids of the detected objects.
|
||||
confidence (Optional[np.ndarray]): An array of shape
|
||||
@@ -109,7 +160,7 @@ class KeyPoints:
|
||||
data: dict[str, npt.NDArray[Any] | list] = field(default_factory=dict)
|
||||
|
||||
def __post_init__(self):
|
||||
validate_keypoints_fields(
|
||||
validate_key_points_fields(
|
||||
xy=self.xy,
|
||||
confidence=self.confidence,
|
||||
class_id=self.class_id,
|
||||
@@ -514,13 +565,13 @@ class KeyPoints:
|
||||
return cls.empty()
|
||||
|
||||
@classmethod
|
||||
def from_transformers(cls, transfomers_results: Any) -> KeyPoints:
|
||||
def from_transformers(cls, transformers_results: Any) -> KeyPoints:
|
||||
"""
|
||||
Create a `sv.KeyPoints` object from the
|
||||
[Transformers](https://github.com/huggingface/transformers) inference result.
|
||||
|
||||
Args:
|
||||
transfomers_results (Any): The output of a
|
||||
transformers_results (Any): The output of a
|
||||
Transformers model containing instances with prediction data.
|
||||
|
||||
Returns:
|
||||
@@ -545,9 +596,9 @@ class KeyPoints:
|
||||
DETECTION_MODEL_ID = "PekingU/rtdetr_r50vd_coco_o365"
|
||||
|
||||
detection_processor = AutoProcessor.from_pretrained(DETECTION_MODEL_ID, use_fast=True)
|
||||
detection_model = RTDetrForObjectDetection.from_pretrained(DETECTION_MODEL_ID, device_map=DEVICE)
|
||||
detection_model = RTDetrForObjectDetection.from_pretrained(DETECTION_MODEL_ID, device_map=device)
|
||||
|
||||
inputs = detection_processor(images=frame, return_tensors="pt").to(DEVICE)
|
||||
inputs = detection_processor(images=frame, return_tensors="pt").to(device)
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = detection_model(**inputs)
|
||||
@@ -563,9 +614,9 @@ class KeyPoints:
|
||||
|
||||
pose_estimation_processor = AutoProcessor.from_pretrained(POSE_ESTIMATION_MODEL_ID)
|
||||
pose_estimation_model = VitPoseForPoseEstimation.from_pretrained(
|
||||
POSE_ESTIMATION_MODEL_ID, device_map=DEVICE)
|
||||
POSE_ESTIMATION_MODEL_ID, device_map=device)
|
||||
|
||||
inputs = pose_estimation_processor(frame, boxes=[boxes], return_tensors="pt").to(DEVICE)
|
||||
inputs = pose_estimation_processor(frame, boxes=[boxes], return_tensors="pt").to(device)
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = pose_estimation_model(**inputs)
|
||||
@@ -576,8 +627,8 @@ class KeyPoints:
|
||||
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
if "keypoints" in transfomers_results[0]:
|
||||
if transfomers_results[0]["keypoints"].cpu().numpy().size == 0:
|
||||
if "keypoints" in transformers_results[0]:
|
||||
if transformers_results[0]["keypoints"].cpu().numpy().size == 0:
|
||||
return cls.empty()
|
||||
|
||||
result_data = [
|
||||
@@ -585,7 +636,7 @@ class KeyPoints:
|
||||
result["keypoints"].cpu().numpy(),
|
||||
result["scores"].cpu().numpy(),
|
||||
)
|
||||
for result in transfomers_results
|
||||
for result in transformers_results
|
||||
]
|
||||
|
||||
xy, scores = zip(*result_data)
|
||||
@@ -599,55 +650,68 @@ class KeyPoints:
|
||||
return cls.empty()
|
||||
|
||||
def __getitem__(
|
||||
self, index: int | slice | list[int] | np.ndarray | str
|
||||
) -> KeyPoints | list | np.ndarray | None:
|
||||
"""
|
||||
Get a subset of the `sv.KeyPoints` object or access an item from its data field.
|
||||
|
||||
When provided with an integer, slice, list of integers, or a numpy array, this
|
||||
method returns a new `sv.KeyPoints` object that represents a subset of the
|
||||
original `sv.KeyPoints`. When provided with a string, it accesses the
|
||||
corresponding item in the data dictionary.
|
||||
|
||||
Args:
|
||||
index (Union[int, slice, List[int], np.ndarray, str]): The index, indices,
|
||||
or key to access a subset of the `sv.KeyPoints` or an item from the
|
||||
data.
|
||||
|
||||
Returns:
|
||||
A subset of the `sv.KeyPoints` object or an item from the data field.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
key_points = sv.KeyPoints()
|
||||
|
||||
# access the first keypoint using an integer index
|
||||
key_points[0]
|
||||
|
||||
# access the first 10 keypoints using index slice
|
||||
key_points[0:10]
|
||||
|
||||
# access selected keypoints using a list of indices
|
||||
key_points[[0, 2, 4]]
|
||||
|
||||
# access keypoints with selected class_id
|
||||
key_points[key_points.class_id == 0]
|
||||
|
||||
# access keypoints with confidence greater than 0.5
|
||||
key_points[key_points.confidence > 0.5]
|
||||
```
|
||||
"""
|
||||
self, index: int | slice | list[int] | np.ndarray | tuple | str
|
||||
) -> KeyPoints | np.ndarray | list | None:
|
||||
if isinstance(index, str):
|
||||
return self.data.get(index)
|
||||
if isinstance(index, int):
|
||||
index = [index]
|
||||
|
||||
if not isinstance(index, tuple):
|
||||
index = (index, slice(None))
|
||||
|
||||
i, j = index
|
||||
|
||||
if isinstance(i, int):
|
||||
i = [i]
|
||||
|
||||
if isinstance(i, list) and all(isinstance(x, bool) for x in i):
|
||||
i = np.array(i)
|
||||
if isinstance(j, list) and all(isinstance(x, bool) for x in j):
|
||||
j = np.array(j)
|
||||
|
||||
if isinstance(i, np.ndarray) and i.dtype == bool:
|
||||
i = np.flatnonzero(i)
|
||||
if isinstance(j, np.ndarray) and j.dtype == bool:
|
||||
j = np.flatnonzero(j)
|
||||
|
||||
if (
|
||||
isinstance(i, (list, np.ndarray))
|
||||
and isinstance(j, (list, np.ndarray))
|
||||
and not np.isscalar(i)
|
||||
and not np.isscalar(j)
|
||||
):
|
||||
i, j = np.ix_(i, j)
|
||||
|
||||
xy_selected = self.xy[i, j]
|
||||
|
||||
conf_selected = self.confidence[i, j] if self.confidence is not None else None
|
||||
|
||||
class_id_selected = self.class_id[i] if self.class_id is not None else None
|
||||
|
||||
data_selected = get_data_item(self.data, i)
|
||||
|
||||
if xy_selected.ndim == 1:
|
||||
xy_selected = xy_selected.reshape(1, 1, 2)
|
||||
if conf_selected is not None:
|
||||
conf_selected = conf_selected.reshape(1, 1)
|
||||
elif xy_selected.ndim == 2:
|
||||
if np.isscalar(index[0]) or (
|
||||
isinstance(index[0], np.ndarray) and index[0].ndim == 0
|
||||
):
|
||||
xy_selected = xy_selected[np.newaxis, ...]
|
||||
if conf_selected is not None:
|
||||
conf_selected = conf_selected[np.newaxis, ...]
|
||||
elif np.isscalar(index[1]) or (
|
||||
isinstance(index[1], np.ndarray) and index[1].ndim == 0
|
||||
):
|
||||
xy_selected = xy_selected[:, np.newaxis, :]
|
||||
if conf_selected is not None:
|
||||
conf_selected = conf_selected[:, np.newaxis]
|
||||
|
||||
return KeyPoints(
|
||||
xy=self.xy[index],
|
||||
confidence=self.confidence[index] if self.confidence is not None else None,
|
||||
class_id=self.class_id[index] if self.class_id is not None else None,
|
||||
data=get_data_item(self.data, index),
|
||||
xy=xy_selected,
|
||||
confidence=conf_selected,
|
||||
class_id=class_id_selected,
|
||||
data=data_selected,
|
||||
)
|
||||
|
||||
def __setitem__(self, key: str, value: np.ndarray | list):
|
||||
@@ -668,12 +732,12 @@ class KeyPoints:
|
||||
model = YOLO('yolov8s.pt')
|
||||
|
||||
result = model(image)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
key_points = sv.KeyPoints.from_ultralytics(result)
|
||||
|
||||
keypoints['class_name'] = [
|
||||
key_points['class_name'] = [
|
||||
model.model.names[class_id]
|
||||
for class_id
|
||||
in keypoints.class_id
|
||||
in key_points.class_id
|
||||
]
|
||||
```
|
||||
"""
|
||||
@@ -688,7 +752,7 @@ class KeyPoints:
|
||||
@classmethod
|
||||
def empty(cls) -> KeyPoints:
|
||||
"""
|
||||
Create an empty Keypoints object with no keypoints.
|
||||
Create an empty KeyPoints object with no key points.
|
||||
|
||||
Returns:
|
||||
An empty `sv.KeyPoints` object.
|
||||
@@ -706,9 +770,9 @@ class KeyPoints:
|
||||
"""
|
||||
Returns `True` if the `KeyPoints` object is considered empty.
|
||||
"""
|
||||
empty_keypoints = KeyPoints.empty()
|
||||
empty_keypoints.data = self.data
|
||||
return self == empty_keypoints
|
||||
empty_key_points = KeyPoints.empty()
|
||||
empty_key_points.data = self.data
|
||||
return self == empty_key_points
|
||||
|
||||
def as_detections(
|
||||
self, selected_keypoint_indices: Iterable[int] | None = None
|
||||
@@ -716,21 +780,21 @@ class KeyPoints:
|
||||
"""
|
||||
Convert a KeyPoints object to a Detections object. This
|
||||
approximates the bounding box of the detected object by
|
||||
taking the bounding box that fits all keypoints.
|
||||
taking the bounding box that fits all key points.
|
||||
|
||||
Arguments:
|
||||
selected_keypoint_indices (Optional[Iterable[int]]): The
|
||||
indices of the keypoints to include in the bounding box
|
||||
calculation. This helps focus on a subset of keypoints,
|
||||
e.g. when some are occluded. Captures all keypoints by default.
|
||||
indices of the key points to include in the bounding box
|
||||
calculation. This helps focus on a subset of key points,
|
||||
e.g. when some are occluded. Captures all key points by default.
|
||||
|
||||
Returns:
|
||||
detections (Detections): The converted detections object.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
keypoints = sv.KeyPoints.from_inference(...)
|
||||
detections = keypoints.as_detections()
|
||||
key_points = sv.KeyPoints.from_inference(...)
|
||||
detections = key_points.as_detections()
|
||||
```
|
||||
"""
|
||||
if self.is_empty():
|
||||
@@ -57,7 +57,11 @@ class MeanAveragePrecisionResult:
|
||||
|
||||
@property
|
||||
def map50_95(self) -> float:
|
||||
return self.mAP_scores.mean()
|
||||
valid_scores = self.mAP_scores[self.mAP_scores > -1]
|
||||
if len(valid_scores) > 0:
|
||||
return valid_scores.mean()
|
||||
else:
|
||||
return -1
|
||||
|
||||
@property
|
||||
def map50(self) -> float:
|
||||
@@ -98,12 +102,12 @@ class MeanAveragePrecisionResult:
|
||||
f"maxDets=100 ] = {self.map50:.3f}\n"
|
||||
f"Average Precision (AP) @[ IoU=0.75 | area= all | "
|
||||
f"maxDets=100 ] = {self.map75:.3f}\n"
|
||||
f"Average Precision (AP) @[ IoU=0.50:0.95 | area= small | maxDets=100 ] "
|
||||
f"= {self.small_objects.map50_95:.3f}\n"
|
||||
f"Average Precision (AP) @[ IoU=0.50:0.95 | area=medium | maxDets=100 ] \
|
||||
= {self.medium_objects.map50_95:.3f}\n"
|
||||
f"Average Precision (AP) @[ IoU=0.50:0.95 | area= large | maxDets=100 ] \
|
||||
= {self.large_objects.map50_95:.3f}"
|
||||
f"Average Precision (AP) @[ IoU=0.50:0.95 | area= small | "
|
||||
f"maxDets=100 ] = {self.small_objects.map50_95:.3f}\n"
|
||||
f"Average Precision (AP) @[ IoU=0.50:0.95 | area=medium | "
|
||||
f"maxDets=100 ] = {self.medium_objects.map50_95:.3f}\n"
|
||||
f"Average Precision (AP) @[ IoU=0.50:0.95 | area= large | "
|
||||
f"maxDets=100 ] = {self.large_objects.map50_95:.3f}"
|
||||
)
|
||||
|
||||
def to_pandas(self) -> pd.DataFrame:
|
||||
@@ -421,6 +425,11 @@ class EvaluationDataset:
|
||||
if not isinstance(predictions, list):
|
||||
raise ValueError("results must be a list")
|
||||
|
||||
# Handle empty predictions
|
||||
if len(predictions) == 0:
|
||||
predictions_dataset.dataset["annotations"] = []
|
||||
return predictions_dataset
|
||||
|
||||
ids = [pred["image_id"] for pred in predictions]
|
||||
|
||||
# Make sure the image ids from predictions exist in the current dataset
|
||||
@@ -909,6 +918,35 @@ class COCOEvaluator:
|
||||
np.array(score_at_recall)
|
||||
)
|
||||
|
||||
self.results = {
|
||||
"params": self.params,
|
||||
"counts": [
|
||||
num_iou_thresholds,
|
||||
num_recall_thresholds,
|
||||
num_categories,
|
||||
num_area_ranges,
|
||||
num_max_detections,
|
||||
],
|
||||
"date": datetime.datetime.now().strftime("%Y-%m-%d %H:%M:%S"),
|
||||
"precision": precision,
|
||||
"recall": recall,
|
||||
"scores": scores,
|
||||
}
|
||||
|
||||
# Helper function to compute average precision while handling -1 sentinel values
|
||||
def compute_average_precision(precision_slice):
|
||||
"""Compute average precision while handling -1 sentinel values."""
|
||||
masked = np.ma.masked_equal(precision_slice, -1)
|
||||
if masked.count() == 0:
|
||||
# All values are -1 (no data)
|
||||
return np.full(num_iou_thresholds, -1), np.full(
|
||||
(num_categories, num_iou_thresholds), -1
|
||||
)
|
||||
else:
|
||||
mAP_scores = np.ma.filled(masked.mean(axis=(1, 2)), -1)
|
||||
ap_per_class = np.ma.filled(masked.mean(axis=1), -1).transpose(1, 0)
|
||||
return mAP_scores, ap_per_class
|
||||
|
||||
# Average precision over all sizes, 100 max detections
|
||||
area_range_idx = list(ObjectSize).index(ObjectSize.ALL)
|
||||
max_100_dets_idx = self.params.max_dets.index(100)
|
||||
@@ -917,10 +955,9 @@ class COCOEvaluator:
|
||||
:, :, :, area_range_idx, max_100_dets_idx
|
||||
]
|
||||
# mAP over thresholds (dimension=num_thresholds)
|
||||
mAP_scores_all_sizes = average_precision_all_sizes.mean(axis=(1, 2))
|
||||
# AP per class
|
||||
ap_per_class_all_sizes = average_precision_all_sizes.mean(axis=1).transpose(
|
||||
1, 0
|
||||
# Use masked array to exclude -1 values when computing mean
|
||||
mAP_scores_all_sizes, ap_per_class_all_sizes = compute_average_precision(
|
||||
average_precision_all_sizes
|
||||
)
|
||||
|
||||
# Average precision for SMALL objects and 100 max detections
|
||||
@@ -928,24 +965,27 @@ class COCOEvaluator:
|
||||
average_precision_small = precision[
|
||||
:, :, :, small_area_range_idx, max_100_dets_idx
|
||||
]
|
||||
mAP_scores_small = average_precision_small.mean(axis=(1, 2))
|
||||
ap_per_class_small = average_precision_small.mean(axis=1).transpose(1, 0)
|
||||
mAP_scores_small, ap_per_class_small = compute_average_precision(
|
||||
average_precision_small
|
||||
)
|
||||
|
||||
# Average precision for MEDIUM objects and 100 max detections
|
||||
medium_area_range_idx = list(ObjectSize).index(ObjectSize.MEDIUM)
|
||||
average_precision_medium = precision[
|
||||
:, :, :, medium_area_range_idx, max_100_dets_idx
|
||||
]
|
||||
mAP_scores_medium = average_precision_medium.mean(axis=(1, 2))
|
||||
ap_per_class_medium = average_precision_medium.mean(axis=1).transpose(1, 0)
|
||||
mAP_scores_medium, ap_per_class_medium = compute_average_precision(
|
||||
average_precision_medium
|
||||
)
|
||||
|
||||
# Average precision for LARGE objects and 100 max detections
|
||||
large_area_range_idx = list(ObjectSize).index(ObjectSize.LARGE)
|
||||
average_precision_large = precision[
|
||||
:, :, :, large_area_range_idx, max_100_dets_idx
|
||||
]
|
||||
mAP_scores_large = average_precision_large.mean(axis=(1, 2))
|
||||
ap_per_class_large = average_precision_large.mean(axis=1).transpose(1, 0)
|
||||
mAP_scores_large, ap_per_class_large = compute_average_precision(
|
||||
average_precision_large
|
||||
)
|
||||
|
||||
self.results = {
|
||||
"params": self.params,
|
||||
@@ -1221,7 +1261,7 @@ class MeanAveragePrecision(Metric):
|
||||
for image_id, image_targets in enumerate(targets):
|
||||
if self._image_indices is not None:
|
||||
image_id = self._image_indices[image_id]
|
||||
for target in image_targets:
|
||||
for target_idx, target in enumerate(image_targets):
|
||||
xyxy = target[0] # or xyxy = prediction[0]; xyxy[2:4] -= xyxy[0:2]
|
||||
xywh = [xyxy[0], xyxy[1], xyxy[2] - xyxy[0], xyxy[3] - xyxy[1]]
|
||||
# Get "area" and "iscrowd" (default 0) from data
|
||||
@@ -1231,13 +1271,20 @@ class MeanAveragePrecision(Metric):
|
||||
category_id = self._class_mapping[target[3].item()]
|
||||
else:
|
||||
category_id = target[3].item()
|
||||
|
||||
# Use area from data if available (e.g., COCO datasets)
|
||||
# Otherwise use Detections.area property
|
||||
area = data.get("area") if data else None
|
||||
if area is None:
|
||||
area = image_targets.area[target_idx]
|
||||
|
||||
dict_annotation = {
|
||||
"area": data.get("area", 0),
|
||||
"area": area,
|
||||
"iscrowd": data.get("iscrowd", 0),
|
||||
"image_id": image_id,
|
||||
"bbox": xywh,
|
||||
"category_id": category_id,
|
||||
"id": len(annotations), # incrementally increase the id
|
||||
"id": len(annotations) + 1, # Start IDs from 1 (0 means no match)
|
||||
}
|
||||
annotations.append(dict_annotation)
|
||||
# Category list
|
||||
|
||||
@@ -4,10 +4,10 @@ import cv2
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.base import ImageType
|
||||
|
||||
|
||||
def ensure_cv2_image_for_annotation(annotate_func):
|
||||
def ensure_cv2_image_for_class_method(annotate_func):
|
||||
"""
|
||||
Decorates `BaseAnnotator.annotate` implementations, converts scene to
|
||||
an image type used internally by the annotators, converts back when annotation
|
||||
@@ -32,7 +32,7 @@ def ensure_cv2_image_for_annotation(annotate_func):
|
||||
return wrapper
|
||||
|
||||
|
||||
def ensure_cv2_image_for_processing(image_processing_fun):
|
||||
def ensure_cv2_image_for_standalone_function(image_processing_fun):
|
||||
"""
|
||||
Decorates image processing functions that accept np.ndarray, converting `image` to
|
||||
np.ndarray, converts back when processing is complete.
|
||||
@@ -55,7 +55,7 @@ def ensure_cv2_image_for_processing(image_processing_fun):
|
||||
return wrapper
|
||||
|
||||
|
||||
def ensure_pil_image_for_annotation(annotate_func):
|
||||
def ensure_pil_image_for_class_method(annotate_func):
|
||||
"""
|
||||
Decorates image processing functions that accept np.ndarray, converting `image` to
|
||||
PIL image, converts back when processing is complete.
|
||||
|
||||
+242
-468
@@ -1,12 +1,7 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import itertools
|
||||
import math
|
||||
import os
|
||||
import shutil
|
||||
from collections.abc import Callable
|
||||
from functools import partial
|
||||
from typing import Literal
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -14,74 +9,60 @@ import numpy.typing as npt
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.color import Color, unify_to_bgr
|
||||
from supervision.draw.utils import calculate_optimal_text_scale, draw_text
|
||||
from supervision.geometry.core import Point
|
||||
from supervision.utils.conversion import (
|
||||
cv2_to_pillow,
|
||||
ensure_cv2_image_for_processing,
|
||||
images_to_cv2,
|
||||
ensure_cv2_image_for_standalone_function,
|
||||
)
|
||||
from supervision.utils.iterables import create_batches, fill
|
||||
|
||||
RelativePosition = Literal["top", "bottom"]
|
||||
|
||||
MAX_COLUMNS_FOR_SINGLE_ROW_GRID = 3
|
||||
from supervision.utils.internal import deprecated
|
||||
|
||||
|
||||
@ensure_cv2_image_for_processing
|
||||
@ensure_cv2_image_for_standalone_function
|
||||
def crop_image(
|
||||
image: ImageType,
|
||||
xyxy: npt.NDArray[int] | list[int] | tuple[int, int, int, int],
|
||||
) -> ImageType:
|
||||
"""
|
||||
Crops the given image based on the given bounding box.
|
||||
Crop image based on bounding box coordinates.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be cropped. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
xyxy (Union[np.ndarray, List[int], Tuple[int, int, int, int]]): A bounding box
|
||||
coordinates in the format `(x_min, y_min, x_max, y_max)`, accepted as either
|
||||
a `numpy.ndarray`, a `list`, or a `tuple`.
|
||||
image (`numpy.ndarray` or `PIL.Image.Image`): The image to crop.
|
||||
xyxy (`numpy.array`, `list[int]`, or `tuple[int, int, int, int]`):
|
||||
Bounding box coordinates in `(x_min, y_min, x_max, y_max)` format.
|
||||
|
||||
Returns:
|
||||
(ImageType): The cropped image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
(`numpy.ndarray` or `PIL.Image.Image`): Cropped image matching input
|
||||
type.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image = cv2.imread("source.png")
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
xyxy = [200, 400, 600, 800]
|
||||
xyxy = (400, 400, 800, 800)
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
cropped_image.shape
|
||||
# (400, 400, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image = Image.open("source.png")
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
xyxy = [200, 400, 600, 800]
|
||||
xyxy = (400, 400, 800, 800)
|
||||
cropped_image = sv.crop_image(image=image, xyxy=xyxy)
|
||||
cropped_image.size
|
||||
# (400, 400)
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
{ align=center width="1000" }
|
||||
""" # noqa E501 // docs
|
||||
|
||||
if isinstance(xyxy, (list, tuple)):
|
||||
xyxy = np.array(xyxy)
|
||||
xyxy = np.round(xyxy).astype(int)
|
||||
@@ -89,31 +70,28 @@ def crop_image(
|
||||
return image[y_min:y_max, x_min:x_max]
|
||||
|
||||
|
||||
@ensure_cv2_image_for_processing
|
||||
@ensure_cv2_image_for_standalone_function
|
||||
def scale_image(image: ImageType, scale_factor: float) -> ImageType:
|
||||
"""
|
||||
Scales the given image based on the given scale factor.
|
||||
Scale image by given factor. Scale factor > 1.0 zooms in, < 1.0 zooms out.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be scaled. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
scale_factor (float): The factor by which the image will be scaled. Scale
|
||||
factor > `1.0` zooms in, < `1.0` zooms out.
|
||||
image (`numpy.ndarray` or `PIL.Image.Image`): The image to scale.
|
||||
scale_factor (`float`): Factor by which to scale the image.
|
||||
|
||||
Returns:
|
||||
(ImageType): The scaled image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
(`numpy.ndarray` or `PIL.Image.Image`): Scaled image matching input
|
||||
type.
|
||||
|
||||
Raises:
|
||||
ValueError: If the scale factor is non-positive.
|
||||
|
||||
=== "OpenCV"
|
||||
ValueError: If scale factor is non-positive.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image = cv2.imread("source.png")
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
@@ -122,13 +100,11 @@ def scale_image(image: ImageType, scale_factor: float) -> ImageType:
|
||||
# (540, 960, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image = Image.open("source.png")
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
@@ -136,7 +112,9 @@ def scale_image(image: ImageType, scale_factor: float) -> ImageType:
|
||||
scaled_image.size
|
||||
# (960, 540)
|
||||
```
|
||||
"""
|
||||
|
||||
{ align=center width="1000" }
|
||||
""" # noqa E501 // docs
|
||||
if scale_factor <= 0:
|
||||
raise ValueError("Scale factor must be positive.")
|
||||
|
||||
@@ -146,35 +124,31 @@ def scale_image(image: ImageType, scale_factor: float) -> ImageType:
|
||||
return cv2.resize(image, (width_new, height_new), interpolation=cv2.INTER_LINEAR)
|
||||
|
||||
|
||||
@ensure_cv2_image_for_processing
|
||||
@ensure_cv2_image_for_standalone_function
|
||||
def resize_image(
|
||||
image: ImageType,
|
||||
resolution_wh: tuple[int, int],
|
||||
keep_aspect_ratio: bool = False,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Resizes the given image to a specified resolution. Can maintain the original aspect
|
||||
ratio or resize directly to the desired dimensions.
|
||||
Resize image to specified resolution. Can optionally maintain aspect ratio.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be resized. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
resolution_wh (Tuple[int, int]): The target resolution as
|
||||
`(width, height)`.
|
||||
keep_aspect_ratio (bool): Flag to maintain the image's original
|
||||
aspect ratio. Defaults to `False`.
|
||||
image (`numpy.ndarray` or `PIL.Image.Image`): The image to resize.
|
||||
resolution_wh (`tuple[int, int]`): Target resolution as `(width, height)`.
|
||||
keep_aspect_ratio (`bool`): Flag to maintain original aspect ratio.
|
||||
Defaults to `False`.
|
||||
|
||||
Returns:
|
||||
(ImageType): The resized image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
(`numpy.ndarray` or `PIL.Image.Image`): Resized image matching input
|
||||
type.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image = cv2.imread("source.png")
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
@@ -185,13 +159,11 @@ def resize_image(
|
||||
# (562, 1000, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image = Image.open("source.png")
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
@@ -202,7 +174,7 @@ def resize_image(
|
||||
# (1000, 562)
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
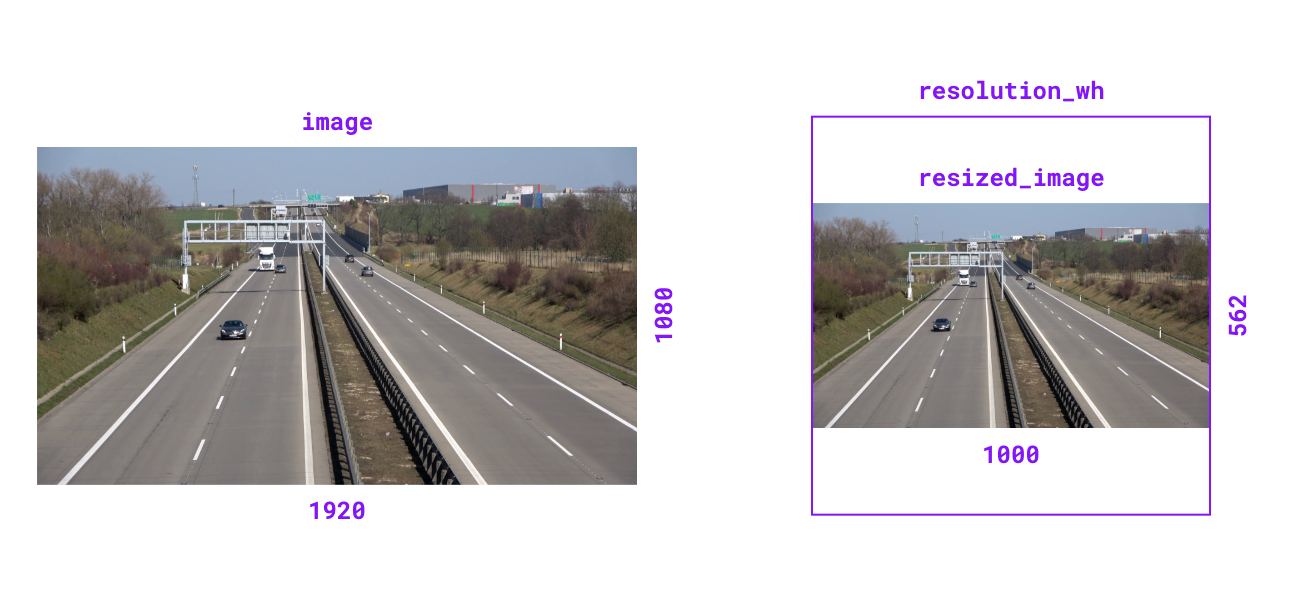{ align=center width="1000" }
|
||||
""" # noqa E501 // docs
|
||||
if keep_aspect_ratio:
|
||||
image_ratio = image.shape[1] / image.shape[0]
|
||||
@@ -219,59 +191,58 @@ def resize_image(
|
||||
return cv2.resize(image, (width_new, height_new), interpolation=cv2.INTER_LINEAR)
|
||||
|
||||
|
||||
@ensure_cv2_image_for_processing
|
||||
@ensure_cv2_image_for_standalone_function
|
||||
def letterbox_image(
|
||||
image: ImageType,
|
||||
resolution_wh: tuple[int, int],
|
||||
color: tuple[int, int, int] | Color = Color.BLACK,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Resizes and pads an image to a specified resolution with a given color, maintaining
|
||||
the original aspect ratio.
|
||||
Resize image and pad with color to achieve desired resolution while
|
||||
maintaining aspect ratio.
|
||||
|
||||
Args:
|
||||
image (ImageType): The image to be resized. `ImageType` is a flexible type,
|
||||
accepting either `numpy.ndarray` or `PIL.Image.Image`.
|
||||
resolution_wh (Tuple[int, int]): The target resolution as
|
||||
`(width, height)`.
|
||||
color (Union[Tuple[int, int, int], Color]): The color to pad with. If tuple
|
||||
provided it should be in BGR format.
|
||||
image (`numpy.ndarray` or `PIL.Image.Image`): The image to resize and pad.
|
||||
resolution_wh (`tuple[int, int]`): Target resolution as `(width, height)`.
|
||||
color (`tuple[int, int, int]` or `Color`): Padding color. If tuple, should
|
||||
be in BGR format. Defaults to `Color.BLACK`.
|
||||
|
||||
Returns:
|
||||
(ImageType): The resized image. The type is determined by the input type and
|
||||
may be either a `numpy.ndarray` or `PIL.Image.Image`.
|
||||
|
||||
=== "OpenCV"
|
||||
(`numpy.ndarray` or `PIL.Image.Image`): Letterboxed image matching input
|
||||
type.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image = cv2.imread("source.png")
|
||||
image.shape
|
||||
# (1080, 1920, 3)
|
||||
|
||||
letterboxed_image = sv.letterbox_image(image=image, resolution_wh=(1000, 1000))
|
||||
letterboxed_image = sv.letterbox_image(
|
||||
image=image, resolution_wh=(1000, 1000)
|
||||
)
|
||||
letterboxed_image.shape
|
||||
# (1000, 1000, 3)
|
||||
```
|
||||
|
||||
=== "Pillow"
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
image = Image.open("source.png")
|
||||
image.size
|
||||
# (1920, 1080)
|
||||
|
||||
letterboxed_image = sv.letterbox_image(image=image, resolution_wh=(1000, 1000))
|
||||
letterboxed_image = sv.letterbox_image(
|
||||
image=image, resolution_wh=(1000, 1000)
|
||||
)
|
||||
letterboxed_image.size
|
||||
# (1000, 1000)
|
||||
```
|
||||
|
||||
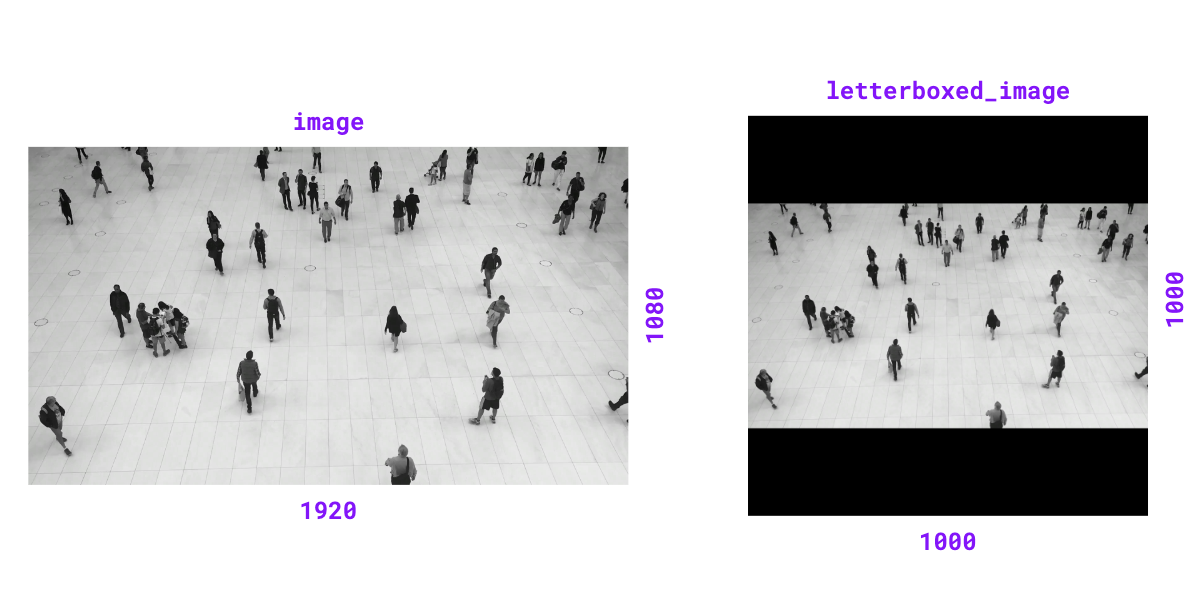{ align=center width="800" }
|
||||
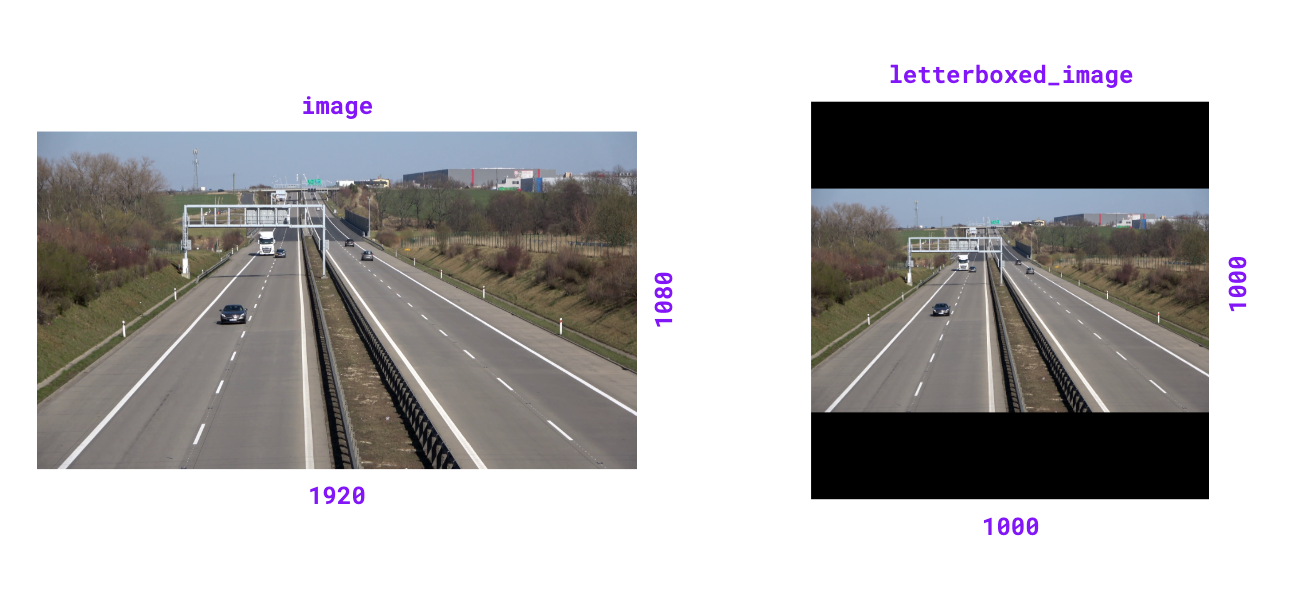{ align=center width="1000" }
|
||||
""" # noqa E501 // docs
|
||||
assert isinstance(image, np.ndarray)
|
||||
color = unify_to_bgr(color=color)
|
||||
@@ -302,37 +273,59 @@ def letterbox_image(
|
||||
return image_with_borders
|
||||
|
||||
|
||||
@deprecated(
|
||||
"`overlay_image` function is deprecated and will be removed in "
|
||||
"`supervision-0.32.0`. Use `draw_image` instead."
|
||||
)
|
||||
def overlay_image(
|
||||
image: npt.NDArray[np.uint8],
|
||||
overlay: npt.NDArray[np.uint8],
|
||||
anchor: tuple[int, int],
|
||||
) -> npt.NDArray[np.uint8]:
|
||||
"""
|
||||
Places an image onto a scene at a given anchor point, handling cases where
|
||||
the image's position is partially or completely outside the scene's bounds.
|
||||
Overlay image onto scene at specified anchor point. Handles cases where
|
||||
overlay position is partially or completely outside scene bounds.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The background scene onto which the image is placed.
|
||||
overlay (np.ndarray): The image to be placed onto the scene.
|
||||
anchor (Tuple[int, int]): The `(x, y)` coordinates in the scene where the
|
||||
top-left corner of the image will be placed.
|
||||
image (`numpy.array`): Background scene with shape `(height, width, 3)`.
|
||||
overlay (`numpy.array`): Image to overlay with shape
|
||||
`(height, width, 3)` or `(height, width, 4)`.
|
||||
anchor (`tuple[int, int]`): Coordinates `(x, y)` where top-left corner
|
||||
of overlay will be placed.
|
||||
|
||||
Returns:
|
||||
(np.ndarray): The result image with overlay.
|
||||
(`numpy.array`): Scene with overlay applied, shape `(height, width, 3)`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
```
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
image = cv2.imread("source.png")
|
||||
overlay = np.zeros((400, 400, 3), dtype=np.uint8)
|
||||
result_image = sv.overlay_image(image=image, overlay=overlay, anchor=(200, 400))
|
||||
overlay[:] = (0, 255, 0) # Green overlay
|
||||
|
||||
result_image = sv.overlay_image(
|
||||
image=image, overlay=overlay, anchor=(200, 400)
|
||||
)
|
||||
cv2.imwrite("target.png", result_image)
|
||||
```
|
||||
|
||||
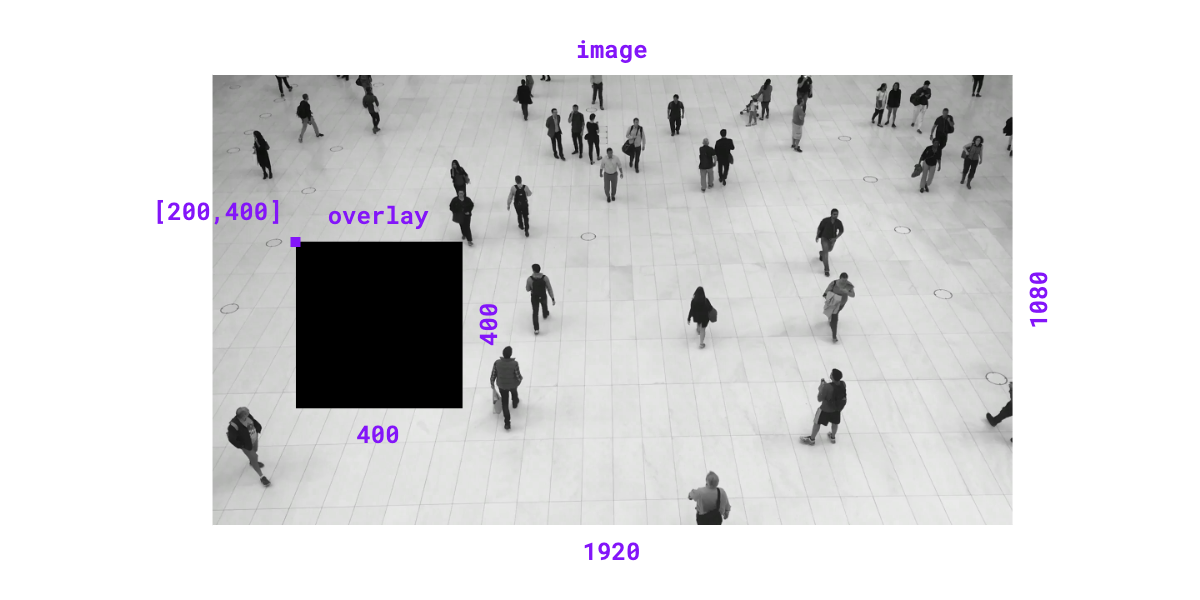{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
```
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread("source.png")
|
||||
overlay = cv2.imread("overlay.png", cv2.IMREAD_UNCHANGED)
|
||||
|
||||
result_image = sv.overlay_image(
|
||||
image=image, overlay=overlay, anchor=(100, 100)
|
||||
)
|
||||
cv2.imwrite("target.png", result_image)
|
||||
```
|
||||
"""
|
||||
scene_height, scene_width = image.shape[:2]
|
||||
image_height, image_width = overlay.shape[:2]
|
||||
anchor_x, anchor_y = anchor
|
||||
@@ -371,6 +364,102 @@ def overlay_image(
|
||||
return image
|
||||
|
||||
|
||||
@ensure_cv2_image_for_standalone_function
|
||||
def tint_image(
|
||||
image: ImageType,
|
||||
color: Color = Color.BLACK,
|
||||
opacity: float = 0.5,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Tint image with solid color overlay at specified opacity.
|
||||
|
||||
Args:
|
||||
image (`numpy.ndarray` or `PIL.Image.Image`): The image to tint.
|
||||
color (`Color`): Overlay tint color. Defaults to `Color.BLACK`.
|
||||
opacity (`float`): Blend ratio between overlay and image (0.0-1.0).
|
||||
Defaults to `0.5`.
|
||||
|
||||
Returns:
|
||||
(`numpy.ndarray` or `PIL.Image.Image`): Tinted image matching input
|
||||
type.
|
||||
|
||||
Raises:
|
||||
ValueError: If opacity is outside range [0.0, 1.0].
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread("source.png")
|
||||
tinted_image = sv.tint_image(
|
||||
image=image, color=sv.Color.ROBOFLOW, opacity=0.5
|
||||
)
|
||||
cv2.imwrite("target.png", tinted_image)
|
||||
```
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open("source.png")
|
||||
tinted_image = sv.tint_image(
|
||||
image=image, color=sv.Color.ROBOFLOW, opacity=0.5
|
||||
)
|
||||
tinted_image.save("target.png")
|
||||
```
|
||||
|
||||
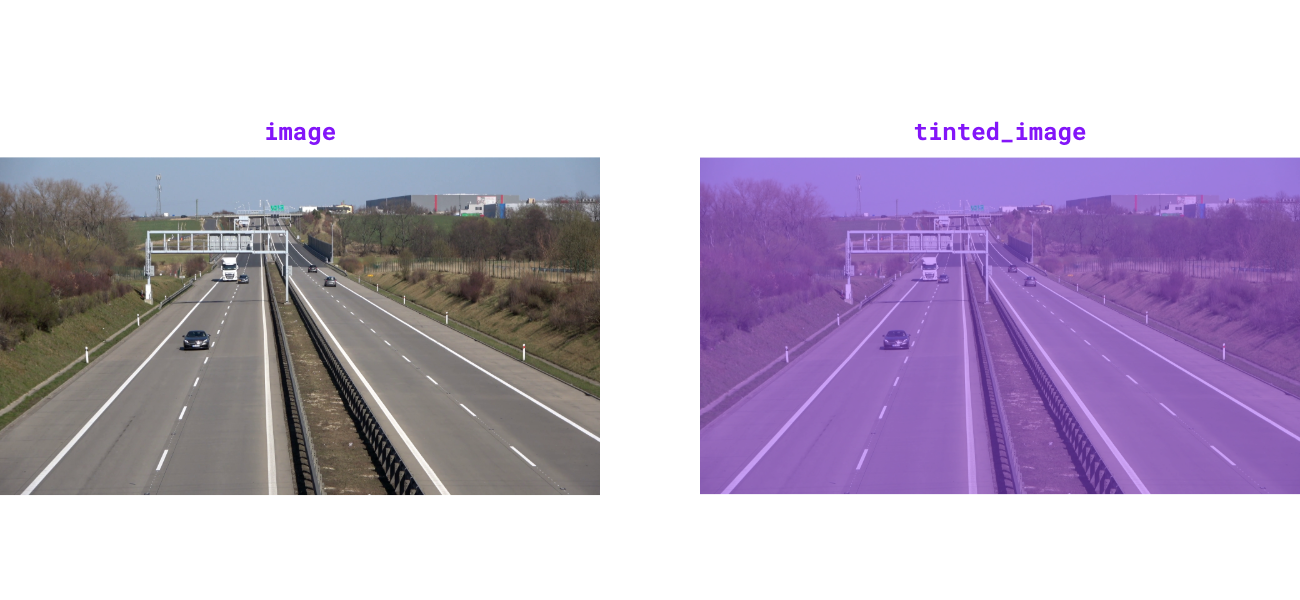{ align=center width="1000" }
|
||||
""" # noqa E501 // docs
|
||||
if not 0.0 <= opacity <= 1.0:
|
||||
raise ValueError("opacity must be between 0.0 and 1.0")
|
||||
|
||||
overlay = np.full_like(image, fill_value=color.as_bgr(), dtype=image.dtype)
|
||||
cv2.addWeighted(
|
||||
src1=overlay, alpha=opacity, src2=image, beta=1 - opacity, gamma=0, dst=image
|
||||
)
|
||||
return image
|
||||
|
||||
|
||||
@ensure_cv2_image_for_standalone_function
|
||||
def grayscale_image(image: ImageType) -> ImageType:
|
||||
"""
|
||||
Convert image to 3-channel grayscale. Luminance channel is broadcast to
|
||||
all three channels for compatibility with color-based drawing helpers.
|
||||
|
||||
Args:
|
||||
image (`numpy.ndarray` or `PIL.Image.Image`): The image to convert to
|
||||
grayscale.
|
||||
|
||||
Returns:
|
||||
(`numpy.ndarray` or `PIL.Image.Image`): 3-channel grayscale image
|
||||
matching input type.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread("source.png")
|
||||
grayscale_image = sv.grayscale_image(image=image)
|
||||
cv2.imwrite("target.png", grayscale_image)
|
||||
```
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
import supervision as sv
|
||||
|
||||
image = Image.open("source.png")
|
||||
grayscale_image = sv.grayscale_image(image=image)
|
||||
grayscale_image.save("target.png")
|
||||
```
|
||||
|
||||
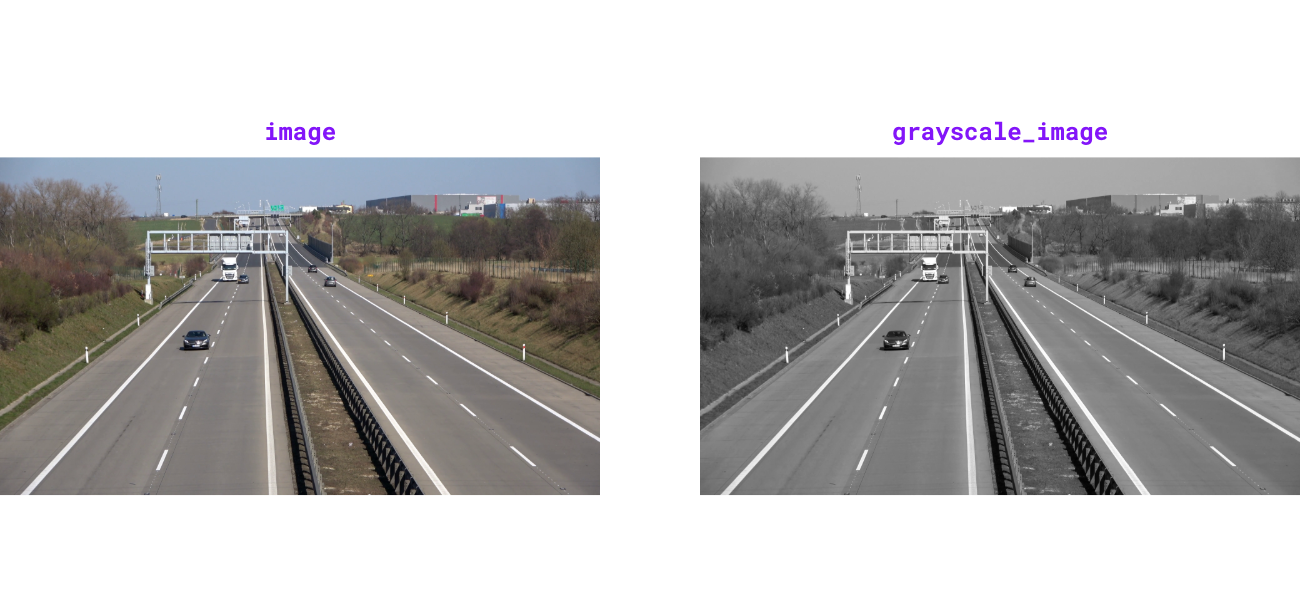{ align=center width="1000" }
|
||||
""" # noqa E501 // docs
|
||||
grayscaled = cv2.cvtColor(image, cv2.COLOR_BGR2GRAY)
|
||||
return cv2.cvtColor(grayscaled, cv2.COLOR_GRAY2BGR)
|
||||
|
||||
|
||||
class ImageSink:
|
||||
def __init__(
|
||||
self,
|
||||
@@ -379,27 +468,64 @@ class ImageSink:
|
||||
image_name_pattern: str = "image_{:05d}.png",
|
||||
):
|
||||
"""
|
||||
Initialize a context manager for saving images.
|
||||
Initialize context manager for saving images to directory.
|
||||
|
||||
Args:
|
||||
target_dir_path (str): The target directory where images will be saved.
|
||||
overwrite (bool): Whether to overwrite the existing directory.
|
||||
Defaults to False.
|
||||
image_name_pattern (str): The image file name pattern.
|
||||
Defaults to "image_{:05d}.png".
|
||||
target_dir_path (`str`): Target directory path where images will be
|
||||
saved.
|
||||
overwrite (`bool`): Whether to overwrite existing directory.
|
||||
Defaults to `False`.
|
||||
image_name_pattern (`str`): File name pattern for saved images.
|
||||
Defaults to `"image_{:05d}.png"`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>, stride=2)
|
||||
frames_generator = sv.get_video_frames_generator(
|
||||
"source.mp4", stride=2
|
||||
)
|
||||
|
||||
with sv.ImageSink(target_dir_path=<TARGET_CROPS_DIRECTORY>) as sink:
|
||||
with sv.ImageSink(target_dir_path="output_frames") as sink:
|
||||
for image in frames_generator:
|
||||
sink.save_image(image=image)
|
||||
```
|
||||
""" # noqa E501 // docs
|
||||
|
||||
# Directory structure:
|
||||
# output_frames/
|
||||
# ├── image_00000.png
|
||||
# ├── image_00001.png
|
||||
# ├── image_00002.png
|
||||
# └── image_00003.png
|
||||
```
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
image = cv2.imread("source.png")
|
||||
crop_boxes = [
|
||||
( 0, 0, 400, 400),
|
||||
(400, 0, 800, 400),
|
||||
( 0, 400, 400, 800),
|
||||
(400, 400, 800, 800)
|
||||
]
|
||||
|
||||
with sv.ImageSink(
|
||||
target_dir_path="image_crops",
|
||||
overwrite=True
|
||||
) as sink:
|
||||
for i, xyxy in enumerate(crop_boxes):
|
||||
crop = sv.crop_image(image=image, xyxy=xyxy)
|
||||
sink.save_image(image=crop, image_name=f"crop_{i}.png")
|
||||
|
||||
# Directory structure:
|
||||
# image_crops/
|
||||
# ├── crop_0.png
|
||||
# ├── crop_1.png
|
||||
# ├── crop_2.png
|
||||
# └── crop_3.png
|
||||
```
|
||||
"""
|
||||
self.target_dir_path = target_dir_path
|
||||
self.overwrite = overwrite
|
||||
self.image_name_pattern = image_name_pattern
|
||||
@@ -417,14 +543,14 @@ class ImageSink:
|
||||
|
||||
def save_image(self, image: np.ndarray, image_name: str | None = None):
|
||||
"""
|
||||
Save a given image in the target directory.
|
||||
Save image to target directory with optional custom filename.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The image to be saved. The image must be in BGR color
|
||||
format.
|
||||
image_name (Optional[str]): The name to use for the saved image.
|
||||
If not provided, a name will be
|
||||
generated using the `image_name_pattern`.
|
||||
image (`numpy.array`): Image to save with shape `(height, width, 3)`
|
||||
in BGR format.
|
||||
image_name (`str` or `None`): Custom filename for saved image. If
|
||||
`None`, generates name using `image_name_pattern`. Defaults to
|
||||
`None`.
|
||||
"""
|
||||
if image_name is None:
|
||||
image_name = self.image_name_pattern.format(self.image_count)
|
||||
@@ -435,355 +561,3 @@ class ImageSink:
|
||||
|
||||
def __exit__(self, exc_type, exc_value, exc_traceback):
|
||||
pass
|
||||
|
||||
|
||||
def create_tiles(
|
||||
images: list[ImageType],
|
||||
grid_size: tuple[int | None, int | None] | None = None,
|
||||
single_tile_size: tuple[int, int] | None = None,
|
||||
tile_scaling: Literal["min", "max", "avg"] = "avg",
|
||||
tile_padding_color: tuple[int, int, int] | Color = Color.from_hex("#D9D9D9"),
|
||||
tile_margin: int = 10,
|
||||
tile_margin_color: tuple[int, int, int] | Color = Color.from_hex("#BFBEBD"),
|
||||
return_type: Literal["auto", "cv2", "pillow"] = "auto",
|
||||
titles: list[str | None] | None = None,
|
||||
titles_anchors: Point | list[Point | None] | None = None,
|
||||
titles_color: tuple[int, int, int] | Color = Color.from_hex("#262523"),
|
||||
titles_scale: float | None = None,
|
||||
titles_thickness: int = 1,
|
||||
titles_padding: int = 10,
|
||||
titles_text_font: int = cv2.FONT_HERSHEY_SIMPLEX,
|
||||
titles_background_color: tuple[int, int, int] | Color = Color.from_hex("#D9D9D9"),
|
||||
default_title_placement: RelativePosition = "top",
|
||||
) -> ImageType:
|
||||
"""
|
||||
Creates tiles mosaic from input images, automating grid placement and
|
||||
converting images to common resolution maintaining aspect ratio. It is
|
||||
also possible to render text titles on tiles, using optional set of
|
||||
parameters specifying text drawing (see parameters description).
|
||||
|
||||
Automated grid placement will try to maintain square shape of grid
|
||||
(with size being the nearest integer square root of #images), up to two exceptions:
|
||||
* if there are up to 3 images - images will be displayed in single row
|
||||
* if square-grid placement causes last row to be empty - number of rows is trimmed
|
||||
until last row has at least one image
|
||||
|
||||
Args:
|
||||
images (List[ImageType]): Images to create tiles. Elements can be either
|
||||
np.ndarray or PIL.Image, common representation will be agreed by the
|
||||
function.
|
||||
grid_size (Optional[Tuple[Optional[int], Optional[int]]]): Expected grid
|
||||
size in format (n_rows, n_cols). If not given - automated grid placement
|
||||
will be applied. One may also provide only one out of two elements of the
|
||||
tuple - then grid will be created with either n_rows or n_cols fixed,
|
||||
leaving the other dimension to be adjusted by the number of images
|
||||
single_tile_size (Optional[Tuple[int, int]]): sizeof a single tile element
|
||||
provided in (width, height) format. If not given - size of tile will be
|
||||
automatically calculated based on `tile_scaling` parameter.
|
||||
tile_scaling (Literal["min", "max", "avg"]): If `single_tile_size` is not
|
||||
given - parameter will be used to calculate tile size - using
|
||||
min / max / avg size of image provided in `images` list.
|
||||
tile_padding_color (Union[Tuple[int, int, int], sv.Color]): Color to be used in
|
||||
images letterbox procedure (while standardising tiles sizes) as a padding.
|
||||
If tuple provided - should be BGR.
|
||||
tile_margin (int): size of margin between tiles (in pixels)
|
||||
tile_margin_color (Union[Tuple[int, int, int], sv.Color]): Color of tile margin.
|
||||
If tuple provided - should be BGR.
|
||||
return_type (Literal["auto", "cv2", "pillow"]): Parameter dictates the format of
|
||||
return image. One may choose specific type ("cv2" or "pillow") to enforce
|
||||
conversion. "auto" mode takes a majority vote between types of elements in
|
||||
`images` list - resolving draws in favour of OpenCV format. "auto" can be
|
||||
safely used when all input images are of the same type.
|
||||
titles (Optional[List[Optional[str]]]): Optional titles to be added to tiles.
|
||||
Elements of that list may be empty - then specific tile (in order presented
|
||||
in `images` parameter) will not be filled with title. It is possible to
|
||||
provide list of titles shorter than `images` - then remaining titles will
|
||||
be assumed empty.
|
||||
titles_anchors (Optional[Union[Point, List[Optional[Point]]]]): Parameter to
|
||||
specify anchor points for titles. It is possible to specify anchor either
|
||||
globally or for specific tiles (following order of `images`).
|
||||
If not given (either globally, or for specific element of the list),
|
||||
it will be calculated automatically based on `default_title_placement`.
|
||||
titles_color (Union[Tuple[int, int, int], Color]): Color of titles text.
|
||||
If tuple provided - should be BGR.
|
||||
titles_scale (Optional[float]): Scale of titles. If not provided - value will
|
||||
be calculated using `calculate_optimal_text_scale(...)`.
|
||||
titles_thickness (int): Thickness of titles text.
|
||||
titles_padding (int): Size of titles padding.
|
||||
titles_text_font (int): Font to be used to render titles. Must be integer
|
||||
constant representing OpenCV font.
|
||||
(See docs: https://docs.opencv.org/4.x/d6/d6e/group__imgproc__draw.html)
|
||||
titles_background_color (Union[Tuple[int, int, int], Color]): Color of title
|
||||
text padding.
|
||||
default_title_placement (Literal["top", "bottom"]): Parameter specifies title
|
||||
anchor placement in case if explicit anchor is not provided.
|
||||
|
||||
Returns:
|
||||
ImageType: Image with all input images located in tails grid. The output type is
|
||||
determined by `return_type` parameter.
|
||||
|
||||
Raises:
|
||||
ValueError: In case when input images list is empty, provided `grid_size` is too
|
||||
small to fit all images, `tile_scaling` mode is invalid.
|
||||
"""
|
||||
if len(images) == 0:
|
||||
raise ValueError("Could not create image tiles from empty list of images.")
|
||||
if return_type == "auto":
|
||||
return_type = _negotiate_tiles_format(images=images)
|
||||
tile_padding_color = unify_to_bgr(color=tile_padding_color)
|
||||
tile_margin_color = unify_to_bgr(color=tile_margin_color)
|
||||
images = images_to_cv2(images=images)
|
||||
if single_tile_size is None:
|
||||
single_tile_size = _aggregate_images_shape(images=images, mode=tile_scaling)
|
||||
resized_images = [
|
||||
letterbox_image(
|
||||
image=i, resolution_wh=single_tile_size, color=tile_padding_color
|
||||
)
|
||||
for i in images
|
||||
]
|
||||
grid_size = _establish_grid_size(images=images, grid_size=grid_size)
|
||||
if len(images) > grid_size[0] * grid_size[1]:
|
||||
raise ValueError(
|
||||
f"Could not place {len(images)} in grid with size: {grid_size}."
|
||||
)
|
||||
if titles is not None:
|
||||
titles = fill(sequence=titles, desired_size=len(images), content=None)
|
||||
titles_anchors = (
|
||||
[titles_anchors]
|
||||
if not issubclass(type(titles_anchors), list)
|
||||
else titles_anchors
|
||||
)
|
||||
titles_anchors = fill(
|
||||
sequence=titles_anchors, desired_size=len(images), content=None
|
||||
)
|
||||
titles_color = unify_to_bgr(color=titles_color)
|
||||
titles_background_color = unify_to_bgr(color=titles_background_color)
|
||||
tiles = _generate_tiles(
|
||||
images=resized_images,
|
||||
grid_size=grid_size,
|
||||
single_tile_size=single_tile_size,
|
||||
tile_padding_color=tile_padding_color,
|
||||
tile_margin=tile_margin,
|
||||
tile_margin_color=tile_margin_color,
|
||||
titles=titles,
|
||||
titles_anchors=titles_anchors,
|
||||
titles_color=titles_color,
|
||||
titles_scale=titles_scale,
|
||||
titles_thickness=titles_thickness,
|
||||
titles_padding=titles_padding,
|
||||
titles_text_font=titles_text_font,
|
||||
titles_background_color=titles_background_color,
|
||||
default_title_placement=default_title_placement,
|
||||
)
|
||||
if return_type == "pillow":
|
||||
tiles = cv2_to_pillow(image=tiles)
|
||||
return tiles
|
||||
|
||||
|
||||
def _negotiate_tiles_format(images: list[ImageType]) -> Literal["cv2", "pillow"]:
|
||||
number_of_np_arrays = sum(issubclass(type(i), np.ndarray) for i in images)
|
||||
if number_of_np_arrays >= (len(images) // 2):
|
||||
return "cv2"
|
||||
return "pillow"
|
||||
|
||||
|
||||
def _calculate_aggregated_images_shape(
|
||||
images: list[np.ndarray], aggregator: Callable[[list[int]], float]
|
||||
) -> tuple[int, int]:
|
||||
height = round(aggregator([i.shape[0] for i in images]))
|
||||
width = round(aggregator([i.shape[1] for i in images]))
|
||||
return width, height
|
||||
|
||||
|
||||
SHAPE_AGGREGATION_FUN = {
|
||||
"min": partial(_calculate_aggregated_images_shape, aggregator=np.min),
|
||||
"max": partial(_calculate_aggregated_images_shape, aggregator=np.max),
|
||||
"avg": partial(_calculate_aggregated_images_shape, aggregator=np.average),
|
||||
}
|
||||
|
||||
|
||||
def _aggregate_images_shape(
|
||||
images: list[np.ndarray], mode: Literal["min", "max", "avg"]
|
||||
) -> tuple[int, int]:
|
||||
if mode not in SHAPE_AGGREGATION_FUN:
|
||||
raise ValueError(
|
||||
f"Could not aggregate images shape - provided unknown mode: {mode}. "
|
||||
f"Supported modes: {list(SHAPE_AGGREGATION_FUN.keys())}."
|
||||
)
|
||||
return SHAPE_AGGREGATION_FUN[mode](images)
|
||||
|
||||
|
||||
def _establish_grid_size(
|
||||
images: list[np.ndarray], grid_size: tuple[int | None, int | None] | None
|
||||
) -> tuple[int, int]:
|
||||
if grid_size is None or all(e is None for e in grid_size):
|
||||
return _negotiate_grid_size(images=images)
|
||||
if grid_size[0] is None:
|
||||
return math.ceil(len(images) / grid_size[1]), grid_size[1]
|
||||
if grid_size[1] is None:
|
||||
return grid_size[0], math.ceil(len(images) / grid_size[0])
|
||||
return grid_size
|
||||
|
||||
|
||||
def _negotiate_grid_size(images: list[np.ndarray]) -> tuple[int, int]:
|
||||
if len(images) <= MAX_COLUMNS_FOR_SINGLE_ROW_GRID:
|
||||
return 1, len(images)
|
||||
nearest_sqrt = math.ceil(np.sqrt(len(images)))
|
||||
proposed_columns = nearest_sqrt
|
||||
proposed_rows = nearest_sqrt
|
||||
while proposed_columns * (proposed_rows - 1) >= len(images):
|
||||
proposed_rows -= 1
|
||||
return proposed_rows, proposed_columns
|
||||
|
||||
|
||||
def _generate_tiles(
|
||||
images: list[np.ndarray],
|
||||
grid_size: tuple[int, int],
|
||||
single_tile_size: tuple[int, int],
|
||||
tile_padding_color: tuple[int, int, int],
|
||||
tile_margin: int,
|
||||
tile_margin_color: tuple[int, int, int],
|
||||
titles: list[str | None] | None,
|
||||
titles_anchors: list[Point | None],
|
||||
titles_color: tuple[int, int, int],
|
||||
titles_scale: float | None,
|
||||
titles_thickness: int,
|
||||
titles_padding: int,
|
||||
titles_text_font: int,
|
||||
titles_background_color: tuple[int, int, int],
|
||||
default_title_placement: RelativePosition,
|
||||
) -> np.ndarray:
|
||||
images = _draw_texts(
|
||||
images=images,
|
||||
titles=titles,
|
||||
titles_anchors=titles_anchors,
|
||||
titles_color=titles_color,
|
||||
titles_scale=titles_scale,
|
||||
titles_thickness=titles_thickness,
|
||||
titles_padding=titles_padding,
|
||||
titles_text_font=titles_text_font,
|
||||
titles_background_color=titles_background_color,
|
||||
default_title_placement=default_title_placement,
|
||||
)
|
||||
rows, columns = grid_size
|
||||
tiles_elements = list(create_batches(sequence=images, batch_size=columns))
|
||||
while len(tiles_elements[-1]) < columns:
|
||||
tiles_elements[-1].append(
|
||||
_generate_color_image(shape=single_tile_size, color=tile_padding_color)
|
||||
)
|
||||
while len(tiles_elements) < rows:
|
||||
tiles_elements.append(
|
||||
[_generate_color_image(shape=single_tile_size, color=tile_padding_color)]
|
||||
* columns
|
||||
)
|
||||
return _merge_tiles_elements(
|
||||
tiles_elements=tiles_elements,
|
||||
grid_size=grid_size,
|
||||
single_tile_size=single_tile_size,
|
||||
tile_margin=tile_margin,
|
||||
tile_margin_color=tile_margin_color,
|
||||
)
|
||||
|
||||
|
||||
def _draw_texts(
|
||||
images: list[np.ndarray],
|
||||
titles: list[str | None] | None,
|
||||
titles_anchors: list[Point | None],
|
||||
titles_color: tuple[int, int, int],
|
||||
titles_scale: float | None,
|
||||
titles_thickness: int,
|
||||
titles_padding: int,
|
||||
titles_text_font: int,
|
||||
titles_background_color: tuple[int, int, int],
|
||||
default_title_placement: RelativePosition,
|
||||
) -> list[np.ndarray]:
|
||||
if titles is None:
|
||||
return images
|
||||
titles_anchors = _prepare_default_titles_anchors(
|
||||
images=images,
|
||||
titles_anchors=titles_anchors,
|
||||
default_title_placement=default_title_placement,
|
||||
)
|
||||
if titles_scale is None:
|
||||
image_height, image_width = images[0].shape[:2]
|
||||
titles_scale = calculate_optimal_text_scale(
|
||||
resolution_wh=(image_width, image_height)
|
||||
)
|
||||
result = []
|
||||
for image, text, anchor in zip(images, titles, titles_anchors):
|
||||
if text is None:
|
||||
result.append(image)
|
||||
continue
|
||||
processed_image = draw_text(
|
||||
scene=image,
|
||||
text=text,
|
||||
text_anchor=anchor,
|
||||
text_color=Color.from_bgr_tuple(titles_color),
|
||||
text_scale=titles_scale,
|
||||
text_thickness=titles_thickness,
|
||||
text_padding=titles_padding,
|
||||
text_font=titles_text_font,
|
||||
background_color=Color.from_bgr_tuple(titles_background_color),
|
||||
)
|
||||
result.append(processed_image)
|
||||
return result
|
||||
|
||||
|
||||
def _prepare_default_titles_anchors(
|
||||
images: list[np.ndarray],
|
||||
titles_anchors: list[Point | None],
|
||||
default_title_placement: RelativePosition,
|
||||
) -> list[Point]:
|
||||
result = []
|
||||
for image, anchor in zip(images, titles_anchors):
|
||||
if anchor is not None:
|
||||
result.append(anchor)
|
||||
continue
|
||||
image_height, image_width = image.shape[:2]
|
||||
if default_title_placement == "top":
|
||||
default_anchor = Point(x=image_width / 2, y=image_height * 0.1)
|
||||
else:
|
||||
default_anchor = Point(x=image_width / 2, y=image_height * 0.9)
|
||||
result.append(default_anchor)
|
||||
return result
|
||||
|
||||
|
||||
def _merge_tiles_elements(
|
||||
tiles_elements: list[list[np.ndarray]],
|
||||
grid_size: tuple[int, int],
|
||||
single_tile_size: tuple[int, int],
|
||||
tile_margin: int,
|
||||
tile_margin_color: tuple[int, int, int],
|
||||
) -> np.ndarray:
|
||||
vertical_padding = (
|
||||
np.ones((single_tile_size[1], tile_margin, 3)) * tile_margin_color
|
||||
)
|
||||
merged_rows = [
|
||||
np.concatenate(
|
||||
list(
|
||||
itertools.chain.from_iterable(
|
||||
zip(row, [vertical_padding] * grid_size[1])
|
||||
)
|
||||
)[:-1],
|
||||
axis=1,
|
||||
)
|
||||
for row in tiles_elements
|
||||
]
|
||||
row_width = merged_rows[0].shape[1]
|
||||
horizontal_padding = (
|
||||
np.ones((tile_margin, row_width, 3), dtype=np.uint8) * tile_margin_color
|
||||
)
|
||||
rows_with_paddings = []
|
||||
for row in merged_rows:
|
||||
rows_with_paddings.append(row)
|
||||
rows_with_paddings.append(horizontal_padding)
|
||||
return np.concatenate(
|
||||
rows_with_paddings[:-1],
|
||||
axis=0,
|
||||
).astype(np.uint8)
|
||||
|
||||
|
||||
def _generate_color_image(
|
||||
shape: tuple[int, int], color: tuple[int, int, int]
|
||||
) -> np.ndarray:
|
||||
return np.ones((*shape[::-1], 3), dtype=np.uint8) * color
|
||||
|
||||
@@ -4,7 +4,7 @@ import cv2
|
||||
import matplotlib.pyplot as plt
|
||||
from PIL import Image
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.draw.base import ImageType
|
||||
from supervision.utils.conversion import pillow_to_cv2
|
||||
|
||||
|
||||
|
||||
@@ -53,7 +53,7 @@ def validate_confidence(confidence: Any, n: int) -> None:
|
||||
)
|
||||
|
||||
|
||||
def validate_keypoint_confidence(confidence: Any, n: int, m: int) -> None:
|
||||
def validate_key_point_confidence(confidence: Any, n: int, m: int) -> None:
|
||||
expected_shape = f"({n, m})"
|
||||
actual_shape = str(getattr(confidence, "shape", None))
|
||||
|
||||
@@ -126,7 +126,7 @@ def validate_detections_fields(
|
||||
validate_data(data, n)
|
||||
|
||||
|
||||
def validate_keypoints_fields(
|
||||
def validate_key_points_fields(
|
||||
xy: Any,
|
||||
class_id: Any,
|
||||
confidence: Any,
|
||||
@@ -136,7 +136,7 @@ def validate_keypoints_fields(
|
||||
m = len(xy[0]) if len(xy) > 0 else 0
|
||||
validate_xy(xy, n, m)
|
||||
validate_class_id(class_id, n)
|
||||
validate_keypoint_confidence(confidence, n, m)
|
||||
validate_key_point_confidence(confidence, n, m)
|
||||
validate_data(data, n)
|
||||
|
||||
|
||||
|
||||
@@ -5,7 +5,7 @@ from contextlib import ExitStack as DoesNotRaise
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.annotators.utils import ColorLookup, resolve_color_idx
|
||||
from supervision.annotators.utils import ColorLookup, resolve_color_idx, wrap_text
|
||||
from supervision.detection.core import Detections
|
||||
from test.test_utils import mock_detections
|
||||
|
||||
@@ -97,7 +97,7 @@ from test.test_utils import mock_detections
|
||||
def test_resolve_color_idx(
|
||||
detections: Detections,
|
||||
detection_idx: int,
|
||||
color_lookup: ColorLookup,
|
||||
color_lookup: ColorLookup | np.ndarray,
|
||||
expected_result: int | None,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
@@ -108,3 +108,67 @@ def test_resolve_color_idx(
|
||||
color_lookup=color_lookup,
|
||||
)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"text, max_line_length, expected_result, exception",
|
||||
[
|
||||
(None, None, [""], DoesNotRaise()), # text is None
|
||||
("", None, [""], DoesNotRaise()), # empty string
|
||||
(" \t ", 3, [""], DoesNotRaise()), # whitespace-only (spaces + tab)
|
||||
(12345, None, ["12345"], DoesNotRaise()), # plain integer
|
||||
(-6789, None, ["-6789"], DoesNotRaise()), # negative integer
|
||||
(np.int64(1000), None, ["1000"], DoesNotRaise()), # NumPy int64
|
||||
([1, 2, 3], None, ["[1, 2, 3]"], DoesNotRaise()), # list to string
|
||||
(
|
||||
"When you play the game of thrones, you win or you die.\nFear cuts deeper than swords.\nA mind needs books as a sword needs a whetstone.", # noqa: E501
|
||||
None,
|
||||
[
|
||||
"When you play the game of thrones, you win or you die.",
|
||||
"Fear cuts deeper than swords.",
|
||||
"A mind needs books as a sword needs a whetstone.",
|
||||
],
|
||||
DoesNotRaise(),
|
||||
), # Game-of-Thrones quotes, multiline
|
||||
("\n", None, [""], DoesNotRaise()), # single newline
|
||||
(
|
||||
"valarmorghulisvalardoharis",
|
||||
6,
|
||||
["valarm", "orghul", "isvala", "rdohar", "is"],
|
||||
DoesNotRaise(),
|
||||
), # long Valyrian phrase, wrapped
|
||||
(
|
||||
"Winter is coming\nFire and blood",
|
||||
10,
|
||||
[
|
||||
"Winter is",
|
||||
"coming",
|
||||
"Fire and",
|
||||
"blood",
|
||||
],
|
||||
DoesNotRaise(),
|
||||
), # mix of short/long with newline
|
||||
(
|
||||
"What is dead may never die",
|
||||
0,
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # width 0 - invalid
|
||||
(
|
||||
"A Lannister always pays his debts",
|
||||
-1,
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # width -1 - invalid
|
||||
(None, 10, [""], DoesNotRaise()), # text None, width set
|
||||
],
|
||||
)
|
||||
def test_wrap_text(
|
||||
text: object,
|
||||
max_line_length: int | None,
|
||||
expected_result: list[str],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = wrap_text(text=text, max_line_length=max_line_length)
|
||||
assert result == expected_result
|
||||
|
||||
@@ -6,7 +6,10 @@ from contextlib import nullcontext as does_not_raise
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.vlm import (
|
||||
VLM,
|
||||
from_florence_2,
|
||||
from_google_gemini_2_0,
|
||||
from_google_gemini_2_5,
|
||||
@@ -1122,3 +1125,110 @@ def test_from_google_gemini_2_5(
|
||||
assert masks is not None
|
||||
assert masks.shape == expected_results[4].shape
|
||||
assert np.array_equal(masks, expected_results[4])
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"exception, result, resolution_wh, classes, expected_detections",
|
||||
[
|
||||
(
|
||||
pytest.raises(ValueError),
|
||||
"",
|
||||
(100, 100),
|
||||
None,
|
||||
None,
|
||||
), # empty text
|
||||
(
|
||||
pytest.raises(ValueError),
|
||||
"random text",
|
||||
(100, 100),
|
||||
None,
|
||||
None,
|
||||
), # random text
|
||||
(
|
||||
does_not_raise(),
|
||||
"<|ref|>cat<|/ref|><|det|>[[100, 200, 300, 400]]<|/det|>",
|
||||
(1000, 1000),
|
||||
None,
|
||||
Detections(
|
||||
xyxy=np.array([[100.1, 200.2, 300.3, 400.4]]),
|
||||
class_id=np.array([0]),
|
||||
data={CLASS_NAME_DATA_FIELD: np.array(["cat"])},
|
||||
),
|
||||
), # single box, no classes
|
||||
(
|
||||
does_not_raise(),
|
||||
"<|ref|>cat<|/ref|><|det|>[[100, 200, 300, 400]]<|/det|>",
|
||||
(1000, 1000),
|
||||
["cat", "dog"],
|
||||
Detections(
|
||||
xyxy=np.array([[100.1, 200.2, 300.3, 400.4]]),
|
||||
class_id=np.array([0]),
|
||||
data={CLASS_NAME_DATA_FIELD: np.array(["cat"])},
|
||||
),
|
||||
), # single box, with classes
|
||||
(
|
||||
does_not_raise(),
|
||||
"<|ref|>person<|/ref|><|det|>[[100, 200, 300, 400]]<|/det|>",
|
||||
(1000, 1000),
|
||||
["cat", "dog"],
|
||||
Detections.empty(),
|
||||
), # single box, wrong class
|
||||
(
|
||||
does_not_raise(),
|
||||
(
|
||||
"<|ref|>cat<|/ref|><|det|>[[100, 200, 300, 400]]<|/det|>"
|
||||
"<|ref|>dog<|/ref|><|det|>[[500, 600, 700, 800]]<|/det|>"
|
||||
),
|
||||
(1000, 1000),
|
||||
["cat"],
|
||||
Detections(
|
||||
xyxy=np.array([[100.1, 200.2, 300.3, 400.4]]),
|
||||
class_id=np.array([0]),
|
||||
data={CLASS_NAME_DATA_FIELD: np.array(["cat"])},
|
||||
),
|
||||
), # multiple boxes, one class correct
|
||||
(
|
||||
pytest.raises(ValueError),
|
||||
"<|ref|>cat<|/ref|>",
|
||||
(100, 100),
|
||||
None,
|
||||
None,
|
||||
), # only ref
|
||||
(
|
||||
pytest.raises(ValueError),
|
||||
"<|det|>[[100, 200, 300, 400]]<|/det|>",
|
||||
(100, 100),
|
||||
None,
|
||||
None,
|
||||
), # only det
|
||||
],
|
||||
)
|
||||
def test_from_deepseek_vl_2(
|
||||
exception,
|
||||
result: str,
|
||||
resolution_wh: tuple[int, int],
|
||||
classes: list[str] | None,
|
||||
expected_detections: Detections,
|
||||
):
|
||||
with exception:
|
||||
detections = Detections.from_vlm(
|
||||
vlm=VLM.DEEPSEEK_VL_2,
|
||||
result=result,
|
||||
resolution_wh=resolution_wh,
|
||||
classes=classes,
|
||||
)
|
||||
|
||||
if expected_detections is None:
|
||||
return
|
||||
|
||||
assert len(detections) == len(expected_detections)
|
||||
|
||||
if len(detections) == 0:
|
||||
return
|
||||
|
||||
assert np.allclose(detections.xyxy, expected_detections.xyxy, atol=1e-1)
|
||||
assert np.array_equal(detections.class_id, expected_detections.class_id)
|
||||
assert np.array_equal(
|
||||
detections.data[CLASS_NAME_DATA_FIELD],
|
||||
expected_detections.data[CLASS_NAME_DATA_FIELD],
|
||||
)
|
||||
|
||||
@@ -6,6 +6,7 @@ import pytest
|
||||
from supervision.detection.utils.converters import (
|
||||
xcycwh_to_xyxy,
|
||||
xywh_to_xyxy,
|
||||
xyxy_to_mask,
|
||||
xyxy_to_xcycarh,
|
||||
xyxy_to_xywh,
|
||||
)
|
||||
@@ -129,3 +130,174 @@ def test_xyxy_to_xcycarh(xyxy: np.ndarray, expected_result: np.ndarray) -> None:
|
||||
def test_xcycwh_to_xyxy(xcycwh: np.ndarray, expected_result: np.ndarray) -> None:
|
||||
result = xcycwh_to_xyxy(xcycwh)
|
||||
np.testing.assert_array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"boxes,resolution_wh,expected",
|
||||
[
|
||||
# 0) Empty input
|
||||
(
|
||||
np.array([], dtype=float).reshape(0, 4),
|
||||
(5, 4),
|
||||
np.array([], dtype=bool).reshape(0, 4, 5),
|
||||
),
|
||||
# 1) Single pixel box
|
||||
(
|
||||
np.array([[2, 1, 2, 1]], dtype=float),
|
||||
(5, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
),
|
||||
# 2) Horizontal line, inclusive bounds
|
||||
(
|
||||
np.array([[1, 2, 3, 2]], dtype=float),
|
||||
(5, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, True, False],
|
||||
[False, False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
),
|
||||
# 3) Vertical line, inclusive bounds
|
||||
(
|
||||
np.array([[3, 0, 3, 2]], dtype=float),
|
||||
(5, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, True, False],
|
||||
[False, False, False, True, False],
|
||||
[False, False, False, True, False],
|
||||
[False, False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
),
|
||||
# 4) Proper rectangle fill
|
||||
(
|
||||
np.array([[1, 1, 3, 2]], dtype=float),
|
||||
(5, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, True, True, True, False],
|
||||
[False, True, True, True, False],
|
||||
[False, False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
),
|
||||
# 5) Negative coordinates clipped to [0, 0]
|
||||
(
|
||||
np.array([[-2, -1, 1, 1]], dtype=float),
|
||||
(5, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[True, True, False, False, False],
|
||||
[True, True, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
),
|
||||
# 6) Overflow coordinates clipped to width-1 and height-1
|
||||
(
|
||||
np.array([[3, 2, 10, 10]], dtype=float),
|
||||
(5, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, True, True],
|
||||
[False, False, False, True, True],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
),
|
||||
# 7) Invalid box where max < min after ints, mask stays empty
|
||||
(
|
||||
np.array([[3, 2, 1, 4]], dtype=float),
|
||||
(5, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
),
|
||||
# 8) Fractional coordinates are floored by int conversion
|
||||
# (0.2,0.2)-(2.8,1.9) -> (0,0)-(2,1)
|
||||
(
|
||||
np.array([[0.2, 0.2, 2.8, 1.9]], dtype=float),
|
||||
(5, 4),
|
||||
np.array(
|
||||
[
|
||||
[
|
||||
[True, True, True, False, False],
|
||||
[True, True, True, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
]
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
),
|
||||
# 9) Multiple boxes, separate masks
|
||||
(
|
||||
np.array([[0, 0, 1, 0], [2, 1, 4, 3]], dtype=float),
|
||||
(5, 4),
|
||||
np.array(
|
||||
[
|
||||
# Box 0: row 0, cols 0..1
|
||||
[
|
||||
[True, True, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
[False, False, False, False, False],
|
||||
],
|
||||
# Box 1: rows 1..3, cols 2..4
|
||||
[
|
||||
[False, False, False, False, False],
|
||||
[False, False, True, True, True],
|
||||
[False, False, True, True, True],
|
||||
[False, False, True, True, True],
|
||||
],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_xyxy_to_mask(boxes: np.ndarray, resolution_wh, expected: np.ndarray) -> None:
|
||||
result = xyxy_to_mask(boxes, resolution_wh)
|
||||
assert result.dtype == np.bool_
|
||||
assert result.shape == expected.shape
|
||||
np.testing.assert_array_equal(result, expected)
|
||||
|
||||
@@ -10,6 +10,7 @@ from supervision.detection.utils.masks import (
|
||||
calculate_masks_centroids,
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
filter_segments_by_distance,
|
||||
move_masks,
|
||||
)
|
||||
|
||||
@@ -500,3 +501,228 @@ def test_contains_multiple_segments(
|
||||
with exception:
|
||||
result = contains_multiple_segments(mask=mask, connectivity=connectivity)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"mask, connectivity, mode, absolute_distance, relative_distance, expected_result, exception", # noqa: E501
|
||||
[
|
||||
# single component, unchanged
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
8,
|
||||
"edge",
|
||||
2.0,
|
||||
None,
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# two components, edge distance 2, kept with abs=1
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 1],
|
||||
[0, 1, 1, 1, 0, 1],
|
||||
[0, 1, 1, 1, 0, 1],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
8,
|
||||
"edge",
|
||||
2.0,
|
||||
None,
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 1],
|
||||
[0, 1, 1, 1, 0, 1],
|
||||
[0, 1, 1, 1, 0, 1],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# centroid mode, far centroids, dropped with small relative threshold
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 1, 1, 1],
|
||||
[0, 0, 0, 1, 1, 1],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
8,
|
||||
"centroid",
|
||||
None,
|
||||
0.3, # diagonal ~8.49, threshold ~2.55, centroid gap ~4.24
|
||||
np.array(
|
||||
[
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# centroid mode, larger relative threshold, kept
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 1, 1, 1],
|
||||
[0, 0, 0, 1, 1, 1],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
8,
|
||||
"centroid",
|
||||
None,
|
||||
0.6, # diagonal ~8.49, threshold ~5.09, centroid gap ~4.24
|
||||
np.array(
|
||||
[
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[1, 1, 1, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 1, 1, 1],
|
||||
[0, 0, 0, 1, 1, 1],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# empty mask
|
||||
(
|
||||
np.zeros((4, 4), dtype=bool),
|
||||
4,
|
||||
"edge",
|
||||
2.0,
|
||||
None,
|
||||
np.zeros((4, 4), dtype=bool),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# full mask
|
||||
(
|
||||
np.ones((4, 4), dtype=bool),
|
||||
8,
|
||||
"centroid",
|
||||
None,
|
||||
0.2,
|
||||
np.ones((4, 4), dtype=bool),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# two components, pixel distance = 2, kept with abs=2
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 1, 1, 1],
|
||||
[0, 1, 1, 1, 0, 1, 1, 1],
|
||||
[0, 1, 1, 1, 0, 1, 1, 1],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
8,
|
||||
"edge",
|
||||
2.0, # was 1.0
|
||||
None,
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 1, 1, 1],
|
||||
[0, 1, 1, 1, 0, 1, 1, 1],
|
||||
[0, 1, 1, 1, 0, 1, 1, 1],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
# two components, pixel distance = 3, dropped with abs=2
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0, 0, 1, 1],
|
||||
[0, 1, 1, 1, 0, 0, 0, 1, 1],
|
||||
[0, 1, 1, 1, 0, 0, 0, 1, 1],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
8,
|
||||
"edge",
|
||||
2.0, # keep threshold below 3 so the right blob is removed
|
||||
None,
|
||||
np.array(
|
||||
[
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
[0, 0, 0, 0, 0, 0, 0, 0, 0],
|
||||
],
|
||||
dtype=bool,
|
||||
),
|
||||
DoesNotRaise(),
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_filter_segments_by_distance_sweep(
|
||||
mask: npt.NDArray,
|
||||
connectivity: int,
|
||||
mode: str,
|
||||
absolute_distance: float | None,
|
||||
relative_distance: float | None,
|
||||
expected_result: npt.NDArray | None,
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = filter_segments_by_distance(
|
||||
mask=mask,
|
||||
connectivity=connectivity,
|
||||
mode=mode, # type: ignore[arg-type]
|
||||
absolute_distance=absolute_distance,
|
||||
relative_distance=relative_distance,
|
||||
)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
@@ -0,0 +1,117 @@
|
||||
import pytest
|
||||
|
||||
from supervision.detection.utils.vlms import edit_distance, fuzzy_match_index
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"string_1, string_2, case_sensitive, expected_result",
|
||||
[
|
||||
# identical strings, various cases
|
||||
("hello", "hello", True, 0),
|
||||
("hello", "hello", False, 0),
|
||||
# case sensitive vs insensitive
|
||||
("Test", "test", True, 1),
|
||||
("Test", "test", False, 0),
|
||||
("CASE", "case", True, 4),
|
||||
("CASE", "case", False, 0),
|
||||
# completely different
|
||||
("abc", "xyz", True, 3),
|
||||
("abc", "xyz", False, 3),
|
||||
# one string empty
|
||||
("hello", "", True, 5),
|
||||
("", "world", True, 5),
|
||||
# single character cases
|
||||
("a", "b", True, 1),
|
||||
("A", "a", True, 1),
|
||||
("A", "a", False, 0),
|
||||
# whitespaces
|
||||
("hello world", "helloworld", True, 1),
|
||||
("test", " test", True, 1),
|
||||
# unicode and emoji
|
||||
("😊", "😊", True, 0),
|
||||
("😊", "😢", True, 1),
|
||||
# long string vs empty
|
||||
("a" * 100, "", True, 100),
|
||||
("", "b" * 100, True, 100),
|
||||
# prefix/suffix
|
||||
("prefix", "prefixes", True, 2),
|
||||
("suffix", "asuffix", True, 1),
|
||||
# leading/trailing whitespace
|
||||
(" hello", "hello", True, 1),
|
||||
("hello", "hello ", True, 1),
|
||||
# long almost-equal string
|
||||
(
|
||||
"The quick brown fox jumps over the lazy dog",
|
||||
"The quick brown fox jumps over the lazy cog",
|
||||
True,
|
||||
1,
|
||||
),
|
||||
(
|
||||
"The quick brown fox jumps over the lazy dog",
|
||||
"The quick brown fox jumps over the lazy cog",
|
||||
False,
|
||||
1,
|
||||
),
|
||||
# both empty
|
||||
("", "", True, 0),
|
||||
("", "", False, 0),
|
||||
# mixed case with symbols
|
||||
("123ABC!", "123abc!", True, 3),
|
||||
("123ABC!", "123abc!", False, 0),
|
||||
],
|
||||
)
|
||||
def test_edit_distance(string_1, string_2, case_sensitive, expected_result):
|
||||
assert (
|
||||
edit_distance(string_1, string_2, case_sensitive=case_sensitive)
|
||||
== expected_result
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"candidates, query, threshold, case_sensitive, expected_result",
|
||||
[
|
||||
# exact match at index 0
|
||||
(["cat", "dog", "rat"], "cat", 0, True, 0),
|
||||
# match at index 2 within threshold
|
||||
(["cat", "dog", "rat"], "dat", 1, True, 0),
|
||||
# no match due to high threshold
|
||||
(["cat", "dog", "rat"], "bat", 0, True, None),
|
||||
# multiple possible matches, returns first
|
||||
(["apple", "apply", "appla"], "apple", 1, True, 0),
|
||||
# case-insensitive match
|
||||
(["Alpha", "beta", "Gamma"], "alpha", 0, False, 0),
|
||||
# case-sensitive: no match
|
||||
(["Alpha", "beta", "Gamma"], "alpha", 0, True, None),
|
||||
# threshold boundary
|
||||
(["alpha", "beta", "gamma"], "bata", 1, True, 1),
|
||||
# no match (all distances too high)
|
||||
(["one", "two", "three"], "ten", 1, True, None),
|
||||
# unicode/emoji match
|
||||
(["😊", "😢", "😁"], "😄", 1, True, 0),
|
||||
(["😊", "😢", "😁"], "😊", 0, True, 0),
|
||||
# empty candidates
|
||||
([], "any", 2, True, None),
|
||||
# empty query, non-empty candidates
|
||||
(["", "abc"], "", 0, True, 0),
|
||||
(["", "abc"], "", 1, True, 0),
|
||||
(["a", "b", "c"], "", 1, True, 0),
|
||||
# non-empty query, empty candidate
|
||||
(["", ""], "a", 1, True, 0),
|
||||
# all candidates require higher edit than threshold
|
||||
(["short", "words", "only"], "longerword", 2, True, None),
|
||||
# repeated candidates
|
||||
(["a", "a", "a"], "b", 1, True, 0),
|
||||
],
|
||||
)
|
||||
def test_fuzzy_match_index(
|
||||
candidates, query, threshold, case_sensitive, expected_result
|
||||
):
|
||||
assert (
|
||||
fuzzy_match_index(
|
||||
candidates=candidates,
|
||||
query=query,
|
||||
threshold=threshold,
|
||||
case_sensitive=case_sensitive,
|
||||
)
|
||||
== expected_result
|
||||
)
|
||||
@@ -0,0 +1,268 @@
|
||||
from contextlib import nullcontext as DoesNotRaise
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.key_points.core import KeyPoints
|
||||
from test.test_utils import mock_key_points
|
||||
|
||||
KEY_POINTS = mock_key_points(
|
||||
xy=[
|
||||
[[0, 1], [2, 3], [4, 5], [6, 7], [8, 9]],
|
||||
[[10, 11], [12, 13], [14, 15], [16, 17], [18, 19]],
|
||||
[[20, 21], [22, 23], [24, 25], [26, 27], [28, 29]],
|
||||
],
|
||||
confidence=[
|
||||
[0.8, 0.2, 0.6, 0.1, 0.5],
|
||||
[0.7, 0.9, 0.3, 0.4, 0.0],
|
||||
[0.1, 0.6, 0.8, 0.2, 0.7],
|
||||
],
|
||||
class_id=[0, 1, 2],
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"key_points, index, expected_result, exception",
|
||||
[
|
||||
(
|
||||
KeyPoints.empty(),
|
||||
slice(None),
|
||||
KeyPoints.empty(),
|
||||
DoesNotRaise(),
|
||||
), # slice all key points when key points object empty
|
||||
(
|
||||
KEY_POINTS,
|
||||
slice(None),
|
||||
KEY_POINTS,
|
||||
DoesNotRaise(),
|
||||
), # slice all key points when key points object nonempty
|
||||
(
|
||||
KEY_POINTS,
|
||||
slice(0, 1),
|
||||
mock_key_points(
|
||||
xy=[[[0, 1], [2, 3], [4, 5], [6, 7], [8, 9]]],
|
||||
confidence=[[0.8, 0.2, 0.6, 0.1, 0.5]],
|
||||
class_id=[0],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the first skeleton by slice
|
||||
(
|
||||
KEY_POINTS,
|
||||
slice(0, 2),
|
||||
mock_key_points(
|
||||
xy=[
|
||||
[[0, 1], [2, 3], [4, 5], [6, 7], [8, 9]],
|
||||
[[10, 11], [12, 13], [14, 15], [16, 17], [18, 19]],
|
||||
],
|
||||
confidence=[
|
||||
[0.8, 0.2, 0.6, 0.1, 0.5],
|
||||
[0.7, 0.9, 0.3, 0.4, 0.0],
|
||||
],
|
||||
class_id=[0, 1],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the first skeleton by slice
|
||||
(
|
||||
KEY_POINTS,
|
||||
0,
|
||||
mock_key_points(
|
||||
xy=[[[0, 1], [2, 3], [4, 5], [6, 7], [8, 9]]],
|
||||
confidence=[[0.8, 0.2, 0.6, 0.1, 0.5]],
|
||||
class_id=[0],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the first skeleton by index
|
||||
(
|
||||
KEY_POINTS,
|
||||
-1,
|
||||
mock_key_points(
|
||||
xy=[[[20, 21], [22, 23], [24, 25], [26, 27], [28, 29]]],
|
||||
confidence=[[0.1, 0.6, 0.8, 0.2, 0.7]],
|
||||
class_id=[2],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the last skeleton by index
|
||||
(
|
||||
KEY_POINTS,
|
||||
[0, 1],
|
||||
mock_key_points(
|
||||
xy=[
|
||||
[[0, 1], [2, 3], [4, 5], [6, 7], [8, 9]],
|
||||
[[10, 11], [12, 13], [14, 15], [16, 17], [18, 19]],
|
||||
],
|
||||
confidence=[
|
||||
[0.8, 0.2, 0.6, 0.1, 0.5],
|
||||
[0.7, 0.9, 0.3, 0.4, 0.0],
|
||||
],
|
||||
class_id=[0, 1],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the first two skeletons by index; list
|
||||
(
|
||||
KEY_POINTS,
|
||||
np.array([0, 1]),
|
||||
mock_key_points(
|
||||
xy=[
|
||||
[[0, 1], [2, 3], [4, 5], [6, 7], [8, 9]],
|
||||
[[10, 11], [12, 13], [14, 15], [16, 17], [18, 19]],
|
||||
],
|
||||
confidence=[
|
||||
[0.8, 0.2, 0.6, 0.1, 0.5],
|
||||
[0.7, 0.9, 0.3, 0.4, 0.0],
|
||||
],
|
||||
class_id=[0, 1],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the first two skeletons by index; np.array
|
||||
(
|
||||
KEY_POINTS,
|
||||
[True, True, False],
|
||||
mock_key_points(
|
||||
xy=[
|
||||
[[0, 1], [2, 3], [4, 5], [6, 7], [8, 9]],
|
||||
[[10, 11], [12, 13], [14, 15], [16, 17], [18, 19]],
|
||||
],
|
||||
confidence=[
|
||||
[0.8, 0.2, 0.6, 0.1, 0.5],
|
||||
[0.7, 0.9, 0.3, 0.4, 0.0],
|
||||
],
|
||||
class_id=[0, 1],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select only skeletons associated with positive filter; list
|
||||
(
|
||||
KEY_POINTS,
|
||||
np.array([True, True, False]),
|
||||
mock_key_points(
|
||||
xy=[
|
||||
[[0, 1], [2, 3], [4, 5], [6, 7], [8, 9]],
|
||||
[[10, 11], [12, 13], [14, 15], [16, 17], [18, 19]],
|
||||
],
|
||||
confidence=[
|
||||
[0.8, 0.2, 0.6, 0.1, 0.5],
|
||||
[0.7, 0.9, 0.3, 0.4, 0.0],
|
||||
],
|
||||
class_id=[0, 1],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select only skeletons associated with positive filter; list
|
||||
(
|
||||
KEY_POINTS,
|
||||
(slice(None), slice(None)),
|
||||
KEY_POINTS,
|
||||
DoesNotRaise(),
|
||||
), # slice all anchors from all skeletons
|
||||
(
|
||||
KEY_POINTS,
|
||||
(slice(None), slice(0, 1)),
|
||||
mock_key_points(
|
||||
xy=[[[0, 1]], [[10, 11]], [[20, 21]]],
|
||||
confidence=[[0.8], [0.7], [0.1]],
|
||||
class_id=[0, 1, 2],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # slice the first anchor from every skeleton
|
||||
(
|
||||
KEY_POINTS,
|
||||
(slice(None), slice(0, 2)),
|
||||
mock_key_points(
|
||||
xy=[[[0, 1], [2, 3]], [[10, 11], [12, 13]], [[20, 21], [22, 23]]],
|
||||
confidence=[[0.8, 0.2], [0.7, 0.9], [0.1, 0.6]],
|
||||
class_id=[0, 1, 2],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # slice the first anchor two anchors from every skeleton
|
||||
(
|
||||
KEY_POINTS,
|
||||
(slice(None), 0),
|
||||
mock_key_points(
|
||||
xy=[[[0, 1]], [[10, 11]], [[20, 21]]],
|
||||
confidence=[[0.8], [0.7], [0.1]],
|
||||
class_id=[0, 1, 2],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the first anchor from every skeleton by index
|
||||
(
|
||||
KEY_POINTS,
|
||||
(slice(None), -1),
|
||||
mock_key_points(
|
||||
xy=[[[8, 9]], [[18, 19]], [[28, 29]]],
|
||||
confidence=[[0.5], [0.0], [0.7]],
|
||||
class_id=[0, 1, 2],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the last anchor from every skeleton by index
|
||||
(
|
||||
KEY_POINTS,
|
||||
(slice(None), [0, 1]),
|
||||
mock_key_points(
|
||||
xy=[[[0, 1], [2, 3]], [[10, 11], [12, 13]], [[20, 21], [22, 23]]],
|
||||
confidence=[[0.8, 0.2], [0.7, 0.9], [0.1, 0.6]],
|
||||
class_id=[0, 1, 2],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the first two anchors from every skeleton by index; list
|
||||
(
|
||||
KEY_POINTS,
|
||||
(slice(None), np.array([0, 1])),
|
||||
mock_key_points(
|
||||
xy=[[[0, 1], [2, 3]], [[10, 11], [12, 13]], [[20, 21], [22, 23]]],
|
||||
confidence=[[0.8, 0.2], [0.7, 0.9], [0.1, 0.6]],
|
||||
class_id=[0, 1, 2],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the first two anchors from every skeleton by index; np.array
|
||||
(
|
||||
KEY_POINTS,
|
||||
(slice(None), [True, True, False, False, False]),
|
||||
mock_key_points(
|
||||
xy=[[[0, 1], [2, 3]], [[10, 11], [12, 13]], [[20, 21], [22, 23]]],
|
||||
confidence=[[0.8, 0.2], [0.7, 0.9], [0.1, 0.6]],
|
||||
class_id=[0, 1, 2],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select only anchors associated with positive filter; list
|
||||
(
|
||||
KEY_POINTS,
|
||||
(slice(None), np.array([True, True, False, False, False])),
|
||||
mock_key_points(
|
||||
xy=[[[0, 1], [2, 3]], [[10, 11], [12, 13]], [[20, 21], [22, 23]]],
|
||||
confidence=[[0.8, 0.2], [0.7, 0.9], [0.1, 0.6]],
|
||||
class_id=[0, 1, 2],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select only anchors associated with positive filter; np.array
|
||||
(
|
||||
KEY_POINTS,
|
||||
(0, 0),
|
||||
mock_key_points(
|
||||
xy=[
|
||||
[[0, 1]],
|
||||
],
|
||||
confidence=[
|
||||
[0.8],
|
||||
],
|
||||
class_id=[0],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the first anchor from the first skeleton by index
|
||||
(
|
||||
KEY_POINTS,
|
||||
(0, -1),
|
||||
mock_key_points(
|
||||
xy=[
|
||||
[[8, 9]],
|
||||
],
|
||||
confidence=[
|
||||
[0.5],
|
||||
],
|
||||
class_id=[0],
|
||||
),
|
||||
DoesNotRaise(),
|
||||
), # select the last anchor from the first skeleton by index
|
||||
],
|
||||
)
|
||||
def test_key_points_getitem(key_points, index, expected_result, exception):
|
||||
with exception:
|
||||
result = key_points[index]
|
||||
assert result == expected_result
|
||||
@@ -0,0 +1,328 @@
|
||||
"""
|
||||
Tests for Mean Average Precision ID=0 bug fix
|
||||
"""
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.metrics.mean_average_precision import MeanAveragePrecision
|
||||
|
||||
|
||||
def test_single_perfect_detection():
|
||||
"""Test that single perfect detection gets 1.0 mAP (not 0.0 due to ID=0 bug)"""
|
||||
# Perfect detection (identical prediction and target)
|
||||
detection = Detections(
|
||||
xyxy=np.array([[10, 10, 50, 50]], dtype=np.float64),
|
||||
class_id=np.array([0]),
|
||||
confidence=np.array([0.9]),
|
||||
)
|
||||
|
||||
metric = MeanAveragePrecision()
|
||||
metric.update([detection], [detection])
|
||||
result = metric.compute()
|
||||
|
||||
# Should be perfect 1.0 mAP, not 0.0 due to ID=0 bug
|
||||
assert abs(result.map50_95 - 1.0) < 1e-6
|
||||
|
||||
|
||||
def test_multiple_perfect_detections():
|
||||
"""Test that multiple perfect detections get 1.0 mAP"""
|
||||
# Multiple perfect detections in one image
|
||||
detections = Detections(
|
||||
xyxy=np.array(
|
||||
[[10, 10, 50, 50], [100, 100, 140, 140], [200, 200, 240, 240]],
|
||||
dtype=np.float64,
|
||||
),
|
||||
class_id=np.array([0, 0, 0]),
|
||||
confidence=np.array([0.9, 0.9, 0.9]),
|
||||
)
|
||||
|
||||
metric = MeanAveragePrecision()
|
||||
metric.update([detections], [detections])
|
||||
result = metric.compute()
|
||||
|
||||
# Should be perfect 1.0 mAP
|
||||
assert abs(result.map50_95 - 1.0) < 1e-6
|
||||
|
||||
|
||||
def test_batch_updates_perfect_detections():
|
||||
"""Test that batch updates with perfect detections get 1.0 mAP"""
|
||||
# Single perfect detection for multiple batch updates
|
||||
detection = Detections(
|
||||
xyxy=np.array([[10, 10, 50, 50]], dtype=np.float64),
|
||||
class_id=np.array([0]),
|
||||
confidence=np.array([0.9]),
|
||||
)
|
||||
|
||||
metric = MeanAveragePrecision()
|
||||
# Add 3 batch updates
|
||||
metric.update([detection], [detection])
|
||||
metric.update([detection], [detection])
|
||||
metric.update([detection], [detection])
|
||||
result = metric.compute()
|
||||
|
||||
# Should be perfect 1.0 mAP across all batches
|
||||
assert abs(result.map50_95 - 1.0) < 1e-6
|
||||
|
||||
|
||||
def test_scenario_1_success_case_imperfect_match():
|
||||
"""Scenario 1: Success Case with imperfect match"""
|
||||
# Small object (class 0) - area = 30*30 = 900 < 1024
|
||||
small_perfect = Detections(
|
||||
xyxy=np.array([[10, 10, 40, 40]], dtype=np.float64),
|
||||
class_id=np.array([0]),
|
||||
confidence=np.array([0.95]),
|
||||
data={"area": np.array([900])},
|
||||
)
|
||||
|
||||
# Medium object (class 1) - area = 50*50 = 2500 (between 1024 and 9216)
|
||||
medium_target = Detections(
|
||||
xyxy=np.array([[10, 10, 60, 60]], dtype=np.float64),
|
||||
class_id=np.array([1]),
|
||||
data={"area": np.array([2500])},
|
||||
)
|
||||
medium_pred = Detections(
|
||||
xyxy=np.array([[12, 12, 60, 60]], dtype=np.float64), # Slightly off
|
||||
class_id=np.array([1]),
|
||||
confidence=np.array([0.9]),
|
||||
data={"area": np.array([2304])}, # 48*48
|
||||
)
|
||||
|
||||
# Large objects (classes 0, 1, 2) - area = 100*100 = 10000 > 9216
|
||||
large_targets = Detections(
|
||||
xyxy=np.array(
|
||||
[[10, 10, 110, 110], [120, 120, 220, 220], [230, 230, 330, 330]],
|
||||
dtype=np.float64,
|
||||
),
|
||||
class_id=np.array([2, 0, 1]),
|
||||
data={"area": np.array([10000, 10000, 10000])},
|
||||
)
|
||||
large_preds = Detections(
|
||||
xyxy=np.array(
|
||||
[[10, 10, 110, 110], [120, 120, 220, 220], [230, 230, 330, 330]],
|
||||
dtype=np.float64,
|
||||
),
|
||||
class_id=np.array([2, 0, 1]),
|
||||
confidence=np.array([0.9, 0.9, 0.9]),
|
||||
data={"area": np.array([10000, 10000, 10000])},
|
||||
)
|
||||
|
||||
metric = MeanAveragePrecision()
|
||||
metric.update([small_perfect], [small_perfect])
|
||||
metric.update([medium_pred], [medium_target])
|
||||
metric.update([large_preds], [large_targets])
|
||||
result = metric.compute()
|
||||
|
||||
# Should be close to 0.9 (slightly less than perfect due to medium object)
|
||||
assert 0.85 < result.map50_95 < 0.98 # Adjusted upper bound
|
||||
assert result.medium_objects.map50_95 < 1.0 # Medium should be less than perfect
|
||||
|
||||
|
||||
def test_scenario_2_missed_detection():
|
||||
"""Scenario 2: GT Present, No Prediction (Missed Detection)"""
|
||||
# Small object - area = 30*30 = 900 < 1024
|
||||
small_detection = Detections(
|
||||
xyxy=np.array([[10, 10, 40, 40]], dtype=np.float64),
|
||||
class_id=np.array([0]),
|
||||
confidence=np.array([0.95]),
|
||||
data={"area": np.array([900])},
|
||||
)
|
||||
|
||||
# Medium object - area = 50*50 = 2500 (between 1024 and 9216) - missed
|
||||
medium_target = Detections(
|
||||
xyxy=np.array([[10, 10, 60, 60]], dtype=np.float64),
|
||||
class_id=np.array([1]),
|
||||
data={"area": np.array([2500])},
|
||||
)
|
||||
no_medium_pred = Detections.empty()
|
||||
|
||||
# Large objects - area = 100*100 = 10000 > 9216
|
||||
large_detections = Detections(
|
||||
xyxy=np.array(
|
||||
[[10, 10, 110, 110], [120, 120, 220, 220], [230, 230, 330, 330]],
|
||||
dtype=np.float64,
|
||||
),
|
||||
class_id=np.array([2, 0, 1]),
|
||||
confidence=np.array([0.9, 0.9, 0.9]),
|
||||
data={"area": np.array([10000, 10000, 10000])},
|
||||
)
|
||||
|
||||
metric = MeanAveragePrecision()
|
||||
metric.update([small_detection], [small_detection])
|
||||
metric.update([no_medium_pred], [medium_target])
|
||||
metric.update([large_detections], [large_detections])
|
||||
result = metric.compute()
|
||||
|
||||
# Medium objects should have 0.0 mAP (missed detection)
|
||||
assert abs(result.medium_objects.map50_95 - 0.0) < 1e-6
|
||||
|
||||
|
||||
def test_scenario_3_false_positive():
|
||||
"""Scenario 3: No GT, Prediction Present (False Positive)"""
|
||||
# Small object - area = 30*30 = 900 < 1024
|
||||
small_detection = Detections(
|
||||
xyxy=np.array([[10, 10, 40, 40]], dtype=np.float64),
|
||||
class_id=np.array([0]),
|
||||
confidence=np.array([0.95]),
|
||||
data={"area": np.array([900])},
|
||||
)
|
||||
|
||||
# Medium object - area = 50*50 = 2500 - false positive (no GT)
|
||||
medium_pred = Detections(
|
||||
xyxy=np.array([[12, 12, 62, 62]], dtype=np.float64),
|
||||
class_id=np.array([1]),
|
||||
confidence=np.array([0.9]),
|
||||
data={"area": np.array([2500])},
|
||||
)
|
||||
no_medium_target = Detections.empty()
|
||||
|
||||
# Large objects - area = 100*100 = 10000 > 9216
|
||||
large_detections = Detections(
|
||||
xyxy=np.array(
|
||||
[[10, 10, 110, 110], [120, 120, 220, 220], [230, 230, 330, 330]],
|
||||
dtype=np.float64,
|
||||
),
|
||||
class_id=np.array([2, 0, 1]),
|
||||
confidence=np.array([0.9, 0.9, 0.9]),
|
||||
data={"area": np.array([10000, 10000, 10000])},
|
||||
)
|
||||
|
||||
metric = MeanAveragePrecision()
|
||||
metric.update([small_detection], [small_detection])
|
||||
metric.update([medium_pred], [no_medium_target])
|
||||
metric.update([large_detections], [large_detections])
|
||||
result = metric.compute()
|
||||
|
||||
# Medium objects should have -1 mAP (false positive, matching pycocotools)
|
||||
assert result.medium_objects.map50_95 == -1
|
||||
|
||||
|
||||
def test_scenario_4_no_data():
|
||||
"""Scenario 4: No GT, No Prediction (Category has no data)"""
|
||||
# Small object - area = 30*30 = 900 < 1024
|
||||
small_detection = Detections(
|
||||
xyxy=np.array([[10, 10, 40, 40]], dtype=np.float64),
|
||||
class_id=np.array([0]),
|
||||
confidence=np.array([0.95]),
|
||||
data={"area": np.array([900])},
|
||||
)
|
||||
|
||||
# Medium object - no data at all
|
||||
no_medium = Detections.empty()
|
||||
|
||||
# Large objects - area = 100*100 = 10000 > 9216 - only classes 0 and 2 (no class 1)
|
||||
large_targets = Detections(
|
||||
xyxy=np.array(
|
||||
[
|
||||
[10, 10, 110, 110],
|
||||
[120, 120, 220, 220],
|
||||
],
|
||||
dtype=np.float64,
|
||||
),
|
||||
class_id=np.array([2, 0]),
|
||||
data={"area": np.array([10000, 10000])},
|
||||
)
|
||||
large_preds = Detections(
|
||||
xyxy=np.array(
|
||||
[
|
||||
[10, 10, 110, 110],
|
||||
[120, 120, 220, 220],
|
||||
],
|
||||
dtype=np.float64,
|
||||
),
|
||||
class_id=np.array([2, 0]),
|
||||
confidence=np.array([0.9, 0.9]),
|
||||
data={"area": np.array([10000, 10000])},
|
||||
)
|
||||
|
||||
metric = MeanAveragePrecision()
|
||||
metric.update([small_detection], [small_detection])
|
||||
metric.update([no_medium], [no_medium])
|
||||
metric.update([large_preds], [large_targets])
|
||||
result = metric.compute()
|
||||
|
||||
# Should NOT have negative mAP values for overall
|
||||
assert result.map50_95 >= 0.0
|
||||
# Medium objects should have -1 mAP (no data, matching pycocotools)
|
||||
assert result.medium_objects.map50_95 == -1
|
||||
|
||||
|
||||
def test_scenario_5_only_one_class_present():
|
||||
"""Scenario 5: Only 1 of 3 Classes Present (Perfect Match)"""
|
||||
# Only class 0 objects with perfect matches
|
||||
detections_class_0 = [
|
||||
Detections(
|
||||
xyxy=np.array([[10, 10, 40, 40]], dtype=np.float64),
|
||||
class_id=np.array([0]),
|
||||
confidence=np.array([0.95]),
|
||||
),
|
||||
Detections(
|
||||
xyxy=np.array([[20, 20, 230, 130]], dtype=np.float64),
|
||||
class_id=np.array([0]),
|
||||
confidence=np.array([0.9]),
|
||||
),
|
||||
]
|
||||
|
||||
metric = MeanAveragePrecision()
|
||||
for det in detections_class_0:
|
||||
metric.update([det], [det])
|
||||
|
||||
result = metric.compute()
|
||||
|
||||
# Should be 1.0 mAP (perfect match for the only class present)
|
||||
assert abs(result.map50_95 - 1.0) < 1e-6
|
||||
assert abs(result.map50 - 1.0) < 1e-6
|
||||
assert abs(result.map75 - 1.0) < 1e-6
|
||||
|
||||
|
||||
def test_mixed_classes_with_missing_detections():
|
||||
"""Test mixed scenario with some classes having no detections"""
|
||||
# Class 0: Perfect detection
|
||||
class_0_det = Detections(
|
||||
xyxy=np.array([[10, 10, 50, 50]], dtype=np.float64),
|
||||
class_id=np.array([0]),
|
||||
confidence=np.array([0.9]),
|
||||
)
|
||||
|
||||
# Class 1: GT exists but no prediction
|
||||
class_1_target = Detections(
|
||||
xyxy=np.array([[60, 60, 100, 100]], dtype=np.float64),
|
||||
class_id=np.array([1]),
|
||||
)
|
||||
class_1_pred = Detections.empty()
|
||||
|
||||
# Class 2: Prediction exists but no GT (false positive)
|
||||
class_2_pred = Detections(
|
||||
xyxy=np.array([[110, 110, 150, 150]], dtype=np.float64),
|
||||
class_id=np.array([2]),
|
||||
confidence=np.array([0.8]),
|
||||
)
|
||||
class_2_target = Detections.empty()
|
||||
|
||||
metric = MeanAveragePrecision()
|
||||
metric.update([class_0_det], [class_0_det])
|
||||
metric.update([class_1_pred], [class_1_target])
|
||||
metric.update([class_2_pred], [class_2_target])
|
||||
result = metric.compute()
|
||||
|
||||
# Should not have negative mAP
|
||||
assert result.map50_95 >= 0.0
|
||||
# Should be less than 1.0 due to missed detection and false positive
|
||||
assert result.map50_95 < 1.0
|
||||
|
||||
|
||||
def test_empty_predictions_and_targets():
|
||||
"""Test completely empty predictions and targets"""
|
||||
metric = MeanAveragePrecision()
|
||||
metric.update([Detections.empty()], [Detections.empty()])
|
||||
result = metric.compute()
|
||||
|
||||
# Should return -1 for no data (matching pycocotools behavior)
|
||||
assert result.map50_95 == -1
|
||||
assert result.map50 == -1
|
||||
assert result.map75 == -1
|
||||
|
||||
# All object size categories should also be -1
|
||||
assert result.small_objects.map50_95 == -1
|
||||
assert result.medium_objects.map50_95 == -1
|
||||
assert result.large_objects.map50_95 == -1
|
||||
@@ -0,0 +1,131 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.metrics.mean_average_precision import MeanAveragePrecision
|
||||
|
||||
|
||||
class TestMeanAveragePrecisionArea:
|
||||
"""Test area calculation in MeanAveragePrecision."""
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"xyxy, expected_areas, expected_size_maps",
|
||||
[
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[10, 10, 40, 40], # Small: 900
|
||||
[100, 100, 200, 150], # Medium: 5000
|
||||
[300, 300, 500, 400], # Large: 20000
|
||||
],
|
||||
dtype=np.float32,
|
||||
),
|
||||
[900.0, 5000.0, 20000.0],
|
||||
{"small": True, "medium": True, "large": True},
|
||||
),
|
||||
(
|
||||
np.array([[0, 0, 10, 10]], dtype=np.float32), # Small: 100
|
||||
[100.0],
|
||||
{"small": True, "medium": False, "large": False},
|
||||
),
|
||||
(
|
||||
np.array([[0, 0, 50, 50]], dtype=np.float32), # Medium: 2500
|
||||
[2500.0],
|
||||
{"small": False, "medium": True, "large": False},
|
||||
),
|
||||
(
|
||||
np.array([[0, 0, 100, 100]], dtype=np.float32), # Large: 10000
|
||||
[10000.0],
|
||||
{"small": False, "medium": False, "large": True},
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_area_calculation_and_size_specific_map(
|
||||
self, xyxy, expected_areas, expected_size_maps
|
||||
):
|
||||
"""Test area calculation and size-specific mAP functionality."""
|
||||
gt = Detections(
|
||||
xyxy=xyxy,
|
||||
class_id=np.arange(len(xyxy)),
|
||||
)
|
||||
pred = Detections(
|
||||
xyxy=gt.xyxy.copy(),
|
||||
class_id=gt.class_id.copy(),
|
||||
confidence=np.full(len(xyxy), 0.9),
|
||||
)
|
||||
|
||||
map_metric = MeanAveragePrecision()
|
||||
map_metric.update([pred], [gt])
|
||||
|
||||
# Test area calculation
|
||||
prepared_targets = map_metric._prepare_targets(map_metric._targets_list)
|
||||
areas = [ann["area"] for ann in prepared_targets["annotations"]]
|
||||
assert np.allclose(areas, expected_areas), (
|
||||
f"Expected {expected_areas}, got {areas}"
|
||||
)
|
||||
|
||||
# Test size-specific mAP
|
||||
result = map_metric.compute()
|
||||
|
||||
if expected_size_maps["small"]:
|
||||
assert result.small_objects.map50 > 0.9, (
|
||||
"Small objects should have high mAP"
|
||||
)
|
||||
else:
|
||||
assert result.small_objects.map50 == -1.0, (
|
||||
"Small objects should have no data"
|
||||
)
|
||||
|
||||
if expected_size_maps["medium"]:
|
||||
assert result.medium_objects.map50 > 0.9, (
|
||||
"Medium objects should have high mAP"
|
||||
)
|
||||
else:
|
||||
assert result.medium_objects.map50 == -1.0, (
|
||||
"Medium objects should have no data"
|
||||
)
|
||||
|
||||
if expected_size_maps["large"]:
|
||||
assert result.large_objects.map50 > 0.9, (
|
||||
"Large objects should have high mAP"
|
||||
)
|
||||
else:
|
||||
assert result.large_objects.map50 == -1.0, (
|
||||
"Large objects should have no data"
|
||||
)
|
||||
|
||||
def test_area_preserved_from_data(self):
|
||||
"""Test that area from data field is preserved (COCO case)."""
|
||||
gt = Detections(
|
||||
xyxy=np.array(
|
||||
[[100, 100, 200, 150]], dtype=np.float32
|
||||
), # Would calculate to 5000
|
||||
class_id=np.array([0]),
|
||||
)
|
||||
# Override with custom area
|
||||
gt.data = {"area": np.array([3000.0])}
|
||||
|
||||
pred = Detections(
|
||||
xyxy=gt.xyxy.copy(),
|
||||
class_id=gt.class_id.copy(),
|
||||
confidence=np.array([0.9]),
|
||||
)
|
||||
pred.data = {"area": np.array([3000.0])}
|
||||
|
||||
map_metric = MeanAveragePrecision()
|
||||
map_metric.update([pred], [gt])
|
||||
|
||||
prepared_targets = map_metric._prepare_targets(map_metric._targets_list)
|
||||
used_area = prepared_targets["annotations"][0]["area"]
|
||||
|
||||
assert np.allclose(used_area, 3000.0), (
|
||||
f"Should use provided area 3000.0, got {used_area}"
|
||||
)
|
||||
|
||||
# Verify it's different from what would be calculated
|
||||
calculated_area = (200 - 100) * (150 - 100) # 100 * 50 = 5000
|
||||
assert not np.allclose(used_area, calculated_area), (
|
||||
"Should use provided area, not calculated"
|
||||
)
|
||||
+5
-6
@@ -3,14 +3,13 @@ from __future__ import annotations
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.keypoint.core import KeyPoints
|
||||
from supervision.key_points.core import KeyPoints
|
||||
|
||||
|
||||
def mock_detections(
|
||||
xyxy: npt.NDArray[np.float32],
|
||||
xyxy: list[list[float]],
|
||||
mask: list[np.ndarray] | None = None,
|
||||
confidence: list[float] | None = None,
|
||||
class_id: list[int] | None = None,
|
||||
@@ -34,9 +33,9 @@ def mock_detections(
|
||||
)
|
||||
|
||||
|
||||
def mock_keypoints(
|
||||
xy: npt.NDArray[np.float32],
|
||||
confidence: list[float] | None = None,
|
||||
def mock_key_points(
|
||||
xy: list[list[list[float]]],
|
||||
confidence: list[list[float]] | None = None,
|
||||
class_id: list[int] | None = None,
|
||||
data: dict[str, list[Any]] | None = None,
|
||||
) -> KeyPoints:
|
||||
|
||||
@@ -3,7 +3,7 @@ from PIL import Image, ImageChops
|
||||
|
||||
from supervision.utils.conversion import (
|
||||
cv2_to_pillow,
|
||||
ensure_cv2_image_for_processing,
|
||||
ensure_cv2_image_for_standalone_function,
|
||||
images_to_cv2,
|
||||
pillow_to_cv2,
|
||||
)
|
||||
@@ -16,7 +16,7 @@ def test_ensure_cv2_image_for_processing_when_pillow_image_submitted(
|
||||
param_a_value = 3
|
||||
param_b_value = "some"
|
||||
|
||||
@ensure_cv2_image_for_processing
|
||||
@ensure_cv2_image_for_standalone_function
|
||||
def my_custom_processing_function(
|
||||
image: np.ndarray,
|
||||
param_a: int,
|
||||
@@ -55,7 +55,7 @@ def test_ensure_cv2_image_for_processing_when_cv2_image_submitted(
|
||||
param_a_value = 3
|
||||
param_b_value = "some"
|
||||
|
||||
@ensure_cv2_image_for_processing
|
||||
@ensure_cv2_image_for_standalone_function
|
||||
def my_custom_processing_function(
|
||||
image: np.ndarray,
|
||||
param_a: int,
|
||||
|
||||
+1
-147
@@ -1,9 +1,7 @@
|
||||
import numpy as np
|
||||
import pytest
|
||||
from PIL import Image, ImageChops
|
||||
|
||||
from supervision import Color, Point
|
||||
from supervision.utils.image import create_tiles, letterbox_image, resize_image
|
||||
from supervision.utils.image import letterbox_image, resize_image
|
||||
|
||||
|
||||
def test_resize_image_for_opencv_image() -> None:
|
||||
@@ -96,147 +94,3 @@ def test_letterbox_image_for_pillow_image() -> None:
|
||||
assert difference.getbbox() is None, (
|
||||
"Expected padding to be added top and bottom with padding added top and bottom"
|
||||
)
|
||||
|
||||
|
||||
def test_create_tiles_with_one_image(
|
||||
one_image: np.ndarray, single_image_tile: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(images=[one_image], single_tile_size=(240, 240))
|
||||
|
||||
# # then
|
||||
assert np.allclose(result, single_image_tile, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_one_image_and_enforced_grid(
|
||||
one_image: np.ndarray, single_image_tile_enforced_grid: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(
|
||||
images=[one_image],
|
||||
grid_size=(None, 3),
|
||||
single_tile_size=(240, 240),
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(result, single_image_tile_enforced_grid, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_two_images(
|
||||
two_images: list[np.ndarray], two_images_tile: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(images=two_images, single_tile_size=(240, 240))
|
||||
|
||||
# then
|
||||
assert np.allclose(result, two_images_tile, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_three_images(
|
||||
three_images: list[np.ndarray], three_images_tile: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(images=three_images, single_tile_size=(240, 240))
|
||||
|
||||
# then
|
||||
assert np.allclose(result, three_images_tile, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_four_images(
|
||||
four_images: list[np.ndarray],
|
||||
four_images_tile: np.ndarray,
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(images=four_images, single_tile_size=(240, 240))
|
||||
|
||||
# then
|
||||
assert np.allclose(result, four_images_tile, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images(
|
||||
all_images: list[np.ndarray],
|
||||
all_images_tile: np.ndarray,
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(images=all_images, single_tile_size=(240, 240))
|
||||
|
||||
# then
|
||||
assert np.allclose(result, all_images_tile, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images_and_custom_grid(
|
||||
all_images: list[np.ndarray], all_images_tile_and_custom_grid: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(
|
||||
images=all_images,
|
||||
grid_size=(3, 3),
|
||||
single_tile_size=(240, 240),
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(result, all_images_tile_and_custom_grid, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images_and_custom_colors(
|
||||
all_images: list[np.ndarray], all_images_tile_and_custom_colors: np.ndarray
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(
|
||||
images=all_images,
|
||||
tile_margin_color=(127, 127, 127),
|
||||
tile_padding_color=(224, 224, 224),
|
||||
single_tile_size=(240, 240),
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(result, all_images_tile_and_custom_colors, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images_and_titles(
|
||||
all_images: list[np.ndarray],
|
||||
all_images_tile_and_custom_colors_and_titles: np.ndarray,
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(
|
||||
images=all_images,
|
||||
titles=["Image 1", None, "Image 3", "Image 4"],
|
||||
single_tile_size=(240, 240),
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(result, all_images_tile_and_custom_colors_and_titles, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images_and_titles_with_custom_configs(
|
||||
all_images: list[np.ndarray],
|
||||
all_images_tile_and_titles_with_custom_configs: np.ndarray,
|
||||
) -> None:
|
||||
# when
|
||||
result = create_tiles(
|
||||
images=all_images,
|
||||
titles=["Image 1", None, "Image 3", "Image 4"],
|
||||
single_tile_size=(240, 240),
|
||||
titles_anchors=[
|
||||
Point(x=200, y=300),
|
||||
Point(x=300, y=400),
|
||||
None,
|
||||
Point(x=300, y=400),
|
||||
],
|
||||
titles_color=Color.RED,
|
||||
titles_scale=1.5,
|
||||
titles_thickness=3,
|
||||
titles_padding=20,
|
||||
titles_background_color=Color.BLACK,
|
||||
default_title_placement="bottom",
|
||||
)
|
||||
|
||||
# then
|
||||
assert np.allclose(result, all_images_tile_and_titles_with_custom_configs, atol=5.0)
|
||||
|
||||
|
||||
def test_create_tiles_with_all_images_and_custom_grid_to_small_to_fit_images(
|
||||
all_images: list[np.ndarray],
|
||||
) -> None:
|
||||
with pytest.raises(ValueError):
|
||||
_ = create_tiles(images=all_images, grid_size=(2, 2))
|
||||
|
||||
Reference in New Issue
Block a user