Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 SkalskiP |
ccc7118bcb | ||
|
Piotr Skalski
|
2cccfc5b62 | ||
|
Onuralp SEZER
|
93584cbb89 | ||
|
Piotr Skalski
|
5bfc977fac | ||
|
Piotr Skalski
|
16c41d9d5d | ||
|
SkalskiP
|
81c2a09430 | ||
|
Piotr Skalski
|
16b7222012 | ||
|
Piotr Skalski
|
6b2136d57b | ||
|
Piotr Skalski
|
908a1b4d89 | ||
|
Onuralp SEZER
|
7e283d4eeb | ||
|
Raif Olson
|
a2aca62ecb | ||
|
Onuralp SEZER
|
0a5fb7b47e | ||
|
Piotr Skalski
|
7132c034ab | ||
|
pre-commit-ci[bot]
|
dc5f841bae | ||
|
SkalskiP
|
64eef66b54 | ||
|
Raif Olson
|
dc45c0a5e0 | ||
|
Piotr Skalski
|
69563b8bbb | ||
|
pre-commit-ci[bot]
|
29ba24f89a | ||
|
Raif Olson
|
da4404e875 | ||
|
Raif Olson
|
089594f72d | ||
|
pre-commit-ci[bot]
|
e9edc2fb1d | ||
|
Raif Olson
|
ad24d3811b | ||
|
dependabot[bot]
|
8fb3ba70b0 | ||
|
SkalskiP
|
34b80eb3c0 | ||
|
Piotr Skalski
|
3276973446 | ||
|
Piotr Skalskiandpre-commit-ci[bot]
|
725d95c6ce | ||
|
pre-commit-ci[bot]
|
13f85ae6cc | ||
|
Griffin-Sullivan
|
c67078b53c | ||
|
Piotr Skalski
|
42f9d4b69b | ||
|
Onuralp SEZER
|
d41caed36f | ||
|
SkalskiP
|
5a040969d7 | ||
|
Raif Olson
|
3ed4aeffff | ||
|
Onuralp SEZER
|
97b8312570 | ||
|
Piotr Skalski
|
94e9719f20 | ||
|
SkalskiP
|
0d16b13e7a | ||
|
Piotr Skalski
|
5c03173c7c | ||
|
pre-commit-ci[bot]
|
cf88cc0384 | ||
|
SkalskiP
|
15e17adef1 | ||
|
pre-commit-ci[bot]
|
ca425a628d | ||
|
Piotr Skalski
|
09a47bec62 | ||
|
pre-commit-ci[bot]
|
90f6893d3d | ||
|
SkalskiP
|
b585bb0724 | ||
|
Piotr Skalski
|
495f9a9003 | ||
|
Piotr Skalski
|
4a6a6dbf6b | ||
|
SkalskiP
|
fec251d979 | ||
|
SkalskiP
|
6d27b8067b | ||
|
Onuralp SEZER
|
3da0ca4ffc | ||
|
Onuralp SEZER
|
fc03b0c386 | ||
|
pre-commit-ci[bot]
|
4660dfd0d3 | ||
|
SkalskiP
|
e7b4d6ec41 | ||
|
pre-commit-ci[bot]
|
bc586562b5 | ||
|
SkalskiP
|
57c6182325 | ||
|
dependabot[bot]
|
c3b617d47e | ||
|
dependabot[bot]
|
6458d4454d | ||
|
Christoforos Aristeidou
|
957ced0614 | ||
|
Christoforos Aristeidou
|
ed3c73eb02 | ||
|
Christoforos Aristeidou
|
3e4ddd5bd9 | ||
|
Christoforos Aristeidou
|
1fbdec6046 | ||
|
Raif Olson
|
1eb877c4d9 | ||
|
Onuralp SEZER
|
781a064d8a | ||
|
dependabot[bot]
|
70218b85e7 | ||
|
Onuralp SEZER
|
37318fafdf | ||
|
dependabot[bot]
|
f377a992e1 | ||
|
Piotr Skalski
|
6208013dcf | ||
|
SkalskiP
|
8a2abe72ae | ||
|
Piotr Skalski
|
d01b636ebe | ||
|
Onuralp SEZER
|
0e3e41287a | ||
|
Onuralp SEZER
|
5f9560afb8 | ||
|
pre-commit-ci[bot]
|
4abd128af5 | ||
|
Piotr Skalski
|
77908fe49b | ||
|
Onuralp SEZER
|
fb3a78f762 | ||
|
Onuralp SEZER
|
f43b3536be | ||
|
dependabot[bot]
|
345c086916 | ||
|
dependabot[bot]
|
123a61f2c6 | ||
|
Onuralp SEZER
|
63b338751f | ||
|
Onuralp SEZER
|
e8810fe8a2 | ||
|
Piotr Skalski
|
3d9d45fc07 | ||
|
Onuralp SEZER
|
4f9e5a590f | ||
|
pre-commit-ci[bot]
|
9f5c63b32d | ||
|
SkalskiP
|
a5b1079e39 | ||
|
Piotr Skalski
|
88d63473fe |
@@ -4,12 +4,18 @@ on:
|
||||
push:
|
||||
branches:
|
||||
- develop
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.event_name == 'push' && github.ref}}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
pull-requests: write
|
||||
|
||||
|
||||
jobs:
|
||||
deploy:
|
||||
runs-on: ubuntu-latest
|
||||
@@ -23,7 +29,7 @@ jobs:
|
||||
with:
|
||||
python-version: '3.10'
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install "mkdocs-material[all]"
|
||||
run: pip install "mkdocs-material"
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
|
||||
@@ -6,22 +6,24 @@ on:
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]+b[0-9]'
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]+rc[0-9]'
|
||||
|
||||
# Allows you to run this workflow manually from the Actions tab
|
||||
workflow_dispatch:
|
||||
|
||||
jobs:
|
||||
build-n-publish:
|
||||
name: Build and publish to PyPI
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: Checkout source
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: 🐍 Set up Python 3.8 environment for build
|
||||
with:
|
||||
ref: ${{ github.head_ref }}
|
||||
- name: 🐍 Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: "3.8"
|
||||
python-version: ${{ matrix.python-version }}
|
||||
|
||||
- name: 🏗️ Build source and wheel distributions
|
||||
run: |
|
||||
|
||||
@@ -4,7 +4,6 @@ on:
|
||||
tags:
|
||||
- '[0-9]+.[0-9]+[0-9]+.[0-9]'
|
||||
|
||||
# Allows you to run this workflow manually from the Actions tab
|
||||
workflow_dispatch:
|
||||
|
||||
jobs:
|
||||
@@ -12,7 +11,7 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
python-version: [3.8]
|
||||
python-version: ["3.10"]
|
||||
steps:
|
||||
- name: 🛎️ Checkout
|
||||
uses: actions/checkout@v4
|
||||
|
||||
@@ -46,7 +46,7 @@ repos:
|
||||
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.3.2
|
||||
rev: v0.3.4
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
|
||||
+10
-3
@@ -260,15 +260,22 @@ status: new
|
||||
=== "Label"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
|
||||
@@ -281,7 +288,7 @@ status: new
|
||||
=== "Crop"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
+4
-4
@@ -41,13 +41,13 @@ comments: true
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_dynamic_font_scale</h2>
|
||||
<h2>calculate_optimal_font_scale</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_text_scale
|
||||
:::supervision.draw.utils.calculate_optimal_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_dynamic_line_thickness</h2>
|
||||
<h2>calculate_optimal_line_thickness</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_line_thickness
|
||||
:::supervision.draw.utils.calculate_optimal_line_thickness
|
||||
|
||||
@@ -1,20 +1,35 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detect and Annotate
|
||||
|
||||
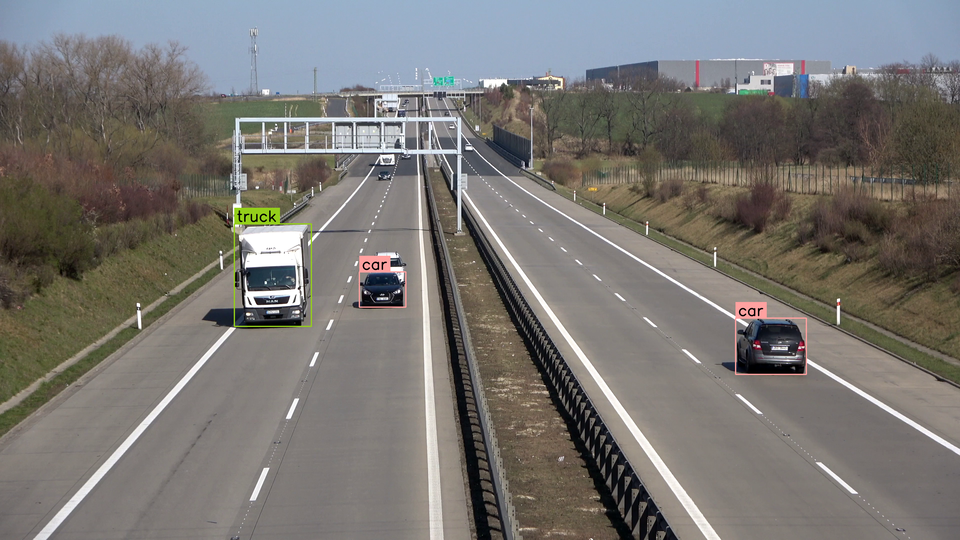
Supervision offers a streamlined solution to effortlessly annotate predictions from a
|
||||
range of object detection and segmentation models. This guide demonstrates how to
|
||||
execute inference using the YOLOv8 model with either the
|
||||
[Inference](https://github.com/roboflow/inference) or
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision for image annotation
|
||||
purposes.
|
||||
Supervision provides a seamless process for annotating predictions generated by various
|
||||
object detection and segmentation models. This guide shows how to perform inference
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision and use them to annotate
|
||||
source image.
|
||||
|
||||
|
||||
|
||||
## Run Inference
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation model.
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
@@ -27,68 +42,52 @@ First, you'll need to obtain predictions from your object detection or segmentat
|
||||
results = model(image)[0]
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from inference.models.utils import get_roboflow_model
|
||||
import torch
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<PATH TO IMAGE>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
```
|
||||
|
||||
## Load Predictions into Supervision
|
||||
|
||||
Now that we have predictions from a model, we can load them into Supervision.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
We can do so using the [`sv.Detections.from_ultralytics`](detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
We can do so using the [`sv.Detections.from_inference`](detection/core/#supervision.detection.core.Detections.from_inference) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
```{ .py hl_lines="2 8" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
You can conveniently load predictions from other computer vision frameworks and libraries using:
|
||||
|
||||
- [`from_deepsparse`](detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_inference`](detection/core/#supervision.detection.core.Detections.from_inference) ([Roboflow Inference](https://github.com/roboflow/inference))
|
||||
- [`from_sam`](detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_transformers`](detection/core/#supervision.detection.core.Detections.from_transformers) ([HuggingFace Transformers](https://github.com/huggingface/transformers))
|
||||
- [`from_yolo_nas`](detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
## Annotate Image
|
||||
|
||||
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](annotators/#supervision.annotators.core.LabelAnnotator) classes. If you are running the segmentation model [`sv.MaskAnnotator`](annotators/#supervision.annotators.core.MaskAnnotator) is a drop-in replacement for [`sv.BoundingBoxAnnotator`](annotators/#supervision.annotators.core.BoundingBoxAnnotator) that will allow you to draw masks instead of boxes.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
We can do so using the [`sv.Detections.from_ultralytics`](detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```{ .py hl_lines="2 8" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
@@ -97,30 +96,54 @@ Finally, we can annotate the image with the predictions. Since we are working wi
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.model.names[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
We can do so using the [`sv.Detections.from_transformers`](detection/core/#supervision.detection.core.Detections.from_transformers) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```{ .py hl_lines="2 19" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<PATH TO IMAGE>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
```
|
||||
|
||||
You can load predictions from other computer vision frameworks and libraries using:
|
||||
|
||||
- [`from_deepsparse`](/latest/detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](/latest/detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](/latest/detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_sam`](/latest/detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_yolo_nas`](/latest/detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
## Annotate Image with Detections
|
||||
|
||||
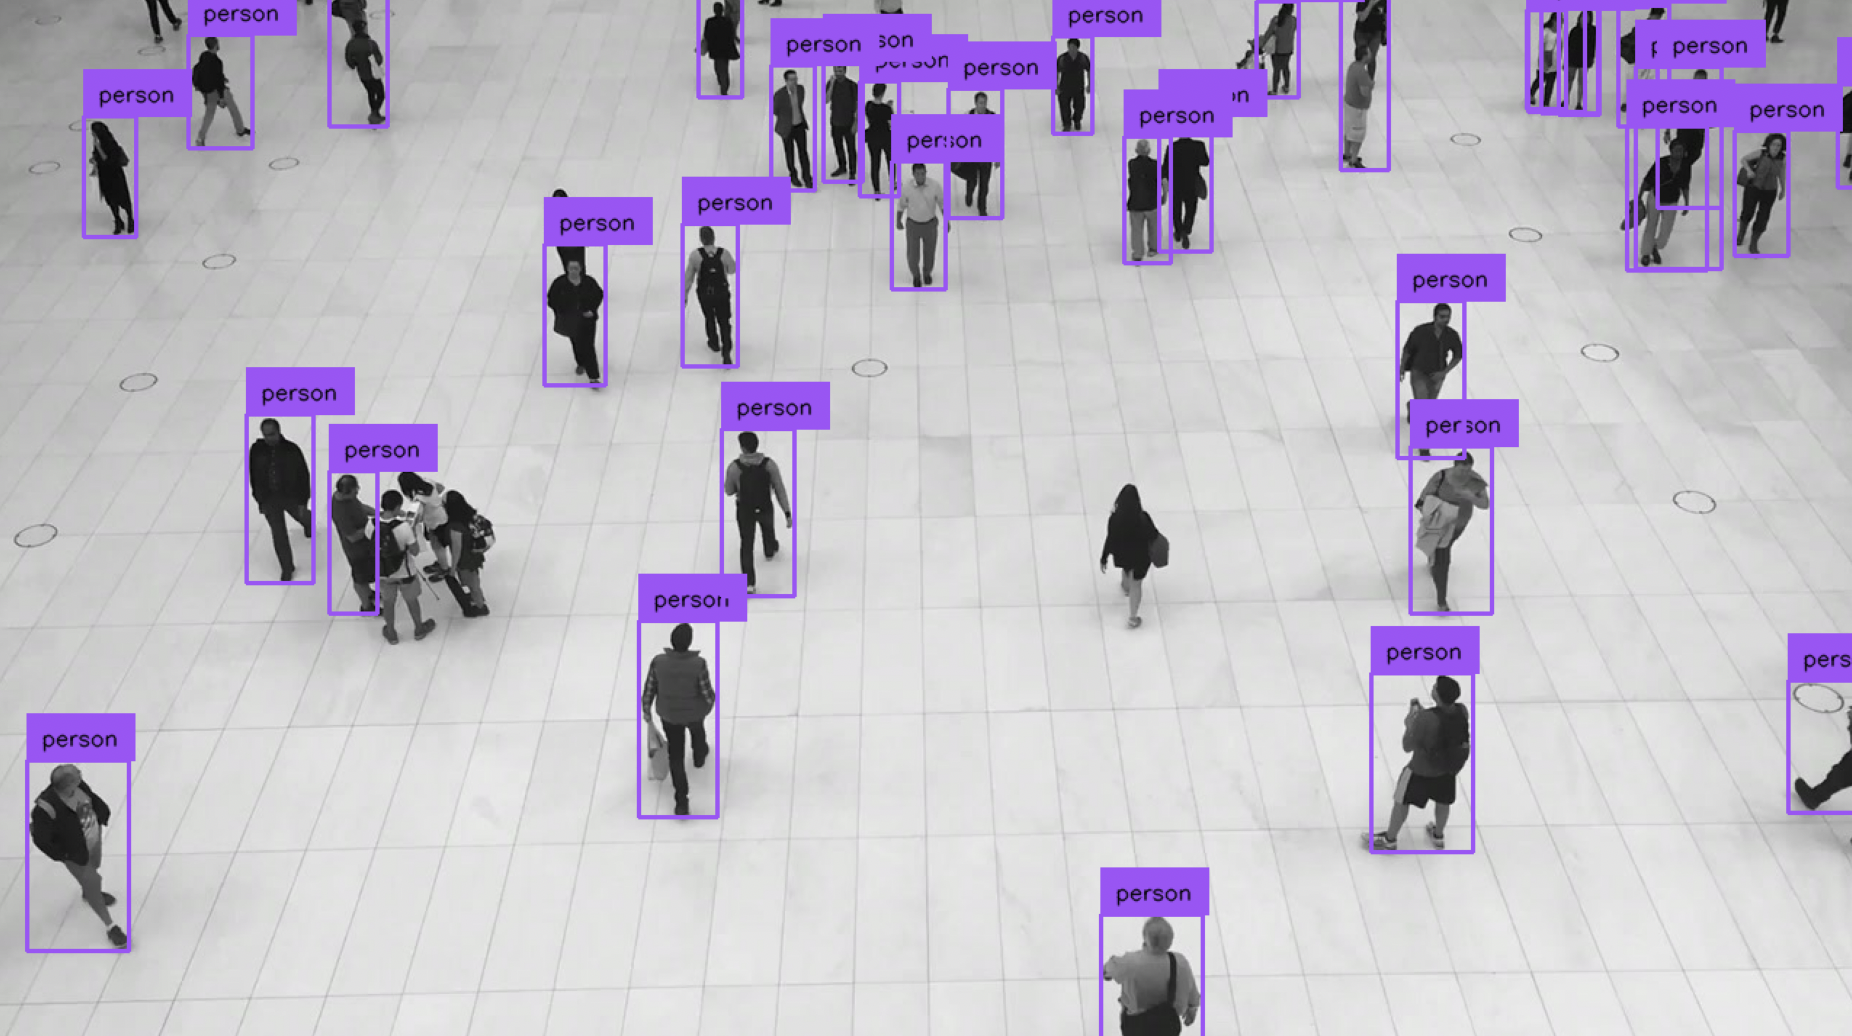
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](/latest/annotators/#supervision.annotators.core.LabelAnnotator) classes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
```{ .py hl_lines="10-16" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
@@ -134,12 +157,209 @@ Finally, we can annotate the image with the predictions. Since we are working wi
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
## Display Annotated Image
|
||||
```{ .py hl_lines="10-16" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
To display the annotated image in Jupyter Notebook or Google Colab, use the [`sv.plot_image`](utils/notebook/#supervision.utils.notebook.plot_image) function.
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
```python
|
||||
sv.plot_image(annotated_image)
|
||||
```
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="21-27" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<PATH TO IMAGE>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||

|
||||
|
||||
## Display Custom Labels
|
||||
|
||||
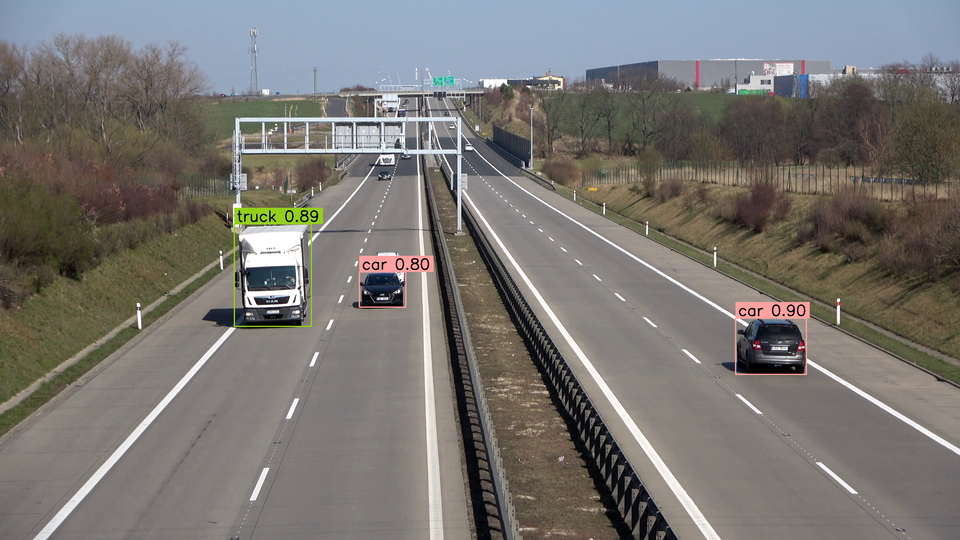
By default, [`sv.LabelAnnotator`](/latest/annotators/#supervision.annotators.core.LabelAnnotator)
|
||||
will label each detection with its `class_name` (if possible) or `class_id`. You can
|
||||
override this behavior by passing a list of custom `labels` to the `annotate` method.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="13-17 22" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="13-17 22" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="24-28 33" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<PATH TO IMAGE>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{model.config.id2label[class_id]} {confidence:.2f}"
|
||||
for class_id, confidence
|
||||
in zip(detections.class_id, detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Annotate Image with Segmentations
|
||||
|
||||
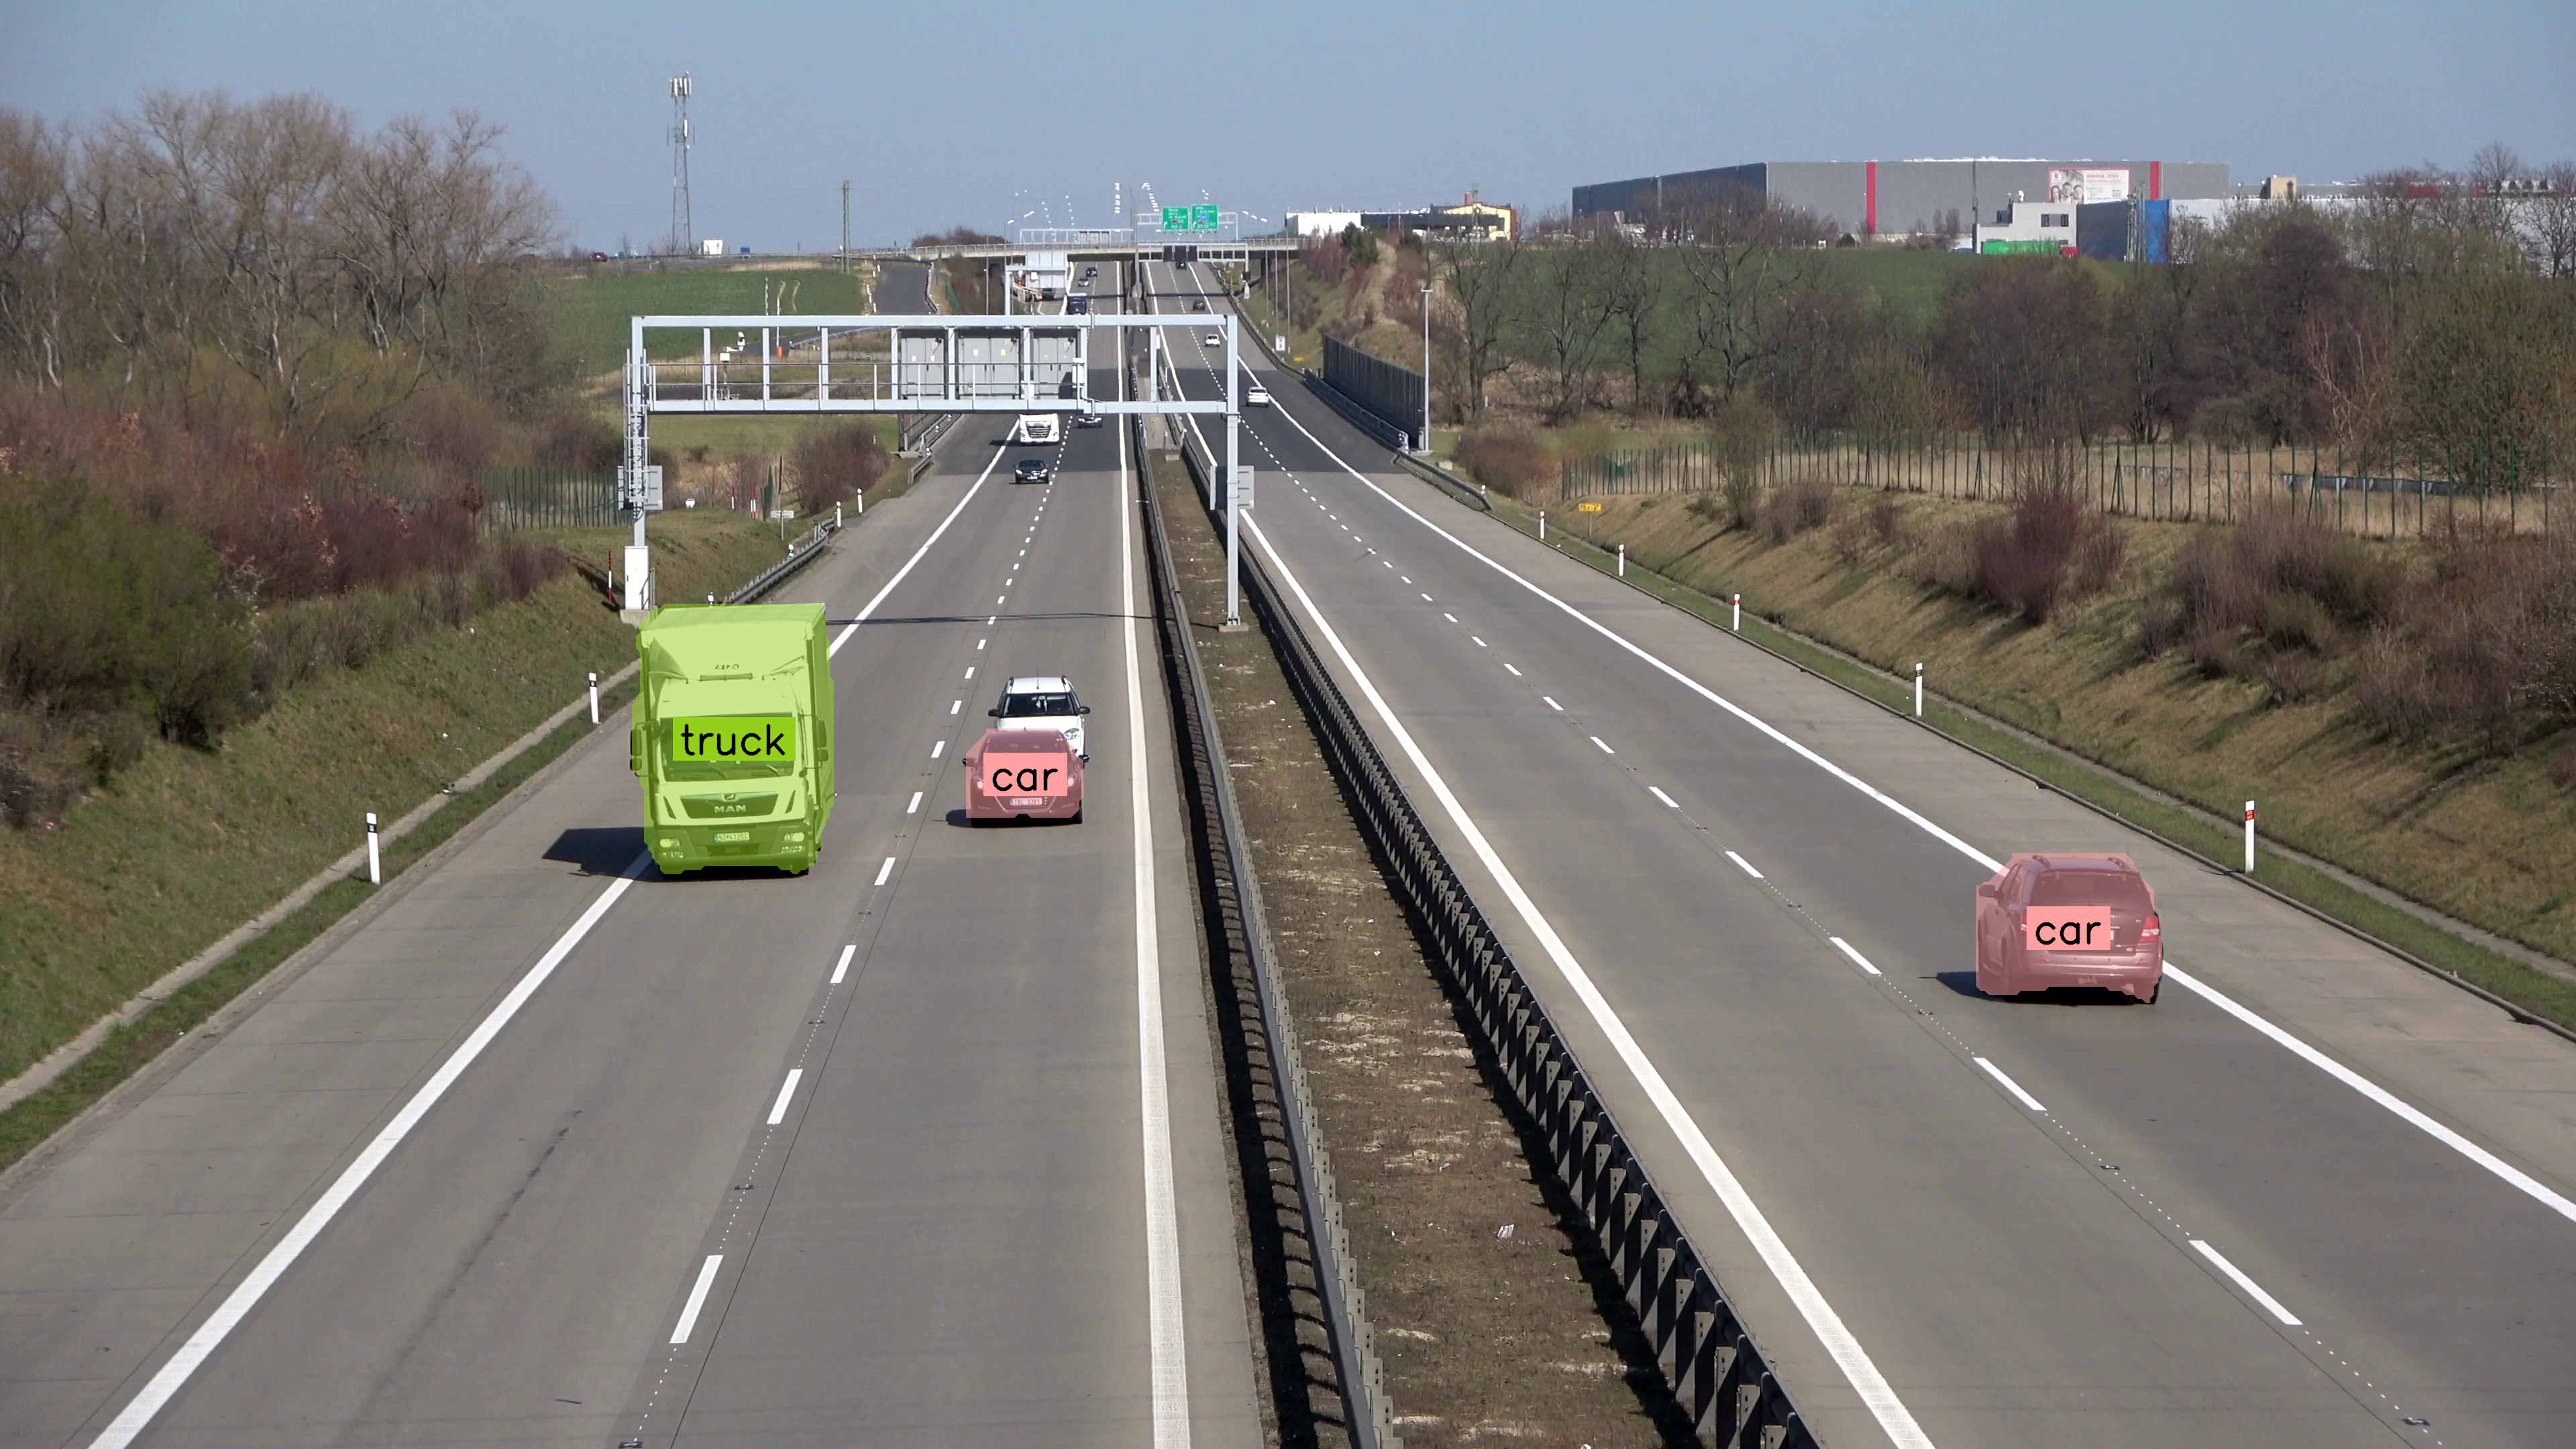
If you are running the segmentation model
|
||||
[`sv.MaskAnnotator`](/latest/annotators/#supervision.annotators.core.MaskAnnotator)
|
||||
is a drop-in replacement for
|
||||
[`sv.BoundingBoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoundingBoxAnnotator)
|
||||
that will allow you to draw masks instead of boxes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-seg-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n-seg.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,266 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detect Small Objects
|
||||
|
||||
This guide shows how to detect small objects
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages using
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer).
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Baseline Detection
|
||||
|
||||
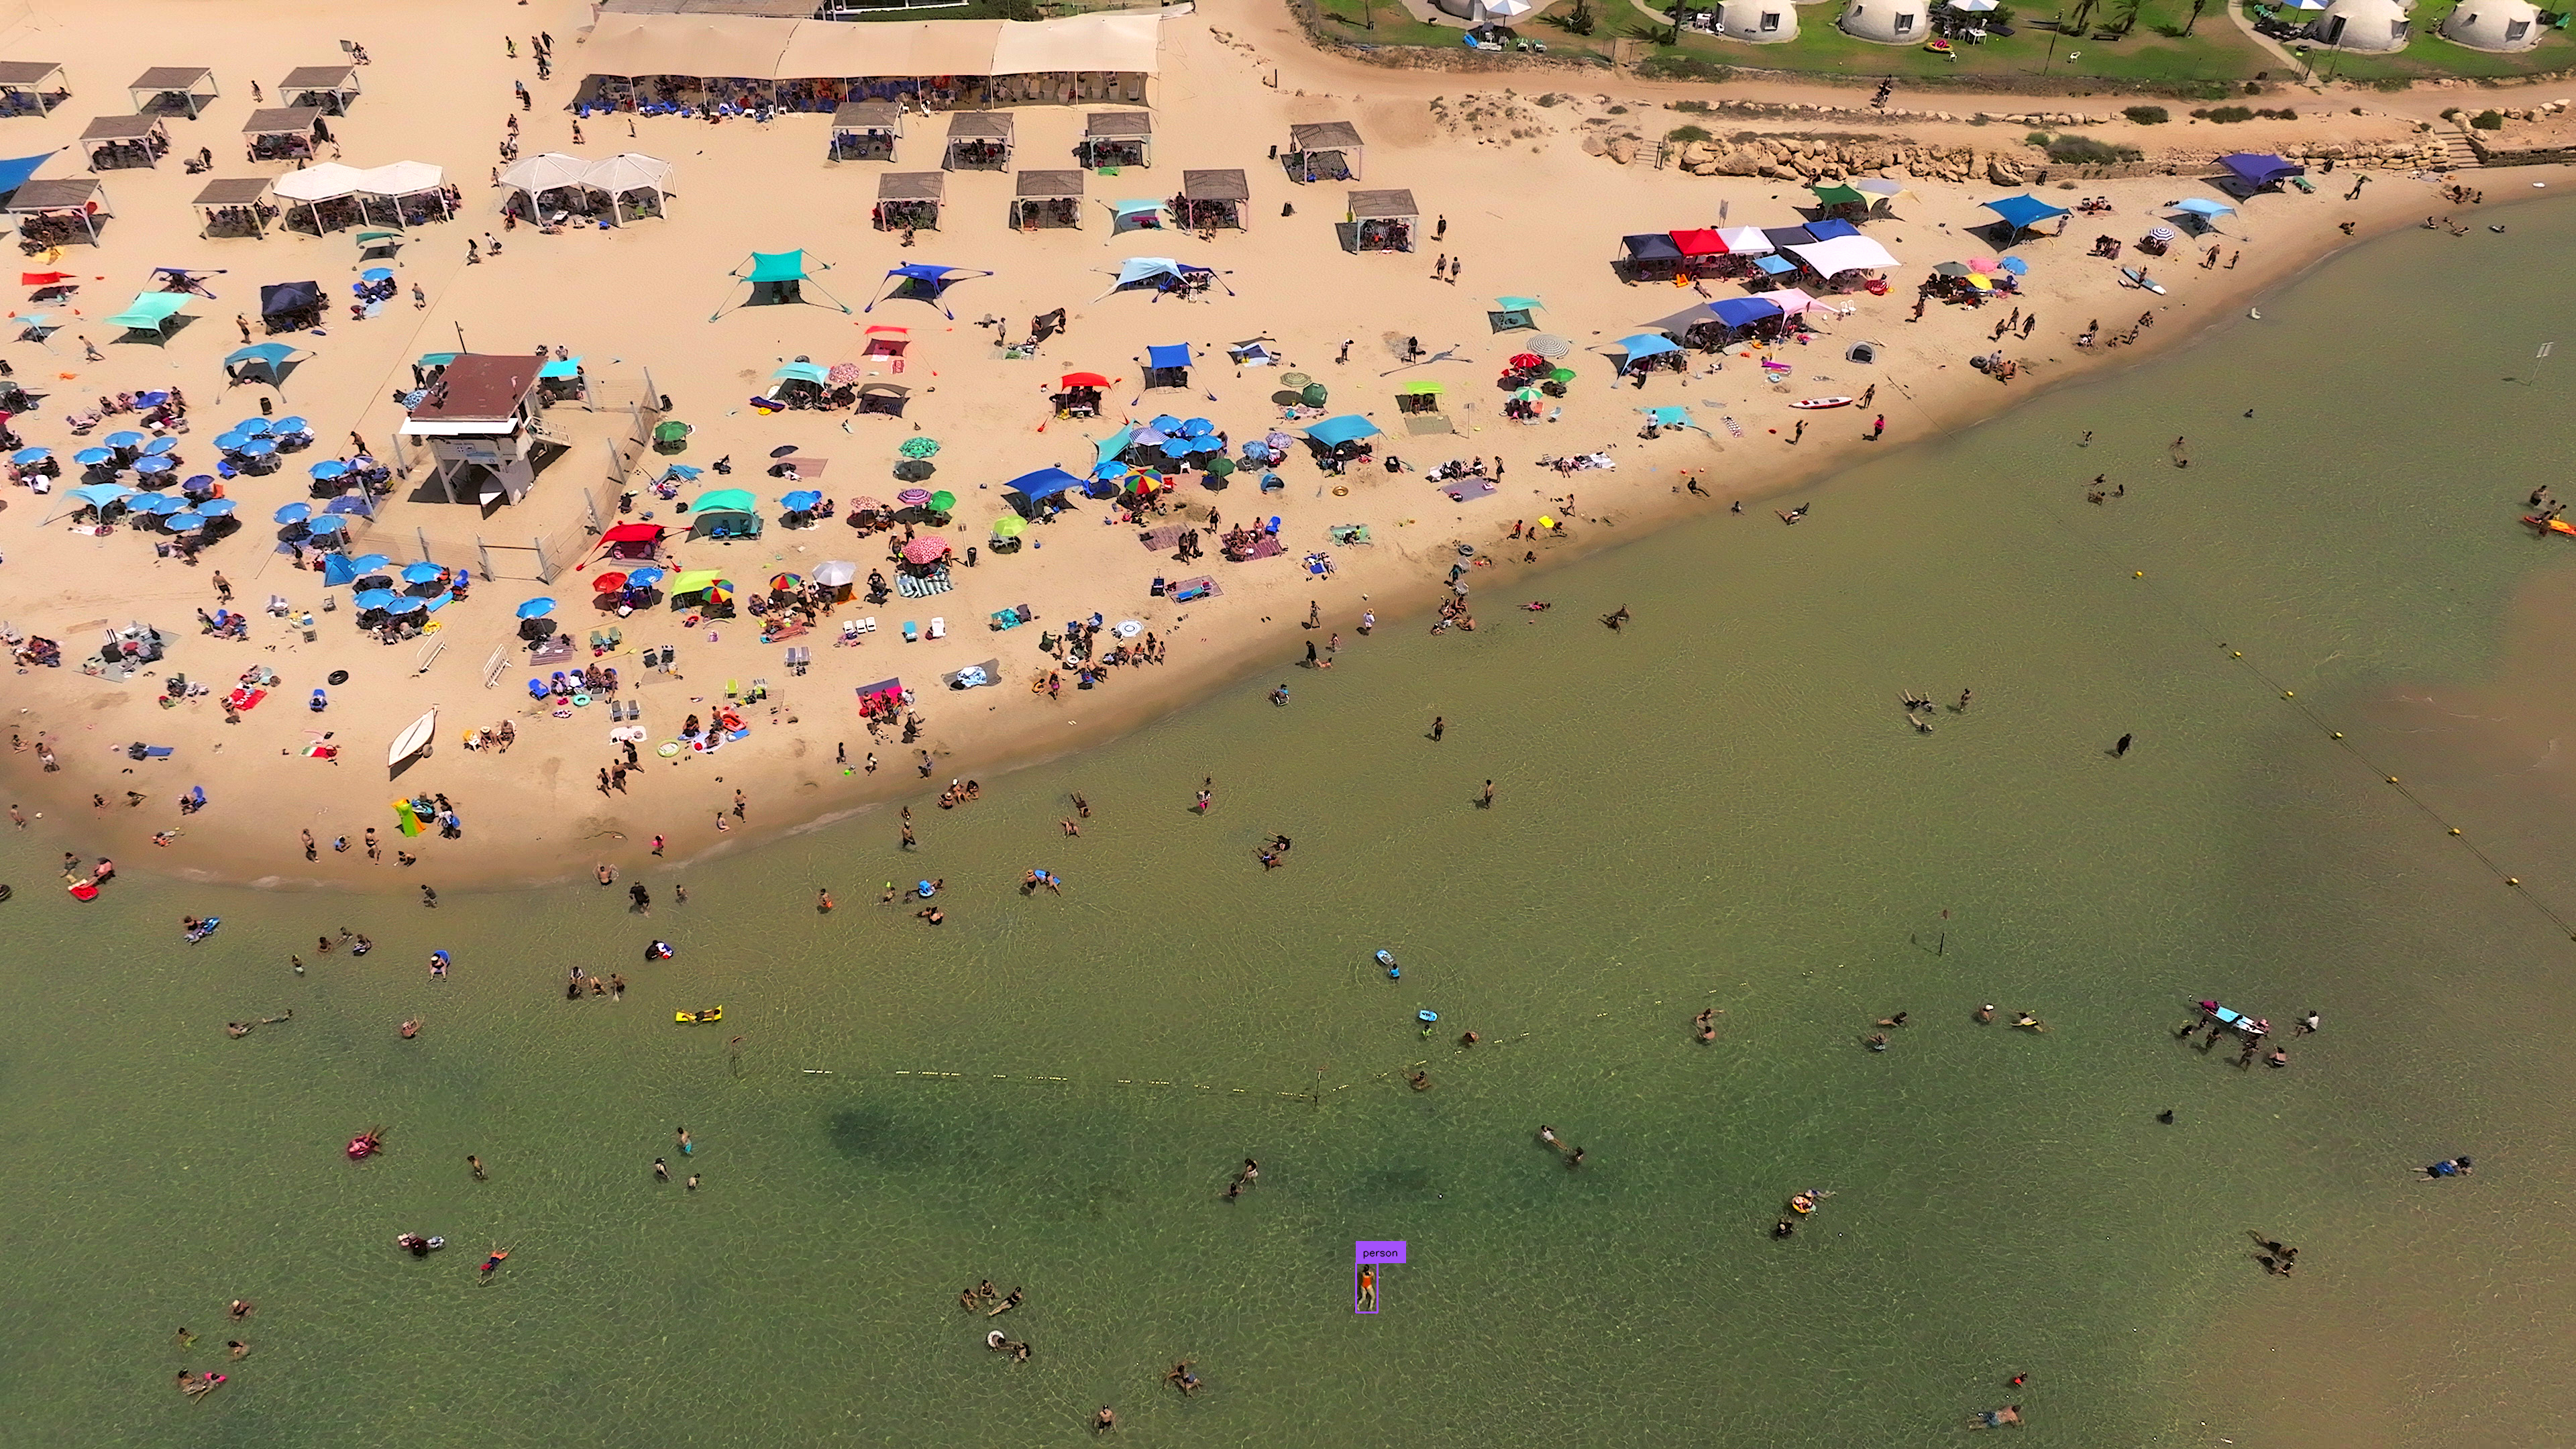
Small object detection in high-resolution images presents challenges due to the objects'
|
||||
size relative to the image resolution.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<PATH TO IMAGE>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.config.id2label[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Input Resolution
|
||||
|
||||
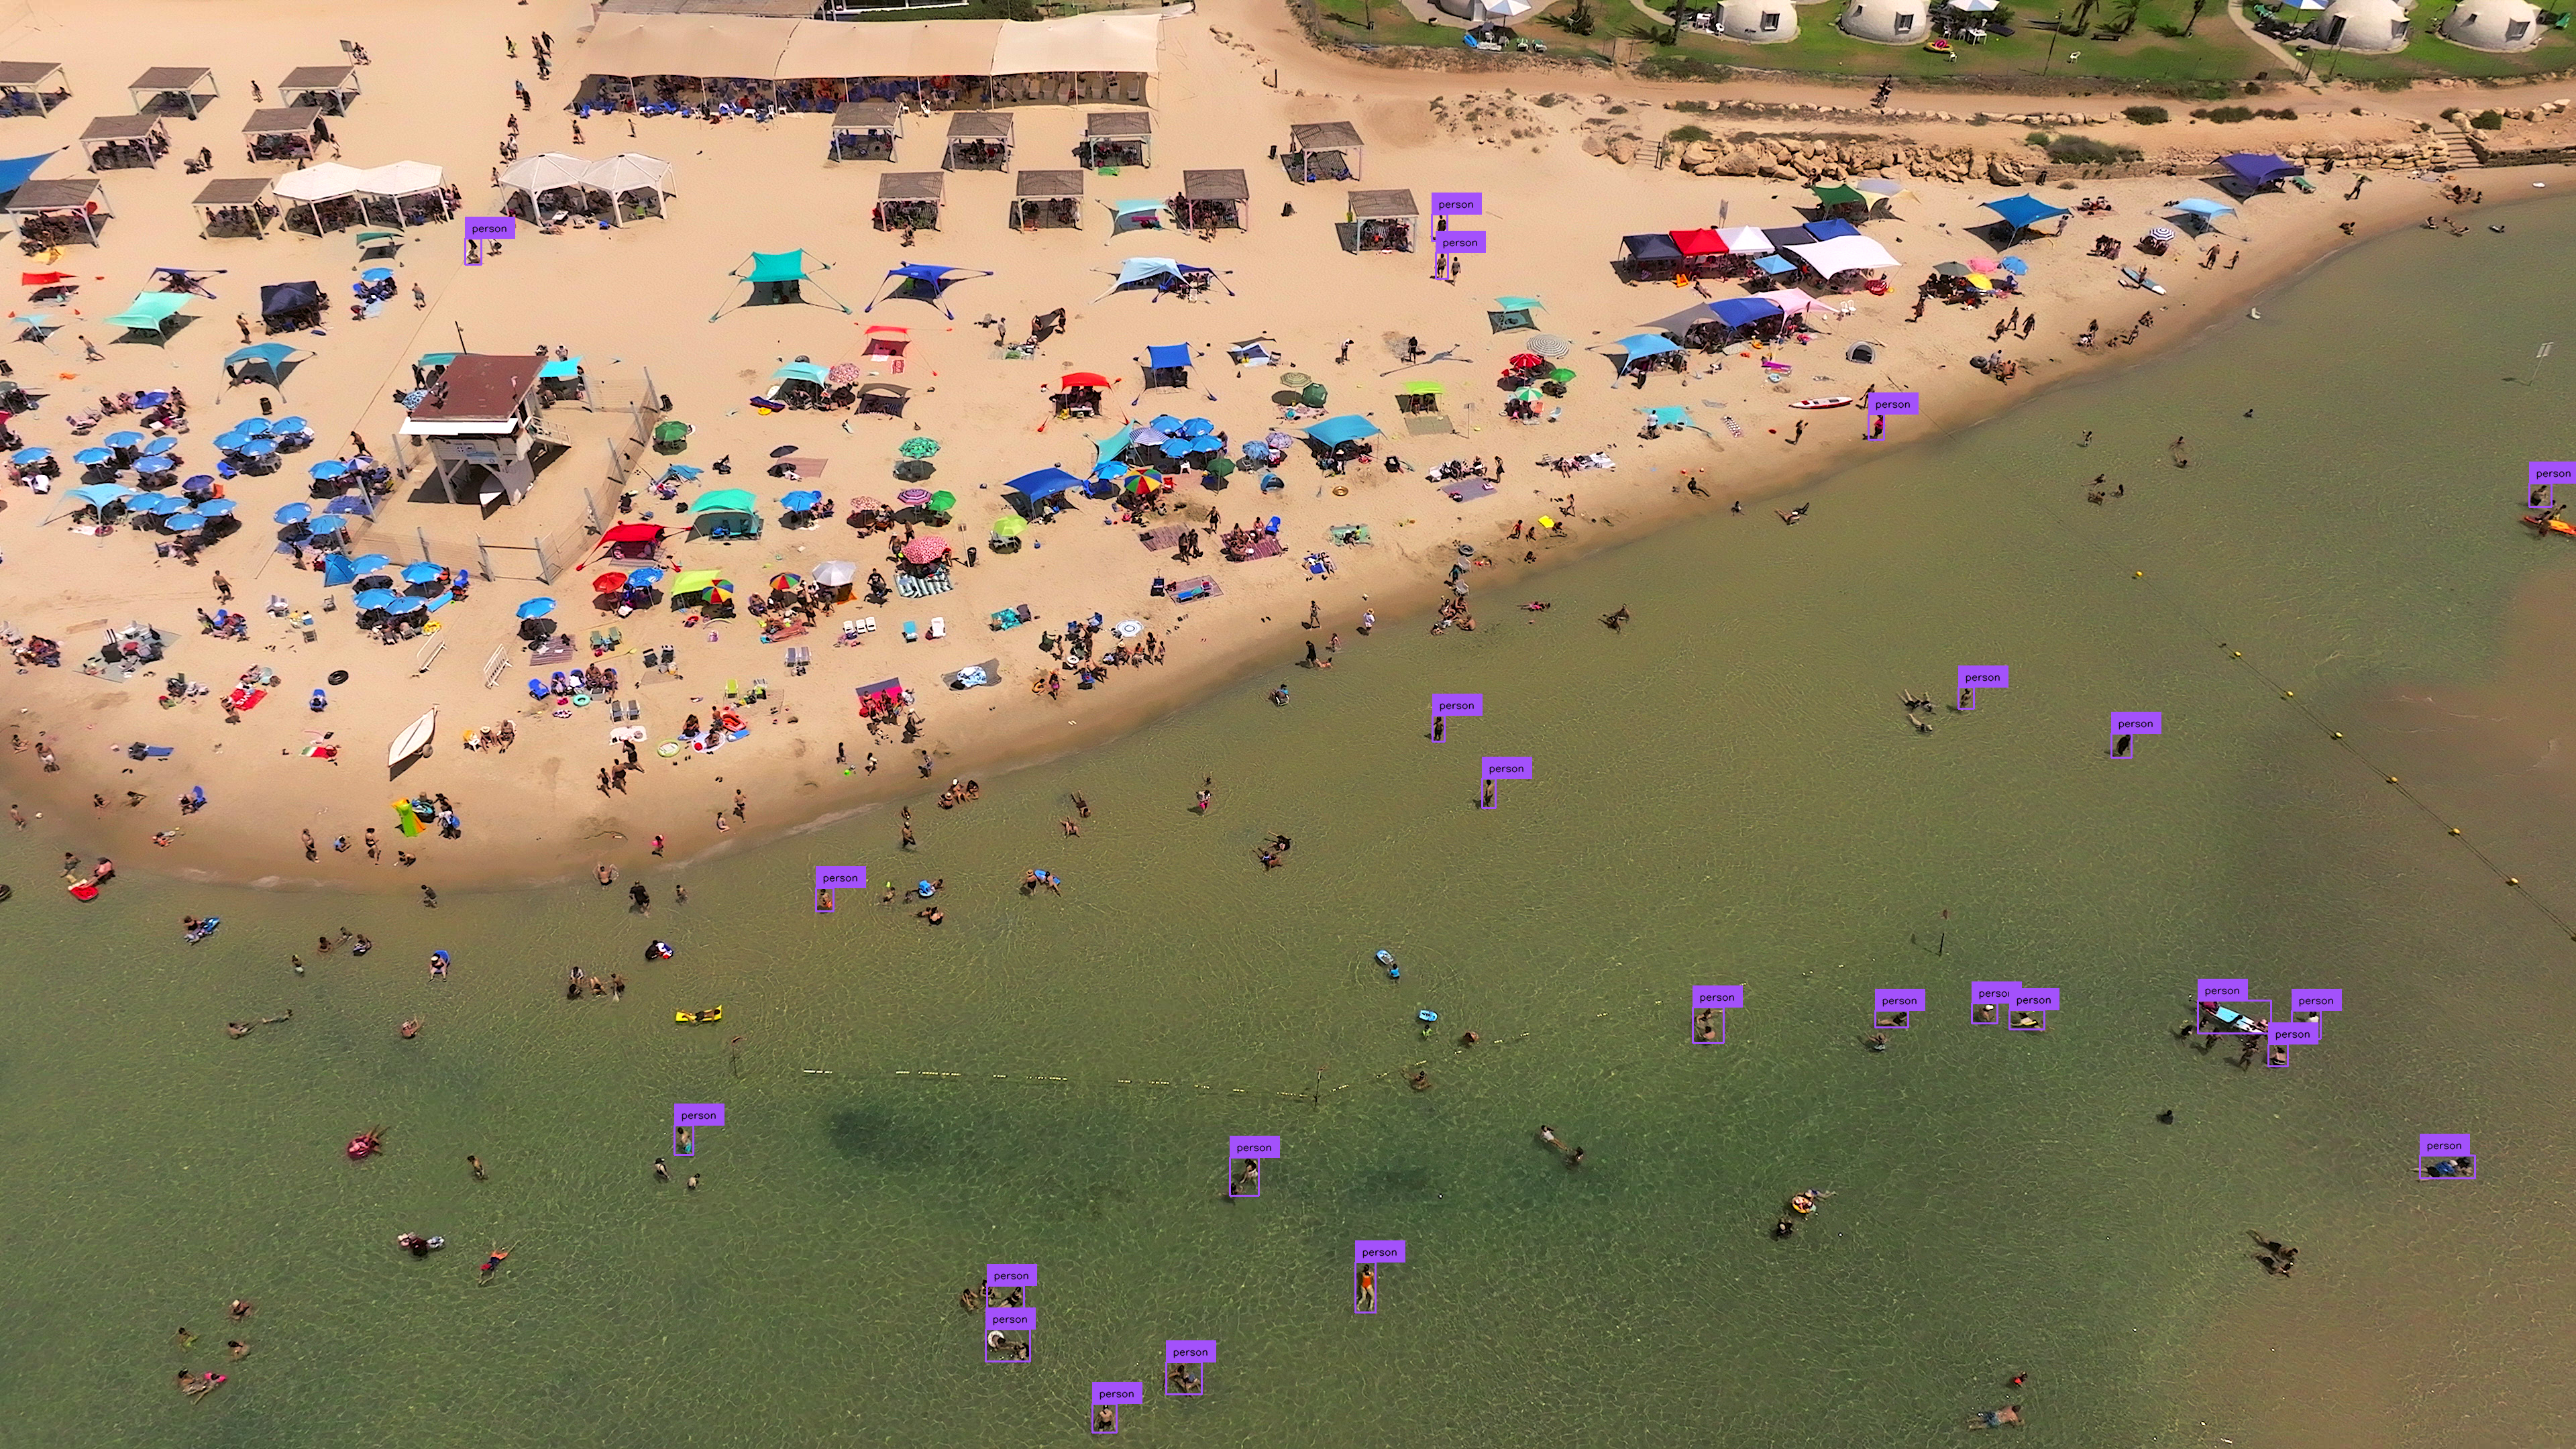
Modifying the input resolution of images before detection can enhance small object
|
||||
identification at the cost of processing speed and increased memory usage. This method
|
||||
is less effective for ultra-high-resolution images (4K and above).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="5" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-1280")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image, imgsz=1280)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Inference Slicer
|
||||
|
||||
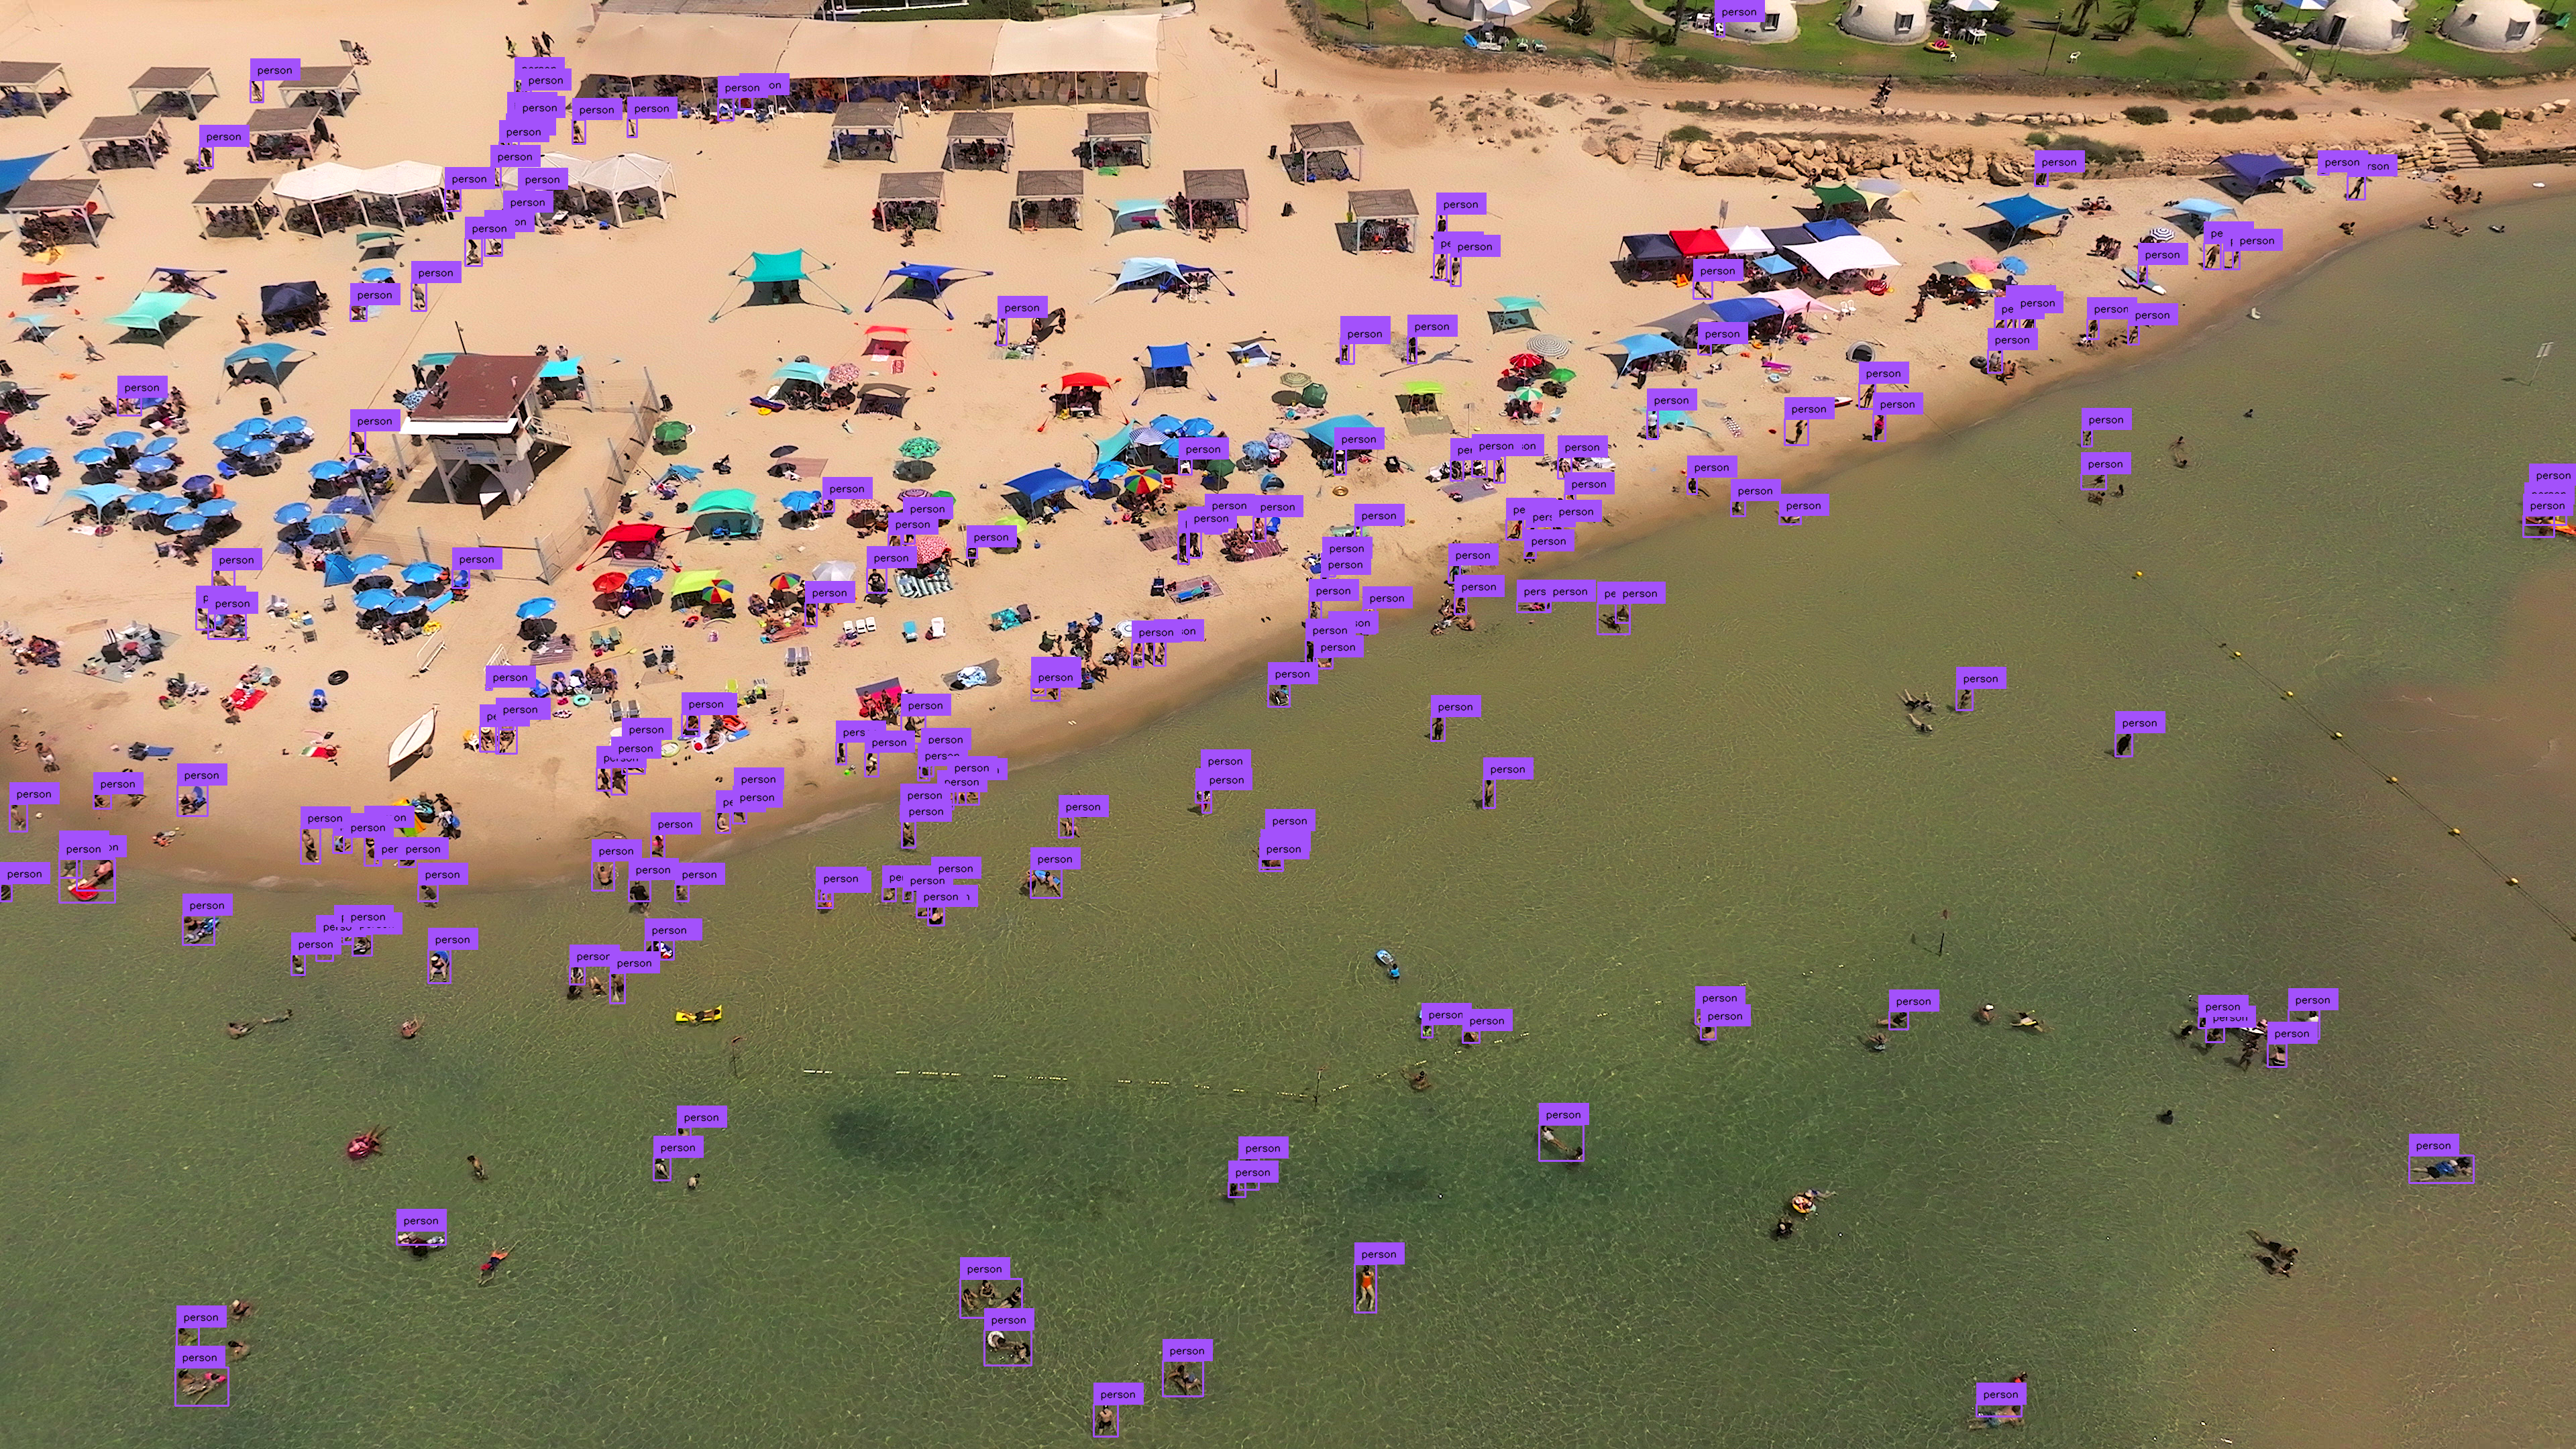
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer)
|
||||
processes high-resolution images by dividing them into smaller segments, detecting
|
||||
objects within each, and aggregating the results.
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example_2.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="9-14" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="9-14" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
result = model(image_slice)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="13-28" }
|
||||
import cv2
|
||||
import torch
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
image_slice = cv2.cvtColor(image_slice, cv2.COLOR_BGR2RGB)
|
||||
image_slice = Image.fromarray(image_slice)
|
||||
inputs = processor(images=image_slice, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
return sv.Detections.from_transformers(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.config.id2label[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
|
||||
@@ -109,6 +109,14 @@ You can install `supervision` with pip in a
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/track_objects.md)
|
||||
|
||||
- __Detect Small Objects__
|
||||
|
||||
---
|
||||
|
||||
Learn how to detect small objects in images
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/detect_small_objects.md)
|
||||
|
||||
- > __Count Objects Crossing Line__
|
||||
|
||||
---
|
||||
|
||||
@@ -8,6 +8,7 @@ interfaces with diverse applications.
|
||||
- [count people in zone](./count_people_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [traffic analysis](./traffic_analysis) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [speed estimation](./speed_estimation) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [time in zone](./time_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [heatmap and track](./heatmap_and_track/) by [@HinePo](https://github.com/HinePo)
|
||||
|
||||
## Contributing
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
gdown
|
||||
inference
|
||||
supervision
|
||||
supervision==0.19.0
|
||||
tqdm
|
||||
ultralytics
|
||||
|
||||
@@ -1,2 +1,2 @@
|
||||
supervision[assets]
|
||||
supervision[assets]==0.19.0
|
||||
ultralytics
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
supervision==0.18.0rc1
|
||||
supervision==0.19.0
|
||||
tqdm==4.66.1
|
||||
requests
|
||||
ultralytics==8.0.237
|
||||
|
||||
@@ -0,0 +1,9 @@
|
||||
data/
|
||||
venv*/
|
||||
*.pt
|
||||
*.pth
|
||||
*.mp4
|
||||
*.mov
|
||||
*.png
|
||||
*.jpg
|
||||
*.jpeg
|
||||
@@ -0,0 +1,262 @@
|
||||
# time in zone
|
||||
|
||||
## 👋 hello
|
||||
|
||||
Practical demonstration on leveraging computer vision for analyzing wait times and
|
||||
monitoring the duration that objects or individuals spend in predefined areas of video
|
||||
frames. This example project, perfect for retail analytics or traffic management
|
||||
applications.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d051cc8a-dd15-41d4-aa36-d38b86334c39
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/time_in_zone
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 🛠 scripts
|
||||
|
||||
### `download_from_youtube`
|
||||
|
||||
This script allows you to download a video from YouTube.
|
||||
|
||||
- `--url`: The full URL of the YouTube video you wish to download.
|
||||
- `--output_path` (optional): Specifies the directory where the video will be saved.
|
||||
- `--file_name` (optional): Sets the name of the saved video file.
|
||||
|
||||
```bash
|
||||
python scripts/download_from_youtube.py \
|
||||
--url "https://www.youtube.com/watch?v=-8zyEwAa50Q" \
|
||||
--output_path "data/checkout" \
|
||||
--file_name "video.mp4"
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/download_from_youtube.py \
|
||||
--url "https://www.youtube.com/watch?v=MNn9qKG2UFI" \
|
||||
--output_path "data/traffic" \
|
||||
--file_name "video.mp4"
|
||||
```
|
||||
|
||||
### `stream_from_file`
|
||||
|
||||
This script allows you to stream video files from a directory. It's an awesome way to
|
||||
mock a live video stream for local testing. Video will be streamed in a loop under
|
||||
`rtsp://localhost:8554/live0.stream` URL. This script requires docker to be installed.
|
||||
|
||||
- `--video_directory`: Directory containing video files to stream.
|
||||
- `--number_of_streams`: Number of video files to stream.
|
||||
|
||||
```bash
|
||||
python scripts/stream_from_file.py \
|
||||
--video_directory "data/checkout" \
|
||||
--number_of_streams 1
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/stream_from_file.py \
|
||||
--video_directory "data/traffic" \
|
||||
--number_of_streams 1
|
||||
```
|
||||
|
||||
### `draw_zones`
|
||||
|
||||
If you want to test zone time in zone analysis on your own video, you can use this
|
||||
script to design custom zones and save results as a JSON file. The script will open a
|
||||
window where you can draw polygons on the source image or video file. The polygons will
|
||||
be saved as a JSON file.
|
||||
|
||||
- `--source_path`: Path to the source image or video file for drawing polygons.
|
||||
- `--zone_configuration_path`: Path where the polygon annotations will be saved as a JSON file.
|
||||
|
||||
|
||||
- `enter` - finish drawing the current polygon.
|
||||
- `escape` - cancel drawing the current polygon.
|
||||
- `q` - quit the drawing window.
|
||||
- `s` - save zone configuration to a JSON file.
|
||||
|
||||
```bash
|
||||
python scripts/draw_zones.py \
|
||||
--source_path "data/checkout/video.mp4" \
|
||||
--zone_configuration_path "data/checkout/config.json"
|
||||
```
|
||||
|
||||
```bash
|
||||
python scripts/draw_zones.py \
|
||||
--source_path "data/traffic/video.mp4" \
|
||||
--zone_configuration_path "data/traffic/custom_config.json"
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/9d514c9e-2a61-418b-ae49-6ac1ad6ae5ac
|
||||
|
||||
## 🎬 video & stream processing
|
||||
|
||||
### `inference_file_example`
|
||||
|
||||
Script to run object detection on a video file using the Roboflow Inference model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--source_video_path`: Path to the source video file.
|
||||
- `--model_id`: Roboflow model ID.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--source_video_path "data/checkout/video.mp4" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d051cc8a-dd15-41d4-aa36-d38b86334c39
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--source_video_path "data/traffic/video.mp4" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/5ec896d7-4b39-4426-8979-11e71666878b
|
||||
|
||||
### `inference_stream_example`
|
||||
|
||||
Script to run object detection on a video stream using the Roboflow Inference model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--rtsp_url`: Complete RTSP URL for the video stream.
|
||||
- `--model_id`: Roboflow model ID.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--model_id "yolov8x-640" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>👉 show ultralytics examples</summary>
|
||||
|
||||
### `ultralytics_file_example`
|
||||
|
||||
Script to run object detection on a video file using the Ultralytics YOLOv8 model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--source_video_path`: Path to the source video file.
|
||||
- `--weights`: Path to the model weights file. Default is `'yolov8s.pt'`.
|
||||
- `--device`: Computation device (`'cpu'`, `'mps'` or `'cuda'`). Default is `'cpu'`.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--source_video_path "data/checkout/video.mp4" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--source_video_path "data/traffic/video.mp4" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
### `ultralytics_stream_example`
|
||||
|
||||
Script to run object detection on a video stream using the Ultralytics YOLOv8 model.
|
||||
|
||||
- `--zone_configuration_path`: Path to the zone configuration JSON file.
|
||||
- `--rtsp_url`: Complete RTSP URL for the video stream.
|
||||
- `--weights`: Path to the model weights file. Default is `'yolov8s.pt'`.
|
||||
- `--device`: Computation device (`'cpu'`, `'mps'` or `'cuda'`). Default is `'cpu'`.
|
||||
- `--classes`: List of class IDs to track. If empty, all classes are tracked.
|
||||
- `--confidence_threshold`: Confidence level for detections (`0` to `1`). Default is `0.3`.
|
||||
- `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`.
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/checkout/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 0 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
```bash
|
||||
python inference_file_example.py \
|
||||
--zone_configuration_path "data/traffic/config.json" \
|
||||
--rtsp_url "rtsp://localhost:8554/live0.stream" \
|
||||
--weights "yolov8x.pt" \
|
||||
--device "cpu" \
|
||||
--classes 2 5 6 7 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.7
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
@@ -0,0 +1,132 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import get_model
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import FPSBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
source_video_path: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = get_model(model_id=model_id)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(source_video_path)
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [FPSBasedTimer(video_info.fps) for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
results = model.infer(frame, confidence=confidence, iou_threshold=iou)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using video file."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source video file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
source_video_path=args.source_video_path,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,142 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import get_model
|
||||
from utils.general import find_in_list, get_stream_frames_generator, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = get_model(model_id=model_id)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url)
|
||||
fps_monitor = sv.FPSMonitor()
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [ClockBasedTimer() for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
fps_monitor.tick()
|
||||
fps = fps_monitor.fps
|
||||
|
||||
results = model.infer(frame, confidence=confidence, iou_threshold=iou)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,158 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import InferencePipeline
|
||||
from inference.core.interfaces.camera.entities import VideoFrame
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
class CustomSink:
|
||||
def __init__(self, zone_configuration_path: str, classes: List[int]):
|
||||
self.classes = classes
|
||||
self.tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
self.polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
self.timers = [ClockBasedTimer() for _ in self.polygons]
|
||||
self.zones = None
|
||||
|
||||
def on_prediction(self, result: dict, frame: VideoFrame) -> None:
|
||||
if self.zones is None:
|
||||
resolution_wh = frame.image.shape[1], frame.image.shape[0]
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
self.fps_monitor.tick()
|
||||
fps = self.fps_monitor.fps
|
||||
|
||||
detections = sv.Detections.from_inference(result)
|
||||
detections = detections[find_in_list(detections.class_id, self.classes)]
|
||||
detections = self.tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.image.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(self.zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = self.timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
cv2.waitKey(1)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
sink = CustomSink(zone_configuration_path=zone_configuration_path, classes=classes)
|
||||
|
||||
pipeline = InferencePipeline.init(
|
||||
model_id=model_id,
|
||||
video_reference=rtsp_url,
|
||||
on_prediction=sink.on_prediction,
|
||||
confidence=confidence,
|
||||
iou_threshold=iou,
|
||||
)
|
||||
|
||||
pipeline.start()
|
||||
|
||||
try:
|
||||
pipeline.join()
|
||||
except KeyboardInterrupt:
|
||||
pipeline.terminate()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id", type=str, default="yolov8s-640", help="Roboflow model ID."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
model_id=args.model_id,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,5 @@
|
||||
opencv-python
|
||||
supervision
|
||||
ultralytics
|
||||
inference
|
||||
pytube
|
||||
@@ -0,0 +1,46 @@
|
||||
import argparse
|
||||
import os
|
||||
from typing import Optional
|
||||
|
||||
from pytube import YouTube
|
||||
|
||||
|
||||
def main(url: str, output_path: Optional[str], file_name: Optional[str]) -> None:
|
||||
yt = YouTube(url)
|
||||
stream = yt.streams.get_highest_resolution()
|
||||
|
||||
if not os.path.exists(output_path):
|
||||
os.makedirs(output_path)
|
||||
|
||||
stream.download(output_path=output_path, filename=file_name)
|
||||
final_name = file_name if file_name else yt.title
|
||||
final_path = output_path if output_path else "current directory"
|
||||
print(f"Download completed! Video saved as '{final_name}' in '{final_path}'.")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Download a specific YouTube video by providing its URL."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="The full URL of the YouTube video you wish to download.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--output_path",
|
||||
type=str,
|
||||
default="data/source",
|
||||
required=False,
|
||||
help="Optional. Specifies the directory where the video will be saved.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--file_name",
|
||||
type=str,
|
||||
default="video.mp4",
|
||||
required=False,
|
||||
help="Optional. Sets the name of the saved video file.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
main(url=args.url, output_path=args.output_path, file_name=args.file_name)
|
||||
@@ -0,0 +1,176 @@
|
||||
import argparse
|
||||
import json
|
||||
import os
|
||||
from typing import Any, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
import supervision as sv
|
||||
|
||||
KEY_ENTER = 13
|
||||
KEY_NEWLINE = 10
|
||||
KEY_ESCAPE = 27
|
||||
KEY_QUIT = ord("q")
|
||||
KEY_SAVE = ord("s")
|
||||
|
||||
THICKNESS = 2
|
||||
COLORS = sv.ColorPalette.DEFAULT
|
||||
WINDOW_NAME = "Draw Zones"
|
||||
POLYGONS = [[]]
|
||||
|
||||
current_mouse_position: Optional[Tuple[int, int]] = None
|
||||
|
||||
|
||||
def resolve_source(source_path: str) -> Optional[np.ndarray]:
|
||||
if not os.path.exists(source_path):
|
||||
return None
|
||||
|
||||
image = cv2.imread(source_path)
|
||||
if image is not None:
|
||||
return image
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=source_path)
|
||||
frame = next(frame_generator)
|
||||
return frame
|
||||
|
||||
|
||||
def mouse_event(event: int, x: int, y: int, flags: int, param: Any) -> None:
|
||||
global current_mouse_position
|
||||
if event == cv2.EVENT_MOUSEMOVE:
|
||||
current_mouse_position = (x, y)
|
||||
elif event == cv2.EVENT_LBUTTONDOWN:
|
||||
POLYGONS[-1].append((x, y))
|
||||
|
||||
|
||||
def redraw(image: np.ndarray, original_image: np.ndarray) -> None:
|
||||
global POLYGONS, current_mouse_position
|
||||
image[:] = original_image.copy()
|
||||
for idx, polygon in enumerate(POLYGONS):
|
||||
color = (
|
||||
COLORS.by_idx(idx).as_bgr()
|
||||
if idx < len(POLYGONS) - 1
|
||||
else sv.Color.WHITE.as_bgr()
|
||||
)
|
||||
|
||||
if len(polygon) > 1:
|
||||
for i in range(1, len(polygon)):
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[i - 1],
|
||||
pt2=polygon[i],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
if idx < len(POLYGONS) - 1:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=polygon[0],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
if idx == len(POLYGONS) - 1 and current_mouse_position is not None and polygon:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=current_mouse_position,
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
|
||||
|
||||
def close_and_finalize_polygon(image: np.ndarray, original_image: np.ndarray) -> None:
|
||||
if len(POLYGONS[-1]) > 2:
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=POLYGONS[-1][-1],
|
||||
pt2=POLYGONS[-1][0],
|
||||
color=COLORS.by_idx(0).as_bgr(),
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
POLYGONS.append([])
|
||||
image[:] = original_image.copy()
|
||||
redraw_polygons(image)
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
|
||||
|
||||
def redraw_polygons(image: np.ndarray) -> None:
|
||||
for idx, polygon in enumerate(POLYGONS[:-1]):
|
||||
if len(polygon) > 1:
|
||||
color = COLORS.by_idx(idx).as_bgr()
|
||||
for i in range(len(polygon) - 1):
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[i],
|
||||
pt2=polygon[i + 1],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
cv2.line(
|
||||
img=image,
|
||||
pt1=polygon[-1],
|
||||
pt2=polygon[0],
|
||||
color=color,
|
||||
thickness=THICKNESS,
|
||||
)
|
||||
|
||||
|
||||
def save_polygons_to_json(polygons, target_path):
|
||||
data_to_save = polygons if polygons[-1] else polygons[:-1]
|
||||
with open(target_path, "w") as f:
|
||||
json.dump(data_to_save, f)
|
||||
|
||||
|
||||
def main(source_path: str, zone_configuration_path: str) -> None:
|
||||
global current_mouse_position
|
||||
original_image = resolve_source(source_path=source_path)
|
||||
if original_image is None:
|
||||
print("Failed to load source image.")
|
||||
return
|
||||
|
||||
image = original_image.copy()
|
||||
cv2.imshow(WINDOW_NAME, image)
|
||||
cv2.setMouseCallback(WINDOW_NAME, mouse_event, image)
|
||||
|
||||
while True:
|
||||
key = cv2.waitKey(1) & 0xFF
|
||||
if key == KEY_ENTER or key == KEY_NEWLINE:
|
||||
close_and_finalize_polygon(image, original_image)
|
||||
elif key == KEY_ESCAPE:
|
||||
POLYGONS[-1] = []
|
||||
current_mouse_position = None
|
||||
elif key == KEY_SAVE:
|
||||
save_polygons_to_json(POLYGONS, zone_configuration_path)
|
||||
print(f"Polygons saved to {zone_configuration_path}")
|
||||
break
|
||||
redraw(image, original_image)
|
||||
if key == KEY_QUIT:
|
||||
break
|
||||
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Interactively draw polygons on images or video frames and save "
|
||||
"the annotations."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source image or video file for drawing polygons.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path where the polygon annotations will be saved as a JSON file.",
|
||||
)
|
||||
arguments = parser.parse_args()
|
||||
main(
|
||||
source_path=arguments.source_path,
|
||||
zone_configuration_path=arguments.zone_configuration_path,
|
||||
)
|
||||
@@ -0,0 +1,104 @@
|
||||
import argparse
|
||||
import os
|
||||
import subprocess
|
||||
import tempfile
|
||||
from glob import glob
|
||||
from threading import Thread
|
||||
|
||||
import yaml
|
||||
|
||||
SERVER_CONFIG = {"protocols": ["tcp"], "paths": {"all": {"source": "publisher"}}}
|
||||
BASE_STREAM_URL = "rtsp://localhost:8554/live"
|
||||
|
||||
|
||||
def main(video_directory: str, number_of_streams: int) -> None:
|
||||
video_files = find_video_files_in_directory(video_directory, number_of_streams)
|
||||
try:
|
||||
with tempfile.TemporaryDirectory() as temporary_directory:
|
||||
config_file_path = create_server_config_file(temporary_directory)
|
||||
run_rtsp_server(config_path=config_file_path)
|
||||
stream_videos(video_files)
|
||||
finally:
|
||||
stop_rtsp_server()
|
||||
|
||||
|
||||
def find_video_files_in_directory(directory: str, limit: int) -> list:
|
||||
video_formats = ["*.mp4", "*.webm"]
|
||||
video_paths = []
|
||||
for video_format in video_formats:
|
||||
video_paths.extend(glob(os.path.join(directory, video_format)))
|
||||
return video_paths[:limit]
|
||||
|
||||
|
||||
def create_server_config_file(directory: str) -> str:
|
||||
config_path = os.path.join(directory, "rtsp-simple-server.yml")
|
||||
with open(config_path, "w") as config_file:
|
||||
yaml.dump(SERVER_CONFIG, config_file)
|
||||
return config_path
|
||||
|
||||
|
||||
def run_rtsp_server(config_path: str) -> None:
|
||||
command = (
|
||||
"docker run --rm --name rtsp_server -d -v "
|
||||
f"{config_path}:/rtsp-simple-server.yml -p 8554:8554 "
|
||||
"aler9/rtsp-simple-server:v1.3.0"
|
||||
)
|
||||
if run_command(command.split()) != 0:
|
||||
raise RuntimeError("Could not start the RTSP server!")
|
||||
|
||||
|
||||
def stop_rtsp_server() -> None:
|
||||
run_command("docker kill rtsp_server".split())
|
||||
|
||||
|
||||
def stream_videos(video_files: list) -> None:
|
||||
threads = []
|
||||
for index, video_file in enumerate(video_files):
|
||||
stream_url = f"{BASE_STREAM_URL}{index}.stream"
|
||||
print(f"Streaming {video_file} under {stream_url}")
|
||||
thread = stream_video_to_url(video_file, stream_url)
|
||||
threads.append(thread)
|
||||
for thread in threads:
|
||||
thread.join()
|
||||
|
||||
|
||||
def stream_video_to_url(video_path: str, stream_url: str) -> Thread:
|
||||
command = (
|
||||
f"ffmpeg -re -stream_loop -1 -i {video_path} "
|
||||
f"-f rtsp -rtsp_transport tcp {stream_url}"
|
||||
)
|
||||
return run_command_in_thread(command.split())
|
||||
|
||||
|
||||
def run_command_in_thread(command: list) -> Thread:
|
||||
thread = Thread(target=run_command, args=(command,))
|
||||
thread.start()
|
||||
return thread
|
||||
|
||||
|
||||
def run_command(command: list) -> int:
|
||||
process = subprocess.run(command)
|
||||
return process.returncode
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Script to stream videos using RTSP protocol."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--video_directory",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Directory containing video files to stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--number_of_streams",
|
||||
type=int,
|
||||
default=6,
|
||||
help="Number of video files to stream.",
|
||||
)
|
||||
arguments = parser.parse_args()
|
||||
main(
|
||||
video_directory=arguments.video_directory,
|
||||
number_of_streams=arguments.number_of_streams,
|
||||
)
|
||||
@@ -0,0 +1,144 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import FPSBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
source_video_path: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(source_video_path)
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [FPSBasedTimer(video_info.fps) for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
results = model(frame, verbose=False, device=device, conf=confidence)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = detections.with_nms(threshold=iou)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using video file."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the source video file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
source_video_path=args.source_video_path,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,154 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, get_stream_frames_generator, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url)
|
||||
fps_monitor = sv.FPSMonitor()
|
||||
|
||||
frame = next(frames_generator)
|
||||
resolution_wh = frame.shape[1], frame.shape[0]
|
||||
|
||||
polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
timers = [ClockBasedTimer() for _ in zones]
|
||||
|
||||
for frame in frames_generator:
|
||||
fps_monitor.tick()
|
||||
fps = fps_monitor.fps
|
||||
|
||||
results = model(frame, verbose=False, device=device, conf=confidence)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = detections[find_in_list(detections.class_id, classes)]
|
||||
detections = detections.with_nms(threshold=iou)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,173 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference import InferencePipeline
|
||||
from inference.core.interfaces.camera.entities import VideoFrame
|
||||
from ultralytics import YOLO
|
||||
from utils.general import find_in_list, load_zones_config
|
||||
from utils.timers import ClockBasedTimer
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.from_hex(["#E6194B", "#3CB44B", "#FFE119", "#3C76D1"])
|
||||
COLOR_ANNOTATOR = sv.ColorAnnotator(color=COLORS)
|
||||
LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
color=COLORS, text_color=sv.Color.from_hex("#000000")
|
||||
)
|
||||
|
||||
|
||||
class CustomSink:
|
||||
def __init__(self, zone_configuration_path: str, classes: List[int]):
|
||||
self.classes = classes
|
||||
self.tracker = sv.ByteTrack(minimum_matching_threshold=0.8)
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
self.polygons = load_zones_config(file_path=zone_configuration_path)
|
||||
self.timers = [ClockBasedTimer() for _ in self.polygons]
|
||||
self.zones = None
|
||||
|
||||
def on_prediction(self, detections: sv.Detections, frame: VideoFrame) -> None:
|
||||
if self.zones is None:
|
||||
resolution_wh = frame.image.shape[1], frame.image.shape[0]
|
||||
self.zones = [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=resolution_wh,
|
||||
triggering_anchors=(sv.Position.CENTER,),
|
||||
)
|
||||
for polygon in self.polygons
|
||||
]
|
||||
|
||||
self.fps_monitor.tick()
|
||||
fps = self.fps_monitor.fps
|
||||
|
||||
detections = detections[find_in_list(detections.class_id, self.classes)]
|
||||
detections = self.tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = frame.image.copy()
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=f"{fps:.1f}",
|
||||
text_anchor=sv.Point(40, 30),
|
||||
background_color=sv.Color.from_hex("#A351FB"),
|
||||
text_color=sv.Color.from_hex("#000000"),
|
||||
)
|
||||
|
||||
for idx, zone in enumerate(self.zones):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
scene=annotated_frame, polygon=zone.polygon, color=COLORS.by_idx(idx)
|
||||
)
|
||||
|
||||
detections_in_zone = detections[zone.trigger(detections)]
|
||||
time_in_zone = self.timers[idx].tick(detections_in_zone)
|
||||
custom_color_lookup = np.full(detections_in_zone.class_id.shape, idx)
|
||||
|
||||
annotated_frame = COLOR_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
labels = [
|
||||
f"#{tracker_id} {int(time // 60):02d}:{int(time % 60):02d}"
|
||||
for tracker_id, time in zip(detections_in_zone.tracker_id, time_in_zone)
|
||||
]
|
||||
annotated_frame = LABEL_ANNOTATOR.annotate(
|
||||
scene=annotated_frame,
|
||||
detections=detections_in_zone,
|
||||
labels=labels,
|
||||
custom_color_lookup=custom_color_lookup,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
cv2.waitKey(1)
|
||||
|
||||
|
||||
def main(
|
||||
rtsp_url: str,
|
||||
zone_configuration_path: str,
|
||||
weights: str,
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
|
||||
def inference_callback(frame: VideoFrame) -> sv.Detections:
|
||||
results = model(frame.image, verbose=False, conf=confidence, device=device)[0]
|
||||
return sv.Detections.from_ultralytics(results).with_nms(threshold=iou)
|
||||
|
||||
sink = CustomSink(zone_configuration_path=zone_configuration_path, classes=classes)
|
||||
|
||||
pipeline = InferencePipeline.init_with_custom_logic(
|
||||
video_reference=rtsp_url,
|
||||
on_video_frame=inference_callback,
|
||||
on_prediction=sink.on_prediction,
|
||||
)
|
||||
|
||||
pipeline.start()
|
||||
|
||||
try:
|
||||
pipeline.join()
|
||||
except KeyboardInterrupt:
|
||||
pipeline.terminate()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Calculating detections dwell time in zones, using RTSP stream."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--rtsp_url",
|
||||
type=str,
|
||||
required=True,
|
||||
help="Complete RTSP URL for the video stream.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--weights",
|
||||
type=str,
|
||||
default="yolov8s.pt",
|
||||
help="Path to the model weights file. Default is 'yolov8s.pt'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="Computation device ('cpu', 'mps' or 'cuda'). Default is 'cpu'.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Confidence level for detections (0 to 1). Default is 0.3.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
type=float,
|
||||
help="IOU threshold for non-max suppression. Default is 0.7.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--classes",
|
||||
nargs="*",
|
||||
type=int,
|
||||
default=[],
|
||||
help="List of class IDs to track. If empty, all classes are tracked.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
main(
|
||||
rtsp_url=args.rtsp_url,
|
||||
zone_configuration_path=args.zone_configuration_path,
|
||||
weights=args.weights,
|
||||
device=args.device,
|
||||
confidence=args.confidence_threshold,
|
||||
iou=args.iou_threshold,
|
||||
classes=args.classes,
|
||||
)
|
||||
@@ -0,0 +1,66 @@
|
||||
import json
|
||||
from typing import Generator, List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
This function reads a JSON file which contains polygon coordinates, and
|
||||
converts them into a list of NumPy arrays. Each polygon is represented as
|
||||
a NumPy array of coordinates.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the JSON configuration file.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data]
|
||||
|
||||
|
||||
def find_in_list(array: np.ndarray, search_list: List[int]) -> np.ndarray:
|
||||
"""Determines if elements of a numpy array are present in a list.
|
||||
|
||||
Args:
|
||||
array (np.ndarray): The numpy array of integers to check.
|
||||
search_list (List[int]): The list of integers to search within.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of booleans, where each boolean indicates whether
|
||||
the corresponding element in `array` is found in `search_list`.
|
||||
"""
|
||||
if not search_list:
|
||||
return np.ones(array.shape, dtype=bool)
|
||||
else:
|
||||
return np.isin(array, search_list)
|
||||
|
||||
|
||||
def get_stream_frames_generator(rtsp_url: str) -> Generator[np.ndarray, None, None]:
|
||||
"""
|
||||
Generator function to yield frames from an RTSP stream.
|
||||
|
||||
Args:
|
||||
rtsp_url (str): URL of the RTSP video stream.
|
||||
|
||||
Yields:
|
||||
np.ndarray: The next frame from the video stream.
|
||||
"""
|
||||
cap = cv2.VideoCapture(rtsp_url)
|
||||
if not cap.isOpened():
|
||||
raise Exception("Error: Could not open video stream.")
|
||||
|
||||
try:
|
||||
while True:
|
||||
ret, frame = cap.read()
|
||||
if not ret:
|
||||
print("End of stream or error reading frame.")
|
||||
break
|
||||
yield frame
|
||||
finally:
|
||||
cap.release()
|
||||
@@ -0,0 +1,88 @@
|
||||
from datetime import datetime
|
||||
from typing import Dict
|
||||
|
||||
import numpy as np
|
||||
|
||||
import supervision as sv
|
||||
|
||||
|
||||
class FPSBasedTimer:
|
||||
"""
|
||||
A timer that calculates the duration each object has been detected based on frames
|
||||
per second (FPS).
|
||||
|
||||
Attributes:
|
||||
fps (int): The frame rate of the video stream, used to calculate time durations.
|
||||
frame_id (int): The current frame number in the sequence.
|
||||
tracker_id2frame_id (Dict[int, int]): Maps each tracker's ID to the frame number
|
||||
at which it was first detected.
|
||||
"""
|
||||
|
||||
def __init__(self, fps: int = 30) -> None:
|
||||
"""Initializes the FPSBasedTimer with the specified frames per second rate.
|
||||
|
||||
Args:
|
||||
fps (int, optional): The frame rate of the video stream. Defaults to 30.
|
||||
"""
|
||||
self.fps = fps
|
||||
self.frame_id = 0
|
||||
self.tracker_id2frame_id: Dict[int, int] = {}
|
||||
|
||||
def tick(self, detections: sv.Detections) -> np.ndarray:
|
||||
"""Processes the current frame, updating time durations for each tracker.
|
||||
|
||||
Args:
|
||||
detections: The detections for the current frame, including tracker IDs.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Time durations (in seconds) for each detected tracker, since
|
||||
their first detection.
|
||||
"""
|
||||
self.frame_id += 1
|
||||
times = []
|
||||
|
||||
for tracker_id in detections.tracker_id:
|
||||
self.tracker_id2frame_id.setdefault(tracker_id, self.frame_id)
|
||||
|
||||
start_frame_id = self.tracker_id2frame_id[tracker_id]
|
||||
time_duration = (self.frame_id - start_frame_id) / self.fps
|
||||
times.append(time_duration)
|
||||
|
||||
return np.array(times)
|
||||
|
||||
|
||||
class ClockBasedTimer:
|
||||
"""
|
||||
A timer that calculates the duration each object has been detected based on the
|
||||
system clock.
|
||||
|
||||
Attributes:
|
||||
tracker_id2start_time (Dict[int, datetime]): Maps each tracker's ID to the
|
||||
datetime when it was first detected.
|
||||
"""
|
||||
|
||||
def __init__(self) -> None:
|
||||
"""Initializes the ClockBasedTimer."""
|
||||
self.tracker_id2start_time: Dict[int, datetime] = {}
|
||||
|
||||
def tick(self, detections: sv.Detections) -> np.ndarray:
|
||||
"""Processes the current frame, updating time durations for each tracker.
|
||||
|
||||
Args:
|
||||
detections: The detections for the current frame, including tracker IDs.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Time durations (in seconds) for each detected tracker, since
|
||||
their first detection.
|
||||
"""
|
||||
current_time = datetime.now()
|
||||
times = []
|
||||
|
||||
for tracker_id in detections.tracker_id:
|
||||
self.tracker_id2start_time.setdefault(tracker_id, current_time)
|
||||
|
||||
start_time = self.tracker_id2start_time[tracker_id]
|
||||
time_duration = (current_time - start_time).total_seconds()
|
||||
times.append(time_duration)
|
||||
|
||||
return np.array(times)
|
||||
@@ -1,4 +1,4 @@
|
||||
inference
|
||||
supervision
|
||||
supervision==0.19.0
|
||||
tqdm
|
||||
ultralytics
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
gdown
|
||||
inference
|
||||
supervision>=0.19.0rc5
|
||||
supervision>=0.19.0
|
||||
tqdm
|
||||
ultralytics
|
||||
|
||||
@@ -38,6 +38,7 @@ nav:
|
||||
- Home: index.md
|
||||
- How to:
|
||||
- Detect and Annotate: how_to/detect_and_annotate.md
|
||||
- Detect Small Objects: how_to/detect_small_objects.md
|
||||
- Track Objects: how_to/track_objects.md
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
- API:
|
||||
|
||||
Generated
+38
-37
@@ -1,4 +1,4 @@
|
||||
# This file is automatically @generated by Poetry 1.7.1 and should not be changed by hand.
|
||||
# This file is automatically @generated by Poetry 1.8.2 and should not be changed by hand.
|
||||
|
||||
[[package]]
|
||||
name = "anyio"
|
||||
@@ -244,26 +244,27 @@ css = ["tinycss2 (>=1.1.0,<1.3)"]
|
||||
|
||||
[[package]]
|
||||
name = "build"
|
||||
version = "1.1.1"
|
||||
version = "1.2.0"
|
||||
description = "A simple, correct Python build frontend"
|
||||
optional = false
|
||||
python-versions = ">= 3.7"
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "build-1.1.1-py3-none-any.whl", hash = "sha256:8ed0851ee76e6e38adce47e4bee3b51c771d86c64cf578d0c2245567ee200e73"},
|
||||
{file = "build-1.1.1.tar.gz", hash = "sha256:8eea65bb45b1aac2e734ba2cc8dad3a6d97d97901a395bd0ed3e7b46953d2a31"},
|
||||
{file = "build-1.2.0-py3-none-any.whl", hash = "sha256:6105465d9b233433ce8ffa151c760f674446ba766af0290fc14bfa32aef92a04"},
|
||||
{file = "build-1.2.0.tar.gz", hash = "sha256:49df7f8e1e74d345fe71e54f5d56423b2111eda89e3da53a2c18392954dade1d"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
colorama = {version = "*", markers = "os_name == \"nt\""}
|
||||
importlib-metadata = {version = ">=4.6", markers = "python_full_version < \"3.10.2\""}
|
||||
packaging = ">=19.0"
|
||||
packaging = ">=19.1"
|
||||
pyproject_hooks = "*"
|
||||
tomli = {version = ">=1.1.0", markers = "python_version < \"3.11\""}
|
||||
|
||||
[package.extras]
|
||||
docs = ["furo (>=2023.08.17)", "sphinx (>=7.0,<8.0)", "sphinx-argparse-cli (>=1.5)", "sphinx-autodoc-typehints (>=1.10)", "sphinx-issues (>=3.0.0)"]
|
||||
test = ["filelock (>=3)", "pytest (>=6.2.4)", "pytest-cov (>=2.12)", "pytest-mock (>=2)", "pytest-rerunfailures (>=9.1)", "pytest-xdist (>=1.34)", "setuptools (>=42.0.0)", "setuptools (>=56.0.0)", "setuptools (>=56.0.0)", "setuptools (>=67.8.0)", "wheel (>=0.36.0)"]
|
||||
typing = ["importlib-metadata (>=5.1)", "mypy (>=1.5.0,<1.6.0)", "tomli", "typing-extensions (>=3.7.4.3)"]
|
||||
test = ["build[uv,virtualenv]", "filelock (>=3)", "pytest (>=6.2.4)", "pytest-cov (>=2.12)", "pytest-mock (>=2)", "pytest-rerunfailures (>=9.1)", "pytest-xdist (>=1.34)", "setuptools (>=42.0.0)", "setuptools (>=56.0.0)", "setuptools (>=56.0.0)", "setuptools (>=67.8.0)", "wheel (>=0.36.0)"]
|
||||
typing = ["build[uv]", "importlib-metadata (>=5.1)", "mypy (>=1.9.0,<1.10.0)", "tomli", "typing-extensions (>=3.7.4.3)"]
|
||||
uv = ["uv (>=0.1.18)"]
|
||||
virtualenv = ["virtualenv (>=20.0.35)"]
|
||||
|
||||
[[package]]
|
||||
@@ -2183,13 +2184,13 @@ test = ["coverage[toml]", "pymdown-extensions", "pytest", "pytest-cov"]
|
||||
|
||||
[[package]]
|
||||
name = "mkdocs-material"
|
||||
version = "9.5.13"
|
||||
version = "9.5.15"
|
||||
description = "Documentation that simply works"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "mkdocs_material-9.5.13-py3-none-any.whl", hash = "sha256:5cbe17fee4e3b4980c8420a04cc762d8dc052ef1e10532abd4fce88e5ea9ce6a"},
|
||||
{file = "mkdocs_material-9.5.13.tar.gz", hash = "sha256:d8e4caae576312a88fd2609b81cf43d233cdbe36860d67a68702b018b425bd87"},
|
||||
{file = "mkdocs_material-9.5.15-py3-none-any.whl", hash = "sha256:e5c96dec3d19491de49ca643fc1dbb92b278e43cdb816c775bc47db77d9b62fb"},
|
||||
{file = "mkdocs_material-9.5.15.tar.gz", hash = "sha256:39f03cca45e82bf54eb7456b5a18bd252eabfdd67f237a229471484a0a4d4635"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2360,13 +2361,13 @@ test = ["flaky", "ipykernel (>=6.19.3)", "ipython", "ipywidgets", "nbconvert (>=
|
||||
|
||||
[[package]]
|
||||
name = "nbconvert"
|
||||
version = "7.16.2"
|
||||
version = "7.16.3"
|
||||
description = "Converting Jupyter Notebooks (.ipynb files) to other formats. Output formats include asciidoc, html, latex, markdown, pdf, py, rst, script. nbconvert can be used both as a Python library (`import nbconvert`) or as a command line tool (invoked as `jupyter nbconvert ...`)."
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "nbconvert-7.16.2-py3-none-any.whl", hash = "sha256:0c01c23981a8de0220255706822c40b751438e32467d6a686e26be08ba784382"},
|
||||
{file = "nbconvert-7.16.2.tar.gz", hash = "sha256:8310edd41e1c43947e4ecf16614c61469ebc024898eb808cce0999860fc9fb16"},
|
||||
{file = "nbconvert-7.16.3-py3-none-any.whl", hash = "sha256:ddeff14beeeedf3dd0bc506623e41e4507e551736de59df69a91f86700292b3b"},
|
||||
{file = "nbconvert-7.16.3.tar.gz", hash = "sha256:a6733b78ce3d47c3f85e504998495b07e6ea9cf9bf6ec1c98dda63ec6ad19142"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -2393,7 +2394,7 @@ docs = ["ipykernel", "ipython", "myst-parser", "nbsphinx (>=0.2.12)", "pydata-sp
|
||||
qtpdf = ["nbconvert[qtpng]"]
|
||||
qtpng = ["pyqtwebengine (>=5.15)"]
|
||||
serve = ["tornado (>=6.1)"]
|
||||
test = ["flaky", "ipykernel", "ipywidgets (>=7.5)", "pytest"]
|
||||
test = ["flaky", "ipykernel", "ipywidgets (>=7.5)", "pytest (>=7)"]
|
||||
webpdf = ["playwright"]
|
||||
|
||||
[[package]]
|
||||
@@ -3645,28 +3646,28 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "ruff"
|
||||
version = "0.3.2"
|
||||
version = "0.3.4"
|
||||
description = "An extremely fast Python linter and code formatter, written in Rust."
|
||||
optional = false
|
||||
python-versions = ">=3.7"
|
||||
files = [
|
||||
{file = "ruff-0.3.2-py3-none-macosx_10_12_x86_64.macosx_11_0_arm64.macosx_10_12_universal2.whl", hash = "sha256:77f2612752e25f730da7421ca5e3147b213dca4f9a0f7e0b534e9562c5441f01"},
|
||||
{file = "ruff-0.3.2-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:9966b964b2dd1107797be9ca7195002b874424d1d5472097701ae8f43eadef5d"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:b83d17ff166aa0659d1e1deaf9f2f14cbe387293a906de09bc4860717eb2e2da"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:bb875c6cc87b3703aeda85f01c9aebdce3d217aeaca3c2e52e38077383f7268a"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:be75e468a6a86426430373d81c041b7605137a28f7014a72d2fc749e47f572aa"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:967978ac2d4506255e2f52afe70dda023fc602b283e97685c8447d036863a302"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:1231eacd4510f73222940727ac927bc5d07667a86b0cbe822024dd00343e77e9"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:2c6d613b19e9a8021be2ee1d0e27710208d1603b56f47203d0abbde906929a9b"},
|
||||
{file = "ruff-0.3.2-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:c8439338a6303585d27b66b4626cbde89bb3e50fa3cae86ce52c1db7449330a7"},
|
||||
{file = "ruff-0.3.2-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:de8b480d8379620cbb5ea466a9e53bb467d2fb07c7eca54a4aa8576483c35d36"},
|
||||
{file = "ruff-0.3.2-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:b74c3de9103bd35df2bb05d8b2899bf2dbe4efda6474ea9681280648ec4d237d"},
|
||||
{file = "ruff-0.3.2-py3-none-musllinux_1_2_i686.whl", hash = "sha256:f380be9fc15a99765c9cf316b40b9da1f6ad2ab9639e551703e581a5e6da6745"},
|
||||
{file = "ruff-0.3.2-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:0ac06a3759c3ab9ef86bbeca665d31ad3aa9a4b1c17684aadb7e61c10baa0df4"},
|
||||
{file = "ruff-0.3.2-py3-none-win32.whl", hash = "sha256:9bd640a8f7dd07a0b6901fcebccedadeb1a705a50350fb86b4003b805c81385a"},
|
||||
{file = "ruff-0.3.2-py3-none-win_amd64.whl", hash = "sha256:0c1bdd9920cab5707c26c8b3bf33a064a4ca7842d91a99ec0634fec68f9f4037"},
|
||||
{file = "ruff-0.3.2-py3-none-win_arm64.whl", hash = "sha256:5f65103b1d76e0d600cabd577b04179ff592064eaa451a70a81085930e907d0b"},
|
||||
{file = "ruff-0.3.2.tar.gz", hash = "sha256:fa78ec9418eb1ca3db392811df3376b46471ae93792a81af2d1cbb0e5dcb5142"},
|
||||
{file = "ruff-0.3.4-py3-none-macosx_10_12_x86_64.macosx_11_0_arm64.macosx_10_12_universal2.whl", hash = "sha256:60c870a7d46efcbc8385d27ec07fe534ac32f3b251e4fc44b3cbfd9e09609ef4"},
|
||||
{file = "ruff-0.3.4-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:6fc14fa742e1d8f24910e1fff0bd5e26d395b0e0e04cc1b15c7c5e5fe5b4af91"},
|
||||
{file = "ruff-0.3.4-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:d3ee7880f653cc03749a3bfea720cf2a192e4f884925b0cf7eecce82f0ce5854"},
|
||||
{file = "ruff-0.3.4-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:cf133dd744f2470b347f602452a88e70dadfbe0fcfb5fd46e093d55da65f82f7"},
|
||||
{file = "ruff-0.3.4-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:3f3860057590e810c7ffea75669bdc6927bfd91e29b4baa9258fd48b540a4365"},
|
||||
{file = "ruff-0.3.4-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:986f2377f7cf12efac1f515fc1a5b753c000ed1e0a6de96747cdf2da20a1b369"},
|
||||
{file = "ruff-0.3.4-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:c4fd98e85869603e65f554fdc5cddf0712e352fe6e61d29d5a6fe087ec82b76c"},
|
||||
{file = "ruff-0.3.4-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:64abeed785dad51801b423fa51840b1764b35d6c461ea8caef9cf9e5e5ab34d9"},
|
||||
{file = "ruff-0.3.4-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:df52972138318bc7546d92348a1ee58449bc3f9eaf0db278906eb511889c4b50"},
|
||||
{file = "ruff-0.3.4-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:98e98300056445ba2cc27d0b325fd044dc17fcc38e4e4d2c7711585bd0a958ed"},
|
||||
{file = "ruff-0.3.4-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:519cf6a0ebed244dce1dc8aecd3dc99add7a2ee15bb68cf19588bb5bf58e0488"},
|
||||
{file = "ruff-0.3.4-py3-none-musllinux_1_2_i686.whl", hash = "sha256:bb0acfb921030d00070539c038cd24bb1df73a2981e9f55942514af8b17be94e"},
|
||||
{file = "ruff-0.3.4-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:cf187a7e7098233d0d0c71175375c5162f880126c4c716fa28a8ac418dcf3378"},
|
||||
{file = "ruff-0.3.4-py3-none-win32.whl", hash = "sha256:af27ac187c0a331e8ef91d84bf1c3c6a5dea97e912a7560ac0cef25c526a4102"},
|
||||
{file = "ruff-0.3.4-py3-none-win_amd64.whl", hash = "sha256:de0d5069b165e5a32b3c6ffbb81c350b1e3d3483347196ffdf86dc0ef9e37dd6"},
|
||||
{file = "ruff-0.3.4-py3-none-win_arm64.whl", hash = "sha256:6810563cc08ad0096b57c717bd78aeac888a1bfd38654d9113cb3dc4d3f74232"},
|
||||
{file = "ruff-0.3.4.tar.gz", hash = "sha256:f0f4484c6541a99862b693e13a151435a279b271cff20e37101116a21e2a1ad1"},
|
||||
]
|
||||
|
||||
[[package]]
|
||||
@@ -3942,13 +3943,13 @@ files = [
|
||||
|
||||
[[package]]
|
||||
name = "tox"
|
||||
version = "4.14.1"
|
||||
version = "4.14.2"
|
||||
description = "tox is a generic virtualenv management and test command line tool"
|
||||
optional = false
|
||||
python-versions = ">=3.8"
|
||||
files = [
|
||||
{file = "tox-4.14.1-py3-none-any.whl", hash = "sha256:b03754b6ee6dadc70f2611da82b4ed8f625fcafd247e15d1d0cb056f90a06d3b"},
|
||||
{file = "tox-4.14.1.tar.gz", hash = "sha256:f0ad758c3bbf7e237059c929d3595479363c3cdd5a06ac3e49d1dd020ffbee45"},
|
||||
{file = "tox-4.14.2-py3-none-any.whl", hash = "sha256:2900c4eb7b716af4a928a7fdc2ed248ad6575294ed7cfae2ea41203937422847"},
|
||||
{file = "tox-4.14.2.tar.gz", hash = "sha256:0defb44f6dafd911b61788325741cc6b2e12ea71f987ac025ad4d649f1f1a104"},
|
||||
]
|
||||
|
||||
[package.dependencies]
|
||||
@@ -4252,4 +4253,4 @@ desktop = ["opencv-python"]
|
||||
[metadata]
|
||||
lock-version = "2.0"
|
||||
python-versions = "^3.8"
|
||||
content-hash = "30b2e5864f20c0b0cf5ddff7658427a18e18c9d387da86725e8e9288f795086a"
|
||||
content-hash = "56ddae6824a9f28c9954badd4c642c57f687b099c6169f97fa0372e294500c17"
|
||||
|
||||
+2
-2
@@ -1,6 +1,6 @@
|
||||
[tool.poetry]
|
||||
name = "supervision"
|
||||
version = "0.19.0"
|
||||
version = "0.20.0rc2"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
authors = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
maintainers = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
@@ -54,7 +54,7 @@ assets = ["requests","tqdm"]
|
||||
twine = ">=4.0.2,<6.0.0"
|
||||
pytest = ">=7.2.2,<9.0.0"
|
||||
wheel = ">=0.40,<0.44"
|
||||
build = ">=0.10,<1.2"
|
||||
build = ">=0.10,<1.3"
|
||||
ruff = ">=0.1.0"
|
||||
mypy = "^1.4.1"
|
||||
pre-commit = "^3.3.3"
|
||||
|
||||
@@ -58,8 +58,8 @@ from supervision.detection.utils import (
|
||||
)
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import (
|
||||
calculate_dynamic_line_thickness,
|
||||
calculate_dynamic_text_scale,
|
||||
calculate_optimal_line_thickness,
|
||||
calculate_optimal_text_scale,
|
||||
draw_filled_rectangle,
|
||||
draw_image,
|
||||
draw_line,
|
||||
|
||||
+126
-24
@@ -914,6 +914,7 @@ class LabelAnnotator:
|
||||
text_padding: int = 10,
|
||||
text_position: Position = Position.TOP_LEFT,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
border_radius: int = 0,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
@@ -927,7 +928,10 @@ class LabelAnnotator:
|
||||
Possible values are defined in the `Position` enum.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
border_radius (int): The radius to apply round edges. If the selected
|
||||
value is higher than the lower dimension, width or height, is clipped.
|
||||
"""
|
||||
self.border_radius: int = border_radius
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.text_color: Color = text_color
|
||||
self.text_scale: float = text_scale
|
||||
@@ -1015,15 +1019,22 @@ class LabelAnnotator:
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
|
||||
@@ -1080,12 +1091,11 @@ class LabelAnnotator:
|
||||
text_x = text_background_xyxy[0] + self.text_padding
|
||||
text_y = text_background_xyxy[1] + self.text_padding + text_h
|
||||
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=(text_background_xyxy[0], text_background_xyxy[1]),
|
||||
pt2=(text_background_xyxy[2], text_background_xyxy[3]),
|
||||
self.draw_rounded_rectangle(
|
||||
scene=scene,
|
||||
xyxy=text_background_xyxy,
|
||||
color=color.as_bgr(),
|
||||
thickness=cv2.FILLED,
|
||||
border_radius=self.border_radius,
|
||||
)
|
||||
cv2.putText(
|
||||
img=scene,
|
||||
@@ -1099,6 +1109,48 @@ class LabelAnnotator:
|
||||
)
|
||||
return scene
|
||||
|
||||
@staticmethod
|
||||
def draw_rounded_rectangle(
|
||||
scene: np.ndarray,
|
||||
xyxy: Tuple[int, int, int, int],
|
||||
color: Tuple[int, int, int],
|
||||
border_radius: int,
|
||||
) -> np.ndarray:
|
||||
x1, y1, x2, y2 = xyxy
|
||||
width = x2 - x1
|
||||
height = y2 - y1
|
||||
|
||||
border_radius = min(border_radius, min(width, height) // 2)
|
||||
|
||||
rectangle_coordinates = [
|
||||
((x1 + border_radius, y1), (x2 - border_radius, y2)),
|
||||
((x1, y1 + border_radius), (x2, y2 - border_radius)),
|
||||
]
|
||||
circle_centers = [
|
||||
(x1 + border_radius, y1 + border_radius),
|
||||
(x2 - border_radius, y1 + border_radius),
|
||||
(x1 + border_radius, y2 - border_radius),
|
||||
(x2 - border_radius, y2 - border_radius),
|
||||
]
|
||||
|
||||
for coordinates in rectangle_coordinates:
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=coordinates[0],
|
||||
pt2=coordinates[1],
|
||||
color=color,
|
||||
thickness=-1,
|
||||
)
|
||||
for center in circle_centers:
|
||||
cv2.circle(
|
||||
img=scene,
|
||||
center=center,
|
||||
radius=border_radius,
|
||||
color=color,
|
||||
thickness=-1,
|
||||
)
|
||||
return scene
|
||||
|
||||
|
||||
class BlurAnnotator(BaseAnnotator):
|
||||
"""
|
||||
@@ -1847,7 +1899,14 @@ class CropAnnotator(BaseAnnotator):
|
||||
A class for drawing scaled up crops of detections on the scene.
|
||||
"""
|
||||
|
||||
def __init__(self, position: Position = Position.TOP_CENTER, scale_factor: int = 2):
|
||||
def __init__(
|
||||
self,
|
||||
position: Position = Position.TOP_CENTER,
|
||||
scale_factor: int = 2,
|
||||
border_color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
border_thickness: int = 2,
|
||||
border_color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
position (Position): The anchor position for placing the cropped and scaled
|
||||
@@ -1855,16 +1914,25 @@ class CropAnnotator(BaseAnnotator):
|
||||
scale_factor (int): The factor by which to scale the cropped image part. A
|
||||
factor of 2, for example, would double the size of the cropped area,
|
||||
allowing for a closer view of the detection.
|
||||
border_color (Union[Color, ColorPalette]): The color or color palette to
|
||||
use for annotating border around the cropped area.
|
||||
border_thickness (int): The thickness of the border around the cropped area.
|
||||
border_color_lookup (ColorLookup): Strategy for mapping colors to
|
||||
annotations. Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.position: Position = position
|
||||
self.scale_factor: int = scale_factor
|
||||
self.border_color: Union[Color, ColorPalette] = border_color
|
||||
self.border_thickness: int = border_thickness
|
||||
self.border_color_lookup: ColorLookup = border_color_lookup
|
||||
|
||||
@scene_to_annotator_img_type
|
||||
def annotate(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
scene: ImageType,
|
||||
detections: Detections,
|
||||
) -> np.ndarray:
|
||||
custom_color_lookup: Optional[np.ndarray] = None,
|
||||
) -> ImageType:
|
||||
"""
|
||||
Annotates the provided scene with scaled and cropped parts of the image based
|
||||
on the provided detections. Each detection is cropped from the original scene
|
||||
@@ -1873,8 +1941,12 @@ class CropAnnotator(BaseAnnotator):
|
||||
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image where cropped detection will be placed.
|
||||
scene (ImageType): The image where cropped detection will be placed.
|
||||
`ImageType` is a flexible type, accepting either `numpy.ndarray`
|
||||
or `PIL.Image.Image`.
|
||||
detections (Detections): Object detections to annotate.
|
||||
custom_color_lookup (Optional[np.ndarray]): Custom color lookup array.
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
The annotated image.
|
||||
@@ -1901,37 +1973,67 @@ class CropAnnotator(BaseAnnotator):
|
||||
]
|
||||
anchors = detections.get_anchors_coordinates(anchor=self.position).astype(int)
|
||||
|
||||
for resized_crop, anchor in zip(resized_crops, anchors):
|
||||
for idx, (resized_crop, anchor) in enumerate(zip(resized_crops, anchors)):
|
||||
crop_wh = resized_crop.shape[1], resized_crop.shape[0]
|
||||
crop_anchor = self.calculate_crop_coordinates(
|
||||
(x1, y1), (x2, y2) = self.calculate_crop_coordinates(
|
||||
anchor=anchor, crop_wh=crop_wh, position=self.position
|
||||
)
|
||||
scene = place_image(scene=scene, image=resized_crop, anchor=crop_anchor)
|
||||
scene = place_image(scene=scene, image=resized_crop, anchor=(x1, y1))
|
||||
color = resolve_color(
|
||||
color=self.border_color,
|
||||
detections=detections,
|
||||
detection_idx=idx,
|
||||
color_lookup=self.border_color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=(x1, y1),
|
||||
pt2=(x2, y2),
|
||||
color=color.as_bgr(),
|
||||
thickness=self.border_thickness,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
@staticmethod
|
||||
def calculate_crop_coordinates(
|
||||
anchor: Tuple[int, int], crop_wh: Tuple[int, int], position: Position
|
||||
) -> Tuple[int, int]:
|
||||
) -> Tuple[Tuple[int, int], Tuple[int, int]]:
|
||||
anchor_x, anchor_y = anchor
|
||||
width, height = crop_wh
|
||||
|
||||
if position == Position.TOP_LEFT:
|
||||
return anchor_x - width, anchor_y - height
|
||||
return (anchor_x - width, anchor_y - height), (anchor_x, anchor_y)
|
||||
elif position == Position.TOP_CENTER:
|
||||
return anchor_x - width // 2, anchor_y - height
|
||||
return (
|
||||
(anchor_x - width // 2, anchor_y - height),
|
||||
(anchor_x + width // 2, anchor_y),
|
||||
)
|
||||
elif position == Position.TOP_RIGHT:
|
||||
return anchor_x, anchor_y - height
|
||||
return (anchor_x, anchor_y - height), (anchor_x + width, anchor_y)
|
||||
elif position == Position.CENTER_LEFT:
|
||||
return anchor_x - width, anchor_y - height // 2
|
||||
return (
|
||||
(anchor_x - width, anchor_y - height // 2),
|
||||
(anchor_x, anchor_y + height // 2),
|
||||
)
|
||||
elif position == Position.CENTER or position == Position.CENTER_OF_MASS:
|
||||
return anchor_x - width // 2, anchor_y - height // 2
|
||||
return (
|
||||
(anchor_x - width // 2, anchor_y - height // 2),
|
||||
(anchor_x + width // 2, anchor_y + height // 2),
|
||||
)
|
||||
elif position == Position.CENTER_RIGHT:
|
||||
return anchor_x, anchor_y - height // 2
|
||||
return (
|
||||
(anchor_x, anchor_y - height // 2),
|
||||
(anchor_x + width, anchor_y + height // 2),
|
||||
)
|
||||
elif position == Position.BOTTOM_LEFT:
|
||||
return anchor_x - width, anchor_y
|
||||
return (anchor_x - width, anchor_y), (anchor_x, anchor_y + height)
|
||||
elif position == Position.BOTTOM_CENTER:
|
||||
return anchor_x - width // 2, anchor_y
|
||||
return (
|
||||
(anchor_x - width // 2, anchor_y),
|
||||
(anchor_x + width // 2, anchor_y + height),
|
||||
)
|
||||
elif position == Position.BOTTOM_RIGHT:
|
||||
return anchor_x, anchor_y
|
||||
return (anchor_x, anchor_y), (anchor_x + width, anchor_y + height)
|
||||
|
||||
@@ -14,6 +14,7 @@ from supervision.detection.utils import (
|
||||
get_data_item,
|
||||
is_data_equal,
|
||||
mask_non_max_suppression,
|
||||
mask_to_xyxy,
|
||||
merge_data,
|
||||
process_roboflow_result,
|
||||
validate_detections_fields,
|
||||
@@ -390,18 +391,30 @@ class Detections:
|
||||
@classmethod
|
||||
def from_transformers(cls, transformers_results: dict) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from object detection
|
||||
Creates a Detections instance from object detection or segmentation
|
||||
[transformer](https://github.com/huggingface/transformers) inference result.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
"""
|
||||
boxes = transformers_results.get("boxes")
|
||||
|
||||
return cls(
|
||||
xyxy=transformers_results["boxes"].cpu().numpy(),
|
||||
confidence=transformers_results["scores"].cpu().numpy(),
|
||||
class_id=transformers_results["labels"].cpu().numpy().astype(int),
|
||||
)
|
||||
# If the boxes key is in the transformers_results then we know it's an
|
||||
# object detection result. Else, we can assume it's a segmentation model
|
||||
if boxes:
|
||||
return cls(
|
||||
xyxy=transformers_results["boxes"].cpu().numpy(),
|
||||
confidence=transformers_results["scores"].cpu().numpy(),
|
||||
class_id=transformers_results["labels"].cpu().numpy().astype(int),
|
||||
)
|
||||
else:
|
||||
masks = transformers_results["masks"].cpu().numpy().astype(bool)
|
||||
return cls(
|
||||
xyxy=mask_to_xyxy(masks),
|
||||
mask=masks,
|
||||
confidence=transformers_results["scores"].cpu().numpy(),
|
||||
class_id=transformers_results["labels"].cpu().numpy().astype(int),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_detectron2(cls, detectron2_results) -> Detections:
|
||||
|
||||
@@ -3,6 +3,7 @@ from typing import Iterable, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision import Detections
|
||||
from supervision.detection.utils import clip_boxes, polygon_to_mask
|
||||
@@ -39,7 +40,7 @@ class PolygonZone:
|
||||
)
|
||||
def __init__(
|
||||
self,
|
||||
polygon: np.ndarray,
|
||||
polygon: npt.NDArray[np.int64],
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
triggering_anchors: Iterable[Position] = (Position.BOTTOM_CENTER,),
|
||||
):
|
||||
@@ -54,7 +55,7 @@ class PolygonZone:
|
||||
polygon=polygon, resolution_wh=(width + 1, height + 1)
|
||||
)
|
||||
|
||||
def trigger(self, detections: Detections) -> np.ndarray:
|
||||
def trigger(self, detections: Detections) -> npt.NDArray[np.bool_]:
|
||||
"""
|
||||
Determines if the detections are within the polygon zone.
|
||||
|
||||
@@ -78,13 +79,13 @@ class PolygonZone:
|
||||
]
|
||||
)
|
||||
|
||||
is_in_zone = (
|
||||
is_in_zone: npt.NDArray[np.bool_] = (
|
||||
self.mask[all_clipped_anchors[:, :, 1], all_clipped_anchors[:, :, 0]]
|
||||
.transpose()
|
||||
.astype(bool)
|
||||
)
|
||||
is_in_zone = np.all(is_in_zone, axis=1)
|
||||
|
||||
is_in_zone: npt.NDArray[np.bool_] = np.all(is_in_zone, axis=1)
|
||||
self.current_count = int(np.sum(is_in_zone))
|
||||
return is_in_zone.astype(bool)
|
||||
|
||||
|
||||
@@ -845,8 +845,15 @@ def get_data_item(
|
||||
elif isinstance(value, list):
|
||||
if isinstance(index, slice):
|
||||
subset_data[key] = value[index]
|
||||
elif isinstance(index, (list, np.ndarray)):
|
||||
elif isinstance(index, list):
|
||||
subset_data[key] = [value[i] for i in index]
|
||||
elif isinstance(index, np.ndarray):
|
||||
if index.dtype == bool:
|
||||
subset_data[key] = [
|
||||
value[i] for i, index_value in enumerate(index) if index_value
|
||||
]
|
||||
else:
|
||||
subset_data[key] = [value[i] for i in index]
|
||||
elif isinstance(index, int):
|
||||
subset_data[key] = [value[index]]
|
||||
else:
|
||||
|
||||
@@ -176,31 +176,31 @@ class Color:
|
||||
return self.b, self.g, self.r
|
||||
|
||||
@classproperty
|
||||
def WHITE(cls):
|
||||
def WHITE(cls) -> Color:
|
||||
return Color.from_hex("#FFFFFF")
|
||||
|
||||
@classproperty
|
||||
def BLACK(cls):
|
||||
def BLACK(cls) -> Color:
|
||||
return Color.from_hex("#000000")
|
||||
|
||||
@classproperty
|
||||
def RED(cls):
|
||||
def RED(cls) -> Color:
|
||||
return Color.from_hex("#FF0000")
|
||||
|
||||
@classproperty
|
||||
def GREEN(cls):
|
||||
def GREEN(cls) -> Color:
|
||||
return Color.from_hex("#00FF00")
|
||||
|
||||
@classproperty
|
||||
def BLUE(cls):
|
||||
def BLUE(cls) -> Color:
|
||||
return Color.from_hex("#0000FF")
|
||||
|
||||
@classproperty
|
||||
def YELLOW(cls):
|
||||
def YELLOW(cls) -> Color:
|
||||
return Color.from_hex("#FFFF00")
|
||||
|
||||
@classproperty
|
||||
def ROBOFLOW(cls):
|
||||
def ROBOFLOW(cls) -> Color:
|
||||
return Color.from_hex("#A351FB")
|
||||
|
||||
@classmethod
|
||||
|
||||
@@ -238,13 +238,13 @@ def draw_image(
|
||||
return scene
|
||||
|
||||
|
||||
def calculate_dynamic_text_scale(resolution_wh: Tuple[int, int]) -> float:
|
||||
def calculate_optimal_text_scale(resolution_wh: Tuple[int, int]) -> float:
|
||||
"""
|
||||
Calculate a dynamic font scale based on the resolution of an image.
|
||||
Calculate font scale based on the resolution of an image.
|
||||
|
||||
Parameters:
|
||||
resolution_wh (Tuple[int, int]): A tuple representing the width and height
|
||||
of the image.
|
||||
of the image.
|
||||
|
||||
Returns:
|
||||
float: The calculated font scale factor.
|
||||
@@ -252,25 +252,17 @@ def calculate_dynamic_text_scale(resolution_wh: Tuple[int, int]) -> float:
|
||||
return min(resolution_wh) * 1e-3
|
||||
|
||||
|
||||
def calculate_dynamic_line_thickness(resolution_wh: Tuple[int, int]) -> int:
|
||||
def calculate_optimal_line_thickness(resolution_wh: Tuple[int, int]) -> int:
|
||||
"""
|
||||
Calculate a dynamic line thickness based on the resolution of an image.
|
||||
Calculate line thickness based on the resolution of an image.
|
||||
|
||||
Parameters:
|
||||
resolution_wh (Tuple[int, int]): A tuple representing the width and height
|
||||
of the image.
|
||||
of the image.
|
||||
|
||||
Returns:
|
||||
int: The calculated line thickness in pixels.
|
||||
"""
|
||||
min_dimension = min(resolution_wh)
|
||||
if min_dimension < 480:
|
||||
if min(resolution_wh) < 1080:
|
||||
return 2
|
||||
if min_dimension < 720:
|
||||
return 2
|
||||
if min_dimension < 1080:
|
||||
return 2
|
||||
if min_dimension < 2160:
|
||||
return 4
|
||||
else:
|
||||
return 4
|
||||
return 4
|
||||
|
||||
@@ -3,6 +3,7 @@ from typing import List, Tuple
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import box_iou_batch
|
||||
from supervision.tracker.byte_tracker import matching
|
||||
from supervision.tracker.byte_tracker.basetrack import BaseTrack, TrackState
|
||||
from supervision.tracker.byte_tracker.kalman_filter import KalmanFilter
|
||||
@@ -270,27 +271,28 @@ class ByteTrack:
|
||||
```
|
||||
"""
|
||||
|
||||
tracks = self.update_with_tensors(
|
||||
tensors=detections2boxes(detections=detections)
|
||||
)
|
||||
detections = Detections.empty()
|
||||
tensors = detections2boxes(detections=detections)
|
||||
tracks = self.update_with_tensors(tensors=tensors)
|
||||
|
||||
if len(tracks) > 0:
|
||||
detections.xyxy = np.array(
|
||||
[track.tlbr for track in tracks], dtype=np.float32
|
||||
)
|
||||
detections.class_id = np.array(
|
||||
[int(t.class_ids) for t in tracks], dtype=int
|
||||
)
|
||||
detections.tracker_id = np.array(
|
||||
[int(t.track_id) for t in tracks], dtype=int
|
||||
)
|
||||
detections.confidence = np.array(
|
||||
[t.score for t in tracks], dtype=np.float32
|
||||
)
|
||||
detection_bounding_boxes = np.asarray([det[:4] for det in tensors])
|
||||
track_bounding_boxes = np.asarray([track.tlbr for track in tracks])
|
||||
|
||||
ious = box_iou_batch(detection_bounding_boxes, track_bounding_boxes)
|
||||
|
||||
iou_costs = 1 - ious
|
||||
|
||||
matches, _, _ = matching.linear_assignment(iou_costs, 0.5)
|
||||
detections.tracker_id = np.full(len(detections), -1, dtype=int)
|
||||
for i_detection, i_track in matches:
|
||||
detections.tracker_id[i_detection] = int(tracks[i_track].track_id)
|
||||
|
||||
return detections[detections.tracker_id != -1]
|
||||
|
||||
else:
|
||||
detections.tracker_id = np.array([], dtype=int)
|
||||
|
||||
return detections
|
||||
return detections
|
||||
|
||||
def reset(self):
|
||||
"""
|
||||
|
||||
@@ -153,7 +153,8 @@ class ImageSink:
|
||||
Save a given image in the target directory.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The image to be saved.
|
||||
image (np.ndarray): The image to be saved. The image must be in BGR color
|
||||
format.
|
||||
image_name (str, optional): The name to use for the saved image.
|
||||
If not provided, a name will be
|
||||
generated using the `image_name_pattern`.
|
||||
|
||||
@@ -105,6 +105,13 @@ class VideoSink:
|
||||
return self
|
||||
|
||||
def write_frame(self, frame: np.ndarray):
|
||||
"""
|
||||
Writes a single video frame to the target video file.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The video frame to be written to the file. The frame
|
||||
must be in BGR color format.
|
||||
"""
|
||||
self.__writer.write(frame)
|
||||
|
||||
def __exit__(self, exc_type, exc_value, exc_traceback):
|
||||
|
||||
@@ -1045,7 +1045,7 @@ def test_merge_data(
|
||||
"test_1": [1],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
), # data dict with a single list field and integer index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
@@ -1055,7 +1055,7 @@ def test_merge_data(
|
||||
"test_1": np.array([1]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
), # data dict with a single np.array field and integer index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
@@ -1065,7 +1065,7 @@ def test_merge_data(
|
||||
"test_1": [1, 2],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
), # data dict with a single list field and slice index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
@@ -1075,7 +1075,7 @@ def test_merge_data(
|
||||
"test_1": np.array([1, 2]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
), # data dict with a single np.array field and slice index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
@@ -1085,7 +1085,7 @@ def test_merge_data(
|
||||
"test_1": [3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
), # data dict with a single list field and negative integer index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
@@ -1095,7 +1095,7 @@ def test_merge_data(
|
||||
"test_1": np.array([3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
), # data dict with a single np.array field and negative integer index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
@@ -1105,7 +1105,7 @@ def test_merge_data(
|
||||
"test_1": [1, 3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
), # data dict with a single list field and integer list index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
@@ -1115,7 +1115,7 @@ def test_merge_data(
|
||||
"test_1": np.array([1, 3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and np.array values as 1D arrays
|
||||
), # data dict with a single np.array field and integer list index
|
||||
(
|
||||
{
|
||||
"test_1": [1, 2, 3],
|
||||
@@ -1125,7 +1125,7 @@ def test_merge_data(
|
||||
"test_1": [1, 3],
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # single data dict with a single field name and list values
|
||||
), # data dict with a single list field and integer np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
@@ -1135,7 +1135,55 @@ def test_merge_data(
|
||||
"test_1": np.array([1, 3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
),
|
||||
), # data dict with a single np.array field and integer np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
np.array([True, True, True]),
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and all-true bool np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
np.array([False, False, False]),
|
||||
{
|
||||
"test_1": np.array([]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and all-false bool np.array index
|
||||
(
|
||||
{
|
||||
"test_1": np.array([1, 2, 3]),
|
||||
},
|
||||
np.array([False, True, False]),
|
||||
{
|
||||
"test_1": np.array([2]),
|
||||
},
|
||||
DoesNotRaise(),
|
||||
), # data dict with a single np.array field and mixed bool np.array index
|
||||
(
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": ["a", "b", "c"]},
|
||||
0,
|
||||
{"test_1": np.array([1]), "test_2": ["a"]},
|
||||
DoesNotRaise(),
|
||||
), # data dict with two fields and integer index
|
||||
(
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": ["a", "b", "c"]},
|
||||
-1,
|
||||
{"test_1": np.array([3]), "test_2": ["c"]},
|
||||
DoesNotRaise(),
|
||||
), # data dict with two fields and negative integer index
|
||||
(
|
||||
{"test_1": np.array([1, 2, 3]), "test_2": ["a", "b", "c"]},
|
||||
np.array([False, True, False]),
|
||||
{"test_1": np.array([2]), "test_2": ["b"]},
|
||||
DoesNotRaise(),
|
||||
), # data dict with two fields and mixed bool np.array index
|
||||
],
|
||||
)
|
||||
def test_get_data_item(
|
||||
|
||||
Reference in New Issue
Block a user