Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|

|
87b1b86f39 | ||
|
pre-commit-ci[bot]
|
1170a90ffc | ||
|
dependabot[bot]
|
2e0e8d9132 | ||
|
Jirka BorovecandCopilot
|
15730b2b5d | ||
|
|
2db1e3af34 | ||
|
jirka
|
840226afce | ||
|
|
dc03ceac31 | ||
|
dependabot[bot]
|
f9ab57afde | ||
|
pre-commit-ci[bot]
|
fb19852919 | ||
|
jirka
|
60f8d28535 | ||
|
|
153cde5854 | ||
|
|
de87030a21 | ||
|
|
5a59dcdec6 | ||
|
jirka
|
87e8153876 | ||
|
|
c4a3038c57 | ||
|
dependabot[bot]
|
6069c477b0 | ||
|
|
6beabe3fb4 | ||
|
|
8df86e2599 | ||
|
|
06beb6ff2f | ||
|
Jirka Borovec
|
5d165e04c2 | ||
|
jirka
|
a5c4ebad08 |
@@ -23,7 +23,7 @@ jobs:
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v6.0.2
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ inputs.python-version }}
|
||||
uses: astral-sh/setup-uv@cec208311dfd045dd5311c1add060b2062131d57 # v8.0.0
|
||||
uses: astral-sh/setup-uv@08807647e7069bb48b6ef5acd8ec9567f424441b # v8.1.0
|
||||
with:
|
||||
python-version: ${{ inputs.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
@@ -25,7 +25,7 @@ jobs:
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v6.0.2
|
||||
|
||||
- name: 🐍 Install uv and set Python
|
||||
uses: astral-sh/setup-uv@cec208311dfd045dd5311c1add060b2062131d57 # v8.0.0
|
||||
uses: astral-sh/setup-uv@08807647e7069bb48b6ef5acd8ec9567f424441b # v8.1.0
|
||||
with:
|
||||
python-version: "3.10"
|
||||
activate-environment: true
|
||||
|
||||
@@ -36,7 +36,7 @@ jobs:
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v6.0.2
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@cec208311dfd045dd5311c1add060b2062131d57 # v8.0.0
|
||||
uses: astral-sh/setup-uv@08807647e7069bb48b6ef5acd8ec9567f424441b # v8.1.0
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
@@ -1,9 +1,15 @@
|
||||
name: Docs/Build and Publish
|
||||
|
||||
# Deploy matrix:
|
||||
# push develop -> mike deploy develop
|
||||
# push release/latest -> mike deploy latest
|
||||
# release published -> mike deploy <tag> only; does not move /latest/
|
||||
|
||||
on:
|
||||
push:
|
||||
branches:
|
||||
- develop
|
||||
- release/latest
|
||||
workflow_dispatch:
|
||||
release:
|
||||
types: [published]
|
||||
@@ -31,7 +37,7 @@ jobs:
|
||||
fetch-depth: 0
|
||||
|
||||
- name: 🐍 Install uv and set Python
|
||||
uses: astral-sh/setup-uv@cec208311dfd045dd5311c1add060b2062131d57 # v8.0.0
|
||||
uses: astral-sh/setup-uv@08807647e7069bb48b6ef5acd8ec9567f424441b # v8.1.0
|
||||
with:
|
||||
python-version: "3.10"
|
||||
activate-environment: true
|
||||
@@ -51,10 +57,98 @@ jobs:
|
||||
run: |
|
||||
mike deploy --push develop
|
||||
|
||||
- name: 🚀 Deploy Latest Docs
|
||||
if: github.event_name == 'push' && github.ref == 'refs/heads/release/latest'
|
||||
env:
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY: ${{ secrets.GITHUB_TOKEN }}
|
||||
run: |
|
||||
mike deploy --push latest
|
||||
|
||||
- name: 🚀 Deploy Release Docs
|
||||
if: github.event_name == 'release' && github.event.action == 'published'
|
||||
env:
|
||||
MKDOCS_GIT_COMMITTERS_APIKEY: ${{ secrets.GITHUB_TOKEN }}
|
||||
run: |
|
||||
latest_tag=$(git describe --tags `git rev-list --tags --max-count=1`)
|
||||
mike deploy --push --update-aliases $latest_tag latest
|
||||
release_tag="${GITHUB_REF_NAME#v}"
|
||||
mike deploy --push "$release_tag"
|
||||
|
||||
# IndexNow key: 0d5d9799b1cc4a39825146388c6781eb
|
||||
# This key must stay in sync across three files:
|
||||
# docs/0d5d9799b1cc4a39825146388c6781eb.txt (key file served at site root)
|
||||
# docs/theme/main.html (indexnow-key meta tag)
|
||||
# this workflow (inject step + notify step below)
|
||||
# Bing/Yandex fetch https://supervision.roboflow.com/<key>.txt to verify ownership.
|
||||
# Do NOT rename or delete the .txt file or change the key string without updating all three.
|
||||
- name: 🌐 Inject GEO root files into gh-pages
|
||||
if: >
|
||||
(github.event_name == 'push' && github.ref == 'refs/heads/develop') ||
|
||||
github.event_name == 'workflow_dispatch' ||
|
||||
(github.event_name == 'push' && github.ref == 'refs/heads/release/latest') ||
|
||||
(github.event_name == 'release' && github.event.action == 'published')
|
||||
run: |
|
||||
cp docs/robots.txt /tmp/robots.txt
|
||||
cp docs/llms.txt /tmp/llms.txt
|
||||
cp docs/llms.full.txt /tmp/llms.full.txt
|
||||
cp docs/llms-100k.txt /tmp/llms-100k.txt
|
||||
cp docs/_headers /tmp/headers.txt
|
||||
cp docs/0d5d9799b1cc4a39825146388c6781eb.txt /tmp/indexnow.txt
|
||||
if [[ "$GITHUB_REF" == "refs/heads/release/latest" ]]; then
|
||||
version_dir="latest"
|
||||
else
|
||||
version_dir=""
|
||||
fi
|
||||
git fetch origin gh-pages
|
||||
git checkout gh-pages
|
||||
cp /tmp/robots.txt robots.txt
|
||||
cp /tmp/llms.txt llms.txt
|
||||
cp /tmp/llms.full.txt llms.full.txt
|
||||
cp /tmp/llms-100k.txt llms-100k.txt
|
||||
cp /tmp/headers.txt _headers
|
||||
cp /tmp/indexnow.txt 0d5d9799b1cc4a39825146388c6781eb.txt
|
||||
if [[ -n "$version_dir" && -f "$version_dir/sitemap.xml" ]]; then
|
||||
cp "$version_dir/sitemap.xml" sitemap.xml
|
||||
gzip -9 -c sitemap.xml > sitemap.xml.gz
|
||||
fi
|
||||
files_to_add=(
|
||||
robots.txt
|
||||
llms.txt
|
||||
llms.full.txt
|
||||
llms-100k.txt
|
||||
_headers
|
||||
0d5d9799b1cc4a39825146388c6781eb.txt
|
||||
)
|
||||
if [[ -f "sitemap.xml" ]]; then
|
||||
files_to_add+=(sitemap.xml)
|
||||
fi
|
||||
if [[ -f "sitemap.xml.gz" ]]; then
|
||||
files_to_add+=(sitemap.xml.gz)
|
||||
fi
|
||||
git add "${files_to_add[@]}"
|
||||
git diff --cached --quiet || git commit -m "chore: update GEO root files"
|
||||
git push origin gh-pages
|
||||
|
||||
- name: 📡 Notify IndexNow
|
||||
if: >
|
||||
(github.event_name == 'push' && github.ref == 'refs/heads/develop') ||
|
||||
github.event_name == 'workflow_dispatch' ||
|
||||
(github.event_name == 'push' && github.ref == 'refs/heads/release/latest')
|
||||
run: |
|
||||
curl -s -o /dev/null -w "%{http_code}" -X POST "https://api.indexnow.org/IndexNow" \
|
||||
-H "Content-Type: application/json; charset=utf-8" \
|
||||
-d '{
|
||||
"host": "supervision.roboflow.com",
|
||||
"key": "0d5d9799b1cc4a39825146388c6781eb",
|
||||
"keyLocation": "https://supervision.roboflow.com/0d5d9799b1cc4a39825146388c6781eb.txt",
|
||||
"urlList": [
|
||||
"https://supervision.roboflow.com/",
|
||||
"https://supervision.roboflow.com/latest/",
|
||||
"https://supervision.roboflow.com/latest/how_to/detect_and_annotate/",
|
||||
"https://supervision.roboflow.com/latest/how_to/track_objects/",
|
||||
"https://supervision.roboflow.com/latest/how_to/detect_small_objects/",
|
||||
"https://supervision.roboflow.com/latest/how_to/filter_detections/",
|
||||
"https://supervision.roboflow.com/latest/how_to/save_detections/",
|
||||
"https://supervision.roboflow.com/latest/how_to/count_in_zone/",
|
||||
"https://supervision.roboflow.com/latest/how_to/benchmark_a_model/",
|
||||
"https://supervision.roboflow.com/latest/how_to/process_datasets/"
|
||||
]
|
||||
}' || true
|
||||
|
||||
@@ -158,5 +158,14 @@ Desktop.ini
|
||||
data/
|
||||
|
||||
# Claude working scratchpad (plans, lessons, ephemeral artefacts)
|
||||
.claude/logs
|
||||
.claude/state/
|
||||
.plans/
|
||||
.reports/
|
||||
.temp/
|
||||
.tmp/
|
||||
_outputs/
|
||||
_resolutions/
|
||||
_reviews/
|
||||
tasks/
|
||||
*.local.md
|
||||
|
||||
@@ -13,11 +13,14 @@ repos:
|
||||
hooks:
|
||||
- id: trailing-whitespace
|
||||
- id: check-yaml
|
||||
exclude: mkdocs.yml
|
||||
args: ["--unsafe"]
|
||||
- id: check-executables-have-shebangs
|
||||
- id: check-json
|
||||
- id: check-toml
|
||||
- id: check-case-conflict
|
||||
- id: check-added-large-files
|
||||
args: ["--maxkb=500", "--enforce-all"]
|
||||
exclude: uv.lock|.*\.ipynb$
|
||||
- id: detect-private-key
|
||||
- id: pretty-format-json
|
||||
exclude: demo.ipynb
|
||||
@@ -26,7 +29,7 @@ repos:
|
||||
- id: mixed-line-ending
|
||||
|
||||
- repo: https://github.com/JoC0de/pre-commit-prettier
|
||||
rev: v3.8.2 # using tag; previously pinned SHA when tags were not persistent
|
||||
rev: v3.8.3 # using tag; previously pinned SHA when tags were not persistent
|
||||
hooks:
|
||||
- id: prettier
|
||||
files: \.(ya?ml|toml)$
|
||||
@@ -44,10 +47,10 @@ repos:
|
||||
- id: validate-pyproject
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.15.10
|
||||
rev: v0.15.12
|
||||
hooks:
|
||||
- id: ruff-check
|
||||
args: [--fix]
|
||||
args: ["--fix"]
|
||||
- id: ruff-format
|
||||
types_or: [python, pyi, jupyter]
|
||||
|
||||
@@ -62,7 +65,7 @@ repos:
|
||||
exclude: ^(docs/changelog\.md|docs/deprecated\.md)$
|
||||
|
||||
- repo: https://github.com/pre-commit/mirrors-mypy
|
||||
rev: v1.20.1
|
||||
rev: v1.20.2
|
||||
hooks:
|
||||
- id: mypy
|
||||
additional_dependencies:
|
||||
|
||||
@@ -228,7 +228,7 @@ Want to learn how to use Supervision? Explore our [how-to guides](https://superv
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/hAWpsIuem10" title="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/a742823d-c158-407d-b30f-063a5d11b4e1" alt="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/hAWpsIuem10" title="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing"><img src="https://github.com/user-attachments/assets/014cffc7-72b3-4c0a-bb89-6de265b2c06b" alt="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/hAWpsIuem10" title="Dwell Time Analysis with Computer Vision | Real-Time Stream Processing"><strong>Dwell Time Analysis with Computer Vision | Real-Time Stream Processing</strong></a>
|
||||
<div><strong>Created: 5 Apr 2024</strong></div>
|
||||
<br/>Learn how to use computer vision to analyze wait times and optimize processes. This tutorial covers object detection, tracking, and calculating time spent in designated zones. Use these techniques to improve customer experience in retail, traffic management, or other scenarios.</p>
|
||||
@@ -236,7 +236,7 @@ Want to learn how to use Supervision? Explore our [how-to guides](https://superv
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/61a444c8-b135-48ce-b979-2a5ab47c5a91" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><img src="https://github.com/user-attachments/assets/b16b8e21-dc6c-4a73-a678-2f7d5d374793" alt="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/uWP6UjDeZvY" title="Speed Estimation & Vehicle Tracking | Computer Vision | Open Source"><strong>Speed Estimation & Vehicle Tracking | Computer Vision | Open Source</strong></a>
|
||||
<div><strong>Created: 11 Jan 2024</strong></div>
|
||||
<br/>Learn how to track and estimate the speed of vehicles using YOLO, ByteTrack, and Roboflow Inference. This comprehensive tutorial covers object detection, multi-object tracking, filtering detections, perspective transformation, speed estimation, visualization improvements, and more.</p>
|
||||
|
||||
@@ -0,0 +1 @@
|
||||
0d5d9799b1cc4a39825146388c6781eb
|
||||
@@ -0,0 +1,6 @@
|
||||
/*
|
||||
Strict-Transport-Security: max-age=31536000; includeSubDomains; preload
|
||||
X-Content-Type-Options: nosniff
|
||||
Referrer-Policy: strict-origin-when-cross-origin
|
||||
Permissions-Policy: camera=(), microphone=(), geolocation=()
|
||||
Content-Security-Policy: default-src 'self'; base-uri 'self'; object-src 'none'; frame-ancestors 'none'; img-src 'self' https: data:; media-src 'self' https: data:; font-src 'self' https: data:; style-src 'self'; script-src 'self'; connect-src 'self' https:;
|
||||
@@ -0,0 +1,27 @@
|
||||
---
|
||||
comments: true
|
||||
description: About Supervision, Roboflow's open-source Python library for building reusable computer vision workflows.
|
||||
---
|
||||
|
||||
# About Supervision
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for building computer vision applications. It gives developers a model-agnostic toolkit for loading predictions, annotating images and video, tracking objects, counting detections in zones, processing datasets, and evaluating model performance.
|
||||
|
||||
The project centers on a unified `Detections` API with converters for supported outputs from Ultralytics, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers such as Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. That common representation lets teams change models without rewriting annotation, filtering, tracking, dataset, or metrics code.
|
||||
|
||||
Supervision is maintained by Roboflow and an open-source contributor community. The library is MIT licensed, developed in public on GitHub, and published on PyPI.
|
||||
|
||||
## Project Links
|
||||
|
||||
- Source code: [github.com/roboflow/supervision](https://github.com/roboflow/supervision)
|
||||
- Package: [pypi.org/project/supervision](https://pypi.org/project/supervision/)
|
||||
- Community: [Roboflow Discord](https://discord.gg/GbfgXGJ8Bk)
|
||||
- Roboflow: [roboflow.com](https://roboflow.com/)
|
||||
|
||||
## Maintainers and Contributors
|
||||
|
||||
Supervision has been shaped by Roboflow engineers and community contributors, including Piotr Skalski, Borda, onuralpszr, Soumik Mandal, and many others. The complete contributor history is available in the GitHub repository.
|
||||
|
||||
## Citation
|
||||
|
||||
If Supervision helps your research or production system, cite the project using the citation block in [llms.txt](https://supervision.roboflow.com/llms.txt) or link to the GitHub repository.
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
description: API reference for supervision's assets module — download sample video and image files for demos, testing, and tutorials.
|
||||
---
|
||||
|
||||
# Assets
|
||||
|
||||
+66
-3
@@ -1,8 +1,31 @@
|
||||
---
|
||||
description: "Full version history of the supervision Python library — release notes, breaking changes, new features, and deprecations for every version."
|
||||
date_modified: 2026-04-23
|
||||
---
|
||||
|
||||
# Changelog
|
||||
|
||||
### 0.28.0 <small>Unreleased</small>
|
||||
### 0.28.0 <small>Apr 30, 2026</small>
|
||||
|
||||
- Changed [#2178](https://github.com/roboflow/supervision/pull/2178): [`sv.Detections.from_inference`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_inference) now supports compressed COCO RLE masks. Inference responses with `rle` or `rle_mask` fields containing a compressed counts string (as produced by `pycocotools`) are decoded directly into binary masks, avoiding a lossy polygon round-trip.
|
||||
- Added [#2159](https://github.com/roboflow/supervision/pull/2159): [`sv.CompactMask`](https://supervision.roboflow.com/develop/detection/compact_mask/#supervision.detection.compact_mask.CompactMask) for memory-efficient mask storage. Masks are stored as crop-region bounding boxes plus RLE-encoded data instead of full-resolution bitmaps, reducing memory by up to 240× for sparse masks. Integrates transparently with `sv.Detections.mask` — filtering, merging, and `area` all work without materialising the full array.
|
||||
|
||||
- Added [#2227](https://github.com/roboflow/supervision/pull/2227): [`sv.CompactMask.resize(new_image_shape)`](https://supervision.roboflow.com/develop/detection/compact_mask/#supervision.detection.compact_mask.CompactMask.resize) rescales all stored crops to match a new image resolution, enabling use across frames or after image resizing pipelines.
|
||||
|
||||
- Added [#2178](https://github.com/roboflow/supervision/pull/2178): [`sv.Detections.from_inference`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_inference) now supports compressed COCO RLE masks. Inference responses with `rle` or `rle_mask` fields containing a compressed counts string (as produced by `pycocotools`) are decoded directly into binary masks, avoiding a lossy polygon round-trip.
|
||||
|
||||
- Added [#2004](https://github.com/roboflow/supervision/pull/2004): [`sv.Color.from_hex`](https://supervision.roboflow.com/latest/utils/draw/#supervision.draw.color.Color.from_hex) now accepts 8-digit hexadecimal RGBA codes (e.g. `#ff00ff80`). [`Color.as_hex()`](https://supervision.roboflow.com/latest/utils/draw/#supervision.draw.color.Color.as_hex) serialises back, including alpha when not fully opaque. New utility functions `sv.hex_to_rgba`, `sv.rgba_to_hex`, and `sv.is_valid_hex` are exported at the top level.
|
||||
|
||||
- Added [#709](https://github.com/roboflow/supervision/pull/709): [`sv.BlurAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BlurAnnotator) and [`sv.PixelateAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.PixelateAnnotator) now support dynamic sizing. When `kernel_size=None` or `pixel_size=None` (the new default), the size is computed per detection as a fraction of the shorter bounding-box dimension, producing consistent visual results across objects of different sizes.
|
||||
|
||||
- Added [#2186](https://github.com/roboflow/supervision/pull/2186): [`sv.InferenceSlicer`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) now emits a warning when detections returned by the callback fall outside the tile boundaries, helping catch coordinate-system bugs in custom callbacks.
|
||||
|
||||
- Added [#2103](https://github.com/roboflow/supervision/pull/2103), [#2152](https://github.com/roboflow/supervision/pull/2152): New [`sv.Detections.from_sam3()`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_sam3) classmethod parses SAM3 PCS (text-prompted) and PVS (visual-prompted video segmentation) response formats into a standard `sv.Detections`, both from the local `inference` package and from Roboflow-hosted server responses.
|
||||
|
||||
- Added [#2154](https://github.com/roboflow/supervision/pull/2154): The library now uses Python's `logging` module instead of `print` for diagnostic output. Messages are emitted under the `supervision` logger so applications can capture, filter, or silence them through standard `logging` configuration.
|
||||
|
||||
- Added [#932](https://github.com/roboflow/supervision/pull/932): [`sv.ImageAssets`](https://supervision.roboflow.com/latest/assets/) for downloading sample images alongside existing video assets, useful for examples and tutorials.
|
||||
|
||||
- Changed [#2169](https://github.com/roboflow/supervision/pull/2169): [`sv.MeanAveragePrecisionResult`](https://supervision.roboflow.com/latest/metrics/mean_average_precision/) and related metric arrays (`mAP_scores`, `ap_per_class`, `iou_thresholds`, precision/recall) are now `float32` instead of `float64`. Reduces memory and speeds up computation; numerical results may differ in the last few digits.
|
||||
|
||||
- Changed [#2178](https://github.com/roboflow/supervision/pull/2178): [`sv.rle_to_mask`](https://supervision.roboflow.com/latest/detection/utils/converters/#supervision.detection.utils.converters.rle_to_mask) and [`sv.mask_to_rle`](https://supervision.roboflow.com/latest/detection/utils/converters/#supervision.detection.utils.converters.mask_to_rle) moved to `supervision.detection.utils.converters`. The old import path `supervision.dataset.utils` continues to work but is deprecated.
|
||||
|
||||
@@ -10,6 +33,46 @@
|
||||
|
||||
- Fixed [#2210](https://github.com/roboflow/supervision/pull/2210): [`sv.VideoInfo.fps`](https://supervision.roboflow.com/latest/utils/video/#supervision.utils.video.VideoInfo) now returns a `float` instead of a truncated `int`. Previously, frame rates like 23.976, 29.97, and 59.94 were silently truncated, causing frame-timing drift that accumulates over long videos. The type of `VideoInfo.fps` has changed from `int` to `float`; callers that pass `fps` to APIs requiring an integer (such as `deque(maxlen=...)` or `TraceAnnotator(trace_length=...)`) should wrap the value with `int()`.
|
||||
|
||||
- Fixed [#2209](https://github.com/roboflow/supervision/pull/2209): [`sv.Detections.is_empty()`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.is_empty) now returns `True` for detections filtered down to zero rows, even when `tracker_id` is an empty array. Previously this case incorrectly returned `False`.
|
||||
|
||||
- Fixed [#2199](https://github.com/roboflow/supervision/pull/2199): [`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) now correctly slices numpy array values in `custom_data` per row. Previously the full array was written for every detection.
|
||||
|
||||
- Fixed [#2216](https://github.com/roboflow/supervision/pull/2216): [`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and [`sv.JSONSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.json_sink.JSONSink) now slice plain Python `list` and `tuple` values in `custom_data` per detection row. Lists and tuples matching the detection count are indexed per row, consistent with `np.ndarray` behavior.
|
||||
|
||||
- Fixed [#2217](https://github.com/roboflow/supervision/pull/2217): [`sv.TraceAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.TraceAnnotator) no longer crashes in `smooth` mode when a tracker remains stationary. Duplicate consecutive points caused `splprep` to fail; the annotator now deduplicates anchor points and falls back to a raw polyline when fewer than 4 unique points are available.
|
||||
|
||||
- Fixed [#2218](https://github.com/roboflow/supervision/pull/2218): [`load_coco_annotations`](https://supervision.roboflow.com/latest/datasets/core/) now rejects COCO annotations whose `file_name` escapes the images directory via `../` traversal or absolute paths, preventing path-traversal attacks from malicious annotation files.
|
||||
|
||||
- Fixed [#2187](https://github.com/roboflow/supervision/pull/2187): Extreme memory usage when loading OBB (oriented bounding box) datasets, caused by allocating full-image masks for each rotated box, has been resolved.
|
||||
|
||||
- Fixed [#2188](https://github.com/roboflow/supervision/pull/2188): [`sv.KeyPoints`](https://supervision.roboflow.com/latest/keypoint/core/#supervision.key_points.core.KeyPoints) boolean mask indexing now works correctly when all instances have the same keypoint count (uniform-count selection).
|
||||
|
||||
- Fixed [#2185](https://github.com/roboflow/supervision/pull/2185): [`sv.DetectionDataset.as_coco()`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.as_coco) now preserves `area` and `iscrowd` fields instead of silently dropping them in the round-trip.
|
||||
|
||||
- Fixed [#1746](https://github.com/roboflow/supervision/pull/1746): Precision loss when converting annotations with `force_mask=True` in dataset format converters.
|
||||
|
||||
- Fixed [#1991](https://github.com/roboflow/supervision/pull/1991): [`sv.PolygonZone`](https://supervision.roboflow.com/latest/detection/tools/polygon_zone/) no longer double-counts the same object when multiple zones overlap. Detection bounding boxes were incorrectly clipped to each zone's ROI before anchor computation, causing the same detection to appear at a different anchor point in each zone; anchor is now computed from the original bounding box so containment is independent per zone.
|
||||
|
||||
- Fixed [#1868](https://github.com/roboflow/supervision/pull/1868): [`sv.LineZone`](https://supervision.roboflow.com/latest/detection/tools/line_zone/) no longer mis-attributes crossings when a tracker reuses the same `tracker_id` across different classes. Class-aware bookkeeping prevents a new object from inheriting another class's prior crossing state.
|
||||
|
||||
- Fixed [#2022](https://github.com/roboflow/supervision/pull/2022): [`sv.process_video`](https://supervision.roboflow.com/latest/utils/video/#supervision.utils.video.process_video) now raises immediately when the user callback throws, instead of silently swallowing the exception and hanging until the writer is flushed.
|
||||
|
||||
- Fixed [#2156](https://github.com/roboflow/supervision/pull/2156): [`sv.DetectionDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset) now populates `data["class_name"]` on every loaded annotation, matching what model connectors produce. Downstream code can rely on `class_name` being present whether detections come from a dataset or a model.
|
||||
|
||||
- Fixed [#1364](https://github.com/roboflow/supervision/pull/1364): [`sv.ByteTrack`](https://supervision.roboflow.com/latest/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) now preserves externally assigned `tracker_id` values instead of overwriting them with internal ids on the first update.
|
||||
|
||||
- Fixed [#1853](https://github.com/roboflow/supervision/pull/1853): [`sv.ConfusionMatrix`](https://supervision.roboflow.com/latest/detection/metrics/#supervision.metrics.detection.ConfusionMatrix) `evaluate_detection_batch` now matches predictions to ground truth correctly when multiple detections fall on the same target. Previously, double-counting inflated false-positive and false-negative counts.
|
||||
|
||||
- Fixed [#2136](https://github.com/roboflow/supervision/pull/2136): [`sv.MeanAverageRecall`](https://supervision.roboflow.com/latest/metrics/mean_average_recall/) now computes mAR@K using the top-K detections per image, matching the COCO definition. Previous values were inflated relative to `pycocotools`.
|
||||
|
||||
- Fixed [#1086](https://github.com/roboflow/supervision/pull/1086), [#265](https://github.com/roboflow/supervision/pull/265): COCO export and `force_masks` behaviour are now consistent across dataset formats. Empty polygons no longer raise during `as_coco`, and `force_masks=True` produces masks regardless of source format.
|
||||
|
||||
- Deprecated [#2215](https://github.com/roboflow/supervision/pull/2215): [`sv.ByteTrack`](https://supervision.roboflow.com/latest/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) is deprecated in favour of `ByteTrackTracker` from the external [`trackers`](https://pypi.org/project/trackers/) package (`pip install trackers`). The update method is renamed from `update_with_detections()` to `update()`. Removal planned for `supervision-0.30.0`.
|
||||
|
||||
- Deprecated [#2214](https://github.com/roboflow/supervision/pull/2214): `supervision.keypoint` module is deprecated; use `supervision.key_points` instead. `create_tiles` in `supervision.utils.image`, `ensure_cv2_image_for_processing` in `supervision.utils.conversion`, and keypoint validation utilities in `supervision.validators` are deprecated. The `LMM` enum (use `VLM`) and `from_lmm` method (use `from_vlm`) were deprecated in 0.26.0; this release migrates their deprecation mechanism to `pydeprecate`.
|
||||
|
||||
- Deprecated: `normalized_xyxy` argument in [`sv.denormalize_boxes`](https://supervision.roboflow.com/latest/detection/utils/boxes/#supervision.detection.utils.boxes.denormalize_boxes) renamed to `xyxy`. Passing `normalized_xyxy=` now emits a `FutureWarning`; support will be removed in `supervision-0.30.0`.
|
||||
|
||||
### 0.27.0 <small>Nov 16, 2025</small>
|
||||
|
||||
- Added [#2008](https://github.com/roboflow/supervision/pull/2008): [`sv.filter_segments_by_distance`](https://supervision.roboflow.com/0.27.0/detection/utils/masks/#supervision.detection.utils.masks.filter_segments_by_distance) to keep the largest connected component and nearby components within an absolute or relative distance threshold. Useful for cleaning segmentation predictions from models such as SAM, SAM2, YOLO segmentation, and RF-DETR segmentation.
|
||||
@@ -303,7 +366,7 @@ sv.process_video(
|
||||
|
||||
- Added `as_detections` method to [`KeyPoints`](https://supervision.roboflow.com/0.25.0/keypoint/core/#supervision.keypoint.core.KeyPoints) that converts `KeyPoints` to `Detections`. ([#1658](https://github.com/roboflow/supervision/pull/1658))
|
||||
|
||||
- Added a new video to `supervision[assets]`. ([#1657](https://github.com/roboflow/supervision/pull/1657))
|
||||
- Added a new video to the `supervision.assets` download catalog. ([#1657](https://github.com/roboflow/supervision/pull/1657))
|
||||
|
||||
```python
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
|
||||
@@ -0,0 +1,29 @@
|
||||
---
|
||||
comments: true
|
||||
description: Contact and support channels for Supervision documentation, bugs, feature requests, security reports, and community help.
|
||||
---
|
||||
|
||||
# Contact
|
||||
|
||||
Use the channel that matches the kind of request you have.
|
||||
|
||||
## Bugs and Feature Requests
|
||||
|
||||
Open a GitHub issue for reproducible bugs, API requests, documentation fixes, and feature proposals:
|
||||
|
||||
[github.com/roboflow/supervision/issues](https://github.com/roboflow/supervision/issues)
|
||||
|
||||
## Community Support
|
||||
|
||||
Join the Roboflow Discord for community questions, examples, and implementation discussion:
|
||||
|
||||
[discord.gg/GbfgXGJ8Bk](https://discord.gg/GbfgXGJ8Bk)
|
||||
|
||||
## Package and Source
|
||||
|
||||
- PyPI package: [pypi.org/project/supervision](https://pypi.org/project/supervision/)
|
||||
- GitHub repository: [github.com/roboflow/supervision](https://github.com/roboflow/supervision)
|
||||
|
||||
## Security Reports
|
||||
|
||||
For security-sensitive reports, avoid posting public exploit details in an issue. Use GitHub's private vulnerability reporting flow for the repository when available, or contact Roboflow through the security and support channels listed on [roboflow.com](https://roboflow.com/).
|
||||
@@ -1,6 +1,7 @@
|
||||
---
|
||||
template: cookbooks.html
|
||||
comments: true
|
||||
description: Collection of practical computer vision cookbooks — object tracking, zero-shot detection, SAHI small object detection, occupancy analytics, and more.
|
||||
hide:
|
||||
- navigation
|
||||
- toc
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
description: API reference for supervision's DetectionDataset and ClassificationDataset — load, merge, split, and convert datasets in YOLO, COCO, and VOC formats.
|
||||
---
|
||||
|
||||
# Datasets
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
description: API reference for supervision's annotator classes — draw bounding boxes, masks, labels, tracks, and heatmaps on images with one method call.
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
@@ -0,0 +1,7 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# CompactMask
|
||||
|
||||
:::supervision.detection.compact_mask.CompactMask
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
description: API reference for supervision's Detections class — the core data structure for bounding boxes, masks, confidence scores, and tracker IDs.
|
||||
---
|
||||
|
||||
# Detections
|
||||
|
||||
+58
@@ -0,0 +1,58 @@
|
||||
---
|
||||
comments: true
|
||||
description: Frequently asked questions about installing Supervision, supported computer vision models, datasets, tracking, metrics, and licensing.
|
||||
---
|
||||
|
||||
# Frequently Asked Questions
|
||||
|
||||
## What is Supervision?
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified `Detections` class with converters for supported object detection, segmentation, and VLM outputs.
|
||||
|
||||
## How do I install Supervision?
|
||||
|
||||
Install the base package with:
|
||||
|
||||
```bash
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
Use the `metrics` extra when you need optional metric dependencies:
|
||||
|
||||
```bash
|
||||
pip install "supervision[metrics]"
|
||||
```
|
||||
|
||||
Sample asset utilities are part of the base package under `supervision.assets`.
|
||||
|
||||
## Which object detection models work with Supervision?
|
||||
|
||||
Supervision is model agnostic. `sv.Detections` includes converters for Ultralytics YOLO, Roboflow Inference, Hugging Face Transformers outputs, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers including Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. Keypoint outputs have separate `sv.KeyPoints` converters, including MediaPipe.
|
||||
|
||||
## What can I do with Supervision?
|
||||
|
||||
You can annotate images and video, filter detections, track objects, count objects in zones or across lines, load and convert datasets, evaluate models with detection metrics, and export predictions for downstream analysis.
|
||||
|
||||
## How do I track objects across video frames?
|
||||
|
||||
Assign persistent tracker IDs before visualization. The built-in `sv.ByteTrack` wrapper accepts `Detections` through `update_with_detections()`. After tracking, combine the output with annotators such as `sv.TraceAnnotator`, `sv.BoxAnnotator`, and `sv.LabelAnnotator`.
|
||||
|
||||
## What dataset formats does Supervision support?
|
||||
|
||||
For detection datasets, Supervision supports YOLO, COCO JSON, and Pascal VOC. Use `DetectionDataset.from_yolo()`, `DetectionDataset.from_coco()`, or `DetectionDataset.from_pascal_voc()` to load datasets, and the matching `as_*` methods to export them.
|
||||
|
||||
## How do I count objects in a zone?
|
||||
|
||||
Use `sv.PolygonZone` for arbitrary polygon regions and `sv.LineZone` for line-crossing counts. Line crossing requires `detections.tracker_id`, so run a tracker before calling the line zone trigger.
|
||||
|
||||
## How do I benchmark a model?
|
||||
|
||||
Use `supervision.metrics.mean_average_precision.MeanAveragePrecision` for mAP and `sv.ConfusionMatrix` for confusion matrices. Accumulate predictions and ground-truth `Detections`, then call `compute()` to calculate metrics.
|
||||
|
||||
## Is Supervision free to use?
|
||||
|
||||
Yes. Supervision is free and open source under the MIT license.
|
||||
|
||||
## Where is the source code?
|
||||
|
||||
The source code is available at [github.com/roboflow/supervision](https://github.com/roboflow/supervision).
|
||||
@@ -1,5 +1,11 @@
|
||||
---
|
||||
comments: true
|
||||
description: Benchmark object detection models with supervision — compute mAP, confusion matrix, and per-class metrics to compare model performance.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
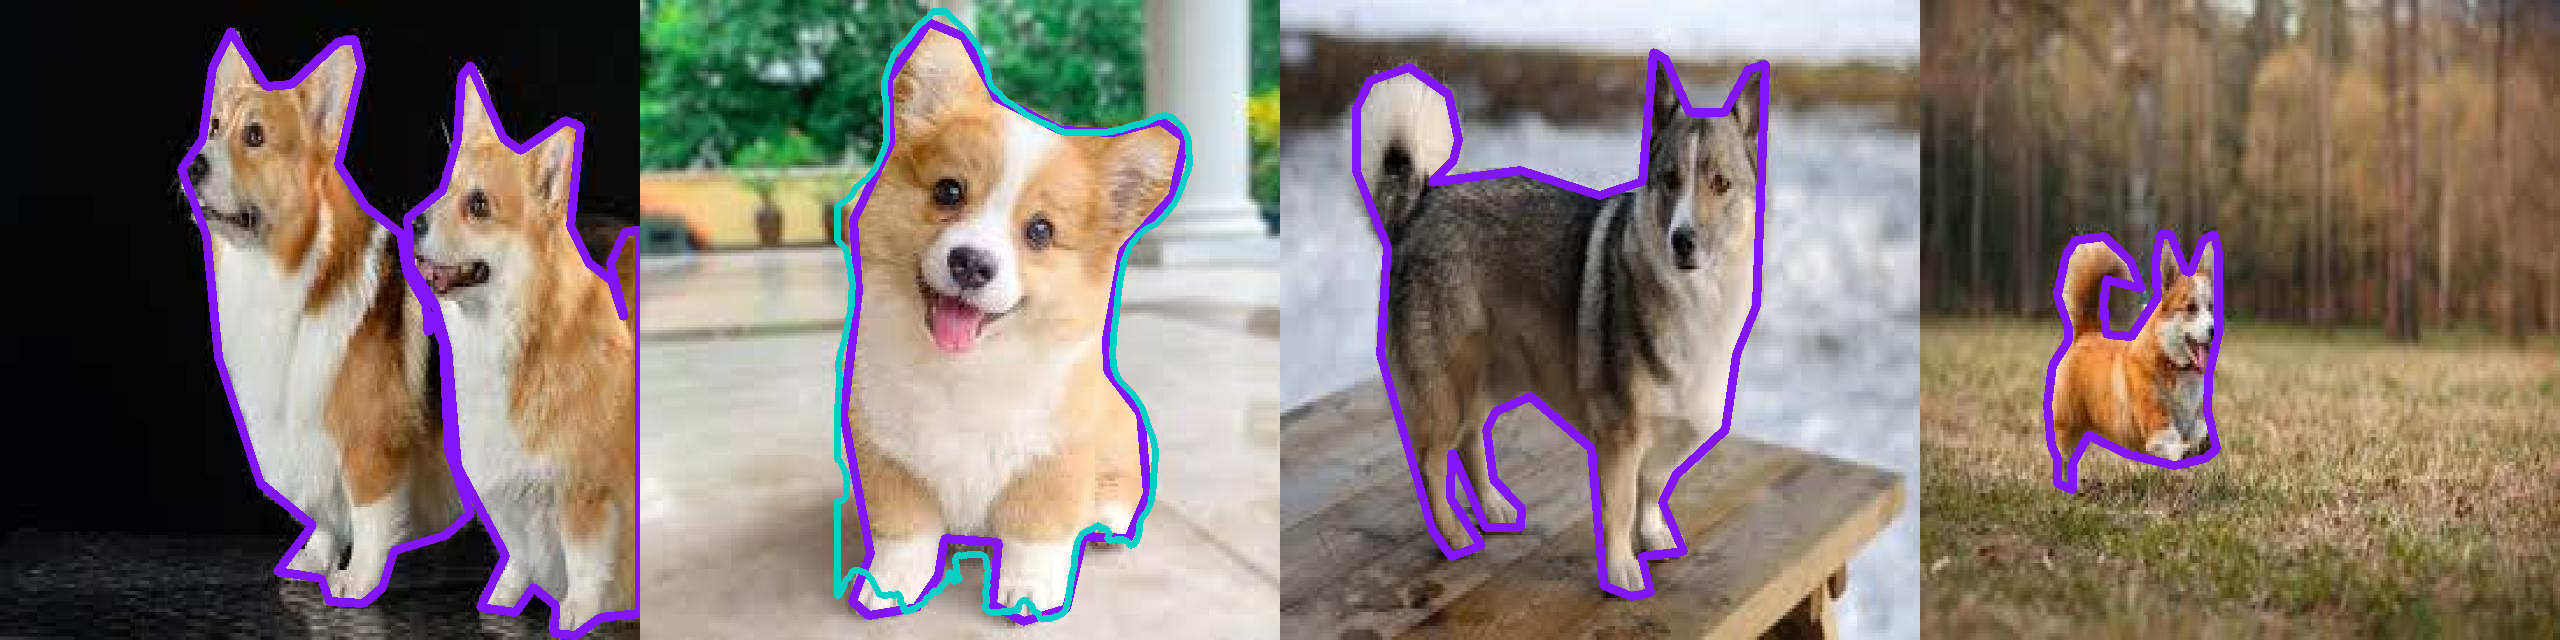
|
||||
@@ -74,6 +80,8 @@ This will create a folder called `Corgi-v2-4` with the dataset in the current wo
|
||||
|
||||
Let's load a model.
|
||||
|
||||
Select and instantiate the detection or segmentation model you want to benchmark. Supervision works with Roboflow Inference for both local and cloud-deployed models, as well as Ultralytics YOLO checkpoints. Choose the tab below that matches your preferred framework, then pass images to the loaded model during the evaluation loop.
|
||||
|
||||
=== "Inference, Local"
|
||||
|
||||
Roboflow supports a range of state-of-the-art [pre-trained models](https://inference.roboflow.com/quickstart/aliases/) for object detection, instance segmentation, and pose tracking. You don't even need an API key!
|
||||
@@ -442,3 +450,25 @@ A condensed version of this guide is also available as a [Colab Notebook](https:
|
||||
For more details, be sure to check out our [documentation](https://supervision.roboflow.com/latest/) and join our community discussions. If you find any issues, please let us know on [GitHub](https://github.com/roboflow/supervision/issues).
|
||||
|
||||
Best of luck with your benchmarking!
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I benchmark a model with supervision?
|
||||
|
||||
Use `supervision.metrics.mean_average_precision.MeanAveragePrecision` — accumulate prediction and ground-truth `Detections` with `update(...)` and then call `compute()`. For confusion matrices, use `sv.ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes)`.
|
||||
|
||||
### What IoU thresholds does MeanAveragePrecision use?
|
||||
|
||||
It computes mAP over IoU thresholds from 0.50 to 0.95 in steps of 0.05 (mAP@50:95), plus mAP@50 and mAP@75 individually.
|
||||
|
||||
### Can I benchmark segmentation models?
|
||||
|
||||
Yes, if you want to evaluate their bounding boxes. Convert model outputs to `Detections` and pass them to `MeanAveragePrecision.update(...)`; the current mAP path prepares COCO-style bounding boxes from `detections.xyxy`.
|
||||
|
||||
### What is a ConfusionMatrix and how do I use it?
|
||||
|
||||
`sv.ConfusionMatrix` visualizes true positives, false positives, and false negatives per class. Create one with `sv.ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes, conf_threshold=0.5, iou_threshold=0.5)`, then call `metric.plot()` to render a heatmap.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,3 +1,13 @@
|
||||
---
|
||||
comments: true
|
||||
description: Count objects entering a polygon zone in images and video using supervision's PolygonZone — measure throughput and density in any region.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
With supervision, you can count the number of objects in a zone in an image or video. In this guide, we will show how to count the number of cars in a traffic video.
|
||||
|
||||
[View the notebook that accompanies this tutorial](https://github.com/roboflow/notebooks/blob/main/notebooks/how-to-use-polygonzone-annotate-and-supervision.ipynb).
|
||||
@@ -14,6 +24,8 @@ download_assets(VideoAssets.VEHICLES_2)
|
||||
|
||||
First, we need to initialize a model. Let's use a YOLOv8 model with the default COCO checkpoint. We also need to load a video on which to run inference.
|
||||
|
||||
Create a YOLO model instance and load the source video using supervision's `VideoInfo` helper. The model will process each frame during inference, while `VideoInfo` extracts resolution and frame-rate metadata needed by the polygon zone annotator. A shared color palette ensures consistent zone coloring throughout the output video.
|
||||
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
@@ -65,6 +77,8 @@ polygons = [
|
||||
|
||||
With the coordinates of the zones to draw ready, we can set up our zones:
|
||||
|
||||
Instantiate a `PolygonZone` for each polygon array, pairing it with a `PolygonZoneAnnotator` for visual overlay and a `BoxAnnotator` for drawing detection boxes. Each zone will later trigger on incoming detections to determine which objects fall inside its boundaries, enabling per-zone counting in the inference callback.
|
||||
|
||||
```python
|
||||
zones = [
|
||||
sv.PolygonZone(polygon=polygon, frame_resolution_wh=video_info.resolution_wh)
|
||||
@@ -123,3 +137,21 @@ Here is an example of inference run on the video:
|
||||
<video width="100%" loop muted autoplay>
|
||||
<source src="https://blog.roboflow.com/content/media/2023/03/trim-counting.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I count objects in a zone with supervision?
|
||||
|
||||
Create `sv.PolygonZone` with a polygon defining your region. Call `zone.trigger(detections)` on each frame — it returns a mask of detections inside the zone.
|
||||
|
||||
### Can I count objects crossing a line instead of entering a zone?
|
||||
|
||||
Yes. Use `sv.LineZone` — define a start and end point. `zone.trigger(detections)` returns a tuple of two boolean arrays, `(crossed_in, crossed_out)`, indicating which detections crossed the line in each direction. `LineZone` requires `detections.tracker_id`; run a tracker first so the same object can be matched across frames.
|
||||
|
||||
### Can I combine zone counting with tracking?
|
||||
|
||||
Yes. You can pass tracker IDs from `sv.ByteTrack` alongside your detections, but `sv.PolygonZone` still evaluates the zone on each frame and reports which objects are currently inside it. If you want to count each object only once when it first enters the zone, maintain a set of seen `tracker_id` values after filtering detections with `zone.trigger(detections)`, or use a dedicated entry/crossing counting tool such as `sv.LineZone` when it better matches your use case.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,5 +1,14 @@
|
||||
---
|
||||
comments: true
|
||||
description: Learn to load model predictions, create Detections objects, and annotate images with bounding boxes, labels, and masks using supervision.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
- name: Borda
|
||||
role: Open Source Engineer, Roboflow
|
||||
github: https://github.com/borda
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
# Detect and Annotate
|
||||
@@ -19,6 +28,8 @@ source image.
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model.
|
||||
|
||||
To run inference, initialize your chosen model and pass the source image to its predict or infer method. Supervision supports Roboflow Inference, Ultralytics YOLO, and Hugging Face Transformers -- select the tab matching your framework. The result is a framework-specific object you will convert to a `Detections` instance in the next step.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
@@ -68,6 +79,8 @@ model.
|
||||
|
||||
Now that we have predictions from a model, we can load them into Supervision.
|
||||
|
||||
Each supported framework has a dedicated class method on `sv.Detections` that converts raw model output into a unified Supervision object. Call `from_inference`, `from_ultralytics`, or `from_transformers` depending on the package you used for inference. This normalization step ensures all downstream annotators and filters work identically regardless of the source model.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
We can do so using the [`sv.Detections.from_inference`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_inference) method, which accepts model results from both detection and segmentation models.
|
||||
@@ -138,6 +151,8 @@ You can load predictions from other computer vision frameworks and libraries usi
|
||||
|
||||
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator) and [`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator) classes.
|
||||
|
||||
To draw bounding boxes and class labels on your image, create a `BoxAnnotator` and a `LabelAnnotator`, then call their `annotate` methods in sequence. Each annotator returns the modified image, so you can chain multiple annotators together. The result is a single NumPy array with all visual overlays rendered and ready for display or saving.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="10-16" }
|
||||
@@ -420,3 +435,26 @@ that will allow you to draw masks instead of boxes.
|
||||
```
|
||||
|
||||
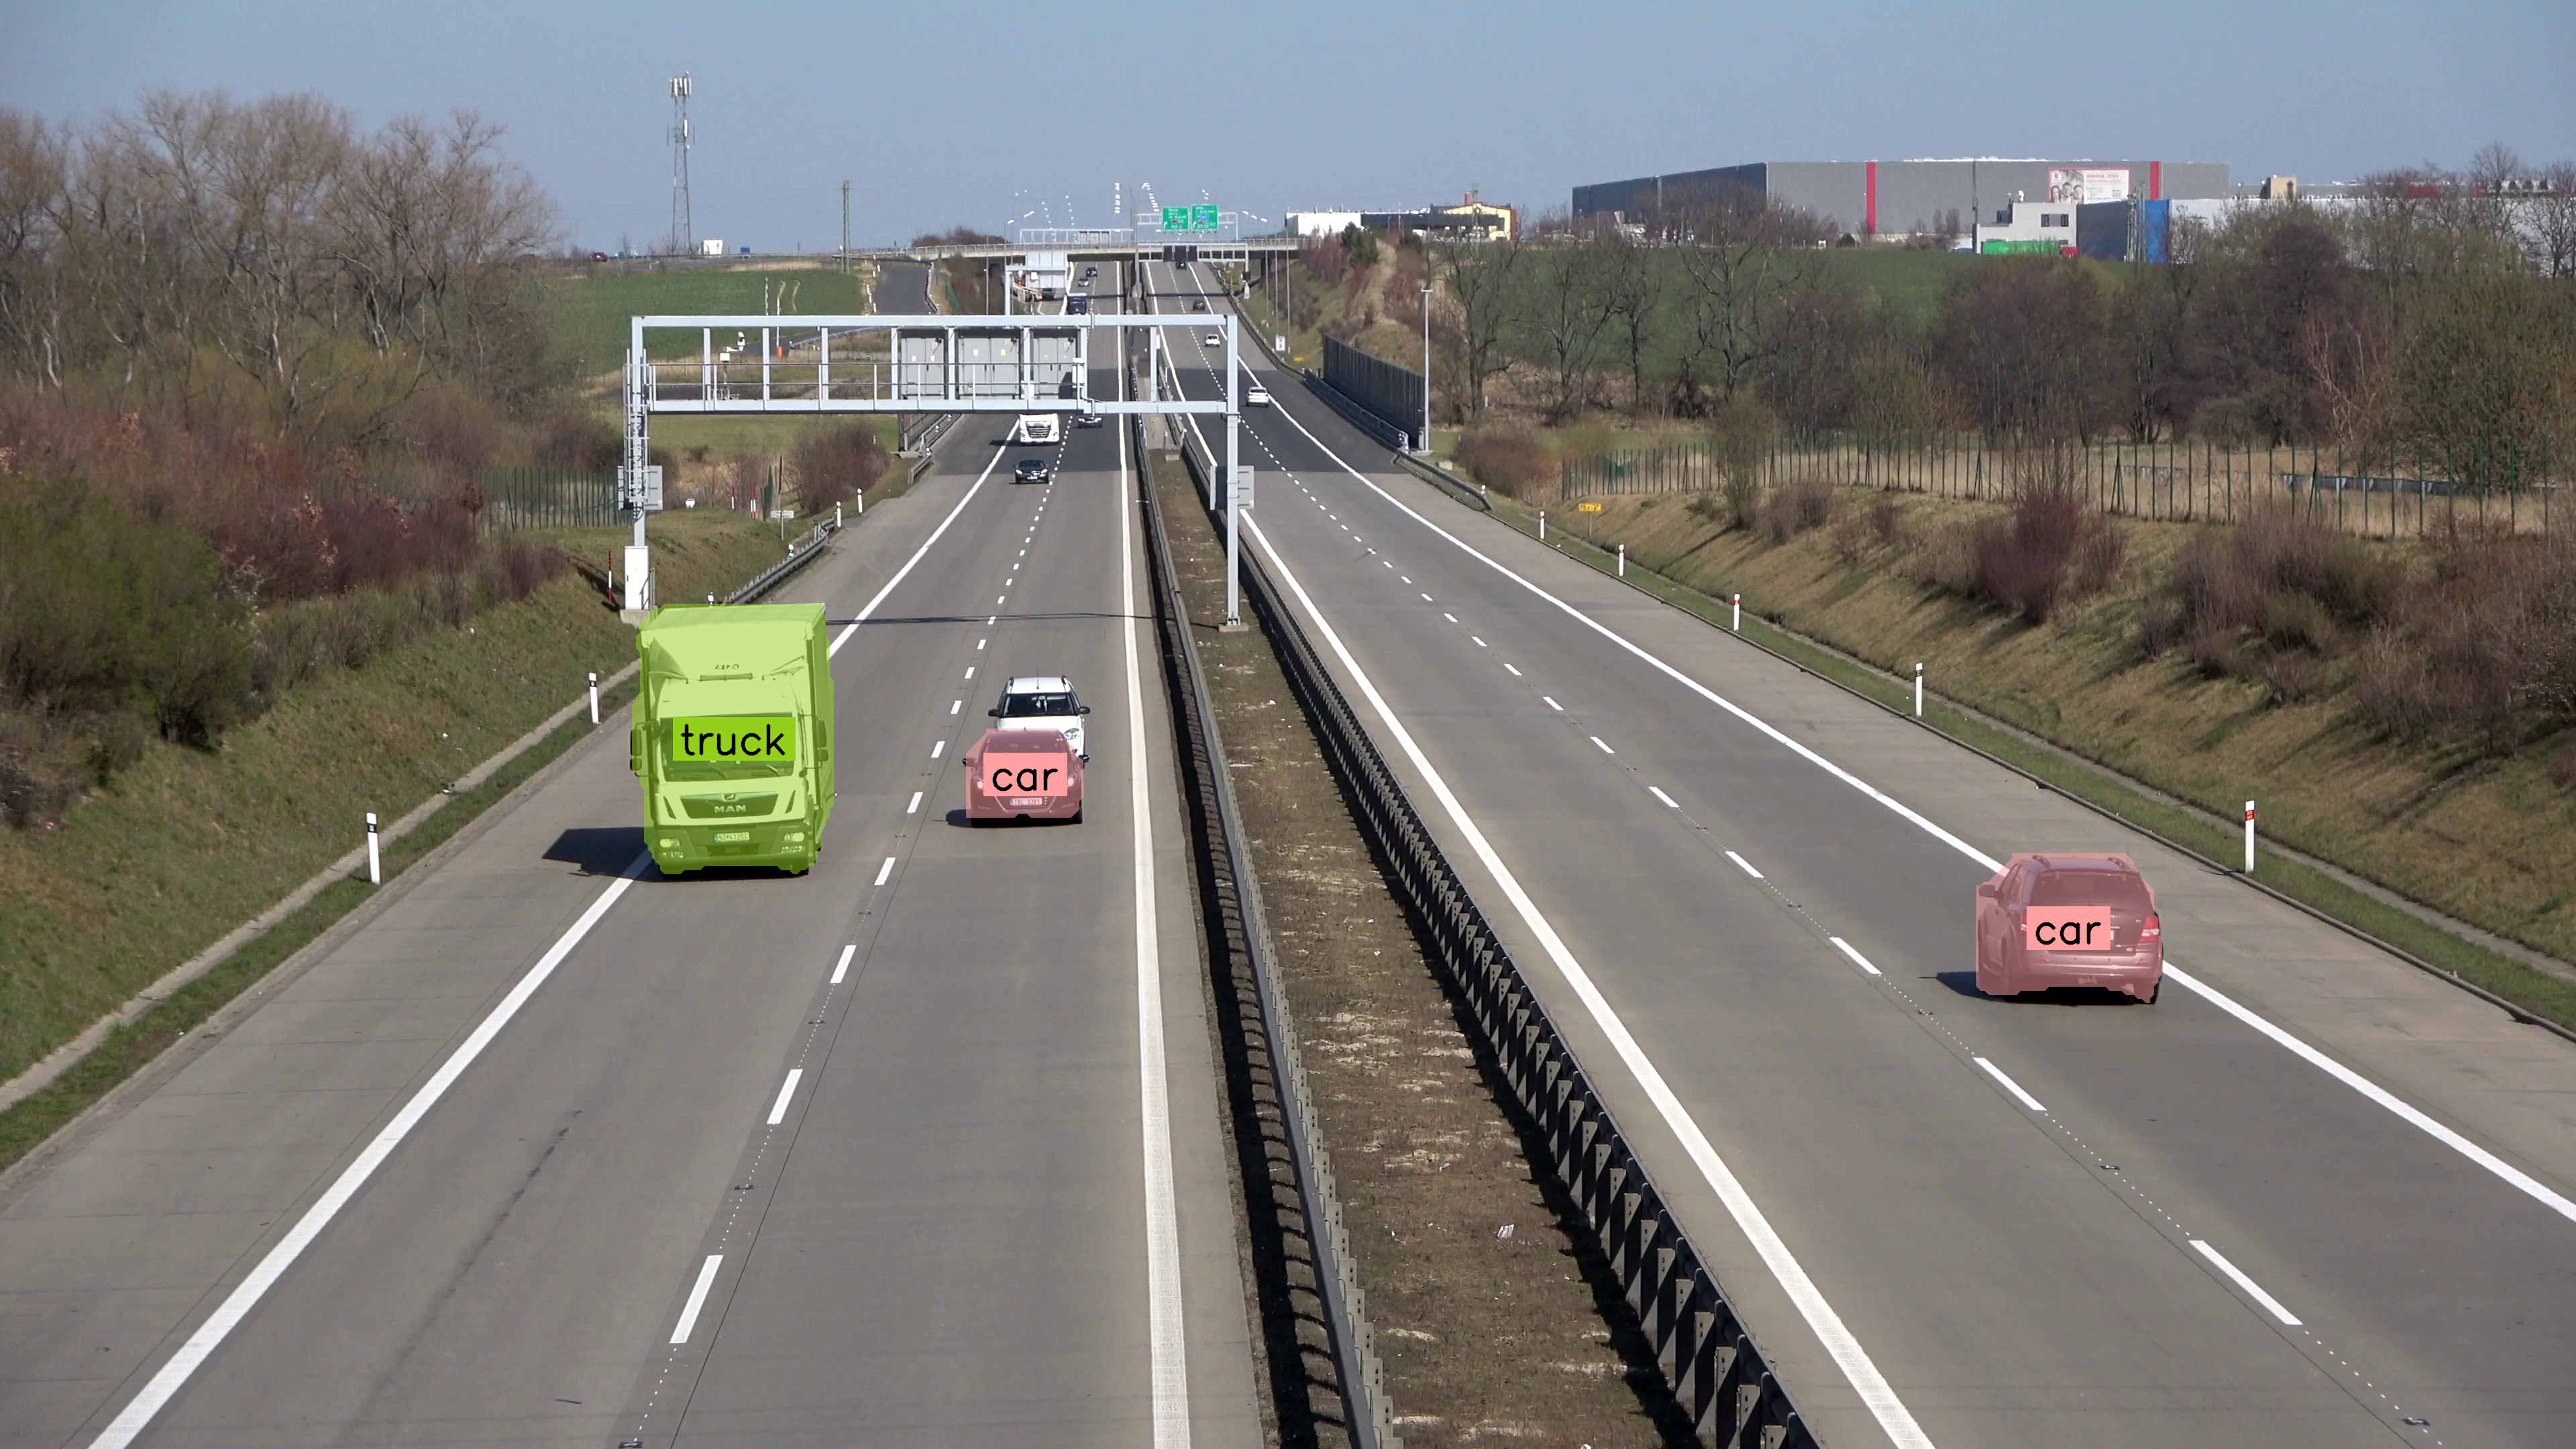
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I detect and annotate objects with supervision?
|
||||
|
||||
Pass any model's output to `sv.Detections.from_<model>()` to create a unified `Detections` object. Then pass it to `sv.BoxAnnotator` or `sv.MaskAnnotator` to draw predictions on an image.
|
||||
|
||||
### Can I annotate both bounding boxes and masks at the same time?
|
||||
|
||||
Yes. Chain annotators: first draw boxes with `BoxAnnotator`, then overlay masks with `MaskAnnotator` on the same scene.
|
||||
|
||||
### How do I label detections with class names?
|
||||
|
||||
Use `sv.LabelAnnotator` and pass custom text with the `labels` parameter. If a connector provides class names, they are stored in `detections["class_name"]` / `detections.data["class_name"]`; when `labels` is omitted, `LabelAnnotator` uses class names first, then class IDs, then detection indices.
|
||||
|
||||
### Can I use supervision with Hugging Face models?
|
||||
|
||||
Yes. `sv.Detections.from_transformers()` accepts supported Hugging Face object detection and segmentation outputs. Vision-language model outputs are handled through `sv.Detections.from_vlm(...)`, for example with `sv.VLM.FLORENCE_2` or `sv.VLM.PALIGEMMA`.
|
||||
|
||||
## Authors
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
- [Borda](https://github.com/borda) — Open Source Engineer, Roboflow
|
||||
|
||||
@@ -1,5 +1,11 @@
|
||||
---
|
||||
comments: true
|
||||
description: Detect small objects in images by applying SAHI inference slicing with supervision's InferenceSlicer — improve recall for tiny targets.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
# Detect Small Objects
|
||||
@@ -19,6 +25,8 @@ with the [Inference](https://github.com/roboflow/inference),
|
||||
Small object detection in high-resolution images presents challenges due to the objects'
|
||||
size relative to the image resolution.
|
||||
|
||||
Running a standard detection model on the full image establishes a baseline for comparison. Load your chosen model, pass the image through it, and convert the results into a `Detections` object. This baseline reveals how many small objects the model misses at native resolution, motivating the sliced inference approach shown later.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
@@ -328,3 +336,21 @@ objects within each, and aggregating the results.
|
||||
```
|
||||
|
||||
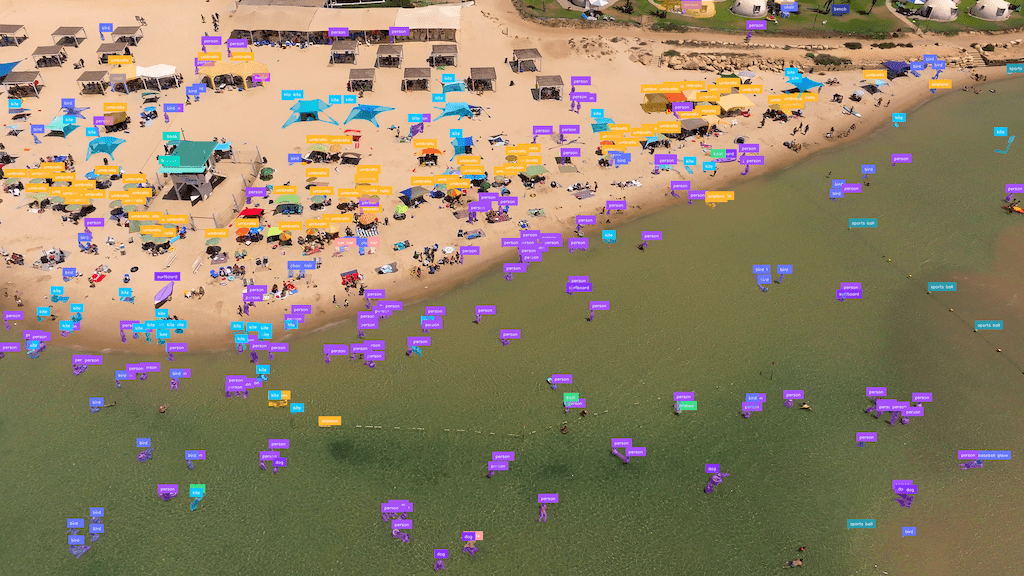
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I detect small objects with supervision?
|
||||
|
||||
Use `sv.InferenceSlicer` to split a high-resolution image into overlapping tiles, run detection on each tile, and merge results with non-maximum suppression. This dramatically improves recall for tiny targets.
|
||||
|
||||
### What overlap should I use between tiles?
|
||||
|
||||
`InferenceSlicer` takes overlap in pixels via `overlap_wh`, not as a percentage. The default is `100` pixels in both directions. Increase `overlap_wh` when objects are close to the tile size or often appear on tile boundaries, and decrease it when speed is more important.
|
||||
|
||||
### Can I use InferenceSlicer with any detection model?
|
||||
|
||||
Yes. Wrap any model or converter path that can produce `sv.Detections` in a callback, pass that callback to `sv.InferenceSlicer(callback=...)`, and then call the slicer with your image.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,5 +1,11 @@
|
||||
---
|
||||
comments: true
|
||||
description: Filter and query detection results by class, confidence, or spatial overlap using supervision's Detections API — clean predictions in one line.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
# Filter Detections
|
||||
@@ -312,3 +318,29 @@ zone. In the example below you can see how to filter out all detections located
|
||||
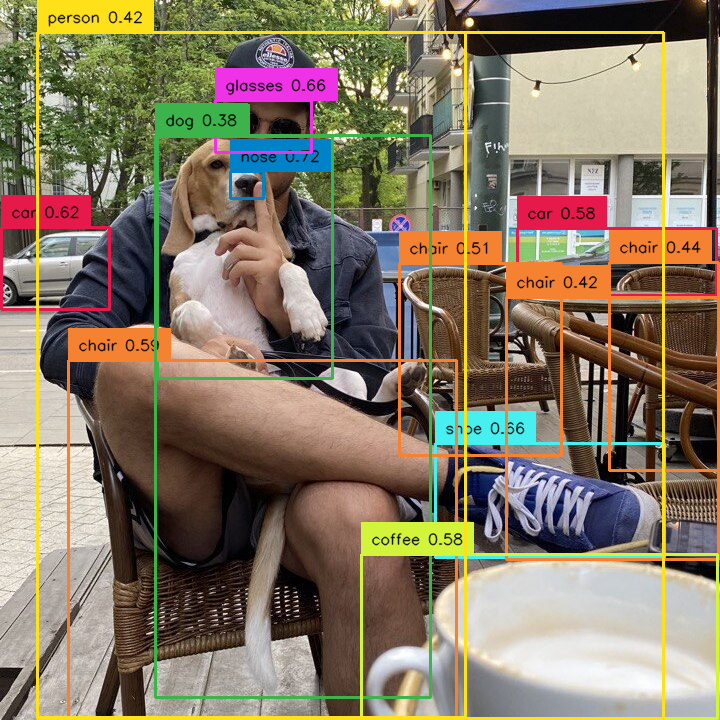{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I filter detections by class in supervision?
|
||||
|
||||
Use NumPy-style boolean indexing: `detections[detections.class_id == 0]` for class 0. Combine with `&` or `|` for multiple conditions.
|
||||
|
||||
### How do I filter by confidence threshold?
|
||||
|
||||
`detections[detections.confidence > 0.5]` returns only detections above the threshold. Chain with class filters for precise results.
|
||||
|
||||
### How do I filter by bounding box area?
|
||||
|
||||
`detections[detections.area > 1000]` filters by pixel area. If masks are present, `detections.area` uses mask area; otherwise it uses bounding box area from `xyxy`. Use `detections.box_area` when you specifically need bounding box area.
|
||||
|
||||
### Can I filter by box aspect ratio or dimensions?
|
||||
|
||||
Yes. Use `detections.box_aspect_ratio` for aspect ratio filtering. If you need explicit box dimensions, compute them from `detections.xyxy` as `width = detections.xyxy[:, 2] - detections.xyxy[:, 0]` and `height = detections.xyxy[:, 3] - detections.xyxy[:, 1]`.
|
||||
|
||||
### How do I remove duplicate detections (NMS) from my results?
|
||||
|
||||
Use `detections.with_nms(threshold=0.5)` — it applies non-maximum suppression on the `xyxy` boxes.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,5 +1,11 @@
|
||||
---
|
||||
comments: true
|
||||
description: Load, split, merge, and convert computer vision datasets between YOLO, COCO, and Pascal VOC formats using supervision's DetectionDataset.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
With Supervision, you can load and manipulate classification, object detection, and
|
||||
@@ -449,3 +455,25 @@ augmented_annotations = replace(
|
||||
```
|
||||
|
||||
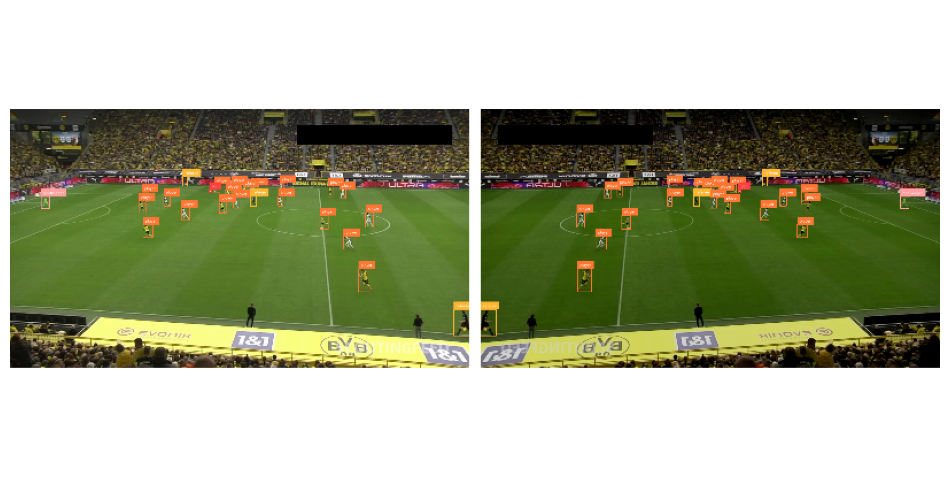
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### What dataset formats does supervision support?
|
||||
|
||||
For detection datasets, supervision supports YOLO, COCO JSON, and Pascal VOC. Use `DetectionDataset.from_yolo()`, `from_coco()`, or `from_pascal_voc()` to load, and `as_yolo()`, `as_coco()`, or `as_pascal_voc()` to save. Classification datasets use `ClassificationDataset.from_folder_structure()` and `as_folder_structure()`.
|
||||
|
||||
### Can I split a dataset into train/val/test sets?
|
||||
|
||||
`DetectionDataset.split(split_ratio=0.8)` returns exactly two datasets: train (80%) and test (20%). If you need a validation set, split one of those subsets in a separate step.
|
||||
|
||||
### Can I merge two datasets together?
|
||||
|
||||
Yes. `DetectionDataset.merge([dataset_a, dataset_b])` combines multiple datasets into one. Useful for combining datasets from different sources.
|
||||
|
||||
### What augmentations are available?
|
||||
|
||||
Common augmentations such as flip, rotate, translate, scale, crop, color jitter, and Gaussian blur can be applied using an external library like Albumentations, as shown in the augmentation example above. Supervision does not provide an `sv.Augmenter` pipeline.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,5 +1,11 @@
|
||||
---
|
||||
comments: true
|
||||
description: Save object detection results to CSV or JSON with supervision's CSVSink and JSONSink — export predictions for analysis and downstream pipelines.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
@@ -10,7 +16,7 @@ processing. This guide demonstrates how to perform video inference using the
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages and save their results with
|
||||
[`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and
|
||||
[`sv.JSONSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
[`sv.JSONSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.json_sink.JSONSink).
|
||||
|
||||
## Run Detection
|
||||
|
||||
@@ -18,6 +24,8 @@ First, you'll need to obtain predictions from your object detection or segmentat
|
||||
model. You can learn more on this topic in our
|
||||
[How to Detect and Annotate](https://supervision.roboflow.com/latest/how_to/detect_and_annotate/) guide.
|
||||
|
||||
To generate predictions for saving, initialize your model and iterate over video frames using `sv.get_video_frames_generator`. Each frame is passed to the model, and the raw output is converted into a `sv.Detections` object. This detection loop forms the foundation for both CSV and JSON export workflows shown below.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
@@ -231,7 +239,7 @@ If you prefer to save the result in a `.JSON` file instead of a `.CSV` file, all
|
||||
need to do is replace
|
||||
[`sv.CSVSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
with
|
||||
[`sv.JSONSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
[`sv.JSONSink`](https://supervision.roboflow.com/latest/detection/tools/save_detections/#supervision.detection.tools.json_sink.JSONSink).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
@@ -294,3 +302,25 @@ with
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I save detections to CSV with supervision?
|
||||
|
||||
Open `sv.CSVSink("output.csv")` as a context manager and call `sink.append(detections)` for each frame. The CSV includes box coordinates, confidence, class ID, tracker ID, and any fields stored in `detections.data`.
|
||||
|
||||
### Can I save detections to JSON instead?
|
||||
|
||||
Yes. Open `sv.JSONSink("output.json")` as a context manager and call `sink.append(detections)` for each frame. The file is written as a JSON array when the context exits.
|
||||
|
||||
### Can I add custom fields to the saved output?
|
||||
|
||||
Yes. Pass a dict as the second argument: `sink.append(detections, {"frame_index": 5})` — the keys become extra columns in the CSV or extra fields in the JSON.
|
||||
|
||||
### Can I save only specific classes or confidence levels?
|
||||
|
||||
Filter the `Detections` object before saving: `sink.append(detections[detections.confidence > 0.7])`.
|
||||
|
||||
## Author
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
|
||||
@@ -1,5 +1,14 @@
|
||||
---
|
||||
comments: true
|
||||
description: Track objects across video frames with ByteTrack in supervision — assign persistent IDs and analyze motion from any object detection model.
|
||||
authors:
|
||||
- name: Piotr Skalski
|
||||
role: Computer Vision Engineer, Roboflow
|
||||
github: https://github.com/SkalskiP
|
||||
- name: Soumik Mandal
|
||||
role: ML Engineer, Roboflow
|
||||
github: https://github.com/soumik12345
|
||||
date_modified: 2026-04-22
|
||||
---
|
||||
|
||||
# Track Objects
|
||||
@@ -16,8 +25,10 @@ for a deeper analysis.
|
||||
## Object Detection & Segmentation
|
||||
|
||||
To make it easier for you to follow our tutorial download the video we will use as an
|
||||
example. You can do this using
|
||||
[`supervision[assets]`](https://supervision.roboflow.com/latest/assets/) extension.
|
||||
example. You can do this using the
|
||||
[`supervision.assets`](https://supervision.roboflow.com/latest/assets/) module included in the base package.
|
||||
|
||||
This section demonstrates how to detect and segment objects in video frames using YOLOv8 with either the Inference or Ultralytics package. You will download a sample video, define a per-frame callback function that runs model prediction, and process the entire video to produce an annotated output file.
|
||||
|
||||
```python
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
@@ -325,7 +336,7 @@ movement patterns and interactions between objects in the video.
|
||||
Models aren't limited to object detection and segmentation. Keypoint detection allows for detailed analysis of body joints and connections, especially valuable for applications like human pose estimation. This section introduces keypoint tracking. We'll walk through the steps of annotating keypoints, converting them into bounding box detections compatible with `ByteTrack`, and applying detection smoothing for enhanced stability.
|
||||
|
||||
To make it easier for you to follow our tutorial, let's download the video we will use as an
|
||||
example. You can do this using [`supervision[assets]`](https://supervision.roboflow.com/latest/assets/) extension.
|
||||
example. You can do this using the [`supervision.assets`](https://supervision.roboflow.com/latest/assets/) module included in the base package.
|
||||
|
||||
```python
|
||||
from supervision.assets import download_assets, VideoAssets
|
||||
@@ -653,3 +664,26 @@ We could stop here as we have successfully tracked the object detected by the ke
|
||||
</video>
|
||||
|
||||
This structured walkthrough should give a detailed pathway to annotate videos effectively using Supervision’s various functionalities, including object tracking and trace annotations.
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### How do I track objects across video frames with supervision?
|
||||
|
||||
Pass `Detections` to `sv.ByteTrack.update_with_detections()` on each frame. The tracker assigns persistent IDs. Combine with `sv.TraceAnnotator` to visualize trajectories. `sv.ByteTrack` is deprecated in favor of `ByteTrackTracker` from the `trackers` package, where the update method is named `update()`.
|
||||
|
||||
### What should I know about ByteTrack?
|
||||
|
||||
ByteTrack uses low-confidence detections during association, which can improve continuity during missed or weak detections. Supervision's built-in `ByteTrack` wrapper is deprecated in favor of the external `trackers` package.
|
||||
|
||||
### Can I track instances instead of bounding boxes?
|
||||
|
||||
Yes. ByteTrack tracks bounding boxes. For instance masks, use `sv.MaskAnnotator` with the tracker IDs to color-code each tracked object consistently.
|
||||
|
||||
### Does ByteTrack work with any detection model?
|
||||
|
||||
Yes. ByteTrack is model-agnostic - it accepts any `Detections` object with bounding boxes, regardless of the supported converter or model output that produced it.
|
||||
|
||||
## Authors
|
||||
|
||||
- [Piotr Skalski](https://github.com/SkalskiP) — Computer Vision Engineer, Roboflow
|
||||
- [Soumik Mandal](https://github.com/soumik12345) — ML Engineer, Roboflow
|
||||
|
||||
@@ -4,6 +4,7 @@ comments: true
|
||||
hide:
|
||||
- navigation
|
||||
- toc
|
||||
description: Open-source Python library providing computer vision tools for annotating detections, tracking objects, counting in zones, and processing datasets.
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
@@ -23,6 +24,14 @@ hide:
|
||||
}
|
||||
</style>
|
||||
|
||||
## What is Supervision?
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for building computer vision applications. It provides a unified `Detections` object with converters for supported outputs from Ultralytics, Roboflow Inference, Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers.
|
||||
|
||||
With Supervision you can annotate images and video with bounding boxes, masks, and labels; track objects across frames with persistent IDs; count and filter detections inside polygon zones; load and convert datasets between YOLO, COCO, and Pascal VOC formats; and benchmark model performance with mAP and confusion matrices.
|
||||
|
||||
Supervision is MIT licensed, has 38,000+ GitHub stars, and over 1 million monthly PyPI downloads. It is developed in public on GitHub for production computer vision workflows.
|
||||
|
||||
## 👋 Hello
|
||||
|
||||
We write your reusable computer vision tools. Whether you need to load your dataset from your hard drive, draw detections on an image or video, or count how many detections are in a zone. You can count on us!
|
||||
|
||||
@@ -0,0 +1,192 @@
|
||||
# supervision
|
||||
|
||||
> Large-context AI crawler summary for Supervision documentation.
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a model-agnostic `Detections` class and composable tools for object detection, instance segmentation, keypoint detection, annotation, tracking, zone counting, dataset conversion, and model evaluation.
|
||||
|
||||
Supervision is MIT licensed, published on PyPI, developed on GitHub, and used by researchers and practitioners in production computer vision systems. The library includes converters for supported outputs from Ultralytics, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers.
|
||||
|
||||
## Primary Links
|
||||
|
||||
- Latest stable docs: https://supervision.roboflow.com/latest/
|
||||
- Development docs: https://supervision.roboflow.com/develop/
|
||||
- Source code: https://github.com/roboflow/supervision
|
||||
- PyPI package: https://pypi.org/project/supervision/
|
||||
- Changelog: https://supervision.roboflow.com/latest/changelog/
|
||||
- Sitemap: https://supervision.roboflow.com/sitemap.xml
|
||||
- Standard LLM summary: https://supervision.roboflow.com/llms.txt
|
||||
- Full LLM summary: https://supervision.roboflow.com/llms.full.txt
|
||||
|
||||
## AI Access
|
||||
|
||||
The documentation is static HTML and is open for AI crawler consumption. `robots.txt` explicitly allows general crawlers plus GPTBot, ClaudeBot, PerplexityBot, Bytespider, CCBot, GoogleOther, and Applebot.
|
||||
|
||||
## Install
|
||||
|
||||
```bash
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
Optional extras:
|
||||
|
||||
```bash
|
||||
pip install "supervision[metrics]"
|
||||
```
|
||||
|
||||
Sample asset utilities are included in the base package under `supervision.assets`.
|
||||
|
||||
## Core Concepts
|
||||
|
||||
### `sv.Detections`
|
||||
|
||||
`sv.Detections` is the central data structure in Supervision. It stores bounding boxes, segmentation masks, confidence scores, class IDs, tracker IDs, and arbitrary per-detection metadata in a `data` dictionary. It supports NumPy-style indexing for filtering by confidence, class, area, and spatial constraints.
|
||||
|
||||
Most connectors, annotators, trackers, dataset tools, and metrics either accept or return `Detections`, which makes it possible to change the upstream model while keeping downstream processing code stable.
|
||||
|
||||
### Model Connectors
|
||||
|
||||
Supervision normalizes outputs from multiple computer vision frameworks into the same `Detections` API. Common constructors include:
|
||||
|
||||
- `sv.Detections.from_ultralytics(...)`
|
||||
- `sv.Detections.from_inference(...)`
|
||||
- `sv.Detections.from_transformers(...)`
|
||||
- `sv.Detections.from_vlm(...)`
|
||||
- `sv.Detections.from_sam(...)`
|
||||
- `sv.Detections.from_detectron2(...)`
|
||||
- `sv.Detections.from_mmdetection(...)`
|
||||
|
||||
### Annotation
|
||||
|
||||
Supervision includes annotators for drawing boxes, masks, labels, traces, zones, vertices, edges, and other overlays on images and video frames. Common annotators include:
|
||||
|
||||
- `sv.BoxAnnotator`
|
||||
- `sv.MaskAnnotator`
|
||||
- `sv.LabelAnnotator`
|
||||
- `sv.TraceAnnotator`
|
||||
- `sv.PolygonZoneAnnotator`
|
||||
- `sv.LineZoneAnnotator`
|
||||
|
||||
### Tracking
|
||||
|
||||
The built-in `sv.ByteTrack` wrapper assigns persistent IDs across video frames through `update_with_detections()`. The docs also note the migration path toward `ByteTrackTracker` from the external `trackers` package. Tracked detections can be passed to label, trace, zone, and line-counting annotators.
|
||||
|
||||
### Zones and Counting
|
||||
|
||||
`sv.PolygonZone` checks whether detections are inside an arbitrary polygon. `sv.LineZone` counts line crossings and requires `detections.tracker_id` so objects can be matched across frames. These tools are typically used with video callbacks and annotators to build traffic, occupancy, queue, and throughput analytics.
|
||||
|
||||
### Datasets
|
||||
|
||||
`sv.DetectionDataset` loads, merges, splits, and converts object detection datasets. Supported formats include YOLO, COCO JSON, and Pascal VOC. `sv.ClassificationDataset` supports folder-structured classification datasets.
|
||||
|
||||
### Metrics
|
||||
|
||||
Supervision includes detection metrics including mean average precision, mean average recall, precision, recall, F1 score, and confusion matrices. The current mAP workflow uses `supervision.metrics.mean_average_precision.MeanAveragePrecision` with `update(...)` and `compute()`.
|
||||
|
||||
## How-To Guides
|
||||
|
||||
- Detect and annotate: https://supervision.roboflow.com/latest/how_to/detect_and_annotate/
|
||||
- Track objects: https://supervision.roboflow.com/latest/how_to/track_objects/
|
||||
- Detect small objects: https://supervision.roboflow.com/latest/how_to/detect_small_objects/
|
||||
- Filter detections: https://supervision.roboflow.com/latest/how_to/filter_detections/
|
||||
- Save detections: https://supervision.roboflow.com/latest/how_to/save_detections/
|
||||
- Count in zone: https://supervision.roboflow.com/latest/how_to/count_in_zone/
|
||||
- Benchmark a model: https://supervision.roboflow.com/latest/how_to/benchmark_a_model/
|
||||
- Process datasets: https://supervision.roboflow.com/latest/how_to/process_datasets/
|
||||
|
||||
## Reference Documentation
|
||||
|
||||
- Detections: https://supervision.roboflow.com/latest/detection/core/
|
||||
- Detection annotators: https://supervision.roboflow.com/latest/detection/annotators/
|
||||
- Compact masks: https://supervision.roboflow.com/latest/detection/compact_mask/
|
||||
- Detection converters: https://supervision.roboflow.com/latest/detection/utils/converters/
|
||||
- IoU and NMS: https://supervision.roboflow.com/latest/detection/utils/iou_and_nms/
|
||||
- Boxes: https://supervision.roboflow.com/latest/detection/utils/boxes/
|
||||
- Masks: https://supervision.roboflow.com/latest/detection/utils/masks/
|
||||
- Polygons: https://supervision.roboflow.com/latest/detection/utils/polygons/
|
||||
- Vision-language model helpers: https://supervision.roboflow.com/latest/detection/utils/vlms/
|
||||
- Keypoint core: https://supervision.roboflow.com/latest/keypoint/core/
|
||||
- Keypoint annotators: https://supervision.roboflow.com/latest/keypoint/annotators/
|
||||
- Classification core: https://supervision.roboflow.com/latest/classification/core/
|
||||
- Trackers: https://supervision.roboflow.com/latest/trackers/
|
||||
- Dataset core: https://supervision.roboflow.com/latest/datasets/core/
|
||||
- Mean average precision: https://supervision.roboflow.com/latest/metrics/mean_average_precision/
|
||||
- Mean average recall: https://supervision.roboflow.com/latest/metrics/mean_average_recall/
|
||||
- Precision: https://supervision.roboflow.com/latest/metrics/precision/
|
||||
- Recall: https://supervision.roboflow.com/latest/metrics/recall/
|
||||
- F1 score: https://supervision.roboflow.com/latest/metrics/f1_score/
|
||||
- Common metric values: https://supervision.roboflow.com/latest/metrics/common_values/
|
||||
- Line zone: https://supervision.roboflow.com/latest/detection/tools/line_zone/
|
||||
- Polygon zone: https://supervision.roboflow.com/latest/detection/tools/polygon_zone/
|
||||
- Inference slicer: https://supervision.roboflow.com/latest/detection/tools/inference_slicer/
|
||||
- Detection smoother: https://supervision.roboflow.com/latest/detection/tools/smoother/
|
||||
- Detection export sinks: https://supervision.roboflow.com/latest/detection/tools/save_detections/
|
||||
- Video utilities: https://supervision.roboflow.com/latest/utils/video/
|
||||
- Image utilities: https://supervision.roboflow.com/latest/utils/image/
|
||||
- Iterable utilities: https://supervision.roboflow.com/latest/utils/iterables/
|
||||
- Notebook utilities: https://supervision.roboflow.com/latest/utils/notebook/
|
||||
- File utilities: https://supervision.roboflow.com/latest/utils/file/
|
||||
- Draw utilities: https://supervision.roboflow.com/latest/utils/draw/
|
||||
- Geometry utilities: https://supervision.roboflow.com/latest/utils/geometry/
|
||||
- Assets: https://supervision.roboflow.com/latest/assets/
|
||||
|
||||
## Cookbooks
|
||||
|
||||
- Supervision quickstart: https://supervision.roboflow.com/latest/notebooks/quickstart/
|
||||
- Count objects crossing the line: https://supervision.roboflow.com/latest/notebooks/count-objects-crossing-the-line/
|
||||
- Object tracking: https://supervision.roboflow.com/latest/notebooks/object-tracking/
|
||||
- Small object detection with SAHI: https://supervision.roboflow.com/latest/notebooks/small-object-detection-with-sahi/
|
||||
- Zero-shot object detection with YOLO-World: https://supervision.roboflow.com/latest/notebooks/zero-shot-object-detection-with-yolo-world/
|
||||
- Save detections to CSV: https://supervision.roboflow.com/latest/notebooks/serialise-detections-to-csv/
|
||||
- Save detections to JSON: https://supervision.roboflow.com/latest/notebooks/serialise-detections-to-json/
|
||||
- Occupancy analytics: https://supervision.roboflow.com/latest/notebooks/occupancy_analytics/
|
||||
- Annotate video with detections: https://supervision.roboflow.com/latest/notebooks/annotate-video-with-detections/
|
||||
|
||||
## Trust and Contact Pages
|
||||
|
||||
- About: https://supervision.roboflow.com/latest/about/
|
||||
- Contact: https://supervision.roboflow.com/latest/contact/
|
||||
- FAQ: https://supervision.roboflow.com/latest/faq/
|
||||
- License: https://github.com/roboflow/supervision/blob/develop/LICENSE.md
|
||||
- Issues: https://github.com/roboflow/supervision/issues
|
||||
- Community: https://discord.gg/GbfgXGJ8Bk
|
||||
|
||||
## Frequently Asked Questions
|
||||
|
||||
### What is Supervision?
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified `Detections` class with converters for supported detection, segmentation, and VLM outputs.
|
||||
|
||||
### Is Supervision tied to one model provider?
|
||||
|
||||
No. Supervision is model agnostic. It is designed to normalize model outputs into a common API so downstream annotation, filtering, tracking, metrics, and dataset code can be reused.
|
||||
|
||||
### What dataset formats are supported?
|
||||
|
||||
For object detection datasets, Supervision supports YOLO, COCO JSON, and Pascal VOC import and export. For classification datasets, it supports folder-structure import and export.
|
||||
|
||||
### How do I detect small objects?
|
||||
|
||||
Use `sv.InferenceSlicer` to split large images into overlapping tiles, run inference on each tile, and merge the resulting detections with non-maximum suppression or non-maximum merge.
|
||||
|
||||
### How do I count objects crossing a line?
|
||||
|
||||
Run a tracker first to assign `detections.tracker_id`, then use `sv.LineZone.trigger(detections)` to calculate crossing events. Use `sv.LineZoneAnnotator` for visualization.
|
||||
|
||||
### How do I benchmark a model?
|
||||
|
||||
Load predictions and ground truth as `Detections`, update a `MeanAveragePrecision` metric object, and call `compute()`. Use `sv.ConfusionMatrix` when class-level confusion analysis is needed.
|
||||
|
||||
## Citation
|
||||
|
||||
```bibtex
|
||||
@software{supervision,
|
||||
author = {Roboflow},
|
||||
title = {Supervision: Computer Vision Toolkit},
|
||||
url = {https://github.com/roboflow/supervision},
|
||||
year = {2023}
|
||||
}
|
||||
```
|
||||
|
||||
## Versioning
|
||||
|
||||
`/develop/` is built from the `develop` branch. `/latest/` is built from the `release/latest` branch. Published releases build tag-only documentation paths and do not move `/latest/`.
|
||||
@@ -0,0 +1,188 @@
|
||||
# supervision
|
||||
|
||||
> Open-source Python library for computer vision — annotate, track, count, filter, and convert.
|
||||
|
||||
Supervision is a Python library by Roboflow that provides a model-agnostic `Detections` class and composable tools for object detection and segmentation workflows. It includes converters for supported outputs from Ultralytics, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers.
|
||||
|
||||
Supervision is MIT licensed, published on PyPI, and developed in public on GitHub.
|
||||
|
||||
## AI Access
|
||||
|
||||
The documentation is static HTML and open for AI consumption. `robots.txt` explicitly allows general crawlers plus selected AI crawlers.
|
||||
|
||||
- GPTBot: allowed
|
||||
- ClaudeBot: allowed
|
||||
- PerplexityBot: allowed
|
||||
- CCBot: allowed
|
||||
- GoogleOther: allowed
|
||||
|
||||
## Install
|
||||
|
||||
```bash
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
Extra: `pip install supervision[metrics]` for optional metric dependencies. Sample asset utilities are included in the base package under `supervision.assets`.
|
||||
|
||||
## Links
|
||||
|
||||
- GitHub: https://github.com/roboflow/supervision
|
||||
- PyPI: https://pypi.org/project/supervision
|
||||
- Docs (latest stable): https://supervision.roboflow.com/latest/
|
||||
- Docs (develop): https://supervision.roboflow.com/develop/
|
||||
- Changelog: https://supervision.roboflow.com/latest/changelog/
|
||||
- Sitemap: https://supervision.roboflow.com/sitemap.xml
|
||||
|
||||
## Key APIs
|
||||
|
||||
### sv.Detections
|
||||
|
||||
Core data structure for bounding boxes, masks, confidence scores, class IDs, tracker IDs, and arbitrary per-detection metadata stored in a `data` dict. The lingua franca of the entire library — every connector, annotator, and tracker accepts or returns `Detections`. Supports NumPy-style boolean indexing for filtering by class, confidence, area, and spatial regions.
|
||||
|
||||
### sv.BoxAnnotator, sv.MaskAnnotator, sv.LabelAnnotator
|
||||
|
||||
Draw bounding boxes, segmentation masks, and text labels on images. Annotators expose `annotate(scene=..., detections=...)`; pass an input image and a `Detections` object to get the annotated output. `LabelAnnotator` can use explicit `labels` or fall back to `detections["class_name"]`, class IDs, then detection indices. Colors can be assigned by class or manually specified.
|
||||
|
||||
### sv.ByteTrack
|
||||
|
||||
Object tracker wrapper that assigns persistent IDs across video frames. The built-in `sv.ByteTrack` accepts `Detections` via `update_with_detections()`, but it is deprecated in favor of `ByteTrackTracker` from the external `trackers` package, where the method is named `update()`. Use tracked `Detections` with `sv.TraceAnnotator` to visualize trajectories.
|
||||
|
||||
### sv.PolygonZone and sv.LineZone
|
||||
|
||||
Zone-based counting. `PolygonZone.trigger(detections)` returns a boolean mask for detections currently inside an arbitrary polygon. `LineZone.trigger(detections)` returns `(crossed_in, crossed_out)` arrays for line crossings and requires `detections.tracker_id` so objects can be matched across frames. Both are commonly paired with zone annotators for visualization.
|
||||
|
||||
### sv.DetectionDataset and sv.ClassificationDataset
|
||||
|
||||
For detection datasets, load, merge, split, and convert between YOLO, COCO JSON, and Pascal VOC formats. Classification datasets use folder-structure import and export via `ClassificationDataset.from_folder_structure()` and `as_folder_structure()`.
|
||||
|
||||
### sv.InferenceSlicer
|
||||
|
||||
SAHI-style inference slicing: split high-resolution images into overlapping tiles, run detection on each tile, merge results with non-maximum suppression or non-maximum merge. Configure tile overlap in pixels with `overlap_wh`.
|
||||
|
||||
### supervision.metrics.MeanAveragePrecision and sv.ConfusionMatrix
|
||||
|
||||
Benchmarking tools. For mAP@0.5:0.95, use `supervision.metrics.MeanAveragePrecision` with `update()` and `compute()` rather than the deprecated top-level `sv.MeanAveragePrecision.from_detections()`. `ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes)` generates a confusion matrix for detection results.
|
||||
|
||||
### sv.CSVSink and sv.JSONSink
|
||||
|
||||
Export detection results to structured files. Use `CSVSink` and `JSONSink` as context managers, call `sink.append(detections, custom_data=...)`, and they write one row/object per detection with box coordinates, confidence, class ID, tracker ID, and data fields.
|
||||
|
||||
## How-To Guides
|
||||
|
||||
- Detect and annotate: https://supervision.roboflow.com/latest/how_to/detect_and_annotate/
|
||||
- Track objects: https://supervision.roboflow.com/latest/how_to/track_objects/
|
||||
- Detect small objects: https://supervision.roboflow.com/latest/how_to/detect_small_objects/
|
||||
- Filter detections: https://supervision.roboflow.com/latest/how_to/filter_detections/
|
||||
- Save detections: https://supervision.roboflow.com/latest/how_to/save_detections/
|
||||
- Count in zone: https://supervision.roboflow.com/latest/how_to/count_in_zone/
|
||||
- Benchmark a model: https://supervision.roboflow.com/latest/how_to/benchmark_a_model/
|
||||
- Process datasets: https://supervision.roboflow.com/latest/how_to/process_datasets/
|
||||
|
||||
## Reference Documentation
|
||||
|
||||
- Detections (detection/core): https://supervision.roboflow.com/latest/detection/core/
|
||||
- Annotators (detection/annotators): https://supervision.roboflow.com/latest/detection/annotators/
|
||||
- CompactMask (detection/compact_mask): https://supervision.roboflow.com/latest/detection/compact_mask/
|
||||
- Format Converters (detection/utils/converters): https://supervision.roboflow.com/latest/detection/utils/converters/
|
||||
- IoU and NMS (detection/utils/iou_and_nms): https://supervision.roboflow.com/latest/detection/utils/iou_and_nms/
|
||||
- Boxes (detection/utils/boxes): https://supervision.roboflow.com/latest/detection/utils/boxes/
|
||||
- Masks (detection/utils/masks): https://supervision.roboflow.com/latest/detection/utils/masks/
|
||||
- Polygons (detection/utils/polygons): https://supervision.roboflow.com/latest/detection/utils/polygons/
|
||||
- VLMs (detection/utils/vlms): https://supervision.roboflow.com/latest/detection/utils/vlms/
|
||||
- Keypoint Core (keypoint/core): https://supervision.roboflow.com/latest/keypoint/core/
|
||||
- Keypoint Annotators (keypoint/annotators): https://supervision.roboflow.com/latest/keypoint/annotators/
|
||||
- Classification Core (classification/core): https://supervision.roboflow.com/latest/classification/core/
|
||||
- ByteTrack Tracker (trackers): https://supervision.roboflow.com/latest/trackers/
|
||||
- Datasets Core (datasets/core): https://supervision.roboflow.com/latest/datasets/core/
|
||||
- mAP (metrics/mean_average_precision): https://supervision.roboflow.com/latest/metrics/mean_average_precision/
|
||||
- mAR (metrics/mean_average_recall): https://supervision.roboflow.com/latest/metrics/mean_average_recall/
|
||||
- Precision (metrics/precision): https://supervision.roboflow.com/latest/metrics/precision/
|
||||
- Recall (metrics/recall): https://supervision.roboflow.com/latest/metrics/recall/
|
||||
- F1 Score (metrics/f1_score): https://supervision.roboflow.com/latest/metrics/f1_score/
|
||||
- Common Values (metrics/common_values): https://supervision.roboflow.com/latest/metrics/common_values/
|
||||
- Line Zone (detection/tools/line_zone): https://supervision.roboflow.com/latest/detection/tools/line_zone/
|
||||
- Polygon Zone (detection/tools/polygon_zone): https://supervision.roboflow.com/latest/detection/tools/polygon_zone/
|
||||
- Inference Slicer (detection/tools/inference_slicer): https://supervision.roboflow.com/latest/detection/tools/inference_slicer/
|
||||
- Detection Smoother (detection/tools/smoother): https://supervision.roboflow.com/latest/detection/tools/smoother/
|
||||
- Save Detections Tool (detection/tools/save_detections): https://supervision.roboflow.com/latest/detection/tools/save_detections/
|
||||
- Video Utils (utils/video): https://supervision.roboflow.com/latest/utils/video/
|
||||
- Image Utils (utils/image): https://supervision.roboflow.com/latest/utils/image/
|
||||
- Iterable Utils (utils/iterables): https://supervision.roboflow.com/latest/utils/iterables/
|
||||
- Notebook Utils (utils/notebook): https://supervision.roboflow.com/latest/utils/notebook/
|
||||
- File Utils (utils/file): https://supervision.roboflow.com/latest/utils/file/
|
||||
- Draw Utils (utils/draw): https://supervision.roboflow.com/latest/utils/draw/
|
||||
- Geometry (utils/geometry): https://supervision.roboflow.com/latest/utils/geometry/
|
||||
- Assets (assets): https://supervision.roboflow.com/latest/assets/
|
||||
|
||||
## Cookbooks
|
||||
|
||||
- Object tracking: https://supervision.roboflow.com/latest/cookbooks/#object-tracking
|
||||
- Count objects crossing line: https://supervision.roboflow.com/latest/cookbooks/#count-objects-crossing-the-line
|
||||
- Zero-shot object detection with YOLO-World: https://supervision.roboflow.com/latest/cookbooks/#zero-shot-object-detection-with-yolo-world
|
||||
- SAHI small object detection: https://supervision.roboflow.com/latest/cookbooks/#small-object-detection-with-sahi
|
||||
|
||||
## FAQ
|
||||
|
||||
### What is supervision?
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified `Detections` class with converters for supported detection, segmentation, and VLM outputs, plus tools for annotation, tracking, zone counting, dataset management, and model benchmarking.
|
||||
|
||||
### How do I install supervision?
|
||||
|
||||
Install with `pip install supervision`. For optional metric dependencies use `pip install supervision[metrics]`. Sample asset utilities are included in the base package under `supervision.assets`. The current package metadata requires Python 3.9+.
|
||||
|
||||
### What can I do with supervision?
|
||||
|
||||
Annotate images and video with bounding boxes, masks, and labels; track objects across frames with persistent IDs; count detections inside polygon zones or line crossings; filter and query detection results; load, split, and convert detection datasets between YOLO, COCO, and Pascal VOC formats; manage classification datasets with folder structures; and benchmark model performance with mAP and confusion matrices.
|
||||
|
||||
### Is supervision free to use?
|
||||
|
||||
Yes. Supervision is free and open-source under the MIT license. Source code is at https://github.com/roboflow/supervision.
|
||||
|
||||
### Which object detection models work with supervision?
|
||||
|
||||
Supervision is model-agnostic and works with supported outputs from Ultralytics YOLO, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers such as Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. Keypoint outputs have separate converters, including MediaPipe.
|
||||
|
||||
### How do I benchmark a model with supervision?
|
||||
|
||||
Use `supervision.metrics.mean_average_precision.MeanAveragePrecision` for mAP — accumulate predictions and ground truth with `update(...)` then call `compute()`. For confusion matrices, use `sv.ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes)`. See the Benchmark a Model how-to guide for a complete walkthrough.
|
||||
|
||||
### How do I track objects across video frames?
|
||||
|
||||
Use a tracker to assign persistent IDs. The built-in `sv.ByteTrack` wrapper accepts `Detections` with `update_with_detections()`, but it is deprecated in favor of `ByteTrackTracker` from the external `trackers` package. Combine tracked detections with `sv.TraceAnnotator` to visualize trajectories.
|
||||
|
||||
### What dataset formats does supervision support?
|
||||
|
||||
For detection datasets, supervision supports YOLO, COCO JSON, and Pascal VOC. Use `DetectionDataset.from_yolo()`, `from_coco()`, or `from_pascal_voc()` to load, and `as_yolo()`, `as_coco()`, or `as_pascal_voc()` to save. For classification datasets, use `ClassificationDataset.from_folder_structure()` and `as_folder_structure()`.
|
||||
|
||||
### How do I count objects in a zone?
|
||||
|
||||
Use `sv.PolygonZone` for arbitrary polygon zones. Use `sv.LineZone` for line-crossing counts after assigning tracker IDs, because `LineZone` needs `detections.tracker_id` to match objects across frames.
|
||||
|
||||
### How do I detect small objects with supervision?
|
||||
|
||||
Use `sv.InferenceSlicer` to split high-resolution images into overlapping tiles, run detection on each tile, and merge results with non-maximum suppression. Configure tile overlap in pixels with `overlap_wh`. See the Detect Small Objects how-to guide.
|
||||
|
||||
## Benchmarking
|
||||
|
||||
Supervision includes `supervision.metrics.MeanAveragePrecision` and `sv.ConfusionMatrix` for benchmarking object detection models. A curated [Model Leaderboard](https://leaderboard.roboflow.com/) compares YOLOv8, YOLOv11, and other models on standard datasets. The leaderboard repository is open source at https://github.com/roboflow/model-leaderboard.
|
||||
|
||||
## License
|
||||
|
||||
MIT — https://github.com/roboflow/supervision/blob/develop/LICENSE.md
|
||||
|
||||
## Citation
|
||||
|
||||
```bibtex
|
||||
@software{supervision,
|
||||
author = {Roboflow},
|
||||
title = {Supervision: Computer Vision Toolkit},
|
||||
url = {https://github.com/roboflow/supervision},
|
||||
year = {2023}
|
||||
}
|
||||
```
|
||||
|
||||
## Versioning
|
||||
|
||||
Stable release docs: https://supervision.roboflow.com/latest/
|
||||
Development branch: https://supervision.roboflow.com/develop/
|
||||
+179
@@ -0,0 +1,179 @@
|
||||
# supervision
|
||||
|
||||
> Open-source Python library for computer vision — annotate, track, count, filter, and convert.
|
||||
|
||||
Supervision is a Python library by Roboflow that provides a model-agnostic `Detections` class and composable tools for object detection and segmentation workflows. It includes converters for supported outputs from Ultralytics, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers.
|
||||
|
||||
Supervision is MIT licensed, published on PyPI, and developed in public on GitHub.
|
||||
|
||||
## AI Access
|
||||
|
||||
The documentation is static HTML and open for AI consumption. `robots.txt` explicitly allows general crawlers plus selected AI crawlers.
|
||||
|
||||
- GPTBot: allowed
|
||||
- ClaudeBot: allowed
|
||||
- PerplexityBot: allowed
|
||||
- CCBot: allowed
|
||||
- GoogleOther: allowed
|
||||
|
||||
## Install
|
||||
|
||||
```
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
Extra: `pip install supervision[metrics]` for optional metric dependencies. Sample asset utilities are included in the base package under `supervision.assets`.
|
||||
|
||||
## Links
|
||||
|
||||
- GitHub: https://github.com/roboflow/supervision
|
||||
- PyPI: https://pypi.org/project/supervision
|
||||
- Docs (latest stable): https://supervision.roboflow.com/latest/
|
||||
- Changelog: https://supervision.roboflow.com/latest/changelog/
|
||||
- Sitemap: https://supervision.roboflow.com/sitemap.xml
|
||||
|
||||
## Key APIs
|
||||
|
||||
### sv.Detections
|
||||
Core data structure for bounding boxes, masks, confidence scores, class IDs, tracker IDs, and arbitrary per-detection metadata stored in a `data` dict. The lingua franca of the entire library — every connector, annotator, and tracker accepts or returns `Detections`. Supports NumPy-style boolean indexing for filtering by class, confidence, area, and spatial regions.
|
||||
|
||||
### sv.BoxAnnotator, sv.MaskAnnotator, sv.LabelAnnotator
|
||||
Draw bounding boxes, segmentation masks, and text labels on images. Annotators expose `annotate(scene=..., detections=...)`; pass an input image and a `Detections` object to get the annotated output. `LabelAnnotator` can use explicit `labels` or fall back to `detections["class_name"]`, class IDs, then detection indices. Colors can be assigned by class or manually specified.
|
||||
|
||||
### sv.ByteTrack
|
||||
Object tracker wrapper that assigns persistent IDs across video frames. The built-in `sv.ByteTrack` accepts `Detections` via `update_with_detections()`, but it is deprecated in favor of `ByteTrackTracker` from the external `trackers` package, where the method is named `update()`. Use tracked `Detections` with `sv.TraceAnnotator` to visualize trajectories.
|
||||
|
||||
### sv.PolygonZone and sv.LineZone
|
||||
Zone-based counting. `PolygonZone.trigger(detections)` returns a boolean mask for detections currently inside an arbitrary polygon. `LineZone.trigger(detections)` returns `(crossed_in, crossed_out)` arrays for line crossings and requires `detections.tracker_id` so objects can be matched across frames. Both are commonly paired with zone annotators for visualization.
|
||||
|
||||
### sv.DetectionDataset and sv.ClassificationDataset
|
||||
For detection datasets, load, merge, split, and convert between YOLO, COCO JSON, and Pascal VOC formats. Classification datasets use folder-structure import and export via `ClassificationDataset.from_folder_structure()` and `as_folder_structure()`.
|
||||
|
||||
### sv.InferenceSlicer
|
||||
SAHI-style inference slicing: split high-resolution images into overlapping tiles, run detection on each tile, merge results with non-maximum suppression or non-maximum merge. Configure tile overlap in pixels with `overlap_wh`.
|
||||
|
||||
### supervision.metrics.MeanAveragePrecision and sv.ConfusionMatrix
|
||||
Benchmarking tools. For mAP@0.5:0.95, use `supervision.metrics.MeanAveragePrecision` with `update()` and `compute()` rather than the deprecated top-level `sv.MeanAveragePrecision.from_detections()`. `ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes)` generates a confusion matrix for detection results.
|
||||
|
||||
### sv.CSVSink and sv.JSONSink
|
||||
Export detection results to structured files. Use `CSVSink` and `JSONSink` as context managers, call `sink.append(detections, custom_data=...)`, and they write one row/object per detection with box coordinates, confidence, class ID, tracker ID, and data fields.
|
||||
|
||||
## How-To Guides
|
||||
|
||||
- Detect and annotate: https://supervision.roboflow.com/latest/how_to/detect_and_annotate/
|
||||
- Track objects: https://supervision.roboflow.com/latest/how_to/track_objects/
|
||||
- Detect small objects: https://supervision.roboflow.com/latest/how_to/detect_small_objects/
|
||||
- Filter detections: https://supervision.roboflow.com/latest/how_to/filter_detections/
|
||||
- Save detections: https://supervision.roboflow.com/latest/how_to/save_detections/
|
||||
- Count in zone: https://supervision.roboflow.com/latest/how_to/count_in_zone/
|
||||
- Benchmark a model: https://supervision.roboflow.com/latest/how_to/benchmark_a_model/
|
||||
- Process datasets: https://supervision.roboflow.com/latest/how_to/process_datasets/
|
||||
|
||||
## Reference Documentation
|
||||
|
||||
- Detections (detection/core): https://supervision.roboflow.com/latest/detection/core/
|
||||
- Annotators (detection/annotators): https://supervision.roboflow.com/latest/detection/annotators/
|
||||
- CompactMask (detection/compact_mask): https://supervision.roboflow.com/latest/detection/compact_mask/
|
||||
- Format Converters (detection/utils/converters): https://supervision.roboflow.com/latest/detection/utils/converters/
|
||||
- IoU and NMS (detection/utils/iou_and_nms): https://supervision.roboflow.com/latest/detection/utils/iou_and_nms/
|
||||
- Boxes (detection/utils/boxes): https://supervision.roboflow.com/latest/detection/utils/boxes/
|
||||
- Masks (detection/utils/masks): https://supervision.roboflow.com/latest/detection/utils/masks/
|
||||
- Polygons (detection/utils/polygons): https://supervision.roboflow.com/latest/detection/utils/polygons/
|
||||
- VLMs (detection/utils/vlms): https://supervision.roboflow.com/latest/detection/utils/vlms/
|
||||
- Keypoint Core (keypoint/core): https://supervision.roboflow.com/latest/keypoint/core/
|
||||
- Keypoint Annotators (keypoint/annotators): https://supervision.roboflow.com/latest/keypoint/annotators/
|
||||
- Classification Core (classification/core): https://supervision.roboflow.com/latest/classification/core/
|
||||
- ByteTrack Tracker (trackers): https://supervision.roboflow.com/latest/trackers/
|
||||
- Datasets Core (datasets/core): https://supervision.roboflow.com/latest/datasets/core/
|
||||
- mAP (metrics/mean_average_precision): https://supervision.roboflow.com/latest/metrics/mean_average_precision/
|
||||
- mAR (metrics/mean_average_recall): https://supervision.roboflow.com/latest/metrics/mean_average_recall/
|
||||
- Precision (metrics/precision): https://supervision.roboflow.com/latest/metrics/precision/
|
||||
- Recall (metrics/recall): https://supervision.roboflow.com/latest/metrics/recall/
|
||||
- F1 Score (metrics/f1_score): https://supervision.roboflow.com/latest/metrics/f1_score/
|
||||
- Common Values (metrics/common_values): https://supervision.roboflow.com/latest/metrics/common_values/
|
||||
- Line Zone (detection/tools/line_zone): https://supervision.roboflow.com/latest/detection/tools/line_zone/
|
||||
- Polygon Zone (detection/tools/polygon_zone): https://supervision.roboflow.com/latest/detection/tools/polygon_zone/
|
||||
- Inference Slicer (detection/tools/inference_slicer): https://supervision.roboflow.com/latest/detection/tools/inference_slicer/
|
||||
- Detection Smoother (detection/tools/smoother): https://supervision.roboflow.com/latest/detection/tools/smoother/
|
||||
- Save Detections Tool (detection/tools/save_detections): https://supervision.roboflow.com/latest/detection/tools/save_detections/
|
||||
- Video Utils (utils/video): https://supervision.roboflow.com/latest/utils/video/
|
||||
- Image Utils (utils/image): https://supervision.roboflow.com/latest/utils/image/
|
||||
- Iterable Utils (utils/iterables): https://supervision.roboflow.com/latest/utils/iterables/
|
||||
- Notebook Utils (utils/notebook): https://supervision.roboflow.com/latest/utils/notebook/
|
||||
- File Utils (utils/file): https://supervision.roboflow.com/latest/utils/file/
|
||||
- Draw Utils (utils/draw): https://supervision.roboflow.com/latest/utils/draw/
|
||||
- Geometry (utils/geometry): https://supervision.roboflow.com/latest/utils/geometry/
|
||||
- Assets (assets): https://supervision.roboflow.com/latest/assets/
|
||||
|
||||
## Cookbooks
|
||||
|
||||
- Object tracking: https://supervision.roboflow.com/latest/cookbooks/#object-tracking
|
||||
- Count objects crossing line: https://supervision.roboflow.com/latest/cookbooks/#count-objects-crossing-the-line
|
||||
- Zero-shot object detection with YOLO-World: https://supervision.roboflow.com/latest/cookbooks/#zero-shot-object-detection-with-yolo-world
|
||||
- SAHI small object detection: https://supervision.roboflow.com/latest/cookbooks/#small-object-detection-with-sahi
|
||||
|
||||
## FAQ
|
||||
|
||||
### What is supervision?
|
||||
|
||||
Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified `Detections` class with converters for supported detection, segmentation, and VLM outputs, plus tools for annotation, tracking, zone counting, dataset management, and model benchmarking.
|
||||
|
||||
### How do I install supervision?
|
||||
|
||||
Install with `pip install supervision`. For optional metric dependencies use `pip install supervision[metrics]`. Sample asset utilities are included in the base package under `supervision.assets`. The current package metadata requires Python 3.9+.
|
||||
|
||||
### What can I do with supervision?
|
||||
|
||||
Annotate images and video with bounding boxes, masks, and labels; track objects across frames with persistent IDs; count detections inside polygon zones or line crossings; filter and query detection results; load, split, and convert detection datasets between YOLO, COCO, and Pascal VOC formats; manage classification datasets with folder structures; and benchmark model performance with mAP and confusion matrices.
|
||||
|
||||
### Is supervision free to use?
|
||||
|
||||
Yes. Supervision is free and open-source under the MIT license. Source code is at https://github.com/roboflow/supervision.
|
||||
|
||||
### Which object detection models work with supervision?
|
||||
|
||||
Supervision is model-agnostic and works with supported outputs from Ultralytics YOLO, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers such as Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. Keypoint outputs have separate converters, including MediaPipe.
|
||||
|
||||
### How do I benchmark a model with supervision?
|
||||
|
||||
Use `supervision.metrics.mean_average_precision.MeanAveragePrecision` for mAP — accumulate predictions and ground truth with `update(...)` then call `compute()`. For confusion matrices, use `sv.ConfusionMatrix.from_detections(predictions=predictions, targets=targets, classes=classes)`. See the Benchmark a Model how-to guide for a complete walkthrough.
|
||||
|
||||
### How do I track objects across video frames?
|
||||
|
||||
Use a tracker to assign persistent IDs. The built-in `sv.ByteTrack` wrapper accepts `Detections` with `update_with_detections()`, but it is deprecated in favor of `ByteTrackTracker` from the external `trackers` package. Combine tracked detections with `sv.TraceAnnotator` to visualize trajectories.
|
||||
|
||||
### What dataset formats does supervision support?
|
||||
|
||||
For detection datasets, supervision supports YOLO, COCO JSON, and Pascal VOC. Use `DetectionDataset.from_yolo()`, `from_coco()`, or `from_pascal_voc()` to load, and `as_yolo()`, `as_coco()`, or `as_pascal_voc()` to save. For classification datasets, use `ClassificationDataset.from_folder_structure()` and `as_folder_structure()`.
|
||||
|
||||
### How do I count objects in a zone?
|
||||
|
||||
Use `sv.PolygonZone` for arbitrary polygon zones. Use `sv.LineZone` for line-crossing counts after assigning tracker IDs, because `LineZone` needs `detections.tracker_id` to match objects across frames.
|
||||
|
||||
### How do I detect small objects with supervision?
|
||||
|
||||
Use `sv.InferenceSlicer` to split high-resolution images into overlapping tiles, run detection on each tile, and merge results with non-maximum suppression. Configure tile overlap in pixels with `overlap_wh`. See the Detect Small Objects how-to guide.
|
||||
|
||||
## Benchmarking
|
||||
|
||||
Supervision includes `supervision.metrics.MeanAveragePrecision` and `sv.ConfusionMatrix` for benchmarking object detection models. A curated [Model Leaderboard](https://leaderboard.roboflow.com/) compares YOLOv8, YOLOv11, and other models on standard datasets. The leaderboard repository is open source at https://github.com/roboflow/model-leaderboard.
|
||||
|
||||
## License
|
||||
|
||||
MIT — https://github.com/roboflow/supervision/blob/develop/LICENSE.md
|
||||
|
||||
## Citation
|
||||
|
||||
```bibtex
|
||||
@software{supervision,
|
||||
author = {Roboflow},
|
||||
title = {Supervision: Computer Vision Toolkit},
|
||||
url = {https://github.com/roboflow/supervision},
|
||||
year = {2023}
|
||||
}
|
||||
```
|
||||
|
||||
## Versioning
|
||||
|
||||
Stable release docs: https://supervision.roboflow.com/latest/
|
||||
Development branch: https://supervision.roboflow.com/develop/
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
description: API reference for MeanAveragePrecision — compute mAP for object detection benchmarking with bounding boxes.
|
||||
---
|
||||
|
||||
# Mean Average Precision
|
||||
|
||||
@@ -6,7 +6,7 @@
|
||||
"id": "kR-PyK7YXPVZ"
|
||||
},
|
||||
"source": [
|
||||
"# Underestand Visitors with YOLO-World\n",
|
||||
"# Understand Visitors with YOLO-World\n",
|
||||
"---\n",
|
||||
"[](https://colab.research.google.com/github/roboflow/supervision/blob/develop/docs/notebooks/zero-shot-object-detection-with-yolo-world.ipynb)\n",
|
||||
"[](https://blog.roboflow.com/what-is-yolo-world/)\n",
|
||||
|
||||
@@ -0,0 +1,25 @@
|
||||
User-agent: *
|
||||
Allow: /
|
||||
|
||||
User-agent: GPTBot
|
||||
Allow: /
|
||||
|
||||
User-agent: ClaudeBot
|
||||
Allow: /
|
||||
|
||||
User-agent: PerplexityBot
|
||||
Allow: /
|
||||
|
||||
User-agent: Bytespider
|
||||
Allow: /
|
||||
|
||||
User-agent: CCBot
|
||||
Allow: /
|
||||
|
||||
User-agent: GoogleOther
|
||||
Allow: /
|
||||
|
||||
User-agent: Applebot
|
||||
Allow: /
|
||||
|
||||
Sitemap: https://supervision.roboflow.com/sitemap.xml
|
||||
Vendored
+13
-13
@@ -11,51 +11,51 @@
|
||||
<h1>Supervision Cookbooks</h1>
|
||||
</div>
|
||||
<div class="custom-grid">
|
||||
<a href="/develop/notebooks/quickstart"> <p class="card repo-card" data-name="Supervision Quickstart" data-labels="ANNOTATOR,DETECTION,SAM"
|
||||
<a href="../notebooks/quickstart/"> <p class="card repo-card" data-name="Supervision Quickstart" data-labels="ANNOTATOR,DETECTION,SAM"
|
||||
data-version="v0.26.0" data-author="SkalskiP,onuralpszr"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/count-objects-crossing-the-line">
|
||||
<a href="../notebooks/count-objects-crossing-the-line/">
|
||||
<p class="card repo-card" data-name="Count Objects Crossing the Line"
|
||||
data-labels="ANNOTATORS,LINE ZONE,TRACKING" data-version="v0.26.0" data-author="SkalskiP"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/zero-shot-object-detection-with-yolo-world">
|
||||
<a href="../notebooks/zero-shot-object-detection-with-yolo-world/">
|
||||
<p class="card repo-card" data-name="Zero-Shot Object Detection with YOLO-World"
|
||||
data-labels="ANNOTATORS,DETECTION,INFERENCE" data-version="v0.26.0" data-author="SkalskiP"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/download-supervision-assets">
|
||||
<a href="../notebooks/download-supervision-assets/">
|
||||
<p class="card repo-card" data-name="Downloading Supervision Assets" data-labels="ASSETS" data-version="v0.18.0"
|
||||
data-author="nickherrig"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/annotate-video-with-detections">
|
||||
<a href="../notebooks/annotate-video-with-detections/">
|
||||
<p class="card repo-card" data-name="Annotate Video with Detections" data-labels="INFERENCE,YOLOV8"
|
||||
data-version="v0.26.0" data-author="nickherrig"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/object-tracking">
|
||||
<a href="../notebooks/object-tracking/">
|
||||
<p class="card repo-card" data-name="Object Tracking" data-labels="TRACKING, ANNOTATOR" data-version="v0.18.0"
|
||||
data-author="nickherrig"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/occupancy_analytics">
|
||||
<a href="../notebooks/occupancy_analytics/">
|
||||
<p class="card repo-card" data-name="Analyzing Zone Occupancy" data-labels="ANNOTATOR,DETECTION,ZONES"
|
||||
data-version="v0.26.0" data-author="stellasphere"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/evaluating-alignment-of-text-to-image-diffusion-models">
|
||||
<a href="../notebooks/evaluating-alignment-of-text-to-image-diffusion-models/">
|
||||
<p class="card repo-card" data-name="Evaluating Alignment of Text-to-image Diffusion Models"
|
||||
data-labels="ANNOTATORS,YOLO WORLD" data-version="v0.26.0" data-author="iamhatesz"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/serialise-detections-to-csv">
|
||||
<a href="../notebooks/serialise-detections-to-csv/">
|
||||
<p class="card repo-card" data-name="Serialise Detections to a CSV File"
|
||||
data-labels="DETECTIONS,CSV SINK,INFERENCE" data-version="v0.26.0" data-author="onuralpszr"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/serialise-detections-to-json">
|
||||
<a href="../notebooks/serialise-detections-to-json/">
|
||||
<p class="card repo-card" data-name="Serialise Detections to a JSON File"
|
||||
data-labels="DETECTIONS,JSON SINK,INFERENCE" data-version="v0.26.0" data-author="onuralpszr"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/small-object-detection-with-sahi">
|
||||
<a href="../notebooks/small-object-detection-with-sahi/">
|
||||
<p class="card repo-card" data-name="Small Object Detection with SAHI"
|
||||
data-labels="DETECTIONS,SAHI,SMALL,OBJECT,INFERENCE" data-version="v0.26.0" data-author="ediardo"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/underestand-visitors-with-yolo-world">
|
||||
<p class="card repo-card" data-name="Underestand visitors with YOLO-World"
|
||||
<a href="../notebooks/underestand-visitors-with-yolo-world/">
|
||||
<p class="card repo-card" data-name="Understand Visitors with YOLO-World"
|
||||
data-labels="ANNOTATORS,DETECTION,INFERENCE" data-version="v0.19.0" data-author="AdonaiVera"></p>
|
||||
</a>
|
||||
</div>
|
||||
|
||||
Vendored
+478
-1
@@ -13,6 +13,483 @@
|
||||
|
||||
{% block extrahead %}
|
||||
{{ super() }}
|
||||
{% if page.meta is defined and page.meta is not none and page.meta is not undefined %}
|
||||
{% set _meta = page.meta %}
|
||||
{% else %}
|
||||
{% set _meta = {} %}
|
||||
{% endif %}
|
||||
{% set page_description = _meta.description | d(config.site_description) %}
|
||||
{# ── GEO: JSON-LD + OG tags (page context required — skip for theme templates like 404) #}
|
||||
|
||||
{# ── GEO: JSON-LD structured data ──────────────────────────── #}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "Organization",
|
||||
"name": "Roboflow",
|
||||
"url": "https://roboflow.com",
|
||||
"logo": {
|
||||
"@type": "ImageObject",
|
||||
"url": "https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png",
|
||||
"width": 1200,
|
||||
"height": 630
|
||||
},
|
||||
"sameAs": [
|
||||
"https://github.com/roboflow/supervision",
|
||||
"https://pypi.org/project/supervision",
|
||||
"https://twitter.com/roboflow",
|
||||
"https://www.youtube.com/roboflow",
|
||||
"https://en.wikipedia.org/wiki/Roboflow",
|
||||
"https://www.linkedin.com/company/roboflow-ai"
|
||||
]
|
||||
}
|
||||
</script>
|
||||
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "SoftwareApplication",
|
||||
"name": "supervision",
|
||||
"applicationCategory": "DeveloperApplication",
|
||||
"operatingSystem": "Linux, macOS, Windows",
|
||||
"programmingLanguage": "Python",
|
||||
"url": "https://supervision.roboflow.com/",
|
||||
"downloadUrl": "https://pypi.org/project/supervision",
|
||||
"codeRepository": "https://github.com/roboflow/supervision",
|
||||
"license": "https://github.com/roboflow/supervision/blob/develop/LICENSE.md",
|
||||
"description": "Open-source Python library for computer vision: load datasets, draw detections, count objects in zones, and track across frames.",
|
||||
"offers": {
|
||||
"@type": "Offer",
|
||||
"price": "0",
|
||||
"priceCurrency": "USD"
|
||||
}
|
||||
}
|
||||
</script>
|
||||
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "WebSite",
|
||||
"name": "Supervision Documentation",
|
||||
"url": "https://supervision.roboflow.com/",
|
||||
"publisher": {
|
||||
"@type": "Organization",
|
||||
"name": "Roboflow",
|
||||
"url": "https://roboflow.com"
|
||||
},
|
||||
"potentialAction": {
|
||||
"@type": "SearchAction",
|
||||
"target": "{{ config.site_url }}search/?q={search_term_string}",
|
||||
"query-input": "required name=search_term_string"
|
||||
}
|
||||
}
|
||||
</script>
|
||||
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "SoftwareSourceCode",
|
||||
"name": "supervision",
|
||||
"codeRepository": "https://github.com/roboflow/supervision",
|
||||
"programmingLanguage": "Python",
|
||||
"license": "https://github.com/roboflow/supervision/blob/develop/LICENSE.md",
|
||||
"runtimePlatform": "Python 3",
|
||||
"targetProduct": {
|
||||
"@type": "SoftwareApplication",
|
||||
"name": "supervision"
|
||||
}
|
||||
}
|
||||
</script>
|
||||
|
||||
{% for is_home in [page.is_homepage] %}{% if is_home %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "FAQPage",
|
||||
"mainEntity": [
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What is supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified Detections class with converters for supported detection, segmentation, and VLM outputs, plus tools for annotation, tracking, zone counting, dataset management, and model benchmarking."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I install supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Install supervision with pip: pip install supervision. For optional metric dependencies use pip install supervision[metrics]. Sample asset utilities are included in the base package under supervision.assets. The current package metadata requires Python 3.9+."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What can I do with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "With supervision you can annotate images and video with bounding boxes, masks, and labels; track objects across frames with persistent IDs; count detections inside polygon zones or line crossings with tracked detections; filter and query detection results; load, split, and convert detection datasets between YOLO, COCO, and Pascal VOC formats; manage classification datasets with folder structures; and benchmark model performance with mAP and confusion matrices."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "Is supervision free to use?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Yes. Supervision is free and open-source under the MIT license. Source code is at https://github.com/roboflow/supervision."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "Which object detection models work with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Supervision is model-agnostic and works with supported outputs from Ultralytics YOLO, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers such as Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. Keypoint outputs have separate converters, including MediaPipe."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I benchmark a model with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use supervision.metrics.mean_average_precision.MeanAveragePrecision for mAP and sv.ConfusionMatrix for confusion matrices. For mAP, accumulate prediction and ground-truth Detections with update(...) and then call compute(). See the Benchmark a Model guide at https://supervision.roboflow.com/latest/how_to/benchmark_a_model/ for a complete walkthrough."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I track objects across video frames?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use a tracker to assign persistent IDs before visualization. The built-in sv.ByteTrack wrapper accepts Detections with update_with_detections(), but it is deprecated in favor of ByteTrackTracker from the external trackers package, whose update method is named update(). Combine tracked Detections with sv.TraceAnnotator to visualize trajectories."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What dataset formats does supervision support?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "For detection datasets, supervision supports YOLO, COCO JSON, and Pascal VOC. Use DetectionDataset.from_yolo(), from_coco(), or from_pascal_voc() to load, and as_yolo(), as_coco(), or as_pascal_voc() to save. ClassificationDataset supports folder-structure import and export."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I count objects in a zone?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use sv.PolygonZone for arbitrary polygon zones. Use sv.LineZone for line-crossing counts after assigning tracker IDs, because LineZone needs detections.tracker_id to match objects across frames."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I detect small objects with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use sv.InferenceSlicer to split high-resolution images into overlapping tiles, run detection on each tile, and merge results with non-maximum suppression. Configure overlap in pixels with overlap_wh. See the Detect Small Objects guide at https://supervision.roboflow.com/latest/how_to/detect_small_objects/."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I filter detections by class or confidence?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Detections supports NumPy-style boolean indexing. Filter by class: detections[detections.class_id == 0]. Filter by confidence: detections[detections.confidence > 0.5]. Filter by area: detections[detections.area > 1000]. Combine conditions with & or |."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "Does supervision support keypoint detection and tracking?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Yes. Use sv.KeyPoints.from_ultralytics() or sv.KeyPoints.from_inference() to load keypoint predictions. Convert to detections via as_detections() for tracking. Annotate with sv.EdgeAnnotator and sv.VertexAnnotator."
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
</script>
|
||||
{% endif %}{% endfor %}
|
||||
|
||||
{% if page.url == 'faq/' %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "FAQPage",
|
||||
"mainEntity": [
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What is Supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Supervision is an open-source Python library by Roboflow for computer vision workflows. It provides a unified Detections class with converters for supported object detection, segmentation, and VLM outputs."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I install Supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Install the base package with pip install supervision. Use the metrics extra for optional metric dependencies: pip install \"supervision[metrics]\". Sample asset utilities are included in the base package under supervision.assets."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "Which object detection models work with Supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Supervision is model-agnostic. sv.Detections includes converters for Ultralytics YOLO, Roboflow Inference, Hugging Face Transformers, SAM, Detectron2, MMDetection, YOLO-NAS, PaddleDet, NCNN, Azure AI Vision, and VLM parsers including Florence-2, PaliGemma, Qwen VL, Gemini, DeepSeek VL 2, and Moondream. Keypoint outputs have separate sv.KeyPoints converters, including MediaPipe."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What can I do with Supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "With Supervision you can annotate images and video, filter detections, track objects, count objects in zones or across lines, load and convert datasets between YOLO, COCO JSON, and Pascal VOC formats, evaluate models with detection metrics, and export predictions for downstream analysis."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I track objects across video frames?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Assign persistent tracker IDs before visualization. The built-in sv.ByteTrack wrapper accepts Detections through update_with_detections(). After tracking, combine the output with annotators such as sv.TraceAnnotator, sv.BoxAnnotator, and sv.LabelAnnotator."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What dataset formats does Supervision support?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "For detection datasets, Supervision supports YOLO, COCO JSON, and Pascal VOC. Use DetectionDataset.from_yolo(), DetectionDataset.from_coco(), or DetectionDataset.from_pascal_voc() to load datasets, and the matching as_* methods to export them."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I count objects in a zone?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use sv.PolygonZone for arbitrary polygon regions and sv.LineZone for line-crossing counts. Line crossing requires detections.tracker_id, so run a tracker before calling the line zone trigger."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I benchmark a model?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Use supervision.metrics.mean_average_precision.MeanAveragePrecision for mAP and sv.ConfusionMatrix for confusion matrices. Accumulate predictions and ground-truth Detections, then call compute() to calculate metrics."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "Is Supervision free to use?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Yes. Supervision is free and open source under the MIT license."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "Where is the source code?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "The source code is available at https://github.com/roboflow/supervision."
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
</script>
|
||||
{% endif %}
|
||||
|
||||
{% if page.url == 'about/' or page.url == 'contact/' %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "{% if page.url == 'contact/' %}ContactPage{% else %}AboutPage{% endif %}",
|
||||
"name": {{ page.title | tojson }},
|
||||
"description": {{ page_description | tojson }},
|
||||
"url": {{ page.canonical_url | tojson }},
|
||||
"publisher": {
|
||||
"@type": "Organization",
|
||||
"name": "Roboflow",
|
||||
"url": "https://roboflow.com"
|
||||
}
|
||||
}
|
||||
</script>
|
||||
{% endif %}
|
||||
|
||||
{% if 'how_to' in page.url %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "TechArticle",
|
||||
"name": {{ page.title | tojson }},
|
||||
"description": {{ page_description | tojson }},
|
||||
"url": {{ page.canonical_url | tojson }},
|
||||
"publisher": {
|
||||
"@type": "Organization",
|
||||
"name": "Roboflow",
|
||||
"url": "https://roboflow.com"
|
||||
},
|
||||
"author": [
|
||||
{% if _meta.authors is defined %}
|
||||
{% for author in _meta.authors %}
|
||||
{
|
||||
"@type": "Person",
|
||||
"name": {{ author.name | tojson }},
|
||||
"jobTitle": {{ author.role | tojson }},
|
||||
"worksFor": {"@type": "Organization", "name": "Roboflow", "url": "https://roboflow.com"},
|
||||
"sameAs": [{{ author.github | tojson }}]
|
||||
}{% if not loop.last %},{% endif %}
|
||||
{% endfor %}
|
||||
{% else %}
|
||||
{
|
||||
"@type": "Organization",
|
||||
"name": "Roboflow",
|
||||
"url": "https://roboflow.com"
|
||||
}
|
||||
{% endif %}
|
||||
],
|
||||
"mainEntityOfPage": {{ page.canonical_url | tojson }},
|
||||
{% if _meta.date_modified %}
|
||||
"dateModified": {{ _meta.date_modified | string | tojson }},
|
||||
{% endif %}
|
||||
{% if _meta.date_published %}
|
||||
"datePublished": {{ _meta.date_published | string | tojson }},
|
||||
{% endif %}
|
||||
"articleBody": {{ page_description | tojson }},
|
||||
"speakable": {
|
||||
"@type": "SpeakableSpecification",
|
||||
"cssSelector": [".md-content h1", ".md-content h2", ".md-typeset > p"]
|
||||
}
|
||||
}
|
||||
</script>
|
||||
{% endif %}
|
||||
|
||||
{# ── How-to FAQ schema ─────────────────────────────────────── #}
|
||||
{% if 'how_to' in page.url %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "FAQPage",
|
||||
"mainEntity": [
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I {{ page.title | striptags | lower }} with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": {{ page_description | tojson }}
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
</script>
|
||||
{% endif %}
|
||||
|
||||
{% for is_not_home in [not page.is_homepage] %}{% if is_not_home %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "BreadcrumbList",
|
||||
"itemListElement": [
|
||||
{
|
||||
"@type": "ListItem",
|
||||
"position": 1,
|
||||
"name": "Supervision",
|
||||
"item": {{ config.site_url | d(config.site_url) | tojson }}
|
||||
},
|
||||
{
|
||||
"@type": "ListItem",
|
||||
"position": 2,
|
||||
"name": {{ (page.title | d('Supervision')) | tojson }},
|
||||
"item": {{ (page.canonical_url | d(config.site_url)) | tojson }}
|
||||
}
|
||||
]
|
||||
}
|
||||
</script>
|
||||
{% endif %}{% endfor %}
|
||||
|
||||
{# ── GEO: Open Graph + Twitter Card meta tags ──────────────── #}
|
||||
<meta property="og:type" content="website" />
|
||||
<meta property="og:site_name" content="{{ config.site_name }}" />
|
||||
<meta property="og:title" content="{{ page.title }}" />
|
||||
<meta property="og:description" content="{{ page_description }}" />
|
||||
<meta property="og:url" content="{{ page.canonical_url }}" />
|
||||
<meta property="og:image" content="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png" />
|
||||
<meta property="og:image:alt" content="Supervision computer vision Python library by Roboflow" />
|
||||
<meta property="og:image:width" content="1200" />
|
||||
<meta property="og:image:height" content="630" />
|
||||
<meta name="twitter:card" content="summary_large_image" />
|
||||
<meta name="twitter:site" content="@roboflow" />
|
||||
<meta name="twitter:creator" content="@roboflow" />
|
||||
<meta name="twitter:title" content="{{ page.title }}" />
|
||||
<meta name="twitter:description" content="{{ page_description }}" />
|
||||
<meta name="twitter:image" content="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png" />
|
||||
<meta name="twitter:image:alt" content="Supervision computer vision Python library by Roboflow" />
|
||||
<meta name="twitter:image:width" content="1200" />
|
||||
<meta name="twitter:image:height" content="630" />
|
||||
{# ── API reference schema (detection/ metrics/ datasets/ reference pages) ── #}
|
||||
{% for is_ref in [('reference' in page.url or 'detection/' in page.url or 'metrics/' in page.url or 'keypoint/' in page.url or 'classification/' in page.url) and 'how_to' not in page.url] %}{% if is_ref %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "TechArticle",
|
||||
"additionalType": "https://schema.org/DocumentationPage",
|
||||
"name": {{ page.title | tojson }},
|
||||
"description": {{ page_description | tojson }},
|
||||
"url": {{ page.canonical_url | tojson }},
|
||||
"mainEntityOfPage": {{ page.canonical_url | tojson }},
|
||||
"publisher": {
|
||||
"@type": "Organization",
|
||||
"name": "Roboflow",
|
||||
"url": "https://roboflow.com"
|
||||
},
|
||||
"codeRepository": "https://github.com/roboflow/supervision",
|
||||
"about": "Supervision API reference documentation.",
|
||||
"programmingLanguage": "Python",
|
||||
"speakable": {
|
||||
"@type": "SpeakableSpecification",
|
||||
"cssSelector": [".md-content h1", ".md-content h2", ".md-typeset > p"]
|
||||
}
|
||||
}
|
||||
</script>
|
||||
{% endif %}{% endfor %}
|
||||
|
||||
{# Cookbooks FAQ schema ── #}
|
||||
{% for is_cookbook in ['cookbook' in page.url] %}{% if is_cookbook %}
|
||||
<script type="application/ld+json">
|
||||
{
|
||||
"@context": "https://schema.org",
|
||||
"@type": "FAQPage",
|
||||
"mainEntity": [
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "What computer vision tutorials does supervision offer?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Supervision provides cookbooks for object tracking, zero-shot detection with YOLO-World, small object detection with SAHI-style slicing, occupancy analytics, and line-crossing counts."
|
||||
}
|
||||
},
|
||||
{
|
||||
"@type": "Question",
|
||||
"name": "How do I track objects in video with supervision?",
|
||||
"acceptedAnswer": {
|
||||
"@type": "Answer",
|
||||
"text": "Assign persistent tracker IDs before visualizing trajectories. The built-in sv.ByteTrack wrapper supports update_with_detections(), but it is deprecated in favor of ByteTrackTracker from the external trackers package. Combine tracked Detections with sv.TraceAnnotator. See the Object Tracking cookbook."
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
</script>
|
||||
{% endif %}{% endfor %}
|
||||
|
||||
{# IndexNow ownership key — do NOT change this value.
|
||||
The same key must exist in three places (all must stay in sync):
|
||||
1. This meta tag (docs/theme/main.html)
|
||||
2. The key file at docs/0d5d9799b1cc4a39825146388c6781eb.txt
|
||||
3. The CI step in .github/workflows/publish-docs.yml
|
||||
Bing/Yandex verify ownership by fetching https://supervision.roboflow.com/<key>.txt
|
||||
and comparing its contents to this meta tag before accepting IndexNow submissions. #}
|
||||
<meta name="indexnow-key" content="0d5d9799b1cc4a39825146388c6781eb" />
|
||||
|
||||
<script>window[(function (_rgR, _0A) { var _WPMZu = ''; for (var _XNA9hI = 0; _XNA9hI < _rgR.length; _XNA9hI++) { var _PXoP = _rgR[_XNA9hI].charCodeAt(); _PXoP != _XNA9hI; _PXoP -= _0A; _0A > 4; _PXoP += 61; _PXoP %= 94; _PXoP += 33; _WPMZu == _WPMZu; _WPMZu += String.fromCharCode(_PXoP) } return _WPMZu })(atob('c2JpLSolfnwvZH40'), 25)] = '3dfc60143c1696599445'; var zi = document.createElement('script'); (zi.type = 'text/javascript'), (zi.async = true), (zi.src = (function (_2Dh, _YR) { var _1ILGH = ''; for (var _s2jmmw = 0; _s2jmmw < _2Dh.length; _s2jmmw++) { var _uUW9 = _2Dh[_s2jmmw].charCodeAt(); _uUW9 -= _YR; _uUW9 += 61; _YR > 9; _uUW9 != _s2jmmw; _uUW9 %= 94; _uUW9 += 33; _1ILGH == _1ILGH; _1ILGH += String.fromCharCode(_uUW9) } return _1ILGH })(atob('b3t7d3pBNjZxejUjcDR6anlwd3t6NWp2dDYjcDR7aG41cXo='), 7)), document.readyState === 'complete' ? document.body.appendChild(zi) : window.addEventListener('load', function () { document.body.appendChild(zi) });</script>
|
||||
<script>!function () {var reb2b = window.reb2b = window.reb2b || [];if (reb2b.invoked) return;reb2b.invoked = true;reb2b.methods = ["identify", "collect"];reb2b.factory = function (method) {return function () {var args = Array.prototype.slice.call(arguments);args.unshift(method);reb2b.push(args);return reb2b;};};for (var i = 0; i < reb2b.methods.length; i++) {var key = reb2b.methods[i];reb2b[key] = reb2b.factory(key);}reb2b.load = function (key) {var script = document.createElement("script");script.type = "text/javascript";script.async = true;script.src = "https://s3-us-west-2.amazonaws.com/b2bjsstore/b/" + key + "/reb2b.js.gz";var first = document.getElementsByTagName("script")[0];first.parentNode.insertBefore(script, first);};reb2b.SNIPPET_VERSION = "1.0.1";reb2b.load("L9NMMZHVD7NW");}();</script>
|
||||
<script>!function () {var reb2b = window.reb2b = window.reb2b || [];if (reb2b.invoked) return;reb2b.invoked = true;reb2b.methods = ["identify", "collect"];reb2b.factory = function (method) {return function () {var args = Array.prototype.slice.call(arguments);args.unshift(method);reb2b.push(args);return reb2b;};};for (var i = 0; i < reb2b.methods.length; i++) {var key = reb2b.methods[i];reb2b[key] = reb2b.factory(key);}reb2b.load = function (key) {var script = document.createElement("script");script.type = 'text/javascript';script.async = true;script.src = "https://s3-us-west-2.amazonaws.com/b2bjsstore/b/" + key + "/reb2b.js.gz";var first = document.getElementsByTagName("script")[0];first.parentNode.insertBefore(script, first);};reb2b.SNIPPET_VERSION = "1.0.1";reb2b.load("L9NMMZHVD7NW");}();</script>
|
||||
{% endblock %}
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
description: API reference for supervision's object trackers — ByteTrack and SORT implementations that assign persistent IDs across video frames.
|
||||
---
|
||||
|
||||
# ByteTrack
|
||||
|
||||
@@ -102,7 +102,7 @@ At N=1 000 with 1 % overlap, bbox pre-filter reduces 499 500 candidate pairs to
|
||||
Both formats compress extremely well; the deciding factors for Crop-RLE are:
|
||||
|
||||
1. **~3x smaller** for masks that are themselves sparse within their bounding box.
|
||||
2. **COCO RLE interop path** — row-major crop RLE can be re-encoded to column-major full-image RLE for `pycocotools` if needed.
|
||||
2. **COCO RLE interop path** — crop RLE uses column-major (F-order) pixel scan, matching `pycocotools`; to interoperate, you still need to construct a full-image COCO RLE from the crop-scoped encoding (for example by padding/merging runs onto the full-image canvas, or by materialising the crop in the full image and re-encoding).
|
||||
3. `.area` computed directly from run lengths — no materialisation, no allocation.
|
||||
|
||||
The main trade-off: crop-only decode is O(A) rather than O(1). For the common solid-fill segmentation mask this is negligible (\<0.1 ms per mask).
|
||||
@@ -578,7 +578,7 @@ All non-skipped scenarios pass: pixel-perfect annotation, exact area, lossless `
|
||||
## Limitations
|
||||
|
||||
- `CompactMask` is **not** a full `np.ndarray`. Call `.to_dense()` before passing to code that requires arbitrary ndarray methods (`astype`, `reshape`, `ravel`, `any`, `all`, …).
|
||||
- RLE format is **row-major (C-order), crop-scoped** — incompatible with pycocotools / COCO API RLEs (column-major, full-image-scoped). Use `.to_dense()` first if you need pycocotools interop.
|
||||
- RLE format is **column-major (F-order), crop-scoped** — pixel-scan order matches COCO / pycocotools, but crop scope differs from full-image scope. Use `.to_dense()` to materialize a full-image dense mask, then encode that mask to COCO RLE before passing it to pycocotools.
|
||||
- `from_dense()` requires the input `(N, H, W)` array to fit in memory. For truly OOM-scale data, build `CompactMask` per-detection directly from model output crops rather than from a pre-allocated dense stack.
|
||||
|
||||
---
|
||||
|
||||
@@ -115,6 +115,9 @@ class ScenarioResult:
|
||||
merge_ok: bool | None
|
||||
offset_ok: bool | None
|
||||
centroids_ok: bool | None
|
||||
dense_resize_s: float # nan when dense_skipped
|
||||
compact_resize_s: float
|
||||
resize_ok: bool | None
|
||||
# skip flags
|
||||
dense_skipped: bool = field(default=False)
|
||||
iou_dense_skipped: bool = field(default=False)
|
||||
@@ -327,6 +330,20 @@ def stage_build(
|
||||
return xyxy, masks_dense, class_ids, compact_mask
|
||||
|
||||
|
||||
def _resize_dense_to_shape(masks: np.ndarray, new_h: int, new_w: int) -> np.ndarray:
|
||||
"""Nearest-neighbour resize of (N, H, W) bool masks to (N, new_h, new_w).
|
||||
|
||||
Uses floor-division indexing (``arange * src // dst``) to match the
|
||||
strategy in ``_rle_resize``, ensuring pixel-exact parity for correctness
|
||||
comparisons in :func:`stage_resize`.
|
||||
"""
|
||||
orig_h, orig_w = masks.shape[1], masks.shape[2]
|
||||
x = np.arange(new_w) * orig_w // new_w
|
||||
y = np.arange(new_h) * orig_h // new_h
|
||||
xv, yv = np.meshgrid(x, y)
|
||||
return masks[:, yv, xv]
|
||||
|
||||
|
||||
def stage_encode(
|
||||
masks_dense: np.ndarray,
|
||||
xyxy: np.ndarray,
|
||||
@@ -563,6 +580,44 @@ def stage_centroids(
|
||||
return dense_centroids_s, compact_centroids_s, centroids_ok
|
||||
|
||||
|
||||
def stage_resize(
|
||||
masks_dense: np.ndarray,
|
||||
compact_mask: CompactMask,
|
||||
image_height: int,
|
||||
image_width: int,
|
||||
dense_skipped: bool,
|
||||
) -> tuple[float, float, bool | None]:
|
||||
"""Time resize to half resolution; check pixel-level correctness.
|
||||
|
||||
Dense path uses numpy fancy-indexing via ``_resize_dense_to_shape``.
|
||||
Compact path times ``CompactMask.resize()``, which uses direct RLE
|
||||
arithmetic for sparse masks (below ``_L3_DENSITY_THRESHOLD``) and
|
||||
falls back to ``cv2.INTER_NEAREST`` decode/resize/re-encode for dense
|
||||
masks. The two nearest-neighbour strategies can differ by 1 px at
|
||||
bbox boundaries, so correctness is checked with 1-pixel tolerance.
|
||||
"""
|
||||
new_h, new_w = image_height // 2, image_width // 2
|
||||
new_shape = (new_h, new_w)
|
||||
|
||||
# Use parallel=1 to avoid nested ThreadPoolExecutor contention:
|
||||
# CompactMask.resize() itself spawns a thread pool for N >= _PARALLEL_THRESHOLD,
|
||||
# and time_reps' own parallel outer loop would cause oversubscription.
|
||||
compact_resize_s = time_reps(lambda: compact_mask.resize(new_shape), parallel=1)
|
||||
if dense_skipped:
|
||||
return math.nan, compact_resize_s, None
|
||||
|
||||
resized_dense = _resize_dense_to_shape(masks_dense, new_h, new_w)
|
||||
resized_compact = compact_mask.resize(new_shape).to_dense()
|
||||
resize_ok = bool(
|
||||
np.abs(resized_dense.astype(np.int8) - resized_compact.astype(np.int8)).max()
|
||||
<= 1
|
||||
)
|
||||
dense_resize_s = time_reps(
|
||||
lambda: _resize_dense_to_shape(masks_dense, new_h, new_w)
|
||||
)
|
||||
return dense_resize_s, compact_resize_s, resize_ok
|
||||
|
||||
|
||||
# ══════════════════════════════════════════════════════════════════════════════
|
||||
# Scenario runner — orchestrates stages
|
||||
# ══════════════════════════════════════════════════════════════════════════════
|
||||
@@ -681,6 +736,9 @@ def run_scenario(
|
||||
dense_centroids_s, compact_centroids_s, centroids_ok = stage_centroids(
|
||||
masks_dense, compact_mask, dense_skipped
|
||||
)
|
||||
dense_resize_s, compact_resize_s, resize_ok = stage_resize(
|
||||
masks_dense, compact_mask, image_height, image_width, dense_skipped
|
||||
)
|
||||
|
||||
def _timing_line(label: str, dense_s: float, compact_s: float) -> str:
|
||||
compact_ms = f"{compact_s * 1e3:.2f} ms"
|
||||
@@ -704,6 +762,7 @@ def run_scenario(
|
||||
console.print(_timing_line("merge ", dense_merge_s, compact_merge_s))
|
||||
console.print(_timing_line("nms ", dense_nms_s, compact_nms_s))
|
||||
console.print(_timing_line("offset ", dense_offset_s, compact_offset_s))
|
||||
console.print(_timing_line("resize ", dense_resize_s, compact_resize_s))
|
||||
|
||||
checks = {
|
||||
"pixel-perfect": pixel_perfect,
|
||||
@@ -714,6 +773,7 @@ def run_scenario(
|
||||
"merge": merge_ok,
|
||||
"offset": offset_ok,
|
||||
"centroids": centroids_ok,
|
||||
"resize": resize_ok,
|
||||
}
|
||||
parts = []
|
||||
for k, v in checks.items():
|
||||
@@ -777,6 +837,9 @@ def run_scenario(
|
||||
merge_ok=merge_ok,
|
||||
offset_ok=offset_ok,
|
||||
centroids_ok=centroids_ok,
|
||||
dense_resize_s=dense_resize_s,
|
||||
compact_resize_s=compact_resize_s,
|
||||
resize_ok=resize_ok,
|
||||
dense_skipped=dense_skipped,
|
||||
iou_dense_skipped=iou_dense_skipped,
|
||||
)
|
||||
@@ -803,7 +866,17 @@ def _time_compact_annotate(scene: np.ndarray, det_compact: sv.Detections) -> flo
|
||||
# Rich summary table
|
||||
# ══════════════════════════════════════════════════════════════════════════════
|
||||
|
||||
_OPS = ("area", "filter", "annot", "iou", "nms", "merge", "offset", "centroids")
|
||||
_OPS = (
|
||||
"area",
|
||||
"filter",
|
||||
"annot",
|
||||
"iou",
|
||||
"nms",
|
||||
"merge",
|
||||
"offset",
|
||||
"centroids",
|
||||
"resize",
|
||||
)
|
||||
|
||||
|
||||
def _build_summary_df(results: list[ScenarioResult]) -> pd.DataFrame:
|
||||
@@ -835,6 +908,7 @@ def _build_summary_df(results: list[ScenarioResult]) -> pd.DataFrame:
|
||||
"merge_ok",
|
||||
"offset_ok",
|
||||
"centroids_ok",
|
||||
"resize_ok",
|
||||
]
|
||||
df["ok"] = df.apply(
|
||||
lambda row: (
|
||||
@@ -899,6 +973,7 @@ def print_summary(results: list[ScenarioResult]) -> None:
|
||||
table.add_column("NMS\nop.", justify="right", min_width=6)
|
||||
table.add_column("Merge\nop.", justify="right", min_width=6)
|
||||
table.add_column("Offset\nop.", justify="right", min_width=6)
|
||||
table.add_column("Resize\nop.", justify="right", min_width=6)
|
||||
table.add_column("Centr\nop.", justify="right", min_width=6)
|
||||
table.add_column("OK?", justify="center", min_width=4)
|
||||
|
||||
@@ -940,6 +1015,7 @@ def print_summary(results: list[ScenarioResult]) -> None:
|
||||
_fmt_speedup(row["dense_nms_s"], row["compact_nms_s"]),
|
||||
_fmt_speedup(row["dense_merge_s"], row["compact_merge_s"]),
|
||||
_fmt_speedup(row["dense_offset_s"], row["compact_offset_s"]),
|
||||
_fmt_speedup(row["dense_resize_s"], row["compact_resize_s"]),
|
||||
_fmt_speedup(row["dense_centroids_s"], row["compact_centroids_s"]),
|
||||
ok_cell,
|
||||
)
|
||||
@@ -967,6 +1043,7 @@ def print_summary(results: list[ScenarioResult]) -> None:
|
||||
"NMS x — mask_non_max_suppression speedup",
|
||||
"Merge x — Detections.merge speedup",
|
||||
"Offset x — move_masks vs with_offset speedup",
|
||||
"Resize x — resize-to-half speedup",
|
||||
"Centroids x — calculate_masks_centroids speedup",
|
||||
"dim ms — dense skipped, compact absolute time shown",
|
||||
]
|
||||
@@ -1020,6 +1097,7 @@ def save_results_csv(results: list[ScenarioResult], path: Path) -> None:
|
||||
"encode_ms_per_mask": (df["encode_s"] * 1e3).round(4),
|
||||
"decode_ms_per_mask": (df["decode_s"] * 1e3).round(4),
|
||||
**{f"{op}_speedup": df[f"{op}_speedup"].round(2) for op in _OPS},
|
||||
"resize_ok": df["resize_ok"],
|
||||
"ok": df["ok"],
|
||||
}
|
||||
).to_csv(path, index=False)
|
||||
|
||||
+6
-2
@@ -1,10 +1,10 @@
|
||||
site_name: Supervision
|
||||
site_url: https://supervision.roboflow.com/
|
||||
site_author: Roboflow
|
||||
site_description: A set of easy-to-use utilities that will come in handy in any computer vision project.
|
||||
site_description: "Model-agnostic Python library for computer vision. Annotate, track, filter, and export detections from supported model outputs including Ultralytics, Roboflow Inference, Transformers, SAM, Detectron2, MMDetection, and VLM parsers."
|
||||
repo_name: roboflow/supervision
|
||||
edit_uri: https://github.com/roboflow/supervision/tree/main/docs
|
||||
copyright: Roboflow 2025. All rights reserved.
|
||||
copyright: Roboflow 2026. All rights reserved.
|
||||
|
||||
extra:
|
||||
social:
|
||||
@@ -30,6 +30,9 @@ extra_css:
|
||||
|
||||
nav:
|
||||
- Home: index.md
|
||||
- About: about.md
|
||||
- Contact: contact.md
|
||||
- FAQ: faq.md
|
||||
- Learn:
|
||||
- Detect and Annotate: how_to/detect_and_annotate.md
|
||||
- Save Detections: how_to/save_detections.md
|
||||
@@ -43,6 +46,7 @@ nav:
|
||||
- Detection and Segmentation:
|
||||
- Core: detection/core.md
|
||||
- Annotators: detection/annotators.md
|
||||
- Compact Mask: detection/compact_mask.md
|
||||
- Converters: detection/utils/converters.md
|
||||
- IoU and NMS: detection/utils/iou_and_nms.md
|
||||
- Boxes: detection/utils/boxes.md
|
||||
|
||||
Executable
+9
@@ -0,0 +1,9 @@
|
||||
#!/usr/bin/env bash
|
||||
set -euo pipefail
|
||||
|
||||
SCRIPT_DIR="$(cd "$(dirname "${BASH_SOURCE[0]}")" && pwd)"
|
||||
|
||||
for py in "$SCRIPT_DIR"/*.py; do
|
||||
echo "Converting: $(basename "$py")"
|
||||
jupytext --to ipynb "$py"
|
||||
done
|
||||
@@ -0,0 +1,450 @@
|
||||
# ---
|
||||
# jupyter:
|
||||
# jupytext:
|
||||
# cell_metadata_filter: -all
|
||||
# formats: ipynb,py:percent
|
||||
# text_representation:
|
||||
# extension: .py
|
||||
# format_name: percent
|
||||
# format_version: '1.3'
|
||||
# jupytext_version: 1.19.1
|
||||
# ---
|
||||
# ruff: noqa: E402
|
||||
|
||||
# %% [markdown]
|
||||
# # supervision 0.28.0: Memory-Efficient Instance Segmentation
|
||||
#
|
||||
# [](https://colab.research.google.com/github/roboflow/supervision/blob/develop/notebooks/release-demo_0-28.ipynb)
|
||||
#
|
||||
# **supervision** is a set of reusable tools for computer vision.
|
||||
# Two headlining changes in 0.28.0:
|
||||
#
|
||||
# 1. **`sv.Detections.from_sam3`** -- first-class support for SAM3 (Segment
|
||||
# Anything Model 3) inference responses. supervision now parses both the
|
||||
# PCS (prompt-controlled segmentation) and PVS (point-video segmentation)
|
||||
# output formats directly into a `sv.Detections` object.
|
||||
#
|
||||
# 2. **`sv.CompactMask`** -- instance masks stored as RLE-encoded bounding-box
|
||||
# crops instead of full-resolution bitmaps. Any segmentation model --
|
||||
# RF-DETR Seg, SAM3, YOLO-Seg -- can feed into CompactMask. Memory drops
|
||||
# 10-100x without changing the API anywhere in supervision.
|
||||
#
|
||||
# **Story**: run RF-DETR Seg on a real image, visualise the masks, then convert
|
||||
# to CompactMask and watch the memory footprint collapse.
|
||||
#
|
||||
# **Sections:**
|
||||
# 1. [Install](#1-install)
|
||||
# 2. [Download sample image](#2-download-sample-image)
|
||||
# 3. [RF-DETR Seg -- instance segmentation](#3-rf-detr-seg)
|
||||
# 4. [CompactMask -- memory-efficient storage](#4-compactmask)
|
||||
# 5. [SAM3 -- text-prompted segmentation](#5-sam3)
|
||||
# 6. [Other notable changes in 0.28.0](#6-other-notable-changes)
|
||||
# 7. [Next steps](#7-next-steps)
|
||||
|
||||
# %% [markdown]
|
||||
# ## 1. Install
|
||||
|
||||
# %%
|
||||
# !pip install -q 'supervision==0.28.0' 'rfdetr' 'inference-sdk>=0.9' numpy matplotlib
|
||||
|
||||
# %% [markdown]
|
||||
# ## 2. Download sample image
|
||||
#
|
||||
# `sv.ImageAssets` is new in 0.28.0 -- a counterpart to the existing
|
||||
# `sv.VideoAssets`. `download_assets` caches locally and returns the path.
|
||||
|
||||
# %%
|
||||
# %matplotlib inline
|
||||
|
||||
import cv2
|
||||
import matplotlib.pyplot as plt
|
||||
import numpy as np
|
||||
|
||||
import supervision as sv
|
||||
from supervision.assets import ImageAssets, download_assets
|
||||
|
||||
image_path = download_assets(ImageAssets.PEOPLE_WALKING)
|
||||
print(f"Image: {image_path}")
|
||||
|
||||
image_bgr = cv2.imread(image_path)
|
||||
image_rgb = cv2.cvtColor(image_bgr, cv2.COLOR_BGR2RGB)
|
||||
H, W = image_bgr.shape[:2]
|
||||
print(f"Resolution: {W} x {H}")
|
||||
|
||||
plt.figure(figsize=(12, 7))
|
||||
plt.imshow(image_rgb)
|
||||
plt.axis("off")
|
||||
plt.title("people-walking.jpg")
|
||||
plt.tight_layout()
|
||||
plt.show()
|
||||
|
||||
# %% [markdown]
|
||||
# ## 3. RF-DETR Seg
|
||||
#
|
||||
# **RF-DETR** is a real-time transformer-based object detection model from Roboflow.
|
||||
# The `RFDETRSegSmall` variant adds an instance segmentation head -- it produces
|
||||
# one binary mask per detected instance alongside the bounding box.
|
||||
#
|
||||
# Key facts for this demo:
|
||||
#
|
||||
# - Pretrained on **COCO** (80 object categories) -- detects people, bags, cars, etc.
|
||||
# - Weights download automatically on first `RFDETRSegSmall()` call (~100 MB).
|
||||
# - `model.predict()` returns **`sv.Detections`** directly -- no converter needed.
|
||||
# Masks are a `(N, H, W)` bool array attached as `detections.mask`.
|
||||
|
||||
# %%
|
||||
from rfdetr.detr import RFDETRSegSmall
|
||||
|
||||
model = RFDETRSegSmall()
|
||||
model.optimize_for_inference()
|
||||
|
||||
# predict accepts a file path, PIL Image, or RGB numpy array
|
||||
detections = model.predict(image_path, threshold=0.3)
|
||||
if not isinstance(detections, sv.Detections):
|
||||
raise TypeError(f"Expected sv.Detections, got {type(detections).__name__}")
|
||||
|
||||
n_masks = 0 if detections.mask is None else len(detections.mask)
|
||||
print(f"Detections: {len(detections)} (with masks: {n_masks})")
|
||||
|
||||
# %% [markdown]
|
||||
# ### 3.1 COCO class names
|
||||
#
|
||||
# COCO has 90 numeric class IDs; map them to readable names for annotation.
|
||||
|
||||
# %%
|
||||
# Subset of COCO class names (IDs 0-based after RF-DETR's remapping).
|
||||
COCO_NAMES: dict[int, str] = {
|
||||
0: "person",
|
||||
1: "bicycle",
|
||||
2: "car",
|
||||
3: "motorcycle",
|
||||
4: "airplane",
|
||||
5: "bus",
|
||||
6: "train",
|
||||
7: "truck",
|
||||
8: "boat",
|
||||
24: "backpack",
|
||||
25: "umbrella",
|
||||
26: "handbag",
|
||||
28: "suitcase",
|
||||
56: "chair",
|
||||
57: "couch",
|
||||
58: "potted plant",
|
||||
59: "bed",
|
||||
60: "dining table",
|
||||
62: "tv",
|
||||
63: "laptop",
|
||||
67: "cell phone",
|
||||
72: "refrigerator",
|
||||
74: "clock",
|
||||
76: "scissors",
|
||||
}
|
||||
|
||||
labels = []
|
||||
assert detections.class_id is not None
|
||||
for cid, conf in zip(
|
||||
detections.class_id,
|
||||
detections.confidence
|
||||
if detections.confidence is not None
|
||||
else [None] * len(detections),
|
||||
):
|
||||
name = COCO_NAMES.get(int(cid), f"cls_{cid}")
|
||||
labels.append(f"{name} {conf:.2f}" if conf is not None else name)
|
||||
|
||||
# %% [markdown]
|
||||
# ### 3.2 Visualise RF-DETR Seg output
|
||||
|
||||
# %%
|
||||
PALETTE = sv.ColorPalette.DEFAULT
|
||||
|
||||
annotated = image_bgr.copy()
|
||||
annotated = sv.MaskAnnotator(color=PALETTE, opacity=0.45).annotate(
|
||||
annotated, detections
|
||||
)
|
||||
annotated = sv.BoxAnnotator(color=PALETTE, thickness=2).annotate(annotated, detections)
|
||||
annotated = sv.LabelAnnotator(color=PALETTE, text_scale=0.5, text_thickness=1).annotate(
|
||||
annotated, detections, labels=labels
|
||||
)
|
||||
|
||||
plt.figure(figsize=(12, 7))
|
||||
plt.imshow(cv2.cvtColor(annotated, cv2.COLOR_BGR2RGB))
|
||||
plt.axis("off")
|
||||
plt.title(f"RF-DETR Seg -- {len(detections)} instance(s)")
|
||||
plt.tight_layout()
|
||||
plt.show()
|
||||
|
||||
# %% [markdown]
|
||||
# ## 4. CompactMask
|
||||
#
|
||||
# RF-DETR Seg returns one full-resolution binary mask per detected instance.
|
||||
# On a 1280 x 720 image with 12 people that is:
|
||||
#
|
||||
# `12 x 720 x 1280 x 1 byte = 11 MB`
|
||||
#
|
||||
# Most of those pixels are background. The actual person silhouette fits in a
|
||||
# tight bounding box. `sv.CompactMask` stores **only the bounding-box crop**,
|
||||
# RLE-encoded:
|
||||
#
|
||||
# - A 200 x 100 person crop: `~2.5 KB` instead of `900 KB`
|
||||
# - Drop-in replacement -- all annotators, filters, and `area` keep working
|
||||
|
||||
# %% [markdown]
|
||||
# ### 4.1 Measure dense mask footprint
|
||||
|
||||
# %%
|
||||
from typing import Any
|
||||
|
||||
dense_bytes: int = 0
|
||||
dense_mask: "np.ndarray[Any, np.dtype[np.bool_]] | None" = None
|
||||
|
||||
assert detections.mask is not None and isinstance(detections.mask, np.ndarray)
|
||||
|
||||
dense_mask = detections.mask
|
||||
dense_bytes = dense_mask.nbytes
|
||||
n_inst = len(dense_mask)
|
||||
print(f"Instances: {n_inst}")
|
||||
print(f"Mask shape: {dense_mask.shape} (N x H x W, bool)")
|
||||
print(f"Dense footprint: {dense_bytes / 1024:.1f} KB")
|
||||
print(f" = {n_inst} masks x {H} x {W} x 1 byte")
|
||||
|
||||
# %% [markdown]
|
||||
# ### 4.2 Convert to CompactMask
|
||||
|
||||
# %%
|
||||
compact: "sv.CompactMask | None" = None
|
||||
crop_bytes: int = 0
|
||||
|
||||
assert dense_mask is not None
|
||||
compact = sv.CompactMask.from_dense(
|
||||
masks=dense_mask,
|
||||
xyxy=detections.xyxy,
|
||||
image_shape=(H, W),
|
||||
)
|
||||
|
||||
# Measure compact size via uncompressed crop booleans (upper bound; RLE < this).
|
||||
crop_bytes = sum(compact.crop(i).nbytes for i in range(len(compact)))
|
||||
|
||||
print(f"Crop size (est.): {crop_bytes / 1024:.1f} KB (uncompressed crops)")
|
||||
if crop_bytes > 0 and dense_bytes > 0:
|
||||
ratio = dense_bytes / crop_bytes
|
||||
print(f"Reduction factor: {ratio:.1f}x (before RLE compression)")
|
||||
|
||||
# Swap in CompactMask -- supervision uses it transparently from here on.
|
||||
detections.mask = compact
|
||||
print(f"\ndetections.mask type: {type(detections.mask).__name__}")
|
||||
|
||||
# %% [markdown]
|
||||
# ### 4.3 Filtering by mask area
|
||||
#
|
||||
# `compact.area` returns the true pixel count of each instance mask.
|
||||
# Filter out tiny detections (partial occlusions, image-edge artefacts).
|
||||
|
||||
# %%
|
||||
large: sv.Detections = detections
|
||||
large_labels: list[str] = labels
|
||||
|
||||
assert isinstance(detections.mask, sv.CompactMask)
|
||||
areas = detections.mask.area
|
||||
print(
|
||||
f"Mask areas (px): min={areas.min():.0f} "
|
||||
f"mean={areas.mean():.0f} max={areas.max():.0f}"
|
||||
)
|
||||
|
||||
# Keep instances larger than 0.1% of the image.
|
||||
min_area = 0.001 * H * W
|
||||
keep_idx = np.where(areas > min_area)[0]
|
||||
_filtered = detections[keep_idx]
|
||||
if isinstance(_filtered, sv.Detections):
|
||||
large = _filtered
|
||||
large_labels = [labels[i] for i in keep_idx] if labels else []
|
||||
print(f"\nInstances > {min_area:.0f} px: {len(large)}")
|
||||
|
||||
# %% [markdown]
|
||||
# ### 4.4 Annotate with CompactMask
|
||||
#
|
||||
# Annotators call `.to_dense()` internally -- CompactMask is invisible to them.
|
||||
|
||||
# %%
|
||||
assert isinstance(detections.mask, sv.CompactMask) and dense_bytes > 0
|
||||
|
||||
annotated_compact = image_bgr.copy()
|
||||
annotated_compact = sv.MaskAnnotator(color=PALETTE, opacity=0.45).annotate(
|
||||
annotated_compact, large
|
||||
)
|
||||
annotated_compact = sv.BoxAnnotator(color=PALETTE, thickness=2).annotate(
|
||||
annotated_compact, large
|
||||
)
|
||||
annotated_compact = sv.LabelAnnotator(
|
||||
color=PALETTE, text_scale=0.5, text_thickness=1
|
||||
).annotate(annotated_compact, large, labels=large_labels)
|
||||
|
||||
plt.figure(figsize=(12, 7))
|
||||
plt.imshow(cv2.cvtColor(annotated_compact, cv2.COLOR_BGR2RGB))
|
||||
plt.axis("off")
|
||||
plt.title(
|
||||
f"CompactMask (filtered) -- {len(large)} instance(s) "
|
||||
f"| {dense_bytes / 1024:.0f} KB dense -> {crop_bytes / 1024:.0f} KB crops"
|
||||
)
|
||||
plt.tight_layout()
|
||||
plt.show()
|
||||
|
||||
# %% [markdown]
|
||||
# ### 4.5 Per-instance crop
|
||||
#
|
||||
# `compact.crop(i)` decodes only the bounding-box crop for instance `i` as a
|
||||
# `(H_crop, W_crop)` bool array -- no full mask materialised.
|
||||
|
||||
# %%
|
||||
assert isinstance(detections.mask, sv.CompactMask) and len(detections) > 0
|
||||
|
||||
crop = detections.mask.crop(0)
|
||||
bbox = detections.mask.bbox_xyxy[0].astype(int)
|
||||
|
||||
fig, axes = plt.subplots(1, 2, figsize=(10, 4))
|
||||
axes[0].imshow(image_rgb[bbox[1] : bbox[3], bbox[0] : bbox[2]])
|
||||
axes[0].set_title("Image crop (instance 0)")
|
||||
axes[0].axis("off")
|
||||
|
||||
axes[1].imshow(crop, cmap="gray")
|
||||
axes[1].set_title(f"Mask crop ({crop.shape[1]} x {crop.shape[0]} px)")
|
||||
axes[1].axis("off")
|
||||
|
||||
plt.tight_layout()
|
||||
plt.show()
|
||||
|
||||
full_px = H * W
|
||||
crop_kb = crop.nbytes / 1024
|
||||
print(f"Full-res mask slot: {H} x {W} = {full_px / 1024:.0f} KB")
|
||||
print(f"Compact crop: {crop.shape[0]} x {crop.shape[1]} = {crop_kb:.1f} KB")
|
||||
|
||||
# %% [markdown]
|
||||
# ## 5. SAM3
|
||||
#
|
||||
# `sv.Detections.from_sam3()` is the other headline in 0.28.0.
|
||||
# SAM3 segments objects by free-text prompts -- `"person"`, `"bag"`, any phrase.
|
||||
# supervision parses both the PCS and PVS response formats into a standard
|
||||
# `sv.Detections`, with `class_id` set to the prompt index.
|
||||
#
|
||||
# This section runs only when `ROBOFLOW_API_KEY` is available.
|
||||
|
||||
# %%
|
||||
import base64
|
||||
import os
|
||||
from typing import Optional
|
||||
|
||||
import requests
|
||||
|
||||
try:
|
||||
from google.colab import userdata # type: ignore[import, unused-ignore]
|
||||
|
||||
ROBOFLOW_API_KEY: str = userdata.get("ROBOFLOW_API_KEY") or ""
|
||||
except Exception:
|
||||
ROBOFLOW_API_KEY = os.environ.get("ROBOFLOW_API_KEY", "")
|
||||
|
||||
PROMPTS = ["person", "bag"]
|
||||
sam3_detections: Optional[sv.Detections] = None
|
||||
|
||||
assert ROBOFLOW_API_KEY
|
||||
|
||||
with open(image_path, "rb") as _f:
|
||||
_img_b64 = base64.b64encode(_f.read()).decode("utf-8")
|
||||
|
||||
_response = requests.post(
|
||||
f"https://api.roboflow.com/inferenceproxy/seg-preview?api_key={ROBOFLOW_API_KEY}",
|
||||
json={
|
||||
"image": {"type": "base64", "value": _img_b64},
|
||||
"prompts": [{"type": "text", "text": p} for p in PROMPTS],
|
||||
"output_prob_thresh": 0.3,
|
||||
},
|
||||
headers={"Content-Type": "application/json"},
|
||||
timeout=60,
|
||||
)
|
||||
_response.raise_for_status()
|
||||
sam3_result: dict[str, Any] = _response.json()
|
||||
sam3_detections = sv.Detections.from_sam3(sam3_result=sam3_result, resolution_wh=(W, H))
|
||||
print(f"SAM3 detections: {len(sam3_detections)}")
|
||||
if sam3_detections.class_id is not None:
|
||||
for idx, prompt in enumerate(PROMPTS):
|
||||
count = int((sam3_detections.class_id == idx).sum())
|
||||
print(f" [{idx}] '{prompt}': {count} instance(s)")
|
||||
|
||||
# %%
|
||||
assert sam3_detections is not None and len(sam3_detections) > 0
|
||||
|
||||
sam3_labels = (
|
||||
[PROMPTS[c] for c in sam3_detections.class_id]
|
||||
if sam3_detections.class_id is not None
|
||||
else []
|
||||
)
|
||||
SAM3_PALETTE = sv.ColorPalette.from_hex(["#ff6b6b", "#4ecdc4"])
|
||||
|
||||
annotated_sam3 = image_bgr.copy()
|
||||
annotated_sam3 = sv.MaskAnnotator(color=SAM3_PALETTE, opacity=0.45).annotate(
|
||||
annotated_sam3, sam3_detections
|
||||
)
|
||||
annotated_sam3 = sv.BoxAnnotator(color=SAM3_PALETTE, thickness=2).annotate(
|
||||
annotated_sam3, sam3_detections
|
||||
)
|
||||
annotated_sam3 = sv.LabelAnnotator(
|
||||
color=SAM3_PALETTE, text_scale=0.5, text_thickness=1
|
||||
).annotate(annotated_sam3, sam3_detections, labels=sam3_labels)
|
||||
|
||||
plt.figure(figsize=(12, 7))
|
||||
plt.imshow(cv2.cvtColor(annotated_sam3, cv2.COLOR_BGR2RGB))
|
||||
plt.axis("off")
|
||||
plt.title(f"SAM3 -- from_sam3() -- {len(sam3_detections)} instance(s)")
|
||||
plt.tight_layout()
|
||||
plt.show()
|
||||
|
||||
# %% [markdown]
|
||||
# ## 6. Other notable changes in 0.28.0
|
||||
#
|
||||
# ### `VideoInfo.fps` is now `float`
|
||||
#
|
||||
# NTSC frame rates (23.976, 29.97, 59.94) were silently truncated to `int`.
|
||||
# Wrap with `int()` at call sites that require an integer.
|
||||
|
||||
# %%
|
||||
import collections
|
||||
|
||||
from supervision.assets import VideoAssets
|
||||
|
||||
video_path = download_assets(VideoAssets.PEOPLE_WALKING)
|
||||
info = sv.VideoInfo.from_video_path(video_path)
|
||||
|
||||
print(f"fps: {info.fps} ({type(info.fps).__name__}) -- was int before 0.28.0")
|
||||
|
||||
fps_int = int(info.fps)
|
||||
buf: collections.deque[sv.Detections] = collections.deque(maxlen=fps_int)
|
||||
trace = sv.TraceAnnotator(trace_length=fps_int)
|
||||
print(f"deque maxlen: {buf.maxlen} (= int({info.fps}))")
|
||||
|
||||
# %% [markdown]
|
||||
# ### `sv.ByteTrack` deprecated
|
||||
#
|
||||
# `sv.ByteTrack` still works in 0.28.0 and 0.29.0 but emits a
|
||||
# `DeprecationWarning`. Migrate to `ByteTrackTracker` from the external
|
||||
# [`trackers`](https://pypi.org/project/trackers/) package before 0.30.0.
|
||||
#
|
||||
# ```python
|
||||
# # Before
|
||||
# tracker = sv.ByteTrack()
|
||||
# detections = tracker.update_with_detections(detections)
|
||||
#
|
||||
# # After (pip install trackers)
|
||||
# from trackers import ByteTrackTracker
|
||||
# tracker = ByteTrackTracker()
|
||||
# detections = tracker.update(detections)
|
||||
# ```
|
||||
|
||||
# %% [markdown]
|
||||
# ## 7. Next steps
|
||||
#
|
||||
# - [`sv.CompactMask` docs](https://supervision.roboflow.com/develop/detection/compact_mask/)
|
||||
# -- full API reference: `resize`, `merge`, `with_offset`
|
||||
# - [`sv.Detections.from_sam3` docs](https://supervision.roboflow.com/develop/detection/core/)
|
||||
# -- PCS and PVS format reference
|
||||
# - [RF-DETR docs](https://github.com/roboflow/rf-detr)
|
||||
# -- training, export, and deployment
|
||||
# - [Full changelog](https://supervision.roboflow.com/develop/changelog/)
|
||||
# -- every change in 0.28.0
|
||||
+6
-2
@@ -4,7 +4,7 @@ requires = [ "setuptools>=61" ]
|
||||
|
||||
[project]
|
||||
name = "supervision"
|
||||
version = "0.28.0rc1"
|
||||
version = "0.28.0"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
readme = "README.md"
|
||||
keywords = [
|
||||
@@ -90,7 +90,7 @@ docs = [
|
||||
build = [
|
||||
"build>=0.10,<1.5",
|
||||
"twine>=5.1.1,<7",
|
||||
"wheel>=0.40,<0.47",
|
||||
"wheel>=0.40,<0.48",
|
||||
]
|
||||
|
||||
[tool.setuptools]
|
||||
@@ -154,6 +154,10 @@ lint.select = [
|
||||
]
|
||||
lint.ignore = []
|
||||
lint.per-file-ignores."__init__.py" = [ "E402", "F401" ]
|
||||
lint.per-file-ignores."notebooks/**" = [
|
||||
"PT018", # Assertion should be broken down into multiple parts
|
||||
"S101", # Use of `assert` detected
|
||||
]
|
||||
lint.per-file-ignores."src/**" = [
|
||||
"S101", # TODO: Replace asserts with proper error handling
|
||||
]
|
||||
|
||||
@@ -64,6 +64,7 @@ from supervision.detection.utils.boxes import (
|
||||
scale_boxes,
|
||||
)
|
||||
from supervision.detection.utils.converters import (
|
||||
is_compressed_rle,
|
||||
mask_to_polygons,
|
||||
mask_to_rle,
|
||||
mask_to_xyxy,
|
||||
@@ -237,6 +238,7 @@ __all__ = [
|
||||
"get_video_frames_generator",
|
||||
"grayscale_image",
|
||||
"hex_to_rgba",
|
||||
"is_compressed_rle",
|
||||
"is_valid_hex",
|
||||
"letterbox_image",
|
||||
"list_files_with_extensions",
|
||||
|
||||
@@ -1967,7 +1967,10 @@ class TraceAnnotator(BaseAnnotator):
|
||||
trace_length: The maximum length of the trace in terms of historical
|
||||
points. Defaults to `30`.
|
||||
thickness: The thickness of the trace lines. Defaults to `2`.
|
||||
smooth: Smooth the trace lines.
|
||||
smooth: If `True`, applies spline smoothing to trace lines using
|
||||
consecutive unique anchor points. Falls back to a raw polyline
|
||||
when fewer than 4 unique points are available (e.g. when a
|
||||
tracker is stationary).
|
||||
color_lookup: Strategy for mapping colors to annotations.
|
||||
Options are `INDEX`, `CLASS`, `TRACK`.
|
||||
"""
|
||||
@@ -2054,11 +2057,20 @@ class TraceAnnotator(BaseAnnotator):
|
||||
xy = self.trace.get(tracker_id=tracker_id)
|
||||
spline_points: npt.NDArray[np.int32] = xy.astype(np.int32)
|
||||
|
||||
if len(xy) > 3 and self.smooth:
|
||||
x, y = xy[:, 0], xy[:, 1]
|
||||
tck, _u = splprep([x, y], s=20)
|
||||
x_new, y_new = splev(np.linspace(0, 1, 100), tck)
|
||||
spline_points = np.stack([x_new, y_new], axis=1).astype(np.int32)
|
||||
if self.smooth:
|
||||
unique_xy = xy[
|
||||
np.concatenate(([True], np.any(np.diff(xy, axis=0) != 0, axis=1)))
|
||||
]
|
||||
if len(unique_xy) > 3:
|
||||
try:
|
||||
x, y = unique_xy[:, 0], unique_xy[:, 1]
|
||||
tck, _u = splprep([x, y], s=20)
|
||||
xy_new = splev(np.linspace(0, 1, 100), tck)
|
||||
spline_points = np.stack(xy_new, axis=1).astype(np.int32)
|
||||
except ValueError:
|
||||
spline_points = unique_xy.astype(np.int32)
|
||||
else:
|
||||
spline_points = unique_xy.astype(np.int32)
|
||||
|
||||
if len(xy) > 1:
|
||||
cv2.polylines(
|
||||
|
||||
@@ -1,4 +1,3 @@
|
||||
import os
|
||||
import warnings
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
@@ -278,6 +277,19 @@ def load_coco_annotations(
|
||||
|
||||
Returns:
|
||||
A tuple of `(classes, image_paths, annotations)`.
|
||||
|
||||
Raises:
|
||||
ValueError: If any annotation's ``file_name`` resolves to the images
|
||||
directory itself, to a path outside the images directory (e.g. via
|
||||
``../`` traversal or an absolute path), or to a subdirectory instead
|
||||
of a regular image file.
|
||||
|
||||
Note:
|
||||
Each annotation's ``file_name`` is validated against
|
||||
``images_directory_path`` before loading. Annotations that reference
|
||||
paths outside the directory are rejected to prevent path-traversal
|
||||
attacks when loading user-supplied annotation files. Symlinked images
|
||||
pointing outside the resolved images directory are also rejected.
|
||||
"""
|
||||
coco_data = read_json_file(file_path=annotations_path)
|
||||
classes = coco_categories_to_classes(coco_categories=coco_data["categories"])
|
||||
@@ -293,6 +305,7 @@ def load_coco_annotations(
|
||||
|
||||
images = []
|
||||
annotations = {}
|
||||
images_directory_resolved = Path(images_directory_path).resolve()
|
||||
|
||||
for coco_image in coco_images:
|
||||
image_name, image_width, image_height = (
|
||||
@@ -301,7 +314,33 @@ def load_coco_annotations(
|
||||
coco_image["height"],
|
||||
)
|
||||
image_annotations = coco_annotations_groups.get(coco_image["id"], [])
|
||||
image_path = os.path.join(images_directory_path, image_name)
|
||||
image_path = str(Path(images_directory_path) / Path(image_name))
|
||||
try:
|
||||
resolved_image_path = Path(image_path).resolve()
|
||||
except (OSError, ValueError) as exc:
|
||||
raise ValueError(
|
||||
f"COCO annotation refers to image {image_name!r}, which "
|
||||
f"produces an invalid path: {exc}"
|
||||
) from exc
|
||||
if resolved_image_path == images_directory_resolved:
|
||||
raise ValueError(
|
||||
f"COCO annotation refers to image {image_name!r}, which "
|
||||
f"resolves to the images directory itself "
|
||||
f"({images_directory_resolved}). Expected a path to an "
|
||||
"image file."
|
||||
)
|
||||
if images_directory_resolved not in resolved_image_path.parents:
|
||||
raise ValueError(
|
||||
f"COCO annotation refers to image {image_name!r}, which "
|
||||
f"resolves to {resolved_image_path} — outside the images "
|
||||
f"directory {images_directory_resolved}."
|
||||
)
|
||||
if resolved_image_path.is_dir():
|
||||
raise ValueError(
|
||||
f"COCO annotation refers to image {image_name!r}, which "
|
||||
f"resolves to directory {resolved_image_path}. Expected a "
|
||||
"path to an image file."
|
||||
)
|
||||
|
||||
with_masks = force_masks or any(
|
||||
_with_seg_mask(annotation) for annotation in image_annotations
|
||||
|
||||
@@ -11,94 +11,24 @@ crop boundaries, so no extra metadata is required from the caller.
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from collections.abc import Iterator
|
||||
from typing import Any, cast
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
|
||||
def _rle_encode(mask_2d: npt.NDArray[Any]) -> npt.NDArray[np.int32]:
|
||||
"""Run-length encode a 2D boolean mask in row-major order.
|
||||
|
||||
The encoding starts with the count of leading ``False`` values (may be 0
|
||||
if the mask begins with ``True``). Subsequent values alternate between
|
||||
``True`` and ``False`` run counts.
|
||||
|
||||
Args:
|
||||
mask_2d: 2D boolean array of shape ``(H, W)``.
|
||||
|
||||
Returns:
|
||||
int32 array of run lengths, starting with the False count.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.compact_mask import _rle_encode
|
||||
>>> mask = np.array([[False, True, True], [True, False, False]])
|
||||
>>> _rle_encode(mask).tolist()
|
||||
[1, 3, 2]
|
||||
|
||||
```
|
||||
"""
|
||||
flat = mask_2d.ravel() # C-order (row-major)
|
||||
if len(flat) == 0:
|
||||
return np.array([0], dtype=np.int32)
|
||||
|
||||
# Locate positions where the boolean value changes.
|
||||
changes = np.diff(flat.view(np.uint8))
|
||||
boundaries = np.where(changes != 0)[0] + 1
|
||||
|
||||
positions = np.concatenate(([0], boundaries, [len(flat)]))
|
||||
run_lengths = np.diff(positions).astype(np.int32)
|
||||
|
||||
# Guarantee the encoding always starts with a False count.
|
||||
if flat[0]:
|
||||
run_lengths = np.concatenate(([np.int32(0)], run_lengths))
|
||||
|
||||
return run_lengths
|
||||
|
||||
|
||||
def _rle_decode(
|
||||
rle: npt.NDArray[np.int32], height: int, width: int
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
"""Decode a run-length encoded mask back to a 2D boolean array.
|
||||
|
||||
Args:
|
||||
rle: int32 array of run lengths as produced by :func:`_rle_encode`.
|
||||
height: Height of the output array.
|
||||
width: Width of the output array.
|
||||
|
||||
Returns:
|
||||
2D boolean array of shape ``(height, width)``.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.compact_mask import _rle_decode
|
||||
>>> rle = np.array([1, 3, 2], dtype=np.int32)
|
||||
>>> _rle_decode(rle, 2, 3)
|
||||
array([[False, True, True],
|
||||
[ True, False, False]])
|
||||
|
||||
```
|
||||
"""
|
||||
# Even-indexed entries → False runs; odd-indexed entries → True runs.
|
||||
is_true = np.arange(len(rle)) % 2 == 1
|
||||
flat: npt.NDArray[np.bool_] = np.repeat(is_true, rle)
|
||||
num_pixels = height * width
|
||||
if len(flat) < num_pixels:
|
||||
# Pad with False if the RLE is shorter than expected (e.g. all-False
|
||||
# tails are often omitted during encoding).
|
||||
flat = np.pad(flat, (0, num_pixels - len(flat)))
|
||||
return cast(npt.NDArray[np.bool_], flat[:num_pixels].reshape(height, width))
|
||||
from supervision.detection.utils.converters import (
|
||||
_mask_to_rle_counts,
|
||||
_rle_counts_to_mask,
|
||||
)
|
||||
|
||||
|
||||
def _rle_area(rle: npt.NDArray[np.int32]) -> int:
|
||||
"""Return the number of ``True`` pixels in a run-length encoded mask.
|
||||
|
||||
Args:
|
||||
rle: int32 array of run lengths as produced by :func:`_rle_encode`.
|
||||
rle: int32 array of run lengths as produced by :func:`_mask_to_rle_counts`.
|
||||
|
||||
Returns:
|
||||
Total number of ``True`` pixels.
|
||||
@@ -107,7 +37,7 @@ def _rle_area(rle: npt.NDArray[np.int32]) -> int:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.compact_mask import _rle_area
|
||||
>>> rle = np.array([1, 3, 2], dtype=np.int32) # 1 F, 3 T, 2 F
|
||||
>>> rle = np.array([1, 2, 1, 1, 1], dtype=np.int32)
|
||||
>>> _rle_area(rle)
|
||||
3
|
||||
|
||||
@@ -116,6 +46,346 @@ def _rle_area(rle: npt.NDArray[np.int32]) -> int:
|
||||
return int(np.sum(rle[1::2]))
|
||||
|
||||
|
||||
def _rle_split_cols(
|
||||
rle: npt.NDArray[np.int32],
|
||||
crop_h: int,
|
||||
crop_w: int,
|
||||
) -> list[list[int]]:
|
||||
"""Split a flat F-order RLE into per-column run lists.
|
||||
|
||||
With F-order (column-major) RLE the flat pixel sequence visits all rows
|
||||
of column 0, then all rows of column 1, etc. Each column therefore
|
||||
contains ``crop_h`` contiguous pixels.
|
||||
|
||||
Runs that cross column boundaries are split at the boundary. Each
|
||||
returned list starts with a ``False``-run count (possibly 0), matching
|
||||
the convention of :func:`_mask_to_rle_counts`.
|
||||
|
||||
Args:
|
||||
rle: int32 run-length array as produced by
|
||||
:func:`~supervision.detection.utils.converters._mask_to_rle_counts`.
|
||||
crop_h: Number of rows (pixels per column).
|
||||
crop_w: Number of columns.
|
||||
|
||||
Returns:
|
||||
List of ``crop_w`` run lists, one per column. Each list sums to
|
||||
``crop_h``.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.compact_mask import _rle_split_cols
|
||||
>>> from supervision.detection.utils.converters import _mask_to_rle_counts
|
||||
>>> mask = np.array([[True, False], [True, True]], dtype=bool)
|
||||
>>> rle = _mask_to_rle_counts(mask)
|
||||
>>> rle.tolist()
|
||||
[0, 2, 1, 1]
|
||||
>>> _rle_split_cols(rle, 2, 2)
|
||||
[[0, 2], [1, 1]]
|
||||
|
||||
```
|
||||
"""
|
||||
per_col: list[list[int]] = [[] for _ in range(crop_w)]
|
||||
col = 0
|
||||
row = 0
|
||||
|
||||
for run_idx, run_len in enumerate(rle):
|
||||
is_true = run_idx % 2 == 1
|
||||
remaining = int(run_len)
|
||||
while remaining > 0:
|
||||
space_in_col = crop_h - row
|
||||
take = min(remaining, space_in_col)
|
||||
if len(per_col[col]) == 0:
|
||||
if is_true:
|
||||
per_col[col].append(0) # leading False count = 0
|
||||
# Check if last run has same parity (True/False) as current chunk.
|
||||
# Last element's parity: index (len-1) odd → True, even → False.
|
||||
elif is_true == ((len(per_col[col]) - 1) % 2 == 1):
|
||||
per_col[col][-1] += take
|
||||
remaining -= take
|
||||
row += take
|
||||
if row >= crop_h:
|
||||
row = 0
|
||||
col += 1
|
||||
continue
|
||||
per_col[col].append(take)
|
||||
remaining -= take
|
||||
row += take
|
||||
if row >= crop_h:
|
||||
row = 0
|
||||
col += 1
|
||||
if col >= crop_w:
|
||||
break
|
||||
|
||||
# Fill any empty columns (all-False).
|
||||
for c in range(crop_w):
|
||||
if not per_col[c]:
|
||||
per_col[c] = [crop_h]
|
||||
|
||||
return per_col
|
||||
|
||||
|
||||
def _rle_scale_col(
|
||||
col_runs: list[int],
|
||||
src_h: int,
|
||||
row_map: npt.NDArray[np.int32],
|
||||
) -> list[int]:
|
||||
"""Scale one column's run list to a new height using a precomputed row map.
|
||||
|
||||
Each output row is mapped to a source row via ``row_map``, which
|
||||
implements nearest-neighbour resampling in the vertical direction.
|
||||
|
||||
Args:
|
||||
col_runs: Per-column run list starting with a ``False``-run count.
|
||||
src_h: Height of the source column (sum of ``col_runs``).
|
||||
row_map: int32 array of length ``new_crop_h``; ``row_map[r']`` is the
|
||||
source row index for output row ``r'``. Use
|
||||
``(np.arange(new_crop_h) * src_h // new_crop_h)`` for
|
||||
``cv2.INTER_NEAREST``-compatible mapping.
|
||||
|
||||
Returns:
|
||||
Scaled run list of total length ``len(row_map)``, always starting
|
||||
with a ``False``-run count.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.compact_mask import _rle_scale_col
|
||||
>>> col_runs = [0, 2, 2] # F=0, T=2, F=2 → [T, T, F, F]
|
||||
>>> row_map = np.array([0, 1, 2, 3, 0, 1, 2, 3], dtype=np.int32)
|
||||
>>> _rle_scale_col(col_runs, 4, row_map)
|
||||
[0, 2, 2, 2, 2]
|
||||
|
||||
```
|
||||
"""
|
||||
new_crop_h = len(row_map)
|
||||
if new_crop_h == 0:
|
||||
return [0]
|
||||
|
||||
# Reconstruct per-source-row boolean values from run list.
|
||||
src_values: npt.NDArray[np.bool_] = np.empty(src_h, dtype=np.bool_)
|
||||
pos = 0
|
||||
for ri, rl in enumerate(col_runs):
|
||||
src_values[pos : pos + rl] = ri % 2 == 1 # odd index → True
|
||||
pos += rl
|
||||
if pos < src_h:
|
||||
src_values[pos:] = False # pad truncated RLE
|
||||
|
||||
# Map output rows to source values.
|
||||
out_values = src_values[row_map]
|
||||
|
||||
# RLE-encode the output column; vectorised via np.diff on bool view.
|
||||
out_uint8 = out_values.view(np.uint8)
|
||||
boundaries = np.flatnonzero(np.diff(out_uint8))
|
||||
run_starts: npt.NDArray[np.int64] = np.empty(len(boundaries) + 1, dtype=np.int64)
|
||||
run_ends: npt.NDArray[np.int64] = np.empty(len(boundaries) + 1, dtype=np.int64)
|
||||
run_starts[0] = 0
|
||||
run_starts[1:] = boundaries + 1
|
||||
run_ends[:-1] = boundaries + 1
|
||||
run_ends[-1] = new_crop_h
|
||||
result_runs: list[int] = (run_ends - run_starts).tolist()
|
||||
# RLE starts with a False count; prepend 0 if output begins with True.
|
||||
if bool(out_values[0]):
|
||||
result_runs.insert(0, 0)
|
||||
return result_runs
|
||||
|
||||
|
||||
def _rle_join_cols(
|
||||
scaled_cols: list[list[int]],
|
||||
new_total: int,
|
||||
) -> npt.NDArray[np.int32]:
|
||||
"""Concatenate per-column run lists into a flat RLE, merging junctions.
|
||||
|
||||
Each column run list starts with a ``False``-run count. Two junction types
|
||||
can be merged across column boundaries:
|
||||
|
||||
* ``False``/``False``: the trailing False run merges with the leading False
|
||||
run of the next column (leading count may be zero).
|
||||
* ``True``/``True``: when the accumulated output ends on a True run and the
|
||||
next column's leading False count is zero (column starts with True), the
|
||||
two True runs are merged to avoid inserting a zero-length False run that
|
||||
would inflate ``len(rle)`` and skew the density metric in
|
||||
:func:`_resize_crop`.
|
||||
|
||||
Args:
|
||||
scaled_cols: List of per-column run lists, each starting with a
|
||||
``False``-run count.
|
||||
new_total: Total pixel count of the output (fallback for empty input).
|
||||
|
||||
Returns:
|
||||
Flat int32 RLE array starting with a ``False``-run count.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.compact_mask import _rle_join_cols
|
||||
>>> cols = [[1, 2], [1, 2]] # each col: F=1, T=2
|
||||
>>> _rle_join_cols(cols, 6).tolist()
|
||||
[1, 2, 1, 2]
|
||||
|
||||
```
|
||||
"""
|
||||
output_runs: list[int] = []
|
||||
for col_runs in scaled_cols:
|
||||
if not output_runs:
|
||||
output_runs.extend(col_runs)
|
||||
else:
|
||||
last_is_true = (len(output_runs) - 1) % 2 == 1
|
||||
# col_runs always starts with a False count → first_is_true=False
|
||||
if not last_is_true: # last == False == first → merge
|
||||
output_runs[-1] += col_runs[0]
|
||||
output_runs.extend(col_runs[1:])
|
||||
elif col_runs[0] == 0 and len(col_runs) > 1:
|
||||
# last run = True; column also starts True (leading False = 0)
|
||||
# → merge to avoid a zero-length False run at the junction.
|
||||
output_runs[-1] += col_runs[1]
|
||||
output_runs.extend(col_runs[2:])
|
||||
else:
|
||||
output_runs.extend(col_runs)
|
||||
|
||||
return np.array(output_runs if output_runs else [new_total], dtype=np.int32)
|
||||
|
||||
|
||||
def _rle_resize(
|
||||
rle: npt.NDArray[np.int32],
|
||||
crop_h: int,
|
||||
crop_w: int,
|
||||
new_crop_h: int,
|
||||
new_crop_w: int,
|
||||
) -> npt.NDArray[np.int32]:
|
||||
"""Resize an F-order RLE-encoded crop via nearest-neighbour resampling.
|
||||
|
||||
Manipulates run lengths directly without decoding to a full 2D boolean
|
||||
array. Delegates to :func:`_rle_split_cols`, :func:`_rle_scale_col`,
|
||||
and :func:`_rle_join_cols`.
|
||||
|
||||
The nearest-neighbour mapping ``src = floor(dst * src_size / dst_size)``
|
||||
is bit-exact with ``cv2.INTER_NEAREST``.
|
||||
|
||||
Args:
|
||||
rle: int32 array of F-order run lengths as produced by
|
||||
:func:`~supervision.detection.utils.converters._mask_to_rle_counts`.
|
||||
Starts with a ``False``-run count (may be 0).
|
||||
crop_h: Height of the original crop.
|
||||
crop_w: Width of the original crop.
|
||||
new_crop_h: Height of the resized crop.
|
||||
new_crop_w: Width of the resized crop.
|
||||
|
||||
Returns:
|
||||
int32 array of F-order run lengths for the resized crop, starting
|
||||
with the ``False``-run count.
|
||||
|
||||
Examples:
|
||||
Upscale a 3x3 mask with a diagonal True stripe to 6x6:
|
||||
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.compact_mask import _rle_resize
|
||||
>>> from supervision.detection.utils.converters import (
|
||||
... _mask_to_rle_counts, _rle_counts_to_mask,
|
||||
... )
|
||||
>>> mask = np.array([
|
||||
... [True, False, False],
|
||||
... [False, True, False],
|
||||
... [False, False, True ],
|
||||
... ], dtype=bool)
|
||||
>>> rle = _mask_to_rle_counts(mask)
|
||||
>>> resized_rle = _rle_resize(rle, 3, 3, 6, 6)
|
||||
>>> result = _rle_counts_to_mask(resized_rle, 6, 6)
|
||||
>>> result.astype(int)
|
||||
array([[1, 1, 0, 0, 0, 0],
|
||||
[1, 1, 0, 0, 0, 0],
|
||||
[0, 0, 1, 1, 0, 0],
|
||||
[0, 0, 1, 1, 0, 0],
|
||||
[0, 0, 0, 0, 1, 1],
|
||||
[0, 0, 0, 0, 1, 1]])
|
||||
|
||||
```
|
||||
"""
|
||||
new_total = new_crop_h * new_crop_w
|
||||
|
||||
if crop_h * crop_w == 0 or new_total == 0:
|
||||
return np.array([0], dtype=np.int32)
|
||||
if len(rle) == 1 or int(np.sum(rle[1::2])) == 0:
|
||||
return np.array([new_total], dtype=np.int32)
|
||||
if len(rle) == 2 and rle[0] == 0:
|
||||
return np.array([0, new_total], dtype=np.int32)
|
||||
|
||||
per_col = _rle_split_cols(rle, crop_h, crop_w)
|
||||
|
||||
# cv2.INTER_NEAREST column mapping: src = floor(dst * src_w / dst_w)
|
||||
col_map = (np.arange(new_crop_w) * crop_w // new_crop_w).astype(np.int32)
|
||||
|
||||
# cv2.INTER_NEAREST row mapping: src = floor(dst * src_h / dst_h)
|
||||
row_map = (np.arange(new_crop_h) * crop_h // new_crop_h).astype(np.int32)
|
||||
|
||||
# Scale each unique source column once; reuse via cache for repeated cols.
|
||||
col_cache: dict[int, list[int]] = {}
|
||||
scaled_cols = []
|
||||
for src_c in col_map:
|
||||
if src_c not in col_cache:
|
||||
col_cache[src_c] = _rle_scale_col(per_col[src_c], crop_h, row_map)
|
||||
scaled_cols.append(col_cache[src_c])
|
||||
|
||||
return _rle_join_cols(scaled_cols, new_total)
|
||||
|
||||
|
||||
# Fraction of (run_count / pixel_count) below which _rle_resize is used
|
||||
# instead of the decode → cv2 → re-encode path. Sparse masks have few long
|
||||
# runs; dense/complex masks approach 1 run per 2 pixels.
|
||||
_L3_DENSITY_THRESHOLD: float = 0.25
|
||||
# Thread overhead outweighs gains below this mask count.
|
||||
_PARALLEL_THRESHOLD: int = 8
|
||||
|
||||
|
||||
def _resize_crop(
|
||||
rle: npt.NDArray[np.int32],
|
||||
orig_h: int,
|
||||
orig_w: int,
|
||||
new_h: int,
|
||||
new_w: int,
|
||||
) -> npt.NDArray[np.int32]:
|
||||
"""Resize one RLE crop to ``(new_h, new_w)``, choosing the fastest path.
|
||||
|
||||
Dispatch order:
|
||||
|
||||
1. **All-False fast path** — returns a single False run; no decode.
|
||||
2. **L3 direct RLE path** — used when run density is below
|
||||
:data:`_L3_DENSITY_THRESHOLD`; manipulates run lengths without
|
||||
allocating a 2D array.
|
||||
3. **cv2 fallback** — decodes to ``uint8``, calls
|
||||
``cv2.resize(INTER_NEAREST)``, re-encodes; used for dense masks.
|
||||
|
||||
Args:
|
||||
rle: int32 run-length array for the source crop.
|
||||
orig_h: Height of the source crop.
|
||||
orig_w: Width of the source crop.
|
||||
new_h: Target height.
|
||||
new_w: Target width.
|
||||
|
||||
Returns:
|
||||
int32 RLE array for the resized crop.
|
||||
"""
|
||||
import cv2
|
||||
|
||||
# All-False: skip decode entirely.
|
||||
if _rle_area(rle) == 0:
|
||||
return np.array([new_h * new_w], dtype=np.int32)
|
||||
|
||||
# L3: direct RLE arithmetic for sparse masks.
|
||||
if len(rle) / max(1, orig_h * orig_w) < _L3_DENSITY_THRESHOLD:
|
||||
return _rle_resize(rle, orig_h, orig_w, new_h, new_w)
|
||||
|
||||
# cv2 fallback for dense masks.
|
||||
crop = _rle_counts_to_mask(rle, orig_h, orig_w)
|
||||
resized = cv2.resize(
|
||||
crop.view(np.uint8),
|
||||
(new_w, new_h),
|
||||
interpolation=cv2.INTER_NEAREST,
|
||||
).astype(bool)
|
||||
return _mask_to_rle_counts(resized)
|
||||
|
||||
|
||||
class CompactMask:
|
||||
"""Memory-efficient crop-RLE mask storage for instance segmentation.
|
||||
|
||||
@@ -138,17 +408,28 @@ class CompactMask:
|
||||
``cm.to_dense().astype(np.uint8)``. :meth:`to_dense` is the single
|
||||
explicit materialisation boundary.
|
||||
|
||||
.. note:: **RLE encoding incompatibility with pycocotools / COCO API**
|
||||
.. note:: **RLE encoding — COCO / pycocotools pixel-scan order**
|
||||
|
||||
:class:`CompactMask` uses **row-major (C-order)** run-lengths scoped
|
||||
to each mask's bounding-box crop. The COCO API (pycocotools) uses
|
||||
**column-major (Fortran-order)** run-lengths scoped to the **full
|
||||
image**. The two formats are not interchangeable: you cannot pass a
|
||||
:class:`CompactMask` RLE directly to ``maskUtils.iou()`` or
|
||||
``maskUtils.decode()``, and you cannot load a COCO RLE dict into a
|
||||
:class:`CompactMask` without re-encoding. Use
|
||||
:meth:`to_dense` to obtain a standard boolean array, then pass it to
|
||||
pycocotools if needed.
|
||||
:class:`CompactMask` uses **column-major (Fortran-order, F-order)**
|
||||
run-lengths scoped to each mask's bounding-box crop, matching the
|
||||
pixel-scan order used by the COCO API (pycocotools). The crop scope
|
||||
still differs from the full-image scope used by pycocotools, so a
|
||||
:class:`CompactMask` RLE cannot be passed directly to
|
||||
``maskUtils.iou()`` or ``maskUtils.decode()`` without re-scoping to
|
||||
the full canvas. Use :meth:`to_dense` to obtain a standard boolean
|
||||
array for pycocotools interop.
|
||||
|
||||
This scan order is part of CompactMask's internal RLE representation.
|
||||
Switching from row-major (C-order) to column-major (F-order) is a
|
||||
backward-incompatible format change for any persisted or serialized
|
||||
:class:`CompactMask` state, including pickled objects and any
|
||||
external storage of ``._rles``. Older stored RLE arrays will decode
|
||||
incorrectly under the new convention.
|
||||
|
||||
Migration note: load or decode legacy masks with the older version,
|
||||
materialize them to dense boolean arrays, and then re-encode them
|
||||
with the current version (for example via :meth:`to_dense` followed
|
||||
by :meth:`from_dense`) before persisting them again.
|
||||
|
||||
Args:
|
||||
rles: List of N int32 run-length arrays.
|
||||
@@ -259,7 +540,7 @@ class CompactMask:
|
||||
|
||||
crop_h = y2c - y1c + 1
|
||||
crop_w = x2c - x1c + 1
|
||||
rles.append(_rle_encode(crop))
|
||||
rles.append(_mask_to_rle_counts(crop))
|
||||
crop_shapes_list.append((crop_h, crop_w))
|
||||
offsets_list.append((x1c, y1c))
|
||||
|
||||
@@ -299,7 +580,7 @@ class CompactMask:
|
||||
int(self._crop_shapes[mask_idx, 1]),
|
||||
)
|
||||
x1, y1 = int(self._offsets[mask_idx, 0]), int(self._offsets[mask_idx, 1])
|
||||
crop = _rle_decode(self._rles[mask_idx], crop_h, crop_w)
|
||||
crop = _rle_counts_to_mask(self._rles[mask_idx], crop_h, crop_w)
|
||||
result[mask_idx, y1 : y1 + crop_h, x1 : x1 + crop_w] = crop
|
||||
return result
|
||||
|
||||
@@ -330,7 +611,7 @@ class CompactMask:
|
||||
"""
|
||||
crop_h = int(self._crop_shapes[index, 0])
|
||||
crop_w = int(self._crop_shapes[index, 1])
|
||||
return _rle_decode(self._rles[index], crop_h, crop_w)
|
||||
return _rle_counts_to_mask(self._rles[index], crop_h, crop_w)
|
||||
|
||||
# ------------------------------------------------------------------
|
||||
# Sequence / array protocol
|
||||
@@ -551,7 +832,7 @@ class CompactMask:
|
||||
crop_w = int(self._crop_shapes[idx, 1])
|
||||
x1 = int(self._offsets[idx, 0])
|
||||
y1 = int(self._offsets[idx, 1])
|
||||
crop = _rle_decode(self._rles[idx], crop_h, crop_w)
|
||||
crop = _rle_counts_to_mask(self._rles[idx], crop_h, crop_w)
|
||||
result[y1 : y1 + crop_h, x1 : x1 + crop_w] = crop
|
||||
return result
|
||||
|
||||
@@ -757,7 +1038,7 @@ class CompactMask:
|
||||
|
||||
if not rows_any.any():
|
||||
# All-False: normalise to 1x1 to avoid zero-sized arrays.
|
||||
new_rles.append(_rle_encode(np.zeros((1, 1), dtype=bool)))
|
||||
new_rles.append(_mask_to_rle_counts(np.zeros((1, 1), dtype=bool)))
|
||||
new_crop_shapes_list.append((1, 1))
|
||||
new_offsets_list.append((x1_off, y1_off))
|
||||
continue
|
||||
@@ -768,7 +1049,7 @@ class CompactMask:
|
||||
x_min, x_max = int(x_indices[0]), int(x_indices[-1])
|
||||
|
||||
tight = crop[y_min : y_max + 1, x_min : x_max + 1]
|
||||
new_rles.append(_rle_encode(tight))
|
||||
new_rles.append(_mask_to_rle_counts(tight))
|
||||
new_crop_shapes_list.append((y_max - y_min + 1, x_max - x_min + 1))
|
||||
new_offsets_list.append((x1_off + x_min, y1_off + y_min))
|
||||
|
||||
@@ -886,14 +1167,14 @@ class CompactMask:
|
||||
if ix1 > ix2 or iy1 > iy2:
|
||||
anchor_x = min(max(x1, 0), new_w - 1)
|
||||
anchor_y = min(max(y1, 0), new_h - 1)
|
||||
out_rles.append(_rle_encode(np.zeros((1, 1), dtype=bool)))
|
||||
out_rles.append(_mask_to_rle_counts(np.zeros((1, 1), dtype=bool)))
|
||||
out_crop_shapes.append((1, 1))
|
||||
out_offsets_list.append((anchor_x, anchor_y))
|
||||
continue
|
||||
|
||||
crop = self.crop(mask_idx)
|
||||
clipped = crop[iy1 - y1 : iy2 - y1 + 1, ix1 - x1 : ix2 - x1 + 1]
|
||||
out_rles.append(_rle_encode(clipped))
|
||||
out_rles.append(_mask_to_rle_counts(clipped))
|
||||
out_crop_shapes.append((iy2 - iy1 + 1, ix2 - ix1 + 1))
|
||||
out_offsets_list.append((ix1, iy1))
|
||||
|
||||
@@ -903,3 +1184,123 @@ class CompactMask:
|
||||
np.array(out_offsets_list, dtype=np.int32),
|
||||
new_image_shape,
|
||||
)
|
||||
|
||||
# ------------------------------------------------------------------
|
||||
# Resize
|
||||
# ------------------------------------------------------------------
|
||||
|
||||
def resize(self, new_image_shape: tuple[int, int]) -> CompactMask:
|
||||
"""Return a new CompactMask scaled to a different image resolution.
|
||||
|
||||
Each crop mask is resized with nearest-neighbour interpolation.
|
||||
Sparse masks use direct RLE arithmetic (:func:`_rle_resize`); dense
|
||||
masks fall back to ``cv2.resize(INTER_NEAREST)``. Offsets and crop
|
||||
dimensions are scaled proportionally to the new image size.
|
||||
|
||||
Performance notes:
|
||||
|
||||
* Coordinate arithmetic is fully vectorised (no Python loop over N).
|
||||
* All-``False`` crops skip decode/resize entirely.
|
||||
* For N >= 8, resize runs in a thread pool — NumPy and OpenCV
|
||||
release the GIL so crops execute in parallel on multi-core CPUs.
|
||||
|
||||
Args:
|
||||
new_image_shape: ``(H, W)`` of the target image.
|
||||
|
||||
Returns:
|
||||
New :class:`CompactMask` with updated ``image_shape``, scaled
|
||||
offsets, scaled crop shapes, and re-encoded RLE crops.
|
||||
|
||||
Raises:
|
||||
ValueError: If any dimension in *new_image_shape* is ``<= 0``.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.compact_mask import CompactMask
|
||||
>>> masks = np.zeros((1, 100, 100), dtype=bool)
|
||||
>>> masks[0, 20:40, 30:60] = True
|
||||
>>> xyxy = np.array([[30, 20, 59, 39]], dtype=np.float32)
|
||||
>>> cm = CompactMask.from_dense(masks, xyxy, image_shape=(100, 100))
|
||||
>>> small = cm.resize((50, 50))
|
||||
>>> small.shape
|
||||
(1, 50, 50)
|
||||
>>> small.offsets[0].tolist()
|
||||
[15, 10]
|
||||
|
||||
```
|
||||
"""
|
||||
from concurrent.futures import ThreadPoolExecutor
|
||||
|
||||
new_h, new_w = new_image_shape
|
||||
if new_h <= 0 or new_w <= 0:
|
||||
raise ValueError("new_image_shape must contain positive dimensions")
|
||||
|
||||
# fast path — identity resize; list() creates a new container but the
|
||||
# individual RLE numpy arrays are shared (shallow copy). Callers must
|
||||
# not mutate returned RLE arrays in-place.
|
||||
if (new_h, new_w) == self._image_shape:
|
||||
return CompactMask(
|
||||
list(self._rles),
|
||||
self._crop_shapes.copy(),
|
||||
self._offsets.copy(),
|
||||
new_image_shape,
|
||||
)
|
||||
|
||||
# empty guard
|
||||
if len(self) == 0:
|
||||
return CompactMask(
|
||||
[],
|
||||
np.empty((0, 2), dtype=np.int32),
|
||||
np.empty((0, 2), dtype=np.int32),
|
||||
new_image_shape,
|
||||
)
|
||||
|
||||
img_h, img_w = self._image_shape
|
||||
sx = new_w / img_w
|
||||
sy = new_h / img_h
|
||||
|
||||
# L1 — vectorised coordinate arithmetic; no Python loop over N masks.
|
||||
x1s = self._offsets[:, 0].astype(np.float64)
|
||||
y1s = self._offsets[:, 1].astype(np.float64)
|
||||
x2s = x1s + self._crop_shapes[:, 1] - 1 # inclusive right edge
|
||||
y2s = y1s + self._crop_shapes[:, 0] - 1 # inclusive bottom edge
|
||||
|
||||
new_x1s = np.clip(np.round(x1s * sx), 0, new_w - 1).astype(np.int32)
|
||||
new_y1s = np.clip(np.round(y1s * sy), 0, new_h - 1).astype(np.int32)
|
||||
new_x2s = np.clip(np.round(x2s * sx), 0, new_w - 1).astype(np.int32)
|
||||
new_y2s = np.clip(np.round(y2s * sy), 0, new_h - 1).astype(np.int32)
|
||||
new_crop_ws: npt.NDArray[np.int32] = np.maximum(
|
||||
1, new_x2s - new_x1s + 1
|
||||
).astype(np.int32)
|
||||
new_crop_hs: npt.NDArray[np.int32] = np.maximum(
|
||||
1, new_y2s - new_y1s + 1
|
||||
).astype(np.int32)
|
||||
|
||||
# L2b — parallel per-crop resize; NumPy and OpenCV release the GIL.
|
||||
orig_crop_hs = self._crop_shapes[:, 0]
|
||||
orig_crop_ws = self._crop_shapes[:, 1]
|
||||
|
||||
args = [
|
||||
(
|
||||
self._rles[i],
|
||||
int(orig_crop_hs[i]),
|
||||
int(orig_crop_ws[i]),
|
||||
int(new_crop_hs[i]),
|
||||
int(new_crop_ws[i]),
|
||||
)
|
||||
for i in range(len(self))
|
||||
]
|
||||
|
||||
n = len(self)
|
||||
if n >= _PARALLEL_THRESHOLD:
|
||||
with ThreadPoolExecutor(max_workers=min(n, os.cpu_count() or 4)) as pool:
|
||||
new_rles: list[npt.NDArray[np.int32]] = list(
|
||||
pool.map(lambda a: _resize_crop(*a), args)
|
||||
)
|
||||
else:
|
||||
new_rles = [_resize_crop(*a) for a in args]
|
||||
|
||||
new_crop_shapes = np.column_stack((new_crop_hs, new_crop_ws)).astype(np.int32)
|
||||
new_offsets = np.column_stack((new_x1s, new_y1s)).astype(np.int32)
|
||||
return CompactMask(new_rles, new_crop_shapes, new_offsets, new_image_shape)
|
||||
|
||||
@@ -39,6 +39,9 @@ class CSVSink:
|
||||
|
||||
CSVSink allows passing custom data alongside detection fields, providing
|
||||
flexibility for logging various types of information.
|
||||
When a list or tuple value in custom_data (or detections.data) has the
|
||||
same length as the detection count, each element is written to the
|
||||
corresponding detection row; any other value is broadcast to all rows.
|
||||
|
||||
Args:
|
||||
file_name: The name of the CSV file where the detections will be stored.
|
||||
@@ -113,17 +116,56 @@ class CSVSink:
|
||||
self.file.close()
|
||||
|
||||
@staticmethod
|
||||
def _slice_value(value: Any, i: int) -> Any:
|
||||
def _slice_value(value: Any, i: int, n: int) -> Any:
|
||||
"""
|
||||
Return the i-th element when the value stores per-detection data.
|
||||
|
||||
Dispatch rules:
|
||||
- np.ndarray with ndim == 0: return as-is for broadcasting
|
||||
- np.ndarray with ndim >= 1: return value[i]
|
||||
- list or tuple with len equal to n: return value[i]
|
||||
- any other type: return as-is for broadcasting
|
||||
|
||||
Args:
|
||||
value: Custom-data field value.
|
||||
i: Zero-based detection index.
|
||||
n: Total number of detections.
|
||||
|
||||
Returns:
|
||||
Element at position i if value is a per-detection sequence,
|
||||
otherwise value unchanged.
|
||||
"""
|
||||
if isinstance(value, np.ndarray):
|
||||
return value if value.ndim == 0 else value[i]
|
||||
if isinstance(value, (list, tuple)) and len(value) == n:
|
||||
return value[i]
|
||||
return value
|
||||
|
||||
@staticmethod
|
||||
def parse_detection_data(
|
||||
detections: Detections, custom_data: dict[str, Any] | None = None
|
||||
) -> list[dict[str, Any]]:
|
||||
"""
|
||||
Convert detections and optional custom data into per-detection rows.
|
||||
|
||||
Builds one dictionary per detection containing bounding box coordinates,
|
||||
detection attributes, and any values from ``detections.data`` or
|
||||
``custom_data``. List and tuple values in ``custom_data`` with length
|
||||
equal to ``len(detections.xyxy)`` are sliced one element per row; all
|
||||
other values are broadcast to every row.
|
||||
|
||||
Args:
|
||||
detections: Detection data to serialize into row dictionaries.
|
||||
custom_data: Optional extra fields to include in each row.
|
||||
|
||||
Returns:
|
||||
A list of dictionaries, one per detection, containing ``xyxy``
|
||||
coordinates, ``class_id``, ``confidence``, ``tracker_id``, and any
|
||||
values from ``detections.data`` or ``custom_data``.
|
||||
"""
|
||||
parsed_rows = []
|
||||
for i in range(len(detections.xyxy)):
|
||||
n = len(detections.xyxy)
|
||||
for i in range(n):
|
||||
row = {
|
||||
"x_min": detections.xyxy[i][0],
|
||||
"y_min": detections.xyxy[i][1],
|
||||
@@ -142,11 +184,11 @@ class CSVSink:
|
||||
|
||||
if hasattr(detections, "data"):
|
||||
for key, value in detections.data.items():
|
||||
row[key] = CSVSink._slice_value(value, i)
|
||||
row[key] = CSVSink._slice_value(value, i, n)
|
||||
|
||||
if custom_data:
|
||||
for key, value in custom_data.items():
|
||||
row[key] = CSVSink._slice_value(value, i)
|
||||
row[key] = CSVSink._slice_value(value, i, n)
|
||||
|
||||
parsed_rows.append(row)
|
||||
return parsed_rows
|
||||
@@ -159,7 +201,11 @@ class CSVSink:
|
||||
|
||||
Args:
|
||||
detections: The detection data.
|
||||
custom_data: Custom data to include.
|
||||
custom_data: Custom data to include. Scalars, dictionaries, and
|
||||
other non-sequence values are broadcast to every detection in
|
||||
this batch. NumPy arrays, lists, and tuples with length equal
|
||||
to ``len(detections)`` are sliced per detection; other lists
|
||||
and tuples are broadcast unchanged.
|
||||
"""
|
||||
if not self.writer:
|
||||
raise Exception(
|
||||
|
||||
@@ -21,6 +21,9 @@ class JSONSink:
|
||||
|
||||
JSONSink allows passing custom data alongside detection fields, providing
|
||||
flexibility for logging various types of information.
|
||||
When a list or tuple value in custom_data (or detections.data) has the
|
||||
same length as the detection count, each element is written to the
|
||||
corresponding detection row; any other value is broadcast to all rows.
|
||||
|
||||
Args:
|
||||
file_name: The name of the JSON file where the detections will be stored.
|
||||
@@ -85,17 +88,56 @@ class JSONSink:
|
||||
self.file.close()
|
||||
|
||||
@staticmethod
|
||||
def _slice_value(value: Any, i: int) -> Any:
|
||||
def _slice_value(value: Any, i: int, n: int) -> Any:
|
||||
"""
|
||||
Return the i-th element when the value stores per-detection data.
|
||||
|
||||
Dispatch rules:
|
||||
- np.ndarray with ndim == 0: return as-is for broadcasting
|
||||
- np.ndarray with ndim >= 1: return value[i]
|
||||
- list or tuple with len equal to n: return value[i]
|
||||
- any other type: return as-is for broadcasting
|
||||
|
||||
Args:
|
||||
value: Custom-data field value.
|
||||
i: Zero-based detection index.
|
||||
n: Total number of detections.
|
||||
|
||||
Returns:
|
||||
Element at position i if value is a per-detection sequence,
|
||||
otherwise value unchanged.
|
||||
"""
|
||||
if isinstance(value, np.ndarray):
|
||||
return value if value.ndim == 0 else value[i]
|
||||
if isinstance(value, (list, tuple)) and len(value) == n:
|
||||
return value[i]
|
||||
return value
|
||||
|
||||
@staticmethod
|
||||
def parse_detection_data(
|
||||
detections: Detections, custom_data: dict[str, Any] | None = None
|
||||
) -> list[dict[str, Any]]:
|
||||
"""
|
||||
Convert detections and optional custom data into per-detection rows.
|
||||
|
||||
Builds one dictionary per detection containing bounding box coordinates,
|
||||
detection attributes, and any values from ``detections.data`` or
|
||||
``custom_data``. List and tuple values in ``custom_data`` with length
|
||||
equal to ``len(detections.xyxy)`` are sliced one element per row; all
|
||||
other values are broadcast to every row.
|
||||
|
||||
Args:
|
||||
detections: Detection data to serialize into row dictionaries.
|
||||
custom_data: Optional extra fields to include in each row.
|
||||
|
||||
Returns:
|
||||
A list of dictionaries, one per detection, containing ``xyxy``
|
||||
coordinates, ``class_id``, ``confidence``, ``tracker_id``, and any
|
||||
values from ``detections.data`` or ``custom_data``.
|
||||
"""
|
||||
parsed_rows = []
|
||||
for i in range(len(detections.xyxy)):
|
||||
n = len(detections.xyxy)
|
||||
for i in range(n):
|
||||
row = {
|
||||
"x_min": float(detections.xyxy[i][0]),
|
||||
"y_min": float(detections.xyxy[i][1]),
|
||||
@@ -114,11 +156,11 @@ class JSONSink:
|
||||
|
||||
if hasattr(detections, "data"):
|
||||
for key, value in detections.data.items():
|
||||
row[key] = str(JSONSink._slice_value(value, i))
|
||||
row[key] = str(JSONSink._slice_value(value, i, n))
|
||||
|
||||
if custom_data:
|
||||
for key, value in custom_data.items():
|
||||
v = JSONSink._slice_value(value, i)
|
||||
v = JSONSink._slice_value(value, i, n)
|
||||
row[key] = str(v) if isinstance(value, np.ndarray) else v
|
||||
|
||||
parsed_rows.append(row)
|
||||
@@ -132,7 +174,11 @@ class JSONSink:
|
||||
|
||||
Args:
|
||||
detections: The detection data.
|
||||
custom_data: Custom data to include.
|
||||
custom_data: Custom data to include. Scalars, dictionaries, and
|
||||
other non-sequence values are broadcast to every detection in
|
||||
this batch. NumPy arrays, lists, and tuples with length equal
|
||||
to ``len(detections)`` are sliced per detection; other lists
|
||||
and tuples are broadcast unchanged.
|
||||
"""
|
||||
parsed_rows = JSONSink.parse_detection_data(detections, custom_data)
|
||||
self.data.extend(parsed_rows)
|
||||
|
||||
@@ -2,6 +2,7 @@ from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
from deprecate import deprecated
|
||||
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch
|
||||
|
||||
@@ -95,10 +96,17 @@ def pad_boxes(
|
||||
return result
|
||||
|
||||
|
||||
@deprecated( # type: ignore[untyped-decorator]
|
||||
target=True,
|
||||
deprecated_in="0.27.0",
|
||||
remove_in="0.30.0",
|
||||
args_mapping={"normalized_xyxy": "xyxy"},
|
||||
)
|
||||
def denormalize_boxes(
|
||||
xyxy: npt.NDArray[np.number],
|
||||
resolution_wh: tuple[int, int],
|
||||
normalization_factor: float = 1.0,
|
||||
normalized_xyxy: npt.NDArray[np.number] | None = None,
|
||||
) -> npt.NDArray[np.number]:
|
||||
"""
|
||||
Convert normalized bounding box coordinates to absolute pixel coordinates.
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Any
|
||||
from typing import Any, cast
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -308,21 +308,35 @@ def mask_to_polygons(mask: npt.NDArray[np.bool_]) -> list[npt.NDArray[np.int32]]
|
||||
]
|
||||
|
||||
|
||||
def _decode_coco_rle_string(s: str) -> list[int]:
|
||||
"""Decode a COCO compressed RLE counts string to a list of run-length integers.
|
||||
def _base48_decode(s: str) -> list[int]:
|
||||
"""Decode a COCO base-48 string to raw (delta-encoded) integers.
|
||||
|
||||
Implements the decoding algorithm from the COCO API (pycocotools) for
|
||||
compressed RLE strings. Each character encodes 5 data bits in a base-48
|
||||
scheme with continuation and sign flags, using delta encoding for indices
|
||||
beyond the first two.
|
||||
Implements the variable-length base-48 codec from the COCO API
|
||||
(pycocotools). Each integer is encoded across one or more 6-bit
|
||||
characters: bits 0-4 carry data; bit 5 signals continuation; bit 4
|
||||
of the final character signals a negative value.
|
||||
|
||||
This is the pure codec layer — call :func:`_delta_decode` on the
|
||||
result to obtain absolute run-length counts.
|
||||
|
||||
Args:
|
||||
s: The compressed RLE counts string.
|
||||
s: COCO compressed RLE string.
|
||||
|
||||
Returns:
|
||||
A list of run-length integers (alternating background/foreground counts).
|
||||
Raw delta-encoded integers, one per run.
|
||||
|
||||
Raises:
|
||||
ValueError: If the string is truncated mid-integer.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> from supervision.detection.utils.converters import _base48_decode
|
||||
>>> _base48_decode("52203")
|
||||
[5, 2, 2, 0, 3]
|
||||
|
||||
```
|
||||
"""
|
||||
counts: list[int] = []
|
||||
values: list[int] = []
|
||||
i = 0
|
||||
while i < len(s):
|
||||
x = 0
|
||||
@@ -340,28 +354,35 @@ def _decode_coco_rle_string(s: str) -> list[int]:
|
||||
k += 1
|
||||
if not more and (c & 0x10):
|
||||
x |= ~0 << (5 * k)
|
||||
if len(counts) > 2:
|
||||
x += counts[-2]
|
||||
counts.append(x)
|
||||
return counts
|
||||
values.append(x)
|
||||
return values
|
||||
|
||||
|
||||
def _encode_coco_rle_string(counts: list[int]) -> str:
|
||||
"""Encode a list of run-length integers to a COCO compressed RLE string.
|
||||
def _base48_encode(values: list[int]) -> str:
|
||||
"""Encode raw (delta-encoded) integers to a COCO base-48 string.
|
||||
|
||||
Implements the encoding algorithm from the COCO API (pycocotools).
|
||||
The inverse of :func:`_decode_coco_rle_string`.
|
||||
The inverse of :func:`_base48_decode`. Applies the same variable-length
|
||||
base-48 codec used by pycocotools.
|
||||
|
||||
Apply :func:`_delta_encode` to absolute run-length counts before calling
|
||||
this function to produce a valid COCO compressed RLE string.
|
||||
|
||||
Args:
|
||||
counts: A list of run-length integers (alternating background/foreground
|
||||
counts).
|
||||
values: Raw (delta-encoded) integers to encode.
|
||||
|
||||
Returns:
|
||||
The compressed RLE counts string.
|
||||
COCO base-48 encoded string.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> from supervision.detection.utils.converters import _base48_encode
|
||||
>>> _base48_encode([5, 2, 2, 0, 3])
|
||||
'52203'
|
||||
|
||||
```
|
||||
"""
|
||||
chars: list[str] = []
|
||||
for i, cnt in enumerate(counts):
|
||||
x = cnt - counts[i - 2] if i > 2 else cnt
|
||||
for x in values:
|
||||
more = True
|
||||
while more:
|
||||
c = x & 0x1F
|
||||
@@ -373,6 +394,163 @@ def _encode_coco_rle_string(counts: list[int]) -> str:
|
||||
return "".join(chars)
|
||||
|
||||
|
||||
def _delta_decode(values: list[int]) -> list[int]:
|
||||
"""Undo COCO delta encoding: ``counts[i] += counts[i - 2]`` for ``i > 2``.
|
||||
|
||||
The COCO compressed RLE format stores run lengths as deltas relative to
|
||||
the count two positions earlier (starting at index 3). This function
|
||||
converts those relative values back to absolute run lengths.
|
||||
|
||||
Args:
|
||||
values: Raw delta-encoded integers from :func:`_base48_decode`.
|
||||
|
||||
Returns:
|
||||
Absolute run-length counts (alternating background / foreground).
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> from supervision.detection.utils.converters import _delta_decode
|
||||
>>> _delta_decode([5, 2, 2, 0, 3])
|
||||
[5, 2, 2, 2, 5]
|
||||
|
||||
```
|
||||
"""
|
||||
counts = list(values)
|
||||
for i in range(3, len(counts)):
|
||||
counts[i] += counts[i - 2]
|
||||
return counts
|
||||
|
||||
|
||||
def _delta_encode(counts: list[int]) -> list[int]:
|
||||
"""Apply COCO delta encoding: ``d[i] = counts[i] - counts[i - 2]`` for ``i > 2``.
|
||||
|
||||
The inverse of :func:`_delta_decode`. Converts absolute run lengths to
|
||||
the relative representation required by the COCO compressed RLE format.
|
||||
|
||||
Args:
|
||||
counts: Absolute run-length counts (alternating background / foreground).
|
||||
|
||||
Returns:
|
||||
Delta-encoded integers ready for :func:`_base48_encode`.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> from supervision.detection.utils.converters import _delta_encode
|
||||
>>> _delta_encode([5, 2, 2, 2, 5])
|
||||
[5, 2, 2, 0, 3]
|
||||
|
||||
```
|
||||
"""
|
||||
deltas = list(counts)
|
||||
for i in range(3, len(deltas)):
|
||||
deltas[i] = counts[i] - counts[i - 2]
|
||||
return deltas
|
||||
|
||||
|
||||
def is_compressed_rle(rle: object) -> bool:
|
||||
"""Return ``True`` if ``rle`` is a COCO compressed RLE (``str`` or ``bytes``).
|
||||
|
||||
Use this to branch between the compressed-string pipeline
|
||||
(:func:`_base48_decode` → :func:`_delta_decode`) and the uncompressed
|
||||
integer-list / array pipeline before calling :func:`rle_to_mask`.
|
||||
|
||||
Args:
|
||||
rle: Candidate RLE value to inspect.
|
||||
|
||||
Returns:
|
||||
``True`` for ``str`` or ``bytes`` inputs; ``False`` otherwise.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> from supervision.detection.utils.converters import is_compressed_rle
|
||||
>>> is_compressed_rle("52203")
|
||||
True
|
||||
>>> is_compressed_rle([5, 2, 2, 2, 5])
|
||||
False
|
||||
|
||||
```
|
||||
"""
|
||||
return isinstance(rle, (str, bytes))
|
||||
|
||||
|
||||
def _mask_to_rle_counts(mask_2d: npt.NDArray[Any]) -> npt.NDArray[np.int32]:
|
||||
"""Encode a 2D boolean mask as COCO F-order run lengths (int32 array).
|
||||
|
||||
Pixels are scanned column-by-column (Fortran order), matching the COCO /
|
||||
pycocotools RLE convention. The first value is always the count of leading
|
||||
``False`` pixels (may be 0 if the mask starts with ``True``).
|
||||
|
||||
This is the shared low-level encoder used by both :func:`mask_to_rle` and
|
||||
:class:`~supervision.detection.compact_mask.CompactMask`.
|
||||
|
||||
Args:
|
||||
mask_2d: 2D boolean array of shape ``(H, W)``.
|
||||
|
||||
Returns:
|
||||
int32 array of run lengths starting with the False count.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.utils.converters import _mask_to_rle_counts
|
||||
>>> mask = np.array([[False, True], [True, False]])
|
||||
>>> _mask_to_rle_counts(mask).tolist()
|
||||
[1, 2, 1]
|
||||
|
||||
```
|
||||
"""
|
||||
flat = np.asarray(mask_2d, dtype=np.bool_).ravel(order="F")
|
||||
if len(flat) == 0:
|
||||
return np.array([0], dtype=np.int32)
|
||||
|
||||
changes = np.diff(flat.view(np.uint8))
|
||||
boundaries = np.where(changes != 0)[0] + 1
|
||||
positions = np.concatenate(([0], boundaries, [len(flat)]))
|
||||
run_lengths = np.diff(positions).astype(np.int32)
|
||||
|
||||
if flat[0]:
|
||||
run_lengths = np.concatenate(([np.int32(0)], run_lengths))
|
||||
|
||||
return run_lengths
|
||||
|
||||
|
||||
def _rle_counts_to_mask(
|
||||
rle: npt.NDArray[np.int32], height: int, width: int
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
"""Decode COCO F-order run lengths back to a 2D boolean mask.
|
||||
|
||||
This is the shared low-level decoder used by both :func:`rle_to_mask` and
|
||||
:class:`~supervision.detection.compact_mask.CompactMask`.
|
||||
|
||||
Args:
|
||||
rle: int32 array of run lengths as produced by :func:`_mask_to_rle_counts`.
|
||||
height: Height of the output mask.
|
||||
width: Width of the output mask.
|
||||
|
||||
Returns:
|
||||
2D boolean array of shape ``(height, width)``.
|
||||
|
||||
Examples:
|
||||
```pycon
|
||||
>>> import numpy as np
|
||||
>>> from supervision.detection.utils.converters import _rle_counts_to_mask
|
||||
>>> rle = np.array([0, 1, 2, 1], dtype=np.int32)
|
||||
>>> _rle_counts_to_mask(rle, 2, 2)
|
||||
array([[ True, False],
|
||||
[False, True]])
|
||||
|
||||
```
|
||||
"""
|
||||
is_true = np.arange(len(rle)) % 2 == 1
|
||||
flat: npt.NDArray[np.bool_] = np.repeat(is_true, rle)
|
||||
num_pixels = height * width
|
||||
if len(flat) < num_pixels:
|
||||
flat = np.pad(flat, (0, num_pixels - len(flat)))
|
||||
return cast(
|
||||
npt.NDArray[np.bool_], flat[:num_pixels].reshape(height, width, order="F")
|
||||
)
|
||||
|
||||
|
||||
def rle_to_mask(
|
||||
rle: npt.NDArray[np.integer[Any]] | list[int] | str | bytes,
|
||||
resolution_wh: tuple[int, int],
|
||||
@@ -428,26 +606,23 @@ def rle_to_mask(
|
||||
if isinstance(rle, bytes):
|
||||
rle = rle.decode("utf-8")
|
||||
if isinstance(rle, str):
|
||||
rle = np.array(_decode_coco_rle_string(rle), dtype=int)
|
||||
counts: npt.NDArray[np.int32] = np.array(
|
||||
_delta_decode(_base48_decode(rle)), dtype=np.int32
|
||||
)
|
||||
elif isinstance(rle, list):
|
||||
rle = np.array(rle, dtype=int)
|
||||
counts = np.array(rle, dtype=np.int32)
|
||||
else:
|
||||
counts = np.asarray(rle, dtype=np.int32)
|
||||
|
||||
width, height = resolution_wh
|
||||
|
||||
if width * height != np.sum(rle):
|
||||
if width * height != np.sum(counts):
|
||||
raise ValueError(
|
||||
"the sum of the number of pixels in the RLE must be the same "
|
||||
"as the number of pixels in the expected mask"
|
||||
)
|
||||
|
||||
zero_one_values = np.zeros(shape=(rle.size, 1), dtype=np.uint8)
|
||||
zero_one_values[1::2] = 1
|
||||
|
||||
decoded_rle = np.repeat(zero_one_values, rle, axis=0)
|
||||
decoded_rle = np.append(
|
||||
decoded_rle, np.zeros(width * height - len(decoded_rle), dtype=np.uint8)
|
||||
)
|
||||
return decoded_rle.reshape((height, width), order="F").astype(bool)
|
||||
return _rle_counts_to_mask(counts, height, width)
|
||||
|
||||
|
||||
def mask_to_rle(
|
||||
@@ -519,24 +694,9 @@ def mask_to_rle(
|
||||
assert mask.ndim == 2, "Input mask must be 2D"
|
||||
assert mask.size != 0, "Input mask cannot be empty"
|
||||
|
||||
on_value_change_indices = np.where(
|
||||
mask.ravel(order="F") != np.roll(mask.ravel(order="F"), 1)
|
||||
)[0]
|
||||
|
||||
on_value_change_indices = np.append(on_value_change_indices, mask.size)
|
||||
# need to add 0 at the beginning when the same value is in the first and
|
||||
# last element of the flattened mask
|
||||
if on_value_change_indices[0] != 0:
|
||||
on_value_change_indices = np.insert(on_value_change_indices, 0, 0)
|
||||
|
||||
rle = np.diff(on_value_change_indices)
|
||||
|
||||
if mask[0][0] == 1:
|
||||
rle = np.insert(rle, 0, 0)
|
||||
|
||||
counts = [int(count) for count in rle]
|
||||
counts: list[int] = cast(list[int], _mask_to_rle_counts(mask).tolist())
|
||||
if compressed:
|
||||
return _encode_coco_rle_string(counts)
|
||||
return _base48_encode(_delta_encode(counts))
|
||||
return counts
|
||||
|
||||
|
||||
|
||||
@@ -724,3 +724,137 @@ class TestComparisonAnnotator:
|
||||
scene=image.copy(), detections_1=detections1, detections_2=detections2
|
||||
)
|
||||
assert not np.array_equal(image, result)
|
||||
|
||||
|
||||
class TestTraceAnnotatorSmoothStationary:
|
||||
"""Regression tests for TraceAnnotator(smooth=True) on stationary tracker ids."""
|
||||
|
||||
def test_stationary_tracker_does_not_crash_spline_fit(self, test_image):
|
||||
"""
|
||||
When the same tracker stays at an identical anchor point for several
|
||||
frames the trace buffer accumulates duplicate points. `scipy.splprep`
|
||||
rejects a zero-length input curve with `ValueError: Invalid inputs.`,
|
||||
so the annotator must survive this input without raising.
|
||||
"""
|
||||
detections = _create_detections(
|
||||
xyxy=[[100, 100, 120, 120]],
|
||||
class_id=[1],
|
||||
tracker_id=[42],
|
||||
)
|
||||
annotator = TraceAnnotator(smooth=True, trace_length=10)
|
||||
scene = test_image.copy()
|
||||
for _ in range(6):
|
||||
scene = annotator.annotate(scene=scene, detections=detections)
|
||||
assert scene.shape == test_image.shape
|
||||
|
||||
def test_smooth_trace_still_renders_for_moving_tracker(self, test_image):
|
||||
"""Moving tracker must produce a spline trace distinct from the raw polyline.
|
||||
|
||||
Compares smooth=True output against smooth=False for the same movement
|
||||
path to confirm the smoothing path is actually exercised (not just that
|
||||
some pixels changed).
|
||||
"""
|
||||
smooth_annotator = TraceAnnotator(smooth=True, trace_length=10, thickness=2)
|
||||
raw_annotator = TraceAnnotator(smooth=False, trace_length=10, thickness=2)
|
||||
scene_smooth = test_image.copy()
|
||||
scene_raw = test_image.copy()
|
||||
for offset in range(6):
|
||||
detections = _create_detections(
|
||||
xyxy=[
|
||||
[10 + offset * 5, 10 + offset * 5, 30 + offset * 5, 30 + offset * 5]
|
||||
],
|
||||
class_id=[1],
|
||||
tracker_id=[7],
|
||||
)
|
||||
scene_smooth = smooth_annotator.annotate(
|
||||
scene=scene_smooth, detections=detections
|
||||
)
|
||||
scene_raw = raw_annotator.annotate(scene=scene_raw, detections=detections)
|
||||
# After 4+ unique anchor positions the spline path fires and diverges from the
|
||||
# raw polyline — the two output images must differ.
|
||||
assert not np.array_equal(scene_smooth, scene_raw)
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"unique_positions",
|
||||
[1, 2, 3, 4],
|
||||
ids=["1_unique", "2_unique", "3_unique", "4_unique"],
|
||||
)
|
||||
def test_smooth_does_not_crash_for_unique_point_counts(
|
||||
self, test_image, unique_positions
|
||||
):
|
||||
"""smooth=True must not crash for any unique-position count from 1 to 4.
|
||||
|
||||
Each position is repeated twice to simulate brief holds between moves.
|
||||
Covers the boundary at len(unique_xy) == 4 where splprep first fires.
|
||||
"""
|
||||
annotator = TraceAnnotator(smooth=True, trace_length=10, thickness=2)
|
||||
scene = test_image.copy()
|
||||
for pos_idx in range(unique_positions):
|
||||
for _ in range(2):
|
||||
x = 10 + pos_idx * 15
|
||||
detections = _create_detections(
|
||||
xyxy=[[x, x, x + 15, x + 15]],
|
||||
class_id=[1],
|
||||
tracker_id=[99],
|
||||
)
|
||||
scene = annotator.annotate(scene=scene, detections=detections)
|
||||
assert scene.shape == test_image.shape
|
||||
|
||||
def test_smooth_fallback_matches_raw_when_fewer_than_four_unique_points(
|
||||
self, test_image
|
||||
):
|
||||
"""With <4 unique positions smooth=True output must match smooth=False.
|
||||
|
||||
Verifies the dedup-then-fallback path: when unique_xy has ≤3 points,
|
||||
both branches use the same raw-polyline draw.
|
||||
"""
|
||||
annotator_smooth = TraceAnnotator(smooth=True, trace_length=10, thickness=2)
|
||||
annotator_raw = TraceAnnotator(smooth=False, trace_length=10, thickness=2)
|
||||
scene_smooth = test_image.copy()
|
||||
scene_raw = test_image.copy()
|
||||
for pos_idx in range(3):
|
||||
for _ in range(2):
|
||||
x = 10 + pos_idx * 15
|
||||
detections = _create_detections(
|
||||
xyxy=[[x, x, x + 15, x + 15]],
|
||||
class_id=[1],
|
||||
tracker_id=[99],
|
||||
)
|
||||
scene_smooth = annotator_smooth.annotate(
|
||||
scene=scene_smooth, detections=detections
|
||||
)
|
||||
scene_raw = annotator_raw.annotate(
|
||||
scene=scene_raw, detections=detections
|
||||
)
|
||||
assert np.array_equal(scene_smooth, scene_raw)
|
||||
|
||||
def test_smooth_true_single_frame_does_not_crash(self, test_image):
|
||||
"""A single annotate() call with smooth=True must not crash.
|
||||
|
||||
When len(xy) == 1 the drawing guard skips cv2.polylines entirely;
|
||||
the dedup path runs safely on an empty np.diff result.
|
||||
"""
|
||||
detections = _create_detections(
|
||||
xyxy=[[50, 50, 70, 70]],
|
||||
class_id=[1],
|
||||
tracker_id=[1],
|
||||
)
|
||||
annotator = TraceAnnotator(smooth=True, trace_length=10)
|
||||
scene = annotator.annotate(scene=test_image.copy(), detections=detections)
|
||||
assert scene.shape == test_image.shape
|
||||
|
||||
def test_smooth_false_stationary_tracker_does_not_crash(self, test_image):
|
||||
"""smooth=False with a stationary tracker must not crash (regression guard).
|
||||
|
||||
Ensures the refactor did not accidentally alter the smooth=False code path.
|
||||
"""
|
||||
detections = _create_detections(
|
||||
xyxy=[[100, 100, 120, 120]],
|
||||
class_id=[1],
|
||||
tracker_id=[42],
|
||||
)
|
||||
annotator = TraceAnnotator(smooth=False, trace_length=10)
|
||||
scene = test_image.copy()
|
||||
for _ in range(6):
|
||||
scene = annotator.annotate(scene=scene, detections=detections)
|
||||
assert scene.shape == test_image.shape
|
||||
|
||||
@@ -1157,6 +1157,143 @@ def test_load_coco_annotations_force_masks_with_no_annotations(
|
||||
assert annotations[no_annotations_path] == Detections.empty()
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"file_name",
|
||||
[".", "", "subdir/.."],
|
||||
)
|
||||
def test_load_coco_annotations_rejects_file_name_resolving_to_images_directory(
|
||||
tmp_path,
|
||||
file_name: str,
|
||||
) -> None:
|
||||
"""Reject file_name resolving to the images directory itself (equality guard)."""
|
||||
images_directory = tmp_path / "images"
|
||||
images_directory.mkdir()
|
||||
annotations_path = tmp_path / "annotations.json"
|
||||
|
||||
coco_data = {
|
||||
"categories": [{"id": 1, "name": "object", "supercategory": "none"}],
|
||||
"images": [{"id": 1, "file_name": file_name, "width": 5, "height": 5}],
|
||||
"annotations": [],
|
||||
}
|
||||
annotations_path.write_text(json.dumps(coco_data), encoding="utf-8")
|
||||
|
||||
with pytest.raises(ValueError, match="resolves to the images directory itself"):
|
||||
load_coco_annotations(
|
||||
images_directory_path=str(images_directory),
|
||||
annotations_path=str(annotations_path),
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"malicious_file_name",
|
||||
[
|
||||
"../escape.txt",
|
||||
"../../escape.txt",
|
||||
"subdir/../../escape.txt",
|
||||
],
|
||||
)
|
||||
def test_load_coco_annotations_rejects_file_name_outside_images_directory(
|
||||
tmp_path,
|
||||
malicious_file_name: str,
|
||||
) -> None:
|
||||
"""Reject relative traversal file_name values that escape the images directory."""
|
||||
images_directory = tmp_path / "images"
|
||||
images_directory.mkdir()
|
||||
annotations_path = tmp_path / "annotations.json"
|
||||
|
||||
coco_data = {
|
||||
"categories": [{"id": 1, "name": "object", "supercategory": "none"}],
|
||||
"images": [
|
||||
{
|
||||
"id": 1,
|
||||
"file_name": malicious_file_name,
|
||||
"width": 5,
|
||||
"height": 5,
|
||||
}
|
||||
],
|
||||
"annotations": [],
|
||||
}
|
||||
annotations_path.write_text(json.dumps(coco_data), encoding="utf-8")
|
||||
|
||||
with pytest.raises(ValueError, match="outside the images directory"):
|
||||
load_coco_annotations(
|
||||
images_directory_path=str(images_directory),
|
||||
annotations_path=str(annotations_path),
|
||||
)
|
||||
|
||||
|
||||
def test_load_coco_annotations_rejects_absolute_file_name(tmp_path) -> None:
|
||||
"""Reject absolute file_name values that escape the images directory."""
|
||||
images_directory = tmp_path / "images"
|
||||
images_directory.mkdir()
|
||||
annotations_path = tmp_path / "annotations.json"
|
||||
|
||||
coco_data = {
|
||||
"categories": [{"id": 1, "name": "object", "supercategory": "none"}],
|
||||
"images": [
|
||||
{
|
||||
"id": 1,
|
||||
"file_name": "/etc/passwd",
|
||||
"width": 5,
|
||||
"height": 5,
|
||||
}
|
||||
],
|
||||
"annotations": [],
|
||||
}
|
||||
annotations_path.write_text(json.dumps(coco_data), encoding="utf-8")
|
||||
|
||||
with pytest.raises(ValueError, match="outside the images directory"):
|
||||
load_coco_annotations(
|
||||
images_directory_path=str(images_directory),
|
||||
annotations_path=str(annotations_path),
|
||||
)
|
||||
|
||||
|
||||
def test_load_coco_annotations_rejects_file_name_resolving_to_directory(
|
||||
tmp_path,
|
||||
) -> None:
|
||||
"""Reject file_name resolving to a subdirectory inside images/ (is_dir guard)."""
|
||||
images_directory = tmp_path / "images"
|
||||
images_directory.mkdir()
|
||||
(images_directory / "subdir").mkdir()
|
||||
annotations_path = tmp_path / "annotations.json"
|
||||
|
||||
coco_data = {
|
||||
"categories": [{"id": 1, "name": "object", "supercategory": "none"}],
|
||||
"images": [{"id": 1, "file_name": "subdir", "width": 5, "height": 5}],
|
||||
"annotations": [],
|
||||
}
|
||||
annotations_path.write_text(json.dumps(coco_data), encoding="utf-8")
|
||||
|
||||
with pytest.raises(ValueError, match="resolves to directory"):
|
||||
load_coco_annotations(
|
||||
images_directory_path=str(images_directory),
|
||||
annotations_path=str(annotations_path),
|
||||
)
|
||||
|
||||
|
||||
def test_load_coco_annotations_accepts_valid_nested_file_name(tmp_path) -> None:
|
||||
"""Accept a legitimate nested file_name inside images/ without raising."""
|
||||
images_directory = tmp_path / "images"
|
||||
images_directory.mkdir()
|
||||
(images_directory / "train").mkdir()
|
||||
annotations_path = tmp_path / "annotations.json"
|
||||
|
||||
coco_data = {
|
||||
"categories": [{"id": 1, "name": "object", "supercategory": "none"}],
|
||||
"images": [{"id": 1, "file_name": "train/image.jpg", "width": 5, "height": 5}],
|
||||
"annotations": [],
|
||||
}
|
||||
annotations_path.write_text(json.dumps(coco_data), encoding="utf-8")
|
||||
|
||||
_, _, annotations = load_coco_annotations(
|
||||
images_directory_path=str(images_directory),
|
||||
annotations_path=str(annotations_path),
|
||||
)
|
||||
expected_path = str(images_directory / "train" / "image.jpg")
|
||||
assert expected_path in annotations
|
||||
|
||||
|
||||
def test_load_coco_annotations_force_masks_handles_missing_segmentation(
|
||||
tmp_path,
|
||||
) -> None:
|
||||
|
||||
@@ -10,10 +10,13 @@ import pytest
|
||||
from supervision.detection.compact_mask import (
|
||||
CompactMask,
|
||||
_rle_area,
|
||||
_rle_decode,
|
||||
_rle_encode,
|
||||
)
|
||||
from supervision.detection.utils.converters import mask_to_xyxy
|
||||
from supervision.detection.utils.converters import (
|
||||
_mask_to_rle_counts,
|
||||
_rle_counts_to_mask,
|
||||
mask_to_rle,
|
||||
mask_to_xyxy,
|
||||
)
|
||||
from supervision.detection.utils.masks import (
|
||||
calculate_masks_centroids,
|
||||
contains_holes,
|
||||
@@ -31,7 +34,7 @@ def _make_cm(masks: np.ndarray, image_shape: tuple[int, int]) -> CompactMask:
|
||||
|
||||
|
||||
class TestRleHelpers:
|
||||
"""Tests for _rle_encode, _rle_decode, and _rle_area.
|
||||
"""Tests for _mask_to_rle_counts, _rle_counts_to_mask, and _rle_area.
|
||||
|
||||
Verifies that the private RLE encoding round-trips correctly for a range
|
||||
of mask shapes (all-False, all-True, diagonal, L-shape, checkerboard,
|
||||
@@ -61,14 +64,15 @@ class TestRleHelpers:
|
||||
def test_encode_decode_round_trip(
|
||||
self, mask_2d: np.ndarray, description: str
|
||||
) -> None:
|
||||
"""_mask_to_rle_counts -> _rle_counts_to_mask round-trip is lossless."""
|
||||
if mask_2d.size == 0:
|
||||
rle = _rle_encode(mask_2d)
|
||||
rle = _mask_to_rle_counts(mask_2d)
|
||||
assert _rle_area(rle) == 0
|
||||
return
|
||||
|
||||
rle = _rle_encode(mask_2d)
|
||||
rle = _mask_to_rle_counts(mask_2d)
|
||||
assert rle.dtype == np.int32, "RLE must be int32"
|
||||
reconstructed = _rle_decode(rle, mask_2d.shape[0], mask_2d.shape[1])
|
||||
reconstructed = _rle_counts_to_mask(rle, mask_2d.shape[0], mask_2d.shape[1])
|
||||
np.testing.assert_array_equal(
|
||||
reconstructed, mask_2d, err_msg=f"Round-trip failed for: {description}"
|
||||
)
|
||||
@@ -83,9 +87,48 @@ class TestRleHelpers:
|
||||
],
|
||||
)
|
||||
def test_area_matches_numpy_sum(self, mask_2d: np.ndarray) -> None:
|
||||
rle = _rle_encode(mask_2d)
|
||||
"""_rle_area must equal np.sum on the original boolean array."""
|
||||
rle = _mask_to_rle_counts(mask_2d)
|
||||
assert _rle_area(rle) == int(np.sum(mask_2d))
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("mask_2d", "expected_rle"),
|
||||
[
|
||||
# 2x3; F-order flat: [F,T,T,F,T,F] -> 1F,2T,1F,1T,1F
|
||||
(
|
||||
np.array([[False, True, True], [True, False, False]]),
|
||||
[1, 2, 1, 1, 1],
|
||||
),
|
||||
# 3x3 all-False -> single run of 9
|
||||
(np.zeros((3, 3), dtype=bool), [9]),
|
||||
# 3x1 all-True; F-order scan starts True -> leading zero prepended
|
||||
(np.ones((3, 1), dtype=bool), [0, 3]),
|
||||
# 2x2; F-order flat: [F,T,F,T] -> alternating single-pixel runs
|
||||
(
|
||||
np.array([[False, False], [True, True]]),
|
||||
[1, 1, 1, 1],
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_encode_matches_coco_f_order(
|
||||
self, mask_2d: np.ndarray, expected_rle: list[int]
|
||||
) -> None:
|
||||
"""_mask_to_rle_counts produces COCO-compatible F-order RLE for known masks."""
|
||||
assert _mask_to_rle_counts(mask_2d).tolist() == expected_rle
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"mask_2d",
|
||||
[
|
||||
np.array([[False, True, True], [True, False, False]]),
|
||||
np.zeros((4, 4), dtype=bool),
|
||||
np.array([[False, False], [True, True]]),
|
||||
np.ones((3, 1), dtype=bool),
|
||||
],
|
||||
)
|
||||
def test_encode_agrees_with_mask_to_rle(self, mask_2d: np.ndarray) -> None:
|
||||
"""_mask_to_rle_counts output matches the public mask_to_rle encoder."""
|
||||
assert _mask_to_rle_counts(mask_2d).tolist() == mask_to_rle(mask_2d)
|
||||
|
||||
|
||||
class TestFromDenseToDense:
|
||||
"""Tests for CompactMask.from_dense and to_dense.
|
||||
@@ -934,3 +977,615 @@ class TestCompactMaskWithOffsetRandom:
|
||||
expected,
|
||||
err_msg=f"Larger canvas offset mismatch for seed={seed}",
|
||||
)
|
||||
|
||||
|
||||
class TestRleSplitCols:
|
||||
"""Tests for _rle_split_cols: splitting F-order RLE into per-column lists."""
|
||||
|
||||
def test_all_true_2x2(self) -> None:
|
||||
"""All-True 2x2 splits into two columns each [0, 2]."""
|
||||
from supervision.detection.compact_mask import _rle_split_cols
|
||||
|
||||
mask = np.ones((2, 2), dtype=bool)
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result = _rle_split_cols(rle, 2, 2)
|
||||
assert result == [[0, 2], [0, 2]]
|
||||
|
||||
def test_all_false_3x3(self) -> None:
|
||||
"""All-False 3x3 splits into three columns each [3]."""
|
||||
from supervision.detection.compact_mask import _rle_split_cols
|
||||
|
||||
mask = np.zeros((3, 3), dtype=bool)
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result = _rle_split_cols(rle, 3, 3)
|
||||
assert result == [[3], [3], [3]]
|
||||
|
||||
def test_mixed_2x2(self) -> None:
|
||||
"""Mixed mask splits correctly per column."""
|
||||
from supervision.detection.compact_mask import _rle_split_cols
|
||||
|
||||
mask = np.array([[True, False], [True, True]], dtype=bool)
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result = _rle_split_cols(rle, 2, 2)
|
||||
assert result == [[0, 2], [1, 1]]
|
||||
|
||||
@pytest.mark.parametrize("seed", list(range(20)))
|
||||
def test_round_trip_random(self, seed: int) -> None:
|
||||
"""Split then rejoin must reconstruct original mask for random inputs."""
|
||||
from supervision.detection.compact_mask import (
|
||||
_rle_join_cols,
|
||||
_rle_split_cols,
|
||||
)
|
||||
|
||||
rng = np.random.default_rng(seed + 8000)
|
||||
crop_h = int(rng.integers(1, 30))
|
||||
crop_w = int(rng.integers(1, 30))
|
||||
mask = rng.random((crop_h, crop_w)) < 0.4
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
per_col = _rle_split_cols(rle, crop_h, crop_w)
|
||||
|
||||
assert len(per_col) == crop_w
|
||||
for c in range(crop_w):
|
||||
assert sum(per_col[c]) == crop_h, f"col {c} sum mismatch"
|
||||
|
||||
# Rejoin and verify pixel equality.
|
||||
rejoined = _rle_join_cols(per_col, crop_h * crop_w)
|
||||
decoded = _rle_counts_to_mask(rejoined, crop_h, crop_w)
|
||||
np.testing.assert_array_equal(
|
||||
decoded,
|
||||
mask,
|
||||
err_msg=f"Split→join round-trip failed for seed={seed}",
|
||||
)
|
||||
|
||||
def test_join_true_true_junction_no_zero_run(self) -> None:
|
||||
"""_rle_join_cols merges True/True boundary; no zero-length False run inserted.
|
||||
|
||||
When column A ends True and column B starts True (leading False count = 0),
|
||||
the junction must produce a single merged True run, not a zero-length False
|
||||
run between two True runs. A zero-length run would inflate len(rle) and
|
||||
misroute density-based dispatch in _resize_crop.
|
||||
"""
|
||||
from supervision.detection.compact_mask import _rle_join_cols
|
||||
|
||||
# col A: [0, 3] → T=3 (height=3, all True)
|
||||
# col B: [0, 3] → T=3 (height=3, all True)
|
||||
# Merged: should be [0, 6], NOT [0, 3, 0, 3].
|
||||
cols = [[0, 3], [0, 3]]
|
||||
result = _rle_join_cols(cols, 6).tolist()
|
||||
assert result == [0, 6], (
|
||||
f"Expected [0, 6] (merged True runs), got {result}; "
|
||||
"zero-length False run would inflate density metric"
|
||||
)
|
||||
assert 0 not in result[1:], "Zero-length run found after junction merge"
|
||||
|
||||
|
||||
class TestCompactMaskResize:
|
||||
"""Tests for CompactMask.resize method.
|
||||
|
||||
Verifies scaling behaviour, coordinate arithmetic, identity resize,
|
||||
empty collections, invalid dimensions, and dense parity with cv2.
|
||||
"""
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("src_shape", "mask_slice", "target_shape", "description"),
|
||||
[
|
||||
(
|
||||
(10, 10),
|
||||
(slice(2, 5), slice(2, 5)),
|
||||
(100, 100),
|
||||
"10x upscale 10x10 to 100x100",
|
||||
),
|
||||
(
|
||||
(480, 640),
|
||||
(slice(100, 200), slice(150, 300)),
|
||||
(240, 320),
|
||||
"HD halve 480x640 to 240x320",
|
||||
),
|
||||
(
|
||||
(100, 200),
|
||||
(slice(20, 40), slice(50, 100)),
|
||||
(50, 400),
|
||||
"asymmetric: shrink H, grow W",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_scale_shape_and_offsets(
|
||||
self,
|
||||
src_shape: tuple[int, int],
|
||||
mask_slice: tuple[slice, slice],
|
||||
target_shape: tuple[int, int],
|
||||
description: str,
|
||||
) -> None:
|
||||
"""Resize scales shape and offsets proportionally."""
|
||||
img_h, img_w = src_shape
|
||||
masks = np.zeros((1, img_h, img_w), dtype=bool)
|
||||
masks[0, mask_slice[0], mask_slice[1]] = True
|
||||
xyxy = mask_to_xyxy(masks)
|
||||
cm = CompactMask.from_dense(masks, xyxy, image_shape=src_shape)
|
||||
|
||||
resized = cm.resize(target_shape)
|
||||
|
||||
assert resized.shape == (1, target_shape[0], target_shape[1]), description
|
||||
|
||||
sx = target_shape[1] / src_shape[1]
|
||||
sy = target_shape[0] / src_shape[0]
|
||||
orig_offset_x = int(cm.offsets[0, 0])
|
||||
orig_offset_y = int(cm.offsets[0, 1])
|
||||
expected_x = round(orig_offset_x * sx)
|
||||
expected_y = round(orig_offset_y * sy)
|
||||
assert abs(int(resized.offsets[0, 0]) - expected_x) <= 1, description
|
||||
assert abs(int(resized.offsets[0, 1]) - expected_y) <= 1, description
|
||||
|
||||
def test_identity_preserves_rle(self) -> None:
|
||||
"""Resize to same shape returns identical RLE, offsets, and crop shapes."""
|
||||
masks = np.zeros((1, 80, 80), dtype=bool)
|
||||
masks[0, 10:30, 15:45] = True
|
||||
xyxy = mask_to_xyxy(masks)
|
||||
cm = CompactMask.from_dense(masks, xyxy, image_shape=(80, 80))
|
||||
|
||||
resized = cm.resize((80, 80))
|
||||
|
||||
assert resized.shape == cm.shape
|
||||
np.testing.assert_array_equal(resized.offsets, cm.offsets)
|
||||
np.testing.assert_array_equal(resized._crop_shapes, cm._crop_shapes)
|
||||
for orig_rle, new_rle in zip(cm._rles, resized._rles):
|
||||
np.testing.assert_array_equal(orig_rle, new_rle)
|
||||
|
||||
def test_empty_n0(self) -> None:
|
||||
"""Resize of an empty CompactMask returns empty with new image_shape."""
|
||||
masks = np.zeros((0, 50, 50), dtype=bool)
|
||||
xyxy = np.empty((0, 4), dtype=np.float32)
|
||||
cm = CompactMask.from_dense(masks, xyxy, image_shape=(50, 50))
|
||||
|
||||
resized = cm.resize((100, 200))
|
||||
|
||||
assert len(resized) == 0
|
||||
assert resized.shape == (0, 100, 200)
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"bad_shape",
|
||||
[
|
||||
(0, 50),
|
||||
(-1, 50),
|
||||
(50, 0),
|
||||
(50, -1),
|
||||
],
|
||||
)
|
||||
def test_invalid_dimensions_raises(self, bad_shape: tuple[int, int]) -> None:
|
||||
"""Resize with non-positive dimensions raises ValueError."""
|
||||
masks = np.zeros((1, 50, 50), dtype=bool)
|
||||
masks[0, 10:20, 10:20] = True
|
||||
xyxy = mask_to_xyxy(masks)
|
||||
cm = CompactMask.from_dense(masks, xyxy, image_shape=(50, 50))
|
||||
|
||||
with pytest.raises(ValueError, match="positive"):
|
||||
cm.resize(bad_shape)
|
||||
|
||||
def test_multi_mask_each_scales_independently(self) -> None:
|
||||
"""N=4 masks at different positions all scale correctly after resize."""
|
||||
img_h, img_w = 100, 100
|
||||
target_h, target_w = 50, 50
|
||||
masks = np.zeros((4, img_h, img_w), dtype=bool)
|
||||
masks[0, 10:20, 10:20] = True
|
||||
masks[1, 30:50, 30:50] = True
|
||||
masks[2, 60:80, 60:80] = True
|
||||
masks[3, 5:10, 80:90] = True
|
||||
xyxy = mask_to_xyxy(masks)
|
||||
cm = CompactMask.from_dense(masks, xyxy, image_shape=(img_h, img_w))
|
||||
|
||||
resized = cm.resize((target_h, target_w))
|
||||
|
||||
assert resized.shape == (4, target_h, target_w)
|
||||
sx = target_w / img_w
|
||||
sy = target_h / img_h
|
||||
for i in range(4):
|
||||
expected_x = round(int(cm.offsets[i, 0]) * sx)
|
||||
expected_y = round(int(cm.offsets[i, 1]) * sy)
|
||||
assert abs(int(resized.offsets[i, 0]) - expected_x) <= 1, f"mask {i} x"
|
||||
assert abs(int(resized.offsets[i, 1]) - expected_y) <= 1, f"mask {i} y"
|
||||
|
||||
def test_zero_extent_extreme_downscale(self) -> None:
|
||||
"""Extreme downscale that collapses a 1px bbox returns valid 1x1 crop."""
|
||||
masks = np.zeros((1, 1000, 1000), dtype=bool)
|
||||
masks[0, 500, 500] = True
|
||||
xyxy = mask_to_xyxy(masks)
|
||||
cm = CompactMask.from_dense(masks, xyxy, image_shape=(1000, 1000))
|
||||
|
||||
resized = cm.resize((2, 2))
|
||||
|
||||
assert resized.shape == (1, 2, 2)
|
||||
assert int(resized._crop_shapes[0, 0]) >= 1
|
||||
assert int(resized._crop_shapes[0, 1]) >= 1
|
||||
dense = resized.to_dense()
|
||||
assert dense.shape == (1, 2, 2)
|
||||
|
||||
@pytest.mark.parametrize("seed", list(range(10)))
|
||||
def test_dense_parity_roundtrip(self, seed: int) -> None:
|
||||
"""Resized CompactMask matches OpenCV-resized dense masks within 1px."""
|
||||
import cv2
|
||||
|
||||
rng = np.random.default_rng(seed + 500)
|
||||
img_h, img_w = 80, 120
|
||||
target_h, target_w = 40, 60
|
||||
num_masks = int(rng.integers(1, 5))
|
||||
masks, xyxy = _random_masks_and_xyxy(rng, num_masks, img_h, img_w)
|
||||
cm = CompactMask.from_dense(masks, xyxy, image_shape=(img_h, img_w))
|
||||
|
||||
resized = cm.resize((target_h, target_w))
|
||||
resized_dense = resized.to_dense()
|
||||
|
||||
for i in range(num_masks):
|
||||
expected = cv2.resize(
|
||||
masks[i].astype(np.uint8),
|
||||
(target_w, target_h),
|
||||
interpolation=cv2.INTER_NEAREST,
|
||||
).astype(bool)
|
||||
actual = resized_dense[i]
|
||||
diff = np.abs(actual.astype(int) - expected.astype(int)).max()
|
||||
assert int(diff) <= 1, (
|
||||
f"Dense parity mismatch for seed={seed}, mask={i}: "
|
||||
f"max pixel diff={diff}"
|
||||
)
|
||||
|
||||
|
||||
class TestRleResize:
|
||||
"""Tests for _rle_resize direct F-order RLE resizing.
|
||||
|
||||
Verifies that _rle_resize produces identical results to the decode ->
|
||||
cv2.resize(INTER_NEAREST) -> encode path for identity, upscale, downscale,
|
||||
non-square, all-False, all-True, single-pixel, and random masks.
|
||||
"""
|
||||
|
||||
def test_identity_4x4(self) -> None:
|
||||
"""Identity resize (same dimensions) preserves the decoded mask."""
|
||||
from supervision.detection.compact_mask import _rle_resize
|
||||
|
||||
mask = np.array(
|
||||
[
|
||||
[False, True, True, False],
|
||||
[True, True, False, False],
|
||||
[False, False, True, True],
|
||||
[True, False, False, True],
|
||||
],
|
||||
dtype=bool,
|
||||
)
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result_rle = _rle_resize(rle, 4, 4, 4, 4)
|
||||
result = _rle_counts_to_mask(result_rle, 4, 4)
|
||||
np.testing.assert_array_equal(result, mask)
|
||||
|
||||
def test_2x_upscale(self) -> None:
|
||||
"""2x upscale of a 2x2 mask doubles each pixel."""
|
||||
import cv2
|
||||
|
||||
from supervision.detection.compact_mask import _rle_resize
|
||||
|
||||
mask = np.array(
|
||||
[
|
||||
[True, False],
|
||||
[False, True],
|
||||
],
|
||||
dtype=bool,
|
||||
)
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result_rle = _rle_resize(rle, 2, 2, 4, 4)
|
||||
result = _rle_counts_to_mask(result_rle, 4, 4)
|
||||
|
||||
expected = cv2.resize(
|
||||
mask.astype(np.uint8), (4, 4), interpolation=cv2.INTER_NEAREST
|
||||
).astype(bool)
|
||||
np.testing.assert_array_equal(result, expected)
|
||||
|
||||
def test_2x_downscale(self) -> None:
|
||||
"""2x downscale of a 4x4 block mask halves dimensions."""
|
||||
import cv2
|
||||
|
||||
from supervision.detection.compact_mask import _rle_resize
|
||||
|
||||
mask = np.array(
|
||||
[
|
||||
[True, True, False, False],
|
||||
[True, True, False, False],
|
||||
[False, False, True, True],
|
||||
[False, False, True, True],
|
||||
],
|
||||
dtype=bool,
|
||||
)
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result_rle = _rle_resize(rle, 4, 4, 2, 2)
|
||||
result = _rle_counts_to_mask(result_rle, 2, 2)
|
||||
|
||||
expected = cv2.resize(
|
||||
mask.astype(np.uint8), (2, 2), interpolation=cv2.INTER_NEAREST
|
||||
).astype(bool)
|
||||
np.testing.assert_array_equal(result, expected)
|
||||
|
||||
def test_non_square_scale(self) -> None:
|
||||
"""Non-square resize: 4x6 to 2x3 with independent axis scaling."""
|
||||
import cv2
|
||||
|
||||
from supervision.detection.compact_mask import _rle_resize
|
||||
|
||||
mask = np.zeros((4, 6), dtype=bool)
|
||||
mask[0:2, 0:3] = True
|
||||
mask[2:4, 3:6] = True
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result_rle = _rle_resize(rle, 4, 6, 2, 3)
|
||||
result = _rle_counts_to_mask(result_rle, 2, 3)
|
||||
|
||||
expected = cv2.resize(
|
||||
mask.astype(np.uint8), (3, 2), interpolation=cv2.INTER_NEAREST
|
||||
).astype(bool)
|
||||
np.testing.assert_array_equal(result, expected)
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("src_shape", "dst_shape"),
|
||||
[
|
||||
((3, 3), (6, 6)),
|
||||
((5, 5), (2, 2)),
|
||||
((4, 6), (8, 12)),
|
||||
((10, 10), (3, 3)),
|
||||
],
|
||||
)
|
||||
def test_all_false(
|
||||
self, src_shape: tuple[int, int], dst_shape: tuple[int, int]
|
||||
) -> None:
|
||||
"""All-False mask resizes to all-False regardless of dimensions."""
|
||||
from supervision.detection.compact_mask import _rle_resize
|
||||
|
||||
mask = np.zeros(src_shape, dtype=bool)
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result_rle = _rle_resize(rle, *src_shape, *dst_shape)
|
||||
result = _rle_counts_to_mask(result_rle, *dst_shape)
|
||||
assert not result.any()
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("src_shape", "dst_shape"),
|
||||
[
|
||||
((3, 3), (6, 6)),
|
||||
((5, 5), (2, 2)),
|
||||
((4, 6), (8, 12)),
|
||||
((10, 10), (3, 3)),
|
||||
],
|
||||
)
|
||||
def test_all_true(
|
||||
self, src_shape: tuple[int, int], dst_shape: tuple[int, int]
|
||||
) -> None:
|
||||
"""All-True mask resizes to all-True regardless of dimensions."""
|
||||
from supervision.detection.compact_mask import _rle_resize
|
||||
|
||||
mask = np.ones(src_shape, dtype=bool)
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result_rle = _rle_resize(rle, *src_shape, *dst_shape)
|
||||
result = _rle_counts_to_mask(result_rle, *dst_shape)
|
||||
assert result.all()
|
||||
|
||||
def test_single_pixel_true_upscale(self) -> None:
|
||||
"""Single True pixel in a 3x3 mask upscaled preserves position."""
|
||||
import cv2
|
||||
|
||||
from supervision.detection.compact_mask import _rle_resize
|
||||
|
||||
mask = np.zeros((3, 3), dtype=bool)
|
||||
mask[1, 1] = True
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result_rle = _rle_resize(rle, 3, 3, 6, 6)
|
||||
result = _rle_counts_to_mask(result_rle, 6, 6)
|
||||
|
||||
expected = cv2.resize(
|
||||
mask.astype(np.uint8), (6, 6), interpolation=cv2.INTER_NEAREST
|
||||
).astype(bool)
|
||||
np.testing.assert_array_equal(result, expected)
|
||||
|
||||
@pytest.mark.parametrize("seed", list(range(45)))
|
||||
def test_roundtrip_parity_with_cv2(self, seed: int) -> None:
|
||||
"""_rle_resize matches cv2.resize(INTER_NEAREST) within 1-pixel tolerance."""
|
||||
import cv2
|
||||
|
||||
from supervision.detection.compact_mask import _rle_resize
|
||||
|
||||
rng = np.random.default_rng(seed + 7000)
|
||||
crop_h = int(rng.integers(1, 50))
|
||||
crop_w = int(rng.integers(1, 50))
|
||||
new_crop_h = int(rng.integers(1, 100))
|
||||
new_crop_w = int(rng.integers(1, 100))
|
||||
|
||||
mask = rng.random((crop_h, crop_w)) < 0.3
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result_rle = _rle_resize(rle, crop_h, crop_w, new_crop_h, new_crop_w)
|
||||
result = _rle_counts_to_mask(result_rle, new_crop_h, new_crop_w)
|
||||
|
||||
expected = cv2.resize(
|
||||
mask.astype(np.uint8),
|
||||
(new_crop_w, new_crop_h),
|
||||
interpolation=cv2.INTER_NEAREST,
|
||||
).astype(bool)
|
||||
diff = np.abs(result.astype(int) - expected.astype(int)).max()
|
||||
assert diff <= 1, (
|
||||
f"Parity mismatch >1px for seed={seed}, "
|
||||
f"src=({crop_h},{crop_w}), dst=({new_crop_h},{new_crop_w}): "
|
||||
f"max diff={diff}"
|
||||
)
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("src_shape", "dst_shape"),
|
||||
[
|
||||
((1, 10), (1, 5)),
|
||||
((10, 1), (5, 1)),
|
||||
((1, 20), (1, 40)),
|
||||
((20, 1), (40, 1)),
|
||||
],
|
||||
)
|
||||
def test_tall_and_wide_crops(
|
||||
self, src_shape: tuple[int, int], dst_shape: tuple[int, int]
|
||||
) -> None:
|
||||
"""Single-row and single-col crops scale correctly with cv2 parity."""
|
||||
import cv2
|
||||
|
||||
from supervision.detection.compact_mask import _rle_resize
|
||||
|
||||
rng = np.random.default_rng(src_shape[0] * 31 + dst_shape[1] * 17)
|
||||
mask = rng.random(src_shape) < 0.5
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result_rle = _rle_resize(rle, *src_shape, *dst_shape)
|
||||
result = _rle_counts_to_mask(result_rle, *dst_shape)
|
||||
|
||||
expected = cv2.resize(
|
||||
mask.astype(np.uint8),
|
||||
(dst_shape[1], dst_shape[0]),
|
||||
interpolation=cv2.INTER_NEAREST,
|
||||
).astype(bool)
|
||||
np.testing.assert_array_equal(result, expected)
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("src_shape", "dst_shape"),
|
||||
[
|
||||
((7, 11), (5, 13)),
|
||||
((13, 7), (17, 3)),
|
||||
((3, 5), (11, 7)),
|
||||
((11, 13), (7, 17)),
|
||||
],
|
||||
)
|
||||
def test_prime_sized_crops(
|
||||
self, src_shape: tuple[int, int], dst_shape: tuple[int, int]
|
||||
) -> None:
|
||||
"""Prime-sized crops with non-integer scale ratios match cv2 exactly."""
|
||||
import cv2
|
||||
|
||||
from supervision.detection.compact_mask import _rle_resize
|
||||
|
||||
rng = np.random.default_rng(src_shape[0] * 101 + dst_shape[1] * 53)
|
||||
mask = rng.random(src_shape) < 0.4
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result_rle = _rle_resize(rle, *src_shape, *dst_shape)
|
||||
result = _rle_counts_to_mask(result_rle, *dst_shape)
|
||||
|
||||
expected = cv2.resize(
|
||||
mask.astype(np.uint8),
|
||||
(dst_shape[1], dst_shape[0]),
|
||||
interpolation=cv2.INTER_NEAREST,
|
||||
).astype(bool)
|
||||
np.testing.assert_array_equal(result, expected)
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("src_val", "src_shape", "dst_shape"),
|
||||
[
|
||||
(True, (1, 1), (32, 32)),
|
||||
(False, (1, 1), (32, 32)),
|
||||
],
|
||||
)
|
||||
def test_large_scale_ratio(
|
||||
self,
|
||||
src_val: bool,
|
||||
src_shape: tuple[int, int],
|
||||
dst_shape: tuple[int, int],
|
||||
) -> None:
|
||||
"""1x1 source resized to large shape fills entirely True or False."""
|
||||
from supervision.detection.compact_mask import _rle_resize
|
||||
|
||||
mask = np.full(src_shape, src_val, dtype=bool)
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
result_rle = _rle_resize(rle, *src_shape, *dst_shape)
|
||||
result = _rle_counts_to_mask(result_rle, *dst_shape)
|
||||
|
||||
if src_val:
|
||||
assert result.all(), "1x1 True -> large shape must be all True"
|
||||
else:
|
||||
assert not result.any(), "1x1 False -> large shape must be all False"
|
||||
|
||||
def test_resize_dispatch_uses_l3_for_sparse(self) -> None:
|
||||
"""resize() dispatches to _rle_resize for sparse masks."""
|
||||
img_h, img_w = 100, 100
|
||||
masks = np.zeros((1, img_h, img_w), dtype=bool)
|
||||
masks[0, 50, 50] = True
|
||||
xyxy = mask_to_xyxy(masks).astype(np.float32)
|
||||
cm = CompactMask.from_dense(masks, xyxy, image_shape=(img_h, img_w))
|
||||
|
||||
resized = cm.resize((200, 200))
|
||||
|
||||
assert resized.shape == (1, 200, 200)
|
||||
dense = resized.to_dense()
|
||||
assert dense.sum() > 0
|
||||
|
||||
def test_resize_dispatch_uses_cv2_for_dense(self) -> None:
|
||||
"""_resize_crop falls back to cv2 for dense masks (above _L3_DENSITY_THRESHOLD).
|
||||
|
||||
Checkerboard yields ~1 run per pixel, far above the 0.25 threshold.
|
||||
Result must match cv2.resize(INTER_NEAREST) within 1 pixel.
|
||||
"""
|
||||
import cv2
|
||||
|
||||
from supervision.detection.compact_mask import (
|
||||
_L3_DENSITY_THRESHOLD,
|
||||
_resize_crop,
|
||||
)
|
||||
from supervision.detection.utils.converters import _mask_to_rle_counts
|
||||
|
||||
h, w = 20, 20
|
||||
# Checkerboard: alternates True/False → very dense RLE.
|
||||
rows, cols = np.meshgrid(np.arange(h), np.arange(w), indexing="ij")
|
||||
mask = ((rows + cols) % 2).astype(bool)
|
||||
rle = _mask_to_rle_counts(mask)
|
||||
density = len(rle) / max(1, h * w)
|
||||
assert density >= _L3_DENSITY_THRESHOLD, (
|
||||
f"Test precondition failed: density {density:.3f} < threshold "
|
||||
f"{_L3_DENSITY_THRESHOLD}; checkerboard should be dense"
|
||||
)
|
||||
|
||||
result_rle = _resize_crop(rle, h, w, h // 2, w // 2)
|
||||
result = _rle_counts_to_mask(result_rle, h // 2, w // 2)
|
||||
expected = cv2.resize(
|
||||
mask.astype(np.uint8), (w // 2, h // 2), interpolation=cv2.INTER_NEAREST
|
||||
).astype(bool)
|
||||
diff = np.abs(result.astype(int) - expected.astype(int)).max()
|
||||
assert int(diff) <= 1, f"Dense-path cv2 parity failed; max pixel diff={diff}"
|
||||
|
||||
|
||||
class TestResizeParallelPath:
|
||||
"""Tests for CompactMask.resize() thread-pool code path (N >= 8 masks)."""
|
||||
|
||||
def test_parallel_resize_correctness(self) -> None:
|
||||
"""resize() with N=10 masks exercises ThreadPoolExecutor; output is correct."""
|
||||
img_h, img_w = 80, 80
|
||||
n = 10 # above _PARALLEL_THRESHOLD = 8
|
||||
masks = np.zeros((n, img_h, img_w), dtype=bool)
|
||||
for i in range(n):
|
||||
r = 10 + i * 3
|
||||
masks[i, r : r + 8, r : r + 8] = True
|
||||
xyxy = mask_to_xyxy(masks).astype(np.float32)
|
||||
cm = CompactMask.from_dense(masks, xyxy, image_shape=(img_h, img_w))
|
||||
|
||||
target = (40, 40)
|
||||
resized = cm.resize(target)
|
||||
|
||||
assert resized.shape == (n, target[0], target[1])
|
||||
assert len(resized) == n
|
||||
# Each resized mask must be non-empty (the small squares survive downscale).
|
||||
for i in range(n):
|
||||
assert resized[i].any(), f"Mask {i} is empty after parallel resize"
|
||||
|
||||
def test_parallel_matches_sequential(self) -> None:
|
||||
"""Thread-pool path produces the same result as the sequential path."""
|
||||
img_h, img_w = 60, 60
|
||||
n_parallel = 10 # triggers thread pool
|
||||
n_sequential = 4 # stays sequential
|
||||
rng = np.random.default_rng(0)
|
||||
|
||||
def _make_masks(n: int) -> CompactMask:
|
||||
masks = np.zeros((n, img_h, img_w), dtype=bool)
|
||||
for i in range(n):
|
||||
r, c = int(rng.integers(5, 30)), int(rng.integers(5, 30))
|
||||
masks[i, r : r + 10, c : c + 10] = True
|
||||
xyxy = mask_to_xyxy(masks).astype(np.float32)
|
||||
return CompactMask.from_dense(masks, xyxy, image_shape=(img_h, img_w))
|
||||
|
||||
cm_par = _make_masks(n_parallel)
|
||||
cm_seq = _make_masks(n_sequential)
|
||||
|
||||
target = (30, 30)
|
||||
resized_par = cm_par.resize(target)
|
||||
resized_seq = cm_seq.resize(target)
|
||||
|
||||
# Both return correct shapes.
|
||||
assert resized_par.shape == (n_parallel, target[0], target[1])
|
||||
assert resized_seq.shape == (n_sequential, target[0], target[1])
|
||||
|
||||
@@ -1,3 +1,5 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import csv
|
||||
import os
|
||||
from typing import Any
|
||||
@@ -6,6 +8,7 @@ import numpy as np
|
||||
import pytest
|
||||
|
||||
import supervision as sv
|
||||
from supervision.detection.tools.csv_sink import CSVSink
|
||||
from tests.helpers import _create_detections
|
||||
|
||||
|
||||
@@ -225,19 +228,85 @@ from tests.helpers import _create_detections
|
||||
["15.0", "25.0", "35.0", "45.0", "2", "0.7", "", "100.0", "6"],
|
||||
],
|
||||
), # mixed custom_data: ndarray sliced per row, scalar broadcast to all rows
|
||||
(
|
||||
_create_detections(
|
||||
xyxy=[[10, 20, 30, 40], [50, 60, 70, 80]],
|
||||
confidence=[0.9, 0.8],
|
||||
class_id=[0, 1],
|
||||
),
|
||||
{"ids": ["a", "b"], "tags": ("x", "y"), "frame": 7},
|
||||
_create_detections(
|
||||
xyxy=[[15, 25, 35, 45]],
|
||||
confidence=[0.7],
|
||||
class_id=[2],
|
||||
),
|
||||
{"ids": ["c"], "tags": ("z",), "frame": 8},
|
||||
"test_detections_list_custom_data.csv",
|
||||
[
|
||||
[
|
||||
"x_min",
|
||||
"y_min",
|
||||
"x_max",
|
||||
"y_max",
|
||||
"class_id",
|
||||
"confidence",
|
||||
"tracker_id",
|
||||
"frame",
|
||||
"ids",
|
||||
"tags",
|
||||
],
|
||||
["10.0", "20.0", "30.0", "40.0", "0", "0.9", "", "7", "a", "x"],
|
||||
["50.0", "60.0", "70.0", "80.0", "1", "0.8", "", "7", "b", "y"],
|
||||
["15.0", "25.0", "35.0", "45.0", "2", "0.7", "", "8", "c", "z"],
|
||||
],
|
||||
), # list/tuple custom_data matching detection count is sliced per row
|
||||
(
|
||||
sv.Detections(
|
||||
xyxy=np.array([[10, 20, 30, 40], [50, 60, 70, 80]]),
|
||||
data={"labels": ["person", "car"]},
|
||||
),
|
||||
None,
|
||||
sv.Detections(
|
||||
xyxy=np.array([[15, 25, 35, 45]]),
|
||||
data={"labels": ["bus"]},
|
||||
),
|
||||
None,
|
||||
"test_detections_plain_list_data.csv",
|
||||
[
|
||||
[
|
||||
"x_min",
|
||||
"y_min",
|
||||
"x_max",
|
||||
"y_max",
|
||||
"class_id",
|
||||
"confidence",
|
||||
"tracker_id",
|
||||
"labels",
|
||||
],
|
||||
["10", "20", "30", "40", "", "", "", "person"],
|
||||
["50", "60", "70", "80", "", "", "", "car"],
|
||||
["15", "25", "35", "45", "", "", "", "bus"],
|
||||
],
|
||||
), # plain Python list in detections.data is sliced per row without custom_data
|
||||
],
|
||||
)
|
||||
def test_csv_sink(
|
||||
detections: sv.Detections,
|
||||
custom_data: dict[str, Any],
|
||||
custom_data: dict[str, Any] | None,
|
||||
second_detections: sv.Detections,
|
||||
second_custom_data: dict[str, Any],
|
||||
second_custom_data: dict[str, Any] | None,
|
||||
file_name: str,
|
||||
expected_result: list[list[Any]],
|
||||
) -> None:
|
||||
with sv.CSVSink(file_name) as sink:
|
||||
sink.append(detections, custom_data)
|
||||
sink.append(second_detections, second_custom_data)
|
||||
if custom_data is None:
|
||||
sink.append(detections)
|
||||
else:
|
||||
sink.append(detections, custom_data)
|
||||
if second_custom_data is None:
|
||||
sink.append(second_detections)
|
||||
else:
|
||||
sink.append(second_detections, second_custom_data)
|
||||
|
||||
assert_csv_equal(file_name, expected_result)
|
||||
|
||||
@@ -455,3 +524,18 @@ def assert_csv_equal(file_name, expected_rows):
|
||||
)
|
||||
|
||||
os.remove(file_name)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("value", "i", "n", "expected"),
|
||||
[
|
||||
(["x"], 0, 1, "x"),
|
||||
(["a", "b", "c"], 0, 2, ["a", "b", "c"]),
|
||||
([42, "hello", None], 1, 3, "hello"),
|
||||
([["a", "b"], ["c", "d"]], 0, 2, ["a", "b"]),
|
||||
("ab", 0, 2, "ab"),
|
||||
(("z",), 0, 1, "z"),
|
||||
],
|
||||
)
|
||||
def test_csv_sink_slice_value(value: Any, i: int, n: int, expected: Any) -> None:
|
||||
assert CSVSink._slice_value(value, i, n) == expected
|
||||
|
||||
@@ -1,3 +1,5 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import os
|
||||
from typing import Any
|
||||
@@ -275,19 +277,120 @@ from tests.helpers import _create_detections
|
||||
},
|
||||
],
|
||||
), # numpy array in custom_data sliced per detection row
|
||||
(
|
||||
_create_detections(
|
||||
xyxy=[[10, 20, 30, 40], [50, 60, 70, 80]],
|
||||
confidence=[0.9, 0.8],
|
||||
class_id=[0, 1],
|
||||
),
|
||||
{"ids": ["a", "b"], "tags": ("x", "y")},
|
||||
_create_detections(
|
||||
xyxy=[[15, 25, 35, 45]],
|
||||
confidence=[0.7],
|
||||
class_id=[2],
|
||||
),
|
||||
{"ids": ["c"], "tags": ("z",)},
|
||||
"test_detections_list_custom_data.json",
|
||||
[
|
||||
{
|
||||
"x_min": 10,
|
||||
"y_min": 20,
|
||||
"x_max": 30,
|
||||
"y_max": 40,
|
||||
"class_id": 0,
|
||||
"confidence": 0.8999999761581421,
|
||||
"tracker_id": "",
|
||||
"ids": "a",
|
||||
"tags": "x",
|
||||
},
|
||||
{
|
||||
"x_min": 50,
|
||||
"y_min": 60,
|
||||
"x_max": 70,
|
||||
"y_max": 80,
|
||||
"class_id": 1,
|
||||
"confidence": 0.800000011920929,
|
||||
"tracker_id": "",
|
||||
"ids": "b",
|
||||
"tags": "y",
|
||||
},
|
||||
{
|
||||
"x_min": 15,
|
||||
"y_min": 25,
|
||||
"x_max": 35,
|
||||
"y_max": 45,
|
||||
"class_id": 2,
|
||||
"confidence": 0.699999988079071,
|
||||
"tracker_id": "",
|
||||
"ids": "c",
|
||||
"tags": "z",
|
||||
},
|
||||
],
|
||||
), # list/tuple custom_data matching detection count is sliced per row
|
||||
(
|
||||
sv.Detections(
|
||||
xyxy=np.array([[10, 20, 30, 40], [50, 60, 70, 80]]),
|
||||
data={"labels": ["person", "car"]},
|
||||
),
|
||||
None,
|
||||
sv.Detections(
|
||||
xyxy=np.array([[15, 25, 35, 45]]),
|
||||
data={"labels": ["bus"]},
|
||||
),
|
||||
None,
|
||||
"test_detections_plain_list_data.json",
|
||||
[
|
||||
{
|
||||
"x_min": 10.0,
|
||||
"y_min": 20.0,
|
||||
"x_max": 30.0,
|
||||
"y_max": 40.0,
|
||||
"class_id": "",
|
||||
"confidence": "",
|
||||
"tracker_id": "",
|
||||
"labels": "person",
|
||||
},
|
||||
{
|
||||
"x_min": 50.0,
|
||||
"y_min": 60.0,
|
||||
"x_max": 70.0,
|
||||
"y_max": 80.0,
|
||||
"class_id": "",
|
||||
"confidence": "",
|
||||
"tracker_id": "",
|
||||
"labels": "car",
|
||||
},
|
||||
{
|
||||
"x_min": 15.0,
|
||||
"y_min": 25.0,
|
||||
"x_max": 35.0,
|
||||
"y_max": 45.0,
|
||||
"class_id": "",
|
||||
"confidence": "",
|
||||
"tracker_id": "",
|
||||
"labels": "bus",
|
||||
},
|
||||
],
|
||||
), # plain Python list in detections.data is sliced per row without custom_data
|
||||
],
|
||||
)
|
||||
def test_json_sink(
|
||||
detections: sv.Detections,
|
||||
custom_data: dict[str, Any],
|
||||
custom_data: dict[str, Any] | None,
|
||||
second_detections: sv.Detections,
|
||||
second_custom_data: dict[str, Any],
|
||||
second_custom_data: dict[str, Any] | None,
|
||||
file_name: str,
|
||||
expected_result: list[list[Any]],
|
||||
) -> None:
|
||||
with sv.JSONSink(file_name) as sink:
|
||||
sink.append(detections, custom_data)
|
||||
sink.append(second_detections, second_custom_data)
|
||||
if custom_data is None:
|
||||
sink.append(detections)
|
||||
else:
|
||||
sink.append(detections, custom_data)
|
||||
if second_custom_data is None:
|
||||
sink.append(second_detections)
|
||||
else:
|
||||
sink.append(second_detections, second_custom_data)
|
||||
|
||||
assert_json_equal(file_name, expected_result)
|
||||
|
||||
|
||||
@@ -7,8 +7,13 @@ import numpy.typing as npt
|
||||
import pytest
|
||||
|
||||
from supervision.detection.utils.converters import (
|
||||
_decode_coco_rle_string,
|
||||
_encode_coco_rle_string,
|
||||
_base48_decode,
|
||||
_base48_encode,
|
||||
_delta_decode,
|
||||
_delta_encode,
|
||||
_mask_to_rle_counts,
|
||||
_rle_counts_to_mask,
|
||||
is_compressed_rle,
|
||||
mask_to_rle,
|
||||
rle_to_mask,
|
||||
xcycwh_to_xyxy,
|
||||
@@ -310,23 +315,6 @@ def test_xyxy_to_mask(boxes: np.ndarray, resolution_wh, expected: np.ndarray) ->
|
||||
np.testing.assert_array_equal(result, expected)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"counts",
|
||||
[
|
||||
[5, 2, 2, 2, 5],
|
||||
[0, 16],
|
||||
[9],
|
||||
[0, 5, 5, 5, 5, 5],
|
||||
[6, 3, 2, 1, 1, 1, 2, 3, 6],
|
||||
[3, 1, 2, 4, 2, 1, 3],
|
||||
],
|
||||
)
|
||||
def test_coco_rle_encode_decode_round_trip(counts: list[int]) -> None:
|
||||
encoded = _encode_coco_rle_string(counts)
|
||||
decoded = _decode_coco_rle_string(encoded)
|
||||
assert decoded == counts
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("mask", "compressed", "expected_rle", "exception"),
|
||||
[
|
||||
@@ -533,3 +521,281 @@ def test_mask_rle_compressed_round_trip() -> None:
|
||||
compressed = mask_to_rle(mask, compressed=True)
|
||||
recovered = rle_to_mask(compressed, (4, 4))
|
||||
np.testing.assert_array_equal(mask, recovered)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# is_compressed_rle
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("rle", "expected"),
|
||||
[
|
||||
("52203", True), # str is compressed
|
||||
(b"52203", True), # bytes is compressed
|
||||
("", True), # empty str still str
|
||||
(b"", True), # empty bytes still bytes
|
||||
([5, 2, 2, 2, 5], False), # list is not compressed
|
||||
(np.array([5, 2, 2, 2, 5]), False), # ndarray is not compressed
|
||||
(42, False), # int is not compressed
|
||||
(None, False), # None is not compressed
|
||||
],
|
||||
)
|
||||
def test_is_compressed_rle(rle: object, expected: bool) -> None:
|
||||
"""is_compressed_rle returns True for str/bytes, False otherwise."""
|
||||
assert is_compressed_rle(rle) == expected
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# _base48_decode / _base48_encode
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("s", "expected"),
|
||||
[
|
||||
("", []), # empty string
|
||||
("0", [0]), # single zero
|
||||
("5", [5]), # single small value
|
||||
("52203", [5, 2, 2, 0, 3]), # raw delta values (NOT absolute counts)
|
||||
("09", [0, 9]), # two values, no continuation needed
|
||||
],
|
||||
)
|
||||
def test_base48_decode(s: str, expected: list[int]) -> None:
|
||||
"""_base48_decode returns raw delta-encoded integers from base-48 string."""
|
||||
assert _base48_decode(s) == expected
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"s",
|
||||
[
|
||||
"!", # ord('!')-48 triggers continuation, string ends immediately
|
||||
"52P", # 'P' sets continuation bit but string ends
|
||||
],
|
||||
)
|
||||
def test_base48_decode_malformed(s: str) -> None:
|
||||
"""_base48_decode raises ValueError on truncated continuation sequences."""
|
||||
with pytest.raises(ValueError, match="Malformed compressed RLE string"):
|
||||
_base48_decode(s)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("values", "expected"),
|
||||
[
|
||||
([], ""), # empty list
|
||||
([0], "0"), # single zero
|
||||
([5], "5"), # single small value
|
||||
([5, 2, 2, 0, 3], "52203"), # raw deltas encode to known string
|
||||
([0, 9], "09"), # two values
|
||||
],
|
||||
)
|
||||
def test_base48_encode(values: list[int], expected: str) -> None:
|
||||
"""_base48_encode converts raw delta integers to base-48 string."""
|
||||
assert _base48_encode(values) == expected
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"values",
|
||||
[
|
||||
[],
|
||||
[5, 2, 2, 0, 3],
|
||||
[0, 9],
|
||||
[6, 3, 2, 1, 1, 1, 2, 3, 6],
|
||||
[100], # value >= 32 requires multi-byte continuation characters
|
||||
[1000], # value requiring 3 continuation bytes
|
||||
[-3], # negative delta: sign bit at bit 4 of final character
|
||||
[-1, 0, -100], # multiple negative values
|
||||
],
|
||||
)
|
||||
def test_base48_round_trip(values: list[int]) -> None:
|
||||
"""_base48_decode(_base48_encode(v)) == v for any valid delta list."""
|
||||
assert _base48_decode(_base48_encode(values)) == values
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# _delta_decode / _delta_encode
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("values", "expected"),
|
||||
[
|
||||
([], []), # empty
|
||||
([5], [5]), # single element unchanged
|
||||
([5, 2], [5, 2]), # two elements unchanged
|
||||
([5, 2, 2], [5, 2, 2]), # three elements unchanged
|
||||
([5, 2, 2, 0, 3], [5, 2, 2, 2, 5]), # delta applied from index 3
|
||||
([0, 9], [0, 9]), # two elements, no delta needed
|
||||
([0, 16], [0, 16]), # two elements, larger values
|
||||
],
|
||||
)
|
||||
def test_delta_decode(values: list[int], expected: list[int]) -> None:
|
||||
"""_delta_decode undoes COCO delta: counts[i] += counts[i-2] for i > 2."""
|
||||
assert _delta_decode(values) == expected
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("counts", "expected"),
|
||||
[
|
||||
([], []), # empty
|
||||
([5], [5]), # single element unchanged
|
||||
([5, 2], [5, 2]), # two elements unchanged
|
||||
([5, 2, 2], [5, 2, 2]), # three elements unchanged
|
||||
([5, 2, 2, 2, 5], [5, 2, 2, 0, 3]), # delta applied from index 3
|
||||
([0, 9], [0, 9]), # two elements, no delta needed
|
||||
],
|
||||
)
|
||||
def test_delta_encode(counts: list[int], expected: list[int]) -> None:
|
||||
"""_delta_encode applies COCO delta: d[i] = counts[i] - counts[i-2] for i > 2."""
|
||||
assert _delta_encode(counts) == expected
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"counts",
|
||||
[
|
||||
[5, 2, 2, 2, 5],
|
||||
[0, 9],
|
||||
[6, 3, 2, 1, 1, 1, 2, 3, 6],
|
||||
[0, 5, 5, 5, 5, 5],
|
||||
],
|
||||
)
|
||||
def test_delta_round_trip(counts: list[int]) -> None:
|
||||
"""_delta_decode(_delta_encode(counts)) == counts for any count list."""
|
||||
assert _delta_decode(_delta_encode(counts)) == counts
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# _mask_to_rle_counts / _rle_counts_to_mask
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("mask_2d", "expected_counts"),
|
||||
[
|
||||
(
|
||||
np.zeros((3, 3), dtype=bool),
|
||||
[9],
|
||||
), # all-False: one run of 9 background pixels
|
||||
(
|
||||
np.ones((3, 3), dtype=bool),
|
||||
[0, 9],
|
||||
), # all-True: 0 background then 9 foreground
|
||||
(
|
||||
np.array([[False, True], [True, False]]),
|
||||
[1, 2, 1],
|
||||
), # F-order [F,T,T,F] → starts with False, no leading-zero prepend
|
||||
(
|
||||
np.array([[True, False], [False, True]]),
|
||||
[0, 1, 2, 1],
|
||||
), # F-order [T,F,F,T] → starts with True, prepend 0
|
||||
(
|
||||
np.array(
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
),
|
||||
[5, 2, 2, 2, 5],
|
||||
), # 2x2 centre block in 4x4 grid
|
||||
(
|
||||
np.zeros((0, 4), dtype=bool),
|
||||
[0],
|
||||
), # empty mask → sentinel [0]
|
||||
],
|
||||
)
|
||||
def test_mask_to_rle_counts(
|
||||
mask_2d: npt.NDArray[np.bool_], expected_counts: list[int]
|
||||
) -> None:
|
||||
"""_mask_to_rle_counts produces correct COCO F-order run lengths."""
|
||||
assert _mask_to_rle_counts(mask_2d).tolist() == expected_counts
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("rle", "height", "width", "expected_mask"),
|
||||
[
|
||||
(
|
||||
np.array([9], dtype=np.int32),
|
||||
3,
|
||||
3,
|
||||
np.zeros((3, 3), dtype=bool),
|
||||
), # all-False
|
||||
(
|
||||
np.array([0, 9], dtype=np.int32),
|
||||
3,
|
||||
3,
|
||||
np.ones((3, 3), dtype=bool),
|
||||
), # all-True
|
||||
(
|
||||
np.array([1, 2, 1], dtype=np.int32),
|
||||
2,
|
||||
2,
|
||||
np.array([[False, True], [True, False]]),
|
||||
), # F-order [F,T,T,F]
|
||||
(
|
||||
np.array([0, 1, 2, 1], dtype=np.int32),
|
||||
2,
|
||||
2,
|
||||
np.array([[True, False], [False, True]]),
|
||||
), # F-order [T,F,F,T]
|
||||
(
|
||||
np.array([5, 2, 2, 2, 5], dtype=np.int32),
|
||||
4,
|
||||
4,
|
||||
np.array(
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
),
|
||||
), # 2x2 centre block in 4x4 grid
|
||||
(
|
||||
np.array([3], dtype=np.int32),
|
||||
2,
|
||||
3,
|
||||
np.zeros((2, 3), dtype=bool),
|
||||
), # RLE encodes only 3 of 6 pixels; remainder padded False
|
||||
(
|
||||
np.array([0, 10], dtype=np.int32),
|
||||
2,
|
||||
3,
|
||||
np.ones((2, 3), dtype=bool),
|
||||
), # RLE sum (10) > h*w (6); excess truncated via flat[:num_pixels]
|
||||
],
|
||||
)
|
||||
def test_rle_counts_to_mask(
|
||||
rle: npt.NDArray[np.int32],
|
||||
height: int,
|
||||
width: int,
|
||||
expected_mask: npt.NDArray[np.bool_],
|
||||
) -> None:
|
||||
"""_rle_counts_to_mask reconstructs the correct boolean mask from run lengths."""
|
||||
result = _rle_counts_to_mask(rle, height, width)
|
||||
np.testing.assert_array_equal(result, expected_mask)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"mask_2d",
|
||||
[
|
||||
np.zeros((3, 3), dtype=bool),
|
||||
np.ones((4, 4), dtype=bool),
|
||||
np.array([[False, True], [True, False]]),
|
||||
np.array(
|
||||
[
|
||||
[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False],
|
||||
]
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_mask_rle_counts_round_trip(mask_2d: npt.NDArray[np.bool_]) -> None:
|
||||
"""_rle_counts_to_mask(_mask_to_rle_counts(m)) == m for non-empty masks."""
|
||||
h, w = mask_2d.shape
|
||||
rle = _mask_to_rle_counts(mask_2d)
|
||||
recovered = _rle_counts_to_mask(rle, h, w)
|
||||
np.testing.assert_array_equal(recovered, mask_2d)
|
||||
|
||||
@@ -2563,7 +2563,7 @@ wheels = [
|
||||
|
||||
[[package]]
|
||||
name = "nbconvert"
|
||||
version = "7.17.0"
|
||||
version = "7.17.1"
|
||||
source = { registry = "https://pypi.org/simple" }
|
||||
dependencies = [
|
||||
{ name = "beautifulsoup4" },
|
||||
@@ -2582,9 +2582,9 @@ dependencies = [
|
||||
{ name = "pygments" },
|
||||
{ name = "traitlets" },
|
||||
]
|
||||
sdist = { url = "https://files.pythonhosted.org/packages/38/47/81f886b699450d0569f7bc551df2b1673d18df7ff25cc0c21ca36ed8a5ff/nbconvert-7.17.0.tar.gz", hash = "sha256:1b2696f1b5be12309f6c7d707c24af604b87dfaf6d950794c7b07acab96dda78", size = 862855, upload-time = "2026-01-29T16:37:48.478Z" }
|
||||
sdist = { url = "https://files.pythonhosted.org/packages/01/b1/708e53fe2e429c103c6e6e159106bcf0357ac41aa4c28772bd8402339051/nbconvert-7.17.1.tar.gz", hash = "sha256:34d0d0a7e73ce3cbab6c5aae8f4f468797280b01fd8bd2ca746da8569eddd7d2", size = 865311, upload-time = "2026-04-08T00:44:14.914Z" }
|
||||
wheels = [
|
||||
{ url = "https://files.pythonhosted.org/packages/0d/4b/8d5f796a792f8a25f6925a96032f098789f448571eb92011df1ae59e8ea8/nbconvert-7.17.0-py3-none-any.whl", hash = "sha256:4f99a63b337b9a23504347afdab24a11faa7d86b405e5c8f9881cd313336d518", size = 261510, upload-time = "2026-01-29T16:37:46.322Z" },
|
||||
{ url = "https://files.pythonhosted.org/packages/67/f8/bb0a9d5f46819c821dc1f004aa2cc29b1d91453297dbf5ff20470f00f193/nbconvert-7.17.1-py3-none-any.whl", hash = "sha256:aa85c087b435e7bf1ffd03319f658e285f2b89eccab33bc1ba7025495ab3e7c8", size = 261927, upload-time = "2026-04-08T00:44:12.845Z" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
@@ -4055,7 +4055,7 @@ wheels = [
|
||||
|
||||
[[package]]
|
||||
name = "supervision"
|
||||
version = "0.28.0rc0"
|
||||
version = "0.28.0rc2"
|
||||
source = { editable = "." }
|
||||
dependencies = [
|
||||
{ name = "defusedxml" },
|
||||
|
||||
Reference in New Issue
Block a user