Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Piotr Skalski |
d8de58d7f3 | ||
|
SkalskiP
|
a1e402987b | ||
|
Piotr Skalski
|
78e5cd56f3 | ||
|
Onuralp SEZER
|
462146b34e | ||
|
Onuralp SEZER
|
12e38da1a0 | ||
|
Piotr Skalski
|
56a0ac5cbf | ||
|
pre-commit-ci[bot]
|
d1aa1726f5 | ||
|
SkalskiP
|
0f56a405c6 | ||
|
SkalskiP
|
4948612cd4 | ||
|
pre-commit-ci[bot]
|
6046e88eb1 | ||
|
soumik12345
|
77c45355ff | ||
|
soumik12345
|
3ff1414fc2 | ||
|
SkalskiP
|
4e832b2cf4 | ||
|
Piotr Skalski
|
5c1a5eab3a | ||
|
Onuralp SEZER
|
5d6f5bfde3 | ||
|
SkalskiP
|
2b47d8e4cc | ||
|
SkalskiP
|
bbadfb3cbd | ||
|
SkalskiP
|
880a9e8eb5 | ||
|
pre-commit-ci[bot]
|
5397031cee | ||
|
SkalskiP
|
c4ede20a2d | ||
|
SkalskiP
|
a135bd6268 | ||
|
SkalskiP
|
0a3333474a | ||
|
SkalskiP
|
d854e23e9a | ||
|
pre-commit-ci[bot]
|
1bc672afd3 | ||
|
soumik12345
|
14d3b79387 | ||
|
pre-commit-ci[bot]
|
facc64bb3a | ||
|
SkalskiP
|
f9cdb93b87 | ||
|
SkalskiP
|
2dca99d0dc | ||
|
Onuralp SEZER
|
334d8e6506 | ||
|
Onuralp SEZER
|
8710bde5b2 | ||
|
pre-commit-ci[bot]
|
3ba5c12211 | ||
|
Onuralp SEZER
|
b8d646ac98 | ||
|
SkalskiP
|
ab9d128828 | ||
|
SkalskiP
|
873f249bf0 | ||
|
SkalskiP
|
5b42be9b4a | ||
|
pre-commit-ci[bot]
|
b507ed90dd | ||
|
SkalskiP
|
a25039ff54 | ||
|
SkalskiP
|
6b905f2d18 | ||
|
Onuralp SEZER
|
d52fcf17a8 | ||
|
pre-commit-ci[bot]
|
592a649b50 | ||
|
SkalskiP
|
fa5fcbb264 | ||
|
Piotr Skalski
|
9dc2785762 | ||
|
Onuralp SEZER
|
212e69b5a4 | ||
|
Onuralp SEZER
|
7fde67ef75 | ||
|
Piotr Skalski
|
8a7e2fedbc | ||
|
Onuralp SEZER
|
3b2ca1b542 | ||
|
Onuralp SEZER
|
8a000b93b0 | ||
|
Onuralp SEZER
|
b6cd9dd3f3 | ||
|
pre-commit-ci[bot]
|
a5155e23f2 | ||
|
Onuralp SEZER
|
3dd1ce4e1c | ||
|
Piotr Skalski
|
71e7c3e17c | ||
|
pre-commit-ci[bot]
|
cf179b9dfe | ||
|
Soumik Rakshit
|
9f3ffdd26d | ||
|
soumik12345
|
7c1168fbc6 | ||
|
soumik12345
|
af31b96199 | ||
|
pre-commit-ci[bot]
|
9400270e34 | ||
|
soumik12345
|
bcbbc57854 | ||
|
Onuralp SEZER
|
b792db72fd | ||
|
soumik12345
|
84c9a34f92 | ||
|
soumik12345
|
c11a7de949 | ||
|
pre-commit-ci[bot]
|
f68a6bc362 | ||
|
soumik12345
|
7ea8c2e43c | ||
|
Onuralp SEZER
|
2adb64b949 | ||
|
pre-commit-ci[bot]
|
9a38ebd15e | ||
|
soumik12345
|
4977fd64b1 | ||
|
pre-commit-ci[bot]
|
ae77077853 | ||
|
soumik12345
|
007d8f5dad | ||
|
soumik12345
|
b3024e780d | ||
|
soumik12345
|
ebf4b930b7 | ||
|
soumik12345
|
fd25f4bf81 | ||
|
soumik12345
|
3fed5f9a25 | ||
|
soumik12345
|
7849831e12 | ||
|
pre-commit-ci[bot]
|
42e9c5ffcb | ||
|
soumik12345
|
fb16bd9ee1 | ||
|
soumik12345
|
2c986abf5e | ||
|
Onuralp SEZER
|
667e6491ac | ||
|
Onuralp SEZER
|
1d3e887fca | ||
|
Onuralp SEZER
|
63cc934cd4 | ||
|
Onuralp SEZER
|
edfe0a944a | ||
|
Onuralp SEZER
|
25edd9be21 | ||
|
Piotr Skalski
|
daaadaa1f9 | ||
|
Onuralp SEZER
|
9443a433fc | ||
|
soumik12345
|
b2776cadf7 | ||
|
soumik12345
|
1337b7ffd5 | ||
|
Onuralp SEZER
|
efe59cb91c | ||
|
Onuralp SEZER
|
13fa672d9e | ||
|
Onuralp SEZER
|
85ec990aa4 | ||
|
pre-commit-ci[bot]
|
6929f1b798 | ||
|
SkalskiP
|
63519dd89c | ||
|
SkalskiP
|
2b052430bd | ||
|
Onuralp SEZER
|
7b8560016e | ||
|
pre-commit-ci[bot]
|
886bc16fd4 | ||
|
pre-commit-ci[bot]
|
4ea79f3634 | ||
|
Onuralp SEZER
|
5d883447a3 | ||
|
Onuralp SEZER
|
00fab37e58 | ||
|
Onuralp SEZER
|
328c34ab8b | ||
|
Onuralp SEZER
|
d29fb8ad05 | ||
|
Onuralp SEZER
|
c2abb24c26 | ||
|
Onuralp SEZER
|
8c4a1e5a5e | ||
|
pre-commit-ci[bot]
|
ff3c85d380 | ||
|
Onuralp SEZER
|
2c63511af6 | ||
|
soumik12345
|
9517987b7b | ||
|
Onuralp SEZER
|
129eb89c20 | ||
|
Onuralp SEZER
|
e8ca201198 | ||
|
Onuralp SEZER
|
b87a504d22 | ||
|
Onuralp SEZER
|
076f9e293f | ||
|
Onuralp SEZER
|
6c4a2a8d44 | ||
|
SkalskiP
|
1a83005a44 | ||
|
pre-commit-ci[bot]
|
74d5f0f9a6 | ||
|
Soumik Rakshit
|
50c0d54dd5 | ||
|
Onuralp SEZER
|
377f7db0ad | ||
|
Onuralp SEZER
|
3b112ffb46 | ||
|
Piotr Skalski
|
a192eed093 | ||
|
soumik12345
|
18cd73f55a | ||
|
Onuralp SEZER
|
4ed667da88 | ||
|
Onuralp SEZER
|
5d866fd8a1 | ||
|
Onuralp SEZER
|
ddf9a060ba | ||
|
pre-commit-ci[bot]
|
8e437f89fa | ||
|
soumik12345
|
9ce4632f47 | ||
|
Piotr Skalski
|
baa78fc4da | ||
|
Onuralp SEZER
|
2bf448f285 | ||
|
Piotr Skalski
|
462468f3d8 | ||
|
Onuralp SEZER
|
6bae8bc6e6 | ||
|
Onuralp SEZER
|
3152f5f0ea | ||
|
Onuralp SEZER
|
c7ebfeb4bc | ||
|
Ashp116
|
d1c27f2d2b | ||
|
Ashp116
|
92599ad497 | ||
|
Ashp116
|
a118599233 | ||
|
pre-commit-ci[bot]
|
2f44aab2b5 | ||
|
Ashp116
|
0488abf083 | ||
|
Ashp116
|
d2ffd04aed | ||
|
pre-commit-ci[bot]
|
ee7782b551 | ||
|
Ashp116
|
2378d8bdca | ||
|
Onuralp SEZER
|
3218da8cbd | ||
|
Onuralp SEZER
|
eb330ac1c1 | ||
|
Onuralp SEZER
|
641b343c7f | ||
|
Onuralp SEZER
|
0601a4157d | ||
|
SkalskiP
|
62e80b82ac | ||
|
Piotr Skalski
|
a352521c15 | ||
|
Piotr Skalski
|
8697fc0233 | ||
|
soumik12345
|
fe0cefd1dc | ||
|
soumik12345
|
4d364885e9 | ||
|
soumik12345
|
857aad66fc | ||
|
soumik12345
|
b860edd8f5 | ||
|
soumik12345
|
ca86f6e64d | ||
|
Onuralp SEZER
|
d002b8afbf | ||
|
Onuralp SEZER
|
c613005f69 | ||
|
Onuralp SEZER
|
99415f1da1 | ||
|
Onuralp SEZER
|
656b9c6c89 | ||
|
Onuralp SEZER
|
d34f050642 | ||
|
Onuralp SEZER
|
89f4242e6f | ||
|
Onuralp SEZER
|
f7d4da9b1d | ||
|
Onuralp SEZER
|
1034313ac2 | ||
|
pre-commit-ci[bot]
|
a6d9550a9a | ||
|
Onuralp SEZERandSoumik Rakshit
|
fd1bb5b4b2 | ||
|
Piotr Skalski
|
8c581e4855 | ||
|
Onuralp SEZER
|
bf2a67b85b | ||
|
hidara2000
|
d3a2012750 | ||
|
hidara2000
|
0b00edc526 | ||
|
Onuralp SEZER
|
fa98266914 | ||
|
hidara2000
|
d7e0dedf74 | ||
|
Onuralp SEZER
|
f90a94be2e | ||
|
Onuralp SEZER
|
5206b6cbbb | ||
|
Onuralp SEZER
|
58aacc788d | ||
|
Onuralp SEZER
|
0343db7d95 | ||
|
Onuralp SEZER
|
7076b4da0c | ||
|
Onuralp SEZER
|
e17e7d712f | ||
|
Onuralp SEZER
|
399d2efa59 | ||
|
Onuralp SEZER
|
300426ed41 | ||
|
Piotr Skalski
|
20066174e5 | ||
|
James
|
413db5a1e5 | ||
|
Onuralp SEZER
|
9855927597 | ||
|
Onuralp SEZER
|
72bff07498 | ||
|
Onuralp SEZER
|
409ff28200 | ||
|
Onuralp SEZER
|
5d2616093d | ||
|
Onuralp SEZER
|
74ba99479c | ||
|
Onuralp SEZER
|
0e8ec18c20 | ||
|
Onuralp SEZER
|
7ca52da776 | ||
|
Piotr Skalski
|
2dfadfe1b1 | ||
|
SkalskiP
|
8b39478913 | ||
|
Soumik Rakshit
|
2c0eaa1059 | ||
|
pre-commit-ci[bot]
|
4804d51de4 | ||
|
soumik12345
|
097af2a38a | ||
|
pre-commit-ci[bot]
|
9cc6d2d325 | ||
|
soumik12345
|
b4f30b5ad6 | ||
|
soumik12345
|
abb881c1a6 | ||
|
soumik12345
|
6448fc7ea1 | ||
|
Piotr Skalski
|
98ba121b5c | ||
|
SkalskiP
|
f50216eebf | ||
|
James
|
21a3584513 | ||
|
pre-commit-ci[bot]
|
091559433a | ||
|
James
|
b15a7ea005 | ||
|
Piotr Skalski
|
451b4b25d1 | ||
|
SkalskiP
|
4879ed38c8 | ||
|
Onuralp SEZER
|
096b9a5b99 | ||
|
pre-commit-ci[bot]
|
5467fbf7c2 | ||
|
Ashp116
|
6e87237070 | ||
|
James
|
796cc26fb9 | ||
|
Onuralp SEZER
|
174253715e | ||
|
James
|
8373a38b35 | ||
|
Onuralp SEZER
|
e608d8204f | ||
|
Onuralp SEZER
|
ddfbaa3127 | ||
|
Soumik Rakshit
|
b5bf082a95 | ||
|
pre-commit-ci[bot]
|
d48614d72b | ||
|
soumik12345
|
b736499fc9 | ||
|
pre-commit-ci[bot]
|
031a0296f9 | ||
|
Onuralp SEZER
|
84d7fb29e0 | ||
|
Onuralp SEZER
|
0af46f6416 | ||
|
Onuralp SEZER
|
a64874f27d | ||
|
pre-commit-ci[bot]
|
e99fc921df | ||
|
James
|
0a7bf58905 | ||
|
Piotr Skalski
|
334d0619e6 | ||
|
Soumik Rakshit
|
1190ed2931 | ||
|
Soumik Rakshit
|
ccf84d5653 | ||
|
Soumik Rakshit
|
8a905ce79a | ||
|
pre-commit-ci[bot]
|
724d851dcd | ||
|
Piotr Skalski
|
95d7204ae8 | ||
|
pre-commit-ci[bot]
|
5aa6b6f959 | ||
|
SkalskiP
|
fcb47f7226 | ||
|
Hao Sun
|
f47f032b23 | ||
|
pre-commit-ci[bot]
|
0b120f1748 | ||
|
AI-Hao
|
13e857cf00 | ||
|
rafaelpadilla
|
b867968a10 | ||
|
rafaelpadilla
|
a95a818441 | ||
|
rafaelpadilla
|
03430699f9 | ||
|
rafaelpadilla
|
c7b4993721 | ||
|
Rafael PadillaandPiotr Skalski
|
d543be924f | ||
|
soumik12345
|
2ef9d69e01 | ||
|
soumik12345
|
3786017424 | ||
|
Onuralp SEZER
|
a6f738d2d1 | ||
|
JESUSROYETH
|
1facc6b28b | ||
|
pre-commit-ci[bot]
|
4414e15a00 | ||
|
rafaelpadilla
|
49a8fd96d6 | ||
|
rafaelpadilla
|
0a55b3b3a2 | ||
|
rafaelpadilla
|
5f9c55d9f3 | ||
|
Onuralp SEZER
|
93c1b5f520 | ||
|
pre-commit-ci[bot]
|
097614f2be | ||
|
AI-Hao
|
eb170bc393 | ||
|
AI-Hao
|
d002858169 | ||
|
pre-commit-ci[bot]
|
646ac83bef | ||
|
Hao Sun
|
9a9324af9a | ||
|
pre-commit-ci[bot]
|
c2d0ed2365 | ||
|
James
|
89ca7226b9 | ||
|
James
|
5313f479a4 | ||
|
James
|
568a94c0e1 | ||
|
James
|
463a54fb58 | ||
|
James
|
d5f06eaf6f | ||
|
James
|
4255e63269 | ||
|
Onuralp SEZER
|
57975735b3 | ||
|
pre-commit-ci[bot]
|
84d190a40c | ||
|
rafaelpadilla
|
fd3135145a | ||
|
rafaelpadilla
|
cff974555e | ||
|
Onuralp SEZER
|
14b6d104df | ||
|
pre-commit-ci[bot]
|
d21ebc77cc | ||
|
Onuralp SEZER
|
95f2b54cc8 | ||
|
pre-commit-ci[bot]
|
9f67fb9f5e | ||
|
Onuralp SEZER
|
3f99fde52d | ||
|
pre-commit-ci[bot]
|
bfe11b3f8e | ||
|
pre-commit-ci[bot]
|
52980a6aa7 | ||
|
rafaelpadilla
|
8f72e49080 | ||
|
rafaelpadilla
|
19c4e44e2c | ||
|
rafaelpadilla
|
790baa615f | ||
|
rafaelpadilla
|
bba43ecdf4 | ||
|
rafaelpadilla
|
688d987765 | ||
|
Onuralp SEZER
|
8b92485b6a | ||
|
pre-commit-ci[bot]
|
2a3c9c9164 | ||
|
Onuralp SEZER
|
5e3573cf84 | ||
|
dependabot[bot]
|
4031a7f3df | ||
|
rafaelpadilla
|
15cd445108 | ||
|
Onuralp SEZER
|
ed3186c506 | ||
|
rafaelpadilla
|
157ed3af06 | ||
|
rafaelpadilla
|
36a21717eb | ||
|
rafaelpadilla
|
232916a8eb | ||
|
rafaelpadilla
|
317cbd3fc4 | ||
|
pre-commit-ci[bot]
|
1bfc67bed7 | ||
|
Onuralp SEZER
|
1c795e4a9f | ||
|
dependabot[bot]
|
087dc939b2 | ||
|
hidara2000
|
0c2aae6bd2 | ||
|
pre-commit-ci[bot]
|
a6aa9b7d3b | ||
|
hidara2000
|
29695055d2 | ||
|
Piotr Skalski
|
1876019faf | ||
|
pre-commit-ci[bot]
|
95a2ecc49b | ||
|
hidara2000
|
5c35af99d0 | ||
|
pre-commit-ci[bot]
|
c68218a07e | ||
|
hidara2000
|
0539ec9d1f | ||
|
hidara2000
|
c4dce2752d | ||
|
hidara2000andOnuralp SEZER
|
474c8bc478 | ||
|
hidara2000andOnuralp SEZER
|
a5c833b80f | ||
|
hidara2000andOnuralp SEZER
|
a1e43f8e93 | ||
|
pre-commit-ci[bot]
|
ca5596ceb2 | ||
|
hidara2000
|
f2e900171e | ||
|
Onuralp SEZER
|
1f692a043f | ||
|
Onuralp SEZER
|
7f1e0ea36b | ||
|
Onuralp SEZER
|
0c4a156662 | ||
|
Onuralp SEZER
|
766467ab78 | ||
|
Onuralp SEZER
|
0cec129cf0 | ||
|
Onuralp SEZER
|
65b48f6b4a | ||
|
SunHao-AI
|
39766f4c0a | ||
|
pre-commit-ci[bot]
|
4679334d86 | ||
|
AI-Hao
|
8d29796810 | ||
|
AI-Hao
|
9cd6549cdc | ||
|
AI-Hao
|
e4b5a8e0f9 |
@@ -34,13 +34,15 @@ jobs:
|
||||
fetch-depth: 0
|
||||
|
||||
- name: 🐍 Install uv and set Python ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@d4b2f3b6ecc6e67c4457f6d3e41ec42d3d0fcb86 # v5.4.2
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
|
||||
- name: 🔑 Create GitHub App token (mkdocs)
|
||||
id: mkdocs_token
|
||||
uses: actions/create-github-app-token@3ff1caaa28b64c9cc276ce0a02e2ff584f3900c5 # v2.0.2
|
||||
uses: actions/create-github-app-token@df432ceedc7162793a195dd1713ff69aefc7379e # v2.0.6
|
||||
with:
|
||||
app-id: ${{ secrets.MKDOCS_APP_ID }}
|
||||
private-key: ${{ secrets.MKDOCS_PEM }}
|
||||
@@ -49,7 +51,7 @@ jobs:
|
||||
|
||||
- name: 🏗️ Install dependencies
|
||||
run: |
|
||||
uv pip install -r pyproject.toml --extra docs
|
||||
uv pip install -r pyproject.toml --group docs
|
||||
# Install mkdocs-material-insiders using the GitHub App token
|
||||
uv pip install "git+https://roboflow:${{ steps.mkdocs_token.outputs.token }}@github.com/roboflow/mkdocs-material-insiders.git@9.5.49-insiders-4.53.14#egg=mkdocs-material[imaging]"
|
||||
|
||||
|
||||
@@ -29,13 +29,15 @@ jobs:
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@d4b2f3b6ecc6e67c4457f6d3e41ec42d3d0fcb86 # v5.4.2
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
|
||||
- name: 🏗️ Build source and wheel distributions
|
||||
run: |
|
||||
uv pip install -r pyproject.toml --extra build
|
||||
uv pip install -r pyproject.toml --group build
|
||||
uv build
|
||||
uv run twine check --strict dist/*
|
||||
|
||||
|
||||
@@ -27,13 +27,15 @@ jobs:
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@d4b2f3b6ecc6e67c4457f6d3e41ec42d3d0fcb86 # v5.4.2
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
|
||||
- name: 🏗️ Build source and wheel distributions
|
||||
run: |
|
||||
uv pip install -r pyproject.toml --extra build
|
||||
uv pip install -r pyproject.toml --group build
|
||||
uv build
|
||||
uv run twine check --strict dist/*
|
||||
|
||||
|
||||
@@ -24,13 +24,15 @@ jobs:
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@d4b2f3b6ecc6e67c4457f6d3e41ec42d3d0fcb86 # v5.4.2
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
|
||||
- name: 🏗️ Build source and wheel distributions
|
||||
run: |
|
||||
uv pip install -r pyproject.toml --extra build
|
||||
uv pip install -r pyproject.toml --group build
|
||||
uv build
|
||||
uv run twine check --strict dist/*
|
||||
|
||||
|
||||
@@ -24,14 +24,14 @@ jobs:
|
||||
fetch-depth: 0
|
||||
|
||||
- name: 🐍 Install uv and set Python ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@d4b2f3b6ecc6e67c4457f6d3e41ec42d3d0fcb86 # v5.4.2
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
- name: 🏗️ Install dependencies
|
||||
run: |
|
||||
uv pip install -r pyproject.toml --extra docs
|
||||
|
||||
uv pip install -r pyproject.toml --group docs
|
||||
|
||||
- name: 🧪 Test Docs Build
|
||||
run: uv run mkdocs build --verbose
|
||||
|
||||
@@ -12,19 +12,21 @@ jobs:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
os: [ubuntu-latest, windows-latest, macos-latest]
|
||||
python-version: ["3.8", "3.9", "3.10", "3.11", "3.12", "3.13"]
|
||||
python-version: ["3.9", "3.10", "3.11", "3.12", "3.13"]
|
||||
runs-on: ${{ matrix.os }}
|
||||
steps:
|
||||
- name: 📥 Checkout the repository
|
||||
uses: actions/checkout@11bd71901bbe5b1630ceea73d27597364c9af683 # v4.2.2
|
||||
|
||||
- name: 🐍 Install uv and set Python version ${{ matrix.python-version }}
|
||||
uses: astral-sh/setup-uv@d4b2f3b6ecc6e67c4457f6d3e41ec42d3d0fcb86 # v5.4.2
|
||||
uses: astral-sh/setup-uv@bd01e18f51369d5a26f1651c3cb451d3417e3bba # v6.3.1
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
activate-environment: true
|
||||
|
||||
|
||||
- name: 🚀 Install Packages
|
||||
run: uv pip install -r pyproject.toml --extra dev --extra docs --extra metrics
|
||||
run: uv pip install -r pyproject.toml --group dev --group docs --extra metrics
|
||||
|
||||
- name: 🧪 Run the Import test
|
||||
run: uv run python -c "import supervision; from supervision import assets; from supervision import metrics; print(supervision.__version__)"
|
||||
|
||||
+10
-2
@@ -25,14 +25,14 @@ repos:
|
||||
- id: mixed-line-ending
|
||||
|
||||
- repo: https://github.com/PyCQA/bandit
|
||||
rev: '1.8.3'
|
||||
rev: '1.8.6'
|
||||
hooks:
|
||||
- id: bandit
|
||||
args: ["-c", "pyproject.toml"]
|
||||
additional_dependencies: ["bandit[toml]"]
|
||||
|
||||
- repo: https://github.com/astral-sh/ruff-pre-commit
|
||||
rev: v0.11.6
|
||||
rev: v0.12.3
|
||||
hooks:
|
||||
- id: ruff
|
||||
args: [--fix, --exit-non-zero-on-fix]
|
||||
@@ -53,3 +53,11 @@ repos:
|
||||
- id: codespell
|
||||
additional_dependencies:
|
||||
- tomli
|
||||
|
||||
- repo: https://github.com/asottile/pyupgrade
|
||||
rev: v3.20.0
|
||||
hooks:
|
||||
- id: pyupgrade
|
||||
args: ["--py310-plus"]
|
||||
additional_dependencies:
|
||||
- tomli
|
||||
|
||||
@@ -37,7 +37,7 @@
|
||||
## 💻 install
|
||||
|
||||
Pip install the supervision package in a
|
||||
[**Python>=3.8**](https://www.python.org/) environment.
|
||||
[**Python>=3.9**](https://www.python.org/) environment.
|
||||
|
||||
```bash
|
||||
pip install supervision
|
||||
|
||||
+176
-1
@@ -1,4 +1,179 @@
|
||||
# CHANGELOG
|
||||
# Changelog
|
||||
|
||||
### 0.26.0 <small>Jul 16, 2025</small>
|
||||
|
||||
!!! failure "Removed"
|
||||
`supervision-0.26.0` drops `python3.8` support and upgrade all codes to `python3.9` syntax style.
|
||||
|
||||
!!! info "Tip"
|
||||
Supervision’s documentation theme now has a fresh look that is consistent with the documentations of all Roboflow open-source projects. ([#1858](https://github.com/roboflow/supervision/pull/1858))
|
||||
|
||||
- Added [#1774](https://github.com/roboflow/supervision/pull/1774): Support for the IOS (Intersection over Smallest) overlap metric that measures how much of the smaller object is covered by the larger one in [`sv.Detections.with_nms`](https://supervision.roboflow.com/0.26.0/detection/core/#supervision.detection.core.Detections.with_nms), [`sv.Detections.with_nmm`](https://supervision.roboflow.com/0.26.0/detection/core/#supervision.detection.core.Detections.with_nmm), [`sv.box_iou_batch`](https://supervision.roboflow.com/0.26.0/detection/utils/iou_and_nms/#supervision.detection.utils.iou_and_nms.box_iou_batch), and [`sv.mask_iou_batch`](https://supervision.roboflow.com/0.26.0/detection/utils/iou_and_nms/#supervision.detection.utils.iou_and_nms.mask_iou_batch).
|
||||
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
boxes_true = np.array([
|
||||
[100, 100, 200, 200],
|
||||
[300, 300, 400, 400]
|
||||
])
|
||||
boxes_detection = np.array([
|
||||
[150, 150, 250, 250],
|
||||
[320, 320, 420, 420]
|
||||
])
|
||||
|
||||
sv.box_iou_batch(
|
||||
boxes_true=boxes_true,
|
||||
boxes_detection=boxes_detection,
|
||||
overlap_metric=sv.OverlapMetric.IOU
|
||||
)
|
||||
|
||||
# array([[0.14285714, 0. ],
|
||||
# [0. , 0.47058824]])
|
||||
|
||||
sv.box_iou_batch(
|
||||
boxes_true=boxes_true,
|
||||
boxes_detection=boxes_detection,
|
||||
overlap_metric=sv.OverlapMetric.IOS
|
||||
)
|
||||
|
||||
# array([[0.25, 0. ],
|
||||
# [0. , 0.64]])
|
||||
```
|
||||
|
||||
- Added [#1874](https://github.com/roboflow/supervision/pull/1874): [`sv.box_iou`](https://supervision.roboflow.com/0.26.0/detection/utils/iou_and_nms/#supervision.detection.utils.iou_and_nms.box_iou) that efficiently computes the Intersection over Union (IoU) between two individual bounding boxes.
|
||||
|
||||
- Added [#1816](https://github.com/roboflow/supervision/pull/1816): Support for frame limitations and progress bar in [`sv.process_video`](https://supervision.roboflow.com/0.26.0/utils/video/#supervision.utils.video.process_video).
|
||||
|
||||
- Added [#1788](https://github.com/roboflow/supervision/pull/1788): Support for creating [`sv.KeyPoints`](https://supervision.roboflow.com/0.26.0/keypoint/core/#supervision.keypoint.core.KeyPoints) objects from [ViTPose](https://huggingface.co/docs/transformers/en/model_doc/vitpose) and [ViTPose++](https://huggingface.co/docs/transformers/en/model_doc/vitpose#vitpose-models) inference results via [`sv.KeyPoints.from_transformers`](https://supervision.roboflow.com/0.26.0/keypoint/core/#supervision.keypoint.core.KeyPoints.from_transformers).
|
||||
|
||||
- Added [#1823](https://github.com/roboflow/supervision/pull/1823): [`sv.xyxy_to_xcycarh`](https://supervision.roboflow.com/0.26.0/detection/utils/converters/#supervision.detection.utils.converters.xyxy_to_xcycarh) function to convert bounding box coordinates from `(x_min, y_min, x_max, y_max)` into measurement space to format `(center x, center y, aspect ratio, height)`, where the aspect ratio is `width / height`.
|
||||
|
||||
- Added [#1788](https://github.com/roboflow/supervision/pull/1788): [`sv.xyxy_to_xywh`](https://supervision.roboflow.com/0.26.0/detection/utils/converters/#supervision.detection.utils.converters.xyxy_to_xywh) function to convert bounding box coordinates from `(x_min, y_min, x_max, y_max)` format to `(x, y, width, height)` format.
|
||||
|
||||
- Changed [#1820](https://github.com/roboflow/supervision/pull/1820): [`sv.LabelAnnotator`](https://supervision.roboflow.com/0.26.0/detection/annotators/#supervision.annotators.core.LabelAnnotator) now supports the `smart_position` parameter to automatically keep labels within frame boundaries, and the `max_line_length` parameter to control text wrapping for long or multi-line labels.
|
||||
|
||||
- Changed [#1825](https://github.com/roboflow/supervision/pull/1825): [`sv.LabelAnnotator`](https://supervision.roboflow.com/0.26.0/detection/annotators/#supervision.annotators.core.LabelAnnotator) now supports non-string labels.
|
||||
|
||||
- Changed [#1792](https://github.com/roboflow/supervision/pull/1792): [`sv.Detections.from_vlm`](https://supervision.roboflow.com/0.26.0/detection/core/#supervision.detection.core.Detections.from_vlm) now supports parsing bounding boxes and segmentation masks from responses generated by [Google Gemini models](https://ai.google.dev/gemini-api/docs/vision).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
gemini_response_text = """```json
|
||||
[
|
||||
{"box_2d": [543, 40, 728, 200], "label": "cat", "id": 1},
|
||||
{"box_2d": [653, 352, 820, 522], "label": "dog", "id": 2}
|
||||
]
|
||||
```"""
|
||||
|
||||
detections = sv.Detections.from_vlm(
|
||||
sv.VLM.GOOGLE_GEMINI_2_5,
|
||||
gemini_response_text,
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog'],
|
||||
)
|
||||
|
||||
detections.xyxy
|
||||
# array([[543., 40., 728., 200.], [653., 352., 820., 522.]])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['cat', 'dog'], dtype='<U26')}
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
```
|
||||
|
||||
- Changed [#1878](https://github.com/roboflow/supervision/pull/1878): [`sv.Detections.from_vlm`](https://supervision.roboflow.com/0.26.0/detection/core/#supervision.detection.core.Detections.from_vlm) now supports parsing bounding boxes from responses generated by [Moondream](https://github.com/vikhyat/moondream).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
moondream_result = {
|
||||
'objects': [
|
||||
{
|
||||
'x_min': 0.5704046934843063,
|
||||
'y_min': 0.20069346576929092,
|
||||
'x_max': 0.7049859315156937,
|
||||
'y_max': 0.3012596592307091
|
||||
},
|
||||
{
|
||||
'x_min': 0.6210969910025597,
|
||||
'y_min': 0.3300672620534897,
|
||||
'x_max': 0.8417936339974403,
|
||||
'y_max': 0.4961046129465103
|
||||
}
|
||||
]
|
||||
}
|
||||
|
||||
detections = sv.Detections.from_vlm(
|
||||
sv.VLM.MOONDREAM,
|
||||
moondream_result,
|
||||
resolution_wh=(1000, 1000),
|
||||
)
|
||||
|
||||
detections.xyxy
|
||||
# array([[1752.28, 818.82, 2165.72, 1229.14],
|
||||
# [1908.01, 1346.67, 2585.99, 2024.11]])
|
||||
```
|
||||
|
||||
- Changed [#1709](https://github.com/roboflow/supervision/pull/1790): [`sv.Detections.from_vlm`](https://supervision.roboflow.com/0.26.0/detection/core/#supervision.detection.core.Detections.from_vlm) now supports parsing bounding boxes from responses generated by [Qwen-2.5 VL](https://github.com/QwenLM/Qwen2.5-VL).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
qwen_2_5_vl_result = """```json
|
||||
[
|
||||
{"bbox_2d": [139, 768, 315, 954], "label": "cat"},
|
||||
{"bbox_2d": [366, 679, 536, 849], "label": "dog"}
|
||||
]
|
||||
```"""
|
||||
|
||||
detections = sv.Detections.from_vlm(
|
||||
sv.VLM.QWEN_2_5_VL,
|
||||
qwen_2_5_vl_result,
|
||||
input_wh=(1000, 1000),
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog'],
|
||||
)
|
||||
|
||||
detections.xyxy
|
||||
# array([[139., 768., 315., 954.], [366., 679., 536., 849.]])
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['cat', 'dog'], dtype='<U10')}
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
```
|
||||
|
||||
- Changed [#1786](https://github.com/roboflow/supervision/pull/1786): Significantly improved the speed of HSV color mapping in [`sv.HeatMapAnnotator`](https://supervision.roboflow.com/0.26.0/detection/annotators/#supervision.annotators.core.HeatMapAnnotator), achieving approximately 28x faster performance on 1920x1080 frames.
|
||||
|
||||
- Fix [#1834](https://github.com/roboflow/supervision/pull/1834): Supervision’s [`sv.MeanAveragePrecision`](https://supervision.roboflow.com/0.26.0/metrics/mean_average_precision/#supervision.metrics.mean_average_precision.MeanAveragePrecision) is now fully aligned with [pycocotools](https://github.com/ppwwyyxx/cocoapi), the official COCO evaluation tool, ensuring accurate and standardized metrics. This update enabled us to launch a new version of the [Computer Vision Model Leaderboard](https://leaderboard.roboflow.com/).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from supervision.metrics import MeanAveragePrecision
|
||||
|
||||
predictions = sv.Detections(...)
|
||||
targets = sv.Detections(...)
|
||||
|
||||
map_metric = MeanAveragePrecision()
|
||||
map_metric.update(predictions, targets).compute()
|
||||
|
||||
# Average Precision (AP) @[ IoU=0.50:0.95 | area= all | maxDets=100 ] = 0.464
|
||||
# Average Precision (AP) @[ IoU=0.50 | area= all | maxDets=100 ] = 0.637
|
||||
# Average Precision (AP) @[ IoU=0.75 | area= all | maxDets=100 ] = 0.203
|
||||
# Average Precision (AP) @[ IoU=0.50:0.95 | area= small | maxDets=100 ] = 0.284
|
||||
# Average Precision (AP) @[ IoU=0.50:0.95 | area=medium | maxDets=100 ] = 0.497
|
||||
# Average Precision (AP) @[ IoU=0.50:0.95 | area= large | maxDets=100 ] = 0.629
|
||||
```
|
||||
|
||||
- Fix [#1767](https://github.com/roboflow/supervision/pull/1767): Fixed losing `sv.Detections.data` when detections filtering.
|
||||
|
||||
### 0.25.0 <small>Nov 12, 2024</small>
|
||||
|
||||
|
||||
+15
-17
@@ -7,21 +7,19 @@ status: deprecated
|
||||
|
||||
These features are phased out due to better alternatives or potential issues in future versions. Deprecated functionalities are supported for **five subsequent releases**, providing time for users to transition to updated methods.
|
||||
|
||||
- Constructing [`DetectionDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset) and [`ClassificationDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.ClassificationDataset) with parameter `images` as `Dict[str, np.ndarray]` will be removed in `supervision-0.26.0`. Please pass a list of paths `List[str]` instead.
|
||||
|
||||
- The `DetectionDataset.images` property will be removed in `supervision-0.26.0`. Please loop over images with `for path, image, annotation in dataset:`, as that does not require loading all images into memory.
|
||||
|
||||
- `BoundingBoxAnnotator` has been renamed to `BoxAnnotator` after the old implementation of [`BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator) has been removed. `BoundingBoxAnnotator` will be removed in `supervision-0.26.0`.
|
||||
|
||||
- `overlap_filter_strategy` in [`InferenceSlicer.__init__`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/) is deprecated and will be removed in `supervision-0.27.0`. Use `overlap_strategy` instead.
|
||||
|
||||
- `overlap_ratio_wh` in [`InferenceSlicer.__init__`](https://supervision.roboflow.com/latest/detection/tools/inference_slicer/) is deprecated and will be removed in `supervision-0.27.0`. Use `overlap_wh` instead.
|
||||
- `sv.LMM` enum is deprecated and will be removed in `supervision-0.31.0`. Use `sv.VLM` instead.
|
||||
- [`sv.Detections.from_lmm`](https://supervision.roboflow.com/0.26.0/detection/core/#supervision.detection.core.Detections.from_lmm) property is deprecated and will be removed in `supervision-0.31.0`. Use [`sv.Detections.from_vlm`](https://supervision.roboflow.com/0.26.0/detection/core/#supervision.detection.core.Detections.from_vlm) instead.
|
||||
|
||||
# Removed
|
||||
|
||||
### 0.25.0
|
||||
### 0.26.0
|
||||
|
||||
- The `sv.DetectionDataset.images` property has been removed in `supervision-0.26.0`. Please loop over images with `for path, image, annotation in dataset:`, as that does not require loading all images into memory. Also, constructing `sv.DetectionDataset` with parameter `images` as `Dict[str, np.ndarray]` is deprecated and has been removed in `supervision-0.26.0`. Please pass a list of paths `List[str]` instead.
|
||||
- The name `sv.BoundingBoxAnnotator` is deprecated and has been removed in `supervision-0.26.0`. It has been renamed to [`sv.BoxAnnotator`](https://supervision.roboflow.com/0.22.0/detection/annotators/#supervision.annotators.core.BoxAnnotator).
|
||||
|
||||
No removals in this version!
|
||||
|
||||
### 0.24.0
|
||||
|
||||
@@ -35,12 +33,12 @@ No removals in this version!
|
||||
|
||||
### 0.22.0
|
||||
|
||||
- `Detections.from_roboflow` is removed as of `supervision-0.22.0`. Use [`Detections.from_inference`](detection/core.md/#supervision.detection.core.Detections.from_inference) instead.
|
||||
- The method `Color.white()` was removed as of `supervision-0.22.0`. Use the constant `Color.WHITE` instead.
|
||||
- The method `Color.black()` was removed as of `supervision-0.22.0`. Use the constant `Color.BLACK` instead.
|
||||
- The method `Color.red()` was removed as of `supervision-0.22.0`. Use the constant `Color.RED` instead.
|
||||
- The method `Color.green()` was removed as of `supervision-0.22.0`. Use the constant `Color.GREEN` instead.
|
||||
- The method `Color.blue()` was removed as of `supervision-0.22.0`. Use the constant `Color.BLUE` instead.
|
||||
- The method `ColorPalette.default()` was removed as of `supervision-0.22.0`. Use the constant [`ColorPalette.DEFAULT`](/utils/draw/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
- `BoxAnnotator` was removed as of `supervision-0.22.0`, however `BoundingBoxAnnotator` was immediately renamed to `BoxAnnotator`. Use [`BoxAnnotator`](detection/annotators.md/#supervision.annotators.core.BoxAnnotator) and [`LabelAnnotator`](detection/annotators.md/#supervision.annotators.core.LabelAnnotator) instead of the old `BoxAnnotator`.
|
||||
- The method `FPSMonitor.__call__` was removed as of `supervision-0.22.0`. Use the attribute [`FPSMonitor.fps`](utils/video.md/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
- `sv.Detections.from_roboflow` is removed as of `supervision-0.22.0`. Use [`Detections.from_inference`](detection/core.md/#supervision.detection.core.Detections.from_inference) instead.
|
||||
- The method `sv.Color.white()` was removed as of `supervision-0.22.0`. Use the constant `sv.Color.WHITE` instead.
|
||||
- The method `sv.Color.black()` was removed as of `supervision-0.22.0`. Use the constant `sv.Color.BLACK` instead.
|
||||
- The method `sv.Color.red()` was removed as of `supervision-0.22.0`. Use the constant `sv.Color.RED` instead.
|
||||
- The method `sv.Color.green()` was removed as of `supervision-0.22.0`. Use the constant `sv.Color.GREEN` instead.
|
||||
- The method `sv.Color.blue()` was removed as of `supervision-0.22.0`. Use the constant `sv.Color.BLUE` instead.
|
||||
- The method `sv.ColorPalette.default()` was removed as of `supervision-0.22.0`. Use the constant [`ColorPalette.DEFAULT`](/utils/draw/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
- `sv.BoxAnnotator` was removed as of `supervision-0.22.0`, however `sv.BoundingBoxAnnotator` was immediately renamed to `sv.BoxAnnotator`. Use [`BoxAnnotator`](detection/annotators.md/#supervision.annotators.core.BoxAnnotator) and [`LabelAnnotator`](detection/annotators.md/#supervision.annotators.core.LabelAnnotator) instead of the old `sv.BoxAnnotator`.
|
||||
- The method `sv.FPSMonitor.__call__` was removed as of `supervision-0.22.0`. Use the attribute [`sv.FPSMonitor.fps`](utils/video.md/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
|
||||
@@ -28,28 +28,26 @@ Annotators accept detections and apply box or mask visualizations to the detecti
|
||||
|
||||
</div>
|
||||
|
||||
<!--
|
||||
=== "RoundBox"
|
||||
=== "RoundBox"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
round_box_annotator = sv.RoundBoxAnnotator()
|
||||
annotated_frame = round_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
round_box_annotator = sv.RoundBoxAnnotator()
|
||||
annotated_frame = round_box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
<div class="result" markdown>
|
||||
|
||||
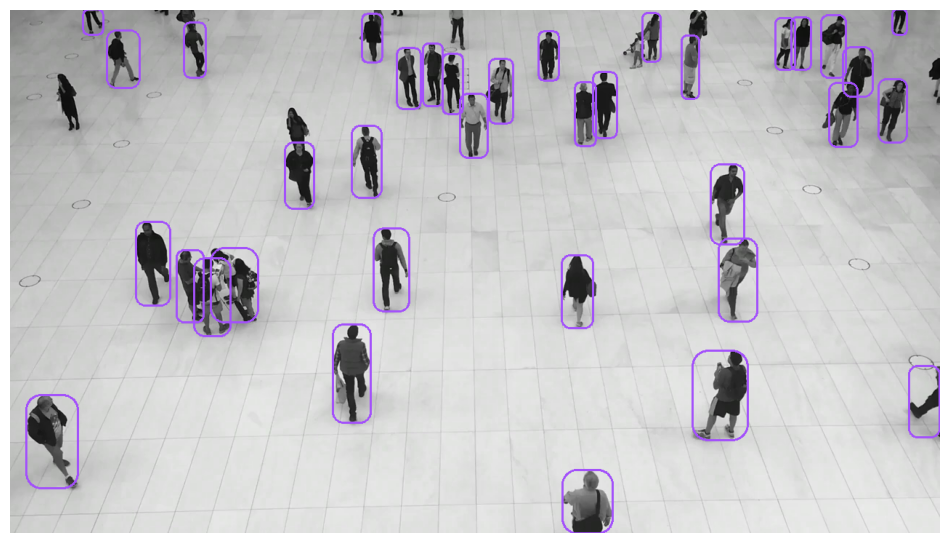{ align=center width="800" }
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
-->
|
||||
</div>
|
||||
|
||||
=== "BoxCorner"
|
||||
|
||||
|
||||
@@ -1,29 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Double Detection Filter
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.OverlapFilter">OverlapFilter</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.OverlapFilter
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.box_non_max_suppression">box_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.mask_non_max_suppression">mask_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.box_non_max_merge">box_non_max_merge</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.box_non_max_merge
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
|
||||
@@ -1,120 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detection Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.box_iou_batch">box_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.mask_iou_batch">mask_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.oriented_box_iou_batch">oriented_box_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.oriented_box_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_mask">polygon_to_mask</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_mask
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.mask_to_xyxy">mask_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.mask_to_polygons">mask_to_polygons</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_polygons
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_xyxy">polygon_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.filter_polygons_by_area">filter_polygons_by_area</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.filter_polygons_by_area
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.move_boxes">move_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.move_masks">move_masks</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_masks
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.scale_boxes">scale_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.scale_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.clip_boxes">clip_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.clip_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.pad_boxes">pad_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.pad_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.xywh_to_xyxy">xywh_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.xywh_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.xyxy_to_xywh">xyxy_to_xywh</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.xyxy_to_xywh
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.xyxy_to_xcycarh">xyxy_to_xcycarh</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.xyxy_to_xcycarh
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.xcycwh_to_xyxy">xcycwh_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.xcycwh_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.contains_holes">contains_holes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.contains_holes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.contains_multiple_segments">contains_multiple_segments</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.contains_multiple_segments
|
||||
@@ -0,0 +1,36 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Boxes Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.boxes.move_boxes">move_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.boxes.move_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.boxes.scale_boxes">scale_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.boxes.scale_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.boxes.utils.clip_boxes">clip_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.boxes.clip_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.boxes.pad_boxes">pad_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.boxes.pad_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.boxes.denormalize_boxes">denormalize_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.boxes.denormalize_boxes
|
||||
@@ -0,0 +1,60 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Converters Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.converters.xyxy_to_xywh">xyxy_to_xywh</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.converters.xyxy_to_xywh
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.converters.xywh_to_xyxy">xywh_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.converters.xywh_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.converters.xyxy_to_xcycarh">xyxy_to_xcycarh</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.converters.xyxy_to_xcycarh
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.converters.xcycwh_to_xyxy">xcycwh_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.converters.xcycwh_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.converters.xyxy_to_polygons">xyxy_to_polygons</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.converters.xyxy_to_polygons
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.converters.mask_to_xyxy">mask_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.converters.mask_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.converters.mask_to_polygons">mask_to_polygons</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.converters.mask_to_polygons
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.converters.polygon_to_mask">polygon_to_mask</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.converters.polygon_to_mask
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.converters.polygon_to_xyxy">polygon_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.converters.polygon_to_xyxy
|
||||
@@ -0,0 +1,72 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# IoU and NMS Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.OverlapFilter">OverlapFilter</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.OverlapFilter
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.OverlapMetric">OverlapMetric</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.OverlapMetric
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.utils.box_iou">box_iou</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.box_iou
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.box_iou_batch">box_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.box_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.box_iou_batch_with_jaccard">box_iou_batch_with_jaccard</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.box_iou_batch_with_jaccard
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.mask_iou_batch">mask_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.mask_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.oriented_box_iou_batch">oriented_box_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.oriented_box_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.box_non_max_suppression">box_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.mask_non_max_suppression">mask_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.box_non_max_merge">box_non_max_merge</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.box_non_max_merge
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.iou_and_nms.mask_non_max_merge">mask_non_max_merge</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.iou_and_nms.mask_non_max_merge
|
||||
@@ -0,0 +1,24 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Masks Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.masks.move_masks">move_masks</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.masks.move_masks
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.masks.contains_holes">contains_holes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.masks.contains_holes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.masks.contains_multiple_segments">contains_multiple_segments</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.masks.contains_multiple_segments
|
||||
@@ -0,0 +1,18 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Polygons Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.polygons.filter_polygons_by_area">filter_polygons_by_area</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygons.filter_polygons_by_area
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.polygons.approximate_polygon">approximate_polygon</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygons.approximate_polygon
|
||||
@@ -177,9 +177,9 @@ offering a clear visual representation of each object's class and unique identif
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
f"#{tracker_id} {class_name}"
|
||||
for class_name, tracker_id
|
||||
in zip(detections.data["class_name"], detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
@@ -212,9 +212,9 @@ offering a clear visual representation of each object's class and unique identif
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
f"#{tracker_id} {class_name}"
|
||||
for class_name, tracker_id
|
||||
in zip(detections.data["class_name"], detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
@@ -260,9 +260,9 @@ movement patterns and interactions between objects in the video.
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
f"#{tracker_id} {class_name}"
|
||||
for class_name, tracker_id
|
||||
in zip(detections.data["class_name"], detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
@@ -298,9 +298,9 @@ movement patterns and interactions between objects in the video.
|
||||
detections = tracker.update_with_detections(detections)
|
||||
|
||||
labels = [
|
||||
f"#{tracker_id} {results.names[class_id]}"
|
||||
for class_id, tracker_id
|
||||
in zip(detections.class_id, detections.tracker_id)
|
||||
f"#{tracker_id} {class_name}"
|
||||
for class_name, tracker_id
|
||||
in zip(detections.data["class_name"], detections.tracker_id)
|
||||
]
|
||||
|
||||
annotated_frame = box_annotator.annotate(
|
||||
|
||||
+8
-2
@@ -10,13 +10,19 @@ hide:
|
||||
<h1></h1>
|
||||
</div>
|
||||
|
||||
<div align="center" id="logo">
|
||||
<div align="center" id="logo" style="padding-top: 1rem;">
|
||||
<a align="center" href="" target="_blank">
|
||||
<img width="850"
|
||||
src="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png?updatedAt=1678995927529">
|
||||
</a>
|
||||
</div>
|
||||
|
||||
<style>
|
||||
#hello {
|
||||
margin: 0;
|
||||
}
|
||||
</style>
|
||||
|
||||
## 👋 Hello
|
||||
|
||||
We write your reusable computer vision tools. Whether you need to load your dataset from your hard drive, draw detections on an image or video, or count how many detections are in a zone. You can count on us!
|
||||
@@ -31,7 +37,7 @@ We write your reusable computer vision tools. Whether you need to load your data
|
||||
## 💻 Install
|
||||
|
||||
You can install `supervision` in a
|
||||
[**Python>=3.8**](https://www.python.org/) environment.
|
||||
[**Python>=3.9**](https://www.python.org/) environment.
|
||||
|
||||
!!! example "Installation"
|
||||
|
||||
|
||||
@@ -59,7 +59,7 @@ document.addEventListener("DOMContentLoaded", function () {
|
||||
<div
|
||||
class="author-container"
|
||||
data-login="${authorData.login}-${elementIndex}"
|
||||
style="margin-left: ${marginLeft}; z-index: ${zIndex};"
|
||||
style="margin-left: ${marginLeft};"
|
||||
>
|
||||
<a
|
||||
href="https://github.com/${authorData.login}"
|
||||
@@ -90,14 +90,17 @@ document.addEventListener("DOMContentLoaded", function () {
|
||||
).join(', ');
|
||||
|
||||
let authorsHTML = `
|
||||
<div class="authors">
|
||||
<div class="authors" style="margin: 0;">
|
||||
${authorAvatarsHTML}
|
||||
<div class="author-names">${authorNamesHTML}</div>
|
||||
</div>
|
||||
`;
|
||||
|
||||
element.innerText = `
|
||||
<div style="flex-direction: column; height: 100%; display: flex;
|
||||
<div style="
|
||||
display: grid !important;
|
||||
grid-template-rows: auto;
|
||||
height: 100%;
|
||||
font-family: -apple-system,BlinkMacSystemFont,Segoe UI,Helvetica,Arial,sans-serif,Apple Color Emoji,Segoe UI Emoji; background: ${theme.background}; font-size: 14px; line-height: 1.5; color: ${theme.color}">
|
||||
<div style="display: flex; align-items: center;">
|
||||
<span style="font-weight: 700; font-size: 1rem; color: ${theme.linkColor};">
|
||||
@@ -105,13 +108,14 @@ document.addEventListener("DOMContentLoaded", function () {
|
||||
</span>
|
||||
</div>
|
||||
${authorsHTML}
|
||||
<div style="font-size: 12px; color: ${theme.color}; display: flex; flex: 0; justify-content: space-between">
|
||||
<div style="font-size: 12px; color: ${theme.color}; display: grid; grid-template-columns: auto 3fr; justify-content: space-between; gap: 1rem;">
|
||||
<div style="display: flex; align-items: center;">
|
||||
<img src="/assets/supervision-lenny.png" aria-label="stars" width="20" height="20" role="img" />
|
||||
|
||||
<span style="margin-left: 4px">${version}</span>
|
||||
</div>
|
||||
<div style="display: flex; align-items: center; flex-wrap: wrap">
|
||||
<div style="display: flex; align-items: center; flex-wrap: wrap; align-content: right;
|
||||
gap: 0.1rem;">
|
||||
${labelHTML}
|
||||
</div>
|
||||
</div>
|
||||
|
||||
@@ -0,0 +1,19 @@
|
||||
window.MathJax = {
|
||||
tex: {
|
||||
inlineMath: [["\\(", "\\)"]],
|
||||
displayMath: [["\\[", "\\]"]],
|
||||
processEscapes: true,
|
||||
processEnvironments: true
|
||||
},
|
||||
options: {
|
||||
ignoreHtmlClass: ".*|",
|
||||
processHtmlClass: "arithmatex"
|
||||
}
|
||||
};
|
||||
|
||||
document$.subscribe(() => {
|
||||
MathJax.startup.output.clearCache()
|
||||
MathJax.typesetClear()
|
||||
MathJax.texReset()
|
||||
MathJax.typesetPromise()
|
||||
})
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Common Values
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# F1 Score
|
||||
|
||||
@@ -16,3 +16,9 @@ status: new
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.mean_average_precision.MeanAveragePrecisionResult
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.dataset.formats.coco.get_coco_class_index_mapping">get_coco_class_index_mapping</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.dataset.formats.coco.get_coco_class_index_mapping
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Mean Average Recall
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Precision
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Recall
|
||||
|
||||
+2
-3
@@ -93,7 +93,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q inference-gpu \"supervision[assets]\""
|
||||
"!pip install -q inference-gpu \"supervision\""
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -156,7 +156,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 4,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -207,7 +207,6 @@
|
||||
],
|
||||
"source": [
|
||||
"import supervision as sv\n",
|
||||
"from supervision.assets import download_assets, VideoAssets\n",
|
||||
"from inference.models.utils import get_roboflow_model\n",
|
||||
"\n",
|
||||
"\n",
|
||||
|
||||
+24
-14
File diff suppressed because one or more lines are too long
+2
-2
@@ -17,7 +17,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 10,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"vscode": {
|
||||
"languageId": "shellscript"
|
||||
@@ -25,7 +25,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q \"supervision[assets]\""
|
||||
"pip install -q \"supervision\""
|
||||
]
|
||||
},
|
||||
{
|
||||
|
||||
+1
-1
@@ -101,7 +101,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q torch diffusers accelerate inference-gpu[yolo-world] dill git+https://github.com/openai/CLIP.git supervision==0.19.0rc5"
|
||||
"!pip install -q torch diffusers accelerate inference-gpu[yolo-world] dill git+https://github.com/openai/CLIP.git supervision"
|
||||
]
|
||||
},
|
||||
{
|
||||
|
||||
Vendored
+1
-1
@@ -92,7 +92,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q inference-gpu \"supervision[assets]\""
|
||||
"!pip install -q inference-gpu \"supervision\""
|
||||
]
|
||||
},
|
||||
{
|
||||
|
||||
+1
-1
@@ -72,7 +72,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install roboflow supervision==0.19.0 -q"
|
||||
"!pip install roboflow supervision -q"
|
||||
]
|
||||
},
|
||||
{
|
||||
|
||||
Vendored
+5
-5
@@ -300,7 +300,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q \"ultralytics<=8.3.40\""
|
||||
"!pip install -q ultralytics"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -495,7 +495,7 @@
|
||||
"source": [
|
||||
"from ultralytics import YOLO\n",
|
||||
"\n",
|
||||
"model = YOLO(\"yolov8x.pt\")\n",
|
||||
"model = YOLO(\"yolo11x.pt\")\n",
|
||||
"result = model(image, verbose=False)[0]\n",
|
||||
"detections = sv.Detections.from_ultralytics(result)"
|
||||
]
|
||||
@@ -594,7 +594,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 33,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "yM6dmicTRGl6"
|
||||
},
|
||||
@@ -602,7 +602,7 @@
|
||||
"source": [
|
||||
"from ultralytics import YOLO\n",
|
||||
"\n",
|
||||
"model = YOLO(\"yolov8x-seg.pt\")\n",
|
||||
"model = YOLO(\"yolo11x-seg.pt\")\n",
|
||||
"result = model(image, verbose=False)[0]\n",
|
||||
"detections = sv.Detections.from_ultralytics(result)"
|
||||
]
|
||||
@@ -926,7 +926,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q supervision[assets]"
|
||||
"!pip install -q supervision"
|
||||
]
|
||||
},
|
||||
{
|
||||
|
||||
+9
-19
File diff suppressed because one or more lines are too long
+4
-4
@@ -32,7 +32,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -q inference requests tqdm supervision==0.21.0"
|
||||
"!pip install -q inference requests tqdm supervision"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -695,12 +695,12 @@
|
||||
"source": [
|
||||
"###\u00a0Annotate Image with Detections\n",
|
||||
"\n",
|
||||
"Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator) classes."
|
||||
"Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator) and [`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator) classes."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 49,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -722,7 +722,7 @@
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"bounding_box_annotator = sv.BoundingBoxAnnotator()\n",
|
||||
"bounding_box_annotator = sv.BoxAnnotator()\n",
|
||||
"label_annotator = sv.LabelAnnotator()\n",
|
||||
"\n",
|
||||
"annotated_frame = frame.copy()\n",
|
||||
|
||||
@@ -15,7 +15,7 @@
|
||||
/* Large screens (1024px and up) */
|
||||
@media (min-width: 1024px) {
|
||||
.custom-grid {
|
||||
grid-template-columns: repeat(3, minmax(0, 1fr));
|
||||
grid-template-columns: repeat(4, minmax(0, 1fr));
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
+241
-2
@@ -1,7 +1,10 @@
|
||||
:root {
|
||||
:root, body {
|
||||
/* Default to light theme */
|
||||
--md-primary-fg-color: #8315F9;
|
||||
--md-accent-fg-color: #00FFCE;
|
||||
--md-code-hl-color: #8315F9 !important;
|
||||
--md-accent-fg-color: #8315F9 !important;
|
||||
--md-code-hl-color--light: #e8d2ff89 !important;
|
||||
--md-footer-fg-color--light: rgb(111, 108, 121) !important;
|
||||
}
|
||||
|
||||
body.light {
|
||||
@@ -9,6 +12,202 @@ body.light {
|
||||
--md-text-color: #000000;
|
||||
--md-h2-color: #000000;
|
||||
}
|
||||
.md-grid {
|
||||
max-width: 85%;
|
||||
margin: auto;
|
||||
}
|
||||
.sublist {
|
||||
display: none;
|
||||
list-style: none;
|
||||
padding-left: 0;
|
||||
background: white;
|
||||
position: absolute;
|
||||
border-radius: 8px;
|
||||
margin-top: 0.25rem;
|
||||
}
|
||||
.sublist {
|
||||
transition: opacity 0.5s ease-in-out;
|
||||
display: none;
|
||||
position: absolute; /* Ensure it overlaps and doesn't break flow */
|
||||
background: white; /* So it's visible */
|
||||
z-index: 1000;
|
||||
}
|
||||
.sublist li {
|
||||
padding: 0.5rem;
|
||||
}
|
||||
#products-list *:hover .products-sublist {
|
||||
display: block;
|
||||
}
|
||||
#resources-list *, #products-list * {
|
||||
cursor: pointer;
|
||||
}
|
||||
.products-sublist, .resources-sublist {
|
||||
padding: 0.25rem;
|
||||
}
|
||||
.products-sublist li:hover, .resources-sublist li:hover, .md-nav__link[href]:hover {
|
||||
background: rgb(242, 241, 247) !important;
|
||||
border-radius: 6px;
|
||||
color: initial !important;
|
||||
}
|
||||
.md-search {
|
||||
flex-grow: 2;
|
||||
}
|
||||
.portfolio-section .md-grid {
|
||||
max-width: 100%;
|
||||
}
|
||||
.md-header__inner {
|
||||
align-items: center;
|
||||
display: grid;
|
||||
grid-template-columns: 0.1fr 1.4fr 2fr 2fr;
|
||||
padding-right: 1rem;
|
||||
}
|
||||
.md-search__inner {
|
||||
max-width: 600px;
|
||||
width: 100%;
|
||||
min-width: 100%;
|
||||
}
|
||||
.md-search__input {
|
||||
background: white;
|
||||
border: 1px solid rgb(229, 231, 235);
|
||||
border-radius: 8px;
|
||||
color: rgb(111, 108, 121);
|
||||
}
|
||||
.md-search__form *, .md-search__icon, .md-search__input {
|
||||
color: rgb(111, 108, 121);
|
||||
}
|
||||
.md-search__input::placeholder {
|
||||
color: rgb(156, 163, 175);
|
||||
}
|
||||
.md-search__form {
|
||||
background: none !important;
|
||||
}
|
||||
.md-footer, .md-footer-meta {
|
||||
background-color: transparent;
|
||||
color: rgb(111, 108, 121);
|
||||
}
|
||||
.md-typeset .tabbed-set > input:first-child:checked ~ .tabbed-labels > :first-child, .md-typeset .tabbed-set > input:nth-child(10):checked ~ .tabbed-labels > :nth-child(10), .md-typeset .tabbed-set > input:nth-child(11):checked ~ .tabbed-labels > :nth-child(11), .md-typeset .tabbed-set > input:nth-child(12):checked ~ .tabbed-labels > :nth-child(12), .md-typeset .tabbed-set > input:nth-child(13):checked ~ .tabbed-labels > :nth-child(13), .md-typeset .tabbed-set > input:nth-child(14):checked ~ .tabbed-labels > :nth-child(14), .md-typeset .tabbed-set > input:nth-child(15):checked ~ .tabbed-labels > :nth-child(15), .md-typeset .tabbed-set > input:nth-child(16):checked ~ .tabbed-labels > :nth-child(16), .md-typeset .tabbed-set > input:nth-child(17):checked ~ .tabbed-labels > :nth-child(17), .md-typeset .tabbed-set > input:nth-child(18):checked ~ .tabbed-labels > :nth-child(18), .md-typeset .tabbed-set > input:nth-child(19):checked ~ .tabbed-labels > :nth-child(19), .md-typeset .tabbed-set > input:nth-child(2):checked ~ .tabbed-labels > :nth-child(2), .md-typeset .tabbed-set > input:nth-child(20):checked ~ .tabbed-labels > :nth-child(20), .md-typeset .tabbed-set > input:nth-child(3):checked ~ .tabbed-labels > :nth-child(3), .md-typeset .tabbed-set > input:nth-child(4):checked ~ .tabbed-labels > :nth-child(4), .md-typeset .tabbed-set > input:nth-child(5):checked ~ .tabbed-labels > :nth-child(5), .md-typeset .tabbed-set > input:nth-child(6):checked ~ .tabbed-labels > :nth-child(6), .md-typeset .tabbed-set > input:nth-child(7):checked ~ .tabbed-labels > :nth-child(7), .md-typeset .tabbed-set > input:nth-child(8):checked ~ .tabbed-labels > :nth-child(8), .md-typeset .tabbed-set > input:nth-child(9):checked ~ .tabbed-labels > :nth-child(9) {
|
||||
color: #8315F9;
|
||||
border-bottom: 1px solid #8315F9;
|
||||
}
|
||||
.md-footer *, html .md-footer-meta.md-typeset a {
|
||||
color: rgb(111, 108, 121);
|
||||
}
|
||||
.repo-card {
|
||||
height: 100%;
|
||||
}
|
||||
.header-btn {
|
||||
text-align: center;
|
||||
}
|
||||
.header-btn, .sublist {
|
||||
box-shadow: rgb(255, 255, 255) 0px 0px 0px 0px, rgb(217, 215, 226) 0px 0px 0px 1px, rgb(217, 215, 226) 0px 1px 2px 0px;
|
||||
}
|
||||
.header-btn:hover {
|
||||
box-shadow: rgb(255, 255, 255) 0px 0px 0px 0px, rgb(217, 215, 226) 0px 0px 0px 1px, rgb(217, 215, 226) 0px 1.0001px 2.00013px -0.0000327245px, rgba(0, 0, 0, 0) 0px 0.000065449px 0.000130898px -0.000065449px;
|
||||
}
|
||||
.md-typeset .headerlink:hover, .md-typeset .headerlink:target {
|
||||
color: #8315F9;
|
||||
}
|
||||
.md-typeset h1, .md-header__title {
|
||||
color: black;
|
||||
font-weight: 800;
|
||||
}
|
||||
.md-typeset h1 {
|
||||
font-weight: normal;
|
||||
margin-bottom: 1rem;
|
||||
}
|
||||
body {
|
||||
background: linear-gradient(to left bottom, rgb(243, 238, 255), rgb(255, 255, 255) 60%) no-repeat;
|
||||
}
|
||||
|
||||
/* .md-nav__link:has([tabindex=""]) {
|
||||
text-transform: uppercase;
|
||||
} */
|
||||
|
||||
.header-list {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
gap: 1rem;
|
||||
list-style: none;
|
||||
font-size: 0.75rem;
|
||||
justify-content: flex-end;
|
||||
}
|
||||
.md-nav__list label, .md-nav--secondary label {
|
||||
/* text-transform: uppercase; */
|
||||
color: rgb(29, 29, 31) !important;
|
||||
font-size: 0.7rem;
|
||||
margin-bottom: 0;
|
||||
}
|
||||
.md-nav--secondary label {
|
||||
margin-left: 0.5rem;
|
||||
}
|
||||
|
||||
.md-nav__link {
|
||||
padding: 0.25rem;
|
||||
padding-left: 0.5rem;
|
||||
padding-right: 0.5rem;
|
||||
}
|
||||
|
||||
.md-nav__link--active {
|
||||
background: rgb(243, 238, 255);
|
||||
border-radius: 6px;
|
||||
padding-top: 0.25rem;
|
||||
}
|
||||
|
||||
.md-tabs__item--active {
|
||||
color: var(--md-primary-fg-color);
|
||||
border-bottom: 2px solid var(--md-primary-fg-color);
|
||||
}
|
||||
|
||||
.md-nav--secondary .md-nav__title {
|
||||
background: transparent;
|
||||
box-shadow: none;
|
||||
}
|
||||
|
||||
.md-header, .md-tabs {
|
||||
color: rgb(111, 108, 121);
|
||||
background-color: transparent;
|
||||
}
|
||||
.md-header--shadow {
|
||||
background: linear-gradient(to left bottom, rgb(243, 238, 255), rgb(255, 255, 255) 60%);
|
||||
box-shadow: none;
|
||||
border-bottom: 1px solid rgb(229, 231, 235);
|
||||
}
|
||||
|
||||
#item-logo {
|
||||
display: none;
|
||||
}
|
||||
.md-main__inner, .md-header__inner, .md-grid {
|
||||
max-width: 100%;
|
||||
}
|
||||
@media (max-width: 1200px) {
|
||||
.md-header__inner {
|
||||
display: flex;
|
||||
}
|
||||
.header-list {
|
||||
display: none;
|
||||
}
|
||||
#item-logo {
|
||||
display: block;
|
||||
}
|
||||
}
|
||||
.md-content {
|
||||
max-width: 40rem;
|
||||
margin: auto;
|
||||
}
|
||||
/* // if no md-sidebar--primary, make .md-content full width */
|
||||
.md-main__inner:has(.md-sidebar--primary[hidden]) .md-content {
|
||||
max-width: 100%;
|
||||
}
|
||||
.md-sidebar--primary {
|
||||
flex: 0 20%;
|
||||
}
|
||||
.md-tabs {
|
||||
border-bottom: 1px solid rgb(229, 231, 235);
|
||||
}
|
||||
.md-main__inner {
|
||||
padding-top: 1rem;
|
||||
margin-top: 0;
|
||||
}
|
||||
|
||||
body.dark {
|
||||
/* Dark theme */
|
||||
@@ -29,3 +228,43 @@ body[data-md-url$="/cookbooks/"] .md-content {
|
||||
margin-left: 0;
|
||||
width: 100%;
|
||||
}
|
||||
|
||||
.md-main, nav .md-grid, .md-header__inner {
|
||||
max-width: 1600px;
|
||||
width: 100%;
|
||||
margin: auto;
|
||||
}
|
||||
.md-search__scrollwrap {
|
||||
width: 100% !important;
|
||||
}
|
||||
.md-nav--secondary .md-nav__title {
|
||||
position: initial !important;
|
||||
}
|
||||
|
||||
.md-header__title .md-ellipsis {
|
||||
overflow: initial !important;
|
||||
text-overflow: initial !important;
|
||||
}
|
||||
.md-search {
|
||||
flex-grow: 0;
|
||||
}
|
||||
|
||||
/* Table style */
|
||||
|
||||
th, td {
|
||||
border: 1px solid var(--md-typeset-table-color);
|
||||
}
|
||||
|
||||
.md-typeset__table {
|
||||
line-height: 1.5;
|
||||
}
|
||||
|
||||
.md-typeset__table table:not([class]) {
|
||||
font-size: 0.6rem;
|
||||
border-collapse: collapse;
|
||||
}
|
||||
|
||||
.md-typeset__table table:not([class]) td,
|
||||
.md-typeset__table table:not([class]) th {
|
||||
padding: 10px;
|
||||
}
|
||||
|
||||
Vendored
+9
-9
@@ -12,15 +12,15 @@
|
||||
</div>
|
||||
<div class="custom-grid">
|
||||
<a href="/develop/notebooks/quickstart"> <p class="card repo-card" data-name="Supervision Quickstart" data-labels="ANNOTATOR,DETECTION,SAM"
|
||||
data-version="v0.18.0" data-author="SkalskiP,onuralpszr"></p>
|
||||
data-version="v0.26.0" data-author="SkalskiP,onuralpszr"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/count-objects-crossing-the-line">
|
||||
<p class="card repo-card" data-name="Count Objects Crossing the Line"
|
||||
data-labels="ANNOTATORS,LINE ZONE,TRACKING" data-version="v0.18.0" data-author="SkalskiP"></p>
|
||||
data-labels="ANNOTATORS,LINE ZONE,TRACKING" data-version="v0.26.0" data-author="SkalskiP"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/zero-shot-object-detection-with-yolo-world">
|
||||
<p class="card repo-card" data-name="Zero-Shot Object Detection with YOLO-World"
|
||||
data-labels="ANNOTATORS,DETECTION,INFERENCE" data-version="v0.19.0" data-author="SkalskiP"></p>
|
||||
data-labels="ANNOTATORS,DETECTION,INFERENCE" data-version="v0.26.0" data-author="SkalskiP"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/download-supervision-assets">
|
||||
<p class="card repo-card" data-name="Downloading Supervision Assets" data-labels="ASSETS" data-version="v0.18.0"
|
||||
@@ -28,7 +28,7 @@
|
||||
</a>
|
||||
<a href="/develop/notebooks/annotate-video-with-detections">
|
||||
<p class="card repo-card" data-name="Annotate Video with Detections" data-labels="INFERENCE,YOLOV8"
|
||||
data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
data-version="v0.26.0" data-author="nickherrig"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/object-tracking">
|
||||
<p class="card repo-card" data-name="Object Tracking" data-labels="TRACKING, ANNOTATOR" data-version="v0.18.0"
|
||||
@@ -36,23 +36,23 @@
|
||||
</a>
|
||||
<a href="/develop/notebooks/occupancy_analytics">
|
||||
<p class="card repo-card" data-name="Analyzing Zone Occupancy" data-labels="ANNOTATOR,DETECTION,ZONES"
|
||||
data-version="v0.19.0" data-author="stellasphere"></p>
|
||||
data-version="v0.26.0" data-author="stellasphere"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/evaluating-alignment-of-text-to-image-diffusion-models">
|
||||
<p class="card repo-card" data-name="Evaluating Alignment of Text-to-image Diffusion Models"
|
||||
data-labels="ANNOTATORS,YOLO WORLD" data-version="v0.19.0rc5" data-author="iamhatesz"></p>
|
||||
data-labels="ANNOTATORS,YOLO WORLD" data-version="v0.26.0" data-author="iamhatesz"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/serialise-detections-to-csv">
|
||||
<p class="card repo-card" data-name="Serialise Detections to a CSV File"
|
||||
data-labels="DETECTIONS,CSV SINK,INFERENCE" data-version="v0.21.0" data-author="onuralpszr"></p>
|
||||
data-labels="DETECTIONS,CSV SINK,INFERENCE" data-version="v0.26.0" data-author="onuralpszr"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/serialise-detections-to-json">
|
||||
<p class="card repo-card" data-name="Serialise Detections to a JSON File"
|
||||
data-labels="DETECTIONS,JSON SINK,INFERENCE" data-version="v0.21.0" data-author="onuralpszr"></p>
|
||||
data-labels="DETECTIONS,JSON SINK,INFERENCE" data-version="v0.26.0" data-author="onuralpszr"></p>
|
||||
</a>
|
||||
<a href="/develop/notebooks/small-object-detection-with-sahi">
|
||||
<p class="card repo-card" data-name="Small Object Detection with SAHI"
|
||||
data-labels="DETECTIONS,SAHI,SMALL,OBJECT,INFERENCE" data-version="v0.23.0" data-author="ediardo"></p>
|
||||
data-labels="DETECTIONS,SAHI,SMALL,OBJECT,INFERENCE" data-version="v0.26.0" data-author="ediardo"></p>
|
||||
</a>
|
||||
</div>
|
||||
</div>
|
||||
|
||||
Vendored
+181
@@ -0,0 +1,181 @@
|
||||
{% set class = "md-header" %}
|
||||
{% if "navigation.tabs.sticky" in features %}
|
||||
{% set class = class ~ " md-header--shadow md-header--lifted" %}
|
||||
{% elif "navigation.tabs" not in features %}
|
||||
{% set class = class ~ " md-header--shadow" %}
|
||||
{% endif %}
|
||||
|
||||
<!-- Header -->
|
||||
<header class="{{ class }}" data-md-component="header">
|
||||
<nav
|
||||
class="md-header__inner md-grid"
|
||||
aria-label="{{ lang.t('header') }}"
|
||||
>
|
||||
|
||||
<!-- Link to home -->
|
||||
<a
|
||||
href="{{ config.extra.homepage | d(nav.homepage.url, true) | url }}"
|
||||
title="{{ config.site_name | e }}"
|
||||
class="md-header__button md-logo"
|
||||
aria-label="{{ config.site_name }}"
|
||||
data-md-component="logo"
|
||||
>
|
||||
{% include "partials/logo.html" %}
|
||||
</a>
|
||||
|
||||
<!-- Button to open drawer -->
|
||||
<label class="md-header__button md-icon" for="__drawer">
|
||||
{% set icon = config.theme.icon.menu or "material/menu" %}
|
||||
{% include ".icons/" ~ icon ~ ".svg" %}
|
||||
</label>
|
||||
|
||||
<!-- Header title -->
|
||||
<div class="md-header__title" data-md-component="header-title">
|
||||
<div class="md-header__ellipsis">
|
||||
<div class="md-header__topic">
|
||||
<span class="md-ellipsis">
|
||||
{{ config.site_name }} Docs
|
||||
</span>
|
||||
</div>
|
||||
<div class="md-header__topic" data-md-component="header-topic">
|
||||
<span class="md-ellipsis" style="display: flex; align-items: center; gap: 0.5rem;">
|
||||
<a
|
||||
href="{{ config.extra.homepage | d(nav.homepage.url, true) | url }}"
|
||||
title="{{ config.site_name | e }}"
|
||||
class="md-header__button md-logo"
|
||||
aria-label="{{ config.site_name }}"
|
||||
data-md-component="logo"
|
||||
id="item-logo"
|
||||
>
|
||||
{% include "partials/logo.html" %}
|
||||
</a>
|
||||
{% if page.meta and page.meta.title %}
|
||||
{{ page.meta.title }}
|
||||
{% else %}
|
||||
{{ page.title }}
|
||||
{% endif %}
|
||||
</span>
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
<!-- Button to open search modal -->
|
||||
{% if "material/search" in config.plugins %}
|
||||
{% set search = config.plugins["material/search"] | attr("config") %}
|
||||
|
||||
<!-- Check if search is actually enabled - see https://t.ly/DT_0V -->
|
||||
{% if search.enabled %}
|
||||
<label class="md-header__button md-icon" for="__search">
|
||||
{% set icon = config.theme.icon.search or "material/magnify" %}
|
||||
{% include ".icons/" ~ icon ~ ".svg" %}
|
||||
</label>
|
||||
|
||||
<!-- Search interface -->
|
||||
{% include "partials/search.html" %}
|
||||
{% endif %}
|
||||
{% endif %}
|
||||
|
||||
|
||||
<ul class="header-list">
|
||||
<li style="align-items: center;" id="resources-list">
|
||||
<label for="dropdown-resources"><span>Resources <img src="https://ka-p.fontawesome.com/releases/v6.6.0/svgs/regular/chevron-down.svg?v=2&token=a463935e93" style="height: 0.5rem;" /></span></label>
|
||||
<input type="radio" name="dropdown" id="dropdown-resources" style="display: none;" />
|
||||
<ul class="resources-sublist sublist">
|
||||
<li><a href="https://blog.roboflow.com">Blog</a></li>
|
||||
<li><a href="https://discuss.roboflow.com">Community Forum</a></li>
|
||||
<li><a href="https://roboflow.com/sales">Contact Sales</a></li>
|
||||
<li><a href="https://universe.roboflow.com">Universe</a></li>
|
||||
</ul>
|
||||
</li>
|
||||
<li style="align-items: center;" id="products-list">
|
||||
<label for="dropdown-products"><span>Docs <img src="https://ka-p.fontawesome.com/releases/v6.6.0/svgs/regular/chevron-down.svg?v=2&token=a463935e93" style="height: 0.5rem;" /></span></label>
|
||||
<input type="radio" name="dropdown" id="dropdown-products" style="display: none;" />
|
||||
<ul class="products-sublist sublist">
|
||||
<li><a href="https://inference.roboflow.com">Inference</a></li>
|
||||
<li><a href="https://supervision.roboflow.com">Supervision</a></li>
|
||||
<li><a href="https://trackers.roboflow.com">Trackers</a></li>
|
||||
<li><a href="https://maestro.roboflow.com">Maestro</a></li>
|
||||
<li><a href="https://docs.roboflow.com">Roboflow</a></li>
|
||||
</ul>
|
||||
</li>
|
||||
<script>
|
||||
document.addEventListener('click', function(event) {
|
||||
const resourcesList = document.getElementById('resources-list');
|
||||
const productsList = document.getElementById('products-list');
|
||||
const dropdownResources = document.getElementById('dropdown-resources');
|
||||
const dropdownProducts = document.getElementById('dropdown-products');
|
||||
|
||||
if (!resourcesList.contains(event.target)) {
|
||||
dropdownResources.checked = false;
|
||||
}
|
||||
if (!productsList.contains(event.target)) {
|
||||
dropdownProducts.checked = false;
|
||||
}
|
||||
});
|
||||
// on mouse over
|
||||
document.getElementById('resources-list').addEventListener('mouseover', function() {
|
||||
document.getElementById('dropdown-resources').checked = true;
|
||||
});
|
||||
document.getElementById('products-list').addEventListener('mouseover', function() {
|
||||
document.getElementById('dropdown-products').checked = true;
|
||||
});
|
||||
// on mouse out
|
||||
document.getElementById('resources-list').addEventListener('mouseout', function() {
|
||||
// if not hovering over the sublist or the label, uncheck the dropdown
|
||||
// wait 1 sec
|
||||
setTimeout(function() {
|
||||
if (!document.querySelector('.resources-sublist:hover') && !document.querySelector('#resources-list:hover')) {
|
||||
document.getElementById('dropdown-resources').checked = false;
|
||||
}
|
||||
}, 350);
|
||||
});
|
||||
// if mouseout of sublist, uncheck immediately
|
||||
document.querySelector('.resources-sublist').addEventListener('mouseout', function() {
|
||||
setTimeout(function() {
|
||||
if (!document.querySelector('.resources-sublist:hover') && !document.querySelector('#resources-list:hover')) {
|
||||
document.getElementById('dropdown-resources').checked = false;
|
||||
}
|
||||
}, 450);
|
||||
});
|
||||
document.getElementById('products-list').addEventListener('mouseout', function() {
|
||||
// if not hovering over the sublist, uncheck the dropdown
|
||||
// wait 1 sec
|
||||
setTimeout(function() {
|
||||
if (!document.querySelector('.products-sublist:hover') && !document.querySelector('#products-list:hover')) {
|
||||
document.getElementById('dropdown-products').checked = false;
|
||||
}
|
||||
}, 500);
|
||||
});
|
||||
// if mouseout of sublist, uncheck immediately
|
||||
document.querySelector('.products-sublist').addEventListener('mouseout', function() {
|
||||
setTimeout(function() {
|
||||
if (!document.querySelector('.products-sublist:hover') && !document.querySelector('#products-list:hover')) {
|
||||
document.getElementById('dropdown-products').checked = false;
|
||||
}
|
||||
}, 500);
|
||||
});
|
||||
|
||||
</script>
|
||||
<style>
|
||||
#dropdown-resources:checked ~ .resources-sublist {
|
||||
display: block;
|
||||
}
|
||||
#dropdown-products:checked ~ .products-sublist {
|
||||
display: block;
|
||||
}
|
||||
/* Hide dropdown if clicking outside */
|
||||
body:not(:has(#dropdown-resources:checked)) .resources-sublist,
|
||||
body:not(:has(#dropdown-products:checked)) .products-sublist {
|
||||
display: none;
|
||||
}
|
||||
</style>
|
||||
<a href="https://github.com/roboflow/supervision"><li class="header-btn" style="border-radius: 5px; color: white; background: var(--md-typeset-a-color); padding-top: 0.25rem; padding-left: 0.5rem; padding-bottom: 0.25rem; padding-right: 0.5rem; border: 1px solid #8315F9;">Go to GitHub</li></a>
|
||||
</ul>
|
||||
</nav>
|
||||
|
||||
<!-- Navigation tabs (sticky) -->
|
||||
{% if "navigation.tabs.sticky" in features %}
|
||||
{% if "navigation.tabs" in features %}
|
||||
{% include "partials/tabs.html" %}
|
||||
{% endif %}
|
||||
{% endif %}
|
||||
</header>
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# ByteTrack
|
||||
|
||||
@@ -1,7 +1,6 @@
|
||||
import argparse
|
||||
import json
|
||||
import os
|
||||
from typing import List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -14,7 +13,7 @@ import supervision as sv
|
||||
COLORS = sv.ColorPalette.DEFAULT
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
def load_zones_config(file_path: str) -> list[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
@@ -28,14 +27,14 @@ def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
with open(file_path) as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data["polygons"]]
|
||||
|
||||
|
||||
def initiate_annotators(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> Tuple[List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoxAnnotator]]:
|
||||
polygons: list[np.ndarray], resolution_wh: tuple[int, int]
|
||||
) -> tuple[list[sv.PolygonZone], list[sv.PolygonZoneAnnotator], list[sv.BoxAnnotator]]:
|
||||
line_thickness = sv.calculate_optimal_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
@@ -93,9 +92,9 @@ def detect(
|
||||
|
||||
def annotate(
|
||||
frame: np.ndarray,
|
||||
zones: List[sv.PolygonZone],
|
||||
zone_annotators: List[sv.PolygonZoneAnnotator],
|
||||
box_annotators: List[sv.BoxAnnotator],
|
||||
zones: list[sv.PolygonZone],
|
||||
zone_annotators: list[sv.PolygonZoneAnnotator],
|
||||
box_annotators: list[sv.BoxAnnotator],
|
||||
detections: sv.Detections,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
gdown
|
||||
inference==0.9.17
|
||||
supervision>=0.20.0
|
||||
inference
|
||||
supervision
|
||||
tqdm
|
||||
ultralytics<=8.3.40
|
||||
ultralytics
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
import argparse
|
||||
import json
|
||||
from typing import List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -12,7 +11,7 @@ import supervision as sv
|
||||
COLORS = sv.ColorPalette.DEFAULT
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
def load_zones_config(file_path: str) -> list[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
@@ -26,14 +25,14 @@ def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
with open(file_path) as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data["polygons"]]
|
||||
|
||||
|
||||
def initiate_annotators(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> Tuple[List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoxAnnotator]]:
|
||||
polygons: list[np.ndarray], resolution_wh: tuple[int, int]
|
||||
) -> tuple[list[sv.PolygonZone], list[sv.PolygonZoneAnnotator], list[sv.BoxAnnotator]]:
|
||||
line_thickness = sv.calculate_optimal_line_thickness(resolution_wh=resolution_wh)
|
||||
text_scale = sv.calculate_optimal_text_scale(resolution_wh=resolution_wh)
|
||||
|
||||
@@ -90,9 +89,9 @@ def detect(
|
||||
|
||||
def annotate(
|
||||
frame: np.ndarray,
|
||||
zones: List[sv.PolygonZone],
|
||||
zone_annotators: List[sv.PolygonZoneAnnotator],
|
||||
box_annotators: List[sv.BoxAnnotator],
|
||||
zones: list[sv.PolygonZone],
|
||||
zone_annotators: list[sv.PolygonZoneAnnotator],
|
||||
box_annotators: list[sv.BoxAnnotator],
|
||||
detections: sv.Detections,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
@@ -135,7 +134,7 @@ if __name__ == "__main__":
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source_weights_path",
|
||||
default="yolov8x.pt",
|
||||
default="yolo11x.pt",
|
||||
help="Path to the source weights file",
|
||||
type=str,
|
||||
)
|
||||
|
||||
@@ -1,2 +1,2 @@
|
||||
supervision[assets]==0.19.0
|
||||
ultralytics<=8.3.40
|
||||
supervision
|
||||
ultralytics
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
supervision>=0.20.0
|
||||
tqdm==4.66.3
|
||||
supervision
|
||||
tqdm
|
||||
requests
|
||||
ultralytics==8.0.237
|
||||
ultralytics
|
||||
super-gradients==3.5.0
|
||||
inference==0.9.17
|
||||
inference
|
||||
|
||||
@@ -70,7 +70,7 @@ if __name__ == "__main__":
|
||||
args = parse_arguments()
|
||||
|
||||
video_info = sv.VideoInfo.from_video_path(video_path=args.source_video_path)
|
||||
model = YOLO("yolov8x.pt")
|
||||
model = YOLO("yolo11x.pt")
|
||||
|
||||
byte_track = sv.ByteTrack(
|
||||
frame_rate=video_info.fps, track_activation_threshold=args.confidence_threshold
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -22,7 +21,7 @@ def main(
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
classes: list[int],
|
||||
) -> None:
|
||||
model = get_model(model_id=model_id)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -22,7 +21,7 @@ def main(
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
classes: list[int],
|
||||
) -> None:
|
||||
model = get_model(model_id=model_id)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -18,7 +17,7 @@ LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
|
||||
|
||||
class CustomSink:
|
||||
def __init__(self, zone_configuration_path: str, classes: List[int]):
|
||||
def __init__(self, zone_configuration_path: str, classes: list[int]):
|
||||
self.classes = classes
|
||||
self.tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
@@ -83,7 +82,7 @@ def main(
|
||||
model_id: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
classes: list[int],
|
||||
) -> None:
|
||||
sink = CustomSink(zone_configuration_path=zone_configuration_path, classes=classes)
|
||||
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
opencv-python
|
||||
supervision>=0.20.0
|
||||
ultralytics<=8.3.40
|
||||
inference==0.9.17
|
||||
supervision
|
||||
ultralytics
|
||||
inference
|
||||
pytube
|
||||
|
||||
@@ -1,11 +1,12 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import os
|
||||
from typing import Optional
|
||||
|
||||
from pytube import YouTube
|
||||
|
||||
|
||||
def main(url: str, output_path: Optional[str], file_name: Optional[str]) -> None:
|
||||
def main(url: str, output_path: str | None, file_name: str | None) -> None:
|
||||
yt = YouTube(url)
|
||||
stream = yt.streams.get_highest_resolution()
|
||||
|
||||
|
||||
@@ -1,7 +1,9 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import os
|
||||
from typing import Any, Optional, Tuple
|
||||
from typing import Any
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -19,10 +21,10 @@ COLORS = sv.ColorPalette.DEFAULT
|
||||
WINDOW_NAME = "Draw Zones"
|
||||
POLYGONS = [[]]
|
||||
|
||||
current_mouse_position: Optional[Tuple[int, int]] = None
|
||||
current_mouse_position: tuple[int, int] | None = None
|
||||
|
||||
|
||||
def resolve_source(source_path: str) -> Optional[np.ndarray]:
|
||||
def resolve_source(source_path: str) -> np.ndarray | None:
|
||||
if not os.path.exists(source_path):
|
||||
return None
|
||||
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -23,7 +22,7 @@ def main(
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
classes: list[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -23,7 +22,7 @@ def main(
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
classes: list[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
tracker = sv.ByteTrack(minimum_matching_threshold=0.5)
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
import argparse
|
||||
from typing import List
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -19,7 +18,7 @@ LABEL_ANNOTATOR = sv.LabelAnnotator(
|
||||
|
||||
|
||||
class CustomSink:
|
||||
def __init__(self, zone_configuration_path: str, classes: List[int]):
|
||||
def __init__(self, zone_configuration_path: str, classes: list[int]):
|
||||
self.classes = classes
|
||||
self.tracker = sv.ByteTrack(minimum_matching_threshold=0.8)
|
||||
self.fps_monitor = sv.FPSMonitor()
|
||||
@@ -84,7 +83,7 @@ def main(
|
||||
device: str,
|
||||
confidence: float,
|
||||
iou: float,
|
||||
classes: List[int],
|
||||
classes: list[int],
|
||||
) -> None:
|
||||
model = YOLO(weights)
|
||||
|
||||
|
||||
@@ -1,11 +1,11 @@
|
||||
import json
|
||||
from typing import Generator, List
|
||||
from collections.abc import Generator
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
def load_zones_config(file_path: str) -> list[np.ndarray]:
|
||||
"""
|
||||
Load polygon zone configurations from a JSON file.
|
||||
|
||||
@@ -19,12 +19,12 @@ def load_zones_config(file_path: str) -> List[np.ndarray]:
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, each represented as a NumPy array.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
with open(file_path) as file:
|
||||
data = json.load(file)
|
||||
return [np.array(polygon, np.int32) for polygon in data]
|
||||
|
||||
|
||||
def find_in_list(array: np.ndarray, search_list: List[int]) -> np.ndarray:
|
||||
def find_in_list(array: np.ndarray, search_list: list[int]) -> np.ndarray:
|
||||
"""Determines if elements of a numpy array are present in a list.
|
||||
|
||||
Args:
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
from datetime import datetime
|
||||
from typing import Dict
|
||||
|
||||
import numpy as np
|
||||
|
||||
@@ -26,7 +25,7 @@ class FPSBasedTimer:
|
||||
"""
|
||||
self.fps = fps
|
||||
self.frame_id = 0
|
||||
self.tracker_id2frame_id: Dict[int, int] = {}
|
||||
self.tracker_id2frame_id: dict[int, int] = {}
|
||||
|
||||
def tick(self, detections: sv.Detections) -> np.ndarray:
|
||||
"""Processes the current frame, updating time durations for each tracker.
|
||||
@@ -63,7 +62,7 @@ class ClockBasedTimer:
|
||||
|
||||
def __init__(self) -> None:
|
||||
"""Initializes the ClockBasedTimer."""
|
||||
self.tracker_id2start_time: Dict[int, datetime] = {}
|
||||
self.tracker_id2start_time: dict[int, datetime] = {}
|
||||
|
||||
def tick(self, detections: sv.Detections) -> np.ndarray:
|
||||
"""Processes the current frame, updating time durations for each tracker.
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
inference==0.9.17
|
||||
supervision==0.19.0
|
||||
inference
|
||||
supervision
|
||||
tqdm
|
||||
ultralytics<=8.3.40
|
||||
ultralytics
|
||||
|
||||
@@ -1,6 +1,8 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import os
|
||||
from typing import Dict, Iterable, List, Optional, Set
|
||||
from collections.abc import Iterable
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -29,14 +31,14 @@ ZONE_OUT_POLYGONS = [
|
||||
|
||||
class DetectionsManager:
|
||||
def __init__(self) -> None:
|
||||
self.tracker_id_to_zone_id: Dict[int, int] = {}
|
||||
self.counts: Dict[int, Dict[int, Set[int]]] = {}
|
||||
self.tracker_id_to_zone_id: dict[int, int] = {}
|
||||
self.counts: dict[int, dict[int, set[int]]] = {}
|
||||
|
||||
def update(
|
||||
self,
|
||||
detections_all: sv.Detections,
|
||||
detections_in_zones: List[sv.Detections],
|
||||
detections_out_zones: List[sv.Detections],
|
||||
detections_in_zones: list[sv.Detections],
|
||||
detections_out_zones: list[sv.Detections],
|
||||
) -> sv.Detections:
|
||||
for zone_in_id, detections_in_zone in enumerate(detections_in_zones):
|
||||
for tracker_id in detections_in_zone.tracker_id:
|
||||
@@ -59,9 +61,9 @@ class DetectionsManager:
|
||||
|
||||
|
||||
def initiate_polygon_zones(
|
||||
polygons: List[np.ndarray],
|
||||
polygons: list[np.ndarray],
|
||||
triggering_anchors: Iterable[sv.Position] = [sv.Position.CENTER],
|
||||
) -> List[sv.PolygonZone]:
|
||||
) -> list[sv.PolygonZone]:
|
||||
return [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
@@ -77,7 +79,7 @@ class VideoProcessor:
|
||||
roboflow_api_key: str,
|
||||
model_id: str,
|
||||
source_video_path: str,
|
||||
target_video_path: Optional[str] = None,
|
||||
target_video_path: str | None = None,
|
||||
confidence_threshold: float = 0.3,
|
||||
iou_threshold: float = 0.7,
|
||||
) -> None:
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
gdown
|
||||
inference==0.9.17
|
||||
supervision>=0.20.0
|
||||
inference
|
||||
supervision
|
||||
tqdm
|
||||
ultralytics<=8.3.40
|
||||
ultralytics
|
||||
|
||||
@@ -1,5 +1,7 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
from typing import Dict, Iterable, List, Optional, Set
|
||||
from collections.abc import Iterable
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -27,14 +29,14 @@ ZONE_OUT_POLYGONS = [
|
||||
|
||||
class DetectionsManager:
|
||||
def __init__(self) -> None:
|
||||
self.tracker_id_to_zone_id: Dict[int, int] = {}
|
||||
self.counts: Dict[int, Dict[int, Set[int]]] = {}
|
||||
self.tracker_id_to_zone_id: dict[int, int] = {}
|
||||
self.counts: dict[int, dict[int, set[int]]] = {}
|
||||
|
||||
def update(
|
||||
self,
|
||||
detections_all: sv.Detections,
|
||||
detections_in_zones: List[sv.Detections],
|
||||
detections_out_zones: List[sv.Detections],
|
||||
detections_in_zones: list[sv.Detections],
|
||||
detections_out_zones: list[sv.Detections],
|
||||
) -> sv.Detections:
|
||||
for zone_in_id, detections_in_zone in enumerate(detections_in_zones):
|
||||
for tracker_id in detections_in_zone.tracker_id:
|
||||
@@ -57,9 +59,9 @@ class DetectionsManager:
|
||||
|
||||
|
||||
def initiate_polygon_zones(
|
||||
polygons: List[np.ndarray],
|
||||
polygons: list[np.ndarray],
|
||||
triggering_anchors: Iterable[sv.Position] = [sv.Position.CENTER],
|
||||
) -> List[sv.PolygonZone]:
|
||||
) -> list[sv.PolygonZone]:
|
||||
return [
|
||||
sv.PolygonZone(
|
||||
polygon=polygon,
|
||||
@@ -74,7 +76,7 @@ class VideoProcessor:
|
||||
self,
|
||||
source_weights_path: str,
|
||||
source_video_path: str,
|
||||
target_video_path: Optional[str] = None,
|
||||
target_video_path: str | None = None,
|
||||
confidence_threshold: float = 0.3,
|
||||
iou_threshold: float = 0.7,
|
||||
) -> None:
|
||||
|
||||
+16
-22
@@ -3,9 +3,8 @@ site_url: https://supervision.roboflow.com/
|
||||
site_author: Roboflow
|
||||
site_description: A set of easy-to-use utilities that will come in handy in any computer vision project.
|
||||
repo_name: roboflow/supervision
|
||||
repo_url: https://github.com/roboflow/supervision
|
||||
edit_uri: https://github.com/roboflow/supervision/tree/main/docs
|
||||
copyright: Roboflow 2024. All rights reserved.
|
||||
copyright: Roboflow 2025. All rights reserved.
|
||||
|
||||
extra:
|
||||
social:
|
||||
@@ -13,12 +12,8 @@ extra:
|
||||
link: https://github.com/roboflow
|
||||
- icon: fontawesome/brands/python
|
||||
link: https://pypi.org/project/supervision
|
||||
- icon: fontawesome/brands/docker
|
||||
link: https://hub.docker.com/u/roboflow
|
||||
- icon: fontawesome/brands/youtube
|
||||
link: https://www.youtube.com/roboflow
|
||||
- icon: fontawesome/brands/linkedin
|
||||
link: https://www.linkedin.com/company/roboflow-ai/
|
||||
- icon: fontawesome/brands/x-twitter
|
||||
link: https://twitter.com/roboflow
|
||||
- icon: fontawesome/brands/discord
|
||||
@@ -34,7 +29,7 @@ extra_css:
|
||||
- stylesheets/cookbooks-card.css
|
||||
|
||||
nav:
|
||||
- Supervision: index.md
|
||||
- Home: index.md
|
||||
- Learn:
|
||||
- Detect and Annotate: how_to/detect_and_annotate.md
|
||||
- Save Detections: how_to/save_detections.md
|
||||
@@ -43,13 +38,15 @@ nav:
|
||||
- Track Objects on Video: how_to/track_objects.md
|
||||
- Process Datasets: how_to/process_datasets.md
|
||||
- Benchmark a Model: how_to/benchmark_a_model.md
|
||||
|
||||
- Reference - Code API:
|
||||
- Reference:
|
||||
- Detection and Segmentation:
|
||||
- Core: detection/core.md
|
||||
- Annotators: detection/annotators.md
|
||||
- Double Detection Filter: detection/double_detection_filter.md
|
||||
- Utils: detection/utils.md
|
||||
- Converters: detection/utils/converters.md
|
||||
- IoU and NMS: detection/utils/iou_and_nms.md
|
||||
- Boxes: detection/utils/boxes.md
|
||||
- Masks: detection/utils/masks.md
|
||||
- Polygons: detection/utils/polygons.md
|
||||
- Keypoint Detection:
|
||||
- Core: keypoint/core.md
|
||||
- Annotators: keypoint/annotators.md
|
||||
@@ -83,12 +80,7 @@ nav:
|
||||
- Geometry: utils/geometry.md
|
||||
- Assets: assets.md
|
||||
- Cookbooks: cookbooks.md
|
||||
- Cheatsheet: https://roboflow.github.io/cheatsheet-supervision/
|
||||
- Contribute:
|
||||
- Contributing: contributing.md
|
||||
- Code of Conduct: code_of_conduct.md
|
||||
- License: license.md
|
||||
- Release Notes:
|
||||
- Changelog:
|
||||
- Changelog: changelog.md
|
||||
- Deprecated: deprecated.md
|
||||
|
||||
@@ -106,6 +98,7 @@ theme:
|
||||
- content.tooltips
|
||||
- content.code.annotate
|
||||
- navigation.tabs
|
||||
- navigation.tabs.sticky
|
||||
|
||||
palette:
|
||||
# Palette for light mode
|
||||
@@ -123,11 +116,8 @@ theme:
|
||||
name: Switch to light mode
|
||||
|
||||
font:
|
||||
text: Roboto
|
||||
code: Roboto Mono
|
||||
features:
|
||||
- content.code.copy
|
||||
- content.code.annotate
|
||||
text: Inter
|
||||
code: IBM Plex Mono
|
||||
|
||||
plugins:
|
||||
- search
|
||||
@@ -181,12 +171,16 @@ markdown_extensions:
|
||||
anchor_linenums: true
|
||||
line_spans: __span
|
||||
pygments_lang_class: true
|
||||
- pymdownx.arithmatex:
|
||||
generic: true
|
||||
|
||||
extra_javascript:
|
||||
- "javascripts/init_kapa_widget.js"
|
||||
- "javascripts/cookbooks-card.js"
|
||||
- "javascripts/segment.js"
|
||||
- "javascripts/mathjax.js"
|
||||
- "https://cdnjs.cloudflare.com/ajax/libs/dompurify/3.0.8/purify.min.js"
|
||||
- "https://unpkg.com/mathjax@3/es5/tex-mml-chtml.js"
|
||||
|
||||
# Messages shown during document build
|
||||
# Reference: https://www.mkdocs.org/user-guide/configuration/#validation
|
||||
|
||||
+7
-5
@@ -2,9 +2,9 @@
|
||||
name = "supervision"
|
||||
description = "A set of easy-to-use utils that will come in handy in any Computer Vision project"
|
||||
license = { text = "MIT" }
|
||||
version = "0.26.0rc7"
|
||||
version = "0.26.0"
|
||||
readme = "README.md"
|
||||
requires-python = ">=3.8"
|
||||
requires-python = ">=3.9"
|
||||
authors = [
|
||||
{ name = "Piotr Skalski", email = "piotr.skalski92@gmail.com" }
|
||||
]
|
||||
@@ -58,6 +58,8 @@ Documentation = "https://supervision.roboflow.com/latest/"
|
||||
metrics = [
|
||||
"pandas>=2.0.0",
|
||||
]
|
||||
|
||||
[dependency-groups]
|
||||
dev = [
|
||||
"pytest>=7.2.2,<9.0.0",
|
||||
"tox>=4.11.4",
|
||||
@@ -73,7 +75,7 @@ docs = [
|
||||
"mkdocstrings-python>=1.10.9",
|
||||
"mike>=2.0.0",
|
||||
"mkdocs-jupyter>=0.24.3",
|
||||
"mkdocs-git-committers-plugin-2>=2.4.1; python_version >= '3.8' and python_version < '4'",
|
||||
"mkdocs-git-committers-plugin-2>=2.4.1; python_version >= '3.9' and python_version < '4'",
|
||||
"mkdocs-git-revision-date-localized-plugin>=1.2.4"
|
||||
]
|
||||
build = [
|
||||
@@ -91,7 +93,7 @@ check = true
|
||||
imports = ["cv2", "supervision"]
|
||||
|
||||
[tool.ruff]
|
||||
target-version = "py38"
|
||||
target-version = "py39"
|
||||
|
||||
# Exclude a variety of commonly ignored directories.
|
||||
exclude = [
|
||||
@@ -126,7 +128,7 @@ indent-width = 4
|
||||
|
||||
[tool.ruff.lint]
|
||||
# Enable pycodestyle (`E`) and Pyflakes (`F`) codes by default.
|
||||
select = ["E", "F", "I", "A", "Q", "W", "RUF"]
|
||||
select = ["E", "F", "I", "A", "Q", "W", "RUF", "UP"]
|
||||
ignore = []
|
||||
# Allow autofix for all enabled rules (when `--fix`) is provided.
|
||||
fixable = [
|
||||
|
||||
+38
-19
@@ -38,6 +38,7 @@ from supervision.dataset.core import (
|
||||
ClassificationDataset,
|
||||
DetectionDataset,
|
||||
)
|
||||
from supervision.dataset.formats.coco import get_coco_class_index_mapping
|
||||
from supervision.dataset.utils import mask_to_rle, rle_to_mask
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.line_zone import (
|
||||
@@ -45,40 +46,52 @@ from supervision.detection.line_zone import (
|
||||
LineZoneAnnotator,
|
||||
LineZoneAnnotatorMulticlass,
|
||||
)
|
||||
from supervision.detection.overlap_filter import (
|
||||
OverlapFilter,
|
||||
box_non_max_merge,
|
||||
box_non_max_suppression,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.tools.csv_sink import CSVSink
|
||||
from supervision.detection.tools.inference_slicer import InferenceSlicer
|
||||
from supervision.detection.tools.json_sink import JSONSink
|
||||
from supervision.detection.tools.polygon_zone import PolygonZone, PolygonZoneAnnotator
|
||||
from supervision.detection.tools.smoother import DetectionsSmoother
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
calculate_masks_centroids,
|
||||
from supervision.detection.utils.boxes import (
|
||||
clip_boxes,
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
filter_polygons_by_area,
|
||||
mask_iou_batch,
|
||||
denormalize_boxes,
|
||||
move_boxes,
|
||||
pad_boxes,
|
||||
scale_boxes,
|
||||
)
|
||||
from supervision.detection.utils.converters import (
|
||||
mask_to_polygons,
|
||||
mask_to_xyxy,
|
||||
move_boxes,
|
||||
move_masks,
|
||||
oriented_box_iou_batch,
|
||||
pad_boxes,
|
||||
polygon_to_mask,
|
||||
polygon_to_xyxy,
|
||||
scale_boxes,
|
||||
xcycwh_to_xyxy,
|
||||
xywh_to_xyxy,
|
||||
xyxy_to_polygons,
|
||||
xyxy_to_xcycarh,
|
||||
xyxy_to_xywh,
|
||||
)
|
||||
from supervision.detection.utils.iou_and_nms import (
|
||||
OverlapFilter,
|
||||
OverlapMetric,
|
||||
box_iou,
|
||||
box_iou_batch,
|
||||
box_iou_batch_with_jaccard,
|
||||
box_non_max_merge,
|
||||
box_non_max_suppression,
|
||||
mask_iou_batch,
|
||||
mask_non_max_merge,
|
||||
mask_non_max_suppression,
|
||||
oriented_box_iou_batch,
|
||||
)
|
||||
from supervision.detection.utils.masks import (
|
||||
calculate_masks_centroids,
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
move_masks,
|
||||
)
|
||||
from supervision.detection.utils.polygons import (
|
||||
approximate_polygon,
|
||||
filter_polygons_by_area,
|
||||
)
|
||||
from supervision.detection.vlm import LMM, VLM
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import (
|
||||
@@ -163,6 +176,7 @@ __all__ = [
|
||||
"MeanAveragePrecision",
|
||||
"OrientedBoxAnnotator",
|
||||
"OverlapFilter",
|
||||
"OverlapMetric",
|
||||
"PercentageBarAnnotator",
|
||||
"PixelateAnnotator",
|
||||
"Point",
|
||||
@@ -179,7 +193,10 @@ __all__ = [
|
||||
"VertexLabelAnnotator",
|
||||
"VideoInfo",
|
||||
"VideoSink",
|
||||
"approximate_polygon",
|
||||
"box_iou",
|
||||
"box_iou_batch",
|
||||
"box_iou_batch_with_jaccard",
|
||||
"box_non_max_merge",
|
||||
"box_non_max_suppression",
|
||||
"calculate_masks_centroids",
|
||||
@@ -199,11 +216,13 @@ __all__ = [
|
||||
"draw_rectangle",
|
||||
"draw_text",
|
||||
"filter_polygons_by_area",
|
||||
"get_coco_class_index_mapping",
|
||||
"get_polygon_center",
|
||||
"get_video_frames_generator",
|
||||
"letterbox_image",
|
||||
"list_files_with_extensions",
|
||||
"mask_iou_batch",
|
||||
"mask_non_max_merge",
|
||||
"mask_non_max_suppression",
|
||||
"mask_to_polygons",
|
||||
"mask_to_rle",
|
||||
@@ -226,6 +245,6 @@ __all__ = [
|
||||
"xcycwh_to_xyxy",
|
||||
"xywh_to_xyxy",
|
||||
"xyxy_to_polygons",
|
||||
"xyxy_to_xyah",
|
||||
"xyxy_to_xcycarh",
|
||||
"xyxy_to_xywh",
|
||||
]
|
||||
|
||||
+341
-326
File diff suppressed because it is too large
Load Diff
+176
-10
@@ -1,8 +1,11 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import textwrap
|
||||
from enum import Enum
|
||||
from typing import Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.geometry.core import Position
|
||||
@@ -33,7 +36,7 @@ class ColorLookup(Enum):
|
||||
def resolve_color_idx(
|
||||
detections: Detections,
|
||||
detection_idx: int,
|
||||
color_lookup: Union[ColorLookup, np.ndarray] = ColorLookup.CLASS,
|
||||
color_lookup: ColorLookup | np.ndarray = ColorLookup.CLASS,
|
||||
) -> int:
|
||||
if detection_idx >= len(detections):
|
||||
raise ValueError(
|
||||
@@ -70,10 +73,10 @@ def resolve_color_idx(
|
||||
|
||||
|
||||
def resolve_text_background_xyxy(
|
||||
center_coordinates: Tuple[int, int],
|
||||
text_wh: Tuple[int, int],
|
||||
center_coordinates: tuple[int, int],
|
||||
text_wh: tuple[int, int],
|
||||
position: Position,
|
||||
) -> Tuple[int, int, int, int]:
|
||||
) -> tuple[int, int, int, int]:
|
||||
center_x, center_y = center_coordinates
|
||||
text_w, text_h = text_wh
|
||||
|
||||
@@ -122,17 +125,17 @@ def resolve_text_background_xyxy(
|
||||
)
|
||||
|
||||
|
||||
def get_color_by_index(color: Union[Color, ColorPalette], idx: int) -> Color:
|
||||
def get_color_by_index(color: Color | ColorPalette, idx: int) -> Color:
|
||||
if isinstance(color, ColorPalette):
|
||||
return color.by_idx(idx)
|
||||
return color
|
||||
|
||||
|
||||
def resolve_color(
|
||||
color: Union[Color, ColorPalette],
|
||||
color: Color | ColorPalette,
|
||||
detections: Detections,
|
||||
detection_idx: int,
|
||||
color_lookup: Union[ColorLookup, np.ndarray] = ColorLookup.CLASS,
|
||||
color_lookup: ColorLookup | np.ndarray = ColorLookup.CLASS,
|
||||
) -> Color:
|
||||
idx = resolve_color_idx(
|
||||
detections=detections,
|
||||
@@ -144,10 +147,170 @@ def resolve_color(
|
||||
return get_color_by_index(color=color, idx=idx)
|
||||
|
||||
|
||||
def wrap_text(text: str, max_line_length=None) -> list[str]:
|
||||
"""
|
||||
Wraps text to the specified maximum line length, respecting existing newlines.
|
||||
Uses the textwrap library for robust text wrapping.
|
||||
|
||||
Args:
|
||||
text (str): The text to wrap.
|
||||
|
||||
Returns:
|
||||
List[str]: A list of text lines after wrapping.
|
||||
"""
|
||||
|
||||
if not text:
|
||||
return [""]
|
||||
|
||||
if max_line_length is None:
|
||||
return text.splitlines() or [""]
|
||||
|
||||
paragraphs = text.split("\n")
|
||||
all_lines = []
|
||||
|
||||
for paragraph in paragraphs:
|
||||
if not paragraph:
|
||||
# Keep empty lines
|
||||
all_lines.append("")
|
||||
continue
|
||||
|
||||
wrapped = textwrap.wrap(
|
||||
paragraph,
|
||||
width=max_line_length,
|
||||
break_long_words=True,
|
||||
replace_whitespace=False,
|
||||
drop_whitespace=True,
|
||||
)
|
||||
|
||||
if wrapped:
|
||||
all_lines.extend(wrapped)
|
||||
else:
|
||||
all_lines.append("")
|
||||
|
||||
return all_lines if all_lines else [""]
|
||||
|
||||
|
||||
def validate_labels(labels: list[str] | None, detections: Detections):
|
||||
"""
|
||||
Validates that the number of provided labels matches the number of detections.
|
||||
|
||||
Args:
|
||||
labels (Optional[List[str]]): A list of labels, one for each detection. Can
|
||||
be None.
|
||||
detections (Detections): The detections to be labeled.
|
||||
|
||||
Raises:
|
||||
ValueError: If `labels` is not None and its length does not match the number
|
||||
of detections.
|
||||
"""
|
||||
if labels is not None and len(labels) != len(detections):
|
||||
raise ValueError(
|
||||
f"The number of labels ({len(labels)}) does not match the "
|
||||
f"number of detections ({len(detections)}). Each detection "
|
||||
f"should have exactly 1 label."
|
||||
)
|
||||
|
||||
|
||||
def get_labels_text(
|
||||
detections: Detections, custom_labels: list[str] | None
|
||||
) -> list[str]:
|
||||
"""
|
||||
Retrieves the text labels for the detections.
|
||||
|
||||
If `custom_labels` are provided, they are used. Otherwise, the labels are
|
||||
extracted from the `detections` object, prioritizing the 'class_name' field,
|
||||
then the `class_id`, and finally using the detection index as a string.
|
||||
|
||||
Args:
|
||||
detections (Detections): The detections to get labels for.
|
||||
custom_labels (Optional[List[str]]): An optional list of custom labels.
|
||||
|
||||
Returns:
|
||||
List[str]: A list of text labels for each detection.
|
||||
"""
|
||||
if custom_labels is not None:
|
||||
return custom_labels
|
||||
|
||||
labels = []
|
||||
for idx in range(len(detections)):
|
||||
if CLASS_NAME_DATA_FIELD in detections.data:
|
||||
labels.append(detections.data[CLASS_NAME_DATA_FIELD][idx])
|
||||
elif detections.class_id is not None:
|
||||
labels.append(str(detections.class_id[idx]))
|
||||
else:
|
||||
labels.append(str(idx))
|
||||
return labels
|
||||
|
||||
|
||||
def snap_boxes(xyxy: np.ndarray, resolution_wh: tuple[int, int]) -> np.ndarray:
|
||||
"""
|
||||
Shifts `label` bounding boxes into the frame so that they are fully contained
|
||||
within the given resolution, prioritizing the top/left edge.
|
||||
Unlike `clip_boxes`, this function does not crop boxes.
|
||||
It moves them entirely if they exceed the frame boundaries.
|
||||
|
||||
Args:
|
||||
xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each
|
||||
row corresponds to a bounding box in the format
|
||||
`(x_min, y_min, x_max, y_max)`.
|
||||
resolution_wh (Tuple[int, int]): A tuple `(width, height)`
|
||||
representing the resolution of the frame.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` with boxes shifted into frame.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
|
||||
# Example boxes:
|
||||
xyxy = np.array([
|
||||
[-10, 10, 30, 50], # Off left edge
|
||||
[310, 200, 350, 250], # Off right edge
|
||||
[100, -20, 150, 30], # Off top edge
|
||||
[200, 220, 250, 270], # Off bottom edge
|
||||
[-20, 10, 350, 50], # Wider than frame (370 vs 320)
|
||||
[10, -20, 30, 260] # Taller than frame (280 vs 240)
|
||||
])
|
||||
|
||||
resolution_wh = (320, 240)
|
||||
snapped_boxes = snap_boxes(xyxy=xyxy, resolution_wh=resolution_wh)
|
||||
|
||||
# Results:
|
||||
# [[ 0 10 40 50] # Left edge shifted right
|
||||
# [280 200 320 250] # Right edge shifted left
|
||||
# [100 0 150 50] # Top edge shifted down
|
||||
# [200 190 250 240] # Bottom edge shifted up
|
||||
# [ 0 10 370 50] # Wide box aligned to left edge
|
||||
# [ 10 0 30 280]] # Tall box aligned to top edge
|
||||
```
|
||||
"""
|
||||
result = np.copy(xyxy)
|
||||
width, height = resolution_wh
|
||||
|
||||
# X-axis (prioritize left edge)
|
||||
left_overflow = result[:, 0] < 0
|
||||
result[left_overflow, 0:3:2] -= result[left_overflow, 0:1]
|
||||
|
||||
right_overflow = (~left_overflow) & (result[:, 2] > width)
|
||||
right_shift = width - result[right_overflow, 2]
|
||||
result[right_overflow, 0:3:2] += right_shift[:, np.newaxis]
|
||||
|
||||
# Y-axis (prioritize top edge)
|
||||
top_overflow = result[:, 1] < 0
|
||||
result[top_overflow, 1:4:2] -= result[top_overflow, 1:2]
|
||||
|
||||
bottom_overflow = (~top_overflow) & (result[:, 3] > height)
|
||||
bottom_shift = height - result[bottom_overflow, 3]
|
||||
result[bottom_overflow, 1:4:2] += bottom_shift[:, np.newaxis]
|
||||
|
||||
return result
|
||||
|
||||
|
||||
class Trace:
|
||||
def __init__(
|
||||
self,
|
||||
max_size: Optional[int] = None,
|
||||
max_size: int | None = None,
|
||||
start_frame_id: int = 0,
|
||||
anchor: Position = Position.CENTER,
|
||||
) -> None:
|
||||
@@ -163,7 +326,10 @@ class Trace:
|
||||
frame_id = np.full(len(detections), self.current_frame_id, dtype=int)
|
||||
self.frame_id = np.concatenate([self.frame_id, frame_id])
|
||||
self.xy = np.concatenate(
|
||||
[self.xy, detections.get_anchors_coordinates(self.anchor)]
|
||||
[
|
||||
self.xy,
|
||||
detections.get_anchors_coordinates(self.anchor),
|
||||
]
|
||||
)
|
||||
self.tracker_id = np.concatenate([self.tracker_id, detections.tracker_id])
|
||||
|
||||
|
||||
@@ -1,8 +1,9 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from hashlib import new as hash_new
|
||||
from pathlib import Path
|
||||
from shutil import copyfileobj
|
||||
from typing import Union
|
||||
|
||||
from requests import get
|
||||
from tqdm.auto import tqdm
|
||||
@@ -32,7 +33,7 @@ def is_md5_hash_matching(filename: str, original_md5_hash: str) -> bool:
|
||||
return computed_md5_hash.hexdigest() == original_md5_hash
|
||||
|
||||
|
||||
def download_assets(asset_name: Union[VideoAssets, str]) -> str:
|
||||
def download_assets(asset_name: VideoAssets | str) -> str:
|
||||
"""
|
||||
Download a specified asset if it doesn't already exist or is corrupted.
|
||||
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
from enum import Enum
|
||||
from typing import Dict, Tuple
|
||||
|
||||
BASE_VIDEO_URL = "https://media.roboflow.com/supervision/video-examples/"
|
||||
|
||||
@@ -39,7 +38,7 @@ class VideoAssets(Enum):
|
||||
return list(map(lambda c: c.value, cls))
|
||||
|
||||
|
||||
VIDEO_ASSETS: Dict[str, Tuple[str, str]] = {
|
||||
VIDEO_ASSETS: dict[str, tuple[str, str]] = {
|
||||
VideoAssets.VEHICLES.value: (
|
||||
f"{BASE_VIDEO_URL}{VideoAssets.VEHICLES.value}",
|
||||
"8155ff4e4de08cfa25f39de96483f918",
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import Any, Optional, Tuple
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
|
||||
@@ -28,7 +28,7 @@ def _validate_confidence(confidence: Any, n: int) -> None:
|
||||
@dataclass
|
||||
class Classifications:
|
||||
class_id: np.ndarray
|
||||
confidence: Optional[np.ndarray] = None
|
||||
confidence: np.ndarray | None = None
|
||||
|
||||
def __post_init__(self) -> None:
|
||||
"""
|
||||
@@ -154,7 +154,7 @@ class Classifications:
|
||||
class_id = np.arange(len(confidence))
|
||||
return cls(class_id=class_id, confidence=confidence)
|
||||
|
||||
def get_top_k(self, k: int) -> Tuple[np.ndarray, np.ndarray]:
|
||||
def get_top_k(self, k: int) -> tuple[np.ndarray, np.ndarray]:
|
||||
"""
|
||||
Retrieve the top k class IDs and confidences,
|
||||
ordered in descending order by confidence.
|
||||
|
||||
+32
-66
@@ -2,10 +2,10 @@ from __future__ import annotations
|
||||
|
||||
import os
|
||||
from abc import ABC, abstractmethod
|
||||
from collections.abc import Iterator
|
||||
from dataclasses import dataclass
|
||||
from itertools import chain
|
||||
from pathlib import Path
|
||||
from typing import Dict, Iterator, List, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -32,7 +32,7 @@ from supervision.dataset.utils import (
|
||||
train_test_split,
|
||||
)
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.utils.internal import deprecated, warn_deprecated
|
||||
from supervision.utils.internal import warn_deprecated
|
||||
from supervision.utils.iterables import find_duplicates
|
||||
|
||||
|
||||
@@ -45,9 +45,9 @@ class BaseDataset(ABC):
|
||||
def split(
|
||||
self,
|
||||
split_ratio: float = 0.8,
|
||||
random_state: Optional[int] = None,
|
||||
random_state: int | None = None,
|
||||
shuffle: bool = True,
|
||||
) -> Tuple[BaseDataset, BaseDataset]:
|
||||
) -> tuple[BaseDataset, BaseDataset]:
|
||||
pass
|
||||
|
||||
|
||||
@@ -71,9 +71,9 @@ class DetectionDataset(BaseDataset):
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
classes: List[str],
|
||||
images: Union[List[str], Dict[str, np.ndarray]],
|
||||
annotations: Dict[str, Detections],
|
||||
classes: list[str],
|
||||
images: list[str] | dict[str, np.ndarray],
|
||||
annotations: dict[str, Detections],
|
||||
) -> None:
|
||||
self.classes = classes
|
||||
|
||||
@@ -86,40 +86,7 @@ class DetectionDataset(BaseDataset):
|
||||
# Eliminate duplicates while preserving order
|
||||
self.image_paths = list(dict.fromkeys(images))
|
||||
|
||||
self._images_in_memory: Dict[str, np.ndarray] = {}
|
||||
if isinstance(images, dict):
|
||||
self._images_in_memory = images
|
||||
warn_deprecated(
|
||||
"Passing a `Dict[str, np.ndarray]` into `DetectionDataset` is "
|
||||
"deprecated and will be removed in `supervision-0.26.0`. Use "
|
||||
"a list of paths `List[str]` instead."
|
||||
)
|
||||
# TODO: when supervision-0.26.0 is released, and Dict[str, np.ndarray]
|
||||
# for images is no longer supported, also simplify the rest of
|
||||
# the code. E.g. list(images) is no longer needed, and merge can
|
||||
# be simplified.
|
||||
|
||||
@property
|
||||
@deprecated(
|
||||
"`DetectionDataset.images` property is deprecated and will be removed in "
|
||||
"`supervision-0.26.0`. Iterate with `for path, image, annotation in dataset:` "
|
||||
"instead."
|
||||
)
|
||||
def images(self) -> Dict[str, np.ndarray]:
|
||||
"""
|
||||
Load all images to memory and return them as a dictionary.
|
||||
|
||||
!!! warning
|
||||
|
||||
Only use this when you need all images at once.
|
||||
It is much more memory-efficient to initialize dataset with
|
||||
image paths and use `for path, image, annotation in dataset:`.
|
||||
"""
|
||||
if self._images_in_memory:
|
||||
return self._images_in_memory
|
||||
|
||||
images = {image_path: cv2.imread(image_path) for image_path in self.image_paths}
|
||||
return images
|
||||
self._images_in_memory: dict[str, np.ndarray] = {}
|
||||
|
||||
def _get_image(self, image_path: str) -> np.ndarray:
|
||||
"""Assumes that image is in dataset"""
|
||||
@@ -130,7 +97,7 @@ class DetectionDataset(BaseDataset):
|
||||
def __len__(self) -> int:
|
||||
return len(self._images_in_memory) or len(self.image_paths)
|
||||
|
||||
def __getitem__(self, i: int) -> Tuple[str, np.ndarray, Detections]:
|
||||
def __getitem__(self, i: int) -> tuple[str, np.ndarray, Detections]:
|
||||
"""
|
||||
Returns:
|
||||
Tuple[str, np.ndarray, Detections]: The image path, image data,
|
||||
@@ -141,7 +108,7 @@ class DetectionDataset(BaseDataset):
|
||||
annotation = self.annotations[image_path]
|
||||
return image_path, image, annotation
|
||||
|
||||
def __iter__(self) -> Iterator[Tuple[str, np.ndarray, Detections]]:
|
||||
def __iter__(self) -> Iterator[tuple[str, np.ndarray, Detections]]:
|
||||
"""
|
||||
Iterate over the images and annotations in the dataset.
|
||||
|
||||
@@ -179,9 +146,9 @@ class DetectionDataset(BaseDataset):
|
||||
def split(
|
||||
self,
|
||||
split_ratio: float = 0.8,
|
||||
random_state: Optional[int] = None,
|
||||
random_state: int | None = None,
|
||||
shuffle: bool = True,
|
||||
) -> Tuple[DetectionDataset, DetectionDataset]:
|
||||
) -> tuple[DetectionDataset, DetectionDataset]:
|
||||
"""
|
||||
Splits the dataset into two parts (training and testing)
|
||||
using the provided split_ratio.
|
||||
@@ -215,8 +182,8 @@ class DetectionDataset(BaseDataset):
|
||||
shuffle=shuffle,
|
||||
)
|
||||
|
||||
train_input: Union[List[str], Dict[str, np.ndarray]]
|
||||
test_input: Union[List[str], Dict[str, np.ndarray]]
|
||||
train_input: list[str] | dict[str, np.ndarray]
|
||||
test_input: list[str] | dict[str, np.ndarray]
|
||||
if self._images_in_memory:
|
||||
train_input = {path: self._images_in_memory[path] for path in train_paths}
|
||||
test_input = {path: self._images_in_memory[path] for path in test_paths}
|
||||
@@ -239,7 +206,7 @@ class DetectionDataset(BaseDataset):
|
||||
return train_dataset, test_dataset
|
||||
|
||||
@classmethod
|
||||
def merge(cls, dataset_list: List[DetectionDataset]) -> DetectionDataset:
|
||||
def merge(cls, dataset_list: list[DetectionDataset]) -> DetectionDataset:
|
||||
"""
|
||||
Merge a list of `DetectionDataset` objects into a single
|
||||
`DetectionDataset` object.
|
||||
@@ -333,8 +300,8 @@ class DetectionDataset(BaseDataset):
|
||||
|
||||
def as_pascal_voc(
|
||||
self,
|
||||
images_directory_path: Optional[str] = None,
|
||||
annotations_directory_path: Optional[str] = None,
|
||||
images_directory_path: str | None = None,
|
||||
annotations_directory_path: str | None = None,
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.0,
|
||||
@@ -507,9 +474,9 @@ class DetectionDataset(BaseDataset):
|
||||
|
||||
def as_yolo(
|
||||
self,
|
||||
images_directory_path: Optional[str] = None,
|
||||
annotations_directory_path: Optional[str] = None,
|
||||
data_yaml_path: Optional[str] = None,
|
||||
images_directory_path: str | None = None,
|
||||
annotations_directory_path: str | None = None,
|
||||
data_yaml_path: str | None = None,
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.0,
|
||||
@@ -574,7 +541,6 @@ class DetectionDataset(BaseDataset):
|
||||
force_masks (bool): If True,
|
||||
forces masks to be loaded for all annotations,
|
||||
regardless of whether they are present.
|
||||
|
||||
Returns:
|
||||
DetectionDataset: A DetectionDataset instance containing
|
||||
the loaded images and annotations.
|
||||
@@ -609,8 +575,8 @@ class DetectionDataset(BaseDataset):
|
||||
|
||||
def as_coco(
|
||||
self,
|
||||
images_directory_path: Optional[str] = None,
|
||||
annotations_path: Optional[str] = None,
|
||||
images_directory_path: str | None = None,
|
||||
annotations_path: str | None = None,
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.0,
|
||||
@@ -681,9 +647,9 @@ class ClassificationDataset(BaseDataset):
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
classes: List[str],
|
||||
images: Union[List[str], Dict[str, np.ndarray]],
|
||||
annotations: Dict[str, Classifications],
|
||||
classes: list[str],
|
||||
images: list[str] | dict[str, np.ndarray],
|
||||
annotations: dict[str, Classifications],
|
||||
) -> None:
|
||||
self.classes = classes
|
||||
|
||||
@@ -696,7 +662,7 @@ class ClassificationDataset(BaseDataset):
|
||||
# Eliminate duplicates while preserving order
|
||||
self.image_paths = list(dict.fromkeys(images))
|
||||
|
||||
self._images_in_memory: Dict[str, np.ndarray] = {}
|
||||
self._images_in_memory: dict[str, np.ndarray] = {}
|
||||
if isinstance(images, dict):
|
||||
self._images_in_memory = images
|
||||
warn_deprecated(
|
||||
@@ -714,7 +680,7 @@ class ClassificationDataset(BaseDataset):
|
||||
def __len__(self) -> int:
|
||||
return len(self._images_in_memory) or len(self.image_paths)
|
||||
|
||||
def __getitem__(self, i: int) -> Tuple[str, np.ndarray, Classifications]:
|
||||
def __getitem__(self, i: int) -> tuple[str, np.ndarray, Classifications]:
|
||||
"""
|
||||
Returns:
|
||||
Tuple[str, np.ndarray, Classifications]: The image path, image data,
|
||||
@@ -725,7 +691,7 @@ class ClassificationDataset(BaseDataset):
|
||||
annotation = self.annotations[image_path]
|
||||
return image_path, image, annotation
|
||||
|
||||
def __iter__(self) -> Iterator[Tuple[str, np.ndarray, Classifications]]:
|
||||
def __iter__(self) -> Iterator[tuple[str, np.ndarray, Classifications]]:
|
||||
"""
|
||||
Iterate over the images and annotations in the dataset.
|
||||
|
||||
@@ -763,9 +729,9 @@ class ClassificationDataset(BaseDataset):
|
||||
def split(
|
||||
self,
|
||||
split_ratio: float = 0.8,
|
||||
random_state: Optional[int] = None,
|
||||
random_state: int | None = None,
|
||||
shuffle: bool = True,
|
||||
) -> Tuple[ClassificationDataset, ClassificationDataset]:
|
||||
) -> tuple[ClassificationDataset, ClassificationDataset]:
|
||||
"""
|
||||
Splits the dataset into two parts (training and testing)
|
||||
using the provided split_ratio.
|
||||
@@ -798,8 +764,8 @@ class ClassificationDataset(BaseDataset):
|
||||
shuffle=shuffle,
|
||||
)
|
||||
|
||||
train_input: Union[List[str], Dict[str, np.ndarray]]
|
||||
test_input: Union[List[str], Dict[str, np.ndarray]]
|
||||
train_input: list[str] | dict[str, np.ndarray]
|
||||
test_input: list[str] | dict[str, np.ndarray]
|
||||
if self._images_in_memory:
|
||||
train_input = {path: self._images_in_memory[path] for path in train_paths}
|
||||
test_input = {path: self._images_in_memory[path] for path in test_paths}
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
import os
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
from typing import TYPE_CHECKING, Dict, List, Tuple
|
||||
from typing import TYPE_CHECKING
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
@@ -13,18 +13,15 @@ from supervision.dataset.utils import (
|
||||
rle_to_mask,
|
||||
)
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
contains_holes,
|
||||
contains_multiple_segments,
|
||||
polygon_to_mask,
|
||||
)
|
||||
from supervision.detection.utils.converters import polygon_to_mask
|
||||
from supervision.detection.utils.masks import contains_holes, contains_multiple_segments
|
||||
from supervision.utils.file import read_json_file, save_json_file
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from supervision.dataset.core import DetectionDataset
|
||||
|
||||
|
||||
def coco_categories_to_classes(coco_categories: List[dict]) -> List[str]:
|
||||
def coco_categories_to_classes(coco_categories: list[dict]) -> list[str]:
|
||||
return [
|
||||
category["name"]
|
||||
for category in sorted(coco_categories, key=lambda category: category["id"])
|
||||
@@ -32,8 +29,8 @@ def coco_categories_to_classes(coco_categories: List[dict]) -> List[str]:
|
||||
|
||||
|
||||
def build_coco_class_index_mapping(
|
||||
coco_categories: List[dict], target_classes: List[str]
|
||||
) -> Dict[int, int]:
|
||||
coco_categories: list[dict], target_classes: list[str]
|
||||
) -> dict[int, int]:
|
||||
source_class_to_index = {
|
||||
category["name"]: category["id"] for category in coco_categories
|
||||
}
|
||||
@@ -43,7 +40,7 @@ def build_coco_class_index_mapping(
|
||||
}
|
||||
|
||||
|
||||
def classes_to_coco_categories(classes: List[str]) -> List[dict]:
|
||||
def classes_to_coco_categories(classes: list[str]) -> list[dict]:
|
||||
return [
|
||||
{
|
||||
"id": class_id,
|
||||
@@ -55,8 +52,8 @@ def classes_to_coco_categories(classes: List[str]) -> List[dict]:
|
||||
|
||||
|
||||
def group_coco_annotations_by_image_id(
|
||||
coco_annotations: List[dict],
|
||||
) -> Dict[int, List[dict]]:
|
||||
coco_annotations: list[dict],
|
||||
) -> dict[int, list[dict]]:
|
||||
annotations = {}
|
||||
for annotation in coco_annotations:
|
||||
image_id = annotation["image_id"]
|
||||
@@ -67,7 +64,7 @@ def group_coco_annotations_by_image_id(
|
||||
|
||||
|
||||
def coco_annotations_to_masks(
|
||||
image_annotations: List[dict], resolution_wh: Tuple[int, int]
|
||||
image_annotations: list[dict], resolution_wh: tuple[int, int]
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
return np.array(
|
||||
[
|
||||
@@ -90,7 +87,10 @@ def coco_annotations_to_masks(
|
||||
|
||||
|
||||
def coco_annotations_to_detections(
|
||||
image_annotations: List[dict], resolution_wh: Tuple[int, int], with_masks: bool
|
||||
image_annotations: list[dict],
|
||||
resolution_wh: tuple[int, int],
|
||||
with_masks: bool,
|
||||
use_iscrowd: bool = True,
|
||||
) -> Detections:
|
||||
if not image_annotations:
|
||||
return Detections.empty()
|
||||
@@ -102,15 +102,26 @@ def coco_annotations_to_detections(
|
||||
xyxy = np.asarray(xyxy)
|
||||
xyxy[:, 2:4] += xyxy[:, 0:2]
|
||||
|
||||
data = dict()
|
||||
if use_iscrowd:
|
||||
iscrowd = [
|
||||
image_annotation["iscrowd"] for image_annotation in image_annotations
|
||||
]
|
||||
area = [image_annotation["area"] for image_annotation in image_annotations]
|
||||
data = dict(
|
||||
iscrowd=np.asarray(iscrowd, dtype=int), area=np.asarray(area, dtype=float)
|
||||
)
|
||||
|
||||
if with_masks:
|
||||
mask = coco_annotations_to_masks(
|
||||
image_annotations=image_annotations, resolution_wh=resolution_wh
|
||||
)
|
||||
return Detections(
|
||||
class_id=np.asarray(class_ids, dtype=int), xyxy=xyxy, mask=mask
|
||||
)
|
||||
else:
|
||||
mask = None
|
||||
|
||||
return Detections(xyxy=xyxy, class_id=np.asarray(class_ids, dtype=int))
|
||||
return Detections(
|
||||
class_id=np.asarray(class_ids, dtype=int), xyxy=xyxy, mask=mask, data=data
|
||||
)
|
||||
|
||||
|
||||
def detections_to_coco_annotations(
|
||||
@@ -120,7 +131,7 @@ def detections_to_coco_annotations(
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> Tuple[List[Dict], int]:
|
||||
) -> tuple[list[dict], int]:
|
||||
coco_annotations = []
|
||||
for xyxy, mask, _, class_id, _, _ in detections:
|
||||
box_width, box_height = xyxy[2] - xyxy[0], xyxy[3] - xyxy[1]
|
||||
@@ -159,16 +170,58 @@ def detections_to_coco_annotations(
|
||||
return coco_annotations, annotation_id
|
||||
|
||||
|
||||
def get_coco_class_index_mapping(annotations_path: str) -> dict[int, int]:
|
||||
"""
|
||||
Generates a mapping from sequential class indices to original COCO class ids.
|
||||
|
||||
This function is essential when working with models that expect class ids to be
|
||||
zero-indexed and sequential (0 to 79), as opposed to the original COCO
|
||||
dataset where category ids are non-contiguous ranging from 1 to 90 but skipping some
|
||||
ids.
|
||||
|
||||
Use Cases:
|
||||
- Evaluating models trained with COCO-style annotations where class ids
|
||||
are sequential ranging from 0 to 79.
|
||||
- Ensuring consistent class indexing across training, inference and evaluation,
|
||||
when using different tools or datasets with COCO format.
|
||||
- Reproducing results from models that assume sequential class ids (0 to 79).
|
||||
|
||||
How it Works:
|
||||
- Reads the COCO annotation file in its original format (`annotations_path`).
|
||||
- Extracts and sorts all class names by their original COCO id (1 to 90).
|
||||
- Builds a mapping from COCO class ids (not sequential with skipped ids) to
|
||||
new class ids (sequential ranging from 0 to 79).
|
||||
- Returns a dictionary mapping: `{new_class_id: original_COCO_class_id}`.
|
||||
|
||||
Args:
|
||||
annotations_path (str): Path to COCO JSON annotations file
|
||||
(e.g., `instances_val2017.json`).
|
||||
|
||||
Returns:
|
||||
Dict[int, int]: A mapping from new class id (sequential ranging from 0 to 79)
|
||||
to original COCO class id (1 to 90 with skipped ids).
|
||||
"""
|
||||
coco_data = read_json_file(annotations_path)
|
||||
classes = coco_categories_to_classes(coco_categories=coco_data["categories"])
|
||||
class_mapping = build_coco_class_index_mapping(
|
||||
coco_categories=coco_data["categories"], target_classes=classes
|
||||
)
|
||||
return {v: k for k, v in class_mapping.items()}
|
||||
|
||||
|
||||
def load_coco_annotations(
|
||||
images_directory_path: str,
|
||||
annotations_path: str,
|
||||
force_masks: bool = False,
|
||||
) -> Tuple[List[str], List[str], Dict[str, Detections]]:
|
||||
use_iscrowd: bool = True,
|
||||
) -> tuple[list[str], list[str], dict[str, Detections]]:
|
||||
coco_data = read_json_file(file_path=annotations_path)
|
||||
classes = coco_categories_to_classes(coco_categories=coco_data["categories"])
|
||||
|
||||
class_index_mapping = build_coco_class_index_mapping(
|
||||
coco_categories=coco_data["categories"], target_classes=classes
|
||||
)
|
||||
|
||||
coco_images = coco_data["images"]
|
||||
coco_annotations_groups = group_coco_annotations_by_image_id(
|
||||
coco_annotations=coco_data["annotations"]
|
||||
@@ -190,7 +243,9 @@ def load_coco_annotations(
|
||||
image_annotations=image_annotations,
|
||||
resolution_wh=(image_width, image_height),
|
||||
with_masks=force_masks,
|
||||
use_iscrowd=use_iscrowd,
|
||||
)
|
||||
|
||||
annotation = map_detections_class_id(
|
||||
source_to_target_mapping=class_index_mapping,
|
||||
detections=annotation,
|
||||
|
||||
@@ -1,6 +1,7 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from pathlib import Path
|
||||
from typing import Dict, List, Optional, Tuple
|
||||
from xml.etree.ElementTree import Element, SubElement
|
||||
|
||||
import cv2
|
||||
@@ -10,12 +11,12 @@ from defusedxml.minidom import parseString
|
||||
|
||||
from supervision.dataset.utils import approximate_mask_with_polygons
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.detection.utils.converters import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.utils.file import list_files_with_extensions
|
||||
|
||||
|
||||
def object_to_pascal_voc(
|
||||
xyxy: np.ndarray, name: str, polygon: Optional[np.ndarray] = None
|
||||
xyxy: np.ndarray, name: str, polygon: np.ndarray | None = None
|
||||
) -> Element:
|
||||
root = Element("object")
|
||||
|
||||
@@ -51,9 +52,9 @@ def object_to_pascal_voc(
|
||||
|
||||
def detections_to_pascal_voc(
|
||||
detections: Detections,
|
||||
classes: List[str],
|
||||
classes: list[str],
|
||||
filename: str,
|
||||
image_shape: Tuple[int, int, int],
|
||||
image_shape: tuple[int, int, int],
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
@@ -138,7 +139,7 @@ def load_pascal_voc_annotations(
|
||||
images_directory_path: str,
|
||||
annotations_directory_path: str,
|
||||
force_masks: bool = False,
|
||||
) -> Tuple[List[str], List[str], Dict[str, Detections]]:
|
||||
) -> tuple[list[str], list[str], dict[str, Detections]]:
|
||||
"""
|
||||
Loads PASCAL VOC XML annotations and returns the image name,
|
||||
a Detections instance, and a list of class names.
|
||||
@@ -163,7 +164,7 @@ def load_pascal_voc_annotations(
|
||||
)
|
||||
]
|
||||
|
||||
classes: List[str] = []
|
||||
classes: list[str] = []
|
||||
annotations = {}
|
||||
|
||||
for image_path in image_paths:
|
||||
@@ -187,8 +188,8 @@ def load_pascal_voc_annotations(
|
||||
|
||||
|
||||
def detections_from_xml_obj(
|
||||
root: Element, classes: List[str], resolution_wh, force_masks: bool = False
|
||||
) -> Tuple[Detections, List[str]]:
|
||||
root: Element, classes: list[str], resolution_wh, force_masks: bool = False
|
||||
) -> tuple[Detections, list[str]]:
|
||||
"""
|
||||
Converts an XML object in Pascal VOC format to a Detections object.
|
||||
Expected XML format:
|
||||
|
||||
@@ -1,6 +1,8 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from pathlib import Path
|
||||
from typing import TYPE_CHECKING, Dict, List, Optional, Tuple
|
||||
from typing import TYPE_CHECKING
|
||||
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
@@ -8,7 +10,7 @@ from PIL import Image
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.dataset.utils import approximate_mask_with_polygons
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.detection.utils.converters import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.utils.file import (
|
||||
list_files_with_extensions,
|
||||
read_txt_file,
|
||||
@@ -21,7 +23,7 @@ if TYPE_CHECKING:
|
||||
from supervision.dataset.core import DetectionDataset
|
||||
|
||||
|
||||
def _parse_box(values: List[str]) -> np.ndarray:
|
||||
def _parse_box(values: list[str]) -> np.ndarray:
|
||||
x_center, y_center, width, height = values
|
||||
return np.array(
|
||||
[
|
||||
@@ -40,12 +42,12 @@ def _box_to_polygon(box: np.ndarray) -> np.ndarray:
|
||||
)
|
||||
|
||||
|
||||
def _parse_polygon(values: List[str]) -> np.ndarray:
|
||||
def _parse_polygon(values: list[str]) -> np.ndarray:
|
||||
return np.array(values, dtype=np.float32).reshape(-1, 2)
|
||||
|
||||
|
||||
def _polygons_to_masks(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
polygons: list[np.ndarray], resolution_wh: tuple[int, int]
|
||||
) -> np.ndarray:
|
||||
return np.array(
|
||||
[
|
||||
@@ -56,11 +58,11 @@ def _polygons_to_masks(
|
||||
)
|
||||
|
||||
|
||||
def _with_mask(lines: List[str]) -> bool:
|
||||
def _with_mask(lines: list[str]) -> bool:
|
||||
return any([len(line.split()) > 5 for line in lines])
|
||||
|
||||
|
||||
def _extract_class_names(file_path: str) -> List[str]:
|
||||
def _extract_class_names(file_path: str) -> list[str]:
|
||||
data = read_yaml_file(file_path=file_path)
|
||||
names = data["names"]
|
||||
if isinstance(names, dict):
|
||||
@@ -74,8 +76,8 @@ def _image_name_to_annotation_name(image_name: str) -> str:
|
||||
|
||||
|
||||
def yolo_annotations_to_detections(
|
||||
lines: List[str],
|
||||
resolution_wh: Tuple[int, int],
|
||||
lines: list[str],
|
||||
resolution_wh: tuple[int, int],
|
||||
with_masks: bool,
|
||||
is_obb: bool = False,
|
||||
) -> Detections:
|
||||
@@ -127,7 +129,7 @@ def load_yolo_annotations(
|
||||
data_yaml_path: str,
|
||||
force_masks: bool = False,
|
||||
is_obb: bool = False,
|
||||
) -> Tuple[List[str], List[str], Dict[str, Detections]]:
|
||||
) -> tuple[list[str], list[str], dict[str, Detections]]:
|
||||
"""
|
||||
Loads YOLO annotations and returns class names, images,
|
||||
and their corresponding detections.
|
||||
@@ -204,8 +206,8 @@ def load_yolo_annotations(
|
||||
def object_to_yolo(
|
||||
xyxy: np.ndarray,
|
||||
class_id: int,
|
||||
image_shape: Tuple[int, int, int],
|
||||
polygon: Optional[np.ndarray] = None,
|
||||
image_shape: tuple[int, int, int],
|
||||
polygon: np.ndarray | None = None,
|
||||
) -> str:
|
||||
h, w, _ = image_shape
|
||||
if polygon is None:
|
||||
@@ -225,11 +227,11 @@ def object_to_yolo(
|
||||
|
||||
def detections_to_yolo_annotations(
|
||||
detections: Detections,
|
||||
image_shape: Tuple[int, int, int],
|
||||
image_shape: tuple[int, int, int],
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> List[str]:
|
||||
) -> list[str]:
|
||||
annotation = []
|
||||
for xyxy, mask, _, class_id, _, _ in detections:
|
||||
if class_id is None:
|
||||
@@ -260,7 +262,7 @@ def detections_to_yolo_annotations(
|
||||
|
||||
|
||||
def save_yolo_annotations(
|
||||
dataset: "DetectionDataset",
|
||||
dataset: DetectionDataset,
|
||||
annotations_directory_path: str,
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
@@ -283,7 +285,7 @@ def save_yolo_annotations(
|
||||
save_text_file(lines=lines, file_path=yolo_annotations_path)
|
||||
|
||||
|
||||
def save_data_yaml(data_yaml_path: str, classes: List[str]) -> None:
|
||||
def save_data_yaml(data_yaml_path: str, classes: list[str]) -> None:
|
||||
data = {"nc": len(classes), "names": classes}
|
||||
Path(data_yaml_path).parent.mkdir(parents=True, exist_ok=True)
|
||||
save_yaml_file(data=data, file_path=data_yaml_path)
|
||||
|
||||
@@ -1,19 +1,21 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import copy
|
||||
import os
|
||||
import random
|
||||
import shutil
|
||||
from pathlib import Path
|
||||
from typing import TYPE_CHECKING, Dict, List, Optional, Tuple, TypeVar, Union
|
||||
from typing import TYPE_CHECKING, TypeVar
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
from supervision.detection.utils.converters import mask_to_polygons
|
||||
from supervision.detection.utils.polygons import (
|
||||
approximate_polygon,
|
||||
filter_polygons_by_area,
|
||||
mask_to_polygons,
|
||||
)
|
||||
|
||||
if TYPE_CHECKING:
|
||||
@@ -27,7 +29,7 @@ def approximate_mask_with_polygons(
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> List[np.ndarray]:
|
||||
) -> list[np.ndarray]:
|
||||
height, width = mask.shape
|
||||
image_area = height * width
|
||||
minimum_detection_area = min_image_area_percentage * image_area
|
||||
@@ -50,7 +52,7 @@ def approximate_mask_with_polygons(
|
||||
]
|
||||
|
||||
|
||||
def merge_class_lists(class_lists: List[List[str]]) -> List[str]:
|
||||
def merge_class_lists(class_lists: list[list[str]]) -> list[str]:
|
||||
unique_classes = set()
|
||||
|
||||
for class_list in class_lists:
|
||||
@@ -61,8 +63,8 @@ def merge_class_lists(class_lists: List[List[str]]) -> List[str]:
|
||||
|
||||
|
||||
def build_class_index_mapping(
|
||||
source_classes: List[str], target_classes: List[str]
|
||||
) -> Dict[int, int]:
|
||||
source_classes: list[str], target_classes: list[str]
|
||||
) -> dict[int, int]:
|
||||
"""Returns the index map of source classes -> target classes."""
|
||||
index_mapping = {}
|
||||
|
||||
@@ -79,7 +81,7 @@ def build_class_index_mapping(
|
||||
|
||||
|
||||
def map_detections_class_id(
|
||||
source_to_target_mapping: Dict[int, int], detections: Detections
|
||||
source_to_target_mapping: dict[int, int], detections: Detections
|
||||
) -> Detections:
|
||||
if detections.class_id is None:
|
||||
raise ValueError("Detections must have class_id attribute.")
|
||||
@@ -98,9 +100,7 @@ def map_detections_class_id(
|
||||
return detections_copy
|
||||
|
||||
|
||||
def save_dataset_images(
|
||||
dataset: "DetectionDataset", images_directory_path: str
|
||||
) -> None:
|
||||
def save_dataset_images(dataset: DetectionDataset, images_directory_path: str) -> None:
|
||||
Path(images_directory_path).mkdir(parents=True, exist_ok=True)
|
||||
for image_path in dataset.image_paths:
|
||||
final_path = os.path.join(images_directory_path, Path(image_path).name)
|
||||
@@ -112,11 +112,11 @@ def save_dataset_images(
|
||||
|
||||
|
||||
def train_test_split(
|
||||
data: List[T],
|
||||
data: list[T],
|
||||
train_ratio: float = 0.8,
|
||||
random_state: Optional[int] = None,
|
||||
random_state: int | None = None,
|
||||
shuffle: bool = True,
|
||||
) -> Tuple[List[T], List[T]]:
|
||||
) -> tuple[list[T], list[T]]:
|
||||
"""
|
||||
Splits the data into two parts using the provided train_ratio.
|
||||
|
||||
@@ -140,7 +140,7 @@ def train_test_split(
|
||||
|
||||
|
||||
def rle_to_mask(
|
||||
rle: Union[npt.NDArray[np.int_], List[int]], resolution_wh: Tuple[int, int]
|
||||
rle: npt.NDArray[np.int_] | list[int], resolution_wh: tuple[int, int]
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
"""
|
||||
Converts run-length encoding (RLE) to a binary mask.
|
||||
@@ -195,7 +195,7 @@ def rle_to_mask(
|
||||
return decoded_rle.reshape((height, width), order="F")
|
||||
|
||||
|
||||
def mask_to_rle(mask: npt.NDArray[np.bool_]) -> List[int]:
|
||||
def mask_to_rle(mask: npt.NDArray[np.bool_]) -> list[int]:
|
||||
"""
|
||||
Converts a binary mask into a run-length encoding (RLE).
|
||||
|
||||
|
||||
+699
-51
@@ -1,8 +1,10 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from collections.abc import Iterator
|
||||
from dataclasses import dataclass, field
|
||||
from enum import Enum
|
||||
from typing import Any, Dict, Iterator, List, Optional, Tuple, Union
|
||||
from functools import reduce
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
|
||||
@@ -10,33 +12,38 @@ from supervision.config import (
|
||||
CLASS_NAME_DATA_FIELD,
|
||||
ORIENTED_BOX_COORDINATES,
|
||||
)
|
||||
from supervision.detection.overlap_filter import (
|
||||
box_non_max_merge,
|
||||
box_non_max_suppression,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.tools.transformers import (
|
||||
process_transformers_detection_result,
|
||||
process_transformers_v4_segmentation_result,
|
||||
process_transformers_v5_segmentation_result,
|
||||
)
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
calculate_masks_centroids,
|
||||
from supervision.detection.utils.converters import mask_to_xyxy, xywh_to_xyxy
|
||||
from supervision.detection.utils.internal import (
|
||||
extract_ultralytics_masks,
|
||||
get_data_item,
|
||||
is_data_equal,
|
||||
is_metadata_equal,
|
||||
mask_to_xyxy,
|
||||
merge_data,
|
||||
merge_metadata,
|
||||
process_roboflow_result,
|
||||
xywh_to_xyxy,
|
||||
)
|
||||
from supervision.detection.utils.iou_and_nms import (
|
||||
OverlapMetric,
|
||||
box_iou_batch,
|
||||
box_non_max_merge,
|
||||
box_non_max_suppression,
|
||||
mask_iou_batch,
|
||||
mask_non_max_merge,
|
||||
mask_non_max_suppression,
|
||||
)
|
||||
from supervision.detection.utils.masks import calculate_masks_centroids
|
||||
from supervision.detection.vlm import (
|
||||
LMM,
|
||||
VLM,
|
||||
from_florence_2,
|
||||
from_google_gemini_2_0,
|
||||
from_google_gemini_2_5,
|
||||
from_moondream,
|
||||
from_paligemma,
|
||||
from_qwen_2_5_vl,
|
||||
validate_vlm_parameters,
|
||||
@@ -135,12 +142,12 @@ class Detections:
|
||||
""" # noqa: E501 // docs
|
||||
|
||||
xyxy: np.ndarray
|
||||
mask: Optional[np.ndarray] = None
|
||||
confidence: Optional[np.ndarray] = None
|
||||
class_id: Optional[np.ndarray] = None
|
||||
tracker_id: Optional[np.ndarray] = None
|
||||
data: Dict[str, Union[np.ndarray, List]] = field(default_factory=dict)
|
||||
metadata: Dict[str, Any] = field(default_factory=dict)
|
||||
mask: np.ndarray | None = None
|
||||
confidence: np.ndarray | None = None
|
||||
class_id: np.ndarray | None = None
|
||||
tracker_id: np.ndarray | None = None
|
||||
data: dict[str, np.ndarray | list] = field(default_factory=dict)
|
||||
metadata: dict[str, Any] = field(default_factory=dict)
|
||||
|
||||
def __post_init__(self):
|
||||
validate_detections_fields(
|
||||
@@ -161,13 +168,13 @@ class Detections:
|
||||
def __iter__(
|
||||
self,
|
||||
) -> Iterator[
|
||||
Tuple[
|
||||
tuple[
|
||||
np.ndarray,
|
||||
Optional[np.ndarray],
|
||||
Optional[float],
|
||||
Optional[int],
|
||||
Optional[int],
|
||||
Dict[str, Union[np.ndarray, List]],
|
||||
np.ndarray | None,
|
||||
float | None,
|
||||
int | None,
|
||||
int | None,
|
||||
dict[str, np.ndarray | list],
|
||||
]
|
||||
]:
|
||||
"""
|
||||
@@ -456,7 +463,7 @@ class Detections:
|
||||
|
||||
@classmethod
|
||||
def from_transformers(
|
||||
cls, transformers_results: dict, id2label: Optional[Dict[int, str]] = None
|
||||
cls, transformers_results: dict, id2label: dict[int, str] | None = None
|
||||
) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from object detection or panoptic, semantic
|
||||
@@ -579,7 +586,7 @@ class Detections:
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_inference(cls, roboflow_result: Union[dict, Any]) -> Detections:
|
||||
def from_inference(cls, roboflow_result: dict | Any) -> Detections:
|
||||
"""
|
||||
Create a `sv.Detections` object from the [Roboflow](https://roboflow.com/)
|
||||
API inference result or the [Inference](https://inference.roboflow.com/)
|
||||
@@ -631,7 +638,7 @@ class Detections:
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_sam(cls, sam_result: List[dict]) -> Detections:
|
||||
def from_sam(cls, sam_result: list[dict]) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from
|
||||
[Segment Anything Model](https://github.com/facebookresearch/segment-anything)
|
||||
@@ -674,7 +681,7 @@ class Detections:
|
||||
|
||||
@classmethod
|
||||
def from_azure_analyze_image(
|
||||
cls, azure_result: dict, class_map: Optional[Dict[int, str]] = None
|
||||
cls, azure_result: dict, class_map: dict[int, str] | None = None
|
||||
) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from [Azure Image Analysis 4.0](
|
||||
@@ -806,13 +813,24 @@ class Detections:
|
||||
"`Detections.from_lmm` property is deprecated and will be removed in "
|
||||
"`supervision-0.31.0`. Use Detections.from_vlm instead."
|
||||
)
|
||||
def from_lmm(
|
||||
cls, lmm: Union[LMM, str], result: Union[str, dict], **kwargs: Any
|
||||
) -> Detections:
|
||||
def from_lmm(cls, lmm: LMM | str, result: str | dict, **kwargs: Any) -> Detections:
|
||||
"""
|
||||
!!! deprecated "Deprecated"
|
||||
`Detections.from_lmm` is **deprecated** and will be removed in `supervision-0.31.0`.
|
||||
Please use `Detections.from_vlm` instead.
|
||||
|
||||
Creates a Detections object from the given result string based on the specified
|
||||
Large Multimodal Model (LMM).
|
||||
|
||||
| Name | Enum (sv.LMM) | Tasks | Required parameters | Optional parameters |
|
||||
|---------------------|----------------------|-------------------------|-----------------------------|---------------------|
|
||||
| PaliGemma | `PALIGEMMA` | detection | `resolution_wh` | `classes` |
|
||||
| PaliGemma 2 | `PALIGEMMA` | detection | `resolution_wh` | `classes` |
|
||||
| Qwen2.5-VL | `QWEN_2_5_VL` | detection | `resolution_wh`, `input_wh` | `classes` |
|
||||
| Google Gemini 2.0 | `GOOGLE_GEMINI_2_0` | detection | `resolution_wh` | `classes` |
|
||||
| Google Gemini 2.5 | `GOOGLE_GEMINI_2_5` | detection, segmentation | `resolution_wh` | `classes` |
|
||||
| Moondream | `MOONDREAM` | detection | `resolution_wh` | |
|
||||
|
||||
Args:
|
||||
lmm (Union[LMM, str]): The type of LMM (Large Multimodal Model) to use.
|
||||
result (str): The result string containing the detection data.
|
||||
@@ -826,8 +844,9 @@ class Detections:
|
||||
disallowed arguments are provided.
|
||||
ValueError: If the specified LMM is not supported.
|
||||
|
||||
Examples:
|
||||
!!! example "PaliGemma"
|
||||
```python
|
||||
|
||||
import supervision as sv
|
||||
|
||||
paligemma_result = "<loc0256><loc0256><loc0768><loc0768> cat"
|
||||
@@ -842,13 +861,271 @@ class Detections:
|
||||
|
||||
detections.class_id
|
||||
# array([0])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['cat'], dtype='<U10')}
|
||||
```
|
||||
"""
|
||||
|
||||
!!! example "Qwen2.5-VL"
|
||||
|
||||
??? tip "Prompt engineering"
|
||||
|
||||
To get the best results from Qwen2.5-VL, use clear and descriptive prompts
|
||||
that specify exactly what you want to detect.
|
||||
|
||||
**For general object detection, use this comprehensive prompt:**
|
||||
|
||||
```
|
||||
Detect all objects in the image and return their locations and labels.
|
||||
```
|
||||
|
||||
**For specific object detection with detailed descriptions:**
|
||||
|
||||
```
|
||||
Detect the red object that is leading in this image and return its location and label.
|
||||
```
|
||||
|
||||
**For simple, targeted detection:**
|
||||
|
||||
```
|
||||
leading blue truck
|
||||
```
|
||||
|
||||
**Additional effective prompts:**
|
||||
|
||||
```
|
||||
Find all people and vehicles in this scene
|
||||
```
|
||||
|
||||
```
|
||||
Locate all animals in the image
|
||||
```
|
||||
|
||||
```
|
||||
Identify traffic signs and their positions
|
||||
```
|
||||
|
||||
**Tips for better results:**
|
||||
|
||||
- Use descriptive language that clearly specifies what to look for
|
||||
- Include color, size, or position descriptors when targeting specific objects
|
||||
- Be specific about the type of objects you want to detect
|
||||
- The model responds well to both detailed instructions and concise phrases
|
||||
- Results are returned in JSON format with `bbox_2d` coordinates and `label` fields
|
||||
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
qwen_2_5_vl_result = \"\"\"```json
|
||||
[
|
||||
{"bbox_2d": [139, 768, 315, 954], "label": "cat"},
|
||||
{"bbox_2d": [366, 679, 536, 849], "label": "dog"}
|
||||
]
|
||||
```\"\"\"
|
||||
detections = sv.Detections.from_lmm(
|
||||
sv.LMM.QWEN_2_5_VL,
|
||||
qwen_2_5_vl_result,
|
||||
input_wh=(1000, 1000),
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog'],
|
||||
)
|
||||
detections.xyxy
|
||||
# array([[139., 768., 315., 954.], [366., 679., 536., 849.]])
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['cat', 'dog'], dtype='<U10')}
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
```
|
||||
|
||||
!!! example "Gemini 2.0"
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
gemini_response_text = \"\"\"```json
|
||||
[
|
||||
{"box_2d": [543, 40, 728, 200], "label": "cat", "id": 1},
|
||||
{"box_2d": [653, 352, 820, 522], "label": "dog", "id": 2}
|
||||
]
|
||||
```\"\"\"
|
||||
|
||||
detections = sv.Detections.from_lmm(
|
||||
sv.LMM.GOOGLE_GEMINI_2_0,
|
||||
gemini_response_text,
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog'],
|
||||
)
|
||||
|
||||
detections.xyxy
|
||||
# array([[543., 40., 728., 200.], [653., 352., 820., 522.]])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['cat', 'dog'], dtype='<U26')}
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
```
|
||||
|
||||
!!! example "Gemini 2.5"
|
||||
|
||||
??? tip "Prompt engineering"
|
||||
|
||||
To get the best results from Google Gemini 2.5, use the following prompt.
|
||||
|
||||
This prompt is designed to detect all visible objects in the image,
|
||||
including small, distant, or partially visible ones, and to return
|
||||
tight bounding boxes.
|
||||
|
||||
```
|
||||
Carefully examine this image and detect ALL visible objects, including
|
||||
small, distant, or partially visible ones.
|
||||
|
||||
IMPORTANT: Focus on finding as many objects as possible, even if you are
|
||||
only moderately confident.
|
||||
|
||||
Make sure each bounding box is as tight as possible.
|
||||
|
||||
Valid object classes: {class_list}
|
||||
|
||||
For each detected object, provide:
|
||||
- "label": the exact class name from the list above
|
||||
- "confidence": your certainty (between 0.0 and 1.0)
|
||||
- "box_2d": the bounding box [ymin, xmin, ymax, xmax] normalized to 0-1000
|
||||
- "mask": the binary mask of the object as a base64-encoded string
|
||||
|
||||
Detect everything that matches the valid classes. Do not be
|
||||
conservative; include objects even with moderate confidence.
|
||||
|
||||
Return a JSON array, for example:
|
||||
[
|
||||
{
|
||||
"label": "person",
|
||||
"confidence": 0.95,
|
||||
"box_2d": [100, 200, 300, 400],
|
||||
"mask": "..."
|
||||
},
|
||||
{
|
||||
"label": "kite",
|
||||
"confidence": 0.80,
|
||||
"box_2d": [50, 150, 250, 350],
|
||||
"mask": "..."
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
When using the google-genai library, it is recommended to set
|
||||
thinking_budget=0 in thinking_config for more direct and faster responses.
|
||||
|
||||
```python
|
||||
from google.generativeai import types
|
||||
|
||||
model.generate_content(
|
||||
...,
|
||||
generation_config=generation_config,
|
||||
safety_settings=safety_settings,
|
||||
thinking_config=types.ThinkingConfig(
|
||||
thinking_budget=0
|
||||
)
|
||||
)
|
||||
```
|
||||
|
||||
For a shorter prompt focused only on segmentation masks, you can use:
|
||||
|
||||
```
|
||||
Return a JSON list of segmentation masks. Each entry should include the
|
||||
2D bounding box in the "box_2d" key, the segmentation mask in the "mask"
|
||||
key, and the text label in the "label" key. Use descriptive labels.
|
||||
```
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
gemini_response_text = \"\"\"```json
|
||||
[
|
||||
{"box_2d": [543, 40, 728, 200], "label": "cat", "id": 1},
|
||||
{"box_2d": [653, 352, 820, 522], "label": "dog", "id": 2}
|
||||
]
|
||||
```\"\"\"
|
||||
|
||||
detections = sv.Detections.from_lmm(
|
||||
sv.LMM.GOOGLE_GEMINI_2_5,
|
||||
gemini_response_text,
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog'],
|
||||
)
|
||||
|
||||
detections.xyxy
|
||||
# array([[543., 40., 728., 200.], [653., 352., 820., 522.]])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['cat', 'dog'], dtype='<U26')}
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
```
|
||||
|
||||
!!! example "Moondream"
|
||||
|
||||
|
||||
??? tip "Prompt engineering"
|
||||
|
||||
To get the best results from Moondream, use optimized prompts that leverage
|
||||
its object detection capabilities effectively.
|
||||
|
||||
**For general object detection, use this simple prompt:**
|
||||
|
||||
```
|
||||
objects
|
||||
```
|
||||
|
||||
This single-word prompt instructs Moondream to detect all visible objects
|
||||
and return them in the proper JSON format with normalized coordinates.
|
||||
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
moondream_result = {
|
||||
'objects': [
|
||||
{
|
||||
'x_min': 0.5704046934843063,
|
||||
'y_min': 0.20069346576929092,
|
||||
'x_max': 0.7049859315156937,
|
||||
'y_max': 0.3012596592307091
|
||||
},
|
||||
{
|
||||
'x_min': 0.6210969910025597,
|
||||
'y_min': 0.3300672620534897,
|
||||
'x_max': 0.8417936339974403,
|
||||
'y_max': 0.4961046129465103
|
||||
}
|
||||
]
|
||||
}
|
||||
|
||||
detections = sv.Detections.from_lmm(
|
||||
sv.LMM.MOONDREAM,
|
||||
moondream_result,
|
||||
resolution_wh=(1000, 1000),
|
||||
)
|
||||
|
||||
detections.xyxy
|
||||
# array([[1752.28, 818.82, 2165.72, 1229.14],
|
||||
# [1908.01, 1346.67, 2585.99, 2024.11]])
|
||||
```
|
||||
""" # noqa: E501
|
||||
|
||||
# filler logic mapping old from_lmm to new from_vlm
|
||||
lmm_to_vlm = {
|
||||
LMM.PALIGEMMA: VLM.PALIGEMMA,
|
||||
LMM.FLORENCE_2: VLM.FLORENCE_2,
|
||||
LMM.QWEN_2_5_VL: VLM.QWEN_2_5_VL,
|
||||
LMM.GOOGLE_GEMINI_2_0: VLM.GOOGLE_GEMINI_2_0,
|
||||
LMM.GOOGLE_GEMINI_2_5: VLM.GOOGLE_GEMINI_2_5,
|
||||
}
|
||||
|
||||
# (this works even if the LMM enum is wrapped by @deprecated)
|
||||
@@ -873,9 +1150,310 @@ class Detections:
|
||||
return cls.from_vlm(vlm=vlm, result=result, **kwargs)
|
||||
|
||||
@classmethod
|
||||
def from_vlm(
|
||||
cls, vlm: Union[VLM, str], result: Union[str, dict], **kwargs: Any
|
||||
) -> Detections:
|
||||
def from_vlm(cls, vlm: VLM | str, result: str | dict, **kwargs: Any) -> Detections:
|
||||
"""
|
||||
|
||||
Creates a Detections object from the given result string based on the specified
|
||||
Vision Language Model (VLM).
|
||||
|
||||
| Name | Enum (sv.VLM) | Tasks | Required parameters | Optional parameters |
|
||||
|---------------------|----------------------|-------------------------|-----------------------------|---------------------|
|
||||
| PaliGemma | `PALIGEMMA` | detection | `resolution_wh` | `classes` |
|
||||
| PaliGemma 2 | `PALIGEMMA` | detection | `resolution_wh` | `classes` |
|
||||
| Qwen2.5-VL | `QWEN_2_5_VL` | detection | `resolution_wh`, `input_wh` | `classes` |
|
||||
| Google Gemini 2.0 | `GOOGLE_GEMINI_2_0` | detection | `resolution_wh` | `classes` |
|
||||
| Google Gemini 2.5 | `GOOGLE_GEMINI_2_5` | detection, segmentation | `resolution_wh` | `classes` |
|
||||
| Moondream | `MOONDREAM` | detection | `resolution_wh` | |
|
||||
|
||||
Args:
|
||||
vlm (Union[VLM, str]): The type of VLM (Vision Language Model) to use.
|
||||
result (str): The result string containing the detection data.
|
||||
**kwargs (Any): Additional keyword arguments required by the specified VLM.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
|
||||
Raises:
|
||||
ValueError: If the VLM is invalid, required arguments are missing, or
|
||||
disallowed arguments are provided.
|
||||
ValueError: If the specified VLM is not supported.
|
||||
|
||||
!!! example "PaliGemma"
|
||||
```python
|
||||
|
||||
import supervision as sv
|
||||
|
||||
paligemma_result = "<loc0256><loc0256><loc0768><loc0768> cat"
|
||||
detections = sv.Detections.from_vlm(
|
||||
sv.VLM.PALIGEMMA,
|
||||
paligemma_result,
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog']
|
||||
)
|
||||
detections.xyxy
|
||||
# array([[250., 250., 750., 750.]])
|
||||
|
||||
detections.class_id
|
||||
# array([0])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['cat'], dtype='<U10')}
|
||||
```
|
||||
|
||||
!!! example "Qwen2.5-VL"
|
||||
|
||||
??? tip "Prompt engineering"
|
||||
|
||||
To get the best results from Qwen2.5-VL, use clear and descriptive prompts
|
||||
that specify exactly what you want to detect.
|
||||
|
||||
**For general object detection, use this comprehensive prompt:**
|
||||
|
||||
```
|
||||
Detect all objects in the image and return their locations and labels.
|
||||
```
|
||||
|
||||
**For specific object detection with detailed descriptions:**
|
||||
|
||||
```
|
||||
Detect the red object that is leading in this image and return its location and label.
|
||||
```
|
||||
|
||||
**For simple, targeted detection:**
|
||||
|
||||
```
|
||||
leading blue truck
|
||||
```
|
||||
|
||||
**Additional effective prompts:**
|
||||
|
||||
```
|
||||
Find all people and vehicles in this scene
|
||||
```
|
||||
|
||||
```
|
||||
Locate all animals in the image
|
||||
```
|
||||
|
||||
```
|
||||
Identify traffic signs and their positions
|
||||
```
|
||||
|
||||
**Tips for better results:**
|
||||
|
||||
- Use descriptive language that clearly specifies what to look for
|
||||
- Include color, size, or position descriptors when targeting specific objects
|
||||
- Be specific about the type of objects you want to detect
|
||||
- The model responds well to both detailed instructions and concise phrases
|
||||
- Results are returned in JSON format with `bbox_2d` coordinates and `label` fields
|
||||
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
qwen_2_5_vl_result = \"\"\"```json
|
||||
[
|
||||
{"bbox_2d": [139, 768, 315, 954], "label": "cat"},
|
||||
{"bbox_2d": [366, 679, 536, 849], "label": "dog"}
|
||||
]
|
||||
```\"\"\"
|
||||
detections = sv.Detections.from_vlm(
|
||||
sv.VLM.QWEN_2_5_VL,
|
||||
qwen_2_5_vl_result,
|
||||
input_wh=(1000, 1000),
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog'],
|
||||
)
|
||||
detections.xyxy
|
||||
# array([[139., 768., 315., 954.], [366., 679., 536., 849.]])
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['cat', 'dog'], dtype='<U10')}
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
```
|
||||
|
||||
!!! example "Gemini 2.0"
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
gemini_response_text = \"\"\"```json
|
||||
[
|
||||
{"box_2d": [543, 40, 728, 200], "label": "cat", "id": 1},
|
||||
{"box_2d": [653, 352, 820, 522], "label": "dog", "id": 2}
|
||||
]
|
||||
```\"\"\"
|
||||
|
||||
detections = sv.Detections.from_vlm(
|
||||
sv.VLM.GOOGLE_GEMINI_2_0,
|
||||
gemini_response_text,
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog'],
|
||||
)
|
||||
|
||||
detections.xyxy
|
||||
# array([[543., 40., 728., 200.], [653., 352., 820., 522.]])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['cat', 'dog'], dtype='<U26')}
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
```
|
||||
|
||||
!!! example "Gemini 2.5"
|
||||
|
||||
??? tip "Prompt engineering"
|
||||
|
||||
To get the best results from Google Gemini 2.5, use the following prompt.
|
||||
|
||||
This prompt is designed to detect all visible objects in the image,
|
||||
including small, distant, or partially visible ones, and to return
|
||||
tight bounding boxes.
|
||||
|
||||
```
|
||||
Carefully examine this image and detect ALL visible objects, including
|
||||
small, distant, or partially visible ones.
|
||||
|
||||
IMPORTANT: Focus on finding as many objects as possible, even if you are
|
||||
only moderately confident.
|
||||
|
||||
Make sure each bounding box is as tight as possible.
|
||||
|
||||
Valid object classes: {class_list}
|
||||
|
||||
For each detected object, provide:
|
||||
- "label": the exact class name from the list above
|
||||
- "confidence": your certainty (between 0.0 and 1.0)
|
||||
- "box_2d": the bounding box [ymin, xmin, ymax, xmax] normalized to 0-1000
|
||||
- "mask": the binary mask of the object as a base64-encoded string
|
||||
|
||||
Detect everything that matches the valid classes. Do not be
|
||||
conservative; include objects even with moderate confidence.
|
||||
|
||||
Return a JSON array, for example:
|
||||
[
|
||||
{
|
||||
"label": "person",
|
||||
"confidence": 0.95,
|
||||
"box_2d": [100, 200, 300, 400],
|
||||
"mask": "..."
|
||||
},
|
||||
{
|
||||
"label": "kite",
|
||||
"confidence": 0.80,
|
||||
"box_2d": [50, 150, 250, 350],
|
||||
"mask": "..."
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
When using the google-genai library, it is recommended to set
|
||||
thinking_budget=0 in thinking_config for more direct and faster responses.
|
||||
|
||||
```python
|
||||
from google.generativeai import types
|
||||
|
||||
model.generate_content(
|
||||
...,
|
||||
generation_config=generation_config,
|
||||
safety_settings=safety_settings,
|
||||
thinking_config=types.ThinkingConfig(
|
||||
thinking_budget=0
|
||||
)
|
||||
)
|
||||
```
|
||||
|
||||
For a shorter prompt focused only on segmentation masks, you can use:
|
||||
|
||||
```
|
||||
Return a JSON list of segmentation masks. Each entry should include the
|
||||
2D bounding box in the "box_2d" key, the segmentation mask in the "mask"
|
||||
key, and the text label in the "label" key. Use descriptive labels.
|
||||
```
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
gemini_response_text = \"\"\"```json
|
||||
[
|
||||
{"box_2d": [543, 40, 728, 200], "label": "cat", "id": 1},
|
||||
{"box_2d": [653, 352, 820, 522], "label": "dog", "id": 2}
|
||||
]
|
||||
```\"\"\"
|
||||
|
||||
detections = sv.Detections.from_vlm(
|
||||
sv.VLM.GOOGLE_GEMINI_2_5,
|
||||
gemini_response_text,
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog'],
|
||||
)
|
||||
|
||||
detections.xyxy
|
||||
# array([[543., 40., 728., 200.], [653., 352., 820., 522.]])
|
||||
|
||||
detections.data
|
||||
# {'class_name': array(['cat', 'dog'], dtype='<U26')}
|
||||
|
||||
detections.class_id
|
||||
# array([0, 1])
|
||||
```
|
||||
|
||||
!!! example "Moondream"
|
||||
|
||||
|
||||
??? tip "Prompt engineering"
|
||||
|
||||
To get the best results from Moondream, use optimized prompts that leverage
|
||||
its object detection capabilities effectively.
|
||||
|
||||
**For general object detection, use this simple prompt:**
|
||||
|
||||
```
|
||||
objects
|
||||
```
|
||||
|
||||
This single-word prompt instructs Moondream to detect all visible objects
|
||||
and return them in the proper JSON format with normalized coordinates.
|
||||
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
moondream_result = {
|
||||
'objects': [
|
||||
{
|
||||
'x_min': 0.5704046934843063,
|
||||
'y_min': 0.20069346576929092,
|
||||
'x_max': 0.7049859315156937,
|
||||
'y_max': 0.3012596592307091
|
||||
},
|
||||
{
|
||||
'x_min': 0.6210969910025597,
|
||||
'y_min': 0.3300672620534897,
|
||||
'x_max': 0.8417936339974403,
|
||||
'y_max': 0.4961046129465103
|
||||
}
|
||||
]
|
||||
}
|
||||
|
||||
detections = sv.Detections.from_vlm(
|
||||
sv.VLM.MOONDREAM,
|
||||
moondream_result,
|
||||
resolution_wh=(1000, 1000),
|
||||
)
|
||||
|
||||
detections.xyxy
|
||||
# array([[1752.28, 818.82, 2165.72, 1229.14],
|
||||
# [1908.01, 1346.67, 2585.99, 2024.11]])
|
||||
```
|
||||
|
||||
""" # noqa: E501
|
||||
|
||||
vlm = validate_vlm_parameters(vlm, result, kwargs)
|
||||
|
||||
if vlm == VLM.PALIGEMMA:
|
||||
@@ -901,6 +1479,30 @@ class Detections:
|
||||
|
||||
return cls(xyxy=xyxy, mask=mask, data=data)
|
||||
|
||||
if vlm == VLM.GOOGLE_GEMINI_2_0:
|
||||
xyxy, class_id, class_name = from_google_gemini_2_0(result, **kwargs)
|
||||
data = {CLASS_NAME_DATA_FIELD: class_name}
|
||||
return cls(xyxy=xyxy, class_id=class_id, data=data)
|
||||
|
||||
if vlm == VLM.MOONDREAM:
|
||||
xyxy = from_moondream(result, **kwargs)
|
||||
return cls(xyxy=xyxy)
|
||||
|
||||
if vlm == VLM.GOOGLE_GEMINI_2_5:
|
||||
xyxy, class_id, class_name, confidence, mask = from_google_gemini_2_5(
|
||||
result, **kwargs
|
||||
)
|
||||
data = {CLASS_NAME_DATA_FIELD: class_name}
|
||||
return cls(
|
||||
xyxy=xyxy,
|
||||
class_id=class_id,
|
||||
mask=mask,
|
||||
confidence=confidence,
|
||||
data=data,
|
||||
)
|
||||
|
||||
return cls.empty()
|
||||
|
||||
@classmethod
|
||||
def from_easyocr(cls, easyocr_results: list) -> Detections:
|
||||
"""
|
||||
@@ -1037,7 +1639,7 @@ class Detections:
|
||||
return self == empty_detections
|
||||
|
||||
@classmethod
|
||||
def merge(cls, detections_list: List[Detections]) -> Detections:
|
||||
def merge(cls, detections_list: list[Detections]) -> Detections:
|
||||
"""
|
||||
Merge a list of Detections objects into a single Detections object.
|
||||
|
||||
@@ -1207,8 +1809,8 @@ class Detections:
|
||||
raise ValueError(f"{anchor} is not supported.")
|
||||
|
||||
def __getitem__(
|
||||
self, index: Union[int, slice, List[int], np.ndarray, str]
|
||||
) -> Union[Detections, List, np.ndarray, None]:
|
||||
self, index: int | slice | list[int] | np.ndarray | str
|
||||
) -> Detections | list | np.ndarray | None:
|
||||
"""
|
||||
Get a subset of the Detections object or access an item from its data field.
|
||||
|
||||
@@ -1256,7 +1858,7 @@ class Detections:
|
||||
metadata=self.metadata,
|
||||
)
|
||||
|
||||
def __setitem__(self, key: str, value: Union[np.ndarray, List]):
|
||||
def __setitem__(self, key: str, value: np.ndarray | list):
|
||||
"""
|
||||
Set a value in the data dictionary of the Detections object.
|
||||
|
||||
@@ -1321,7 +1923,10 @@ class Detections:
|
||||
return (self.xyxy[:, 3] - self.xyxy[:, 1]) * (self.xyxy[:, 2] - self.xyxy[:, 0])
|
||||
|
||||
def with_nms(
|
||||
self, threshold: float = 0.5, class_agnostic: bool = False
|
||||
self,
|
||||
threshold: float = 0.5,
|
||||
class_agnostic: bool = False,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> Detections:
|
||||
"""
|
||||
Performs non-max suppression on detection set. If the detections result
|
||||
@@ -1334,6 +1939,8 @@ class Detections:
|
||||
class_agnostic (bool): Whether to perform class-agnostic
|
||||
non-maximum suppression. If True, the class_id of each detection
|
||||
will be ignored. Defaults to False.
|
||||
overlap_metric (OverlapMetric): Metric used for measuring overlap between
|
||||
detections in slices.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object containing the subset of detections
|
||||
@@ -1367,17 +1974,25 @@ class Detections:
|
||||
|
||||
if self.mask is not None:
|
||||
indices = mask_non_max_suppression(
|
||||
predictions=predictions, masks=self.mask, iou_threshold=threshold
|
||||
predictions=predictions,
|
||||
masks=self.mask,
|
||||
iou_threshold=threshold,
|
||||
overlap_metric=overlap_metric,
|
||||
)
|
||||
else:
|
||||
indices = box_non_max_suppression(
|
||||
predictions=predictions, iou_threshold=threshold
|
||||
predictions=predictions,
|
||||
iou_threshold=threshold,
|
||||
overlap_metric=overlap_metric,
|
||||
)
|
||||
|
||||
return self[indices]
|
||||
|
||||
def with_nmm(
|
||||
self, threshold: float = 0.5, class_agnostic: bool = False
|
||||
self,
|
||||
threshold: float = 0.5,
|
||||
class_agnostic: bool = False,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> Detections:
|
||||
"""
|
||||
Perform non-maximum merging on the current set of object detections.
|
||||
@@ -1388,6 +2003,8 @@ class Detections:
|
||||
class_agnostic (bool): Whether to perform class-agnostic
|
||||
non-maximum merging. If True, the class_id of each detection
|
||||
will be ignored. Defaults to False.
|
||||
overlap_metric (OverlapMetric): Metric used for measuring overlap between
|
||||
detections in slices.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object containing the subset of detections
|
||||
@@ -1421,15 +2038,25 @@ class Detections:
|
||||
)
|
||||
)
|
||||
|
||||
merge_groups = box_non_max_merge(
|
||||
predictions=predictions, iou_threshold=threshold
|
||||
)
|
||||
if self.mask is not None:
|
||||
merge_groups = mask_non_max_merge(
|
||||
predictions=predictions,
|
||||
masks=self.mask,
|
||||
iou_threshold=threshold,
|
||||
overlap_metric=overlap_metric,
|
||||
)
|
||||
else:
|
||||
merge_groups = box_non_max_merge(
|
||||
predictions=predictions,
|
||||
iou_threshold=threshold,
|
||||
overlap_metric=overlap_metric,
|
||||
)
|
||||
|
||||
result = []
|
||||
for merge_group in merge_groups:
|
||||
unmerged_detections = [self[i] for i in merge_group]
|
||||
merged_detections = merge_inner_detections_objects(
|
||||
unmerged_detections, threshold
|
||||
merged_detections = merge_inner_detections_objects_without_iou(
|
||||
unmerged_detections
|
||||
)
|
||||
result.append(merged_detections)
|
||||
|
||||
@@ -1529,7 +2156,9 @@ def merge_inner_detection_object_pair(
|
||||
|
||||
|
||||
def merge_inner_detections_objects(
|
||||
detections: List[Detections], threshold=0.5
|
||||
detections: list[Detections],
|
||||
threshold=0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> Detections:
|
||||
"""
|
||||
Given N detections each of length 1 (exactly one object inside), combine them into a
|
||||
@@ -1541,13 +2170,32 @@ def merge_inner_detections_objects(
|
||||
"""
|
||||
detections_1 = detections[0]
|
||||
for detections_2 in detections[1:]:
|
||||
box_iou = box_iou_batch(detections_1.xyxy, detections_2.xyxy)[0]
|
||||
if box_iou < threshold:
|
||||
if detections_1.mask is not None and detections_2.mask is not None:
|
||||
iou = mask_iou_batch(detections_1.mask, detections_2.mask, overlap_metric)[
|
||||
0
|
||||
]
|
||||
else:
|
||||
iou = box_iou_batch(detections_1.xyxy, detections_2.xyxy, overlap_metric)[0]
|
||||
if iou < threshold:
|
||||
break
|
||||
detections_1 = merge_inner_detection_object_pair(detections_1, detections_2)
|
||||
return detections_1
|
||||
|
||||
|
||||
def merge_inner_detections_objects_without_iou(
|
||||
detections: list[Detections],
|
||||
) -> Detections:
|
||||
"""
|
||||
Given N detections each of length 1 (exactly one object inside), combine them into a
|
||||
single detection object of length 1. The contained inner object will be the merged
|
||||
result of all the input detections.
|
||||
|
||||
For example, this lets you merge N boxes into one big box, N masks into one mask,
|
||||
etc.
|
||||
"""
|
||||
return reduce(merge_inner_detection_object_pair, detections)
|
||||
|
||||
|
||||
def validate_fields_both_defined_or_none(
|
||||
detections_1: Detections, detections_2: Detections
|
||||
) -> None:
|
||||
|
||||
@@ -1,8 +1,11 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import math
|
||||
import warnings
|
||||
from collections import Counter, defaultdict, deque
|
||||
from collections.abc import Iterable
|
||||
from functools import lru_cache
|
||||
from typing import Any, Deque, Dict, Iterable, List, Literal, Optional, Tuple
|
||||
from typing import Any, Literal
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -10,7 +13,7 @@ import numpy.typing as npt
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import cross_product
|
||||
from supervision.detection.utils.internal import cross_product
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_rectangle, draw_text
|
||||
from supervision.geometry.core import Point, Position, Rect, Vector
|
||||
@@ -99,7 +102,7 @@ class LineZone:
|
||||
self.vector = Vector(start=start, end=end)
|
||||
self.limits = self._calculate_region_of_interest_limits(vector=self.vector)
|
||||
self.crossing_history_length = max(2, minimum_crossing_threshold + 1)
|
||||
self.crossing_state_history: Dict[int, Deque[bool]] = defaultdict(
|
||||
self.crossing_state_history: dict[int, deque[bool]] = defaultdict(
|
||||
lambda: deque(maxlen=self.crossing_history_length)
|
||||
)
|
||||
self._in_count_per_class: Counter = Counter()
|
||||
@@ -107,7 +110,7 @@ class LineZone:
|
||||
self.triggering_anchors = triggering_anchors
|
||||
if not list(self.triggering_anchors):
|
||||
raise ValueError("Triggering anchors cannot be empty.")
|
||||
self.class_id_to_name: Dict[int, str] = {}
|
||||
self.class_id_to_name: dict[int, str] = {}
|
||||
|
||||
@property
|
||||
def in_count(self) -> int:
|
||||
@@ -118,14 +121,14 @@ class LineZone:
|
||||
return sum(self._out_count_per_class.values())
|
||||
|
||||
@property
|
||||
def in_count_per_class(self) -> Dict[int, int]:
|
||||
def in_count_per_class(self) -> dict[int, int]:
|
||||
return dict(self._in_count_per_class)
|
||||
|
||||
@property
|
||||
def out_count_per_class(self) -> Dict[int, int]:
|
||||
def out_count_per_class(self) -> dict[int, int]:
|
||||
return dict(self._out_count_per_class)
|
||||
|
||||
def trigger(self, detections: Detections) -> Tuple[np.ndarray, np.ndarray]:
|
||||
def trigger(self, detections: Detections) -> tuple[np.ndarray, np.ndarray]:
|
||||
"""
|
||||
Update the `in_count` and `out_count` based on the objects that cross the line.
|
||||
|
||||
@@ -160,7 +163,7 @@ class LineZone:
|
||||
self._compute_anchor_sides(detections)
|
||||
)
|
||||
|
||||
class_ids: List[Optional[int]] = (
|
||||
class_ids: list[int | None] = (
|
||||
list(detections.class_id)
|
||||
if detections.class_id is not None
|
||||
else [None] * len(detections)
|
||||
@@ -200,7 +203,7 @@ class LineZone:
|
||||
return crossed_in, crossed_out
|
||||
|
||||
@staticmethod
|
||||
def _calculate_region_of_interest_limits(vector: Vector) -> Tuple[Vector, Vector]:
|
||||
def _calculate_region_of_interest_limits(vector: Vector) -> tuple[Vector, Vector]:
|
||||
magnitude = vector.magnitude
|
||||
|
||||
if magnitude == 0:
|
||||
@@ -233,7 +236,7 @@ class LineZone:
|
||||
|
||||
def _compute_anchor_sides(
|
||||
self, detections: Detections
|
||||
) -> Tuple[npt.NDArray[np.bool_], npt.NDArray[np.bool_], npt.NDArray[np.bool_]]:
|
||||
) -> tuple[npt.NDArray[np.bool_], npt.NDArray[np.bool_], npt.NDArray[np.bool_]]:
|
||||
"""
|
||||
Find if detections' anchors are within the limit of the line
|
||||
zone and which anchors are on its left and right side.
|
||||
@@ -324,8 +327,8 @@ class LineZoneAnnotator:
|
||||
text_scale: float = 0.5,
|
||||
text_offset: float = 1.5,
|
||||
text_padding: int = 10,
|
||||
custom_in_text: Optional[str] = None,
|
||||
custom_out_text: Optional[str] = None,
|
||||
custom_in_text: str | None = None,
|
||||
custom_out_text: str | None = None,
|
||||
display_in_count: bool = True,
|
||||
display_out_count: bool = True,
|
||||
display_text_box: bool = True,
|
||||
@@ -471,7 +474,7 @@ class LineZoneAnnotator:
|
||||
text_height: int,
|
||||
is_in_count: bool,
|
||||
label_dimension: int,
|
||||
) -> Tuple[int, int]:
|
||||
) -> tuple[int, int]:
|
||||
"""
|
||||
Calculate insertion anchor in frame to position the center of the count image.
|
||||
|
||||
@@ -663,7 +666,7 @@ class LineZoneAnnotator:
|
||||
annotation = np.zeros((*annotation_shape, 3), dtype=np.uint8)
|
||||
annotation_alpha = np.zeros((*annotation_shape, 1), dtype=np.uint8)
|
||||
|
||||
text_args: Dict[str, Any] = dict(
|
||||
text_args: dict[str, Any] = dict(
|
||||
text=text,
|
||||
text_anchor=annotation_center,
|
||||
text_scale=text_scale,
|
||||
@@ -756,8 +759,8 @@ class LineZoneAnnotatorMulticlass:
|
||||
def annotate(
|
||||
self,
|
||||
frame: np.ndarray,
|
||||
line_zones: List[LineZone],
|
||||
line_zone_labels: Optional[List[str]] = None,
|
||||
line_zones: list[LineZone],
|
||||
line_zone_labels: list[str] | None = None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Draws a table with the number of objects of each class that crossed each line.
|
||||
|
||||
@@ -1,269 +0,0 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from enum import Enum
|
||||
from typing import List, Union
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.utils import box_iou_batch, mask_iou_batch
|
||||
|
||||
|
||||
def resize_masks(masks: np.ndarray, max_dimension: int = 640) -> np.ndarray:
|
||||
"""
|
||||
Resize all masks in the array to have a maximum dimension of max_dimension,
|
||||
maintaining aspect ratio.
|
||||
|
||||
Args:
|
||||
masks (np.ndarray): 3D array of binary masks with shape (N, H, W).
|
||||
max_dimension (int): The maximum dimension for the resized masks.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Array of resized masks.
|
||||
"""
|
||||
max_height = np.max(masks.shape[1])
|
||||
max_width = np.max(masks.shape[2])
|
||||
scale = min(max_dimension / max_height, max_dimension / max_width)
|
||||
|
||||
new_height = int(scale * max_height)
|
||||
new_width = int(scale * max_width)
|
||||
|
||||
x = np.linspace(0, max_width - 1, new_width).astype(int)
|
||||
y = np.linspace(0, max_height - 1, new_height).astype(int)
|
||||
xv, yv = np.meshgrid(x, y)
|
||||
|
||||
resized_masks = masks[:, yv, xv]
|
||||
|
||||
resized_masks = resized_masks.reshape(masks.shape[0], new_height, new_width)
|
||||
return resized_masks
|
||||
|
||||
|
||||
def mask_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
mask_dimension: int = 640,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on segmentation predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): A 2D array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or
|
||||
`(N, 6)`, where N is the number of predictions.
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
mask_dimension (int): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after
|
||||
non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the closed
|
||||
range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
sort_index = predictions[:, 4].argsort()[::-1]
|
||||
predictions = predictions[sort_index]
|
||||
masks = masks[sort_index]
|
||||
masks_resized = resize_masks(masks, mask_dimension)
|
||||
ious = mask_iou_batch(masks_resized, masks_resized)
|
||||
categories = predictions[:, 5]
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
for i in range(rows):
|
||||
if keep[i]:
|
||||
condition = (ious[i] > iou_threshold) & (categories[i] == categories)
|
||||
keep[i + 1 :] = np.where(condition[i + 1 :], False, keep[i + 1 :])
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def box_non_max_suppression(
|
||||
predictions: np.ndarray, iou_threshold: float = 0.5
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on object detection predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): An array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after n
|
||||
on-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the
|
||||
closed range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
# add column #5 - category filled with zeros for agnostic nms
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
# sort predictions column #4 - score
|
||||
sort_index = np.flip(predictions[:, 4].argsort())
|
||||
predictions = predictions[sort_index]
|
||||
|
||||
boxes = predictions[:, :4]
|
||||
categories = predictions[:, 5]
|
||||
ious = box_iou_batch(boxes, boxes)
|
||||
ious = ious - np.eye(rows)
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
|
||||
for index, (iou, category) in enumerate(zip(ious, categories)):
|
||||
if not keep[index]:
|
||||
continue
|
||||
|
||||
# drop detections with iou > iou_threshold and
|
||||
# same category as current detections
|
||||
condition = (iou > iou_threshold) & (categories == category)
|
||||
keep = keep & ~condition
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def group_overlapping_boxes(
|
||||
predictions: npt.NDArray[np.float64], iou_threshold: float = 0.5
|
||||
) -> List[List[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging to avoid detecting too many
|
||||
overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
and the confidence scores.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
|
||||
Returns:
|
||||
List[List[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
merge_groups: List[List[int]] = []
|
||||
|
||||
scores = predictions[:, 4]
|
||||
order = scores.argsort()
|
||||
|
||||
while len(order) > 0:
|
||||
idx = int(order[-1])
|
||||
|
||||
order = order[:-1]
|
||||
if len(order) == 0:
|
||||
merge_groups.append([idx])
|
||||
break
|
||||
|
||||
merge_candidate = np.expand_dims(predictions[idx], axis=0)
|
||||
ious = box_iou_batch(predictions[order][:, :4], merge_candidate[:, :4])
|
||||
ious = ious.flatten()
|
||||
|
||||
above_threshold = ious >= iou_threshold
|
||||
merge_group = [idx, *np.flip(order[above_threshold]).tolist()]
|
||||
merge_groups.append(merge_group)
|
||||
order = order[~above_threshold]
|
||||
return merge_groups
|
||||
|
||||
|
||||
def box_non_max_merge(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
) -> List[List[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging per category to avoid detecting
|
||||
too many overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` or `(n, 6)`
|
||||
containing the bounding boxes coordinates in format `[x1, y1, x2, y2]`,
|
||||
the confidence scores and class_ids. Omit class_id column to allow
|
||||
detections of different classes to be merged.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
|
||||
Returns:
|
||||
List[List[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
if predictions.shape[1] == 5:
|
||||
return group_overlapping_boxes(predictions, iou_threshold)
|
||||
|
||||
category_ids = predictions[:, 5]
|
||||
merge_groups = []
|
||||
for category_id in np.unique(category_ids):
|
||||
curr_indices = np.where(category_ids == category_id)[0]
|
||||
merge_class_groups = group_overlapping_boxes(
|
||||
predictions[curr_indices], iou_threshold
|
||||
)
|
||||
|
||||
for merge_class_group in merge_class_groups:
|
||||
merge_groups.append(curr_indices[merge_class_group].tolist())
|
||||
|
||||
for merge_group in merge_groups:
|
||||
if len(merge_group) == 0:
|
||||
raise ValueError(
|
||||
f"Empty group detected when non-max-merging detections: {merge_groups}"
|
||||
)
|
||||
return merge_groups
|
||||
|
||||
|
||||
class OverlapFilter(Enum):
|
||||
"""
|
||||
Enum specifying the strategy for filtering overlapping detections.
|
||||
|
||||
Attributes:
|
||||
NONE: Do not filter detections based on overlap.
|
||||
NON_MAX_SUPPRESSION: Filter detections using non-max suppression. This means,
|
||||
detections that overlap by more than a set threshold will be discarded,
|
||||
except for the one with the highest confidence.
|
||||
NON_MAX_MERGE: Merge detections with non-max merging. This means,
|
||||
detections that overlap by more than a set threshold will be merged
|
||||
into a single detection.
|
||||
"""
|
||||
|
||||
NONE = "none"
|
||||
NON_MAX_SUPPRESSION = "non_max_suppression"
|
||||
NON_MAX_MERGE = "non_max_merge"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
return list(map(lambda c: c.value, cls))
|
||||
|
||||
@classmethod
|
||||
def from_value(cls, value: Union[OverlapFilter, str]) -> OverlapFilter:
|
||||
if isinstance(value, cls):
|
||||
return value
|
||||
if isinstance(value, str):
|
||||
value = value.lower()
|
||||
try:
|
||||
return cls(value)
|
||||
except ValueError:
|
||||
raise ValueError(f"Invalid value: {value}. Must be one of {cls.list()}")
|
||||
raise ValueError(
|
||||
f"Invalid value type: {type(value)}. Must be an instance of "
|
||||
f"{cls.__name__} or str."
|
||||
)
|
||||
@@ -2,7 +2,7 @@ from __future__ import annotations
|
||||
|
||||
import csv
|
||||
import os
|
||||
from typing import Any, Dict, List, Optional
|
||||
from typing import Any
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
|
||||
@@ -61,8 +61,8 @@ class CSVSink:
|
||||
None
|
||||
"""
|
||||
self.file_name = file_name
|
||||
self.file: Optional[open] = None
|
||||
self.writer: Optional[csv.writer] = None
|
||||
self.file: open | None = None
|
||||
self.writer: csv.writer | None = None
|
||||
self.header_written = False
|
||||
self.field_names = []
|
||||
|
||||
@@ -72,9 +72,9 @@ class CSVSink:
|
||||
|
||||
def __exit__(
|
||||
self,
|
||||
exc_type: Optional[type],
|
||||
exc_val: Optional[Exception],
|
||||
exc_tb: Optional[Any],
|
||||
exc_type: type | None,
|
||||
exc_val: Exception | None,
|
||||
exc_tb: Any | None,
|
||||
) -> None:
|
||||
self.close()
|
||||
|
||||
@@ -104,8 +104,8 @@ class CSVSink:
|
||||
|
||||
@staticmethod
|
||||
def parse_detection_data(
|
||||
detections: Detections, custom_data: Optional[Dict[str, Any]] = None
|
||||
) -> List[Dict[str, Any]]:
|
||||
detections: Detections, custom_data: dict[str, Any] | None = None
|
||||
) -> list[dict[str, Any]]:
|
||||
parsed_rows = []
|
||||
for i in range(len(detections.xyxy)):
|
||||
row = {
|
||||
@@ -137,7 +137,7 @@ class CSVSink:
|
||||
return parsed_rows
|
||||
|
||||
def append(
|
||||
self, detections: Detections, custom_data: Optional[Dict[str, Any]] = None
|
||||
self, detections: Detections, custom_data: dict[str, Any] | None = None
|
||||
) -> None:
|
||||
"""
|
||||
Append detection data to the CSV file.
|
||||
@@ -173,8 +173,8 @@ class CSVSink:
|
||||
|
||||
@staticmethod
|
||||
def parse_field_names(
|
||||
detections: Detections, custom_data: Dict[str, Any]
|
||||
) -> List[str]:
|
||||
detections: Detections, custom_data: dict[str, Any]
|
||||
) -> list[str]:
|
||||
dynamic_header = sorted(
|
||||
set(custom_data.keys()) | set(getattr(detections, "data", {}).keys())
|
||||
)
|
||||
|
||||
@@ -1,13 +1,16 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import warnings
|
||||
from collections.abc import Callable
|
||||
from concurrent.futures import ThreadPoolExecutor, as_completed
|
||||
from typing import Callable, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.config import ORIENTED_BOX_COORDINATES
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.overlap_filter import OverlapFilter
|
||||
from supervision.detection.utils import move_boxes, move_masks, move_oriented_boxes
|
||||
from supervision.detection.utils.boxes import move_boxes, move_oriented_boxes
|
||||
from supervision.detection.utils.iou_and_nms import OverlapFilter
|
||||
from supervision.detection.utils.masks import move_masks
|
||||
from supervision.utils.image import crop_image
|
||||
from supervision.utils.internal import (
|
||||
SupervisionWarnings,
|
||||
@@ -18,7 +21,7 @@ from supervision.utils.internal import (
|
||||
def move_detections(
|
||||
detections: Detections,
|
||||
offset: np.ndarray,
|
||||
resolution_wh: Optional[Tuple[int, int]] = None,
|
||||
resolution_wh: tuple[int, int] | None = None,
|
||||
) -> Detections:
|
||||
"""
|
||||
Args:
|
||||
@@ -72,6 +75,8 @@ class InferenceSlicer:
|
||||
filtering or merging overlapping detections in slices.
|
||||
iou_threshold (float): Intersection over Union (IoU) threshold
|
||||
used when filtering by overlap.
|
||||
match_metric (str): Metric used for matching detections in slices.
|
||||
"IOU" or "IOS". Defaults "IOU".
|
||||
callback (Callable): A function that performs inference on a given image
|
||||
slice and returns detections.
|
||||
thread_workers (int): Number of threads for parallel execution.
|
||||
@@ -86,11 +91,12 @@ class InferenceSlicer:
|
||||
def __init__(
|
||||
self,
|
||||
callback: Callable[[np.ndarray], Detections],
|
||||
slice_wh: Tuple[int, int] = (320, 320),
|
||||
overlap_ratio_wh: Optional[Tuple[float, float]] = (0.2, 0.2),
|
||||
overlap_wh: Optional[Tuple[int, int]] = None,
|
||||
overlap_filter: Union[OverlapFilter, str] = OverlapFilter.NON_MAX_SUPPRESSION,
|
||||
slice_wh: tuple[int, int] = (320, 320),
|
||||
overlap_ratio_wh: tuple[float, float] | None = (0.2, 0.2),
|
||||
overlap_wh: tuple[int, int] | None = None,
|
||||
overlap_filter: OverlapFilter | str = OverlapFilter.NON_MAX_SUPPRESSION,
|
||||
iou_threshold: float = 0.5,
|
||||
match_metric: str = "IOU",
|
||||
thread_workers: int = 1,
|
||||
):
|
||||
if overlap_ratio_wh is not None:
|
||||
@@ -106,6 +112,7 @@ class InferenceSlicer:
|
||||
|
||||
self.slice_wh = slice_wh
|
||||
self.iou_threshold = iou_threshold
|
||||
self.match_metric = match_metric
|
||||
self.overlap_filter = OverlapFilter.from_value(overlap_filter)
|
||||
self.callback = callback
|
||||
self.thread_workers = thread_workers
|
||||
@@ -165,9 +172,13 @@ class InferenceSlicer:
|
||||
if self.overlap_filter == OverlapFilter.NONE:
|
||||
return merged
|
||||
elif self.overlap_filter == OverlapFilter.NON_MAX_SUPPRESSION:
|
||||
return merged.with_nms(threshold=self.iou_threshold)
|
||||
return merged.with_nms(
|
||||
threshold=self.iou_threshold, match_metric=self.match_metric
|
||||
)
|
||||
elif self.overlap_filter == OverlapFilter.NON_MAX_MERGE:
|
||||
return merged.with_nmm(threshold=self.iou_threshold)
|
||||
return merged.with_nmm(
|
||||
threshold=self.iou_threshold, match_metric=self.match_metric
|
||||
)
|
||||
else:
|
||||
warnings.warn(
|
||||
f"Invalid overlap filter strategy: {self.overlap_filter}",
|
||||
@@ -198,10 +209,10 @@ class InferenceSlicer:
|
||||
|
||||
@staticmethod
|
||||
def _generate_offset(
|
||||
resolution_wh: Tuple[int, int],
|
||||
slice_wh: Tuple[int, int],
|
||||
overlap_ratio_wh: Optional[Tuple[float, float]],
|
||||
overlap_wh: Optional[Tuple[int, int]],
|
||||
resolution_wh: tuple[int, int],
|
||||
slice_wh: tuple[int, int],
|
||||
overlap_ratio_wh: tuple[float, float] | None,
|
||||
overlap_wh: tuple[int, int] | None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Generate offset coordinates for slicing an image based on the given resolution,
|
||||
@@ -260,8 +271,8 @@ class InferenceSlicer:
|
||||
|
||||
@staticmethod
|
||||
def _validate_overlap(
|
||||
overlap_ratio_wh: Optional[Tuple[float, float]],
|
||||
overlap_wh: Optional[Tuple[int, int]],
|
||||
overlap_ratio_wh: tuple[float, float] | None,
|
||||
overlap_wh: tuple[int, int] | None,
|
||||
) -> None:
|
||||
if overlap_ratio_wh is not None and overlap_wh is not None:
|
||||
raise ValueError(
|
||||
|
||||
@@ -2,7 +2,7 @@ from __future__ import annotations
|
||||
|
||||
import json
|
||||
import os
|
||||
from typing import Any, Dict, List, Optional
|
||||
from typing import Any
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
|
||||
@@ -51,8 +51,8 @@ class JSONSink:
|
||||
None
|
||||
"""
|
||||
self.file_name = file_name
|
||||
self.file: Optional[open] = None
|
||||
self.data: List[Dict[str, Any]] = []
|
||||
self.file: open | None = None
|
||||
self.data: list[dict[str, Any]] = []
|
||||
|
||||
def __enter__(self) -> JSONSink:
|
||||
self.open()
|
||||
@@ -60,9 +60,9 @@ class JSONSink:
|
||||
|
||||
def __exit__(
|
||||
self,
|
||||
exc_type: Optional[type],
|
||||
exc_val: Optional[Exception],
|
||||
exc_tb: Optional[Any],
|
||||
exc_type: type | None,
|
||||
exc_val: Exception | None,
|
||||
exc_tb: Any | None,
|
||||
) -> None:
|
||||
self.write_and_close()
|
||||
|
||||
@@ -92,8 +92,8 @@ class JSONSink:
|
||||
|
||||
@staticmethod
|
||||
def parse_detection_data(
|
||||
detections: Detections, custom_data: Optional[Dict[str, Any]] = None
|
||||
) -> List[Dict[str, Any]]:
|
||||
detections: Detections, custom_data: dict[str, Any] | None = None
|
||||
) -> list[dict[str, Any]]:
|
||||
parsed_rows = []
|
||||
for i in range(len(detections.xyxy)):
|
||||
row = {
|
||||
@@ -126,7 +126,7 @@ class JSONSink:
|
||||
return parsed_rows
|
||||
|
||||
def append(
|
||||
self, detections: Detections, custom_data: Optional[Dict[str, Any]] = None
|
||||
self, detections: Detections, custom_data: dict[str, Any] | None = None
|
||||
) -> None:
|
||||
"""
|
||||
Append detection data to the JSON file.
|
||||
|
||||
@@ -1,12 +1,15 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from collections.abc import Iterable
|
||||
from dataclasses import replace
|
||||
from typing import Iterable, Optional
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision import Detections
|
||||
from supervision.detection.utils import clip_boxes, polygon_to_mask
|
||||
from supervision.detection.utils.boxes import clip_boxes
|
||||
from supervision.detection.utils.converters import polygon_to_mask
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_filled_polygon, draw_polygon, draw_text
|
||||
from supervision.geometry.core import Position
|
||||
@@ -153,7 +156,7 @@ class PolygonZoneAnnotator:
|
||||
self.display_in_zone_count = display_in_zone_count
|
||||
self.opacity = opacity
|
||||
|
||||
def annotate(self, scene: np.ndarray, label: Optional[str] = None) -> np.ndarray:
|
||||
def annotate(self, scene: np.ndarray, label: str | None = None) -> np.ndarray:
|
||||
"""
|
||||
Annotates the polygon zone within a frame with a count of detected objects.
|
||||
|
||||
|
||||
@@ -1,7 +1,8 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import warnings
|
||||
from collections import defaultdict, deque
|
||||
from copy import deepcopy
|
||||
from typing import Optional
|
||||
|
||||
import numpy as np
|
||||
|
||||
@@ -95,7 +96,7 @@ class DetectionsSmoother:
|
||||
|
||||
return self.get_smoothed_detections()
|
||||
|
||||
def get_track(self, track_id: int) -> Optional[Detections]:
|
||||
def get_track(self, track_id: int) -> Detections | None:
|
||||
track = self.tracks.get(track_id, None)
|
||||
if track is None:
|
||||
return None
|
||||
|
||||
@@ -1,15 +1,17 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import io
|
||||
from typing import Any, Dict, Optional
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.utils import mask_to_xyxy
|
||||
from supervision.detection.utils.converters import mask_to_xyxy
|
||||
|
||||
|
||||
def process_transformers_detection_result(
|
||||
detection_result: dict, id2label: Optional[Dict[int, str]]
|
||||
detection_result: dict, id2label: dict[int, str] | None
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of Transformers object detection functions such as
|
||||
@@ -38,7 +40,7 @@ def process_transformers_detection_result(
|
||||
|
||||
|
||||
def process_transformers_v4_segmentation_result(
|
||||
segmentation_result: dict, id2label: Optional[Dict[int, str]]
|
||||
segmentation_result: dict, id2label: dict[int, str] | None
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of Transformers segmentation functions such as
|
||||
@@ -77,7 +79,7 @@ def process_transformers_v4_segmentation_result(
|
||||
|
||||
|
||||
def process_transformers_v5_segmentation_result(
|
||||
segmentation_result: dict, id2label: Optional[Dict[int, str]]
|
||||
segmentation_result: dict, id2label: dict[int, str] | None
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of Transformers segmentation functions such as
|
||||
@@ -107,7 +109,7 @@ def process_transformers_v5_segmentation_result(
|
||||
|
||||
|
||||
def process_transformers_v5_semantic_or_instance_segmentation_result(
|
||||
segmentation_result: dict, id2label: Optional[Dict[int, str]]
|
||||
segmentation_result: dict, id2label: dict[int, str] | None
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of Transformers segmentation functions such as
|
||||
@@ -143,7 +145,7 @@ def process_transformers_v5_semantic_or_instance_segmentation_result(
|
||||
|
||||
|
||||
def process_transformers_v4_panoptic_segmentation_result(
|
||||
segmentation_result: dict, id2label: Optional[Dict[int, str]]
|
||||
segmentation_result: dict, id2label: dict[int, str] | None
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of the Transformers function `post_process_panoptic` (v4).
|
||||
@@ -177,7 +179,7 @@ def process_transformers_v4_panoptic_segmentation_result(
|
||||
|
||||
|
||||
def process_transformers_v5_panoptic_segmentation_result(
|
||||
segmentation_array: np.ndarray, id2label: Optional[Dict[int, str]]
|
||||
segmentation_array: np.ndarray, id2label: dict[int, str] | None
|
||||
) -> dict:
|
||||
"""
|
||||
Process the result of the Transformers function
|
||||
@@ -220,9 +222,9 @@ def png_string_to_segmentation_array(png_string: bytes) -> np.ndarray:
|
||||
|
||||
def append_class_names_to_data(
|
||||
class_ids: np.ndarray,
|
||||
id2label: Optional[Dict[int, str]],
|
||||
data: Optional[Dict[str, Any]] = None,
|
||||
) -> Dict[str, Any]:
|
||||
id2label: dict[int, str] | None,
|
||||
data: dict[str, Any] | None = None,
|
||||
) -> dict[str, Any]:
|
||||
"""
|
||||
Helper function to create or append to a data dictionary with class names if
|
||||
available.
|
||||
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,336 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.utils.iou_and_nms import box_iou_batch
|
||||
|
||||
|
||||
def clip_boxes(xyxy: np.ndarray, resolution_wh: tuple[int, int]) -> np.ndarray:
|
||||
"""
|
||||
Clips bounding boxes coordinates to fit within the frame resolution.
|
||||
|
||||
Args:
|
||||
xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each
|
||||
row corresponds to a bounding box in
|
||||
the format `(x_min, y_min, x_max, y_max)`.
|
||||
resolution_wh (Tuple[int, int]): A tuple of the form `(width, height)`
|
||||
representing the resolution of the frame.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row
|
||||
corresponds to a bounding box with coordinates clipped to fit
|
||||
within the frame resolution.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 20, 300, 200],
|
||||
[15, 25, 350, 450],
|
||||
[-10, -20, 30, 40]
|
||||
])
|
||||
|
||||
sv.clip_boxes(xyxy=xyxy, resolution_wh=(320, 240))
|
||||
# array([
|
||||
# [ 10, 20, 300, 200],
|
||||
# [ 15, 25, 320, 240],
|
||||
# [ 0, 0, 30, 40]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
result = np.copy(xyxy)
|
||||
width, height = resolution_wh
|
||||
result[:, [0, 2]] = result[:, [0, 2]].clip(0, width)
|
||||
result[:, [1, 3]] = result[:, [1, 3]].clip(0, height)
|
||||
return result
|
||||
|
||||
|
||||
def pad_boxes(xyxy: np.ndarray, px: int, py: int | None = None) -> np.ndarray:
|
||||
"""
|
||||
Pads bounding boxes coordinates with a constant padding.
|
||||
|
||||
Args:
|
||||
xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each
|
||||
row corresponds to a bounding box in the format
|
||||
`(x_min, y_min, x_max, y_max)`.
|
||||
px (int): The padding value to be added to both the left and right sides of
|
||||
each bounding box.
|
||||
py (Optional[int]): The padding value to be added to both the top and bottom
|
||||
sides of each bounding box. If not provided, `px` will be used for both
|
||||
dimensions.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds to a
|
||||
bounding box with coordinates padded according to the provided padding
|
||||
values.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 20, 30, 40],
|
||||
[15, 25, 35, 45]
|
||||
])
|
||||
|
||||
sv.pad_boxes(xyxy=xyxy, px=5, py=10)
|
||||
# array([
|
||||
# [ 5, 10, 35, 50],
|
||||
# [10, 15, 40, 55]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
if py is None:
|
||||
py = px
|
||||
|
||||
result = xyxy.copy()
|
||||
result[:, [0, 1]] -= [px, py]
|
||||
result[:, [2, 3]] += [px, py]
|
||||
|
||||
return result
|
||||
|
||||
|
||||
def denormalize_boxes(
|
||||
normalized_xyxy: np.ndarray,
|
||||
resolution_wh: tuple[int, int],
|
||||
normalization_factor: float = 1.0,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Converts normalized bounding box coordinates to absolute pixel values.
|
||||
|
||||
Args:
|
||||
normalized_xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each row
|
||||
contains normalized coordinates in the format `(x_min, y_min, x_max, y_max)`,
|
||||
with values between 0 and `normalization_factor`.
|
||||
resolution_wh (Tuple[int, int]): A tuple `(width, height)` representing the
|
||||
target image resolution.
|
||||
normalization_factor (float, optional): The normalization range of the input
|
||||
coordinates. Defaults to 1.0.
|
||||
|
||||
Returns:
|
||||
np.ndarray: An array of shape `(N, 4)` with absolute coordinates in
|
||||
`(x_min, y_min, x_max, y_max)` format.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
# Default normalization (0-1)
|
||||
normalized_xyxy = np.array([
|
||||
[0.1, 0.2, 0.5, 0.6],
|
||||
[0.3, 0.4, 0.7, 0.8]
|
||||
])
|
||||
resolution_wh = (100, 200)
|
||||
sv.denormalize_boxes(normalized_xyxy, resolution_wh)
|
||||
# array([
|
||||
# [ 10., 40., 50., 120.],
|
||||
# [ 30., 80., 70., 160.]
|
||||
# ])
|
||||
|
||||
# Custom normalization (0-100)
|
||||
normalized_xyxy = np.array([
|
||||
[10., 20., 50., 60.],
|
||||
[30., 40., 70., 80.]
|
||||
])
|
||||
sv.denormalize_boxes(normalized_xyxy, resolution_wh, normalization_factor=100.0)
|
||||
# array([
|
||||
# [ 10., 40., 50., 120.],
|
||||
# [ 30., 80., 70., 160.]
|
||||
# ])
|
||||
```
|
||||
""" # noqa E501 // docs
|
||||
width, height = resolution_wh
|
||||
result = normalized_xyxy.copy()
|
||||
|
||||
result[[0, 2]] = (result[[0, 2]] * width) / normalization_factor
|
||||
result[[1, 3]] = (result[[1, 3]] * height) / normalization_factor
|
||||
|
||||
return result
|
||||
|
||||
|
||||
def move_boxes(
|
||||
xyxy: npt.NDArray[np.float64], offset: npt.NDArray[np.int32]
|
||||
) -> npt.NDArray[np.float64]:
|
||||
"""
|
||||
Parameters:
|
||||
xyxy (npt.NDArray[np.float64]): An array of shape `(n, 4)` containing the
|
||||
bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
offset (np.array): An array of shape `(2,)` containing offset values in format
|
||||
is `[dx, dy]`.
|
||||
|
||||
Returns:
|
||||
npt.NDArray[np.float64]: Repositioned bounding boxes.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 10, 20, 20],
|
||||
[30, 30, 40, 40]
|
||||
])
|
||||
offset = np.array([5, 5])
|
||||
|
||||
sv.move_boxes(xyxy=xyxy, offset=offset)
|
||||
# array([
|
||||
# [15, 15, 25, 25],
|
||||
# [35, 35, 45, 45]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
return xyxy + np.hstack([offset, offset])
|
||||
|
||||
|
||||
def move_oriented_boxes(
|
||||
xyxyxyxy: npt.NDArray[np.float64], offset: npt.NDArray[np.int32]
|
||||
) -> npt.NDArray[np.float64]:
|
||||
"""
|
||||
Parameters:
|
||||
xyxyxyxy (npt.NDArray[np.float64]): An array of shape `(n, 4, 2)` containing the
|
||||
oriented bounding boxes coordinates in format
|
||||
`[[x1, y1], [x2, y2], [x3, y3], [x3, y3]]`
|
||||
offset (np.array): An array of shape `(2,)` containing offset values in format
|
||||
is `[dx, dy]`.
|
||||
|
||||
Returns:
|
||||
npt.NDArray[np.float64]: Repositioned bounding boxes.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxyxyxy = np.array([
|
||||
[
|
||||
[20, 10],
|
||||
[10, 20],
|
||||
[20, 30],
|
||||
[30, 20]
|
||||
],
|
||||
[
|
||||
[30 ,30],
|
||||
[20, 40],
|
||||
[30, 50],
|
||||
[40, 40]
|
||||
]
|
||||
])
|
||||
offset = np.array([5, 5])
|
||||
|
||||
sv.move_oriented_boxes(xyxy=xyxy, offset=offset)
|
||||
# array([
|
||||
# [
|
||||
# [25, 15],
|
||||
# [15, 25],
|
||||
# [25, 35],
|
||||
# [35, 25]
|
||||
# ],
|
||||
# [
|
||||
# [35, 35],
|
||||
# [25, 45],
|
||||
# [35, 55],
|
||||
# [45, 45]
|
||||
# ]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
return xyxyxyxy + offset
|
||||
|
||||
|
||||
def scale_boxes(
|
||||
xyxy: npt.NDArray[np.float64], factor: float
|
||||
) -> npt.NDArray[np.float64]:
|
||||
"""
|
||||
Scale the dimensions of bounding boxes.
|
||||
|
||||
Parameters:
|
||||
xyxy (npt.NDArray[np.float64]): An array of shape `(n, 4)` containing the
|
||||
bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
factor (float): A float value representing the factor by which the box
|
||||
dimensions are scaled. A factor greater than 1 enlarges the boxes, while a
|
||||
factor less than 1 shrinks them.
|
||||
|
||||
Returns:
|
||||
npt.NDArray[np.float64]: Scaled bounding boxes.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 10, 20, 20],
|
||||
[30, 30, 40, 40]
|
||||
])
|
||||
|
||||
sv.scale_boxes(xyxy=xyxy, factor=1.5)
|
||||
# array([
|
||||
# [ 7.5, 7.5, 22.5, 22.5],
|
||||
# [27.5, 27.5, 42.5, 42.5]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
centers = (xyxy[:, :2] + xyxy[:, 2:]) / 2
|
||||
new_sizes = (xyxy[:, 2:] - xyxy[:, :2]) * factor
|
||||
return np.concatenate((centers - new_sizes / 2, centers + new_sizes / 2), axis=1)
|
||||
|
||||
|
||||
def spread_out_boxes(
|
||||
xyxy: np.ndarray,
|
||||
max_iterations: int = 100,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Spread out boxes that overlap with each other.
|
||||
|
||||
Args:
|
||||
xyxy: Numpy array of shape (N, 4) where N is the number of boxes.
|
||||
max_iterations: Maximum number of iterations to run the algorithm for.
|
||||
"""
|
||||
if len(xyxy) == 0:
|
||||
return xyxy
|
||||
|
||||
xyxy_padded = pad_boxes(xyxy, px=1)
|
||||
for _ in range(max_iterations):
|
||||
# NxN
|
||||
iou = box_iou_batch(xyxy_padded, xyxy_padded)
|
||||
np.fill_diagonal(iou, 0)
|
||||
if np.all(iou == 0):
|
||||
break
|
||||
|
||||
overlap_mask = iou > 0
|
||||
|
||||
# Nx2
|
||||
centers = (xyxy_padded[:, :2] + xyxy_padded[:, 2:]) / 2
|
||||
|
||||
# NxNx2
|
||||
delta_centers = centers[:, np.newaxis, :] - centers[np.newaxis, :, :]
|
||||
delta_centers *= overlap_mask[:, :, np.newaxis]
|
||||
|
||||
# Nx2
|
||||
delta_sum = np.sum(delta_centers, axis=1)
|
||||
delta_magnitude = np.linalg.norm(delta_sum, axis=1, keepdims=True)
|
||||
direction_vectors = np.divide(
|
||||
delta_sum,
|
||||
delta_magnitude,
|
||||
out=np.zeros_like(delta_sum),
|
||||
where=delta_magnitude != 0,
|
||||
)
|
||||
|
||||
force_vectors = np.sum(iou, axis=1)
|
||||
force_vectors = force_vectors[:, np.newaxis] * direction_vectors
|
||||
|
||||
force_vectors *= 10
|
||||
force_vectors[(force_vectors > 0) & (force_vectors < 2)] = 2
|
||||
force_vectors[(force_vectors < 0) & (force_vectors > -2)] = -2
|
||||
|
||||
force_vectors = force_vectors.astype(int)
|
||||
|
||||
xyxy_padded[:, [0, 1]] += force_vectors
|
||||
xyxy_padded[:, [2, 3]] += force_vectors
|
||||
|
||||
return pad_boxes(xyxy_padded, px=-1)
|
||||
@@ -0,0 +1,272 @@
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
MIN_POLYGON_POINT_COUNT = 3
|
||||
|
||||
|
||||
def xyxy_to_polygons(box: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Convert an array of boxes to an array of polygons.
|
||||
Retains the input datatype.
|
||||
|
||||
Args:
|
||||
box (np.ndarray): An array of boxes (N, 4), where each box is represented as a
|
||||
list of four coordinates in the format `(x_min, y_min, x_max, y_max)`.
|
||||
|
||||
Returns:
|
||||
np.ndarray: An array of polygons (N, 4, 2), where each polygon is
|
||||
represented as a list of four coordinates in the format `(x, y)`.
|
||||
"""
|
||||
polygon = np.zeros((box.shape[0], 4, 2), dtype=box.dtype)
|
||||
polygon[:, :, 0] = box[:, [0, 2, 2, 0]]
|
||||
polygon[:, :, 1] = box[:, [1, 1, 3, 3]]
|
||||
return polygon
|
||||
|
||||
|
||||
def polygon_to_mask(polygon: np.ndarray, resolution_wh: tuple[int, int]) -> np.ndarray:
|
||||
"""Generate a mask from a polygon.
|
||||
|
||||
Args:
|
||||
polygon (np.ndarray): The polygon for which the mask should be generated,
|
||||
given as a list of vertices.
|
||||
resolution_wh (Tuple[int, int]): The width and height of the desired resolution.
|
||||
|
||||
Returns:
|
||||
np.ndarray: The generated 2D mask, where the polygon is marked with
|
||||
`1`'s and the rest is filled with `0`'s.
|
||||
"""
|
||||
width, height = map(int, resolution_wh)
|
||||
mask = np.zeros((height, width), dtype=np.uint8)
|
||||
cv2.fillPoly(mask, [polygon.astype(np.int32)], color=1)
|
||||
return mask
|
||||
|
||||
|
||||
def xywh_to_xyxy(xywh: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts bounding box coordinates from `(x, y, width, height)`
|
||||
format to `(x_min, y_min, x_max, y_max)` format.
|
||||
|
||||
Args:
|
||||
xywh (np.ndarray): A numpy array of shape `(N, 4)` where each row
|
||||
corresponds to a bounding box in the format `(x, y, width, height)`.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds
|
||||
to a bounding box in the format `(x_min, y_min, x_max, y_max)`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xywh = np.array([
|
||||
[10, 20, 30, 40],
|
||||
[15, 25, 35, 45]
|
||||
])
|
||||
|
||||
sv.xywh_to_xyxy(xywh=xywh)
|
||||
# array([
|
||||
# [10, 20, 40, 60],
|
||||
# [15, 25, 50, 70]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
xyxy = xywh.copy()
|
||||
xyxy[:, 2] = xywh[:, 0] + xywh[:, 2]
|
||||
xyxy[:, 3] = xywh[:, 1] + xywh[:, 3]
|
||||
return xyxy
|
||||
|
||||
|
||||
def xyxy_to_xywh(xyxy: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts bounding box coordinates from `(x_min, y_min, x_max, y_max)`
|
||||
format to `(x, y, width, height)` format.
|
||||
|
||||
Args:
|
||||
xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each row
|
||||
corresponds to a bounding box in the format `(x_min, y_min, x_max,
|
||||
y_max)`.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds
|
||||
to a bounding box in the format `(x, y, width, height)`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 20, 40, 60],
|
||||
[15, 25, 50, 70]
|
||||
])
|
||||
|
||||
sv.xyxy_to_xywh(xyxy=xyxy)
|
||||
# array([
|
||||
# [10, 20, 30, 40],
|
||||
# [15, 25, 35, 45]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
xywh = xyxy.copy()
|
||||
xywh[:, 2] = xyxy[:, 2] - xyxy[:, 0]
|
||||
xywh[:, 3] = xyxy[:, 3] - xyxy[:, 1]
|
||||
return xywh
|
||||
|
||||
|
||||
def xcycwh_to_xyxy(xcycwh: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts bounding box coordinates from `(center_x, center_y, width, height)`
|
||||
format to `(x_min, y_min, x_max, y_max)` format.
|
||||
|
||||
Args:
|
||||
xcycwh (np.ndarray): A numpy array of shape `(N, 4)` where each row
|
||||
corresponds to a bounding box in the format `(center_x, center_y, width,
|
||||
height)`.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds
|
||||
to a bounding box in the format `(x_min, y_min, x_max, y_max)`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xcycwh = np.array([
|
||||
[50, 50, 20, 30],
|
||||
[30, 40, 10, 15]
|
||||
])
|
||||
|
||||
sv.xcycwh_to_xyxy(xcycwh=xcycwh)
|
||||
# array([
|
||||
# [40, 35, 60, 65],
|
||||
# [25, 32.5, 35, 47.5]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
xyxy = xcycwh.copy()
|
||||
xyxy[:, 0] = xcycwh[:, 0] - xcycwh[:, 2] / 2
|
||||
xyxy[:, 1] = xcycwh[:, 1] - xcycwh[:, 3] / 2
|
||||
xyxy[:, 2] = xcycwh[:, 0] + xcycwh[:, 2] / 2
|
||||
xyxy[:, 3] = xcycwh[:, 1] + xcycwh[:, 3] / 2
|
||||
return xyxy
|
||||
|
||||
|
||||
def xyxy_to_xcycarh(xyxy: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts bounding box coordinates from `(x_min, y_min, x_max, y_max)`
|
||||
into measurement space to format `(center x, center y, aspect ratio, height)`,
|
||||
where the aspect ratio is `width / height`.
|
||||
|
||||
Args:
|
||||
xyxy (np.ndarray): Bounding box in format `(x1, y1, x2, y2)`.
|
||||
Expected shape is `(N, 4)`.
|
||||
Returns:
|
||||
np.ndarray: Bounding box in format
|
||||
`(center x, center y, aspect ratio, height)`. Shape `(N, 4)`.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
xyxy = np.array([
|
||||
[10, 20, 40, 60],
|
||||
[15, 25, 50, 70]
|
||||
])
|
||||
|
||||
sv.xyxy_to_xcycarh(xyxy=xyxy)
|
||||
# array([
|
||||
# [25. , 40. , 0.75, 40. ],
|
||||
# [32.5 , 47.5 , 0.77777778, 45. ]
|
||||
# ])
|
||||
```
|
||||
|
||||
"""
|
||||
if xyxy.size == 0:
|
||||
return np.empty((0, 4), dtype=float)
|
||||
|
||||
x1, y1, x2, y2 = xyxy.T
|
||||
width = x2 - x1
|
||||
height = y2 - y1
|
||||
center_x = x1 + width / 2
|
||||
center_y = y1 + height / 2
|
||||
|
||||
aspect_ratio = np.divide(
|
||||
width,
|
||||
height,
|
||||
out=np.zeros_like(width, dtype=float),
|
||||
where=height != 0,
|
||||
)
|
||||
result = np.column_stack((center_x, center_y, aspect_ratio, height))
|
||||
return result.astype(float)
|
||||
|
||||
|
||||
def mask_to_xyxy(masks: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts a 3D `np.array` of 2D bool masks into a 2D `np.array` of bounding boxes.
|
||||
|
||||
Parameters:
|
||||
masks (np.ndarray): A 3D `np.array` of shape `(N, W, H)`
|
||||
containing 2D bool masks
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 2D `np.array` of shape `(N, 4)` containing the bounding boxes
|
||||
`(x_min, y_min, x_max, y_max)` for each mask
|
||||
"""
|
||||
n = masks.shape[0]
|
||||
xyxy = np.zeros((n, 4), dtype=int)
|
||||
|
||||
for i, mask in enumerate(masks):
|
||||
rows, cols = np.where(mask)
|
||||
|
||||
if len(rows) > 0 and len(cols) > 0:
|
||||
x_min, x_max = np.min(cols), np.max(cols)
|
||||
y_min, y_max = np.min(rows), np.max(rows)
|
||||
xyxy[i, :] = [x_min, y_min, x_max, y_max]
|
||||
|
||||
return xyxy
|
||||
|
||||
|
||||
def mask_to_polygons(mask: np.ndarray) -> list[np.ndarray]:
|
||||
"""
|
||||
Converts a binary mask to a list of polygons.
|
||||
|
||||
Parameters:
|
||||
mask (np.ndarray): A binary mask represented as a 2D NumPy array of
|
||||
shape `(H, W)`, where H and W are the height and width of
|
||||
the mask, respectively.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, where each polygon is represented by a
|
||||
NumPy array of shape `(N, 2)`, containing the `x`, `y` coordinates
|
||||
of the points. Polygons with fewer points than `MIN_POLYGON_POINT_COUNT = 3`
|
||||
are excluded from the output.
|
||||
"""
|
||||
|
||||
contours, _ = cv2.findContours(
|
||||
mask.astype(np.uint8), cv2.RETR_TREE, cv2.CHAIN_APPROX_SIMPLE
|
||||
)
|
||||
return [
|
||||
np.squeeze(contour, axis=1)
|
||||
for contour in contours
|
||||
if contour.shape[0] >= MIN_POLYGON_POINT_COUNT
|
||||
]
|
||||
|
||||
|
||||
def polygon_to_xyxy(polygon: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts a polygon represented by a NumPy array into a bounding box.
|
||||
|
||||
Parameters:
|
||||
polygon (np.ndarray): A polygon represented by a NumPy array of shape `(N, 2)`,
|
||||
containing the `x`, `y` coordinates of the points.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 1D NumPy array containing the bounding box
|
||||
`(x_min, y_min, x_max, y_max)` of the input polygon.
|
||||
"""
|
||||
x_min, y_min = np.min(polygon, axis=0)
|
||||
x_max, y_max = np.max(polygon, axis=0)
|
||||
return np.array([x_min, y_min, x_max, y_max])
|
||||
@@ -0,0 +1,338 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from itertools import chain
|
||||
from typing import Any
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.config import CLASS_NAME_DATA_FIELD
|
||||
from supervision.detection.utils.converters import polygon_to_mask
|
||||
from supervision.geometry.core import Vector
|
||||
|
||||
|
||||
def extract_ultralytics_masks(yolov8_results) -> np.ndarray | None:
|
||||
if not yolov8_results.masks:
|
||||
return None
|
||||
|
||||
orig_shape = yolov8_results.orig_shape
|
||||
inference_shape = tuple(yolov8_results.masks.data.shape[1:])
|
||||
|
||||
pad = (0, 0)
|
||||
|
||||
if inference_shape != orig_shape:
|
||||
gain = min(
|
||||
inference_shape[0] / orig_shape[0],
|
||||
inference_shape[1] / orig_shape[1],
|
||||
)
|
||||
pad = (
|
||||
(inference_shape[1] - orig_shape[1] * gain) / 2,
|
||||
(inference_shape[0] - orig_shape[0] * gain) / 2,
|
||||
)
|
||||
|
||||
top, left = int(pad[1]), int(pad[0])
|
||||
bottom, right = int(inference_shape[0] - pad[1]), int(inference_shape[1] - pad[0])
|
||||
|
||||
mask_maps = []
|
||||
masks = yolov8_results.masks.data.cpu().numpy()
|
||||
for i in range(masks.shape[0]):
|
||||
mask = masks[i]
|
||||
mask = mask[top:bottom, left:right]
|
||||
|
||||
if mask.shape != orig_shape:
|
||||
mask = cv2.resize(mask, (orig_shape[1], orig_shape[0]))
|
||||
|
||||
mask_maps.append(mask)
|
||||
|
||||
return np.asarray(mask_maps, dtype=bool)
|
||||
|
||||
|
||||
def process_roboflow_result(
|
||||
roboflow_result: dict,
|
||||
) -> tuple[
|
||||
np.ndarray,
|
||||
np.ndarray,
|
||||
np.ndarray,
|
||||
np.ndarray | None,
|
||||
np.ndarray | None,
|
||||
dict[str, list[np.ndarray] | np.ndarray],
|
||||
]:
|
||||
if not roboflow_result["predictions"]:
|
||||
return (
|
||||
np.empty((0, 4)),
|
||||
np.empty(0),
|
||||
np.empty(0),
|
||||
None,
|
||||
None,
|
||||
{CLASS_NAME_DATA_FIELD: np.empty(0)},
|
||||
)
|
||||
|
||||
xyxy: list[list[float]] = []
|
||||
confidence: list[float] = []
|
||||
class_id: list[int] = []
|
||||
class_name: list[str] = []
|
||||
masks: list[np.ndarray] = []
|
||||
tracker_ids: list[int] = []
|
||||
|
||||
image_width = int(roboflow_result["image"]["width"])
|
||||
image_height = int(roboflow_result["image"]["height"])
|
||||
|
||||
for prediction in roboflow_result["predictions"]:
|
||||
x = prediction["x"]
|
||||
y = prediction["y"]
|
||||
width = prediction["width"]
|
||||
height = prediction["height"]
|
||||
x_min = x - width / 2
|
||||
y_min = y - height / 2
|
||||
x_max = x_min + width
|
||||
y_max = y_min + height
|
||||
|
||||
if "points" not in prediction:
|
||||
xyxy.append([x_min, y_min, x_max, y_max])
|
||||
class_id.append(prediction["class_id"])
|
||||
class_name.append(prediction["class"])
|
||||
confidence.append(prediction["confidence"])
|
||||
if "tracker_id" in prediction:
|
||||
tracker_ids.append(prediction["tracker_id"])
|
||||
elif len(prediction["points"]) >= 3:
|
||||
polygon = np.array(
|
||||
[[point["x"], point["y"]] for point in prediction["points"]], dtype=int
|
||||
)
|
||||
mask = polygon_to_mask(polygon, resolution_wh=(image_width, image_height))
|
||||
xyxy.append([x_min, y_min, x_max, y_max])
|
||||
class_id.append(prediction["class_id"])
|
||||
class_name.append(prediction["class"])
|
||||
confidence.append(prediction["confidence"])
|
||||
masks.append(mask)
|
||||
if "tracker_id" in prediction:
|
||||
tracker_ids.append(prediction["tracker_id"])
|
||||
|
||||
xyxy_arr = np.array(xyxy) if len(xyxy) > 0 else np.empty((0, 4))
|
||||
confidence_arr = np.array(confidence) if len(confidence) > 0 else np.empty(0)
|
||||
class_id_arr = np.array(class_id).astype(int) if len(class_id) > 0 else np.empty(0)
|
||||
class_name_arr = np.array(class_name) if len(class_name) > 0 else np.empty(0)
|
||||
masks_arr = np.array(masks, dtype=bool) if len(masks) > 0 else None
|
||||
tracker_id_arr = np.array(tracker_ids).astype(int) if len(tracker_ids) > 0 else None
|
||||
data: dict[str, np.ndarray] = {CLASS_NAME_DATA_FIELD: class_name_arr}
|
||||
|
||||
return (
|
||||
xyxy_arr,
|
||||
confidence_arr,
|
||||
class_id_arr,
|
||||
masks_arr,
|
||||
tracker_id_arr,
|
||||
data,
|
||||
)
|
||||
|
||||
|
||||
def is_data_equal(data_a: dict[str, np.ndarray], data_b: dict[str, np.ndarray]) -> bool:
|
||||
"""
|
||||
Compares the data payloads of two Detections instances.
|
||||
|
||||
Args:
|
||||
data_a, data_b: The data payloads of the instances.
|
||||
|
||||
Returns:
|
||||
True if the data payloads are equal, False otherwise.
|
||||
"""
|
||||
return set(data_a.keys()) == set(data_b.keys()) and all(
|
||||
np.array_equal(data_a[key], data_b[key]) for key in data_a
|
||||
)
|
||||
|
||||
|
||||
def is_metadata_equal(metadata_a: dict[str, Any], metadata_b: dict[str, Any]) -> bool:
|
||||
"""
|
||||
Compares the metadata payloads of two Detections instances.
|
||||
|
||||
Args:
|
||||
metadata_a, metadata_b: The metadata payloads of the instances.
|
||||
|
||||
Returns:
|
||||
True if the metadata payloads are equal, False otherwise.
|
||||
"""
|
||||
return set(metadata_a.keys()) == set(metadata_b.keys()) and all(
|
||||
np.array_equal(metadata_a[key], metadata_b[key])
|
||||
if (
|
||||
isinstance(metadata_a[key], np.ndarray)
|
||||
and isinstance(metadata_b[key], np.ndarray)
|
||||
)
|
||||
else metadata_a[key] == metadata_b[key]
|
||||
for key in metadata_a
|
||||
)
|
||||
|
||||
|
||||
def merge_data(
|
||||
data_list: list[dict[str, npt.NDArray[np.generic] | list]],
|
||||
) -> dict[str, npt.NDArray[np.generic] | list]:
|
||||
"""
|
||||
Merges the data payloads of a list of Detections instances.
|
||||
|
||||
Warning: Assumes that empty detections were filtered-out before passing data to
|
||||
this function.
|
||||
|
||||
Args:
|
||||
data_list: The data payloads of the Detections instances. Each data payload
|
||||
is a dictionary with the same keys, and the values are either lists or
|
||||
npt.NDArray[np.generic].
|
||||
|
||||
Returns:
|
||||
A single data payload containing the merged data, preserving the original data
|
||||
types (list or npt.NDArray[np.generic]).
|
||||
|
||||
Raises:
|
||||
ValueError: If data values within a single object have different lengths or if
|
||||
dictionaries have different keys.
|
||||
"""
|
||||
if not data_list:
|
||||
return {}
|
||||
|
||||
all_keys_sets = [set(data.keys()) for data in data_list]
|
||||
if not all(keys_set == all_keys_sets[0] for keys_set in all_keys_sets):
|
||||
raise ValueError("All data dictionaries must have the same keys to merge.")
|
||||
|
||||
for data in data_list:
|
||||
lengths = [len(value) for value in data.values()]
|
||||
if len(set(lengths)) > 1:
|
||||
raise ValueError(
|
||||
"All data values within a single object must have equal length."
|
||||
)
|
||||
|
||||
merged_data = {key: [] for key in all_keys_sets[0]}
|
||||
for data in data_list:
|
||||
for key in data:
|
||||
merged_data[key].append(data[key])
|
||||
|
||||
for key in merged_data:
|
||||
if all(isinstance(item, list) for item in merged_data[key]):
|
||||
merged_data[key] = list(chain.from_iterable(merged_data[key]))
|
||||
elif all(isinstance(item, np.ndarray) for item in merged_data[key]):
|
||||
ndim = merged_data[key][0].ndim
|
||||
if ndim == 1:
|
||||
merged_data[key] = np.hstack(merged_data[key])
|
||||
elif ndim > 1:
|
||||
merged_data[key] = np.vstack(merged_data[key])
|
||||
else:
|
||||
raise ValueError(f"Unexpected array dimension for key '{key}'.")
|
||||
else:
|
||||
raise ValueError(
|
||||
f"Inconsistent data types for key '{key}'. Only np.ndarray and list "
|
||||
f"types are allowed."
|
||||
)
|
||||
|
||||
return merged_data
|
||||
|
||||
|
||||
def merge_metadata(metadata_list: list[dict[str, Any]]) -> dict[str, Any]:
|
||||
"""
|
||||
Merge metadata from a list of metadata dictionaries.
|
||||
|
||||
This function combines the metadata dictionaries. If a key appears in more than one
|
||||
dictionary, the values must be identical for the merge to succeed.
|
||||
|
||||
Warning: Assumes that empty detections were filtered-out before passing metadata to
|
||||
this function.
|
||||
|
||||
Args:
|
||||
metadata_list (List[Dict[str, Any]]): A list of metadata dictionaries to merge.
|
||||
|
||||
Returns:
|
||||
Dict[str, Any]: A single merged metadata dictionary.
|
||||
|
||||
Raises:
|
||||
ValueError: If there are conflicting values for the same key or if
|
||||
dictionaries have different keys.
|
||||
"""
|
||||
if not metadata_list:
|
||||
return {}
|
||||
|
||||
all_keys_sets = [set(metadata.keys()) for metadata in metadata_list]
|
||||
if not all(keys_set == all_keys_sets[0] for keys_set in all_keys_sets):
|
||||
raise ValueError("All metadata dictionaries must have the same keys to merge.")
|
||||
|
||||
merged_metadata: dict[str, Any] = {}
|
||||
for metadata in metadata_list:
|
||||
for key, value in metadata.items():
|
||||
if key not in merged_metadata:
|
||||
merged_metadata[key] = value
|
||||
continue
|
||||
|
||||
other_value = merged_metadata[key]
|
||||
if isinstance(value, np.ndarray) and isinstance(other_value, np.ndarray):
|
||||
if not np.array_equal(merged_metadata[key], value):
|
||||
raise ValueError(
|
||||
f"Conflicting metadata for key: '{key}': "
|
||||
"{type(value)}, {type(other_value)}."
|
||||
)
|
||||
elif isinstance(value, np.ndarray) or isinstance(other_value, np.ndarray):
|
||||
# Since [] == np.array([]).
|
||||
raise ValueError(
|
||||
f"Conflicting metadata for key: '{key}': "
|
||||
"{type(value)}, {type(other_value)}."
|
||||
)
|
||||
else:
|
||||
print("hm")
|
||||
if merged_metadata[key] != value:
|
||||
raise ValueError(f"Conflicting metadata for key: '{key}'.")
|
||||
|
||||
return merged_metadata
|
||||
|
||||
|
||||
def get_data_item(
|
||||
data: dict[str, np.ndarray | list],
|
||||
index: int | slice | list[int] | np.ndarray,
|
||||
) -> dict[str, np.ndarray | list]:
|
||||
"""
|
||||
Retrieve a subset of the data dictionary based on the given index.
|
||||
|
||||
Args:
|
||||
data: The data dictionary of the Detections object.
|
||||
index: The index or indices specifying the subset to retrieve.
|
||||
|
||||
Returns:
|
||||
A subset of the data dictionary corresponding to the specified index.
|
||||
"""
|
||||
subset_data: dict[str, np.ndarray | list] = {}
|
||||
for key, value in data.items():
|
||||
if isinstance(value, np.ndarray):
|
||||
subset_data[key] = value[index]
|
||||
elif isinstance(value, list):
|
||||
if isinstance(index, slice):
|
||||
subset_data[key] = value[index]
|
||||
elif isinstance(index, list):
|
||||
subset_data[key] = [value[i] for i in index]
|
||||
elif isinstance(index, np.ndarray):
|
||||
if index.dtype == bool:
|
||||
subset_data[key] = [
|
||||
value[i] for i, index_value in enumerate(index) if index_value
|
||||
]
|
||||
else:
|
||||
subset_data[key] = [value[i] for i in index]
|
||||
elif isinstance(index, int):
|
||||
subset_data[key] = [value[index]]
|
||||
else:
|
||||
raise TypeError(f"Unsupported index type: {type(index)}")
|
||||
else:
|
||||
raise TypeError(f"Unsupported data type for key '{key}': {type(value)}")
|
||||
|
||||
return subset_data
|
||||
|
||||
|
||||
def cross_product(anchors: np.ndarray, vector: Vector) -> np.ndarray:
|
||||
"""
|
||||
Get array of cross products of each anchor with a vector.
|
||||
Args:
|
||||
anchors: Array of anchors of shape (number of anchors, detections, 2)
|
||||
vector: Vector to calculate cross product with
|
||||
|
||||
Returns:
|
||||
Array of cross products of shape (number of anchors, detections)
|
||||
"""
|
||||
vector_at_zero = np.array(
|
||||
[
|
||||
vector.end.x - vector.start.x,
|
||||
vector.end.y - vector.start.y,
|
||||
]
|
||||
)
|
||||
vector_start = np.array([vector.start.x, vector.start.y])
|
||||
return np.cross(vector_at_zero, anchors - vector_start)
|
||||
@@ -0,0 +1,793 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from enum import Enum
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
from supervision.detection.utils.converters import polygon_to_mask
|
||||
from supervision.detection.utils.masks import resize_masks
|
||||
|
||||
|
||||
class OverlapFilter(Enum):
|
||||
"""
|
||||
Enum specifying the strategy for filtering overlapping detections.
|
||||
|
||||
Attributes:
|
||||
NONE: Do not filter detections based on overlap.
|
||||
NON_MAX_SUPPRESSION: Filter detections using non-max suppression. This means,
|
||||
detections that overlap by more than a set threshold will be discarded,
|
||||
except for the one with the highest confidence.
|
||||
NON_MAX_MERGE: Merge detections with non-max merging. This means,
|
||||
detections that overlap by more than a set threshold will be merged
|
||||
into a single detection.
|
||||
"""
|
||||
|
||||
NONE = "none"
|
||||
NON_MAX_SUPPRESSION = "non_max_suppression"
|
||||
NON_MAX_MERGE = "non_max_merge"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
return list(map(lambda c: c.value, cls))
|
||||
|
||||
@classmethod
|
||||
def from_value(cls, value: OverlapFilter | str) -> OverlapFilter:
|
||||
if isinstance(value, cls):
|
||||
return value
|
||||
if isinstance(value, str):
|
||||
value = value.lower()
|
||||
try:
|
||||
return cls(value)
|
||||
except ValueError:
|
||||
raise ValueError(f"Invalid value: {value}. Must be one of {cls.list()}")
|
||||
raise ValueError(
|
||||
f"Invalid value type: {type(value)}. Must be an instance of "
|
||||
f"{cls.__name__} or str."
|
||||
)
|
||||
|
||||
|
||||
class OverlapMetric(Enum):
|
||||
"""
|
||||
Enum specifying the metric for measuring overlap between detections.
|
||||
|
||||
Attributes:
|
||||
IOU: Intersection over Union. A region-overlap metric that compares
|
||||
two shapes (usually bounding boxes or masks) by normalising the
|
||||
shared area with the area of their union.
|
||||
IOS: Intersection over Smaller, a region-overlap metric that compares
|
||||
two shapes (usually bounding boxes or masks) by normalising the
|
||||
shared area with the smaller of the two shapes.
|
||||
"""
|
||||
|
||||
IOU = "IOU"
|
||||
IOS = "IOS"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
return list(map(lambda c: c.value, cls))
|
||||
|
||||
@classmethod
|
||||
def from_value(cls, value: OverlapMetric | str) -> OverlapMetric:
|
||||
if isinstance(value, cls):
|
||||
return value
|
||||
if isinstance(value, str):
|
||||
value = value.lower()
|
||||
try:
|
||||
return cls(value)
|
||||
except ValueError:
|
||||
raise ValueError(f"Invalid value: {value}. Must be one of {cls.list()}")
|
||||
raise ValueError(
|
||||
f"Invalid value type: {type(value)}. Must be an instance of "
|
||||
f"{cls.__name__} or str."
|
||||
)
|
||||
|
||||
|
||||
def box_iou(
|
||||
box_true: list[float] | np.ndarray,
|
||||
box_detection: list[float] | np.ndarray,
|
||||
) -> float:
|
||||
r"""
|
||||
Compute the Intersection over Union (IoU) between two bounding boxes.
|
||||
|
||||
\[
|
||||
\text{IoU} = \frac{|\text{box}_{\text{true}} \cap \text{box}_{\text{detection}}|}{|\text{box}_{\text{true}} \cup \text{box}_{\text{detection}}|}
|
||||
\]
|
||||
|
||||
Note:
|
||||
Use `box_iou` when computing IoU between two individual boxes.
|
||||
For comparing multiple boxes (arrays of boxes), use `box_iou_batch` for better
|
||||
performance.
|
||||
|
||||
Args:
|
||||
box_true (Union[List[float], np.ndarray]): A single bounding box represented as
|
||||
[x_min, y_min, x_max, y_max].
|
||||
box_detection (Union[List[float], np.ndarray]):
|
||||
A single bounding box represented as [x_min, y_min, x_max, y_max].
|
||||
|
||||
Returns:
|
||||
IoU (float): IoU score between the two boxes. Ranges from 0.0 (no overlap)
|
||||
to 1.0 (perfect overlap).
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
box_true = np.array([100, 100, 200, 200])
|
||||
box_detection = np.array([150, 150, 250, 250])
|
||||
|
||||
sv.box_iou(box_true=box_true, box_detection=box_detection)
|
||||
# 0.14285814285714285
|
||||
```
|
||||
""" # noqa: E501
|
||||
box_true = np.array(box_true)
|
||||
box_detection = np.array(box_detection)
|
||||
|
||||
inter_x1 = max(box_true[0], box_detection[0])
|
||||
inter_y1 = max(box_true[1], box_detection[1])
|
||||
inter_x2 = min(box_true[2], box_detection[2])
|
||||
inter_y2 = min(box_true[3], box_detection[3])
|
||||
|
||||
inter_w = max(0, inter_x2 - inter_x1)
|
||||
inter_h = max(0, inter_y2 - inter_y1)
|
||||
|
||||
inter_area = inter_w * inter_h
|
||||
|
||||
area_true = (box_true[2] - box_true[0]) * (box_true[3] - box_true[1])
|
||||
area_detection = (box_detection[2] - box_detection[0]) * (
|
||||
box_detection[3] - box_detection[1]
|
||||
)
|
||||
|
||||
union_area = area_true + area_detection - inter_area
|
||||
|
||||
return inter_area / union_area + 1e-6
|
||||
|
||||
|
||||
def box_iou_batch(
|
||||
boxes_true: np.ndarray,
|
||||
boxes_detection: np.ndarray,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Compute Intersection over Union (IoU) of two sets of bounding boxes -
|
||||
`boxes_true` and `boxes_detection`. Both sets
|
||||
of boxes are expected to be in `(x_min, y_min, x_max, y_max)` format.
|
||||
|
||||
Note:
|
||||
Use `box_iou` when computing IoU between two individual boxes.
|
||||
For comparing multiple boxes (arrays of boxes), use `box_iou_batch` for better
|
||||
performance.
|
||||
|
||||
Args:
|
||||
boxes_true (np.ndarray): 2D `np.ndarray` representing ground-truth boxes.
|
||||
`shape = (N, 4)` where `N` is number of true objects.
|
||||
boxes_detection (np.ndarray): 2D `np.ndarray` representing detection boxes.
|
||||
`shape = (M, 4)` where `M` is number of detected objects.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of boxes from `boxes_true` and `boxes_detection`.
|
||||
`shape = (N, M)` where `N` is number of true objects and
|
||||
`M` is number of detected objects.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
boxes_true = np.array([
|
||||
[100, 100, 200, 200],
|
||||
[300, 300, 400, 400]
|
||||
])
|
||||
boxes_detection = np.array([
|
||||
[150, 150, 250, 250],
|
||||
[320, 320, 420, 420]
|
||||
])
|
||||
|
||||
sv.box_iou_batch(boxes_true=boxes_true, boxes_detection=boxes_detection)
|
||||
# array([
|
||||
# [0.14285714, 0. ],
|
||||
# [0. , 0.47058824]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
|
||||
def box_area(box):
|
||||
return (box[2] - box[0]) * (box[3] - box[1])
|
||||
|
||||
area_true = box_area(boxes_true.T)
|
||||
area_detection = box_area(boxes_detection.T)
|
||||
|
||||
top_left = np.maximum(boxes_true[:, None, :2], boxes_detection[:, :2])
|
||||
bottom_right = np.minimum(boxes_true[:, None, 2:], boxes_detection[:, 2:])
|
||||
|
||||
area_inter = np.prod(np.clip(bottom_right - top_left, a_min=0, a_max=None), 2)
|
||||
|
||||
if overlap_metric == OverlapMetric.IOU:
|
||||
union_area = area_true[:, None] + area_detection - area_inter
|
||||
ious = np.divide(
|
||||
area_inter,
|
||||
union_area,
|
||||
out=np.zeros_like(area_inter, dtype=float),
|
||||
where=union_area != 0,
|
||||
)
|
||||
elif overlap_metric == OverlapMetric.IOS:
|
||||
small_area = np.minimum(area_true[:, None], area_detection)
|
||||
ious = np.divide(
|
||||
area_inter,
|
||||
small_area,
|
||||
out=np.zeros_like(area_inter, dtype=float),
|
||||
where=small_area != 0,
|
||||
)
|
||||
else:
|
||||
raise ValueError(
|
||||
f"overlap_metric {overlap_metric} is not supported, "
|
||||
"only 'IOU' and 'IOS' are supported"
|
||||
)
|
||||
|
||||
ious = np.nan_to_num(ious)
|
||||
return ious
|
||||
|
||||
|
||||
def _jaccard(box_a: list[float], box_b: list[float], is_crowd: bool) -> float:
|
||||
"""
|
||||
Calculate the Jaccard index (intersection over union) between two bounding boxes.
|
||||
If a gt object is marked as "iscrowd", a dt is allowed to match any subregion
|
||||
of the gt. Choosing gt'=intersect(dt,gt). Since by definition union(gt',dt)=dt, computing
|
||||
iou(gt,dt,iscrowd) = iou(gt',dt) = area(intersect(gt,dt)) / area(dt)
|
||||
|
||||
Args:
|
||||
box_a (List[float]): Box coordinates in the format [x, y, width, height].
|
||||
box_b (List[float]): Box coordinates in the format [x, y, width, height].
|
||||
iscrowd (bool): Flag indicating if the second box is a crowd region or not.
|
||||
|
||||
Returns:
|
||||
float: Jaccard index between the two bounding boxes.
|
||||
""" # noqa: E501
|
||||
# Smallest number to avoid division by zero
|
||||
EPS = np.spacing(1)
|
||||
|
||||
xa, ya, x2a, y2a = box_a[0], box_a[1], box_a[0] + box_a[2], box_a[1] + box_a[3]
|
||||
xb, yb, x2b, y2b = box_b[0], box_b[1], box_b[0] + box_b[2], box_b[1] + box_b[3]
|
||||
|
||||
# Innermost left x
|
||||
xi = max(xa, xb)
|
||||
# Innermost right x
|
||||
x2i = min(x2a, x2b)
|
||||
# Same for y
|
||||
yi = max(ya, yb)
|
||||
y2i = min(y2a, y2b)
|
||||
|
||||
# Calculate areas
|
||||
Aa = max(x2a - xa, 0.0) * max(y2a - ya, 0.0)
|
||||
Ab = max(x2b - xb, 0.0) * max(y2b - yb, 0.0)
|
||||
Ai = max(x2i - xi, 0.0) * max(y2i - yi, 0.0)
|
||||
|
||||
if is_crowd:
|
||||
return Ai / (Aa + EPS)
|
||||
|
||||
return Ai / (Aa + Ab - Ai + EPS)
|
||||
|
||||
|
||||
def box_iou_batch_with_jaccard(
|
||||
boxes_true: list[list[float]],
|
||||
boxes_detection: list[list[float]],
|
||||
is_crowd: list[bool],
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Calculate the intersection over union (IoU) between detection bounding boxes (dt)
|
||||
and ground-truth bounding boxes (gt).
|
||||
Reference: https://github.com/rafaelpadilla/review_object_detection_metrics
|
||||
|
||||
Args:
|
||||
boxes_true (List[List[float]]): List of ground-truth bounding boxes in the \
|
||||
format [x, y, width, height].
|
||||
boxes_detection (List[List[float]]): List of detection bounding boxes in the \
|
||||
format [x, y, width, height].
|
||||
is_crowd (List[bool]): List indicating if each ground-truth bounding box \
|
||||
is a crowd region or not.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Array of IoU values of shape (len(dt), len(gt)).
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
boxes_true = [
|
||||
[10, 20, 30, 40], # x, y, w, h
|
||||
[15, 25, 35, 45]
|
||||
]
|
||||
boxes_detection = [
|
||||
[12, 22, 28, 38],
|
||||
[16, 26, 36, 46]
|
||||
]
|
||||
is_crowd = [False, False]
|
||||
|
||||
ious = sv.box_iou_batch_with_jaccard(
|
||||
boxes_true=boxes_true,
|
||||
boxes_detection=boxes_detection,
|
||||
is_crowd=is_crowd
|
||||
)
|
||||
# array([
|
||||
# [0.8866..., 0.4960...],
|
||||
# [0.4000..., 0.8622...]
|
||||
# ])
|
||||
```
|
||||
"""
|
||||
assert len(is_crowd) == len(boxes_true), (
|
||||
"`is_crowd` must have the same length as `boxes_true`"
|
||||
)
|
||||
if len(boxes_detection) == 0 or len(boxes_true) == 0:
|
||||
return np.array([])
|
||||
ious = np.zeros((len(boxes_detection), len(boxes_true)), dtype=np.float64)
|
||||
for g_idx, g in enumerate(boxes_true):
|
||||
for d_idx, d in enumerate(boxes_detection):
|
||||
ious[d_idx, g_idx] = _jaccard(d, g, is_crowd[g_idx])
|
||||
return ious
|
||||
|
||||
|
||||
def oriented_box_iou_batch(
|
||||
boxes_true: np.ndarray, boxes_detection: np.ndarray
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Compute Intersection over Union (IoU) of two sets of oriented bounding boxes -
|
||||
`boxes_true` and `boxes_detection`. Both sets of boxes are expected to be in
|
||||
`((x1, y1), (x2, y2), (x3, y3), (x4, y4))` format.
|
||||
|
||||
Args:
|
||||
boxes_true (np.ndarray): a `np.ndarray` representing ground-truth boxes.
|
||||
`shape = (N, 4, 2)` where `N` is number of true objects.
|
||||
boxes_detection (np.ndarray): a `np.ndarray` representing detection boxes.
|
||||
`shape = (M, 4, 2)` where `M` is number of detected objects.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of boxes from `boxes_true` and `boxes_detection`.
|
||||
`shape = (N, M)` where `N` is number of true objects and
|
||||
`M` is number of detected objects.
|
||||
"""
|
||||
|
||||
boxes_true = boxes_true.reshape(-1, 4, 2)
|
||||
boxes_detection = boxes_detection.reshape(-1, 4, 2)
|
||||
|
||||
max_height = int(max(boxes_true[:, :, 0].max(), boxes_detection[:, :, 0].max()) + 1)
|
||||
# adding 1 because we are 0-indexed
|
||||
max_width = int(max(boxes_true[:, :, 1].max(), boxes_detection[:, :, 1].max()) + 1)
|
||||
|
||||
mask_true = np.zeros((boxes_true.shape[0], max_height, max_width))
|
||||
for i, box_true in enumerate(boxes_true):
|
||||
mask_true[i] = polygon_to_mask(box_true, (max_width, max_height))
|
||||
|
||||
mask_detection = np.zeros((boxes_detection.shape[0], max_height, max_width))
|
||||
for i, box_detection in enumerate(boxes_detection):
|
||||
mask_detection[i] = polygon_to_mask(box_detection, (max_width, max_height))
|
||||
|
||||
ious = mask_iou_batch(mask_true, mask_detection)
|
||||
return ious
|
||||
|
||||
|
||||
def _mask_iou_batch_split(
|
||||
masks_true: np.ndarray,
|
||||
masks_detection: np.ndarray,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Internal function.
|
||||
Compute Intersection over Union (IoU) of two sets of masks -
|
||||
`masks_true` and `masks_detection`.
|
||||
|
||||
Args:
|
||||
masks_true (np.ndarray): 3D `np.ndarray` representing ground-truth masks.
|
||||
masks_detection (np.ndarray): 3D `np.ndarray` representing detection masks.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of masks from `masks_true` and `masks_detection`.
|
||||
"""
|
||||
intersection_area = np.logical_and(masks_true[:, None], masks_detection).sum(
|
||||
axis=(2, 3)
|
||||
)
|
||||
|
||||
masks_true_area = masks_true.sum(axis=(1, 2)) # (area1, area2, ...)
|
||||
masks_detection_area = masks_detection.sum(axis=(1, 2)) # (area1)
|
||||
|
||||
if overlap_metric == OverlapMetric.IOU:
|
||||
union_area = masks_true_area[:, None] + masks_detection_area - intersection_area
|
||||
ious = np.divide(
|
||||
intersection_area,
|
||||
union_area,
|
||||
out=np.zeros_like(intersection_area, dtype=float),
|
||||
where=union_area != 0,
|
||||
)
|
||||
elif overlap_metric == OverlapMetric.IOS:
|
||||
# ios = intersection_area / min(area1, area2)
|
||||
small_area = np.minimum(masks_true_area[:, None], masks_detection_area)
|
||||
ious = np.divide(
|
||||
intersection_area,
|
||||
small_area,
|
||||
out=np.zeros_like(intersection_area, dtype=float),
|
||||
where=small_area != 0,
|
||||
)
|
||||
else:
|
||||
raise ValueError(
|
||||
f"overlap_metric {overlap_metric} is not supported, "
|
||||
"only 'IOU' and 'IOS' are supported"
|
||||
)
|
||||
|
||||
ious = np.nan_to_num(ious)
|
||||
return ious
|
||||
|
||||
|
||||
def mask_iou_batch(
|
||||
masks_true: np.ndarray,
|
||||
masks_detection: np.ndarray,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
memory_limit: int = 1024 * 5,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Compute Intersection over Union (IoU) of two sets of masks -
|
||||
`masks_true` and `masks_detection`.
|
||||
|
||||
Args:
|
||||
masks_true (np.ndarray): 3D `np.ndarray` representing ground-truth masks.
|
||||
masks_detection (np.ndarray): 3D `np.ndarray` representing detection masks.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
memory_limit (int): memory limit in MB, default is 1024 * 5 MB (5GB).
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of masks from `masks_true` and `masks_detection`.
|
||||
"""
|
||||
memory = (
|
||||
masks_true.shape[0]
|
||||
* masks_true.shape[1]
|
||||
* masks_true.shape[2]
|
||||
* masks_detection.shape[0]
|
||||
/ 1024
|
||||
/ 1024
|
||||
)
|
||||
if memory <= memory_limit:
|
||||
return _mask_iou_batch_split(masks_true, masks_detection, overlap_metric)
|
||||
|
||||
ious = []
|
||||
step = max(
|
||||
memory_limit
|
||||
* 1024
|
||||
* 1024
|
||||
// (
|
||||
masks_detection.shape[0]
|
||||
* masks_detection.shape[1]
|
||||
* masks_detection.shape[2]
|
||||
),
|
||||
1,
|
||||
)
|
||||
for i in range(0, masks_true.shape[0], step):
|
||||
ious.append(
|
||||
_mask_iou_batch_split(
|
||||
masks_true[i : i + step], masks_detection, overlap_metric
|
||||
)
|
||||
)
|
||||
|
||||
return np.vstack(ious)
|
||||
|
||||
|
||||
def mask_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
mask_dimension: int = 640,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on segmentation predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): A 2D array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or
|
||||
`(N, 6)`, where N is the number of predictions.
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
mask_dimension (int): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after
|
||||
non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the closed
|
||||
range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
sort_index = predictions[:, 4].argsort()[::-1]
|
||||
predictions = predictions[sort_index]
|
||||
masks = masks[sort_index]
|
||||
masks_resized = resize_masks(masks, mask_dimension)
|
||||
ious = mask_iou_batch(masks_resized, masks_resized, overlap_metric)
|
||||
categories = predictions[:, 5]
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
for i in range(rows):
|
||||
if keep[i]:
|
||||
condition = (ious[i] > iou_threshold) & (categories[i] == categories)
|
||||
keep[i + 1 :] = np.where(condition[i + 1 :], False, keep[i + 1 :])
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def box_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on object detection predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): An array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after n
|
||||
on-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the
|
||||
closed range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
# add column #5 - category filled with zeros for agnostic nms
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
# sort predictions column #4 - score
|
||||
sort_index = np.flip(predictions[:, 4].argsort())
|
||||
predictions = predictions[sort_index]
|
||||
|
||||
boxes = predictions[:, :4]
|
||||
categories = predictions[:, 5]
|
||||
ious = box_iou_batch(boxes, boxes, overlap_metric)
|
||||
ious = ious - np.eye(rows)
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
|
||||
for index, (iou, category) in enumerate(zip(ious, categories)):
|
||||
if not keep[index]:
|
||||
continue
|
||||
|
||||
# drop detections with iou > iou_threshold and
|
||||
# same category as current detections
|
||||
condition = (iou > iou_threshold) & (categories == category)
|
||||
keep = keep & ~condition
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def _group_overlapping_masks(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
masks: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging to avoid detecting too many
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
and the confidence scores.
|
||||
masks (npt.NDArray[np.float64]): A 3D array of binary masks corresponding to
|
||||
the predictions.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
merge_groups: list[list[int]] = []
|
||||
|
||||
scores = predictions[:, 4]
|
||||
order = scores.argsort()
|
||||
|
||||
while len(order) > 0:
|
||||
idx = int(order[-1])
|
||||
|
||||
order = order[:-1]
|
||||
if len(order) == 0:
|
||||
merge_groups.append([idx])
|
||||
break
|
||||
|
||||
merge_candidate = masks[idx][None, ...]
|
||||
candidate_groups = [idx]
|
||||
while len(order) > 0:
|
||||
ious = mask_iou_batch(masks[order], merge_candidate, overlap_metric)
|
||||
above_threshold: np.ndarray = ious.flatten() >= iou_threshold
|
||||
if not above_threshold.any():
|
||||
break
|
||||
above_idx = order[above_threshold]
|
||||
merge_candidate = np.logical_or.reduce(
|
||||
np.concatenate([masks[above_idx], merge_candidate]),
|
||||
axis=0,
|
||||
keepdims=True,
|
||||
)
|
||||
candidate_groups.extend(np.flip(above_idx).tolist())
|
||||
order = order[~above_threshold]
|
||||
|
||||
merge_groups.append(candidate_groups)
|
||||
return merge_groups
|
||||
|
||||
|
||||
def mask_non_max_merge(
|
||||
predictions: np.ndarray,
|
||||
masks: np.ndarray,
|
||||
iou_threshold: float = 0.5,
|
||||
mask_dimension: int = 640,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Perform Non-Maximum Merging (NMM) on segmentation predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): A 2D array of object detection predictions in
|
||||
the format of `(x_min, y_min, x_max, y_max, score)`
|
||||
or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or
|
||||
`(N, 6)`, where N is the number of predictions.
|
||||
masks (np.ndarray): A 3D array of binary masks corresponding to the predictions.
|
||||
Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the
|
||||
dimensions of each mask.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression.
|
||||
mask_dimension (int): The dimension to which the masks should be
|
||||
resized before computing IOU values. Defaults to 640.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after
|
||||
non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the closed
|
||||
range from `0` to `1`.
|
||||
"""
|
||||
masks_resized = resize_masks(masks, mask_dimension)
|
||||
if predictions.shape[1] == 5:
|
||||
return _group_overlapping_masks(
|
||||
predictions, masks_resized, iou_threshold, overlap_metric
|
||||
)
|
||||
|
||||
category_ids = predictions[:, 5]
|
||||
merge_groups = []
|
||||
for category_id in np.unique(category_ids):
|
||||
curr_indices = np.where(category_ids == category_id)[0]
|
||||
merge_class_groups = _group_overlapping_masks(
|
||||
predictions[curr_indices],
|
||||
masks_resized[curr_indices],
|
||||
iou_threshold,
|
||||
overlap_metric,
|
||||
)
|
||||
|
||||
for merge_class_group in merge_class_groups:
|
||||
merge_groups.append(curr_indices[merge_class_group].tolist())
|
||||
|
||||
for merge_group in merge_groups:
|
||||
if len(merge_group) == 0:
|
||||
raise ValueError(
|
||||
f"Empty group detected when non-max-merging detections: {merge_groups}"
|
||||
)
|
||||
return merge_groups
|
||||
|
||||
|
||||
def _group_overlapping_boxes(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging to avoid detecting too many
|
||||
overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
and the confidence scores.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
merge_groups: list[list[int]] = []
|
||||
|
||||
scores = predictions[:, 4]
|
||||
order = scores.argsort()
|
||||
|
||||
while len(order) > 0:
|
||||
idx = int(order[-1])
|
||||
|
||||
order = order[:-1]
|
||||
if len(order) == 0:
|
||||
merge_groups.append([idx])
|
||||
break
|
||||
|
||||
merge_candidate = np.expand_dims(predictions[idx], axis=0)
|
||||
ious = box_iou_batch(
|
||||
predictions[order][:, :4], merge_candidate[:, :4], overlap_metric
|
||||
)
|
||||
ious = ious.flatten()
|
||||
|
||||
above_threshold = ious >= iou_threshold
|
||||
merge_group = [idx, *np.flip(order[above_threshold]).tolist()]
|
||||
merge_groups.append(merge_group)
|
||||
order = order[~above_threshold]
|
||||
return merge_groups
|
||||
|
||||
|
||||
def box_non_max_merge(
|
||||
predictions: npt.NDArray[np.float64],
|
||||
iou_threshold: float = 0.5,
|
||||
overlap_metric: OverlapMetric = OverlapMetric.IOU,
|
||||
) -> list[list[int]]:
|
||||
"""
|
||||
Apply greedy version of non-maximum merging per category to avoid detecting
|
||||
too many overlapping bounding boxes for a given object.
|
||||
|
||||
Args:
|
||||
predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` or `(n, 6)`
|
||||
containing the bounding boxes coordinates in format `[x1, y1, x2, y2]`,
|
||||
the confidence scores and class_ids. Omit class_id column to allow
|
||||
detections of different classes to be merged.
|
||||
iou_threshold (float): The intersection-over-union threshold
|
||||
to use for non-maximum suppression. Defaults to 0.5.
|
||||
overlap_metric (OverlapMetric): Metric used for matching detections in slices.
|
||||
|
||||
Returns:
|
||||
list[list[int]]: Groups of prediction indices be merged.
|
||||
Each group may have 1 or more elements.
|
||||
"""
|
||||
if predictions.shape[1] == 5:
|
||||
return _group_overlapping_boxes(predictions, iou_threshold, overlap_metric)
|
||||
|
||||
category_ids = predictions[:, 5]
|
||||
merge_groups = []
|
||||
for category_id in np.unique(category_ids):
|
||||
curr_indices = np.where(category_ids == category_id)[0]
|
||||
merge_class_groups = _group_overlapping_boxes(
|
||||
predictions[curr_indices], iou_threshold, overlap_metric
|
||||
)
|
||||
|
||||
for merge_class_group in merge_class_groups:
|
||||
merge_groups.append(curr_indices[merge_class_group].tolist())
|
||||
|
||||
for merge_group in merge_groups:
|
||||
if len(merge_group) == 0:
|
||||
raise ValueError(
|
||||
f"Empty group detected when non-max-merging detections: {merge_groups}"
|
||||
)
|
||||
return merge_groups
|
||||
@@ -0,0 +1,262 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
|
||||
|
||||
def move_masks(
|
||||
masks: npt.NDArray[np.bool_],
|
||||
offset: npt.NDArray[np.int32],
|
||||
resolution_wh: tuple[int, int],
|
||||
) -> npt.NDArray[np.bool_]:
|
||||
"""
|
||||
Offset the masks in an array by the specified (x, y) amount.
|
||||
|
||||
Args:
|
||||
masks (npt.NDArray[np.bool_]): A 3D array of binary masks corresponding to the
|
||||
predictions. Shape: `(N, H, W)`, where N is the number of predictions, and
|
||||
H, W are the dimensions of each mask.
|
||||
offset (npt.NDArray[np.int32]): An array of shape `(2,)` containing int values
|
||||
`[dx, dy]`. Supports both positive and negative values for bidirectional
|
||||
movement.
|
||||
resolution_wh (Tuple[int, int]): The width and height of the desired mask
|
||||
resolution.
|
||||
|
||||
Returns:
|
||||
(npt.NDArray[np.bool_]) repositioned masks, optionally padded to the specified
|
||||
shape.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([[[False, False, False, False],
|
||||
[False, True, True, False],
|
||||
[False, True, True, False],
|
||||
[False, False, False, False]]], dtype=bool)
|
||||
|
||||
offset = np.array([1, 1])
|
||||
sv.move_masks(mask, offset, resolution_wh=(4, 4))
|
||||
# array([[[False, False, False, False],
|
||||
# [False, False, False, False],
|
||||
# [False, False, True, True],
|
||||
# [False, False, True, True]]], dtype=bool)
|
||||
|
||||
offset = np.array([-2, 2])
|
||||
sv.move_masks(mask, offset, resolution_wh=(4, 4))
|
||||
# array([[[False, False, False, False],
|
||||
# [False, False, False, False],
|
||||
# [False, False, False, False],
|
||||
# [True, False, False, False]]], dtype=bool)
|
||||
```
|
||||
"""
|
||||
mask_array = np.full((masks.shape[0], resolution_wh[1], resolution_wh[0]), False)
|
||||
|
||||
if offset[0] < 0:
|
||||
source_x_start = -offset[0]
|
||||
source_x_end = min(masks.shape[2], resolution_wh[0] - offset[0])
|
||||
destination_x_start = 0
|
||||
destination_x_end = min(resolution_wh[0], masks.shape[2] + offset[0])
|
||||
else:
|
||||
source_x_start = 0
|
||||
source_x_end = min(masks.shape[2], resolution_wh[0] - offset[0])
|
||||
destination_x_start = offset[0]
|
||||
destination_x_end = offset[0] + source_x_end - source_x_start
|
||||
|
||||
if offset[1] < 0:
|
||||
source_y_start = -offset[1]
|
||||
source_y_end = min(masks.shape[1], resolution_wh[1] - offset[1])
|
||||
destination_y_start = 0
|
||||
destination_y_end = min(resolution_wh[1], masks.shape[1] + offset[1])
|
||||
else:
|
||||
source_y_start = 0
|
||||
source_y_end = min(masks.shape[1], resolution_wh[1] - offset[1])
|
||||
destination_y_start = offset[1]
|
||||
destination_y_end = offset[1] + source_y_end - source_y_start
|
||||
|
||||
if source_x_end > source_x_start and source_y_end > source_y_start:
|
||||
mask_array[
|
||||
:,
|
||||
destination_y_start:destination_y_end,
|
||||
destination_x_start:destination_x_end,
|
||||
] = masks[:, source_y_start:source_y_end, source_x_start:source_x_end]
|
||||
|
||||
return mask_array
|
||||
|
||||
|
||||
def calculate_masks_centroids(masks: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Calculate the centroids of binary masks in a tensor.
|
||||
|
||||
Parameters:
|
||||
masks (np.ndarray): A 3D NumPy array of shape (num_masks, height, width).
|
||||
Each 2D array in the tensor represents a binary mask.
|
||||
|
||||
Returns:
|
||||
A 2D NumPy array of shape (num_masks, 2), where each row contains the x and y
|
||||
coordinates (in that order) of the centroid of the corresponding mask.
|
||||
"""
|
||||
num_masks, height, width = masks.shape
|
||||
total_pixels = masks.sum(axis=(1, 2))
|
||||
|
||||
# offset for 1-based indexing
|
||||
vertical_indices, horizontal_indices = np.indices((height, width)) + 0.5
|
||||
# avoid division by zero for empty masks
|
||||
total_pixels[total_pixels == 0] = 1
|
||||
|
||||
def sum_over_mask(indices: np.ndarray, axis: tuple) -> np.ndarray:
|
||||
return np.tensordot(masks, indices, axes=axis)
|
||||
|
||||
aggregation_axis = ([1, 2], [0, 1])
|
||||
centroid_x = sum_over_mask(horizontal_indices, aggregation_axis) / total_pixels
|
||||
centroid_y = sum_over_mask(vertical_indices, aggregation_axis) / total_pixels
|
||||
|
||||
return np.column_stack((centroid_x, centroid_y)).astype(int)
|
||||
|
||||
|
||||
def contains_holes(mask: npt.NDArray[np.bool_]) -> bool:
|
||||
"""
|
||||
Checks if the binary mask contains holes (background pixels fully enclosed by
|
||||
foreground pixels).
|
||||
|
||||
Args:
|
||||
mask (npt.NDArray[np.bool_]): 2D binary mask where `True` indicates foreground
|
||||
object and `False` indicates background.
|
||||
|
||||
Returns:
|
||||
True if holes are detected, False otherwise.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 1, 0, 1, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 0, 0, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_holes(mask=mask)
|
||||
# True
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 1, 1, 1, 0],
|
||||
[0, 0, 0, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_holes(mask=mask)
|
||||
# False
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
mask_uint8 = mask.astype(np.uint8)
|
||||
_, hierarchy = cv2.findContours(mask_uint8, cv2.RETR_CCOMP, cv2.CHAIN_APPROX_SIMPLE)
|
||||
|
||||
if hierarchy is not None:
|
||||
parent_contour_index = 3
|
||||
for h in hierarchy[0]:
|
||||
if h[parent_contour_index] != -1:
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def contains_multiple_segments(
|
||||
mask: npt.NDArray[np.bool_], connectivity: int = 4
|
||||
) -> bool:
|
||||
"""
|
||||
Checks if the binary mask contains multiple unconnected foreground segments.
|
||||
|
||||
Args:
|
||||
mask (npt.NDArray[np.bool_]): 2D binary mask where `True` indicates foreground
|
||||
object and `False` indicates background.
|
||||
connectivity (int) : Default: 4 is 4-way connectivity, which means that
|
||||
foreground pixels are the part of the same segment/component
|
||||
if their edges touch.
|
||||
Alternatively: 8 for 8-way connectivity, when foreground pixels are
|
||||
connected by their edges or corners touch.
|
||||
|
||||
Returns:
|
||||
True when the mask contains multiple not connected components, False otherwise.
|
||||
|
||||
Raises:
|
||||
ValueError: If connectivity(int) parameter value is not 4 or 8.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 0, 1, 1],
|
||||
[0, 1, 1, 0, 1, 1],
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0],
|
||||
[0, 1, 1, 1, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_multiple_segments(mask=mask, connectivity=4)
|
||||
# True
|
||||
|
||||
mask = np.array([
|
||||
[0, 0, 0, 0, 0, 0],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 1, 1, 1, 1, 1],
|
||||
[0, 0, 0, 0, 0, 0]
|
||||
]).astype(bool)
|
||||
|
||||
sv.contains_multiple_segments(mask=mask, connectivity=4)
|
||||
# False
|
||||
```
|
||||
|
||||
{ align=center width="800" }
|
||||
""" # noqa E501 // docs
|
||||
if connectivity != 4 and connectivity != 8:
|
||||
raise ValueError(
|
||||
"Incorrect connectivity value. Possible connectivity values: 4 or 8."
|
||||
)
|
||||
mask_uint8 = mask.astype(np.uint8)
|
||||
labels = np.zeros_like(mask_uint8, dtype=np.int32)
|
||||
number_of_labels, _ = cv2.connectedComponents(
|
||||
mask_uint8, labels, connectivity=connectivity
|
||||
)
|
||||
return number_of_labels > 2
|
||||
|
||||
|
||||
def resize_masks(masks: np.ndarray, max_dimension: int = 640) -> np.ndarray:
|
||||
"""
|
||||
Resize all masks in the array to have a maximum dimension of max_dimension,
|
||||
maintaining aspect ratio.
|
||||
|
||||
Args:
|
||||
masks (np.ndarray): 3D array of binary masks with shape (N, H, W).
|
||||
max_dimension (int): The maximum dimension for the resized masks.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Array of resized masks.
|
||||
"""
|
||||
max_height = np.max(masks.shape[1])
|
||||
max_width = np.max(masks.shape[2])
|
||||
scale = min(max_dimension / max_height, max_dimension / max_width)
|
||||
|
||||
new_height = int(scale * max_height)
|
||||
new_width = int(scale * max_width)
|
||||
|
||||
x = np.linspace(0, max_width - 1, new_width).astype(int)
|
||||
y = np.linspace(0, max_height - 1, new_height).astype(int)
|
||||
xv, yv = np.meshgrid(x, y)
|
||||
|
||||
resized_masks = masks[:, yv, xv]
|
||||
|
||||
return resized_masks.reshape(masks.shape[0], new_height, new_width)
|
||||
@@ -0,0 +1,87 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def filter_polygons_by_area(
|
||||
polygons: list[np.ndarray],
|
||||
min_area: float | None = None,
|
||||
max_area: float | None = None,
|
||||
) -> list[np.ndarray]:
|
||||
"""
|
||||
Filters a list of polygons based on their area.
|
||||
|
||||
Parameters:
|
||||
polygons (List[np.ndarray]): A list of polygons, where each polygon is
|
||||
represented by a NumPy array of shape `(N, 2)`,
|
||||
containing the `x`, `y` coordinates of the points.
|
||||
min_area (Optional[float]): The minimum area threshold.
|
||||
Only polygons with an area greater than or equal to this value
|
||||
will be included in the output. If set to None,
|
||||
no minimum area constraint will be applied.
|
||||
max_area (Optional[float]): The maximum area threshold.
|
||||
Only polygons with an area less than or equal to this value
|
||||
will be included in the output. If set to None,
|
||||
no maximum area constraint will be applied.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A new list of polygons containing only those with
|
||||
areas within the specified thresholds.
|
||||
"""
|
||||
if min_area is None and max_area is None:
|
||||
return polygons
|
||||
ares = [cv2.contourArea(polygon) for polygon in polygons]
|
||||
return [
|
||||
polygon
|
||||
for polygon, area in zip(polygons, ares)
|
||||
if (min_area is None or area >= min_area)
|
||||
and (max_area is None or area <= max_area)
|
||||
]
|
||||
|
||||
|
||||
def approximate_polygon(
|
||||
polygon: np.ndarray, percentage: float, epsilon_step: float = 0.05
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Approximates a given polygon by reducing a certain percentage of points.
|
||||
|
||||
This function uses the Ramer-Douglas-Peucker algorithm to simplify the input
|
||||
polygon by reducing the number of points
|
||||
while preserving the general shape.
|
||||
|
||||
Parameters:
|
||||
polygon (np.ndarray): A 2D NumPy array of shape `(N, 2)` containing
|
||||
the `x`, `y` coordinates of the input polygon's points.
|
||||
percentage (float): The percentage of points to be removed from the
|
||||
input polygon, in the range `[0, 1)`.
|
||||
epsilon_step (float): Approximation accuracy step.
|
||||
Epsilon is the maximum distance between the original curve
|
||||
and its approximation.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A new 2D NumPy array of shape `(M, 2)`,
|
||||
where `M <= N * (1 - percentage)`, containing
|
||||
the `x`, `y` coordinates of the
|
||||
approximated polygon's points.
|
||||
"""
|
||||
|
||||
if percentage < 0 or percentage >= 1:
|
||||
raise ValueError("Percentage must be in the range [0, 1).")
|
||||
|
||||
target_points = max(int(len(polygon) * (1 - percentage)), 3)
|
||||
|
||||
if len(polygon) <= target_points:
|
||||
return polygon
|
||||
|
||||
epsilon = 0
|
||||
approximated_points = polygon
|
||||
while True:
|
||||
epsilon += epsilon_step
|
||||
new_approximated_points = cv2.approxPolyDP(polygon, epsilon, closed=True)
|
||||
if len(new_approximated_points) > target_points:
|
||||
approximated_points = new_approximated_points
|
||||
else:
|
||||
break
|
||||
|
||||
return np.squeeze(approximated_points, axis=1)
|
||||
+435
-33
@@ -1,12 +1,19 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import base64
|
||||
import io
|
||||
import json
|
||||
import re
|
||||
from enum import Enum
|
||||
from typing import Any, Dict, List, Optional, Tuple, Union
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
from supervision.detection.utils import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.detection.utils.boxes import denormalize_boxes
|
||||
from supervision.detection.utils.converters import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.utils.internal import deprecated
|
||||
from supervision.validators import validate_resolution
|
||||
|
||||
|
||||
@deprecated(
|
||||
@@ -14,33 +21,110 @@ from supervision.utils.internal import deprecated
|
||||
"`supervision-0.31.0`. Use VLM instead."
|
||||
)
|
||||
class LMM(Enum):
|
||||
"""
|
||||
Enum specifying supported Large Multimodal Models (LMMs).
|
||||
|
||||
Attributes:
|
||||
PALIGEMMA: Google's PaliGemma vision-language model.
|
||||
FLORENCE_2: Microsoft's Florence-2 vision-language model.
|
||||
QWEN_2_5_VL: Qwen2.5-VL open vision-language model from Alibaba.
|
||||
GOOGLE_GEMINI_2_0: Google Gemini 2.0 vision-language model.
|
||||
GOOGLE_GEMINI_2_5: Google Gemini 2.5 vision-language model.
|
||||
MOONDREAM: The Moondream vision-language model.
|
||||
"""
|
||||
|
||||
PALIGEMMA = "paligemma"
|
||||
FLORENCE_2 = "florence_2"
|
||||
QWEN_2_5_VL = "qwen_2_5_vl"
|
||||
GOOGLE_GEMINI_2_0 = "gemini_2_0"
|
||||
GOOGLE_GEMINI_2_5 = "gemini_2_5"
|
||||
MOONDREAM = "moondream"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
return list(map(lambda c: c.value, cls))
|
||||
|
||||
@classmethod
|
||||
def from_value(cls, value: LMM | str) -> LMM:
|
||||
if isinstance(value, cls):
|
||||
return value
|
||||
if isinstance(value, str):
|
||||
value = value.lower()
|
||||
try:
|
||||
return cls(value)
|
||||
except ValueError:
|
||||
raise ValueError(f"Invalid value: {value}. Must be one of {cls.list()}")
|
||||
raise ValueError(
|
||||
f"Invalid value type: {type(value)}. Must be an instance of "
|
||||
f"{cls.__name__} or str."
|
||||
)
|
||||
|
||||
|
||||
class VLM(Enum):
|
||||
"""
|
||||
Enum specifying supported Vision-Language Models (VLMs).
|
||||
|
||||
Attributes:
|
||||
PALIGEMMA: Google's PaliGemma vision-language model.
|
||||
FLORENCE_2: Microsoft's Florence-2 vision-language model.
|
||||
QWEN_2_5_VL: Qwen2.5-VL open vision-language model from Alibaba.
|
||||
GOOGLE_GEMINI_2_0: Google Gemini 2.0 vision-language model.
|
||||
GOOGLE_GEMINI_2_5: Google Gemini 2.5 vision-language model.
|
||||
MOONDREAM: The Moondream vision-language model.
|
||||
"""
|
||||
|
||||
PALIGEMMA = "paligemma"
|
||||
FLORENCE_2 = "florence_2"
|
||||
QWEN_2_5_VL = "qwen_2_5_vl"
|
||||
GOOGLE_GEMINI_2_0 = "gemini_2_0"
|
||||
GOOGLE_GEMINI_2_5 = "gemini_2_5"
|
||||
MOONDREAM = "moondream"
|
||||
|
||||
@classmethod
|
||||
def list(cls):
|
||||
return list(map(lambda c: c.value, cls))
|
||||
|
||||
@classmethod
|
||||
def from_value(cls, value: VLM | str) -> VLM:
|
||||
if isinstance(value, cls):
|
||||
return value
|
||||
if isinstance(value, str):
|
||||
value = value.lower()
|
||||
try:
|
||||
return cls(value)
|
||||
except ValueError:
|
||||
raise ValueError(f"Invalid value: {value}. Must be one of {cls.list()}")
|
||||
raise ValueError(
|
||||
f"Invalid value type: {type(value)}. Must be an instance of "
|
||||
f"{cls.__name__} or str."
|
||||
)
|
||||
|
||||
|
||||
RESULT_TYPES: Dict[VLM, type] = {
|
||||
RESULT_TYPES: dict[VLM, type] = {
|
||||
VLM.PALIGEMMA: str,
|
||||
VLM.FLORENCE_2: dict,
|
||||
VLM.QWEN_2_5_VL: str,
|
||||
VLM.GOOGLE_GEMINI_2_0: str,
|
||||
VLM.GOOGLE_GEMINI_2_5: str,
|
||||
VLM.MOONDREAM: dict,
|
||||
}
|
||||
|
||||
REQUIRED_ARGUMENTS: Dict[VLM, List[str]] = {
|
||||
REQUIRED_ARGUMENTS: dict[VLM, list[str]] = {
|
||||
VLM.PALIGEMMA: ["resolution_wh"],
|
||||
VLM.FLORENCE_2: ["resolution_wh"],
|
||||
VLM.QWEN_2_5_VL: ["input_wh", "resolution_wh"],
|
||||
VLM.GOOGLE_GEMINI_2_0: ["resolution_wh"],
|
||||
VLM.GOOGLE_GEMINI_2_5: ["resolution_wh"],
|
||||
VLM.MOONDREAM: ["resolution_wh"],
|
||||
}
|
||||
|
||||
ALLOWED_ARGUMENTS: Dict[VLM, List[str]] = {
|
||||
ALLOWED_ARGUMENTS: dict[VLM, list[str]] = {
|
||||
VLM.PALIGEMMA: ["resolution_wh", "classes"],
|
||||
VLM.FLORENCE_2: ["resolution_wh"],
|
||||
VLM.QWEN_2_5_VL: ["input_wh", "resolution_wh", "classes"],
|
||||
VLM.GOOGLE_GEMINI_2_0: ["resolution_wh", "classes"],
|
||||
VLM.GOOGLE_GEMINI_2_5: ["resolution_wh", "classes"],
|
||||
VLM.MOONDREAM: ["resolution_wh"],
|
||||
}
|
||||
|
||||
SUPPORTED_TASKS_FLORENCE_2 = [
|
||||
@@ -57,9 +141,21 @@ SUPPORTED_TASKS_FLORENCE_2 = [
|
||||
]
|
||||
|
||||
|
||||
def validate_vlm_parameters(
|
||||
vlm: Union[VLM, str], result: Any, kwargs: Dict[str, Any]
|
||||
) -> VLM:
|
||||
def validate_vlm_parameters(vlm: VLM | str, result: Any, kwargs: dict[str, Any]) -> VLM:
|
||||
"""
|
||||
Validates the parameters and result type for a given Vision-Language Model (VLM).
|
||||
|
||||
Args:
|
||||
vlm: The VLM enum or string specifying the model.
|
||||
result: The result object to validate (type depends on VLM).
|
||||
kwargs: Dictionary of arguments to validate against required/allowed lists.
|
||||
|
||||
Returns:
|
||||
VLM: The validated VLM enum value.
|
||||
|
||||
Raises:
|
||||
ValueError: If the VLM, result type, or arguments are invalid.
|
||||
"""
|
||||
if isinstance(vlm, str):
|
||||
try:
|
||||
vlm = VLM(vlm.lower())
|
||||
@@ -87,15 +183,15 @@ def validate_vlm_parameters(
|
||||
|
||||
|
||||
def from_paligemma(
|
||||
result: str, resolution_wh: Tuple[int, int], classes: Optional[List[str]] = None
|
||||
) -> Tuple[np.ndarray, Optional[np.ndarray], np.ndarray]:
|
||||
result: str, resolution_wh: tuple[int, int], classes: list[str] | None = None
|
||||
) -> tuple[np.ndarray, np.ndarray | None, np.ndarray]:
|
||||
"""
|
||||
Parse bounding boxes from paligemma-formatted text, scale them to the specified
|
||||
resolution, and optionally filter by classes.
|
||||
|
||||
Args:
|
||||
result: String containing paligemma-formatted locations and labels.
|
||||
resolution_wh: Tuple (width, height) to which we scale the box coordinates.
|
||||
resolution_wh: tuple (width, height) to which we scale the box coordinates.
|
||||
classes: Optional list of valid class names. If provided, boxes and labels not
|
||||
in this list are filtered out.
|
||||
|
||||
@@ -109,11 +205,7 @@ def from_paligemma(
|
||||
the class labels for each bounding box.
|
||||
"""
|
||||
|
||||
w, h = resolution_wh
|
||||
if w <= 0 or h <= 0:
|
||||
raise ValueError(
|
||||
f"Both dimensions in resolution_wh must be positive. Got ({w}, {h})."
|
||||
)
|
||||
w, h = validate_resolution(resolution_wh)
|
||||
|
||||
pattern = re.compile(
|
||||
r"(?<!<loc\d{4}>)<loc(\d{4})><loc(\d{4})><loc(\d{4})><loc(\d{4})> ([\w\s\-]+)"
|
||||
@@ -140,10 +232,10 @@ def from_paligemma(
|
||||
|
||||
def from_qwen_2_5_vl(
|
||||
result: str,
|
||||
input_wh: Tuple[int, int],
|
||||
resolution_wh: Tuple[int, int],
|
||||
classes: Optional[List[str]] = None,
|
||||
) -> Tuple[np.ndarray, Optional[np.ndarray], np.ndarray]:
|
||||
input_wh: tuple[int, int],
|
||||
resolution_wh: tuple[int, int],
|
||||
classes: list[str] | None = None,
|
||||
) -> tuple[np.ndarray, np.ndarray | None, np.ndarray]:
|
||||
"""
|
||||
Parse and scale bounding boxes from Qwen-2.5-VL style JSON output.
|
||||
|
||||
@@ -172,14 +264,9 @@ def from_qwen_2_5_vl(
|
||||
class_name (np.ndarray): An array of shape `(n,)` containing
|
||||
the class labels for each bounding box
|
||||
"""
|
||||
in_w, in_h = input_wh
|
||||
out_w, out_h = resolution_wh
|
||||
|
||||
if in_w <= 0 or in_h <= 0 or out_w <= 0 or out_h <= 0:
|
||||
raise ValueError(
|
||||
f"Both input and resolution dimensions must be positive. "
|
||||
f"Got input_wh=({in_w}, {in_h}), resolution_wh=({out_w}, {out_h})."
|
||||
)
|
||||
in_w, in_h = validate_resolution(input_wh)
|
||||
out_w, out_h = validate_resolution(resolution_wh)
|
||||
|
||||
pattern = re.compile(r"```json\s*(.*?)\s*```", re.DOTALL)
|
||||
|
||||
@@ -224,16 +311,15 @@ def from_qwen_2_5_vl(
|
||||
|
||||
|
||||
def from_florence_2(
|
||||
result: dict, resolution_wh: Tuple[int, int]
|
||||
) -> Tuple[
|
||||
np.ndarray, Optional[np.ndarray], Optional[np.ndarray], Optional[np.ndarray]
|
||||
]:
|
||||
result: dict, resolution_wh: tuple[int, int]
|
||||
) -> tuple[np.ndarray, np.ndarray | None, np.ndarray | None, np.ndarray | None]:
|
||||
"""
|
||||
Parse results from the Florence 2 multi-model model.
|
||||
https://huggingface.co/microsoft/Florence-2-large
|
||||
|
||||
Parameters:
|
||||
Args:
|
||||
result: dict containing the model output
|
||||
resolution_wh: (output_width, output_height) to which we rescale the boxes.
|
||||
|
||||
Returns:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
@@ -307,7 +393,7 @@ def from_florence_2(
|
||||
f"Expected string to end in location tags, but got {result}"
|
||||
)
|
||||
|
||||
w, h = resolution_wh
|
||||
w, h = validate_resolution(resolution_wh)
|
||||
xyxy = np.array([match.groups()], dtype=np.float32)
|
||||
xyxy *= np.array([w, h, w, h]) / 1000
|
||||
result_string = result[: match.start()]
|
||||
@@ -315,3 +401,319 @@ def from_florence_2(
|
||||
return xyxy, labels, None, None
|
||||
|
||||
assert False, f"Unimplemented task: {task}"
|
||||
|
||||
|
||||
def from_google_gemini_2_0(
|
||||
result: str,
|
||||
resolution_wh: tuple[int, int],
|
||||
classes: list[str] | None = None,
|
||||
) -> tuple[np.ndarray, np.ndarray | None, np.ndarray]:
|
||||
"""
|
||||
Parse and scale bounding boxes from Google Gemini style
|
||||
[JSON output](https://ai.google.dev/gemini-api/docs/vision?lang=python).
|
||||
|
||||
The JSON is expected to be enclosed in triple backticks with the format:
|
||||
```json
|
||||
[
|
||||
{"box_2d": [x1, y1, x2, y2], "label": "some class name"},
|
||||
...
|
||||
]
|
||||
```
|
||||
|
||||
For example:
|
||||
```json
|
||||
[
|
||||
{"box_2d": [10, 20, 110, 120], "label": "cat"},
|
||||
{"box_2d": [50, 100, 150, 200], "label": "dog"}
|
||||
]
|
||||
```
|
||||
|
||||
Args:
|
||||
result: String containing the JSON snippet enclosed by triple backticks.
|
||||
resolution_wh: (output_width, output_height) to which we rescale the boxes.
|
||||
classes: Optional list of valid class names. If provided, returned boxes/labels
|
||||
are filtered to only those classes found here.
|
||||
|
||||
Returns:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
class_id (Optional[np.ndarray]): An array of shape `(n,)` containing
|
||||
the class indices for each bounding box (or None if `classes` is not
|
||||
provided)
|
||||
class_name (np.ndarray): An array of shape `(n,)` containing
|
||||
the class labels for each bounding box
|
||||
|
||||
"""
|
||||
|
||||
w, h = validate_resolution(resolution_wh)
|
||||
|
||||
lines = result.splitlines()
|
||||
for i, line in enumerate(lines):
|
||||
if line == "```json":
|
||||
result = "\n".join(lines[i + 1 :])
|
||||
result = result.split("```")[0]
|
||||
break
|
||||
|
||||
try:
|
||||
data = json.loads(result)
|
||||
except json.JSONDecodeError:
|
||||
return np.empty((0, 4)), None, np.empty((0,), dtype=str)
|
||||
|
||||
labels = []
|
||||
boxes_list = []
|
||||
|
||||
for item in data:
|
||||
if "box_2d" not in item or "label" not in item:
|
||||
continue
|
||||
labels.append(item["label"])
|
||||
box = item["box_2d"]
|
||||
# Gemini bbox order is [y_min, x_min, y_max, x_max]
|
||||
boxes_list.append(
|
||||
denormalize_boxes(
|
||||
np.array([box[1], box[0], box[3], box[2]]).astype(np.float64),
|
||||
resolution_wh=(w, h),
|
||||
normalization_factor=1000,
|
||||
)
|
||||
)
|
||||
|
||||
if not boxes_list:
|
||||
return np.empty((0, 4)), None, np.empty((0,), dtype=str)
|
||||
|
||||
xyxy = np.array(boxes_list)
|
||||
class_name = np.array(labels)
|
||||
class_id = None
|
||||
|
||||
if classes is not None:
|
||||
mask = np.array([name in classes for name in class_name], dtype=bool)
|
||||
xyxy = xyxy[mask]
|
||||
class_name = class_name[mask]
|
||||
class_id = np.array([classes.index(name) for name in class_name])
|
||||
|
||||
return xyxy, class_id, class_name
|
||||
|
||||
|
||||
def from_google_gemini_2_5(
|
||||
result: str,
|
||||
resolution_wh: tuple[int, int],
|
||||
classes: list[str] | None = None,
|
||||
) -> tuple[
|
||||
np.ndarray,
|
||||
np.ndarray | None,
|
||||
np.ndarray,
|
||||
np.ndarray | None,
|
||||
np.ndarray | None,
|
||||
]:
|
||||
"""
|
||||
Parse and scale bounding boxes and masks from Google Gemini 2.5 style
|
||||
[JSON output](https://ai.google.dev/gemini-api/docs/vision?lang=python).
|
||||
|
||||
The JSON is expected to be enclosed in triple backticks with the format:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"box_2d": [x1, y1, x2, y2],
|
||||
"mask": "data:image/png;base64,...",
|
||||
"label": "some class name",
|
||||
"confidence": 0.95,
|
||||
},
|
||||
...
|
||||
]
|
||||
```
|
||||
|
||||
Args:
|
||||
result: String containing the JSON snippet enclosed by triple backticks.
|
||||
resolution_wh: (output_width, output_height) to which we rescale the boxes.
|
||||
classes: Optional list of valid class names. If provided, returned boxes/labels
|
||||
are filtered to only those classes found here.
|
||||
|
||||
Returns:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
class_id (np.ndarray): An array of shape `(n,)` containing
|
||||
the class indices for each bounding box
|
||||
class_name (np.ndarray): An array of shape `(n,)` containing
|
||||
the class labels for each bounding box
|
||||
confidence: Optional[np.ndarray]: An array of shape `(n,)` containing
|
||||
the confidence scores for each bounding box. If not provided,
|
||||
it defaults to 0.0 for each box.
|
||||
masks (Optional[np.ndarray]): An array of shape `(n, h, w)` containing
|
||||
the segmentation masks for each bounding box
|
||||
"""
|
||||
w, h = validate_resolution(resolution_wh)
|
||||
|
||||
lines = result.splitlines()
|
||||
for i, line in enumerate(lines):
|
||||
if line == "```json":
|
||||
result = "\n".join(lines[i + 1 :])
|
||||
result = result.split("```")[0]
|
||||
break
|
||||
|
||||
try:
|
||||
data = json.loads(result)
|
||||
except json.JSONDecodeError:
|
||||
return (
|
||||
np.empty((0, 4)),
|
||||
np.array([], dtype=int),
|
||||
np.array([], dtype=str),
|
||||
np.array([], dtype=float),
|
||||
None,
|
||||
)
|
||||
|
||||
boxes_list: list = []
|
||||
labels_list: list = []
|
||||
confidence_list: list | None = []
|
||||
masks_list: list | None = []
|
||||
|
||||
for item in data:
|
||||
if "box_2d" not in item or "label" not in item:
|
||||
continue
|
||||
labels_list.append(item["label"])
|
||||
box = item["box_2d"]
|
||||
# Gemini bbox order is [y_min, x_min, y_max, x_max]
|
||||
absolute_bbox = denormalize_boxes(
|
||||
np.array([box[1], box[0], box[3], box[2]]).astype(np.float64),
|
||||
resolution_wh=(w, h),
|
||||
normalization_factor=1000,
|
||||
)
|
||||
boxes_list.append(absolute_bbox)
|
||||
|
||||
if "mask" in item:
|
||||
if masks_list is not None:
|
||||
png_str = item["mask"]
|
||||
if not png_str.startswith("data:image/png;base64,"):
|
||||
masks_list.append(np.zeros((h, w), dtype=bool))
|
||||
continue
|
||||
|
||||
png_str = png_str.removeprefix("data:image/png;base64,")
|
||||
png_str = base64.b64decode(png_str)
|
||||
mask_img = Image.open(io.BytesIO(png_str))
|
||||
|
||||
y_min, y_max = int(absolute_bbox[1]), int(absolute_bbox[3])
|
||||
x_min, x_max = int(absolute_bbox[0]), int(absolute_bbox[2])
|
||||
|
||||
bbox_height = y_max - y_min
|
||||
bbox_width = x_max - x_min
|
||||
|
||||
if bbox_height > 0 and bbox_width > 0:
|
||||
mask_img = mask_img.resize(
|
||||
(bbox_width, bbox_height), resample=Image.Resampling.BILINEAR
|
||||
)
|
||||
np_mask = np.zeros((h, w), dtype=bool)
|
||||
np_mask[y_min:y_max, x_min:x_max] = np.array(mask_img) > 0
|
||||
masks_list.append(np_mask)
|
||||
else:
|
||||
masks_list.append(np.zeros((h, w), dtype=bool))
|
||||
else:
|
||||
masks_list = None
|
||||
|
||||
if "confidence" in item:
|
||||
if confidence_list is not None:
|
||||
confidence_list.append(item["confidence"])
|
||||
else:
|
||||
confidence_list = None
|
||||
|
||||
if not boxes_list:
|
||||
return (
|
||||
np.empty((0, 4)),
|
||||
np.array([], dtype=int),
|
||||
np.array([], dtype=str),
|
||||
np.array([], dtype=float),
|
||||
None,
|
||||
)
|
||||
|
||||
xyxy = np.array(boxes_list, dtype=float)
|
||||
class_name = np.array(labels_list)
|
||||
class_id: np.ndarray
|
||||
|
||||
if classes is not None:
|
||||
mask = np.array([name in classes for name in class_name], dtype=bool)
|
||||
xyxy = xyxy[mask]
|
||||
class_name = class_name[mask]
|
||||
class_id = np.array([classes.index(name) for name in class_name])
|
||||
if masks_list is not None:
|
||||
masks_list = [m for m, keep in zip(masks_list, mask) if keep]
|
||||
|
||||
if confidence_list is not None:
|
||||
confidence_list = [c for c, keep in zip(confidence_list, mask) if keep]
|
||||
else:
|
||||
unique_labels = sorted(list(set(class_name)))
|
||||
label_to_id = {label: i for i, label in enumerate(unique_labels)}
|
||||
class_id = np.array([label_to_id[name] for name in class_name])
|
||||
|
||||
confidence = (
|
||||
np.array(confidence_list, dtype=float) if confidence_list is not None else None
|
||||
)
|
||||
masks = np.array(masks_list) if masks_list is not None else None
|
||||
|
||||
return (
|
||||
xyxy,
|
||||
class_id,
|
||||
class_name,
|
||||
confidence,
|
||||
masks,
|
||||
)
|
||||
|
||||
|
||||
def from_moondream(
|
||||
result: dict,
|
||||
resolution_wh: tuple[int, int],
|
||||
) -> tuple[np.ndarray]:
|
||||
"""
|
||||
Parse and scale bounding boxes from moondream JSON output.
|
||||
|
||||
The JSON is expected to have a key "objects" with a list of dictionaries:
|
||||
{
|
||||
"objects": [
|
||||
{"x_min": 0.1, "y_min": 0.2, "x_max": 0.3, "y_max": 0.4},
|
||||
...
|
||||
]
|
||||
}
|
||||
|
||||
For Example:
|
||||
{
|
||||
"objects": [
|
||||
{"x_min": 0.1, "y_min": 0.2, "x_max": 0.3, "y_max": 0.4},
|
||||
{"x_min": 0.5, "y_min": 0.6, "x_max": 0.7, "y_max": 0.8}
|
||||
]
|
||||
}
|
||||
|
||||
Args:
|
||||
result: Dictionary containing the JSON output from the model.
|
||||
resolution_wh: (output_width, output_height) to which we rescale the boxes.
|
||||
|
||||
Returns:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing
|
||||
the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
"""
|
||||
|
||||
w, h = resolution_wh
|
||||
if w <= 0 or h <= 0:
|
||||
raise ValueError(
|
||||
f"Both dimensions in resolution_wh must be positive. Got ({w}, {h})."
|
||||
)
|
||||
|
||||
if "objects" not in result or not isinstance(result["objects"], list):
|
||||
return np.empty((0, 4), dtype=float)
|
||||
|
||||
denormalize_xyxy = []
|
||||
|
||||
for item in result["objects"]:
|
||||
if not all(k in item for k in ["x_min", "y_min", "x_max", "y_max"]):
|
||||
continue
|
||||
|
||||
x_min = item["x_min"]
|
||||
y_min = item["y_min"]
|
||||
x_max = item["x_max"]
|
||||
y_max = item["y_max"]
|
||||
|
||||
denormalize_xyxy.append(
|
||||
denormalize_boxes(
|
||||
np.array([x_min, y_min, x_max, y_max]).astype(np.float64),
|
||||
resolution_wh=(w, h),
|
||||
)
|
||||
)
|
||||
|
||||
if not denormalize_xyxy:
|
||||
return np.empty((0, 4))
|
||||
|
||||
return np.array(denormalize_xyxy, dtype=float)
|
||||
|
||||
@@ -1,7 +1,6 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import List, Tuple, Union
|
||||
|
||||
import matplotlib.pyplot as plt
|
||||
|
||||
@@ -132,7 +131,7 @@ class Color:
|
||||
return cls(r, g, b)
|
||||
|
||||
@classmethod
|
||||
def from_rgb_tuple(cls, color_tuple: Tuple[int, int, int]) -> Color:
|
||||
def from_rgb_tuple(cls, color_tuple: tuple[int, int, int]) -> Color:
|
||||
"""
|
||||
Create a Color instance from an RGB tuple.
|
||||
|
||||
@@ -155,7 +154,7 @@ class Color:
|
||||
return cls(r=r, g=g, b=b)
|
||||
|
||||
@classmethod
|
||||
def from_bgr_tuple(cls, color_tuple: Tuple[int, int, int]) -> Color:
|
||||
def from_bgr_tuple(cls, color_tuple: tuple[int, int, int]) -> Color:
|
||||
"""
|
||||
Create a Color instance from a BGR tuple.
|
||||
|
||||
@@ -194,7 +193,7 @@ class Color:
|
||||
"""
|
||||
return f"#{self.r:02x}{self.g:02x}{self.b:02x}"
|
||||
|
||||
def as_rgb(self) -> Tuple[int, int, int]:
|
||||
def as_rgb(self) -> tuple[int, int, int]:
|
||||
"""
|
||||
Returns the color as an RGB tuple.
|
||||
|
||||
@@ -211,7 +210,7 @@ class Color:
|
||||
"""
|
||||
return self.r, self.g, self.b
|
||||
|
||||
def as_bgr(self) -> Tuple[int, int, int]:
|
||||
def as_bgr(self) -> tuple[int, int, int]:
|
||||
"""
|
||||
Returns the color as a BGR tuple.
|
||||
|
||||
@@ -274,7 +273,7 @@ class Color:
|
||||
|
||||
@dataclass
|
||||
class ColorPalette:
|
||||
colors: List[Color]
|
||||
colors: list[Color]
|
||||
|
||||
@classproperty
|
||||
def DEFAULT(cls) -> ColorPalette:
|
||||
@@ -323,7 +322,7 @@ class ColorPalette:
|
||||
return ColorPalette.from_hex(color_hex_list=LEGACY_COLOR_PALETTE)
|
||||
|
||||
@classmethod
|
||||
def from_hex(cls, color_hex_list: List[str]) -> ColorPalette:
|
||||
def from_hex(cls, color_hex_list: list[str]) -> ColorPalette:
|
||||
"""
|
||||
Create a ColorPalette instance from a list of hex strings.
|
||||
|
||||
@@ -412,7 +411,7 @@ class ColorPalette:
|
||||
return len(self.colors)
|
||||
|
||||
|
||||
def unify_to_bgr(color: Union[Tuple[int, int, int], Color]) -> Tuple[int, int, int]:
|
||||
def unify_to_bgr(color: tuple[int, int, int] | Color) -> tuple[int, int, int]:
|
||||
"""
|
||||
Converts a color input in multiple formats to a standardized BGR format.
|
||||
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from typing import Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -215,7 +216,7 @@ def draw_text(
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
text_font: int = cv2.FONT_HERSHEY_SIMPLEX,
|
||||
background_color: Optional[Color] = None,
|
||||
background_color: Color | None = None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Draw text with background on a scene.
|
||||
@@ -282,7 +283,7 @@ def draw_text(
|
||||
|
||||
|
||||
def draw_image(
|
||||
scene: np.ndarray, image: Union[str, np.ndarray], opacity: float, rect: Rect
|
||||
scene: np.ndarray, image: str | np.ndarray, opacity: float, rect: Rect
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Draws an image onto a given scene with specified opacity and dimensions.
|
||||
@@ -343,7 +344,7 @@ def draw_image(
|
||||
return scene
|
||||
|
||||
|
||||
def calculate_optimal_text_scale(resolution_wh: Tuple[int, int]) -> float:
|
||||
def calculate_optimal_text_scale(resolution_wh: tuple[int, int]) -> float:
|
||||
"""
|
||||
Calculate font scale based on the resolution of an image.
|
||||
|
||||
@@ -357,7 +358,7 @@ def calculate_optimal_text_scale(resolution_wh: Tuple[int, int]) -> float:
|
||||
return min(resolution_wh) * 1e-3
|
||||
|
||||
|
||||
def calculate_optimal_line_thickness(resolution_wh: Tuple[int, int]) -> int:
|
||||
def calculate_optimal_line_thickness(resolution_wh: tuple[int, int]) -> int:
|
||||
"""
|
||||
Calculate line thickness based on the resolution of an image.
|
||||
|
||||
|
||||
@@ -3,7 +3,6 @@ from __future__ import annotations
|
||||
from dataclasses import dataclass
|
||||
from enum import Enum
|
||||
from math import sqrt
|
||||
from typing import Tuple
|
||||
|
||||
|
||||
class Position(Enum):
|
||||
@@ -32,10 +31,10 @@ class Point:
|
||||
x: float
|
||||
y: float
|
||||
|
||||
def as_xy_int_tuple(self) -> Tuple[int, int]:
|
||||
def as_xy_int_tuple(self) -> tuple[int, int]:
|
||||
return int(self.x), int(self.y)
|
||||
|
||||
def as_xy_float_tuple(self) -> Tuple[float, float]:
|
||||
def as_xy_float_tuple(self) -> tuple[float, float]:
|
||||
return self.x, self.y
|
||||
|
||||
|
||||
@@ -99,7 +98,7 @@ class Rect:
|
||||
height: float
|
||||
|
||||
@classmethod
|
||||
def from_xyxy(cls, xyxy: Tuple[float, float, float, float]) -> Rect:
|
||||
def from_xyxy(cls, xyxy: tuple[float, float, float, float]) -> Rect:
|
||||
x1, y1, x2, y2 = xyxy
|
||||
return cls(x=x1, y=y1, width=x2 - x1, height=y2 - y1)
|
||||
|
||||
@@ -119,7 +118,7 @@ class Rect:
|
||||
height=self.height + 2 * padding,
|
||||
)
|
||||
|
||||
def as_xyxy_int_tuple(self) -> Tuple[int, int, int, int]:
|
||||
def as_xyxy_int_tuple(self) -> tuple[int, int, int, int]:
|
||||
return (
|
||||
int(self.x),
|
||||
int(self.y),
|
||||
|
||||
@@ -1,12 +1,13 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from abc import ABC, abstractmethod
|
||||
from logging import warn
|
||||
from typing import List, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.annotators.base import ImageType
|
||||
from supervision.detection.utils import pad_boxes, spread_out_boxes
|
||||
from supervision.detection.utils.boxes import pad_boxes, spread_out_boxes
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_rounded_rectangle
|
||||
from supervision.geometry.core import Rect
|
||||
@@ -106,7 +107,7 @@ class EdgeAnnotator(BaseKeyPointAnnotator):
|
||||
self,
|
||||
color: Color = Color.ROBOFLOW,
|
||||
thickness: int = 2,
|
||||
edges: Optional[List[Tuple[int, int]]] = None,
|
||||
edges: list[tuple[int, int]] | None = None,
|
||||
) -> None:
|
||||
"""
|
||||
Args:
|
||||
@@ -196,8 +197,8 @@ class VertexLabelAnnotator:
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, List[Color]] = Color.ROBOFLOW,
|
||||
text_color: Union[Color, List[Color]] = Color.WHITE,
|
||||
color: Color | list[Color] = Color.ROBOFLOW,
|
||||
text_color: Color | list[Color] = Color.WHITE,
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
@@ -220,8 +221,8 @@ class VertexLabelAnnotator:
|
||||
smart_position (bool): Spread out the labels to avoid overlap.
|
||||
"""
|
||||
self.border_radius: int = border_radius
|
||||
self.color: Union[Color, List[Color]] = color
|
||||
self.text_color: Union[Color, List[Color]] = text_color
|
||||
self.color: Color | list[Color] = color
|
||||
self.text_color: Color | list[Color] = text_color
|
||||
self.text_scale: float = text_scale
|
||||
self.text_thickness: int = text_thickness
|
||||
self.text_padding: int = text_padding
|
||||
@@ -231,7 +232,7 @@ class VertexLabelAnnotator:
|
||||
self,
|
||||
scene: ImageType,
|
||||
key_points: KeyPoints,
|
||||
labels: Optional[List[str]] = None,
|
||||
labels: list[str] | None = None,
|
||||
) -> ImageType:
|
||||
"""
|
||||
A class that draws labels of skeleton vertices on images. It uses specified key
|
||||
@@ -394,8 +395,8 @@ class VertexLabelAnnotator:
|
||||
font: int,
|
||||
text_scale: float,
|
||||
text_thickness: int,
|
||||
center_coordinates: Tuple[int, int],
|
||||
) -> Tuple[int, int, int, int]:
|
||||
center_coordinates: tuple[int, int],
|
||||
) -> tuple[int, int, int, int]:
|
||||
text_w, text_h = cv2.getTextSize(
|
||||
text=text,
|
||||
fontFace=font,
|
||||
@@ -412,7 +413,7 @@ class VertexLabelAnnotator:
|
||||
|
||||
@staticmethod
|
||||
def preprocess_and_validate_labels(
|
||||
labels: Optional[List[str]], points_count: int, skeletons_count: int
|
||||
labels: list[str] | None, points_count: int, skeletons_count: int
|
||||
) -> np.ndarray:
|
||||
if labels and len(labels) != points_count:
|
||||
raise ValueError(
|
||||
@@ -426,7 +427,7 @@ class VertexLabelAnnotator:
|
||||
|
||||
@staticmethod
|
||||
def preprocess_and_validate_colors(
|
||||
colors: Optional[Union[Color, List[Color]]],
|
||||
colors: Color | list[Color] | None,
|
||||
points_count: int,
|
||||
skeletons_count: int,
|
||||
) -> np.ndarray:
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user