Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 SkalskiP |
9adc953780 | ||
|
Piotr Skalski
|
4ace93f9ab | ||
|
SkalskiP
|
c1d3ab2944 | ||
|
SkalskiP
|
2072eeac12 | ||
|
Piotr Skalski
|
c74efc4908 | ||
|
SkalskiP
|
08f399cf19 | ||
|
SkalskiP
|
17020b23de | ||
|
SkalskiP
|
cd929525f6 | ||
|
SkalskiP
|
bb18de8dce | ||
|
SkalskiP
|
dec96aec4d | ||
|
hd
|
ee45c684d0 | ||
|
SkalskiP
|
ea517642f0 | ||
|
SkalskiP
|
cdc08c0455 | ||
|
SkalskiP
|
a0c808cfdf | ||
|
Piotr Skalski
|
f146e88ceb | ||
|
SkalskiP
|
66d29015d6 | ||
|
SkalskiP
|
46cb82797e | ||
|
SkalskiP
|
194ff0aaad | ||
|
SkalskiP
|
a579ed46c6 | ||
|
Piotr Skalski
|
8918783702 | ||
|
Piotr Skalski
|
6adb0f019d | ||
|
Piotr Skalski
|
84ae12768a | ||
|
SkalskiP
|
9cbec9fc94 | ||
|
hd
|
ed12daf77d | ||
|
hd
|
84cfa9609b | ||
|
hd
|
f2eccae88e | ||
|
hd
|
55c8295755 | ||
|
hd
|
7849033da3 | ||
|
Piotr Skalski
|
2e443c80c7 | ||
|
SkalskiP
|
006caa0b9b | ||
|
Piotr Skalski
|
34e45bed5e | ||
|
Piotr Skalski
|
0d39de898a | ||
|
SkalskiP
|
782e7e5a39 | ||
|
SkalskiP
|
b40265db9e | ||
|
SkalskiP
|
de1ceff065 | ||
|
SkalskiP
|
5bf78e5505 | ||
|
SkalskiP
|
f63336a824 | ||
|
SkalskiP
|
4d82460358 | ||
|
SkalskiP
|
540efc80ce | ||
|
hd
|
beea21a97d | ||
|
hd
|
484e3d4afd | ||
|
hd
|
ab9728cca2 | ||
|
hd
|
769b6b967c | ||
|
hd
|
253113fa88 | ||
|
hd
|
3b2902c87c | ||
|
Piotr Skalski
|
9cff624e15 | ||
|
SkalskiP
|
584c4fef82 | ||
|
Piotr Skalski
|
282aa2c5d3 | ||
|
SkalskiP
|
453d4df068 | ||
|
SkalskiP
|
4d4b38b292 | ||
|
SkalskiP
|
13e8afa996 | ||
|
James Gallagher
|
dd4cae328b | ||
|
James
|
ed7103851a | ||
|
James Gallagher
|
ca40b001dc | ||
|
Piotr Skalski
|
de3ccc5c5d | ||
|
SkalskiP
|
1b6d02898c | ||
|
SkalskiP
|
5ac92bc43b | ||
|
Piotr Skalski
|
86d9293770 | ||
|
Daniel M. García-Ocaña
|
0e943e673e | ||
|
James Gallagher
|
234e376fca | ||
|
SkalskiP
|
54b7cbeb70 | ||
|
SkalskiP
|
d000292eb2 | ||
|
SkalskiP
|
b551e6d410 | ||
|
James Gallagher
|
138c271af0 | ||
|
James Gallagher
|
d22940ce30 | ||
|
James Gallagher
|
06da0e70d2 | ||
|
James Gallagher
|
5d8b378f35 | ||
|
James Gallagher
|
a4830389de | ||
|
James Gallagher
|
d9a2efc64b | ||
|
James Gallagher
|
f91b844b7d | ||
|
James Gallagher
|
dc45d47e7e | ||
|
James Gallagher
|
b5dedf09cd | ||
|
James Gallagher
|
eb1ae1b790 | ||
|
James Gallagher
|
f2f8a564e0 | ||
|
James Gallagher
|
140a219091 | ||
|
James Gallagher
|
86af9b9dce | ||
|
Piotr Skalski
|
4366e4480f | ||
|
James Gallagher
|
b66e9c8c32 | ||
|
James Gallagher
|
d0d5626156 | ||
|
James Gallagher
|
c661bf250d | ||
|
SkalskiP
|
ccb32f8aa1 | ||
|
Piotr Skalski
|
97b9edcbec | ||
|
SkalskiP
|
6b52863c9f | ||
|
SkalskiP
|
2fcc035413 | ||
|
Piotr Skalski
|
7c8f16bf0f | ||
|
SkalskiP
|
1870670c77 | ||
|
SkalskiP
|
802347f4d8 | ||
|
Piotr Skalski
|
920019c887 | ||
|
SkalskiP
|
477b9a8f38 | ||
|
SkalskiP
|
14f62deacf | ||
|
SkalskiP
|
08eb513594 | ||
|
SkalskiP
|
a1615fd275 | ||
|
SkalskiP
|
ce979216f2 | ||
|
SkalskiP
|
95f94319f8 | ||
|
SkalskiP
|
98f60c24d3 | ||
|
Piotr Skalski
|
1c043d6cc7 | ||
|
Piotr Skalski
|
86aee5ed98 | ||
|
SkalskiP
|
0d38b95da7 | ||
|
SkalskiP
|
97892e3138 | ||
|
Piotr Skalski
|
17a42bc728 | ||
|
Stephen Lomnes
|
be65ba7370 | ||
|
Hardik Dava
|
72d86ba180 | ||
|
Hardik Dava
|
fba83ec371 | ||
|
Hardik Dava
|
4a81a17ddb | ||
|
Hardik Dava
|
30d253d5cc | ||
|
James Gallagher
|
544f9cb0e2 | ||
|
James Gallagher
|
84928a2da9 | ||
|
Hardik Dava
|
08ae0b2fc7 | ||
|
Piotr Skalski
|
0261bec2ce | ||
|
Piotr Skalski
|
5a4cb1b302 | ||
|
Piotr Skalski
|
91655f9609 | ||
|
Piotr Skalski
|
42d4079b23 | ||
|
Piotr Skalski
|
f03a47a5df | ||
|
Piotr Skalski
|
c01efeaaca | ||
|
SkalskiP
|
5489d405c6 | ||
|
SkalskiP
|
5f97eac9a9 | ||
|
SkalskiP
|
30f105f267 | ||
|
SkalskiP
|
a34e64866e | ||
|
Piotr Skalski
|
c02f69428e | ||
|
SkalskiP
|
55f4f00c0c | ||
|
SkalskiP
|
91100e8393 | ||
|
Hardik Dava
|
b474a47065 | ||
|
Piotr Skalski
|
83d357d973 | ||
|
SkalskiP
|
b536c6c889 | ||
|
SkalskiP
|
df579c866c | ||
|
SkalskiP
|
f224bceb6f | ||
|
SkalskiP
|
bd3503e7d5 | ||
|
SkalskiP
|
f63f5acb2f | ||
|
SkalskiP
|
2f5b1b0f0d | ||
|
SkalskiP
|
3af32800d3 | ||
|
SkalskiP
|
8222bee9dd | ||
|
SkalskiP
|
06ea737336 | ||
|
SkalskiP
|
f616bda40f | ||
|
SkalskiP
|
0e835f1b0a | ||
|
SkalskiP
|
4c024214b2 | ||
|
SkalskiP
|
6a15093277 | ||
|
SkalskiP
|
abcf453119 | ||
|
SkalskiP
|
ba2926688f | ||
|
SkalskiP
|
3da433f90f | ||
|
Piotr Skalski
|
a911cbd554 | ||
|
SkalskiP
|
d10618a8b3 | ||
|
Piotr Skalski
|
eaf5b7e95f | ||
|
Piotr Skalski
|
4ae8ac1db0 | ||
|
SkalskiP
|
74efca7c22 | ||
|
SkalskiP
|
3063dfb1f5 | ||
|
SkalskiP
|
6c81d21a03 | ||
|
SkalskiP
|
f4b91d0175 | ||
|
SkalskiP
|
45fdb1e805 | ||
|
SkalskiP
|
8c0a294ca1 | ||
|
SkalskiP
|
cf7f003133 | ||
|
SkalskiP
|
1bebbb14a6 | ||
|
SkalskiP
|
3d0aec03e0 | ||
|
SkalskiP
|
306d7bd27e | ||
|
SkalskiP
|
43fc5d6205 | ||
|
SkalskiP
|
d13238bc42 | ||
|
SkalskiP
|
77243f1752 | ||
|
SkalskiP
|
e16cca4349 | ||
|
Piotr Skalski
|
e592a44bea | ||
|
SkalskiP
|
c2833bc8ca | ||
|
SkalskiP
|
feb08d10b2 | ||
|
Piotr Skalski
|
74bd403dc0 | ||
|
SkalskiP
|
6a013382d3 | ||
|
Piotr Skalski
|
92290979c7 | ||
|
Hardik Dava
|
696b6f9276 | ||
|
Piotr Skalski
|
29450139f9 | ||
|
SkalskiP
|
ea400feb6a | ||
|
SkalskiP
|
05495aca75 | ||
|
SkalskiP
|
a3bea9ae37 | ||
|
SkalskiP
|
651690f838 | ||
|
SkalskiP
|
d87761f75d | ||
|
Piotr Skalski
|
b20e4a6c19 | ||
|
SkalskiP
|
0ef2ab7273 | ||
|
SkalskiP
|
d1bb169593 | ||
|
SkalskiP
|
c8f3f59a45 | ||
|
SkalskiP
|
12523afe9a | ||
|
SkalskiP
|
68412500fa | ||
|
SkalskiP
|
49d4441419 | ||
|
SkalskiP
|
0394a3f545 | ||
|
SkalskiP
|
2bcd1e1dfd | ||
|
SkalskiP
|
e62937c8ce | ||
|
SkalskiP
|
b37aca52e2 | ||
|
SkalskiP
|
790d2f6c5b | ||
|
SkalskiP
|
0cb722e91e | ||
|
SkalskiP
|
55cd04d0aa | ||
|
SkalskiP
|
58181e6a7a | ||
|
SkalskiP
|
ab00d2db0d | ||
|
SkalskiP
|
6a76c96df5 | ||
|
SkalskiP
|
d4a6a1a85b | ||
|
SkalskiP
|
7c78feb4b8 | ||
|
Piotr Skalski
|
73a7983719 | ||
|
SkalskiP
|
1d6c2bc080 | ||
|
alexandercarruthers
|
889461574f | ||
|
SkalskiP
|
f95426540b | ||
|
SkalskiP
|
c16599269c | ||
|
SkalskiP
|
888edfbc67 | ||
|
Piotr Skalski
|
7497f8d96a | ||
|
SkalskiP
|
b34ecd53cf | ||
|
Piotr Skalski
|
e9649acd90 | ||
|
Chase Dubauskas
|
2cf7a9b620 | ||
|
SkalskiP
|
e091f9c959 | ||
|
SkalskiP
|
f12504b0dd | ||
|
Piotr Skalski
|
dba4d9f8ad | ||
|
SkalskiP
|
ddc8a8ccce | ||
|
SkalskiP
|
c1ccff474f | ||
|
SkalskiP
|
d02bac75c4 | ||
|
SkalskiP
|
f3c4a966c4 | ||
|
SkalskiP
|
5bc436b1c5 | ||
|
SkalskiP
|
c37590ef3a | ||
|
SkalskiP
|
a14bb94b46 | ||
|
SkalskiP
|
aab7e238e4 | ||
|
SkalskiP
|
34dba17641 | ||
|
SkalskiP
|
ef5ee71f0b | ||
|
SkalskiP
|
bed0e41cb7 | ||
|
SkalskiP
|
e439b29f07 | ||
|
SkalskiP
|
511375f24b | ||
|
SkalskiP
|
ff2788945d | ||
|
SkalskiP
|
5b9eef363d | ||
|
SkalskiP
|
bcc4b25eb9 | ||
|
SkalskiP
|
d5d2035048 | ||
|
SkalskiP
|
14795a6626 | ||
|
Piotr Skalski
|
bc12a8ea0b | ||
|
SkalskiP
|
2be4981c76 | ||
|
SkalskiP
|
fe68327b75 | ||
|
SkalskiP
|
141809ae92 | ||
|
iPoe
|
ac61598ad4 | ||
|
SkalskiP
|
1fa4a1c72e | ||
|
Piotr Skalski
|
2df4261355 | ||
|
SkalskiP
|
a88eff868e | ||
|
SkalskiP
|
8bf686e23b | ||
|
SkalskiP
|
b2f6520b87 | ||
|
SkalskiP
|
420dae9e70 | ||
|
SkalskiP
|
550c913dbb | ||
|
SkalskiP
|
4dcca5309c | ||
|
SkalskiP
|
d30cc180d0 | ||
|
Piotr Skalski
|
ace8301b12 | ||
|
SkalskiP
|
b91bc91897 | ||
|
SkalskiP
|
e04c531c05 | ||
|
SkalskiP
|
63fd5a3f8a | ||
|
SkalskiP
|
38f52a04ae | ||
|
Piotr Skalski
|
65090f612c | ||
|
SkalskiP
|
9401210aa5 | ||
|
Piotr Skalski
|
59d8655014 | ||
|
SkalskiP
|
4dde484141 | ||
|
SkalskiP
|
e6f250dbfb | ||
|
SkalskiP
|
e6090be9eb | ||
|
SkalskiP
|
25c19b4422 | ||
|
Piotr Skalski
|
ac1658268c | ||
|
SkalskiP
|
8e7228313b | ||
|
SkalskiP
|
a27377aaf3 | ||
|
SkalskiP
|
eefc5ddf7d | ||
|
SkalskiP
|
96d8badf1a | ||
|
SkalskiP
|
c0ae62a460 | ||
|
SkalskiP
|
1c2d946527 | ||
|
SkalskiP
|
95b44db2bd | ||
|
SkalskiP
|
ba732330a5 | ||
|
Piotr Skalski
|
3ea95b3966 | ||
|
Dave Conway-Jones
|
c2a5161ff9 | ||
|
SkalskiP
|
c3eec02b6c | ||
|
Piotr Skalski
|
8c68999324 | ||
|
SkalskiP
|
4a43f4ec69 | ||
|
SkalskiP
|
78d267e169 | ||
|
Piotr Skalski
|
7780308533 |
@@ -0,0 +1 @@
|
||||
*.ipynb linguist-vendored
|
||||
+1
-1
@@ -2,7 +2,7 @@ cff-version: 1.2.0
|
||||
author: Roboflow
|
||||
message: If you use this software, please cite it as below.
|
||||
title: supervision
|
||||
version: 0.1.0
|
||||
version: 0.11.0
|
||||
date-released: 2023-01-19
|
||||
license: MIT
|
||||
repository-code: https://github.com/roboflow/supervision
|
||||
|
||||
+14
-1
@@ -35,4 +35,17 @@ When creating new functions, please ensure you have the following:
|
||||
|
||||
All pull requests will be reviewed by the maintainers of the project. We will provide feedback and ask for changes if necessary.
|
||||
|
||||
PRs must pass all tests and linting requirements before they can be merged.
|
||||
PRs must pass all tests and linting requirements before they can be merged.
|
||||
|
||||
## 🧹 code quality
|
||||
|
||||
We provide two handy commands inside the `Makefile`, namely:
|
||||
|
||||
- `make style` to format the code
|
||||
- `make check_code_quality` to check code quality (PEP8 basically)
|
||||
|
||||
So far, **there is no types checking with mypy**. See [issue](https://github.com/roboflow-ai/template-python/issues/4).
|
||||
|
||||
## 🧪 tests
|
||||
|
||||
[`pytests`](https://docs.pytest.org/en/7.1.x/) is used to run our tests.
|
||||
@@ -2,13 +2,273 @@
|
||||
<p>
|
||||
<a align="center" href="" target="_blank">
|
||||
<img
|
||||
width="850"
|
||||
src="https://media.roboflow.com/open-source/supervision/roboflow-supervision-banner.png?ik-sdk-version=javascript-1.4.3&updatedAt=1674062891088"
|
||||
width="100%"
|
||||
src="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png?updatedAt=1678995927529"
|
||||
>
|
||||
</a>
|
||||
</p>
|
||||
|
||||
<br>
|
||||
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://pypistats.org/packages/supervision)
|
||||
[](https://github.com/roboflow/supervision/blob/main/LICENSE.md)
|
||||
[](https://badge.fury.io/py/supervision)
|
||||
[](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb)
|
||||
|
||||
</div>
|
||||
|
||||
## 👋 hello
|
||||
|
||||
**We write your reusable computer vision tools.** Whether you need to load your dataset from your hard drive, draw detections on an image or video, or count how many detections are in a zone. You can count on us! 🤝
|
||||
|
||||
## 💻 install
|
||||
|
||||
Pip install the supervision package in a
|
||||
[**3.11>=Python>=3.7**](https://www.python.org/) environment.
|
||||
|
||||
```bash
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
<details close>
|
||||
<summary>👉 install from source</summary>
|
||||
|
||||
```bash
|
||||
# clone repository and navigate to root directory
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision
|
||||
|
||||
# setup python environment and activate it
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
|
||||
# install
|
||||
pip install -e ".[dev]"
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## 🔥 quickstart
|
||||
|
||||
### [detections processing](https://roboflow.github.io/supervision/detection/core/)
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> from ultralytics import YOLO
|
||||
|
||||
>>> model = YOLO('yolov8s.pt')
|
||||
>>> result = model(IMAGE)[0]
|
||||
>>> detections = sv.Detections.from_yolov8(result)
|
||||
|
||||
>>> len(detections)
|
||||
5
|
||||
```
|
||||
|
||||
<details close>
|
||||
<summary>👉 more detections utils</summary>
|
||||
|
||||
- Easily switch inference pipeline between supported object detection / instance segmentation models
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> from segment_anything import sam_model_registry, SamAutomaticMaskGenerator
|
||||
|
||||
>>> sam = sam_model_registry[MODEL_TYPE](checkpoint=CHECKPOINT_PATH).to(device=DEVICE)
|
||||
>>> mask_generator = SamAutomaticMaskGenerator(sam)
|
||||
>>> sam_result = mask_generator.generate(IMAGE)
|
||||
>>> detections = sv.Detections.from_sam(sam_result=sam_result)
|
||||
```
|
||||
|
||||
- [Advanced filtering](https://roboflow.github.io/supervision/quickstart/detections/)
|
||||
|
||||
```python
|
||||
>>> detections = detections[detections.class_id == 0]
|
||||
>>> detections = detections[detections.confidence > 0.5]
|
||||
>>> detections = detections[detections.area > 1000]
|
||||
```
|
||||
|
||||
- Image annotation
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> box_annotator = sv.BoxAnnotator()
|
||||
>>> annotated_frame = box_annotator.annotate(
|
||||
... scene=IMAGE,
|
||||
... detections=detections
|
||||
... )
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
### [datasets processing](https://roboflow.github.io/supervision/dataset/core/)
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... )
|
||||
|
||||
>>> dataset.classes
|
||||
['dog', 'person']
|
||||
|
||||
>>> len(dataset)
|
||||
1000
|
||||
```
|
||||
|
||||
<details close>
|
||||
<summary>👉 more dataset utils</summary>
|
||||
|
||||
- Load object detection / instance segmentation datasets in one of supported formats
|
||||
|
||||
```python
|
||||
>>> dataset = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... )
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_pascal_voc(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...'
|
||||
... )
|
||||
|
||||
>>> dataset = sv.DetectionDataset.from_coco(
|
||||
... images_directory_path='...',
|
||||
... annotations_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Loop over dataset entries
|
||||
|
||||
```python
|
||||
>>> for name, image, labels in dataset:
|
||||
... print(labels.xyxy)
|
||||
|
||||
array([[404. , 719. , 538. , 884.5 ],
|
||||
[155. , 497. , 404. , 833.5 ],
|
||||
[ 20.154999, 347.825 , 416.125 , 915.895 ]], dtype=float32)
|
||||
```
|
||||
|
||||
- Split dataset for training, testing and validation
|
||||
|
||||
```python
|
||||
>>> train_dataset, test_dataset = dataset.split(split_ratio=0.7)
|
||||
>>> test_dataset, valid_dataset = test_dataset.split(split_ratio=0.5)
|
||||
|
||||
>>> len(train_dataset), len(test_dataset), len(valid_dataset)
|
||||
(700, 150, 150)
|
||||
```
|
||||
|
||||
- Merge multiple datasets together
|
||||
|
||||
```python
|
||||
>>> ds_1 = sv.DetectionDataset(...)
|
||||
>>> len(ds_1)
|
||||
100
|
||||
>>> ds_1.classes
|
||||
['dog', 'person']
|
||||
|
||||
>>> ds_2 = sv.DetectionDataset(...)
|
||||
>>> len(ds_2)
|
||||
200
|
||||
>>> ds_2.classes
|
||||
['cat']
|
||||
|
||||
>>> ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
>>> len(ds_merged)
|
||||
300
|
||||
>>> ds_merged.classes
|
||||
['cat', 'dog', 'person']
|
||||
```
|
||||
|
||||
- Save object detection / instance segmentation datasets in one of supported formats
|
||||
|
||||
```python
|
||||
>>> dataset.as_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... )
|
||||
|
||||
>>> dataset.as_pascal_voc(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...'
|
||||
... )
|
||||
|
||||
>>> dataset.as_coco(
|
||||
... images_directory_path='...',
|
||||
... annotations_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Convert labels between supported formats
|
||||
|
||||
```python
|
||||
>>> sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...',
|
||||
... data_yaml_path='...'
|
||||
... ).as_pascal_voc(
|
||||
... images_directory_path='...',
|
||||
... annotations_directory_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Load classification datasets in one of supported formats
|
||||
|
||||
```python
|
||||
>>> cs = sv.ClassificationDataset.from_folder_structure(
|
||||
... root_directory_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Save classification datasets in one of supported formats
|
||||
|
||||
```python
|
||||
>>> cs.as_folder_structure(
|
||||
... root_directory_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## 🎬 tutorials
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/oEQYStnF2l8" title="Accelerate Image Annotation with SAM and Grounding DINO"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/ae1ca38e-40b7-4b35-8582-e8ea5de3806e" alt="Accelerate Image Annotation with SAM and Grounding DINO" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/oEQYStnF2l8" title="Accelerate Image Annotation with SAM and Grounding DINO"><strong>Accelerate Image Annotation with SAM and Grounding DINO</strong></a>
|
||||
<div><strong>Created: 20 Apr 2023</strong> | <strong>Updated: 20 Apr 2023</strong></div>
|
||||
<br/> Discover how to speed up your image annotation process using Grounding DINO and Segment Anything Model (SAM). Learn how to convert object detection datasets into instance segmentation datasets, and see the potential of using these models to automatically annotate your datasets for real-time detectors like YOLOv8... </p>
|
||||
|
||||
<br/>
|
||||
|
||||
<p align="left">
|
||||
<a href="https://youtu.be/oEQYStnF2l8" title="SAM - Segment Anything Model by Meta AI: Complete Guide"><img src="https://github.com/SkalskiP/SkalskiP/assets/26109316/6913ff11-53c6-4341-8d90-eaff3023c3fd" alt="SAM - Segment Anything Model by Meta AI: Complete Guide" width="300px" align="left" /></a>
|
||||
<a href="https://youtu.be/oEQYStnF2l8" title="SAM - Segment Anything Model by Meta AI: Complete Guide"><strong>SAM - Segment Anything Model by Meta AI: Complete Guide</strong></a>
|
||||
<div><strong>Created: 11 Apr 2023</strong> | <strong>Updated: 11 Apr 2023</strong></div>
|
||||
<br/> Discover the incredible potential of Meta AI's Segment Anything Model (SAM)! We dive into SAM, an efficient and promptable model for image segmentation, which has revolutionized computer vision tasks. With over 1 billion masks on 11M licensed and privacy-respecting images, SAM's zero-shot performance is often competitive with or even superior to prior fully supervised results... </p>
|
||||
|
||||
## 📚 documentation
|
||||
|
||||
Curious how Supervision can help you solve problems on your project? Visit our [documentation](https://roboflow.github.io/supervision) page!
|
||||
|
||||
## 💜 built with supervision
|
||||
|
||||
You built something cool using supervision? [Let us know!](https://github.com/roboflow/supervision/discussions/categories/built-with-supervision)
|
||||
|
||||
## 🏆 contribution
|
||||
|
||||
We love your input! Please see our [contributing guide](https://github.com/roboflow/supervision/blob/main/CONTRIBUTING.md) to get started. Thank you 🙏 to all our contributors!
|
||||
|
||||
<br>
|
||||
|
||||
<div align="center">
|
||||
|
||||
<div align="center">
|
||||
<a href="https://youtube.com/roboflow">
|
||||
<img
|
||||
@@ -54,64 +314,3 @@
|
||||
</div>
|
||||
|
||||
</div>
|
||||
|
||||
## 👋 hello
|
||||
|
||||
A set of easy-to-use utils that will come in handy in any Computer Vision project. **Supervision** is still in
|
||||
pre-release stage. 🚧 Keep your eyes open for potential bugs and be aware that at this stage our API is still fluid
|
||||
and may change.
|
||||
|
||||
## 💻 install
|
||||
|
||||
Pip install the supervision package in a
|
||||
[**3.10>=Python>=3.7**](https://www.python.org/) environment.
|
||||
|
||||
```bash
|
||||
pip install supervision
|
||||
```
|
||||
|
||||
<details close>
|
||||
<summary>Install from source</summary>
|
||||
|
||||
```bash
|
||||
# clone repository and navigate to root directory
|
||||
git clone https://github.com/roboflow/supervision.git
|
||||
cd supervision
|
||||
|
||||
# setup python environment and activate it
|
||||
python3 -m venv venv
|
||||
source venv/bin/activate
|
||||
|
||||
# install
|
||||
pip install -e ".[dev]"
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## 📖 documentation
|
||||
|
||||
Curious how Supervision can help you solve problems on your project? Visit our [documentation](https://roboflow.github.io/supervision) page!
|
||||
|
||||
## 🎬 videos
|
||||
|
||||
Learn how to use YOLOv8, ByteTrack and **Supervision** to detect, track and count objects. 🔥
|
||||
[Subscribe](https://www.youtube.com/@Roboflow), and stay up to date with our latest YouTube videos!
|
||||
|
||||
<p align="center">
|
||||
<a href="https://youtu.be/OS5qI9YBkfk">
|
||||
<img src="https://user-images.githubusercontent.com/26109316/213702005-ddd568f0-b902-46c2-9af9-e6ff33db23bf.jpg" alt="latest-roboflow-tutorial">
|
||||
</a>
|
||||
</p>
|
||||
|
||||
## 🧹 code quality
|
||||
|
||||
We provide two handy commands inside the `Makefile`, namely:
|
||||
|
||||
- `make style` to format the code
|
||||
- `make check_code_quality` to check code quality (PEP8 basically)
|
||||
|
||||
So far, **there is no types checking with mypy**. See [issue](https://github.com/roboflow-ai/template-python/issues/4).
|
||||
|
||||
## 🧪 tests
|
||||
|
||||
[`pytests`](https://docs.pytest.org/en/7.1.x/) is used to run our tests.
|
||||
|
||||
Vendored
+1325
File diff suppressed because one or more lines are too long
@@ -0,0 +1,208 @@
|
||||
### 0.11.0 <small>June 28, 2023</small>
|
||||
|
||||
- Added [[#150](https://github.com/roboflow/supervision/pull/150)]: ability to load and save [`sv.DetectionDataset`](https://roboflow.github.io/supervision/dataset/core/#detectiondataset) in COCO format using [`as_coco`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.as_coco) and [`from_coco`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.from_coco) methods.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> ds = sv.DetectionDataset.from_coco(
|
||||
... images_directory_path='...',
|
||||
... annotations_path='...'
|
||||
... )
|
||||
|
||||
>>> ds.as_coco(
|
||||
... images_directory_path='...',
|
||||
... annotations_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [[#158](https://github.com/roboflow/supervision/pull/158)]: ability to marge multiple [`sv.DetectionDataset`](https://roboflow.github.io/supervision/dataset/core/#detectiondataset) together using [`merge`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.merge) method.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> ds_1 = sv.DetectionDataset(...)
|
||||
>>> len(ds_1)
|
||||
100
|
||||
>>> ds_1.classes
|
||||
['dog', 'person']
|
||||
|
||||
>>> ds_2 = sv.DetectionDataset(...)
|
||||
>>> len(ds_2)
|
||||
200
|
||||
>>> ds_2.classes
|
||||
['cat']
|
||||
|
||||
>>> ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
>>> len(ds_merged)
|
||||
300
|
||||
>>> ds_merged.classes
|
||||
['cat', 'dog', 'person']
|
||||
```
|
||||
|
||||
- Added [[#162](https://github.com/roboflow/supervision/pull/162)]: additional `start` and `end` arguments to [`sv.get_video_frames_generator`](https://roboflow.github.io/supervision/utils/video/#get_video_frames_generator) allowing to generate frames only for a selected part of the video.
|
||||
|
||||
- Fix [[#157](https://github.com/roboflow/supervision/pull/157)]: incorrect loading of YOLO dataset class names from `data.yaml`.
|
||||
|
||||
### 0.10.0 <small>June 14, 2023</small>
|
||||
|
||||
- Added [[#125](https://github.com/roboflow/supervision/pull/125)]: ability to load and save [`sv.ClassificationDataset`](https://roboflow.github.io/supervision/dataset/core/#classificationdataset) in a folder structure format.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> cs = sv.ClassificationDataset.from_folder_structure(
|
||||
... root_directory_path='...'
|
||||
... )
|
||||
|
||||
>>> cs.as_folder_structure(
|
||||
... root_directory_path='...'
|
||||
... )
|
||||
```
|
||||
|
||||
- Added [[#125](https://github.com/roboflow/supervision/pull/125)]: support for [`sv.ClassificationDataset.split`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.ClassificationDataset.split) allowing to divide `sv.ClassificationDataset` into two parts.
|
||||
|
||||
- Added [[#110](https://github.com/roboflow/supervision/pull/110)]: ability to extract masks from Roboflow API results using [`sv.Detections.from_roboflow`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_roboflow).
|
||||
|
||||
- Added [[commit hash](https://github.com/roboflow/supervision/commit/d000292eb2f2342544e0947b65528082e60fb8d6)]: Supervision Quickstart [notebook](https://colab.research.google.com/github/roboflow/supervision/blob/main/demo.ipynb) where you can learn more about Detection, Dataset and Video APIs.
|
||||
|
||||
- Changed [[#135](https://github.com/roboflow/supervision/pull/135)]: `sv.get_video_frames_generator` documentation to better describe actual behavior.
|
||||
|
||||
### 0.9.0 <small>June 7, 2023</small>
|
||||
|
||||
- Added [[#118](https://github.com/roboflow/supervision/pull/118)]: ability to select [`sv.Detections`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.__getitem__) by index, list of indexes or slice. Here is an example illustrating the new selection methods.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> detections = sv.Detections(...)
|
||||
>>> len(detections[0])
|
||||
1
|
||||
>>> len(detections[[0, 1]])
|
||||
2
|
||||
>>> len(detections[0:2])
|
||||
2
|
||||
```
|
||||
|
||||
- Added [[#101](https://github.com/roboflow/supervision/pull/101)]: ability to extract masks from YOLOv8 result using [`sv.Detections.from_yolov8`](https://roboflow.github.io/supervision/detection/core/#supervision.detection.core.Detections.from_yolov8). Here is an example illustrating how to extract boolean masks from the result of the YOLOv8 model inference.
|
||||
|
||||
- Added [[#122](https://github.com/roboflow/supervision/pull/122)]: ability to crop image using [`sv.crop`](https://roboflow.github.io/supervision/utils/image/#crop). Here is an example showing how to get a separate crop for each detection in `sv.Detections`.
|
||||
|
||||
- Added [[#120](https://github.com/roboflow/supervision/pull/120)]: ability to conveniently save multiple images into directory using [`sv.ImageSink`](https://roboflow.github.io/supervision/utils/image/#imagesink). Here is an example showing how to save every tenth video frame as a separate image.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> with sv.ImageSink(target_dir_path='target/directory/path') as sink:
|
||||
... for image in sv.get_video_frames_generator(source_path='source_video.mp4', stride=10):
|
||||
... sink.save_image(image=image)
|
||||
```
|
||||
|
||||
- Fixed [[#106](https://github.com/roboflow/supervision/issues/106)]: inconvenient handling of [`sv.PolygonZone`](https://roboflow.github.io/supervision/detection/tools/polygon_zone/#polygonzone) coordinates. Now `sv.PolygonZone` accepts coordinates in the form of `[[x1, y1], [x2, y2], ...]` that can be both integers and floats.
|
||||
|
||||
### 0.8.0 <small>May 17, 2023</small>
|
||||
|
||||
- Added [[#100](https://github.com/roboflow/supervision/pull/100)]: support for dataset inheritance. The current `Dataset` got renamed to `DetectionDataset`. Now [`DetectionDataset`](https://roboflow.github.io/supervision/dataset/core/#detectiondataset) inherits from `BaseDataset`. This change was made to enforce the future consistency of APIs of different types of computer vision datasets.
|
||||
- Added [[#100](https://github.com/roboflow/supervision/pull/100)]: ability to save datasets in YOLO format using [`DetectionDataset.as_yolo`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.as_yolo).
|
||||
|
||||
```python
|
||||
>>> import roboflow
|
||||
>>> from roboflow import Roboflow
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> roboflow.login()
|
||||
|
||||
>>> rf = Roboflow()
|
||||
|
||||
>>> project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
>>> dataset = project.version(PROJECT_VERSION).download("yolov5")
|
||||
|
||||
>>> ds = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path=f"{dataset.location}/train/images",
|
||||
... annotations_directory_path=f"{dataset.location}/train/labels",
|
||||
... data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
... )
|
||||
|
||||
>>> ds.classes
|
||||
['dog', 'person']
|
||||
```
|
||||
|
||||
- Added [[#102](https://github.com/roboflow/supervision/pull/103)]: support for [`DetectionDataset.split`](https://roboflow.github.io/supervision/dataset/core/#supervision.dataset.core.DetectionDataset.split) allowing to divide `DetectionDataset` into two parts.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> ds = sv.DetectionDataset(...)
|
||||
>>> train_ds, test_ds = ds.split(split_ratio=0.7, random_state=42, shuffle=True)
|
||||
|
||||
>>> len(train_ds), len(test_ds)
|
||||
(700, 300)
|
||||
```
|
||||
|
||||
- Changed [[#100](https://github.com/roboflow/supervision/pull/100)]: default value of `approximation_percentage` parameter from `0.75` to `0.0` in `DetectionDataset.as_yolo` and `DetectionDataset.as_pascal_voc`.
|
||||
|
||||
### 0.7.0 <small>May 11, 2023</small>
|
||||
|
||||
- Added [[#91](https://github.com/roboflow/supervision/pull/91)]: `Detections.from_yolo_nas` to enable seamless integration with [YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md) model.
|
||||
- Added [[#86](https://github.com/roboflow/supervision/pull/86)]: ability to load datasets in YOLO format using `Dataset.from_yolo`.
|
||||
- Added [[#84](https://github.com/roboflow/supervision/pull/84)]: `Detections.merge` to merge multiple `Detections` objects together.
|
||||
- Fixed [[#81](https://github.com/roboflow/supervision/pull/81)]: `LineZoneAnnotator.annotate` does not return annotated frame.
|
||||
- Changed [[#44](https://github.com/roboflow/supervision/pull/44)]: `LineZoneAnnotator.annotate` to allow for custom text for the in and out tags.
|
||||
|
||||
### 0.6.0 <small>April 19, 2023</small>
|
||||
|
||||
- Added [[#71](https://github.com/roboflow/supervision/pull/71)]: initial `Dataset` support and ability to save `Detections` in Pascal VOC XML format.
|
||||
- Added [[#71](https://github.com/roboflow/supervision/pull/71)]: new `mask_to_polygons`, `filter_polygons_by_area`, `polygon_to_xyxy` and `approximate_polygon` utilities.
|
||||
- Added [[#72](https://github.com/roboflow/supervision/pull/72)]: ability to load Pascal VOC XML **object detections** dataset as `Dataset`.
|
||||
- Changed [[#70](https://github.com/roboflow/supervision/pull/70)]: order of `Detections` attributes to make it consistent with order of objects in `__iter__` tuple.
|
||||
- Changed [[#71](https://github.com/roboflow/supervision/pull/71)]: `generate_2d_mask` to `polygon_to_mask`.
|
||||
|
||||
### 0.5.2 <small>April 13, 2023</small>
|
||||
|
||||
- Fixed [[#63](https://github.com/roboflow/supervision/pull/63)]: `LineZone.trigger` function expects 4 values instead of 5.
|
||||
|
||||
### 0.5.1 <small>April 12, 2023</small>
|
||||
|
||||
- Fixed `Detections.__getitem__` method did not return mask for selected item.
|
||||
- Fixed `Detections.area` crashed for mask detections.
|
||||
|
||||
### 0.5.0 <small>April 10, 2023</small>
|
||||
|
||||
- Added [[#58](https://github.com/roboflow/supervision/pull/58)]: `Detections.mask` to enable segmentation support.
|
||||
- Added [[#58](https://github.com/roboflow/supervision/pull/58)]: `MaskAnnotator` to allow easy `Detections.mask` annotation.
|
||||
- Added [[#58](https://github.com/roboflow/supervision/pull/58)]: `Detections.from_sam` to enable native Segment Anything Model (SAM) support.
|
||||
- Changed [[#58](https://github.com/roboflow/supervision/pull/58)]: `Detections.area` behaviour to work not only with boxes but also with masks.
|
||||
|
||||
### 0.4.0 <small>April 5, 2023</small>
|
||||
|
||||
- Added [[#46](https://github.com/roboflow/supervision/discussions/48)]: `Detections.empty` to allow easy creation of empty `Detections` objects.
|
||||
- Added [[#56](https://github.com/roboflow/supervision/pull/56)]: `Detections.from_roboflow` to allow easy creation of `Detections` objects from Roboflow API inference results.
|
||||
- Added [[#56](https://github.com/roboflow/supervision/pull/56)]: `plot_images_grid` to allow easy plotting of multiple images on single plot.
|
||||
- Added [[#56](https://github.com/roboflow/supervision/pull/56)]: initial support for Pascal VOC XML format with `detections_to_voc_xml` method.
|
||||
- Changed [[#56](https://github.com/roboflow/supervision/pull/56)]: `show_frame_in_notebook` refactored and renamed to `plot_image`.
|
||||
|
||||
### 0.3.2 <small>March 23, 2023</small>
|
||||
|
||||
- Changed [[#50](https://github.com/roboflow/supervision/issues/50)]: Allow `Detections.class_id` to be `None`.
|
||||
|
||||
### 0.3.1 <small>March 6, 2023</small>
|
||||
|
||||
- Fixed [[#41](https://github.com/roboflow/supervision/issues/41)]: `PolygonZone` throws an exception when the object touches the bottom edge of the image.
|
||||
- Fixed [[#42](https://github.com/roboflow/supervision/issues/42)]: `Detections.wth_nms` method throws an exception when `Detections` is empty.
|
||||
- Changed [[#36](https://github.com/roboflow/supervision/pull/36)]: `Detections.wth_nms` support class agnostic and non-class agnostic case.
|
||||
|
||||
### 0.3.0 <small>March 6, 2023</small>
|
||||
|
||||
- Changed: Allow `Detections.confidence` to be `None`.
|
||||
- Added: `Detections.from_transformers` and `Detections.from_detectron2` to enable seamless integration with Transformers and Detectron2 models.
|
||||
- Added: `Detections.area` to dynamically calculate bounding box area.
|
||||
- Added: `Detections.wth_nms` to filter out double detections with NMS. Initial - only class agnostic - implementation.
|
||||
|
||||
### 0.2.0 <small>February 2, 2023</small>
|
||||
|
||||
- Added: Advanced `Detections` filtering with pandas-like API.
|
||||
- Added: `Detections.from_yolov5` and `Detections.from_yolov8` to enable seamless integration with YOLOv5 and YOLOv8 models.
|
||||
|
||||
### 0.1.0 <small>January 19, 2023</small>
|
||||
|
||||
Say hello to Supervision 👋
|
||||
@@ -0,0 +1,3 @@
|
||||
## Classifications
|
||||
|
||||
:::supervision.classification.core.Classifications
|
||||
@@ -0,0 +1,12 @@
|
||||
!!! warning
|
||||
|
||||
Dataset API is still fluid and may change. If you use Dataset API in your project until further notice, freeze the
|
||||
`supervision` version in your `requirements.txt` or `setup.py`.
|
||||
|
||||
## DetectionDataset
|
||||
|
||||
:::supervision.dataset.core.DetectionDataset
|
||||
|
||||
## ClassificationDataset
|
||||
|
||||
:::supervision.dataset.core.ClassificationDataset
|
||||
@@ -0,0 +1,7 @@
|
||||
## BoxAnnotator
|
||||
|
||||
:::supervision.detection.annotate.BoxAnnotator
|
||||
|
||||
## MaskAnnotator
|
||||
|
||||
:::supervision.detection.annotate.MaskAnnotator
|
||||
@@ -0,0 +1,7 @@
|
||||
## PolygonZone
|
||||
|
||||
:::supervision.detection.tools.polygon_zone.PolygonZone
|
||||
|
||||
## PolygonZoneAnnotator
|
||||
|
||||
:::supervision.detection.tools.polygon_zone.PolygonZoneAnnotator
|
||||
@@ -0,0 +1,27 @@
|
||||
## box_iou_batch
|
||||
|
||||
:::supervision.detection.utils.box_iou_batch
|
||||
|
||||
## non_max_suppression
|
||||
|
||||
:::supervision.detection.utils.non_max_suppression
|
||||
|
||||
## polygon_to_mask
|
||||
|
||||
:::supervision.detection.utils.polygon_to_mask
|
||||
|
||||
## mask_to_xyxy
|
||||
|
||||
:::supervision.detection.utils.mask_to_xyxy
|
||||
|
||||
## mask_to_polygons
|
||||
|
||||
:::supervision.detection.utils.mask_to_polygons
|
||||
|
||||
## polygon_to_xyxy
|
||||
|
||||
:::supervision.detection.utils.polygon_to_xyxy
|
||||
|
||||
## filter_polygons_by_area
|
||||
|
||||
:::supervision.detection.utils.filter_polygons_by_area
|
||||
@@ -1,3 +0,0 @@
|
||||
## generate_2d_mask
|
||||
|
||||
:::supervision.detection.utils.generate_2d_mask
|
||||
@@ -1,7 +0,0 @@
|
||||
## draw_line
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
## draw_rectangle
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
@@ -0,0 +1,19 @@
|
||||
## draw_line
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
## draw_rectangle
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
## draw_filled_rectangle
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
## draw_polygon
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
## draw_text
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
+1
-1
@@ -19,7 +19,7 @@ pre-release stage 🚧 Keep your eyes open for potential bugs and be aware that
|
||||
## 💻 How to Install
|
||||
|
||||
You can install `supervision` with pip in a
|
||||
[**3.10>=Python>=3.7**](https://www.python.org/) environment.
|
||||
[**3.11>=Python>=3.7**](https://www.python.org/) environment.
|
||||
|
||||
!!! example "Pip install method (recommended)"
|
||||
|
||||
|
||||
@@ -1,3 +0,0 @@
|
||||
## show_frame_in_notebook
|
||||
|
||||
:::supervision.notebook.utils.show_frame_in_notebook
|
||||
@@ -0,0 +1,312 @@
|
||||
## advanced filtering
|
||||
|
||||
|
||||
The advanced filtering capabilities of the `Detections` class offer users a versatile and efficient way to narrow down
|
||||
and refine object detections. This section outlines various filtering methods, including filtering by specific class
|
||||
or a set of classes, confidence, object area, bounding box area, relative area, box dimensions, and designated zones.
|
||||
Each method is demonstrated with concise code examples to provide users with a clear understanding of how to implement
|
||||
the filters in their applications.
|
||||
|
||||
### by specific class
|
||||
|
||||
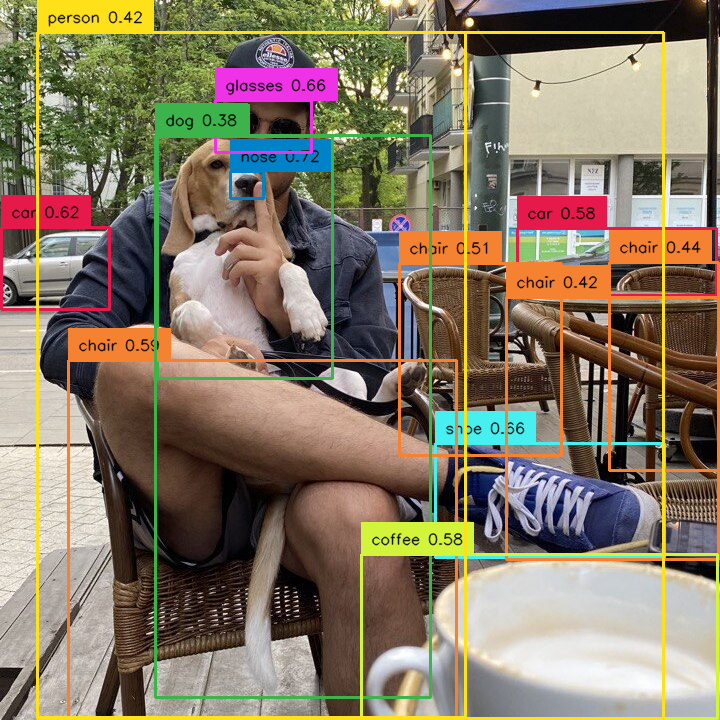
Allows you to select detections that belong only to one selected class.
|
||||
|
||||
=== "After"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
detections = sv.Detections(...)
|
||||
detections = detections[detections.class_id == 0]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Before"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
detections = sv.Detections(...)
|
||||
detections = detections[detections.class_id == 0]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
|
||||
### by set of classes
|
||||
|
||||
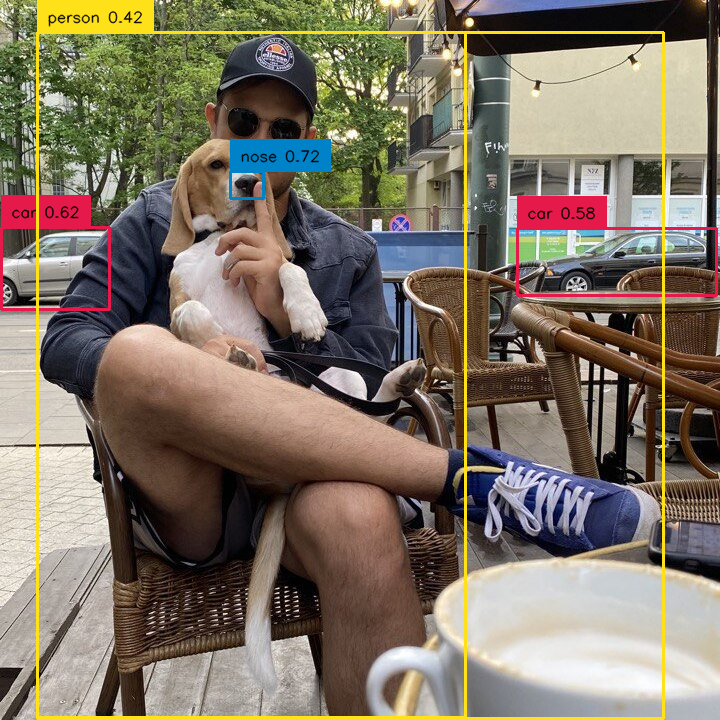
Allows you to select detections that belong only to selected set of classes.
|
||||
|
||||
=== "After"
|
||||
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
selected_classes = [0, 2, 3]
|
||||
detections = sv.Detections(...)
|
||||
detections = detections[np.isin(detections.class_id, selected_classes)]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Before"
|
||||
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
|
||||
class_id = [0, 2, 3]
|
||||
detections = sv.Detections(...)
|
||||
detections = detections[np.isin(detections.class_id, class_id)]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
### by confidence
|
||||
|
||||
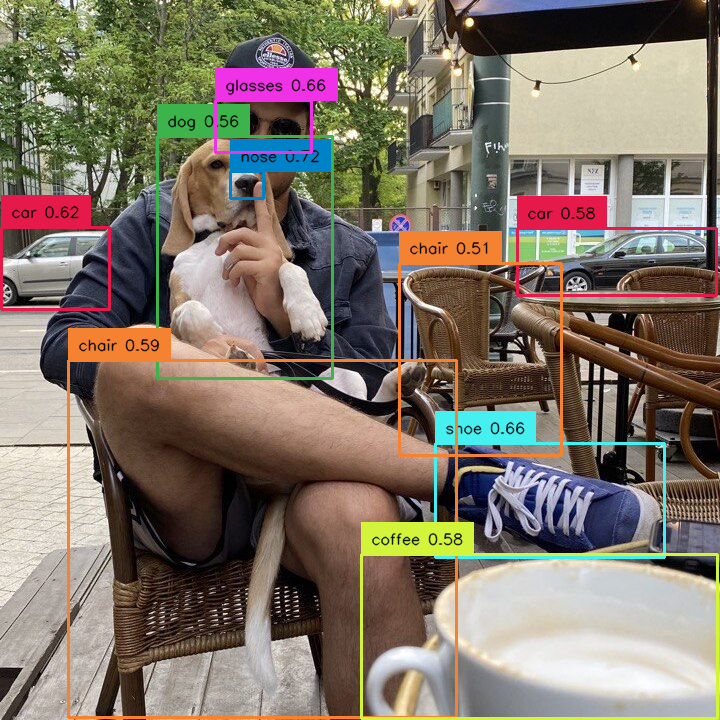
Allows you to select detections with specific confidence value, for example higher than selected threshold.
|
||||
|
||||
=== "After"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
detections = sv.Detections(...)
|
||||
detections = detections[detections.confidence > 0.5]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Before"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
detections = sv.Detections(...)
|
||||
detections = detections[detections.confidence > 0.5]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
### by area
|
||||
|
||||
Allows you to select detections based on their size. We define the area as the number of pixels occupied by the
|
||||
detection in the image. In the example below, we have sifted out the detections that are too small.
|
||||
|
||||
=== "After"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
detections = sv.Detections(...)
|
||||
detections = detections[detections.area > 1000]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
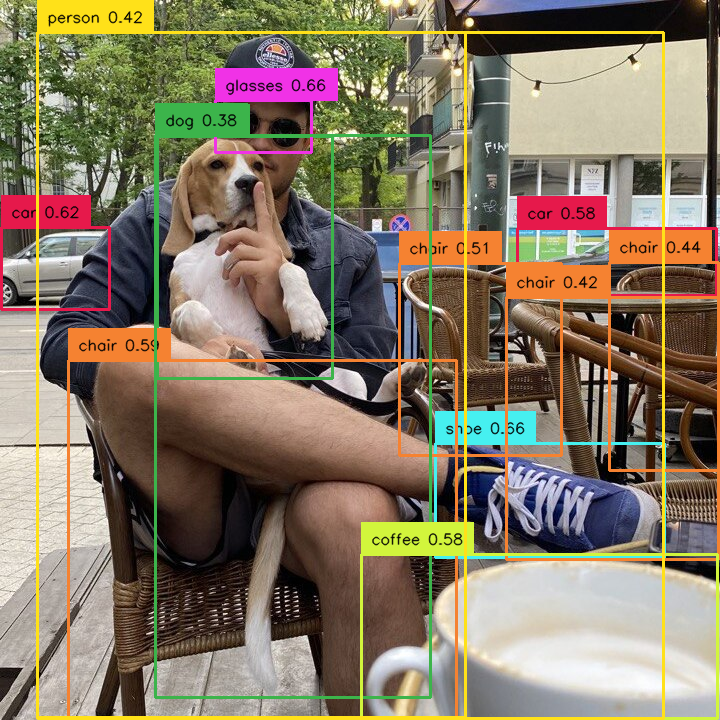{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Before"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
detections = sv.Detections(...)
|
||||
detections = detections[detections.area > 1000]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
### by relative area
|
||||
|
||||
Allows you to select detections based on their size in relation to the size of whole image. Sometimes the concept of
|
||||
detection size changes depending on the image. Detection occupying 10000 square px can be large on a 1280x720 image
|
||||
but small on a 3840x2160 image. In such cases, we can filter out detections based on the percentage of the image area
|
||||
occupied by them. In the example below, we remove too large detections.
|
||||
|
||||
=== "After"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
height, width, channels = image.shape
|
||||
image_area = height * width
|
||||
|
||||
detections = sv.Detections(...)
|
||||
detections = detections[(detections.area / image_area) < 0.8]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
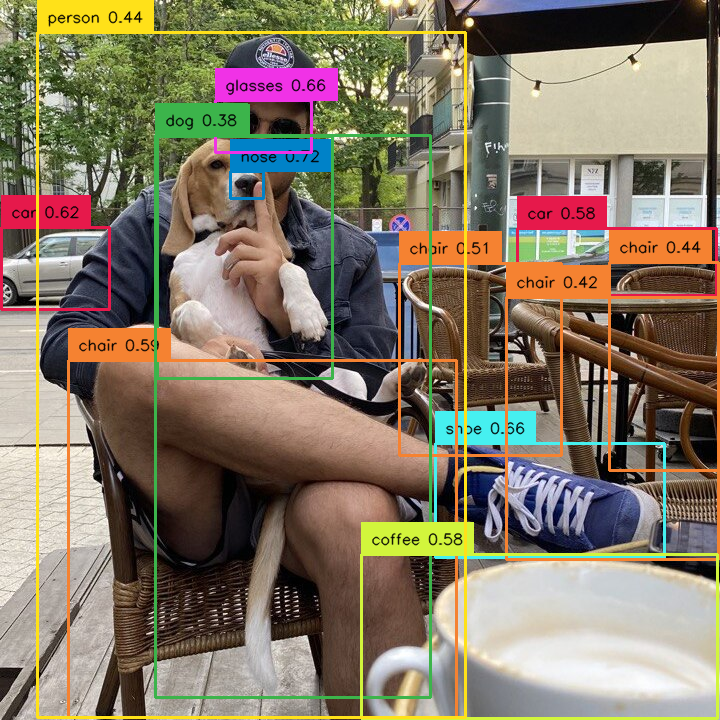{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Before"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
height, width, channels = image.shape
|
||||
image_area = height * width
|
||||
|
||||
detections = sv.Detections(...)
|
||||
detections = detections[(detections.area / image_area) < 0.8]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
### by box dimensions
|
||||
|
||||
Allows you to select detections based on their dimensions. The size of the bounding box, as well as its coordinates,
|
||||
can be criteria for rejecting detection. Implementing such filtering requires a bit of custom code but is relatively
|
||||
simple and fast.
|
||||
|
||||
=== "After"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
detections = sv.Detections(...)
|
||||
w = detections.xyxy[:, 2] - detections.xyxy[:, 0]
|
||||
h = detections.xyxy[:, 3] - detections.xyxy[:, 1]
|
||||
detections = detections[(w > 200) & (h > 200)]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
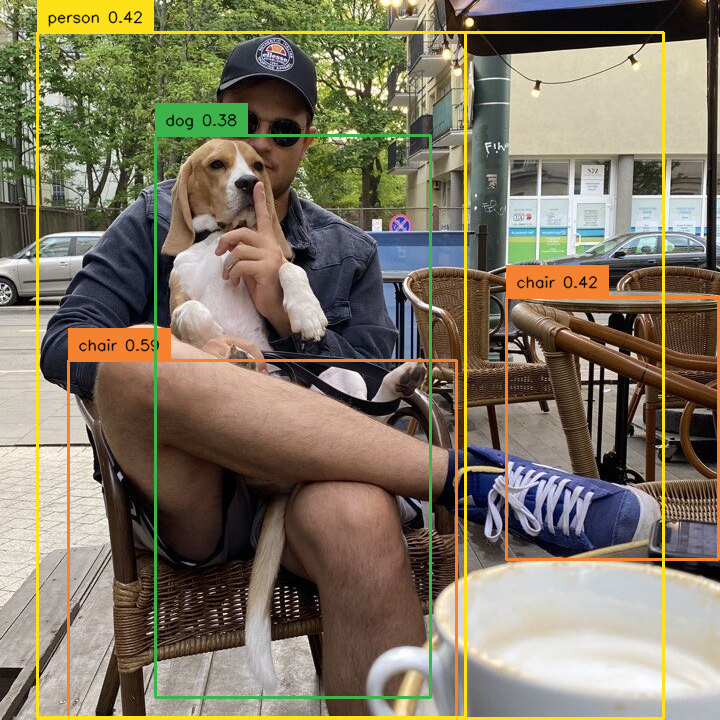{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Before"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
detections = sv.Detections(...)
|
||||
w = detections.xyxy[:, 2] - detections.xyxy[:, 0]
|
||||
h = detections.xyxy[:, 3] - detections.xyxy[:, 1]
|
||||
detections = detections[(w > 200) & (h > 200)]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
### by `PolygonZone`
|
||||
|
||||
Allows you to use `Detections` in combination with `PolygonZone` to weed out bounding boxes that are in and out of the
|
||||
zone. In the example below you can see how to filter out all detections located in the lower part of the image.
|
||||
|
||||
=== "After"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
zone = sv.PolygonZone(...)
|
||||
detections = sv.Detections(...)
|
||||
mask = zone.trigger(detections=detections)
|
||||
detections = detections[mask]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
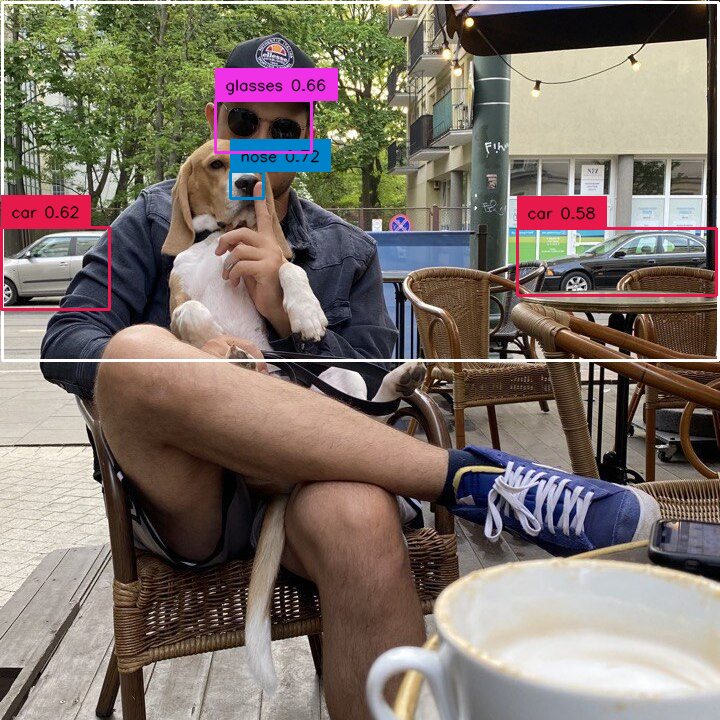{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Before"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
zone = sv.PolygonZone(...)
|
||||
detections = sv.Detections(...)
|
||||
mask = zone.trigger(detections=detections)
|
||||
detections = detections[mask]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
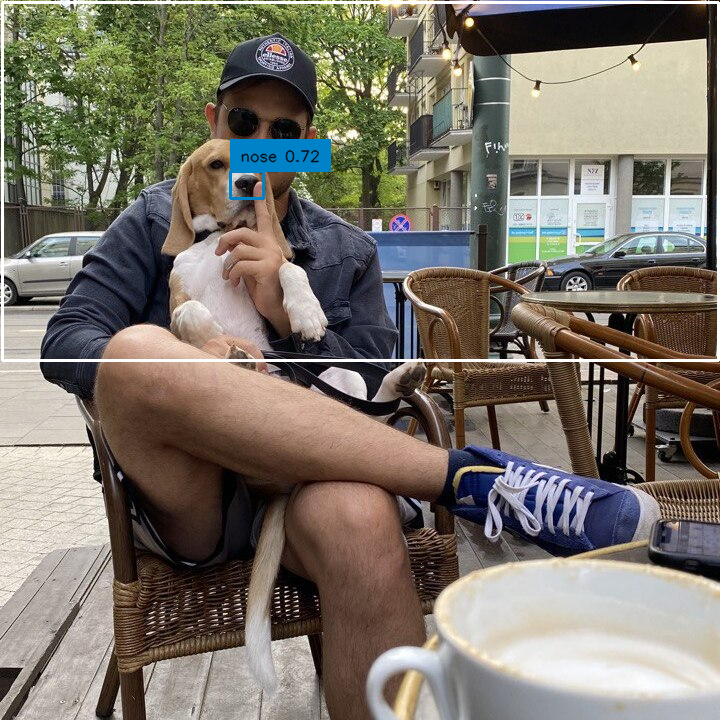
### by mixed conditions
|
||||
|
||||
`Detections`' greatest strength, however, is that you can build arbitrarily complex logical conditions by simply combining separate conditions using `&` or `|`.
|
||||
|
||||
=== "After"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
zone = sv.PolygonZone(...)
|
||||
detections = sv.Detections(...)
|
||||
mask = zone.trigger(detections=detections)
|
||||
detections = detections[(detections.confidence > 0.7) & mask]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Before"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
zone = sv.PolygonZone(...)
|
||||
detections = sv.Detections(...)
|
||||
mask = zone.trigger(detections=detections)
|
||||
detections = detections[mask]
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
@@ -0,0 +1,4 @@
|
||||
:root {
|
||||
--md-primary-fg-color: #8315F9;
|
||||
--md-accent-fg-color: #00FFCE;
|
||||
}
|
||||
@@ -0,0 +1,3 @@
|
||||
## list_files_with_extensions
|
||||
|
||||
:::supervision.utils.file.list_files_with_extensions
|
||||
@@ -0,0 +1,7 @@
|
||||
## ImageSink
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
||||
## crop
|
||||
|
||||
:::supervision.utils.image.crop
|
||||
@@ -0,0 +1,7 @@
|
||||
## plot_image
|
||||
|
||||
:::supervision.utils.notebook.plot_image
|
||||
|
||||
## plot_images_grid
|
||||
|
||||
:::supervision.utils.notebook.plot_images_grid
|
||||
@@ -0,0 +1,15 @@
|
||||
## VideoInfo
|
||||
|
||||
:::supervision.utils.video.VideoInfo
|
||||
|
||||
## VideoSink
|
||||
|
||||
:::supervision.utils.video.VideoSink
|
||||
|
||||
## get_video_frames_generator
|
||||
|
||||
:::supervision.utils.video.get_video_frames_generator
|
||||
|
||||
## process_video
|
||||
|
||||
:::supervision.utils.video.process_video
|
||||
@@ -1,15 +0,0 @@
|
||||
## VideoInfo
|
||||
|
||||
:::supervision.video.VideoInfo
|
||||
|
||||
## VideoSink
|
||||
|
||||
:::supervision.video.VideoSink
|
||||
|
||||
## get_video_frames_generator
|
||||
|
||||
:::supervision.video.get_video_frames_generator
|
||||
|
||||
## process_video
|
||||
|
||||
:::supervision.video.process_video
|
||||
+45
-12
@@ -21,24 +21,51 @@ extra:
|
||||
provider: google
|
||||
property: G-P7ZG0Y19G5
|
||||
|
||||
extra_css:
|
||||
- stylesheets/extra.css
|
||||
|
||||
nav:
|
||||
- Home: index.md
|
||||
- Quickstart:
|
||||
- Detections: quickstart/detections.md
|
||||
- API reference:
|
||||
- Video: video.md
|
||||
- Detection:
|
||||
- Core: detection_core.md
|
||||
- Utils: detection_utils.md
|
||||
- Draw: draw.md
|
||||
- Geometry: geometry.md
|
||||
- Notebook: notebook.md
|
||||
- Classifications:
|
||||
- Core: classification/core.md
|
||||
- Detections:
|
||||
- Core: detection/core.md
|
||||
- Annotate: detection/annotate.md
|
||||
- Utils: detection/utils.md
|
||||
- Tools:
|
||||
- Polygon Zone: detection/tools/polygon_zone.md
|
||||
- Dataset:
|
||||
- Core: dataset/core.md
|
||||
- Draw:
|
||||
- Utils: draw/utils.md
|
||||
- Utils:
|
||||
- Video: utils/video.md
|
||||
- Image: utils/image.md
|
||||
- Notebook: utils/notebook.md
|
||||
- File: utils/file.md
|
||||
- Changelog: changelog.md
|
||||
|
||||
theme:
|
||||
name: 'material'
|
||||
logo: https://raw.githubusercontent.com/roboflow/supervision/main/docs/assets/roboflow_logomark_white.svg
|
||||
favicon: https://raw.githubusercontent.com/roboflow/supervision/main/docs/assets/roboflow_logomark_color.svg
|
||||
logo: https://media.roboflow.com/open-source/supervision/supervision-lenny.png
|
||||
favicon: https://media.roboflow.com/open-source/supervision/supervision-lenny.png
|
||||
palette:
|
||||
primary: 'deep purple'
|
||||
accent: 'teal'
|
||||
# Palette for light mode
|
||||
- scheme: default
|
||||
primary: 'custom'
|
||||
toggle:
|
||||
icon: material/brightness-7
|
||||
name: Switch to dark mode
|
||||
|
||||
# Palette toggle for dark mode
|
||||
- scheme: slate
|
||||
primary: 'custom'
|
||||
toggle:
|
||||
icon: material/brightness-4
|
||||
name: Switch to light mode
|
||||
font:
|
||||
text: Roboto
|
||||
code: Roboto Mono
|
||||
@@ -50,4 +77,10 @@ plugins:
|
||||
markdown_extensions:
|
||||
- admonition
|
||||
- pymdownx.details
|
||||
- pymdownx.superfences
|
||||
- pymdownx.superfences
|
||||
- attr_list
|
||||
- md_in_html
|
||||
- pymdownx.tabbed:
|
||||
alternate_style: true
|
||||
- toc:
|
||||
permalink: true
|
||||
@@ -1,30 +0,0 @@
|
||||
certifi==2022.12.7
|
||||
charset-normalizer==3.0.1
|
||||
click==8.1.3
|
||||
colorama==0.4.6
|
||||
ghp-import==2.1.0
|
||||
griffe==0.25.4
|
||||
idna==3.4
|
||||
importlib-metadata==6.0.0
|
||||
Jinja2==3.1.2
|
||||
Markdown==3.3.7
|
||||
MarkupSafe==2.1.2
|
||||
mergedeep==1.3.4
|
||||
mkdocs==1.4.2
|
||||
mkdocs-autorefs==0.4.1
|
||||
mkdocs-material==9.0.9
|
||||
mkdocs-material-extensions==1.1.1
|
||||
mkdocstrings==0.20.0
|
||||
mkdocstrings-python==0.8.3
|
||||
packaging==23.0
|
||||
Pygments==2.14.0
|
||||
pymdown-extensions==9.9.2
|
||||
python-dateutil==2.8.2
|
||||
PyYAML==6.0
|
||||
pyyaml_env_tag==0.1
|
||||
regex==2022.10.31
|
||||
requests==2.28.2
|
||||
six==1.16.0
|
||||
urllib3==1.26.14
|
||||
watchdog==2.2.1
|
||||
zipp==3.12.0
|
||||
@@ -24,9 +24,10 @@ setuptools.setup(
|
||||
long_description_content_type='text/markdown',
|
||||
url='https://github.com/roboflow/supervision',
|
||||
install_requires=[
|
||||
'numpy',
|
||||
'numpy>=1.20.0',
|
||||
'opencv-python',
|
||||
'matplotlib'
|
||||
'matplotlib',
|
||||
'pyyaml'
|
||||
],
|
||||
packages=find_packages(exclude=("tests",)),
|
||||
extras_require={
|
||||
@@ -43,14 +44,17 @@ setuptools.setup(
|
||||
],
|
||||
},
|
||||
classifiers=[
|
||||
'Development Status :: 4 - Beta',
|
||||
'Intended Audience :: Developers',
|
||||
'Intended Audience :: Education',
|
||||
'Intended Audience :: Science/Research',
|
||||
'License :: OSI Approved :: BSD License',
|
||||
'License :: OSI Approved :: MIT License',
|
||||
'Programming Language :: Python :: 3',
|
||||
'Programming Language :: Python :: 3.7',
|
||||
'Programming Language :: Python :: 3.8',
|
||||
'Programming Language :: Python :: 3.9',
|
||||
'Programming Language :: Python :: 3.10',
|
||||
'Programming Language :: Python :: 3.11',
|
||||
'Programming Language :: Python :: 3 :: Only',
|
||||
'Topic :: Software Development',
|
||||
'Topic :: Scientific/Engineering',
|
||||
@@ -62,6 +66,6 @@ setuptools.setup(
|
||||
'Operating System :: Unix',
|
||||
'Operating System :: MacOS'
|
||||
],
|
||||
keywords="machine-learning, deep-learning, vision, ML, DL, AI, YOLOv5, YOLOv8, Roboflow",
|
||||
keywords="machine-learning, deep-learning, vision, ML, DL, AI, YOLOv5, YOLOv8, SAM, Roboflow",
|
||||
python_requires='>=3.7',
|
||||
)
|
||||
|
||||
+24
-6
@@ -1,14 +1,32 @@
|
||||
__version__ = "0.2.0"
|
||||
__version__ = "0.11.0"
|
||||
|
||||
from supervision.detection.core import BoxAnnotator, Detections
|
||||
from supervision.detection.polygon_zone import PolygonZone, PolygonZoneAnnotator
|
||||
from supervision.detection.utils import generate_2d_mask
|
||||
from supervision.classification.core import Classifications
|
||||
from supervision.dataset.core import (
|
||||
BaseDataset,
|
||||
ClassificationDataset,
|
||||
DetectionDataset,
|
||||
)
|
||||
from supervision.detection.annotate import BoxAnnotator, MaskAnnotator
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.line_counter import LineZone, LineZoneAnnotator
|
||||
from supervision.detection.tools.polygon_zone import PolygonZone, PolygonZoneAnnotator
|
||||
from supervision.detection.utils import (
|
||||
box_iou_batch,
|
||||
filter_polygons_by_area,
|
||||
mask_to_polygons,
|
||||
mask_to_xyxy,
|
||||
non_max_suppression,
|
||||
polygon_to_mask,
|
||||
polygon_to_xyxy,
|
||||
)
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.draw.utils import draw_filled_rectangle, draw_polygon, draw_text
|
||||
from supervision.geometry.core import Point, Position, Rect
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
from supervision.notebook.utils import show_frame_in_notebook
|
||||
from supervision.video import (
|
||||
from supervision.utils.file import list_files_with_extensions
|
||||
from supervision.utils.image import ImageSink, crop
|
||||
from supervision.utils.notebook import plot_image, plot_images_grid
|
||||
from supervision.utils.video import (
|
||||
VideoInfo,
|
||||
VideoSink,
|
||||
get_video_frames_generator,
|
||||
|
||||
@@ -0,0 +1,97 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import Any, Optional, Tuple
|
||||
|
||||
import numpy as np
|
||||
|
||||
|
||||
def _validate_class_ids(class_id: Any, n: int) -> None:
|
||||
"""
|
||||
Ensure that class_id is a 1d np.ndarray with (n, ) shape.
|
||||
"""
|
||||
is_valid = isinstance(class_id, np.ndarray) and class_id.shape == (n,)
|
||||
if not is_valid:
|
||||
raise ValueError("class_id must be 1d np.ndarray with (n, ) shape")
|
||||
|
||||
|
||||
def _validate_confidence(confidence: Any, n: int) -> None:
|
||||
"""
|
||||
Ensure that confidence is a 1d np.ndarray with (n, ) shape.
|
||||
"""
|
||||
if confidence is not None:
|
||||
is_valid = isinstance(confidence, np.ndarray) and confidence.shape == (n,)
|
||||
if not is_valid:
|
||||
raise ValueError("confidence must be 1d np.ndarray with (n, ) shape")
|
||||
|
||||
|
||||
@dataclass
|
||||
class Classifications:
|
||||
class_id: np.ndarray
|
||||
confidence: Optional[np.ndarray] = None
|
||||
|
||||
def __post_init__(self) -> None:
|
||||
"""
|
||||
Validate the classification inputs.
|
||||
"""
|
||||
n = len(self.class_id)
|
||||
|
||||
_validate_class_ids(self.class_id, n)
|
||||
_validate_confidence(self.confidence, n)
|
||||
|
||||
@classmethod
|
||||
def from_yolov8(cls, yolov8_results) -> Classifications:
|
||||
"""
|
||||
Creates a Classifications instance from a [YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
|
||||
Args:
|
||||
yolov8_results (ultralytics.yolo.engine.results.Results): The output Results instance from YOLOv8
|
||||
|
||||
Returns:
|
||||
Detections: A new Classifications object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> from ultralytics import YOLO
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> model = YOLO('yolov8s-cls.pt')
|
||||
>>> result = model(image)[0]
|
||||
>>> classifications = sv.Classifications.from_yolov8(result)
|
||||
```
|
||||
"""
|
||||
confidence = yolov8_results.probs.data.cpu().numpy()
|
||||
return cls(class_id=np.arange(confidence.shape[0]), confidence=confidence)
|
||||
|
||||
def get_top_k(self, k: int) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""
|
||||
Retrieve the top k class IDs and confidences, ordered in descending order by confidence.
|
||||
|
||||
Args:
|
||||
k (int): The number of top class IDs and confidences to retrieve.
|
||||
|
||||
Returns:
|
||||
Tuple[np.ndarray, np.ndarray]: A tuple containing the top k class IDs and confidences.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> classifications = sv.Classifications(...)
|
||||
|
||||
>>> classifications.get_top_k(1)
|
||||
|
||||
(array([1]), array([0.9]))
|
||||
```
|
||||
"""
|
||||
if self.confidence is None:
|
||||
raise ValueError("top_k could not be calculated, confidence is None")
|
||||
|
||||
order = np.argsort(self.confidence)[::-1]
|
||||
top_k_order = order[:k]
|
||||
top_k_class_id = self.class_id[top_k_order]
|
||||
top_k_confidence = self.confidence[top_k_order]
|
||||
|
||||
return top_k_class_id, top_k_confidence
|
||||
@@ -0,0 +1,642 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from abc import ABC, abstractmethod
|
||||
from dataclasses import dataclass
|
||||
from pathlib import Path
|
||||
from typing import Dict, Iterator, List, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.classification.core import Classifications
|
||||
from supervision.dataset.formats.coco import (
|
||||
load_coco_annotations,
|
||||
save_coco_annotations,
|
||||
)
|
||||
from supervision.dataset.formats.pascal_voc import (
|
||||
detections_to_pascal_voc,
|
||||
load_pascal_voc_annotations,
|
||||
)
|
||||
from supervision.dataset.formats.yolo import (
|
||||
load_yolo_annotations,
|
||||
save_data_yaml,
|
||||
save_yolo_annotations,
|
||||
)
|
||||
from supervision.dataset.utils import (
|
||||
build_class_index_mapping,
|
||||
map_detections_class_id,
|
||||
merge_class_lists,
|
||||
save_dataset_images,
|
||||
train_test_split,
|
||||
)
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.utils.file import list_files_with_extensions
|
||||
|
||||
|
||||
@dataclass
|
||||
class BaseDataset(ABC):
|
||||
@abstractmethod
|
||||
def __len__(self) -> int:
|
||||
pass
|
||||
|
||||
@abstractmethod
|
||||
def split(
|
||||
self, split_ratio=0.8, random_state=None, shuffle: bool = True
|
||||
) -> Tuple[BaseDataset, BaseDataset]:
|
||||
pass
|
||||
|
||||
|
||||
@dataclass
|
||||
class DetectionDataset(BaseDataset):
|
||||
"""
|
||||
Dataclass containing information about object detection dataset.
|
||||
|
||||
Attributes:
|
||||
classes (List[str]): List containing dataset class names.
|
||||
images (Dict[str, np.ndarray]): Dictionary mapping image name to image.
|
||||
annotations (Dict[str, Detections]): Dictionary mapping image name to annotations.
|
||||
"""
|
||||
|
||||
classes: List[str]
|
||||
images: Dict[str, np.ndarray]
|
||||
annotations: Dict[str, Detections]
|
||||
|
||||
def __len__(self) -> int:
|
||||
"""
|
||||
Return the number of images in the dataset.
|
||||
|
||||
Returns:
|
||||
int: The number of images.
|
||||
"""
|
||||
return len(self.images)
|
||||
|
||||
def __iter__(self) -> Iterator[Tuple[str, np.ndarray, Detections]]:
|
||||
"""
|
||||
Iterate over the images and annotations in the dataset.
|
||||
|
||||
Yields:
|
||||
Iterator[Tuple[str, np.ndarray, Detections]]: An iterator that yields tuples containing the image name,
|
||||
the image data, and its corresponding annotation.
|
||||
"""
|
||||
for image_name, image in self.images.items():
|
||||
yield image_name, image, self.annotations.get(image_name, None)
|
||||
|
||||
def __eq__(self, other):
|
||||
if not isinstance(other, DetectionDataset):
|
||||
return False
|
||||
|
||||
if set(self.classes) != set(other.classes):
|
||||
return False
|
||||
|
||||
for key in self.images:
|
||||
if not np.array_equal(self.images[key], other.images[key]):
|
||||
return False
|
||||
if not self.annotations[key] == other.annotations[key]:
|
||||
return False
|
||||
|
||||
return True
|
||||
|
||||
def split(
|
||||
self, split_ratio=0.8, random_state=None, shuffle: bool = True
|
||||
) -> Tuple[DetectionDataset, DetectionDataset]:
|
||||
"""
|
||||
Splits the dataset into two parts (training and testing) using the provided split_ratio.
|
||||
|
||||
Args:
|
||||
split_ratio (float, optional): The ratio of the training set to the entire dataset.
|
||||
random_state (int, optional): The seed for the random number generator. This is used for reproducibility.
|
||||
shuffle (bool, optional): Whether to shuffle the data before splitting.
|
||||
|
||||
Returns:
|
||||
Tuple[DetectionDataset, DetectionDataset]: A tuple containing the training and testing datasets.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> ds = sv.DetectionDataset(...)
|
||||
>>> train_ds, test_ds = ds.split(split_ratio=0.7, random_state=42, shuffle=True)
|
||||
>>> len(train_ds), len(test_ds)
|
||||
(700, 300)
|
||||
```
|
||||
"""
|
||||
|
||||
image_names = list(self.images.keys())
|
||||
train_names, test_names = train_test_split(
|
||||
data=image_names,
|
||||
train_ratio=split_ratio,
|
||||
random_state=random_state,
|
||||
shuffle=shuffle,
|
||||
)
|
||||
|
||||
train_dataset = DetectionDataset(
|
||||
classes=self.classes,
|
||||
images={name: self.images[name] for name in train_names},
|
||||
annotations={name: self.annotations[name] for name in train_names},
|
||||
)
|
||||
test_dataset = DetectionDataset(
|
||||
classes=self.classes,
|
||||
images={name: self.images[name] for name in test_names},
|
||||
annotations={name: self.annotations[name] for name in test_names},
|
||||
)
|
||||
return train_dataset, test_dataset
|
||||
|
||||
def as_pascal_voc(
|
||||
self,
|
||||
images_directory_path: Optional[str] = None,
|
||||
annotations_directory_path: Optional[str] = None,
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.0,
|
||||
) -> None:
|
||||
"""
|
||||
Exports the dataset to PASCAL VOC format. This method saves the images and their corresponding annotations in
|
||||
PASCAL VOC format.
|
||||
|
||||
Args:
|
||||
images_directory_path (Optional[str]): The path to the directory where the images should be saved.
|
||||
If not provided, images will not be saved.
|
||||
annotations_directory_path (Optional[str]): The path to the directory where the annotations in
|
||||
PASCAL VOC format should be saved. If not provided, annotations will not be saved.
|
||||
min_image_area_percentage (float): The minimum percentage of detection area relative to
|
||||
the image area for a detection to be included. Argument is used only for segmentation datasets.
|
||||
max_image_area_percentage (float): The maximum percentage of detection area relative to
|
||||
the image area for a detection to be included. Argument is used only for segmentation datasets.
|
||||
approximation_percentage (float): The percentage of polygon points to be removed from the input polygon,
|
||||
in the range [0, 1). Argument is used only for segmentation datasets.
|
||||
"""
|
||||
if images_directory_path:
|
||||
images_path = Path(images_directory_path)
|
||||
images_path.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
if annotations_directory_path:
|
||||
annotations_path = Path(annotations_directory_path)
|
||||
annotations_path.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
for image_name, image in self.images.items():
|
||||
detections = self.annotations[image_name]
|
||||
|
||||
if images_directory_path:
|
||||
cv2.imwrite(str(images_path / image_name), image)
|
||||
|
||||
if annotations_directory_path:
|
||||
annotation_name = Path(image_name).stem
|
||||
pascal_voc_xml = detections_to_pascal_voc(
|
||||
detections=detections,
|
||||
classes=self.classes,
|
||||
filename=image_name,
|
||||
image_shape=image.shape,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)
|
||||
|
||||
with open(annotations_path / f"{annotation_name}.xml", "w") as f:
|
||||
f.write(pascal_voc_xml)
|
||||
|
||||
@classmethod
|
||||
def from_pascal_voc(
|
||||
cls, images_directory_path: str, annotations_directory_path: str
|
||||
) -> DetectionDataset:
|
||||
"""
|
||||
Creates a Dataset instance from PASCAL VOC formatted data.
|
||||
|
||||
Args:
|
||||
images_directory_path (str): The path to the directory containing the images.
|
||||
annotations_directory_path (str): The path to the directory containing the PASCAL VOC XML annotations.
|
||||
|
||||
Returns:
|
||||
DetectionDataset: A DetectionDataset instance containing the loaded images and annotations.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import roboflow
|
||||
>>> from roboflow import Roboflow
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> roboflow.login()
|
||||
|
||||
>>> rf = Roboflow()
|
||||
|
||||
>>> project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
>>> dataset = project.version(PROJECT_VERSION).download("voc")
|
||||
|
||||
>>> ds = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path=f"{dataset.location}/train/images",
|
||||
... annotations_directory_path=f"{dataset.location}/train/labels"
|
||||
... )
|
||||
|
||||
>>> ds.classes
|
||||
['dog', 'person']
|
||||
```
|
||||
"""
|
||||
image_paths = list_files_with_extensions(
|
||||
directory=images_directory_path, extensions=["jpg", "jpeg", "png"]
|
||||
)
|
||||
annotation_paths = list_files_with_extensions(
|
||||
directory=annotations_directory_path, extensions=["xml"]
|
||||
)
|
||||
|
||||
raw_annotations: List[Tuple[str, Detections, List[str]]] = [
|
||||
load_pascal_voc_annotations(annotation_path=str(annotation_path))
|
||||
for annotation_path in annotation_paths
|
||||
]
|
||||
|
||||
classes = []
|
||||
for annotation in raw_annotations:
|
||||
classes.extend(annotation[2])
|
||||
classes = list(set(classes))
|
||||
|
||||
for annotation in raw_annotations:
|
||||
class_id = [classes.index(class_name) for class_name in annotation[2]]
|
||||
annotation[1].class_id = np.array(class_id)
|
||||
|
||||
images = {
|
||||
image_path.name: cv2.imread(str(image_path)) for image_path in image_paths
|
||||
}
|
||||
|
||||
annotations = {
|
||||
image_name: detections for image_name, detections, _ in raw_annotations
|
||||
}
|
||||
return DetectionDataset(classes=classes, images=images, annotations=annotations)
|
||||
|
||||
@classmethod
|
||||
def from_yolo(
|
||||
cls,
|
||||
images_directory_path: str,
|
||||
annotations_directory_path: str,
|
||||
data_yaml_path: str,
|
||||
force_masks: bool = False,
|
||||
) -> DetectionDataset:
|
||||
"""
|
||||
Creates a Dataset instance from YOLO formatted data.
|
||||
|
||||
Args:
|
||||
images_directory_path (str): The path to the directory containing the images.
|
||||
annotations_directory_path (str): The path to the directory containing the YOLO annotation files.
|
||||
data_yaml_path (str): The path to the data YAML file containing class information.
|
||||
force_masks (bool, optional): If True, forces masks to be loaded for all annotations, regardless of whether they are present.
|
||||
|
||||
Returns:
|
||||
DetectionDataset: A DetectionDataset instance containing the loaded images and annotations.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import roboflow
|
||||
>>> from roboflow import Roboflow
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> roboflow.login()
|
||||
|
||||
>>> rf = Roboflow()
|
||||
|
||||
>>> project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
>>> dataset = project.version(PROJECT_VERSION).download("yolov5")
|
||||
|
||||
>>> ds = sv.DetectionDataset.from_yolo(
|
||||
... images_directory_path=f"{dataset.location}/train/images",
|
||||
... annotations_directory_path=f"{dataset.location}/train/labels",
|
||||
... data_yaml_path=f"{dataset.location}/data.yaml"
|
||||
... )
|
||||
|
||||
>>> ds.classes
|
||||
['dog', 'person']
|
||||
```
|
||||
"""
|
||||
classes, images, annotations = load_yolo_annotations(
|
||||
images_directory_path=images_directory_path,
|
||||
annotations_directory_path=annotations_directory_path,
|
||||
data_yaml_path=data_yaml_path,
|
||||
force_masks=force_masks,
|
||||
)
|
||||
return DetectionDataset(classes=classes, images=images, annotations=annotations)
|
||||
|
||||
def as_yolo(
|
||||
self,
|
||||
images_directory_path: Optional[str] = None,
|
||||
annotations_directory_path: Optional[str] = None,
|
||||
data_yaml_path: Optional[str] = None,
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.0,
|
||||
) -> None:
|
||||
"""
|
||||
Exports the dataset to YOLO format. This method saves the images and their corresponding
|
||||
annotations in YOLO format.
|
||||
|
||||
Args:
|
||||
images_directory_path (Optional[str]): The path to the directory where the images should be saved.
|
||||
If not provided, images will not be saved.
|
||||
annotations_directory_path (Optional[str]): The path to the directory where the annotations in
|
||||
YOLO format should be saved. If not provided, annotations will not be saved.
|
||||
data_yaml_path (Optional[str]): The path where the data.yaml file should be saved.
|
||||
If not provided, the file will not be saved.
|
||||
min_image_area_percentage (float): The minimum percentage of detection area relative to
|
||||
the image area for a detection to be included. Argument is used only for segmentation datasets.
|
||||
max_image_area_percentage (float): The maximum percentage of detection area relative to
|
||||
the image area for a detection to be included. Argument is used only for segmentation datasets.
|
||||
approximation_percentage (float): The percentage of polygon points to be removed from the input polygon,
|
||||
in the range [0, 1). This is useful for simplifying the annotations. Argument is used only for
|
||||
segmentation datasets.
|
||||
"""
|
||||
if images_directory_path is not None:
|
||||
save_dataset_images(
|
||||
images_directory_path=images_directory_path, images=self.images
|
||||
)
|
||||
if annotations_directory_path is not None:
|
||||
save_yolo_annotations(
|
||||
annotations_directory_path=annotations_directory_path,
|
||||
images=self.images,
|
||||
annotations=self.annotations,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)
|
||||
if data_yaml_path is not None:
|
||||
save_data_yaml(data_yaml_path=data_yaml_path, classes=self.classes)
|
||||
|
||||
@classmethod
|
||||
def from_coco(
|
||||
cls,
|
||||
images_directory_path: str,
|
||||
annotations_path: str,
|
||||
force_masks: bool = False,
|
||||
) -> DetectionDataset:
|
||||
"""
|
||||
Creates a Dataset instance from COCO formatted data.
|
||||
|
||||
Args:
|
||||
images_directory_path (str): The path to the directory containing the images.
|
||||
annotations_path (str): The path to the json annotation files.
|
||||
force_masks (bool, optional): If True, forces masks to be loaded for all annotations, regardless of whether they are present.
|
||||
|
||||
Returns:
|
||||
DetectionDataset: A DetectionDataset instance containing the loaded images and annotations.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import roboflow
|
||||
>>> from roboflow import Roboflow
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> roboflow.login()
|
||||
|
||||
>>> rf = Roboflow()
|
||||
|
||||
>>> project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
>>> dataset = project.version(PROJECT_VERSION).download("coco")
|
||||
|
||||
>>> ds = sv.DetectionDataset.from_coco(
|
||||
... images_directory_path=f"{dataset.location}/train",
|
||||
... annotations_path=f"{dataset.location}/train/_annotations.coco.json",
|
||||
... )
|
||||
|
||||
>>> ds.classes
|
||||
['dog', 'person']
|
||||
```
|
||||
"""
|
||||
classes, images, annotations = load_coco_annotations(
|
||||
images_directory_path=images_directory_path,
|
||||
annotations_path=annotations_path,
|
||||
force_masks=force_masks,
|
||||
)
|
||||
return DetectionDataset(classes=classes, images=images, annotations=annotations)
|
||||
|
||||
def as_coco(
|
||||
self,
|
||||
images_directory_path: Optional[str] = None,
|
||||
annotations_path: Optional[str] = None,
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.0,
|
||||
) -> None:
|
||||
"""
|
||||
Exports the dataset to COCO format. This method saves the images and their corresponding
|
||||
annotations in COCO format.
|
||||
|
||||
Args:
|
||||
images_directory_path (Optional[str]): The path to the directory where the images should be saved.
|
||||
If not provided, images will not be saved.
|
||||
annotations_path (Optional[str]): The path to COCO annotation file.
|
||||
min_image_area_percentage (float): The minimum percentage of detection area relative to
|
||||
the image area for a detection to be included. Argument is used only for segmentation datasets.
|
||||
max_image_area_percentage (float): The maximum percentage of detection area relative to
|
||||
the image area for a detection to be included. Argument is used only for segmentation datasets.
|
||||
approximation_percentage (float): The percentage of polygon points to be removed from the input polygon,
|
||||
in the range [0, 1). This is useful for simplifying the annotations. Argument is used only for
|
||||
segmentation datasets.
|
||||
"""
|
||||
if images_directory_path is not None:
|
||||
save_dataset_images(
|
||||
images_directory_path=images_directory_path, images=self.images
|
||||
)
|
||||
if annotations_path is not None:
|
||||
save_coco_annotations(
|
||||
annotation_path=annotations_path,
|
||||
images=self.images,
|
||||
annotations=self.annotations,
|
||||
classes=self.classes,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def merge(cls, dataset_list: List[DetectionDataset]) -> DetectionDataset:
|
||||
"""
|
||||
Merge a list of `DetectionDataset` objects into a single `DetectionDataset` object.
|
||||
|
||||
This method takes a list of `DetectionDataset` objects and combines their respective fields (`classes`, `images`,
|
||||
`annotations`) into a single `DetectionDataset` object.
|
||||
|
||||
Args:
|
||||
dataset_list (List[DetectionDataset]): A list of `DetectionDataset` objects to merge.
|
||||
|
||||
Returns:
|
||||
(DetectionDataset): A single `DetectionDataset` object containing the merged data from the input list.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> ds_1 = sv.DetectionDataset(...)
|
||||
>>> len(ds_1)
|
||||
100
|
||||
>>> ds_1.classes
|
||||
['dog', 'person']
|
||||
|
||||
>>> ds_2 = sv.DetectionDataset(...)
|
||||
>>> len(ds_2)
|
||||
200
|
||||
>>> ds_2.classes
|
||||
['cat']
|
||||
|
||||
>>> ds_merged = sv.DetectionDataset.merge([ds_1, ds_2])
|
||||
>>> len(ds_merged)
|
||||
300
|
||||
>>> ds_merged.classes
|
||||
['cat', 'dog', 'person']
|
||||
```
|
||||
"""
|
||||
merged_images, merged_annotations = {}, {}
|
||||
class_lists = [dataset.classes for dataset in dataset_list]
|
||||
merged_classes = merge_class_lists(class_lists=class_lists)
|
||||
|
||||
for dataset in dataset_list:
|
||||
class_index_mapping = build_class_index_mapping(
|
||||
source_classes=dataset.classes, target_classes=merged_classes
|
||||
)
|
||||
for image_name, image, detections in dataset:
|
||||
if image_name in merged_annotations:
|
||||
raise ValueError(
|
||||
f"Image name {image_name} is not unique across datasets."
|
||||
)
|
||||
|
||||
merged_images[image_name] = image
|
||||
merged_annotations[image_name] = map_detections_class_id(
|
||||
source_to_target_mapping=class_index_mapping,
|
||||
detections=detections,
|
||||
)
|
||||
|
||||
return cls(
|
||||
classes=merged_classes, images=merged_images, annotations=merged_annotations
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ClassificationDataset(BaseDataset):
|
||||
"""
|
||||
Dataclass containing information about a classification dataset.
|
||||
|
||||
Attributes:
|
||||
classes (List[str]): List containing dataset class names.
|
||||
images (Dict[str, np.ndarray]): Dictionary mapping image name to image.
|
||||
annotations (Dict[str, Detections]): Dictionary mapping image name to annotations.
|
||||
"""
|
||||
|
||||
classes: List[str]
|
||||
images: Dict[str, np.ndarray]
|
||||
annotations: Dict[str, Classifications]
|
||||
|
||||
def __len__(self) -> int:
|
||||
return len(self.images)
|
||||
|
||||
def split(
|
||||
self, split_ratio=0.8, random_state=None, shuffle: bool = True
|
||||
) -> Tuple[ClassificationDataset, ClassificationDataset]:
|
||||
"""
|
||||
Splits the dataset into two parts (training and testing) using the provided split_ratio.
|
||||
|
||||
Args:
|
||||
split_ratio (float, optional): The ratio of the training set to the entire dataset.
|
||||
random_state (int, optional): The seed for the random number generator. This is used for reproducibility.
|
||||
shuffle (bool, optional): Whether to shuffle the data before splitting.
|
||||
|
||||
Returns:
|
||||
Tuple[ClassificationDataset, ClassificationDataset]: A tuple containing the training and testing datasets.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> cd = sv.ClassificationDataset(...)
|
||||
>>> train_cd, test_cd = cd.split(split_ratio=0.7, random_state=42, shuffle=True)
|
||||
>>> len(train_cd), len(test_cd)
|
||||
(700, 300)
|
||||
```
|
||||
"""
|
||||
image_names = list(self.images.keys())
|
||||
train_names, test_names = train_test_split(
|
||||
data=image_names,
|
||||
train_ratio=split_ratio,
|
||||
random_state=random_state,
|
||||
shuffle=shuffle,
|
||||
)
|
||||
|
||||
train_dataset = ClassificationDataset(
|
||||
classes=self.classes,
|
||||
images={name: self.images[name] for name in train_names},
|
||||
annotations={name: self.annotations[name] for name in train_names},
|
||||
)
|
||||
test_dataset = ClassificationDataset(
|
||||
classes=self.classes,
|
||||
images={name: self.images[name] for name in test_names},
|
||||
annotations={name: self.annotations[name] for name in test_names},
|
||||
)
|
||||
return train_dataset, test_dataset
|
||||
|
||||
def as_folder_structure(self, root_directory_path: str) -> None:
|
||||
"""
|
||||
Saves the dataset as a multi-class folder structure.
|
||||
|
||||
Args:
|
||||
root_directory_path (str): The path to the directory where the dataset will be saved.
|
||||
"""
|
||||
os.makedirs(root_directory_path, exist_ok=True)
|
||||
|
||||
for class_name in self.classes:
|
||||
os.makedirs(os.path.join(root_directory_path, class_name), exist_ok=True)
|
||||
|
||||
for image_name in self.images:
|
||||
classification = self.annotations[image_name]
|
||||
image = self.images[image_name]
|
||||
class_id = (
|
||||
classification.class_id[0]
|
||||
if classification.confidence is None
|
||||
else classification.get_top_k(1)[0]
|
||||
)
|
||||
class_name = self.classes[class_id]
|
||||
image_path = os.path.join(root_directory_path, class_name, image_name)
|
||||
cv2.imwrite(image_path, image)
|
||||
|
||||
@classmethod
|
||||
def from_folder_structure(cls, root_directory_path: str) -> ClassificationDataset:
|
||||
"""
|
||||
Load data from a multiclass folder structure into a ClassificationDataset.
|
||||
|
||||
Args:
|
||||
root_directory_path (str): The path to the dataset directory.
|
||||
|
||||
Returns:
|
||||
ClassificationDataset: The dataset.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import roboflow
|
||||
>>> from roboflow import Roboflow
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> roboflow.login()
|
||||
|
||||
>>> rf = Roboflow()
|
||||
|
||||
>>> project = rf.workspace(WORKSPACE_ID).project(PROJECT_ID)
|
||||
>>> dataset = project.version(PROJECT_VERSION).download("folder")
|
||||
|
||||
>>> cd = sv.ClassificationDataset.from_folder_structure(
|
||||
... root_directory_path=f"{dataset.location}/train"
|
||||
... )
|
||||
```
|
||||
"""
|
||||
classes = os.listdir(root_directory_path)
|
||||
classes = sorted(set(classes))
|
||||
|
||||
images = {}
|
||||
annotations = {}
|
||||
|
||||
for class_name in classes:
|
||||
class_id = classes.index(class_name)
|
||||
|
||||
for image in os.listdir(os.path.join(root_directory_path, class_name)):
|
||||
image_dir = os.path.join(root_directory_path, class_name, image)
|
||||
images[image] = cv2.imread(image_dir)
|
||||
annotations[image] = Classifications(
|
||||
class_id=np.array([class_id]),
|
||||
)
|
||||
|
||||
return cls(
|
||||
classes=classes,
|
||||
images=images,
|
||||
annotations=annotations,
|
||||
)
|
||||
@@ -0,0 +1,216 @@
|
||||
import os
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
from typing import Dict, List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.dataset.utils import approximate_mask_with_polygons
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import polygon_to_mask
|
||||
from supervision.utils.file import read_json_file, save_json_file
|
||||
|
||||
|
||||
def coco_categories_to_classes(coco_categories: List[dict]) -> List[str]:
|
||||
return [
|
||||
category["name"]
|
||||
for category in sorted(coco_categories, key=lambda category: category["id"])
|
||||
]
|
||||
|
||||
|
||||
def classes_to_coco_categories(classes: List[str]) -> List[dict]:
|
||||
return [
|
||||
{
|
||||
"id": class_id,
|
||||
"name": class_name,
|
||||
"supercategory": "common-objects",
|
||||
}
|
||||
for class_id, class_name in enumerate(classes)
|
||||
]
|
||||
|
||||
|
||||
def group_coco_annotations_by_image_id(
|
||||
coco_annotations: List[dict],
|
||||
) -> Dict[int, List[dict]]:
|
||||
annotations = {}
|
||||
for annotation in coco_annotations:
|
||||
image_id = annotation["image_id"]
|
||||
if image_id not in annotations:
|
||||
annotations[image_id] = []
|
||||
annotations[image_id].append(annotation)
|
||||
return annotations
|
||||
|
||||
|
||||
def _polygons_to_masks(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> np.ndarray:
|
||||
return np.array(
|
||||
[
|
||||
polygon_to_mask(polygon=polygon, resolution_wh=resolution_wh)
|
||||
for polygon in polygons
|
||||
],
|
||||
dtype=bool,
|
||||
)
|
||||
|
||||
|
||||
def coco_annotations_to_detections(
|
||||
image_annotations: List[dict], resolution_wh: Tuple[int, int], with_masks: bool
|
||||
) -> Detections:
|
||||
if not image_annotations:
|
||||
return Detections.empty()
|
||||
|
||||
class_ids = [
|
||||
image_annotation["category_id"] for image_annotation in image_annotations
|
||||
]
|
||||
xyxy = [image_annotation["bbox"] for image_annotation in image_annotations]
|
||||
xyxy = np.asarray(xyxy)
|
||||
xyxy[:, 2:4] += xyxy[:, 0:2]
|
||||
|
||||
if with_masks:
|
||||
polygons = [
|
||||
np.reshape(
|
||||
np.asarray(image_annotation["segmentation"], dtype=np.int32), (-1, 2)
|
||||
)
|
||||
for image_annotation in image_annotations
|
||||
]
|
||||
mask = _polygons_to_masks(polygons=polygons, resolution_wh=resolution_wh)
|
||||
return Detections(
|
||||
class_id=np.asarray(class_ids, dtype=int), xyxy=xyxy, mask=mask
|
||||
)
|
||||
|
||||
return Detections(xyxy=xyxy, class_id=np.asarray(class_ids, dtype=int))
|
||||
|
||||
|
||||
def detections_to_coco_annotations(
|
||||
detections: Detections,
|
||||
image_id: int,
|
||||
annotation_id: int,
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> Tuple[List[Dict], int]:
|
||||
coco_annotations = []
|
||||
for xyxy, mask, _, class_id, _ in detections:
|
||||
box_width, box_height = xyxy[2] - xyxy[0], xyxy[3] - xyxy[1]
|
||||
polygon = []
|
||||
if mask is not None:
|
||||
polygon = list(
|
||||
approximate_mask_with_polygons(
|
||||
mask=mask,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)[0].flatten()
|
||||
)
|
||||
coco_annotation = {
|
||||
"id": annotation_id,
|
||||
"image_id": image_id,
|
||||
"category_id": int(class_id),
|
||||
"bbox": [xyxy[0], xyxy[1], box_width, box_height],
|
||||
"area": box_width * box_height,
|
||||
"segmentation": polygon,
|
||||
"iscrowd": 0,
|
||||
}
|
||||
coco_annotations.append(coco_annotation)
|
||||
annotation_id += 1
|
||||
return coco_annotations, annotation_id
|
||||
|
||||
|
||||
def load_coco_annotations(
|
||||
images_directory_path: str,
|
||||
annotations_path: str,
|
||||
force_masks: bool = False,
|
||||
) -> Tuple[List[str], Dict[str, np.ndarray], Dict[str, Detections]]:
|
||||
coco_data = read_json_file(file_path=annotations_path)
|
||||
classes = coco_categories_to_classes(coco_categories=coco_data["categories"])
|
||||
coco_images = coco_data["images"]
|
||||
coco_annotations_groups = group_coco_annotations_by_image_id(
|
||||
coco_annotations=coco_data["annotations"]
|
||||
)
|
||||
|
||||
images = {}
|
||||
annotations = {}
|
||||
|
||||
for coco_image in coco_images:
|
||||
image_name, image_width, image_height = (
|
||||
coco_image["file_name"],
|
||||
coco_image["width"],
|
||||
coco_image["height"],
|
||||
)
|
||||
image_annotations = coco_annotations_groups.get(coco_image["id"], [])
|
||||
image_path = os.path.join(images_directory_path, image_name)
|
||||
|
||||
image = cv2.imread(str(image_path))
|
||||
annotation = coco_annotations_to_detections(
|
||||
image_annotations=image_annotations,
|
||||
resolution_wh=(image_width, image_height),
|
||||
with_masks=force_masks,
|
||||
)
|
||||
|
||||
images[image_name] = image
|
||||
annotations[image_name] = annotation
|
||||
|
||||
return classes, images, annotations
|
||||
|
||||
|
||||
def save_coco_annotations(
|
||||
annotation_path: str,
|
||||
images: Dict[str, np.ndarray],
|
||||
annotations: Dict[str, Detections],
|
||||
classes: List[str],
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> None:
|
||||
Path(annotation_path).parent.mkdir(parents=True, exist_ok=True)
|
||||
info = {}
|
||||
licenses = [
|
||||
{
|
||||
"id": 1,
|
||||
"url": "https://creativecommons.org/licenses/by/4.0/",
|
||||
"name": "CC BY 4.0",
|
||||
}
|
||||
]
|
||||
|
||||
coco_annotations = []
|
||||
coco_images = []
|
||||
coco_categories = classes_to_coco_categories(classes=classes)
|
||||
|
||||
image_id = 0
|
||||
annotation_id = 0
|
||||
for image_name, image in images.items():
|
||||
image_height, image_width, _ = image.shape
|
||||
|
||||
coco_image = {
|
||||
"id": image_id,
|
||||
"license": 1,
|
||||
"file_name": image_name,
|
||||
"height": image_height,
|
||||
"width": image_width,
|
||||
"date_captured": datetime.now().strftime("%m/%d/%Y,%H:%M:%S"),
|
||||
}
|
||||
|
||||
coco_images.append(coco_image)
|
||||
detections = annotations[image_name]
|
||||
|
||||
coco_annotation, label_id = detections_to_coco_annotations(
|
||||
detections=detections,
|
||||
image_id=image_id,
|
||||
annotation_id=annotation_id,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)
|
||||
|
||||
coco_annotations.extend(coco_annotation)
|
||||
image_id += 1
|
||||
|
||||
annotation_dict = {
|
||||
"info": info,
|
||||
"licenses": licenses,
|
||||
"categories": coco_categories,
|
||||
"images": coco_images,
|
||||
"annotations": coco_annotations,
|
||||
}
|
||||
save_json_file(annotation_dict, file_path=annotation_path)
|
||||
@@ -0,0 +1,156 @@
|
||||
from typing import List, Optional, Tuple
|
||||
from xml.dom.minidom import parseString
|
||||
from xml.etree.ElementTree import Element, SubElement, parse, tostring
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.dataset.utils import approximate_mask_with_polygons
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import polygon_to_xyxy
|
||||
|
||||
|
||||
def object_to_pascal_voc(
|
||||
xyxy: np.ndarray, name: str, polygon: Optional[np.ndarray] = None
|
||||
) -> Element:
|
||||
root = Element("object")
|
||||
|
||||
object_name = SubElement(root, "name")
|
||||
object_name.text = name
|
||||
|
||||
bndbox = SubElement(root, "bndbox")
|
||||
xmin = SubElement(bndbox, "xmin")
|
||||
xmin.text = str(int(xyxy[0]))
|
||||
ymin = SubElement(bndbox, "ymin")
|
||||
ymin.text = str(int(xyxy[1]))
|
||||
xmax = SubElement(bndbox, "xmax")
|
||||
xmax.text = str(int(xyxy[2]))
|
||||
ymax = SubElement(bndbox, "ymax")
|
||||
ymax.text = str(int(xyxy[3]))
|
||||
|
||||
if polygon is not None:
|
||||
object_polygon = SubElement(root, "polygon")
|
||||
for index, point in enumerate(polygon, start=1):
|
||||
x_coordinate, y_coordinate = point
|
||||
x = SubElement(object_polygon, f"x{index}")
|
||||
x.text = str(x_coordinate)
|
||||
y = SubElement(object_polygon, f"y{index}")
|
||||
y.text = str(y_coordinate)
|
||||
|
||||
return root
|
||||
|
||||
|
||||
def detections_to_pascal_voc(
|
||||
detections: Detections,
|
||||
classes: List[str],
|
||||
filename: str,
|
||||
image_shape: Tuple[int, int, int],
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> str:
|
||||
"""
|
||||
Converts Detections object to Pascal VOC XML format.
|
||||
|
||||
Args:
|
||||
detections (Detections): A Detections object containing bounding boxes, class ids, and other relevant information.
|
||||
classes (List[str]): A list of class names corresponding to the class ids in the Detections object.
|
||||
filename (str): The name of the image file associated with the detections.
|
||||
image_shape (Tuple[int, int, int]): The shape of the image file associated with the detections.
|
||||
min_image_area_percentage (float): Minimum detection area relative to area of image associated with it.
|
||||
max_image_area_percentage (float): Maximum detection area relative to area of image associated with it.
|
||||
approximation_percentage (float): The percentage of polygon points to be removed from the input polygon, in the range [0, 1).
|
||||
Returns:
|
||||
str: An XML string in Pascal VOC format representing the detections.
|
||||
"""
|
||||
height, width, depth = image_shape
|
||||
|
||||
# Create root element
|
||||
annotation = Element("annotation")
|
||||
|
||||
# Add folder element
|
||||
folder = SubElement(annotation, "folder")
|
||||
folder.text = "VOC"
|
||||
|
||||
# Add filename element
|
||||
file_name = SubElement(annotation, "filename")
|
||||
file_name.text = filename
|
||||
|
||||
# Add source element
|
||||
source = SubElement(annotation, "source")
|
||||
database = SubElement(source, "database")
|
||||
database.text = "roboflow.ai"
|
||||
|
||||
# Add size element
|
||||
size = SubElement(annotation, "size")
|
||||
w = SubElement(size, "width")
|
||||
w.text = str(width)
|
||||
h = SubElement(size, "height")
|
||||
h.text = str(height)
|
||||
d = SubElement(size, "depth")
|
||||
d.text = str(depth)
|
||||
|
||||
# Add segmented element
|
||||
segmented = SubElement(annotation, "segmented")
|
||||
segmented.text = "0"
|
||||
|
||||
# Add object elements
|
||||
for xyxy, mask, _, class_id, _ in detections:
|
||||
name = classes[class_id]
|
||||
if mask is not None:
|
||||
polygons = approximate_mask_with_polygons(
|
||||
mask=mask,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)
|
||||
for polygon in polygons:
|
||||
xyxy = polygon_to_xyxy(polygon=polygon)
|
||||
next_object = object_to_pascal_voc(
|
||||
xyxy=xyxy, name=name, polygon=polygon
|
||||
)
|
||||
annotation.append(next_object)
|
||||
else:
|
||||
next_object = object_to_pascal_voc(xyxy=xyxy, name=name)
|
||||
annotation.append(next_object)
|
||||
|
||||
# Generate XML string
|
||||
xml_string = parseString(tostring(annotation)).toprettyxml(indent=" ")
|
||||
|
||||
return xml_string
|
||||
|
||||
|
||||
def load_pascal_voc_annotations(
|
||||
annotation_path: str,
|
||||
) -> Tuple[str, Detections, List[str]]:
|
||||
"""
|
||||
Loads PASCAL VOC XML annotations and returns the image name, a Detections instance, and a list of class names.
|
||||
|
||||
Args:
|
||||
annotation_path (str): The path to the PASCAL VOC XML annotations file.
|
||||
|
||||
Returns:
|
||||
Tuple[str, Detections, List[str]]: A tuple containing the image name, a Detections instance, and a list of class names of objects in the detections.
|
||||
"""
|
||||
tree = parse(annotation_path)
|
||||
root = tree.getroot()
|
||||
|
||||
image_name = root.find("filename").text
|
||||
|
||||
xyxy = []
|
||||
class_names = []
|
||||
for obj in root.findall("object"):
|
||||
class_name = obj.find("name").text
|
||||
class_names.append(class_name)
|
||||
|
||||
bbox = obj.find("bndbox")
|
||||
x1 = int(bbox.find("xmin").text)
|
||||
y1 = int(bbox.find("ymin").text)
|
||||
x2 = int(bbox.find("xmax").text)
|
||||
y2 = int(bbox.find("ymax").text)
|
||||
|
||||
xyxy.append([x1, y1, x2, y2])
|
||||
|
||||
xyxy = np.array(xyxy)
|
||||
detections = Detections(xyxy=xyxy)
|
||||
|
||||
return image_name, detections, class_names
|
||||
@@ -0,0 +1,246 @@
|
||||
import os
|
||||
from pathlib import Path
|
||||
from typing import Dict, List, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.dataset.utils import approximate_mask_with_polygons
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import polygon_to_mask, polygon_to_xyxy
|
||||
from supervision.utils.file import (
|
||||
list_files_with_extensions,
|
||||
read_txt_file,
|
||||
read_yaml_file,
|
||||
save_text_file,
|
||||
save_yaml_file,
|
||||
)
|
||||
|
||||
|
||||
def _parse_box(values: List[str]) -> np.ndarray:
|
||||
x_center, y_center, width, height = values
|
||||
return np.array(
|
||||
[
|
||||
float(x_center) - float(width) / 2,
|
||||
float(y_center) - float(height) / 2,
|
||||
float(x_center) + float(width) / 2,
|
||||
float(y_center) + float(height) / 2,
|
||||
],
|
||||
dtype=np.float32,
|
||||
)
|
||||
|
||||
|
||||
def _box_to_polygon(box: np.ndarray) -> np.ndarray:
|
||||
return np.array(
|
||||
[[box[0], box[1]], [box[2], box[1]], [box[2], box[3]], [box[0], box[3]]]
|
||||
)
|
||||
|
||||
|
||||
def _parse_polygon(values: List[str]) -> np.ndarray:
|
||||
return np.array(values, dtype=np.float32).reshape(-1, 2)
|
||||
|
||||
|
||||
def _polygons_to_masks(
|
||||
polygons: List[np.ndarray], resolution_wh: Tuple[int, int]
|
||||
) -> np.ndarray:
|
||||
return np.array(
|
||||
[
|
||||
polygon_to_mask(polygon=polygon, resolution_wh=resolution_wh)
|
||||
for polygon in polygons
|
||||
],
|
||||
dtype=bool,
|
||||
)
|
||||
|
||||
|
||||
def _pair_image_with_annotation(
|
||||
image_paths: List[Union[str, Path]], annotation_paths: List[Union[str, Path]]
|
||||
) -> List[Tuple[Union[str, Path], Union[str, Path]]]:
|
||||
image_dict = {p.stem: p for p in image_paths}
|
||||
return [
|
||||
(image_dict[annotation_path.stem], annotation_path)
|
||||
for annotation_path in annotation_paths
|
||||
if annotation_path.stem in image_dict
|
||||
]
|
||||
|
||||
|
||||
def _with_mask(lines: List[str]) -> bool:
|
||||
return any([len(line.split()) > 5 for line in lines])
|
||||
|
||||
|
||||
def _extract_class_names(file_path: str) -> List[str]:
|
||||
data = read_yaml_file(file_path=file_path)
|
||||
return data["names"]
|
||||
|
||||
|
||||
def _image_name_to_annotation_name(image_name: str) -> str:
|
||||
base_name, _ = os.path.splitext(image_name)
|
||||
return base_name + ".txt"
|
||||
|
||||
|
||||
def yolo_annotations_to_detections(
|
||||
lines: List[str], resolution_wh: Tuple[int, int], with_masks: bool
|
||||
) -> Detections:
|
||||
if len(lines) == 0:
|
||||
return Detections.empty()
|
||||
|
||||
class_id, relative_xyxy, relative_polygon = [], [], []
|
||||
w, h = resolution_wh
|
||||
for line in lines:
|
||||
values = line.split()
|
||||
class_id.append(int(values[0]))
|
||||
if len(values) == 5:
|
||||
box = _parse_box(values=values[1:])
|
||||
relative_xyxy.append(box)
|
||||
if with_masks:
|
||||
relative_polygon.append(_box_to_polygon(box=box))
|
||||
elif len(values) > 5:
|
||||
polygon = _parse_polygon(values=values[1:])
|
||||
relative_xyxy.append(polygon_to_xyxy(polygon=polygon))
|
||||
if with_masks:
|
||||
relative_polygon.append(polygon)
|
||||
|
||||
class_id = np.array(class_id, dtype=int)
|
||||
relative_xyxy = np.array(relative_xyxy, dtype=np.float32)
|
||||
xyxy = relative_xyxy * np.array([w, h, w, h], dtype=np.float32)
|
||||
|
||||
if not with_masks:
|
||||
return Detections(class_id=class_id, xyxy=xyxy)
|
||||
|
||||
polygons = [
|
||||
(polygon * np.array(resolution_wh)).astype(int) for polygon in relative_polygon
|
||||
]
|
||||
mask = _polygons_to_masks(polygons=polygons, resolution_wh=resolution_wh)
|
||||
return Detections(class_id=class_id, xyxy=xyxy, mask=mask)
|
||||
|
||||
|
||||
def load_yolo_annotations(
|
||||
images_directory_path: str,
|
||||
annotations_directory_path: str,
|
||||
data_yaml_path: str,
|
||||
force_masks: bool = False,
|
||||
) -> Tuple[List[str], Dict[str, np.ndarray], Dict[str, Detections]]:
|
||||
"""
|
||||
Loads YOLO annotations and returns class names, images, and their corresponding detections.
|
||||
|
||||
Args:
|
||||
images_directory_path (str): The path to the directory containing the images.
|
||||
annotations_directory_path (str): The path to the directory containing the YOLO annotation files.
|
||||
data_yaml_path (str): The path to the data YAML file containing class information.
|
||||
force_masks (bool, optional): If True, forces masks to be loaded for all annotations, regardless of whether they are present.
|
||||
|
||||
Returns:
|
||||
Tuple[List[str], Dict[str, np.ndarray], Dict[str, Detections]]: A tuple containing a list of class names, a dictionary with image names as keys and images as values, and a dictionary with image names as keys and corresponding Detections instances as values.
|
||||
"""
|
||||
image_paths = list_files_with_extensions(
|
||||
directory=images_directory_path, extensions=["jpg", "jpeg", "png"]
|
||||
)
|
||||
annotation_paths = list_files_with_extensions(
|
||||
directory=annotations_directory_path, extensions=["txt"]
|
||||
)
|
||||
path_pairs = _pair_image_with_annotation(
|
||||
image_paths=image_paths, annotation_paths=annotation_paths
|
||||
)
|
||||
classes = _extract_class_names(file_path=data_yaml_path)
|
||||
images = {}
|
||||
annotations = {}
|
||||
for image_path, annotation_path in path_pairs:
|
||||
image = cv2.imread(str(image_path))
|
||||
lines = read_txt_file(str(annotation_path))
|
||||
h, w, _ = image.shape
|
||||
resolution_wh = (w, h)
|
||||
|
||||
with_masks = _with_mask(lines=lines)
|
||||
with_masks = force_masks if force_masks else with_masks
|
||||
annotation = yolo_annotations_to_detections(
|
||||
lines=lines, resolution_wh=resolution_wh, with_masks=with_masks
|
||||
)
|
||||
|
||||
images[image_path.name] = image
|
||||
annotations[image_path.name] = annotation
|
||||
return classes, images, annotations
|
||||
|
||||
|
||||
def object_to_yolo(
|
||||
xyxy: np.ndarray,
|
||||
class_id: int,
|
||||
image_shape: Tuple[int, int, int],
|
||||
polygon: Optional[np.ndarray] = None,
|
||||
) -> str:
|
||||
h, w, _ = image_shape
|
||||
if polygon is None:
|
||||
xyxy_relative = xyxy / np.array([w, h, w, h], dtype=np.float32)
|
||||
x_min, y_min, x_max, y_max = xyxy_relative
|
||||
x_center = (x_min + x_max) / 2
|
||||
y_center = (y_min + y_max) / 2
|
||||
width = x_max - x_min
|
||||
height = y_max - y_min
|
||||
return f"{int(class_id)} {x_center:.5f} {y_center:.5f} {width:.5f} {height:.5f}"
|
||||
else:
|
||||
polygon_relative = polygon / np.array([w, h], dtype=np.float32)
|
||||
polygon_relative = polygon_relative.reshape(-1)
|
||||
polygon_parsed = " ".join([f"{value:.5f}" for value in polygon_relative])
|
||||
return f"{int(class_id)} {polygon_parsed}"
|
||||
|
||||
|
||||
def detections_to_yolo_annotations(
|
||||
detections: Detections,
|
||||
image_shape: Tuple[int, int, int],
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> List[str]:
|
||||
annotation = []
|
||||
for xyxy, mask, _, class_id, _ in detections:
|
||||
if mask is not None:
|
||||
polygons = approximate_mask_with_polygons(
|
||||
mask=mask,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)
|
||||
for polygon in polygons:
|
||||
xyxy = polygon_to_xyxy(polygon=polygon)
|
||||
next_object = object_to_yolo(
|
||||
xyxy=xyxy,
|
||||
class_id=class_id,
|
||||
image_shape=image_shape,
|
||||
polygon=polygon,
|
||||
)
|
||||
annotation.append(next_object)
|
||||
else:
|
||||
next_object = object_to_yolo(
|
||||
xyxy=xyxy, class_id=class_id, image_shape=image_shape
|
||||
)
|
||||
annotation.append(next_object)
|
||||
return annotation
|
||||
|
||||
|
||||
def save_yolo_annotations(
|
||||
annotations_directory_path: str,
|
||||
images: Dict[str, np.ndarray],
|
||||
annotations: Dict[str, Detections],
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> None:
|
||||
Path(annotations_directory_path).mkdir(parents=True, exist_ok=True)
|
||||
for image_name, image in images.items():
|
||||
detections = annotations[image_name]
|
||||
yolo_annotations_name = _image_name_to_annotation_name(image_name=image_name)
|
||||
yolo_annotations_path = os.path.join(
|
||||
annotations_directory_path, yolo_annotations_name
|
||||
)
|
||||
lines = detections_to_yolo_annotations(
|
||||
detections=detections,
|
||||
image_shape=image.shape,
|
||||
min_image_area_percentage=min_image_area_percentage,
|
||||
max_image_area_percentage=max_image_area_percentage,
|
||||
approximation_percentage=approximation_percentage,
|
||||
)
|
||||
save_text_file(lines=lines, file_path=yolo_annotations_path)
|
||||
|
||||
|
||||
def save_data_yaml(data_yaml_path: str, classes: List[str]) -> None:
|
||||
data = {"nc": len(classes), "names": classes}
|
||||
Path(data_yaml_path).parent.mkdir(parents=True, exist_ok=True)
|
||||
save_yaml_file(data=data, file_path=data_yaml_path)
|
||||
@@ -0,0 +1,128 @@
|
||||
import copy
|
||||
import os
|
||||
import random
|
||||
from pathlib import Path
|
||||
from typing import Dict, List, Optional, Tuple, TypeVar
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.detection.utils import (
|
||||
approximate_polygon,
|
||||
filter_polygons_by_area,
|
||||
mask_to_polygons,
|
||||
)
|
||||
|
||||
T = TypeVar("T")
|
||||
|
||||
|
||||
def approximate_mask_with_polygons(
|
||||
mask: np.ndarray,
|
||||
min_image_area_percentage: float = 0.0,
|
||||
max_image_area_percentage: float = 1.0,
|
||||
approximation_percentage: float = 0.75,
|
||||
) -> List[np.ndarray]:
|
||||
height, width = mask.shape
|
||||
image_area = height * width
|
||||
minimum_detection_area = min_image_area_percentage * image_area
|
||||
maximum_detection_area = max_image_area_percentage * image_area
|
||||
|
||||
polygons = mask_to_polygons(mask=mask)
|
||||
if len(polygons) == 1:
|
||||
polygons = filter_polygons_by_area(
|
||||
polygons=polygons, min_area=None, max_area=maximum_detection_area
|
||||
)
|
||||
else:
|
||||
polygons = filter_polygons_by_area(
|
||||
polygons=polygons,
|
||||
min_area=minimum_detection_area,
|
||||
max_area=maximum_detection_area,
|
||||
)
|
||||
return [
|
||||
approximate_polygon(polygon=polygon, percentage=approximation_percentage)
|
||||
for polygon in polygons
|
||||
]
|
||||
|
||||
|
||||
def merge_class_lists(class_lists: List[List[str]]) -> List[str]:
|
||||
unique_classes = set()
|
||||
|
||||
for class_list in class_lists:
|
||||
for class_name in class_list:
|
||||
unique_classes.add(class_name.lower())
|
||||
|
||||
return sorted(list(unique_classes))
|
||||
|
||||
|
||||
def build_class_index_mapping(
|
||||
source_classes: List[str], target_classes: List[str]
|
||||
) -> Dict[int, int]:
|
||||
index_mapping = {}
|
||||
|
||||
for i, class_name in enumerate(source_classes):
|
||||
if class_name not in target_classes:
|
||||
raise ValueError(
|
||||
f"Class {class_name} not found in target classes. "
|
||||
f"source_classes must be a subset of target_classes."
|
||||
)
|
||||
corresponding_index = target_classes.index(class_name)
|
||||
index_mapping[i] = corresponding_index
|
||||
|
||||
return index_mapping
|
||||
|
||||
|
||||
def map_detections_class_id(
|
||||
source_to_target_mapping: Dict[int, int], detections: Detections
|
||||
) -> Detections:
|
||||
if detections.class_id is None:
|
||||
raise ValueError("Detections must have class_id attribute.")
|
||||
if set(np.unique(detections.class_id)) - set(source_to_target_mapping.keys()):
|
||||
raise ValueError(
|
||||
"Detections class_id must be a subset of source_to_target_mapping keys."
|
||||
)
|
||||
|
||||
detections_copy = copy.deepcopy(detections)
|
||||
detections_copy.class_id = np.vectorize(source_to_target_mapping.get)(
|
||||
detections_copy.class_id
|
||||
)
|
||||
|
||||
return detections_copy
|
||||
|
||||
|
||||
def save_dataset_images(
|
||||
images_directory_path: str, images: Dict[str, np.ndarray]
|
||||
) -> None:
|
||||
Path(images_directory_path).mkdir(parents=True, exist_ok=True)
|
||||
|
||||
for image_name, image in images.items():
|
||||
target_image_path = os.path.join(images_directory_path, image_name)
|
||||
cv2.imwrite(target_image_path, image)
|
||||
|
||||
|
||||
def train_test_split(
|
||||
data: List[T],
|
||||
train_ratio: float = 0.8,
|
||||
random_state: Optional[int] = None,
|
||||
shuffle: bool = True,
|
||||
) -> Tuple[List[T], List[T]]:
|
||||
"""
|
||||
Splits the data into two parts using the provided train_ratio.
|
||||
|
||||
Args:
|
||||
data (List[T]): The data to split.
|
||||
train_ratio (float): The ratio of the training set to the entire dataset.
|
||||
random_state (Optional[int]): The seed for the random number generator.
|
||||
shuffle (bool): Whether to shuffle the data before splitting.
|
||||
|
||||
Returns:
|
||||
Tuple[List[T], List[T]]: The split data.
|
||||
"""
|
||||
if random_state is not None:
|
||||
random.seed(random_state)
|
||||
|
||||
if shuffle:
|
||||
random.shuffle(data)
|
||||
|
||||
split_index = int(len(data) * train_ratio)
|
||||
return data[:split_index], data[split_index:]
|
||||
@@ -0,0 +1,195 @@
|
||||
from typing import List, Optional, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
|
||||
|
||||
class BoxAnnotator:
|
||||
"""
|
||||
A class for drawing bounding boxes on an image using detections provided.
|
||||
|
||||
Attributes:
|
||||
color (Union[Color, ColorPalette]): The color to draw the bounding box, can be a single color or a color palette
|
||||
thickness (int): The thickness of the bounding box lines, default is 2
|
||||
text_color (Color): The color of the text on the bounding box, default is white
|
||||
text_scale (float): The scale of the text on the bounding box, default is 0.5
|
||||
text_thickness (int): The thickness of the text on the bounding box, default is 1
|
||||
text_padding (int): The padding around the text on the bounding box, default is 5
|
||||
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
thickness: int = 2,
|
||||
text_color: Color = Color.black(),
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
):
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.thickness: int = thickness
|
||||
self.text_color: Color = text_color
|
||||
self.text_scale: float = text_scale
|
||||
self.text_thickness: int = text_thickness
|
||||
self.text_padding: int = text_padding
|
||||
|
||||
def annotate(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
detections: Detections,
|
||||
labels: Optional[List[str]] = None,
|
||||
skip_label: bool = False,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Draws bounding boxes on the frame using the detections provided.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image on which the bounding boxes will be drawn
|
||||
detections (Detections): The detections for which the bounding boxes will be drawn
|
||||
labels (Optional[List[str]]): An optional list of labels corresponding to each detection. If `labels` are not provided, corresponding `class_id` will be used as label.
|
||||
skip_label (bool): Is set to `True`, skips bounding box label annotation.
|
||||
Returns:
|
||||
np.ndarray: The image with the bounding boxes drawn on it
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> classes = ['person', ...]
|
||||
>>> image = ...
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> box_annotator = sv.BoxAnnotator()
|
||||
>>> labels = [
|
||||
... f"{classes[class_id]} {confidence:0.2f}"
|
||||
... for _, _, confidence, class_id, _
|
||||
... in detections
|
||||
... ]
|
||||
>>> annotated_frame = box_annotator.annotate(
|
||||
... scene=image.copy(),
|
||||
... detections=detections,
|
||||
... labels=labels
|
||||
... )
|
||||
```
|
||||
"""
|
||||
font = cv2.FONT_HERSHEY_SIMPLEX
|
||||
for i in range(len(detections)):
|
||||
x1, y1, x2, y2 = detections.xyxy[i].astype(int)
|
||||
class_id = (
|
||||
detections.class_id[i] if detections.class_id is not None else None
|
||||
)
|
||||
idx = class_id if class_id is not None else i
|
||||
color = (
|
||||
self.color.by_idx(idx)
|
||||
if isinstance(self.color, ColorPalette)
|
||||
else self.color
|
||||
)
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=(x1, y1),
|
||||
pt2=(x2, y2),
|
||||
color=color.as_bgr(),
|
||||
thickness=self.thickness,
|
||||
)
|
||||
if skip_label:
|
||||
continue
|
||||
|
||||
text = (
|
||||
f"{class_id}"
|
||||
if (labels is None or len(detections) != len(labels))
|
||||
else labels[i]
|
||||
)
|
||||
|
||||
text_width, text_height = cv2.getTextSize(
|
||||
text=text,
|
||||
fontFace=font,
|
||||
fontScale=self.text_scale,
|
||||
thickness=self.text_thickness,
|
||||
)[0]
|
||||
|
||||
text_x = x1 + self.text_padding
|
||||
text_y = y1 - self.text_padding
|
||||
|
||||
text_background_x1 = x1
|
||||
text_background_y1 = y1 - 2 * self.text_padding - text_height
|
||||
|
||||
text_background_x2 = x1 + 2 * self.text_padding + text_width
|
||||
text_background_y2 = y1
|
||||
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=(text_background_x1, text_background_y1),
|
||||
pt2=(text_background_x2, text_background_y2),
|
||||
color=color.as_bgr(),
|
||||
thickness=cv2.FILLED,
|
||||
)
|
||||
cv2.putText(
|
||||
img=scene,
|
||||
text=text,
|
||||
org=(text_x, text_y),
|
||||
fontFace=font,
|
||||
fontScale=self.text_scale,
|
||||
color=self.text_color.as_rgb(),
|
||||
thickness=self.text_thickness,
|
||||
lineType=cv2.LINE_AA,
|
||||
)
|
||||
return scene
|
||||
|
||||
|
||||
class MaskAnnotator:
|
||||
"""
|
||||
A class for overlaying masks on an image using detections provided.
|
||||
|
||||
Attributes:
|
||||
color (Union[Color, ColorPalette]): The color to fill the mask, can be a single color or a color palette
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
):
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
|
||||
def annotate(
|
||||
self, scene: np.ndarray, detections: Detections, opacity: float = 0.5
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Overlays the masks on the given image based on the provided detections, with a specified opacity.
|
||||
|
||||
Args:
|
||||
scene (np.ndarray): The image on which the masks will be overlaid
|
||||
detections (Detections): The detections for which the masks will be overlaid
|
||||
opacity (float): The opacity of the masks, between 0 and 1, default is 0.5
|
||||
|
||||
Returns:
|
||||
np.ndarray: The image with the masks overlaid
|
||||
"""
|
||||
if detections.mask is None:
|
||||
return scene
|
||||
|
||||
for i in np.flip(np.argsort(detections.area)):
|
||||
class_id = (
|
||||
detections.class_id[i] if detections.class_id is not None else None
|
||||
)
|
||||
idx = class_id if class_id is not None else i
|
||||
color = (
|
||||
self.color.by_idx(idx)
|
||||
if isinstance(self.color, ColorPalette)
|
||||
else self.color
|
||||
)
|
||||
|
||||
mask = detections.mask[i]
|
||||
colored_mask = np.zeros_like(scene, dtype=np.uint8)
|
||||
colored_mask[:] = color.as_bgr()
|
||||
|
||||
scene = np.where(
|
||||
np.expand_dims(mask, axis=-1),
|
||||
np.uint8(opacity * colored_mask + (1 - opacity) * scene),
|
||||
scene,
|
||||
)
|
||||
|
||||
return scene
|
||||
+440
-180
@@ -1,51 +1,83 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import List, Optional, Union
|
||||
from dataclasses import astuple, dataclass
|
||||
from typing import Any, Iterator, List, Optional, Tuple, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision.draw.color import Color, ColorPalette
|
||||
from supervision.detection.utils import (
|
||||
extract_yolov8_masks,
|
||||
non_max_suppression,
|
||||
process_roboflow_result,
|
||||
xywh_to_xyxy,
|
||||
)
|
||||
from supervision.geometry.core import Position
|
||||
|
||||
|
||||
def _validate_xyxy(xyxy: Any, n: int) -> None:
|
||||
is_valid = isinstance(xyxy, np.ndarray) and xyxy.shape == (n, 4)
|
||||
if not is_valid:
|
||||
raise ValueError("xyxy must be 2d np.ndarray with (n, 4) shape")
|
||||
|
||||
|
||||
def _validate_mask(mask: Any, n: int) -> None:
|
||||
is_valid = mask is None or (
|
||||
isinstance(mask, np.ndarray) and len(mask.shape) == 3 and mask.shape[0] == n
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("mask must be 3d np.ndarray with (n, W, H) shape")
|
||||
|
||||
|
||||
def _validate_class_id(class_id: Any, n: int) -> None:
|
||||
is_valid = class_id is None or (
|
||||
isinstance(class_id, np.ndarray) and class_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("class_id must be None or 1d np.ndarray with (n,) shape")
|
||||
|
||||
|
||||
def _validate_confidence(confidence: Any, n: int) -> None:
|
||||
is_valid = confidence is None or (
|
||||
isinstance(confidence, np.ndarray) and confidence.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("confidence must be None or 1d np.ndarray with (n,) shape")
|
||||
|
||||
|
||||
def _validate_tracker_id(tracker_id: Any, n: int) -> None:
|
||||
is_valid = tracker_id is None or (
|
||||
isinstance(tracker_id, np.ndarray) and tracker_id.shape == (n,)
|
||||
)
|
||||
if not is_valid:
|
||||
raise ValueError("tracker_id must be None or 1d np.ndarray with (n,) shape")
|
||||
|
||||
|
||||
@dataclass
|
||||
class Detections:
|
||||
"""
|
||||
Data class containing information about the detections in a video frame.
|
||||
|
||||
Attributes:
|
||||
xyxy (np.ndarray): An array of shape `(n, 4)` containing the bounding boxes coordinates in format `[x1, y1, x2, y2]`
|
||||
confidence (np.ndarray): An array of shape `(n,)` containing the confidence scores of the detections.
|
||||
class_id (np.ndarray): An array of shape `(n,)` containing the class ids of the detections.
|
||||
mask: (Optional[np.ndarray]): An array of shape `(n, W, H)` containing the segmentation masks.
|
||||
confidence (Optional[np.ndarray]): An array of shape `(n,)` containing the confidence scores of the detections.
|
||||
class_id (Optional[np.ndarray]): An array of shape `(n,)` containing the class ids of the detections.
|
||||
tracker_id (Optional[np.ndarray]): An array of shape `(n,)` containing the tracker ids of the detections.
|
||||
"""
|
||||
|
||||
xyxy: np.ndarray
|
||||
confidence: np.ndarray
|
||||
class_id: np.ndarray
|
||||
mask: np.Optional[np.ndarray] = None
|
||||
confidence: Optional[np.ndarray] = None
|
||||
class_id: Optional[np.ndarray] = None
|
||||
tracker_id: Optional[np.ndarray] = None
|
||||
|
||||
def __post_init__(self):
|
||||
n = len(self.xyxy)
|
||||
validators = [
|
||||
(isinstance(self.xyxy, np.ndarray) and self.xyxy.shape == (n, 4)),
|
||||
(isinstance(self.confidence, np.ndarray) and self.confidence.shape == (n,)),
|
||||
(isinstance(self.class_id, np.ndarray) and self.class_id.shape == (n,)),
|
||||
self.tracker_id is None
|
||||
or (
|
||||
isinstance(self.tracker_id, np.ndarray)
|
||||
and self.tracker_id.shape == (n,)
|
||||
),
|
||||
]
|
||||
if not all(validators):
|
||||
raise ValueError(
|
||||
"xyxy must be 2d np.ndarray with (n, 4) shape, "
|
||||
"confidence must be 1d np.ndarray with (n,) shape, "
|
||||
"class_id must be 1d np.ndarray with (n,) shape, "
|
||||
"tracker_id must be None or 1d np.ndarray with (n,) shape"
|
||||
)
|
||||
_validate_xyxy(xyxy=self.xyxy, n=n)
|
||||
_validate_mask(mask=self.mask, n=n)
|
||||
_validate_class_id(class_id=self.class_id, n=n)
|
||||
_validate_confidence(confidence=self.confidence, n=n)
|
||||
_validate_tracker_id(tracker_id=self.tracker_id, n=n)
|
||||
|
||||
def __len__(self):
|
||||
"""
|
||||
@@ -53,39 +85,84 @@ class Detections:
|
||||
"""
|
||||
return len(self.xyxy)
|
||||
|
||||
def __iter__(self):
|
||||
def __iter__(
|
||||
self,
|
||||
) -> Iterator[
|
||||
Tuple[
|
||||
np.ndarray,
|
||||
Optional[np.ndarray],
|
||||
Optional[float],
|
||||
Optional[int],
|
||||
Optional[int],
|
||||
]
|
||||
]:
|
||||
"""
|
||||
Iterates over the Detections object and yield a tuple of `(xyxy, confidence, class_id, tracker_id)` for each detection.
|
||||
Iterates over the Detections object and yield a tuple of `(xyxy, mask, confidence, class_id, tracker_id)` for each detection.
|
||||
"""
|
||||
for i in range(len(self.xyxy)):
|
||||
yield (
|
||||
self.xyxy[i],
|
||||
self.confidence[i],
|
||||
self.class_id[i],
|
||||
self.mask[i] if self.mask is not None else None,
|
||||
self.confidence[i] if self.confidence is not None else None,
|
||||
self.class_id[i] if self.class_id is not None else None,
|
||||
self.tracker_id[i] if self.tracker_id is not None else None,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_yolov5(cls, yolov5_detections):
|
||||
"""
|
||||
Creates a Detections instance from a YOLOv5 output Detections
|
||||
def __eq__(self, other: Detections):
|
||||
return all(
|
||||
[
|
||||
np.array_equal(self.xyxy, other.xyxy),
|
||||
any(
|
||||
[
|
||||
self.mask is None and other.mask is None,
|
||||
np.array_equal(self.mask, other.mask),
|
||||
]
|
||||
),
|
||||
any(
|
||||
[
|
||||
self.class_id is None and other.class_id is None,
|
||||
np.array_equal(self.class_id, other.class_id),
|
||||
]
|
||||
),
|
||||
any(
|
||||
[
|
||||
self.confidence is None and other.confidence is None,
|
||||
np.array_equal(self.confidence, other.confidence),
|
||||
]
|
||||
),
|
||||
any(
|
||||
[
|
||||
self.tracker_id is None and other.tracker_id is None,
|
||||
np.array_equal(self.tracker_id, other.tracker_id),
|
||||
]
|
||||
),
|
||||
]
|
||||
)
|
||||
|
||||
Attributes:
|
||||
yolov5_detections (yolov5.models.common.Detections): The output Detections instance from YOLOv5
|
||||
@classmethod
|
||||
def from_yolov5(cls, yolov5_results) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from a [YOLOv5](https://github.com/ultralytics/yolov5) inference result.
|
||||
|
||||
Args:
|
||||
yolov5_results (yolov5.models.common.Detections): The output Detections instance from YOLOv5
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import torch
|
||||
>>> from supervision import Detections
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> model = torch.hub.load('ultralytics/yolov5', 'yolov5s')
|
||||
>>> results = model(frame)
|
||||
>>> detections = Detections.from_yolov5(results)
|
||||
>>> result = model(image)
|
||||
>>> detections = sv.Detections.from_yolov5(result)
|
||||
```
|
||||
"""
|
||||
yolov5_detections_predictions = yolov5_detections.pred[0].cpu().cpu().numpy()
|
||||
yolov5_detections_predictions = yolov5_results.pred[0].cpu().cpu().numpy()
|
||||
return cls(
|
||||
xyxy=yolov5_detections_predictions[:, :4],
|
||||
confidence=yolov5_detections_predictions[:, 4],
|
||||
@@ -93,65 +170,265 @@ class Detections:
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_yolov8(cls, yolov8_results):
|
||||
def from_yolov8(cls, yolov8_results) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from a YOLOv8 output Results
|
||||
Creates a Detections instance from a [YOLOv8](https://github.com/ultralytics/ultralytics) inference result.
|
||||
|
||||
Attributes:
|
||||
Args:
|
||||
yolov8_results (ultralytics.yolo.engine.results.Results): The output Results instance from YOLOv8
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> from ultralytics import YOLO
|
||||
>>> from supervision import Detections
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> model = YOLO('yolov8s.pt')
|
||||
>>> results = model(frame)
|
||||
>>> detections = Detections.from_yolov8(results)
|
||||
>>> result = model(image)[0]
|
||||
>>> detections = sv.Detections.from_yolov8(result)
|
||||
```
|
||||
"""
|
||||
return cls(
|
||||
xyxy=yolov8_results.boxes.xyxy.cpu().numpy(),
|
||||
confidence=yolov8_results.boxes.conf.cpu().numpy(),
|
||||
class_id=yolov8_results.boxes.cls.cpu().numpy().astype(int),
|
||||
mask=extract_yolov8_masks(yolov8_results),
|
||||
)
|
||||
|
||||
def filter(self, mask: np.ndarray, inplace: bool = False) -> Optional[Detections]:
|
||||
@classmethod
|
||||
def from_yolo_nas(cls, yolo_nas_results) -> Detections:
|
||||
"""
|
||||
Filter the detections by applying a mask.
|
||||
Creates a Detections instance from a [YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md) inference result.
|
||||
|
||||
Attributes:
|
||||
mask (np.ndarray): A mask of shape `(n,)` containing a boolean value for each detection indicating if it should be included in the filtered detections
|
||||
inplace (bool): If True, the original data will be modified and self will be returned.
|
||||
Args:
|
||||
yolo_nas_results (super_gradients.training.models.prediction_results.ImageDetectionPrediction): The output Results instance from YOLO-NAS
|
||||
|
||||
Returns:
|
||||
Optional[np.ndarray]: A new instance of Detections with the filtered detections, if inplace is set to `False`. `None` otherwise.
|
||||
Detections: A new Detections object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> from super_gradients.training import models
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> model = models.get('yolo_nas_l', pretrained_weights="coco")
|
||||
>>> result = list(model.predict(image, conf=0.35))[0]
|
||||
>>> detections = sv.Detections.from_yolo_nas(result)
|
||||
```
|
||||
"""
|
||||
if inplace:
|
||||
self.xyxy = self.xyxy[mask]
|
||||
self.confidence = self.confidence[mask]
|
||||
self.class_id = self.class_id[mask]
|
||||
self.tracker_id = (
|
||||
self.tracker_id[mask] if self.tracker_id is not None else None
|
||||
)
|
||||
return self
|
||||
else:
|
||||
return Detections(
|
||||
xyxy=self.xyxy[mask],
|
||||
confidence=self.confidence[mask],
|
||||
class_id=self.class_id[mask],
|
||||
tracker_id=self.tracker_id[mask]
|
||||
if self.tracker_id is not None
|
||||
else None,
|
||||
)
|
||||
return cls(
|
||||
xyxy=yolo_nas_results.prediction.bboxes_xyxy,
|
||||
confidence=yolo_nas_results.prediction.confidence,
|
||||
class_id=yolo_nas_results.prediction.labels.astype(int),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_transformers(cls, transformers_results: dict) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from object detection [transformer](https://github.com/huggingface/transformers) inference result.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
"""
|
||||
return cls(
|
||||
xyxy=transformers_results["boxes"].cpu().numpy(),
|
||||
confidence=transformers_results["scores"].cpu().numpy(),
|
||||
class_id=transformers_results["labels"].cpu().numpy().astype(int),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_detectron2(cls, detectron2_results) -> Detections:
|
||||
"""
|
||||
Create a Detections object from the [Detectron2](https://github.com/facebookresearch/detectron2) inference result.
|
||||
|
||||
Args:
|
||||
detectron2_results: The output of a Detectron2 model containing instances with prediction data.
|
||||
|
||||
Returns:
|
||||
(Detections): A Detections object containing the bounding boxes, class IDs, and confidences of the predictions.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> from detectron2.engine import DefaultPredictor
|
||||
>>> from detectron2.config import get_cfg
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = cv2.imread(SOURCE_IMAGE_PATH)
|
||||
>>> cfg = get_cfg()
|
||||
>>> cfg.merge_from_file("path/to/config.yaml")
|
||||
>>> cfg.MODEL.WEIGHTS = "path/to/model_weights.pth"
|
||||
>>> predictor = DefaultPredictor(cfg)
|
||||
>>> result = predictor(image)
|
||||
|
||||
>>> detections = sv.Detections.from_detectron2(result)
|
||||
```
|
||||
"""
|
||||
return cls(
|
||||
xyxy=detectron2_results["instances"].pred_boxes.tensor.cpu().numpy(),
|
||||
confidence=detectron2_results["instances"].scores.cpu().numpy(),
|
||||
class_id=detectron2_results["instances"]
|
||||
.pred_classes.cpu()
|
||||
.numpy()
|
||||
.astype(int),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_roboflow(cls, roboflow_result: dict, class_list: List[str]) -> Detections:
|
||||
"""
|
||||
Create a Detections object from the [Roboflow](https://roboflow.com/) API inference result.
|
||||
|
||||
Args:
|
||||
roboflow_result (dict): The result from the Roboflow API containing predictions.
|
||||
class_list (List[str]): A list of class names corresponding to the class IDs in the API result.
|
||||
|
||||
Returns:
|
||||
(Detections): A Detections object containing the bounding boxes, class IDs, and confidences of the predictions.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> roboflow_result = {
|
||||
... "predictions": [
|
||||
... {
|
||||
... "x": 0.5,
|
||||
... "y": 0.5,
|
||||
... "width": 0.2,
|
||||
... "height": 0.3,
|
||||
... "class": "person",
|
||||
... "confidence": 0.9
|
||||
... },
|
||||
... # ... more predictions ...
|
||||
... ]
|
||||
... }
|
||||
>>> class_list = ["person", "car", "dog"]
|
||||
|
||||
>>> detections = sv.Detections.from_roboflow(roboflow_result, class_list)
|
||||
```
|
||||
"""
|
||||
xyxy, confidence, class_id, masks = process_roboflow_result(
|
||||
roboflow_result=roboflow_result, class_list=class_list
|
||||
)
|
||||
return Detections(
|
||||
xyxy=xyxy,
|
||||
confidence=confidence,
|
||||
class_id=class_id,
|
||||
mask=masks,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_sam(cls, sam_result: List[dict]) -> Detections:
|
||||
"""
|
||||
Creates a Detections instance from [Segment Anything Model](https://github.com/facebookresearch/segment-anything) inference result.
|
||||
|
||||
Args:
|
||||
sam_result (List[dict]): The output Results instance from SAM
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
>>> from segment_anything import sam_model_registry, SamAutomaticMaskGenerator
|
||||
|
||||
>>> sam = sam_model_registry[MODEL_TYPE](checkpoint=CHECKPOINT_PATH).to(device=DEVICE)
|
||||
>>> mask_generator = SamAutomaticMaskGenerator(sam)
|
||||
>>> sam_result = mask_generator.generate(IMAGE)
|
||||
>>> detections = sv.Detections.from_sam(sam_result=sam_result)
|
||||
```
|
||||
"""
|
||||
sorted_generated_masks = sorted(
|
||||
sam_result, key=lambda x: x["area"], reverse=True
|
||||
)
|
||||
|
||||
xywh = np.array([mask["bbox"] for mask in sorted_generated_masks])
|
||||
mask = np.array([mask["segmentation"] for mask in sorted_generated_masks])
|
||||
|
||||
return Detections(xyxy=xywh_to_xyxy(boxes_xywh=xywh), mask=mask)
|
||||
|
||||
@classmethod
|
||||
def empty(cls) -> Detections:
|
||||
"""
|
||||
Create an empty Detections object with no bounding boxes, confidences, or class IDs.
|
||||
|
||||
Returns:
|
||||
(Detections): An empty Detections object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from supervision import Detections
|
||||
|
||||
>>> empty_detections = Detections.empty()
|
||||
```
|
||||
"""
|
||||
return cls(
|
||||
xyxy=np.empty((0, 4), dtype=np.float32),
|
||||
confidence=np.array([], dtype=np.float32),
|
||||
class_id=np.array([], dtype=int),
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def merge(cls, detections_list: List[Detections]) -> Detections:
|
||||
"""
|
||||
Merge a list of Detections objects into a single Detections object.
|
||||
|
||||
This method takes a list of Detections objects and combines their respective fields (`xyxy`, `mask`,
|
||||
`confidence`, `class_id`, and `tracker_id`) into a single Detections object. If all elements in a field are not
|
||||
`None`, the corresponding field will be stacked. Otherwise, the field will be set to `None`.
|
||||
|
||||
Args:
|
||||
detections_list (List[Detections]): A list of Detections objects to merge.
|
||||
|
||||
Returns:
|
||||
(Detections): A single Detections object containing the merged data from the input list.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> from supervision import Detections
|
||||
|
||||
>>> detections_1 = Detections(...)
|
||||
>>> detections_2 = Detections(...)
|
||||
|
||||
>>> merged_detections = Detections.merge([detections_1, detections_2])
|
||||
```
|
||||
"""
|
||||
if len(detections_list) == 0:
|
||||
return Detections.empty()
|
||||
|
||||
detections_tuples_list = [astuple(detection) for detection in detections_list]
|
||||
xyxy, mask, confidence, class_id, tracker_id = [
|
||||
list(field) for field in zip(*detections_tuples_list)
|
||||
]
|
||||
|
||||
all_not_none = lambda l: all(x is not None for x in l)
|
||||
|
||||
xyxy = np.vstack(xyxy)
|
||||
mask = np.vstack(mask) if all_not_none(mask) else None
|
||||
confidence = np.hstack(confidence) if all_not_none(confidence) else None
|
||||
class_id = np.hstack(class_id) if all_not_none(class_id) else None
|
||||
tracker_id = np.hstack(tracker_id) if all_not_none(tracker_id) else None
|
||||
|
||||
return cls(
|
||||
xyxy=xyxy,
|
||||
mask=mask,
|
||||
confidence=confidence,
|
||||
class_id=class_id,
|
||||
tracker_id=tracker_id,
|
||||
)
|
||||
|
||||
def get_anchor_coordinates(self, anchor: Position) -> np.ndarray:
|
||||
"""
|
||||
Returns the bounding box coordinates for a specific anchor.
|
||||
|
||||
Properties:
|
||||
Args:
|
||||
anchor (Position): Position of bounding box anchor for which to return the coordinates.
|
||||
|
||||
Returns:
|
||||
@@ -171,123 +448,106 @@ class Detections:
|
||||
|
||||
raise ValueError(f"{anchor} is not supported.")
|
||||
|
||||
def __getitem__(self, index: np.ndarray) -> Detections:
|
||||
if isinstance(index, np.ndarray) and index.dtype == np.bool:
|
||||
return Detections(
|
||||
xyxy=self.xyxy[index],
|
||||
confidence=self.confidence[index],
|
||||
class_id=self.class_id[index],
|
||||
tracker_id=self.tracker_id[index]
|
||||
if self.tracker_id is not None
|
||||
else None,
|
||||
)
|
||||
raise TypeError(
|
||||
f"Detections.__getitem__ not supported for index of type {type(index)}."
|
||||
def __getitem__(
|
||||
self, index: Union[int, slice, List[int], np.ndarray]
|
||||
) -> Detections:
|
||||
"""
|
||||
Get a subset of the Detections object.
|
||||
|
||||
Args:
|
||||
index (Union[int, slice, List[int], np.ndarray]): The index or indices of the subset of the Detections
|
||||
|
||||
Returns:
|
||||
(Detections): A subset of the Detections object.
|
||||
|
||||
Example:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> detections = sv.Detections(...)
|
||||
|
||||
>>> first_detection = detections[0]
|
||||
|
||||
>>> first_10_detections = detections[0:10]
|
||||
|
||||
>>> some_detections = detections[[0, 2, 4]]
|
||||
|
||||
>>> class_0_detections = detections[detections.class_id == 0]
|
||||
|
||||
>>> high_confidence_detections = detections[detections.confidence > 0.5]
|
||||
```
|
||||
"""
|
||||
if isinstance(index, int):
|
||||
index = [index]
|
||||
return Detections(
|
||||
xyxy=self.xyxy[index],
|
||||
mask=self.mask[index] if self.mask is not None else None,
|
||||
confidence=self.confidence[index] if self.confidence is not None else None,
|
||||
class_id=self.class_id[index] if self.class_id is not None else None,
|
||||
tracker_id=self.tracker_id[index] if self.tracker_id is not None else None,
|
||||
)
|
||||
|
||||
|
||||
class BoxAnnotator:
|
||||
def __init__(
|
||||
self,
|
||||
color: Union[Color, ColorPalette] = ColorPalette.default(),
|
||||
thickness: int = 2,
|
||||
text_color: Color = Color.black(),
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
):
|
||||
@property
|
||||
def area(self) -> np.ndarray:
|
||||
"""
|
||||
A class for drawing bounding boxes on an image using detections provided.
|
||||
Calculate the area of each detection in the set of object detections. If masks field is defined property
|
||||
returns are of each mask. If only box is given property return area of each box.
|
||||
|
||||
Attributes:
|
||||
color (Union[Color, ColorPalette]): The color to draw the bounding box, can be a single color or a color palette
|
||||
thickness (int): The thickness of the bounding box lines, default is 2
|
||||
text_color (Color): The color of the text on the bounding box, default is white
|
||||
text_scale (float): The scale of the text on the bounding box, default is 0.5
|
||||
text_thickness (int): The thickness of the text on the bounding box, default is 1
|
||||
text_padding (int): The padding around the text on the bounding box, default is 5
|
||||
|
||||
"""
|
||||
self.color: Union[Color, ColorPalette] = color
|
||||
self.thickness: int = thickness
|
||||
self.text_color: Color = text_color
|
||||
self.text_scale: float = text_scale
|
||||
self.text_thickness: int = text_thickness
|
||||
self.text_padding: int = text_padding
|
||||
|
||||
def annotate(
|
||||
self,
|
||||
scene: np.ndarray,
|
||||
detections: Detections,
|
||||
labels: Optional[List[str]] = None,
|
||||
skip_label: bool = False,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Draws bounding boxes on the frame using the detections provided.
|
||||
|
||||
Parameters:
|
||||
scene (np.ndarray): The image on which the bounding boxes will be drawn
|
||||
detections (Detections): The detections for which the bounding boxes will be drawn
|
||||
labels (Optional[List[str]]): An optional list of labels corresponding to each detection. If labels is provided, the confidence score of the detection will be replaced with the label.
|
||||
skip_label (bool): Is set to True, skips bounding box label annotation.
|
||||
Returns:
|
||||
np.ndarray: The image with the bounding boxes drawn on it
|
||||
np.ndarray: An array of floats containing the area of each detection in the format of `(area_1, area_2, ..., area_n)`, where n is the number of detections.
|
||||
"""
|
||||
font = cv2.FONT_HERSHEY_SIMPLEX
|
||||
for i, (xyxy, confidence, class_id, tracker_id) in enumerate(detections):
|
||||
x1, y1, x2, y2 = xyxy.astype(int)
|
||||
color = (
|
||||
self.color.by_idx(class_id)
|
||||
if isinstance(self.color, ColorPalette)
|
||||
else self.color
|
||||
if self.mask is not None:
|
||||
return np.array([np.sum(mask) for mask in self.mask])
|
||||
else:
|
||||
return self.box_area
|
||||
|
||||
@property
|
||||
def box_area(self) -> np.ndarray:
|
||||
"""
|
||||
Calculate the area of each bounding box in the set of object detections.
|
||||
|
||||
Returns:
|
||||
np.ndarray: An array of floats containing the area of each bounding box in the format of `(area_1, area_2, ..., area_n)`, where n is the number of detections.
|
||||
"""
|
||||
return (self.xyxy[:, 3] - self.xyxy[:, 1]) * (self.xyxy[:, 2] - self.xyxy[:, 0])
|
||||
|
||||
def with_nms(
|
||||
self, threshold: float = 0.5, class_agnostic: bool = False
|
||||
) -> Detections:
|
||||
"""
|
||||
Perform non-maximum suppression on the current set of object detections.
|
||||
|
||||
Args:
|
||||
threshold (float, optional): The intersection-over-union threshold to use for non-maximum suppression. Defaults to 0.5.
|
||||
class_agnostic (bool, optional): Whether to perform class-agnostic non-maximum suppression. If True, the class_id of each detection will be ignored. Defaults to False.
|
||||
|
||||
Returns:
|
||||
Detections: A new Detections object containing the subset of detections after non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `confidence` is None and class_agnostic is False. If `class_id` is None and class_agnostic is False.
|
||||
"""
|
||||
if len(self) == 0:
|
||||
return self
|
||||
|
||||
assert (
|
||||
self.confidence is not None
|
||||
), f"Detections confidence must be given for NMS to be executed."
|
||||
|
||||
if class_agnostic:
|
||||
predictions = np.hstack((self.xyxy, self.confidence.reshape(-1, 1)))
|
||||
indices = non_max_suppression(
|
||||
predictions=predictions, iou_threshold=threshold
|
||||
)
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=(x1, y1),
|
||||
pt2=(x2, y2),
|
||||
color=color.as_bgr(),
|
||||
thickness=self.thickness,
|
||||
)
|
||||
if skip_label:
|
||||
continue
|
||||
return self[indices]
|
||||
|
||||
text = (
|
||||
f"{confidence:0.2f}"
|
||||
if (labels is None or len(detections) != len(labels))
|
||||
else labels[i]
|
||||
)
|
||||
assert self.class_id is not None, (
|
||||
f"Detections class_id must be given for NMS to be executed. If you intended to perform class agnostic "
|
||||
f"NMS set class_agnostic=True."
|
||||
)
|
||||
|
||||
text_width, text_height = cv2.getTextSize(
|
||||
text=text,
|
||||
fontFace=font,
|
||||
fontScale=self.text_scale,
|
||||
thickness=self.text_thickness,
|
||||
)[0]
|
||||
|
||||
text_x = x1 + self.text_padding
|
||||
text_y = y1 - self.text_padding
|
||||
|
||||
text_background_x1 = x1
|
||||
text_background_y1 = y1 - 2 * self.text_padding - text_height
|
||||
|
||||
text_background_x2 = x1 + 2 * self.text_padding + text_width
|
||||
text_background_y2 = y1
|
||||
|
||||
cv2.rectangle(
|
||||
img=scene,
|
||||
pt1=(text_background_x1, text_background_y1),
|
||||
pt2=(text_background_x2, text_background_y2),
|
||||
color=color.as_bgr(),
|
||||
thickness=cv2.FILLED,
|
||||
)
|
||||
cv2.putText(
|
||||
img=scene,
|
||||
text=text,
|
||||
org=(text_x, text_y),
|
||||
fontFace=font,
|
||||
fontScale=self.text_scale,
|
||||
color=self.text_color.as_rgb(),
|
||||
thickness=self.text_thickness,
|
||||
lineType=cv2.LINE_AA,
|
||||
)
|
||||
return scene
|
||||
predictions = np.hstack(
|
||||
(self.xyxy, self.confidence.reshape(-1, 1), self.class_id.reshape(-1, 1))
|
||||
)
|
||||
indices = non_max_suppression(predictions=predictions, iou_threshold=threshold)
|
||||
return self[indices]
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
from typing import Dict
|
||||
from typing import Dict, Optional
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -35,7 +35,7 @@ class LineZone:
|
||||
detections (Detections): The detections for which to update the counts.
|
||||
|
||||
"""
|
||||
for xyxy, confidence, class_id, tracker_id in detections:
|
||||
for xyxy, _, confidence, class_id, tracker_id in detections:
|
||||
# handle detections with no tracker_id
|
||||
if tracker_id is None:
|
||||
continue
|
||||
@@ -81,6 +81,8 @@ class LineZoneAnnotator:
|
||||
text_scale: float = 0.5,
|
||||
text_offset: float = 1.5,
|
||||
text_padding: int = 10,
|
||||
custom_in_text: Optional[str] = None,
|
||||
custom_out_text: Optional[str] = None,
|
||||
):
|
||||
"""
|
||||
Initialize the LineCounterAnnotator object with default values.
|
||||
@@ -102,6 +104,8 @@ class LineZoneAnnotator:
|
||||
self.text_scale: float = text_scale
|
||||
self.text_offset: float = text_offset
|
||||
self.text_padding: int = text_padding
|
||||
self.custom_in_text: str = custom_in_text
|
||||
self.custom_out_text: str = custom_out_text
|
||||
|
||||
def annotate(self, frame: np.ndarray, line_counter: LineZone) -> np.ndarray:
|
||||
"""
|
||||
@@ -141,8 +145,16 @@ class LineZoneAnnotator:
|
||||
lineType=cv2.LINE_AA,
|
||||
)
|
||||
|
||||
in_text = f"in: {line_counter.in_count}"
|
||||
out_text = f"out: {line_counter.out_count}"
|
||||
in_text = (
|
||||
f"{self.custom_in_text}: {line_counter.in_count}"
|
||||
if self.custom_in_text is not None
|
||||
else f"in: {line_counter.in_count}"
|
||||
)
|
||||
out_text = (
|
||||
f"{self.custom_out_text}: {line_counter.out_count}"
|
||||
if self.custom_out_text is not None
|
||||
else f"out: {line_counter.out_count}"
|
||||
)
|
||||
|
||||
(in_text_width, in_text_height), _ = cv2.getTextSize(
|
||||
in_text, cv2.FONT_HERSHEY_SIMPLEX, self.text_scale, self.text_thickness
|
||||
@@ -219,3 +231,4 @@ class LineZoneAnnotator:
|
||||
self.text_thickness,
|
||||
cv2.LINE_AA,
|
||||
)
|
||||
return frame
|
||||
|
||||
@@ -1,80 +0,0 @@
|
||||
from typing import Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision import Detections
|
||||
from supervision.detection.utils import generate_2d_mask
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_polygon, draw_text
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
|
||||
|
||||
class PolygonZone:
|
||||
def __init__(
|
||||
self,
|
||||
polygon: np.ndarray,
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
triggering_position: Position = Position.BOTTOM_CENTER,
|
||||
):
|
||||
self.polygon = polygon
|
||||
self.frame_resolution_wh = frame_resolution_wh
|
||||
self.triggering_position = triggering_position
|
||||
self.mask = generate_2d_mask(polygon=polygon, resolution_wh=frame_resolution_wh)
|
||||
self.current_count = 0
|
||||
|
||||
def trigger(self, detections: Detections) -> np.ndarray:
|
||||
anchors = (
|
||||
np.ceil(
|
||||
detections.get_anchor_coordinates(anchor=self.triggering_position)
|
||||
).astype(int)
|
||||
- 1
|
||||
)
|
||||
is_in_zone = self.mask[anchors[:, 1], anchors[:, 0]]
|
||||
self.current_count = np.sum(is_in_zone)
|
||||
return is_in_zone.astype(bool)
|
||||
|
||||
|
||||
class PolygonZoneAnnotator:
|
||||
def __init__(
|
||||
self,
|
||||
zone: PolygonZone,
|
||||
color: Color,
|
||||
thickness: int = 2,
|
||||
text_color: Color = Color.black(),
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
):
|
||||
self.zone = zone
|
||||
self.color = color
|
||||
self.thickness = thickness
|
||||
self.text_color = text_color
|
||||
self.text_scale = text_scale
|
||||
self.text_thickness = text_thickness
|
||||
self.text_padding = text_padding
|
||||
self.font = cv2.FONT_HERSHEY_SIMPLEX
|
||||
self.center = get_polygon_center(polygon=zone.polygon)
|
||||
|
||||
def annotate(self, scene: np.ndarray, label: Optional[str] = None) -> np.ndarray:
|
||||
annotated_frame = draw_polygon(
|
||||
scene=scene,
|
||||
polygon=self.zone.polygon,
|
||||
color=self.color,
|
||||
thickness=self.thickness,
|
||||
)
|
||||
|
||||
annotated_frame = draw_text(
|
||||
scene=annotated_frame,
|
||||
text=str(self.zone.current_count) if label is None else label,
|
||||
text_anchor=self.center,
|
||||
background_color=self.color,
|
||||
text_color=self.text_color,
|
||||
text_scale=self.text_scale,
|
||||
text_thickness=self.text_thickness,
|
||||
text_padding=self.text_padding,
|
||||
text_font=self.font,
|
||||
)
|
||||
|
||||
return annotated_frame
|
||||
@@ -0,0 +1,132 @@
|
||||
from dataclasses import replace
|
||||
from typing import Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from supervision import Detections
|
||||
from supervision.detection.utils import clip_boxes, polygon_to_mask
|
||||
from supervision.draw.color import Color
|
||||
from supervision.draw.utils import draw_polygon, draw_text
|
||||
from supervision.geometry.core import Position
|
||||
from supervision.geometry.utils import get_polygon_center
|
||||
|
||||
|
||||
class PolygonZone:
|
||||
"""
|
||||
A class for defining a polygon-shaped zone within a frame for detecting objects.
|
||||
|
||||
Attributes:
|
||||
polygon (np.ndarray): A polygon represented by a numpy array of shape `(N, 2)`, containing the `x`, `y` coordinates of the points.
|
||||
frame_resolution_wh (Tuple[int, int]): The frame resolution (width, height)
|
||||
triggering_position (Position): The position within the bounding box that triggers the zone (default: Position.BOTTOM_CENTER)
|
||||
current_count (int): The current count of detected objects within the zone
|
||||
mask (np.ndarray): The 2D bool mask for the polygon zone
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
polygon: np.ndarray,
|
||||
frame_resolution_wh: Tuple[int, int],
|
||||
triggering_position: Position = Position.BOTTOM_CENTER,
|
||||
):
|
||||
self.polygon = polygon.astype(int)
|
||||
self.frame_resolution_wh = frame_resolution_wh
|
||||
self.triggering_position = triggering_position
|
||||
self.current_count = 0
|
||||
|
||||
width, height = frame_resolution_wh
|
||||
self.mask = polygon_to_mask(
|
||||
polygon=polygon, resolution_wh=(width + 1, height + 1)
|
||||
)
|
||||
|
||||
def trigger(self, detections: Detections) -> np.ndarray:
|
||||
"""
|
||||
Determines if the detections are within the polygon zone.
|
||||
|
||||
Parameters:
|
||||
detections (Detections): The detections to be checked against the polygon zone
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean numpy array indicating if each detection is within the polygon zone
|
||||
"""
|
||||
|
||||
clipped_xyxy = clip_boxes(
|
||||
boxes_xyxy=detections.xyxy, frame_resolution_wh=self.frame_resolution_wh
|
||||
)
|
||||
clipped_detections = replace(detections, xyxy=clipped_xyxy)
|
||||
clipped_anchors = np.ceil(
|
||||
clipped_detections.get_anchor_coordinates(anchor=self.triggering_position)
|
||||
).astype(int)
|
||||
is_in_zone = self.mask[clipped_anchors[:, 1], clipped_anchors[:, 0]]
|
||||
self.current_count = np.sum(is_in_zone)
|
||||
return is_in_zone.astype(bool)
|
||||
|
||||
|
||||
class PolygonZoneAnnotator:
|
||||
"""
|
||||
A class for annotating a polygon-shaped zone within a frame with a count of detected objects.
|
||||
|
||||
Attributes:
|
||||
zone (PolygonZone): The polygon zone to be annotated
|
||||
color (Color): The color to draw the polygon lines
|
||||
thickness (int): The thickness of the polygon lines, default is 2
|
||||
text_color (Color): The color of the text on the polygon, default is black
|
||||
text_scale (float): The scale of the text on the polygon, default is 0.5
|
||||
text_thickness (int): The thickness of the text on the polygon, default is 1
|
||||
text_padding (int): The padding around the text on the polygon, default is 10
|
||||
font (int): The font type for the text on the polygon, default is cv2.FONT_HERSHEY_SIMPLEX
|
||||
center (Tuple[int, int]): The center of the polygon for text placement
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
zone: PolygonZone,
|
||||
color: Color,
|
||||
thickness: int = 2,
|
||||
text_color: Color = Color.black(),
|
||||
text_scale: float = 0.5,
|
||||
text_thickness: int = 1,
|
||||
text_padding: int = 10,
|
||||
):
|
||||
self.zone = zone
|
||||
self.color = color
|
||||
self.thickness = thickness
|
||||
self.text_color = text_color
|
||||
self.text_scale = text_scale
|
||||
self.text_thickness = text_thickness
|
||||
self.text_padding = text_padding
|
||||
self.font = cv2.FONT_HERSHEY_SIMPLEX
|
||||
self.center = get_polygon_center(polygon=zone.polygon)
|
||||
|
||||
def annotate(self, scene: np.ndarray, label: Optional[str] = None) -> np.ndarray:
|
||||
"""
|
||||
Annotates the polygon zone within a frame with a count of detected objects.
|
||||
|
||||
Parameters:
|
||||
scene (np.ndarray): The image on which the polygon zone will be annotated
|
||||
label (Optional[str]): An optional label for the count of detected objects within the polygon zone (default: None)
|
||||
|
||||
Returns:
|
||||
np.ndarray: The image with the polygon zone and count of detected objects
|
||||
"""
|
||||
annotated_frame = draw_polygon(
|
||||
scene=scene,
|
||||
polygon=self.zone.polygon,
|
||||
color=self.color,
|
||||
thickness=self.thickness,
|
||||
)
|
||||
|
||||
annotated_frame = draw_text(
|
||||
scene=annotated_frame,
|
||||
text=str(self.zone.current_count) if label is None else label,
|
||||
text_anchor=self.center,
|
||||
background_color=self.color,
|
||||
text_color=self.text_color,
|
||||
text_scale=self.text_scale,
|
||||
text_thickness=self.text_thickness,
|
||||
text_padding=self.text_padding,
|
||||
text_font=self.font,
|
||||
)
|
||||
|
||||
return annotated_frame
|
||||
@@ -1,13 +1,15 @@
|
||||
from typing import Tuple
|
||||
from typing import List, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
MIN_POLYGON_POINT_COUNT = 3
|
||||
|
||||
def generate_2d_mask(polygon: np.ndarray, resolution_wh: Tuple[int, int]) -> np.ndarray:
|
||||
"""Generate a 2D mask from a polygon.
|
||||
|
||||
Properties:
|
||||
def polygon_to_mask(polygon: np.ndarray, resolution_wh: Tuple[int, int]) -> np.ndarray:
|
||||
"""Generate a mask from a polygon.
|
||||
|
||||
Args:
|
||||
polygon (np.ndarray): The polygon for which the mask should be generated, given as a list of vertices.
|
||||
resolution_wh (Tuple[int, int]): The width and height of the desired resolution.
|
||||
|
||||
@@ -18,3 +20,321 @@ def generate_2d_mask(polygon: np.ndarray, resolution_wh: Tuple[int, int]) -> np.
|
||||
mask = np.zeros((height, width), dtype=np.uint8)
|
||||
cv2.fillPoly(mask, [polygon], color=1)
|
||||
return mask
|
||||
|
||||
|
||||
def box_iou_batch(boxes_true: np.ndarray, boxes_detection: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Compute Intersection over Union (IoU) of two sets of bounding boxes - `boxes_true` and `boxes_detection`. Both sets
|
||||
of boxes are expected to be in `(x_min, y_min, x_max, y_max)` format.
|
||||
|
||||
Args:
|
||||
boxes_true (np.ndarray): 2D `np.ndarray` representing ground-truth boxes. `shape = (N, 4)` where `N` is number of true objects.
|
||||
boxes_detection (np.ndarray): 2D `np.ndarray` representing detection boxes. `shape = (M, 4)` where `M` is number of detected objects.
|
||||
|
||||
Returns:
|
||||
np.ndarray: Pairwise IoU of boxes from `boxes_true` and `boxes_detection`. `shape = (N, M)` where `N` is number of true objects and `M` is number of detected objects.
|
||||
"""
|
||||
|
||||
def box_area(box):
|
||||
return (box[2] - box[0]) * (box[3] - box[1])
|
||||
|
||||
area_true = box_area(boxes_true.T)
|
||||
area_detection = box_area(boxes_detection.T)
|
||||
|
||||
top_left = np.maximum(boxes_true[:, None, :2], boxes_detection[:, :2])
|
||||
bottom_right = np.minimum(boxes_true[:, None, 2:], boxes_detection[:, 2:])
|
||||
|
||||
area_inter = np.prod(np.clip(bottom_right - top_left, a_min=0, a_max=None), 2)
|
||||
return area_inter / (area_true[:, None] + area_detection - area_inter)
|
||||
|
||||
|
||||
def non_max_suppression(
|
||||
predictions: np.ndarray, iou_threshold: float = 0.5
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Perform Non-Maximum Suppression (NMS) on object detection predictions.
|
||||
|
||||
Args:
|
||||
predictions (np.ndarray): An array of object detection predictions in the format of `(x_min, y_min, x_max, y_max, score)` or `(x_min, y_min, x_max, y_max, score, class)`.
|
||||
iou_threshold (float, optional): The intersection-over-union threshold to use for non-maximum suppression.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A boolean array indicating which predictions to keep after non-maximum suppression.
|
||||
|
||||
Raises:
|
||||
AssertionError: If `iou_threshold` is not within the closed range from `0` to `1`.
|
||||
"""
|
||||
assert 0 <= iou_threshold <= 1, (
|
||||
f"Value of `iou_threshold` must be in the closed range from 0 to 1, "
|
||||
f"{iou_threshold} given."
|
||||
)
|
||||
rows, columns = predictions.shape
|
||||
|
||||
# add column #5 - category filled with zeros for agnostic nms
|
||||
if columns == 5:
|
||||
predictions = np.c_[predictions, np.zeros(rows)]
|
||||
|
||||
# sort predictions column #4 - score
|
||||
sort_index = np.flip(predictions[:, 4].argsort())
|
||||
predictions = predictions[sort_index]
|
||||
|
||||
boxes = predictions[:, :4]
|
||||
categories = predictions[:, 5]
|
||||
ious = box_iou_batch(boxes, boxes)
|
||||
ious = ious - np.eye(rows)
|
||||
|
||||
keep = np.ones(rows, dtype=bool)
|
||||
|
||||
for index, (iou, category) in enumerate(zip(ious, categories)):
|
||||
if not keep[index]:
|
||||
continue
|
||||
|
||||
# drop detections with iou > iou_threshold and same category as current detections
|
||||
condition = (iou > iou_threshold) & (categories == category)
|
||||
keep = keep & ~condition
|
||||
|
||||
return keep[sort_index.argsort()]
|
||||
|
||||
|
||||
def clip_boxes(
|
||||
boxes_xyxy: np.ndarray, frame_resolution_wh: Tuple[int, int]
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Clips bounding boxes coordinates to fit within the frame resolution.
|
||||
|
||||
Args:
|
||||
boxes_xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each row corresponds to a bounding box in
|
||||
the format `(x_min, y_min, x_max, y_max)`.
|
||||
frame_resolution_wh (Tuple[int, int]): A tuple of the form `(width, height)` representing the resolution of the
|
||||
frame.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds to a bounding box with coordinates
|
||||
clipped to fit within the frame resolution.
|
||||
"""
|
||||
result = np.copy(boxes_xyxy)
|
||||
width, height = frame_resolution_wh
|
||||
result[:, [0, 2]] = result[:, [0, 2]].clip(0, width)
|
||||
result[:, [1, 3]] = result[:, [1, 3]].clip(0, height)
|
||||
return result
|
||||
|
||||
|
||||
def xywh_to_xyxy(boxes_xywh: np.ndarray) -> np.ndarray:
|
||||
xyxy = boxes_xywh.copy()
|
||||
xyxy[:, 2] = boxes_xywh[:, 0] + boxes_xywh[:, 2]
|
||||
xyxy[:, 3] = boxes_xywh[:, 1] + boxes_xywh[:, 3]
|
||||
return xyxy
|
||||
|
||||
|
||||
def mask_to_xyxy(masks: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts a 3D `np.array` of 2D bool masks into a 2D `np.array` of bounding boxes.
|
||||
|
||||
Parameters:
|
||||
masks (np.ndarray): A 3D `np.array` of shape `(N, W, H)` containing 2D bool masks
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 2D `np.array` of shape `(N, 4)` containing the bounding boxes `(x_min, y_min, x_max, y_max)` for each mask
|
||||
"""
|
||||
n = masks.shape[0]
|
||||
bboxes = np.zeros((n, 4), dtype=int)
|
||||
|
||||
for i, mask in enumerate(masks):
|
||||
rows, cols = np.where(mask)
|
||||
|
||||
if len(rows) > 0 and len(cols) > 0:
|
||||
x_min, x_max = np.min(cols), np.max(cols)
|
||||
y_min, y_max = np.min(rows), np.max(rows)
|
||||
bboxes[i, :] = [x_min, y_min, x_max, y_max]
|
||||
|
||||
return bboxes
|
||||
|
||||
|
||||
def mask_to_polygons(mask: np.ndarray) -> List[np.ndarray]:
|
||||
"""
|
||||
Converts a binary mask to a list of polygons.
|
||||
|
||||
Parameters:
|
||||
mask (np.ndarray): A binary mask represented as a 2D NumPy array of shape `(H, W)`,
|
||||
where H and W are the height and width of the mask, respectively.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A list of polygons, where each polygon is represented by a NumPy array of shape `(N, 2)`,
|
||||
containing the `x`, `y` coordinates of the points. Polygons with fewer points than `MIN_POLYGON_POINT_COUNT = 3`
|
||||
are excluded from the output.
|
||||
"""
|
||||
|
||||
contours, _ = cv2.findContours(
|
||||
mask.astype(np.uint8), cv2.RETR_TREE, cv2.CHAIN_APPROX_SIMPLE
|
||||
)
|
||||
return [
|
||||
np.squeeze(contour, axis=1)
|
||||
for contour in contours
|
||||
if contour.shape[0] >= MIN_POLYGON_POINT_COUNT
|
||||
]
|
||||
|
||||
|
||||
def filter_polygons_by_area(
|
||||
polygons: List[np.ndarray],
|
||||
min_area: Optional[float] = None,
|
||||
max_area: Optional[float] = None,
|
||||
) -> List[np.ndarray]:
|
||||
"""
|
||||
Filters a list of polygons based on their area.
|
||||
|
||||
Parameters:
|
||||
polygons (List[np.ndarray]): A list of polygons, where each polygon is represented by a NumPy array of shape `(N, 2)`,
|
||||
containing the `x`, `y` coordinates of the points.
|
||||
min_area (Optional[float]): The minimum area threshold. Only polygons with an area greater than or equal to this value
|
||||
will be included in the output. If set to None, no minimum area constraint will be applied.
|
||||
max_area (Optional[float]): The maximum area threshold. Only polygons with an area less than or equal to this value
|
||||
will be included in the output. If set to None, no maximum area constraint will be applied.
|
||||
|
||||
Returns:
|
||||
List[np.ndarray]: A new list of polygons containing only those with areas within the specified thresholds.
|
||||
"""
|
||||
if min_area is None and max_area is None:
|
||||
return polygons
|
||||
ares = [cv2.contourArea(polygon) for polygon in polygons]
|
||||
return [
|
||||
polygon
|
||||
for polygon, area in zip(polygons, ares)
|
||||
if (min_area is None or area >= min_area)
|
||||
and (max_area is None or area <= max_area)
|
||||
]
|
||||
|
||||
|
||||
def polygon_to_xyxy(polygon: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Converts a polygon represented by a NumPy array into a bounding box.
|
||||
|
||||
Parameters:
|
||||
polygon (np.ndarray): A polygon represented by a NumPy array of shape `(N, 2)`,
|
||||
containing the `x`, `y` coordinates of the points.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 1D NumPy array containing the bounding box `(x_min, y_min, x_max, y_max)` of the input polygon.
|
||||
"""
|
||||
x_min, y_min = np.min(polygon, axis=0)
|
||||
x_max, y_max = np.max(polygon, axis=0)
|
||||
return np.array([x_min, y_min, x_max, y_max])
|
||||
|
||||
|
||||
def approximate_polygon(
|
||||
polygon: np.ndarray, percentage: float, epsilon_step: float = 0.05
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Approximates a given polygon by reducing a certain percentage of points.
|
||||
|
||||
This function uses the Ramer-Douglas-Peucker algorithm to simplify the input polygon by reducing the number of points
|
||||
while preserving the general shape.
|
||||
|
||||
Parameters:
|
||||
polygon (np.ndarray): A 2D NumPy array of shape `(N, 2)` containing the `x`, `y` coordinates of the input polygon's points.
|
||||
percentage (float): The percentage of points to be removed from the input polygon, in the range `[0, 1)`.
|
||||
epsilon_step (float): Approximation accuracy step. Epsilon is the maximum distance between the original curve and its approximation.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A new 2D NumPy array of shape `(M, 2)`, where `M <= N * (1 - percentage)`, containing the `x`, `y` coordinates of the
|
||||
approximated polygon's points.
|
||||
"""
|
||||
|
||||
if percentage < 0 or percentage >= 1:
|
||||
raise ValueError("Percentage must be in the range [0, 1).")
|
||||
|
||||
target_points = max(int(len(polygon) * (1 - percentage)), 3)
|
||||
|
||||
if len(polygon) <= target_points:
|
||||
return polygon
|
||||
|
||||
epsilon = 0
|
||||
approximated_points = polygon
|
||||
while True:
|
||||
epsilon += epsilon_step
|
||||
new_approximated_points = cv2.approxPolyDP(polygon, epsilon, closed=True)
|
||||
if len(new_approximated_points) > target_points:
|
||||
approximated_points = new_approximated_points
|
||||
else:
|
||||
break
|
||||
|
||||
return np.squeeze(approximated_points, axis=1)
|
||||
|
||||
|
||||
def extract_yolov8_masks(yolov8_results) -> Optional[np.ndarray]:
|
||||
if not yolov8_results.masks:
|
||||
return None
|
||||
|
||||
orig_shape = yolov8_results.orig_shape
|
||||
inference_shape = tuple(yolov8_results.masks.data.shape[1:])
|
||||
|
||||
gain = 0
|
||||
pad = (0, 0)
|
||||
|
||||
if inference_shape != orig_shape:
|
||||
gain = min(
|
||||
inference_shape[0] / orig_shape[0],
|
||||
inference_shape[1] / orig_shape[1],
|
||||
)
|
||||
pad = (
|
||||
(inference_shape[1] - orig_shape[1] * gain) / 2,
|
||||
(inference_shape[0] - orig_shape[0] * gain) / 2,
|
||||
)
|
||||
|
||||
top, left = int(pad[1]), int(pad[0])
|
||||
bottom, right = int(inference_shape[0] - pad[1]), int(inference_shape[1] - pad[0])
|
||||
|
||||
mask_maps = []
|
||||
masks = yolov8_results.masks.data.cpu().numpy()
|
||||
for i in range(masks.shape[0]):
|
||||
mask = masks[i]
|
||||
mask = mask[top:bottom, left:right]
|
||||
mask = cv2.resize(mask, (orig_shape[1], orig_shape[0]))
|
||||
mask_maps.append(mask)
|
||||
|
||||
return np.asarray(mask_maps, dtype=bool)
|
||||
|
||||
|
||||
def process_roboflow_result(
|
||||
roboflow_result: dict, class_list: List[str]
|
||||
) -> Tuple[np.ndarray, np.ndarray, np.ndarray, Optional[np.ndarray]]:
|
||||
if not roboflow_result["predictions"]:
|
||||
return np.empty((0, 4)), np.empty(0), np.empty(0), None
|
||||
|
||||
xyxy = []
|
||||
confidence = []
|
||||
class_id = []
|
||||
masks = []
|
||||
|
||||
image_width = int(roboflow_result["image"]["width"])
|
||||
image_height = int(roboflow_result["image"]["height"])
|
||||
|
||||
for prediction in roboflow_result["predictions"]:
|
||||
x = prediction["x"]
|
||||
y = prediction["y"]
|
||||
width = prediction["width"]
|
||||
height = prediction["height"]
|
||||
x_min = x - width / 2
|
||||
y_min = y - height / 2
|
||||
x_max = x_min + width
|
||||
y_max = y_min + height
|
||||
|
||||
xyxy.append([x_min, y_min, x_max, y_max])
|
||||
class_id.append(class_list.index(prediction["class"]))
|
||||
confidence.append(prediction["confidence"])
|
||||
|
||||
if "points" not in prediction:
|
||||
continue
|
||||
|
||||
polygon = np.array(
|
||||
[[point["x"], point["y"]] for point in prediction["points"]], dtype=int
|
||||
)
|
||||
|
||||
mask = polygon_to_mask(polygon, resolution_wh=(image_width, image_height))
|
||||
masks.append(mask)
|
||||
|
||||
xyxy = np.array(xyxy)
|
||||
confidence = np.array(confidence)
|
||||
class_id = np.array(class_id).astype(int)
|
||||
masks = np.array(masks, dtype=bool) if len(masks) > 0 else None
|
||||
|
||||
return xyxy, confidence, class_id, masks
|
||||
|
||||
@@ -39,7 +39,7 @@ def draw_rectangle(
|
||||
"""
|
||||
Draws a rectangle on an image.
|
||||
|
||||
Attributes:
|
||||
Parameters:
|
||||
scene (np.ndarray): The scene on which the rectangle will be drawn
|
||||
rect (Rect): The rectangle to be drawn
|
||||
color (Color): The color of the rectangle
|
||||
@@ -60,14 +60,9 @@ def draw_rectangle(
|
||||
|
||||
def draw_filled_rectangle(scene: np.ndarray, rect: Rect, color: Color) -> np.ndarray:
|
||||
"""
|
||||
Draws a filled rectangle on the given scene.
|
||||
Draws a filled rectangle on an image.
|
||||
|
||||
:param scene: np.ndarray : The scene on which to draw the rectangle.
|
||||
:param rect: Rect : The rectangle to be drawn.
|
||||
:param color: Color : The color of the rectangle.
|
||||
:return: np.ndarray : The updated scene with the filled rectangle drawn on it.
|
||||
|
||||
Attributes:
|
||||
Parameters:
|
||||
scene (np.ndarray): The scene on which the rectangle will be drawn
|
||||
rect (Rect): The rectangle to be drawn
|
||||
color (Color): The color of the rectangle
|
||||
@@ -90,7 +85,7 @@ def draw_polygon(
|
||||
) -> np.ndarray:
|
||||
"""Draw a polygon on a scene.
|
||||
|
||||
Attributes:
|
||||
Parameters:
|
||||
scene (np.ndarray): The scene to draw the polygon on.
|
||||
polygon (np.ndarray): The polygon to be drawn, given as a list of vertices.
|
||||
color (Color): The color of the polygon.
|
||||
@@ -117,9 +112,7 @@ def draw_text(
|
||||
background_color: Optional[Color] = None,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Draw text on a scene.
|
||||
|
||||
This function takes in a 2-dimensional numpy ndarray representing an image or scene, and draws text on it using OpenCV's putText function. The text is anchored at a specified Point, and its appearance can be customized using arguments such as color, scale, and font. An optional background color and padding can be specified to draw a rectangle behind the text.
|
||||
Draw text with background on a scene.
|
||||
|
||||
Parameters:
|
||||
scene (np.ndarray): A 2-dimensional numpy ndarray representing an image or scene.
|
||||
|
||||
@@ -1,33 +0,0 @@
|
||||
from typing import Tuple
|
||||
|
||||
import cv2
|
||||
import matplotlib.pyplot as plt
|
||||
import numpy as np
|
||||
|
||||
|
||||
def show_frame_in_notebook(
|
||||
frame: np.ndarray, size: Tuple[int, int] = (10, 10), cmap: str = "gray"
|
||||
):
|
||||
"""
|
||||
Display a frame in Jupyter Notebook using Matplotlib
|
||||
|
||||
Attributes:
|
||||
frame (np.ndarray): The frame to be displayed.
|
||||
size (Tuple[int, int]): The size of the plot. default:(10,10)
|
||||
cmap (str): the colormap to use for single channel images. default:gray
|
||||
|
||||
Examples:
|
||||
```python
|
||||
>>> from supervision.notebook.utils import show_frame_in_notebook
|
||||
|
||||
%matplotlib inline
|
||||
show_frame_in_notebook(frame, (16, 16))
|
||||
```
|
||||
"""
|
||||
if frame.ndim == 2:
|
||||
plt.figure(figsize=size)
|
||||
plt.imshow(frame, cmap=cmap)
|
||||
else:
|
||||
plt.figure(figsize=size)
|
||||
plt.imshow(cv2.cvtColor(frame, cv2.COLOR_BGR2RGB))
|
||||
plt.show()
|
||||
@@ -0,0 +1,140 @@
|
||||
import json
|
||||
from pathlib import Path
|
||||
from typing import List, Optional, Union
|
||||
|
||||
import numpy as np
|
||||
import yaml
|
||||
|
||||
|
||||
class NumpyJsonEncoder(json.JSONEncoder):
|
||||
def default(self, obj):
|
||||
if isinstance(obj, np.integer):
|
||||
return int(obj)
|
||||
if isinstance(obj, np.floating):
|
||||
return float(obj)
|
||||
if isinstance(obj, np.ndarray):
|
||||
return obj.tolist()
|
||||
return super(NumpyJsonEncoder, self).default(obj)
|
||||
|
||||
|
||||
def list_files_with_extensions(
|
||||
directory: Union[str, Path], extensions: Optional[List[str]] = None
|
||||
) -> List[Path]:
|
||||
"""
|
||||
List files in a directory with specified extensions or all files if no extensions are provided.
|
||||
|
||||
Args:
|
||||
directory (Union[str, Path]): The directory path as a string or Path object.
|
||||
extensions (Optional[List[str]]): A list of file extensions to filter. Default is None, which lists all files.
|
||||
|
||||
Returns:
|
||||
(List[Path]): A list of Path objects for the matching files.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> # List all files in the directory
|
||||
>>> files = sv.list_files_with_extensions(directory='my_directory')
|
||||
|
||||
>>> # List only files with '.txt' and '.md' extensions
|
||||
>>> files = sv.list_files_with_extensions(directory='my_directory', extensions=['txt', 'md'])
|
||||
```
|
||||
"""
|
||||
directory = Path(directory)
|
||||
files_with_extensions = []
|
||||
|
||||
if extensions is not None:
|
||||
for ext in extensions:
|
||||
files_with_extensions.extend(directory.glob(f"*.{ext}"))
|
||||
else:
|
||||
files_with_extensions.extend(directory.glob("*"))
|
||||
|
||||
return files_with_extensions
|
||||
|
||||
|
||||
def read_txt_file(file_path: str) -> List[str]:
|
||||
"""
|
||||
Read a text file and return a list of strings without newline characters.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the text file.
|
||||
|
||||
Returns:
|
||||
List[str]: A list of strings representing the lines in the text file.
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
lines = file.readlines()
|
||||
lines = [line.rstrip("\n") for line in lines]
|
||||
|
||||
return lines
|
||||
|
||||
|
||||
def save_text_file(lines: List[str], file_path: str):
|
||||
"""
|
||||
Write a list of strings to a text file, each string on a new line.
|
||||
|
||||
Args:
|
||||
lines (List[str]): The list of strings to be written to the file.
|
||||
file_path (str): The path to the text file.
|
||||
"""
|
||||
with open(file_path, "w") as file:
|
||||
for line in lines:
|
||||
file.write(line + "\n")
|
||||
|
||||
|
||||
def read_json_file(file_path: str) -> dict:
|
||||
"""
|
||||
Read a json file and return a dict.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the json file.
|
||||
|
||||
Returns:
|
||||
dict: A dict of annotations information
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
data = json.load(file)
|
||||
return data
|
||||
|
||||
|
||||
def save_json_file(data: dict, file_path: str, indent: int = 3) -> None:
|
||||
"""
|
||||
Write a dict to a json file.
|
||||
|
||||
Args:
|
||||
indent:
|
||||
data (dict): dict with unique keys and value as pair.
|
||||
file_path (str): The path to the json file.
|
||||
"""
|
||||
with open(file_path, "w") as fp:
|
||||
json.dump(data, fp, cls=NumpyJsonEncoder, indent=indent)
|
||||
|
||||
|
||||
def read_yaml_file(file_path: str) -> dict:
|
||||
"""
|
||||
Read a yaml file and return a dict.
|
||||
|
||||
Args:
|
||||
file_path (str): The path to the yaml file.
|
||||
|
||||
Returns:
|
||||
dict: A dict of content information
|
||||
"""
|
||||
with open(file_path, "r") as file:
|
||||
data = yaml.safe_load(file)
|
||||
return data
|
||||
|
||||
|
||||
def save_yaml_file(data: dict, file_path: str) -> None:
|
||||
"""
|
||||
Save a dict to a json file.
|
||||
|
||||
Args:
|
||||
indent:
|
||||
data (dict): dict with unique keys and value as pair.
|
||||
file_path (str): The path to the json file.
|
||||
"""
|
||||
|
||||
with open(file_path, "w") as outfile:
|
||||
yaml.dump(data, outfile, sort_keys=False, default_flow_style=None)
|
||||
@@ -0,0 +1,93 @@
|
||||
import os
|
||||
import shutil
|
||||
from typing import Optional
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def crop(image: np.ndarray, xyxy: np.ndarray) -> np.ndarray:
|
||||
"""
|
||||
Crops the given image based on the given bounding box.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The image to be cropped, represented as a numpy array.
|
||||
xyxy (np.ndarray): A numpy array containing the bounding box coordinates in the format (x1, y1, x2, y2).
|
||||
|
||||
Returns:
|
||||
(np.ndarray): The cropped image as a numpy array.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> detection = sv.Detections(...)
|
||||
>>> with sv.ImageSink(target_dir_path='target/directory/path') as sink:
|
||||
... for xyxy in detection.xyxy:
|
||||
... cropped_image = sv.crop(image=image, xyxy=xyxy)
|
||||
... sink.save_image(image=image)
|
||||
```
|
||||
"""
|
||||
|
||||
xyxy = np.round(xyxy).astype(int)
|
||||
x1, y1, x2, y2 = xyxy
|
||||
cropped_img = image[y1:y2, x1:x2]
|
||||
return cropped_img
|
||||
|
||||
|
||||
class ImageSink:
|
||||
def __init__(
|
||||
self,
|
||||
target_dir_path: str,
|
||||
overwrite: bool = False,
|
||||
image_name_pattern: str = "image_{:05d}.png",
|
||||
):
|
||||
"""
|
||||
Initialize a context manager for saving images.
|
||||
|
||||
Args:
|
||||
target_dir_path (str): The target directory where images will be saved.
|
||||
overwrite (bool, optional): Whether to overwrite the existing directory. Defaults to False.
|
||||
image_name_pattern (str, optional): The image file name pattern. Defaults to "image_{:05d}.png".
|
||||
|
||||
Examples:
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> with sv.ImageSink(target_dir_path='target/directory/path', overwrite=True) as sink:
|
||||
... for image in sv.get_video_frames_generator(source_path='source_video.mp4', stride=2):
|
||||
... sink.save_image(image=image)
|
||||
```
|
||||
"""
|
||||
self.target_dir_path = target_dir_path
|
||||
self.overwrite = overwrite
|
||||
self.image_name_pattern = image_name_pattern
|
||||
self.image_count = 0
|
||||
|
||||
def __enter__(self):
|
||||
if os.path.exists(self.target_dir_path):
|
||||
if self.overwrite:
|
||||
shutil.rmtree(self.target_dir_path)
|
||||
os.makedirs(self.target_dir_path)
|
||||
else:
|
||||
os.makedirs(self.target_dir_path)
|
||||
|
||||
return self
|
||||
|
||||
def save_image(self, image: np.ndarray, image_name: Optional[str] = None):
|
||||
"""
|
||||
Save a given image in the target directory.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The image to be saved.
|
||||
image_name (str, optional): The name to use for the saved image. If not provided, a name will be generated using the `image_name_pattern`.
|
||||
"""
|
||||
if image_name is None:
|
||||
image_name = self.image_name_pattern.format(self.image_count)
|
||||
|
||||
image_path = os.path.join(self.target_dir_path, image_name)
|
||||
cv2.imwrite(image_path, image)
|
||||
self.image_count += 1
|
||||
|
||||
def __exit__(self, exc_type, exc_value, exc_traceback):
|
||||
pass
|
||||
@@ -0,0 +1,18 @@
|
||||
import functools
|
||||
import warnings
|
||||
|
||||
|
||||
def deprecated(reason: str):
|
||||
def decorator(func):
|
||||
@functools.wraps(func)
|
||||
def wrapper(*args, **kwargs):
|
||||
warnings.warn(
|
||||
f"{func.__name__} is deprecated: {reason}",
|
||||
category=DeprecationWarning,
|
||||
stacklevel=2,
|
||||
)
|
||||
return func(*args, **kwargs)
|
||||
|
||||
return wrapper
|
||||
|
||||
return decorator
|
||||
@@ -0,0 +1,97 @@
|
||||
from typing import List, Optional, Tuple
|
||||
|
||||
import cv2
|
||||
import matplotlib.pyplot as plt
|
||||
import numpy as np
|
||||
|
||||
|
||||
def plot_image(
|
||||
image: np.ndarray, size: Tuple[int, int] = (12, 12), cmap: Optional[str] = "gray"
|
||||
) -> None:
|
||||
"""
|
||||
Plots image using matplotlib.
|
||||
|
||||
Args:
|
||||
image (np.ndarray): The frame to be displayed.
|
||||
size (Tuple[int, int]): The size of the plot.
|
||||
cmap (str): the colormap to use for single channel images.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image = cv2.imread("path/to/image.jpg")
|
||||
|
||||
%matplotlib inline
|
||||
>>> sv.plot_image(image=image, size=(16, 16))
|
||||
```
|
||||
"""
|
||||
plt.figure(figsize=size)
|
||||
|
||||
if image.ndim == 2:
|
||||
plt.imshow(image, cmap=cmap)
|
||||
else:
|
||||
plt.imshow(cv2.cvtColor(image, cv2.COLOR_BGR2RGB))
|
||||
|
||||
plt.axis("off")
|
||||
plt.show()
|
||||
|
||||
|
||||
def plot_images_grid(
|
||||
images: List[np.ndarray],
|
||||
grid_size: Tuple[int, int],
|
||||
titles: Optional[List[str]] = None,
|
||||
size: Tuple[int, int] = (12, 12),
|
||||
cmap: Optional[str] = "gray",
|
||||
) -> None:
|
||||
"""
|
||||
Plots images in a grid using matplotlib.
|
||||
|
||||
Args:
|
||||
images (List[np.ndarray]): A list of images as numpy arrays.
|
||||
grid_size (Tuple[int, int]): A tuple specifying the number of rows and columns for the grid.
|
||||
titles (Optional[List[str]]): A list of titles for each image. Defaults to None.
|
||||
size (Tuple[int, int]): A tuple specifying the width and height of the entire plot in inches.
|
||||
cmap (str): the colormap to use for single channel images.
|
||||
|
||||
Raises:
|
||||
ValueError: If the number of images exceeds the grid size.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
>>> import cv2
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> image1 = cv2.imread("path/to/image1.jpg")
|
||||
>>> image2 = cv2.imread("path/to/image2.jpg")
|
||||
>>> image3 = cv2.imread("path/to/image3.jpg")
|
||||
|
||||
>>> images = [image1, image2, image3]
|
||||
>>> titles = ["Image 1", "Image 2", "Image 3"]
|
||||
|
||||
%matplotlib inline
|
||||
>>> plot_images_grid(images, grid_size=(2, 2), titles=titles, size=(16, 16))
|
||||
```
|
||||
"""
|
||||
nrows, ncols = grid_size
|
||||
|
||||
if len(images) > nrows * ncols:
|
||||
raise ValueError(
|
||||
"The number of images exceeds the grid size. Please increase the grid size or reduce the number of images."
|
||||
)
|
||||
|
||||
fig, axes = plt.subplots(nrows=nrows, ncols=ncols, figsize=size)
|
||||
|
||||
for idx, ax in enumerate(axes.flat):
|
||||
if idx < len(images):
|
||||
if images[idx].ndim == 2:
|
||||
ax.imshow(images[idx], cmap=cmap)
|
||||
else:
|
||||
ax.imshow(cv2.cvtColor(images[idx], cv2.COLOR_BGR2RGB))
|
||||
|
||||
if titles is not None and idx < len(titles):
|
||||
ax.set_title(titles[idx])
|
||||
|
||||
ax.axis("off")
|
||||
plt.show()
|
||||
@@ -20,9 +20,9 @@ class VideoInfo:
|
||||
|
||||
Examples:
|
||||
```python
|
||||
>>> from supervision import VideoInfo
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> video_info = VideoInfo.from_video_path(video_path='video.mp4')
|
||||
>>> video_info = sv.VideoInfo.from_video_path(video_path='video.mp4')
|
||||
|
||||
>>> video_info
|
||||
VideoInfo(width=3840, height=2160, fps=25, total_frames=538)
|
||||
@@ -63,15 +63,15 @@ class VideoSink:
|
||||
target_path (str): The path to the output file where the video will be saved.
|
||||
video_info (VideoInfo): Information about the video resolution, fps, and total frame count.
|
||||
|
||||
Examples:
|
||||
Example:
|
||||
```python
|
||||
>>> from supervision import VideoInfo, VideoSink
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> video_info = VideoInfo.from_video_path(video_path='source_video.mp4')
|
||||
>>> video_info = sv.VideoInfo.from_video_path(video_path='source_video.mp4')
|
||||
|
||||
>>> with VideoSink(target_path='target_video.mp4', video_info=video_info) as s:
|
||||
... frame = ...
|
||||
... s.write_frame(frame=frame)
|
||||
>>> with sv.VideoSink(target_path='target_video.mp4', video_info=video_info) as sink:
|
||||
... for frame in get_video_frames_generator(source_path='source_video.mp4', stride=2):
|
||||
... sink.write_frame(frame=frame)
|
||||
```
|
||||
"""
|
||||
|
||||
@@ -93,35 +93,58 @@ class VideoSink:
|
||||
def write_frame(self, frame: np.ndarray):
|
||||
self.__writer.write(frame)
|
||||
|
||||
def __exit__(self, exc_type, exc_val, exc_tb):
|
||||
def __exit__(self, exc_type, exc_value, exc_traceback):
|
||||
self.__writer.release()
|
||||
|
||||
|
||||
def get_video_frames_generator(source_path: str) -> Generator[np.ndarray, None, None]:
|
||||
def _validate_and_setup_video(source_path: str, start: int, end: Optional[int]):
|
||||
video = cv2.VideoCapture(source_path)
|
||||
if not video.isOpened():
|
||||
raise Exception(f"Could not open video at {source_path}")
|
||||
total_frames = int(video.get(cv2.CAP_PROP_FRAME_COUNT))
|
||||
if end is not None and end > total_frames:
|
||||
raise Exception(f"Requested frames are outbound")
|
||||
start = max(start, 0)
|
||||
end = min(end, total_frames) if end is not None else total_frames
|
||||
video.set(cv2.CAP_PROP_POS_FRAMES, start)
|
||||
return video, start, end
|
||||
|
||||
|
||||
def get_video_frames_generator(
|
||||
source_path: str, stride: int = 1, start: int = 0, end: Optional[int] = None
|
||||
) -> Generator[np.ndarray, None, None]:
|
||||
"""
|
||||
Get a generator that yields the frames of the video.
|
||||
|
||||
Args:
|
||||
source_path (str): The path of the video file.
|
||||
stride (int): Indicates the interval at which frames are returned, skipping stride - 1 frames between each.
|
||||
start (int): Indicates the starting position from which video should generate frames
|
||||
end (Optional[int]): Indicates the ending position at which video should stop generating frames. If None, video will be read to the end.
|
||||
|
||||
Returns:
|
||||
(Generator[np.ndarray, None, None]): A generator that yields the frames of the video.
|
||||
|
||||
Examples:
|
||||
```python
|
||||
>>> from supervision import get_video_frames_generator
|
||||
>>> import supervision as sv
|
||||
|
||||
>>> for frame in get_video_frames_generator(source_path='source_video.mp4'):
|
||||
>>> for frame in sv.get_video_frames_generator(source_path='source_video.mp4'):
|
||||
... ...
|
||||
```
|
||||
"""
|
||||
video = cv2.VideoCapture(source_path)
|
||||
if not video.isOpened():
|
||||
raise Exception(f"Could not open video at {source_path}")
|
||||
success, frame = video.read()
|
||||
while success:
|
||||
yield frame
|
||||
video, start, end = _validate_and_setup_video(source_path, start, end)
|
||||
frame_position = start
|
||||
while True:
|
||||
success, frame = video.read()
|
||||
if not success or frame_position >= end:
|
||||
break
|
||||
yield frame
|
||||
for _ in range(stride - 1):
|
||||
success = video.grab()
|
||||
if not success:
|
||||
break
|
||||
frame_position += stride
|
||||
video.release()
|
||||
|
||||
|
||||
@@ -0,0 +1,63 @@
|
||||
from typing import List, Optional, Tuple
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
|
||||
import pytest
|
||||
import numpy as np
|
||||
|
||||
from supervision.classification.core import Classifications
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"class_id, confidence, k, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.array([0, 1, 2, 3, 4]),
|
||||
np.array([0.1, 0.2, 0.9, 0.4, 0.5]),
|
||||
5,
|
||||
(np.array([2, 4, 3, 1, 0]), np.array([0.9, 0.5, 0.4, 0.2, 0.1])),
|
||||
DoesNotRaise(),
|
||||
), # class_id with 5 numbers and 5 confidences
|
||||
(
|
||||
np.array([5, 1, 2, 3, 4]),
|
||||
np.array([0.1, 0.2, 0.9, 0.4, 0.5]),
|
||||
1,
|
||||
(np.array([2]), np.array([0.9])),
|
||||
DoesNotRaise(),
|
||||
), # class_id with 5 numbers and 5 confidences, retrieve where k = 1
|
||||
(
|
||||
np.array([4, 1, 2, 3, 6, 5]),
|
||||
np.array([0.8, 0.2, 0.9, 0.4, 0.5, 0.1]),
|
||||
2,
|
||||
(np.array([2, 4]), np.array([0.9, 0.8])),
|
||||
DoesNotRaise(),
|
||||
), # class_id with 5 numbers and 5 confidences, retrieve where k = 3
|
||||
(
|
||||
np.array([0, 1, 2, 3, 4]),
|
||||
np.array([]),
|
||||
5,
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # class_id with 5 numbers and 0 confidences
|
||||
(
|
||||
[0, 1, 2, 3, 4],
|
||||
[0.1, 0.2, 0.3, 0.4],
|
||||
5,
|
||||
None,
|
||||
pytest.raises(ValueError),
|
||||
), # class_id with 5 numbers and 4 confidences
|
||||
],
|
||||
)
|
||||
def test_top_k(
|
||||
class_id: np.ndarray,
|
||||
confidence: Optional[np.ndarray],
|
||||
k: int,
|
||||
expected_result: Optional[Tuple[np.ndarray, np.ndarray]],
|
||||
exception: Exception,
|
||||
) -> None:
|
||||
with exception:
|
||||
result = Classifications(
|
||||
class_id=np.array(class_id), confidence=np.array(confidence)
|
||||
).get_top_k(k)
|
||||
|
||||
assert np.array_equal(result[0], expected_result[0])
|
||||
assert np.array_equal(result[1], expected_result[1])
|
||||
@@ -0,0 +1,292 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from typing import List, Tuple
|
||||
|
||||
import pytest
|
||||
|
||||
from supervision import Detections
|
||||
from supervision.dataset.formats.coco import classes_to_coco_categories, coco_categories_to_classes, \
|
||||
group_coco_annotations_by_image_id, coco_annotations_to_detections
|
||||
|
||||
import numpy as np
|
||||
|
||||
|
||||
def mock_cock_coco_annotation(
|
||||
annotation_id: int = 0,
|
||||
image_id: int = 0,
|
||||
category_id: int = 0,
|
||||
bbox: Tuple[float, float, float, float] = (0.0, 0.0, 0.0, 0.0),
|
||||
area: float = 0.0
|
||||
) -> dict:
|
||||
return {
|
||||
"id": annotation_id,
|
||||
"image_id": image_id,
|
||||
"category_id": category_id,
|
||||
"bbox": list(bbox),
|
||||
"area": area,
|
||||
"iscrowd": 0
|
||||
}
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"coco_categories, expected_result, exception",
|
||||
[
|
||||
(
|
||||
[],
|
||||
[],
|
||||
DoesNotRaise()
|
||||
), # empty coco categories
|
||||
(
|
||||
[
|
||||
{
|
||||
"id": 0,
|
||||
"name": "fashion-assistant",
|
||||
"supercategory": "none"
|
||||
}
|
||||
],
|
||||
["fashion-assistant"],
|
||||
DoesNotRaise()
|
||||
), # single coco category with supercategory == "none"
|
||||
(
|
||||
[
|
||||
{
|
||||
"id": 0,
|
||||
"name": "fashion-assistant",
|
||||
"supercategory": "none"
|
||||
},
|
||||
{
|
||||
"id": 1,
|
||||
"name": "baseball cap",
|
||||
"supercategory": "fashion-assistant"
|
||||
}
|
||||
],
|
||||
[
|
||||
"fashion-assistant", "baseball cap"
|
||||
],
|
||||
DoesNotRaise()
|
||||
), # two coco categories; one with supercategory == "none" and one with supercategory != "none"
|
||||
(
|
||||
[
|
||||
{
|
||||
"id": 0,
|
||||
"name": "fashion-assistant",
|
||||
"supercategory": "none"
|
||||
},
|
||||
{
|
||||
"id": 1,
|
||||
"name": "baseball cap",
|
||||
"supercategory": "fashion-assistant"
|
||||
},
|
||||
{
|
||||
"id": 2,
|
||||
"name": "hoodie",
|
||||
"supercategory": "fashion-assistant"
|
||||
}
|
||||
],
|
||||
[
|
||||
"fashion-assistant",
|
||||
"baseball cap",
|
||||
"hoodie"
|
||||
],
|
||||
DoesNotRaise()
|
||||
), # three coco categories; one with supercategory == "none" and two with supercategory != "none"
|
||||
(
|
||||
[
|
||||
{
|
||||
"id": 0,
|
||||
"name": "fashion-assistant",
|
||||
"supercategory": "none"
|
||||
},
|
||||
{
|
||||
"id": 2,
|
||||
"name": "hoodie",
|
||||
"supercategory": "fashion-assistant"
|
||||
},
|
||||
{
|
||||
"id": 1,
|
||||
"name": "baseball cap",
|
||||
"supercategory": "fashion-assistant"
|
||||
}
|
||||
],
|
||||
[
|
||||
"fashion-assistant",
|
||||
"baseball cap",
|
||||
"hoodie"
|
||||
],
|
||||
DoesNotRaise()
|
||||
), # three coco categories; one with supercategory == "none" and two with supercategory != "none" (different order)
|
||||
]
|
||||
)
|
||||
def test_coco_categories_to_classes(
|
||||
coco_categories: List[dict],
|
||||
expected_result: List[str],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = coco_categories_to_classes(coco_categories=coco_categories)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"classes, exception",
|
||||
[
|
||||
(
|
||||
[],
|
||||
DoesNotRaise()
|
||||
), # empty classes
|
||||
(
|
||||
[
|
||||
"baseball cap"
|
||||
],
|
||||
DoesNotRaise()
|
||||
), # single class
|
||||
(
|
||||
[
|
||||
"baseball cap",
|
||||
"hoodie"
|
||||
],
|
||||
DoesNotRaise()
|
||||
), # two classes
|
||||
]
|
||||
)
|
||||
def test_classes_to_coco_categories_and_back_to_classes(classes: List[str], exception: Exception) -> None:
|
||||
with exception:
|
||||
coco_categories = classes_to_coco_categories(classes=classes)
|
||||
result = coco_categories_to_classes(coco_categories=coco_categories)
|
||||
assert result == classes
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"coco_annotations, expected_result, exception",
|
||||
[
|
||||
(
|
||||
[],
|
||||
{},
|
||||
DoesNotRaise()
|
||||
), # empty coco annotations
|
||||
(
|
||||
[
|
||||
mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0)
|
||||
],
|
||||
{
|
||||
0: [
|
||||
mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0)
|
||||
]
|
||||
},
|
||||
DoesNotRaise()
|
||||
), # single coco annotation
|
||||
(
|
||||
[
|
||||
mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0),
|
||||
mock_cock_coco_annotation(annotation_id=1, image_id=1, category_id=0)
|
||||
],
|
||||
{
|
||||
0: [
|
||||
mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0)
|
||||
],
|
||||
1: [
|
||||
mock_cock_coco_annotation(annotation_id=1, image_id=1, category_id=0)
|
||||
]
|
||||
},
|
||||
DoesNotRaise()
|
||||
), # two coco annotations
|
||||
(
|
||||
[
|
||||
mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0),
|
||||
mock_cock_coco_annotation(annotation_id=1, image_id=1, category_id=1),
|
||||
mock_cock_coco_annotation(annotation_id=2, image_id=1, category_id=2),
|
||||
mock_cock_coco_annotation(annotation_id=3, image_id=2, category_id=3),
|
||||
mock_cock_coco_annotation(annotation_id=4, image_id=3, category_id=1),
|
||||
mock_cock_coco_annotation(annotation_id=5, image_id=3, category_id=2),
|
||||
mock_cock_coco_annotation(annotation_id=5, image_id=3, category_id=3),
|
||||
],
|
||||
{
|
||||
0: [
|
||||
mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0),
|
||||
],
|
||||
1: [
|
||||
mock_cock_coco_annotation(annotation_id=1, image_id=1, category_id=1),
|
||||
mock_cock_coco_annotation(annotation_id=2, image_id=1, category_id=2),
|
||||
],
|
||||
2: [
|
||||
mock_cock_coco_annotation(annotation_id=3, image_id=2, category_id=3),
|
||||
],
|
||||
3: [
|
||||
mock_cock_coco_annotation(annotation_id=4, image_id=3, category_id=1),
|
||||
mock_cock_coco_annotation(annotation_id=5, image_id=3, category_id=2),
|
||||
mock_cock_coco_annotation(annotation_id=5, image_id=3, category_id=3),
|
||||
]
|
||||
},
|
||||
DoesNotRaise()
|
||||
), # two coco annotations
|
||||
]
|
||||
)
|
||||
def test_group_coco_annotations_by_image_id(
|
||||
coco_annotations: List[dict],
|
||||
expected_result: dict,
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = group_coco_annotations_by_image_id(coco_annotations=coco_annotations)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"image_annotations, resolution_wh, with_masks, expected_result, exception",
|
||||
[
|
||||
(
|
||||
[],
|
||||
(1000, 1000),
|
||||
False,
|
||||
Detections.empty(),
|
||||
DoesNotRaise()
|
||||
), # empty image annotations
|
||||
(
|
||||
[
|
||||
mock_cock_coco_annotation(category_id=0, bbox=(0, 0, 100, 100), area=100 * 100)
|
||||
],
|
||||
(1000, 1000),
|
||||
False,
|
||||
Detections(
|
||||
xyxy=np.array([
|
||||
[ 0, 0, 100, 100]
|
||||
], dtype=np.float32),
|
||||
class_id=np.array([
|
||||
0
|
||||
], dtype=int)
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # single image annotations
|
||||
(
|
||||
[
|
||||
mock_cock_coco_annotation(category_id=0, bbox=(0, 0, 100, 100), area=100 * 100),
|
||||
mock_cock_coco_annotation(category_id=0, bbox=(100, 100, 100, 100), area=100 * 100),
|
||||
],
|
||||
(1000, 1000),
|
||||
False,
|
||||
Detections(
|
||||
xyxy=np.array([
|
||||
[ 0, 0, 100, 100],
|
||||
[ 100, 100, 200, 200]
|
||||
], dtype=np.float32),
|
||||
class_id=np.array([
|
||||
0, 0
|
||||
], dtype=int)
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # two image annotations
|
||||
]
|
||||
)
|
||||
def test_coco_annotations_to_detections(
|
||||
image_annotations: List[dict],
|
||||
resolution_wh: Tuple[int, int],
|
||||
with_masks: bool,
|
||||
expected_result: Detections,
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = coco_annotations_to_detections(
|
||||
image_annotations=image_annotations,
|
||||
resolution_wh=resolution_wh,
|
||||
with_masks=with_masks
|
||||
)
|
||||
assert result == expected_result
|
||||
@@ -0,0 +1,304 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from typing import List, Tuple, Optional
|
||||
|
||||
import pytest
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.core import Detections
|
||||
from supervision.dataset.formats.yolo import yolo_annotations_to_detections, _with_mask, _image_name_to_annotation_name, \
|
||||
object_to_yolo
|
||||
|
||||
|
||||
def _mock_simple_mask(resolution_wh: Tuple[int, int], box: List[int]) -> np.array:
|
||||
x_min, y_min, x_max, y_max = box
|
||||
mask = np.full(resolution_wh, False, dtype=bool)
|
||||
mask[y_min:y_max, x_min:x_max] = True
|
||||
return mask
|
||||
|
||||
|
||||
# The result of _mock_simple_mask is a little different from the result produced by cv2.
|
||||
def _arrays_almost_equal(arr1: np.ndarray, arr2: np.ndarray, threshold: float = 0.99) -> bool:
|
||||
equal_elements = np.equal(arr1, arr2)
|
||||
proportion_equal = np.mean(equal_elements)
|
||||
return proportion_equal >= threshold
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'lines, expected_result, exception',
|
||||
[
|
||||
(
|
||||
[],
|
||||
False,
|
||||
DoesNotRaise()
|
||||
), # empty yolo annotation file
|
||||
(
|
||||
[
|
||||
'0 0.5 0.5 0.2 0.2'
|
||||
],
|
||||
False,
|
||||
DoesNotRaise()
|
||||
), # yolo annotation file with single line with box
|
||||
(
|
||||
[
|
||||
'0 0.50 0.50 0.20 0.20',
|
||||
'1 0.11 0.47 0.22 0.30'
|
||||
],
|
||||
False,
|
||||
DoesNotRaise()
|
||||
), # yolo annotation file with two lines with box
|
||||
(
|
||||
[
|
||||
'0 0.5 0.5 0.2 0.2'
|
||||
],
|
||||
False,
|
||||
DoesNotRaise()
|
||||
),
|
||||
(
|
||||
[
|
||||
'0 0.4 0.4 0.6 0.4 0.6 0.6 0.4 0.6'
|
||||
],
|
||||
True,
|
||||
DoesNotRaise()
|
||||
), # yolo annotation file with single line with polygon
|
||||
(
|
||||
[
|
||||
'0 0.4 0.4 0.6 0.4 0.6 0.6 0.4 0.6',
|
||||
'1 0.11 0.47 0.22 0.30'
|
||||
],
|
||||
True,
|
||||
DoesNotRaise()
|
||||
), # yolo annotation file with two lines - one box and one polygon
|
||||
]
|
||||
)
|
||||
def test_with_mask(lines: List[str], expected_result: Optional[bool], exception: Exception) -> None:
|
||||
with exception:
|
||||
result = _with_mask(lines=lines)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'lines, resolution_wh, with_masks, expected_result, exception',
|
||||
[
|
||||
(
|
||||
[],
|
||||
(1000, 1000),
|
||||
False,
|
||||
Detections.empty(),
|
||||
DoesNotRaise()
|
||||
), # empty yolo annotation file
|
||||
(
|
||||
[
|
||||
'0 0.5 0.5 0.2 0.2'
|
||||
],
|
||||
(1000, 1000),
|
||||
False,
|
||||
Detections(
|
||||
xyxy=np.array([
|
||||
[400, 400, 600, 600]
|
||||
], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int)
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # yolo annotation file with single line with box
|
||||
(
|
||||
[
|
||||
'0 0.50 0.50 0.20 0.20',
|
||||
'1 0.11 0.47 0.22 0.30'
|
||||
],
|
||||
(1000, 1000),
|
||||
False,
|
||||
Detections(
|
||||
xyxy=np.array([
|
||||
[400, 400, 600, 600],
|
||||
[ 0, 320, 220, 620]
|
||||
], dtype=np.float32),
|
||||
class_id=np.array([0, 1], dtype=int)
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # yolo annotation file with two lines with box
|
||||
(
|
||||
[
|
||||
'0 0.5 0.5 0.2 0.2'
|
||||
],
|
||||
(1000, 1000),
|
||||
True,
|
||||
Detections(
|
||||
xyxy=np.array([
|
||||
[400, 400, 600, 600]
|
||||
], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=np.array([
|
||||
_mock_simple_mask(resolution_wh=(1000, 1000), box=[400, 400, 600, 600])
|
||||
], dtype=bool)
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # yolo annotation file with single line with box in with_masks mode
|
||||
(
|
||||
[
|
||||
'0 0.4 0.4 0.6 0.4 0.6 0.6 0.4 0.6'
|
||||
],
|
||||
(1000, 1000),
|
||||
True,
|
||||
Detections(
|
||||
xyxy=np.array([
|
||||
[400, 400, 600, 600]
|
||||
], dtype=np.float32),
|
||||
class_id=np.array([0], dtype=int),
|
||||
mask=np.array([
|
||||
_mock_simple_mask(resolution_wh=(1000, 1000), box=[400, 400, 600, 600])
|
||||
], dtype=bool)
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # yolo annotation file with single line with polygon
|
||||
(
|
||||
[
|
||||
'0 0.4 0.4 0.6 0.4 0.6 0.6 0.4 0.6',
|
||||
'1 0.11 0.47 0.22 0.30'
|
||||
],
|
||||
(1000, 1000),
|
||||
True,
|
||||
Detections(
|
||||
xyxy=np.array([
|
||||
[400, 400, 600, 600],
|
||||
[ 0, 320, 220, 620]
|
||||
], dtype=np.float32),
|
||||
class_id=np.array([0, 1], dtype=int),
|
||||
mask=np.array([
|
||||
_mock_simple_mask(resolution_wh=(1000, 1000), box=[400, 400, 600, 600]),
|
||||
_mock_simple_mask(resolution_wh=(1000, 1000), box=[ 0, 320, 220, 620])
|
||||
], dtype=bool)
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # yolo annotation file with two lines - one box and one polygon in with_masks mode
|
||||
(
|
||||
[
|
||||
'0 0.4 0.4 0.6 0.4 0.6 0.6 0.4 0.6',
|
||||
'1 0.11 0.47 0.22 0.30'
|
||||
],
|
||||
(1000, 1000),
|
||||
False,
|
||||
Detections(
|
||||
xyxy=np.array([
|
||||
[400, 400, 600, 600],
|
||||
[ 0, 320, 220, 620]
|
||||
], dtype=np.float32),
|
||||
class_id=np.array([0, 1], dtype=int)
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # yolo annotation file with two lines - one box and one polygon
|
||||
]
|
||||
)
|
||||
def test_yolo_annotations_to_detections(
|
||||
lines: List[str],
|
||||
resolution_wh: Tuple[int, int],
|
||||
with_masks: bool,
|
||||
expected_result: Optional[Detections],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = yolo_annotations_to_detections(
|
||||
lines=lines,
|
||||
resolution_wh=resolution_wh,
|
||||
with_masks=with_masks)
|
||||
assert np.array_equal(result.xyxy, expected_result.xyxy)
|
||||
assert np.array_equal(result.class_id, expected_result.class_id)
|
||||
assert (result.mask is None and expected_result.mask is None) or _arrays_almost_equal(result.mask, expected_result.mask)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'image_name, expected_result, exception',
|
||||
[
|
||||
(
|
||||
'image.png',
|
||||
'image.txt',
|
||||
DoesNotRaise()
|
||||
), # simple png image
|
||||
(
|
||||
'image.jpeg',
|
||||
'image.txt',
|
||||
DoesNotRaise()
|
||||
), # simple jpeg image
|
||||
(
|
||||
'image.jpg',
|
||||
'image.txt',
|
||||
DoesNotRaise()
|
||||
), # simple jpg image
|
||||
(
|
||||
'image.000.jpg',
|
||||
'image.000.txt',
|
||||
DoesNotRaise()
|
||||
), # jpg image with multiple dots in name
|
||||
]
|
||||
)
|
||||
def test_image_name_to_annotation_name(
|
||||
image_name: str,
|
||||
expected_result: Optional[str],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = _image_name_to_annotation_name(image_name=image_name)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'xyxy, class_id, image_shape, polygon, expected_result, exception',
|
||||
[
|
||||
(
|
||||
np.array([100, 100, 200, 200], dtype=np.float32),
|
||||
1,
|
||||
(1000, 1000, 3),
|
||||
None,
|
||||
'1 0.15000 0.15000 0.10000 0.10000',
|
||||
DoesNotRaise()
|
||||
), # square bounding box on square image
|
||||
(
|
||||
np.array([100, 100, 200, 200], dtype=np.float32),
|
||||
1,
|
||||
(800, 1000, 3),
|
||||
None,
|
||||
'1 0.15000 0.18750 0.10000 0.12500',
|
||||
DoesNotRaise()
|
||||
), # square bounding box on horizontal image
|
||||
(
|
||||
np.array([100, 100, 200, 200], dtype=np.float32),
|
||||
1,
|
||||
(1000, 800, 3),
|
||||
None,
|
||||
'1 0.18750 0.15000 0.12500 0.10000',
|
||||
DoesNotRaise()
|
||||
), # square bounding box on vertical image
|
||||
(
|
||||
np.array([100, 200, 200, 400], dtype=np.float32),
|
||||
1,
|
||||
(1000, 1000, 3),
|
||||
None,
|
||||
'1 0.15000 0.30000 0.10000 0.20000',
|
||||
DoesNotRaise()
|
||||
), # horizontal bounding box on square image
|
||||
(
|
||||
np.array([200, 100, 400, 200], dtype=np.float32),
|
||||
1,
|
||||
(1000, 1000, 3),
|
||||
None,
|
||||
'1 0.30000 0.15000 0.20000 0.10000',
|
||||
DoesNotRaise()
|
||||
), # vertical bounding box on square image
|
||||
(
|
||||
np.array([100, 100, 200, 200], dtype=np.float32),
|
||||
1,
|
||||
(1000, 1000, 3),
|
||||
np.array([
|
||||
[100, 100],
|
||||
[200, 100],
|
||||
[200, 200],
|
||||
[100, 100]
|
||||
], dtype=np.float32),
|
||||
'1 0.10000 0.10000 0.20000 0.10000 0.20000 0.20000 0.10000 0.10000',
|
||||
DoesNotRaise()
|
||||
), # square mask on square image
|
||||
]
|
||||
)
|
||||
def test_object_to_yolo(xyxy: np.ndarray, class_id: int, image_shape: Tuple[int, int, int], polygon: Optional[np.ndarray], expected_result: Optional[str], exception: Exception) -> None:
|
||||
with exception:
|
||||
result = object_to_yolo(xyxy=xyxy, class_id=class_id, image_shape=image_shape, polygon=polygon)
|
||||
assert result == expected_result
|
||||
@@ -0,0 +1,176 @@
|
||||
from typing import List, Optional
|
||||
|
||||
import pytest
|
||||
|
||||
from supervision import DetectionDataset
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
|
||||
import numpy as np
|
||||
|
||||
from test.utils import mock_detections
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"dataset_list, expected_result, exception",
|
||||
[
|
||||
(
|
||||
[],
|
||||
DetectionDataset(classes=[], images={}, annotations={}),
|
||||
DoesNotRaise()
|
||||
), # empty dataset list
|
||||
(
|
||||
[
|
||||
DetectionDataset(classes=[], images={}, annotations={})
|
||||
],
|
||||
DetectionDataset(classes=[], images={}, annotations={}),
|
||||
DoesNotRaise()
|
||||
), # single empty dataset
|
||||
(
|
||||
[
|
||||
DetectionDataset(classes=['dog', 'person'], images={}, annotations={}),
|
||||
DetectionDataset(classes=['dog', 'person'], images={}, annotations={})
|
||||
],
|
||||
DetectionDataset(classes=['dog', 'person'], images={}, annotations={}),
|
||||
DoesNotRaise()
|
||||
), # two datasets; no images and annotations, the same classes
|
||||
(
|
||||
[
|
||||
DetectionDataset(classes=['dog', 'person'], images={}, annotations={}),
|
||||
DetectionDataset(classes=['cat'], images={}, annotations={})
|
||||
],
|
||||
DetectionDataset(classes=['cat', 'dog', 'person'], images={}, annotations={}),
|
||||
DoesNotRaise()
|
||||
), # two datasets; no images and annotations, different classes
|
||||
(
|
||||
[
|
||||
DetectionDataset(
|
||||
classes=['dog', 'person'],
|
||||
images={
|
||||
'image-1.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
'image-2.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
},
|
||||
annotations={
|
||||
'image-1.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
'image-2.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[1]),
|
||||
}
|
||||
),
|
||||
DetectionDataset(classes=[], images={}, annotations={}),
|
||||
],
|
||||
DetectionDataset(
|
||||
classes=['dog', 'person'],
|
||||
images={
|
||||
'image-1.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
'image-2.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
},
|
||||
annotations={
|
||||
'image-1.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
'image-2.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[1]),
|
||||
}
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # two datasets; images and annotations, the same classes
|
||||
(
|
||||
[
|
||||
DetectionDataset(
|
||||
classes=['dog', 'person'],
|
||||
images={
|
||||
'image-1.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
'image-2.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
},
|
||||
annotations={
|
||||
'image-1.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
'image-2.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[1]),
|
||||
}
|
||||
),
|
||||
DetectionDataset(classes=['cat'], images={}, annotations={}),
|
||||
],
|
||||
DetectionDataset(
|
||||
classes=['cat', 'dog', 'person'],
|
||||
images={
|
||||
'image-1.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
'image-2.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
},
|
||||
annotations={
|
||||
'image-1.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[1]),
|
||||
'image-2.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[2]),
|
||||
}
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # two datasets; images and annotations, different classes
|
||||
(
|
||||
[
|
||||
DetectionDataset(
|
||||
classes=['dog', 'person'],
|
||||
images={
|
||||
'image-1.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
'image-2.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
},
|
||||
annotations={
|
||||
'image-1.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
'image-2.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[1]),
|
||||
}
|
||||
),
|
||||
DetectionDataset(
|
||||
classes=['cat'],
|
||||
images={
|
||||
'image-3.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
},
|
||||
annotations={
|
||||
'image-3.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
}
|
||||
),
|
||||
],
|
||||
DetectionDataset(
|
||||
classes=['cat', 'dog', 'person'],
|
||||
images={
|
||||
'image-1.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
'image-2.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
'image-3.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
},
|
||||
annotations={
|
||||
'image-1.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[1]),
|
||||
'image-2.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[2]),
|
||||
'image-3.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
}
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # two datasets; images and annotations, different classes
|
||||
(
|
||||
[
|
||||
DetectionDataset(
|
||||
classes=['dog', 'person'],
|
||||
images={
|
||||
'image-1.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
'image-2.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
},
|
||||
annotations={
|
||||
'image-1.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
'image-2.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[1]),
|
||||
}
|
||||
),
|
||||
DetectionDataset(
|
||||
classes=['dog', 'person'],
|
||||
images={
|
||||
'image-2.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
'image-3.png': np.zeros((100, 100, 3), dtype=np.uint8),
|
||||
},
|
||||
annotations={
|
||||
'image-2.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
'image-3.png': mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[1]),
|
||||
}
|
||||
),
|
||||
],
|
||||
None,
|
||||
pytest.raises(ValueError)
|
||||
)
|
||||
]
|
||||
)
|
||||
def test_dataset_merge(
|
||||
dataset_list: List[DetectionDataset],
|
||||
expected_result: Optional[DetectionDataset],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = DetectionDataset.merge(dataset_list=dataset_list)
|
||||
print(result.images.keys())
|
||||
assert result == expected_result
|
||||
@@ -0,0 +1,241 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from typing import List, TypeVar, Optional, Tuple, Dict
|
||||
|
||||
import pytest
|
||||
|
||||
from supervision import Detections
|
||||
from supervision.dataset.utils import train_test_split, merge_class_lists, build_class_index_mapping, \
|
||||
map_detections_class_id
|
||||
from test.utils import mock_detections
|
||||
|
||||
T = TypeVar("T")
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'data, train_ratio, random_state, shuffle, expected_result, exception',
|
||||
[
|
||||
(
|
||||
[],
|
||||
0.5,
|
||||
None,
|
||||
False,
|
||||
([], []),
|
||||
DoesNotRaise()
|
||||
), # empty data
|
||||
(
|
||||
[0, 1, 2, 3, 4, 5, 6, 7, 8, 9],
|
||||
0.5,
|
||||
None,
|
||||
False,
|
||||
([0, 1, 2, 3, 4], [5, 6, 7, 8, 9]),
|
||||
DoesNotRaise()
|
||||
), # data with 10 numbers and 50% train split
|
||||
(
|
||||
[0, 1, 2, 3, 4, 5, 6, 7, 8, 9],
|
||||
1.0,
|
||||
None,
|
||||
False,
|
||||
([0, 1, 2, 3, 4, 5, 6, 7, 8, 9], []),
|
||||
DoesNotRaise()
|
||||
), # data with 10 numbers and 100% train split
|
||||
(
|
||||
[0, 1, 2, 3, 4, 5, 6, 7, 8, 9],
|
||||
0.0,
|
||||
None,
|
||||
False,
|
||||
([], [0, 1, 2, 3, 4, 5, 6, 7, 8, 9]),
|
||||
DoesNotRaise()
|
||||
), # data with 10 numbers and 0% train split
|
||||
(
|
||||
['a', 'b', 'c', 'd', 'e', 'f', 'g', 'h', 'i', 'j'],
|
||||
0.5,
|
||||
None,
|
||||
False,
|
||||
(['a', 'b', 'c', 'd', 'e'], ['f', 'g', 'h', 'i', 'j']),
|
||||
DoesNotRaise()
|
||||
), # data with 10 chars and 50% train split
|
||||
(
|
||||
[0, 1, 2, 3, 4, 5, 6, 7, 8, 9],
|
||||
0.5,
|
||||
23,
|
||||
True,
|
||||
([7, 8, 5, 6, 3], [2, 9, 0, 1, 4]),
|
||||
DoesNotRaise()
|
||||
), # data with 10 numbers and 50% train split with 23 random seed
|
||||
(
|
||||
[0, 1, 2, 3, 4, 5, 6, 7, 8, 9],
|
||||
0.5,
|
||||
32,
|
||||
True,
|
||||
([4, 6, 0, 8, 9], [5, 7, 2, 3, 1]),
|
||||
DoesNotRaise()
|
||||
), # data with 10 numbers and 50% train split with 23 random seed
|
||||
]
|
||||
)
|
||||
def test_train_test_split(
|
||||
data: List[T],
|
||||
train_ratio: float,
|
||||
random_state: int,
|
||||
shuffle: bool,
|
||||
expected_result: Optional[Tuple[List[T], List[T]]],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = train_test_split(data=data, train_ratio=train_ratio, random_state=random_state, shuffle=shuffle)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'class_lists, expected_result, exception',
|
||||
[
|
||||
(
|
||||
[],
|
||||
[],
|
||||
DoesNotRaise()
|
||||
), # empty class lists
|
||||
(
|
||||
[
|
||||
['dog', 'person']
|
||||
],
|
||||
['dog', 'person'],
|
||||
DoesNotRaise()
|
||||
), # single class list; already alphabetically sorted
|
||||
(
|
||||
[
|
||||
['person', 'dog']
|
||||
],
|
||||
['dog', 'person'],
|
||||
DoesNotRaise()
|
||||
), # single class list; not alphabetically sorted
|
||||
(
|
||||
[
|
||||
['dog', 'person'],
|
||||
['dog', 'person']
|
||||
],
|
||||
['dog', 'person'],
|
||||
DoesNotRaise()
|
||||
), # two class lists; the same classes; already alphabetically sorted
|
||||
(
|
||||
[
|
||||
['dog', 'person'],
|
||||
['cat']
|
||||
],
|
||||
['cat', 'dog', 'person'],
|
||||
DoesNotRaise()
|
||||
), # two class lists; different classes; already alphabetically sorted
|
||||
]
|
||||
)
|
||||
def test_merge_class_maps(class_lists: List[List[str]], expected_result: List[str], exception: Exception) -> None:
|
||||
with exception:
|
||||
result = merge_class_lists(class_lists=class_lists)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'source_classes, target_classes, expected_result, exception',
|
||||
[
|
||||
(
|
||||
[],
|
||||
[],
|
||||
{},
|
||||
DoesNotRaise()
|
||||
), # empty class lists
|
||||
(
|
||||
[],
|
||||
['dog', 'person'],
|
||||
{},
|
||||
DoesNotRaise()
|
||||
), # empty source class list
|
||||
(
|
||||
['dog', 'person'],
|
||||
[],
|
||||
None,
|
||||
pytest.raises(ValueError)
|
||||
), # empty target class list
|
||||
(
|
||||
['dog', 'person'],
|
||||
['dog', 'person'],
|
||||
{0: 0, 1: 1},
|
||||
DoesNotRaise()
|
||||
), # same class lists
|
||||
(
|
||||
['dog', 'person'],
|
||||
['person', 'dog'],
|
||||
{0: 1, 1: 0},
|
||||
DoesNotRaise()
|
||||
), # same class lists but not alphabetically sorted
|
||||
(
|
||||
['dog', 'person'],
|
||||
['cat', 'dog', 'person'],
|
||||
{0: 1, 1: 2},
|
||||
DoesNotRaise()
|
||||
), # source class list is a subset of target class list
|
||||
(
|
||||
['dog', 'person'],
|
||||
['cat', 'dog'],
|
||||
None,
|
||||
pytest.raises(ValueError)
|
||||
), # source class list is not a subset of target class list
|
||||
]
|
||||
)
|
||||
def test_build_class_index_mapping(
|
||||
source_classes: List[str],
|
||||
target_classes: List[str],
|
||||
expected_result: Optional[Dict[int, int]],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = build_class_index_mapping(source_classes=source_classes, target_classes=target_classes)
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'source_to_target_mapping, detections, expected_result, exception',
|
||||
[
|
||||
(
|
||||
{},
|
||||
mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
None,
|
||||
pytest.raises(ValueError)
|
||||
), # empty mapping
|
||||
(
|
||||
{0: 1},
|
||||
mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[1]),
|
||||
DoesNotRaise()
|
||||
), # single mapping
|
||||
(
|
||||
{0: 1, 1: 2},
|
||||
mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0]),
|
||||
mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[1]),
|
||||
DoesNotRaise()
|
||||
), # multiple mappings
|
||||
(
|
||||
{0: 1, 1: 2},
|
||||
mock_detections(xyxy=[[0, 0, 10, 10], [0, 0, 10, 10]], class_id=[0, 1]),
|
||||
mock_detections(xyxy=[[0, 0, 10, 10], [0, 0, 10, 10]], class_id=[1, 2]),
|
||||
DoesNotRaise()
|
||||
), # multiple mappings
|
||||
(
|
||||
{0: 1, 1: 2},
|
||||
mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[2]),
|
||||
None,
|
||||
pytest.raises(ValueError)
|
||||
), # class_id not in mapping
|
||||
(
|
||||
{0: 1, 1: 2},
|
||||
mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[0], confidence=[0.5]),
|
||||
mock_detections(xyxy=[[0, 0, 10, 10]], class_id=[1], confidence=[0.5]),
|
||||
DoesNotRaise(),
|
||||
), # confidence is not None
|
||||
]
|
||||
)
|
||||
def test_map_detections_class_id(
|
||||
source_to_target_mapping: Dict[int, int],
|
||||
detections: Detections,
|
||||
expected_result: Optional[Detections],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = map_detections_class_id(source_to_target_mapping=source_to_target_mapping, detections=detections)
|
||||
assert result == expected_result
|
||||
@@ -0,0 +1,245 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
|
||||
import pytest
|
||||
|
||||
from supervision import Detections
|
||||
|
||||
from typing import Optional, Union, List
|
||||
|
||||
import numpy as np
|
||||
|
||||
from test.utils import mock_detections
|
||||
|
||||
PREDICTIONS = np.array([
|
||||
[ 2254, 906, 2447, 1353, 0.90538, 0],
|
||||
[ 2049, 1133, 2226, 1371, 0.59002, 56],
|
||||
[ 727, 1224, 838, 1601, 0.51119, 39],
|
||||
[ 808, 1214, 910, 1564, 0.45287, 39],
|
||||
[ 6, 52, 1131, 2133, 0.45057, 72],
|
||||
[ 299, 1225, 512, 1663, 0.45029, 39],
|
||||
[ 529, 874, 645, 945, 0.31101, 39],
|
||||
[ 8, 47, 1935, 2135, 0.28192, 72],
|
||||
[ 2265, 813, 2328, 901, 0.2714, 62]
|
||||
], dtype=np.float32)
|
||||
|
||||
DETECTIONS = Detections(
|
||||
xyxy=PREDICTIONS[:, :4],
|
||||
confidence=PREDICTIONS[:, 4],
|
||||
class_id=PREDICTIONS[:, 5].astype(int)
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'detections, index, expected_result, exception',
|
||||
[
|
||||
(
|
||||
DETECTIONS,
|
||||
DETECTIONS.class_id == 0,
|
||||
mock_detections(
|
||||
xyxy=[[2254, 906, 2447, 1353]],
|
||||
confidence=[0.90538],
|
||||
class_id=[0]
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # take only detections with class_id = 0
|
||||
(
|
||||
DETECTIONS,
|
||||
DETECTIONS.confidence > 0.5,
|
||||
mock_detections(
|
||||
xyxy=[
|
||||
[2254, 906, 2447, 1353],
|
||||
[2049, 1133, 2226, 1371],
|
||||
[727, 1224, 838, 1601]
|
||||
],
|
||||
confidence=[0.90538, 0.59002, 0.51119],
|
||||
class_id=[0, 56, 39]
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # take only detections with confidence > 0.5
|
||||
(
|
||||
DETECTIONS,
|
||||
np.array([True, True, True, True, True, True, True, True, True], dtype=bool),
|
||||
DETECTIONS,
|
||||
DoesNotRaise()
|
||||
), # take all detections
|
||||
(
|
||||
DETECTIONS,
|
||||
np.array([False, False, False, False, False, False, False, False, False], dtype=bool),
|
||||
Detections(
|
||||
xyxy=np.empty((0, 4), dtype=np.float32),
|
||||
confidence=np.array([], dtype=np.float32),
|
||||
class_id=np.array([], dtype=int)
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # take no detections
|
||||
(
|
||||
DETECTIONS,
|
||||
[0, 2],
|
||||
mock_detections(
|
||||
xyxy=[
|
||||
[2254, 906, 2447, 1353],
|
||||
[727, 1224, 838, 1601]
|
||||
],
|
||||
confidence=[0.90538, 0.51119],
|
||||
class_id=[0, 39]
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # take only first and third detection using List[int] index
|
||||
(
|
||||
DETECTIONS,
|
||||
np.array([0, 2]),
|
||||
mock_detections(
|
||||
xyxy=[
|
||||
[2254, 906, 2447, 1353],
|
||||
[727, 1224, 838, 1601]
|
||||
],
|
||||
confidence=[0.90538, 0.51119],
|
||||
class_id=[0, 39]
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # take only first and third detection using np.ndarray index
|
||||
(
|
||||
DETECTIONS,
|
||||
0,
|
||||
mock_detections(
|
||||
xyxy=[[2254, 906, 2447, 1353]],
|
||||
confidence=[0.90538],
|
||||
class_id=[0]
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # take only first detection by index
|
||||
(
|
||||
DETECTIONS,
|
||||
slice(1, 3),
|
||||
mock_detections(
|
||||
xyxy=[
|
||||
[2049, 1133, 2226, 1371],
|
||||
[727, 1224, 838, 1601]
|
||||
],
|
||||
confidence=[0.59002, 0.51119],
|
||||
class_id=[56, 39]
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # take only first detection by index slice (1, 3)
|
||||
(
|
||||
DETECTIONS,
|
||||
10,
|
||||
None,
|
||||
pytest.raises(IndexError)
|
||||
), # index out of range
|
||||
(
|
||||
DETECTIONS,
|
||||
[0, 2, 10],
|
||||
None,
|
||||
pytest.raises(IndexError)
|
||||
), # index out of range
|
||||
(
|
||||
DETECTIONS,
|
||||
np.array([0, 2, 10]),
|
||||
None,
|
||||
pytest.raises(IndexError)
|
||||
),
|
||||
(
|
||||
DETECTIONS,
|
||||
np.array([True, True, True, True, True, True, True, True, True, True, True]),
|
||||
None,
|
||||
pytest.raises(IndexError)
|
||||
)
|
||||
]
|
||||
)
|
||||
def test_getitem(
|
||||
detections: Detections,
|
||||
index: Union[int, slice, List[int], np.ndarray],
|
||||
expected_result: Optional[Detections],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = detections[index]
|
||||
assert result == expected_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'detections_list, expected_result, exception',
|
||||
[
|
||||
(
|
||||
[],
|
||||
Detections.empty(),
|
||||
DoesNotRaise()
|
||||
), # empty detections list
|
||||
(
|
||||
[
|
||||
Detections.empty()
|
||||
],
|
||||
Detections.empty(),
|
||||
DoesNotRaise()
|
||||
), # single empty detections
|
||||
(
|
||||
[
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]])
|
||||
],
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
DoesNotRaise()
|
||||
), # single detection with xyxy field
|
||||
(
|
||||
[
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
Detections.empty()
|
||||
],
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
DoesNotRaise()
|
||||
), # single detection with xyxy field + empty detection
|
||||
(
|
||||
[
|
||||
mock_detections(xyxy=[[10, 10, 20, 20]]),
|
||||
mock_detections(xyxy=[[20, 20, 30, 30]])
|
||||
],
|
||||
mock_detections(
|
||||
xyxy=[
|
||||
[10, 10, 20, 20],
|
||||
[20, 20, 30, 30]
|
||||
]),
|
||||
DoesNotRaise()
|
||||
), # two detections with xyxy field
|
||||
(
|
||||
[
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 20, 20]],
|
||||
class_id=[0]),
|
||||
mock_detections(
|
||||
xyxy=[[20, 20, 30, 30]])
|
||||
],
|
||||
mock_detections(
|
||||
xyxy=[
|
||||
[10, 10, 20, 20],
|
||||
[20, 20, 30, 30]
|
||||
]),
|
||||
DoesNotRaise()
|
||||
), # detection with xyxy, class_id fields + detection with xyxy field
|
||||
(
|
||||
[
|
||||
mock_detections(
|
||||
xyxy=[[10, 10, 20, 20]],
|
||||
class_id=[0]),
|
||||
mock_detections(
|
||||
xyxy=[[20, 20, 30, 30]],
|
||||
class_id=[1]),
|
||||
],
|
||||
mock_detections(
|
||||
xyxy=[
|
||||
[10, 10, 20, 20],
|
||||
[20, 20, 30, 30]
|
||||
],
|
||||
class_id=[0, 1]
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # two detections with xyxy, class_id fields
|
||||
]
|
||||
)
|
||||
def test_merge(
|
||||
detections_list: List[Detections],
|
||||
expected_result: Optional[Detections],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = Detections.merge(detections_list=detections_list)
|
||||
assert result == expected_result
|
||||
@@ -0,0 +1,337 @@
|
||||
from contextlib import ExitStack as DoesNotRaise
|
||||
from typing import Optional, Tuple, List
|
||||
|
||||
import pytest
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision.detection.utils import non_max_suppression, clip_boxes, filter_polygons_by_area, \
|
||||
process_roboflow_result
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"predictions, iou_threshold, expected_result, exception",
|
||||
[
|
||||
(
|
||||
np.empty(shape=(0, 5)),
|
||||
0.5,
|
||||
np.array([]),
|
||||
DoesNotRaise()
|
||||
), # single box with no category
|
||||
(
|
||||
np.array([
|
||||
[10.0, 10.0, 40.0, 40.0, 0.8]
|
||||
]),
|
||||
0.5,
|
||||
np.array([
|
||||
True
|
||||
]),
|
||||
DoesNotRaise()
|
||||
), # single box with no category
|
||||
(
|
||||
np.array([
|
||||
[10.0, 10.0, 40.0, 40.0, 0.8, 0]
|
||||
]),
|
||||
0.5,
|
||||
np.array([
|
||||
True
|
||||
]),
|
||||
DoesNotRaise()
|
||||
), # single box with category
|
||||
(
|
||||
np.array([
|
||||
[10.0, 10.0, 40.0, 40.0, 0.8],
|
||||
[15.0, 15.0, 40.0, 40.0, 0.9],
|
||||
]),
|
||||
0.5,
|
||||
np.array([
|
||||
False,
|
||||
True
|
||||
]),
|
||||
DoesNotRaise()
|
||||
), # two boxes with no category
|
||||
(
|
||||
np.array([
|
||||
[10.0, 10.0, 40.0, 40.0, 0.8, 0],
|
||||
[15.0, 15.0, 40.0, 40.0, 0.9, 1],
|
||||
]),
|
||||
0.5,
|
||||
np.array([
|
||||
True,
|
||||
True
|
||||
]),
|
||||
DoesNotRaise()
|
||||
), # two boxes with different category
|
||||
(
|
||||
np.array([
|
||||
[10.0, 10.0, 40.0, 40.0, 0.8, 0],
|
||||
[15.0, 15.0, 40.0, 40.0, 0.9, 0],
|
||||
]),
|
||||
0.5,
|
||||
np.array([
|
||||
False,
|
||||
True
|
||||
]),
|
||||
DoesNotRaise()
|
||||
), # two boxes with same category
|
||||
(
|
||||
np.array([
|
||||
[0.0, 0.0, 30.0, 40.0, 0.8],
|
||||
[5.0, 5.0, 35.0, 45.0, 0.9],
|
||||
[10.0, 10.0, 40.0, 50.0, 0.85],
|
||||
]),
|
||||
0.5,
|
||||
np.array([
|
||||
False,
|
||||
True,
|
||||
False
|
||||
]),
|
||||
DoesNotRaise()
|
||||
), # three boxes with no category
|
||||
(
|
||||
np.array([
|
||||
[0.0, 0.0, 30.0, 40.0, 0.8, 0],
|
||||
[5.0, 5.0, 35.0, 45.0, 0.9, 1],
|
||||
[10.0, 10.0, 40.0, 50.0, 0.85, 2],
|
||||
]),
|
||||
0.5,
|
||||
np.array([
|
||||
True,
|
||||
True,
|
||||
True
|
||||
]),
|
||||
DoesNotRaise()
|
||||
), # three boxes with same category
|
||||
(
|
||||
np.array([
|
||||
[0.0, 0.0, 30.0, 40.0, 0.8, 0],
|
||||
[5.0, 5.0, 35.0, 45.0, 0.9, 0],
|
||||
[10.0, 10.0, 40.0, 50.0, 0.85, 1],
|
||||
]),
|
||||
0.5,
|
||||
np.array([
|
||||
False,
|
||||
True,
|
||||
True
|
||||
]),
|
||||
DoesNotRaise()
|
||||
), # three boxes with different category
|
||||
]
|
||||
)
|
||||
def test_non_max_suppression(
|
||||
predictions: np.ndarray,
|
||||
iou_threshold: float,
|
||||
expected_result: Optional[np.ndarray],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = non_max_suppression(predictions=predictions, iou_threshold=iou_threshold)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"boxes_xyxy, frame_resolution_wh, expected_result",
|
||||
[
|
||||
(
|
||||
np.empty(shape=(0, 4)),
|
||||
(1280, 720),
|
||||
np.empty(shape=(0, 4)),
|
||||
),
|
||||
(
|
||||
np.array([
|
||||
[1.0, 1.0, 1279.0, 719.0]
|
||||
]),
|
||||
(1280, 720),
|
||||
np.array([
|
||||
[1.0, 1.0, 1279.0, 719.0]
|
||||
]),
|
||||
),
|
||||
(
|
||||
np.array([
|
||||
[-1.0, 1.0, 1279.0, 719.0]
|
||||
]),
|
||||
(1280, 720),
|
||||
np.array([
|
||||
[0.0, 1.0, 1279.0, 719.0]
|
||||
]),
|
||||
),
|
||||
(
|
||||
np.array([
|
||||
[1.0, -1.0, 1279.0, 719.0]
|
||||
]),
|
||||
(1280, 720),
|
||||
np.array([
|
||||
[1.0, 0.0, 1279.0, 719.0]
|
||||
]),
|
||||
),
|
||||
(
|
||||
np.array([
|
||||
[1.0, 1.0, 1281.0, 719.0]
|
||||
]),
|
||||
(1280, 720),
|
||||
np.array([
|
||||
[1.0, 1.0, 1280.0, 719.0]
|
||||
]),
|
||||
),
|
||||
(
|
||||
np.array([
|
||||
[1.0, 1.0, 1279.0, 721.0]
|
||||
]),
|
||||
(1280, 720),
|
||||
np.array([
|
||||
[1.0, 1.0, 1279.0, 720.0]
|
||||
]),
|
||||
),
|
||||
]
|
||||
)
|
||||
def test_clip_boxes(boxes_xyxy: np.ndarray, frame_resolution_wh: Tuple[int, int], expected_result: np.ndarray) -> None:
|
||||
result = clip_boxes(boxes_xyxy=boxes_xyxy, frame_resolution_wh=frame_resolution_wh)
|
||||
assert np.array_equal(result, expected_result)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"polygons, min_area, max_area, expected_result, exception",
|
||||
[
|
||||
(
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
None,
|
||||
None,
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
DoesNotRaise()
|
||||
), # single polygon without area constraints
|
||||
(
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
50,
|
||||
None,
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
DoesNotRaise()
|
||||
), # single polygon with min_area constraint
|
||||
(
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
None,
|
||||
50,
|
||||
[],
|
||||
DoesNotRaise()
|
||||
), # single polygon with max_area constraint
|
||||
(
|
||||
[
|
||||
np.array([[0, 0], [0, 10], [10, 10], [10, 0]]),
|
||||
np.array([[0, 0], [0, 20], [20, 20], [20, 0]])
|
||||
],
|
||||
200,
|
||||
None,
|
||||
[np.array([[0, 0], [0, 20], [20, 20], [20, 0]])],
|
||||
DoesNotRaise()
|
||||
), # two polygons with min_area constraint
|
||||
(
|
||||
[
|
||||
np.array([[0, 0], [0, 10], [10, 10], [10, 0]]),
|
||||
np.array([[0, 0], [0, 20], [20, 20], [20, 0]])
|
||||
],
|
||||
None,
|
||||
200,
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
DoesNotRaise()
|
||||
), # two polygons with max_area constraint
|
||||
(
|
||||
[
|
||||
np.array([[0, 0], [0, 10], [10, 10], [10, 0]]),
|
||||
np.array([[0, 0], [0, 20], [20, 20], [20, 0]])
|
||||
],
|
||||
200,
|
||||
200,
|
||||
[],
|
||||
DoesNotRaise()
|
||||
), # two polygons with both area constraints
|
||||
(
|
||||
[
|
||||
np.array([[0, 0], [0, 10], [10, 10], [10, 0]]),
|
||||
np.array([[0, 0], [0, 20], [20, 20], [20, 0]])
|
||||
],
|
||||
100,
|
||||
100,
|
||||
[np.array([[0, 0], [0, 10], [10, 10], [10, 0]])],
|
||||
DoesNotRaise()
|
||||
), # two polygons with min_area and max_area equal to the area of the first polygon
|
||||
(
|
||||
[
|
||||
np.array([[0, 0], [0, 10], [10, 10], [10, 0]]),
|
||||
np.array([[0, 0], [0, 20], [20, 20], [20, 0]])
|
||||
],
|
||||
400,
|
||||
400,
|
||||
[np.array([[0, 0], [0, 20], [20, 20], [20, 0]])],
|
||||
DoesNotRaise()
|
||||
), # two polygons with min_area and max_area equal to the area of the second polygon
|
||||
]
|
||||
)
|
||||
def test_filter_polygons_by_area(
|
||||
polygons: List[np.ndarray],
|
||||
min_area: Optional[float],
|
||||
max_area: Optional[float],
|
||||
expected_result: List[np.ndarray],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = filter_polygons_by_area(polygons=polygons, min_area=min_area, max_area=max_area)
|
||||
assert len(result) == len(expected_result)
|
||||
for result_polygon, expected_result_polygon in zip(result, expected_result):
|
||||
assert np.array_equal(result_polygon, expected_result_polygon)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"roboflow_result, class_list, expected_result, exception",
|
||||
[
|
||||
(
|
||||
{
|
||||
"predictions": [],
|
||||
"image": {"width": 1000, "height": 1000}
|
||||
},
|
||||
["person", "car", "truck"],
|
||||
(
|
||||
np.empty((0, 4)),
|
||||
np.empty(0),
|
||||
np.empty(0),
|
||||
None
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # empty result
|
||||
(
|
||||
{
|
||||
"predictions": [
|
||||
{
|
||||
"x": 200.0,
|
||||
"y": 300.0,
|
||||
"width": 50.0,
|
||||
"height": 50.0,
|
||||
"confidence": 0.9,
|
||||
"class": "person"
|
||||
}
|
||||
],
|
||||
"image": {"width": 1000, "height": 1000}
|
||||
},
|
||||
["person", "car", "truck"],
|
||||
(
|
||||
np.array([
|
||||
[175.0, 275.0, 225.0, 325.0]
|
||||
]),
|
||||
np.array([0.9]),
|
||||
np.array([0]),
|
||||
None
|
||||
),
|
||||
DoesNotRaise()
|
||||
), # single bounding box
|
||||
]
|
||||
)
|
||||
def test_process_roboflow_result(
|
||||
roboflow_result: dict,
|
||||
class_list: List[str],
|
||||
expected_result: Tuple[np.ndarray, np.ndarray, np.ndarray, Optional[np.ndarray]],
|
||||
exception: Exception
|
||||
) -> None:
|
||||
with exception:
|
||||
result = process_roboflow_result(roboflow_result=roboflow_result, class_list=class_list)
|
||||
assert np.array_equal(result[0], expected_result[0])
|
||||
assert np.array_equal(result[1], expected_result[1])
|
||||
assert np.array_equal(result[2], expected_result[2])
|
||||
assert (result[3] is None and expected_result[3] is None) or (np.array_equal(result[3], expected_result[3]))
|
||||
@@ -0,0 +1,19 @@
|
||||
from typing import List
|
||||
|
||||
import numpy as np
|
||||
|
||||
from supervision import Detections
|
||||
|
||||
|
||||
def mock_detections(
|
||||
xyxy: List[List[float]],
|
||||
confidence: List[float] = None,
|
||||
class_id: List[int] = None,
|
||||
tracker_id: List[int] = None
|
||||
) -> Detections:
|
||||
return Detections(
|
||||
xyxy=np.array(xyxy, dtype=np.float32),
|
||||
confidence=confidence if confidence is None else np.array(confidence, dtype=np.float32),
|
||||
class_id=class_id if class_id is None else np.array(class_id, dtype=int),
|
||||
tracker_id=tracker_id if tracker_id is None else np.array(tracker_id, dtype=int)
|
||||
)
|
||||
Reference in New Issue
Block a user