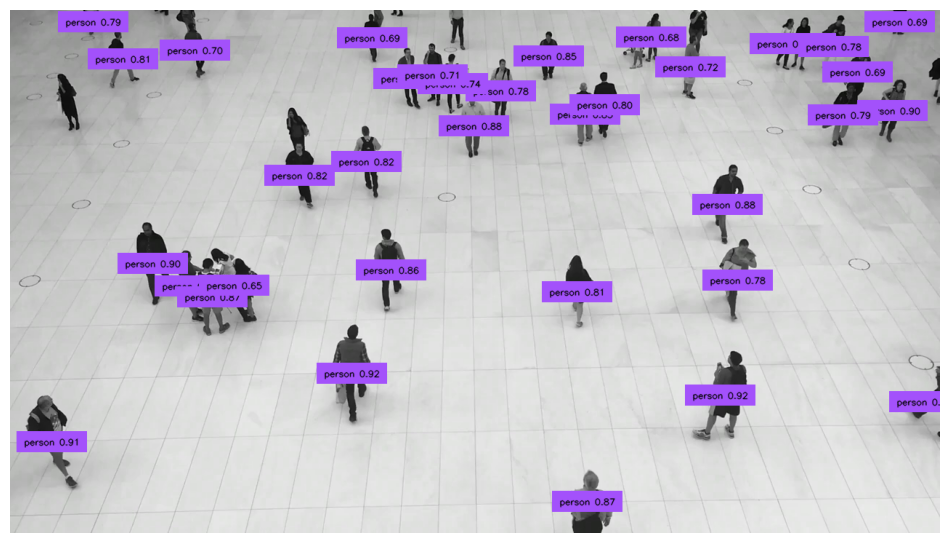
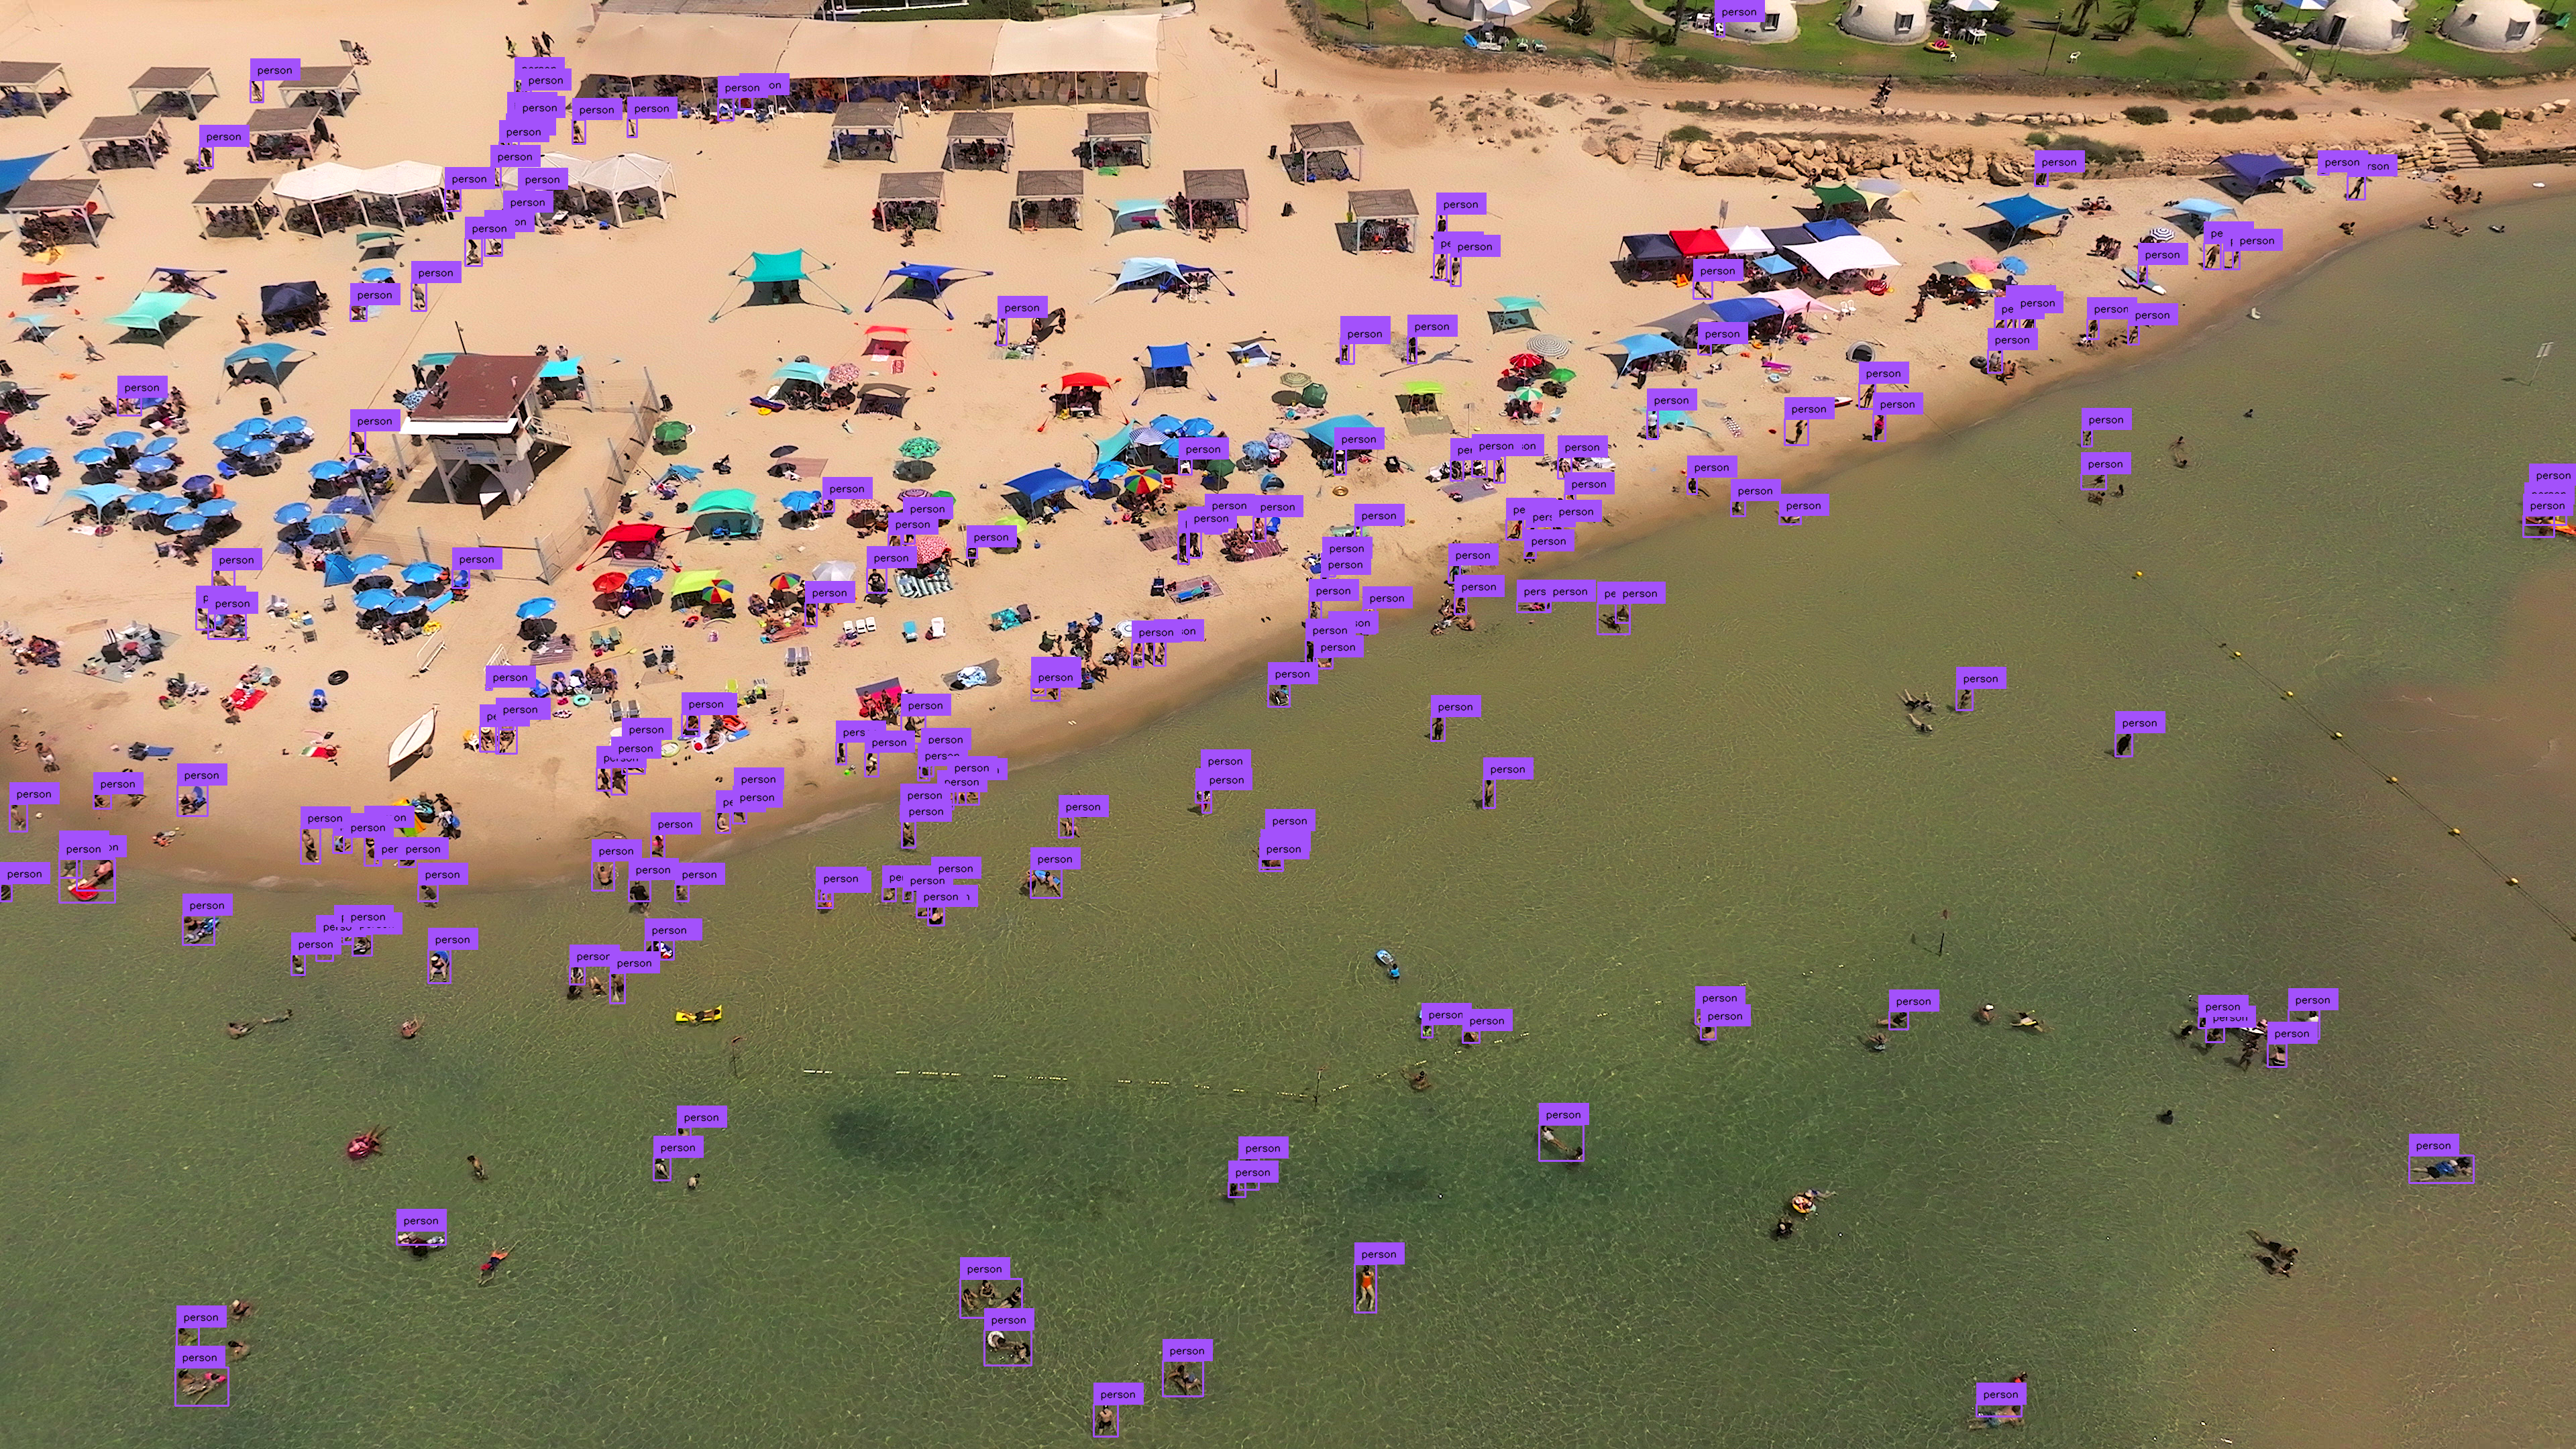
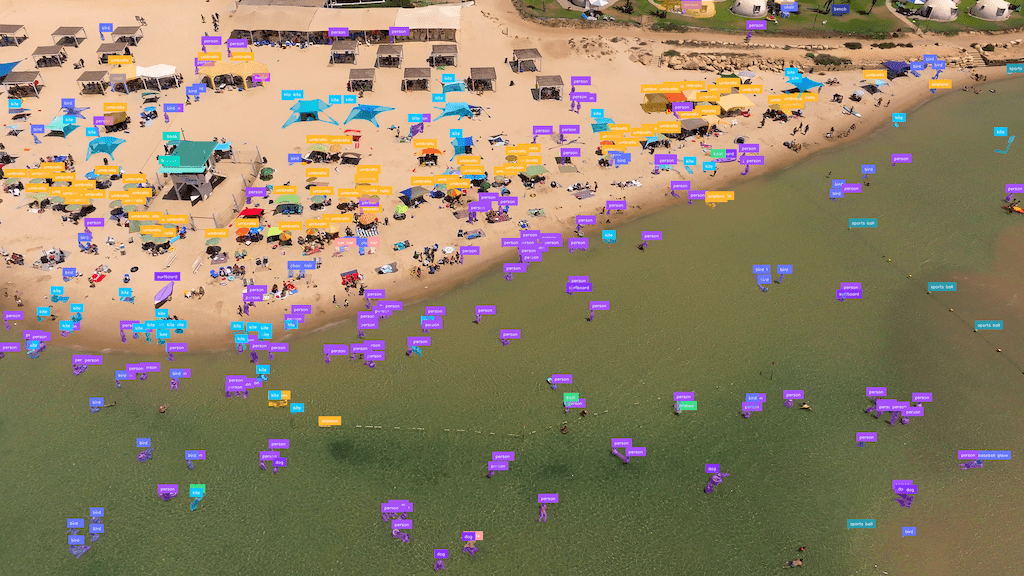
diff --git a/.pre-commit-config.yaml b/.pre-commit-config.yaml index ef3620b1..2acdf342 100644 --- a/.pre-commit-config.yaml +++ b/.pre-commit-config.yaml @@ -45,7 +45,7 @@ repos: - repo: https://github.com/astral-sh/ruff-pre-commit - rev: v0.4.1 + rev: v0.4.7 hooks: - id: ruff args: [--fix, --exit-non-zero-on-fix] diff --git a/docs/changelog.md b/docs/changelog.md index 47d160aa..024edd1a 100644 --- a/docs/changelog.md +++ b/docs/changelog.md @@ -1,3 +1,83 @@ +### 0.21.0 Jun 5, 2024 + +- Added [#500](https://github.com/roboflow/supervision/pull/500): [`sv.Detections.with_nmm`](https://supervision.roboflow.com/develop/detection/core/#supervision.detection.core.Detections.with_nmm) to perform non-maximum merging on the current set of object detections. + +- Added [#1221](https://github.com/roboflow/supervision/pull/1221): [`sv.Detections.from_lmm`](https://supervision.roboflow.com/develop/detection/core/#supervision.detection.core.Detections.from_lmm) allowing to parse Large Multimodal Model (LMM) text result into [`sv.Detections`](https://supervision.roboflow.com/develop/detection/core/) object. For now `from_lmm` supports only [PaliGemma](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-finetune-paligemma-on-detection-dataset.ipynb) result parsing. + +```python +import supervision as sv + +paligemma_result = " cat" +detections = sv.Detections.from_lmm( + sv.LMM.PALIGEMMA, + paligemma_result, + resolution_wh=(1000, 1000), + classes=['cat', 'dog'] +) +detections.xyxy +# array([[250., 250., 750., 750.]]) + +detections.class_id +# array([0]) +``` + +- Added [#1236](https://github.com/roboflow/supervision/pull/1236): [`sv.VertexLabelAnnotator`](https://supervision.roboflow.com/develop/keypoint/annotators/#supervision.keypoint.annotators.EdgeAnnotator.annotate) allowing to annotate every vertex of a keypoint skeleton with custom text and color. + +```python +import supervision as sv + +image = ... +key_points = sv.KeyPoints(...) + +edge_annotator = sv.EdgeAnnotator( + color=sv.Color.GREEN, + thickness=5 +) +annotated_frame = edge_annotator.annotate( + scene=image.copy(), + key_points=key_points +) +``` + +- Added [#1147](https://github.com/roboflow/supervision/pull/1147): [`sv.KeyPoints.from_inference`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints.from_inference) allowing to create [`sv.KeyPoints`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints) from [Inference](https://github.com/roboflow/inference) result. + +- Added [#1138](https://github.com/roboflow/supervision/pull/1138): [`sv.KeyPoints.from_yolo_nas`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints.from_yolo_nas) allowing to create [`sv.KeyPoints`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints) from [YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md) result. + +- Added [#1163](https://github.com/roboflow/supervision/pull/1163): [`sv.mask_to_rle`](https://supervision.roboflow.com/develop/datasets/utils/#supervision.dataset.utils.rle_to_mask) and [`sv.rle_to_mask`](https://supervision.roboflow.com/develop/datasets/utils/#supervision.dataset.utils.rle_to_mask) allowing for easy conversion between mask and rle formats. + +- Changed [#1236](https://github.com/roboflow/supervision/pull/1236): [`sv.InferenceSlicer`](https://supervision.roboflow.com/develop/detection/tools/inference_slicer/) allowing to select overlap filtering strategy (`NONE`, `NON_MAX_SUPPRESSION` and `NON_MAX_MERGE`). + +- Changed [#1178](https://github.com/roboflow/supervision/pull/1178): [`sv.InferenceSlicer`](https://supervision.roboflow.com/develop/detection/tools/inference_slicer/) adding instance segmentation model support. + +```python +import cv2 +import numpy as np +import supervision as sv +from inference import get_model + +model = get_model(model_id="yolov8x-seg-640") +image = cv2.imread() + +def callback(image_slice: np.ndarray) -> sv.Detections: + results = model.infer(image_slice)[0] + return sv.Detections.from_inference(results) + +slicer = sv.InferenceSlicer(callback = callback) +detections = slicer(image) + +mask_annotator = sv.MaskAnnotator() +label_annotator = sv.LabelAnnotator() + +annotated_image = mask_annotator.annotate( + scene=image, detections=detections) +annotated_image = label_annotator.annotate( + scene=annotated_image, detections=detections) +``` + +- Changed [#1228](https://github.com/roboflow/supervision/pull/1228): [`sv.LineZone`](https://supervision.roboflow.com/develop/detection/tools/line_zone/) making it 10-20 times faster, depending on the use case. + +- Changed [#1163](https://github.com/roboflow/supervision/pull/1163): [`sv.DetectionDataset.from_coco`](https://supervision.roboflow.com/develop/datasets/core/#supervision.dataset.core.DetectionDataset.from_coco) and [`sv.DetectionDataset.as_coco`](https://supervision.roboflow.com/develop/datasets/core/#supervision.dataset.core.DetectionDataset.as_coco) adding support for run-length encoding (RLE) mask format. + ### 0.20.0 April 24, 2024 - Added [#1128](https://github.com/roboflow/supervision/pull/1128): [`sv.KeyPoints`](/0.20.0/keypoint/core/#supervision.keypoint.core.KeyPoints) to provide initial support for pose estimation and broader keypoint detection models. diff --git a/docs/cookbooks.md b/docs/cookbooks.md index dd963edb..6f87958f 100644 --- a/docs/cookbooks.md +++ b/docs/cookbooks.md @@ -1,7 +1,6 @@ --- template: cookbooks.html comments: true -status: new hide: - navigation - toc diff --git a/docs/datasets.md b/docs/datasets/core.md similarity index 97% rename from docs/datasets.md rename to docs/datasets/core.md index 73931515..03d0c196 100644 --- a/docs/datasets.md +++ b/docs/datasets/core.md @@ -1,5 +1,6 @@ --- comments: true +status: new --- # Datasets diff --git a/docs/datasets/utils.md b/docs/datasets/utils.md new file mode 100644 index 00000000..6be56303 --- /dev/null +++ b/docs/datasets/utils.md @@ -0,0 +1,18 @@ +--- +comments: true +status: new +--- + +# Datasets Utils + + + +:::supervision.dataset.utils.rle_to_mask + + + +:::supervision.dataset.utils.mask_to_rle diff --git a/docs/detection/annotators.md b/docs/detection/annotators.md index e1f4b115..4d912cae 100644 --- a/docs/detection/annotators.md +++ b/docs/detection/annotators.md @@ -1,6 +1,5 @@ --- comments: true -status: new --- # Annotators @@ -285,6 +284,37 @@ status: new +=== "RichLabel" + + ```python + import supervision as sv + + image = ... + detections = sv.Detections(...) + + labels = [ + f"{class_name} {confidence:.2f}" + for class_name, confidence + in zip(detections['class_name'], detections.confidence) + ] + + rich_label_annotator = sv.RichLabelAnnotator( + font_path=".../font.ttf", + text_position=sv.Position.CENTER + ) + annotated_frame = label_annotator.annotate( + scene=image.copy(), + detections=detections, + labels=labels + ) + ``` + +
+ + ![label-annotator-example](https://media.roboflow.com/supervision-annotator-examples/label-annotator-example-purple.png){ align=center width="800" } + +
+ === "Crop" ```python @@ -492,6 +522,12 @@ status: new :::supervision.annotators.core.LabelAnnotator + + +:::supervision.annotators.core.RichLabelAnnotator + diff --git a/docs/detection/double_detection_filter.md b/docs/detection/double_detection_filter.md new file mode 100644 index 00000000..1631852f --- /dev/null +++ b/docs/detection/double_detection_filter.md @@ -0,0 +1,30 @@ +--- +comments: true +status: new +--- + +# Double Detection Filter + + + +:::supervision.detection.overlap_filter.OverlapFilter + + + +:::supervision.detection.overlap_filter.box_non_max_suppression + + + +:::supervision.detection.overlap_filter.mask_non_max_suppression + + + +:::supervision.detection.overlap_filter.box_non_max_merge diff --git a/docs/detection/tools/inference_slicer.md b/docs/detection/tools/inference_slicer.md index 5d5d08bc..7a5d3e57 100644 --- a/docs/detection/tools/inference_slicer.md +++ b/docs/detection/tools/inference_slicer.md @@ -1,5 +1,6 @@ --- comments: true +status: new --- # InferenceSlicer diff --git a/docs/detection/tools/line_zone.md b/docs/detection/tools/line_zone.md index 8d13822c..22e9c0a8 100644 --- a/docs/detection/tools/line_zone.md +++ b/docs/detection/tools/line_zone.md @@ -1,5 +1,6 @@ --- comments: true +status: new ---
diff --git a/docs/detection/tools/save_detections.md b/docs/detection/tools/save_detections.md index a82ce5df..a24cee57 100644 --- a/docs/detection/tools/save_detections.md +++ b/docs/detection/tools/save_detections.md @@ -1,6 +1,5 @@ --- comments: true -status: new --- # Save Detections diff --git a/docs/detection/utils.md b/docs/detection/utils.md index abacdc21..ea98c868 100644 --- a/docs/detection/utils.md +++ b/docs/detection/utils.md @@ -1,6 +1,5 @@ --- comments: true -status: new --- # Detection Utils @@ -17,18 +16,6 @@ status: new :::supervision.detection.utils.mask_iou_batch - - -:::supervision.detection.utils.box_non_max_suppression - - - -:::supervision.detection.utils.mask_non_max_suppression - @@ -65,8 +52,38 @@ status: new :::supervision.detection.utils.move_boxes + + +:::supervision.detection.utils.move_masks + :::supervision.detection.utils.scale_boxes + + + +:::supervision.detection.utils.clip_boxes + + + +:::supervision.detection.utils.pad_boxes + + + +:::supervision.detection.utils.contains_holes + + + +:::supervision.detection.utils.contains_multiple_segments diff --git a/docs/how_to/detect_and_annotate.md b/docs/how_to/detect_and_annotate.md index a9a4405e..52e3174b 100644 --- a/docs/how_to/detect_and_annotate.md +++ b/docs/how_to/detect_and_annotate.md @@ -1,6 +1,5 @@ --- comments: true -status: new --- # Detect and Annotate diff --git a/docs/how_to/detect_small_objects.md b/docs/how_to/detect_small_objects.md index e2d02328..175b4f36 100644 --- a/docs/how_to/detect_small_objects.md +++ b/docs/how_to/detect_small_objects.md @@ -6,7 +6,7 @@ status: new # Detect Small Objects This guide shows how to detect small objects -with the [Inference](https://github.com/roboflow/inference), +with the [Inference](https://github.com/roboflow/inference), [Ultralytics](https://github.com/ultralytics/ultralytics) or [Transformers](https://github.com/huggingface/transformers) packages using [`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer). @@ -68,10 +68,10 @@ size relative to the image resolution. import torch import supervision as sv from PIL import Image - from transformers import DetrImageProcessor, DetrForObjectDetection + from transformers import DetrImageProcessor, DetrForSegmentation processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50") - model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50") + model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50") image = Image.open() inputs = processor(images=image, return_tensors="pt") @@ -79,8 +79,8 @@ size relative to the image resolution. with torch.no_grad(): outputs = model(**inputs) - width, height = image.size - target_size = torch.tensor([[height, width]]) + width, height = image_slice.size + target_size = torch.tensor([[width, height]]) results = processor.post_process_object_detection( outputs=outputs, target_sizes=target_size)[0] detections = sv.Detections.from_transformers(results) @@ -175,7 +175,7 @@ objects within each, and aggregating the results. def callback(image_slice: np.ndarray) -> sv.Detections: results = model.infer(image_slice)[0] - detections = sv.Detections.from_inference(results) + return sv.Detections.from_inference(results) slicer = sv.InferenceSlicer(callback = callback) detections = slicer(image) @@ -239,8 +239,8 @@ objects within each, and aggregating the results. with torch.no_grad(): outputs = model(**inputs) - width, height = image.size - target_size = torch.tensor([[height, width]]) + width, height = image_slice.size + target_size = torch.tensor([[width, height]]) results = processor.post_process_object_detection( outputs=outputs, target_sizes=target_size)[0] return sv.Detections.from_transformers(results) @@ -264,3 +264,63 @@ objects within each, and aggregating the results. ``` ![detection-with-inference-slicer](https://media.roboflow.com/supervision_detect_small_objects_example_3.png) + +## Small Object Segmentation + +[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) can perform segmentation tasks too. + +=== "Inference" + + ```{ .py hl_lines="6 16 19-20" } + import cv2 + import numpy as np + import supervision as sv + from inference import get_model + + model = get_model(model_id="yolov8x-seg-640") + image = cv2.imread() + + def callback(image_slice: np.ndarray) -> sv.Detections: + results = model.infer(image_slice)[0] + return sv.Detections.from_inference(results) + + slicer = sv.InferenceSlicer(callback = callback) + detections = slicer(image) + + mask_annotator = sv.MaskAnnotator() + label_annotator = sv.LabelAnnotator() + + annotated_image = mask_annotator.annotate( + scene=image, detections=detections) + annotated_image = label_annotator.annotate( + scene=annotated_image, detections=detections) + ``` + +=== "Ultralytics" + + ```{ .py hl_lines="6 16 19-20" } + import cv2 + import numpy as np + import supervision as sv + from ultralytics import YOLO + + model = YOLO("yolov8x-seg.pt") + image = cv2.imread() + + def callback(image_slice: np.ndarray) -> sv.Detections: + result = model(image_slice)[0] + return sv.Detections.from_ultralytics(result) + + slicer = sv.InferenceSlicer(callback = callback) + detections = slicer(image) + + mask_annotator = sv.MaskAnnotator() + label_annotator = sv.LabelAnnotator() + + annotated_image = mask_annotator.annotate( + scene=image, detections=detections) + annotated_image = label_annotator.annotate( + scene=annotated_image, detections=detections) + ``` + +![detection-with-inference-slicer](https://media.roboflow.com/supervision-docs/inference-slicer-segmentation-example.png) diff --git a/docs/how_to/save_detections.md b/docs/how_to/save_detections.md index 94de6c61..05d5faad 100644 --- a/docs/how_to/save_detections.md +++ b/docs/how_to/save_detections.md @@ -1,6 +1,5 @@ --- comments: true -status: new --- # Save Detections diff --git a/docs/keypoint/annotators.md b/docs/keypoint/annotators.md index b5f998bc..30a970ec 100644 --- a/docs/keypoint/annotators.md +++ b/docs/keypoint/annotators.md @@ -13,7 +13,10 @@ status: new image = ... key_points = sv.KeyPoints(...) - vertex_annotator = sv.VertexAnnotator(color=sv.Color.GREEN, radius=10) + vertex_annotator = sv.VertexAnnotator( + color=sv.Color.GREEN, + radius=10 + ) annotated_frame = vertex_annotator.annotate( scene=image.copy(), key_points=key_points @@ -34,7 +37,10 @@ status: new image = ... key_points = sv.KeyPoints(...) - edge_annotator = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5) + edge_annotator = sv.EdgeAnnotator( + color=sv.Color.GREEN, + thickness=5 + ) annotated_frame = edge_annotator.annotate( scene=image.copy(), key_points=key_points @@ -47,6 +53,31 @@ status: new
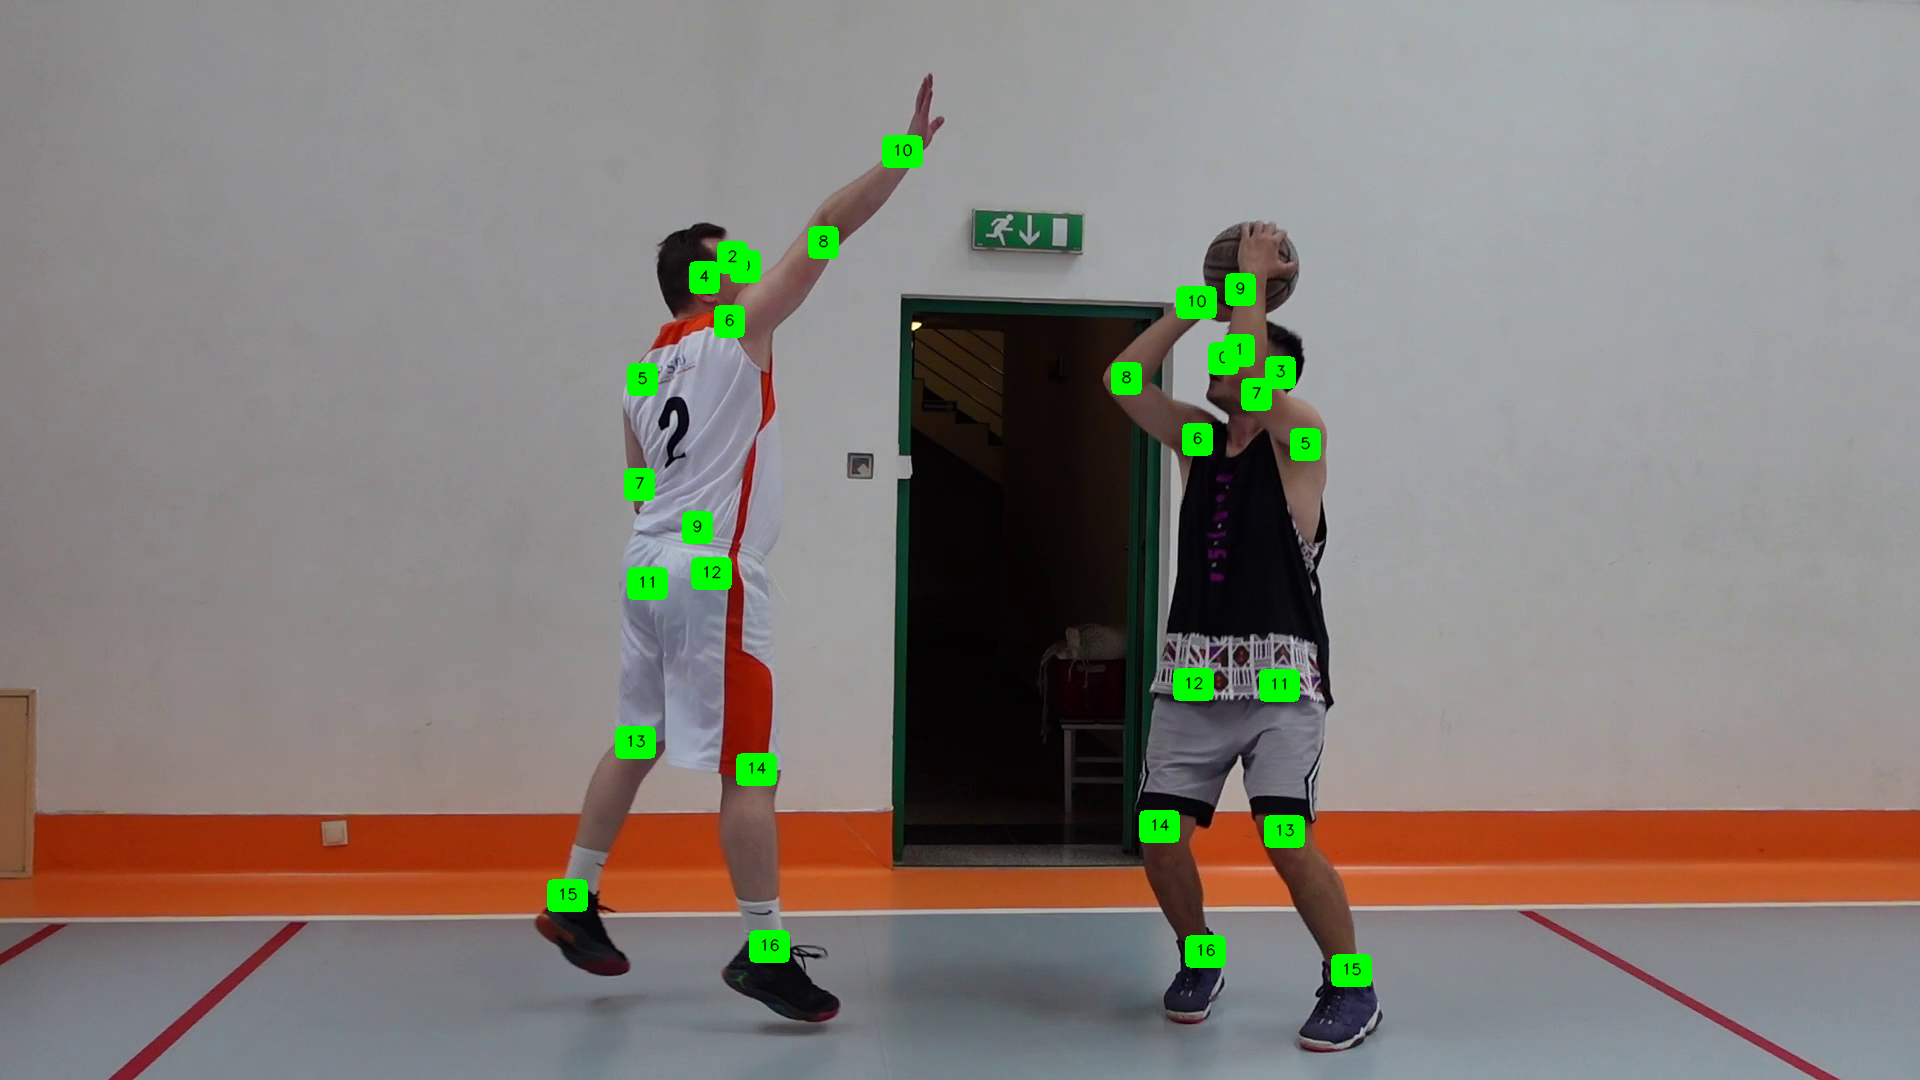
+=== "VertexLabelAnnotator" + + ```python + import supervision as sv + + image = ... + key_points = sv.KeyPoints(...) + + vertex_label_annotator = sv.VertexLabelAnnotator( + color=sv.Color.GREEN, + text_color=sv.Color.BLACK, + border_radius=5 + ) + annotated_frame = vertex_label_annotator.annotate( + scene=image.copy(), + key_points=key_points + ) + ``` + +
+ + ![vertex-label-annotator-example](https://media.roboflow.com/supervision-annotator-examples/vertex-label-annotator-example.png){ align=center width="800" } + +
+ @@ -58,3 +89,9 @@ status: new :::supervision.keypoint.annotators.EdgeAnnotator + + + +:::supervision.keypoint.annotators.VertexLabelAnnotator diff --git a/docs/trackers.md b/docs/trackers.md index 47f70061..cb44441f 100644 --- a/docs/trackers.md +++ b/docs/trackers.md @@ -1,6 +1,5 @@ --- comments: true -status: new --- # ByteTrack diff --git a/docs/utils/draw.md b/docs/utils/draw.md index 84758e06..f4b86a53 100644 --- a/docs/utils/draw.md +++ b/docs/utils/draw.md @@ -41,7 +41,7 @@ comments: true :::supervision.draw.utils.draw_image :::supervision.draw.utils.calculate_optimal_text_scale diff --git a/docs/utils/image.md b/docs/utils/image.md index 8f170d35..8e39136a 100644 --- a/docs/utils/image.md +++ b/docs/utils/image.md @@ -1,6 +1,5 @@ --- comments: true -status: new --- # Image Utils @@ -12,7 +11,7 @@ status: new :::supervision.utils.image.crop_image :::supervision.utils.image.scale_image diff --git a/docs/utils/iterables.md b/docs/utils/iterables.md index b65cd954..5ae92dc9 100644 --- a/docs/utils/iterables.md +++ b/docs/utils/iterables.md @@ -1,6 +1,5 @@ --- comments: true -status: new --- # Iterables Utils diff --git a/examples/count_people_in_zone/inference_example.py b/examples/count_people_in_zone/inference_example.py index 6fd0f340..c5086806 100644 --- a/examples/count_people_in_zone/inference_example.py +++ b/examples/count_people_in_zone/inference_example.py @@ -38,15 +38,15 @@ def initiate_annotators( ) -> Tuple[ List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator] ]: - line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh) - text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh) + line_thickness = sv.calculate_optimal_line_thickness(resolution_wh=resolution_wh) + text_scale = sv.calculate_optimal_text_scale(resolution_wh=resolution_wh) zones = [] zone_annotators = [] box_annotators = [] for index, polygon in enumerate(polygons): - zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh) + zone = sv.PolygonZone(polygon=polygon) zone_annotator = sv.PolygonZoneAnnotator( zone=zone, color=COLORS.by_idx(index), diff --git a/examples/count_people_in_zone/requirements.txt b/examples/count_people_in_zone/requirements.txt index d9e27264..1cd58655 100644 --- a/examples/count_people_in_zone/requirements.txt +++ b/examples/count_people_in_zone/requirements.txt @@ -1,5 +1,5 @@ gdown -inference -supervision==0.19.0 +inference==0.9.17 +supervision>=0.20.0 tqdm ultralytics diff --git a/examples/count_people_in_zone/ultralytics_example.py b/examples/count_people_in_zone/ultralytics_example.py index cfd37bcc..c17e4d7b 100644 --- a/examples/count_people_in_zone/ultralytics_example.py +++ b/examples/count_people_in_zone/ultralytics_example.py @@ -36,15 +36,15 @@ def initiate_annotators( ) -> Tuple[ List[sv.PolygonZone], List[sv.PolygonZoneAnnotator], List[sv.BoundingBoxAnnotator] ]: - line_thickness = sv.calculate_dynamic_line_thickness(resolution_wh=resolution_wh) - text_scale = sv.calculate_dynamic_text_scale(resolution_wh=resolution_wh) + line_thickness = sv.calculate_optimal_line_thickness(resolution_wh=resolution_wh) + text_scale = sv.calculate_optimal_text_scale(resolution_wh=resolution_wh) zones = [] zone_annotators = [] box_annotators = [] for index, polygon in enumerate(polygons): - zone = sv.PolygonZone(polygon=polygon, frame_resolution_wh=resolution_wh) + zone = sv.PolygonZone(polygon=polygon) zone_annotator = sv.PolygonZoneAnnotator( zone=zone, color=COLORS.by_idx(index), diff --git a/examples/speed_estimation/inference_example.py b/examples/speed_estimation/inference_example.py index b0ff84dd..e715d88e 100644 --- a/examples/speed_estimation/inference_example.py +++ b/examples/speed_estimation/inference_example.py @@ -98,10 +98,10 @@ if __name__ == "__main__": frame_rate=video_info.fps, track_thresh=args.confidence_threshold ) - thickness = sv.calculate_dynamic_line_thickness( + thickness = sv.calculate_optimal_line_thickness( resolution_wh=video_info.resolution_wh ) - text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh) + text_scale = sv.calculate_optimal_text_scale(resolution_wh=video_info.resolution_wh) bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness) label_annotator = sv.LabelAnnotator( text_scale=text_scale, @@ -116,9 +116,7 @@ if __name__ == "__main__": frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path) - polygon_zone = sv.PolygonZone( - polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh - ) + polygon_zone = sv.PolygonZone(polygon=SOURCE) view_transformer = ViewTransformer(source=SOURCE, target=TARGET) coordinates = defaultdict(lambda: deque(maxlen=video_info.fps)) diff --git a/examples/speed_estimation/requirements.txt b/examples/speed_estimation/requirements.txt index 36de970d..343a687d 100644 --- a/examples/speed_estimation/requirements.txt +++ b/examples/speed_estimation/requirements.txt @@ -1,6 +1,6 @@ -supervision==0.19.0 -tqdm==4.66.1 +supervision>=0.20.0 +tqdm==4.66.3 requests ultralytics==8.0.237 super-gradients==3.5.0 -inference==0.9.8 +inference==0.9.17 diff --git a/examples/speed_estimation/ultralytics_example.py b/examples/speed_estimation/ultralytics_example.py index 4b0436a0..4440d4d9 100644 --- a/examples/speed_estimation/ultralytics_example.py +++ b/examples/speed_estimation/ultralytics_example.py @@ -76,10 +76,10 @@ if __name__ == "__main__": frame_rate=video_info.fps, track_thresh=args.confidence_threshold ) - thickness = sv.calculate_dynamic_line_thickness( + thickness = sv.calculate_optimal_line_thickness( resolution_wh=video_info.resolution_wh ) - text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh) + text_scale = sv.calculate_optimal_text_scale(resolution_wh=video_info.resolution_wh) bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness) label_annotator = sv.LabelAnnotator( text_scale=text_scale, @@ -94,9 +94,7 @@ if __name__ == "__main__": frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path) - polygon_zone = sv.PolygonZone( - polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh - ) + polygon_zone = sv.PolygonZone(polygon=SOURCE) view_transformer = ViewTransformer(source=SOURCE, target=TARGET) coordinates = defaultdict(lambda: deque(maxlen=video_info.fps)) diff --git a/examples/speed_estimation/yolo_nas_example.py b/examples/speed_estimation/yolo_nas_example.py index 77f1fd0f..4bb1d960 100644 --- a/examples/speed_estimation/yolo_nas_example.py +++ b/examples/speed_estimation/yolo_nas_example.py @@ -77,10 +77,10 @@ if __name__ == "__main__": frame_rate=video_info.fps, track_thresh=args.confidence_threshold ) - thickness = sv.calculate_dynamic_line_thickness( + thickness = sv.calculate_optimal_line_thickness( resolution_wh=video_info.resolution_wh ) - text_scale = sv.calculate_dynamic_text_scale(resolution_wh=video_info.resolution_wh) + text_scale = sv.calculate_optimal_text_scale(resolution_wh=video_info.resolution_wh) bounding_box_annotator = sv.BoundingBoxAnnotator(thickness=thickness) label_annotator = sv.LabelAnnotator( text_scale=text_scale, @@ -95,9 +95,7 @@ if __name__ == "__main__": frame_generator = sv.get_video_frames_generator(source_path=args.source_video_path) - polygon_zone = sv.PolygonZone( - polygon=SOURCE, frame_resolution_wh=video_info.resolution_wh - ) + polygon_zone = sv.PolygonZone(polygon=SOURCE) view_transformer = ViewTransformer(source=SOURCE, target=TARGET) coordinates = defaultdict(lambda: deque(maxlen=video_info.fps)) diff --git a/examples/time_in_zone/README.md b/examples/time_in_zone/README.md index 98587999..0a366a94 100644 --- a/examples/time_in_zone/README.md +++ b/examples/time_in_zone/README.md @@ -103,7 +103,7 @@ python scripts/draw_zones.py \ ```bash python scripts/draw_zones.py \ --source_path "data/traffic/video.mp4" \ ---zone_configuration_path "data/traffic/custom_config.json" +--zone_configuration_path "data/traffic/config.json" ``` https://github.com/roboflow/supervision/assets/26109316/9d514c9e-2a61-418b-ae49-6ac1ad6ae5ac @@ -157,7 +157,7 @@ Script to run object detection on a video stream using the Roboflow Inference mo - `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`. ```bash -python inference_file_example.py \ +python inference_stream_example.py \ --zone_configuration_path "data/checkout/config.json" \ --rtsp_url "rtsp://localhost:8554/live0.stream" \ --model_id "yolov8x-640" \ @@ -167,7 +167,7 @@ python inference_file_example.py \ ``` ```bash -python inference_file_example.py \ +python inference_stream_example.py \ --zone_configuration_path "data/traffic/config.json" \ --rtsp_url "rtsp://localhost:8554/live0.stream" \ --model_id "yolov8x-640" \ @@ -192,7 +192,7 @@ Script to run object detection on a video file using the Ultralytics YOLOv8 mode - `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`. ```bash -python inference_file_example.py \ +python ultralytics_file_example.py \ --zone_configuration_path "data/checkout/config.json" \ --source_video_path "data/checkout/video.mp4" \ --weights "yolov8x.pt" \ @@ -203,7 +203,7 @@ python inference_file_example.py \ ``` ```bash -python inference_file_example.py \ +python ultralytics_file_example.py \ --zone_configuration_path "data/traffic/config.json" \ --source_video_path "data/traffic/video.mp4" \ --weights "yolov8x.pt" \ @@ -226,7 +226,7 @@ Script to run object detection on a video stream using the Ultralytics YOLOv8 mo - `--iou_threshold`: IOU threshold for non-max suppression. Default is `0.7`. ```bash -python inference_file_example.py \ +python ultralytics_stream_example.py \ --zone_configuration_path "data/checkout/config.json" \ --rtsp_url "rtsp://localhost:8554/live0.stream" \ --weights "yolov8x.pt" \ @@ -237,7 +237,7 @@ python inference_file_example.py \ ``` ```bash -python inference_file_example.py \ +python ultralytics_stream_example.py \ --zone_configuration_path "data/traffic/config.json" \ --rtsp_url "rtsp://localhost:8554/live0.stream" \ --weights "yolov8x.pt" \ diff --git a/examples/time_in_zone/inference_file_example.py b/examples/time_in_zone/inference_file_example.py index 5feb1d83..f4955464 100644 --- a/examples/time_in_zone/inference_file_example.py +++ b/examples/time_in_zone/inference_file_example.py @@ -29,14 +29,10 @@ def main( video_info = sv.VideoInfo.from_video_path(video_path=source_video_path) frames_generator = sv.get_video_frames_generator(source_video_path) - frame = next(frames_generator) - resolution_wh = frame.shape[1], frame.shape[0] - polygons = load_zones_config(file_path=zone_configuration_path) zones = [ sv.PolygonZone( polygon=polygon, - frame_resolution_wh=resolution_wh, triggering_anchors=(sv.Position.CENTER,), ) for polygon in polygons diff --git a/examples/time_in_zone/inference_naive_stream_example.py b/examples/time_in_zone/inference_naive_stream_example.py index dd2d68a5..21880269 100644 --- a/examples/time_in_zone/inference_naive_stream_example.py +++ b/examples/time_in_zone/inference_naive_stream_example.py @@ -29,14 +29,10 @@ def main( frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url) fps_monitor = sv.FPSMonitor() - frame = next(frames_generator) - resolution_wh = frame.shape[1], frame.shape[0] - polygons = load_zones_config(file_path=zone_configuration_path) zones = [ sv.PolygonZone( polygon=polygon, - frame_resolution_wh=resolution_wh, triggering_anchors=(sv.Position.CENTER,), ) for polygon in polygons diff --git a/examples/time_in_zone/inference_stream_example.py b/examples/time_in_zone/inference_stream_example.py index e1fae57f..0dfdf660 100644 --- a/examples/time_in_zone/inference_stream_example.py +++ b/examples/time_in_zone/inference_stream_example.py @@ -24,20 +24,15 @@ class CustomSink: self.fps_monitor = sv.FPSMonitor() self.polygons = load_zones_config(file_path=zone_configuration_path) self.timers = [ClockBasedTimer() for _ in self.polygons] - self.zones = None + self.zones = [ + sv.PolygonZone( + polygon=polygon, + triggering_anchors=(sv.Position.CENTER,), + ) + for polygon in self.polygons + ] def on_prediction(self, result: dict, frame: VideoFrame) -> None: - if self.zones is None: - resolution_wh = frame.image.shape[1], frame.image.shape[0] - self.zones = [ - sv.PolygonZone( - polygon=polygon, - frame_resolution_wh=resolution_wh, - triggering_anchors=(sv.Position.CENTER,), - ) - for polygon in self.polygons - ] - self.fps_monitor.tick() fps = self.fps_monitor.fps diff --git a/examples/time_in_zone/requirements.txt b/examples/time_in_zone/requirements.txt index fa17b986..6154c3eb 100644 --- a/examples/time_in_zone/requirements.txt +++ b/examples/time_in_zone/requirements.txt @@ -1,5 +1,5 @@ opencv-python -supervision +supervision>=0.20.0 ultralytics -inference +inference==0.9.17 pytube diff --git a/examples/time_in_zone/ultralytics_file_example.py b/examples/time_in_zone/ultralytics_file_example.py index fe8ce58d..b470b7a3 100644 --- a/examples/time_in_zone/ultralytics_file_example.py +++ b/examples/time_in_zone/ultralytics_file_example.py @@ -30,14 +30,10 @@ def main( video_info = sv.VideoInfo.from_video_path(video_path=source_video_path) frames_generator = sv.get_video_frames_generator(source_video_path) - frame = next(frames_generator) - resolution_wh = frame.shape[1], frame.shape[0] - polygons = load_zones_config(file_path=zone_configuration_path) zones = [ sv.PolygonZone( polygon=polygon, - frame_resolution_wh=resolution_wh, triggering_anchors=(sv.Position.CENTER,), ) for polygon in polygons diff --git a/examples/time_in_zone/ultralytics_naive_stream_example.py b/examples/time_in_zone/ultralytics_naive_stream_example.py index 1cc82b44..d6922143 100644 --- a/examples/time_in_zone/ultralytics_naive_stream_example.py +++ b/examples/time_in_zone/ultralytics_naive_stream_example.py @@ -30,14 +30,10 @@ def main( frames_generator = get_stream_frames_generator(rtsp_url=rtsp_url) fps_monitor = sv.FPSMonitor() - frame = next(frames_generator) - resolution_wh = frame.shape[1], frame.shape[0] - polygons = load_zones_config(file_path=zone_configuration_path) zones = [ sv.PolygonZone( polygon=polygon, - frame_resolution_wh=resolution_wh, triggering_anchors=(sv.Position.CENTER,), ) for polygon in polygons diff --git a/examples/time_in_zone/ultralytics_stream_example.py b/examples/time_in_zone/ultralytics_stream_example.py index 25dc874f..8b8ecd60 100644 --- a/examples/time_in_zone/ultralytics_stream_example.py +++ b/examples/time_in_zone/ultralytics_stream_example.py @@ -25,20 +25,15 @@ class CustomSink: self.fps_monitor = sv.FPSMonitor() self.polygons = load_zones_config(file_path=zone_configuration_path) self.timers = [ClockBasedTimer() for _ in self.polygons] - self.zones = None + self.zones = [ + sv.PolygonZone( + polygon=polygon, + triggering_anchors=(sv.Position.CENTER,), + ) + for polygon in self.polygons + ] def on_prediction(self, detections: sv.Detections, frame: VideoFrame) -> None: - if self.zones is None: - resolution_wh = frame.image.shape[1], frame.image.shape[0] - self.zones = [ - sv.PolygonZone( - polygon=polygon, - frame_resolution_wh=resolution_wh, - triggering_anchors=(sv.Position.CENTER,), - ) - for polygon in self.polygons - ] - self.fps_monitor.tick() fps = self.fps_monitor.fps diff --git a/examples/tracking/requirements.txt b/examples/tracking/requirements.txt index 8d5a9233..a45d9291 100644 --- a/examples/tracking/requirements.txt +++ b/examples/tracking/requirements.txt @@ -1,4 +1,4 @@ -inference +inference==0.9.17 supervision==0.19.0 tqdm ultralytics diff --git a/examples/traffic_analysis/inference_example.py b/examples/traffic_analysis/inference_example.py index 7da5f37c..3cf750ad 100644 --- a/examples/traffic_analysis/inference_example.py +++ b/examples/traffic_analysis/inference_example.py @@ -1,6 +1,6 @@ import argparse import os -from typing import Dict, Iterable, List, Set, Tuple +from typing import Dict, Iterable, List, Set import cv2 import numpy as np @@ -60,13 +60,11 @@ class DetectionsManager: def initiate_polygon_zones( polygons: List[np.ndarray], - frame_resolution_wh: Tuple[int, int], triggering_anchors: Iterable[sv.Position] = [sv.Position.CENTER], ) -> List[sv.PolygonZone]: return [ sv.PolygonZone( polygon=polygon, - frame_resolution_wh=frame_resolution_wh, triggering_anchors=triggering_anchors, ) for polygon in polygons @@ -92,12 +90,8 @@ class VideoProcessor: self.tracker = sv.ByteTrack() self.video_info = sv.VideoInfo.from_video_path(source_video_path) - self.zones_in = initiate_polygon_zones( - ZONE_IN_POLYGONS, self.video_info.resolution_wh, [sv.Position.CENTER] - ) - self.zones_out = initiate_polygon_zones( - ZONE_OUT_POLYGONS, self.video_info.resolution_wh, [sv.Position.CENTER] - ) + self.zones_in = initiate_polygon_zones(ZONE_IN_POLYGONS, [sv.Position.CENTER]) + self.zones_out = initiate_polygon_zones(ZONE_OUT_POLYGONS, [sv.Position.CENTER]) self.bounding_box_annotator = sv.BoundingBoxAnnotator(color=COLORS) self.label_annotator = sv.LabelAnnotator( diff --git a/examples/traffic_analysis/requirements.txt b/examples/traffic_analysis/requirements.txt index 6e72dd55..1cd58655 100644 --- a/examples/traffic_analysis/requirements.txt +++ b/examples/traffic_analysis/requirements.txt @@ -1,5 +1,5 @@ gdown -inference -supervision>=0.19.0 +inference==0.9.17 +supervision>=0.20.0 tqdm ultralytics diff --git a/examples/traffic_analysis/ultralytics_example.py b/examples/traffic_analysis/ultralytics_example.py index 78189d29..16ba6d8c 100644 --- a/examples/traffic_analysis/ultralytics_example.py +++ b/examples/traffic_analysis/ultralytics_example.py @@ -1,5 +1,5 @@ import argparse -from typing import Dict, Iterable, List, Set, Tuple +from typing import Dict, Iterable, List, Set import cv2 import numpy as np @@ -58,13 +58,11 @@ class DetectionsManager: def initiate_polygon_zones( polygons: List[np.ndarray], - frame_resolution_wh: Tuple[int, int], triggering_anchors: Iterable[sv.Position] = [sv.Position.CENTER], ) -> List[sv.PolygonZone]: return [ sv.PolygonZone( polygon=polygon, - frame_resolution_wh=frame_resolution_wh, triggering_anchors=triggering_anchors, ) for polygon in polygons @@ -89,12 +87,8 @@ class VideoProcessor: self.tracker = sv.ByteTrack() self.video_info = sv.VideoInfo.from_video_path(source_video_path) - self.zones_in = initiate_polygon_zones( - ZONE_IN_POLYGONS, self.video_info.resolution_wh, [sv.Position.CENTER] - ) - self.zones_out = initiate_polygon_zones( - ZONE_OUT_POLYGONS, self.video_info.resolution_wh, [sv.Position.CENTER] - ) + self.zones_in = initiate_polygon_zones(ZONE_IN_POLYGONS, [sv.Position.CENTER]) + self.zones_out = initiate_polygon_zones(ZONE_OUT_POLYGONS, [sv.Position.CENTER]) self.bounding_box_annotator = sv.BoundingBoxAnnotator(color=COLORS) self.label_annotator = sv.LabelAnnotator( diff --git a/mkdocs.yml b/mkdocs.yml index cf206a82..96728971 100644 --- a/mkdocs.yml +++ b/mkdocs.yml @@ -35,19 +35,20 @@ extra_css: nav: - - Home: index.md - - How to: + - Supervision: index.md + - Learn: - Detect and Annotate: how_to/detect_and_annotate.md - Save Detections: how_to/save_detections.md - Filter Detections: how_to/filter_detections.md - Detect Small Objects: how_to/detect_small_objects.md - - Track Objects: how_to/track_objects.md + - Track Objects on Video: how_to/track_objects.md - - API: + - Reference - Code API: - Detection and Segmentation: - Core: detection/core.md - Annotators: detection/annotators.md - Metrics: detection/metrics.md + - Double Detection Filter: detection/double_detection_filter.md - Utils: detection/utils.md - Keypoint Detection: - Core: keypoint/core.md @@ -61,7 +62,9 @@ nav: - Detection Smoother: detection/tools/smoother.md - Save Detections: detection/tools/save_detections.md - Trackers: trackers.md - - Datasets: datasets.md + - Datasets: + - Core: datasets/core.md + - Utils: datasets/utils.md - Utils: - Video: utils/video.md - Image: utils/image.md @@ -76,7 +79,7 @@ nav: - Contributing: contributing.md - Code of Conduct: code_of_conduct.md - License: license.md - - Changelog: + - Release Notes: - Changelog: changelog.md - Deprecated: deprecated.md diff --git a/poetry.lock b/poetry.lock index 95cbef01..4d1b52ae 100644 --- a/poetry.lock +++ b/poetry.lock @@ -1253,21 +1253,21 @@ test-extra = ["curio", "matplotlib (!=3.2.0)", "nbformat", "numpy (>=1.21)", "pa [[package]] name = "ipywidgets" -version = "8.1.2" +version = "8.1.3" description = "Jupyter interactive widgets" optional = false python-versions = ">=3.7" files = [ - {file = "ipywidgets-8.1.2-py3-none-any.whl", hash = "sha256:bbe43850d79fb5e906b14801d6c01402857996864d1e5b6fa62dd2ee35559f60"}, - {file = "ipywidgets-8.1.2.tar.gz", hash = "sha256:d0b9b41e49bae926a866e613a39b0f0097745d2b9f1f3dd406641b4a57ec42c9"}, + {file = "ipywidgets-8.1.3-py3-none-any.whl", hash = "sha256:efafd18f7a142248f7cb0ba890a68b96abd4d6e88ddbda483c9130d12667eaf2"}, + {file = "ipywidgets-8.1.3.tar.gz", hash = "sha256:f5f9eeaae082b1823ce9eac2575272952f40d748893972956dc09700a6392d9c"}, ] [package.dependencies] comm = ">=0.1.3" ipython = ">=6.1.0" -jupyterlab-widgets = ">=3.0.10,<3.1.0" +jupyterlab-widgets = ">=3.0.11,<3.1.0" traitlets = ">=4.3.1" -widgetsnbextension = ">=4.0.10,<4.1.0" +widgetsnbextension = ">=4.0.11,<4.1.0" [package.extras] test = ["ipykernel", "jsonschema", "pytest (>=3.6.0)", "pytest-cov", "pytz"] @@ -1340,13 +1340,13 @@ trio = ["async_generator", "trio"] [[package]] name = "jinja2" -version = "3.1.3" +version = "3.1.4" description = "A very fast and expressive template engine." optional = false python-versions = ">=3.7" files = [ - {file = "Jinja2-3.1.3-py3-none-any.whl", hash = "sha256:7d6d50dd97d52cbc355597bd845fabfbac3f551e1f99619e39a35ce8c370b5fa"}, - {file = "Jinja2-3.1.3.tar.gz", hash = "sha256:ac8bd6544d4bb2c9792bf3a159e80bba8fda7f07e81bc3aed565432d5925ba90"}, + {file = "jinja2-3.1.4-py3-none-any.whl", hash = "sha256:bc5dd2abb727a5319567b7a813e6a2e7318c39f4f487cfe6c89c6f9c7d25197d"}, + {file = "jinja2-3.1.4.tar.gz", hash = "sha256:4a3aee7acbbe7303aede8e9648d13b8bf88a429282aa6122a993f0ac800cb369"}, ] [package.dependencies] @@ -1566,13 +1566,13 @@ test = ["jupyter-server (>=2.0.0)", "pytest (>=7.0)", "pytest-jupyter[server] (> [[package]] name = "jupyterlab" -version = "4.1.2" +version = "4.2.0" description = "JupyterLab computational environment" optional = false python-versions = ">=3.8" files = [ - {file = "jupyterlab-4.1.2-py3-none-any.whl", hash = "sha256:aa88193f03cf4d3555f6712f04d74112b5eb85edd7d222c588c7603a26d33c5b"}, - {file = "jupyterlab-4.1.2.tar.gz", hash = "sha256:5d6348b3ed4085181499f621b7dfb6eb0b1f57f3586857aadfc8e3bf4c4885f9"}, + {file = "jupyterlab-4.2.0-py3-none-any.whl", hash = "sha256:0dfe9278e25a145362289c555d9beb505697d269c10e99909766af7c440ad3cc"}, + {file = "jupyterlab-4.2.0.tar.gz", hash = "sha256:356e9205a6a2ab689c47c8fe4919dba6c076e376d03f26baadc05748c2435dd5"}, ] [package.dependencies] @@ -1580,23 +1580,24 @@ async-lru = ">=1.0.0" httpx = ">=0.25.0" importlib-metadata = {version = ">=4.8.3", markers = "python_version < \"3.10\""} importlib-resources = {version = ">=1.4", markers = "python_version < \"3.9\""} -ipykernel = "*" +ipykernel = ">=6.5.0" jinja2 = ">=3.0.3" jupyter-core = "*" jupyter-lsp = ">=2.0.0" jupyter-server = ">=2.4.0,<3" -jupyterlab-server = ">=2.19.0,<3" +jupyterlab-server = ">=2.27.1,<3" notebook-shim = ">=0.2" packaging = "*" -tomli = {version = "*", markers = "python_version < \"3.11\""} +tomli = {version = ">=1.2.2", markers = "python_version < \"3.11\""} tornado = ">=6.2.0" traitlets = "*" [package.extras] -dev = ["build", "bump2version", "coverage", "hatch", "pre-commit", "pytest-cov", "ruff (==0.2.0)"] +dev = ["build", "bump2version", "coverage", "hatch", "pre-commit", "pytest-cov", "ruff (==0.3.5)"] docs = ["jsx-lexer", "myst-parser", "pydata-sphinx-theme (>=0.13.0)", "pytest", "pytest-check-links", "pytest-jupyter", "sphinx (>=1.8,<7.3.0)", "sphinx-copybutton"] -docs-screenshots = ["altair (==5.2.0)", "ipython (==8.16.1)", "ipywidgets (==8.1.1)", "jupyterlab-geojson (==3.4.0)", "jupyterlab-language-pack-zh-cn (==4.0.post6)", "matplotlib (==3.8.2)", "nbconvert (>=7.0.0)", "pandas (==2.2.0)", "scipy (==1.12.0)", "vega-datasets (==0.9.0)"] +docs-screenshots = ["altair (==5.3.0)", "ipython (==8.16.1)", "ipywidgets (==8.1.2)", "jupyterlab-geojson (==3.4.0)", "jupyterlab-language-pack-zh-cn (==4.1.post2)", "matplotlib (==3.8.3)", "nbconvert (>=7.0.0)", "pandas (==2.2.1)", "scipy (==1.12.0)", "vega-datasets (==0.9.0)"] test = ["coverage", "pytest (>=7.0)", "pytest-check-links (>=0.7)", "pytest-console-scripts", "pytest-cov", "pytest-jupyter (>=0.5.3)", "pytest-timeout", "pytest-tornasync", "requests", "requests-cache", "virtualenv"] +upgrade-extension = ["copier (>=8,<10)", "jinja2-time (<0.3)", "pydantic (<2.0)", "pyyaml-include (<2.0)", "tomli-w (<2.0)"] [[package]] name = "jupyterlab-pygments" @@ -1611,13 +1612,13 @@ files = [ [[package]] name = "jupyterlab-server" -version = "2.25.3" +version = "2.27.1" description = "A set of server components for JupyterLab and JupyterLab like applications." optional = false python-versions = ">=3.8" files = [ - {file = "jupyterlab_server-2.25.3-py3-none-any.whl", hash = "sha256:c48862519fded9b418c71645d85a49b2f0ec50d032ba8316738e9276046088c1"}, - {file = "jupyterlab_server-2.25.3.tar.gz", hash = "sha256:846f125a8a19656611df5b03e5912c8393cea6900859baa64fa515eb64a8dc40"}, + {file = "jupyterlab_server-2.27.1-py3-none-any.whl", hash = "sha256:f5e26156e5258b24d532c84e7c74cc212e203bff93eb856f81c24c16daeecc75"}, + {file = "jupyterlab_server-2.27.1.tar.gz", hash = "sha256:097b5ac709b676c7284ac9c5e373f11930a561f52cd5a86e4fc7e5a9c8a8631d"}, ] [package.dependencies] @@ -1633,28 +1634,28 @@ requests = ">=2.31" [package.extras] docs = ["autodoc-traits", "jinja2 (<3.2.0)", "mistune (<4)", "myst-parser", "pydata-sphinx-theme", "sphinx", "sphinx-copybutton", "sphinxcontrib-openapi (>0.8)"] openapi = ["openapi-core (>=0.18.0,<0.19.0)", "ruamel-yaml"] -test = ["hatch", "ipykernel", "openapi-core (>=0.18.0,<0.19.0)", "openapi-spec-validator (>=0.6.0,<0.8.0)", "pytest (>=7.0)", "pytest-console-scripts", "pytest-cov", "pytest-jupyter[server] (>=0.6.2)", "pytest-timeout", "requests-mock", "ruamel-yaml", "sphinxcontrib-spelling", "strict-rfc3339", "werkzeug"] +test = ["hatch", "ipykernel", "openapi-core (>=0.18.0,<0.19.0)", "openapi-spec-validator (>=0.6.0,<0.8.0)", "pytest (>=7.0,<8)", "pytest-console-scripts", "pytest-cov", "pytest-jupyter[server] (>=0.6.2)", "pytest-timeout", "requests-mock", "ruamel-yaml", "sphinxcontrib-spelling", "strict-rfc3339", "werkzeug"] [[package]] name = "jupyterlab-widgets" -version = "3.0.10" +version = "3.0.11" description = "Jupyter interactive widgets for JupyterLab" optional = false python-versions = ">=3.7" files = [ - {file = "jupyterlab_widgets-3.0.10-py3-none-any.whl", hash = "sha256:dd61f3ae7a5a7f80299e14585ce6cf3d6925a96c9103c978eda293197730cb64"}, - {file = "jupyterlab_widgets-3.0.10.tar.gz", hash = "sha256:04f2ac04976727e4f9d0fa91cdc2f1ab860f965e504c29dbd6a65c882c9d04c0"}, + {file = "jupyterlab_widgets-3.0.11-py3-none-any.whl", hash = "sha256:78287fd86d20744ace330a61625024cf5521e1c012a352ddc0a3cdc2348becd0"}, + {file = "jupyterlab_widgets-3.0.11.tar.gz", hash = "sha256:dd5ac679593c969af29c9bed054c24f26842baa51352114736756bc035deee27"}, ] [[package]] name = "jupytext" -version = "1.16.1" +version = "1.16.2" description = "Jupyter notebooks as Markdown documents, Julia, Python or R scripts" optional = false python-versions = ">=3.8" files = [ - {file = "jupytext-1.16.1-py3-none-any.whl", hash = "sha256:796ec4f68ada663569e5d38d4ef03738a01284bfe21c943c485bc36433898bd0"}, - {file = "jupytext-1.16.1.tar.gz", hash = "sha256:68c7b68685e870e80e60fda8286fbd6269e9c74dc1df4316df6fe46eabc94c99"}, + {file = "jupytext-1.16.2-py3-none-any.whl", hash = "sha256:197a43fef31dca612b68b311e01b8abd54441c7e637810b16b6cb8f2ab66065e"}, + {file = "jupytext-1.16.2.tar.gz", hash = "sha256:8627dd9becbbebd79cc4a4ed4727d89d78e606b4b464eab72357b3b029023a14"}, ] [package.dependencies] @@ -1663,16 +1664,16 @@ mdit-py-plugins = "*" nbformat = "*" packaging = "*" pyyaml = "*" -toml = "*" +tomli = {version = "*", markers = "python_version < \"3.11\""} [package.extras] -dev = ["jupytext[test-cov,test-external]"] +dev = ["autopep8", "black", "flake8", "gitpython", "ipykernel", "isort", "jupyter-fs (<0.4.0)", "jupyter-server (!=2.11)", "nbconvert", "pre-commit", "pytest", "pytest-cov (>=2.6.1)", "pytest-randomly", "pytest-xdist", "sphinx-gallery (<0.8)"] docs = ["myst-parser", "sphinx", "sphinx-copybutton", "sphinx-rtd-theme"] test = ["pytest", "pytest-randomly", "pytest-xdist"] -test-cov = ["jupytext[test-integration]", "pytest-cov (>=2.6.1)"] -test-external = ["autopep8", "black", "flake8", "gitpython", "isort", "jupyter-fs (<0.4.0)", "jupytext[test-integration]", "pre-commit", "sphinx-gallery (<0.8)"] -test-functional = ["jupytext[test]"] -test-integration = ["ipykernel", "jupyter-server (!=2.11)", "jupytext[test-functional]", "nbconvert"] +test-cov = ["ipykernel", "jupyter-server (!=2.11)", "nbconvert", "pytest", "pytest-cov (>=2.6.1)", "pytest-randomly", "pytest-xdist"] +test-external = ["autopep8", "black", "flake8", "gitpython", "ipykernel", "isort", "jupyter-fs (<0.4.0)", "jupyter-server (!=2.11)", "nbconvert", "pre-commit", "pytest", "pytest-randomly", "pytest-xdist", "sphinx-gallery (<0.8)"] +test-functional = ["pytest", "pytest-randomly", "pytest-xdist"] +test-integration = ["ipykernel", "jupyter-server (!=2.11)", "nbconvert", "pytest", "pytest-randomly", "pytest-xdist"] test-ui = ["calysto-bash"] [[package]] @@ -2048,13 +2049,13 @@ files = [ [[package]] name = "mike" -version = "2.0.0" +version = "2.1.1" description = "Manage multiple versions of your MkDocs-powered documentation" optional = false python-versions = "*" files = [ - {file = "mike-2.0.0-py3-none-any.whl", hash = "sha256:87f496a65900f93ba92d72940242b65c86f3f2f82871bc60ebdcffc91fad1d9e"}, - {file = "mike-2.0.0.tar.gz", hash = "sha256:566f1cab1a58cc50b106fb79ea2f1f56e7bfc8b25a051e95e6eaee9fba0922de"}, + {file = "mike-2.1.1-py3-none-any.whl", hash = "sha256:0b1d01a397a423284593eeb1b5f3194e37169488f929b860c9bfe95c0d5efb79"}, + {file = "mike-2.1.1.tar.gz", hash = "sha256:f39ed39f3737da83ad0adc33e9f885092ed27f8c9e7ff0523add0480352a2c22"}, ] [package.dependencies] @@ -2064,6 +2065,7 @@ jinja2 = ">=2.7" mkdocs = ">=1.0" pyparsing = ">=3.0" pyyaml = ">=5.1" +pyyaml-env-tag = "*" verspec = "*" [package.extras] @@ -2083,34 +2085,34 @@ files = [ [[package]] name = "mkdocs" -version = "1.5.3" +version = "1.6.0" description = "Project documentation with Markdown." optional = false -python-versions = ">=3.7" +python-versions = ">=3.8" files = [ - {file = "mkdocs-1.5.3-py3-none-any.whl", hash = "sha256:3b3a78e736b31158d64dbb2f8ba29bd46a379d0c6e324c2246c3bc3d2189cfc1"}, - {file = "mkdocs-1.5.3.tar.gz", hash = "sha256:eb7c99214dcb945313ba30426c2451b735992c73c2e10838f76d09e39ff4d0e2"}, + {file = "mkdocs-1.6.0-py3-none-any.whl", hash = "sha256:1eb5cb7676b7d89323e62b56235010216319217d4af5ddc543a91beb8d125ea7"}, + {file = "mkdocs-1.6.0.tar.gz", hash = "sha256:a73f735824ef83a4f3bcb7a231dcab23f5a838f88b7efc54a0eef5fbdbc3c512"}, ] [package.dependencies] click = ">=7.0" colorama = {version = ">=0.4", markers = "platform_system == \"Windows\""} ghp-import = ">=1.0" -importlib-metadata = {version = ">=4.3", markers = "python_version < \"3.10\""} +importlib-metadata = {version = ">=4.4", markers = "python_version < \"3.10\""} jinja2 = ">=2.11.1" -markdown = ">=3.2.1" +markdown = ">=3.3.6" markupsafe = ">=2.0.1" mergedeep = ">=1.3.4" +mkdocs-get-deps = ">=0.2.0" packaging = ">=20.5" pathspec = ">=0.11.1" -platformdirs = ">=2.2.0" pyyaml = ">=5.1" pyyaml-env-tag = ">=0.1" watchdog = ">=2.0" [package.extras] i18n = ["babel (>=2.9.0)"] -min-versions = ["babel (==2.9.0)", "click (==7.0)", "colorama (==0.4)", "ghp-import (==1.0)", "importlib-metadata (==4.3)", "jinja2 (==2.11.1)", "markdown (==3.2.1)", "markupsafe (==2.0.1)", "mergedeep (==1.3.4)", "packaging (==20.5)", "pathspec (==0.11.1)", "platformdirs (==2.2.0)", "pyyaml (==5.1)", "pyyaml-env-tag (==0.1)", "typing-extensions (==3.10)", "watchdog (==2.0)"] +min-versions = ["babel (==2.9.0)", "click (==7.0)", "colorama (==0.4)", "ghp-import (==1.0)", "importlib-metadata (==4.4)", "jinja2 (==2.11.1)", "markdown (==3.3.6)", "markupsafe (==2.0.1)", "mergedeep (==1.3.4)", "mkdocs-get-deps (==0.2.0)", "packaging (==20.5)", "pathspec (==0.11.1)", "pyyaml (==5.1)", "pyyaml-env-tag (==0.1)", "watchdog (==2.0)"] [[package]] name = "mkdocs-autorefs" @@ -2127,6 +2129,23 @@ files = [ Markdown = ">=3.3" mkdocs = ">=1.1" +[[package]] +name = "mkdocs-get-deps" +version = "0.2.0" +description = "MkDocs extension that lists all dependencies according to a mkdocs.yml file" +optional = false +python-versions = ">=3.8" +files = [ + {file = "mkdocs_get_deps-0.2.0-py3-none-any.whl", hash = "sha256:2bf11d0b133e77a0dd036abeeb06dec8775e46efa526dc70667d8863eefc6134"}, + {file = "mkdocs_get_deps-0.2.0.tar.gz", hash = "sha256:162b3d129c7fad9b19abfdcb9c1458a651628e4b1dea628ac68790fb3061c60c"}, +] + +[package.dependencies] +importlib-metadata = {version = ">=4.3", markers = "python_version < \"3.10\""} +mergedeep = ">=1.3.4" +platformdirs = ">=2.2.0" +pyyaml = ">=5.1" + [[package]] name = "mkdocs-git-committers-plugin-2" version = "2.3.0" @@ -2145,13 +2164,13 @@ requests = "*" [[package]] name = "mkdocs-git-revision-date-localized-plugin" -version = "1.2.4" +version = "1.2.6" description = "Mkdocs plugin that enables displaying the localized date of the last git modification of a markdown file." optional = false python-versions = ">=3.8" files = [ - {file = "mkdocs-git-revision-date-localized-plugin-1.2.4.tar.gz", hash = "sha256:08fd0c6f33c8da9e00daf40f7865943113b3879a1c621b2bbf0fa794ffe997d3"}, - {file = "mkdocs_git_revision_date_localized_plugin-1.2.4-py3-none-any.whl", hash = "sha256:1f94eb510862ef94e982a2910404fa17a1657ecf29f45a07b0f438c00767fc85"}, + {file = "mkdocs_git_revision_date_localized_plugin-1.2.6-py3-none-any.whl", hash = "sha256:f015cb0f3894a39b33447b18e270ae391c4e25275cac5a626e80b243784e2692"}, + {file = "mkdocs_git_revision_date_localized_plugin-1.2.6.tar.gz", hash = "sha256:e432942ce4ee8aa9b9f4493e993dee9d2cc08b3ea2b40a3d6b03ca0f2a4bcaa2"}, ] [package.dependencies] @@ -2180,13 +2199,13 @@ pygments = ">2.12.0" [[package]] name = "mkdocs-material" -version = "9.5.18" +version = "9.5.25" description = "Documentation that simply works" optional = false python-versions = ">=3.8" files = [ - {file = "mkdocs_material-9.5.18-py3-none-any.whl", hash = "sha256:1e0e27fc9fe239f9064318acf548771a4629d5fd5dfd45444fd80a953fe21eb4"}, - {file = "mkdocs_material-9.5.18.tar.gz", hash = "sha256:a43f470947053fa2405c33995f282d24992c752a50114f23f30da9d8d0c57e62"}, + {file = "mkdocs_material-9.5.25-py3-none-any.whl", hash = "sha256:68fdab047a0b9bfbefe79ce267e8a7daaf5128bcf7867065fcd201ee335fece1"}, + {file = "mkdocs_material-9.5.25.tar.gz", hash = "sha256:d0662561efb725b712207e0ee01f035ca15633f29a64628e24f01ec99d7078f4"}, ] [package.dependencies] @@ -2195,7 +2214,7 @@ cairosvg = {version = ">=2.6,<3.0", optional = true, markers = "extra == \"imagi colorama = ">=0.4,<1.0" jinja2 = ">=3.0,<4.0" markdown = ">=3.2,<4.0" -mkdocs = ">=1.5.3,<1.6.0" +mkdocs = ">=1.6,<2.0" mkdocs-material-extensions = ">=1.3,<2.0" paginate = ">=0.5,<1.0" pillow = {version = ">=10.2,<11.0", optional = true, markers = "extra == \"imaging\""} @@ -2222,13 +2241,13 @@ files = [ [[package]] name = "mkdocstrings" -version = "0.24.3" +version = "0.25.1" description = "Automatic documentation from sources, for MkDocs." optional = false python-versions = ">=3.8" files = [ - {file = "mkdocstrings-0.24.3-py3-none-any.whl", hash = "sha256:5c9cf2a32958cd161d5428699b79c8b0988856b0d4a8c5baf8395fc1bf4087c3"}, - {file = "mkdocstrings-0.24.3.tar.gz", hash = "sha256:f327b234eb8d2551a306735436e157d0a22d45f79963c60a8b585d5f7a94c1d2"}, + {file = "mkdocstrings-0.25.1-py3-none-any.whl", hash = "sha256:da01fcc2670ad61888e8fe5b60afe9fee5781017d67431996832d63e887c2e51"}, + {file = "mkdocstrings-0.25.1.tar.gz", hash = "sha256:c3a2515f31577f311a9ee58d089e4c51fc6046dbd9e9b4c3de4c3194667fe9bf"}, ] [package.dependencies] @@ -2277,38 +2296,38 @@ files = [ [[package]] name = "mypy" -version = "1.9.0" +version = "1.10.0" description = "Optional static typing for Python" optional = false python-versions = ">=3.8" files = [ - {file = "mypy-1.9.0-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:f8a67616990062232ee4c3952f41c779afac41405806042a8126fe96e098419f"}, - {file = "mypy-1.9.0-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:d357423fa57a489e8c47b7c85dfb96698caba13d66e086b412298a1a0ea3b0ed"}, - {file = "mypy-1.9.0-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:49c87c15aed320de9b438ae7b00c1ac91cd393c1b854c2ce538e2a72d55df150"}, - {file = "mypy-1.9.0-cp310-cp310-musllinux_1_1_x86_64.whl", hash = "sha256:48533cdd345c3c2e5ef48ba3b0d3880b257b423e7995dada04248725c6f77374"}, - {file = "mypy-1.9.0-cp310-cp310-win_amd64.whl", hash = "sha256:4d3dbd346cfec7cb98e6cbb6e0f3c23618af826316188d587d1c1bc34f0ede03"}, - {file = "mypy-1.9.0-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:653265f9a2784db65bfca694d1edd23093ce49740b2244cde583aeb134c008f3"}, - {file = "mypy-1.9.0-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:3a3c007ff3ee90f69cf0a15cbcdf0995749569b86b6d2f327af01fd1b8aee9dc"}, - {file = "mypy-1.9.0-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:2418488264eb41f69cc64a69a745fad4a8f86649af4b1041a4c64ee61fc61129"}, - {file = "mypy-1.9.0-cp311-cp311-musllinux_1_1_x86_64.whl", hash = "sha256:68edad3dc7d70f2f17ae4c6c1b9471a56138ca22722487eebacfd1eb5321d612"}, - {file = "mypy-1.9.0-cp311-cp311-win_amd64.whl", hash = "sha256:85ca5fcc24f0b4aeedc1d02f93707bccc04733f21d41c88334c5482219b1ccb3"}, - {file = "mypy-1.9.0-cp312-cp312-macosx_10_9_x86_64.whl", hash = "sha256:aceb1db093b04db5cd390821464504111b8ec3e351eb85afd1433490163d60cd"}, - {file = "mypy-1.9.0-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:0235391f1c6f6ce487b23b9dbd1327b4ec33bb93934aa986efe8a9563d9349e6"}, - {file = "mypy-1.9.0-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:d4d5ddc13421ba3e2e082a6c2d74c2ddb3979c39b582dacd53dd5d9431237185"}, - {file = "mypy-1.9.0-cp312-cp312-musllinux_1_1_x86_64.whl", hash = "sha256:190da1ee69b427d7efa8aa0d5e5ccd67a4fb04038c380237a0d96829cb157913"}, - {file = "mypy-1.9.0-cp312-cp312-win_amd64.whl", hash = "sha256:fe28657de3bfec596bbeef01cb219833ad9d38dd5393fc649f4b366840baefe6"}, - {file = "mypy-1.9.0-cp38-cp38-macosx_10_9_x86_64.whl", hash = "sha256:e54396d70be04b34f31d2edf3362c1edd023246c82f1730bbf8768c28db5361b"}, - {file = "mypy-1.9.0-cp38-cp38-macosx_11_0_arm64.whl", hash = "sha256:5e6061f44f2313b94f920e91b204ec600982961e07a17e0f6cd83371cb23f5c2"}, - {file = "mypy-1.9.0-cp38-cp38-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:81a10926e5473c5fc3da8abb04119a1f5811a236dc3a38d92015cb1e6ba4cb9e"}, - {file = "mypy-1.9.0-cp38-cp38-musllinux_1_1_x86_64.whl", hash = "sha256:b685154e22e4e9199fc95f298661deea28aaede5ae16ccc8cbb1045e716b3e04"}, - {file = "mypy-1.9.0-cp38-cp38-win_amd64.whl", hash = "sha256:5d741d3fc7c4da608764073089e5f58ef6352bedc223ff58f2f038c2c4698a89"}, - {file = "mypy-1.9.0-cp39-cp39-macosx_10_9_x86_64.whl", hash = "sha256:587ce887f75dd9700252a3abbc9c97bbe165a4a630597845c61279cf32dfbf02"}, - {file = "mypy-1.9.0-cp39-cp39-macosx_11_0_arm64.whl", hash = "sha256:f88566144752999351725ac623471661c9d1cd8caa0134ff98cceeea181789f4"}, - {file = "mypy-1.9.0-cp39-cp39-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:61758fabd58ce4b0720ae1e2fea5cfd4431591d6d590b197775329264f86311d"}, - {file = "mypy-1.9.0-cp39-cp39-musllinux_1_1_x86_64.whl", hash = "sha256:e49499be624dead83927e70c756970a0bc8240e9f769389cdf5714b0784ca6bf"}, - {file = "mypy-1.9.0-cp39-cp39-win_amd64.whl", hash = "sha256:571741dc4194b4f82d344b15e8837e8c5fcc462d66d076748142327626a1b6e9"}, - {file = "mypy-1.9.0-py3-none-any.whl", hash = "sha256:a260627a570559181a9ea5de61ac6297aa5af202f06fd7ab093ce74e7181e43e"}, - {file = "mypy-1.9.0.tar.gz", hash = "sha256:3cc5da0127e6a478cddd906068496a97a7618a21ce9b54bde5bf7e539c7af974"}, + {file = "mypy-1.10.0-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:da1cbf08fb3b851ab3b9523a884c232774008267b1f83371ace57f412fe308c2"}, + {file = "mypy-1.10.0-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:12b6bfc1b1a66095ab413160a6e520e1dc076a28f3e22f7fb25ba3b000b4ef99"}, + {file = "mypy-1.10.0-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:9e36fb078cce9904c7989b9693e41cb9711e0600139ce3970c6ef814b6ebc2b2"}, + {file = "mypy-1.10.0-cp310-cp310-musllinux_1_1_x86_64.whl", hash = "sha256:2b0695d605ddcd3eb2f736cd8b4e388288c21e7de85001e9f85df9187f2b50f9"}, + {file = "mypy-1.10.0-cp310-cp310-win_amd64.whl", hash = "sha256:cd777b780312ddb135bceb9bc8722a73ec95e042f911cc279e2ec3c667076051"}, + {file = "mypy-1.10.0-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:3be66771aa5c97602f382230165b856c231d1277c511c9a8dd058be4784472e1"}, + {file = "mypy-1.10.0-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:8b2cbaca148d0754a54d44121b5825ae71868c7592a53b7292eeb0f3fdae95ee"}, + {file = "mypy-1.10.0-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:1ec404a7cbe9fc0e92cb0e67f55ce0c025014e26d33e54d9e506a0f2d07fe5de"}, + {file = "mypy-1.10.0-cp311-cp311-musllinux_1_1_x86_64.whl", hash = "sha256:e22e1527dc3d4aa94311d246b59e47f6455b8729f4968765ac1eacf9a4760bc7"}, + {file = "mypy-1.10.0-cp311-cp311-win_amd64.whl", hash = "sha256:a87dbfa85971e8d59c9cc1fcf534efe664d8949e4c0b6b44e8ca548e746a8d53"}, + {file = "mypy-1.10.0-cp312-cp312-macosx_10_9_x86_64.whl", hash = "sha256:a781f6ad4bab20eef8b65174a57e5203f4be627b46291f4589879bf4e257b97b"}, + {file = "mypy-1.10.0-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:b808e12113505b97d9023b0b5e0c0705a90571c6feefc6f215c1df9381256e30"}, + {file = "mypy-1.10.0-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:8f55583b12156c399dce2df7d16f8a5095291354f1e839c252ec6c0611e86e2e"}, + {file = "mypy-1.10.0-cp312-cp312-musllinux_1_1_x86_64.whl", hash = "sha256:4cf18f9d0efa1b16478c4c129eabec36148032575391095f73cae2e722fcf9d5"}, + {file = "mypy-1.10.0-cp312-cp312-win_amd64.whl", hash = "sha256:bc6ac273b23c6b82da3bb25f4136c4fd42665f17f2cd850771cb600bdd2ebeda"}, + {file = "mypy-1.10.0-cp38-cp38-macosx_10_9_x86_64.whl", hash = "sha256:9fd50226364cd2737351c79807775136b0abe084433b55b2e29181a4c3c878c0"}, + {file = "mypy-1.10.0-cp38-cp38-macosx_11_0_arm64.whl", hash = "sha256:f90cff89eea89273727d8783fef5d4a934be2fdca11b47def50cf5d311aff727"}, + {file = "mypy-1.10.0-cp38-cp38-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:fcfc70599efde5c67862a07a1aaf50e55bce629ace26bb19dc17cece5dd31ca4"}, + {file = "mypy-1.10.0-cp38-cp38-musllinux_1_1_x86_64.whl", hash = "sha256:075cbf81f3e134eadaf247de187bd604748171d6b79736fa9b6c9685b4083061"}, + {file = "mypy-1.10.0-cp38-cp38-win_amd64.whl", hash = "sha256:3f298531bca95ff615b6e9f2fc0333aae27fa48052903a0ac90215021cdcfa4f"}, + {file = "mypy-1.10.0-cp39-cp39-macosx_10_9_x86_64.whl", hash = "sha256:fa7ef5244615a2523b56c034becde4e9e3f9b034854c93639adb667ec9ec2976"}, + {file = "mypy-1.10.0-cp39-cp39-macosx_11_0_arm64.whl", hash = "sha256:3236a4c8f535a0631f85f5fcdffba71c7feeef76a6002fcba7c1a8e57c8be1ec"}, + {file = "mypy-1.10.0-cp39-cp39-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:4a2b5cdbb5dd35aa08ea9114436e0d79aceb2f38e32c21684dcf8e24e1e92821"}, + {file = "mypy-1.10.0-cp39-cp39-musllinux_1_1_x86_64.whl", hash = "sha256:92f93b21c0fe73dc00abf91022234c79d793318b8a96faac147cd579c1671746"}, + {file = "mypy-1.10.0-cp39-cp39-win_amd64.whl", hash = "sha256:28d0e038361b45f099cc086d9dd99c15ff14d0188f44ac883010e172ce86c38a"}, + {file = "mypy-1.10.0-py3-none-any.whl", hash = "sha256:f8c083976eb530019175aabadb60921e73b4f45736760826aa1689dda8208aee"}, + {file = "mypy-1.10.0.tar.gz", hash = "sha256:3d087fcbec056c4ee34974da493a826ce316947485cef3901f511848e687c131"}, ] [package.dependencies] @@ -2357,13 +2376,13 @@ test = ["flaky", "ipykernel (>=6.19.3)", "ipython", "ipywidgets", "nbconvert (>= [[package]] name = "nbconvert" -version = "7.16.3" +version = "7.16.4" description = "Converting Jupyter Notebooks (.ipynb files) to other formats. Output formats include asciidoc, html, latex, markdown, pdf, py, rst, script. nbconvert can be used both as a Python library (`import nbconvert`) or as a command line tool (invoked as `jupyter nbconvert ...`)." optional = false python-versions = ">=3.8" files = [ - {file = "nbconvert-7.16.3-py3-none-any.whl", hash = "sha256:ddeff14beeeedf3dd0bc506623e41e4507e551736de59df69a91f86700292b3b"}, - {file = "nbconvert-7.16.3.tar.gz", hash = "sha256:a6733b78ce3d47c3f85e504998495b07e6ea9cf9bf6ec1c98dda63ec6ad19142"}, + {file = "nbconvert-7.16.4-py3-none-any.whl", hash = "sha256:05873c620fe520b6322bf8a5ad562692343fe3452abda5765c7a34b7d1aa3eb3"}, + {file = "nbconvert-7.16.4.tar.gz", hash = "sha256:86ca91ba266b0a448dc96fa6c5b9d98affabde2867b363258703536807f9f7f4"}, ] [package.dependencies] @@ -2385,9 +2404,9 @@ tinycss2 = "*" traitlets = ">=5.1" [package.extras] -all = ["nbconvert[docs,qtpdf,serve,test,webpdf]"] +all = ["flaky", "ipykernel", "ipython", "ipywidgets (>=7.5)", "myst-parser", "nbsphinx (>=0.2.12)", "playwright", "pydata-sphinx-theme", "pyqtwebengine (>=5.15)", "pytest (>=7)", "sphinx (==5.0.2)", "sphinxcontrib-spelling", "tornado (>=6.1)"] docs = ["ipykernel", "ipython", "myst-parser", "nbsphinx (>=0.2.12)", "pydata-sphinx-theme", "sphinx (==5.0.2)", "sphinxcontrib-spelling"] -qtpdf = ["nbconvert[qtpng]"] +qtpdf = ["pyqtwebengine (>=5.15)"] qtpng = ["pyqtwebengine (>=5.15)"] serve = ["tornado (>=6.1)"] test = ["flaky", "ipykernel", "ipywidgets (>=7.5)", "pytest (>=7)"] @@ -2466,26 +2485,26 @@ setuptools = "*" [[package]] name = "notebook" -version = "7.1.3" +version = "7.2.0" description = "Jupyter Notebook - A web-based notebook environment for interactive computing" optional = false python-versions = ">=3.8" files = [ - {file = "notebook-7.1.3-py3-none-any.whl", hash = "sha256:919b911e59f41f6e3857ce93c9d93535ba66bb090059712770e5968c07e1004d"}, - {file = "notebook-7.1.3.tar.gz", hash = "sha256:41fcebff44cf7bb9377180808bcbae066629b55d8c7722f1ebbe75ca44f9cfc1"}, + {file = "notebook-7.2.0-py3-none-any.whl", hash = "sha256:b4752d7407d6c8872fc505df0f00d3cae46e8efb033b822adacbaa3f1f3ce8f5"}, + {file = "notebook-7.2.0.tar.gz", hash = "sha256:34a2ba4b08ad5d19ec930db7484fb79746a1784be9e1a5f8218f9af8656a141f"}, ] [package.dependencies] jupyter-server = ">=2.4.0,<3" -jupyterlab = ">=4.1.1,<4.2" -jupyterlab-server = ">=2.22.1,<3" +jupyterlab = ">=4.2.0,<4.3" +jupyterlab-server = ">=2.27.1,<3" notebook-shim = ">=0.2,<0.3" tornado = ">=6.2.0" [package.extras] dev = ["hatch", "pre-commit"] docs = ["myst-parser", "nbsphinx", "pydata-sphinx-theme", "sphinx (>=1.3.6)", "sphinxcontrib-github-alt", "sphinxcontrib-spelling"] -test = ["importlib-resources (>=5.0)", "ipykernel", "jupyter-server[test] (>=2.4.0,<3)", "jupyterlab-server[test] (>=2.22.1,<3)", "nbval", "pytest (>=7.0)", "pytest-console-scripts", "pytest-timeout", "pytest-tornasync", "requests"] +test = ["importlib-resources (>=5.0)", "ipykernel", "jupyter-server[test] (>=2.4.0,<3)", "jupyterlab-server[test] (>=2.27.1,<3)", "nbval", "pytest (>=7.0)", "pytest-console-scripts", "pytest-timeout", "pytest-tornasync", "requests"] [[package]] name = "notebook-shim" @@ -2815,13 +2834,13 @@ test = ["appdirs (==1.4.4)", "covdefaults (>=2.3)", "pytest (>=7.4.3)", "pytest- [[package]] name = "pluggy" -version = "1.4.0" +version = "1.5.0" description = "plugin and hook calling mechanisms for python" optional = false python-versions = ">=3.8" files = [ - {file = "pluggy-1.4.0-py3-none-any.whl", hash = "sha256:7db9f7b503d67d1c5b95f59773ebb58a8c1c288129a88665838012cfb07b8981"}, - {file = "pluggy-1.4.0.tar.gz", hash = "sha256:8c85c2876142a764e5b7548e7d9a0e0ddb46f5185161049a79b7e974454223be"}, + {file = "pluggy-1.5.0-py3-none-any.whl", hash = "sha256:44e1ad92c8ca002de6377e165f3e0f1be63266ab4d554740532335b9d75ea669"}, + {file = "pluggy-1.5.0.tar.gz", hash = "sha256:2cffa88e94fdc978c4c574f15f9e59b7f4201d439195c3715ca9e2486f1d0cf1"}, ] [package.extras] @@ -3020,13 +3039,13 @@ tomli = {version = ">=1.1.0", markers = "python_version < \"3.11\""} [[package]] name = "pytest" -version = "8.1.1" +version = "8.2.2" description = "pytest: simple powerful testing with Python" optional = false python-versions = ">=3.8" files = [ - {file = "pytest-8.1.1-py3-none-any.whl", hash = "sha256:2a8386cfc11fa9d2c50ee7b2a57e7d898ef90470a7a34c4b949ff59662bb78b7"}, - {file = "pytest-8.1.1.tar.gz", hash = "sha256:ac978141a75948948817d360297b7aae0fcb9d6ff6bc9ec6d514b85d5a65c044"}, + {file = "pytest-8.2.2-py3-none-any.whl", hash = "sha256:c434598117762e2bd304e526244f67bf66bbd7b5d6cf22138be51ff661980343"}, + {file = "pytest-8.2.2.tar.gz", hash = "sha256:de4bb8104e201939ccdc688b27a89a7be2079b22e2bd2b07f806b6ba71117977"}, ] [package.dependencies] @@ -3034,11 +3053,11 @@ colorama = {version = "*", markers = "sys_platform == \"win32\""} exceptiongroup = {version = ">=1.0.0rc8", markers = "python_version < \"3.11\""} iniconfig = "*" packaging = "*" -pluggy = ">=1.4,<2.0" +pluggy = ">=1.5,<2.0" tomli = {version = ">=1", markers = "python_version < \"3.11\""} [package.extras] -testing = ["argcomplete", "attrs (>=19.2)", "hypothesis (>=3.56)", "mock", "pygments (>=2.7.2)", "requests", "setuptools", "xmlschema"] +dev = ["argcomplete", "attrs (>=19.2)", "hypothesis (>=3.56)", "mock", "pygments (>=2.7.2)", "requests", "setuptools", "xmlschema"] [[package]] name = "python-dateutil" @@ -3442,13 +3461,13 @@ files = [ [[package]] name = "requests" -version = "2.31.0" +version = "2.32.3" description = "Python HTTP for Humans." optional = false -python-versions = ">=3.7" +python-versions = ">=3.8" files = [ - {file = "requests-2.31.0-py3-none-any.whl", hash = "sha256:58cd2187c01e70e6e26505bca751777aa9f2ee0b7f4300988b709f44e013003f"}, - {file = "requests-2.31.0.tar.gz", hash = "sha256:942c5a758f98d790eaed1a29cb6eefc7ffb0d1cf7af05c3d2791656dbd6ad1e1"}, + {file = "requests-2.32.3-py3-none-any.whl", hash = "sha256:70761cfe03c773ceb22aa2f671b4757976145175cdfca038c02654d061d6dcc6"}, + {file = "requests-2.32.3.tar.gz", hash = "sha256:55365417734eb18255590a9ff9eb97e9e1da868d4ccd6402399eaf68af20a760"}, ] [package.dependencies] @@ -3643,28 +3662,28 @@ files = [ [[package]] name = "ruff" -version = "0.4.1" +version = "0.4.7" description = "An extremely fast Python linter and code formatter, written in Rust." optional = false python-versions = ">=3.7" files = [ - {file = "ruff-0.4.1-py3-none-macosx_10_12_x86_64.macosx_11_0_arm64.macosx_10_12_universal2.whl", hash = "sha256:2d9ef6231e3fbdc0b8c72404a1a0c46fd0dcea84efca83beb4681c318ea6a953"}, - {file = "ruff-0.4.1-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:9485f54a7189e6f7433e0058cf8581bee45c31a25cd69009d2a040d1bd4bfaef"}, - {file = "ruff-0.4.1-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:d2921ac03ce1383e360e8a95442ffb0d757a6a7ddd9a5be68561a671e0e5807e"}, - {file = "ruff-0.4.1-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:eec8d185fe193ad053eda3a6be23069e0c8ba8c5d20bc5ace6e3b9e37d246d3f"}, - {file = "ruff-0.4.1-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:baa27d9d72a94574d250f42b7640b3bd2edc4c58ac8ac2778a8c82374bb27984"}, - {file = "ruff-0.4.1-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:f1ee41580bff1a651339eb3337c20c12f4037f6110a36ae4a2d864c52e5ef954"}, - {file = "ruff-0.4.1-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:0926cefb57fc5fced629603fbd1a23d458b25418681d96823992ba975f050c2b"}, - {file = "ruff-0.4.1-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:2c6e37f2e3cd74496a74af9a4fa67b547ab3ca137688c484749189bf3a686ceb"}, - {file = "ruff-0.4.1-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:efd703a5975ac1998c2cc5e9494e13b28f31e66c616b0a76e206de2562e0843c"}, - {file = "ruff-0.4.1-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:b92f03b4aa9fa23e1799b40f15f8b95cdc418782a567d6c43def65e1bbb7f1cf"}, - {file = "ruff-0.4.1-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:1c859f294f8633889e7d77de228b203eb0e9a03071b72b5989d89a0cf98ee262"}, - {file = "ruff-0.4.1-py3-none-musllinux_1_2_i686.whl", hash = "sha256:b34510141e393519a47f2d7b8216fec747ea1f2c81e85f076e9f2910588d4b64"}, - {file = "ruff-0.4.1-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:6e68d248ed688b9d69fd4d18737edcbb79c98b251bba5a2b031ce2470224bdf9"}, - {file = "ruff-0.4.1-py3-none-win32.whl", hash = "sha256:b90506f3d6d1f41f43f9b7b5ff845aeefabed6d2494307bc7b178360a8805252"}, - {file = "ruff-0.4.1-py3-none-win_amd64.whl", hash = "sha256:c7d391e5936af5c9e252743d767c564670dc3889aff460d35c518ee76e4b26d7"}, - {file = "ruff-0.4.1-py3-none-win_arm64.whl", hash = "sha256:a1eaf03d87e6a7cd5e661d36d8c6e874693cb9bc3049d110bc9a97b350680c43"}, - {file = "ruff-0.4.1.tar.gz", hash = "sha256:d592116cdbb65f8b1b7e2a2b48297eb865f6bdc20641879aa9d7b9c11d86db79"}, + {file = "ruff-0.4.7-py3-none-macosx_10_12_x86_64.whl", hash = "sha256:e089371c67892a73b6bb1525608e89a2aca1b77b5440acf7a71dda5dac958f9e"}, + {file = "ruff-0.4.7-py3-none-macosx_11_0_arm64.whl", hash = "sha256:10f973d521d910e5f9c72ab27e409e839089f955be8a4c8826601a6323a89753"}, + {file = "ruff-0.4.7-py3-none-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:59c3d110970001dfa494bcd95478e62286c751126dfb15c3c46e7915fc49694f"}, + {file = "ruff-0.4.7-py3-none-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:fa9773c6c00f4958f73b317bc0fd125295110c3776089f6ef318f4b775f0abe4"}, + {file = "ruff-0.4.7-py3-none-manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:07fc80bbb61e42b3b23b10fda6a2a0f5a067f810180a3760c5ef1b456c21b9db"}, + {file = "ruff-0.4.7-py3-none-manylinux_2_17_ppc64.manylinux2014_ppc64.whl", hash = "sha256:fa4dafe3fe66d90e2e2b63fa1591dd6e3f090ca2128daa0be33db894e6c18648"}, + {file = "ruff-0.4.7-py3-none-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:a7c0083febdec17571455903b184a10026603a1de078428ba155e7ce9358c5f6"}, + {file = "ruff-0.4.7-py3-none-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:ad1b20e66a44057c326168437d680a2166c177c939346b19c0d6b08a62a37589"}, + {file = "ruff-0.4.7-py3-none-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:cbf5d818553add7511c38b05532d94a407f499d1a76ebb0cad0374e32bc67202"}, + {file = "ruff-0.4.7-py3-none-musllinux_1_2_aarch64.whl", hash = "sha256:50e9651578b629baec3d1513b2534de0ac7ed7753e1382272b8d609997e27e83"}, + {file = "ruff-0.4.7-py3-none-musllinux_1_2_armv7l.whl", hash = "sha256:8874a9df7766cb956b218a0a239e0a5d23d9e843e4da1e113ae1d27ee420877a"}, + {file = "ruff-0.4.7-py3-none-musllinux_1_2_i686.whl", hash = "sha256:b9de9a6e49f7d529decd09381c0860c3f82fa0b0ea00ea78409b785d2308a567"}, + {file = "ruff-0.4.7-py3-none-musllinux_1_2_x86_64.whl", hash = "sha256:13a1768b0691619822ae6d446132dbdfd568b700ecd3652b20d4e8bc1e498f78"}, + {file = "ruff-0.4.7-py3-none-win32.whl", hash = "sha256:769e5a51df61e07e887b81e6f039e7ed3573316ab7dd9f635c5afaa310e4030e"}, + {file = "ruff-0.4.7-py3-none-win_amd64.whl", hash = "sha256:9e3ab684ad403a9ed1226894c32c3ab9c2e0718440f6f50c7c5829932bc9e054"}, + {file = "ruff-0.4.7-py3-none-win_arm64.whl", hash = "sha256:10f2204b9a613988e3484194c2c9e96a22079206b22b787605c255f130db5ed7"}, + {file = "ruff-0.4.7.tar.gz", hash = "sha256:2331d2b051dc77a289a653fcc6a42cce357087c5975738157cd966590b18b5e1"}, ] [[package]] @@ -3896,17 +3915,6 @@ webencodings = ">=0.4" doc = ["sphinx", "sphinx_rtd_theme"] test = ["flake8", "isort", "pytest"] -[[package]] -name = "toml" -version = "0.10.2" -description = "Python Library for Tom's Obvious, Minimal Language" -optional = false -python-versions = ">=2.6, !=3.0.*, !=3.1.*, !=3.2.*" -files = [ - {file = "toml-0.10.2-py2.py3-none-any.whl", hash = "sha256:806143ae5bfb6a3c6e736a764057db0e6a0e05e338b5630894a5f779cabb4f9b"}, - {file = "toml-0.10.2.tar.gz", hash = "sha256:b3bda1d108d5dd99f4a20d24d9c348e91c4db7ab1b749200bded2f839ccbe68f"}, -] - [[package]] name = "tomli" version = "2.0.1" @@ -3940,13 +3948,13 @@ files = [ [[package]] name = "tox" -version = "4.14.2" +version = "4.15.0" description = "tox is a generic virtualenv management and test command line tool" optional = false python-versions = ">=3.8" files = [ - {file = "tox-4.14.2-py3-none-any.whl", hash = "sha256:2900c4eb7b716af4a928a7fdc2ed248ad6575294ed7cfae2ea41203937422847"}, - {file = "tox-4.14.2.tar.gz", hash = "sha256:0defb44f6dafd911b61788325741cc6b2e12ea71f987ac025ad4d649f1f1a104"}, + {file = "tox-4.15.0-py3-none-any.whl", hash = "sha256:300055f335d855b2ab1b12c5802de7f62a36d4fd53f30bd2835f6a201dda46ea"}, + {file = "tox-4.15.0.tar.gz", hash = "sha256:7a0beeef166fbe566f54f795b4906c31b428eddafc0102ac00d20998dd1933f6"}, ] [package.dependencies] @@ -3967,13 +3975,13 @@ testing = ["build[virtualenv] (>=1.0.3)", "covdefaults (>=2.3)", "detect-test-po [[package]] name = "tqdm" -version = "4.66.2" +version = "4.66.4" description = "Fast, Extensible Progress Meter" optional = true python-versions = ">=3.7" files = [ - {file = "tqdm-4.66.2-py3-none-any.whl", hash = "sha256:1ee4f8a893eb9bef51c6e35730cebf234d5d0b6bd112b0271e10ed7c24a02bd9"}, - {file = "tqdm-4.66.2.tar.gz", hash = "sha256:6cd52cdf0fef0e0f543299cfc96fec90d7b8a7e88745f411ec33eb44d5ed3531"}, + {file = "tqdm-4.66.4-py3-none-any.whl", hash = "sha256:b75ca56b413b030bc3f00af51fd2c1a1a5eac6a0c1cca83cbb37a5c52abce644"}, + {file = "tqdm-4.66.4.tar.gz", hash = "sha256:e4d936c9de8727928f3be6079590e97d9abfe8d39a590be678eb5919ffc186bb"}, ] [package.dependencies] @@ -4002,13 +4010,13 @@ test = ["argcomplete (>=3.0.3)", "mypy (>=1.7.0)", "pre-commit", "pytest (>=7.0, [[package]] name = "twine" -version = "5.0.0" +version = "5.1.0" description = "Collection of utilities for publishing packages on PyPI" optional = false python-versions = ">=3.8" files = [ - {file = "twine-5.0.0-py3-none-any.whl", hash = "sha256:a262933de0b484c53408f9edae2e7821c1c45a3314ff2df9bdd343aa7ab8edc0"}, - {file = "twine-5.0.0.tar.gz", hash = "sha256:89b0cc7d370a4b66421cc6102f269aa910fe0f1861c124f573cf2ddedbc10cf4"}, + {file = "twine-5.1.0-py3-none-any.whl", hash = "sha256:fe1d814395bfe50cfbe27783cb74efe93abeac3f66deaeb6c8390e4e92bacb43"}, + {file = "twine-5.1.0.tar.gz", hash = "sha256:4d74770c88c4fcaf8134d2a6a9d863e40f08255ff7d8e2acb3cbbd57d25f6e9d"}, ] [package.dependencies] @@ -4219,13 +4227,13 @@ test = ["pytest (>=6.0.0)", "setuptools (>=65)"] [[package]] name = "widgetsnbextension" -version = "4.0.10" +version = "4.0.11" description = "Jupyter interactive widgets for Jupyter Notebook" optional = false python-versions = ">=3.7" files = [ - {file = "widgetsnbextension-4.0.10-py3-none-any.whl", hash = "sha256:d37c3724ec32d8c48400a435ecfa7d3e259995201fbefa37163124a9fcb393cc"}, - {file = "widgetsnbextension-4.0.10.tar.gz", hash = "sha256:64196c5ff3b9a9183a8e699a4227fb0b7002f252c814098e66c4d1cd0644688f"}, + {file = "widgetsnbextension-4.0.11-py3-none-any.whl", hash = "sha256:55d4d6949d100e0d08b94948a42efc3ed6dfdc0e9468b2c4b128c9a2ce3a7a36"}, + {file = "widgetsnbextension-4.0.11.tar.gz", hash = "sha256:8b22a8f1910bfd188e596fe7fc05dcbd87e810c8a4ba010bdb3da86637398474"}, ] [[package]] @@ -4250,4 +4258,4 @@ desktop = ["opencv-python"] [metadata] lock-version = "2.0" python-versions = "^3.8" -content-hash = "56ddae6824a9f28c9954badd4c642c57f687b099c6169f97fa0372e294500c17" +content-hash = "e3d79f6c93041323b04c7b45e93bb3c4198b21889044004af8a0485a6145a207" diff --git a/pyproject.toml b/pyproject.toml index de0df748..59d4176d 100644 --- a/pyproject.toml +++ b/pyproject.toml @@ -1,6 +1,6 @@ [tool.poetry] name = "supervision" -version = "0.20.0" +version = "0.21.0" description = "A set of easy-to-use utils that will come in handy in any Computer Vision project" authors = ["Piotr Skalski "] maintainers = ["Piotr Skalski "] @@ -42,8 +42,8 @@ pyyaml = ">=5.3" defusedxml = "^0.7.1" opencv-python = { version = ">=4.5.5.64", optional = true } opencv-python-headless = ">=4.5.5.64" -requests = { version = ">=2.26.0,<=2.31.0", optional = true } -tqdm = { version = ">=4.62.3,<=4.66.2", optional = true } +requests = { version = ">=2.26.0,<=2.32.3", optional = true } +tqdm = { version = ">=4.62.3,<=4.66.4", optional = true } pillow = ">=9.4" [tool.poetry.extras] @@ -67,7 +67,7 @@ nbconvert = "^7.14.2" [tool.poetry.group.docs.dependencies] mkdocs-material = {extras = ["imaging"], version = "^9.5.5"} -mkdocstrings = {extras = ["python"], version = ">=0.20,<0.25"} +mkdocstrings = {extras = ["python"], version = ">=0.20,<0.26"} mike = "^2.0.0" # For Documentation Development use Python 3.10 or above # Use Latest mkdocs-jupyter min 0.24.6 for Jupyter Notebook Theme support diff --git a/supervision/__init__.py b/supervision/__init__.py index bb526514..4f28d49f 100644 --- a/supervision/__init__.py +++ b/supervision/__init__.py @@ -23,6 +23,7 @@ from supervision.annotators.core import ( PercentageBarAnnotator, PixelateAnnotator, PolygonAnnotator, + RichLabelAnnotator, RoundBoxAnnotator, TraceAnnotator, TriangleAnnotator, @@ -34,9 +35,17 @@ from supervision.dataset.core import ( ClassificationDataset, DetectionDataset, ) +from supervision.dataset.utils import mask_to_rle, rle_to_mask from supervision.detection.annotate import BoxAnnotator from supervision.detection.core import Detections from supervision.detection.line_zone import LineZone, LineZoneAnnotator +from supervision.detection.lmm import LMM +from supervision.detection.overlap_filter import ( + OverlapFilter, + box_non_max_merge, + box_non_max_suppression, + mask_non_max_suppression, +) from supervision.detection.tools.csv_sink import CSVSink from supervision.detection.tools.inference_slicer import InferenceSlicer from supervision.detection.tools.json_sink import JSONSink @@ -44,14 +53,17 @@ from supervision.detection.tools.polygon_zone import PolygonZone, PolygonZoneAnn from supervision.detection.tools.smoother import DetectionsSmoother from supervision.detection.utils import ( box_iou_batch, - box_non_max_suppression, calculate_masks_centroids, + clip_boxes, + contains_holes, + contains_multiple_segments, filter_polygons_by_area, mask_iou_batch, - mask_non_max_suppression, mask_to_polygons, mask_to_xyxy, move_boxes, + move_masks, + pad_boxes, polygon_to_mask, polygon_to_xyxy, scale_boxes, @@ -69,7 +81,11 @@ from supervision.draw.utils import ( ) from supervision.geometry.core import Point, Position, Rect from supervision.geometry.utils import get_polygon_center -from supervision.keypoint.annotators import EdgeAnnotator, VertexAnnotator +from supervision.keypoint.annotators import ( + EdgeAnnotator, + VertexAnnotator, + VertexLabelAnnotator, +) from supervision.keypoint.core import KeyPoints from supervision.metrics.detection import ConfusionMatrix, MeanAveragePrecision from supervision.tracker.byte_tracker.core import ByteTrack diff --git a/supervision/annotators/core.py b/supervision/annotators/core.py index ac901862..1c0ad8af 100644 --- a/supervision/annotators/core.py +++ b/supervision/annotators/core.py @@ -3,9 +3,15 @@ from typing import List, Optional, Tuple, Union import cv2 import numpy as np +from PIL import Image, ImageDraw, ImageFont from supervision.annotators.base import BaseAnnotator, ImageType -from supervision.annotators.utils import ColorLookup, Trace, resolve_color +from supervision.annotators.utils import ( + ColorLookup, + Trace, + resolve_color, + resolve_text_background_xyxy, +) from supervision.config import CLASS_NAME_DATA_FIELD, ORIENTED_BOX_COORDINATES from supervision.detection.core import Detections from supervision.detection.utils import clip_boxes, mask_to_polygons @@ -936,59 +942,6 @@ class LabelAnnotator: self.text_anchor: Position = text_position self.color_lookup: ColorLookup = color_lookup - @staticmethod - def resolve_text_background_xyxy( - center_coordinates: Tuple[int, int], - text_wh: Tuple[int, int], - position: Position, - ) -> Tuple[int, int, int, int]: - center_x, center_y = center_coordinates - text_w, text_h = text_wh - - if position == Position.TOP_LEFT: - return center_x, center_y - text_h, center_x + text_w, center_y - elif position == Position.TOP_RIGHT: - return center_x - text_w, center_y - text_h, center_x, center_y - elif position == Position.TOP_CENTER: - return ( - center_x - text_w // 2, - center_y - text_h, - center_x + text_w // 2, - center_y, - ) - elif position == Position.CENTER or position == Position.CENTER_OF_MASS: - return ( - center_x - text_w // 2, - center_y - text_h // 2, - center_x + text_w // 2, - center_y + text_h // 2, - ) - elif position == Position.BOTTOM_LEFT: - return center_x, center_y, center_x + text_w, center_y + text_h - elif position == Position.BOTTOM_RIGHT: - return center_x - text_w, center_y, center_x, center_y + text_h - elif position == Position.BOTTOM_CENTER: - return ( - center_x - text_w // 2, - center_y, - center_x + text_w // 2, - center_y + text_h, - ) - elif position == Position.CENTER_LEFT: - return ( - center_x - text_w, - center_y - text_h // 2, - center_x, - center_y + text_h // 2, - ) - elif position == Position.CENTER_RIGHT: - return ( - center_x, - center_y - text_h // 2, - center_x + text_w, - center_y + text_h // 2, - ) - @convert_for_annotation_method def annotate( self, @@ -1056,9 +1009,11 @@ class LabelAnnotator: color=self.color, detections=detections, detection_idx=detection_idx, - color_lookup=self.color_lookup - if custom_color_lookup is None - else custom_color_lookup, + color_lookup=( + self.color_lookup + if custom_color_lookup is None + else custom_color_lookup + ), ) if labels is not None: @@ -1078,7 +1033,7 @@ class LabelAnnotator: )[0] text_w_padded = text_w + 2 * self.text_padding text_h_padded = text_h + 2 * self.text_padding - text_background_xyxy = self.resolve_text_background_xyxy( + text_background_xyxy = resolve_text_background_xyxy( center_coordinates=tuple(center_coordinates), text_wh=(text_w_padded, text_h_padded), position=self.text_anchor, @@ -1148,6 +1103,165 @@ class LabelAnnotator: return scene +class RichLabelAnnotator: + """ + A class for annotating labels on an image using provided detections, + with support for Unicode characters by using a custom font. + """ + + def __init__( + self, + color: Union[Color, ColorPalette] = ColorPalette.DEFAULT, + text_color: Color = Color.WHITE, + font_path: str = None, + font_size: int = 10, + text_padding: int = 10, + text_position: Position = Position.TOP_LEFT, + color_lookup: ColorLookup = ColorLookup.CLASS, + border_radius: int = 0, + ): + """ + Args: + color (Union[Color, ColorPalette]): The color or color palette to use for + annotating the text background. + text_color (Color): The color to use for the text. + font_path (str): Path to the font file (e.g., ".ttf" or ".otf") to use for + rendering text. If `None`, the default PIL font will be used. + font_size (int): Font size for the text. + text_padding (int): Padding around the text within its background box. + text_position (Position): Position of the text relative to the detection. + Possible values are defined in the `Position` enum. + color_lookup (ColorLookup): Strategy for mapping colors to annotations. + Options are `INDEX`, `CLASS`, `TRACK`. + border_radius (int): The radius to apply round edges. If the selected + value is higher than the lower dimension, width or height, is clipped. + """ + self.color = color + self.text_color = text_color + self.text_padding = text_padding + self.text_anchor = text_position + self.color_lookup = color_lookup + self.border_radius = border_radius + if font_path is not None: + try: + self.font = ImageFont.truetype(font_path, font_size) + except OSError: + print(f"Font path '{font_path}' not found. Using PIL's default font.") + self.font = ImageFont.load_default(size=font_size) + else: + self.font = ImageFont.load_default(size=font_size) + + def annotate( + self, + scene: ImageType, + detections: Detections, + labels: List[str] = None, + custom_color_lookup: Optional[np.ndarray] = None, + ) -> ImageType: + """ + Annotates the given scene with labels based on the provided + detections, with support for Unicode characters. + + Args: + scene (ImageType): The image where labels will be drawn. + `ImageType` is a flexible type, accepting either `numpy.ndarray` + or `PIL.Image.Image`. + detections (Detections): Object detections to annotate. + labels (List[str]): Optional. Custom labels for each detection. + custom_color_lookup (Optional[np.ndarray]): Custom color lookup array. + Allows to override the default color mapping strategy. + + Returns: + The annotated image, matching the type of `scene` (`numpy.ndarray` + or `PIL.Image.Image`) + + Example: + ```python + import supervision as sv + + image = ... + detections = sv.Detections(...) + + labels = [ + f"{class_name} {confidence:.2f}" + for class_name, confidence + in zip(detections['class_name'], detections.confidence) + ] + + rich_label_annotator = sv.RichLabelAnnotator(font_path="path/to/font.ttf") + annotated_frame = label_annotator.annotate( + scene=image.copy(), + detections=detections, + labels=labels + ) + ``` + + """ + if isinstance(scene, np.ndarray): + scene = Image.fromarray(cv2.cvtColor(scene, cv2.COLOR_BGR2RGB)) + draw = ImageDraw.Draw(scene) + anchors_coordinates = detections.get_anchors_coordinates( + anchor=self.text_anchor + ).astype(int) + if labels is not None and len(labels) != len(detections): + raise ValueError( + f"The number of labels provided ({len(labels)}) does not match the " + f"number of detections ({len(detections)}). Each detection should have " + f"a corresponding label. This discrepancy can occur if the labels and " + f"detections are not aligned or if an incorrect number of labels has " + f"been provided. Please ensure that the labels array has the same " + f"length as the Detections object." + ) + for detection_idx, center_coordinates in enumerate(anchors_coordinates): + color = resolve_color( + color=self.color, + detections=detections, + detection_idx=detection_idx, + color_lookup=( + self.color_lookup + if custom_color_lookup is None + else custom_color_lookup + ), + ) + if labels is not None: + text = labels[detection_idx] + elif detections[CLASS_NAME_DATA_FIELD] is not None: + text = detections[CLASS_NAME_DATA_FIELD][detection_idx] + elif detections.class_id is not None: + text = str(detections.class_id[detection_idx]) + else: + text = str(detection_idx) + + left, top, right, bottom = draw.textbbox((0, 0), text, font=self.font) + text_width = right - left + text_height = bottom - top + text_w_padded = text_width + 2 * self.text_padding + text_h_padded = text_height + 2 * self.text_padding + text_background_xyxy = resolve_text_background_xyxy( + center_coordinates=tuple(center_coordinates), + text_wh=(text_w_padded, text_h_padded), + position=self.text_anchor, + ) + + text_x = text_background_xyxy[0] + self.text_padding - left + text_y = text_background_xyxy[1] + self.text_padding - top + + draw.rounded_rectangle( + text_background_xyxy, + radius=self.border_radius, + fill=color.as_rgb(), + outline=None, + ) + draw.text( + xy=(text_x, text_y), + text=text, + font=self.font, + fill=self.text_color.as_rgb(), + ) + + return scene + + class BlurAnnotator(BaseAnnotator): """ A class for blurring regions in an image using provided detections. diff --git a/supervision/annotators/utils.py b/supervision/annotators/utils.py index e206c8cb..100b7874 100644 --- a/supervision/annotators/utils.py +++ b/supervision/annotators/utils.py @@ -1,5 +1,5 @@ from enum import Enum -from typing import Optional, Union +from typing import Optional, Tuple, Union import numpy as np @@ -34,14 +34,14 @@ def resolve_color_idx( ) -> int: if detection_idx >= len(detections): raise ValueError( - f"Detection index {detection_idx}" + f"Detection index {detection_idx} " f"is out of bounds for detections of length {len(detections)}" ) if isinstance(color_lookup, np.ndarray): if len(color_lookup) != len(detections): raise ValueError( - f"Length of color lookup {len(color_lookup)}" + f"Length of color lookup {len(color_lookup)} " f"does not match length of detections {len(detections)}" ) return color_lookup[detection_idx] @@ -50,19 +50,72 @@ def resolve_color_idx( elif color_lookup == ColorLookup.CLASS: if detections.class_id is None: raise ValueError( - "Could not resolve color by class because" + "Could not resolve color by class because " "Detections do not have class_id" ) return detections.class_id[detection_idx] elif color_lookup == ColorLookup.TRACK: if detections.tracker_id is None: raise ValueError( - "Could not resolve color by track because" + "Could not resolve color by track because " "Detections do not have tracker_id" ) return detections.tracker_id[detection_idx] +def resolve_text_background_xyxy( + center_coordinates: Tuple[int, int], + text_wh: Tuple[int, int], + position: Position, +) -> Tuple[int, int, int, int]: + center_x, center_y = center_coordinates + text_w, text_h = text_wh + + if position == Position.TOP_LEFT: + return center_x, center_y - text_h, center_x + text_w, center_y + elif position == Position.TOP_RIGHT: + return center_x - text_w, center_y - text_h, center_x, center_y + elif position == Position.TOP_CENTER: + return ( + center_x - text_w // 2, + center_y - text_h, + center_x + text_w // 2, + center_y, + ) + elif position == Position.CENTER or position == Position.CENTER_OF_MASS: + return ( + center_x - text_w // 2, + center_y - text_h // 2, + center_x + text_w // 2, + center_y + text_h // 2, + ) + elif position == Position.BOTTOM_LEFT: + return center_x, center_y, center_x + text_w, center_y + text_h + elif position == Position.BOTTOM_RIGHT: + return center_x - text_w, center_y, center_x, center_y + text_h + elif position == Position.BOTTOM_CENTER: + return ( + center_x - text_w // 2, + center_y, + center_x + text_w // 2, + center_y + text_h, + ) + elif position == Position.CENTER_LEFT: + return ( + center_x - text_w, + center_y - text_h // 2, + center_x, + center_y + text_h // 2, + ) + elif position == Position.CENTER_RIGHT: + return ( + center_x, + center_y - text_h // 2, + center_x + text_w, + center_y + text_h // 2, + ) + + def get_color_by_index(color: Union[Color, ColorPalette], idx: int) -> Color: if isinstance(color, ColorPalette): return color.by_idx(idx) diff --git a/supervision/dataset/core.py b/supervision/dataset/core.py index 551e96da..c8863df3 100644 --- a/supervision/dataset/core.py +++ b/supervision/dataset/core.py @@ -116,13 +116,12 @@ class DetectionDataset(BaseDataset): Tuple[DetectionDataset, DetectionDataset]: A tuple containing the training and testing datasets. - Example: + Examples: ```python import supervision as sv ds = sv.DetectionDataset(...) - train_ds, test_ds = ds.split(split_ratio=0.7, - random_state=42, shuffle=True) + train_ds, test_ds = ds.split(split_ratio=0.7, random_state=42, shuffle=True) len(train_ds), len(test_ds) # (700, 300) ``` @@ -229,7 +228,7 @@ class DetectionDataset(BaseDataset): DetectionDataset: A DetectionDataset instance containing the loaded images and annotations. - Example: + Examples: ```python import roboflow from roboflow import Roboflow @@ -286,7 +285,7 @@ class DetectionDataset(BaseDataset): DetectionDataset: A DetectionDataset instance containing the loaded images and annotations. - Example: + Examples: ```python import roboflow from roboflow import Roboflow @@ -391,7 +390,7 @@ class DetectionDataset(BaseDataset): DetectionDataset: A DetectionDataset instance containing the loaded images and annotations. - Example: + Examples: ```python import roboflow from roboflow import Roboflow @@ -431,6 +430,20 @@ class DetectionDataset(BaseDataset): Exports the dataset to COCO format. This method saves the images and their corresponding annotations in COCO format. + !!! tip + + The format of the mask is determined automatically based on its structure: + + - If a mask contains multiple disconnected components or holes, it will be + saved using the Run-Length Encoding (RLE) format for efficient storage and + processing. + - If a mask consists of a single, contiguous region without any holes, it + will be encoded as a polygon, preserving the outline of the object. + + This automatic selection ensures that the masks are stored in the most + appropriate and space-efficient format, complying with COCO dataset + standards. + Args: images_directory_path (Optional[str]): The path to the directory where the images should be saved. @@ -482,7 +495,7 @@ class DetectionDataset(BaseDataset): (DetectionDataset): A single `DetectionDataset` object containing the merged data from the input list. - Example: + Examples: ```python import supervision as sv @@ -567,13 +580,12 @@ class ClassificationDataset(BaseDataset): Tuple[ClassificationDataset, ClassificationDataset]: A tuple containing the training and testing datasets. - Example: + Examples: ```python import supervision as sv cd = sv.ClassificationDataset(...) - train_cd,test_cd = cd.split(split_ratio=0.7, - random_state=42,shuffle=True) + train_cd,test_cd = cd.split(split_ratio=0.7, random_state=42,shuffle=True) len(train_cd), len(test_cd) # (700, 300) ``` @@ -635,7 +647,7 @@ class ClassificationDataset(BaseDataset): Returns: ClassificationDataset: The dataset. - Example: + Examples: ```python import roboflow from roboflow import Roboflow diff --git a/supervision/dataset/formats/coco.py b/supervision/dataset/formats/coco.py index 4f8679d5..353e33f5 100644 --- a/supervision/dataset/formats/coco.py +++ b/supervision/dataset/formats/coco.py @@ -5,13 +5,20 @@ from typing import Dict, List, Tuple import cv2 import numpy as np +import numpy.typing as npt from supervision.dataset.utils import ( approximate_mask_with_polygons, map_detections_class_id, + mask_to_rle, + rle_to_mask, ) from supervision.detection.core import Detections -from supervision.detection.utils import polygon_to_mask +from supervision.detection.utils import ( + contains_holes, + contains_multiple_segments, + polygon_to_mask, +) from supervision.utils.file import read_json_file, save_json_file @@ -57,13 +64,24 @@ def group_coco_annotations_by_image_id( return annotations -def _polygons_to_masks( - polygons: List[np.ndarray], resolution_wh: Tuple[int, int] -) -> np.ndarray: +def coco_annotations_to_masks( + image_annotations: List[dict], resolution_wh: Tuple[int, int] +) -> npt.NDArray[np.bool_]: return np.array( [ - polygon_to_mask(polygon=polygon, resolution_wh=resolution_wh) - for polygon in polygons + rle_to_mask( + rle=np.array(image_annotation["segmentation"]["counts"]), + resolution_wh=resolution_wh, + ) + if image_annotation["iscrowd"] + else polygon_to_mask( + polygon=np.reshape( + np.asarray(image_annotation["segmentation"], dtype=np.int32), + (-1, 2), + ), + resolution_wh=resolution_wh, + ) + for image_annotation in image_annotations ], dtype=bool, ) @@ -83,13 +101,9 @@ def coco_annotations_to_detections( xyxy[:, 2:4] += xyxy[:, 0:2] if with_masks: - polygons = [ - np.reshape( - np.asarray(image_annotation["segmentation"], dtype=np.int32), (-1, 2) - ) - for image_annotation in image_annotations - ] - mask = _polygons_to_masks(polygons=polygons, resolution_wh=resolution_wh) + mask = coco_annotations_to_masks( + image_annotations=image_annotations, resolution_wh=resolution_wh + ) return Detections( class_id=np.asarray(class_ids, dtype=int), xyxy=xyxy, mask=mask ) @@ -108,24 +122,35 @@ def detections_to_coco_annotations( coco_annotations = [] for xyxy, mask, _, class_id, _, _ in detections: box_width, box_height = xyxy[2] - xyxy[0], xyxy[3] - xyxy[1] - polygon = [] + segmentation = [] + iscrowd = 0 if mask is not None: - polygon = list( - approximate_mask_with_polygons( - mask=mask, - min_image_area_percentage=min_image_area_percentage, - max_image_area_percentage=max_image_area_percentage, - approximation_percentage=approximation_percentage, - )[0].flatten() - ) + iscrowd = contains_holes(mask=mask) or contains_multiple_segments(mask=mask) + + if iscrowd: + segmentation = { + "counts": mask_to_rle(mask=mask), + "size": list(mask.shape[:2]), + } + else: + segmentation = [ + list( + approximate_mask_with_polygons( + mask=mask, + min_image_area_percentage=min_image_area_percentage, + max_image_area_percentage=max_image_area_percentage, + approximation_percentage=approximation_percentage, + )[0].flatten() + ) + ] coco_annotation = { "id": annotation_id, "image_id": image_id, "category_id": int(class_id), "bbox": [xyxy[0], xyxy[1], box_width, box_height], "area": box_width * box_height, - "segmentation": [polygon] if polygon else [], - "iscrowd": 0, + "segmentation": segmentation, + "iscrowd": iscrowd, } coco_annotations.append(coco_annotation) annotation_id += 1 diff --git a/supervision/dataset/utils.py b/supervision/dataset/utils.py index 05ee3201..32ece6bf 100644 --- a/supervision/dataset/utils.py +++ b/supervision/dataset/utils.py @@ -2,10 +2,11 @@ import copy import os import random from pathlib import Path -from typing import Dict, List, Optional, Tuple, TypeVar +from typing import Dict, List, Optional, Tuple, TypeVar, Union import cv2 import numpy as np +import numpy.typing as npt from supervision.detection.core import Detections from supervision.detection.utils import ( @@ -129,3 +130,123 @@ def train_test_split( split_index = int(len(data) * train_ratio) return data[:split_index], data[split_index:] + + +def rle_to_mask( + rle: Union[npt.NDArray[np.int_], List[int]], resolution_wh: Tuple[int, int] +) -> npt.NDArray[np.bool_]: + """ + Converts run-length encoding (RLE) to a binary mask. + + Args: + rle (Union[npt.NDArray[np.int_], List[int]]): The 1D RLE array, the format + used in the COCO dataset (column-wise encoding, values of an array with + even indices represent the number of pixels assigned as background, + values of an array with odd indices represent the number of pixels + assigned as foreground object). + resolution_wh (Tuple[int, int]): The width (w) and height (h) + of the desired binary mask. + + Returns: + The generated 2D Boolean mask of shape `(h, w)`, where the foreground object is + marked with `True`'s and the rest is filled with `False`'s. + + Raises: + AssertionError: If the sum of pixels encoded in RLE differs from the + number of pixels in the expected mask (computed based on resolution_wh). + + Examples: + ```python + import supervision as sv + + sv.rle_to_mask([5, 2, 2, 2, 5], (4, 4)) + # array([ + # [False, False, False, False], + # [False, True, True, False], + # [False, True, True, False], + # [False, False, False, False], + # ]) + ``` + """ + if isinstance(rle, list): + rle = np.array(rle, dtype=int) + + width, height = resolution_wh + + assert width * height == np.sum(rle), ( + "the sum of the number of pixels in the RLE must be the same " + "as the number of pixels in the expected mask" + ) + + zero_one_values = np.zeros(shape=(rle.size, 1), dtype=np.uint8) + zero_one_values[1::2] = 1 + + decoded_rle = np.repeat(zero_one_values, rle, axis=0) + decoded_rle = np.append( + decoded_rle, np.zeros(width * height - len(decoded_rle), dtype=np.uint8) + ) + return decoded_rle.reshape((height, width), order="F") + + +def mask_to_rle(mask: npt.NDArray[np.bool_]) -> List[int]: + """ + Converts a binary mask into a run-length encoding (RLE). + + Args: + mask (npt.NDArray[np.bool_]): 2D binary mask where `True` indicates foreground + object and `False` indicates background. + + Returns: + The run-length encoded mask. Values of a list with even indices + represent the number of pixels assigned as background (`False`), values + of a list with odd indices represent the number of pixels assigned + as foreground object (`True`). + + Raises: + AssertionError: If input mask is not 2D or is empty. + + Examples: + ```python + import numpy as np + import supervision as sv + + mask = np.array([ + [True, True, True, True], + [True, True, True, True], + [True, True, True, True], + [True, True, True, True], + ]) + sv.mask_to_rle(mask) + # [0, 16] + + mask = np.array([ + [False, False, False, False], + [False, True, True, False], + [False, True, True, False], + [False, False, False, False], + ]) + sv.mask_to_rle(mask) + # [5, 2, 2, 2, 5] + ``` + + ![mask_to_rle](https://media.roboflow.com/supervision-docs/mask-to-rle.png){ align=center width="800" } + """ # noqa E501 // docs + assert mask.ndim == 2, "Input mask must be 2D" + assert mask.size != 0, "Input mask cannot be empty" + + on_value_change_indices = np.where( + mask.ravel(order="F") != np.roll(mask.ravel(order="F"), 1) + )[0] + + on_value_change_indices = np.append(on_value_change_indices, mask.size) + # need to add 0 at the beginning when the same value is in the first and + # last element of the flattened mask + if on_value_change_indices[0] != 0: + on_value_change_indices = np.insert(on_value_change_indices, 0, 0) + + rle = np.diff(on_value_change_indices) + + if mask[0][0] == 1: + rle = np.insert(rle, 0, 0) + + return list(rle) diff --git a/supervision/detection/core.py b/supervision/detection/core.py index 1900954d..37dde153 100644 --- a/supervision/detection/core.py +++ b/supervision/detection/core.py @@ -7,20 +7,25 @@ from typing import Any, Dict, Iterator, List, Optional, Tuple, Union import numpy as np from supervision.config import CLASS_NAME_DATA_FIELD, ORIENTED_BOX_COORDINATES -from supervision.detection.utils import ( +from supervision.detection.lmm import LMM, from_paligemma, validate_lmm_and_kwargs +from supervision.detection.overlap_filter import ( + box_non_max_merge, box_non_max_suppression, + mask_non_max_suppression, +) +from supervision.detection.utils import ( + box_iou_batch, calculate_masks_centroids, extract_ultralytics_masks, get_data_item, is_data_equal, - mask_non_max_suppression, mask_to_xyxy, merge_data, process_roboflow_result, xywh_to_xyxy, ) from supervision.geometry.core import Position -from supervision.utils.internal import deprecated +from supervision.utils.internal import deprecated, get_instance_variables from supervision.validators import validate_detections_fields @@ -240,7 +245,7 @@ class Detections: Class names values can be accessed using `detections["class_name"]`. """ # noqa: E501 // docs - if "obb" in ultralytics_results and ultralytics_results.obb is not None: + if hasattr(ultralytics_results, "obb") and ultralytics_results.obb is not None: class_id = ultralytics_results.obb.cls.cpu().numpy().astype(int) class_names = np.array([ultralytics_results.names[i] for i in class_id]) oriented_box_coordinates = ultralytics_results.obb.xyxyxyxy.cpu().numpy() @@ -418,6 +423,9 @@ class Detections: xyxy=mmdet_results.pred_instances.bboxes.cpu().numpy(), confidence=mmdet_results.pred_instances.scores.cpu().numpy(), class_id=mmdet_results.pred_instances.labels.cpu().numpy().astype(int), + mask=mmdet_results.pred_instances.masks.cpu().numpy() + if "masks" in mmdet_results.pred_instances + else None, ) @classmethod @@ -802,6 +810,52 @@ class Detections: class_id=paddledet_result["bbox"][:, 0].astype(int), ) + @classmethod + def from_lmm(cls, lmm: Union[LMM, str], result: str, **kwargs) -> Detections: + """ + Creates a Detections object from the given result string based on the specified + Large Multimodal Model (LMM). + + Args: + lmm (Union[LMM, str]): The type of LMM (Large Multimodal Model) to use. + result (str): The result string containing the detection data. + **kwargs: Additional keyword arguments required by the specified LMM. + + Returns: + Detections: A new Detections object. + + Raises: + ValueError: If the LMM is invalid, required arguments are missing, or + disallowed arguments are provided. + ValueError: If the specified LMM is not supported. + + Examples: + ```python + import supervision as sv + + paligemma_result = " cat" + detections = sv.Detections.from_lmm( + sv.LMM.PALIGEMMA, + paligemma_result, + resolution_wh=(1000, 1000), + classes=['cat', 'dog'] + ) + detections.xyxy + # array([[250., 250., 750., 750.]]) + + detections.class_id + # array([0]) + ``` + """ + lmm = validate_lmm_and_kwargs(lmm, kwargs) + + if lmm == LMM.PALIGEMMA: + xyxy, class_id, class_name = from_paligemma(result, **kwargs) + data = {CLASS_NAME_DATA_FIELD: class_name} + return cls(xyxy=xyxy, class_id=class_id, data=data) + + raise ValueError(f"Unsupported LMM: {lmm}") + @classmethod def empty(cls) -> Detections: """ @@ -824,6 +878,14 @@ class Detections: class_id=np.array([], dtype=int), ) + def is_empty(self) -> bool: + """ + Returns `True` if the `Detections` object is considered empty. + """ + empty_detections = Detections.empty() + empty_detections.data = self.data + return self == empty_detections + @classmethod def merge(cls, detections_list: List[Detections]) -> Detections: """ @@ -831,9 +893,14 @@ class Detections: This method takes a list of Detections objects and combines their respective fields (`xyxy`, `mask`, `confidence`, `class_id`, and `tracker_id`) - into a single Detections object. If all elements in a field are not - `None`, the corresponding field will be stacked. - Otherwise, the field will be set to `None`. + into a single Detections object. + + For example, if merging Detections with 3 and 4 detected objects, this method + will return a Detections with 7 objects (7 entries in `xyxy`, `mask`, etc). + + !!! Note + + When merging, empty `Detections` objects are ignored. Args: detections_list (List[Detections]): A list of Detections objects to merge. @@ -873,6 +940,10 @@ class Detections: array([0.1, 0.2, 0.3]) ``` """ + detections_list = [ + detections for detections in detections_list if not detections.is_empty() + ] + if len(detections_list) == 0: return Detections.empty() @@ -1147,3 +1218,195 @@ class Detections: ) return self[indices] + + def with_nmm( + self, threshold: float = 0.5, class_agnostic: bool = False + ) -> Detections: + """ + Perform non-maximum merging on the current set of object detections. + + Args: + threshold (float, optional): The intersection-over-union threshold + to use for non-maximum merging. Defaults to 0.5. + class_agnostic (bool, optional): Whether to perform class-agnostic + non-maximum merging. If True, the class_id of each detection + will be ignored. Defaults to False. + + Returns: + Detections: A new Detections object containing the subset of detections + after non-maximum merging. + + Raises: + AssertionError: If `confidence` is None or `class_id` is None and + class_agnostic is False. + + ![non-max-merging](https://media.roboflow.com/supervision-docs/non-max-merging.png){ align=center width="800" } + """ # noqa: E501 // docs + if len(self) == 0: + return self + + assert ( + self.confidence is not None + ), "Detections confidence must be given for NMM to be executed." + + if class_agnostic: + predictions = np.hstack((self.xyxy, self.confidence.reshape(-1, 1))) + else: + assert self.class_id is not None, ( + "Detections class_id must be given for NMM to be executed. If you" + " intended to perform class agnostic NMM set class_agnostic=True." + ) + predictions = np.hstack( + ( + self.xyxy, + self.confidence.reshape(-1, 1), + self.class_id.reshape(-1, 1), + ) + ) + + merge_groups = box_non_max_merge( + predictions=predictions, iou_threshold=threshold + ) + + result = [] + for merge_group in merge_groups: + unmerged_detections = [self[i] for i in merge_group] + merged_detections = merge_inner_detections_objects( + unmerged_detections, threshold + ) + result.append(merged_detections) + + return Detections.merge(result) + + +def merge_inner_detection_object_pair( + detections_1: Detections, detections_2: Detections +) -> Detections: + """ + Merges two Detections object into a single Detections object. + Assumes each Detections contains exactly one object. + + A `winning` detection is determined based on the confidence score of the two + input detections. This winning detection is then used to specify which + `class_id`, `tracker_id`, and `data` to include in the merged Detections object. + + The resulting `confidence` of the merged object is calculated by the weighted + contribution of ea detection to the merged object. + The bounding boxes and masks of the two input detections are merged into a + single bounding box and mask, respectively. + + Args: + detections_1 (Detections): + The first Detections object + detections_2 (Detections): + The second Detections object + + Returns: + Detections: A new Detections object, with merged attributes. + + Raises: + ValueError: If the input Detections objects do not have exactly 1 detected + object. + + Example: + ```python + import cv2 + import supervision as sv + from inference import get_model + + image = cv2.imread() + model = get_model(model_id="yolov8s-640") + + result = model.infer(image)[0] + detections = sv.Detections.from_inference(result) + + merged_detections = merge_object_detection_pair( + detections[0], detections[1]) + ``` + """ + if len(detections_1) != 1 or len(detections_2) != 1: + raise ValueError("Both Detections should have exactly 1 detected object.") + + validate_fields_both_defined_or_none(detections_1, detections_2) + + xyxy_1 = detections_1.xyxy[0] + xyxy_2 = detections_2.xyxy[0] + if detections_1.confidence is None and detections_2.confidence is None: + merged_confidence = None + else: + detection_1_area = (xyxy_1[2] - xyxy_1[0]) * (xyxy_1[3] - xyxy_1[1]) + detections_2_area = (xyxy_2[2] - xyxy_2[0]) * (xyxy_2[3] - xyxy_2[1]) + merged_confidence = ( + detection_1_area * detections_1.confidence[0] + + detections_2_area * detections_2.confidence[0] + ) / (detection_1_area + detections_2_area) + merged_confidence = np.array([merged_confidence]) + + merged_x1, merged_y1 = np.minimum(xyxy_1[:2], xyxy_2[:2]) + merged_x2, merged_y2 = np.maximum(xyxy_1[2:], xyxy_2[2:]) + merged_xyxy = np.array([[merged_x1, merged_y1, merged_x2, merged_y2]]) + + if detections_1.mask is None and detections_2.mask is None: + merged_mask = None + else: + merged_mask = np.logical_or(detections_1.mask, detections_2.mask) + + if detections_1.confidence is None and detections_2.confidence is None: + winning_detection = detections_1 + elif detections_1.confidence[0] >= detections_2.confidence[0]: + winning_detection = detections_1 + else: + winning_detection = detections_2 + + return Detections( + xyxy=merged_xyxy, + mask=merged_mask, + confidence=merged_confidence, + class_id=winning_detection.class_id, + tracker_id=winning_detection.tracker_id, + data=winning_detection.data, + ) + + +def merge_inner_detections_objects( + detections: List[Detections], threshold=0.5 +) -> Detections: + """ + Given N detections each of length 1 (exactly one object inside), combine them into a + single detection object of length 1. The contained inner object will be the merged + result of all the input detections. + + For example, this lets you merge N boxes into one big box, N masks into one mask, + etc. + """ + detections_1 = detections[0] + for detections_2 in detections[1:]: + box_iou = box_iou_batch(detections_1.xyxy, detections_2.xyxy)[0] + if box_iou < threshold: + break + detections_1 = merge_inner_detection_object_pair(detections_1, detections_2) + return detections_1 + + +def validate_fields_both_defined_or_none( + detections_1: Detections, detections_2: Detections +) -> None: + """ + Verify that for each optional field in the Detections, both instances either have + the field set to None or both have it set to non-None values. + + `data` field is ignored. + + Raises: + ValueError: If one field is None and the other is not, for any of the fields. + """ + attributes = get_instance_variables(detections_1) + for attribute in attributes: + value_1 = getattr(detections_1, attribute) + value_2 = getattr(detections_2, attribute) + + if (value_1 is None) != (value_2 is None): + raise ValueError( + f"Field '{attribute}' should be consistently None or not None in both " + "Detections." + ) diff --git a/supervision/detection/line_zone.py b/supervision/detection/line_zone.py index 53d762a0..4255a0ad 100644 --- a/supervision/detection/line_zone.py +++ b/supervision/detection/line_zone.py @@ -1,12 +1,15 @@ +import warnings from typing import Dict, Iterable, Optional, Tuple import cv2 import numpy as np from supervision.detection.core import Detections +from supervision.detection.utils import cross_product from supervision.draw.color import Color from supervision.draw.utils import draw_text from supervision.geometry.core import Point, Position, Vector +from supervision.utils.internal import SupervisionWarnings class LineZone: @@ -81,6 +84,8 @@ class LineZone: self.in_count: int = 0 self.out_count: int = 0 self.triggering_anchors = triggering_anchors + if not list(self.triggering_anchors): + raise ValueError("Triggering anchors cannot be empty.") @staticmethod def calculate_region_of_interest_limits(vector: Vector) -> Tuple[Vector, Vector]: @@ -140,6 +145,15 @@ class LineZone: if len(detections) == 0: return crossed_in, crossed_out + if detections.tracker_id is None: + warnings.warn( + "Line zone counting skipped. LineZone requires tracker_id. Refer to " + "https://supervision.roboflow.com/latest/trackers for more " + "information.", + category=SupervisionWarnings, + ) + return crossed_in, crossed_out + all_anchors = np.array( [ detections.get_anchors_coordinates(anchor) @@ -147,31 +161,23 @@ class LineZone: ] ) + cross_products_1 = cross_product(all_anchors, self.limits[0]) + cross_products_2 = cross_product(all_anchors, self.limits[1]) + in_limits = (cross_products_1 > 0) == (cross_products_2 > 0) + in_limits = np.all(in_limits, axis=0) + + triggers = cross_product(all_anchors, self.vector) < 0 + has_any_left_trigger = np.any(triggers, axis=0) + has_any_right_trigger = np.any(~triggers, axis=0) + is_uniformly_triggered = ~(has_any_left_trigger & has_any_right_trigger) for i, tracker_id in enumerate(detections.tracker_id): - if tracker_id is None: + if not in_limits[i]: continue - box_anchors = [Point(x=x, y=y) for x, y in all_anchors[:, i, :]] - - in_limits = all( - [ - self.is_point_in_limits(point=anchor, limits=self.limits) - for anchor in box_anchors - ] - ) - - if not in_limits: + if not is_uniformly_triggered[i]: continue - triggers = [ - self.vector.cross_product(point=anchor) < 0 for anchor in box_anchors - ] - - if len(set(triggers)) == 2: - continue - - tracker_state = triggers[0] - + tracker_state = has_any_left_trigger[i] if tracker_id not in self.tracker_state: self.tracker_state[tracker_id] = tracker_state continue diff --git a/supervision/detection/lmm.py b/supervision/detection/lmm.py new file mode 100644 index 00000000..5f61db0a --- /dev/null +++ b/supervision/detection/lmm.py @@ -0,0 +1,59 @@ +import re +from enum import Enum +from typing import Any, Dict, List, Optional, Tuple, Union + +import numpy as np + + +class LMM(Enum): + PALIGEMMA = "paligemma" + + +REQUIRED_ARGUMENTS: Dict[LMM, List[str]] = {LMM.PALIGEMMA: ["resolution_wh"]} + +ALLOWED_ARGUMENTS: Dict[LMM, List[str]] = {LMM.PALIGEMMA: ["resolution_wh", "classes"]} + + +def validate_lmm_and_kwargs(lmm: Union[LMM, str], kwargs: Dict[str, Any]) -> LMM: + if isinstance(lmm, str): + try: + lmm = LMM(lmm.lower()) + except ValueError: + raise ValueError( + f"Invalid lmm value: {lmm}. Must be one of {[e.value for e in LMM]}" + ) + + required_args = REQUIRED_ARGUMENTS.get(lmm, []) + for arg in required_args: + if arg not in kwargs: + raise ValueError(f"Missing required argument: {arg}") + + allowed_args = ALLOWED_ARGUMENTS.get(lmm, []) + for arg in kwargs: + if arg not in allowed_args: + raise ValueError(f"Argument {arg} is not allowed for {lmm.name}") + + return lmm + + +def from_paligemma( + result: str, resolution_wh: Tuple[int, int], classes: Optional[List[str]] = None +) -> Tuple[np.ndarray, Optional[np.ndarray], np.ndarray]: + w, h = resolution_wh + pattern = re.compile( + r"(?) ([\w\s\-]+)" + ) + matches = pattern.findall(result) + matches = np.array(matches) if matches else np.empty((0, 5)) + + xyxy, class_name = matches[:, [1, 0, 3, 2]], matches[:, 4] + xyxy = xyxy.astype(int) / 1024 * np.array([w, h, w, h]) + class_name = np.char.strip(class_name.astype(str)) + class_id = None + + if classes is not None: + mask = np.array([name in classes for name in class_name]).astype(bool) + xyxy, class_name = xyxy[mask], class_name[mask] + class_id = np.array([classes.index(name) for name in class_name]) + + return xyxy, class_id, class_name diff --git a/supervision/detection/overlap_filter.py b/supervision/detection/overlap_filter.py new file mode 100644 index 00000000..ab4408d1 --- /dev/null +++ b/supervision/detection/overlap_filter.py @@ -0,0 +1,263 @@ +from enum import Enum +from typing import List, Union + +import numpy as np +import numpy.typing as npt + +from supervision.detection.utils import box_iou_batch, mask_iou_batch + + +def resize_masks(masks: np.ndarray, max_dimension: int = 640) -> np.ndarray: + """ + Resize all masks in the array to have a maximum dimension of max_dimension, + maintaining aspect ratio. + + Args: + masks (np.ndarray): 3D array of binary masks with shape (N, H, W). + max_dimension (int): The maximum dimension for the resized masks. + + Returns: + np.ndarray: Array of resized masks. + """ + max_height = np.max(masks.shape[1]) + max_width = np.max(masks.shape[2]) + scale = min(max_dimension / max_height, max_dimension / max_width) + + new_height = int(scale * max_height) + new_width = int(scale * max_width) + + x = np.linspace(0, max_width - 1, new_width).astype(int) + y = np.linspace(0, max_height - 1, new_height).astype(int) + xv, yv = np.meshgrid(x, y) + + resized_masks = masks[:, yv, xv] + + resized_masks = resized_masks.reshape(masks.shape[0], new_height, new_width) + return resized_masks + + +def mask_non_max_suppression( + predictions: np.ndarray, + masks: np.ndarray, + iou_threshold: float = 0.5, + mask_dimension: int = 640, +) -> np.ndarray: + """ + Perform Non-Maximum Suppression (NMS) on segmentation predictions. + + Args: + predictions (np.ndarray): A 2D array of object detection predictions in + the format of `(x_min, y_min, x_max, y_max, score)` + or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or + `(N, 6)`, where N is the number of predictions. + masks (np.ndarray): A 3D array of binary masks corresponding to the predictions. + Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the + dimensions of each mask. + iou_threshold (float, optional): The intersection-over-union threshold + to use for non-maximum suppression. + mask_dimension (int, optional): The dimension to which the masks should be + resized before computing IOU values. Defaults to 640. + + Returns: + np.ndarray: A boolean array indicating which predictions to keep after + non-maximum suppression. + + Raises: + AssertionError: If `iou_threshold` is not within the closed + range from `0` to `1`. + """ + assert 0 <= iou_threshold <= 1, ( + "Value of `iou_threshold` must be in the closed range from 0 to 1, " + f"{iou_threshold} given." + ) + rows, columns = predictions.shape + + if columns == 5: + predictions = np.c_[predictions, np.zeros(rows)] + + sort_index = predictions[:, 4].argsort()[::-1] + predictions = predictions[sort_index] + masks = masks[sort_index] + masks_resized = resize_masks(masks, mask_dimension) + ious = mask_iou_batch(masks_resized, masks_resized) + categories = predictions[:, 5] + + keep = np.ones(rows, dtype=bool) + for i in range(rows): + if keep[i]: + condition = (ious[i] > iou_threshold) & (categories[i] == categories) + keep[i + 1 :] = np.where(condition[i + 1 :], False, keep[i + 1 :]) + + return keep[sort_index.argsort()] + + +def box_non_max_suppression( + predictions: np.ndarray, iou_threshold: float = 0.5 +) -> np.ndarray: + """ + Perform Non-Maximum Suppression (NMS) on object detection predictions. + + Args: + predictions (np.ndarray): An array of object detection predictions in + the format of `(x_min, y_min, x_max, y_max, score)` + or `(x_min, y_min, x_max, y_max, score, class)`. + iou_threshold (float, optional): The intersection-over-union threshold + to use for non-maximum suppression. + + Returns: + np.ndarray: A boolean array indicating which predictions to keep after n + on-maximum suppression. + + Raises: + AssertionError: If `iou_threshold` is not within the + closed range from `0` to `1`. + """ + assert 0 <= iou_threshold <= 1, ( + "Value of `iou_threshold` must be in the closed range from 0 to 1, " + f"{iou_threshold} given." + ) + rows, columns = predictions.shape + + # add column #5 - category filled with zeros for agnostic nms + if columns == 5: + predictions = np.c_[predictions, np.zeros(rows)] + + # sort predictions column #4 - score + sort_index = np.flip(predictions[:, 4].argsort()) + predictions = predictions[sort_index] + + boxes = predictions[:, :4] + categories = predictions[:, 5] + ious = box_iou_batch(boxes, boxes) + ious = ious - np.eye(rows) + + keep = np.ones(rows, dtype=bool) + + for index, (iou, category) in enumerate(zip(ious, categories)): + if not keep[index]: + continue + + # drop detections with iou > iou_threshold and + # same category as current detections + condition = (iou > iou_threshold) & (categories == category) + keep = keep & ~condition + + return keep[sort_index.argsort()] + + +def group_overlapping_boxes( + predictions: npt.NDArray[np.float64], iou_threshold: float = 0.5 +) -> List[List[int]]: + """ + Apply greedy version of non-maximum merging to avoid detecting too many + overlapping bounding boxes for a given object. + + Args: + predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` containing + the bounding boxes coordinates in format `[x1, y1, x2, y2]` + and the confidence scores. + iou_threshold (float, optional): The intersection-over-union threshold + to use for non-maximum suppression. Defaults to 0.5. + + Returns: + List[List[int]]: Groups of prediction indices be merged. + Each group may have 1 or more elements. + """ + merge_groups: List[List[int]] = [] + + scores = predictions[:, 4] + order = scores.argsort() + + while len(order) > 0: + idx = int(order[-1]) + + order = order[:-1] + if len(order) == 0: + merge_groups.append([idx]) + break + + merge_candidate = np.expand_dims(predictions[idx], axis=0) + ious = box_iou_batch(predictions[order][:, :4], merge_candidate[:, :4]) + ious = ious.flatten() + + above_threshold = ious >= iou_threshold + merge_group = [idx] + np.flip(order[above_threshold]).tolist() + merge_groups.append(merge_group) + order = order[~above_threshold] + return merge_groups + + +def box_non_max_merge( + predictions: npt.NDArray[np.float64], + iou_threshold: float = 0.5, +) -> List[List[int]]: + """ + Apply greedy version of non-maximum merging per category to avoid detecting + too many overlapping bounding boxes for a given object. + + Args: + predictions (npt.NDArray[np.float64]): An array of shape `(n, 5)` or `(n, 6)` + containing the bounding boxes coordinates in format `[x1, y1, x2, y2]`, + the confidence scores and class_ids. Omit class_id column to allow + detections of different classes to be merged. + iou_threshold (float, optional): The intersection-over-union threshold + to use for non-maximum suppression. Defaults to 0.5. + + Returns: + List[List[int]]: Groups of prediction indices be merged. + Each group may have 1 or more elements. + """ + if predictions.shape[1] == 5: + return group_overlapping_boxes(predictions, iou_threshold) + + category_ids = predictions[:, 5] + merge_groups = [] + for category_id in np.unique(category_ids): + curr_indices = np.where(category_ids == category_id)[0] + merge_class_groups = group_overlapping_boxes( + predictions[curr_indices], iou_threshold + ) + + for merge_class_group in merge_class_groups: + merge_groups.append(curr_indices[merge_class_group].tolist()) + + for merge_group in merge_groups: + if len(merge_group) == 0: + raise ValueError( + f"Empty group detected when non-max-merging " + f"detections: {merge_groups}" + ) + return merge_groups + + +class OverlapFilter(Enum): + """ + Enum specifying the strategy for filtering overlapping detections. + + Attributes: + NONE: Do not filter detections based on overlap. + NON_MAX_SUPPRESSION: Filter detections using non-max suppression. This means, + detections that overlap by more than a set threshold will be discarded, + except for the one with the highest confidence. + NON_MAX_MERGE: Merge detections with non-max merging. This means, + detections that overlap by more than a set threshold will be merged + into a single detection. + """ + + NONE = "none" + NON_MAX_SUPPRESSION = "non_max_suppression" + NON_MAX_MERGE = "non_max_merge" + + +def validate_overlap_filter( + strategy: Union[OverlapFilter, str], +) -> OverlapFilter: + if isinstance(strategy, str): + try: + strategy = OverlapFilter(strategy.lower()) + except ValueError: + raise ValueError( + f"Invalid strategy value: {strategy}. Must be one of " + f"{[e.value for e in OverlapFilter]}" + ) + return strategy diff --git a/supervision/detection/tools/inference_slicer.py b/supervision/detection/tools/inference_slicer.py index 7157723f..134361bd 100644 --- a/supervision/detection/tools/inference_slicer.py +++ b/supervision/detection/tools/inference_slicer.py @@ -1,23 +1,42 @@ +import warnings from concurrent.futures import ThreadPoolExecutor, as_completed -from typing import Callable, Optional, Tuple +from typing import Callable, Optional, Tuple, Union import numpy as np from supervision.detection.core import Detections -from supervision.detection.utils import move_boxes +from supervision.detection.overlap_filter import OverlapFilter, validate_overlap_filter +from supervision.detection.utils import move_boxes, move_masks from supervision.utils.image import crop_image +from supervision.utils.internal import SupervisionWarnings -def move_detections(detections: Detections, offset: np.array) -> Detections: +def move_detections( + detections: Detections, + offset: np.ndarray, + resolution_wh: Optional[Tuple[int, int]] = None, +) -> Detections: """ Args: detections (sv.Detections): Detections object to be moved. - offset (np.array): An array of shape `(2,)` containing offset values in format + offset (np.ndarray): An array of shape `(2,)` containing offset values in format is `[dx, dy]`. + resolution_wh (Tuple[int, int]): The width and height of the desired mask + resolution. Required for segmentation detections. + Returns: (sv.Detections) repositioned Detections object. """ detections.xyxy = move_boxes(xyxy=detections.xyxy, offset=offset) + if detections.mask is not None: + if resolution_wh is None: + raise ValueError( + "Resolution width and height are required for moving segmentation " + "detections. This should be the same as (width, height) of image shape." + ) + detections.mask = move_masks( + masks=detections.mask, offset=offset, resolution_wh=resolution_wh + ) return detections @@ -34,8 +53,10 @@ class InferenceSlicer: `(width, height)`. overlap_ratio_wh (Tuple[float, float]): Overlap ratio between consecutive slices in the format `(width_ratio, height_ratio)`. - iou_threshold (Optional[float]): Intersection over Union (IoU) threshold - used for non-max suppression. + overlap_filter_strategy (Union[OverlapFilter, str]): Strategy for + filtering or merging overlapping detections in slices. + iou_threshold (float): Intersection over Union (IoU) threshold + used when filtering by overlap. callback (Callable): A function that performs inference on a given image slice and returns detections. thread_workers (int): Number of threads for parallel execution. @@ -52,12 +73,18 @@ class InferenceSlicer: callback: Callable[[np.ndarray], Detections], slice_wh: Tuple[int, int] = (320, 320), overlap_ratio_wh: Tuple[float, float] = (0.2, 0.2), - iou_threshold: Optional[float] = 0.5, + overlap_filter_strategy: Union[ + OverlapFilter, str + ] = OverlapFilter.NON_MAX_SUPPRESSION, + iou_threshold: float = 0.5, thread_workers: int = 1, ): + overlap_filter_strategy = validate_overlap_filter(overlap_filter_strategy) + self.slice_wh = slice_wh self.overlap_ratio_wh = overlap_ratio_wh self.iou_threshold = iou_threshold + self.overlap_filter_strategy = overlap_filter_strategy self.callback = callback self.thread_workers = thread_workers @@ -88,7 +115,10 @@ class InferenceSlicer: result = model(image_slice)[0] return sv.Detections.from_ultralytics(result) - slicer = sv.InferenceSlicer(callback = callback) + slicer = sv.InferenceSlicer( + callback=callback, + overlap_filter_strategy=sv.OverlapFilter.NON_MAX_SUPPRESSION, + ) detections = slicer(image) ``` @@ -108,9 +138,19 @@ class InferenceSlicer: for future in as_completed(futures): detections_list.append(future.result()) - return Detections.merge(detections_list=detections_list).with_nms( - threshold=self.iou_threshold - ) + merged = Detections.merge(detections_list=detections_list) + if self.overlap_filter_strategy == OverlapFilter.NONE: + return merged + elif self.overlap_filter_strategy == OverlapFilter.NON_MAX_SUPPRESSION: + return merged.with_nms(threshold=self.iou_threshold) + elif self.overlap_filter_strategy == OverlapFilter.NON_MAX_MERGE: + return merged.with_nmm(threshold=self.iou_threshold) + else: + warnings.warn( + f"Invalid overlap filter strategy: {self.overlap_filter_strategy}", + category=SupervisionWarnings, + ) + return merged def _run_callback(self, image, offset) -> Detections: """ @@ -126,7 +166,10 @@ class InferenceSlicer: """ image_slice = crop_image(image=image, xyxy=offset) detections = self.callback(image_slice) - detections = move_detections(detections=detections, offset=offset[:2]) + resolution_wh = (image.shape[1], image.shape[0]) + detections = move_detections( + detections=detections, offset=offset[:2], resolution_wh=resolution_wh + ) return detections diff --git a/supervision/detection/tools/polygon_zone.py b/supervision/detection/tools/polygon_zone.py index a1997212..f1c48f94 100644 --- a/supervision/detection/tools/polygon_zone.py +++ b/supervision/detection/tools/polygon_zone.py @@ -54,6 +54,8 @@ class PolygonZone: self.polygon = polygon.astype(int) self.triggering_anchors = triggering_anchors + if not list(self.triggering_anchors): + raise ValueError("Triggering anchors cannot be empty.") self.current_count = 0 diff --git a/supervision/detection/tools/smoother.py b/supervision/detection/tools/smoother.py index f58f3299..5768c3e8 100644 --- a/supervision/detection/tools/smoother.py +++ b/supervision/detection/tools/smoother.py @@ -1,3 +1,4 @@ +import warnings from collections import defaultdict, deque from copy import deepcopy from typing import Optional @@ -5,6 +6,7 @@ from typing import Optional import numpy as np from supervision.detection.core import Detections +from supervision.utils.internal import SupervisionWarnings class DetectionsSmoother: @@ -70,16 +72,16 @@ class DetectionsSmoother: """ if detections.tracker_id is None: - print( + warnings.warn( "Smoothing skipped. DetectionsSmoother requires tracker_id. Refer to " - "https://supervision.roboflow.com/latest/trackers for more information." + "https://supervision.roboflow.com/latest/trackers for more " + "information.", + category=SupervisionWarnings, ) return detections for detection_idx in range(len(detections)): tracker_id = detections.tracker_id[detection_idx] - if tracker_id is None: - continue self.tracks[tracker_id].append(detections[detection_idx]) diff --git a/supervision/detection/utils.py b/supervision/detection/utils.py index 3eeba5b4..5b92aedd 100644 --- a/supervision/detection/utils.py +++ b/supervision/detection/utils.py @@ -3,8 +3,10 @@ from typing import Dict, List, Optional, Tuple, Union import cv2 import numpy as np +import numpy.typing as npt from supervision.config import CLASS_NAME_DATA_FIELD +from supervision.geometry.core import Vector MIN_POLYGON_POINT_COUNT = 3 @@ -56,7 +58,9 @@ def box_iou_batch(boxes_true: np.ndarray, boxes_detection: np.ndarray) -> np.nda bottom_right = np.minimum(boxes_true[:, None, 2:], boxes_detection[:, 2:]) area_inter = np.prod(np.clip(bottom_right - top_left, a_min=0, a_max=None), 2) - return area_inter / (area_true[:, None] + area_detection - area_inter) + ious = area_inter / (area_true[:, None] + area_detection - area_inter) + ious = np.nan_to_num(ious) + return ious def _mask_iou_batch_split( @@ -136,144 +140,6 @@ def mask_iou_batch( return np.vstack(ious) -def resize_masks(masks: np.ndarray, max_dimension: int = 640) -> np.ndarray: - """ - Resize all masks in the array to have a maximum dimension of max_dimension, - maintaining aspect ratio. - - Args: - masks (np.ndarray): 3D array of binary masks with shape (N, H, W). - max_dimension (int): The maximum dimension for the resized masks. - - Returns: - np.ndarray: Array of resized masks. - """ - max_height = np.max(masks.shape[1]) - max_width = np.max(masks.shape[2]) - scale = min(max_dimension / max_height, max_dimension / max_width) - - new_height = int(scale * max_height) - new_width = int(scale * max_width) - - x = np.linspace(0, max_width - 1, new_width).astype(int) - y = np.linspace(0, max_height - 1, new_height).astype(int) - xv, yv = np.meshgrid(x, y) - - resized_masks = masks[:, yv, xv] - - resized_masks = resized_masks.reshape(masks.shape[0], new_height, new_width) - return resized_masks - - -def mask_non_max_suppression( - predictions: np.ndarray, - masks: np.ndarray, - iou_threshold: float = 0.5, - mask_dimension: int = 640, -) -> np.ndarray: - """ - Perform Non-Maximum Suppression (NMS) on segmentation predictions. - - Args: - predictions (np.ndarray): A 2D array of object detection predictions in - the format of `(x_min, y_min, x_max, y_max, score)` - or `(x_min, y_min, x_max, y_max, score, class)`. Shape: `(N, 5)` or - `(N, 6)`, where N is the number of predictions. - masks (np.ndarray): A 3D array of binary masks corresponding to the predictions. - Shape: `(N, H, W)`, where N is the number of predictions, and H, W are the - dimensions of each mask. - iou_threshold (float, optional): The intersection-over-union threshold - to use for non-maximum suppression. - mask_dimension (int, optional): The dimension to which the masks should be - resized before computing IOU values. Defaults to 640. - - Returns: - np.ndarray: A boolean array indicating which predictions to keep after - non-maximum suppression. - - Raises: - AssertionError: If `iou_threshold` is not within the closed - range from `0` to `1`. - """ - assert 0 <= iou_threshold <= 1, ( - "Value of `iou_threshold` must be in the closed range from 0 to 1, " - f"{iou_threshold} given." - ) - rows, columns = predictions.shape - - if columns == 5: - predictions = np.c_[predictions, np.zeros(rows)] - - sort_index = predictions[:, 4].argsort()[::-1] - predictions = predictions[sort_index] - masks = masks[sort_index] - masks_resized = resize_masks(masks, mask_dimension) - ious = mask_iou_batch(masks_resized, masks_resized) - categories = predictions[:, 5] - - keep = np.ones(rows, dtype=bool) - for i in range(rows): - if keep[i]: - condition = (ious[i] > iou_threshold) & (categories[i] == categories) - keep[i + 1 :] = np.where(condition[i + 1 :], False, keep[i + 1 :]) - - return keep[sort_index.argsort()] - - -def box_non_max_suppression( - predictions: np.ndarray, iou_threshold: float = 0.5 -) -> np.ndarray: - """ - Perform Non-Maximum Suppression (NMS) on object detection predictions. - - Args: - predictions (np.ndarray): An array of object detection predictions in - the format of `(x_min, y_min, x_max, y_max, score)` - or `(x_min, y_min, x_max, y_max, score, class)`. - iou_threshold (float, optional): The intersection-over-union threshold - to use for non-maximum suppression. - - Returns: - np.ndarray: A boolean array indicating which predictions to keep after n - on-maximum suppression. - - Raises: - AssertionError: If `iou_threshold` is not within the - closed range from `0` to `1`. - """ - assert 0 <= iou_threshold <= 1, ( - "Value of `iou_threshold` must be in the closed range from 0 to 1, " - f"{iou_threshold} given." - ) - rows, columns = predictions.shape - - # add column #5 - category filled with zeros for agnostic nms - if columns == 5: - predictions = np.c_[predictions, np.zeros(rows)] - - # sort predictions column #4 - score - sort_index = np.flip(predictions[:, 4].argsort()) - predictions = predictions[sort_index] - - boxes = predictions[:, :4] - categories = predictions[:, 5] - ious = box_iou_batch(boxes, boxes) - ious = ious - np.eye(rows) - - keep = np.ones(rows, dtype=bool) - - for index, (iou, category) in enumerate(zip(ious, categories)): - if not keep[index]: - continue - - # drop detections with iou > iou_threshold and - # same category as current detections - condition = (iou > iou_threshold) & (categories == category) - keep = keep & ~condition - - return keep[sort_index.argsort()] - - def clip_boxes(xyxy: np.ndarray, resolution_wh: Tuple[int, int]) -> np.ndarray: """ Clips bounding boxes coordinates to fit within the frame resolution. @@ -289,6 +155,25 @@ def clip_boxes(xyxy: np.ndarray, resolution_wh: Tuple[int, int]) -> np.ndarray: np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds to a bounding box with coordinates clipped to fit within the frame resolution. + + Examples: + ```python + import numpy as np + import supervision as sv + + xyxy = np.array([ + [10, 20, 300, 200], + [15, 25, 350, 450], + [-10, -20, 30, 40] + ]) + + sv.clip_boxes(xyxy=xyxy, resolution_wh=(320, 240)) + # array([ + # [ 10, 20, 300, 200], + # [ 15, 25, 320, 240], + # [ 0, 0, 30, 40] + # ]) + ``` """ result = np.copy(xyxy) width, height = resolution_wh @@ -297,6 +182,52 @@ def clip_boxes(xyxy: np.ndarray, resolution_wh: Tuple[int, int]) -> np.ndarray: return result +def pad_boxes(xyxy: np.ndarray, px: int, py: Optional[int] = None) -> np.ndarray: + """ + Pads bounding boxes coordinates with a constant padding. + + Args: + xyxy (np.ndarray): A numpy array of shape `(N, 4)` where each + row corresponds to a bounding box in the format + `(x_min, y_min, x_max, y_max)`. + px (int): The padding value to be added to both the left and right sides of + each bounding box. + py (Optional[int]): The padding value to be added to both the top and bottom + sides of each bounding box. If not provided, `px` will be used for both + dimensions. + + Returns: + np.ndarray: A numpy array of shape `(N, 4)` where each row corresponds to a + bounding box with coordinates padded according to the provided padding + values. + + Examples: + ```python + import numpy as np + import supervision as sv + + xyxy = np.array([ + [10, 20, 30, 40], + [15, 25, 35, 45] + ]) + + sv.pad_boxes(xyxy=xyxy, px=5, py=10) + # array([ + # [ 5, 10, 35, 50], + # [10, 15, 40, 55] + # ]) + ``` + """ + if py is None: + py = px + + result = xyxy.copy() + result[:, [0, 1]] -= [px, py] + result[:, [2, 3]] += [px, py] + + return result + + def xywh_to_xyxy(boxes_xywh: np.ndarray) -> np.ndarray: xyxy = boxes_xywh.copy() xyxy[:, 2] = boxes_xywh[:, 0] + boxes_xywh[:, 2] @@ -317,7 +248,7 @@ def mask_to_xyxy(masks: np.ndarray) -> np.ndarray: `(x_min, y_min, x_max, y_max)` for each mask """ n = masks.shape[0] - bboxes = np.zeros((n, 4), dtype=int) + xyxy = np.zeros((n, 4), dtype=int) for i, mask in enumerate(masks): rows, cols = np.where(mask) @@ -325,9 +256,9 @@ def mask_to_xyxy(masks: np.ndarray) -> np.ndarray: if len(rows) > 0 and len(cols) > 0: x_min, x_max = np.min(cols), np.max(cols) y_min, y_max = np.min(rows), np.max(rows) - bboxes[i, :] = [x_min, y_min, x_max, y_max] + xyxy[i, :] = [x_min, y_min, x_max, y_max] - return bboxes + return xyxy def mask_to_polygons(mask: np.ndarray) -> List[np.ndarray]: @@ -500,7 +431,7 @@ def process_roboflow_result( np.ndarray, Optional[np.ndarray], Optional[np.ndarray], - Dict[str, List[np.ndarray]], + Dict[str, Union[List[np.ndarray], np.ndarray]], ]: if not roboflow_result["predictions"]: return ( @@ -563,59 +494,103 @@ def process_roboflow_result( return xyxy, confidence, class_id, masks, tracker_id, data -def move_boxes(xyxy: np.ndarray, offset: np.ndarray) -> np.ndarray: +def move_boxes( + xyxy: npt.NDArray[np.float64], offset: npt.NDArray[np.int32] +) -> npt.NDArray[np.float64]: """ Parameters: - xyxy (np.ndarray): An array of shape `(n, 4)` containing the bounding boxes - coordinates in format `[x1, y1, x2, y2]` + xyxy (npt.NDArray[np.float64]): An array of shape `(n, 4)` containing the + bounding boxes coordinates in format `[x1, y1, x2, y2]` offset (np.array): An array of shape `(2,)` containing offset values in format is `[dx, dy]`. Returns: - np.ndarray: Repositioned bounding boxes. + npt.NDArray[np.float64]: Repositioned bounding boxes. - Example: + Examples: ```python import numpy as np import supervision as sv - boxes = np.array([[10, 10, 20, 20], [30, 30, 40, 40]]) + xyxy = np.array([ + [10, 10, 20, 20], + [30, 30, 40, 40] + ]) offset = np.array([5, 5]) - moved_box = sv.move_boxes(boxes, offset) - print(moved_box) - # np.array([ + + sv.move_boxes(xyxy=xyxy, offset=offset) + # array([ # [15, 15, 25, 25], - # [35, 35, 45, 45] + # [35, 35, 45, 45] # ]) ``` """ return xyxy + np.hstack([offset, offset]) -def scale_boxes(xyxy: np.ndarray, factor: float) -> np.ndarray: +def move_masks( + masks: npt.NDArray[np.bool_], + offset: npt.NDArray[np.int32], + resolution_wh: Tuple[int, int], +) -> npt.NDArray[np.bool_]: + """ + Offset the masks in an array by the specified (x, y) amount. + + Args: + masks (npt.NDArray[np.bool_]): A 3D array of binary masks corresponding to the + predictions. Shape: `(N, H, W)`, where N is the number of predictions, and + H, W are the dimensions of each mask. + offset (npt.NDArray[np.int32]): An array of shape `(2,)` containing non-negative + int values `[dx, dy]`. + resolution_wh (Tuple[int, int]): The width and height of the desired mask + resolution. + + Returns: + (npt.NDArray[np.bool_]) repositioned masks, optionally padded to the specified + shape. + """ + + if offset[0] < 0 or offset[1] < 0: + raise ValueError(f"Offset values must be non-negative integers. Got: {offset}") + + mask_array = np.full((masks.shape[0], resolution_wh[1], resolution_wh[0]), False) + mask_array[ + :, + offset[1] : masks.shape[1] + offset[1], + offset[0] : masks.shape[2] + offset[0], + ] = masks + + return mask_array + + +def scale_boxes( + xyxy: npt.NDArray[np.float64], factor: float +) -> npt.NDArray[np.float64]: """ Scale the dimensions of bounding boxes. Parameters: - xyxy (np.ndarray): An array of shape `(n, 4)` containing the bounding boxes - coordinates in format `[x1, y1, x2, y2]` + xyxy (npt.NDArray[np.float64]): An array of shape `(n, 4)` containing the + bounding boxes coordinates in format `[x1, y1, x2, y2]` factor (float): A float value representing the factor by which the box dimensions are scaled. A factor greater than 1 enlarges the boxes, while a factor less than 1 shrinks them. Returns: - np.ndarray: Scaled bounding boxes. + npt.NDArray[np.float64]: Scaled bounding boxes. - Example: + Examples: ```python import numpy as np import supervision as sv - boxes = np.array([[10, 10, 20, 20], [30, 30, 40, 40]]) - factor = 1.5 - scaled_bb = sv.scale_boxes(boxes, factor) - print(scaled_bb) - # np.array([ + xyxy = np.array([ + [10, 10, 20, 20], + [30, 30, 40, 40] + ]) + + sv.scale_boxes(xyxy=xyxy, factor=1.5) + # array([ # [ 7.5, 7.5, 22.5, 22.5], # [27.5, 27.5, 42.5, 42.5] # ]) @@ -672,17 +647,19 @@ def is_data_equal(data_a: Dict[str, np.ndarray], data_b: Dict[str, np.ndarray]) def merge_data( - data_list: List[Dict[str, Union[np.ndarray, List]]], -) -> Dict[str, Union[np.ndarray, List]]: + data_list: List[Dict[str, Union[npt.NDArray[np.generic], List]]], +) -> Dict[str, Union[npt.NDArray[np.generic], List]]: """ Merges the data payloads of a list of Detections instances. Args: - data_list: The data payloads of the instances. + data_list: The data payloads of the Detections instances. Each data payload + is a dictionary with the same keys, and the values are either lists or + npt.NDArray[np.generic]. Returns: A single data payload containing the merged data, preserving the original data - types (list or np.ndarray). + types (list or npt.NDArray[np.generic]). Raises: ValueError: If data values within a single object have different lengths or if @@ -703,9 +680,8 @@ def merge_data( ) merged_data = {key: [] for key in all_keys_sets[0]} - for data in data_list: - for key in merged_data: + for key in data: merged_data[key].append(data[key]) for key in merged_data: @@ -766,3 +742,138 @@ def get_data_item( raise TypeError(f"Unsupported data type for key '{key}': {type(value)}") return subset_data + + +def contains_holes(mask: npt.NDArray[np.bool_]) -> bool: + """ + Checks if the binary mask contains holes (background pixels fully enclosed by + foreground pixels). + + Args: + mask (npt.NDArray[np.bool_]): 2D binary mask where `True` indicates foreground + object and `False` indicates background. + + Returns: + True if holes are detected, False otherwise. + + Examples: + ```python + import numpy as np + import supervision as sv + + mask = np.array([ + [0, 0, 0, 0, 0], + [0, 1, 1, 1, 0], + [0, 1, 0, 1, 0], + [0, 1, 1, 1, 0], + [0, 0, 0, 0, 0] + ]).astype(bool) + + sv.contains_holes(mask=mask) + # True + + mask = np.array([ + [0, 0, 0, 0, 0], + [0, 1, 1, 1, 0], + [0, 1, 1, 1, 0], + [0, 1, 1, 1, 0], + [0, 0, 0, 0, 0] + ]).astype(bool) + + sv.contains_holes(mask=mask) + # False + ``` + + ![contains_holes](https://media.roboflow.com/supervision-docs/contains-holes.png){ align=center width="800" } + """ # noqa E501 // docs + mask_uint8 = mask.astype(np.uint8) + _, hierarchy = cv2.findContours(mask_uint8, cv2.RETR_CCOMP, cv2.CHAIN_APPROX_SIMPLE) + + if hierarchy is not None: + parent_contour_index = 3 + for h in hierarchy[0]: + if h[parent_contour_index] != -1: + return True + return False + + +def contains_multiple_segments( + mask: npt.NDArray[np.bool_], connectivity: int = 4 +) -> bool: + """ + Checks if the binary mask contains multiple unconnected foreground segments. + + Args: + mask (npt.NDArray[np.bool_]): 2D binary mask where `True` indicates foreground + object and `False` indicates background. + connectivity (int) : Default: 4 is 4-way connectivity, which means that + foreground pixels are the part of the same segment/component + if their edges touch. + Alternatively: 8 for 8-way connectivity, when foreground pixels are + connected by their edges or corners touch. + + Returns: + True when the mask contains multiple not connected components, False otherwise. + + Raises: + ValueError: If connectivity(int) parameter value is not 4 or 8. + + Examples: + ```python + import numpy as np + import supervision as sv + + mask = np.array([ + [0, 0, 0, 0, 0, 0], + [0, 1, 1, 0, 1, 1], + [0, 1, 1, 0, 1, 1], + [0, 0, 0, 0, 0, 0], + [0, 1, 1, 1, 0, 0], + [0, 1, 1, 1, 0, 0] + ]).astype(bool) + + sv.contains_multiple_segments(mask=mask, connectivity=4) + # True + + mask = np.array([ + [0, 0, 0, 0, 0, 0], + [0, 1, 1, 1, 1, 1], + [0, 1, 1, 1, 1, 1], + [0, 1, 1, 1, 1, 1], + [0, 1, 1, 1, 1, 1], + [0, 0, 0, 0, 0, 0] + ]).astype(bool) + + sv.contains_multiple_segments(mask=mask, connectivity=4) + # False + ``` + + ![contains_multiple_segments](https://media.roboflow.com/supervision-docs/contains-multiple-segments.png){ align=center width="800" } + """ # noqa E501 // docs + if connectivity != 4 and connectivity != 8: + raise ValueError( + "Incorrect connectivity value. Possible connectivity values: 4 or 8." + ) + mask_uint8 = mask.astype(np.uint8) + labels = np.zeros_like(mask_uint8, dtype=np.int32) + number_of_labels, _ = cv2.connectedComponents( + mask_uint8, labels, connectivity=connectivity + ) + return number_of_labels > 2 + + +def cross_product(anchors: np.ndarray, vector: Vector) -> np.ndarray: + """ + Get array of cross products of each anchor with a vector. + Args: + anchors: Array of anchors of shape (number of anchors, detections, 2) + vector: Vector to calculate cross product with + + Returns: + Array of cross products of shape (number of anchors, detections) + """ + vector_at_zero = np.array( + [vector.end.x - vector.start.x, vector.end.y - vector.start.y] + ) + vector_start = np.array([vector.start.x, vector.start.y]) + return np.cross(vector_at_zero, anchors - vector_start) diff --git a/supervision/draw/utils.py b/supervision/draw/utils.py index 638e6b75..6783ae25 100644 --- a/supervision/draw/utils.py +++ b/supervision/draw/utils.py @@ -81,6 +81,58 @@ def draw_filled_rectangle(scene: np.ndarray, rect: Rect, color: Color) -> np.nda return scene +def draw_rounded_rectangle( + scene: np.ndarray, + rect: Rect, + color: Color, + border_radius: int, +) -> np.ndarray: + """ + Draws a rounded rectangle on an image. + + Parameters: + scene (np.ndarray): The image on which the rounded rectangle will be drawn. + rect (Rect): The rectangle to be drawn. + color (Color): The color of the rounded rectangle. + border_radius (int): The radius of the corner rounding. + + Returns: + np.ndarray: The image with the rounded rectangle drawn on it. + """ + x1, y1, x2, y2 = rect.as_xyxy_int_tuple() + width, height = x2 - x1, y2 - y1 + border_radius = min(border_radius, min(width, height) // 2) + + rectangle_coordinates = [ + ((x1 + border_radius, y1), (x2 - border_radius, y2)), + ((x1, y1 + border_radius), (x2, y2 - border_radius)), + ] + circle_centers = [ + (x1 + border_radius, y1 + border_radius), + (x2 - border_radius, y1 + border_radius), + (x1 + border_radius, y2 - border_radius), + (x2 - border_radius, y2 - border_radius), + ] + + for coordinates in rectangle_coordinates: + cv2.rectangle( + img=scene, + pt1=coordinates[0], + pt2=coordinates[1], + color=color.as_bgr(), + thickness=-1, + ) + for center in circle_centers: + cv2.circle( + img=scene, + center=center, + radius=border_radius, + color=color.as_bgr(), + thickness=-1, + ) + return scene + + def draw_polygon( scene: np.ndarray, polygon: np.ndarray, color: Color, thickness: int = 2 ) -> np.ndarray: diff --git a/supervision/geometry/core.py b/supervision/geometry/core.py index 39d42c60..a884a9da 100644 --- a/supervision/geometry/core.py +++ b/supervision/geometry/core.py @@ -98,6 +98,11 @@ class Rect: width: float height: float + @classmethod + def from_xyxy(cls, xyxy: Tuple[float, float, float, float]) -> Rect: + x1, y1, x2, y2 = xyxy + return cls(x=x1, y=y1, width=x2 - x1, height=y2 - y1) + @property def top_left(self) -> Point: return Point(x=self.x, y=self.y) @@ -113,3 +118,11 @@ class Rect: width=self.width + 2 * padding, height=self.height + 2 * padding, ) + + def as_xyxy_int_tuple(self) -> Tuple[int, int, int, int]: + return ( + int(self.x), + int(self.y), + int(self.x + self.width), + int(self.y + self.height), + ) diff --git a/supervision/keypoint/annotators.py b/supervision/keypoint/annotators.py index 4b43765c..e6ff1fcf 100644 --- a/supervision/keypoint/annotators.py +++ b/supervision/keypoint/annotators.py @@ -1,12 +1,14 @@ from abc import ABC, abstractmethod from logging import warn -from typing import List, Optional, Tuple +from typing import List, Optional, Tuple, Union import cv2 import numpy as np +from supervision import Rect, pad_boxes from supervision.annotators.base import ImageType from supervision.draw.color import Color +from supervision.draw.utils import draw_rounded_rectangle from supervision.keypoint.core import KeyPoints from supervision.keypoint.skeletons import SKELETONS_BY_VERTEX_COUNT from supervision.utils.conversion import convert_for_annotation_method @@ -46,8 +48,8 @@ class VertexAnnotator(BaseKeyPointAnnotator): points. It draws circles at each key point location. Args: - scene (ImageType): The image where bounding boxes will be drawn. `ImageType` - is a flexible type, accepting either `numpy.ndarray` or + scene (ImageType): The image where skeleton vertices will be drawn. + `ImageType` is a flexible type, accepting either `numpy.ndarray` or `PIL.Image.Image`. key_points (KeyPoints): A collection of key points where each key point consists of x and y coordinates. @@ -63,7 +65,10 @@ class VertexAnnotator(BaseKeyPointAnnotator): image = ... key_points = sv.KeyPoints(...) - vertex_annotator = sv.VertexAnnotator(color=sv.Color.GREEN, radius=10) + vertex_annotator = sv.VertexAnnotator( + color=sv.Color.GREEN, + radius=10 + ) annotated_frame = vertex_annotator.annotate( scene=image.copy(), key_points=key_points @@ -119,7 +124,7 @@ class EdgeAnnotator(BaseKeyPointAnnotator): edges. Args: - scene (ImageType): The image where bounding boxes will be drawn. `ImageType` + scene (ImageType): The image where skeleton edges will be drawn. `ImageType` is a flexible type, accepting either `numpy.ndarray` or `PIL.Image.Image`. key_points (KeyPoints): A collection of key points where each key point @@ -137,7 +142,10 @@ class EdgeAnnotator(BaseKeyPointAnnotator): image = ... key_points = sv.KeyPoints(...) - edge_annotator = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5) + edge_annotator = sv.EdgeAnnotator( + color=sv.Color.GREEN, + thickness=5 + ) annotated_frame = edge_annotator.annotate( scene=image.copy(), key_points=key_points @@ -175,3 +183,236 @@ class EdgeAnnotator(BaseKeyPointAnnotator): ) return scene + + +class VertexLabelAnnotator: + """ + A class that draws labels of skeleton vertices on images. It uses specified key + points to determine the locations where the vertices should be drawn. + """ + + def __init__( + self, + color: Union[Color, List[Color]] = Color.ROBOFLOW, + text_color: Color = Color.WHITE, + text_scale: float = 0.5, + text_thickness: int = 1, + text_padding: int = 10, + border_radius: int = 0, + ): + """ + Args: + color (Union[Color, List[Color]], optional): The color to use for each + keypoint label. If a list is provided, the colors will be used in order + for each keypoint. + text_color (Color, optional): The color to use for the labels. + text_scale (float, optional): The scale of the text. + text_thickness (int, optional): The thickness of the text. + text_padding (int, optional): The padding around the text. + border_radius (int, optional): The radius of the rounded corners of the + boxes. Set to a high value to produce circles. + """ + self.border_radius: int = border_radius + self.color: Union[Color, List[Color]] = color + self.text_color: Color = text_color + self.text_scale: float = text_scale + self.text_thickness: int = text_thickness + self.text_padding: int = text_padding + + def annotate( + self, scene: ImageType, key_points: KeyPoints, labels: List[str] = None + ) -> ImageType: + """ + A class that draws labels of skeleton vertices on images. It uses specified key + points to determine the locations where the vertices should be drawn. + + Args: + scene (ImageType): The image where vertex labels will be drawn. `ImageType` + is a flexible type, accepting either `numpy.ndarray` or + `PIL.Image.Image`. + key_points (KeyPoints): A collection of key points where each key point + consists of x and y coordinates. + labels (List[str], optional): A list of labels to be displayed on the + annotated image. If not provided, keypoint indices will be used. + + Returns: + The annotated image, matching the type of `scene` (`numpy.ndarray` + or `PIL.Image.Image`) + + Example: + ```python + import supervision as sv + + image = ... + key_points = sv.KeyPoints(...) + + vertex_label_annotator = sv.VertexLabelAnnotator( + color=sv.Color.GREEN, + text_color=sv.Color.BLACK, + border_radius=5 + ) + annotated_frame = vertex_label_annotator.annotate( + scene=image.copy(), + key_points=key_points + ) + ``` + + ![vertex-label-annotator-example](https://media.roboflow.com/ + supervision-annotator-examples/vertex-label-annotator-example.png) + + !!! tip + + `VertexLabelAnnotator` allows to customize the color of each keypoint label + values. + + Example: + ```python + import supervision as sv + + image = ... + key_points = sv.KeyPoints(...) + + LABELS = [ + "nose", "left eye", "right eye", "left ear", + "right ear", "left shoulder", "right shoulder", "left elbow", + "right elbow", "left wrist", "right wrist", "left hip", + "right hip", "left knee", "right knee", "left ankle", + "right ankle" + ] + + COLORS = [ + "#FF6347", "#FF6347", "#FF6347", "#FF6347", + "#FF6347", "#FF1493", "#00FF00", "#FF1493", + "#00FF00", "#FF1493", "#00FF00", "#FFD700", + "#00BFFF", "#FFD700", "#00BFFF", "#FFD700", + "#00BFFF" + ] + COLORS = [sv.Color.from_hex(color_hex=c) for c in COLORS] + + vertex_label_annotator = sv.VertexLabelAnnotator( + color=COLORS, + text_color=sv.Color.BLACK, + border_radius=5 + ) + annotated_frame = vertex_label_annotator.annotate( + scene=image.copy(), + key_points=key_points, + labels=labels + ) + ``` + ![vertex-label-annotator-custom-example](https://media.roboflow.com/ + supervision-annotator-examples/vertex-label-annotator-custom-example.png) + """ + font = cv2.FONT_HERSHEY_SIMPLEX + + skeletons_count, points_count, _ = key_points.xy.shape + if skeletons_count == 0: + return scene + + anchors = key_points.xy.reshape(points_count * skeletons_count, 2).astype(int) + mask = np.all(anchors != 0, axis=1) + + if not np.any(mask): + return scene + + colors = self.preprocess_and_validate_colors( + colors=self.color, + points_count=points_count, + skeletons_count=skeletons_count, + ) + + labels = self.preprocess_and_validate_labels( + labels=labels, points_count=points_count, skeletons_count=skeletons_count + ) + + anchors = anchors[mask] + colors = colors[mask] + labels = labels[mask] + + xyxy = np.array( + [ + self.get_text_bounding_box( + text=label, + font=font, + text_scale=self.text_scale, + text_thickness=self.text_thickness, + center_coordinates=tuple(anchor), + ) + for anchor, label in zip(anchors, labels) + ] + ) + + xyxy_padded = pad_boxes(xyxy=xyxy, px=self.text_padding) + + for text, color, box, box_padded in zip(labels, colors, xyxy, xyxy_padded): + draw_rounded_rectangle( + scene=scene, + rect=Rect.from_xyxy(box_padded), + color=color, + border_radius=self.border_radius, + ) + cv2.putText( + img=scene, + text=text, + org=(box[0], box[1] + self.text_padding), + fontFace=font, + fontScale=self.text_scale, + color=self.text_color.as_rgb(), + thickness=self.text_thickness, + lineType=cv2.LINE_AA, + ) + + return scene + + @staticmethod + def get_text_bounding_box( + text: str, + font: int, + text_scale: float, + text_thickness: int, + center_coordinates: Tuple[int, int], + ) -> Tuple[int, int, int, int]: + text_w, text_h = cv2.getTextSize( + text=text, + fontFace=font, + fontScale=text_scale, + thickness=text_thickness, + )[0] + center_x, center_y = center_coordinates + return ( + center_x - text_w // 2, + center_y - text_h // 2, + center_x + text_w // 2, + center_y + text_h // 2, + ) + + @staticmethod + def preprocess_and_validate_labels( + labels: Optional[List[str]], points_count: int, skeletons_count: int + ) -> np.array: + if labels and len(labels) != points_count: + raise ValueError( + f"Number of labels ({len(labels)}) must match number of key points " + f"({points_count})." + ) + if labels is None: + labels = [str(i) for i in range(points_count)] + + return np.array(labels * skeletons_count) + + @staticmethod + def preprocess_and_validate_colors( + colors: Optional[Union[Color, List[Color]]], + points_count: int, + skeletons_count: int, + ) -> np.array: + if isinstance(colors, list) and len(colors) != points_count: + raise ValueError( + f"Number of colors ({len(colors)}) must match number of key points " + f"({points_count})." + ) + return ( + np.array(colors * skeletons_count) + if isinstance(colors, list) + else np.array([colors] * points_count * skeletons_count) + ) diff --git a/supervision/keypoint/core.py b/supervision/keypoint/core.py index 8a97b51c..87ad9579 100644 --- a/supervision/keypoint/core.py +++ b/supervision/keypoint/core.py @@ -1,5 +1,6 @@ from __future__ import annotations +from contextlib import suppress from dataclasses import dataclass, field from typing import Any, Dict, Iterator, List, Optional, Tuple, Union @@ -100,10 +101,94 @@ class KeyPoints: ] ) + @classmethod + def from_inference(cls, inference_result: Union[dict, Any]) -> KeyPoints: + """ + Create a `sv.KeyPoints` object from the [Roboflow](https://roboflow.com/) + API inference result or the [Inference](https://inference.roboflow.com/) + package results. When a keypoint detection model is used, this method + extracts the keypoint coordinates, class IDs, confidences, and class names. + + Args: + inference_result (dict, any): The result from the + Roboflow API or Inference package containing predictions with keypoints. + + Returns: + (KeyPoints): A KeyPoints object containing the keypoint coordinates, + class IDs, and confidences of each keypoint. + + Example: + ```python + import cv2 + import supervision as sv + from inference import get_model + + image = cv2.imread() + model = get_model(model_id=, api_key=) + + result = model.infer(image)[0] + key_points = sv.KeyPoints.from_inference(result) + ``` + + ```python + import cv2 + import supervision as sv + from inference_sdk import InferenceHTTPClient + + image = cv2.imread() + client = InferenceHTTPClient( + api_url="https://detect.roboflow.com", + api_key= + ) + + result = client.infer(image, model_id=) + key_points = sv.KeyPoints.from_inference(result) + ``` + """ + if isinstance(inference_result, list): + raise ValueError( + "from_inference() operates on a single result at a time." + "You can retrieve it like so: inference_result = model.infer(image)[0]" + ) + + # Unpack the result if received from inference.get_model, + # rather than inference_sdk.InferenceHTTPClient + with suppress(AttributeError): + inference_result = inference_result.dict(exclude_none=True, by_alias=True) + + if not inference_result.get("predictions"): + return cls.empty() + + xy = [] + confidence = [] + class_id = [] + class_names = [] + + for prediction in inference_result["predictions"]: + prediction_xy = [] + prediction_confidence = [] + for keypoint in prediction["keypoints"]: + prediction_xy.append([keypoint["x"], keypoint["y"]]) + prediction_confidence.append(keypoint["confidence"]) + xy.append(prediction_xy) + confidence.append(prediction_confidence) + + class_id.append(prediction["class_id"]) + class_names.append(prediction["class"]) + + data = {CLASS_NAME_DATA_FIELD: np.array(class_names)} + + return cls( + xy=np.array(xy, dtype=np.float32), + confidence=np.array(confidence, dtype=np.float32), + class_id=np.array(class_id, dtype=int), + data=data, + ) + @classmethod def from_ultralytics(cls, ultralytics_results) -> KeyPoints: """ - Creates a Keypoints instance from a + Creates a KeyPoints instance from a [YOLOv8](https://github.com/ultralytics/ultralytics) inference result. Args: @@ -111,7 +196,7 @@ class KeyPoints: The output Results instance from YOLOv8 Returns: - KeyPoints: A new Keypoints object. + KeyPoints: A new KeyPoints object. Example: ```python @@ -136,9 +221,66 @@ class KeyPoints: data = {CLASS_NAME_DATA_FIELD: class_names} return cls(xy, class_id, confidence, data) + @classmethod + def from_yolo_nas(cls, yolo_nas_results) -> KeyPoints: + """ + Create a KeyPoints instance from a YOLO NAS results. + + Args: + yolo_nas_results (ImagePoseEstimationPrediction): + The output object from YOLO NAS. + + Returns: + KeyPoints: A new KeyPoints object. + + Example: + ```python + import cv2 + import torch + import supervision as sv + import super_gradients + + image = cv2.imread() + + device = "cuda" if torch.cuda.is_available() else "cpu" + yolo_nas = super_gradients.training.models.get( + "yolo_nas_pose_s", pretrained_weights="coco_pose").to(device) + + results = yolo_nas.predict(image, conf=0.1) + keypoints = sv.KeyPoints.from_yolo_nas(results) + ``` + """ + if len(yolo_nas_results.prediction.poses) == 0: + return cls.empty() + + xy = yolo_nas_results.prediction.poses[:, :, :2] + confidence = yolo_nas_results.prediction.poses[:, :, 2] + + # yolo_nas_results treats params differently. + # prediction.labels may not exist, whereas class_names might be None + if hasattr(yolo_nas_results.prediction, "labels"): + class_id = yolo_nas_results.prediction.labels # np.array[int] + else: + class_id = None + + data = {} + if class_id is not None and yolo_nas_results.class_names is not None: + class_names = [] + for c_id in class_id: + name = yolo_nas_results.class_names[c_id] # tuple[str] + class_names.append(name) + data[CLASS_NAME_DATA_FIELD] = class_names + + return cls( + xy=xy, + confidence=confidence, + class_id=class_id, + data=data, + ) + def __getitem__( self, index: Union[int, slice, List[int], np.ndarray, str] - ) -> Union["KeyPoints", List, np.ndarray, None]: + ) -> Union[KeyPoints, List, np.ndarray, None]: """ Get a subset of the KeyPoints object or access an item from its data field. diff --git a/supervision/tracker/byte_tracker/core.py b/supervision/tracker/byte_tracker/core.py index c77878cf..ce3bbbbf 100644 --- a/supervision/tracker/byte_tracker/core.py +++ b/supervision/tracker/byte_tracker/core.py @@ -12,8 +12,9 @@ from supervision.utils.internal import deprecated_parameter class STrack(BaseTrack): shared_kalman = KalmanFilter() + _external_count = 0 - def __init__(self, tlwh, score, class_ids): + def __init__(self, tlwh, score, class_ids, minimum_consecutive_frames): # wait activate self._tlwh = np.asarray(tlwh, dtype=np.float32) self.kalman_filter = None @@ -24,6 +25,10 @@ class STrack(BaseTrack): self.class_ids = class_ids self.tracklet_len = 0 + self.external_track_id = -1 + + self.minimum_consecutive_frames = minimum_consecutive_frames + def predict(self): mean_state = self.mean.copy() if self.state != TrackState.Tracked: @@ -53,7 +58,7 @@ class STrack(BaseTrack): def activate(self, kalman_filter, frame_id): """Start a new tracklet""" self.kalman_filter = kalman_filter - self.track_id = self.next_id() + self.internal_track_id = self.next_id() self.mean, self.covariance = self.kalman_filter.initiate( self.tlwh_to_xyah(self._tlwh) ) @@ -62,6 +67,10 @@ class STrack(BaseTrack): self.state = TrackState.Tracked if frame_id == 1: self.is_activated = True + + if self.minimum_consecutive_frames == 1: + self.external_track_id = self.next_external_id() + self.frame_id = frame_id self.start_frame = frame_id @@ -71,10 +80,10 @@ class STrack(BaseTrack): ) self.tracklet_len = 0 self.state = TrackState.Tracked - self.is_activated = True + self.frame_id = frame_id if new_id: - self.track_id = self.next_id() + self.internal_track_id = self.next_id() self.score = new_track.score def update(self, new_track, frame_id): @@ -93,7 +102,10 @@ class STrack(BaseTrack): self.mean, self.covariance, self.tlwh_to_xyah(new_tlwh) ) self.state = TrackState.Tracked - self.is_activated = True + if self.tracklet_len == self.minimum_consecutive_frames: + self.is_activated = True + if self.external_track_id == -1: + self.external_track_id = self.next_external_id() self.score = new_track.score @@ -131,6 +143,15 @@ class STrack(BaseTrack): def to_xyah(self): return self.tlwh_to_xyah(self.tlwh) + @staticmethod + def next_external_id(): + STrack._external_count += 1 + return STrack._external_count + + @staticmethod + def reset_external_counter(): + STrack._external_count = 0 + @staticmethod def tlbr_to_tlwh(tlbr): ret = np.asarray(tlbr).copy() @@ -144,7 +165,9 @@ class STrack(BaseTrack): return ret def __repr__(self): - return "OT_{}_({}-{})".format(self.track_id, self.start_frame, self.end_frame) + return "OT_{}_({}-{})".format( + self.internal_track_id, self.start_frame, self.end_frame + ) def detections2boxes(detections: Detections) -> np.ndarray: @@ -186,6 +209,10 @@ class ByteTrack: Increasing minimum_matching_threshold improves accuracy but risks fragmentation. Decreasing it improves completeness but risks false positives and drift. frame_rate (int, optional): The frame rate of the video. + minimum_consecutive_frames (int, optional): Number of consecutive frames that an object must + be tracked before it is considered a 'valid' track. + Increasing minimum_consecutive_frames prevents the creation of accidental tracks from + false detection or double detection, but risks missing shorter tracks. """ # noqa: E501 // docs @deprecated_parameter( @@ -218,6 +245,7 @@ class ByteTrack: lost_track_buffer: int = 30, minimum_matching_threshold: float = 0.8, frame_rate: int = 30, + minimum_consecutive_frames: int = 1, ): self.track_activation_threshold = track_activation_threshold self.minimum_matching_threshold = minimum_matching_threshold @@ -225,6 +253,7 @@ class ByteTrack: self.frame_id = 0 self.det_thresh = self.track_activation_threshold + 0.1 self.max_time_lost = int(frame_rate / 30.0 * lost_track_buffer) + self.minimum_consecutive_frames = minimum_consecutive_frames self.kalman_filter = KalmanFilter() self.tracked_tracks: List[STrack] = [] @@ -285,11 +314,14 @@ class ByteTrack: matches, _, _ = matching.linear_assignment(iou_costs, 0.5) detections.tracker_id = np.full(len(detections), -1, dtype=int) for i_detection, i_track in matches: - detections.tracker_id[i_detection] = int(tracks[i_track].track_id) + detections.tracker_id[i_detection] = int( + tracks[i_track].external_track_id + ) return detections[detections.tracker_id != -1] else: + detections = Detections.empty() detections.tracker_id = np.array([], dtype=int) return detections @@ -308,6 +340,7 @@ class ByteTrack: self.lost_tracks: List[STrack] = [] self.removed_tracks: List[STrack] = [] BaseTrack.reset_counter() + STrack.reset_external_counter() def update_with_tensors(self, tensors: np.ndarray) -> List[STrack]: """ @@ -345,7 +378,7 @@ class ByteTrack: if len(dets) > 0: """Detections""" detections = [ - STrack(STrack.tlbr_to_tlwh(tlbr), s, c) + STrack(STrack.tlbr_to_tlwh(tlbr), s, c, self.minimum_consecutive_frames) for (tlbr, s, c) in zip(dets, scores_keep, class_ids_keep) ] else: @@ -387,7 +420,7 @@ class ByteTrack: if len(dets_second) > 0: """Detections""" detections_second = [ - STrack(STrack.tlbr_to_tlwh(tlbr), s, c) + STrack(STrack.tlbr_to_tlwh(tlbr), s, c, self.minimum_consecutive_frames) for (tlbr, s, c) in zip(dets_second, scores_second, class_ids_second) ] else: @@ -454,7 +487,7 @@ class ByteTrack: self.lost_tracks = sub_tracks(self.lost_tracks, self.tracked_tracks) self.lost_tracks.extend(lost_stracks) self.lost_tracks = sub_tracks(self.lost_tracks, self.removed_tracks) - self.removed_tracks.extend(removed_stracks) + self.removed_tracks = removed_stracks self.tracked_tracks, self.lost_tracks = remove_duplicate_tracks( self.tracked_tracks, self.lost_tracks ) @@ -468,22 +501,22 @@ def joint_tracks( ) -> List[STrack]: """ Joins two lists of tracks, ensuring that the resulting list does not - contain tracks with duplicate track_id values. + contain tracks with duplicate internal_track_id values. Parameters: - track_list_a: First list of tracks (with track_id attribute). - track_list_b: Second list of tracks (with track_id attribute). + track_list_a: First list of tracks (with internal_track_id attribute). + track_list_b: Second list of tracks (with internal_track_id attribute). Returns: Combined list of tracks from track_list_a and track_list_b - without duplicate track_id values. + without duplicate internal_track_id values. """ seen_track_ids = set() result = [] for track in track_list_a + track_list_b: - if track.track_id not in seen_track_ids: - seen_track_ids.add(track.track_id) + if track.internal_track_id not in seen_track_ids: + seen_track_ids.add(track.internal_track_id) result.append(track) return result @@ -492,17 +525,17 @@ def joint_tracks( def sub_tracks(track_list_a: List, track_list_b: List) -> List[int]: """ Returns a list of tracks from track_list_a after removing any tracks - that share the same track_id with tracks in track_list_b. + that share the same internal_track_id with tracks in track_list_b. Parameters: - track_list_a: List of tracks (with track_id attribute). - track_list_b: List of tracks (with track_id attribute) to + track_list_a: List of tracks (with internal_track_id attribute). + track_list_b: List of tracks (with internal_track_id attribute) to be subtracted from track_list_a. Returns: List of remaining tracks from track_list_a after subtraction. """ - tracks = {track.track_id: track for track in track_list_a} - track_ids_b = {track.track_id for track in track_list_b} + tracks = {track.internal_track_id: track for track in track_list_a} + track_ids_b = {track.internal_track_id for track in track_list_b} for track_id in track_ids_b: tracks.pop(track_id, None) diff --git a/supervision/utils/internal.py b/supervision/utils/internal.py index 978a1448..072c03b7 100644 --- a/supervision/utils/internal.py +++ b/supervision/utils/internal.py @@ -1,7 +1,8 @@ import functools +import inspect import os import warnings -from typing import Callable +from typing import Any, Callable, Set class SupervisionWarnings(Warning): @@ -141,3 +142,42 @@ class classproperty(property): The result of calling the function stored in 'fget' with 'owner_cls'. """ return self.fget(owner_cls) + + +def get_instance_variables(instance: Any, include_properties=False) -> Set[str]: + """ + Get the public variables of a class instance. + + Args: + instance (Any): The instance of a class + include_properties (bool): Whether to include properties in the result + + Usage: + ```python + detections = Detections(xyxy=np.array([1,2,3,4])) + variables = get_class_variables(detections) + # ["xyxy", "mask", "confidence", ..., "data"] + ``` + """ + if isinstance(instance, type): + raise ValueError("Only class instances are supported, not classes.") + + fields = set( + ( + name + for name, val in inspect.getmembers(instance) + if not callable(val) and not name.startswith("_") + ) + ) + + if not include_properties: + properties = set( + ( + name + for name, val in inspect.getmembers(instance.__class__) + if isinstance(val, property) + ) + ) + fields -= properties + + return fields diff --git a/test/dataset/formats/test_coco.py b/test/dataset/formats/test_coco.py index 62d1b75b..7e269dae 100644 --- a/test/dataset/formats/test_coco.py +++ b/test/dataset/formats/test_coco.py @@ -1,5 +1,5 @@ from contextlib import ExitStack as DoesNotRaise -from typing import Dict, List, Tuple +from typing import Dict, List, Tuple, Union import numpy as np import pytest @@ -10,24 +10,30 @@ from supervision.dataset.formats.coco import ( classes_to_coco_categories, coco_annotations_to_detections, coco_categories_to_classes, + detections_to_coco_annotations, group_coco_annotations_by_image_id, ) -def mock_cock_coco_annotation( +def mock_coco_annotation( annotation_id: int = 0, image_id: int = 0, category_id: int = 0, bbox: Tuple[float, float, float, float] = (0.0, 0.0, 0.0, 0.0), area: float = 0.0, + segmentation: Union[List[list], Dict] = None, + iscrowd: bool = False, ) -> dict: + if not segmentation: + segmentation = [] return { "id": annotation_id, "image_id": image_id, "category_id": category_id, "bbox": list(bbox), "area": area, - "iscrowd": 0, + "segmentation": segmentation, + "iscrowd": int(iscrowd), } @@ -101,74 +107,46 @@ def test_classes_to_coco_categories_and_back_to_classes( [ ([], {}, DoesNotRaise()), # empty coco annotations ( - [mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0)], - { - 0: [ - mock_cock_coco_annotation( - annotation_id=0, image_id=0, category_id=0 - ) - ] - }, + [mock_coco_annotation(annotation_id=0, image_id=0, category_id=0)], + {0: [mock_coco_annotation(annotation_id=0, image_id=0, category_id=0)]}, DoesNotRaise(), ), # single coco annotation ( [ - mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0), - mock_cock_coco_annotation(annotation_id=1, image_id=1, category_id=0), + mock_coco_annotation(annotation_id=0, image_id=0, category_id=0), + mock_coco_annotation(annotation_id=1, image_id=1, category_id=0), ], { - 0: [ - mock_cock_coco_annotation( - annotation_id=0, image_id=0, category_id=0 - ) - ], - 1: [ - mock_cock_coco_annotation( - annotation_id=1, image_id=1, category_id=0 - ) - ], + 0: [mock_coco_annotation(annotation_id=0, image_id=0, category_id=0)], + 1: [mock_coco_annotation(annotation_id=1, image_id=1, category_id=0)], }, DoesNotRaise(), ), # two coco annotations ( [ - mock_cock_coco_annotation(annotation_id=0, image_id=0, category_id=0), - mock_cock_coco_annotation(annotation_id=1, image_id=1, category_id=1), - mock_cock_coco_annotation(annotation_id=2, image_id=1, category_id=2), - mock_cock_coco_annotation(annotation_id=3, image_id=2, category_id=3), - mock_cock_coco_annotation(annotation_id=4, image_id=3, category_id=1), - mock_cock_coco_annotation(annotation_id=5, image_id=3, category_id=2), - mock_cock_coco_annotation(annotation_id=5, image_id=3, category_id=3), + mock_coco_annotation(annotation_id=0, image_id=0, category_id=0), + mock_coco_annotation(annotation_id=1, image_id=1, category_id=1), + mock_coco_annotation(annotation_id=2, image_id=1, category_id=2), + mock_coco_annotation(annotation_id=3, image_id=2, category_id=3), + mock_coco_annotation(annotation_id=4, image_id=3, category_id=1), + mock_coco_annotation(annotation_id=5, image_id=3, category_id=2), + mock_coco_annotation(annotation_id=5, image_id=3, category_id=3), ], { 0: [ - mock_cock_coco_annotation( - annotation_id=0, image_id=0, category_id=0 - ), + mock_coco_annotation(annotation_id=0, image_id=0, category_id=0), ], 1: [ - mock_cock_coco_annotation( - annotation_id=1, image_id=1, category_id=1 - ), - mock_cock_coco_annotation( - annotation_id=2, image_id=1, category_id=2 - ), + mock_coco_annotation(annotation_id=1, image_id=1, category_id=1), + mock_coco_annotation(annotation_id=2, image_id=1, category_id=2), ], 2: [ - mock_cock_coco_annotation( - annotation_id=3, image_id=2, category_id=3 - ), + mock_coco_annotation(annotation_id=3, image_id=2, category_id=3), ], 3: [ - mock_cock_coco_annotation( - annotation_id=4, image_id=3, category_id=1 - ), - mock_cock_coco_annotation( - annotation_id=5, image_id=3, category_id=2 - ), - mock_cock_coco_annotation( - annotation_id=5, image_id=3, category_id=3 - ), + mock_coco_annotation(annotation_id=4, image_id=3, category_id=1), + mock_coco_annotation(annotation_id=5, image_id=3, category_id=2), + mock_coco_annotation(annotation_id=5, image_id=3, category_id=3), ], }, DoesNotRaise(), @@ -195,7 +173,7 @@ def test_group_coco_annotations_by_image_id( ), # empty image annotations ( [ - mock_cock_coco_annotation( + mock_coco_annotation( category_id=0, bbox=(0, 0, 100, 100), area=100 * 100 ) ], @@ -209,10 +187,10 @@ def test_group_coco_annotations_by_image_id( ), # single image annotations ( [ - mock_cock_coco_annotation( + mock_coco_annotation( category_id=0, bbox=(0, 0, 100, 100), area=100 * 100 ), - mock_cock_coco_annotation( + mock_coco_annotation( category_id=0, bbox=(100, 100, 100, 100), area=100 * 100 ), ], @@ -226,6 +204,156 @@ def test_group_coco_annotations_by_image_id( ), DoesNotRaise(), ), # two image annotations + ( + [ + mock_coco_annotation( + category_id=0, + bbox=(0, 0, 5, 5), + area=5 * 5, + segmentation=[[0, 0, 2, 0, 2, 2, 4, 2, 4, 4, 0, 4]], + ) + ], + (5, 5), + True, + Detections( + xyxy=np.array([[0, 0, 5, 5]], dtype=np.float32), + class_id=np.array([0], dtype=int), + mask=np.array( + [ + [ + [1, 1, 1, 0, 0], + [1, 1, 1, 0, 0], + [1, 1, 1, 1, 1], + [1, 1, 1, 1, 1], + [1, 1, 1, 1, 1], + ] + ] + ), + ), + DoesNotRaise(), + ), # single image annotations with mask as polygon + ( + [ + mock_coco_annotation( + category_id=0, + bbox=(0, 0, 5, 5), + area=5 * 5, + segmentation={ + "size": [5, 5], + "counts": [0, 15, 2, 3, 2, 3], + }, + iscrowd=True, + ) + ], + (5, 5), + True, + Detections( + xyxy=np.array([[0, 0, 5, 5]], dtype=np.float32), + class_id=np.array([0], dtype=int), + mask=np.array( + [ + [ + [1, 1, 1, 0, 0], + [1, 1, 1, 0, 0], + [1, 1, 1, 1, 1], + [1, 1, 1, 1, 1], + [1, 1, 1, 1, 1], + ] + ] + ), + ), + DoesNotRaise(), + ), # single image annotations with mask, RLE segmentation mask + ( + [ + mock_coco_annotation( + category_id=0, + bbox=(0, 0, 5, 5), + area=5 * 5, + segmentation=[[0, 0, 2, 0, 2, 2, 4, 2, 4, 4, 0, 4]], + ), + mock_coco_annotation( + category_id=0, + bbox=(3, 0, 2, 2), + area=2 * 2, + segmentation={ + "size": [5, 5], + "counts": [15, 2, 3, 2, 3], + }, + iscrowd=True, + ), + ], + (5, 5), + True, + Detections( + xyxy=np.array([[0, 0, 5, 5], [3, 0, 5, 2]], dtype=np.float32), + class_id=np.array([0, 0], dtype=int), + mask=np.array( + [ + [ + [1, 1, 1, 0, 0], + [1, 1, 1, 0, 0], + [1, 1, 1, 1, 1], + [1, 1, 1, 1, 1], + [1, 1, 1, 1, 1], + ], + [ + [0, 0, 0, 1, 1], + [0, 0, 0, 1, 1], + [0, 0, 0, 0, 0], + [0, 0, 0, 0, 0], + [0, 0, 0, 0, 0], + ], + ] + ), + ), + DoesNotRaise(), + ), # two image annotations with mask, one mask as polygon ans second as RLE + ( + [ + mock_coco_annotation( + category_id=0, + bbox=(3, 0, 2, 2), + area=2 * 2, + segmentation={ + "size": [5, 5], + "counts": [15, 2, 3, 2, 3], + }, + iscrowd=True, + ), + mock_coco_annotation( + category_id=1, + bbox=(0, 0, 5, 5), + area=5 * 5, + segmentation=[[0, 0, 2, 0, 2, 2, 4, 2, 4, 4, 0, 4]], + ), + ], + (5, 5), + True, + Detections( + xyxy=np.array([[3, 0, 5, 2], [0, 0, 5, 5]], dtype=np.float32), + class_id=np.array([0, 1], dtype=int), + mask=np.array( + [ + [ + [0, 0, 0, 1, 1], + [0, 0, 0, 1, 1], + [0, 0, 0, 0, 0], + [0, 0, 0, 0, 0], + [0, 0, 0, 0, 0], + ], + [ + [1, 1, 1, 0, 0], + [1, 1, 1, 0, 0], + [1, 1, 1, 1, 1], + [1, 1, 1, 1, 1], + [1, 1, 1, 1, 1], + ], + ] + ), + ), + DoesNotRaise(), + ), # two image annotations with mask, first mask as RLE and second as polygon ], ) def test_coco_annotations_to_detections( @@ -301,3 +429,131 @@ def test_build_coco_class_index_mapping( coco_categories=coco_categories, target_classes=target_classes ) assert result == expected_result + + +@pytest.mark.parametrize( + "detections, image_id, annotation_id, expected_result, exception", + [ + ( + Detections( + xyxy=np.array([[0, 0, 100, 100]], dtype=np.float32), + class_id=np.array([0], dtype=int), + ), + 0, + 0, + [ + mock_coco_annotation( + category_id=0, bbox=(0, 0, 100, 100), area=100 * 100 + ) + ], + DoesNotRaise(), + ), # no segmentation mask + ( + Detections( + xyxy=np.array([[0, 0, 4, 5]], dtype=np.float32), + class_id=np.array([0], dtype=int), + mask=np.array( + [ + [ + [1, 1, 1, 1, 0], + [1, 1, 1, 1, 0], + [1, 1, 1, 1, 0], + [1, 1, 1, 1, 0], + [1, 1, 1, 1, 0], + ] + ] + ), + ), + 0, + 0, + [ + mock_coco_annotation( + category_id=0, + bbox=(0, 0, 4, 5), + area=4 * 5, + segmentation=[[0, 0, 0, 4, 3, 4, 3, 0]], + ) + ], + DoesNotRaise(), + ), # segmentation mask in single component,no holes in mask, + # expects polygon mask + ( + Detections( + xyxy=np.array([[0, 0, 5, 5]], dtype=np.float32), + class_id=np.array([0], dtype=int), + mask=np.array( + [ + [ + [1, 1, 1, 0, 0], + [1, 1, 1, 0, 0], + [1, 1, 1, 0, 0], + [0, 0, 0, 1, 1], + [0, 0, 0, 1, 1], + ] + ] + ), + ), + 0, + 0, + [ + mock_coco_annotation( + category_id=0, + bbox=(0, 0, 5, 5), + area=5 * 5, + segmentation={ + "size": [5, 5], + "counts": [0, 3, 2, 3, 2, 3, 5, 2, 3, 2], + }, + iscrowd=True, + ) + ], + DoesNotRaise(), + ), # segmentation mask with 2 components, no holes in mask, expects RLE mask + ( + Detections( + xyxy=np.array([[0, 0, 5, 5]], dtype=np.float32), + class_id=np.array([0], dtype=int), + mask=np.array( + [ + [ + [0, 1, 1, 1, 1], + [0, 1, 1, 1, 1], + [1, 1, 0, 0, 1], + [1, 1, 0, 0, 1], + [1, 1, 1, 1, 1], + ] + ] + ), + ), + 0, + 0, + [ + mock_coco_annotation( + category_id=0, + bbox=(0, 0, 5, 5), + area=5 * 5, + segmentation={ + "size": [5, 5], + "counts": [2, 10, 2, 3, 2, 6], + }, + iscrowd=True, + ) + ], + DoesNotRaise(), + ), # seg mask in single component, with holes in mask, expects RLE mask + ], +) +def test_detections_to_coco_annotations( + detections: Detections, + image_id: int, + annotation_id: int, + expected_result: List[Dict], + exception: Exception, +) -> None: + with exception: + result, _ = detections_to_coco_annotations( + detections=detections, + image_id=image_id, + annotation_id=annotation_id, + ) + assert result == expected_result diff --git a/test/dataset/test_utils.py b/test/dataset/test_utils.py index 5ca96ca5..41e1da5b 100644 --- a/test/dataset/test_utils.py +++ b/test/dataset/test_utils.py @@ -2,13 +2,17 @@ from contextlib import ExitStack as DoesNotRaise from test.test_utils import mock_detections from typing import Dict, List, Optional, Tuple, TypeVar +import numpy as np +import numpy.typing as npt import pytest from supervision import Detections from supervision.dataset.utils import ( build_class_index_mapping, map_detections_class_id, + mask_to_rle, merge_class_lists, + rle_to_mask, train_test_split, ) @@ -229,3 +233,131 @@ def test_map_detections_class_id( source_to_target_mapping=source_to_target_mapping, detections=detections ) assert result == expected_result + + +@pytest.mark.parametrize( + "mask, expected_rle, exception", + [ + ( + np.zeros((3, 3)).astype(bool), + [9], + DoesNotRaise(), + ), # mask with background only (mask with only False values) + ( + np.ones((3, 3)).astype(bool), + [0, 9], + DoesNotRaise(), + ), # mask with foreground only (mask with only True values) + ( + np.array( + [ + [0, 0, 0, 0, 0], + [0, 1, 1, 1, 0], + [0, 1, 0, 1, 0], + [0, 1, 1, 1, 0], + [0, 0, 0, 0, 0], + ] + ).astype(bool), + [6, 3, 2, 1, 1, 1, 2, 3, 6], + DoesNotRaise(), + ), # mask where foreground object has hole + ( + np.array( + [ + [1, 0, 1, 0, 1], + [1, 0, 1, 0, 1], + [1, 0, 1, 0, 1], + [1, 0, 1, 0, 1], + [1, 0, 1, 0, 1], + ] + ).astype(bool), + [0, 5, 5, 5, 5, 5], + DoesNotRaise(), + ), # mask where foreground consists of 3 separate components + ( + np.array([[[]]]).astype(bool), + None, + pytest.raises(AssertionError), + ), # raises AssertionError because mask dimentionality is not 2D + ( + np.array([[]]).astype(bool), + None, + pytest.raises(AssertionError), + ), # raises AssertionError because mask is empty + ], +) +def test_mask_to_rle( + mask: npt.NDArray[np.bool_], expected_rle: List[int], exception: Exception +) -> None: + with exception: + result = mask_to_rle(mask=mask) + assert result == expected_rle + + +@pytest.mark.parametrize( + "rle, resolution_wh, expected_mask, exception", + [ + ( + np.array([9]), + [3, 3], + np.zeros((3, 3)).astype(bool), + DoesNotRaise(), + ), # mask with background only (mask with only False values); rle as array + ( + [9], + [3, 3], + np.zeros((3, 3)).astype(bool), + DoesNotRaise(), + ), # mask with background only (mask with only False values); rle as list + ( + np.array([0, 9]), + [3, 3], + np.ones((3, 3)).astype(bool), + DoesNotRaise(), + ), # mask with foreground only (mask with only True values) + ( + np.array([6, 3, 2, 1, 1, 1, 2, 3, 6]), + [5, 5], + np.array( + [ + [0, 0, 0, 0, 0], + [0, 1, 1, 1, 0], + [0, 1, 0, 1, 0], + [0, 1, 1, 1, 0], + [0, 0, 0, 0, 0], + ] + ).astype(bool), + DoesNotRaise(), + ), # mask where foreground object has hole + ( + np.array([0, 5, 5, 5, 5, 5]), + [5, 5], + np.array( + [ + [1, 0, 1, 0, 1], + [1, 0, 1, 0, 1], + [1, 0, 1, 0, 1], + [1, 0, 1, 0, 1], + [1, 0, 1, 0, 1], + ] + ).astype(bool), + DoesNotRaise(), + ), # mask where foreground consists of 3 separate components + ( + np.array([0, 5, 5, 5, 5, 5]), + [2, 2], + None, + pytest.raises(AssertionError), + ), # raises AssertionError because number of pixels in RLE does not match + # number of pixels in expected mask (width x height). + ], +) +def test_rle_to_mask( + rle: npt.NDArray[np.int_], + resolution_wh: Tuple[int, int], + expected_mask: npt.NDArray[np.bool_], + exception: Exception, +) -> None: + with exception: + result = rle_to_mask(rle=rle, resolution_wh=resolution_wh) + assert np.all(result == expected_mask) diff --git a/test/detection/test_core.py b/test/detection/test_core.py index f3b739e8..300d6dfe 100644 --- a/test/detection/test_core.py +++ b/test/detection/test_core.py @@ -5,7 +5,7 @@ from typing import List, Optional, Union import numpy as np import pytest -from supervision.detection.core import Detections +from supervision.detection.core import Detections, merge_inner_detection_object_pair from supervision.geometry.core import Position PREDICTIONS = np.array( @@ -30,6 +30,84 @@ DETECTIONS = Detections( ) +# Merge test +TEST_MASK = np.zeros((1000, 1000), dtype=bool) +TEST_MASK[300:351, 200:251] = True +TEST_DET_1 = Detections( + xyxy=np.array([[10, 10, 20, 20], [30, 30, 40, 40], [50, 50, 60, 60]]), + mask=np.array([TEST_MASK, TEST_MASK, TEST_MASK]), + confidence=np.array([0.1, 0.2, 0.3]), + class_id=np.array([1, 2, 3]), + tracker_id=np.array([1, 2, 3]), + data={ + "some_key": [1, 2, 3], + "other_key": [["1", "2"], ["3", "4"], ["5", "6"]], + }, +) +TEST_DET_2 = Detections( + xyxy=np.array([[70, 70, 80, 80], [90, 90, 100, 100]]), + mask=np.array([TEST_MASK, TEST_MASK]), + confidence=np.array([0.4, 0.5]), + class_id=np.array([4, 5]), + tracker_id=np.array([4, 5]), + data={ + "some_key": [4, 5], + "other_key": [["7", "8"], ["9", "10"]], + }, +) +TEST_DET_1_2 = Detections( + xyxy=np.array( + [ + [10, 10, 20, 20], + [30, 30, 40, 40], + [50, 50, 60, 60], + [70, 70, 80, 80], + [90, 90, 100, 100], + ] + ), + mask=np.array([TEST_MASK, TEST_MASK, TEST_MASK, TEST_MASK, TEST_MASK]), + confidence=np.array([0.1, 0.2, 0.3, 0.4, 0.5]), + class_id=np.array([1, 2, 3, 4, 5]), + tracker_id=np.array([1, 2, 3, 4, 5]), + data={ + "some_key": [1, 2, 3, 4, 5], + "other_key": [["1", "2"], ["3", "4"], ["5", "6"], ["7", "8"], ["9", "10"]], + }, +) +TEST_DET_ZERO_LENGTH = Detections( + xyxy=np.empty((0, 4), dtype=np.float32), + mask=np.empty((0, *TEST_MASK.shape), dtype=bool), + confidence=np.empty((0,)), + class_id=np.empty((0,)), + tracker_id=np.empty((0,)), + data={ + "some_key": [], + "other_key": [], + }, +) +TEST_DET_NONE = Detections( + xyxy=np.empty((0, 4), dtype=np.float32), +) +TEST_DET_DIFFERENT_FIELDS = Detections( + xyxy=np.array([[88, 88, 99, 99]]), + mask=np.array([np.logical_not(TEST_MASK)]), + confidence=None, + class_id=None, + tracker_id=np.array([9]), + data={"some_key": [9], "other_key": [["11", "12"]]}, +) +TEST_DET_DIFFERENT_DATA = Detections( + xyxy=np.array([[88, 88, 99, 99]]), + mask=np.array([np.logical_not(TEST_MASK)]), + confidence=np.array([0.9]), + class_id=np.array([9]), + tracker_id=np.array([9]), + data={ + "never_seen_key": [9], + }, +) + + @pytest.mark.parametrize( "detections, index, expected_result, exception", [ @@ -148,52 +226,73 @@ def test_getitem( DoesNotRaise(), ), # single empty detections ( - [mock_detections(xyxy=[[10, 10, 20, 20]])], - mock_detections(xyxy=[[10, 10, 20, 20]]), + [Detections.empty(), Detections.empty()], + Detections.empty(), DoesNotRaise(), - ), # single detection with xyxy field + ), # two empty detections + ( + [TEST_DET_1], + TEST_DET_1, + DoesNotRaise(), + ), # single detection with fields + ( + [TEST_DET_NONE], + TEST_DET_NONE, + DoesNotRaise(), + ), # Single weakly-defined detection + ( + [TEST_DET_1, TEST_DET_2], + TEST_DET_1_2, + DoesNotRaise(), + ), # Fields with same keys + ( + [TEST_DET_1, Detections.empty()], + TEST_DET_1, + DoesNotRaise(), + ), # single detection with fields ( [ - mock_detections(xyxy=[[10, 10, 20, 20]]), - mock_detections(xyxy=np.empty((0, 4), dtype=np.float32)), + TEST_DET_1, + TEST_DET_ZERO_LENGTH, ], - mock_detections(xyxy=[[10, 10, 20, 20]]), + TEST_DET_1, DoesNotRaise(), - ), # single detection with xyxy field + empty detection + ), # Single detection and empty-array fields ( [ - mock_detections(xyxy=[[10, 10, 20, 20]]), - mock_detections(xyxy=[[20, 20, 30, 30]]), + TEST_DET_1, + TEST_DET_NONE, ], - mock_detections(xyxy=[[10, 10, 20, 20], [20, 20, 30, 30]]), - DoesNotRaise(), - ), # two detections with xyxy field - ( - [ - mock_detections(xyxy=[[10, 10, 20, 20]], class_id=[0]), - mock_detections(xyxy=[[20, 20, 30, 30]]), - ], - mock_detections(xyxy=[[10, 10, 20, 20], [20, 20, 30, 30]]), + None, pytest.raises(ValueError), - ), # detection with xyxy, class_id fields + detection with xyxy field + ), # Empty detection, but not Detections.empty() + # Errors: Non-zero-length differently defined keys & data + ( + [TEST_DET_1, TEST_DET_DIFFERENT_FIELDS], + None, + pytest.raises(ValueError), + ), # Non-empty detections with different fields + ( + [TEST_DET_1, TEST_DET_DIFFERENT_DATA], + None, + pytest.raises(ValueError), + ), # Non-empty detections with different data keys ( [ - mock_detections(xyxy=[[10, 10, 20, 20]], class_id=[0]), - mock_detections(xyxy=[[20, 20, 30, 30]], class_id=[1]), - ], - mock_detections(xyxy=[[10, 10, 20, 20], [20, 20, 30, 30]], class_id=[0, 1]), - DoesNotRaise(), - ), # two detections with xyxy, class_id fields - ( - [ - mock_detections(xyxy=[[10, 10, 20, 20]], data={"test": [1]}), - mock_detections(xyxy=[[20, 20, 30, 30]], data={"test": [2]}), + mock_detections( + xyxy=[[10, 10, 20, 20]], + class_id=[1], + mask=[np.zeros((4, 4), dtype=bool)], + ), + Detections.empty(), ], mock_detections( - xyxy=[[10, 10, 20, 20], [20, 20, 30, 30]], data={"test": [1, 2]} + xyxy=[[10, 10, 20, 20]], + class_id=[1], + mask=[np.zeros((4, 4), dtype=bool)], ), DoesNotRaise(), - ), # two detections with xyxy, data fields + ), # Segmentation + Empty ], ) def test_merge( @@ -337,3 +436,172 @@ def test_equal( detections_a: Detections, detections_b: Detections, expected_result: bool ) -> None: assert (detections_a == detections_b) == expected_result + + +@pytest.mark.parametrize( + "detection_1, detection_2, expected_result, exception", + [ + ( + mock_detections( + xyxy=[[10, 10, 30, 30]], + ), + mock_detections( + xyxy=[[10, 10, 30, 30]], + ), + mock_detections( + xyxy=[[10, 10, 30, 30]], + ), + DoesNotRaise(), + ), # Merge with self + ( + mock_detections( + xyxy=[[10, 10, 30, 30]], + ), + Detections.empty(), + None, + pytest.raises(ValueError), + ), # merge with empty: error + ( + mock_detections( + xyxy=[[10, 10, 30, 30]], + ), + mock_detections( + xyxy=[[10, 10, 30, 30], [40, 40, 60, 60]], + ), + None, + pytest.raises(ValueError), + ), # merge with 2+ objects: error + ( + mock_detections( + xyxy=[[10, 10, 30, 30]], + confidence=[0.1], + class_id=[1], + mask=[np.array([[1, 1, 0], [1, 1, 0], [0, 0, 0]], dtype=bool)], + tracker_id=[1], + data={"key_1": [1]}, + ), + mock_detections( + xyxy=[[20, 20, 40, 40]], + confidence=[0.1], + class_id=[2], + mask=[np.array([[0, 0, 0], [0, 1, 1], [0, 1, 1]], dtype=bool)], + tracker_id=[2], + data={"key_2": [2]}, + ), + mock_detections( + xyxy=[[10, 10, 40, 40]], + confidence=[0.1], + class_id=[1], + mask=[np.array([[1, 1, 0], [1, 1, 1], [0, 1, 1]], dtype=bool)], + tracker_id=[1], + data={"key_1": [1]}, + ), + DoesNotRaise(), + ), # Same confidence - merge box & mask, tie-break to detection_1 + ( + mock_detections( + xyxy=[[0, 0, 20, 20]], + confidence=[0.1], + class_id=[1], + mask=[np.array([[1, 1, 0], [1, 1, 0], [0, 0, 0]], dtype=bool)], + tracker_id=[1], + data={"key_1": [1]}, + ), + mock_detections( + xyxy=[[10, 10, 50, 50]], + confidence=[0.2], + class_id=[2], + mask=[np.array([[0, 0, 0], [0, 1, 1], [0, 1, 1]], dtype=bool)], + tracker_id=[2], + data={"key_2": [2]}, + ), + mock_detections( + xyxy=[[0, 0, 50, 50]], + confidence=[(1 * 0.1 + 4 * 0.2) / 5], + class_id=[2], + mask=[np.array([[1, 1, 0], [1, 1, 1], [0, 1, 1]], dtype=bool)], + tracker_id=[2], + data={"key_2": [2]}, + ), + DoesNotRaise(), + ), # Different confidence, different area + ( + mock_detections( + xyxy=[[10, 10, 30, 30]], + confidence=None, + class_id=[1], + mask=[np.array([[1, 1, 0], [1, 1, 0], [0, 0, 0]], dtype=bool)], + tracker_id=[1], + data={"key_1": [1]}, + ), + mock_detections( + xyxy=[[20, 20, 40, 40]], + confidence=None, + class_id=[2], + mask=[np.array([[0, 0, 0], [0, 1, 1], [0, 1, 1]], dtype=bool)], + tracker_id=[2], + data={"key_2": [2]}, + ), + mock_detections( + xyxy=[[10, 10, 40, 40]], + confidence=None, + class_id=[1], + mask=[np.array([[1, 1, 0], [1, 1, 1], [0, 1, 1]], dtype=bool)], + tracker_id=[1], + data={"key_1": [1]}, + ), + DoesNotRaise(), + ), # No confidence at all + ( + mock_detections( + xyxy=[[0, 0, 20, 20]], + confidence=None, + ), + mock_detections( + xyxy=[[10, 10, 30, 30]], + confidence=[0.2], + ), + None, + pytest.raises(ValueError), + ), # confidence: None + [x] + ( + mock_detections( + xyxy=[[0, 0, 20, 20]], + mask=[np.array([[1, 1, 0], [1, 1, 0], [0, 0, 0]], dtype=bool)], + ), + mock_detections( + xyxy=[[10, 10, 30, 30]], + mask=None, + ), + None, + pytest.raises(ValueError), + ), # mask: None + [x] + ( + mock_detections(xyxy=[[0, 0, 20, 20]], tracker_id=[1]), + mock_detections( + xyxy=[[10, 10, 30, 30]], + tracker_id=None, + ), + None, + pytest.raises(ValueError), + ), # tracker_id: None + [] + ( + mock_detections(xyxy=[[0, 0, 20, 20]], class_id=[1]), + mock_detections( + xyxy=[[10, 10, 30, 30]], + class_id=None, + ), + None, + pytest.raises(ValueError), + ), # class_id: None + [] + ], +) +def test_merge_inner_detection_object_pair( + detection_1: Detections, + detection_2: Detections, + expected_result: Optional[Detections], + exception: Exception, +): + with exception: + result = merge_inner_detection_object_pair(detection_1, detection_2) + assert result == expected_result diff --git a/test/detection/test_line_counter.py b/test/detection/test_line_counter.py index 73780414..66118e97 100644 --- a/test/detection/test_line_counter.py +++ b/test/detection/test_line_counter.py @@ -1,10 +1,11 @@ from contextlib import ExitStack as DoesNotRaise -from typing import Optional, Tuple +from test.test_utils import mock_detections +from typing import List, Optional, Tuple import pytest from supervision import LineZone -from supervision.geometry.core import Point, Vector +from supervision.geometry.core import Point, Position, Vector @pytest.mark.parametrize( @@ -70,3 +71,409 @@ def test_calculate_region_of_interest_limits( with exception: result = LineZone.calculate_region_of_interest_limits(vector=vector) assert result == expected_result + + +@pytest.mark.parametrize( + "vector, xyxy_sequence, expected_crossed_in, expected_crossed_out", + [ + ( # Vertical line, simple crossing + Vector(Point(0, 0), Point(0, 10)), + [ + [4, 4, 6, 6], + [4 - 10, 4, 6 - 10, 6], + [4, 4, 6, 6], + [4 - 10, 4, 6 - 10, 6], + ], + [False, False, True, False], + [False, True, False, True], + ), + ( # Vertical line reversed, simple crossing + Vector(Point(0, 10), Point(0, 0)), + [ + [4, 4, 6, 6], + [4 - 10, 4, 6 - 10, 6], + [4, 4, 6, 6], + [4 - 10, 4, 6 - 10, 6], + ], + [False, True, False, True], + [False, False, True, False], + ), + ( # Horizontal line, simple crossing + Vector(Point(0, 0), Point(10, 0)), + [ + [4, 4, 6, 6], + [4, 4 - 10, 6, 6 - 10], + [4, 4, 6, 6], + [4, 4 - 10, 6, 6 - 10], + ], + [False, True, False, True], + [False, False, True, False], + ), + ( # Horizontal line reversed, simple crossing + Vector(Point(10, 0), Point(0, 0)), + [ + [4, 4, 6, 6], + [4, 4 - 10, 6, 6 - 10], + [4, 4, 6, 6], + [4, 4 - 10, 6, 6 - 10], + ], + [False, False, True, False], + [False, True, False, True], + ), + ( # Diagonal line, simple crossing + Vector(Point(5, 0), Point(0, 5)), + [ + [0, 0, 2, 2], + [0 + 10, 0 + 10, 2 + 10, 2 + 10], + [0, 0, 2, 2], + [0 + 10, 0 + 10, 2 + 10, 2 + 10], + ], + [False, True, False, True], + [False, False, True, False], + ), + ( # Crossing beside - right side + Vector(Point(0, 0), Point(10, 0)), + [ + [20, 4, 24, 6], + [20, 4 - 10, 24, 6 - 10], + [20, 4, 24, 6], + [20, 4 - 10, 24, 6 - 10], + ], + [False, False, False, False], + [False, False, False, False], + ), + ( # Horizontal line, simple crossing, far away + Vector(Point(0, 0), Point(10, 0)), + [ + [4, 1e32, 6, 1e32 + 2], + [4, -1e32, 6, -1e32 + 2], + [4, 1e32, 6, 1e32 + 2], + [4, -1e32, 6, -1e32 + 2], + ], + [False, True, False, True], + [False, False, True, False], + ), + ( # Crossing beside - left side + Vector(Point(0, 0), Point(10, 0)), + [ + [-20, 4, -24, 6], + [-20, 4 - 10, -24, 6 - 10], + [-20, 4, -24, 6], + [-20, 4 - 10, -24, 6 - 10], + ], + [False, False, False, False], + [False, False, False, False], + ), + ( # Move above + Vector(Point(0, 0), Point(10, 0)), + [ + [-4, 4, -2, 6], + [-4 + 20, 4, -2 + 20, 6], + [-4, 4, -2, 6], + [-4 + 20, 4, -2 + 20, 6], + ], + [False, False, False, False], + [False, False, False, False], + ), + ( # Move below + Vector(Point(0, 0), Point(10, 0)), + [ + [-4, -6, -2, -4], + [-4 + 20, -6, -2 + 20, -4], + [-4, -6, -2, -4], + [-4 + 20, -6, -2 + 20, -4], + ], + [False, False, False, False], + [False, False, False, False], + ), + ( # Move into line partway + Vector(Point(0, 0), Point(10, 0)), + [ + [4, 4, 6, 6], + [4 + 5, 4, 6 + 5, 6], + [4, 4, 6, 6], + [4 + 5, 4, 6 + 5, 6], + ], + [False, False, False, False], + [False, False, False, False], + ), + ( # V-shaped crossing from outside limits - not supported. + Vector(Point(0, 0), Point(10, 0)), + [[-3, 6, -1, 8], [4, -6, 6, -4], [11, 6, 13, 8]], + [False, False, False], + [False, False, False], + ), + ( # Diagonal movement, from within limits to outside - not supported + Vector(Point(0, 0), Point(10, 0)), + [[4, 1, 6, 3], [11, 1 - 20, 13, 3 - 20]], + [False, False], + [False, False], + ), + ( # Diagonal movement, from outside limits to within - not supported + Vector(Point(0, 0), Point(10, 0)), + [ + [11, 21, 13, 23], + [4, -3, 6, -1], + ], + [False, False], + [False, False], + ), + ( # Diagonal crossing, from outside to outside limits - not supported. + Vector(Point(0, 0), Point(10, 0)), + [ + [-4, 4, -2, 8], + [-4 + 16, -4, -2 + 16, -6], + [-4, 4, -2, 8], + [-4 + 16, -4, -2 + 16, -6], + ], + [False, False, False, False], + [False, False, False, False], + ), + ], +) +def test_line_zone_one_detection_default_anchors( + vector: Vector, + xyxy_sequence: List[List[float]], + expected_crossed_in: List[bool], + expected_crossed_out: List[bool], +) -> None: + line_zone = LineZone(start=vector.start, end=vector.end) + + crossed_in_list = [] + crossed_out_list = [] + for i, bbox in enumerate(xyxy_sequence): + detections = mock_detections( + xyxy=[bbox], + tracker_id=[0], + ) + crossed_in, crossed_out = line_zone.trigger(detections) + crossed_in_list.append(crossed_in[0]) + crossed_out_list.append(crossed_out[0]) + + assert ( + crossed_in_list == expected_crossed_in + ), f"expected {expected_crossed_in}, got {crossed_in_list}" + assert ( + crossed_out_list == expected_crossed_out + ), f"expected {expected_crossed_out}, got {crossed_out_list}" + + +@pytest.mark.parametrize( + "vector, xyxy_sequence, triggering_anchors, expected_crossed_in, " + "expected_crossed_out", + [ + ( # Scrape line, left side, corner anchors + Vector(Point(0, 0), Point(10, 0)), + [ + [-2, 4, 2, 6], + [-2, 4 - 10, 2, 6 - 10], + [-2, 4, 2, 6], + [-2, 4 - 10, 2, 6 - 10], + ], + [ + Position.TOP_LEFT, + Position.BOTTOM_LEFT, + Position.TOP_RIGHT, + Position.BOTTOM_RIGHT, + ], + [False, False, False, False], + [False, False, False, False], + ), + ( # Scrape line, left side, right anchors + Vector(Point(0, 0), Point(10, 0)), + [ + [-2, 4, 2, 6], + [-2, 4 - 10, 2, 6 - 10], + [-2, 4, 2, 6], + [-2, 4 - 10, 2, 6 - 10], + ], + [Position.TOP_RIGHT, Position.BOTTOM_RIGHT], + [False, True, False, True], + [False, False, True, False], + ), + ( # Scrape line, left side, center anchor (along line point) + Vector(Point(0, 0), Point(10, 0)), + [ + [-2, 4, 2, 6], + [-2, 4 - 10, 2, 6 - 10], + [-2, 4, 2, 6], + [-2, 4 - 10, 2, 6 - 10], + ], + [Position.CENTER], + [False, True, False, True], + [False, False, True, False], + ), + ( # Scrape line, right side, corner anchors + Vector(Point(0, 0), Point(10, 0)), + [ + [8, 4, 12, 6], + [8, 4 - 10, 12, 6 - 10], + [8, 4, 12, 6], + [8, 4 - 10, 12, 6 - 10], + ], + [ + Position.TOP_LEFT, + Position.BOTTOM_LEFT, + Position.TOP_RIGHT, + Position.BOTTOM_RIGHT, + ], + [False, False, False, False], + [False, False, False, False], + ), + ( # Scrape line, right side, left anchors + Vector(Point(0, 0), Point(10, 0)), + [ + [8, 4, 12, 6], + [8, 4 - 10, 12, 6 - 10], + [8, 4, 12, 6], + [8, 4 - 10, 12, 6 - 10], + ], + [Position.TOP_LEFT, Position.BOTTOM_LEFT], + [False, True, False, True], + [False, False, True, False], + ), + ( # Scrape line, right side, center anchor (along line point) + Vector(Point(0, 0), Point(10, 0)), + [ + [8, 4, 12, 6], + [8, 4 - 10, 12, 6 - 10], + [8, 4, 12, 6], + [8, 4 - 10, 12, 6 - 10], + ], + [Position.CENTER], + [False, True, False, True], + [False, False, True, False], + ), + ( # Simple crossing, one anchor + Vector(Point(0, 0), Point(10, 0)), + [ + [4, 4, 6, 6], + [4, 4 - 10, 6, 6 - 10], + [4, 4, 6, 6], + [4, 4 - 10, 6, 6 - 10], + ], + [Position.CENTER], + [False, True, False, True], + [False, False, True, False], + ), + ( # Simple crossing, all box anchors + Vector(Point(0, 0), Point(10, 0)), + [ + [4, 4, 6, 6], + [4, 4 - 10, 6, 6 - 10], + [4, 4, 6, 6], + [4, 4 - 10, 6, 6 - 10], + ], + [ + Position.CENTER, + Position.CENTER_LEFT, + Position.CENTER_RIGHT, + Position.TOP_CENTER, + Position.TOP_LEFT, + Position.TOP_RIGHT, + Position.BOTTOM_LEFT, + Position.BOTTOM_CENTER, + Position.BOTTOM_RIGHT, + ], + [False, True, False, True], + [False, False, True, False], + ), + ], +) +def test_line_zone_one_detection( + vector: Vector, + xyxy_sequence: List[List[float]], + triggering_anchors: List[Position], + expected_crossed_in: List[bool], + expected_crossed_out: List[bool], +) -> None: + line_zone = LineZone( + start=vector.start, end=vector.end, triggering_anchors=triggering_anchors + ) + + crossed_in_list = [] + crossed_out_list = [] + for i, bbox in enumerate(xyxy_sequence): + detections = mock_detections( + xyxy=[bbox], + tracker_id=[0], + ) + crossed_in, crossed_out = line_zone.trigger(detections) + crossed_in_list.append(crossed_in[0]) + crossed_out_list.append(crossed_out[0]) + + assert ( + crossed_in_list == expected_crossed_in + ), f"expected {expected_crossed_in}, got {crossed_in_list}" + assert ( + crossed_out_list == expected_crossed_out + ), f"expected {expected_crossed_out}, got {crossed_out_list}" + + +@pytest.mark.parametrize( + "vector, xyxy_sequence, anchors, expected_crossed_in, " + "expected_crossed_out, exception", + [ + ( # One stays, one crosses + Vector(Point(0, 0), Point(10, 0)), + [ + [[4, 4, 6, 6], [4, 4, 6, 6]], + [[4, 4, 6, 6], [4, 4 - 10, 6, 6 - 10]], + [[4, 4, 6, 6], [4, 4, 6, 6]], + [[4, 4, 6, 6], [4, 4 - 10, 6, 6 - 10]], + ], + [ + Position.TOP_LEFT, + Position.TOP_RIGHT, + Position.BOTTOM_LEFT, + Position.BOTTOM_RIGHT, + ], + [[False, False], [False, True], [False, False], [False, True]], + [[False, False], [False, False], [False, True], [False, False]], + DoesNotRaise(), + ), + ( # Both cross at the same time + Vector(Point(0, 0), Point(10, 0)), + [ + [[4, 4, 6, 6], [4, 4, 6, 6]], + [[4, 4 - 10, 6, 6 - 10], [4, 4 - 10, 6, 6 - 10]], + [[4, 4, 6, 6], [4, 4, 6, 6]], + [[4, 4 - 10, 6, 6 - 10], [4, 4 - 10, 6, 6 - 10]], + ], + [ + Position.TOP_LEFT, + Position.TOP_RIGHT, + Position.BOTTOM_LEFT, + Position.BOTTOM_RIGHT, + ], + [[False, False], [True, True], [False, False], [True, True]], + [[False, False], [False, False], [True, True], [False, False]], + DoesNotRaise(), + ), + ], +) +def test_line_zone_multiple_detections( + vector: Vector, + xyxy_sequence: List[List[List[float]]], + anchors: List[Position], + expected_crossed_in: List[List[bool]], + expected_crossed_out: List[List[bool]], + exception: Exception, +) -> None: + with exception: + line_zone = LineZone( + start=vector.start, end=vector.end, triggering_anchors=anchors + ) + crossed_in_list = [] + crossed_out_list = [] + for bboxes in xyxy_sequence: + detections = mock_detections( + xyxy=bboxes, + tracker_id=[i for i in range(0, len(bboxes))], + ) + crossed_in, crossed_out = line_zone.trigger(detections) + crossed_in_list.append(list(crossed_in)) + crossed_out_list.append(list(crossed_out)) + + assert crossed_in_list == expected_crossed_in + assert crossed_out_list == expected_crossed_out diff --git a/test/detection/test_lmm.py b/test/detection/test_lmm.py new file mode 100644 index 00000000..4448d8db --- /dev/null +++ b/test/detection/test_lmm.py @@ -0,0 +1,151 @@ +from typing import List, Optional, Tuple + +import numpy as np +import pytest + +from supervision.detection.lmm import from_paligemma + + +@pytest.mark.parametrize( + "result, resolution_wh, classes, expected_results", + [ + ( + "", + (1000, 1000), + None, + (np.empty((0, 4)), None, np.empty(0).astype(str)), + ), # empty response + ( + "", + (1000, 1000), + ["cat", "dog"], + (np.empty((0, 4)), None, np.empty(0).astype(str)), + ), # empty response with classes + ( + "\n", + (1000, 1000), + None, + (np.empty((0, 4)), None, np.empty(0).astype(str)), + ), # new line response + ( + "the quick brown fox jumps over the lazy dog.", + (1000, 1000), + None, + (np.empty((0, 4)), None, np.empty(0).astype(str)), + ), # response with no location + ( + " cat", + (1000, 1000), + None, + (np.empty((0, 4)), None, np.empty(0).astype(str)), + ), # response with missing location + ( + " cat", + (1000, 1000), + None, + (np.empty((0, 4)), None, np.empty(0).astype(str)), + ), # response with extra location + ( + "", + (1000, 1000), + None, + (np.empty((0, 4)), None, np.empty(0).astype(str)), + ), # response with no class + ( + " catt", + (1000, 1000), + ["cat", "dog"], + (np.empty((0, 4)), np.empty(0), np.empty(0).astype(str)), + ), # response with invalid class + ( + " cat", + (1000, 1000), + None, + ( + np.array([[250.0, 250.0, 750.0, 750.0]]), + None, + np.array(["cat"]).astype(str), + ), + ), # correct response; no classes + ( + " black cat", + (1000, 1000), + None, + ( + np.array([[250.0, 250.0, 750.0, 750.0]]), + None, + np.array(["black cat"]).astype(np.dtype("U")), + ), + ), # correct response; class name with space; no classes + ( + " black-cat", + (1000, 1000), + None, + ( + np.array([[250.0, 250.0, 750.0, 750.0]]), + None, + np.array(["black-cat"]).astype(np.dtype("U")), + ), + ), # correct response; class name with hyphen; no classes + ( + " black_cat", + (1000, 1000), + None, + ( + np.array([[250.0, 250.0, 750.0, 750.0]]), + None, + np.array(["black_cat"]).astype(np.dtype("U")), + ), + ), # correct response; class name with underscore; no classes + ( + " cat ;", + (1000, 1000), + ["cat", "dog"], + ( + np.array([[250.0, 250.0, 750.0, 750.0]]), + np.array([0]), + np.array(["cat"]).astype(str), + ), + ), # correct response; with classes + ( + " cat ; dog", # noqa: E501 + (1000, 1000), + ["cat", "dog"], + ( + np.array([[250.0, 250.0, 750.0, 750.0], [250.0, 250.0, 750.0, 750.0]]), + np.array([0, 1]), + np.array(["cat", "dog"]).astype(np.dtype("U")), + ), + ), # correct response; with classes + ( + " cat ; cat", # noqa: E501 + (1000, 1000), + ["cat", "dog"], + ( + np.array([[250.0, 250.0, 750.0, 750.0]]), + np.array([0]), + np.array(["cat"]).astype(str), + ), + ), # partially correct response; with classes + ( + " cat ; cat", # noqa: E501 + (1000, 1000), + ["cat", "dog"], + ( + np.array([[250.0, 250.0, 750.0, 750.0]]), + np.array([0]), + np.array(["cat"]).astype(str), + ), + ), # partially correct response; with classes + ], +) +def test_from_paligemma( + result: str, + resolution_wh: Tuple[int, int], + classes: Optional[List[str]], + expected_results: Tuple[np.ndarray, Optional[np.ndarray], np.ndarray], +) -> None: + result = from_paligemma(result=result, resolution_wh=resolution_wh, classes=classes) + np.testing.assert_array_equal(result[0], expected_results[0]) + np.testing.assert_array_equal(result[1], expected_results[1]) + np.testing.assert_array_equal(result[2], expected_results[2]) diff --git a/test/detection/test_overlap_filter.py b/test/detection/test_overlap_filter.py new file mode 100644 index 00000000..f628c30f --- /dev/null +++ b/test/detection/test_overlap_filter.py @@ -0,0 +1,449 @@ +from contextlib import ExitStack as DoesNotRaise +from typing import List, Optional + +import numpy as np +import pytest + +from supervision.detection.overlap_filter import ( + box_non_max_suppression, + group_overlapping_boxes, + mask_non_max_suppression, +) + + +@pytest.mark.parametrize( + "predictions, iou_threshold, expected_result, exception", + [ + ( + np.empty(shape=(0, 5), dtype=float), + 0.5, + [], + DoesNotRaise(), + ), + ( + np.array([[0, 0, 10, 10, 1.0]]), + 0.5, + [[0]], + DoesNotRaise(), + ), + ( + np.array([[0, 0, 10, 10, 1.0], [0, 0, 9, 9, 1.0]]), + 0.5, + [[1, 0]], + DoesNotRaise(), + ), # High overlap, tie-break to second det + ( + np.array([[0, 0, 10, 10, 1.0], [0, 0, 9, 9, 0.99]]), + 0.5, + [[0, 1]], + DoesNotRaise(), + ), # High overlap, merge to high confidence + ( + np.array([[0, 0, 10, 10, 0.99], [0, 0, 9, 9, 1.0]]), + 0.5, + [[1, 0]], + DoesNotRaise(), + ), # (test symmetry) High overlap, merge to high confidence + ( + np.array([[0, 0, 10, 10, 0.90], [0, 0, 9, 9, 1.0]]), + 0.5, + [[1, 0]], + DoesNotRaise(), + ), # (test symmetry) High overlap, merge to high confidence + ( + np.array([[0, 0, 10, 10, 1.0], [0, 0, 9, 9, 1.0]]), + 1.0, + [[1], [0]], + DoesNotRaise(), + ), # High IOU required + ( + np.array([[0, 0, 10, 10, 1.0], [0, 0, 9, 9, 1.0]]), + 0.0, + [[1, 0]], + DoesNotRaise(), + ), # No IOU required + ( + np.array([[0, 0, 10, 10, 1.0], [0, 0, 5, 5, 0.9]]), + 0.25, + [[0, 1]], + DoesNotRaise(), + ), # Below IOU requirement + ( + np.array([[0, 0, 10, 10, 1.0], [0, 0, 5, 5, 0.9]]), + 0.26, + [[0], [1]], + DoesNotRaise(), + ), # Above IOU requirement + ( + np.array([[0, 0, 10, 10, 1.0], [0, 0, 9, 9, 1.0], [0, 0, 8, 8, 1.0]]), + 0.5, + [[2, 1, 0]], + DoesNotRaise(), + ), # 3 boxes + ( + np.array( + [ + [0, 0, 10, 10, 1.0], + [0, 0, 9, 9, 1.0], + [5, 5, 10, 10, 1.0], + [6, 6, 10, 10, 1.0], + [9, 9, 10, 10, 1.0], + ] + ), + 0.5, + [[4], [3, 2], [1, 0]], + DoesNotRaise(), + ), # 5 boxes, 2 merges, 1 separate + ( + np.array( + [ + [0, 0, 2, 1, 1.0], + [1, 0, 3, 1, 1.0], + [2, 0, 4, 1, 1.0], + [3, 0, 5, 1, 1.0], + [4, 0, 6, 1, 1.0], + ] + ), + 0.33, + [[4, 3], [2, 1], [0]], + DoesNotRaise(), + ), # sequential merge, half overlap + ( + np.array( + [ + [0, 0, 2, 1, 0.9], + [1, 0, 3, 1, 0.9], + [2, 0, 4, 1, 1.0], + [3, 0, 5, 1, 0.9], + [4, 0, 6, 1, 0.9], + ] + ), + 0.33, + [[2, 3, 1], [4], [0]], + DoesNotRaise(), + ), # confidence + ], +) +def test_group_overlapping_boxes( + predictions: np.ndarray, + iou_threshold: float, + expected_result: List[List[int]], + exception: Exception, +) -> None: + with exception: + result = group_overlapping_boxes( + predictions=predictions, iou_threshold=iou_threshold + ) + + assert result == expected_result + + +@pytest.mark.parametrize( + "predictions, iou_threshold, expected_result, exception", + [ + ( + np.empty(shape=(0, 5)), + 0.5, + np.array([]), + DoesNotRaise(), + ), # single box with no category + ( + np.array([[10.0, 10.0, 40.0, 40.0, 0.8]]), + 0.5, + np.array([True]), + DoesNotRaise(), + ), # single box with no category + ( + np.array([[10.0, 10.0, 40.0, 40.0, 0.8, 0]]), + 0.5, + np.array([True]), + DoesNotRaise(), + ), # single box with category + ( + np.array( + [ + [10.0, 10.0, 40.0, 40.0, 0.8], + [15.0, 15.0, 40.0, 40.0, 0.9], + ] + ), + 0.5, + np.array([False, True]), + DoesNotRaise(), + ), # two boxes with no category + ( + np.array( + [ + [10.0, 10.0, 40.0, 40.0, 0.8, 0], + [15.0, 15.0, 40.0, 40.0, 0.9, 1], + ] + ), + 0.5, + np.array([True, True]), + DoesNotRaise(), + ), # two boxes with different category + ( + np.array( + [ + [10.0, 10.0, 40.0, 40.0, 0.8, 0], + [15.0, 15.0, 40.0, 40.0, 0.9, 0], + ] + ), + 0.5, + np.array([False, True]), + DoesNotRaise(), + ), # two boxes with same category + ( + np.array( + [ + [0.0, 0.0, 30.0, 40.0, 0.8], + [5.0, 5.0, 35.0, 45.0, 0.9], + [10.0, 10.0, 40.0, 50.0, 0.85], + ] + ), + 0.5, + np.array([False, True, False]), + DoesNotRaise(), + ), # three boxes with no category + ( + np.array( + [ + [0.0, 0.0, 30.0, 40.0, 0.8, 0], + [5.0, 5.0, 35.0, 45.0, 0.9, 1], + [10.0, 10.0, 40.0, 50.0, 0.85, 2], + ] + ), + 0.5, + np.array([True, True, True]), + DoesNotRaise(), + ), # three boxes with same category + ( + np.array( + [ + [0.0, 0.0, 30.0, 40.0, 0.8, 0], + [5.0, 5.0, 35.0, 45.0, 0.9, 0], + [10.0, 10.0, 40.0, 50.0, 0.85, 1], + ] + ), + 0.5, + np.array([False, True, True]), + DoesNotRaise(), + ), # three boxes with different category + ], +) +def test_box_non_max_suppression( + predictions: np.ndarray, + iou_threshold: float, + expected_result: Optional[np.ndarray], + exception: Exception, +) -> None: + with exception: + result = box_non_max_suppression( + predictions=predictions, iou_threshold=iou_threshold + ) + assert np.array_equal(result, expected_result) + + +@pytest.mark.parametrize( + "predictions, masks, iou_threshold, expected_result, exception", + [ + ( + np.empty((0, 6)), + np.empty((0, 5, 5)), + 0.5, + np.array([]), + DoesNotRaise(), + ), # empty predictions and masks + ( + np.array([[0, 0, 0, 0, 0.8]]), + np.array( + [ + [ + [False, False, False, False, False], + [False, True, True, True, False], + [False, True, True, True, False], + [False, True, True, True, False], + [False, False, False, False, False], + ] + ] + ), + 0.5, + np.array([True]), + DoesNotRaise(), + ), # single mask with no category + ( + np.array([[0, 0, 0, 0, 0.8, 0]]), + np.array( + [ + [ + [False, False, False, False, False], + [False, True, True, True, False], + [False, True, True, True, False], + [False, True, True, True, False], + [False, False, False, False, False], + ] + ] + ), + 0.5, + np.array([True]), + DoesNotRaise(), + ), # single mask with category + ( + np.array([[0, 0, 0, 0, 0.8], [0, 0, 0, 0, 0.9]]), + np.array( + [ + [ + [False, False, False, False, False], + [False, True, True, False, False], + [False, True, True, False, False], + [False, False, False, False, False], + [False, False, False, False, False], + ], + [ + [False, False, False, False, False], + [False, False, False, False, False], + [False, False, False, True, True], + [False, False, False, True, True], + [False, False, False, False, False], + ], + ] + ), + 0.5, + np.array([True, True]), + DoesNotRaise(), + ), # two masks non-overlapping with no category + ( + np.array([[0, 0, 0, 0, 0.8], [0, 0, 0, 0, 0.9]]), + np.array( + [ + [ + [False, False, False, False, False], + [False, True, True, True, False], + [False, True, True, True, False], + [False, True, True, True, False], + [False, False, False, False, False], + ], + [ + [False, False, False, False, False], + [False, False, True, True, True], + [False, False, True, True, True], + [False, False, True, True, True], + [False, False, False, False, False], + ], + ] + ), + 0.4, + np.array([False, True]), + DoesNotRaise(), + ), # two masks partially overlapping with no category + ( + np.array([[0, 0, 0, 0, 0.8, 0], [0, 0, 0, 0, 0.9, 1]]), + np.array( + [ + [ + [False, False, False, False, False], + [False, True, True, True, False], + [False, True, True, True, False], + [False, True, True, True, False], + [False, False, False, False, False], + ], + [ + [False, False, False, False, False], + [False, False, True, True, True], + [False, False, True, True, True], + [False, False, True, True, True], + [False, False, False, False, False], + ], + ] + ), + 0.5, + np.array([True, True]), + DoesNotRaise(), + ), # two masks partially overlapping with different category + ( + np.array( + [ + [0, 0, 0, 0, 0.8], + [0, 0, 0, 0, 0.85], + [0, 0, 0, 0, 0.9], + ] + ), + np.array( + [ + [ + [False, False, False, False, False], + [False, True, True, False, False], + [False, True, True, False, False], + [False, False, False, False, False], + [False, False, False, False, False], + ], + [ + [False, False, False, False, False], + [False, True, True, False, False], + [False, True, True, False, False], + [False, False, False, False, False], + [False, False, False, False, False], + ], + [ + [False, False, False, False, False], + [False, False, False, True, True], + [False, False, False, True, True], + [False, False, False, False, False], + [False, False, False, False, False], + ], + ] + ), + 0.5, + np.array([False, True, True]), + DoesNotRaise(), + ), # three masks with no category + ( + np.array( + [ + [0, 0, 0, 0, 0.8, 0], + [0, 0, 0, 0, 0.85, 1], + [0, 0, 0, 0, 0.9, 2], + ] + ), + np.array( + [ + [ + [False, False, False, False, False], + [False, True, True, False, False], + [False, True, True, False, False], + [False, False, False, False, False], + [False, False, False, False, False], + ], + [ + [False, False, False, False, False], + [False, True, True, False, False], + [False, True, True, False, False], + [False, True, True, False, False], + [False, False, False, False, False], + ], + [ + [False, False, False, False, False], + [False, True, True, False, False], + [False, True, True, False, False], + [False, False, False, False, False], + [False, False, False, False, False], + ], + ] + ), + 0.5, + np.array([True, True, True]), + DoesNotRaise(), + ), # three masks with different category + ], +) +def test_mask_non_max_suppression( + predictions: np.ndarray, + masks: np.ndarray, + iou_threshold: float, + expected_result: Optional[np.ndarray], + exception: Exception, +) -> None: + with exception: + result = mask_non_max_suppression( + predictions=predictions, masks=masks, iou_threshold=iou_threshold + ) + assert np.array_equal(result, expected_result) diff --git a/test/detection/test_polygonzone.py b/test/detection/test_polygonzone.py index 1a86a45b..ed899615 100644 --- a/test/detection/test_polygonzone.py +++ b/test/detection/test_polygonzone.py @@ -92,3 +92,19 @@ def test_polygon_zone_trigger( with exception: in_zone = polygon_zone.trigger(detections) assert np.all(in_zone == expected_results) + + +@pytest.mark.parametrize( + "polygon, triggering_anchors, exception", + [ + (POLYGON, [sv.Position.CENTER], DoesNotRaise()), + ( + POLYGON, + [], + pytest.raises(ValueError), + ), + ], +) +def test_polygon_zone_initialization(polygon, triggering_anchors, exception): + with exception: + sv.PolygonZone(polygon, FRAME_RESOLUTION, triggering_anchors=triggering_anchors) diff --git a/test/detection/test_utils.py b/test/detection/test_utils.py index 1c4a1d34..20c818e6 100644 --- a/test/detection/test_utils.py +++ b/test/detection/test_utils.py @@ -2,16 +2,17 @@ from contextlib import ExitStack as DoesNotRaise from typing import Any, Dict, List, Optional, Tuple import numpy as np +import numpy.typing as npt import pytest from supervision.config import CLASS_NAME_DATA_FIELD from supervision.detection.utils import ( - box_non_max_suppression, calculate_masks_centroids, clip_boxes, + contains_holes, + contains_multiple_segments, filter_polygons_by_area, get_data_item, - mask_non_max_suppression, merge_data, move_boxes, process_roboflow_result, @@ -22,317 +23,6 @@ TEST_MASK = np.zeros((1, 1000, 1000), dtype=bool) TEST_MASK[:, 300:351, 200:251] = True -@pytest.mark.parametrize( - "predictions, iou_threshold, expected_result, exception", - [ - ( - np.empty(shape=(0, 5)), - 0.5, - np.array([]), - DoesNotRaise(), - ), # single box with no category - ( - np.array([[10.0, 10.0, 40.0, 40.0, 0.8]]), - 0.5, - np.array([True]), - DoesNotRaise(), - ), # single box with no category - ( - np.array([[10.0, 10.0, 40.0, 40.0, 0.8, 0]]), - 0.5, - np.array([True]), - DoesNotRaise(), - ), # single box with category - ( - np.array( - [ - [10.0, 10.0, 40.0, 40.0, 0.8], - [15.0, 15.0, 40.0, 40.0, 0.9], - ] - ), - 0.5, - np.array([False, True]), - DoesNotRaise(), - ), # two boxes with no category - ( - np.array( - [ - [10.0, 10.0, 40.0, 40.0, 0.8, 0], - [15.0, 15.0, 40.0, 40.0, 0.9, 1], - ] - ), - 0.5, - np.array([True, True]), - DoesNotRaise(), - ), # two boxes with different category - ( - np.array( - [ - [10.0, 10.0, 40.0, 40.0, 0.8, 0], - [15.0, 15.0, 40.0, 40.0, 0.9, 0], - ] - ), - 0.5, - np.array([False, True]), - DoesNotRaise(), - ), # two boxes with same category - ( - np.array( - [ - [0.0, 0.0, 30.0, 40.0, 0.8], - [5.0, 5.0, 35.0, 45.0, 0.9], - [10.0, 10.0, 40.0, 50.0, 0.85], - ] - ), - 0.5, - np.array([False, True, False]), - DoesNotRaise(), - ), # three boxes with no category - ( - np.array( - [ - [0.0, 0.0, 30.0, 40.0, 0.8, 0], - [5.0, 5.0, 35.0, 45.0, 0.9, 1], - [10.0, 10.0, 40.0, 50.0, 0.85, 2], - ] - ), - 0.5, - np.array([True, True, True]), - DoesNotRaise(), - ), # three boxes with same category - ( - np.array( - [ - [0.0, 0.0, 30.0, 40.0, 0.8, 0], - [5.0, 5.0, 35.0, 45.0, 0.9, 0], - [10.0, 10.0, 40.0, 50.0, 0.85, 1], - ] - ), - 0.5, - np.array([False, True, True]), - DoesNotRaise(), - ), # three boxes with different category - ], -) -def test_box_non_max_suppression( - predictions: np.ndarray, - iou_threshold: float, - expected_result: Optional[np.ndarray], - exception: Exception, -) -> None: - with exception: - result = box_non_max_suppression( - predictions=predictions, iou_threshold=iou_threshold - ) - assert np.array_equal(result, expected_result) - - -@pytest.mark.parametrize( - "predictions, masks, iou_threshold, expected_result, exception", - [ - ( - np.empty((0, 6)), - np.empty((0, 5, 5)), - 0.5, - np.array([]), - DoesNotRaise(), - ), # empty predictions and masks - ( - np.array([[0, 0, 0, 0, 0.8]]), - np.array( - [ - [ - [False, False, False, False, False], - [False, True, True, True, False], - [False, True, True, True, False], - [False, True, True, True, False], - [False, False, False, False, False], - ] - ] - ), - 0.5, - np.array([True]), - DoesNotRaise(), - ), # single mask with no category - ( - np.array([[0, 0, 0, 0, 0.8, 0]]), - np.array( - [ - [ - [False, False, False, False, False], - [False, True, True, True, False], - [False, True, True, True, False], - [False, True, True, True, False], - [False, False, False, False, False], - ] - ] - ), - 0.5, - np.array([True]), - DoesNotRaise(), - ), # single mask with category - ( - np.array([[0, 0, 0, 0, 0.8], [0, 0, 0, 0, 0.9]]), - np.array( - [ - [ - [False, False, False, False, False], - [False, True, True, False, False], - [False, True, True, False, False], - [False, False, False, False, False], - [False, False, False, False, False], - ], - [ - [False, False, False, False, False], - [False, False, False, False, False], - [False, False, False, True, True], - [False, False, False, True, True], - [False, False, False, False, False], - ], - ] - ), - 0.5, - np.array([True, True]), - DoesNotRaise(), - ), # two masks non-overlapping with no category - ( - np.array([[0, 0, 0, 0, 0.8], [0, 0, 0, 0, 0.9]]), - np.array( - [ - [ - [False, False, False, False, False], - [False, True, True, True, False], - [False, True, True, True, False], - [False, True, True, True, False], - [False, False, False, False, False], - ], - [ - [False, False, False, False, False], - [False, False, True, True, True], - [False, False, True, True, True], - [False, False, True, True, True], - [False, False, False, False, False], - ], - ] - ), - 0.4, - np.array([False, True]), - DoesNotRaise(), - ), # two masks partially overlapping with no category - ( - np.array([[0, 0, 0, 0, 0.8, 0], [0, 0, 0, 0, 0.9, 1]]), - np.array( - [ - [ - [False, False, False, False, False], - [False, True, True, True, False], - [False, True, True, True, False], - [False, True, True, True, False], - [False, False, False, False, False], - ], - [ - [False, False, False, False, False], - [False, False, True, True, True], - [False, False, True, True, True], - [False, False, True, True, True], - [False, False, False, False, False], - ], - ] - ), - 0.5, - np.array([True, True]), - DoesNotRaise(), - ), # two masks partially overlapping with different category - ( - np.array( - [ - [0, 0, 0, 0, 0.8], - [0, 0, 0, 0, 0.85], - [0, 0, 0, 0, 0.9], - ] - ), - np.array( - [ - [ - [False, False, False, False, False], - [False, True, True, False, False], - [False, True, True, False, False], - [False, False, False, False, False], - [False, False, False, False, False], - ], - [ - [False, False, False, False, False], - [False, True, True, False, False], - [False, True, True, False, False], - [False, False, False, False, False], - [False, False, False, False, False], - ], - [ - [False, False, False, False, False], - [False, False, False, True, True], - [False, False, False, True, True], - [False, False, False, False, False], - [False, False, False, False, False], - ], - ] - ), - 0.5, - np.array([False, True, True]), - DoesNotRaise(), - ), # three masks with no category - ( - np.array( - [ - [0, 0, 0, 0, 0.8, 0], - [0, 0, 0, 0, 0.85, 1], - [0, 0, 0, 0, 0.9, 2], - ] - ), - np.array( - [ - [ - [False, False, False, False, False], - [False, True, True, False, False], - [False, True, True, False, False], - [False, False, False, False, False], - [False, False, False, False, False], - ], - [ - [False, False, False, False, False], - [False, True, True, False, False], - [False, True, True, False, False], - [False, True, True, False, False], - [False, False, False, False, False], - ], - [ - [False, False, False, False, False], - [False, True, True, False, False], - [False, True, True, False, False], - [False, False, False, False, False], - [False, False, False, False, False], - ], - ] - ), - 0.5, - np.array([True, True, True]), - DoesNotRaise(), - ), # three masks with different category - ], -) -def test_mask_non_max_suppression( - predictions: np.ndarray, - masks: np.ndarray, - iou_threshold: float, - expected_result: Optional[np.ndarray], - exception: Exception, -) -> None: - with exception: - result = mask_non_max_suppression( - predictions=predictions, masks=masks, iou_threshold=iou_threshold - ) - assert np.array_equal(result, expected_result) - - @pytest.mark.parametrize( "xyxy, resolution_wh, expected_result", [ @@ -911,6 +601,14 @@ def test_calculate_masks_centroids( {"test_1": []}, DoesNotRaise(), ), # single data dict with a single field name and empty list values + ( + [ + {"test_1": []}, + {"test_1": []}, + ], + {"test_1": []}, + DoesNotRaise(), + ), # two data dicts with the same field name and empty list values ( [ {"test_1": np.array([])}, @@ -918,6 +616,14 @@ def test_calculate_masks_centroids( {"test_1": np.array([])}, DoesNotRaise(), ), # single data dict with a single field name and empty np.array values + ( + [ + {"test_1": np.array([])}, + {"test_1": np.array([])}, + ], + {"test_1": np.array([])}, + DoesNotRaise(), + ), # two data dicts with the same field name and empty np.array values ( [ {"test_1": [1, 2, 3]}, @@ -932,7 +638,7 @@ def test_calculate_masks_centroids( ], {"test_1": [3, 2, 1]}, DoesNotRaise(), - ), # two data dicts with the same field name and empty and list values + ), # two data dicts with the same field name; one of with empty list as value ( [ {"test_1": [1, 2, 3]}, @@ -1012,6 +718,49 @@ def test_calculate_masks_centroids( None, pytest.raises(ValueError), ), # two data dicts with the same field name and different length arrays values + ( + [{}, {"test_1": [1, 2, 3]}], + None, + pytest.raises(ValueError), + ), # two data dicts; one empty and one non-empty dict + ( + [{"test_1": [], "test_2": []}, {"test_1": [1, 2, 3], "test_2": [1, 2, 3]}], + {"test_1": [1, 2, 3], "test_2": [1, 2, 3]}, + DoesNotRaise(), + ), # two data dicts; one empty and one non-empty dict; same keys + ( + [{"test_1": []}, {"test_1": [1, 2, 3], "test_2": [4, 5, 6]}], + None, + pytest.raises(ValueError), + ), # two data dicts; one empty and one non-empty dict; different keys + ( + [ + { + "test_1": [1, 2, 3], + "test_2": [4, 5, 6], + "test_3": [7, 8, 9], + }, + {"test_1": [1, 2, 3], "test_2": [4, 5, 6]}, + ], + None, + pytest.raises(ValueError), + ), # two data dicts; one with three keys, one with two keys + ( + [ + {"test_1": [1, 2, 3]}, + {"test_1": [1, 2, 3], "test_2": [1, 2, 3]}, + ], + None, + pytest.raises(ValueError), + ), # some keys missing in one dict + ( + [ + {"test_1": [1, 2, 3], "test_2": ["a", "b"]}, + {"test_1": [4, 5], "test_2": ["c", "d", "e"]}, + ], + None, + pytest.raises(ValueError), + ), # different value lengths for the same key ], ) def test_merge_data( @@ -1021,6 +770,9 @@ def test_merge_data( ): with exception: result = merge_data(data_list=data_list) + if expected_result is None: + assert False, f"Expected an error, but got result {result}" + for key in result: if isinstance(result[key], np.ndarray): assert np.array_equal( @@ -1203,3 +955,138 @@ def test_get_data_item( assert ( result[key] == expected_result[key] ), f"Mismatch in non-array data for key {key}" + + +@pytest.mark.parametrize( + "mask, expected_result, exception", + [ + ( + np.array([[0, 0, 0, 0], [0, 1, 1, 0], [0, 1, 0, 0], [0, 1, 1, 0]]).astype( + bool + ), + False, + DoesNotRaise(), + ), # foreground object in one continuous piece + ( + np.array([[1, 0, 0, 0], [1, 0, 0, 0], [0, 0, 0, 0], [0, 1, 1, 0]]).astype( + bool + ), + False, + DoesNotRaise(), + ), # foreground object in 2 seperate elements + ( + np.array([[0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0]]).astype( + bool + ), + False, + DoesNotRaise(), + ), # no foreground pixels in mask + ( + np.array([[1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1]]).astype( + bool + ), + False, + DoesNotRaise(), + ), # only foreground pixels in mask + ( + np.array([[1, 1, 1, 0], [1, 0, 1, 0], [1, 1, 1, 0], [0, 0, 0, 0]]).astype( + bool + ), + True, + DoesNotRaise(), + ), # foreground object has 1 hole + ( + np.array([[1, 1, 1, 0], [1, 0, 1, 1], [1, 1, 0, 1], [0, 1, 1, 1]]).astype( + bool + ), + True, + DoesNotRaise(), + ), # foreground object has 2 holes + ], +) +def test_contains_holes( + mask: npt.NDArray[np.bool_], expected_result: bool, exception: Exception +) -> None: + with exception: + result = contains_holes(mask) + assert result == expected_result + + +@pytest.mark.parametrize( + "mask, connectivity, expected_result, exception", + [ + ( + np.array([[0, 0, 0, 0], [0, 1, 1, 0], [0, 1, 0, 0], [0, 1, 1, 0]]).astype( + bool + ), + 4, + False, + DoesNotRaise(), + ), # foreground object in one continuous piece + ( + np.array([[1, 0, 0, 0], [1, 0, 0, 0], [0, 0, 0, 0], [0, 1, 1, 0]]).astype( + bool + ), + 4, + True, + DoesNotRaise(), + ), # foreground object in 2 seperate elements + ( + np.array([[0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0], [0, 0, 0, 0]]).astype( + bool + ), + 4, + False, + DoesNotRaise(), + ), # no foreground pixels in mask + ( + np.array([[1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1], [1, 1, 1, 1]]).astype( + bool + ), + 4, + False, + DoesNotRaise(), + ), # only foreground pixels in mask + ( + np.array([[1, 1, 1, 0], [1, 0, 1, 1], [1, 1, 0, 1], [0, 1, 1, 1]]).astype( + bool + ), + 4, + False, + DoesNotRaise(), + ), # foreground object has 2 holes, but is in single piece + ( + np.array([[1, 1, 0, 0], [1, 1, 0, 1], [1, 0, 1, 1], [0, 0, 1, 1]]).astype( + bool + ), + 4, + True, + DoesNotRaise(), + ), # foreground object in 2 elements with respect to 4-way connectivity + ( + np.array([[1, 1, 0, 0], [1, 1, 0, 1], [1, 0, 1, 1], [0, 0, 1, 1]]).astype( + bool + ), + 8, + False, + DoesNotRaise(), + ), # foreground object in single piece with respect to 8-way connectivity + ( + np.array([[1, 1, 0, 0], [1, 1, 0, 1], [1, 0, 1, 1], [0, 0, 1, 1]]).astype( + bool + ), + 5, + None, + pytest.raises(ValueError), + ), # Incorrect connectivity parameter value, raises ValueError + ], +) +def test_contains_multiple_segments( + mask: npt.NDArray[np.bool_], + connectivity: int, + expected_result: bool, + exception: Exception, +) -> None: + with exception: + result = contains_multiple_segments(mask=mask, connectivity=connectivity) + assert result == expected_result diff --git a/test/utils/test_internal.py b/test/utils/test_internal.py new file mode 100644 index 00000000..eee614e6 --- /dev/null +++ b/test/utils/test_internal.py @@ -0,0 +1,193 @@ +from contextlib import ExitStack as DoesNotRaise +from dataclasses import dataclass, field +from typing import Any, Set + +import numpy as np +import pytest + +from supervision.detection.core import Detections +from supervision.utils.internal import get_instance_variables + + +class MockClass: + def __init__(self): + self.public = 0 + self._protected = 1 + self.__private = 2 + + def public_method(self): + pass + + def _protected_method(self): + pass + + def __private_method(self): + pass + + @property + def public_property(self): + return 0 + + @property + def _protected_property(self): + return 1 + + @property + def __private_property(self): + return 2 + + +@dataclass +class MockDataclass: + public: int = 0 + _protected: int = 1 + __private: int = 2 + + public_field: int = field(default=0) + _protected_field: int = field(default=1) + __private_field: int = field(default=2) + + public_field_with_factory: dict = field(default_factory=dict) + _protected_field_with_factory: dict = field(default_factory=dict) + __private_field_with_factory: dict = field(default_factory=dict) + + def public_method(self): + pass + + def _protected_method(self): + pass + + def __private_method(self): + pass + + @property + def public_property(self): + return 0 + + @property + def _protected_property(self): + return 1 + + @property + def __private_property(self): + return 2 + + +@pytest.mark.parametrize( + "input_instance, include_properties, expected, exception", + [ + ( + MockClass, + False, + None, + pytest.raises(ValueError), + ), + ( + MockClass(), + False, + {"public"}, + DoesNotRaise(), + ), + ( + MockClass(), + True, + {"public", "public_property"}, + DoesNotRaise(), + ), + ( + MockDataclass(), + False, + {"public", "public_field", "public_field_with_factory"}, + DoesNotRaise(), + ), + ( + MockDataclass(), + True, + {"public", "public_field", "public_field_with_factory", "public_property"}, + DoesNotRaise(), + ), + ( + Detections, + False, + None, + pytest.raises(ValueError), + ), + ( + Detections, + True, + None, + pytest.raises(ValueError), + ), + ( + Detections.empty(), + False, + {"xyxy", "class_id", "confidence", "mask", "tracker_id", "data"}, + DoesNotRaise(), + ), + ( + Detections.empty(), + True, + { + "xyxy", + "class_id", + "confidence", + "mask", + "tracker_id", + "data", + "area", + "box_area", + }, + DoesNotRaise(), + ), + ( + Detections(xyxy=np.array([[1, 2, 3, 4]])), + False, + { + "xyxy", + "class_id", + "confidence", + "mask", + "tracker_id", + "data", + }, + DoesNotRaise(), + ), + ( + Detections( + xyxy=np.array([[1, 2, 3, 4], [5, 6, 7, 8]]), + class_id=np.array([1, 2]), + confidence=np.array([0.1, 0.2]), + mask=np.array([[[1]], [[2]]]), + tracker_id=np.array([1, 2]), + data={"key_1": [1, 2], "key_2": [3, 4]}, + ), + False, + { + "xyxy", + "class_id", + "confidence", + "mask", + "tracker_id", + "data", + }, + DoesNotRaise(), + ), + ( + Detections.empty(), + False, + {"xyxy", "class_id", "confidence", "mask", "tracker_id", "data"}, + DoesNotRaise(), + ), + ], +) +def test_get_instance_variables( + input_instance: Any, + include_properties: bool, + expected: Set[str], + exception: Exception, +) -> None: + with exception: + result = get_instance_variables( + input_instance, include_properties=include_properties + ) + assert result == expected