Merge branch 'develop' into dfreilich/add-icon-annotator
This commit is contained in:
 LinasKo
+2
-2
@@ -19,13 +19,13 @@ as an extra within the Supervision package.
|
||||
```
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>download_assets</h2>
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.download_assets">download_assets</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.downloader.download_assets
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoAssets</h2>
|
||||
<h2><a href="#supervision.assets.downloader.download_assets.VideoAssets">VideoAssets</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.assets.list.VideoAssets
|
||||
|
||||
+376
-5
@@ -1,6 +1,380 @@
|
||||
### 0.22.0 <small>Jul 12, 2024</small>
|
||||
|
||||
- Added [#1326](https://github.com/roboflow/supervision/pull/1326): [`sv.DetectionsDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset) and [`sv.ClassificationDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.ClassificationDataset) allowing to load the images into memory only when necessary (lazy loading).
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
Constructing `DetectionDataset` with parameter `images` as `Dict[str, np.ndarray]` is deprecated and will be removed in `supervision-0.26.0`. Please pass a list of paths `List[str]` instead.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `DetectionDataset.images` property is deprecated and will be removed in `supervision-0.26.0`. Please loop over images with `for path, image, annotation in dataset:`, as that does not require loading all images into memory.
|
||||
|
||||
```python
|
||||
import roboflow
|
||||
from roboflow import Roboflow
|
||||
import supervision as sv
|
||||
|
||||
roboflow.login()
|
||||
rf = Roboflow()
|
||||
|
||||
project = rf.workspace(<WORKSPACE_ID>).project(<PROJECT_ID>)
|
||||
dataset = project.version(<PROJECT_VERSION>).download("coco")
|
||||
|
||||
ds_train = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f"{dataset.location}/train",
|
||||
annotations_path=f"{dataset.location}/train/_annotations.coco.json",
|
||||
)
|
||||
|
||||
path, image, annotation = ds_train[0]
|
||||
# loads image on demand
|
||||
|
||||
for path, image, annotation in ds_train:
|
||||
# loads image on demand
|
||||
```
|
||||
|
||||
- Added [#1296](https://github.com/roboflow/supervision/pull/1296): [`sv.Detections.from_lmm`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_lmm) now supports parsing results from the [Florence 2](https://huggingface.co/microsoft/Florence-2-large) model, extending the capability to handle outputs from this Large Multimodal Model (LMM). This includes detailed object detection, OCR with region proposals, segmentation, and more. Find out more in our [Colab notebook](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-finetune-florence-2-on-detection-dataset.ipynb).
|
||||
|
||||
- Added [#1232](https://github.com/roboflow/supervision/pull/1232) to support keypoint detection with Mediapipe. Both [legacy](https://colab.research.google.com/github/googlesamples/mediapipe/blob/main/examples/pose_landmarker/python/%5BMediaPipe_Python_Tasks%5D_Pose_Landmarker.ipynb) and [modern](https://ai.google.dev/edge/mediapipe/solutions/vision/pose_landmarker/python) pipelines are supported. See [`sv.KeyPoints.from_mediapipe`](https://supervision.roboflow.com/latest/keypoint/core/#supervision.keypoint.core.KeyPoints.from_mediapipe) for more.
|
||||
|
||||
- Added [#1316](https://github.com/roboflow/supervision/pull/1316): [`sv.KeyPoints.from_mediapipe`](https://supervision.roboflow.com/latest/keypoint/core/#supervision.keypoint.core.KeyPoints.from_mediapipe) extended to support FaceMesh from Mediapipe. This enhancement allows for processing both face landmarks from `FaceLandmarker`, and legacy results from `FaceMesh`.
|
||||
|
||||
- Added [#1310](https://github.com/roboflow/supervision/pull/1310): [`sv.KeyPoints.from_detectron2`](https://supervision.roboflow.com/latest/keypoint/core/#supervision.keypoint.core.KeyPoints.from_detectron2) is a new `KeyPoints` method, adding support for extracting keypoints from the popular [Detectron 2](https://github.com/facebookresearch/detectron2) platform.
|
||||
|
||||
- Added [#1300](https://github.com/roboflow/supervision/pull/1300): [`sv.Detections.from_detectron2`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_detectron2) now supports segmentation models detectron2. The resulting masks can be used with [`sv.MaskAnnotator`](https://supervision.roboflow.com/latest/annotators/#supervision.annotators.core.MaskAnnotator) for displaying annotations.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from detectron2 import model_zoo
|
||||
from detectron2.engine import DefaultPredictor
|
||||
from detectron2.config import get_cfg
|
||||
import cv2
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
cfg = get_cfg()
|
||||
cfg.merge_from_file(model_zoo.get_config_file("COCO-InstanceSegmentation/mask_rcnn_R_50_FPN_3x.yaml"))
|
||||
cfg.MODEL.WEIGHTS = model_zoo.get_checkpoint_url("COCO-InstanceSegmentation/mask_rcnn_R_50_FPN_3x.yaml")
|
||||
predictor = DefaultPredictor(cfg)
|
||||
|
||||
result = predictor(image)
|
||||
detections = sv.Detections.from_detectron2(result)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
annotated_frame = mask_annotator.annotate(scene=image.copy(), detections=detections)
|
||||
```
|
||||
|
||||
- Added [#1277](https://github.com/roboflow/supervision/pull/1277): if you provide a font that supports symbols of a language, [`sv.RichLabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator.annotate) will draw them on your images.
|
||||
- Various other annotators have been revised to ensure proper in-place functionality when used with `numpy` arrays. Additionally, we fixed a bug where `sv.ColorAnnotator` was filling boxes with solid color when used in-place.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
import
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
rich_label_annotator = sv.RichLabelAnnotator(font_path=<TTF_FONT_PATH>)
|
||||
annotated_image = rich_label_annotator.annotate(scene=image.copy(), detections=detections)
|
||||
```
|
||||
|
||||
- Added [#1227](https://github.com/roboflow/supervision/pull/1227): Added support for loading Oriented Bounding Boxes dataset in YOLO format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
train_ds = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path="/content/dataset/train/images",
|
||||
annotations_directory_path="/content/dataset/train/labels",
|
||||
data_yaml_path="/content/dataset/data.yaml",
|
||||
is_obb=True
|
||||
)
|
||||
|
||||
_, image, detections in train_ds[0]
|
||||
|
||||
obb_annotator = OrientedBoxAnnotator()
|
||||
annotated_image = obb_annotator.annotate(scene=image.copy(), detections=detections)
|
||||
```
|
||||
|
||||
- Fixed [#1312](https://github.com/roboflow/supervision/pull/1312): Fixed [`CropAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.TraceAnnotator.annotate).
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
`BoxAnnotator` was removed, however `BoundingBoxAnnotator` has been renamed to `BoxAnnotator`. Use a combination of [`BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator) and [`LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator) to simulate old `BoundingBox` behavior.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The name `BoundingBoxAnnotator` has been deprecated and will be removed in `supervision-0.26.0`. It has been renamed to [`BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator).
|
||||
|
||||
- Added [#975](https://github.com/roboflow/supervision/pull/975) 📝 New Cookbooks: serialize detections into [json](https://github.com/roboflow/supervision/blob/de896189b83a1f9434c0a37dd9192ee00d2a1283/docs/notebooks/serialise-detections-to-json.ipynb) and [csv](https://github.com/roboflow/supervision/blob/de896189b83a1f9434c0a37dd9192ee00d2a1283/docs/notebooks/serialise-detections-to-csv.ipynb).
|
||||
|
||||
- Added [#1290](https://github.com/roboflow/supervision/pull/1290): Mostly an internal change, our file utility function now support both `str` and `pathlib` paths.
|
||||
|
||||
- Added [#1340](https://github.com/roboflow/supervision/pull/1340): Two new methods for converting between bounding box formats - [`xywh_to_xyxy`](https://supervision.roboflow.com/latest/detection/utils/#supervision.detection.utils.xywh_to_xyxy) and [`xcycwh_to_xyxy`](https://supervision.roboflow.com/latest/detection/utils/#supervision.detection.utils.xcycwh_to_xyxy)
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
`from_roboflow` method has been removed due to deprecation. Use [from_inference](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_inference) instead.
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
`Color.white()` has been removed due to deprecation. Use `color.WHITE` instead.
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
`Color.black()` has been removed due to deprecation. Use `color.BLACK` instead.
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
`Color.red()` has been removed due to deprecation. Use `color.RED` instead.
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
`Color.green()` has been removed due to deprecation. Use `color.GREEN` instead.
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
`Color.blue()` has been removed due to deprecation. Use `color.BLUE` instead.
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
`ColorPalette.default()` has been removed due to deprecation. Use [ColorPalette.DEFAULT](https://supervision.roboflow.com/latest/utils/draw/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
|
||||
!!! failure "Removed"
|
||||
|
||||
`FPSMonitor.__call__` has been removed due to deprecation. Use the attribute [FPSMonitor.fps](https://supervision.roboflow.com/latest/utils/video/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
|
||||
### 0.21.0 <small>Jun 5, 2024</small>
|
||||
|
||||
- Added [#500](https://github.com/roboflow/supervision/pull/500): [`sv.Detections.with_nmm`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.with_nmm) to perform non-maximum merging on the current set of object detections.
|
||||
|
||||
- Added [#1221](https://github.com/roboflow/supervision/pull/1221): [`sv.Detections.from_lmm`](https://supervision.roboflow.com/latest/detection/core/#supervision.detection.core.Detections.from_lmm) allowing to parse Large Multimodal Model (LMM) text result into [`sv.Detections`](https://supervision.roboflow.com/latest/detection/core/) object. For now `from_lmm` supports only [PaliGemma](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/how-to-finetune-paligemma-on-detection-dataset.ipynb) result parsing.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
paligemma_result = "<loc0256><loc0256><loc0768><loc0768> cat"
|
||||
detections = sv.Detections.from_lmm(
|
||||
sv.LMM.PALIGEMMA,
|
||||
paligemma_result,
|
||||
resolution_wh=(1000, 1000),
|
||||
classes=['cat', 'dog']
|
||||
)
|
||||
detections.xyxy
|
||||
# array([[250., 250., 750., 750.]])
|
||||
|
||||
detections.class_id
|
||||
# array([0])
|
||||
```
|
||||
|
||||
- Added [#1236](https://github.com/roboflow/supervision/pull/1236): [`sv.VertexLabelAnnotator`](https://supervision.roboflow.com/latest/keypoint/annotators/#supervision.keypoint.annotators.EdgeAnnotator.annotate) allowing to annotate every vertex of a keypoint skeleton with custom text and color.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
thickness=5
|
||||
)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
- Added [#1147](https://github.com/roboflow/supervision/pull/1147): [`sv.KeyPoints.from_inference`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints.from_inference) allowing to create [`sv.KeyPoints`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints) from [Inference](https://github.com/roboflow/inference) result.
|
||||
|
||||
- Added [#1138](https://github.com/roboflow/supervision/pull/1138): [`sv.KeyPoints.from_yolo_nas`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints.from_yolo_nas) allowing to create [`sv.KeyPoints`](https://supervision.roboflow.com/develop/keypoint/core/#supervision.keypoint.core.KeyPoints) from [YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md) result.
|
||||
|
||||
- Added [#1163](https://github.com/roboflow/supervision/pull/1163): [`sv.mask_to_rle`](https://supervision.roboflow.com/develop/datasets/utils/#supervision.dataset.utils.rle_to_mask) and [`sv.rle_to_mask`](https://supervision.roboflow.com/develop/datasets/utils/#supervision.dataset.utils.rle_to_mask) allowing for easy conversion between mask and rle formats.
|
||||
|
||||
- Changed [#1236](https://github.com/roboflow/supervision/pull/1236): [`sv.InferenceSlicer`](https://supervision.roboflow.com/develop/detection/tools/inference_slicer/) allowing to select overlap filtering strategy (`NONE`, `NON_MAX_SUPPRESSION` and `NON_MAX_MERGE`).
|
||||
|
||||
- Changed [#1178](https://github.com/roboflow/supervision/pull/1178): [`sv.InferenceSlicer`](https://supervision.roboflow.com/develop/detection/tools/inference_slicer/) adding instance segmentation model support.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-seg-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
return sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
- Changed [#1228](https://github.com/roboflow/supervision/pull/1228): [`sv.LineZone`](https://supervision.roboflow.com/develop/detection/tools/line_zone/) making it 10-20 times faster, depending on the use case.
|
||||
|
||||
- Changed [#1163](https://github.com/roboflow/supervision/pull/1163): [`sv.DetectionDataset.from_coco`](https://supervision.roboflow.com/develop/datasets/core/#supervision.dataset.core.DetectionDataset.from_coco) and [`sv.DetectionDataset.as_coco`](https://supervision.roboflow.com/develop/datasets/core/#supervision.dataset.core.DetectionDataset.as_coco) adding support for run-length encoding (RLE) mask format.
|
||||
|
||||
### 0.20.0 <small>April 24, 2024</small>
|
||||
|
||||
- Added [#1128](https://github.com/roboflow/supervision/pull/1128): [`sv.KeyPoints`](/0.20.0/keypoint/core/#supervision.keypoint.core.KeyPoints) to provide initial support for pose estimation and broader keypoint detection models.
|
||||
|
||||
- Added [#1128](https://github.com/roboflow/supervision/pull/1128): [`sv.EdgeAnnotator`](/0.20.0/keypoint/annotators/#supervision.keypoint.annotators.EdgeAnnotator) and [`sv.VertexAnnotator`](/0.20.0/keypoint/annotators/#supervision.keypoint.annotators.VertexAnnotator) to enable rendering of results from keypoint detection models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = YOLO('yolov8l-pose')
|
||||
|
||||
result = model(image, verbose=False)[0]
|
||||
keypoints = sv.KeyPoints.from_ultralytics(result)
|
||||
|
||||
edge_annotators = sv.EdgeAnnotator(color=sv.Color.GREEN, thickness=5)
|
||||
annotated_image = edge_annotators.annotate(image.copy(), keypoints)
|
||||
```
|
||||
|
||||
- Changed [#1037](https://github.com/roboflow/supervision/pull/1037): [`sv.LabelAnnotator`](/0.20.0/annotators/#supervision.annotators.core.LabelAnnotator) by adding an additional `corner_radius` argument that allows for rounding the corners of the bounding box.
|
||||
|
||||
- Changed [#1109](https://github.com/roboflow/supervision/pull/1109): [`sv.PolygonZone`](/0.20.0/detection/tools/polygon_zone/#supervision.detection.tools.polygon_zone.PolygonZone) such that the `frame_resolution_wh` argument is no longer required to initialize `sv.PolygonZone`.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `frame_resolution_wh` parameter in `sv.PolygonZone` is deprecated and will be removed in `supervision-0.24.0`.
|
||||
|
||||
- Changed [#1084](https://github.com/roboflow/supervision/pull/1084): [`sv.get_polygon_center`](/0.20.0/utils/geometry/#supervision.geometry.core.utils.get_polygon_center) to calculate a more accurate polygon centroid.
|
||||
|
||||
- Changed [#1069](https://github.com/roboflow/supervision/pull/1069): [`sv.Detections.from_transformers`](/0.20.0/detection/core/#supervision.detection.core.Detections.from_transformers) by adding support for Transformers segmentation models and extract class names values.
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForSegmentation
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_segmentation(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results, id2label=model.config.id2label)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
- Fixed [#787](https://github.com/roboflow/supervision/pull/787): [`sv.ByteTrack.update_with_detections`](/0.20.0/trackers/#supervision.tracker.byte_tracker.core.ByteTrack.update_with_detections) which was removing segmentation masks while tracking. Now, `ByteTrack` can be used alongside segmentation models.
|
||||
|
||||
### 0.19.0 <small>March 15, 2024</small>
|
||||
|
||||
- Added [#818](https://github.com/roboflow/supervision/pull/818): [`sv.CSVSink`](/0.19.0/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) allowing for the straightforward saving of image, video, or stream inference results in a `.csv` file.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO(<SOURCE_MODEL_PATH>)
|
||||
csv_sink = sv.CSVSink(<RESULT_CSV_FILE_PATH>)
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with csv_sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
csv_sink.append(detections, custom_data={<CUSTOM_LABEL>:<CUSTOM_DATA>})
|
||||
```
|
||||
|
||||
- Added [#819](https://github.com/roboflow/supervision/pull/819): [`sv.JSONSink`](/0.19.0/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink) allowing for the straightforward saving of image, video, or stream inference results in a `.json` file.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO(<SOURCE_MODEL_PATH>)
|
||||
json_sink = sv.JSONSink(<RESULT_JSON_FILE_PATH>)
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with json_sink:
|
||||
for frame in frames_generator:
|
||||
result = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(result)
|
||||
json_sink.append(detections, custom_data={<CUSTOM_LABEL>:<CUSTOM_DATA>})
|
||||
```
|
||||
|
||||
- Added [#847](https://github.com/roboflow/supervision/pull/847): [`sv.mask_iou_batch`](/0.19.0/detection/utils/#supervision.detection.utils.mask_iou_batch) allowing to compute Intersection over Union (IoU) of two sets of masks.
|
||||
|
||||
- Added [#847](https://github.com/roboflow/supervision/pull/847): [`sv.mask_non_max_suppression`](/0.19.0/detection/utils/#supervision.detection.utils.mask_non_max_suppression) allowing to perform Non-Maximum Suppression (NMS) on segmentation predictions.
|
||||
|
||||
- Added [#888](https://github.com/roboflow/supervision/pull/888): [`sv.CropAnnotator`](/0.19.0/annotators/#supervision.annotators.core.CropAnnotator) allowing users to annotate the scene with scaled-up crops of detections.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
|
||||
result = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(result)
|
||||
|
||||
crop_annotator = sv.CropAnnotator()
|
||||
annotated_frame = crop_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
- Changed [#827](https://github.com/roboflow/supervision/pull/827): [`sv.ByteTrack.reset`](/0.19.0/tracking/#supervision.tracking.ByteTrack.reset) allowing users to clear trackers state, enabling the processing of multiple video files in sequence.
|
||||
|
||||
- Changed [#802](https://github.com/roboflow/supervision/pull/802): [`sv.LineZoneAnnotator`](/0.19.0/detection/tools/line_zone/#supervision.detection.line_zone.LineZone) allowing to hide in/out count using `display_in_count` and `display_out_count` properties.
|
||||
|
||||
- Changed [#787](https://github.com/roboflow/supervision/pull/787): [`sv.ByteTrack`](/0.19.0/tracking/#supervision.tracking.ByteTrack) input arguments and docstrings updated to improve readability and ease of use.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `track_buffer`, `track_thresh`, and `match_thresh` parameters in `sv.ByterTrack` are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
|
||||
- Changed [#910](https://github.com/roboflow/supervision/pull/910): [`sv.PolygonZone`](/0.19.0/detection/tools/polygon_zone/#supervision.detection.tools.polygon_zone.PolygonZone) to now accept a list of specific box anchors that must be in zone for a detection to be counted.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
The `triggering_position ` parameter in `sv.PolygonZone` is deprecated and will be removed in `supervision-0.23.0`. Use `triggering_anchors` instead.
|
||||
|
||||
- Changed [#875](https://github.com/roboflow/supervision/pull/875): annotators adding support for Pillow images. All supervision Annotators can now accept an image as either a numpy array or a Pillow Image. They automatically detect its type, draw annotations, and return the output in the same format as the input.
|
||||
|
||||
- Fixed [#944](https://github.com/roboflow/supervision/pull/944): [`sv.DetectionsSmoother`](/0.19.0/detection/tools/smoother/#supervision.detection.tools.smoother.DetectionsSmoother) removing `tracking_id` from `sv.Detections`.
|
||||
|
||||
### 0.18.0 <small>January 25, 2024</small>
|
||||
|
||||
- Added [#633](https://github.com/roboflow/supervision/pull/720): [`sv.PercentageBarAnnotator`](/0.18.0/annotators/#percentagebarannotator) allowing to annotate images and videos with percentage values representing confidence or other custom property.
|
||||
- Added [#720](https://github.com/roboflow/supervision/pull/720): [`sv.PercentageBarAnnotator`](/0.18.0/annotators/#percentagebarannotator) allowing to annotate images and videos with percentage values representing confidence or other custom property.
|
||||
|
||||
```python
|
||||
>>> import supervision as sv
|
||||
@@ -58,7 +432,6 @@ ColorPalette(colors=[Color(r=68, g=1, b=84), Color(r=59, g=82, b=139), ...])
|
||||
|
||||
`sv.ColorPalette.default()` is deprecated and will be removed in `supervision-0.22.0`. Use `sv.ColorPalette.DEFAULT` instead.
|
||||
|
||||
|
||||
- Changed [#769](https://github.com/roboflow/supervision/pull/769): [`sv.ColorPalette.DEFAULT`](/0.18.0/draw/color/#colorpalette) value, giving users a more extensive set of annotation colors.
|
||||
|
||||
- Changed [#677](https://github.com/roboflow/supervision/pull/677): `sv.Detections.from_roboflow` to [`sv.Detections.from_inference`](/0.18.0/detection/core/#supervision.detection.core.Detections.from_inference) streamlining its functionality to be compatible with both the both [inference](https://github.com/roboflow/inference) pip package and the Robloflow [hosted API](https://docs.roboflow.com/deploy/hosted-api).
|
||||
@@ -67,7 +440,6 @@ ColorPalette(colors=[Color(r=68, g=1, b=84), Color(r=59, g=82, b=139), ...])
|
||||
|
||||
`Detections.from_roboflow()` is deprecated and will be removed in `supervision-0.22.0`. Use `Detections.from_inference` instead.
|
||||
|
||||
|
||||
- Fixed [#735](https://github.com/roboflow/supervision/pull/735): [`sv.LineZone`](/0.18.0/detection/tools/line_zone/#linezone) functionality to accurately update the counter when an object crosses a line from any direction, including from the side. This enhancement enables more precise tracking and analytics, such as calculating individual in/out counts for each lane on the road.
|
||||
|
||||
### 0.17.0 <small>December 06, 2023</small>
|
||||
@@ -160,13 +532,12 @@ ColorPalette(colors=[Color(r=68, g=1, b=84), Color(r=59, g=82, b=139), ...])
|
||||
|
||||
- Fixed [#477](https://github.com/roboflow/supervision/pull/477): Poetry env definition allowing proper local installation.
|
||||
|
||||
- Fixed [#430](https://github.com/roboflow/supervision/pull/430): [`sv.ByteTrack`](/0.16.0/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) to return `np.array([], dtype=int)` when `svDetections` is empty.
|
||||
- Fixed [#430](https://github.com/roboflow/supervision/pull/430): [`sv.ByteTrack`](/0.16.0/trackers/#supervision.tracker.byte_tracker.core.ByteTrack) to return `np.array([], dtype=int)` when `svDetections` is empty.
|
||||
|
||||
!!! failure "Deprecated"
|
||||
|
||||
`sv.Detections.from_yolov8` and `sv.Classifications.from_yolov8` as those are now replaced by [`sv.Detections.from_ultralytics`](/0.16.0/detection/core/#supervision.detection.core.Detections.from_ultralytics) and [`sv.Classifications.from_ultralytics`](/0.16.0/classification/core/#supervision.classification.core.Classifications.from_ultralytics).
|
||||
|
||||
|
||||
### 0.15.0 <small>October 5, 2023</small>
|
||||
|
||||
- Added [#170](https://github.com/roboflow/supervision/pull/170): [`sv.BoundingBoxAnnotator`](/0.15.0/annotators/#supervision.annotators.core.BoundingBoxAnnotator) allowing to annotate images and videos with bounding boxes.
|
||||
|
||||
@@ -1,7 +1,6 @@
|
||||
---
|
||||
template: cookbooks.html
|
||||
comments: true
|
||||
status: new
|
||||
hide:
|
||||
- navigation
|
||||
- toc
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Datasets
|
||||
@@ -0,0 +1,17 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Datasets Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.dataset.utils.rle_to_mask">rle_to_mask</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.dataset.utils.rle_to_mask
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.dataset.utils.mask_to_rle">mask_to_rle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.dataset.utils.mask_to_rle
|
||||
+21
-10
@@ -3,14 +3,25 @@ comments: true
|
||||
status: deprecated
|
||||
---
|
||||
|
||||
These features are phased out due to better alternatives or potential issues in future versions. Deprecated functionalities are supported for **three subsequent releases**, providing time for users to transition to updated methods.
|
||||
# Deprecated
|
||||
|
||||
- [`Detections.from_froboflow`](detection/core.md/#supervision.detection.core.Detections.from_roboflow) is deprecated and will be removed in `supervision-0.22.0`. Use [`Detections.from_inference`](detection/core.md/#supervision.detection.core.Detections.from_inference) instead.
|
||||
- `Color.white()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.WHITE` instead.
|
||||
- `Color.black()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.BLACK` instead.
|
||||
- `Color.red()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.RED` instead.
|
||||
- `Color.green()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.GREEN` instead.
|
||||
- `Color.blue()` is deprecated and will be removed in `supervision-0.22.0`. Use `Color.BLUE` instead.
|
||||
- [`ColorPalette.default()`](draw/color.md/#supervision.draw.color.ColorPalette.default) is deprecated and will be removed in `supervision-0.22.0`. Use [`ColorPalette.DEFAULT`](draw/color.md/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
- `BoxAnnotator` is deprecated and will be removed in `supervision-0.22.0`. Use [`BoundingBoxAnnotator`](annotators.md/#supervision.annotators.core.BoundingBoxAnnotator) and [`LabelAnnotator`](annotators.md/#supervision.annotators.core.LabelAnnotator) instead.
|
||||
- [`FPSMonitor.__call__`](utils/video.md/#supervision.utils.video.FPSMonitor.__call__) is deprecated and will be removed in `supervision-0.22.0`. Use [`FPSMonitor.fps`](utils/video.md/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
These features are phased out due to better alternatives or potential issues in future versions. Deprecated functionalities are supported for **five subsequent releases**, providing time for users to transition to updated methods.
|
||||
|
||||
- The `track_buffer`, `track_thresh`, and `match_thresh` parameters in [`ByterTrack`](trackers.md/#supervision.tracker.byte_tracker.core.ByteTrack) are deprecated and will be removed in `supervision-0.23.0`. Use `lost_track_buffer,` `track_activation_threshold`, and `minimum_matching_threshold` instead.
|
||||
- The `triggering_position ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) will be removed in `supervision-0.23.0`. Use `triggering_anchors ` instead.
|
||||
- The `frame_resolution_wh ` parameter in [`sv.PolygonZone`](detection/tools/polygon_zone.md/#supervision.detection.tools.polygon_zone.PolygonZone) will be removed in `supervision-0.24.0`.
|
||||
- Constructing `DetectionDataset` and `ClassificationDataset` with parameter `images` as `Dict[str, np.ndarray]` will be removed in `supervision-0.26.0`. Please pass a list of paths `List[str]` instead.
|
||||
- The `DetectionDataset.images` property will be removed in `supervision-0.26.0`. Please loop over images with `for path, image, annotation in dataset:`, as that does not require loading all images into memory.
|
||||
- `BoundingBoxAnnotator` has been renamed to `BoxAnnotator` after the old implementation of `BoxAnnotator` has been removed. `BoundingBoxAnnotator` will be removed in `supervision-0.26.0`.
|
||||
|
||||
# Removed
|
||||
|
||||
- [`Detections.from_froboflow`](detection/core.md/#supervision.detection.core.Detections.from_roboflow) is removed as of `supervision-0.22.0`. Use [`Detections.from_inference`](detection/core.md/#supervision.detection.core.Detections.from_inference) instead.
|
||||
- The method `Color.white()` was removed as of `supervision-0.22.0`. Use the constant `Color.WHITE` instead.
|
||||
- The method `Color.black()` was removed as of `supervision-0.22.0`. Use the constant `Color.BLACK` instead.
|
||||
- The method `Color.red()` was removed as of `supervision-0.22.0`. Use the constant `Color.RED` instead.
|
||||
- The method `Color.green()` was removed as of `supervision-0.22.0`. Use the constant `Color.GREEN` instead.
|
||||
- The method `Color.blue()` was removed as of `supervision-0.22.0`. Use the constant `Color.BLUE` instead.
|
||||
- The method [`ColorPalette.default()`](draw/color.md/#supervision.draw.color.ColorPalette.default) was removed as of `supervision-0.22.0`. Use the constant [`ColorPalette.DEFAULT`](draw/color.md/#supervision.draw.color.ColorPalette.DEFAULT) instead.
|
||||
- `BoxAnnotator` was removed as of `supervision-0.22.0`, however `BoundingBoxAnnotator` was immediately renamed to `BoxAnnotator`. Use [`BoxAnnotator`](detection/annotators.md/#supervision.annotators.core.BoxAnnotator) and [`LabelAnnotator`](detection/annotators.md/#supervision.annotators.core.LabelAnnotator) instead of the old `BoxAnnotator`.
|
||||
- The method [`FPSMonitor.__call__`](utils/video.md/#supervision.utils.video.FPSMonitor.__call__) was removed as of `supervision-0.22.0`. Use the attribute [`FPSMonitor.fps`](utils/video.md/#supervision.utils.video.FPSMonitor.fps) instead.
|
||||
|
||||
@@ -5,7 +5,7 @@ status: new
|
||||
|
||||
# Annotators
|
||||
|
||||
=== "BoundingBox"
|
||||
=== "Box"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
@@ -13,8 +13,8 @@ status: new
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
annotated_frame = bounding_box_annotator.annotate(
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
annotated_frame = box_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
@@ -260,15 +260,22 @@ status: new
|
||||
=== "Label"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER)
|
||||
annotated_frame = label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
|
||||
@@ -278,6 +285,52 @@ status: new
|
||||
|
||||
</div>
|
||||
|
||||
=== "RichLabel"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
rich_label_annotator = sv.RichLabelAnnotator(
|
||||
font_path="<TTF_FONT_PATH>",
|
||||
text_position=sv.Position.CENTER
|
||||
)
|
||||
annotated_frame = rich_label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections,
|
||||
labels=labels
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
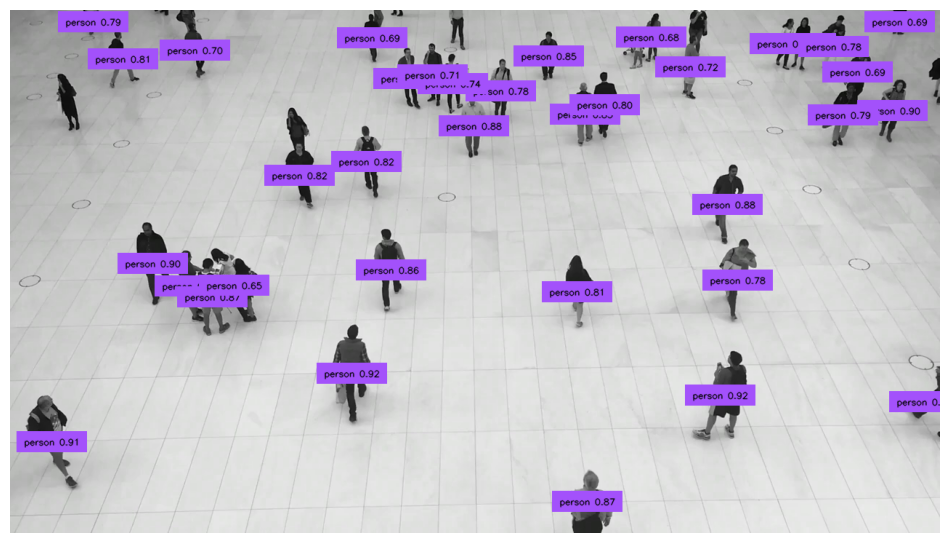{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "Crop"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
crop_annotator = sv.CropAnnotator()
|
||||
annotated_frame = crop_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
=== "Blur"
|
||||
|
||||
```python
|
||||
@@ -380,11 +433,32 @@ status: new
|
||||
|
||||
</div>
|
||||
|
||||
=== "Background Color"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
detections = sv.Detections(...)
|
||||
|
||||
background_overlay_annotator = sv.BackgroundOverlayAnnotator()
|
||||
annotated_frame = background_overlay_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
detections=detections
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
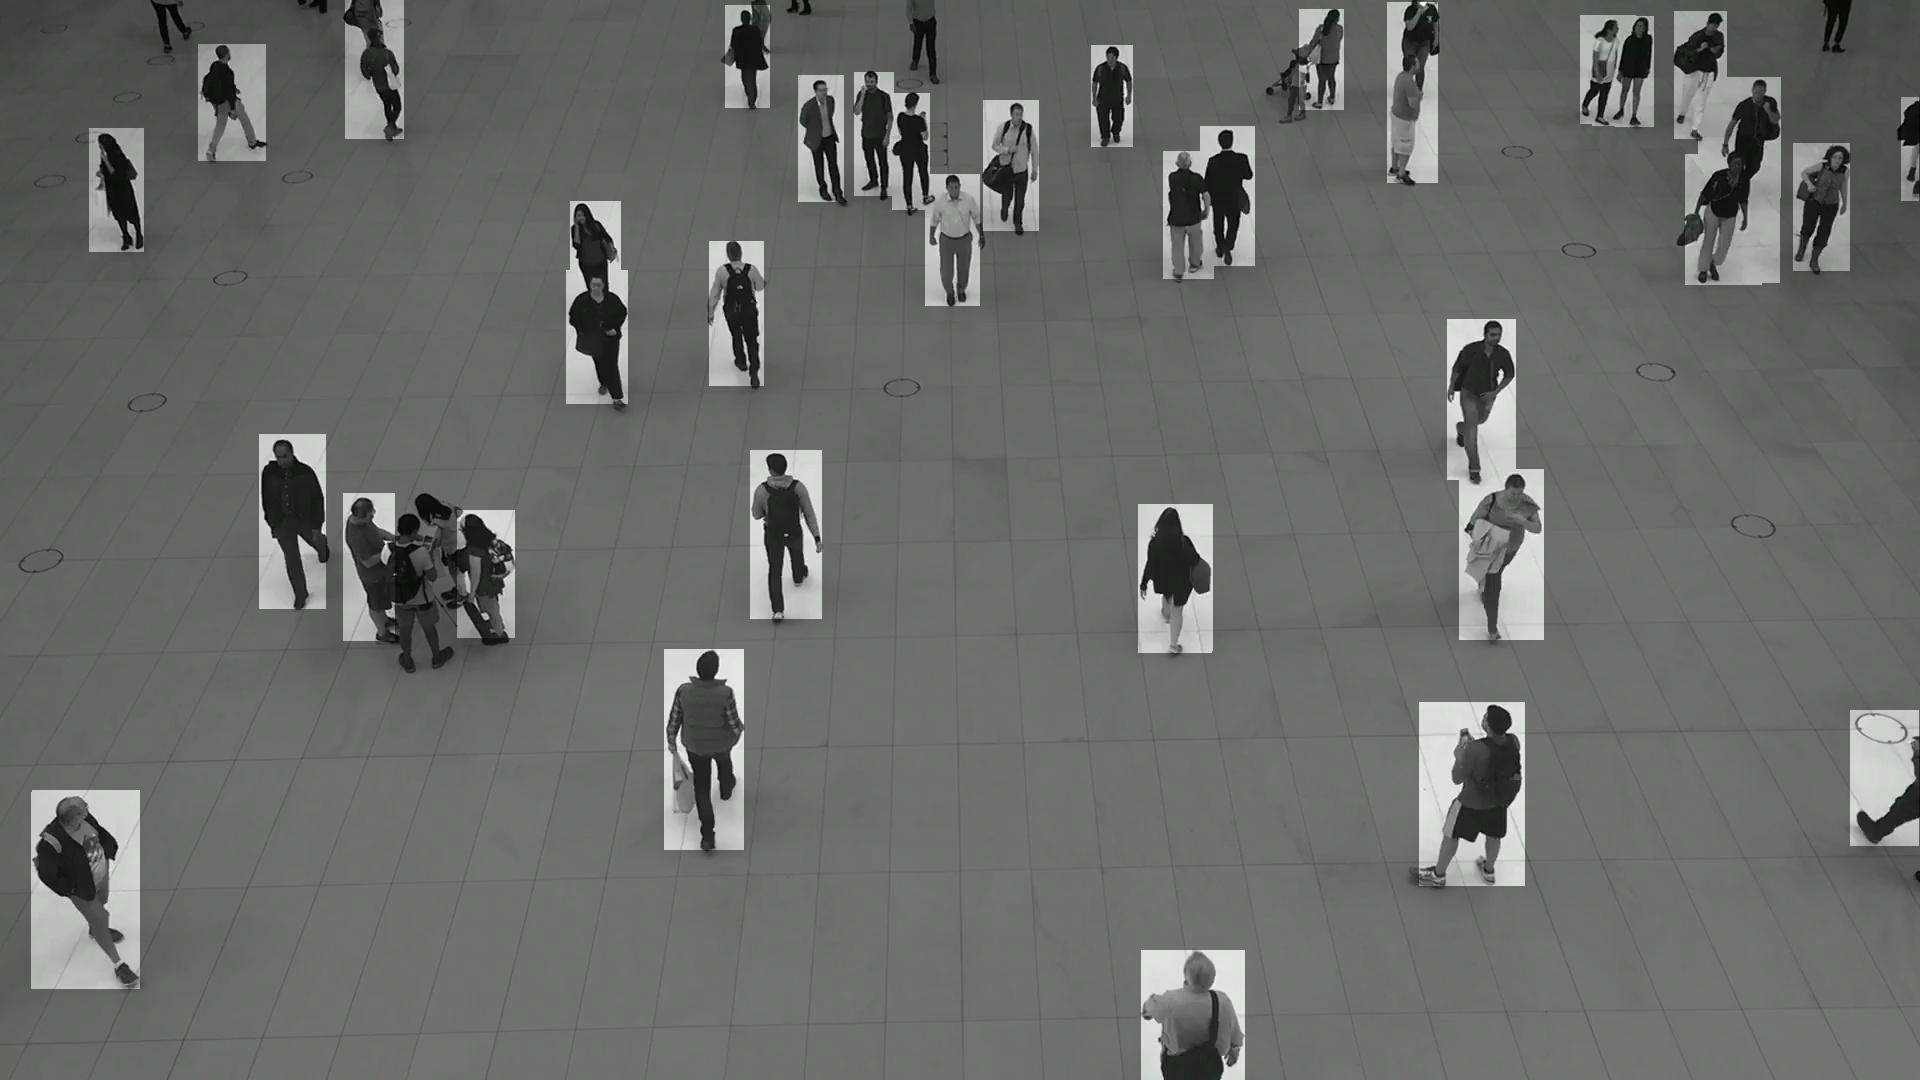
|
||||
|
||||
</div>
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BoundingBoxAnnotator">BoundingBoxAnnotator</a></h2>
|
||||
<h2><a href="#supervision.annotators.core.BoxAnnotator">BoxAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.BoundingBoxAnnotator
|
||||
:::supervision.annotators.core.BoxAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.RoundBoxAnnotator">RoundBoxAnnotator</a></h2>
|
||||
@@ -470,6 +544,18 @@ status: new
|
||||
|
||||
:::supervision.annotators.core.LabelAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.RichLabelAnnotator">RichLabelAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.RichLabelAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.IconAnnotator">IconAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.IconAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BlurAnnotator">BlurAnnotator</a></h2>
|
||||
</div>
|
||||
@@ -489,10 +575,16 @@ status: new
|
||||
:::supervision.annotators.core.TraceAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.IconAnnotator">IconAnnotator</a></h2>
|
||||
<h2><a href="#supervision.annotators.core.CropAnnotator">CropAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.IconAnnotator
|
||||
:::supervision.annotators.core.CropAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.BackgroundOverlayAnnotator">BackgroundOverlayAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.annotators.core.BackgroundOverlayAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.ColorLookup">ColorLookup</a></h2>
|
||||
@@ -0,0 +1,29 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Double Detection Filter
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.OverlapFilter">OverlapFilter</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.OverlapFilter
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.box_non_max_suppression">box_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.mask_non_max_suppression">mask_non_max_suppression</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.overlap_filter.box_non_max_merge">box_non_max_merge</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.overlap_filter.box_non_max_merge
|
||||
@@ -0,0 +1,17 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Metrics
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
@@ -1,6 +1,5 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
@@ -10,3 +9,9 @@ status: new
|
||||
</div>
|
||||
|
||||
:::supervision.detection.tools.csv_sink.CSVSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>JSON Sink</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.tools.json_sink.JSONSink
|
||||
|
||||
+52
-21
@@ -1,71 +1,102 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Detection Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_iou_batch</h2>
|
||||
<h2><a href="#supervision.detection.utils.box_iou_batch">box_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_iou_batch</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_iou_batch">mask_iou_batch</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_iou_batch
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>box_non_max_suppression</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.box_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_non_max_suppression</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_non_max_suppression
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_mask</h2>
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_mask">polygon_to_mask</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_mask
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_xyxy</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_to_xyxy">mask_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>mask_to_polygons</h2>
|
||||
<h2><a href="#supervision.detection.utils.mask_to_polygons">mask_to_polygons</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.mask_to_polygons
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>polygon_to_xyxy</h2>
|
||||
<h2><a href="#supervision.detection.utils.polygon_to_xyxy">polygon_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.polygon_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>filter_polygons_by_area</h2>
|
||||
<h2><a href="#supervision.detection.utils.filter_polygons_by_area">filter_polygons_by_area</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.filter_polygons_by_area
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>move_boxes</h2>
|
||||
<h2><a href="#supervision.detection.utils.move_boxes">move_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>scale_boxes</h2>
|
||||
<h2><a href="#supervision.detection.utils.move_masks">move_masks</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.move_masks
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.scale_boxes">scale_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.scale_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.clip_boxes">clip_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.clip_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.pad_boxes">pad_boxes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.pad_boxes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.contains_holes">contains_holes</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.xywh_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.xywh_to_xyxy">xywh_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.xcycwh_to_xyxy
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.xcycwh_to_xyxy">xcycwh_to_xyxy</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.contains_holes
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.detection.utils.contains_multiple_segments">contains_multiple_segments</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.detection.utils.contains_multiple_segments
|
||||
|
||||
@@ -1,13 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Color
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>ColorPalette</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
@@ -1,53 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_line</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_filled_rectangle</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_polygon</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_text</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>draw_image</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_dynamic_font_scale</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>calculate_dynamic_line_thickness</h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_dynamic_line_thickness
|
||||
@@ -1,7 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Position
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
@@ -4,17 +4,31 @@ comments: true
|
||||
|
||||
# Detect and Annotate
|
||||
|
||||
Supervision offers a streamlined solution to effortlessly annotate predictions from a
|
||||
range of object detection and segmentation models. This guide demonstrates how to
|
||||
execute inference using the YOLOv8 model with either the
|
||||
[Inference](https://github.com/roboflow/inference) or
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision for image annotation
|
||||
purposes.
|
||||
Supervision provides a seamless process for annotating predictions generated by various
|
||||
object detection and segmentation models. This guide shows how to perform inference
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages. Following this,
|
||||
you'll learn how to import these predictions into Supervision and use them to annotate
|
||||
source image.
|
||||
|
||||
## Run Inference
|
||||
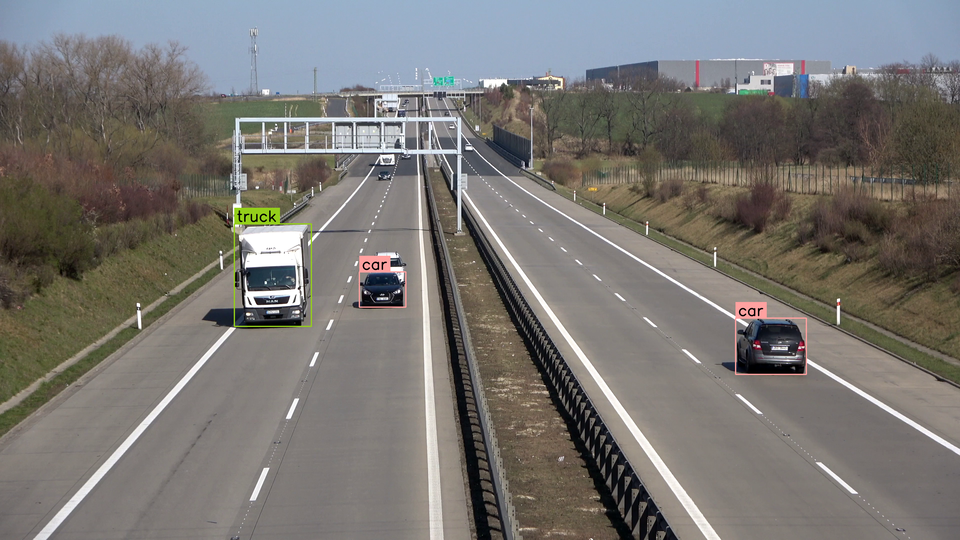
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation model.
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
@@ -23,123 +37,374 @@ First, you'll need to obtain predictions from your object detection or segmentat
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
from inference.models.utils import get_roboflow_model
|
||||
import torch
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>)
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model.infer(image)[0]
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
```
|
||||
|
||||
## Load Predictions into Supervision
|
||||
|
||||
Now that we have predictions from a model, we can load them into Supervision.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
We can do so using the [`sv.Detections.from_ultralytics`](detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Inference"
|
||||
|
||||
We can do so using the [`sv.Detections.from_inference`](detection/core/#supervision.detection.core.Detections.from_inference) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```python
|
||||
```{ .py hl_lines="2 8" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
You can conveniently load predictions from other computer vision frameworks and libraries using:
|
||||
|
||||
- [`from_deepsparse`](detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_inference`](detection/core/#supervision.detection.core.Detections.from_inference) ([Roboflow Inference](https://github.com/roboflow/inference))
|
||||
- [`from_sam`](detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_transformers`](detection/core/#supervision.detection.core.Detections.from_transformers) ([HuggingFace Transformers](https://github.com/huggingface/transformers))
|
||||
- [`from_yolo_nas`](detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
## Annotate Image
|
||||
|
||||
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoundingBoxAnnotator`](annotators/#supervision.annotators.core.BoundingBoxAnnotator) and [`sv.LabelAnnotator`](annotators/#supervision.annotators.core.LabelAnnotator) classes. If you are running the segmentation model [`sv.MaskAnnotator`](annotators/#supervision.annotators.core.MaskAnnotator) is a drop-in replacement for [`sv.BoundingBoxAnnotator`](annotators/#supervision.annotators.core.BoundingBoxAnnotator) that will allow you to draw masks instead of boxes.
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
We can do so using the [`sv.Detections.from_ultralytics`](detection/core/#supervision.detection.core.Detections.from_ultralytics) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```{ .py hl_lines="2 8" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.model.names[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
We can do so using the [`sv.Detections.from_transformers`](detection/core/#supervision.detection.core.Detections.from_transformers) method, which accepts model results from both detection and segmentation models.
|
||||
|
||||
```{ .py hl_lines="2 19-21" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
```
|
||||
|
||||
You can load predictions from other computer vision frameworks and libraries using:
|
||||
|
||||
- [`from_deepsparse`](/latest/detection/core/#supervision.detection.core.Detections.from_deepsparse) ([Deepsparse](https://github.com/neuralmagic/deepsparse))
|
||||
- [`from_detectron2`](/latest/detection/core/#supervision.detection.core.Detections.from_detectron2) ([Detectron2](https://github.com/facebookresearch/detectron2))
|
||||
- [`from_mmdetection`](/latest/detection/core/#supervision.detection.core.Detections.from_mmdetection) ([MMDetection](https://github.com/open-mmlab/mmdetection))
|
||||
- [`from_sam`](/latest/detection/core/#supervision.detection.core.Detections.from_sam) ([Segment Anything Model](https://github.com/facebookresearch/segment-anything))
|
||||
- [`from_yolo_nas`](/latest/detection/core/#supervision.detection.core.Detections.from_yolo_nas) ([YOLO-NAS](https://github.com/Deci-AI/super-gradients/blob/master/YOLONAS.md))
|
||||
|
||||
## Annotate Image with Detections
|
||||
|
||||
Finally, we can annotate the image with the predictions. Since we are working with an object detection model, we will use the [`sv.BoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoxAnnotator) and [`sv.LabelAnnotator`](/latest/annotators/#supervision.annotators.core.LabelAnnotator) classes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
```{ .py hl_lines="10-16" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference.models.utils import get_roboflow_model
|
||||
from inference import get_model
|
||||
|
||||
model = get_roboflow_model(model_id="yolov8n-640", api_key=<ROBOFLOW API KEY>
|
||||
image = cv2.imread(<PATH TO IMAGE>)
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
bounding_box_annotator = sv.BoundingBoxAnnotator()
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = bounding_box_annotator.annotate(
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
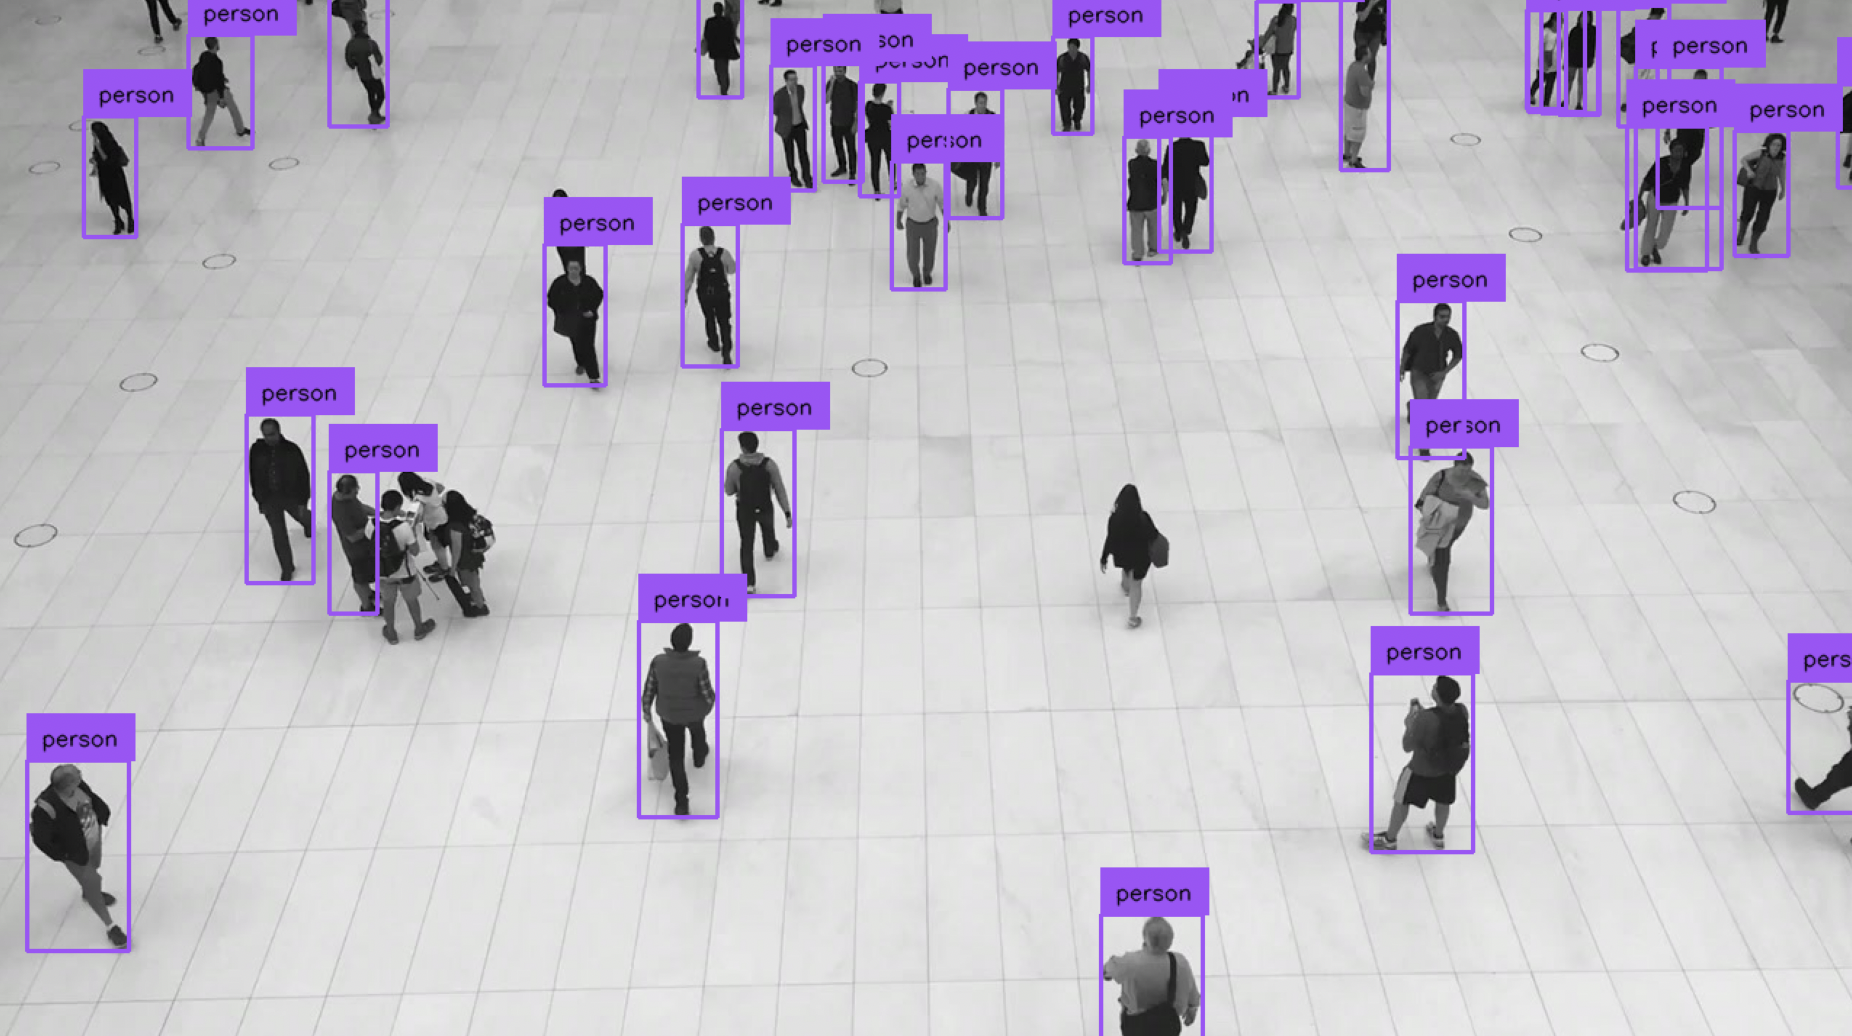
|
||||
=== "Ultralytics"
|
||||
|
||||
## Display Annotated Image
|
||||
```{ .py hl_lines="10-16" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
To display the annotated image in Jupyter Notebook or Google Colab, use the [`sv.plot_image`](utils/notebook/#supervision.utils.notebook.plot_image) function.
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
```python
|
||||
sv.plot_image(annotated_image)
|
||||
```
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="23-30" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||

|
||||
|
||||
## Display Custom Labels
|
||||
|
||||
By default, [`sv.LabelAnnotator`](/latest/annotators/#supervision.annotators.core.LabelAnnotator)
|
||||
will label each detection with its `class_name` (if possible) or `class_id`. You can
|
||||
override this behavior by passing a list of custom `labels` to the `annotate` method.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="13-17 22" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="13-17 22" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="26-30 35" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
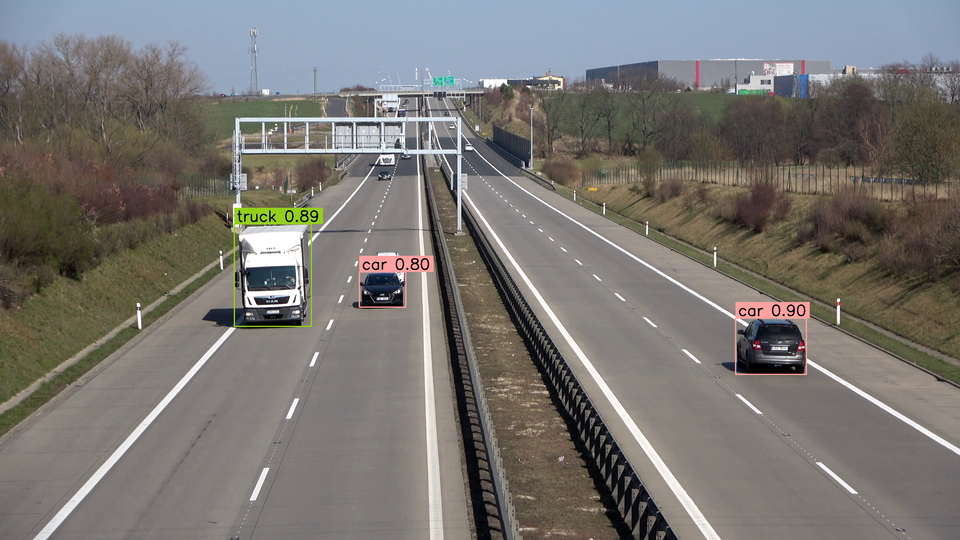
|
||||
|
||||
## Annotate Image with Segmentations
|
||||
|
||||
If you are running the segmentation model
|
||||
[`sv.MaskAnnotator`](/latest/annotators/#supervision.annotators.core.MaskAnnotator)
|
||||
is a drop-in replacement for
|
||||
[`sv.BoxAnnotator`](/latest/annotators/#supervision.annotators.core.BoxAnnotator)
|
||||
that will allow you to draw masks instead of boxes.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-seg-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n-seg.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForSegmentation
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50-panoptic")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_segmentation(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(
|
||||
transformers_results=results,
|
||||
id2label=model.config.id2label)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)
|
||||
|
||||
labels = [
|
||||
f"{class_name} {confidence:.2f}"
|
||||
for class_name, confidence
|
||||
in zip(detections['class_name'], detections.confidence)
|
||||
]
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
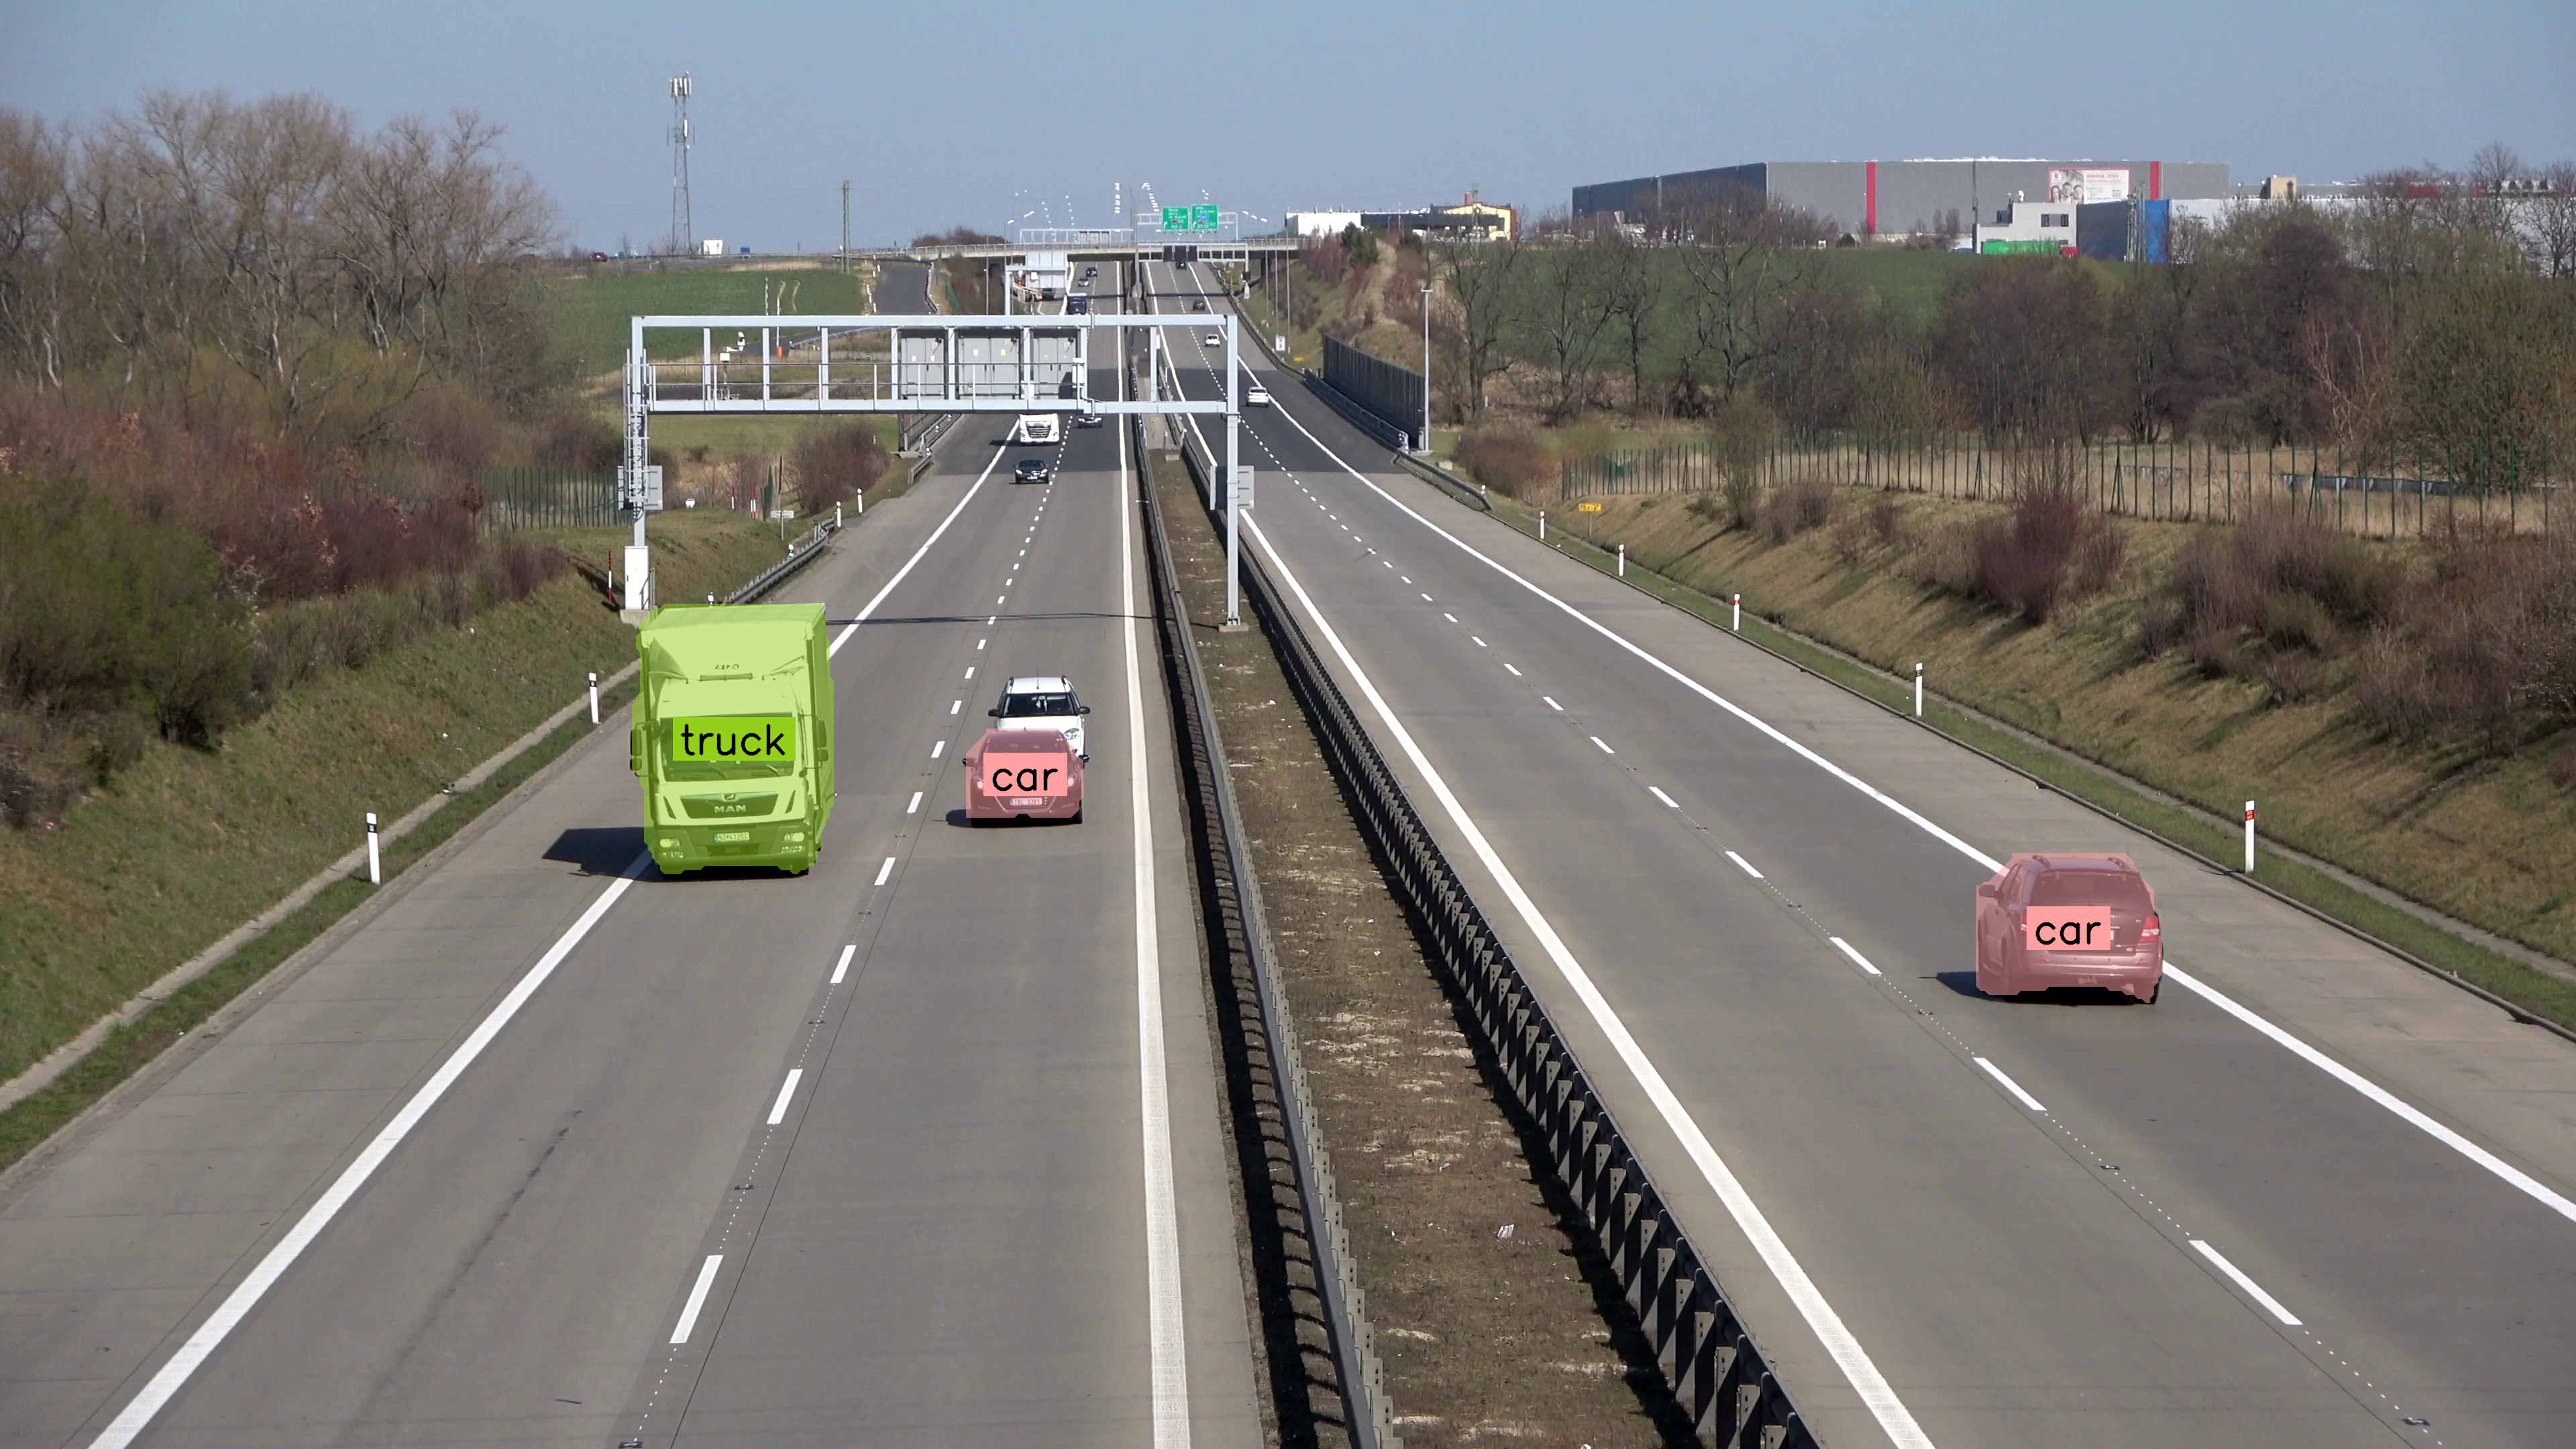
|
||||
|
||||
@@ -0,0 +1,325 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Detect Small Objects
|
||||
|
||||
This guide shows how to detect small objects
|
||||
with the [Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages using
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer).
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Baseline Detection
|
||||
|
||||
Small object detection in high-resolution images presents challenges due to the objects'
|
||||
size relative to the image resolution.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForSegmentation
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForSegmentation.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = Image.open(<SOURCE_IMAGE_PATH>)
|
||||
inputs = processor(images=image, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image_slice.size
|
||||
target_size = torch.tensor([[width, height]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.config.id2label[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Input Resolution
|
||||
|
||||
Modifying the input resolution of images before detection can enhance small object
|
||||
identification at the cost of processing speed and increased memory usage. This method
|
||||
is less effective for ultra-high-resolution images (4K and above).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="5" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-1280")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import cv2
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
results = model(image, imgsz=1280)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Inference Slicer
|
||||
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer)
|
||||
processes high-resolution images by dividing them into smaller segments, detecting
|
||||
objects within each, and aggregating the results.
|
||||
|
||||
<video controls>
|
||||
<source src="https://media.roboflow.com/supervision_detect_small_objects_example_2.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="9-14" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
return sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="9-14" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
result = model(image_slice)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="13-28" }
|
||||
import cv2
|
||||
import torch
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from PIL import Image
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
image_slice = cv2.cvtColor(image_slice, cv2.COLOR_BGR2RGB)
|
||||
image_slice = Image.fromarray(image_slice)
|
||||
inputs = processor(images=image_slice, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = image_slice.size
|
||||
target_size = torch.tensor([[width, height]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
return sv.Detections.from_transformers(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
labels = [
|
||||
model.config.id2label[class_id]
|
||||
for class_id
|
||||
in detections.class_id
|
||||
]
|
||||
|
||||
annotated_image = box_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections, labels=labels)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Small Object Segmentation
|
||||
|
||||
[`InferenceSlicer`](/latest/detection/tools/inference_slicer/#supervision.detection.tools.inference_slicer.InferenceSlicer) can perform segmentation tasks too.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="6 16 19-20" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8x-seg-640")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
results = model.infer(image_slice)[0]
|
||||
return sv.Detections.from_inference(results)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="6 16 19-20" }
|
||||
import cv2
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8x-seg.pt")
|
||||
image = cv2.imread(<SOURCE_IMAGE_PATH>)
|
||||
|
||||
def callback(image_slice: np.ndarray) -> sv.Detections:
|
||||
result = model(image_slice)[0]
|
||||
return sv.Detections.from_ultralytics(result)
|
||||
|
||||
slicer = sv.InferenceSlicer(callback = callback)
|
||||
detections = slicer(image)
|
||||
|
||||
mask_annotator = sv.MaskAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_image = mask_annotator.annotate(
|
||||
scene=image, detections=detections)
|
||||
annotated_image = label_annotator.annotate(
|
||||
scene=annotated_image, detections=detections)
|
||||
```
|
||||
|
||||
|
||||
@@ -0,0 +1,455 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
With Supervision, you can load and manipulate classification, object detection, and
|
||||
segmentation datasets. This tutorial will walk you through how to load, split, merge,
|
||||
visualize, and augment datasets in Supervision.
|
||||
|
||||
## Download Dataset
|
||||
|
||||
In this tutorial, we will use a dataset from
|
||||
[Roboflow Universe](https://universe.roboflow.com/), a public repository of
|
||||
thousands of computer vision datasets. If you already have your dataset in
|
||||
[COCO](https://roboflow.com/formats/coco-json),
|
||||
[YOLO](https://roboflow.com/formats/yolov8-pytorch-txt),
|
||||
or [Pascal VOC](https://roboflow.com/formats/pascal-voc-xml) format, you can skip this
|
||||
section.
|
||||
|
||||
```bash
|
||||
pip install roboflow
|
||||
```
|
||||
|
||||
Next, log into your Roboflow account and download the dataset of your choice in the
|
||||
COCO, YOLO, or Pascal VOC format. You can customize the following code snippet with
|
||||
your workspace ID, project ID, and version number.
|
||||
|
||||
=== "COCO"
|
||||
|
||||
```python
|
||||
import roboflow
|
||||
|
||||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace('<WORKSPACE_ID>').project('<PROJECT_ID>')
|
||||
dataset = project.version('<PROJECT_VERSION>').download("coco")
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
||||
```python
|
||||
import roboflow
|
||||
|
||||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace('<WORKSPACE_ID>').project('<PROJECT_ID>')
|
||||
dataset = project.version('<PROJECT_VERSION>').download("yolov8")
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
```python
|
||||
import roboflow
|
||||
|
||||
roboflow.login()
|
||||
|
||||
rf = roboflow.Roboflow()
|
||||
project = rf.workspace('<WORKSPACE_ID>').project('<PROJECT_ID>')
|
||||
dataset = project.version('<PROJECT_VERSION>').download("voc")
|
||||
```
|
||||
|
||||
## Load Dataset
|
||||
|
||||
The Supervision library provides convenient functions to load datasets in various
|
||||
formats. If your dataset is already split into train, test, and valid subsets, you can
|
||||
load each of those as separate [`sv.DetectionDataset`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset)
|
||||
instances.
|
||||
|
||||
=== "COCO"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.from_coco`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.from_coco) to load annotations in [COCO](https://roboflow.com/formats/coco-json) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/train',
|
||||
annotations_path=f'{dataset.location}/train/_annotations.coco.json',
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/valid',
|
||||
annotations_path=f'{dataset.location}/valid/_annotations.coco.json',
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/test',
|
||||
annotations_path=f'{dataset.location}/test/_annotations.coco.json',
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.from_yolo`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.from_yolo) to load annotations in [YOLO](https://roboflow.com/formats/yolov8-pytorch-txt) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.from_pascal_voc`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.from_pascal_voc) to load annotations in [Pascal VOC](https://roboflow.com/formats/pascal-voc-xml) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
## Split Dataset
|
||||
|
||||
If your dataset is not already split into train, test, and valid subsets, you can
|
||||
easily do so using the [`sv.DetectionDataset.split`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.split)
|
||||
method. We can split it as follows, ensuring a random shuffle of the data.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
len(ds)
|
||||
# 1000
|
||||
|
||||
ds_train, ds = ds.split(split_ratio=0.8, shuffle=True)
|
||||
ds_valid, ds_test = ds.split(split_ratio=0.5, shuffle=True)
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
```
|
||||
|
||||
## Merge Dataset
|
||||
|
||||
If you have multiple datasets that you would like to merge, you can do so using the
|
||||
[`sv.DetectionDataset.merge`](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.merge)
|
||||
method.
|
||||
|
||||
=== "COCO"
|
||||
|
||||
```{ .py hl_lines="22-28" }
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/train',
|
||||
annotations_path=f'{dataset.location}/train/_annotations.coco.json',
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/valid',
|
||||
annotations_path=f'{dataset.location}/valid/_annotations.coco.json',
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_coco(
|
||||
images_directory_path=f'{dataset.location}/test',
|
||||
annotations_path=f'{dataset.location}/test/_annotations.coco.json',
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
|
||||
ds = sv.DetectionDataset.merge([ds_train, ds_valid, ds_test])
|
||||
|
||||
ds.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds)
|
||||
# 1000
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
||||
```{ .py hl_lines="25-31" }
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_yolo(
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels',
|
||||
data_yaml_path=f'{dataset.location}/data.yaml'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
|
||||
ds = sv.DetectionDataset.merge([ds_train, ds_valid, ds_test])
|
||||
|
||||
ds.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds)
|
||||
# 1000
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
```{ .py hl_lines="22-28" }
|
||||
import supervision as sv
|
||||
|
||||
ds_train = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/train/images',
|
||||
annotations_directory_path=f'{dataset.location}/train/labels'
|
||||
)
|
||||
ds_valid = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/valid/images',
|
||||
annotations_directory_path=f'{dataset.location}/valid/labels'
|
||||
)
|
||||
ds_test = sv.DetectionDataset.from_pascal_voc(
|
||||
images_directory_path=f'{dataset.location}/test/images',
|
||||
annotations_directory_path=f'{dataset.location}/test/labels'
|
||||
)
|
||||
|
||||
ds_train.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds_train), len(ds_valid), len(ds_test)
|
||||
# 800, 100, 100
|
||||
|
||||
ds = sv.DetectionDataset.merge([ds_train, ds_valid, ds_test])
|
||||
|
||||
ds.classes
|
||||
# ['person', 'bicycle', 'car', ...]
|
||||
|
||||
len(ds)
|
||||
# 1000
|
||||
```
|
||||
|
||||
## Iterate over Dataset
|
||||
|
||||
There are two ways to loop over a `sv.DetectionDataset`: using a direct
|
||||
[for loop](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__iter__)
|
||||
called on the `sv.DetectionDataset` instance or loading `sv.DetectionDataset` entries
|
||||
[by index](https://supervision.roboflow.com/latest/datasets/core/#supervision.dataset.core.DetectionDataset.__getitem__).
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
# Option 1
|
||||
for image_path, image, annotations in ds:
|
||||
... # Process each image and its annotations
|
||||
|
||||
# Option 2
|
||||
for idx in range(len(ds)):
|
||||
image_path, image, annotations = ds[idx]
|
||||
... # Process the image and annotations at index `idx`
|
||||
```
|
||||
|
||||
## Visualize Dataset
|
||||
|
||||
The Supervision library provides tools for easily visualizing your detection dataset.
|
||||
You can create a grid of annotated images to quickly inspect your data and labels.
|
||||
First, initialize the [`sv.BoxAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.BoxAnnotator)
|
||||
and [`sv.LabelAnnotator`](https://supervision.roboflow.com/latest/detection/annotators/#supervision.annotators.core.LabelAnnotator).
|
||||
Then, iterate through a subset of the dataset (e.g., the first 25 images), drawing
|
||||
bounding boxes and class labels on each image. Finally, combine the annotated images
|
||||
into a grid for display.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
box_annotator = sv.BoxAnnotator()
|
||||
label_annotator = sv.LabelAnnotator()
|
||||
|
||||
annotated_images = []
|
||||
for i in range(16):
|
||||
_, image, annotations = ds[i]
|
||||
|
||||
labels = [ds.classes[class_id] for class_id in annotations.class_id]
|
||||
|
||||
annotated_image = image.copy()
|
||||
annotated_image = box_annotator.annotate(annotated_image, annotations)
|
||||
annotated_image = label_annotator.annotate(annotated_image, annotations, labels)
|
||||
annotated_images.append(annotated_image)
|
||||
|
||||
grid = sv.create_tiles(
|
||||
annotated_images,
|
||||
grid_size=(4, 4),
|
||||
single_tile_size=(400, 400),
|
||||
tile_padding_color=sv.Color.WHITE,
|
||||
tile_margin_color=sv.Color.WHITE
|
||||
)
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Save Dataset
|
||||
|
||||
=== "COCO"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.as_coco`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_coco) method to save annotations in [COCO](https://roboflow.com/formats/coco-json) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
ds.as_coco(
|
||||
images_directory_path='<IMAGE_DIRECTORY_PATH>',
|
||||
annotations_path='<ANNOTATIONS_PATH>'
|
||||
)
|
||||
```
|
||||
|
||||
=== "YOLO"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.as_yolo`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_yolo) method to save annotations in [YOLO](https://roboflow.com/formats/yolov8-pytorch-txt) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
ds.as_yolo(
|
||||
images_directory_path='<IMAGE_DIRECTORY_PATH>',
|
||||
annotations_directory_path='<ANNOTATIONS_DIRECTORY_PATH>',
|
||||
data_yaml_path='<DATA_YAML_PATH>'
|
||||
)
|
||||
```
|
||||
|
||||
=== "Pascal VOC"
|
||||
|
||||
We can do so using the [`sv.DetectionDataset.as_pascal_voc`](https://supervision.roboflow.com/datasets/#supervision.dataset.core.DetectionDataset.as_pascal_voc) method to save annotations in [Pascal VOC](https://roboflow.com/formats/pascal-voc-xml) format.
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
ds.as_pascal_voc(
|
||||
images_directory_path='<IMAGE_DIRECTORY_PATH>',
|
||||
annotations_directory_path='<ANNOTATIONS_DIRECTORY_PATH>'
|
||||
)
|
||||
```
|
||||
|
||||
## Augment Dataset
|
||||
|
||||
In this section, we'll explore using Supervision in combination with Albumentations to
|
||||
augment our dataset. Data augmentation is a common technique in computer vision to
|
||||
increase the size and diversity of training datasets, leading to improved model
|
||||
performance and generalization.
|
||||
|
||||
```bash
|
||||
pip install augmentation
|
||||
```
|
||||
|
||||
Albumentations provides a flexible and powerful API for image augmentation. The core of
|
||||
the library is the [`Compose`](https://albumentations.ai/docs/api_reference/full_reference/?h=compose#albumentations.core.composition.Compose)
|
||||
class, which allows you to chain multiple image transformations together. Each
|
||||
transformation is defined using a dedicated class, such as
|
||||
[`HorizontalFlip`](https://albumentations.ai/docs/api_reference/full_reference/?h=horizontalflip#albumentations.augmentations.geometric.transforms.HorizontalFlip),
|
||||
[`RandomBrightnessContrast`](https://albumentations.ai/docs/api_reference/full_reference/?h=horizontalflip#albumentations.augmentations.transforms.RandomBrightnessContrast),
|
||||
or [`Perspective`](https://albumentations.ai/docs/api_reference/full_reference/?h=horizontalflip#albumentations.augmentations.geometric.transforms.Perspective).
|
||||
|
||||
```python
|
||||
import albumentations as A
|
||||
|
||||
augmentation = A.Compose(
|
||||
transforms=[
|
||||
A.Perspective(p=0.1),
|
||||
A.HorizontalFlip(p=0.5),
|
||||
A.RandomBrightnessContrast(p=0.5)
|
||||
],
|
||||
bbox_params=A.BboxParams(
|
||||
format='pascal_voc',
|
||||
label_fields=['category']
|
||||
),
|
||||
)
|
||||
```
|
||||
|
||||
The key is to set `format='pascal_voc'`, which corresponds to the
|
||||
`[x_min, y_min, x_max, y_max]` bounding box format used in Supervision.
|
||||
|
||||
```python
|
||||
import numpy as np
|
||||
import supervision as sv
|
||||
from dataclasses import replace
|
||||
|
||||
ds = sv.DetectionDataset(...)
|
||||
|
||||
_, original_image, original_annotations = ds[0]
|
||||
|
||||
output = augmentation(
|
||||
image=original_image,
|
||||
bboxes=original_annotations.xyxy,
|
||||
category=original_annotations.class_id
|
||||
)
|
||||
|
||||
augmented_image = output['image']
|
||||
augmented_annotations = replace(
|
||||
original_annotations,
|
||||
xyxy=np.array(output['bboxes']),
|
||||
class_id=np.array(output['category'])
|
||||
)
|
||||
```
|
||||
|
||||
|
||||
@@ -0,0 +1,298 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Save Detections
|
||||
|
||||
Supervision enables an easy way to save detections in .CSV and .JSON files for offline
|
||||
processing. This guide demonstrates how to perform video inference using the
|
||||
[Inference](https://github.com/roboflow/inference),
|
||||
[Ultralytics](https://github.com/ultralytics/ultralytics) or
|
||||
[Transformers](https://github.com/huggingface/transformers) packages and save their results with
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink) and
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
## Run Detection
|
||||
|
||||
First, you'll need to obtain predictions from your object detection or segmentation
|
||||
model. You can learn more on this topic in our
|
||||
[How to Detect and Annotate](/latest/how_to/detect_and_annotate.md) guide.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```python
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
```
|
||||
|
||||
## Save Detections as CSV
|
||||
|
||||
To save detections to a `.CSV` file, open our
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
and then pass the
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections)
|
||||
object resulting from the inference to it. Its fields are parsed and saved on disk.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame in frames_generator:
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car |
|
||||
|
||||
## Custom Fields
|
||||
|
||||
Besides regular fields in
|
||||
[`sv.Detections`](/latest/detection/core/#supervision.detection.core.Detections),
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
also allows you to add custom information to each row, which can be passed via the
|
||||
`custom_data` dictionary. Let's utilize this feature to save information about the
|
||||
frame index from which the detections originate.
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="8 12" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="10 23" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.CSVSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
| x_min | y_min | x_max | y_max | class_id | confidence | tracker_id | class_name | frame_index |
|
||||
|---------|----------|---------|----------|----------|------------|------------|------------|-------------|
|
||||
| 2941.14 | 1269.31 | 3220.77 | 1500.67 | 2 | 0.8517 | | car | 0 |
|
||||
| 944.889 | 899.641 | 1235.42 | 1308.80 | 7 | 0.6752 | | truck | 0 |
|
||||
| 1439.78 | 1077.79 | 1621.27 | 1231.40 | 2 | 0.6450 | | car | 0 |
|
||||
|
||||
## Save Detections as JSON
|
||||
|
||||
If you prefer to save the result in a `.JSON` file instead of a `.CSV` file, all you
|
||||
need to do is replace
|
||||
[`sv.CSVSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.CSVSink)
|
||||
with
|
||||
[`sv.JSONSink`](/latest/detection/tools/save_detections/#supervision.detection.tools.csv_sink.JSONSink).
|
||||
|
||||
=== "Inference"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from inference import get_model
|
||||
|
||||
model = get_model(model_id="yolov8n-640")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model.infer(image)[0]
|
||||
detections = sv.Detections.from_inference(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Ultralytics"
|
||||
|
||||
```{ .py hl_lines="7" }
|
||||
import supervision as sv
|
||||
from ultralytics import YOLO
|
||||
|
||||
model = YOLO("yolov8n.pt")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
results = model(frame)[0]
|
||||
detections = sv.Detections.from_ultralytics(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
|
||||
=== "Transformers"
|
||||
|
||||
```{ .py hl_lines="9" }
|
||||
import torch
|
||||
import supervision as sv
|
||||
from transformers import DetrImageProcessor, DetrForObjectDetection
|
||||
|
||||
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50")
|
||||
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
|
||||
frames_generator = sv.get_video_frames_generator(<SOURCE_VIDEO_PATH>)
|
||||
|
||||
with sv.JSONSink(<TARGET_CSV_PATH>) as sink:
|
||||
for frame_index, frame in enumerate(frames_generator):
|
||||
|
||||
frame = sv.cv2_to_pillow(frame)
|
||||
inputs = processor(images=frame, return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
outputs = model(**inputs)
|
||||
|
||||
width, height = frame.size
|
||||
target_size = torch.tensor([[height, width]])
|
||||
results = processor.post_process_object_detection(
|
||||
outputs=outputs, target_sizes=target_size)[0]
|
||||
detections = sv.Detections.from_transformers(results)
|
||||
sink.append(detections, {"frame_index": frame_index})
|
||||
```
|
||||
+47
-12
@@ -1,19 +1,20 @@
|
||||
---
|
||||
template: index.html
|
||||
comments: true
|
||||
hide:
|
||||
- navigation
|
||||
- toc
|
||||
---
|
||||
|
||||
<div align="center">
|
||||
<p>
|
||||
<a align="center" href="" target="_blank">
|
||||
<img
|
||||
width="850"
|
||||
src="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png?updatedAt=1678995927529"
|
||||
>
|
||||
</a>
|
||||
</p>
|
||||
<div class="md-typeset">
|
||||
<h1></h1>
|
||||
</div>
|
||||
|
||||
<div align="center" id="logo">
|
||||
<a align="center" href="" target="_blank">
|
||||
<img width="850"
|
||||
src="https://media.roboflow.com/open-source/supervision/rf-supervision-banner.png?updatedAt=1678995927529">
|
||||
</a>
|
||||
</div>
|
||||
|
||||
## 👋 Hello
|
||||
@@ -29,7 +30,7 @@ We write your reusable computer vision tools. Whether you need to load your data
|
||||
|
||||
## 💻 Install
|
||||
|
||||
You can install `supervision` with pip in a
|
||||
You can install `supervision` in a
|
||||
[**Python>=3.8**](https://www.python.org/) environment.
|
||||
|
||||
!!! example "pip install (recommended)"
|
||||
@@ -45,7 +46,25 @@ You can install `supervision` with pip in a
|
||||
If you require the full version of `supervision` with GUI support you can install the desktop version. This version includes the GUI components of OpenCV, allowing you to display images and videos on the screen.
|
||||
|
||||
```bash
|
||||
pip install supervision[desktop]
|
||||
pip install "supervision[desktop]"
|
||||
```
|
||||
|
||||
!!! example "conda/mamba install"
|
||||
|
||||
=== "conda"
|
||||
|
||||
[](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision)
|
||||
|
||||
```bash
|
||||
conda install -c conda-forge supervision
|
||||
```
|
||||
|
||||
=== "mamba"
|
||||
|
||||
[](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision) [](https://anaconda.org/conda-forge/supervision)
|
||||
|
||||
```bash
|
||||
mamba install -c conda-forge supervision
|
||||
```
|
||||
|
||||
!!! example "git clone (for development)"
|
||||
@@ -87,7 +106,6 @@ You can install `supervision` with pip in a
|
||||
poetry install --extras "desktop"
|
||||
```
|
||||
|
||||
|
||||
## 🚀 Quickstart
|
||||
|
||||
<div class="grid cards" markdown>
|
||||
@@ -108,6 +126,14 @@ You can install `supervision` with pip in a
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/track_objects.md)
|
||||
|
||||
- __Detect Small Objects__
|
||||
|
||||
---
|
||||
|
||||
Learn how to detect small objects in images
|
||||
|
||||
[:octicons-arrow-right-24: Tutorial](how_to/detect_small_objects.md)
|
||||
|
||||
- > __Count Objects Crossing Line__
|
||||
|
||||
---
|
||||
@@ -120,4 +146,13 @@ You can install `supervision` with pip in a
|
||||
|
||||
Master the techniques to selectively filter and focus on objects within a specific zone
|
||||
|
||||
- **Cheatsheet**
|
||||
|
||||
***
|
||||
|
||||
Access a quick reference guide to the most common `supervision` functions
|
||||
|
||||
[:octicons-arrow-right-24: Cheatsheet](https://roboflow.github.io/cheatsheet-supervision/)
|
||||
|
||||
|
||||
</div>
|
||||
|
||||
@@ -55,7 +55,7 @@ document.addEventListener("DOMContentLoaded", function () {
|
||||
|
||||
let authorAvatarsHTML = authorDataArray.map((authorData, index) => {
|
||||
const marginLeft = index === 0 ? '0' : '-10px';
|
||||
const zIndex = 100 - index;
|
||||
const zIndex = 4 - index;
|
||||
return `
|
||||
<div
|
||||
class="author-container"
|
||||
|
||||
@@ -0,0 +1,96 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Annotators
|
||||
|
||||
=== "VertexAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_annotator = sv.VertexAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
radius=10
|
||||
)
|
||||
annotated_frame = vertex_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
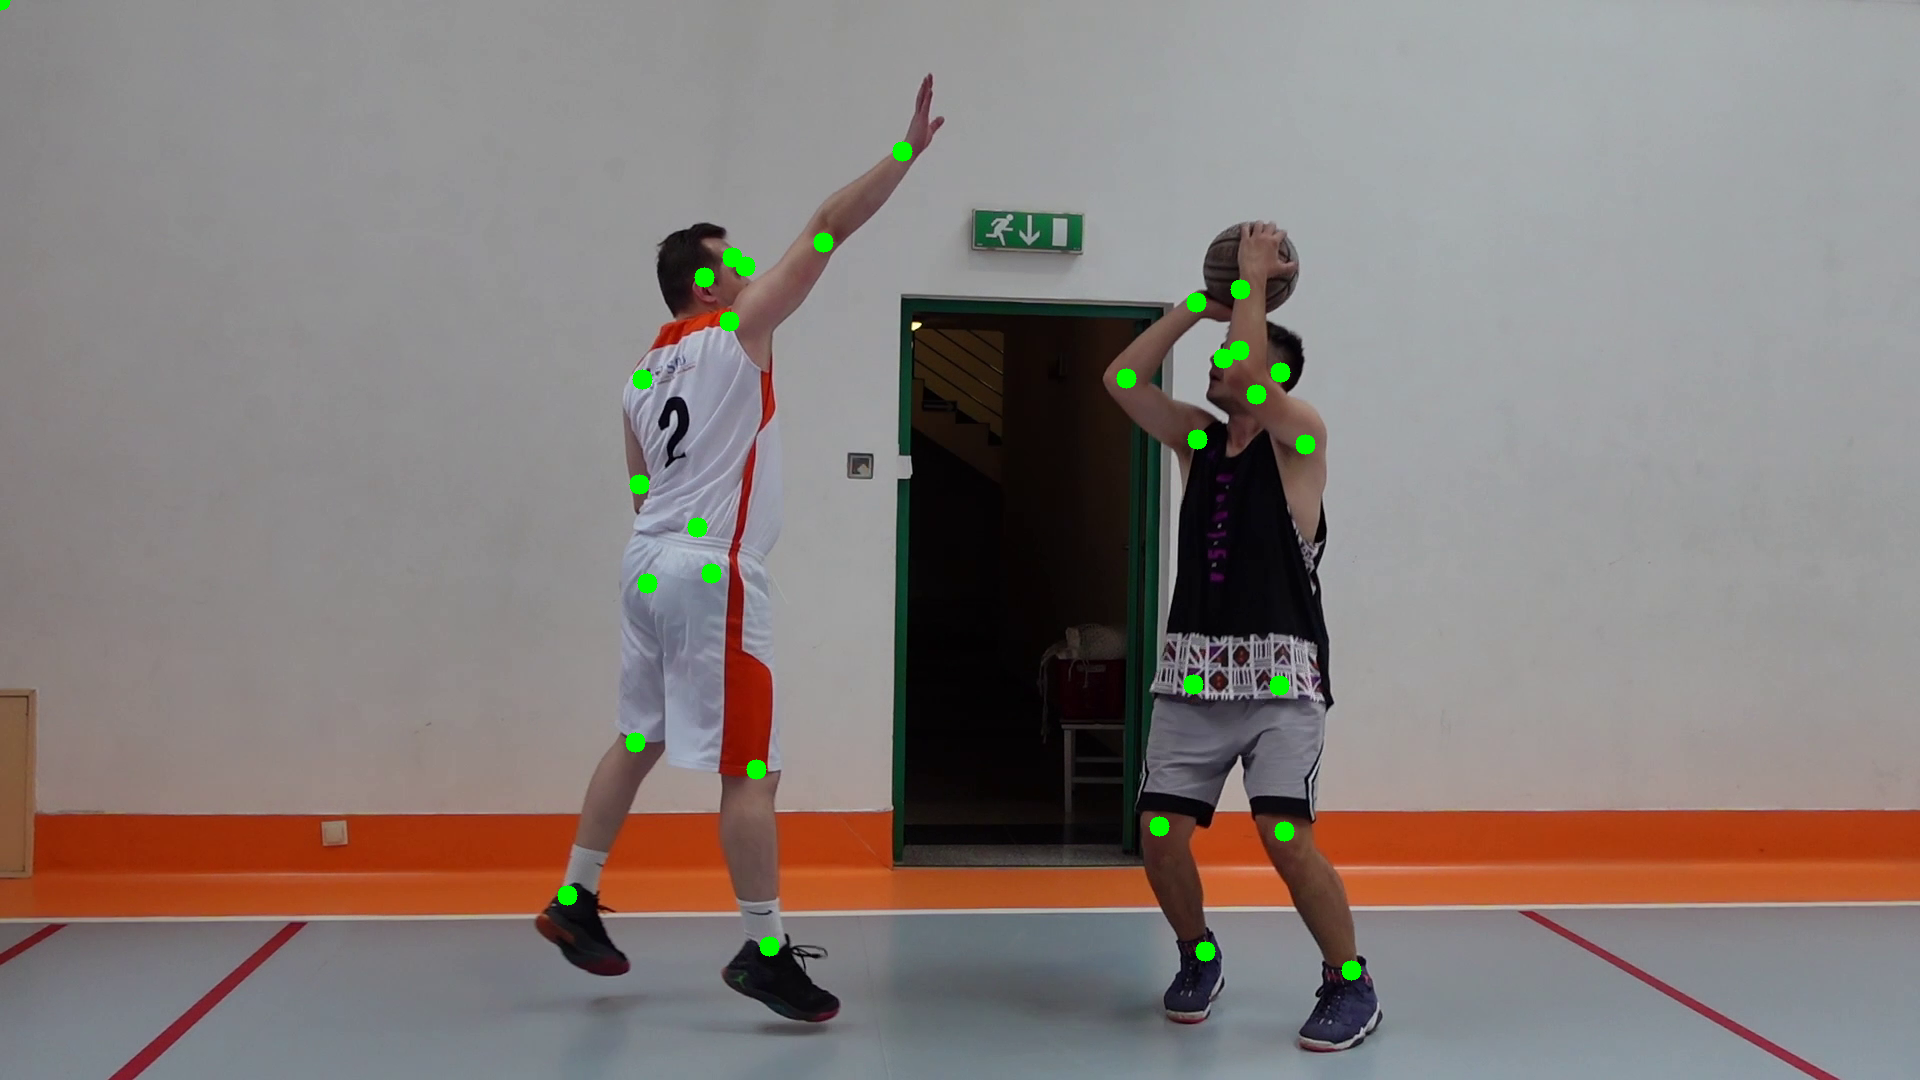{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "EdgeAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
edge_annotator = sv.EdgeAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
thickness=5
|
||||
)
|
||||
annotated_frame = edge_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
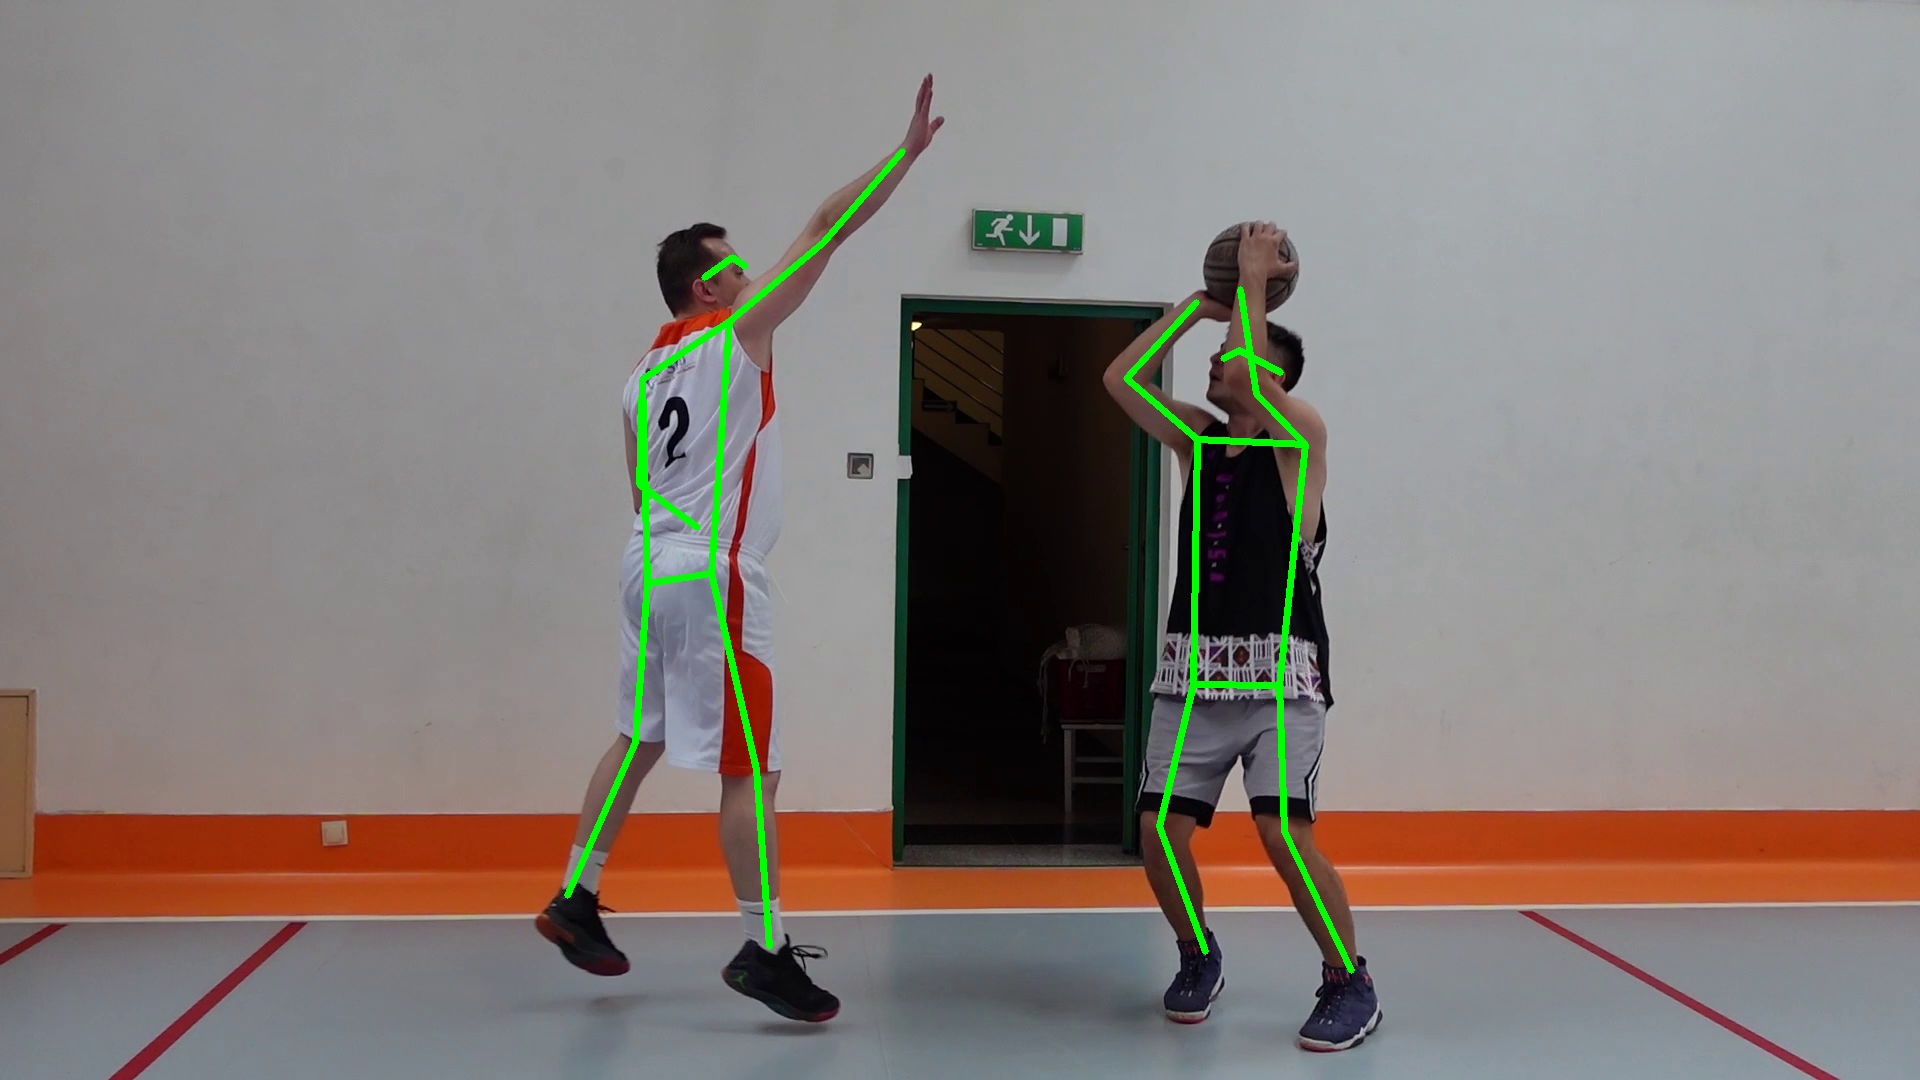{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
=== "VertexLabelAnnotator"
|
||||
|
||||
```python
|
||||
import supervision as sv
|
||||
|
||||
image = ...
|
||||
key_points = sv.KeyPoints(...)
|
||||
|
||||
vertex_label_annotator = sv.VertexLabelAnnotator(
|
||||
color=sv.Color.GREEN,
|
||||
text_color=sv.Color.BLACK,
|
||||
border_radius=5
|
||||
)
|
||||
annotated_frame = vertex_label_annotator.annotate(
|
||||
scene=image.copy(),
|
||||
key_points=key_points
|
||||
)
|
||||
```
|
||||
|
||||
<div class="result" markdown>
|
||||
|
||||
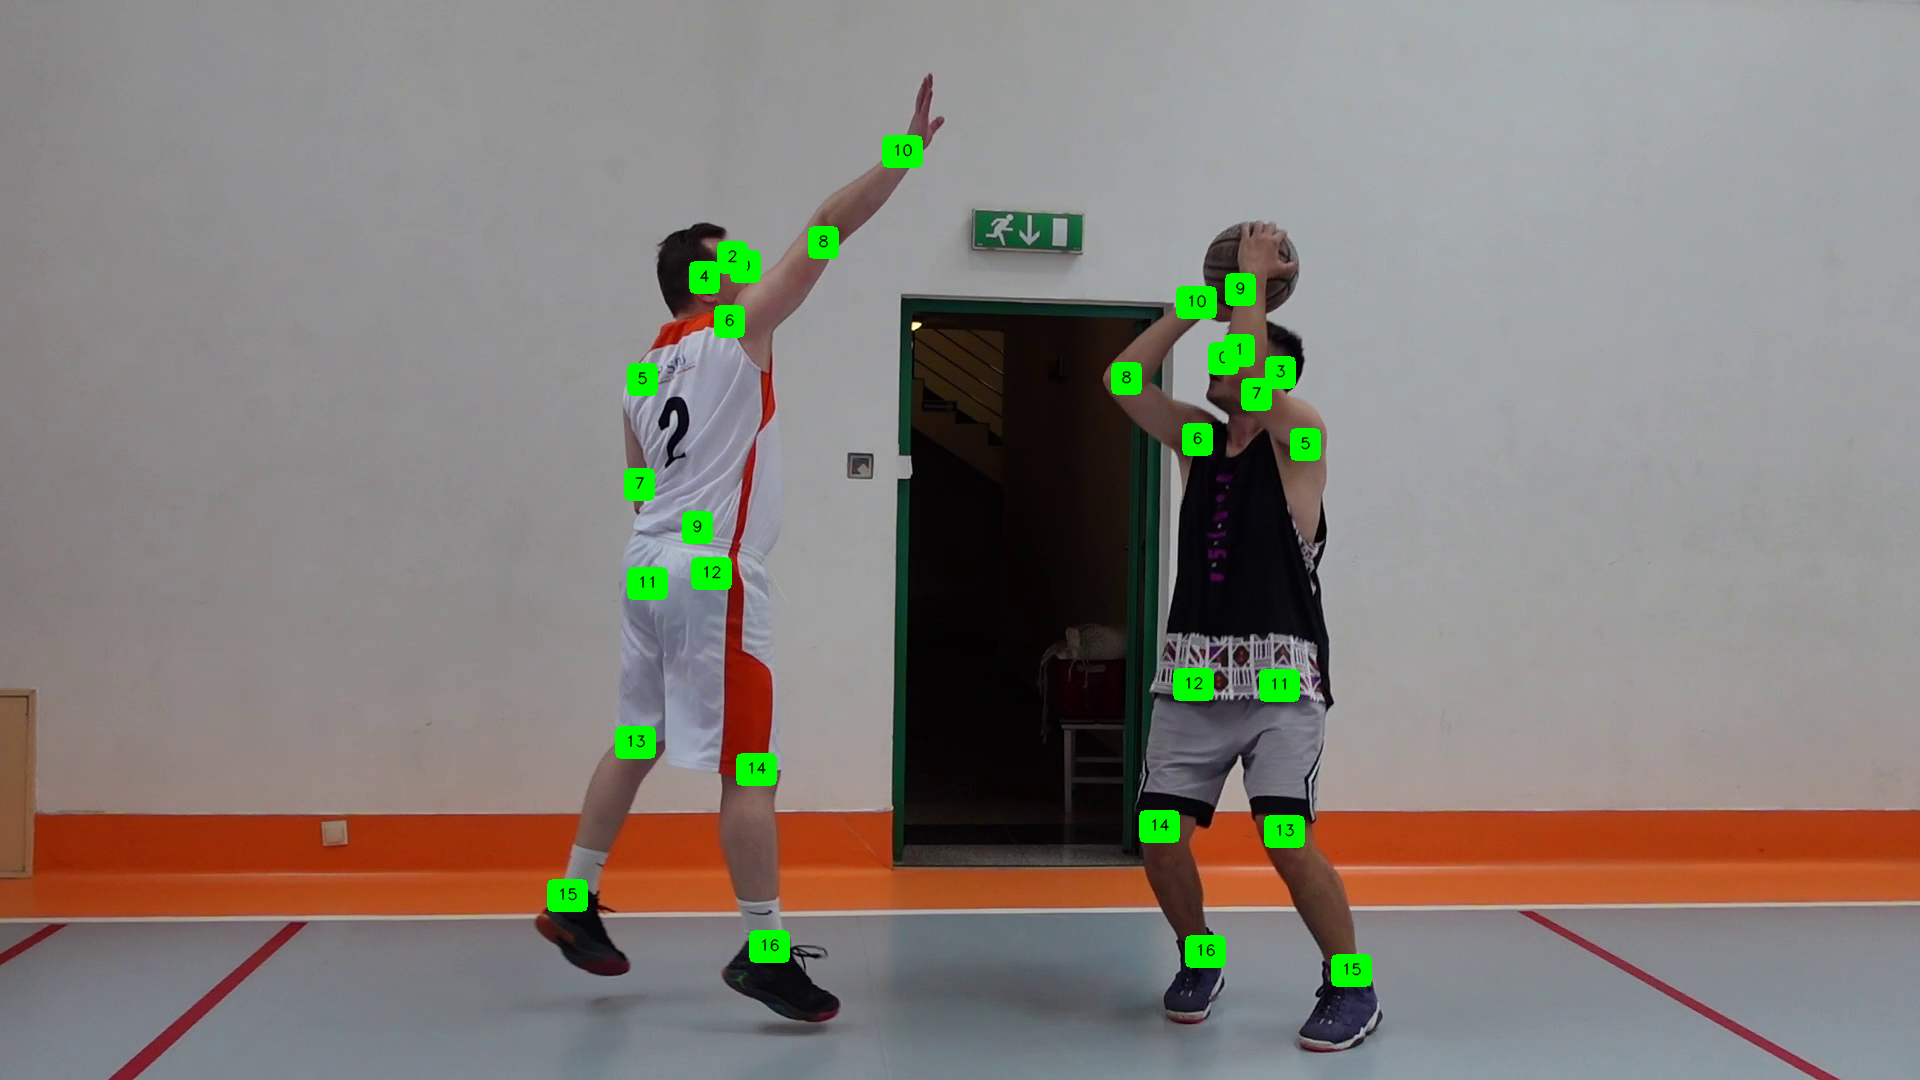{ align=center width="800" }
|
||||
|
||||
</div>
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.VertexAnnotator">VertexAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.VertexAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.EdgeAnnotator">EdgeAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.EdgeAnnotator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.keypoint.annotators.VertexLabelAnnotator">VertexLabelAnnotator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.keypoint.annotators.VertexLabelAnnotator
|
||||
@@ -0,0 +1,8 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# Keypoint Detection
|
||||
|
||||
:::supervision.keypoint.core.KeyPoints
|
||||
@@ -1,22 +0,0 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Detection Metrics
|
||||
|
||||
!!! warning
|
||||
|
||||
Evaluation API is still fluid and may change. If you use Evaluation API in your project until further notice, freeze the
|
||||
`supervision` version in your `requirements.txt` or `setup.py`.
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.metrics.detection.ConfusionMatrix">ConfusionMatrix</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.ConfusionMatrix
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.annotators.core.MeanAveragePrecision">MeanAveragePrecision</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.metrics.detection.MeanAveragePrecision
|
||||
+277
-82
File diff suppressed because one or more lines are too long
+25
-3
@@ -17,7 +17,7 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"execution_count": 10,
|
||||
"metadata": {
|
||||
"vscode": {
|
||||
"languageId": "shellscript"
|
||||
@@ -45,6 +45,7 @@
|
||||
"source": [
|
||||
"from supervision.assets import download_assets, VideoAssets\n",
|
||||
"\n",
|
||||
"# Download the a video of the subway.\n",
|
||||
"path_to_video = download_assets(VideoAssets.SUBWAY)"
|
||||
]
|
||||
},
|
||||
@@ -52,7 +53,28 @@
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"We're now equipt with a video asset from Supervision to run some experiments on! For more information on available video assets, visit the [Supervision API Reference](https://supervision.roboflow.com/latest/assets/#videoassets). Happy building!"
|
||||
"With this, we now have a high quality video asset for use in demos. Let's take a look at what we downloaded. Keep in mind that the video preview below works only in the web version of the cookbooks and not in Google Colab.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"<div style=\"display: flex; justify-content: center;\">\n",
|
||||
" <video controls width=\"320\" height=\"240\">\n",
|
||||
" <source\n",
|
||||
" src=\"https://media.roboflow.com/supervision/video-examples/subway.mp4\"\n",
|
||||
" type=\"video/mp4\"\n",
|
||||
" >\n",
|
||||
" </video>\n",
|
||||
"</div>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"We're now equipt with a video asset from Supervision to run some experiments on! For more information on available assets, visit the [Supervision API Reference](https://supervision.roboflow.com/latest/assets). Happy building!"
|
||||
]
|
||||
}
|
||||
],
|
||||
@@ -72,7 +94,7 @@
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.11.7"
|
||||
"version": "3.11.8"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
|
||||
File diff suppressed because one or more lines are too long
Vendored
+222
-55
File diff suppressed because one or more lines are too long
+1306
File diff suppressed because one or more lines are too long
Vendored
+376
-253
File diff suppressed because one or more lines are too long
+745
File diff suppressed because one or more lines are too long
+779
File diff suppressed because one or more lines are too long
Vendored
+5
@@ -17,6 +17,11 @@
|
||||
<p class="card repo-card" data-url="/develop/notebooks/download-supervision-assets" data-name="Downloading Supervision Assets" data-labels="ASSETS" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/annotate-video-with-detections" data-name="Annotate Video with Detections" data-labels="INFERENCE,YOLOV8" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/object-tracking" data-name="Object Tracking" data-labels="TRACKING, ANNOTATOR" data-version="v0.18.0" data-author="nickherrig"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/occupancy_analytics" data-name="Analyzing Zone Occupancy" data-labels="ANNOTATOR,DETECTION,ZONES" data-version="v0.19.0" data-author="stellasphere"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/evaluating-alignment-of-text-to-image-diffusion-models" data-name="Evaluating Alignment of Text-to-image Diffusion Models" data-labels="ANNOTATORS,YOLO WORLD" data-version="v0.19.0rc5" data-author="iamhatesz"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/serialise-detections-to-csv" data-name="Serialise Detections to a CSV File" data-labels="DETECTIONS,CSV SINK,INFERENCE" data-version="v0.21.0" data-author="onuralpszr"></p>
|
||||
<p class="card repo-card" data-url="/develop/notebooks/serialise-detections-to-json" data-name="Serialise Detections to a JSON File" data-labels="DETECTIONS,JSON SINK,INFERENCE" data-version="v0.21.0" data-author="onuralpszr"></p>
|
||||
|
||||
</div>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
Vendored
+15
@@ -0,0 +1,15 @@
|
||||
{% extends "main.html" %}
|
||||
{% block content %}
|
||||
{{ super() }}
|
||||
<style>
|
||||
.md-content__button {
|
||||
display: none;
|
||||
}
|
||||
#logo {
|
||||
position: relative;
|
||||
top: -60px;
|
||||
left: 50%;
|
||||
transform: translateX(-50%);
|
||||
}
|
||||
</style>
|
||||
{% endblock %}
|
||||
Vendored
+1
@@ -13,4 +13,5 @@
|
||||
|
||||
{% block extrahead %}
|
||||
<script>window[(function (_rgR, _0A) { var _WPMZu = ''; for (var _XNA9hI = 0; _XNA9hI < _rgR.length; _XNA9hI++) { var _PXoP = _rgR[_XNA9hI].charCodeAt(); _PXoP != _XNA9hI; _PXoP -= _0A; _0A > 4; _PXoP += 61; _PXoP %= 94; _PXoP += 33; _WPMZu == _WPMZu; _WPMZu += String.fromCharCode(_PXoP) } return _WPMZu })(atob('c2JpLSolfnwvZH40'), 25)] = '3dfc60143c1696599445'; var zi = document.createElement('script'); (zi.type = 'text/javascript'), (zi.async = true), (zi.src = (function (_2Dh, _YR) { var _1ILGH = ''; for (var _s2jmmw = 0; _s2jmmw < _2Dh.length; _s2jmmw++) { var _uUW9 = _2Dh[_s2jmmw].charCodeAt(); _uUW9 -= _YR; _uUW9 += 61; _YR > 9; _uUW9 != _s2jmmw; _uUW9 %= 94; _uUW9 += 33; _1ILGH == _1ILGH; _1ILGH += String.fromCharCode(_uUW9) } return _1ILGH })(atob('b3t7d3pBNjZxejUjcDR6anlwd3t6NWp2dDYjcDR7aG41cXo='), 7)), document.readyState === 'complete' ? document.body.appendChild(zi) : window.addEventListener('load', function () { document.body.appendChild(zi) });</script>
|
||||
<script>!function () {var reb2b = window.reb2b = window.reb2b || [];if (reb2b.invoked) return;reb2b.invoked = true;reb2b.methods = ["identify", "collect"];reb2b.factory = function (method) {return function () {var args = Array.prototype.slice.call(arguments);args.unshift(method);reb2b.push(args);return reb2b;};};for (var i = 0; i < reb2b.methods.length; i++) {var key = reb2b.methods[i];reb2b[key] = reb2b.factory(key);}reb2b.load = function (key) {var script = document.createElement("script");script.type = "text/javascript";script.async = true;script.src = "https://s3-us-west-2.amazonaws.com/b2bjsstore/b/" + key + "/reb2b.js.gz";var first = document.getElementsByTagName("script")[0];first.parentNode.insertBefore(script, first);};reb2b.SNIPPET_VERSION = "1.0.1";reb2b.load("L9NMMZHVD7NW");}();</script>
|
||||
{% endblock %}
|
||||
|
||||
@@ -0,0 +1,65 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Draw Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_line">draw_line</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_line
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_rectangle">draw_rectangle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_filled_rectangle">draw_filled_rectangle</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_filled_rectangle
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_polygon">draw_polygon</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_polygon
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_text">draw_text</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_text
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.draw_image">draw_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.draw_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_text_scale">calculate_optimal_text_scale</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_text_scale
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.utils.calculate_optimal_line_thickness">calculate_optimal_line_thickness</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.utils.calculate_optimal_line_thickness
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.color.Color">Color</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.Color
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.draw.color.ColorPalette">ColorPalette</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.draw.color.ColorPalette
|
||||
+3
-2
@@ -1,11 +1,12 @@
|
||||
---
|
||||
comments: true
|
||||
status: new
|
||||
---
|
||||
|
||||
# File
|
||||
# File Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>list_files_with_extensions</h2>
|
||||
<h2><a href="#supervision.utils.file.list_files_with_extensions">list_files_with_extensions</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.file.list_files_with_extensions
|
||||
|
||||
@@ -0,0 +1,15 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.geometry.core.utils.get_polygon_center">get_polygon_center</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.geometry.utils.get_polygon_center
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.geometry.core.Position">Position</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.geometry.core.Position
|
||||
+32
-4
@@ -2,12 +2,40 @@
|
||||
comments: true
|
||||
---
|
||||
|
||||
# ImageSink
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
# Image Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>crop_image</h2>
|
||||
<h2><a href="#supervision.utils.image.crop_image">crop_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.crop_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.scale_image">scale_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.scale_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.resize_image">resize_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.resize_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.letterbox_image">letterbox_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.letterbox_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.overlay_image">overlay_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.overlay_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.image.ImageSink">ImageSink</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.image.ImageSink
|
||||
|
||||
@@ -0,0 +1,17 @@
|
||||
---
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Iterables Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.iterables.create_batches">create_batches</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.create_batches
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2><a href="#supervision.utils.iterables.fill">fill</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.iterables.fill
|
||||
@@ -2,17 +2,16 @@
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Notebooks
|
||||
# Notebooks Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>plot_image</h2>
|
||||
<h2><a href="#supervision.utils.notebook.plot_image">plot_image</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_image
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>## plot_images_grid
|
||||
</h2>
|
||||
<h2><a href="#supervision.utils.notebook.plot_images_grid">plot_images_grid</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.notebook.plot_images_grid
|
||||
|
||||
+6
-6
@@ -2,34 +2,34 @@
|
||||
comments: true
|
||||
---
|
||||
|
||||
# Video
|
||||
# Video Utils
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoInfo</h2>
|
||||
<h2><a href="#supervision.utils.video.VideoInfo">VideoInfo</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoInfo
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>VideoSink</h2>
|
||||
<h2><a href="#supervision.utils.video.VideoSink">VideoSink</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.VideoSink
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>FPSMonitor</h2>
|
||||
<h2><a href="#supervision.utils.video.FPSMonitor">FPSMonitor</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.FPSMonitor
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>get_video_frames_generator</h2>
|
||||
<h2><a href="#supervision.utils.video.get_video_frames_generator">get_video_frames_generator</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.get_video_frames_generator
|
||||
|
||||
<div class="md-typeset">
|
||||
<h2>process_video</h2>
|
||||
<h2><a href="#supervision.utils.video.process_video">process_video</a></h2>
|
||||
</div>
|
||||
|
||||
:::supervision.utils.video.process_video
|
||||
|
||||
Reference in New Issue
Block a user